Your product can rank in conventional search and still disappear when a shopper asks an AI assistant what to buy. The missing piece is usually not another generic category paragraph. It is making the product easy to identify, test against constraints, and defend in a recommendation.
AI personal shoppers can shape which products make the shortlist. That changes your visibility target. You are no longer optimizing only for a page visit; you are helping a system decide whether your product is eligible, relevant, credible, and safe to recommend for a particular request.
AI shopping visibility is a three-gate problem
There is no universal ranking formula for AI shopping. Assistants use different catalogs, retrieval systems, merchant feeds, pages, and models. Their answers can also change as availability, prices, prompts, and underlying systems change. A practical three-gate model is more useful than pretending every platform works the same way.
- Discovery: Can the assistant find and identify the correct product or variant?
- Qualification: Can it determine whether the product satisfies the shopper’s stated constraints?
- Selection: Is there enough relevant evidence to choose the product and explain that choice?
A product has to pass the gates in that order. Better promotional copy cannot rescue a product the system cannot identify. Strong reviews cannot compensate for an unspecified compatibility requirement. Complete structured data does not prove a broad superiority claim.
This sequence gives you a diagnostic method. If the product never appears, inspect discovery before rewriting the sales copy. If it appears for broad prompts but disappears when a constraint is added, inspect the relevant attribute. If it remains eligible but another product receives the recommendation, inspect comparative relevance and supporting evidence.
The important distinction is between being mentioned and being recommendable. A system may know that your product exists while lacking the facts needed to place it in a defensible shortlist.
Build one canonical product truth
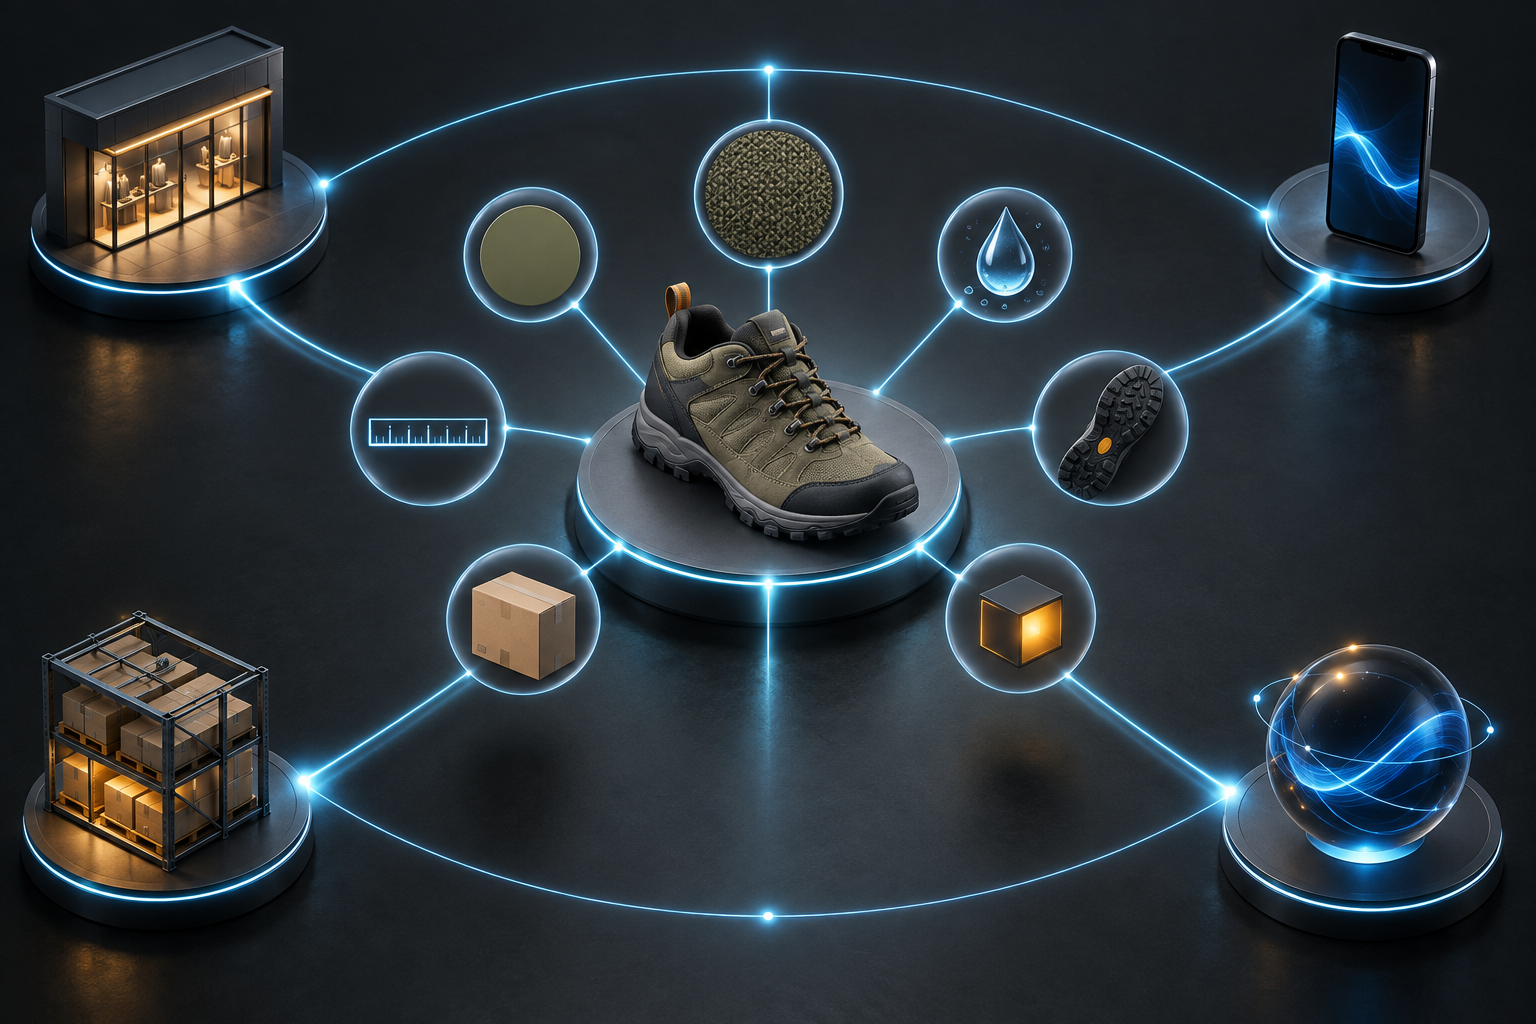
Start with an internal product record, not a block of marketing copy. This record should be the authoritative source for the product page, structured data, merchant feeds, marketplace listings, comparison pages, and support content. When those surfaces disagree, an assistant has to choose among conflicting claims or avoid repeating them.
For each product and meaningful variant, define the following fields explicitly:
- Identity: brand, product name, model, assigned SKU or GTIN, canonical URL, and product category.
- Variant: color, size, capacity, material, pack quantity, configuration, and the relationship to the parent product.
- Eligibility attributes: dimensions, weight, compatibility, intended use, required accessories, included components, operating conditions, and other category-specific constraints.
- Commercial facts: price, currency, condition, availability, fulfillment terms, returns, and warranty terms.
- Evidence: certifications, documented test conditions, review data, manuals, specifications, and the exact scope of each claim.
Do not populate a field because competitors use it or because a schema validator permits it. An unknown value should remain unknown until the business can verify it. A precise false claim is worse than an honest omission because the false claim can be repeated in a recommendation, create a poor purchase, and undermine trust in the rest of your data.
Keep the visible page, schema, and feeds aligned
Product structured data should encode facts that a shopper can also verify on the page. Use Product markup to identify the item and its attributes. Use Offer data only for an offer that actually exists. Add rating or review properties only when the corresponding information is genuine, visible, and attached to the correct product or variant.
JSON-LD does not create product truth. It translates product truth into a machine-readable form. If the page says one material, the markup says another, and the feed omits the field, adding more schema will multiply the ambiguity rather than fix it.
Variant handling deserves particular attention. A family page may describe several configurations, but price, dimensions, availability, ratings, and compatibility can belong to only one of them. Give meaningful variants stable identities and make the selected variant unambiguous in the page content, URL behavior, structured data, and feed.
Separate durable facts from fast-changing facts
Product data fails at different speeds. Model identity, dimensions, materials, compatibility, and included components are usually durable. Price, availability, promotions, delivery estimates, and review aggregates can change much faster.
Give each fast-changing field an owner, a system of record, and a refresh trigger. Avoid embedding volatile values in editorial prose unless that prose is updated from the same source. A stale promotional page and a current product feed can leave an assistant with two plausible answers and no reliable way to reconcile them.
Match shopper constraints and support every important claim
Traditional product copy often begins with a head keyword and expands into benefits. AI shopping requests are more likely to combine a job, a hard constraint, and a preference: a product for a particular use, compatible with something the shopper already owns, within a budget, and with a preferred trade-off.
Create a prompt set from the decisions people make, not just the phrases with the highest search volume. Include several distinct request types:
- Job prompts: What is the shopper trying to accomplish?
- Constraint prompts: What would make a product ineligible, such as size, compatibility, material, price, or availability?
- Trade-off prompts: Which quality matters more when no option maximizes everything?
- Comparison prompts: Which alternatives are genuinely close enough to compare?
- Risk prompts: What must the shopper verify before buying?
Then map every consequential question to a field and a piece of evidence. The map exposes a common failure: the marketing team believes a benefit is obvious, but the product page never supplies the fact an assistant would need to infer it safely.
| Shopper question | Machine-readable answer | Human-verifiable support |
|---|---|---|
| Will it fit? | Dimensions, weight, capacity, or supported size range | Specification table, diagram, or installation instructions |
| Will it work with what I own? | Compatible models, interfaces, versions, or required accessories | Compatibility page, manual, or clearly scoped support content |
| Can I buy it under my stated conditions? | Current price, currency, condition, availability, and offer details | Visible offer and fulfillment information |
| Is it suitable for this use? | Intended use and relevant product attributes | Use-case explanation tied to specifications rather than slogans |
| Can I trust this claim? | Named evidence and its scope | Certification details, documented method, policy, or attributable review data |
State who the product is and is not for
A useful product page helps an assistant eliminate the wrong matches. State the primary use, the buyer or environment it suits, the constraints it satisfies, and any condition that would make another option more appropriate.
This does not weaken the offer. A clear limitation can make the positive recommendation more credible. If a product requires an adapter, has a fixed dimension, excludes a particular model, or is designed for one usage pattern rather than another, say so close to the relevant benefit. Hiding the qualifier may generate more initial interest, but it gives an assistant less reason to trust or repeat the claim.
Comparison content should use decision criteria rather than a list of adjectives. Explain which product fits which condition and why. Avoid declaring an item the best without naming the use case, comparison set, and evidence. An unqualified superlative is difficult to defend and easy for a recommendation system to ignore.
Maintain a claim-to-evidence ledger
For every claim that could change a purchase decision, keep an internal ledger containing the claim, its exact qualifier, the supporting evidence, the page where that evidence is visible, the responsible owner, and the event that should trigger a review.
The qualifier matters. A certification may apply to one variant, a test may use specific conditions, and a warranty may differ by market. Preserve that scope everywhere the claim appears. Do not turn narrow evidence into a product-wide promise.
Customer reviews can help describe recurring strengths and limitations, but keep review data attached to the product or variant it evaluates. Combining materially different variants may produce a stronger aggregate while giving the assistant a less accurate picture of the item in front of the shopper.
Support pages, manuals, compatibility resources, return policies, and comparison pages should link back to the canonical product and use the same names and identifiers. That creates a coherent evidence trail instead of a set of disconnected documents with slightly different terminology.
Audit the complete path from prompt to recommendation
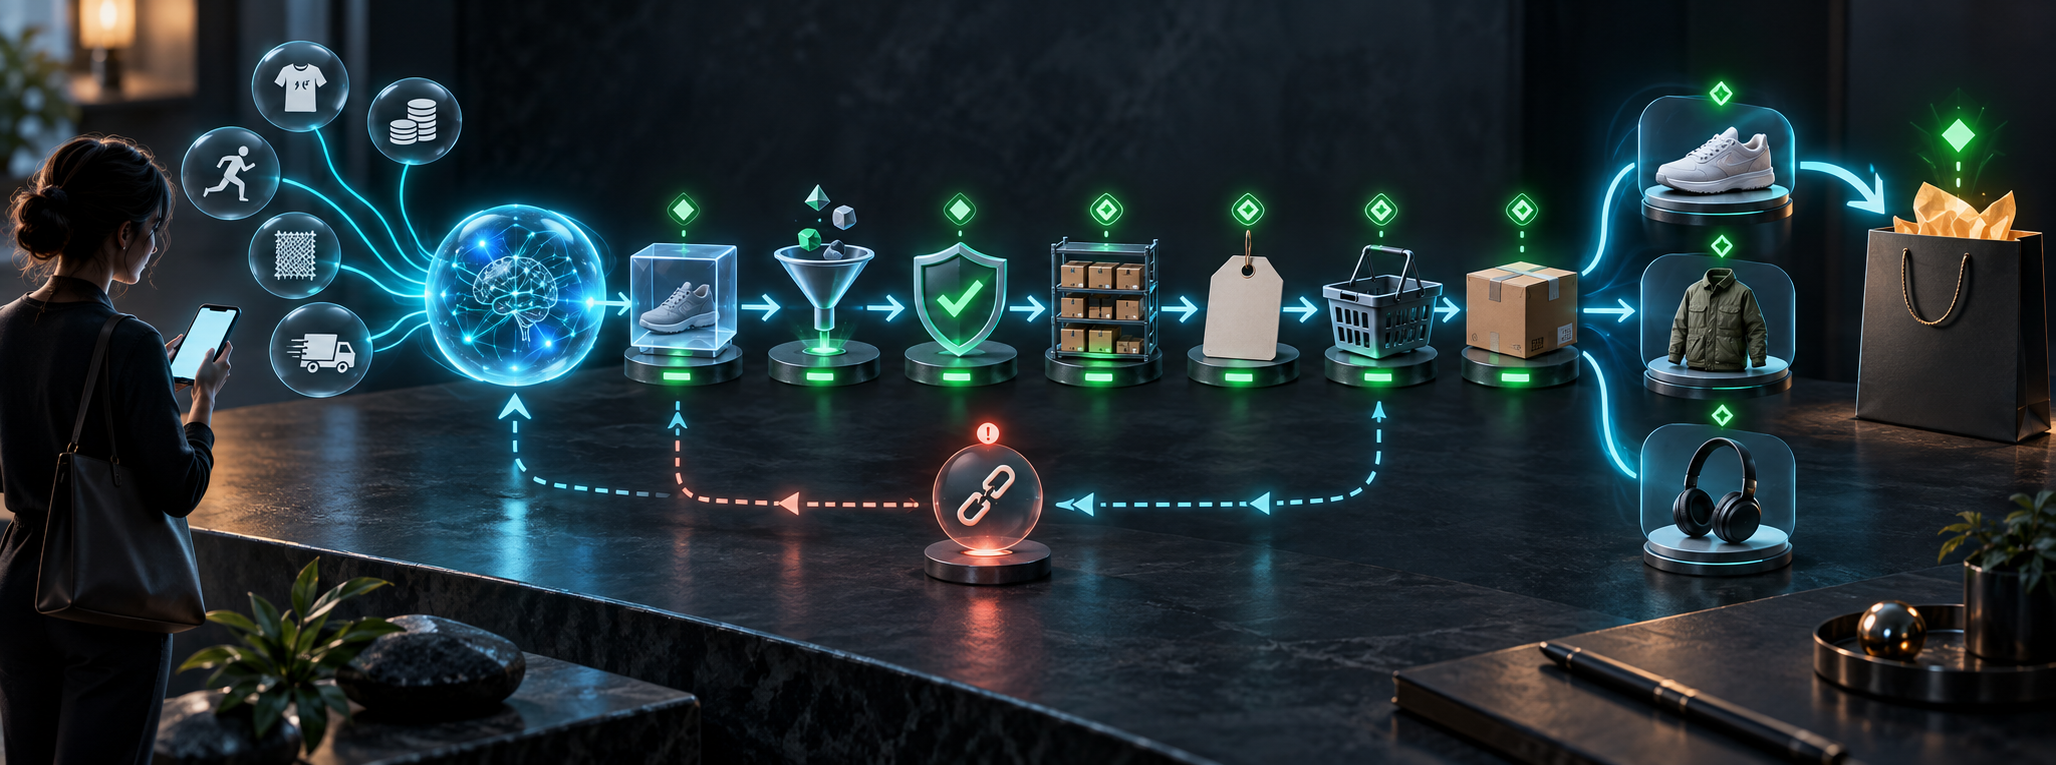
Do not reduce AI shopping visibility to a rank check. You need to see where the product exits the decision process and whether the answer is factually correct when it does appear.
- Choose eligible prompts. Test requests for which the product could honestly be a suitable answer. Irrelevant prompts distort the score and tempt teams to broaden claims beyond the product’s real fit.
- Record a baseline. Save the exact prompt, assistant, date, market or locale, response, recommended products, stated reasons, and any surfaced links.
- Label the outcome. Distinguish absence, failed qualification, incorrect description, unsupported mention, and an eligible product that lost on a documented trade-off.
- Trace the earliest failed gate. Repair identity and discovery before attributes, attributes before evidence, and evidence before promotional expansion.
- Rerun the same prompt set. Compare changes in coverage and accuracy while recognizing that any individual generated response can vary.
- Inspect the commercial handoff. If the recommendation is accurate but the shopper does not proceed, examine the offer, availability, landing experience, and product-market fit rather than calling every weak outcome an AI visibility problem.
The failure pattern tells you where to look first:
| Observed result | Likely failure area | First inspection |
|---|---|---|
| The product never appears | Discovery | Indexability, canonical URL, feed inclusion, product identity, and internal linking |
| The wrong variant appears | Identity | Variant names, identifiers, URLs, parent relationships, and selected-offer data |
| The product disappears after a valid constraint is added | Qualification | The missing, ambiguous, or conflicting attribute associated with that constraint |
| The assistant states an incorrect fact | Product truth | Conflicts and stale values across the page, schema, feed, marketplace, and support content |
| The product is considered but not recommended | Selection | Use-case specificity, comparison criteria, limitations, and claim-level evidence |
| The recommendation is accurate but does not convert | Commercial handoff | Price, availability, trust, offer clarity, landing experience, and actual product fit |
Track metrics that correspond to those states. Prompt coverage shows whether the product appears for eligible requests. Attribute resolution shows whether the assistant can answer the important constraint questions. Answer accuracy catches misdescription. Evidence visibility shows whether useful supporting pages are surfaced. Recommendation share shows how often the product is selected when it is genuinely eligible. Commercial outcomes tell you whether improved visibility creates useful demand.
Keep the prompt set and eligibility rules stable while evaluating a change. If you change the content, prompts, markets, and success definition at the same time, you will not know what improved. Treat assistant outputs as observations, not permanent rankings.
Key takeaways
- Optimize for discovery, qualification, and selection as separate gates.
- Create one canonical product record before expanding copy, schema, feeds, or comparison content.
- Make decisive constraints explicit; do not ask an assistant to infer compatibility, fit, or eligibility from vague prose.
- Keep visible content, Product structured data, offers, variants, and merchant feeds consistent.
- Attach meaningful claims to scoped evidence and state important limitations plainly.
- Measure eligible prompt coverage and factual accuracy before treating recommendation share as the main result.
Start with one commercially important product family. Establish its canonical facts, build prompts around real purchase constraints, and fix the earliest gate that fails. Once that path is reliable, extend the same operating model to the rest of the catalog. That gives you a repeatable visibility system instead of a collection of schema additions and copy changes whose effect you cannot explain.
References

Leave a Reply