Tag: AI SEO

  • How to Choose a Robotics SEO Agency for Search and AI

    How to Choose a Robotics SEO Agency for Search and AI

    You are not hiring someone to make a robotics blog busier. You are choosing who will translate technical products, applications, integrations, and proof into pages that engineers trust, buyers can navigate, and search systems can understand.

    The right agency depends less on a league-table position than on your actual constraint. You may need deeper robotics fluency, stronger search execution, an AI visibility program, a new industrial website, or a broader B2B marketing partner. Identify that constraint first, then make every finalist prove it can remove it.

    Key takeaways

    • Choose an agency model before choosing an agency. SEO/GEO specialists, engineering marketing firms, full-service B2B agencies, and industrial web firms solve different problems.
    • Test technical accuracy with a paid assignment based on a real product or application. A polished generic sample does not show whether the team can handle your terminology, evidence, and commercial intent.
    • Score search performance and robotics expertise separately. High rankings do not prove that an agency can produce content your engineers will approve or your prospects will use.
    • Require distinct SEO and generative engine optimization measurements. The work can share a content plan, but rankings, qualified organic conversions, AI mentions, citations, and referral traffic are not interchangeable metrics.
    • Put roles, review responsibilities, account access, content ownership, correction procedures, and reporting definitions into the agreement before production begins.

    Choose the agency model before you compare agencies
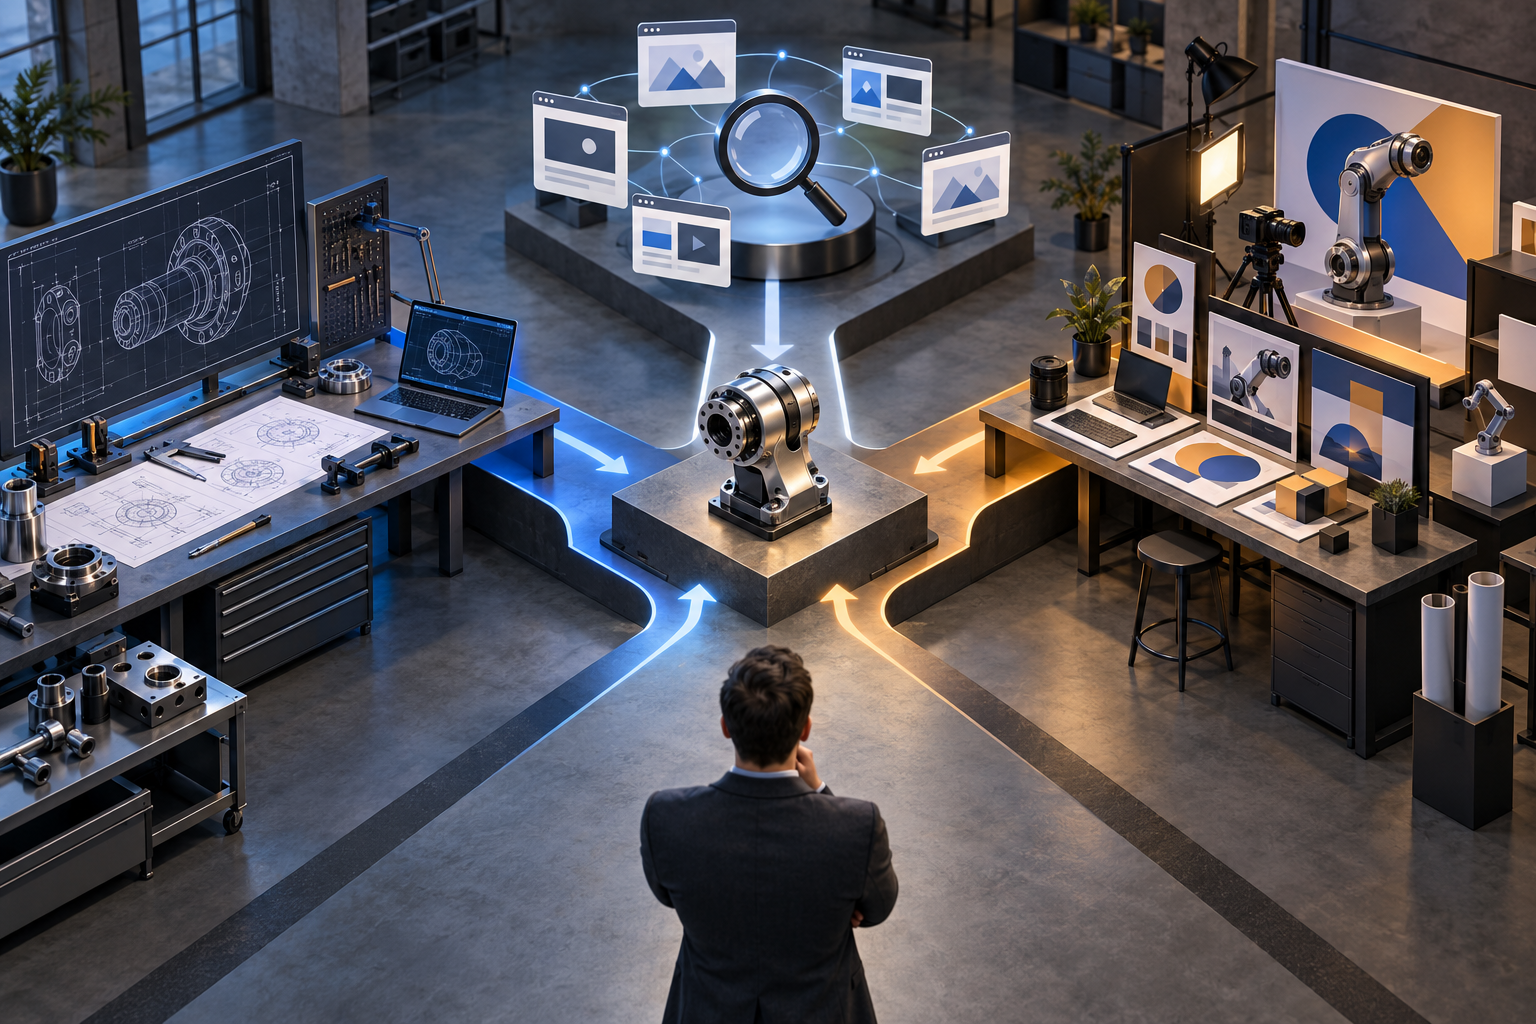
    A decision-maker compares three visual pathways leading to a robot component, representing technical, search-focused, and integrated agency models.

    Your practical options fall into four models. The named 2026 field includes eight agencies, but their operating models matter more than their order.

    Agency modelCandidates to investigatePut this model on your shortlist whenWhat you must verify
    SEO and GEO specialistFirst Page Sage, Driven Metrics, GenevateOrganic discovery across conventional search and generative platforms is the central assignment.Robotics fluency, writer credentials, technical review requirements, and evidence connecting visibility to qualified pipeline.
    Engineering or industrial marketing specialistTREW Marketing, Gorilla 76Your team needs technical content and wider industrial positioning, branding, or demand-generation support.Who owns technical SEO, search-intent analysis, authority development, structured data, and AI visibility measurement.
    Full-service or regional B2B agencyWalker Sands, Motion MarketingYou need a broader B2B program, or regional fit in the UK and Europe is a meaningful requirement.Whether SEO has dedicated leadership and resources rather than being a small component inside a larger account.
    Industrial web and positioning partnerWindmill StrategyA website rebuild, industrial user experience, and market positioning are tied to the search project.The content, authority, conversion, and measurement program that continues after the new site launches.

    Start with the bottleneck. If engineering spends most of its time correcting outsourced copy, favor technical specialization. If good technical material already exists but qualified prospects cannot find it, favor search execution. If the website cannot express product relationships or route different buyers to the right next step, address information architecture before funding a large publishing schedule.

    Do not treat GEO as a decorative add-on. If AI discovery matters to your buyers, the agency should be able to explain which questions it will monitor, which pages should become citable answers, how it will record mentions and cited URLs, and how that activity connects to your commercial funnel. A logo slide that lists ChatGPT or AI search is not a strategy.

    One conflict deserves explicit treatment: First Page Sage created the ranking that places First Page Sage first. Its grades and review snippets are useful for finding candidates, but they are not independent validation. Apply the same evidence request to every firm, including the evaluator.

    Test whether the team can support a technical buying decision

    Robotics search is not one market. A company may need to reach people researching industrial robots, collaborative robots, machine vision, robotic components, automation applications, autonomous navigation, or AI-powered robotics. Those are not interchangeable keyword groups. Each can involve different buyers, technical questions, objections, evidence, and conversion paths.

    This is where generic content programs break. An agency can produce grammatically clean pages while confusing a component with a complete system, overlooking an integration constraint, mixing educational and transactional intent, or sending an engineer to a call-to-action meant for an executive buyer. Traffic does not repair that mismatch.

    Require a product-to-query map

    Before approving a content calendar, ask the agency to map your real offer into page roles. The map should show how a prospect moves from a problem or application to a technology, a product, credible proof, and an appropriate next step.

    • Product and category pages should establish what you sell, who it is for, where it fits, and which technical claims can be supported.
    • Application pages should connect a real operating problem to the relevant system without pretending that every deployment has the same requirements.
    • Technology pages should explain important mechanisms, components, software, sensing, navigation, or integration concepts in language that remains technically defensible.
    • Evaluation pages should help a buyer compare approaches, specifications, implementation requirements, and tradeoffs without manufacturing a false winner.
    • Proof pages should make case evidence, technical documentation, certifications, test information, and deployment details easy to locate when those materials exist.
    • Conversion paths should match intent. A buyer who needs documentation, an integration discussion, or a system assessment should not be forced through the same generic contact form.

    Reject a proposal that turns this architecture into a pile of loosely related blog topics. Informational content can create discovery, but the program also needs pages that explain the offer, resolve evaluation questions, establish evidence, and let a qualified prospect act.

    Run a paid proof-of-work assignment

    Portfolio samples show what survived another client’s approval process. They do not reveal how the agency handles your technology. A contained paid assignment is a fairer test for both sides.

    1. Select a commercially important product, category, or application page. Use something technical enough to expose weak reasoning, but remove confidential material.
    2. Give every finalist the same brief, approved terminology, existing evidence, target audience, and business objective.
    3. Ask for a search-intent assessment, proposed outline, representative passage, internal-link recommendations, conversion step, and a list of questions or unsupported claims that require expert review.
    4. Have marketing, product, engineering, and sales review the work independently. Each group should mark factual errors, missing buyer questions, unclear positioning, and commercially irrelevant material.
    5. Compare not only the finished prose but also the questions each agency asked. A team that identifies uncertainty is safer than one that fills knowledge gaps with confident language.

    Use hard gates. An invented capability, altered specification, unsupported performance claim, or fabricated customer outcome should fail the test. So should a page with no identifiable audience or next step. Minor editing is normal; rebuilding the technical logic is evidence that your subject-matter experts will become unpaid ghostwriters for the agency.

    Score SEO and GEO as connected but different jobs
    A robot connects to a search network on one side and an AI source network on the other through a shared technical knowledge core.

    You can borrow a transparent starting scorecard from the market: ranking proficiency at 25%, robotics expertise at 20%, content execution at 20%, client ratings at 15%, SEO specialization at 10%, and a GEO offering at 10%. Those dimensions expose useful differences, but they should not make the decision for you.

    • Ranking proficiency asks whether the agency can earn meaningful search visibility, not merely publish optimized pages.
    • Robotics expertise asks how quickly the team can understand your technology, language, ecosystem, and buyer concerns.
    • Content execution asks whether the agency can turn that understanding into accurate, useful, discoverable material.
    • Client ratings can surface communication and delivery patterns, but references should be checked directly and matched to work similar to yours.
    • SEO specialization indicates whether organic search is a central discipline or one service inside a much broader portfolio.
    • GEO capability asks whether the agency has a defined approach to discovery and citation in generative platforms rather than a newly relabeled content package.

    Add four pass-or-fail criteria before you total any score: commercial relevance, measurement quality, operating fit, and ownership. A highly rated firm is still the wrong choice if it cannot connect work to your ideal customer profile, fit your expert-review capacity, expose how results are measured, or leave you in control of your assets.

    Demand separate measurement plans

    SEO and GEO can use the same underlying knowledge, pages, proof, and authority signals. They should not be collapsed into a single visibility number.

    • For SEO, require reporting by query family and landing-page group. Track relevant visibility, qualified organic actions, sales acceptance, opportunity creation, and pipeline where your systems allow it.
    • For AI discovery, define a repeatable set of buyer questions. Record the platform, prompt, date, brand mention, cited domain, cited landing page, competitor presence, referral traffic when identifiable, and any resulting qualified action.
    • For technical health, monitor whether important pages can be crawled, indexed, understood, internally linked, and kept aligned with the site’s visible structured information.
    • For content operations, monitor approval delays, substantive factual corrections, revision causes, and the amount of subject-matter-expert effort required for each deliverable.

    Ask to see how reporting changes a decision. If a dashboard cannot tell the team what to update, consolidate, expand, stop, or promote, it is record-keeping rather than management.

    Keep schema in its proper role

    A robotics SEO agency should understand structured data, but schema markup cannot rescue vague positioning or unsupported technical claims. Ask how the agency will keep company names, product relationships, applications, specifications, authorship, and other visible facts consistent between page copy, structured data, internal links, and external profiles.

    Reject promises that markup alone will create rankings or AI recommendations. The useful test is whether structured data accurately represents visible, maintained content and makes important entities and relationships less ambiguous. It should be part of technical implementation and governance, not a substitute for evidence-rich pages.

    Contract for the operating model, not the pitch

    The sales team can sound technically fluent while the delivery team operates very differently. Before signing, ask for the proposed strategist, project lead, writer, editor, technical SEO owner, analytics owner, and backup coverage. If names are not yet available, require role descriptions, relevant backgrounds, allocation expectations, and the process for approving replacements.

    Define the review workflow

    • State who interviews subject-matter experts, prepares questions, records approved terminology, and maintains the factual brief.
    • Separate factual approval from brand editing. Engineers should not have to rewrite tone, headings, metadata, calls to action, or basic page structure.
    • Define what counts as a deliverable: a draft in a document is different from a published, internally linked, quality-checked page with appropriate metadata and structured information.
    • Create a correction path for technical errors. Specify who pauses publication, who approves the correction, and how related pages are checked for the same mistake.
    • Agree on how changes in products, specifications, positioning, regulations, or supporting evidence reach the content team and trigger updates.

    Your internal capacity should influence the choice. A search specialist that expects substantial client expertise may work well when product marketers and engineers can support it. The same arrangement will stall if experts are unavailable or if every draft becomes a reconstruction project. Make that workload visible in the proposal rather than discovering it after the content calendar starts.

    Protect access, ownership, and continuity

    Confirm in the agreement who owns commissioned content, keyword and prompt maps, reporting files, creative assets, analytics configurations, structured-data work, and any custom tooling. Keep company-controlled access to the CMS, analytics, search accounts, tag management, domain, hosting, and relevant AI-monitoring systems. Losing those assets or permissions can make an agency transition expensive and slow, so have the appropriate internal or legal reviewer check the final terms.

    Also define what happens when performance disappoints. The agency should be able to diagnose whether the constraint is technical, competitive, editorial, authoritative, commercial, or operational. A useful review ends with a decision and an owner, not another month of unchanged production.

    Before your next agency call, choose a real commercial page and a real family of buyer questions. Send the same sanitized assignment to each finalist and compare the returned reasoning, not just the presentation. The strongest candidate will expose uncertainty, protect technical accuracy, connect discovery to a buying decision, and define measurement before promising growth.

    References


  • How to Build an SEO Career Without Waiting to Be Hired

    How to Build an SEO Career Without Waiting to Be Hired

    If you have been learning SEO but keep meeting the same barrier — no job without experience, no experience without a job — stop treating an offer letter as permission to begin. A certificate can show that you studied the subject. It cannot show how you make decisions when the audience, budget, traffic, and outcome are real.

    Build a small project with a real audience and a useful offer. Use it to practise SEO, GEO, content, measurement, and responsible AI use as connected disciplines. The project does not need to become a large business. It needs to produce credible evidence of how you identify a problem, choose an action, measure the result, and learn from what happened.

    Stop optimizing for permission and start producing evidence

    The conventional entry route is harder to navigate when businesses can automate tasks that once gave junior employees their initial experience. Economic pressure and uncertainty around search add to the problem. Sending applications still matters, but it cannot be your only career strategy.

    Learning and evidence are different things. Learning tells you what a canonical tag does. Evidence shows that you found a canonicalization problem, understood its effect, chose a safe correction, and checked the result. Learning explains search intent. Evidence shows how you mapped a real customer’s questions to pages and calls to action.

    CapabilityWeak career signalStronger project evidence
    Audience researchYou say that you understand search intent.You show how customer questions shaped an offer, query map, and page plan.
    Technical SEOYou list an auditing tool on your CV.You document an indexing, internal-linking, canonical, or rendering issue and the reasoning behind your response.
    ContentYou publish generic advice about SEO.You create content that helps a defined audience evaluate or use something, then examine what visitors do next.
    GEO and AI visibilityYou describe yourself as an AI search expert.You keep a dated record of how relevant AI systems represent the project, where answers are inaccurate, and what you changed.
    Commercial judgmentYou claim to be strategic.You explain why one task deserved limited time or money while another did not.

    Your project gives an employer or client something concrete to question. Why did you target that audience? Why did you create that page before another one? What evidence changed your mind? What failed? Strong answers reveal judgment more reliably than a collection of tool badges.

    You also do not need to create financial pressure for the sake of appearing committed. If you need the income from your current job, keep it. An SEO career can begin alongside the work and responsibilities you already have. Choose a project small enough to maintain consistently rather than planning a second full-time job that you will abandon.

    Choose a project with a real audience and a real action

    A creator photographs a handmade planter at a community market while two visitors examine the product and use a phone.

    A practice website about SEO may help you learn a content management system, but it often removes the hard part of the job: understanding somebody else’s customer. It also encourages a weak success metric — publishing articles and waiting for traffic.

    A better project gives people something useful to do, request, join, download, book, or buy. It might be a small app, service, product, or other offer in a field you understand. Content then supports the offer instead of becoming the entire business model.

    Use these filters before committing:

    • Audience access: You can observe where the intended users ask questions and how they describe the problem. If you cannot reach or listen to them, your assumptions will be hard to correct.
    • A recognizable need: The project solves a specific problem rather than serving a vague interest. The need does not have to be large, but a real person should be able to recognize it as their own.
    • A meaningful action: Visitors can do more than read. Give them a clear next step that creates a measurable signal of interest.
    • Manageable production: You can build and support the offer with the time, skills, and money available to you. A narrower live project is more useful than an ambitious concept that never launches.
    • Room for discovery work: Potential users look for answers, recommendations, providers, products, or comparisons through search, AI assistants, communities, or relevant publications.
    • Safe subject matter: Avoid a field in which useful advice would require professional credentials or access to sensitive information you do not have.

    Write a short opportunity brief before building anything. It should name the audience, the problem, the offer, the intended user action, the places where discovery may happen, and the constraints under which you will work. Add what you currently believe and what evidence could prove you wrong. This turns the project from an open-ended hobby into a series of decisions.

    Do not define success as becoming a large business. That outcome is outside your control and unnecessary for the career goal. Define success as producing an honest body of evidence: a live offer, observable user behavior, documented interventions, technical decisions, and conclusions that respect the limits of the data.

    A project that receives little interest can still teach you something valuable. Perhaps the need was weak, the positioning was unclear, the audience was difficult to reach, or the offer asked for too much commitment. Your task is not to disguise that result. It is to work out which explanations the evidence supports and what you would test next.

    Run the project like a small SEO and GEO account

    The project becomes career evidence only when you can reconstruct what happened. Keep a decision log from the beginning. Memory turns experiments into neat stories; a dated record preserves the uncertainty, alternatives, and inconvenient results that demonstrate how you actually think.

    Capture a baseline before making changes

    Record the condition you are starting from, even if the initial values are empty. Depending on the project, the baseline may include:

    • The pages you intend search engines to access and the pages currently indexed.
    • The queries, impressions, clicks, and landing pages visible in Google Search Console.
    • The actions you count as meaningful, such as an inquiry, signup, download, booking request, or purchase.
    • Existing brand mentions, links, directory entries, referrals, and community visibility.
    • How relevant AI systems answer discovery and comparison questions connected to the project.
    • Errors, omissions, inconsistent facts, missing citations, or competitor recommendations in those AI answers.

    For AI observations, save the exact question, the system or model used, the date, the answer, any cited pages, and your interpretation. Treat that record as an observation of a changing interface, not as a universal ranking report. A later answer may differ for reasons unrelated to your work.

    Make each change answer a defined question

    Start with access and comprehension. Check response status, robots directives, canonical signals, internal links, sitemaps, page templates, and whether important content is available without a fragile interaction. If you add structured data, it should describe information that is genuinely present and visible on the page. Passing a validator does not repair a weak or misleading page.

    Then connect demand to the offer. Group queries and audience questions by the task behind them: learning, comparing, evaluating suitability, resolving an objection, or taking action. Map each meaningful task to the page best equipped to satisfy it. This prevents the common habit of producing disconnected articles merely because a keyword tool returned a phrase.

    For every substantial intervention, record:

    • Observation: What did you notice, and where did the evidence come from?
    • Hypothesis: What do you think is happening, and what alternative explanation remains plausible?
    • Decision: What will you change, postpone, or deliberately leave alone?
    • Expected signal: What behavior or search signal would support the hypothesis?
    • Result: What happened after the change, including a null or negative outcome?
    • Confounders: What else changed that could have affected the result?
    • Next action: What will you do because of what you learned?

    Where practical, avoid changing several major variables at once. Allow an observation period that makes sense for the project’s traffic and the type of change, and choose that period before seeing the outcome. Sparse data may not justify a firm conclusion. Say so. Causal restraint is a strength in a case study, not an admission of weakness.

    Use AI to increase your capacity, not to impersonate expertise

    AI can help you prototype an interface, organize audience language, classify information, draft test cases, or automate repetitive work. It can also produce plausible errors. The useful professional skill is not collecting prompts; it is knowing enough about the underlying task to recognize and correct bad output.

    Keep the review step visible. Note what AI helped produce, what you verified, what you rejected, and why. If it drafts structured data, compare every property with the visible page and the vocabulary you intend to use. If it clusters queries, inspect ambiguous terms and outliers. If it summarizes customer comments, return to the original language before deciding what customers need.

    Apply the same discipline to tools. You do not need an agency-sized stack to prove that you can do SEO. Every paid subscription should answer a practical question: Did it reveal information you could not obtain another way? Did that information change a decision? Did the resulting action contribute to a useful outcome? Working without somebody else’s software budget can sharpen the commercial judgment future employers need.

    Traffic alone is not the outcome. Connect discovery to behavior. A page can gain impressions without attracting the right visitors, and visits can grow without producing interest in the offer. Report the chain honestly: visibility, visits, meaningful actions, and any evidence of commercial value. If the chain breaks, the break is the problem to investigate.

    Turn the decision trail into a portfolio and relationships

    Hands review a portfolio case containing research cards, content thumbnails, interface mockups, and a finished product photograph arranged in sequence.

    A portfolio should not be a gallery of screenshots or a list of services you hope to sell. It should let another practitioner inspect your reasoning. Publish the work while it is still in progress, with enough context that a reader can distinguish evidence from interpretation.

    Write case studies as decisions, not victory laps

    Use a consistent case-study structure:

    • Context: What is the project, who is it for, and what constraint mattered?
    • Problem: What specific condition required a decision?
    • Evidence: What did you observe before acting?
    • Options: What credible alternatives did you consider?
    • Choice: What did you do, and why was it the best use of limited resources?
    • Implementation: What changed on the site, in the content, or in distribution?
    • Outcome: What moved, what did not, and over what recorded observation period?
    • Limits: What prevents a stronger causal claim?
    • Next decision: What will you preserve, reverse, or test next?

    Show relevant absolute values when you can do so safely, not just favorable percentages. Explain whether the baseline was small and whether seasonality, another campaign, a platform change, or simultaneous site work could have contributed. Never convert correlation into certainty merely because certainty makes the headline stronger.

    Publish failures too. A careful account of an unsuccessful experiment can demonstrate diagnosis, accountability, and adaptability better than recycled advice. The useful question is not whether every idea worked. It is whether you noticed the result, updated your understanding, and made a better next decision.

    Let communities see work that is already in motion

    Use an owned home for complete case studies and a social profile or community presence for shorter updates. Start with a channel you can maintain. Publishing creates visibility for both the project and the person learning how to grow it: potential users can discover the offer, while practitioners can see the decisions behind it.

    Join communities where people are doing the work: relevant forums, Slack groups, local meetups, or a paid community when it provides access or support you genuinely need. Do not arrive with a broad request for somebody to mentor you. Bring a specific artifact and a narrow question. Show the baseline, what you changed, what happened, and the part of your interpretation you want challenged.

    • Answer questions when your project gives you relevant evidence, and state the limits of that evidence.
    • Share a useful template, diagnostic process, or failed test without turning every interaction into self-promotion.
    • Ask for criticism of a particular decision rather than general approval of your career plan.
    • Return after acting on feedback and explain what changed in your thinking.
    • Protect private information and obtain permission before discussing work that belongs to somebody else.

    If you work on another person’s business, agree on scope, access, data handling, ownership, and expectations before touching the site. Do not imply that rankings or revenue are guaranteed. A project you own is often simpler because you control the asset, can publish the process, and do not expose somebody else to an inexperienced change.

    Use the portfolio to make applications and outreach more precise. When a role emphasizes technical diagnosis, link to the case that shows your diagnosis. When it emphasizes content growth, show how audience research became pages and measurable actions. When it mentions AI search, share your dated observation method and the limits you placed on the conclusions. You are giving the reader a reason to discuss your work rather than asking them to infer ability from enthusiasm.

    The same evidence can open several routes: an employed role, a bounded freelance assignment, a collaboration, or an introduction to somebody with a harder problem. None is guaranteed. The point is to create more ways for useful work to encounter opportunity than a CV inside a crowded recruitment system.

    Key takeaways and your next move

    • You do not need an SEO job before you can begin producing SEO evidence.
    • A small live offer with a defined audience teaches more than a practice blog built only to attract traffic.
    • Your strongest portfolio material is the full reasoning chain: baseline, hypothesis, decision, implementation, outcome, limitations, and next action.
    • SEO, GEO, content, conversion, and AI-assisted work should meet inside the same project because real businesses experience them as connected problems.
    • Responsible AI use includes verification, rejection of weak output, and enough subject knowledge to explain both.
    • Publishing honest work gives potential users a way to find the project and practitioners a way to assess your judgment.

    At your next work session, write down the audience, problem, offer, intended action, discovery surfaces, and current baseline for one manageable idea. If you cannot fill those fields without vague language, narrow the project. If you can, put the smallest useful version in front of real people and begin the decision log. Your next application can then lead with work somebody can inspect, question, and remember.

    References


  • Google’s AI Content Guidance: A Practical Quality Workflow

    Google’s AI Content Guidance: A Practical Quality Workflow

    If an AI draft can move from prompt to publish after a spelling check, your workflow has a quality gap. The problem is not simply that AI touched the page. The problem is that no accountable person has verified the claims, improved the substance, and confirmed that the finished page deserves to exist.

    Google now treats manual fact-checking and review of all AI-generated content as critical before publication. For you, that turns human oversight from a vague editorial ideal into a required publishing gate.

    Key takeaways

    • A human reviewer must verify AI-generated claims before they reach readers. A grammar pass, plagiarism scan, or automated confidence score is not a fact-check.
    • Judge the complete main content, not just the body copy. Titles, headings, images, videos, tools, reviews, comments, tabs, and expandable sections can all affect whether a page fulfills its purpose.
    • Use four separate quality tests: effort, originality, talent or skill, and accuracy. Passing one does not compensate for failing another.
    • Citations support factual claims, but attribution does not create original value. A page still needs useful analysis, experience, functionality, or perspective of its own.
    • Apply review gates to every AI-assisted page. Publishing at scale does not reduce the need for accountable human oversight.

    The quality test applies to the finished page

    Do not reduce Google’s position to a debate about whether AI is allowed. That framing misses the operational question: does the finished page accomplish a clear purpose and give the visitor a satisfying experience?

    The quality of the main content is one of the most important page-quality considerations. Four attributes help you turn that broad principle into an editorial test.

    Quality attributeQuestion for the reviewerEvidence you should be able to point to
    EffortWhat meaningful human work or useful system capability improved this page?Manual verification, substantive editing, original analysis, a tested tool, careful curation, or another contribution beyond generating text.
    OriginalityWhat can a visitor learn, see, or do here that is not already available in equivalent form elsewhere?A distinct explanation, first-party evidence, a worked example, a useful decision framework, original media, or genuinely different functionality.
    Talent or skillDoes the execution meet the level of ability the page’s purpose requires?Clear writing, sound reasoning, well-produced media, functional interactive elements, or appropriate subject expertise.
    AccuracyCan every consequential factual claim be verified, and are uncertainty and limitations represented honestly?Claim-level checks, reliable supporting material, corrected citations, and expert review where the stakes demand it.

    These tests are independent. An accurate page can still be derivative. An original opinion can still be poorly reasoned. A polished page can still contain invented facts. A team can spend hours editing a draft without adding anything that helps the reader.

    Effort is especially easy to misread. It is not a word-count target or proof that somebody moved sentences around. Automatically producing large volumes of text without manual oversight or curation represents little or no original effort in this quality framework. Adding links does not fix that weakness, because attribution cannot substitute for a real contribution.

    The required skill also depends on purpose. A personal account can be useful without professional credentials. A page that could materially affect a person’s health, finances, safety, or well-being carries a much higher accuracy burden and should remain consistent with established expert consensus.

    Audit every part of the main content, not only the prose

    A review team examines the prose, imagery, sources, interface, and structure of a layered web page on a large display.

    Your editorial team may call the central text the content, but Google’s definition is broader. Main content includes anything that directly helps the page fulfill its purpose. That distinction matters because an excellent paragraph cannot rescue a misleading title, a broken calculator, or inaccurate specifications hidden in a tab.

    • Titles and headings: Check that each heading accurately describes the material beneath it. Remove promises the page does not fulfill, and do not frame a qualified answer as a certainty merely to win a click.
    • Primary text and media: Verify claims made in copy, diagrams, captions, audio, and video. If two formats state different facts, the page is not accurate simply because the prose version is correct.
    • Interactive features: Test calculators, search functions, games, maps, and other tools with normal inputs, edge cases, and invalid inputs. A tool that looks complete but returns unreliable results fails the page’s purpose.
    • User contributions: Reviews, comments, forum replies, and uploaded media may be the reason the page exists. Make the distinction between editorial information and user claims clear, and review how unsupported or harmful contributions are handled.
    • Tabbed and expandable content: Treat hidden specifications, safety notes, comparisons, and reviews as fully part of the page. Being collapsed by default does not make inaccurate information less important.

    This broader audit also keeps SEO, AEO, and schema work honest. Structured data should describe visible, verified content. It cannot make an unsupported claim trustworthy, turn a duplicated explanation into an original one, or repair a tool that does not work.

    Use a claim-level review before an AI draft can publish

    A fact-checker connects individual glowing claim tiles from an AI draft to supporting source cards before an approval barrier.

    Generative models predict likely sequences of words rather than retrieving facts. A fluent answer can therefore contain fabricated, outdated, contradictory, or weakly supported details. The safest workflow separates factual verification from stylistic editing so that polished language does not disguise an unchecked claim.

    1. Write the page purpose in one sentence. Name the intended reader, the task they need to complete, and the decision or outcome the page should support. If the team cannot agree on that sentence, it cannot reliably judge whether the draft succeeds.
    2. Mark every checkable claim. Include names, dates, quotations, product capabilities, specifications, definitions, causal statements, procedural instructions, and factual comparisons. Do not limit the review to claims that already have citations; hallucinated details often arrive without one.
    3. Verify each claim manually. Open the supporting material and confirm that it actually supports the wording used. A real URL is not sufficient if the linked page discusses a different population, product version, condition, or conclusion.
    4. Separate fact from inference. Label analysis, recommendations, and predictions as such. If the evidence supports correlation, possibility, or a limited case, do not let the AI turn it into causation, certainty, or a universal rule.
    5. Resolve contradictions instead of smoothing them over. When reliable material disagrees, identify the disagreement and preserve the relevant uncertainty. Do not ask the model to blend incompatible claims into a confident middle position.
    6. Add a reason to choose the page. Contribute something beyond a rearrangement of available wording: a decision tree, a worked example, original analysis, first-party evidence, useful media, or tested functionality. Choose the contribution that helps the page fulfill its stated purpose.
    7. Review the complete experience. Test the title, headings, media, links, tabs, tools, calls to action, and mobile reading order alongside the text. Confirm that the answer is easy to find and that supporting detail appears where the reader needs it.
    8. Record accountable approval. Store the reviewer’s name, the completed fact-check, unresolved limitations, and the reason the page is ready. The person approving publication should be willing to own the accuracy of the final version, not merely the prompt that produced the first draft.

    Rewriting is not verification. Asking another model to check the first model is also not the manual review Google calls for. Automation can help inventory claims, find inconsistent terminology, or flag missing fields, but a person still has to inspect the evidence and make the publishing decision.

    For high-stakes topics, route the draft to someone with the expertise needed to evaluate it. A general editor may catch awkward wording and obvious contradictions while still missing a dangerous technical error. If qualified review is unavailable, narrow the claim, remove the unsupported passage, or hold the page rather than publishing certainty you cannot defend.

    Make human oversight a publishing gate, not a promise

    A policy that says editors should check AI content will fail under deadline pressure unless the content system makes the check visible. Build the requirement into the workflow.

    • Require a clear page purpose before drafting begins.
    • Add fields for the factual reviewer, editorial approver, verification notes, and unresolved limitations.
    • Prevent AI-assisted drafts from moving directly from generation to scheduled or published status.
    • Require supporting material at the claim level when a statement is consequential, disputed, or likely to change.
    • Give high-stakes pages an expert-review route rather than sending every topic through the same general queue.
    • Trigger a new review when facts, products, rules, consensus, or interactive functionality change.

    Do not replace universal review with a spot check of a few generated pages. Sampling can reveal patterns in a production system, but it cannot establish that the unchecked pages are accurate. Every AI-generated output still needs a manual prepublication review for accuracy and trustworthiness.

    Your stop conditions should be equally explicit. Hold publication when a consequential claim cannot be verified, a citation does not support the sentence, the page adds no meaningful value beyond existing material, a tool has not been tested, a heading promises an answer that never appears, or nobody is prepared to own the final result.

    Turn the guidance into a decision this week

    Start with your ten most recently published AI-assisted pages. For each URL, record its purpose, accountable reviewer, verified claims, and original contribution. A blank field identifies real editorial work: verify the claim, improve the page, correct the misleading element, or remove what you cannot support.

    Then apply the same fields before the next draft can publish. That is the practical standard: AI may accelerate production, but a named person must still make the finished page accurate, useful, original enough to merit attention, and fit for its purpose.

    References


  • AI Search Ranking Signals: A Practical Priority Order

    AI Search Ranking Signals: A Practical Priority Order

    If your team is debating whether the next optimization sprint should go to schema markup, an llms.txt file, or another FAQ block, pause. The larger opportunity is usually earlier in the chain: make it unmistakable what you offer, who it fits, and whether the same facts appear everywhere an AI system may encounter your brand.

    Markup can help a machine interpret a strong page. It cannot rescue vague positioning, missing proof, or conflicting information. If you want more visibility in ChatGPT, Gemini, Claude, AI Mode, and agentic search, use the priority order below to decide what to fix first.

    The strongest measured signals are clarity and consistency

    From June 8 to September 18, 2026, 4,213 commercial prompts and 657 agentic shortlisting or purchasing tasks were run through ChatGPT, Google Gemini, including AI Mode, and Claude. The analysis covered 1,089 brands across 14 industries and measured recommendation rate: the share of relevant prompts in which a platform named a brand as a recommended option.

    Clear descriptions of offerings and suitability had the largest adjusted association with recommendation rate at +11.2 percentage points. Consistent information across a brand’s website and third-party sources followed at +9.4 points. The adjustment controlled for authority signals such as list mentions, reviews, and awards.

    SignalDifference before authority controlDifference after authority controlWhat to do with it
    Clear offerings and suitability+15.8 points+11.2 pointsState what each offer is, who it serves, and when it is suitable.
    Consistent brand information+16.9 points+9.4 pointsReconcile important facts across owned pages and third-party profiles.
    Comparison tables on service pages+6.7 points+1.9 pointsUse tables when they make fit and differences easier to evaluate.
    Any schema markup+3.7 points+0.4 pointsTreat schema as a representation layer, not the main ranking project.
    Organization schema+2.1 points+0.2 pointsImplement it accurately, but do not expect it to create authority.
    FAQ schema+0.8 points-0.3 pointsAdd useful FAQs for readers, not to manufacture a ranking signal.
    llms.txt+0.8 points-0.1 pointsKeep it behind clarity, consistency, and authority work in the backlog.
    Product schema for ecommerce brands+6.7 points+4.8 pointsGive this greater priority when products are the entities being evaluated.

    Do not treat those adjusted differences as universal ranking weights. They are associations from one observational dataset, not proof that changing one field will produce a fixed lift on every platform. The negative FAQ schema and llms.txt figures do not show that either feature causes harm; they show that no measurable positive effect remained after authority was controlled in this sample.

    The more useful lesson is about sequencing. Schema appeared more powerful before authority was held constant because brands that invest in technical optimization often have stronger authority signals too. If your page still leaves its audience or use case implicit, technical polish is unlikely to be the constraint holding it back.

    Cross the clarity threshold before adding more structure

    Scattered translucent shapes merge into one clear object before passing through a glowing gateway toward neatly organized blocks.

    Clarity is not the same as short copy. A clear page gives a model enough explicit information to connect an offering to a person, problem, location, and buying situation without having to infer the missing pieces.

    On the specific ten-point rubric used in the commercial-prompt analysis, brands scoring 5 to 6 averaged an 11.2% recommendation rate. Brands scoring 7 to 8 averaged 23.6%, while those scoring 9 to 10 averaged 24.8%. The large change occurred when sites moved from partially clear to explicitly clear; the difference between clear and comprehensive was much smaller.

    A score of 7 is not an industry standard or a guarantee. It is a useful diagnostic line from this dataset. Below it, missing fit information can prevent a brand from entering the serious consideration set. Above it, suitability and authority have more room to decide which clear option gets recommended.

    Audit each commercially important page against four questions:

    • Offering: Can a reader identify exactly what is being sold from the opening copy, without decoding a slogan?
    • Fit: Does the page explicitly name the customer types, use cases, and situations for which the offer is appropriate?
    • Specifics and proof: Does it provide available details about the process, pricing approach, service area, results, awards, or relevant customer examples?
    • Organization: Can someone scan headings, bullets, and genuine comparison tables to find those answers quickly?

    The common failure is a page that names the service but makes the reader infer suitability from logos or broad language such as “businesses of all sizes.” Replace that implication with a direct statement. A useful opening pattern is: “[Offering] is a [category] for [customer type] that needs [use case or outcome] in [relevant situation].” The brackets are prompts for substance, not a sentence to copy mechanically.

    Give each material offering its own page. Add a fit section that says who should consider it and which conditions change the recommendation. Explain how it differs from adjacent options. Publish concrete facts you can support, including a pricing approach when exact prices cannot be public. This work improves both human evaluation and machine interpretation because it removes the need to guess.

    Make your facts consistent, then build the right authority

    Several abstract information sources send matching light pulses to a central sphere supported by an illuminated framework, while one conflicting pulse fades away.

    Consistency is more than spelling the company name the same way. It means that your offer names, audience, locations, pricing model, capabilities, and proof do not change as someone moves between your website and independent references.

    That matters because cross-source consistency retained a +9.4-point association with recommendation rate after authority was controlled. A model can work with a qualified claim repeated accurately across several places. It has a harder decision when the homepage, product page, directory profile, and review coverage describe materially different businesses.

    Create a canonical fact ledger before asking teams to update pages independently. It should contain:

    • The official brand name and a plain description of the business.
    • The canonical name and definition of every material offering.
    • The audience, use cases, and suitability conditions for each offer.
    • Locations or service areas, where relevant.
    • The pricing approach and any public qualification criteria.
    • Approved proof points, including the exact scope and date behind each result.
    • Awards, credentials, and other claims that can be independently verified.

    Compare that ledger with your homepage, product and service pages, location pages, directory entries, review profiles, and independent coverage. Correct owned pages first. Then request corrections where third-party information is outdated. Prioritize contradictions that change eligibility or fit, such as an old service area, a discontinued product name, or a claim that applies to one offer but appears to describe the whole company.

    Authority is not interchangeable with structured data. The unadjusted difference associated with any schema was +3.7 points, but it fell to +0.4 after list mentions, reviews, awards, and related authority signals were controlled. That does not assign a causal value to any one authority tactic. It does show why adding markup to an under-recognized brand should not be mistaken for building recognition.

    The most useful form of third-party evidence also depends on the buying market. In consumer categories, expert reviews outweighed customer reviews by 15 to 1 in AI search, while B2B software showed the reverse pattern. Treat that result as directional rather than a rule for every niche, but do not copy one review strategy across both markets.

    • For a consumer category, identify the credible expert reviewers and category comparisons that buyers already use. Make your product facts easy to verify, and correct inaccurate coverage where possible.
    • For B2B software, prioritize authentic, specific customer-review evidence in the places buyers consult. Generic praise is less useful than a review that identifies the customer situation and the product’s role.
    • For either market, keep externally promoted claims aligned with the canonical facts on your site. More mentions will not solve a contradiction that makes the offer harder to classify.

    Use schema to transmit facts, not invent importance

    Schema has a real job: it labels entities and properties in machine-readable form. That job is valuable, but it is different from earning a recommendation. The safest implementation rule is simple: structured data should faithfully represent useful facts that a visitor can already verify on the page.

    Product schema deserves separate treatment for ecommerce. Among the 214 ecommerce brands in the sample, it retained a +4.8-point association after authority control. That is the only measured markup type with a meaningful adjusted difference in the available data. It still does not prove a guaranteed lift, but it gives ecommerce teams a stronger reason to prioritize accurate Product markup than a service business has to deploy several marginal schema types.

    Use this implementation order:

    1. Fix the visible offer, fit, and proof on the page.
    2. Select a schema type that corresponds to the entity actually described, such as Organization or Product.
    3. Make names, descriptions, and other claims match the visible content and your canonical fact ledger.
    4. For ecommerce, prioritize accurate Product markup before adding loosely relevant schema types merely to increase the count.
    5. Add FAQ content only when it answers questions that help a buyer decide. Treat FAQ schema as encoding for that content, not as an independent visibility lever.
    6. Validate the markup and review it whenever the visible facts change.

    Apply the same discipline to llms.txt. Its adjusted difference was -0.1 points in the measured sample, which is effectively no demonstrated lift there. You may still test it as a low-cost machine-accessibility experiment, but it should not displace work on unclear pages, conflicting facts, or missing authority.

    Comparison tables sit between content and structure. Their adjusted association was a modest +1.9 points. Use one when a buyer genuinely needs to compare audiences, use cases, features, or alternatives. A table that exposes meaningful differences can improve clarity; a table built only to look optimized adds no new information.

    Key takeaways: choose your next optimization ticket

    • Fix explicit fit first. Every important offer should state what it is, who it serves, when it is suitable, and what evidence supports it.
    • Reconcile facts across the web. Maintain one canonical ledger and use it to correct high-impact contradictions on owned pages and third-party profiles.
    • Build market-appropriate authority. Consumer categories may lean more heavily on expert reviews, while B2B software may depend more on customer-review evidence.
    • Make schema accurate and proportionate. Product schema has the strongest measured case for ecommerce; Organization schema, FAQ schema, and llms.txt should not outrank clarity work.
    • Measure recommendations, not implementation volume. Use a fixed set of commercial prompts across the platforms that matter, record whether your brand is named and for which use case, then inspect the pages and evidence supporting each result.

    Start with the highest-value product or service page, not a sitewide markup rollout. Make one offer fully explicit, reconcile its facts, align its external evidence, and then encode it accurately. Once that page can answer what, who, when, where, and why without inference, you have a useful model for the rest of the site.

    References


  • How to Hire Senior SEO Talent for Judgment, Not Tasks

    How to Hire Senior SEO Talent for Judgment, Not Tasks

    You are not hiring a human backlog. You are hiring someone to decide which search problem is real, which evidence deserves trust, and which work should win scarce support.

    A polished candidate can discuss crawling, content, links, reporting, and AI visibility. The harder test begins when those signals disagree. Organic clicks can fall while conversion and quality indicators improve. Visibility can grow in a market the business cannot serve. An impressive AI score can have no demonstrated relationship to revenue. Your hiring process needs to reveal who can navigate those conflicts without retreating into a generic checklist.

    Start with the decision this person must improve

    Before writing the job description, finish this sentence: We need this person to help us decide and execute…

    The words that follow should describe a business problem, not an SEO department. You may need more qualified demand in a particular industry, better conversion from existing traffic, clearer priorities for a neglected backlog, or someone who can move discovery work through engineering, content, product, PR, and legal. You may need to learn whether visibility in ChatGPT and other AI experiences produces valuable customer behavior. Those are different mandates.

    Build a short role charter before listing responsibilities. It should define:

    • The business problem: What is currently underperforming, uncertain, or blocked?
    • The outcome: What should improve for customers or the business if the hire succeeds?
    • The constraints: Which budgets, markets, technical limits, compliance requirements, or capacity limits are real?
    • The dependencies: Which teams must approve, build, publish, measure, or support the work?
    • The decision rights: What can this person prioritize directly, and where must they persuade others?
    • The non-goals: Which adjacent responsibilities belong to other people?

    The non-goals matter. A description that combines technical SEO, content strategy, AI discovery, analytics, conversion optimization, link acquisition, reporting, and project management may conceal several jobs inside one salary. It also makes evaluation incoherent: one interviewer rewards technical depth, another expects an editorial strategist, and a third wants a cross-functional program leader.

    Decide whether you primarily need a specialist who will complete defined work or a leader who will determine what the work should be. A senior discovery leader may not personally execute every migration ticket or content brief. They should be able to diagnose the system, select a defensible sequence, obtain support, and keep the work connected to a business outcome.

    Build a scorecard that rewards judgment

    Five symbolic assessment objects form a balanced structure while an unnecessary metallic piece is set aside.

    Technical competence remains a threshold requirement. A senior SEO leader must recognize technically plausible explanations, interrogate the right systems, and understand the consequences of a recommendation. But technical fluency should not consume the entire scorecard. One useful hiring model treats SEO- and AI-specific knowledge as roughly 25% of what makes a senior discovery hire effective, with the rest carried by critical thinking, communication, persuasion, prioritization, and business judgment. That percentage is not a universal formula. It is a practical guardrail against hiring the candidate with the largest vocabulary.

    Use evidence-based dimensions instead of adjectives such as strategic, data-driven, or collaborative. Those words are too easy to claim and too difficult to score consistently.

    DimensionWhat to ask the candidate to doStrong evidenceRisk signal
    Problem framingInterpret a situation in which search and business metrics disagreeSeparates the observed symptom from the decision the business must makeAccepts the prompt’s framing and immediately recommends familiar tactics
    Measurement judgmentIdentify what must be validated before comparing performanceQuestions tracking, consent, definitions, time comparisons, and the relationship between proxy and outcome metricsTreats every dashboard value as equally reliable and meaningful
    PrioritizationChoose work under a real resource constraintNames what will be deferred, explains the opportunity cost, and states what could change the orderLabels most of the backlog urgent or critical
    Business connectionMap search demand to capacity, conversion, and revenueDistinguishes available demand from demand the business can profitably serveTreats rankings, traffic, or AI mentions as the final objective
    InfluenceExplain the same recommendation to technical and commercial stakeholdersChanges the language and level of detail while preserving the reasoningUses channel jargon in place of a business case
    Technical and AI literacyDevelop and test plausible causes across conventional and AI-mediated discoveryKnows what evidence would support or falsify each explanationRepeats platform announcements or best practices without connecting them to the case

    Listen for causal reasoning. A candidate should be able to say: this observation could have several causes; this is the evidence that would separate them; this decision is safe while we investigate; and this is the point at which we would change course. Memorized recommendations rarely contain that structure.

    Do not penalize a candidate for challenging the premise. Senior judgment often appears as "I need more information." The phrase becomes useful only when the candidate identifies the missing information, explains why it changes the decision, and offers a provisional path instead of stopping the conversation.

    Use an ambiguous work sample instead of a trivia test

    A candidate sorts ambiguous evidence cards and selects one resource token while two interviewers observe.

    A realistic exercise should contain enough evidence for a recommendation and enough ambiguity to make a checklist inadequate. Keep it close to your operating environment, but fictionalize sensitive data so every candidate receives the same case.

    A useful brief could contain these conditions:

    • Organic clicks are down, while conversion and customer-quality indicators are up.
    • Keyword trends and an AI visibility score are available, but neither has been connected conclusively to the business outcome.
    • Some markets have unused service capacity, while others cannot absorb much more demand.
    • An analytics or cookie-consent change may have affected the year-over-year comparison.
    • Engineering can contribute only 40 hours during the quarter.

    Ask the candidate to make a recommendation, not produce an audit. The deliverable should require them to:

    1. Define the decision the business actually needs to make.
    2. Identify the assumptions and measurement questions that could materially change that decision.
    3. Offer a working recommendation while those questions are being resolved.
    4. Allocate the constrained engineering capacity and state what will not be done.
    5. Choose outcome measures that distinguish commercial progress from visibility alone.
    6. Explain what new evidence would cause the plan to change.

    A weaker response usually expands the scope. It proposes a technical audit, content refresh, cleanup program, link initiative, and AI visibility project at the same time. Every tactic may be legitimate in isolation, but the candidate has not shown why any of them deserves priority in this situation.

    A stronger response first tests whether the apparent decline is a problem. If conversions and customer quality are improving, the lost clicks may include less valuable demand, the measurement may have changed, or another part of the journey may be performing better. The candidate should not assume which explanation is correct. They should specify how to tell them apart.

    Market capacity creates another revealing choice. Improving visibility where the business cannot serve more customers may produce attractive charts and operational frustration. A candidate with business judgment will examine where additional demand can become a completed sale, appointment, subscription, or other real outcome. They may prioritize a market with unused capacity even when its search opportunity looks less glamorous.

    Treat the AI visibility metric the same way. It is a hypothesis-generating signal until the candidate can show a credible relationship to customer discovery and business results. The right next step may be a bounded test, better attribution, or closer analysis of the queries and citations involved. It is not automatically a mandate to maximize the score.

    Use a short panel discussion after the exercise. Grade the candidate’s reasoning, questions, tradeoffs, and communication – not whether the final recommendation matches an answer your team decided in advance. If there is only one answer you will accept, you are testing compliance rather than judgment.

    Interview for tradeoffs, influence, and restraint

    The best interview questions make the candidate choose. Broad prompts such as "How would you improve our SEO?" reward confident improvisation. Constrained prompts reveal whether the person can protect the business from low-value work.

    Questions that reveal diagnosis

    • Organic traffic has declined while qualified conversions have improved. Under what conditions is that good news, bad news, or a measurement problem?
    • Which data would you validate before comparing this period with the previous one, and why?
    • What finding would make you decide not to run a broad technical audit?
    • One market has a visibility gap but no service capacity. Another has spare capacity but lower apparent search demand. How would you choose where to work?
    • Our AI visibility score increased. What would you need to see before treating that increase as business progress?
    • Which recommendation would you make now, and which decision would you deliberately postpone?

    Do not judge the candidate by the number of questions asked. Judge whether each question can change the decision. Asking about a consent implementation that may invalidate a trend is valuable. Asking for every report the company owns may simply delay commitment.

    Questions that reveal leadership

    • Engineering gives you 40 hours this quarter, while the proposed work would take six months. What ships, what waits, and what do you tell the executive team?
    • Explain your recommendation first to a CFO and then to a CTO. What changes in the explanation, and what remains constant?
    • A technically sound recommendation is blocked by product or legal. How do you determine whether to modify it, build a stronger case, or stop pursuing it?
    • When can conversion, inventory, follow-up, reputation, or product preference be a more important discovery constraint than crawlability?
    • Tell us about a recommendation you would reject even if it increased rankings or visibility. What makes the tradeoff unattractive?

    A senior leader should be able to operate outside the SEO silo. Search performance connects to product experience, customer support, paid landing pages, brand reputation, conversion paths, operational capacity, and revenue. That does not mean the SEO leader owns every function. It means they can recognize when the limiting factor sits elsewhere and bring the right owner into the decision.

    Restraint is part of the job. If the candidate describes six months of work as critical despite a narrow engineering allowance, they have not prioritized. They have reformatted the backlog. Look for explicit deferrals, sequencing logic, reversible first moves, and thresholds that would justify further investment.

    During the debrief, record evidence before discussing overall impressions. Ask what assumption the candidate challenged, what they chose not to do, how they connected discovery to business capacity, and whether a non-specialist could follow the logic. A charismatic presentation should not compensate for an undefined problem or an unbounded plan.

    Key takeaways and your next move

    • Define the business decision before defining the SEO role.
    • Treat technical and AI fluency as essential foundations, not the whole senior-level scorecard.
    • Use conflicting metrics and real constraints to expose how a candidate thinks.
    • Reward requests for more information when they identify decision-changing evidence and still produce a provisional recommendation.
    • Make candidates connect search and AI visibility to capacity, conversion, customer quality, and revenue.
    • Grade tradeoffs, communication, and restraint rather than agreement with a predetermined answer.

    Before you publish the role, replace its opening list of channel responsibilities with the decision this person must improve. Then replace the generic take-home audit with an ambiguous case drawn from that decision. The candidate who clarifies the problem, makes a choice, and earns support for it is showing the judgment you are actually hiring.

    References


  • AI Search Visibility Monitoring: A Repeatable Framework

    AI Search Visibility Monitoring: A Repeatable Framework

    You checked an AI answer, saw your brand missing, and now you need to know whether you have a visibility problem. One response cannot answer that. AI recommendations vary between runs, and buyers can approach the same purchase through several different questions.

    A useful monitoring program treats visibility as a measured distribution, not a rank. It samples real buying decisions, repeats prompts under controlled conditions, records how each brand is presented, and turns the resulting patterns into specific content and positioning work.

    Key takeaways

    • Monitor buyer decisions and prompt families, not a list of exact phrases that tries to imitate traditional keyword tracking.
    • Run each prompt at least 10 times for a quick directional estimate. A single answer is an observation, not a baseline.
    • Measure recommendation seats, prompt coverage, citations, cited pages, and buyer-fit descriptions separately.
    • Keep prompt wording, search mode, environment, and run counts consistent when comparing one period with another.
    • Use monitoring to diagnose the next action. A missing recommendation, an uncited mention, and an inaccurate best for description are different problems.

    Define visibility before you try to measure it

    Transparent chambers show the same blue marker as prominent, peripheral, grouped with alternatives, or absent after repeated inputs.

    AI search visibility is not simply whether your company name appears. An answer can cite your page without recommending your product. It can recommend your brand while linking to a review site. It can also place you on a shortlist but describe you as suitable for the wrong customer.

    The distinction matters because AI-generated shortlists can be narrow. In one workforce-management sample, 100 responses contained an average of 5.6 recommended brands, while the referenced vendor directory contained 215 listings in the relevant category. That result belongs to one category and one test design, so it is not a universal benchmark. It does show why merely being eligible for consideration does not mean a brand will receive a seat.

    Record these six layers for every completed run:

    <!– wp:list {
  • How to Test AI Search SEO Claims Before You Act on Them

    How to Test AI Search SEO Claims Before You Act on Them

    Your AI search roadmap probably contains at least one recommendation that arrived as a certainty: abandon traffic forecasts, publish more AI-written pages, add llms.txt, or rebuild the site for a new class of crawler. Before you spend budget on it, you need to know what the evidence actually permits you to conclude.

    The practical rule is simple: match the size of the decision to the strength and scope of the evidence. A single successful page can disprove a claim that something is impossible, but it cannot prove the tactic will usually work. A trend in search activity cannot tell you how many visits websites will receive. An official statement about one platform cannot describe every AI system.

    First, identify what the claim is actually measuring

    Claims about AI search often collapse several different stages into one word: search. That makes weak arguments sound stronger than they are. A person can search, receive an answer, see a brand cited, click a link, and complete a valuable action. Each is a separate event, and each needs its own metric.

    • Demand: Are people conducting more or fewer searches on a particular surface?
    • Answer visibility: Does your brand or content appear in the responses that matter to your audience?
    • Citations: Does the response identify your page as supporting material?
    • Traffic: Do those appearances produce visits to your site?
    • Business outcomes: Do those visits produce qualified leads, sales, subscriptions, or another useful result?

    No single metric can stand in for the whole journey. In Q2 2026, the available measurements showed AI search and traditional search growing at roughly the same quarter-over-quarter rate. That does not support the broad claim that AI usage is simply replacing traditional search. Yet clicks to non-Google-owned desktop results were also at their lowest level since April 2025. Search activity and website traffic were moving differently.

    This distinction should change your reporting. Put search demand, answer visibility, citations, website visits, and conversions on separate lines. If demand is growing while click-through declines, do not diagnose the problem as disappearing interest. Investigate where the journey now ends, which queries still produce visits, and whether your pages earn visibility in the answer itself.

    The same discipline applies to AI referral traffic. A low referral count does not, by itself, prove that your brand is absent from AI answers. It may indicate low visibility, low citation frequency, low click-through, incomplete referral attribution, or some combination of them. Measure the stage you intend to improve.

    Match the evidence type to the question you need answered

    Four research stations use different instruments to examine website models, search signals, a page fragment, and documents around a central focal point.

    Evidence is not simply strong or weak in the abstract. It is useful when its design fits the decision. An official platform statement is valuable for learning whether that platform supports a file or protocol. It does not prove the file will improve performance. A crawler test can reveal whether content is technically retrievable. It cannot establish that the retrieved content will be cited. A traffic case can prove that growth remains possible. It cannot forecast growth for every site.

    Use the following evidence types deliberately:

    • Official implementation statements answer whether a named platform says it uses, supports, or ignores a feature. Keep the conclusion limited to that platform and the behavior described.
    • Direct technical observations, such as server logs or raw-response tests, answer what a crawler requested and what the server returned under the tested conditions.
    • Controlled comparisons help determine whether a change caused a result. The comparison needs a baseline, a suitable control, and protection against unrelated changes.
    • Repeated results across sites or page groups show whether an effect travels beyond one example. Check whether the sample resembles your site before generalizing.
    • Case examples establish possibility. They are particularly useful for rejecting absolute claims containing words such as never, impossible, or cannot.
    • Anecdotes and expert opinions are starting points for investigation, not automatic reasons to change a production site.

    The burden of proof should rise with the cost of the decision. A reversible metadata experiment does not require the same confidence as a sitewide rendering migration. Replacing a publishing workflow, moving engineering capacity, or abandoning an established acquisition channel should require evidence that addresses your actual platform, audience, metric, and risk.

    Before accepting a claim, ask six questions:

    • What exact outcome was measured?
    • Which sites, pages, queries, crawlers, or users were included?
    • How long did the observation run?
    • Was there a baseline or comparison group?
    • What else changed during the same period?
    • Does the conclusion describe possibility, frequency, causation, or expected return?

    That final question catches a common reasoning error. One counterexample is enough to defeat a universal claim that a tactic can never work. It is not enough to show that the tactic works consistently, causes the result, or deserves investment.

    Five AI SEO claims that require narrower conclusions

    Claim: AI search is killing traditional search

    The demand-level evidence does not support a simple replacement story. In the measured Q2 2026 period, AI and traditional search expanded at approximately the same quarter-over-quarter rate. The click-level evidence is less comfortable: Google was sending fewer desktop clicks to non-Google-owned results.

    The defensible conclusion is that AI adds another discovery layer while answer-first experiences can reduce the share of activity that reaches the open web. Treating those observations as contradictory creates a false choice. Both can occur at once.

    For planning, maintain separate assumptions for search activity and click yield. If traditional search demand remains healthy but fewer impressions turn into visits, concentrate on query classes that still produce action, improve the value communicated in titles and snippets, and measure visibility inside answer surfaces. Do not erase an entire channel from the forecast because its click efficiency changed.

    Claim: Zero-click search makes organic growth impossible

    A local business reached its highest recorded month of organic website clicks in July 2026, with the increase attributed to nonbranded blog content and service pages. That example is enough to reject the word impossible. It is not evidence that every publisher, retailer, software company, or national brand should expect the same outcome.

    Local businesses occupy a different risk category because the route from a location- or service-specific query to an action can differ from the route for an informational publisher. Segment your expectations by site model, query intent, geography, and page type. An average across unrelated sites can conceal the part of your portfolio that still has room to grow.

    Instead of pausing organic work on the strength of a market-wide prediction, choose a coherent set of nonbranded queries and the pages that serve them. Track impressions, clicks, qualified actions, and landing-page performance against an unchanged comparison group. Your own result will be narrower than a universal forecast, but much more useful for deciding where your next unit of effort belongs.

    Claim: Purely AI-generated content cannot rank

    A four-page test provides a useful counterexample: four articles generated entirely through AI continued to rank and perform after careful prompting, light human review, and no manual rewriting. This defeats the categorical claim that AI-written material is automatically barred from search performance. Four pages cannot establish the success rate of AI-generated content in general.

    The more useful distinction is between production method and information value. An LLM can accelerate drafting, but it does not supply a worthwhile premise by default. Pages still need a clear purpose, accurate claims, relevant expertise, original information or analysis where available, and a point of view specific enough to help the reader make a decision. Low-effort, repetitive output fails that test regardless of how quickly it was produced.

    Audit AI-assisted pages with the same questions you would apply to any other page: What new information or synthesis does this provide? Which claims can be checked? Where does the page answer the query more precisely than existing results? Which paragraphs could appear on any competitor’s site without alteration? Remove generic sections, verify factual claims, and give a qualified reviewer responsibility for the final page. The percentage of words produced by a model is not a useful performance target.

    Claim: Adding llms.txt will improve AI visibility

    Google has explicitly stated that it does not use llms.txt for AI search discovery. A separate implementation check covering 10 sites for 90 days found no measurable change in AI crawl frequency or AI-referred traffic for most sites. Where movement appeared, other SEO work accounted for it.

    This is stronger evidence than the mere availability of the file, but the conclusion still needs boundaries. A 10-site, 90-day observation cannot prove that no present or future AI system will ever use llms.txt. It does show that the file should not be presented as a demonstrated visibility lever on the evidence available.

    Treat llms.txt as optional infrastructure, not as a strategy or key performance indicator. If it sits in your backlog beside crawl access, server-rendered content, useful page creation, or measurement, the supported work comes first. If you implement the file, record what mechanism you expect, which crawlers should respond, what metric should change, and what result would justify maintaining it. The existence of the file is an output, not an outcome.

    Claim: AI crawlers can render JavaScript like a browser

    Crawler-behavior testing found that the emerging AI search crawlers examined did not render JavaScript. That finding should not be stretched to every crawler forever, but it is enough to make client-side-only delivery a material visibility risk.

    Test what the server returns before a browser executes scripts. Use page source or an HTTP fetch that does not run JavaScript, then search the response for the exact answer text, product or service facts, links, and structured data you expect a machine to consume. Looking at the finished page in a browser is not the same test; the browser may have assembled content that an AI crawler never received.

    If critical material is absent from the initial HTML, render it on the server or provide a static pre-rendered response. Apply the same check to JSON-LD injected by client-side scripts. This does not guarantee that an AI system will cite the page, but it removes a basic access failure: the system cannot evaluate information that its crawler never obtains.

    Build a claim ledger before changing the roadmap

    A hand sorts evidence pieces into blank color-coded rows on an open planning board while a modular roadmap waits in the background.

    A claim ledger turns AI SEO discussion into a decision process. Create one entry for every recommendation competing for budget, including recommendations you already believe. Each entry should contain the following:

    1. Write the claim precisely. Name the platform, behavior, metric, and affected page group. Replace broad language such as AI visibility will improve with a testable statement.
    2. Describe the mechanism. State what the platform or crawler would need to do for the proposed change to produce the expected result.
    3. Record the evidence type and scope. Distinguish an official statement, technical observation, controlled comparison, multi-site pattern, case example, and opinion.
    4. List the boundary conditions. Note the sites, queries, crawlers, rendering setup, market, and observation period to which the evidence actually applies.
    5. Identify competing explanations. Content changes, technical fixes, brand activity, seasonality, and measurement changes can move the same metric.
    6. Set the decision rule before implementation. Define the outcome that would justify scaling, revising, or stopping the tactic.
    7. Assign a review point. Platform behavior changes, so a sound decision needs a date or trigger for re-examination rather than permanent acceptance.

    Then label each backlog item keep, test, defer, or stop. Keep work supported by direct evidence and a clear mechanism, such as making critical content available in server-returned HTML when relevant crawlers do not render it. Test plausible changes whose effect remains uncertain. Defer tactics whose evidence is weak and whose opportunity cost is high. Stop initiatives built on a categorical premise that available counterexamples have already disproved.

    Do not let measurement begin after implementation. Capture the baseline first, avoid unrelated changes to the same test group where practical, and keep a comparison group. If several SEO changes launch together, you may observe improvement without learning which change caused it. That can produce an attractive chart and a poor investment decision.

    Key takeaways

    • Search demand, answer visibility, citations, website traffic, and conversions are different outcomes. Use a metric that matches the claim.
    • A counterexample can disprove an absolute claim, but it cannot establish how often a tactic succeeds or what return you should expect.
    • Traditional and AI search can grow while website click-through declines. Model demand and click yield separately.
    • Judge AI-assisted content by its accuracy, originality, specificity, and usefulness, not by an unsupported assumption about authorship detection.
    • Treat llms.txt as optional infrastructure until evidence connects it to a measurable outcome for the platforms you care about.
    • Inspect the raw server response. If essential content or JSON-LD exists only after JavaScript runs, some AI crawlers may never receive it.

    At your next planning review, pick the most expensive AI SEO recommendation on the roadmap and reduce it to one testable sentence. Name its mechanism, metric, evidence type, boundary conditions, and stopping rule. If the claim cannot survive that exercise, it is not ready to consume the budget. If it can, you have the beginnings of a test that will teach you something specific about your own visibility.

    References


  • How to Make Products Visible to AI Personal Shoppers

    How to Make Products Visible to AI Personal Shoppers

    Your product can rank in conventional search and still disappear when a shopper asks an AI assistant what to buy. The missing piece is usually not another generic category paragraph. It is making the product easy to identify, test against constraints, and defend in a recommendation.

    AI personal shoppers can shape which products make the shortlist. That changes your visibility target. You are no longer optimizing only for a page visit; you are helping a system decide whether your product is eligible, relevant, credible, and safe to recommend for a particular request.

    AI shopping visibility is a three-gate problem

    There is no universal ranking formula for AI shopping. Assistants use different catalogs, retrieval systems, merchant feeds, pages, and models. Their answers can also change as availability, prices, prompts, and underlying systems change. A practical three-gate model is more useful than pretending every platform works the same way.

    1. Discovery: Can the assistant find and identify the correct product or variant?
    2. Qualification: Can it determine whether the product satisfies the shopper’s stated constraints?
    3. Selection: Is there enough relevant evidence to choose the product and explain that choice?

    A product has to pass the gates in that order. Better promotional copy cannot rescue a product the system cannot identify. Strong reviews cannot compensate for an unspecified compatibility requirement. Complete structured data does not prove a broad superiority claim.

    This sequence gives you a diagnostic method. If the product never appears, inspect discovery before rewriting the sales copy. If it appears for broad prompts but disappears when a constraint is added, inspect the relevant attribute. If it remains eligible but another product receives the recommendation, inspect comparative relevance and supporting evidence.

    The important distinction is between being mentioned and being recommendable. A system may know that your product exists while lacking the facts needed to place it in a defensible shortlist.

    Build one canonical product truth

    A hiking shoe on a central platform sends the same set of visual product attributes to a storefront, phone, warehouse shelf, and AI orb.

    Start with an internal product record, not a block of marketing copy. This record should be the authoritative source for the product page, structured data, merchant feeds, marketplace listings, comparison pages, and support content. When those surfaces disagree, an assistant has to choose among conflicting claims or avoid repeating them.

    For each product and meaningful variant, define the following fields explicitly:

    • Identity: brand, product name, model, assigned SKU or GTIN, canonical URL, and product category.
    • Variant: color, size, capacity, material, pack quantity, configuration, and the relationship to the parent product.
    • Eligibility attributes: dimensions, weight, compatibility, intended use, required accessories, included components, operating conditions, and other category-specific constraints.
    • Commercial facts: price, currency, condition, availability, fulfillment terms, returns, and warranty terms.
    • Evidence: certifications, documented test conditions, review data, manuals, specifications, and the exact scope of each claim.

    Do not populate a field because competitors use it or because a schema validator permits it. An unknown value should remain unknown until the business can verify it. A precise false claim is worse than an honest omission because the false claim can be repeated in a recommendation, create a poor purchase, and undermine trust in the rest of your data.

    Keep the visible page, schema, and feeds aligned

    Product structured data should encode facts that a shopper can also verify on the page. Use Product markup to identify the item and its attributes. Use Offer data only for an offer that actually exists. Add rating or review properties only when the corresponding information is genuine, visible, and attached to the correct product or variant.

    JSON-LD does not create product truth. It translates product truth into a machine-readable form. If the page says one material, the markup says another, and the feed omits the field, adding more schema will multiply the ambiguity rather than fix it.

    Variant handling deserves particular attention. A family page may describe several configurations, but price, dimensions, availability, ratings, and compatibility can belong to only one of them. Give meaningful variants stable identities and make the selected variant unambiguous in the page content, URL behavior, structured data, and feed.

    Separate durable facts from fast-changing facts

    Product data fails at different speeds. Model identity, dimensions, materials, compatibility, and included components are usually durable. Price, availability, promotions, delivery estimates, and review aggregates can change much faster.

    Give each fast-changing field an owner, a system of record, and a refresh trigger. Avoid embedding volatile values in editorial prose unless that prose is updated from the same source. A stale promotional page and a current product feed can leave an assistant with two plausible answers and no reliable way to reconcile them.

    Match shopper constraints and support every important claim

    Traditional product copy often begins with a head keyword and expands into benefits. AI shopping requests are more likely to combine a job, a hard constraint, and a preference: a product for a particular use, compatible with something the shopper already owns, within a budget, and with a preferred trade-off.

    Create a prompt set from the decisions people make, not just the phrases with the highest search volume. Include several distinct request types:

    • Job prompts: What is the shopper trying to accomplish?
    • Constraint prompts: What would make a product ineligible, such as size, compatibility, material, price, or availability?
    • Trade-off prompts: Which quality matters more when no option maximizes everything?
    • Comparison prompts: Which alternatives are genuinely close enough to compare?
    • Risk prompts: What must the shopper verify before buying?

    Then map every consequential question to a field and a piece of evidence. The map exposes a common failure: the marketing team believes a benefit is obvious, but the product page never supplies the fact an assistant would need to infer it safely.

    Shopper questionMachine-readable answerHuman-verifiable support
    Will it fit?Dimensions, weight, capacity, or supported size rangeSpecification table, diagram, or installation instructions
    Will it work with what I own?Compatible models, interfaces, versions, or required accessoriesCompatibility page, manual, or clearly scoped support content
    Can I buy it under my stated conditions?Current price, currency, condition, availability, and offer detailsVisible offer and fulfillment information
    Is it suitable for this use?Intended use and relevant product attributesUse-case explanation tied to specifications rather than slogans
    Can I trust this claim?Named evidence and its scopeCertification details, documented method, policy, or attributable review data

    State who the product is and is not for

    A useful product page helps an assistant eliminate the wrong matches. State the primary use, the buyer or environment it suits, the constraints it satisfies, and any condition that would make another option more appropriate.

    This does not weaken the offer. A clear limitation can make the positive recommendation more credible. If a product requires an adapter, has a fixed dimension, excludes a particular model, or is designed for one usage pattern rather than another, say so close to the relevant benefit. Hiding the qualifier may generate more initial interest, but it gives an assistant less reason to trust or repeat the claim.

    Comparison content should use decision criteria rather than a list of adjectives. Explain which product fits which condition and why. Avoid declaring an item the best without naming the use case, comparison set, and evidence. An unqualified superlative is difficult to defend and easy for a recommendation system to ignore.

    Maintain a claim-to-evidence ledger

    For every claim that could change a purchase decision, keep an internal ledger containing the claim, its exact qualifier, the supporting evidence, the page where that evidence is visible, the responsible owner, and the event that should trigger a review.

    The qualifier matters. A certification may apply to one variant, a test may use specific conditions, and a warranty may differ by market. Preserve that scope everywhere the claim appears. Do not turn narrow evidence into a product-wide promise.

    Customer reviews can help describe recurring strengths and limitations, but keep review data attached to the product or variant it evaluates. Combining materially different variants may produce a stronger aggregate while giving the assistant a less accurate picture of the item in front of the shopper.

    Support pages, manuals, compatibility resources, return policies, and comparison pages should link back to the canonical product and use the same names and identifiers. That creates a coherent evidence trail instead of a set of disconnected documents with slightly different terminology.

    Audit the complete path from prompt to recommendation

    A shopper request travels through product, evidence, inventory, checkout, and delivery checkpoints before reaching an unbranded product shortlist.

    Do not reduce AI shopping visibility to a rank check. You need to see where the product exits the decision process and whether the answer is factually correct when it does appear.

    1. Choose eligible prompts. Test requests for which the product could honestly be a suitable answer. Irrelevant prompts distort the score and tempt teams to broaden claims beyond the product’s real fit.
    2. Record a baseline. Save the exact prompt, assistant, date, market or locale, response, recommended products, stated reasons, and any surfaced links.
    3. Label the outcome. Distinguish absence, failed qualification, incorrect description, unsupported mention, and an eligible product that lost on a documented trade-off.
    4. Trace the earliest failed gate. Repair identity and discovery before attributes, attributes before evidence, and evidence before promotional expansion.
    5. Rerun the same prompt set. Compare changes in coverage and accuracy while recognizing that any individual generated response can vary.
    6. Inspect the commercial handoff. If the recommendation is accurate but the shopper does not proceed, examine the offer, availability, landing experience, and product-market fit rather than calling every weak outcome an AI visibility problem.

    The failure pattern tells you where to look first:

    Observed resultLikely failure areaFirst inspection
    The product never appearsDiscoveryIndexability, canonical URL, feed inclusion, product identity, and internal linking
    The wrong variant appearsIdentityVariant names, identifiers, URLs, parent relationships, and selected-offer data
    The product disappears after a valid constraint is addedQualificationThe missing, ambiguous, or conflicting attribute associated with that constraint
    The assistant states an incorrect factProduct truthConflicts and stale values across the page, schema, feed, marketplace, and support content
    The product is considered but not recommendedSelectionUse-case specificity, comparison criteria, limitations, and claim-level evidence
    The recommendation is accurate but does not convertCommercial handoffPrice, availability, trust, offer clarity, landing experience, and actual product fit

    Track metrics that correspond to those states. Prompt coverage shows whether the product appears for eligible requests. Attribute resolution shows whether the assistant can answer the important constraint questions. Answer accuracy catches misdescription. Evidence visibility shows whether useful supporting pages are surfaced. Recommendation share shows how often the product is selected when it is genuinely eligible. Commercial outcomes tell you whether improved visibility creates useful demand.

    Keep the prompt set and eligibility rules stable while evaluating a change. If you change the content, prompts, markets, and success definition at the same time, you will not know what improved. Treat assistant outputs as observations, not permanent rankings.

    Key takeaways

    • Optimize for discovery, qualification, and selection as separate gates.
    • Create one canonical product record before expanding copy, schema, feeds, or comparison content.
    • Make decisive constraints explicit; do not ask an assistant to infer compatibility, fit, or eligibility from vague prose.
    • Keep visible content, Product structured data, offers, variants, and merchant feeds consistent.
    • Attach meaningful claims to scoped evidence and state important limitations plainly.
    • Measure eligible prompt coverage and factual accuracy before treating recommendation share as the main result.

    Start with one commercially important product family. Establish its canonical facts, build prompts around real purchase constraints, and fix the earliest gate that fails. Once that path is reliable, extend the same operating model to the rest of the catalog. That gives you a repeatable visibility system instead of a collection of schema additions and copy changes whose effect you cannot explain.

    References


  • Title Tag SEO: A Practical Guide to Relevance and Clicks

    Title Tag SEO: A Practical Guide to Relevance and Clicks

    Your page can hold its position in search and still become easier to ignore. The usual problem is not a missing keyword. It is a title tag that names the topic without showing why this result is the right one for the searcher.

    A strong title tag makes relevance obvious, sets an accurate expectation, and gives the listing a reason to be chosen. Here is how to write one, evaluate it in context, and diagnose it when rankings and clicks tell different stories.

    Make relevance unmistakable before you try to be clever

    The title tag is the HTML <title> element that summarizes a page. Google may use it as the clickable title link in search results, but that wording is not guaranteed to appear unchanged. It is also different from the H1: the title tag describes the page in search and other external contexts, while the H1 introduces the content on the page itself.

    Before writing the title, answer three questions:

    • What phrase or entity would the intended searcher recognize immediately?
    • What specific task, answer, product, or outcome does the page provide?
    • What truthful detail distinguishes this page from neighboring results?

    A dependable working structure is: recognizable topic + specific value + useful qualifier. That might produce Title Tag SEO: A Practical Writing Guide, Invoice Approval Software for Small Teams, or Family Red T-Shirts: XS-XXL Under $25. The structure is not a template you must fill mechanically. It is a check that each word has a job.

    Include the keyword phrase or entity you want the page associated with, using the language your audience actually uses. Exact wording can be especially helpful when someone is new to a subject and does not know its synonyms, product nicknames, or category jargon. Search systems may understand related entities, but that does not remove the need for clear user-facing terminology.

    Consider meal replacement shakes and mass gainers. The products may overlap, but the phrases imply different needs. A page can be technically relevant to both while its title speaks convincingly to neither. Choose the primary audience for that page, use that audience’s term in the title, and handle secondary language naturally in the body.

    Do not treat the keyword as a guarantee of ranking. Its more immediate value is recognition: the searcher should not have to infer whether the page addresses the query. We would usually place the subject near the beginning when it reads naturally, not because the first position is a magic signal, but because the page should identify itself before secondary wording consumes the visible space.

    This clarity also matters beyond the conventional results page. AI systems can use search results to ground answers and select material to recommend. A title tag is not a command that makes an AI system cite you, but weakening organic discoverability can also reduce your opportunity to be found through AI-assisted search.

    Keep the important meaning inside the visible title

    Essential page and search symbols remain visible inside a title-shaped frame while decorative shapes are cropped at the right edge.

    A practical character-based recommendation is to keep a title tag at roughly 55 characters or fewer, including spaces. Treat that as a planning constraint, not a universal law. Search results are rendered by width, so different words consume different amounts of visible space. A content management system may also append a brand name or separator that was not present in your draft.

    Long titles create two presentation risks: the visible title may end with an ellipsis, or Google may choose different wording. Neither outcome automatically means the page cannot rank. It means you have surrendered some control over the message a searcher sees.

    Use this editing sequence:

    1. Write a natural draft that states the page’s subject and benefit.
    2. Move the essential topic and qualifier into the opening portion.
    3. Delete repeated category words, empty adjectives, and phrases already implied by the topic.
    4. Count the complete title, including spaces, separators, dates, and any brand text added by the site.
    5. Read the shortened version as a promise. If it becomes vague or misleading, restore the words needed for accuracy.
    6. Compare it with the live results for the target query before publishing.

    For example, Complete Guide to Title Tag SEO: Everything You Need to Know spends much of its space announcing comprehensiveness. Title Tag SEO: A Practical Writing Guide identifies the subject and the utility with less ceremony. The second title is not better merely because it is shorter. It is better if the page genuinely provides a practical writing process.

    Do not add filler to reach the available limit. When surrounding listings use nearly all of their space, a shorter, specific title can become visually distinct. Length is therefore an upper constraint and a competitive choice, not a target you need to hit.

    Stand out with evidence, not decoration

    You cannot judge differentiation inside a spreadsheet. Search the primary query and inspect the titles around yours. You are looking for repeated structures: the same adjective, the same year, the same question, the same long chain of benefits, or the same punctuation-heavy formula.

    Then work through this SERP review:

    1. List the dominant title patterns on the results page.
    2. Mark the words every result uses because the query requires them.
    3. Separate those necessary terms from language that merely copies the category.
    4. Choose one concrete distinction the page can prove.
    5. Rewrite the title so the shared topic remains recognizable and the distinction is visible.

    Useful distinctions often come from the decision the visitor is already making. For a product page, that could be price, discount, size, or length. For software, it could be the intended team or task. For an instructional page, it could be the precise deliverable. Numbers and symbols can attract attention when they communicate one of those real details rather than decorating a generic claim.

    • Family Red T-Shirts: XS-XXL identifies the available size range.
    • Red T-Shirts Under $25 identifies a spending threshold.
    • Invoice Approval Software for Small Teams identifies the intended user.
    • Title Tag Audit: A Six-Step Workflow identifies a concrete format.

    Every modifier creates an obligation. If the title says Under $25, the landing page must honor that threshold. If it promises six steps, the page must contain six usable steps. If a price or promotion changes frequently, connect the title-update process to the same operational change or choose a more durable distinction. A stale claim may win the wrong click and lose trust on arrival.

    Avoid relying on Best, Ultimate, Complete, or Essential unless the page demonstrates what the word means. These terms are not automatically forbidden, but they rarely distinguish a listing when every competitor uses them. Formulaic question titles, stacked separators, parenthetical asides, and repeated keyword variants can also make a title look machine-assembled. One clear proposition usually communicates more than a chain of loosely related promises.

    Diagnose title problems from the symptom you can observe

    A magnifying glass connects two abstract search-result symptoms to separate diagnostic paths on a dark digital workbench.

    Do not rewrite a title simply because traffic fell. Ranking movement, result-page changes, terminology, and the title itself are different variables. Check them separately so the edit addresses the actual problem.

    Observed symptomPossible readingFirst action
    Rankings and the results layout are stable, but traffic has fallenThe title may use a product or service name that searchers no longer preferCompare the wording in the title with the current language used in relevant queries and competing results
    The visible title is cut off before the differentiatorThe essential value appears too lateMove the topic and deciding detail forward, then remove repetition
    Google displays substantially different wordingThe HTML title may be long, vague, repetitive, or less useful than another page labelCompare the displayed wording with the title tag, H1, and actual page purpose before revising
    Visibility is healthy, but clicks lagThe title may be relevant without being distinctive or may answer the wrong intentInspect adjacent results and add one truthful qualifier tied to the searcher’s decision
    Clicks rise, but qualified actions weakenThe title may attract an audience the page is not designed to serveMake the audience, scope, price condition, or use case more explicit

    The first pattern deserves particular attention. When ranking and the SERP layout have not materially changed, a traffic decline can point to a mismatch between the title’s terminology and the audience’s current wording. A competitor using the more familiar name can earn the click without displacing your ranking.

    Keep a simple change record for every meaningful revision: the previous HTML title, the replacement, the target query, the displayed search title, the date, and the reason for the change. Hold other page changes steady where practical. That makes the result interpretable instead of leaving you to guess whether the title, content, or layout change moved the metric.

    Evaluate the outcome against the hypothesis. If you changed terminology, look for stronger response from the intended queries. If you shortened the title, verify that the deciding words now appear. If you added a price or size, check whether the arriving audience behaves like the audience that qualifier was meant to attract. A ranking check alone cannot tell you whether the title is doing its user-facing job.

    Key takeaways

    • Lead with the phrase or entity your intended searcher will recognize, then state a concrete value or qualifier.
    • Use roughly 55 characters, including spaces, as a practical editing constraint rather than a quota.
    • Inspect the live results page before writing; differentiation depends on what appears beside your listing.
    • Use prices, percentages, sizes, lengths, and other modifiers only when the page can prove and maintain them.
    • When rankings stay steady but traffic falls, check audience terminology before assuming the page has lost relevance.
    • Treat AI visibility as an extension of sound search visibility, not as a reason to stuff conversational phrases into the title.

    Start with one page that has stable visibility but an underperforming search listing. Write down its audience, primary phrase, promise, and strongest truthful distinction. Reduce those four inputs to one clear title, log the change, and judge it by whether it attracts more of the right clicks.

    References


  • SEO Career Signals That Prove You Can Drive Business Value

    SEO Career Signals That Prove You Can Drive Business Value

    You can be excellent at keyword research, technical audits, content briefs, internal linking, and structured data and still struggle to explain why you should be hired, promoted, or protected when budgets tighten. If your evidence stops at completed tasks, you are showing competence in work that software can increasingly accelerate.

    The career question has shifted from Can you find SEO work? to Can you identify the work worth doing, earn its priority, and connect it to a business result? This is how you build career signals that answer that question with evidence.

    Key takeaways

    • SEO fundamentals remain necessary, but they no longer distinguish you on their own.
    • Your strongest career signal is a well-supported decision under real constraints, not the size of an audit or task list.
    • A recommendation should identify the business effect, proposed action, tradeoff, dependency, and proof of success.
    • Your portfolio should show how your reasoning changed a decision, influenced implementation, and affected an outcome.
    • AI fluency matters when you can verify its output and apply judgment, not merely generate more deliverables.

    Make business judgment your primary SEO signal

    AI can already draft audits, summarize search results, suggest content briefs, write metadata, identify schema gaps, and assemble roadmaps. Knowing how to produce those deliverables still matters. Treating their production as your main value does not.

    A strong career signal is observable evidence that you can make a useful choice when the answer is not sitting in a checklist. It shows that you understand what the company sells, why customers choose it, where organic discovery supports the buying journey, and what the business would have to give up to pursue your recommendation.

    Before proposing work, force the opportunity through these questions:

    • Which business or customer outcome is constrained? Name the decision, transaction, lead, adoption step, or customer need that the work is meant to support.
    • What evidence makes this an organic-search problem? Separate observed search behavior, crawl or indexation evidence, page performance, and customer behavior from assumptions.
    • What happens if the company does nothing? Describe the likely cost of delay without manufacturing urgency.
    • What are the realistic alternatives? Compare the SEO proposal with product, engineering, content, brand, paid distribution, or no action.
    • What is the smallest useful move? Define the change that can test the reasoning before asking for a broad program.
    • What evidence would change your mind? Decide in advance what would cause you to expand, revise, or stop the work.

    Put the answers into a short opportunity brief. Its purpose is not to display everything you know. It should help someone choose among competing uses of time and money.

    • Situation: the relevant business context and verified search condition.
    • Effect: the customer or commercial consequence of that condition.
    • Options: plausible responses, including doing nothing.
    • Recommendation: the action you prefer and why it is the best available choice.
    • Tradeoff: the engineering, editorial, design, or analytical capacity the action requires.
    • Dependency: the people, systems, approvals, and release conditions needed for implementation.
    • Evidence plan: the leading and business indicators you will examine, plus any limits on interpretation.

    This format exposes weak reasoning early. If you cannot connect a proposed content cluster, template change, or schema implementation to a meaningful problem, you may have found a valid best practice without finding a priority.

    Use a simple prioritization ladder when requests compete:

    • Act: the evidence is strong, the affected journey matters, and delay has a credible cost.
    • Validate: the opportunity is plausible, but a limited investigation or reversible test should come before substantial investment.
    • Schedule: the work has a reasonable path to value but loses to a more consequential constraint.
    • Decline: the request has no convincing path to a customer or business outcome, or another intervention addresses the problem more directly.

    Saying no is part of this skill. The useful version of no sounds like this: The concern is real, but this action is unlikely to resolve it because the evidence points to a different constraint. We recommend addressing that constraint first, then reassessing this request with the resulting data. You are not blocking work; you are making the opportunity cost visible.

    You also need to recognize when the problem is not SEO. A page that earns visits but fails to move people forward may have a product, pricing, positioning, user-experience, or conversion-path problem. Weak brand recognition may limit demand that another content campaign cannot create by itself. Strategic SEOs can identify those boundaries instead of prescribing SEO for every symptom.

    Your career signal is not that you can personally fix every adjacent problem. It is that you can diagnose the boundary, involve the right owner, and prevent the company from spending on the wrong remedy.

    Build a portfolio around decisions, influence, and outcomes

    Two colleagues review a portfolio-like case containing abstract research cards, prioritization tokens, a product model, and illuminated outcome blocks.

    A ranking chart, audit export, or traffic graph shows an event. It does not show whether you understood the business, selected the right intervention, influenced the people who controlled implementation, or interpreted the result responsibly. Even a long tenure is not proof that your decisions made the business better.

    Rebuild each portfolio example as an evidence chain:

    • Context: what the company sold, who the relevant customer was, and where organic discovery fit in the journey.
    • Constraint: the verified problem and why it mattered at that moment.
    • Diagnosis: the evidence you used, the uncertainty that remained, and the non-SEO explanations you considered.
    • Decision: what you recommended, what you explicitly did not recommend, and why.
    • Influence: how you adapted the case for the people whose support or work was required.
    • Implementation: what actually shipped, how it differed from the original proposal, and what compromises were accepted.
    • Outcome: what changed in search behavior, customer behavior, or business performance, without claiming causation the evidence cannot establish.
    • Learning: what the result confirmed, what it disproved, and what you changed next.

    The rejected options are important. They reveal judgment. If you chose a template-level fix over manually editing many pages, explain the operational reason. If you accepted a technically imperfect release because the remaining issue did not justify delaying a customer-facing launch, describe the tradeoff. If you stopped a content plan after discovering that product positioning was the real constraint, show that decision.

    Do not retrofit a commercial success story onto evidence that only supports a search result. Use the strongest claim the data permits:

    • If you only know that the recommendation was accepted, say that.
    • If you know the change shipped and technical validation passed, show that implementation proof.
    • If visibility or qualified visits changed, distinguish that from revenue or lead impact.
    • If conversions changed but attribution is uncertain, state the uncertainty and identify other contributing factors.
    • If nothing improved, explain what you learned and why the next decision became better.

    This makes modest projects useful portfolio material. You do not need to manufacture a dramatic win. Preventing low-value work, clarifying measurement, narrowing an oversized initiative, or uncovering a non-SEO constraint can demonstrate better judgment than a lucky ranking gain.

    Select examples that match the level of role you want. Early-career evidence should make your analytical discipline and ownership visible. Mid-career evidence should show prioritization, cross-functional execution, and measurement. Senior evidence should show how you allocated scarce resources, managed uncertainty, improved the decision system, and connected search investments to company strategy.

    Keep confidential information out of public materials. Replace identifying details with truthful descriptions, remove proprietary data, and never imply that anonymized figures are precise if you have transformed them. You can demonstrate reasoning without exposing an employer or client.

    Make communication part of SEO delivery

    A technically correct recommendation that nobody implements creates no business result. That is why communication determines whether SEO receives resources, priority, implementation, and a connection to revenue. It is not decoration added after the analysis. It is part of delivering the work.

    A line item such as implement schema or improve internal linking describes activity. It leaves the decision-maker to work out why the activity matters, whether it outranks other work, and how anyone will know it helped. A decision-ready recommendation supplies that missing logic:

    • What is happening: the condition you verified, stated without unnecessary jargon.
    • Why it matters here: the affected customer journey, product area, operational process, or commercial objective.
    • What inaction means: the credible consequence of waiting or declining.
    • What should happen first: a specific, bounded action rather than a broad aspiration.
    • What the team is trading: the capacity, release risk, or competing work involved.
    • How you will evaluate it: implementation checks, leading indicators, business measures, and interpretive limits.

    For example, turn a generic schema ticket into a decision: the affected template currently presents inconsistent product facts between visible content and machine-readable fields; standardize the underlying fields and generate matching structured data from that source; prioritize the work only if it addresses a verified inconsistency on commercially important pages or supports a relevant eligible search experience; acknowledge the required template engineering time; validate the output and observe the intended search behavior without promising that a platform will display it.

    The technical action is still present, but the recommendation now tells a team why it deserves attention and what success does and does not mean.

    Adapt the same recommendation to the person receiving it:

    • Leadership needs the outcome, confidence level, resource request, downside of delay, and opportunity cost.
    • Engineering needs a reproducible condition, affected scope, constraints, acceptance criteria, release risk, and validation method.
    • Content teams need the audience need, editorial gap, evidence standard, distribution path, and definition of a useful page.
    • Analytics teams need the question being measured, required data, event logic, comparison method, and known attribution limits.

    Do not end an update with information alone. State the decision you need, who needs to make it, what input remains unresolved, and what happens after approval. Record the owner and next checkpoint. This turns communication into forward movement instead of another status artifact.

    Measure your influence as well as the search result. Useful evidence includes whether the recommendation was understood, accepted, funded, correctly implemented, and incorporated into later planning. Those milestones do not replace business outcomes, but they show where delivery succeeded or failed.

    Use AI to raise the standard of your work

    An SEO specialist reviews abstract AI-generated options, verifies one with research tools, and shares the refined result with two colleagues.

    AI lowers the cost of producing plausible SEO output. It does not remove the need for technical knowledge, content judgment, analytics, distribution, or an understanding of how search and answer engines work. It raises the standard for what you do after the first draft appears.

    Prompt fluency alone is a weak career signal. A stronger AI workflow makes your judgment auditable:

    • Frame the question: define the business decision before asking a model for an audit, summary, classification, or plan.
    • Control the inputs: provide relevant first-party information and distinguish it from assumptions or generic best practices.
    • Verify the output: check technical claims against the site, search behavior, platform requirements, analytics, and customer context.
    • Find the omission: look for product, brand, pricing, user-experience, operational, and measurement factors the generated answer did not consider.
    • Make the decision: choose what to act on, test, defer, or reject, and document the tradeoff.
    • Close the loop: compare the result with the original reasoning so the next decision improves.

    This distinction is especially important in AI SEO, AEO, and GEO work. A third-party visibility score may help you observe change, but it is not the business outcome. Search rankings, sessions, and third-party AI visibility scores should not be mistaken for the purpose of the work. Use them as diagnostic indicators and connect them, where the evidence allows, to relevant queries, brand representation, qualified behavior, customer decisions, conversions, or another defined business objective.

    You should also be able to explain the boundary between what your team controls and what a search or answer platform controls. You can improve accessible content, factual consistency, structured data, internal connections, source clarity, and technical availability. You cannot guarantee that a platform will crawl, index, rank, cite, summarize, or display the material in a particular format. Clear boundary-setting is a professional signal because it protects decision quality from inflated promises.

    Before your next interview or performance review, open a recent deliverable and remove the task list from its opening. Replace it with the constrained outcome, verified evidence, options considered, recommended decision, required tradeoff, implementation record, and strongest defensible result. Then ask whether someone outside SEO could understand why the work mattered.

    If the answer is no, you do not need another checklist yet. Rewrite that project until it proves that you can choose well, bring other people with you, and connect organic discovery to a result the organization actually values. That is the career signal worth building next.

    References