Category: Ecommerce

  • Google Merchant Center UCP Integrations: What to Enable

    Google Merchant Center UCP Integrations: What to Enable

    You have three separate decisions to make when Google’s UCP integration hub appears in Merchant Center. You can send a cart to your website, support checkout on Google, link customer identities, or adopt only the capabilities that fit your operation.

    The right choice depends less on what you can switch on than on where you can safely own the customer, order, and recovery experience. Use the framework below to choose a scope, test the handoffs, and measure whether UCP removes purchasing friction without creating an operational blind spot.

    What the UCP integration hub actually changes

    Google is gradually making the Merchant Center UCP integration hub available to eligible U.S. merchants. UCP stands for Universal Commerce Protocol. In this rollout, it acts as a connection layer between Google’s shopping experiences and a merchant’s commerce infrastructure.

    The meaningful change is modularity. An eligible merchant can select individual capabilities instead of accepting one predetermined checkout experience. That turns UCP configuration into a set of business decisions rather than a single technical integration.

    CapabilityWhat changes in the journeyYour release gate
    Cart transferThe shopper’s cart moves from Google to the merchant’s website, where the purchase can continue.The correct products, variants, quantities, prices, and context must survive the handoff.
    Native checkout on GoogleThe shopper can complete checkout within Google’s experience.Your order operation must reliably receive, fulfill, reconcile, support, cancel, and refund the resulting orders.
    Identity linkingThe shopper’s Google identity can be connected with the merchant’s customer relationship.The customer benefit, consent path, account-matching rules, unlinking process, and support recovery must be clear.

    Treat the last column as your own acceptance standard. The presence of a capability in Merchant Center tells you that it is available to configure; it does not prove that your downstream systems, policies, analytics, or support team are ready for it.

    For SEO, AEO, and GEO teams, the boundary matters. UCP is commerce infrastructure. It can shorten the distance between product discovery and purchase, including journeys in which AI agents help people research products, assemble carts, and transact. It should not be treated as a ranking switch, a replacement for Merchant Center feed quality, or a substitute for accurate product pages and structured data.

    Choose each capability by ownership and failure radius
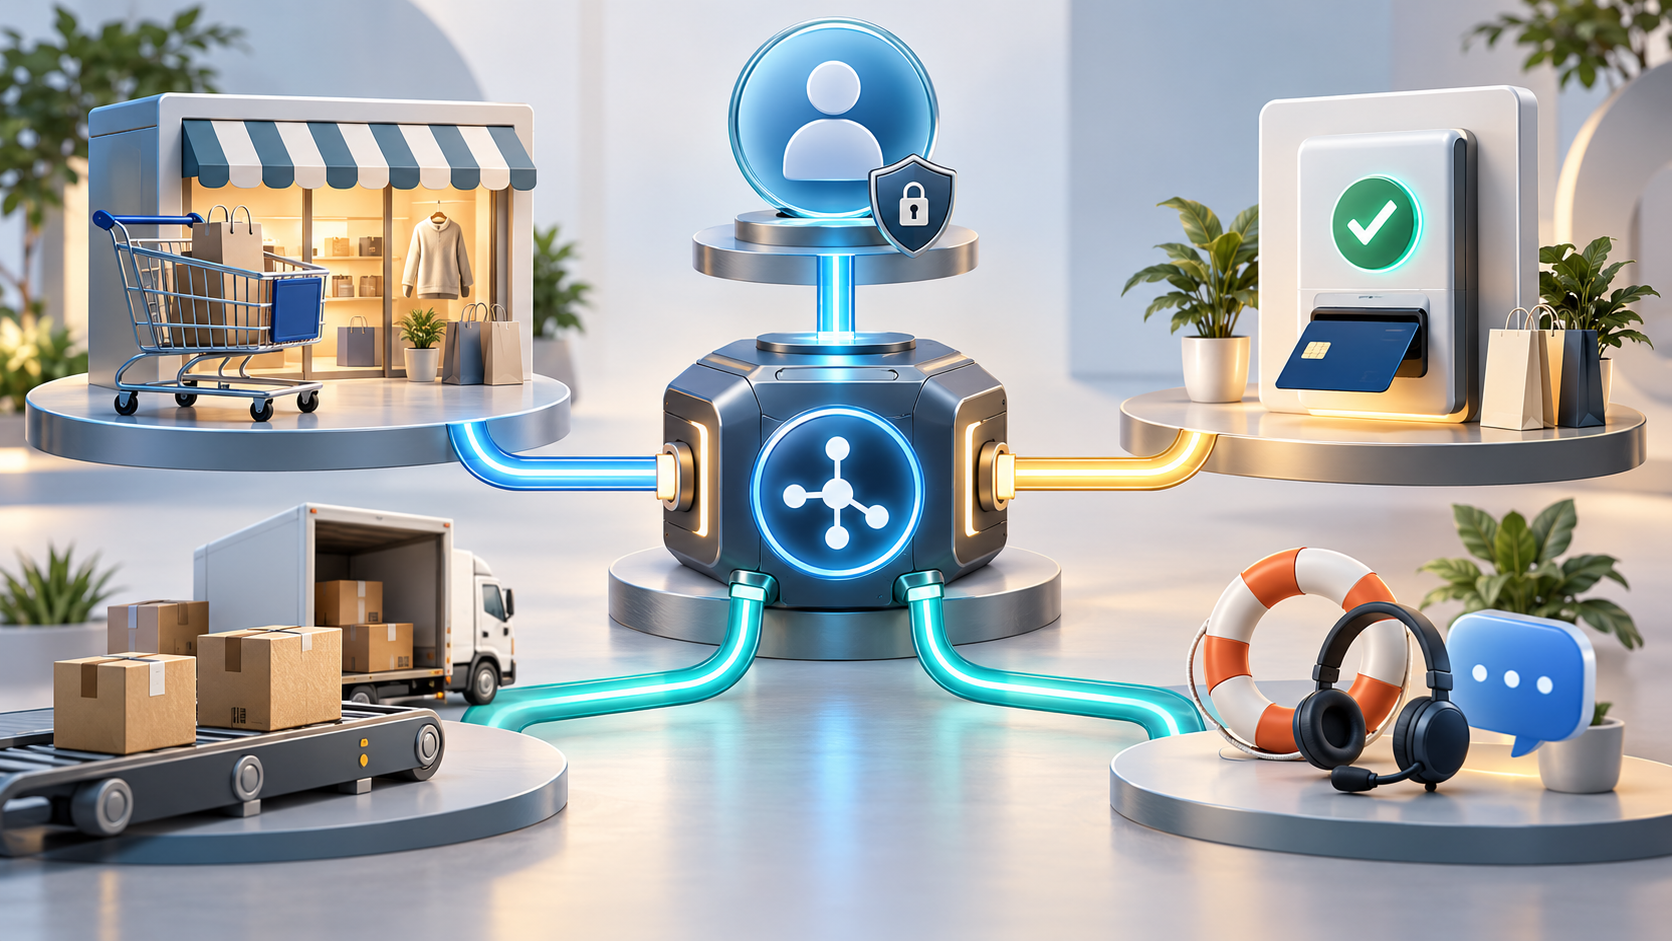
    A modular ecommerce system separates identity, checkout, and fulfillment into bounded zones, with an amber warning contained inside the checkout area.

    Start with the customer journey you can operate reliably. A shorter path is valuable only when the order that emerges from it is accurate, observable, and recoverable.

    1. Consider cart transfer first when your website checkout is already the strongest part of the journey. It lets Google participate in discovery and cart creation while your existing site remains the purchase destination. Test the handoff as a data contract: the product identifier, selected variant, quantity, current price, availability, promotion context, and destination page must agree. Also define what the shopper sees when a price changes, an item sells out, or the cart cannot be reconstructed.
    2. Consider native checkout when your order operation can support a transaction completed outside your website. Map the entire order lifecycle before enabling it: creation, payment state, tax, shipping, inventory reservation, fulfillment, cancellation, returns, refunds, customer notifications, fraud review, and support. Do not assume that a native interface transfers responsibility for these functions. Confirm the division of responsibility for your particular setup.
    3. Consider identity linking when signing in produces a real customer benefit. That benefit might involve account continuity, saved preferences, loyalty, or post-purchase service, but the benefit must be explicit. Define how accounts are matched, what happens when identifiers disagree, how duplicate accounts are handled, how consent is recorded, and how a customer can unlink or recover access.

    The hub’s capability-by-capability selection model gives you a reason to avoid an all-at-once launch. Enable the smallest useful combination first. If cart transfer fails, you can investigate the cart contract. If identity linking and native checkout go live at the same time, an order problem may involve identity resolution, checkout state, or the order pipeline, making the cause harder to isolate.

    That sequencing is especially important for identity linking. It introduces customer-data, authentication, privacy, and support consequences that are different from the mechanics of moving a cart. Review it as its own workstream rather than treating it as a convenience setting attached to checkout.

    Build six release checks before changing the customer journey
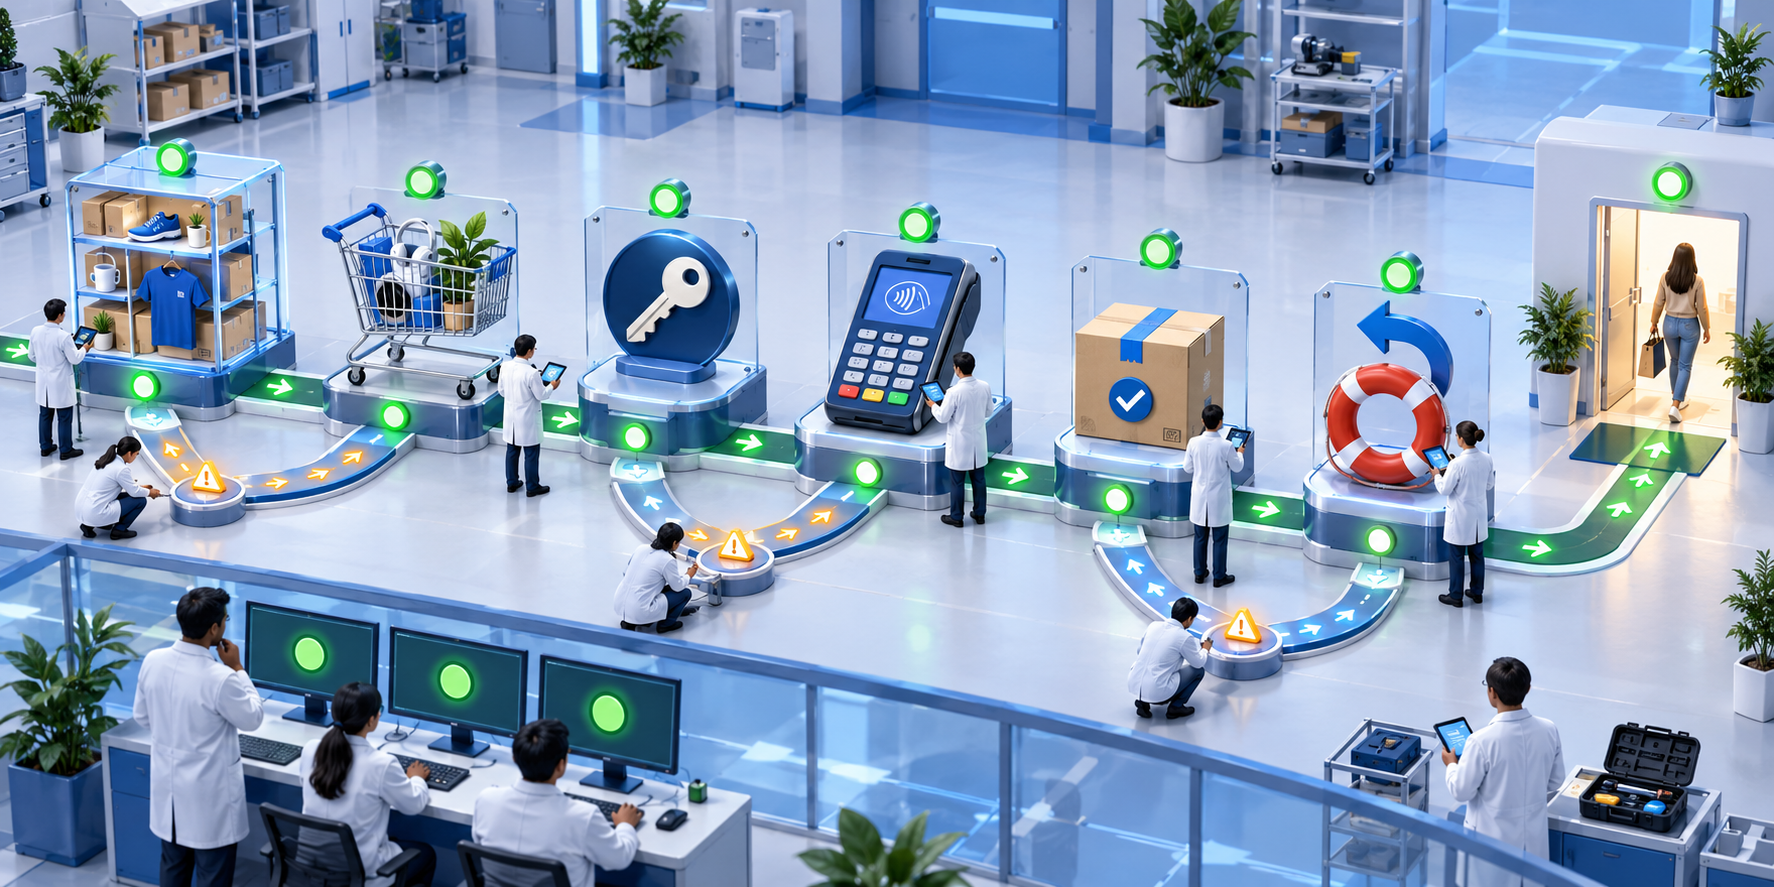
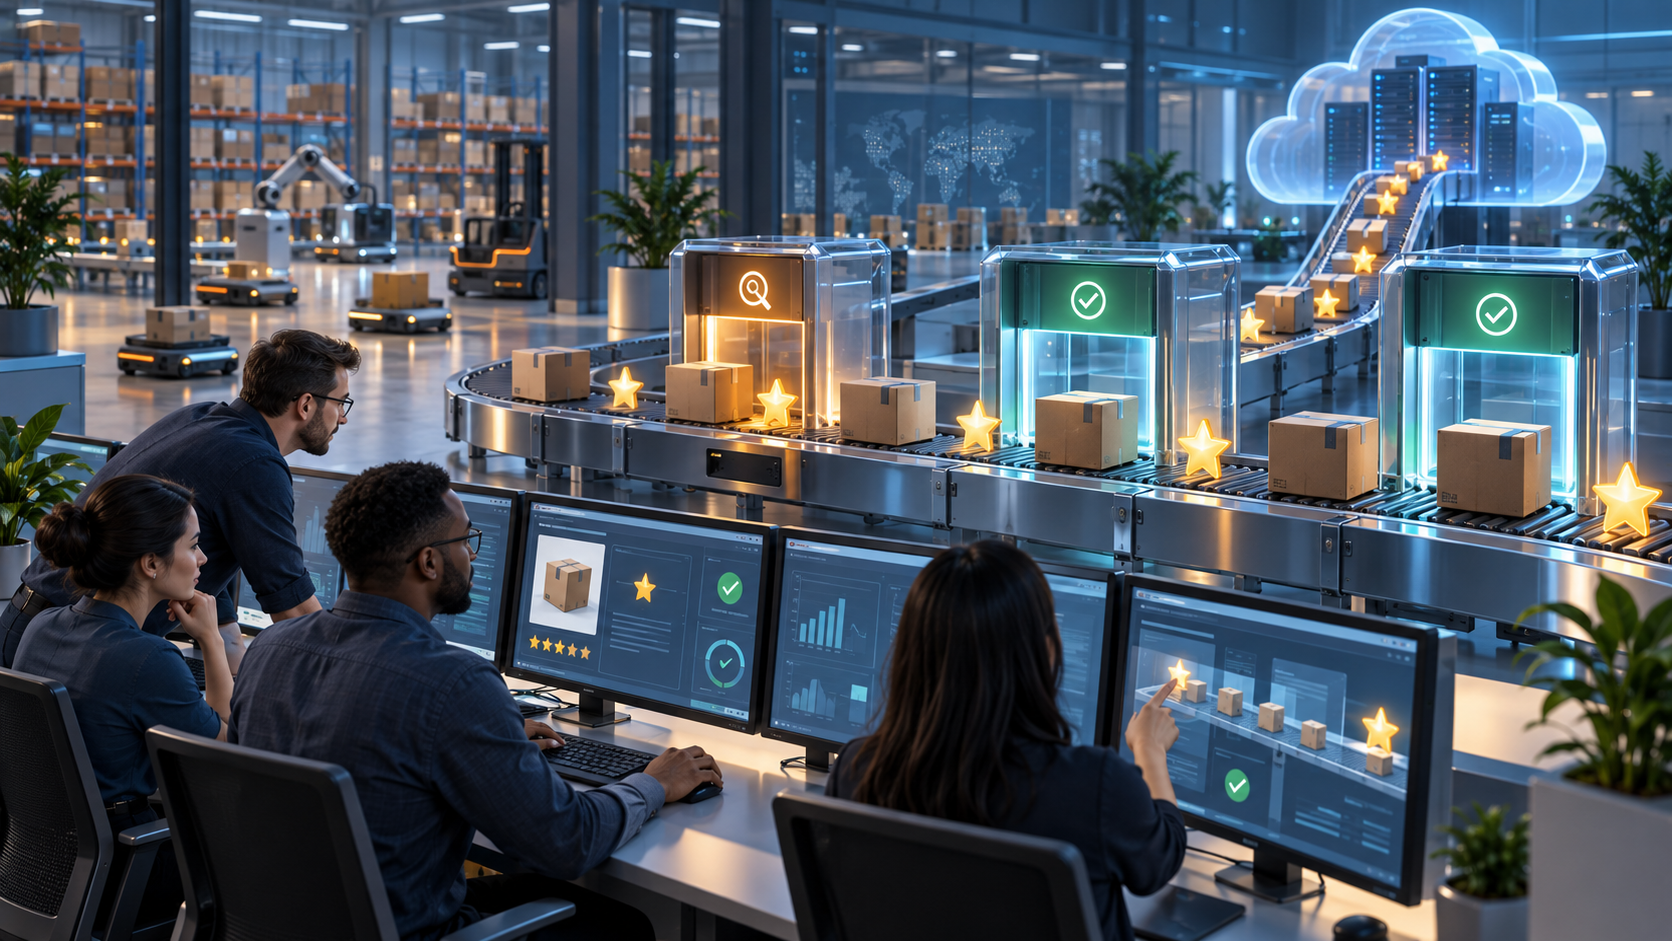
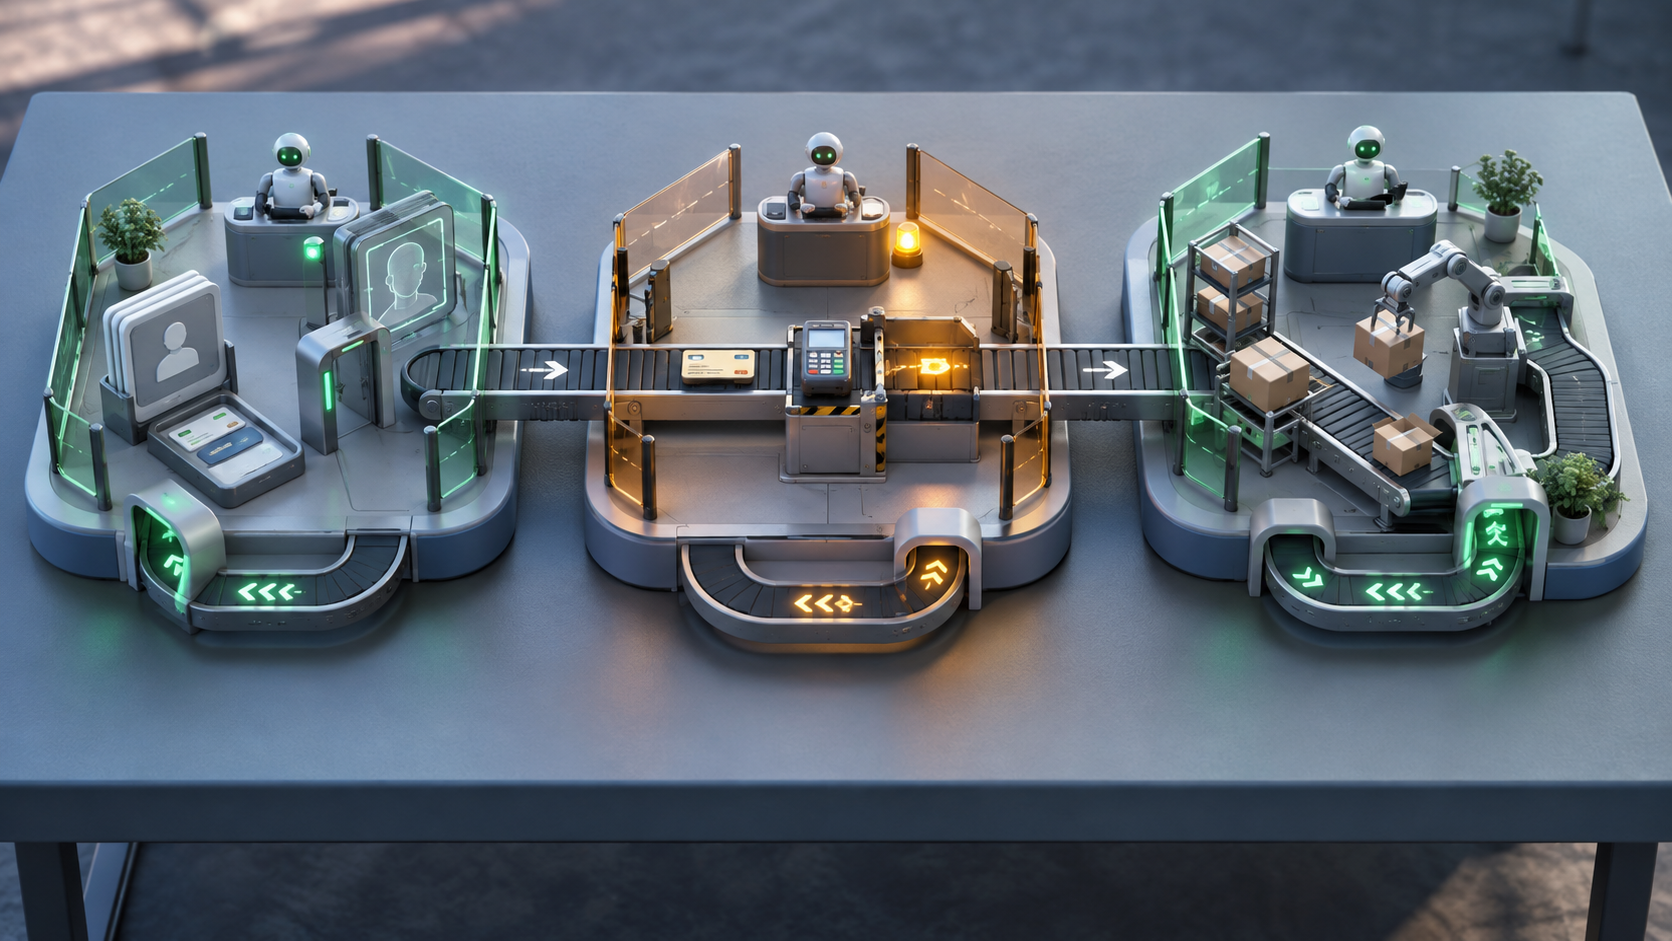
    Six quality-control stations test product availability, cart transfer, identity, payment, order confirmation, and customer recovery along an ecommerce purchase path.

    You do not need to wait for a full implementation project before preparing. You do need a written acceptance plan. Build these six checks while access is rolling out:

    1. Confirm the actual scope in your account. Record which Merchant Center account, market, storefront, and capabilities are eligible. The rollout begins with eligible U.S. merchants, while plans for Australia and Canada have moved to a later schedule. Work from the controls present in your account rather than treating an announced market sequence as a guaranteed activation date.
    2. Define the catalog contract. Name the system that owns each product identifier, variant, price, currency, availability state, image, and fulfillment promise. The website, Merchant Center data, cart, and order record should refer to the same sellable item. If two systems can overwrite a value, document which one wins and when.
    3. Define the cart contract. Specify what must survive a transfer and what can be recalculated on arrival. Include quantity limits, variant selections, promotions, unavailable items, expired carts, and price changes. Write the customer-facing fallback for each failure; a silent empty cart is not an acceptable recovery path.
    4. Define the order contract. For native checkout, trace a successful order and every material exception through the systems your teams use. An order is not complete merely because payment appears successful. It must enter inventory, fulfillment, notifications, reporting, customer service, cancellation, return, and refund workflows with a stable identifier.
    5. Define the identity contract. Decide what data is linked, why it is needed, what consent is required, how long it is retained, and which team handles mismatches. Include duplicate accounts, shared email addresses, changed email addresses, revoked access, deletion requests, and support verification.
    6. Define observability and recovery. Assign an owner for integration errors, order discrepancies, customer complaints, and rollback decisions. Preserve enough identifiers to trace a journey across the surfaces you control without exposing unnecessary personal data. Document how you will pause a capability safely if failures rise.

    Use any preview, testing, or diagnostic path that your Merchant Center account makes available. If your account exposes only a broad production control, complete the data and operational checks before changing it. Do not discover your refund path, account-recovery rules, or missing order identifiers through the first customer complaint.

    Launch one capability at a time when the available controls permit it. Start with the smallest reversible product or operational scope supported by your setup. Keep a written record of the prior configuration, the activation time, the owner on duty, the expected signals, and the condition that triggers a pause.

    Measure the handoff, not just the final sale

    A conversion total can hide the exact friction UCP is meant to remove. Build a funnel that shows where an eligible journey stopped. Instrument the events available on the systems you control, then reconcile them with the commerce and order records available from the integration.

    • Eligible journey volume: the number of shopping journeys that could use the enabled capability.
    • Cart initiation and transfer: how many carts begin, how many handoffs are attempted, and how many arrive with usable contents.
    • Checkout progression: how many transferred or native journeys reach checkout, encounter an error, and complete.
    • Order reconciliation: whether each completed transaction produces one accurate order in the system of record, without omissions or duplicates.
    • Commercial consistency: discrepancies involving products, variants, quantities, price, availability, tax, shipping, discounts, or currency.
    • Operational consequences: cancellations, refunds, identity-recovery cases, integration-related support contacts, and manual corrections.

    Capture a baseline before launch. Compare the same journey before and after enablement where your data permits, and separate technical success from business success. A cart can transfer perfectly while conversion falls because the landing experience is confusing. Native checkout can increase completed orders while creating reconciliation work that erases the operational benefit.

    Website analytics alone will be incomplete when checkout finishes on another surface. Do not interpret a drop in site-recorded purchases as a drop in total purchases until native orders have been reconciled. Conversely, do not count an external checkout confirmation as a clean success until the corresponding order is present and actionable in your system of record.

    Keep search visibility and commerce performance in separate reporting layers. Monitor product discovery, landing-page visibility, feed health, and structured-data quality alongside the UCP funnel, but do not attribute a ranking change to UCP merely because the dates overlap. Its immediate job is to connect discovery, cart, identity, and transaction paths more effectively.

    Consistency is the point where the SEO and commerce teams meet. Use the same product identity, variant language, pricing state, availability, and merchant policy across Merchant Center, the website, structured data, cart, checkout, and order systems. UCP cannot compensate for contradictory facts moving through those systems; it can only make those contradictions reach the customer faster.

    Key takeaways

    • UCP in Merchant Center is a selectable integration layer, not one mandatory checkout model.
    • Choose cart transfer when your site checkout should remain the transaction destination and you can preserve cart accuracy through the handoff.
    • Choose native checkout only after the complete order, support, cancellation, return, and refund lifecycle works outside a website-completed purchase.
    • Review identity linking separately because it adds consent, account-matching, privacy, authentication, and recovery requirements.
    • Measure attempted handoffs, errors, discrepancies, and reconciled orders as well as conversions.
    • Do not treat UCP enablement as evidence of improved rankings; maintain product data, content, feeds, and structured data as separate visibility work.

    If the hub is already available in your account, begin with a capability decision and an acceptance checklist, not the activation control. If it is not available, prepare the catalog, cart, order, identity, and measurement contracts now. That work remains useful regardless of when eligibility reaches your market or account.

    References


  • Ecommerce Category Internal Linking: A Practical System

    Ecommerce Category Internal Linking: A Practical System

    Your ecommerce site has more category pages than your navigation can reasonably promote. Merchandising wants one collection featured, SEO sees demand for another, and yesterday’s bestseller still holds most of the site’s internal links. Adding links everywhere won’t resolve that conflict.

    You need a repeatable way to decide which categories deserve support, identify where the current architecture sends the wrong signal, and place links that are useful to shoppers. The goal isn’t an equal distribution. It is an intentional one.

    Make each category earn additional internal links

    Start with the category’s value, not its current link count. A URL does not become important merely because your platform created it, an audit flagged it, or a team wants to rank it. Before you promote a category, confirm that it represents a durable opportunity for both the business and the shopper.

    Evaluate each candidate against these criteria:

    • Business importance: The category supports a defined commercial priority, such as profitable growth, a strategic product line, or a sustained merchandising commitment.
    • Search opportunity: People look for the category as a distinct concept. Its intent is meaningfully different from the parent category and nearby alternatives.
    • Inventory strength: The page offers enough relevant products to satisfy the visit, and stock is likely to remain available. A prominent link to a thin or frequently empty collection sends shoppers into a dead end.
    • Durability: The category will matter beyond a brief promotion. A recurring seasonal category can qualify, but a disposable campaign URL usually should not receive permanent architectural prominence.
    • Landing-page usefulness: The page helps someone understand the selection and continue shopping. Links cannot compensate for an unclear category, irrelevant products, or an experience dominated by unavailable inventory.

    A practical approval record can be short. For every proposed target, write down the target URL, its business purpose, the demand it serves, the inventory owner, and whether it is permanent, recurring, or temporary. That forces the team to distinguish a real category opportunity from a request for more SEO attention.

    Be especially selective with filters. Color, size, brand, material, price, and other facets can produce a large population of URL combinations. Opening internal paths to all of them can slow the discovery of more useful content. Promote a filtered landing page only when it has distinct demand, dependable inventory, a stable purpose, and enough structural support to function as a genuine category.

    If a URL fails those tests, more internal links are not the remedy. Improve or consolidate the page, keep the filter available for shoppers without broadly promoting its URL, or direct attention to the stronger parent category.

    Audit the gap between business priority and site architecture

    Tabletop model contrasting prominently displayed product collections with uneven pathways through a digital storefront structure.

    Once you have a qualified set of categories, compare what the business considers important with what the site currently presents as important. This is the central diagnostic step.

    Google can infer a page’s relative importance from internal-link relationships, including how many internal links lead to the page and how many links a crawler must follow to reach it. Shoppers receive a similar message: categories exposed in navigation and related content look central, while deeply buried categories look peripheral.

    Run the audit in this order:

    1. Set the commercial priority first. Label each approved category as a current priority, a category to maintain, or a low-priority page. Do this before reviewing SEO metrics so existing visibility does not quietly become your definition of importance.
    2. Crawl from the shopper-facing site. Record the shortest click path from the homepage, the number of crawlable internal links pointing to each category, and the templates or pages supplying those links.
    3. Separate structural links from incidental links. A persistent navigation link, a parent-category path, an editorial recommendation, and an old campaign link do not play the same role. Label the source and placement instead of treating every link as interchangeable.
    4. Check relevance. Inspect whether the linking pages share a real product, audience, or shopping relationship with the target. A large count of unrelated links can conceal a weak architecture.
    5. Find mismatches. Prioritize categories with high commercial importance but weak site support. Also flag low-priority categories that still occupy prominent navigation or receive extensive legacy links.

    Use relative comparisons within your own catalog. A universal target for click depth or link count would ignore differences in store size, navigation design, and taxonomy. Compare equivalent category types, then look for outliers.

    Business priorityCurrent site supportWhat it meansRecommended action
    HighLowThe architecture understates a qualified opportunity.Find relevant, prominent pages that can supply links.
    HighHighThe site already reflects the priority.Maintain the paths; investigate other constraints before adding more links.
    LowHighLegacy architecture may be spending attention on an outdated priority.Review navigation and inherited modules before promoting new targets.
    LowLowThe architecture and current business priority are aligned.Leave it alone unless its role changes.

    This matrix prevents a common mistake: assuming that every important category needs more links. If a category is already easy to reach, prominently represented, and supported by relevant pages, its problem may be weak inventory, poor intent alignment, or an unhelpful landing page. Another batch of links would obscure that diagnosis.

    Place links where they help someone continue shopping

    Shopper viewing image-only product panels for trail shoes, hiking socks, outdoor clothing, and backpacks connected in a natural shopping sequence.

    After identifying an under-supported category, choose donor pages by relationship rather than raw authority. The best question is simple: would a shopper on this page reasonably want to explore that category next?

    Consider link locations in descending order of structural fit:

    1. Primary navigation: Reserve this scarce space for durable categories that matter broadly to the business and to shoppers. A short campaign or narrow subcategory rarely belongs here.
    2. Parent categories: A broader department or collection is often the clearest route to an important child category. Make the child visible in the page’s category list or other useful navigation, rather than relying on filters alone.
    3. Closely related categories: Add a related-category module when the destination is a plausible alternative or next step. The relationship should remain understandable without an SEO explanation.
    4. Buying guides and editorial content: Link when the content discusses the product type or helps the reader choose it. This connects informational intent with an appropriate shopping destination.
    5. Recurring seasonal hubs: Use them to support stable seasonal categories while the relationship is useful. Do not let expired promotional pages become the category’s only meaningful route.

    Use anchor text that identifies the destination in ordinary language. The category name is usually clearer than a vague phrase such as “shop now” or an awkward string of keyword variations. Surrounding copy should explain why the destination is relevant; the link should feel like part of the shopping decision, not an SEO insertion.

    Keep the implementation crawlable and consistent with the site’s existing components. Test the final rendered page rather than approving a design mockup alone. Confirm that the link resolves to the intended URL, appears for users and crawlers, works on mobile, and does not point through an unnecessary redirect.

    Avoid solving every mismatch with global navigation or a sitewide footer. Broad placements multiply links quickly, but they ignore context and consume space across the entire store. A focused set of strong paths from parent, related, and editorial pages usually tells a more coherent story about the category’s role.

    Roll out changes as an allocation test

    Internal-link changes often coincide with promotions, inventory shifts, content launches, paid campaigns, and seasonal demand. Without a record of what changed, an improvement or decline becomes difficult to interpret.

    Create a change log with the target category, donor page, placement type, anchor text, implementation date, and business reason. Capture a baseline before release for:

    • the target’s click path and internal-link sources;
    • organic impressions, clicks, and landing-page visibility;
    • shopper clicks on the new link or module;
    • category entrances, product engagement, and conversion outcomes;
    • inventory availability and any promotions affecting demand.

    When possible, phase the work by category group instead of changing the whole taxonomy at once. Keep a comparable set of qualified categories unchanged during the same period. It will not create a perfect experiment, but it gives you a better reference point than a simple before-and-after comparison.

    Look for a coherent chain of evidence. The new paths should be live and used; the target should become easier to discover; search visibility should move in a useful direction; and the traffic should produce meaningful shopping behavior. A ranking movement without inventory, engagement, or commercial value is not enough to justify permanent prominence.

    Review allocation when the business changes. A category that deserved navigation space during a sustained growth phase may later belong under its parent. Likewise, a category with emerging demand and dependable inventory may outgrow its old position. Internal architecture should reflect current priorities without swinging with every short promotion.

    FAQ: ecommerce category internal linking decisions

    Should every category receive a similar number of internal links?

    No. Equal counts would treat strategic categories, utility filters, temporary collections, and minor subcategories as if they had the same role. Allocate links according to business importance, search opportunity, inventory, durability, and relevance.

    Should a buried priority category go into the main navigation?

    Only when it is durable, broadly useful, and important enough to justify scarce navigation space. A narrower category may be better supported through its parent, related collections, and relevant buying content. The right correction is the clearest useful path, not automatically the most global placement.

    Should filtered pages receive internal links?

    Most filter combinations should remain shopping tools rather than promoted landing pages. Support a filtered URL only when it represents distinct and sustained demand, carries adequate inventory, has a stable purpose, and deserves a defined place in the taxonomy.

    Can internal links fix an underperforming category?

    They can correct weak discovery and an architecture that understates the category’s importance. They cannot create search demand, replenish inventory, clarify a confused taxonomy, or make a weak landing page useful. Diagnose those constraints before treating link volume as the answer.

    Start with one qualified category that the business values but the site currently hides. Document the mismatch, add the smallest set of relevant paths that corrects it, and measure the entire journey from discovery to commercial outcome. That gives you a defensible model for the next category instead of another sitewide link rule.

    References


  • AI Search and Shopping Agent Visibility: A Practical System

    AI Search and Shopping Agent Visibility: A Practical System

    Your product appears in an AI answer on Monday, disappears on Tuesday, and returns through a different citation on Friday. That does not automatically mean your optimization worked, failed, and recovered. It means you are looking at a system that assembles answers dynamically rather than assigning one durable position.

    You need a visibility program built for that volatility. The goal is to increase the probability that your brand is found, understood, supported by credible evidence, and selected when an AI system moves from answering a question to helping someone choose a product.

    Replace the idea of one ranking with three layers of visibility

    A conventional ranking gives you a page, a query, and a position. An AI answer can vary its wording, cited URLs, recommended brands, and product shortlist from one run to the next. Treating one generated response as a ranking report will produce false alarms when you disappear and false confidence when you happen to appear.

    The volatility is large enough to affect how you interpret every test. When 10,000 keywords were run through Google AI Mode three times on the same day, the average URL overlap was only 9.2%. For 21.2% of the keywords, the three runs had no cited URLs in common. In another large test, Google AI Overview content changed in roughly 70% of checks, while only 54.5% of cited URLs overlapped between consecutive runs.

    Yet changing citations do not always mean that the underlying answer has changed. The semantic similarity of those AI Overviews remained at 0.95 even while their wording and evidence rotated. You can therefore lose a particular citation while the system continues to express the same category preference, recommendation criteria, or view of your brand.

    Measure three layers separately:

    • Answer visibility: Does the brand or product appear in the generated response, recommendation, shortlist, or comparison?
    • Evidence visibility: Which owned or third-party pages are cited, and what claims are those pages supporting?
    • Commerce readiness: Can a shopping agent determine what the product is, who it suits, which variant applies, and whether the commercial information is complete enough to support a decision?

    This distinction matters because the remedy depends on the layer. If your brand remains recommended but your URL stops being cited, you may have an evidence-distribution problem. If your pages are cited but your product never reaches the shortlist, your positioning or product fit may be unclear. If the product appears but the agent reports an incorrect price, variant, or use case, the problem is data consistency rather than general brand awareness.

    Shopping agents raise the stakes. Personal agents such as Muse and Instinct can find products, compare options, and make purchasing decisions for users. Your job is no longer finished when an AI system mentions the brand. The system must also be able to qualify the product against the buyer’s situation.

    Build a measurement system that survives volatile answers

    A stable monitoring hub tracks a shifting field of abstract answer panels and citation nodes connected by changing paths.

    Start with the questions that precede a real decision, not a collection of high-volume keywords. A useful prompt library represents the different jobs a buyer asks an assistant to perform:

    • Problem discovery: asking what kind of product solves a stated need.
    • Use-case qualification: looking for a product that fits a particular audience, environment, workflow, or constraint.
    • Comparison: weighing products or product types against explicit criteria.
    • Risk reduction: checking compatibility, limitations, policies, reliability, or suitability.
    • Purchase preparation: verifying variants, availability, price, delivery, returns, or another decision-critical fact.
    • Branded evaluation: asking whether your product is suitable and what alternatives should be considered.

    Write prompts in the buyer’s language and preserve the qualifiers that change the answer. “Best project-management software” and “project-management software for a small agency that needs client approvals” are not interchangeable questions. The second prompt gives the system criteria it can use to include or exclude a product.

    Run the same library on each AI platform you care about, but do not blend the results into one universal score. Google AI Overviews and AI Mode shared only 13.7% of their citations in one comparison. Platform-specific shifts can also be abrupt: Reddit’s average share of ChatGPT Search citations fell from 3.83% to 0.52% across the reported periods, an 86.4% decline, while the broader pattern was not uniform across AI systems.

    A blended average can hide exactly what you need to diagnose. Keep separate views for each platform, answer surface, market, and language you test. Aggregate them only after you have inspected the underlying results.

    Repetition is equally important. Published sampling guidance indicates that 60 to 100 runs of a prompt can produce meaningful visibility data. Another longitudinal approach recommends at least seven runs per prompt per day for brand-level estimates, assessed through rolling windows of two to four weeks. These are measurement benchmarks, not a claim that every team must immediately test at that scale. If your budget supports fewer observations, label the result as directional and avoid making budget or content decisions from a single response.

    Your dashboard should answer operational questions rather than merely count mentions:

    QuestionMetricWhat to recordLikely next action
    Are we present?Brand mention rateValid runs containing the brand divided by all valid runs for that prompt setInvestigate prompt clusters where competitors appear consistently and you do not
    Are products being considered?Product inclusion rateRuns in which an eligible product enters the shortlist or comparisonClarify audience fit, category language, and comparison attributes
    What supports the answer?Citation rate by domain and URLOwned and third-party pages cited for each claim or recommendationStrengthen missing evidence and pursue relevant independent coverage
    Is the answer accurate?Fact accuracy rateCorrect and incorrect statements about fit, specifications, terms, and availabilityResolve contradictions across pages, catalogs, feeds, and structured data
    Is the change persistent?Rolling visibility rangeRates and ranges over repeated runs, separated by platformAct on sustained movement rather than an isolated response

    Keep a changelog beside the data. Record platform and model updates, material website changes, catalog releases, content refreshes, and significant third-party coverage. The log will not prove causation, but it prevents the team from inventing an explanation after every rise or fall.

    Use a simple decision rule: one unusual answer is an observation; a repeated change within the same platform and prompt cluster is a pattern worth diagnosing. If the decline appears everywhere at once, inspect broad accessibility, brand evidence, and product-data issues. If it appears only for comparison prompts, look first at the criteria buyers use to distinguish products.

    Make every product answerable before expecting it to be selectable

    A generic product moves from organized attributes and evidence nodes through a transparent reasoning structure into a highlighted selection tray.

    A shopping agent cannot infer a reliable recommendation from a product name and a persuasive description alone. Early testing of personal agents points to three practical visibility requirements: usable product catalogs, accessible websites, and clear statements about who each product is for.

    Audit each commercially important product as a package of decision facts. The exact attributes will vary by category, but the agent should be able to resolve the following without reconciling conflicting pages:

    • Identity: a stable product name, canonical URL, model or SKU, brand, and an unambiguous relationship between the main product and its variants.
    • Audience fit: the user, situation, problem, or level of experience the product is designed for. State meaningful limitations when they affect suitability.
    • Comparison attributes: the specifications, capabilities, materials, dimensions, compatibility details, or service limits a buyer would use to compare alternatives in your category.
    • Commercial terms: current price and currency, availability, variant-level differences, applicable delivery information, returns, and warranty terms where relevant.
    • Evidence: explanations, documentation, or independent validation that supports important claims instead of merely repeating them.
    • Consistency: agreement among the visible product page, catalog or feed, structured data, policy pages, and any regional or variant pages.

    “Who it is for” deserves its own content block. Avoid empty labels such as “for everyone” or “perfect for professionals.” Give the agent usable selection criteria: the problem solved, the expected environment, required compatibility, relevant experience level, and conditions that would make another option more suitable. Clear exclusions can improve recommendation quality because they reduce the chance that your product is matched to the wrong request.

    Use Product and Offer structured data as a consistency layer, not as a magic entry ticket. Markup should express facts that a visitor can also verify on the page. If the visible page says one price, the catalog says another, and the structured data carries an expired offer, adding more schema will multiply ambiguity rather than remove it.

    Variant handling needs particular care. A parent product page may describe the range, but decision-critical facts should remain attributable to the correct size, configuration, color, region, or service tier. An agent comparing two variants should not have to guess which price or specification belongs to which option.

    Test accessibility from the agent’s point of view. Open the page in a clean session. Confirm that the product identity, fit, principal attributes, and commercial terms are available without signing in, accepting an unnecessary location flow, opening an image, or relying on an interaction that hides the only copy of a critical fact. Then compare the rendered page with the catalog and structured data field by field.

    Finally, test a decision sequence rather than one branded prompt. Ask an assistant to identify products for a constrained use case, compare the candidates, explain which user each candidate suits, and verify the facts needed for a decision. Record where your product disappears and which unresolved criterion caused the exclusion. That point is a more useful optimization target than the wording of the final answer.

    Publish and earn evidence that AI systems can resample

    Once a product is technically legible, it still needs current evidence. AI-cited URLs were 25.7% fresher on average than conventional organic results in one large comparison: cited pages averaged 1,064 days old, versus 1,432 days for organic results. This does not mean that changing a date will improve visibility. It means the information environment being sampled by AI systems tends to include fresher material.

    Refresh a page only when you can make it more useful. Add new product facts, answer newly important buyer questions, update obsolete comparisons, correct policy details, incorporate original data, or explain a material change. Keep the URL stable when the underlying resource remains the same, show a meaningful update date, and remove contradictions left by earlier versions.

    Owned content is necessary but insufficient. In one citation analysis, owned media accounted for 13.7% of AI citations while earned media accounted for 84%. Journalism represented 27%, and paid content represented only 0.3%. These labels should not be treated as a simple exclusive pie chart, but the practical signal is clear: visibility often depends on credible pages you do not control.

    Build an evidence map around the claims that determine selection. For each important prompt cluster, list the claims an assistant would need to justify: category membership, audience fit, distinctive capability, compatibility, comparative strength, limitation, and commercial availability. Then mark where each claim is supported:

    • on a canonical owned page;
    • in your product catalog and structured data;
    • in independent reporting, reviews, comparisons, or other third-party material;
    • nowhere reliable enough to support a recommendation.

    The empty cells are your publishing and public-relations brief. Create original material where you control the underlying evidence. Seek independent coverage where an outside assessment would carry more value. Do not treat a press release as a durable substitute for either one; press-release citation share proved unstable and declined over the reported period, largely because ChatGPT cited releases less often.

    Prioritize third-party coverage that contributes information of its own. A useful comparison, test, interview, dataset, or category explanation gives an AI system a reason to retrieve the page beyond the presence of your brand name. Repetition across low-value placements may expand the number of mentions without supplying better evidence for a recommendation.

    Connect publishing back to measurement. When a prompt cluster lacks visibility, identify whether the missing input is product data, owned explanation, or independent evidence. Make the smallest substantive change that addresses that gap, record it in the changelog, and assess it across repeated runs. That gives you a testable operating cycle instead of a stream of unrelated content.

    Key takeaways for your next visibility cycle

    • Treat an AI response as one sample, not a permanent ranking. Report visibility as a rate and range across repeated runs.
    • Separate brand inclusion, cited evidence, and commerce readiness. Each layer has a different failure mode and remedy.
    • Build prompts around discovery, qualification, comparison, risk reduction, and purchase preparation rather than isolated keywords.
    • Measure each AI platform separately. A blended score can conceal a platform-specific gain, loss, or citation shift.
    • Make product identity, audience fit, comparison attributes, variants, and commercial terms explicit and consistent across the page, catalog, feed, and structured data.
    • Refresh important pages with substantive information, not a changed date, and cultivate independent evidence for claims that influence selection.

    Begin with one commercially important product family and the prompts closest to a decision. Establish a repeated baseline, inspect where the product falls out of the journey, and fix that exact gap. Once the page, catalog, schema, and outside evidence tell the same clear story, extend the system to the next product family.

    References


  • ChatGPT Virtual Try-On: An Ecommerce Optimization Playbook

    ChatGPT Virtual Try-On: An Ecommerce Optimization Playbook

    You may be asking a deceptively simple question: what should your ecommerce team change now that a shopper can preview a product inside ChatGPT? The answer isn’t to add AI shopping phrases to every page. Virtual try-on moves part of product evaluation upstream, before the shopper reaches your store.

    Your job is to make each product understandable during discovery, visually recognizable during evaluation, and easy to buy when the shopper finally reaches the product page. That requires coordinated work across imagery, catalog data, structured data, fit guidance, landing-page UX, and measurement.

    Virtual try-on changes where product evaluation happens

    On eligible clothing and accessory listings, ChatGPT can display a Try on button that lets a shopper take or upload a selfie. ChatGPT Images then generates a visualization of that person wearing the item. A product doesn’t have to originate in a ChatGPT recommendation: the shopper can also upload an image or screenshot of something found elsewhere and request a virtual try-on.

    That creates a shopping path that may look like this:

    1. The shopper describes the clothing or accessory they want.
    2. ChatGPT surfaces products that appear relevant.
    3. The shopper visualizes a candidate product on their own image.
    4. They compare it with other possibilities.
    5. They save promising items or visit a merchant to inspect the offer and buy.

    Product discovery and visual evaluation can therefore happen within the same conversation. ChatGPT also lets shoppers save products to Favorites, organize them into Library folders, and return to them on mobile or the web. A recommendation is no longer necessarily followed by an immediate click. The shopper may build a shortlist first and arrive at your store later with a narrower set of questions.

    For an ecommerce SEO or GEO team, that changes the optimization target. You need to support three decisions:

    • Recognition: Can the product be distinguished from superficially similar items?
    • Evaluation: Can the shopper understand its color, cut, pattern, material, and available variations?
    • Completion: Can your product page resolve size, price, availability, delivery, and return questions without introducing contradictions?

    This doesn’t make the product page less important. It gives the page a more demanding role. The visitor may already like the apparent look; the merchant must now establish exactly what is being sold and reduce the remaining purchase risk.

    The screenshot workflow matters just as much as native product discovery. A shopper may encounter your item in search, on a marketplace, in a social post, or on another page before bringing its image into ChatGPT. Your visual assets need to remain recognizable when separated from their original context.

    Build a coherent product record, not an AI optimization gimmick

    An unbranded sneaker is surrounded by connected product images, color swatches, size cells, packaging, and a product card.

    There is no established Try on optimization formula, required image dimension, or special schema property that guarantees eligibility. Treat promises of guaranteed inclusion through a single field with skepticism. The practical goal is coherence across the product image, visible copy, variation selector, commerce feed, and structured data.

    Use images that still make sense outside the product page

    Start with the main image because it is the most likely visual shorthand for the product. It should make the item easy to identify without forcing a system or shopper to infer which object is for sale.

    • Show the complete garment or accessory clearly in at least one image.
    • Keep the product visually distinct from props, backgrounds, and neighboring items.
    • Use the correct image for each color or pattern variation.
    • Provide additional views when the front image hides important construction, shape, fastening, or pattern details.
    • Keep image treatment consistent enough that a shopper can recognize the same item across a listing, a screenshot, and the product page.
    • Avoid putting essential product facts only inside image text. Those facts also belong in visible HTML.
    • Write useful alternative text for accessibility and page comprehension, but don’t claim that alt text controls a virtual try-on rendering.

    Run a simple crop test. View the product image without its title, price, or surrounding page. Ask whether a person could identify the item type, dominant color, pattern, and intended variation. If the answer depends on the missing copy, the image is doing too little. If several products compete for attention, it is doing too much.

    Don’t replace accurate catalog photography with speculative AI composites merely to appear AI-ready. A visualization system needs a dependable representation of the product. Your controlled assets should establish ground truth, while the generated try-on remains a separate, personalized interpretation.

    Make attributes explicit and consistent

    Product copy should identify the attributes that distinguish the item. A poetic collection name may support branding, but it shouldn’t carry the entire descriptive burden. Pair it with plain product language that states what the shopper is looking at.

    • Use a stable product name, brand, and product type.
    • Name the actual color as well as any branded color name.
    • Describe the material or fabric without making unsupported performance claims.
    • State the silhouette, length, pattern, closure, and other decision-relevant features when they apply.
    • Map every displayed image to the correct selectable variation.
    • Keep price, currency, availability, and condition aligned wherever those fields appear.
    • Use valid product identifiers consistently. Never invent an SKU, GTIN, or other identifier to fill an empty field.
    • Provide measurements and size information in accessible page content rather than relying on an image alone.

    Structured data should mirror that visible record. Product and Offer JSON-LD can express product and commercial facts in a machine-readable form, but markup is not a substitute for accurate page content and isn’t evidence of virtual try-on eligibility. If the page shows one price while the Offer markup publishes another, the problem isn’t a missing AI tactic; it is a conflicting product record.

    Check variation handling closely. The selected color, image, SKU, availability, price, and structured data should refer to the same offer. If your implementation updates some of those fields dynamically, verify the rendered state rather than reviewing only the page template or source code. A technically valid block of JSON-LD can still describe the wrong variant.

    Audit the complete product path

    Use this sequence on representative clothing and accessory templates:

    1. Open a live product and select each meaningful variation.
    2. Compare the selected option with the main image, gallery, visible name, price, stock state, and product identifier.
    3. Inspect the rendered Product and Offer data for the same variation.
    4. Check the size guide, measurements, material details, delivery information, and return policy.
    5. Capture the main product image as a shopper might encounter it elsewhere and verify that the product remains recognizable.
    6. Resolve contradictions before adding more copy or markup. Consistency is the prerequisite, not the finishing touch.

    This audit is useful beyond ChatGPT. It removes ambiguity from the catalog record that your own customers, feeds, analytics, search systems, and other shopping interfaces must interpret.

    Separate appearance visualization from fit, then strengthen the handoff

    A shopper previews a coat on a virtual avatar beside fit tools, size samples, and an abstract checkout screen.

    The most important boundary is also the easiest one to blur: virtual try-on is a visualization, not a fitting room. The generated result may not represent the shopper or product exactly and doesn’t guarantee size or fit. Merchant measurements, product details, and return policies remain part of the buying decision.

    Think of the preview and product page as answering different questions:

    Shopper questionBest answer surfaceWhat the answer must communicate
    How might this style look on me?Virtual try-on visualizationA directional visual impression, not a promise of exact appearance or fit
    Which size should I order?Merchant size guide and measurementsClear measurement definitions, units, garment dimensions, and relevant sizing notes
    What exactly am I buying?Product page and variation selectorThe selected color, material, construction, images, price, and availability
    What happens if it isn’t right?Delivery and return informationApplicable conditions, timing, process, and customer costs

    Your size guidance needs enough context to be usable. Distinguish body measurements from garment measurements. Name the measurement points and units. Explain relevant stretch, cut, or layering considerations without pretending they can predict an individual’s fit. If sizing differs by product line or market, put the correct guide on the affected product rather than sending everyone to a generic chart.

    The landing page should preserve continuity with what the shopper evaluated. The same variation should be easy to recognize, and the page should expose the remaining decision information without making the visitor hunt for it.

    • Keep the product name and selected variation visible near the main image.
    • Show current price and availability for that variation.
    • Place the size selector close to the relevant size guide.
    • Make material and care information easy to scan.
    • Present delivery and return terms before the shopper commits to checkout.
    • Explain unavailable variations honestly rather than silently switching the selection.
    • Keep mobile layouts usable because the shopping features are available on both mobile and web.

    Favorites add another handoff consideration. A shopper may save an item, compare it with alternatives, and return after the original discovery session. Stable product URLs, persistent identifiers, current inventory, and clear replacement behavior matter more than a landing experience built only for an immediate click.

    If you describe AI visualization on a page you control, keep the claim narrow. Plain language such as “The preview is a visual approximation; check the product measurements and return terms before ordering” sets the right expectation. Don’t call a generated image proof of fit, exact drape, precise color reproduction, or guaranteed appearance.

    Measure discovery, merchant handoff, and post-purchase outcomes

    Referral traffic alone will not describe the full effect. A shopper can upload a product screenshot found elsewhere, evaluate it in ChatGPT, save it, and return by another route. Some influence will therefore be invisible to your analytics or appear under a later source.

    Observe visibility without treating one answer as a ranking report

    Create a repeatable set of prompts based on real customer language. Include product type, material, color, occasion, style, and other attributes your catalog genuinely supports. Record whether your products appear, whether the correct variation is represented, whether the cited destination resolves correctly, and whether a Try on option is shown when relevant.

    Use those checks diagnostically. They can expose ambiguous naming, weak imagery, broken destinations, and inconsistent variants. They do not establish universal market share, a permanent ranking, or the cause of a recommendation. Avoid turning a favorable answer from one session into a performance claim.

    Instrument the merchant handoff

    Preserve raw referrer information where your analytics and consent setup permit it, and group identifiable ChatGPT visits without overwriting the underlying source. Then evaluate the onsite sequence rather than counting sessions alone.

    • Which products receive identifiable AI referral visits?
    • Does the landing URL resolve to the intended product and variation?
    • Do those visitors use the gallery, variation selector, or size guide?
    • Where do they leave the product and checkout funnels?
    • Do they add the evaluated item to the cart, or switch to another variation or product?
    • Are analytics events firing consistently across mobile and desktop?

    A high click count with frequent variant switching may indicate that the upstream image or product description set the wrong expectation. Strong product-page engagement with weak size selection may point to incomplete fit guidance. Treat these as diagnostic signals to investigate, not automatic proof of causation.

    Connect the experiment to business outcomes

    Virtual try-on is intended to help a shopper evaluate a product, so the useful outcomes sit deeper than impressions. Track completed purchases, cancellations, exchanges, returns, and available reason codes for the affected products. A generated preview that increases curiosity but creates a mismatch at delivery is not an unqualified success.

    Use a controlled improvement cycle:

    1. Save a baseline for the selected product group, including its images, visible attributes, structured data, funnel behavior, and return outcomes.
    2. Fix one interpretable layer, such as variation-image mapping or measurement content.
    3. Repeat the same visibility checks and review the same onsite events.
    4. Annotate concurrent changes in price, promotion, inventory, seasonality, and delivery terms.
    5. Read the result as directional unless the design actually isolates the changed variable.

    Don’t label every post-change sale as AI-driven revenue. Report what you can observe directly, separate identifiable referrals from inferred influence, and name the blind spots. Favorites activity inside ChatGPT and screenshot-based exploration are not merchant-side analytics events.

    Key takeaways

    • ChatGPT virtual try-on can combine product discovery, selfie-based visualization, comparison, and shortlisting before a merchant visit.
    • A shopper can upload a product image found elsewhere, so clear and recognizable assets matter beyond native ChatGPT listings.
    • There is no basis for promising eligibility from one schema field, keyword, image treatment, or feed attribute.
    • Product images, visible content, variations, commerce feeds, and Product and Offer structured data should describe the same item and offer.
    • Virtual try-on visualizes a possible look; merchant measurements, size guidance, product facts, and return terms must handle fit and purchase risk.
    • Measure visibility, onsite behavior, purchases, and returns while acknowledging that screenshot and Favorites activity may leave no direct referral trail.

    Start with a representative clothing or accessory template and follow one product from its standalone image through variant selection, JSON-LD, size guidance, return information, and analytics events. Fix every contradiction you find before scaling the audit across the catalog. That gives you a durable commerce foundation whether the next shopper discovers the product through ChatGPT, another AI interface, a conventional search result, or a saved screenshot.

    References

  • Ecommerce Advertising Readiness: When and Where to Scale

    Ecommerce Advertising Readiness: When and Where to Scale

    Your campaigns can be approved and spending while your store is still unprepared to scale. The weakness usually appears after demand rises: a feed rejects sale prices, a bestseller runs out, attribution has not caught up, or a promotion turns an apparently healthy return on ad spend into a loss.

    Advertising readiness means knowing what you can profitably sell, trusting the data used to optimize it, and choosing a channel that matches the customer’s current level of intent. Work through those decisions in that order and you can expand without asking automation to repair a broken funnel.

    Key takeaways

    • Do not scale traffic until purchase tracking, product availability, pricing, and contribution margin are reliable.
    • Use Search and Shopping to capture existing demand. Use YouTube to create demand when the lower funnel already converts.
    • Performance Max can distribute ads onto YouTube, but distribution is not a YouTube strategy. You still need deliberate creative, audience logic, measurement, and testing.
    • Segment products by margin, promotion, and stock position so one blended ROAS target does not treat fundamentally different products as equals.
    • Make campaign, feed, approval, and payment changes before a peak period. During the event, monitor exceptions and respect conversion lag instead of repeatedly resetting the system.

    Pass the readiness gate before choosing another channel

    A new channel adds traffic. It does not fix weak economics, inaccurate measurement, or a checkout that already loses qualified shoppers. In fact, sending cold YouTube traffic into a funnel where Search and Shopping traffic does not convert can simply accelerate the existing loss.

    Before increasing spend, give the store a clear pass or fail on four gates:

    1. Lower-funnel performance: Search and Shopping can turn relevant, high-intent visits into completed purchases without unexplained breaks in the journey.
    2. Measurement: transactions, order values, currency, and customer signals reach the advertising platforms accurately enough to guide bidding.
    3. Economics: you know the contribution available after discounts and variable order costs, not just revenue and platform-reported ROAS.
    4. Operations: the feed, stock data, payment methods, landing pages, creative approvals, and alerting process can withstand a sudden increase in demand.

    A failure on any gate determines your next investment. A tracking failure calls for measurement work. A stock or price failure calls for feed operations. A negative contribution margin calls for a commercial decision. None of those problems should be handed to a bidding algorithm as if they were targeting problems.

    Verify the data that bidding will learn from

    Run a test order from the storefront through the complete measurement path. Confirm that the purchase appears once, carries the correct value and currency, and can be reconciled with the order record. Then inspect the supporting stack: server-side measurement where appropriate, Consent Mode, Enhanced Conversions, and offline conversion measurement if meaningful outcomes happen after the online event. These are among the data checks that should be completed before a high-demand period, not during it.

    First-party audiences also need structure. An undifferentiated customer upload tells the platform that every buyer has equal value. Segment usable lists by factors such as average order value and customer lifetime value, then keep acquisition and retention decisions distinct. Apply the same discipline to the audience data used across Google Ads and Meta.

    Finally, document conversion lag. If purchases commonly arrive several days after an ad interaction, the newest dates will always look artificially weak. A reporting delay is not a campaign collapse, and reacting to it every morning can turn normal lag into genuine instability.

    Set a profit boundary before approving a discount

    Revenue-based ROAS can hide whether an order creates value. Start with a product or product-group calculation:

    Net selling price – product cost – variable fulfillment, payment, and expected return costs = contribution before advertising.

    That contribution is the amount available to pay for acquisition and leave profit behind. If you lower the selling price, recalculate it before setting the promotion live. A 15% discount removes part of the margin at the same time acquisition costs may rise. Matching a competitor’s discount without doing this calculation can produce more orders and less profit.

    To judge the promotion, divide the baseline contribution you want to preserve by the new contribution per order. The result is the number of discounted orders required before advertising costs are considered. Then add the expected acquisition cost. If the required volume is implausible, change the offer, limit it to suitable products, or accept that the promotion has a strategic cost rather than pretending it is profitable.

    Give each channel one clear job

    Channel choice becomes easier when you start with the customer’s state. Search and Shopping are pull channels: the shopper expresses intent and the advertiser competes to answer it. YouTube is a push channel: the advertiser interrupts someone who was doing something else and must create enough interest to earn a later action. Those conditions require different creative, timelines, skills, and measurement.

    Channel or campaign typeCustomer statePrimary jobWhat you must control
    Search and ShoppingAlready looking for a product, category, or solutionCapture existing demandQuery or product relevance, offer quality, feed accuracy, bids, margin, and landing-page conversion
    YouTubeNot actively shopping at that momentCreate interest, demonstrate a product, and generate future demandHook, argument, demonstration, proof, audience, creative refresh, and a longer evaluation window
    Performance MaxVaries because inventory spans multiple Google surfacesAllocate spend across eligible inventory toward the configured conversion goalFeed quality, conversion inputs, asset quality, product segmentation, budget, targets, and interpretation of blended reporting

    This distinction matters because Performance Max may already be buying YouTube impressions for your store. It can reuse uploaded assets or, when no video is supplied, assemble video from product images, transitions, and text. That gives the campaign something to serve, but it does not supply positioning, persuasion, creative sequencing, or a channel-specific learning plan.

    Treat Performance Max as a distribution system, not proof that you have a YouTube strategy. A blended conversion total cannot tell you whether upper-funnel impressions created new demand, harvested demand that already existed, or received credit for a purchase that would have happened anyway. Do not accept that number uncritically, but do not make the opposite mistake of testing YouTube once, grading it like Search, and declaring the channel ineffective.

    Use a simple channel decision sequence

    1. If relevant Search and Shopping traffic does not convert, repair the offer, product pages, checkout, feed, or measurement before adding cold reach.
    2. If profitable search demand is still available, capture it before paying to manufacture more awareness.
    3. If existing demand is constrained, or the product is new and lacks search volume, assess whether YouTube can create demand.
    4. If the goal is product discovery, brand awareness that can drive later searches, a time-limited seasonal promotion, or a new-product launch, give YouTube a defined budget and its own measurement plan.
    5. If you cannot produce and refresh persuasive video, postpone the channel rather than allowing generic automated assets to stand in for strategy.

    Build YouTube creative as a persuasion sequence

    A YouTube viewer did not ask to see your product. The creative therefore has to do more than show it. Build each concept around a complete sequence:

    1. Hook: earn attention in the first five seconds.
    2. Problem: make the relevant frustration, desire, or missed opportunity recognizable.
    3. Mechanism: explain how the product addresses that problem.
    4. Demonstration: show the product doing the work instead of relying on a claim alone.
    5. Proof: give the viewer a reason to believe the result.
    6. Call to action: make the next step explicit and consistent with the landing page.

    Creative is the operating cost of this channel. Fatigue arrives faster than it does in intent-led campaigns, so two or three occasional videos are not a substantial testing program. For a serious effort, plan the people, production process, and approval capacity needed to test 20 or 30 videos per month. If that volume is beyond reach, narrow the test deliberately rather than spreading a small set of assets across too many audiences and offers.

    Define success before launch. Direct sales still matter, but the feedback loop is longer and attribution is less clean than it is for Search. Separate YouTube’s budget and evaluation from the assumptions used for demand capture, account for the store’s observed conversion lag, and watch whether the channel is creating the future demand it was assigned to create. Changing the success definition after seeing the result makes the test impossible to interpret.

    Make feed and margin structure govern spend

    An overhead arrangement of unbranded products, packaging, coins, a calculator, and a tablet with abstract product tiles.

    For an ecommerce advertiser, Google Merchant Center is not an administrative afterthought. Its product feed is a core input to Shopping and Performance Max. When availability, price, or identifiers are wrong, automation makes decisions from a distorted catalog.

    Configure the feed around the decisions your team will need to make under pressure:

    • Automate promotional prices. Populate sale_price and sale_price_effective_date with exact start and end timestamps. This allows scheduled price changes and reduces the risk of a mismatch between the website and feed when a sale begins.
    • Protect price-annotation eligibility. If strikethrough pricing is part of the plan, the base price must have been active for at least 30 days within the previous 200 nonconsecutive days.
    • Increase freshness during peak windows. Raise feed synchronization to three or four times per day when prices and inventory are changing quickly.
    • Stop advertising unavailable inventory. Use automated rules or feed scripts to flag and pause out-of-stock SKUs instead of buying visits to products that cannot be ordered.
    • Add commercial labels. Use Custom Label 0 through Custom Label 4 to represent attributes such as actual margin, promotional status, and stock position.

    Do not wait for the promotion to discover whether the feed and checkout disagree. Schedule a sale-price test, verify the timestamps, inspect the landing page and cart, and confirm that a product returns to its normal price after the test window. A valid feed submission is useful, but the shopper experiences the complete path.

    Translate labels into campaign decisions

    Labels become valuable when they change how you allocate spend. A high-margin, well-stocked bestseller can support a different target and budget from a low-margin item with limited inventory. Blending the two under one target ROAS encourages the platform to optimize revenue while concealing the difference in profit.

    • High margin and strong stock: make these products eligible for more assertive acquisition, subject to the contribution boundary.
    • Low margin: use a more defensive target or restrict promotion unless the product has a deliberate strategic role.
    • Promotional: isolate the discounted economics so ordinary-price performance does not subsidize an unprofitable event in the reporting.
    • Low stock: reduce exposure before availability becomes a customer and feed problem.
    • Out of stock: pause promptly and restore eligibility only after the feed and storefront agree.

    Keep a working record for each important SKU or product group: normal price, promotional price, product cost, variable order cost, contribution before advertising, stock position, and active promotion. That record gives the media team a commercial map. Without it, campaign structure is merely technical organization.

    Prepare the peak-period operation before demand arrives

    Workers pack unbranded orders at organized stations in a well-stocked ecommerce fulfillment area.

    Peak-period readiness is mostly timing. A change that is sensible in an ordinary month can be reckless immediately before Black Friday if it triggers a learning period, waits for approval, or alters the data used by bidding. Depending on account size and market, Q4 preparation may need to begin in August or September.

    Sequence the work around risk

    1. Months before demand peaks: validate measurement, segment first-party audiences, repair the lower funnel, calculate promotion economics, and begin warming audiences where demand creation is part of the plan.
    2. Well before the event: launch new campaign structures and bidding strategies early enough to move beyond their initial learning behavior. Upload creative with time for review instead of risking a pending approval on the day before the sale.
    3. Before prices change: test sale attributes and effective dates, confirm stock rules, set feed schedules, fund the advertising account, and add a backup payment method.
    4. During Cyber Week: inspect Merchant Center Diagnostics early each morning, prioritize disapproved bestsellers, and maintain the higher feed-sync frequency.
    5. After each major sales window: wait for the known conversion lag before treating recent ROAS as complete, then compare product-level contribution with the target established before launch.

    Decide in advance how much control you want over rising CPCs and CPMs, including whether a portfolio bid cap belongs in the plan or whether the bidding system will operate without one. The important point is to make that choice from economics and risk tolerance before the auction becomes unusually competitive.

    Monitor exceptions instead of micromanaging campaigns

    Create alerts for payment failures, material CPC changes, rapid budget consumption, feed disapprovals, and inventory problems. Then write the response beside each alert. An alert without a response rule merely creates anxiety; an alert tied to a check and an owner shortens the time to a useful decision.

    • If a bestseller is disapproved, inspect price, availability, and landing-page consistency before changing a bid.
    • If a campaign consumes its daily budget unusually early, check traffic quality, CPC movement, and the promotion schedule before reallocating money.
    • If reported ROAS falls on the newest dates, compare that window with the account’s normal conversion lag before changing targets.
    • If stock becomes scarce, use the stock label or automated rule to reduce exposure rather than continuing to sell demand you cannot fulfill.
    • If a payment method fails, switch to the verified backup before delivery stops during the most valuable traffic window.

    Frequent intervention can be as damaging as neglect. When conversion lag is several days, daily changes based on incomplete purchases make each decision depend on a partial result. Reserve emergency changes for genuine operational failures or clearly breached financial boundaries. Let ordinary performance accumulate enough evidence to judge.

    Your next move is not automatically another campaign. Choose one upcoming promotion or product launch and score it against the four readiness gates. Fix the first failed gate. When all four pass, assign Search, Shopping, Performance Max, or YouTube a precise job, budget, success measure, and stopping condition. That is the point at which scaling becomes a controlled decision rather than a bet.

    References

  • How to Make Products Visible to AI Personal Shoppers

    How to Make Products Visible to AI Personal Shoppers

    Your product can rank in conventional search and still disappear when a shopper asks an AI assistant what to buy. The missing piece is usually not another generic category paragraph. It is making the product easy to identify, test against constraints, and defend in a recommendation.

    AI personal shoppers can shape which products make the shortlist. That changes your visibility target. You are no longer optimizing only for a page visit; you are helping a system decide whether your product is eligible, relevant, credible, and safe to recommend for a particular request.

    AI shopping visibility is a three-gate problem

    There is no universal ranking formula for AI shopping. Assistants use different catalogs, retrieval systems, merchant feeds, pages, and models. Their answers can also change as availability, prices, prompts, and underlying systems change. A practical three-gate model is more useful than pretending every platform works the same way.

    1. Discovery: Can the assistant find and identify the correct product or variant?
    2. Qualification: Can it determine whether the product satisfies the shopper’s stated constraints?
    3. Selection: Is there enough relevant evidence to choose the product and explain that choice?

    A product has to pass the gates in that order. Better promotional copy cannot rescue a product the system cannot identify. Strong reviews cannot compensate for an unspecified compatibility requirement. Complete structured data does not prove a broad superiority claim.

    This sequence gives you a diagnostic method. If the product never appears, inspect discovery before rewriting the sales copy. If it appears for broad prompts but disappears when a constraint is added, inspect the relevant attribute. If it remains eligible but another product receives the recommendation, inspect comparative relevance and supporting evidence.

    The important distinction is between being mentioned and being recommendable. A system may know that your product exists while lacking the facts needed to place it in a defensible shortlist.

    Build one canonical product truth

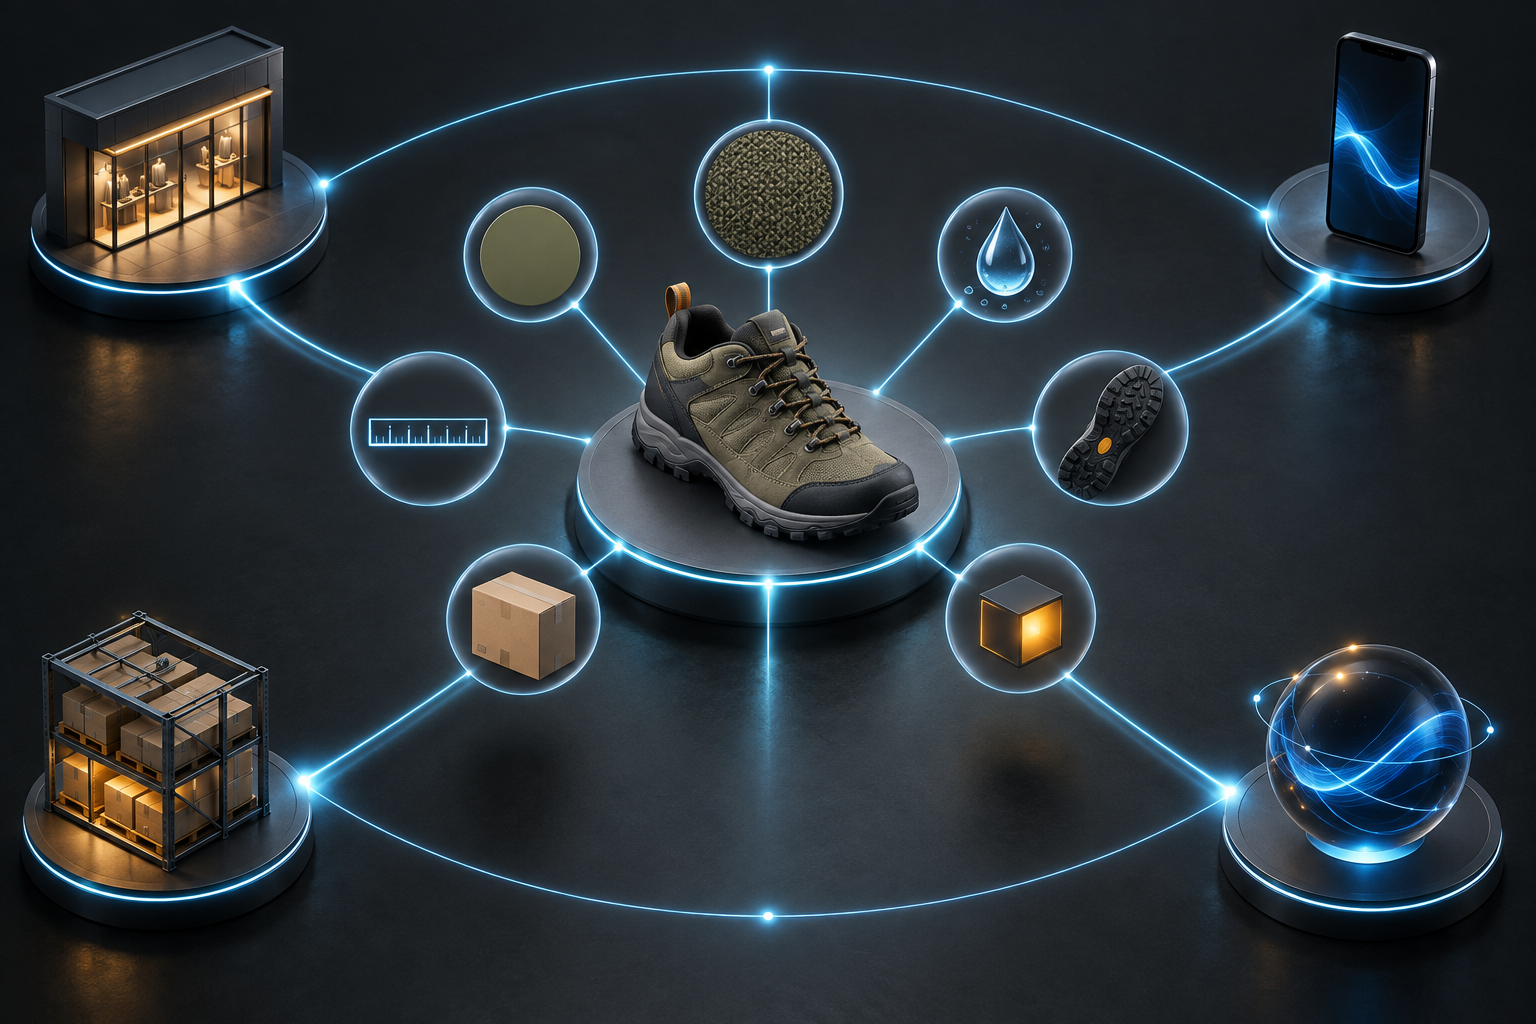
    A hiking shoe on a central platform sends the same set of visual product attributes to a storefront, phone, warehouse shelf, and AI orb.

    Start with an internal product record, not a block of marketing copy. This record should be the authoritative source for the product page, structured data, merchant feeds, marketplace listings, comparison pages, and support content. When those surfaces disagree, an assistant has to choose among conflicting claims or avoid repeating them.

    For each product and meaningful variant, define the following fields explicitly:

    • Identity: brand, product name, model, assigned SKU or GTIN, canonical URL, and product category.
    • Variant: color, size, capacity, material, pack quantity, configuration, and the relationship to the parent product.
    • Eligibility attributes: dimensions, weight, compatibility, intended use, required accessories, included components, operating conditions, and other category-specific constraints.
    • Commercial facts: price, currency, condition, availability, fulfillment terms, returns, and warranty terms.
    • Evidence: certifications, documented test conditions, review data, manuals, specifications, and the exact scope of each claim.

    Do not populate a field because competitors use it or because a schema validator permits it. An unknown value should remain unknown until the business can verify it. A precise false claim is worse than an honest omission because the false claim can be repeated in a recommendation, create a poor purchase, and undermine trust in the rest of your data.

    Keep the visible page, schema, and feeds aligned

    Product structured data should encode facts that a shopper can also verify on the page. Use Product markup to identify the item and its attributes. Use Offer data only for an offer that actually exists. Add rating or review properties only when the corresponding information is genuine, visible, and attached to the correct product or variant.

    JSON-LD does not create product truth. It translates product truth into a machine-readable form. If the page says one material, the markup says another, and the feed omits the field, adding more schema will multiply the ambiguity rather than fix it.

    Variant handling deserves particular attention. A family page may describe several configurations, but price, dimensions, availability, ratings, and compatibility can belong to only one of them. Give meaningful variants stable identities and make the selected variant unambiguous in the page content, URL behavior, structured data, and feed.

    Separate durable facts from fast-changing facts

    Product data fails at different speeds. Model identity, dimensions, materials, compatibility, and included components are usually durable. Price, availability, promotions, delivery estimates, and review aggregates can change much faster.

    Give each fast-changing field an owner, a system of record, and a refresh trigger. Avoid embedding volatile values in editorial prose unless that prose is updated from the same source. A stale promotional page and a current product feed can leave an assistant with two plausible answers and no reliable way to reconcile them.

    Match shopper constraints and support every important claim

    Traditional product copy often begins with a head keyword and expands into benefits. AI shopping requests are more likely to combine a job, a hard constraint, and a preference: a product for a particular use, compatible with something the shopper already owns, within a budget, and with a preferred trade-off.

    Create a prompt set from the decisions people make, not just the phrases with the highest search volume. Include several distinct request types:

    • Job prompts: What is the shopper trying to accomplish?
    • Constraint prompts: What would make a product ineligible, such as size, compatibility, material, price, or availability?
    • Trade-off prompts: Which quality matters more when no option maximizes everything?
    • Comparison prompts: Which alternatives are genuinely close enough to compare?
    • Risk prompts: What must the shopper verify before buying?

    Then map every consequential question to a field and a piece of evidence. The map exposes a common failure: the marketing team believes a benefit is obvious, but the product page never supplies the fact an assistant would need to infer it safely.

    Shopper questionMachine-readable answerHuman-verifiable support
    Will it fit?Dimensions, weight, capacity, or supported size rangeSpecification table, diagram, or installation instructions
    Will it work with what I own?Compatible models, interfaces, versions, or required accessoriesCompatibility page, manual, or clearly scoped support content
    Can I buy it under my stated conditions?Current price, currency, condition, availability, and offer detailsVisible offer and fulfillment information
    Is it suitable for this use?Intended use and relevant product attributesUse-case explanation tied to specifications rather than slogans
    Can I trust this claim?Named evidence and its scopeCertification details, documented method, policy, or attributable review data

    State who the product is and is not for

    A useful product page helps an assistant eliminate the wrong matches. State the primary use, the buyer or environment it suits, the constraints it satisfies, and any condition that would make another option more appropriate.

    This does not weaken the offer. A clear limitation can make the positive recommendation more credible. If a product requires an adapter, has a fixed dimension, excludes a particular model, or is designed for one usage pattern rather than another, say so close to the relevant benefit. Hiding the qualifier may generate more initial interest, but it gives an assistant less reason to trust or repeat the claim.

    Comparison content should use decision criteria rather than a list of adjectives. Explain which product fits which condition and why. Avoid declaring an item the best without naming the use case, comparison set, and evidence. An unqualified superlative is difficult to defend and easy for a recommendation system to ignore.

    Maintain a claim-to-evidence ledger

    For every claim that could change a purchase decision, keep an internal ledger containing the claim, its exact qualifier, the supporting evidence, the page where that evidence is visible, the responsible owner, and the event that should trigger a review.

    The qualifier matters. A certification may apply to one variant, a test may use specific conditions, and a warranty may differ by market. Preserve that scope everywhere the claim appears. Do not turn narrow evidence into a product-wide promise.

    Customer reviews can help describe recurring strengths and limitations, but keep review data attached to the product or variant it evaluates. Combining materially different variants may produce a stronger aggregate while giving the assistant a less accurate picture of the item in front of the shopper.

    Support pages, manuals, compatibility resources, return policies, and comparison pages should link back to the canonical product and use the same names and identifiers. That creates a coherent evidence trail instead of a set of disconnected documents with slightly different terminology.

    Audit the complete path from prompt to recommendation

    A shopper request travels through product, evidence, inventory, checkout, and delivery checkpoints before reaching an unbranded product shortlist.

    Do not reduce AI shopping visibility to a rank check. You need to see where the product exits the decision process and whether the answer is factually correct when it does appear.

    1. Choose eligible prompts. Test requests for which the product could honestly be a suitable answer. Irrelevant prompts distort the score and tempt teams to broaden claims beyond the product’s real fit.
    2. Record a baseline. Save the exact prompt, assistant, date, market or locale, response, recommended products, stated reasons, and any surfaced links.
    3. Label the outcome. Distinguish absence, failed qualification, incorrect description, unsupported mention, and an eligible product that lost on a documented trade-off.
    4. Trace the earliest failed gate. Repair identity and discovery before attributes, attributes before evidence, and evidence before promotional expansion.
    5. Rerun the same prompt set. Compare changes in coverage and accuracy while recognizing that any individual generated response can vary.
    6. Inspect the commercial handoff. If the recommendation is accurate but the shopper does not proceed, examine the offer, availability, landing experience, and product-market fit rather than calling every weak outcome an AI visibility problem.

    The failure pattern tells you where to look first:

    Observed resultLikely failure areaFirst inspection
    The product never appearsDiscoveryIndexability, canonical URL, feed inclusion, product identity, and internal linking
    The wrong variant appearsIdentityVariant names, identifiers, URLs, parent relationships, and selected-offer data
    The product disappears after a valid constraint is addedQualificationThe missing, ambiguous, or conflicting attribute associated with that constraint
    The assistant states an incorrect factProduct truthConflicts and stale values across the page, schema, feed, marketplace, and support content
    The product is considered but not recommendedSelectionUse-case specificity, comparison criteria, limitations, and claim-level evidence
    The recommendation is accurate but does not convertCommercial handoffPrice, availability, trust, offer clarity, landing experience, and actual product fit

    Track metrics that correspond to those states. Prompt coverage shows whether the product appears for eligible requests. Attribute resolution shows whether the assistant can answer the important constraint questions. Answer accuracy catches misdescription. Evidence visibility shows whether useful supporting pages are surfaced. Recommendation share shows how often the product is selected when it is genuinely eligible. Commercial outcomes tell you whether improved visibility creates useful demand.

    Keep the prompt set and eligibility rules stable while evaluating a change. If you change the content, prompts, markets, and success definition at the same time, you will not know what improved. Treat assistant outputs as observations, not permanent rankings.

    Key takeaways

    • Optimize for discovery, qualification, and selection as separate gates.
    • Create one canonical product record before expanding copy, schema, feeds, or comparison content.
    • Make decisive constraints explicit; do not ask an assistant to infer compatibility, fit, or eligibility from vague prose.
    • Keep visible content, Product structured data, offers, variants, and merchant feeds consistent.
    • Attach meaningful claims to scoped evidence and state important limitations plainly.
    • Measure eligible prompt coverage and factual accuracy before treating recommendation share as the main result.

    Start with one commercially important product family. Establish its canonical facts, build prompts around real purchase constraints, and fix the earliest gate that fails. Once that path is reliable, extend the same operating model to the rest of the catalog. That gives you a repeatable visibility system instead of a collection of schema additions and copy changes whose effect you cannot explain.

    References


  • Agentic Ecommerce: A Playbook for Discovery and Advertising

    Agentic Ecommerce: A Playbook for Discovery and Advertising

    If your product pages rank and your ads are live, but your products still disappear from AI-guided shopping conversations, the missing layer is usually not more promotional copy. It is decision-ready product data: facts an agent can retrieve, compare, explain, and carry into checkout.

    Your goal is no longer just to win a click. You need to help an AI determine whether a specific product fits a specific buyer’s constraints, answer the next question accurately, and make the handoff to your store without changing the facts along the way.

    The shopping funnel now contains a conversation

    A conventional product ad asks the shopper to click before learning much. A conversational ad can answer questions about fit, compatibility, features, availability, or policies inside the discovery surface. ChatGPT is testing clearly labeled Sponsored Agents that open a separate brand conversation, while Google’s Business Agent is being tested inside YouTube ads for eligible U.S. retailers.

    That changes the intermediate step, not the buyer’s underlying job. People still need to eliminate unsuitable choices, understand tradeoffs, and trust the terms of the purchase. The difference is that an agent may now perform part of that evaluation before the shopper reaches your product page.

    Do not collapse every appearance in AI into one visibility metric. There are three distinct outcomes:

    • Citation: your content supplies an explanation or fact used in an answer.
    • Recommendation: your brand enters the suggested set for a category or use case.
    • Selection: a particular product is matched to the shopper’s stated requirements and advanced toward purchase.

    Each outcome requires different work. Clear, retrievable content helps with citation. Consistent brand context supports recommendation. Complete product attributes, current commercial data, and a usable transaction path support selection. This is why LLM readability, brand context, and agentic commerce are separate optimization disciplines, even when one team owns all three.

    Do not fund this shift by abandoning traditional search. An Ahrefs-based measurement found AI Overviews on 24% of shopping queries on Sept. 3, 2026, but a Datos panel of more than 10 million desktop users measured dedicated AI Mode at only about 0.13% of web traffic. A separate panel of 75 ecommerce stores, mostly producing $1 million to $20 million in annual revenue, still placed non-branded organic search second only to paid search for revenue. The practical response is a parallel search and AI strategy, not a wholesale channel migration.

    Build a product record an agent can safely choose

    An unbranded hiking shoe is surrounded by organized visual layers representing its materials, size, fit, availability, shipping, and return details.

    An agent cannot reliably recommend what it cannot distinguish. A polished category description will not compensate for missing variant measurements, ambiguous compatibility, stale availability, or different prices in the feed and on the page.

    For every product and variant you want an agent to select, create one canonical record with five layers:

    • Identity: product name, brand, category, model, SKU or other applicable identifiers, plus the exact relationship between parent products and variants.
    • Transaction truth: price, currency, condition, availability, fulfillment choices, shipping terms, returns, warranty, and any eligibility rules for discounts or member pricing.
    • Decision attributes: dimensions, materials, fit, capacity, supported devices or systems, care requirements, included components, and other facts buyers use to rule products in or out.
    • Evidence and instructions: manuals, size charts, compatibility tables, policy pages, certifications when applicable, and factual answers to recurring pre-purchase questions.
    • Destinations: the correct product page, variant URL, cart action, policy page, or support handoff for each answer.

    Publish the same facts through the channels machines use: visible page content, merchant feeds, platform catalog integrations, and Product and Offer structured data where applicable. JSON-LD should be generated from the same commerce data as the page and feed. Treating schema as a separate copywriting exercise creates exactly the contradictions an agent should not have to resolve.

    Run a variant-level consistency check before activating an agent or campaign. Compare title, identifier, price, currency, availability, shipping, return terms, and the primary decision attributes across the page, feed, structured data, and commerce API. If a field is genuinely unknown, leave it unknown and define a safe fallback. Do not let the agent infer compatibility, delivery, or warranty coverage from adjacent products.

    Product copy still matters, but it should answer rather than decorate. Put the direct answer first, then the explanation, supporting evidence, and relevant conditions. Keep each FAQ block focused on one buyer question so it can be retrieved without unrelated text changing its meaning.

    The commercial case for this cleanup is promising but should not be overstated. Google reports that merchants following its core Merchant Center feed practices see an average 5% conversion increase in the following month. In a Lululemon test, retailer-supplied conversational attributes were incorporated in 50% of relevant AI Mode product recommendations. These are platform-reported results, not guaranteed lifts. Their useful lesson is narrower: attributes that exist as maintained data can participate in recommendations; facts trapped in campaign copy cannot be depended on in the same way.

    Design conversational ads around the next unanswered question

    A shopper and an abstract AI guide exchange symbol-filled bubbles while narrowing several coffee machines to one suitable choice.

    A conversational ad should not be a chat-shaped version of a display ad. Its job is to resolve the next material uncertainty and route the shopper to the correct action. Build an answer map before you generate creative.

    Buyer questionRequired dataSafe handoff
    Will this fit?Variant measurements, sizing method, and size-chart rulesThe selected variant and relevant size guide
    Will it work with what I own?Supported models, exclusions, required accessories, and version limitsThe compatible variant or compatibility table
    What will I actually pay?Current price, currency, shipping terms, and applicable member benefitsA cart with the same disclosed terms
    Can I get it when and where I need it?Live inventory and available fulfillment methodsThe available purchase or pickup path
    What if it is unsuitable?Return window, condition requirements, exclusions, and warranty termsThe relevant policy section or support route

    For each row, define an answer contract: the approved system of record, the claims the agent may make, the data that must be checked live, the fallback when data is unavailable, and the destination that preserves context. A useful fallback is specific: state which fact cannot be confirmed and direct the shopper to the place or person that can confirm it. A confident guess is not customer service.

    AI can also compress campaign production. ChatGPT Work’s Ads Manager plugin can create, update, and analyze campaigns from natural-language instructions; its assistance can propose copy and imagery from a landing page and campaign objective. Optional text customization can adapt headlines and descriptions to the conversation or translate them into the user’s preferred language. U.S. Shopify merchants can also use a ChatGPT Ads app to manage campaigns, while Shopify Catalog data supports more accurate product appearances in shopping conversations. These workflow and catalog integrations reduce interface work, but they do not remove the need for review.

    • Review generated copy against the canonical product record, not just the landing page’s marketing language.
    • Validate translated claims, units, policies, and variant names before enabling localized customization.
    • Require a live lookup for price, stock, delivery, and personalized benefits when those values can change.
    • Send every answer to a landing state that preserves the chosen product or variant. Do not make the shopper repeat the conversation.
    • Log unsupported questions and corrected answers as product-data defects, then fix the underlying record.

    Keep paid and independent answers conceptually separate. OpenAI says Sponsored Agent conversations are labeled and separated from the original ChatGPT conversation, advertising does not influence ChatGPT’s independent answers, and advertisers do not receive users’ private conversations. Plan your measurement around the signals the platform legitimately exposes; do not design a campaign that assumes access to private prompt history.

    Measure the path from question to profitable order

    Click-through rate cannot describe the whole experience when a conversation performs part of the product-page job. It may produce fewer but better-qualified visits, expose missing information, or assist a purchase completed through another surface. Build a measurement chain that distinguishes those outcomes.

    • Visibility: eligible ad exposure, AI share of voice, recommendation coverage across a fixed set of target shopping prompts, and the products most often surfaced.
    • Conversation: conversation starts, qualified question rate, common question categories, answer failure rate, and the share of conversations that reach a site handoff.
    • Selection: variant views, product comparisons, cart additions, and checkout starts originating from the agent experience.
    • Transaction: completed orders, revenue, margin where available, assisted conversions, and member-benefit usage.
    • Outcome quality: cancellations, returns, exchanges, and support contacts attached to agent-assisted orders.

    Define the denominators before launch. Conversation start rate is starts divided by eligible ad exposures when the platform supplies both values. Qualified question rate is conversations containing a decision question divided by starts. Answer failure rate is unsupported, corrected, or escalated answers divided by starts. If a platform withholds a denominator, mark the rate unavailable instead of combining unrelated proxies.

    Use distinct campaign identifiers and landing URLs for each agent surface, preserve product and variant context in the handoff, and record launch dates in your analytics annotations. Compare performance with a suitable unactivated product, market, or campaign group where possible. Keep budget, promotion, inventory, and seasonal differences visible so a lift is not automatically credited to the agent.

    Google’s AI performance insights in Merchant Center are generally available in Australia, Canada, India, New Zealand, and the U.S., including comparisons of brand share of voice across AI Mode and AI Overviews. Its Universal Commerce Protocol integration can also support cart transfers to merchant sites and expanded checkout testing. Loyalty data can surface member-specific pricing and benefits. These discovery, checkout, and personalization capabilities make segmentation essential: report new and returning customers, members and non-members, and agent-assisted and conventional journeys separately.

    Key takeaways: use this launch sequence

    • Choose one decision-heavy category. Start where buyers repeatedly ask about fit, compatibility, delivery, or policy terms, because those questions reveal whether the agent adds real value.
    • Separate your goals. Decide whether each activity is intended to earn a citation, a brand recommendation, a product selection, or a paid conversation.
    • Repair the product record first. Align variant identity, decision attributes, price, inventory, policies, page content, feed data, and JSON-LD before generating campaigns.
    • Create the answer map. Pair each common buyer question with an approved data field, a safe fallback, and a destination that preserves the selected product.
    • Apply campaign guardrails. Human-review generated claims and translations, require live checks for changing commercial facts, and prohibit unsupported inference.
    • Instrument the whole path. Track visibility, dialogue, selection, checkout, and post-purchase quality rather than using clicks as the sole success signal.
    • Feed failures back into operations. Repeated unanswered questions belong in the catalog backlog; frequent returns after an agent interaction may indicate that an answer or attribute is misleading.

    Start with the category where a wrong answer would most often block or spoil a purchase. Make that category reliably answerable across organic discovery, conversational ads, and checkout. Scale only after the same facts survive every handoff.

    References


  • How to Win Commercial Visibility in AI Search and Shopping

    How to Win Commercial Visibility in AI Search and Shopping

    If your products rank in Google but disappear when a shopper asks an AI assistant what to buy, the problem may not be your position. The assistant can assemble its answer from product feeds, web pages, structured data, and corroborating mentions before a familiar blue-link ranking earns a click.

    Your job is to make the same commercial facts easy to retrieve, understand, compare, verify, and act on across those surfaces. That requires more than publishing extra content or adding Product schema. You need a consistent product record, decision-ready evidence, and measurement that follows the buying journey beyond rankings.

    Treat AI commerce as a retrieval problem, not a ranking report

    AI shopping has made product feeds much more important. After the release of ChatGPT 5.6, integrated-feed retrieval grew by roughly 6.5 times and overtook web-search retrieval for product recommendations in Shopping mode in one vendor’s measurement. Treat that finding as directional rather than universal: it concerns a particular platform, release, and observed period, not every assistant or product category.

    The practical implication is still substantial. A strong product page may not rescue a weak or stale feed, while a complete feed may not make your product persuasive when an assistant needs to explain why it fits a shopper’s situation. Feed optimization and web optimization are related jobs, but they are not interchangeable.

    It helps to separate commercial visibility into three states:

    • Eligible: the platform can ingest the product and its offer without running into missing, invalid, or conflicting commercial data.
    • Retrievable: the system can identify the product, connect it to the right brand and variant, and recover the relevant facts from a feed or page.
    • Selectable: the system has enough evidence to recommend the product for a particular need, distinguish it from alternatives, and send the shopper toward a credible next step.

    A conventional rank tracker mainly observes part of the retrievable state. It does not tell you whether a shopping system accepted the product, whether a product card appeared, whether the assistant understood the right variant, or whether a competing brand supplied clearer evidence for the recommendation.

    Start an audit with a small set of products that matter commercially. For each one, ask:

    • Does the product appear when the exact brand, model, and variant are requested?
    • Does it appear for the unbranded need it is supposed to solve?
    • Are the displayed price, currency, availability, image, and destination URL correct?
    • Can the assistant explain who the product is for and the conditions under which it is a better choice?
    • Does the answer cite or link to you, merely mention you, or omit you entirely?

    You usually cannot inspect an assistant’s internal retrieval path. Record the observable evidence instead: the exact prompt, market, visible product cards, cited pages, linked domains, stated commercial facts, and landing URLs. That is enough to distinguish a likely feed problem from a content, authority, or conversion problem.

    Build one canonical commercial record for every product

    An unbranded appliance sits in a central data hub that distributes consistent product details to storefront and AI assistant interfaces.

    An AI system should not have to decide which version of your product data is true. The product feed, visible page content, structured data, and checkout path should describe the same entity and active offer.

    Create a parity sheet for each priority product. This is not a general SEO inventory. It is a field-by-field comparison of the places from which a shopping or search system could recover a buying fact.

    Commercial fieldWhat to comparePassing condition
    Product identityFeed title, page title, visible product name, and Product JSON-LDThe same brand, model, product type, and variant are identifiable everywhere
    OfferPrice, currency, availability, and any stated offer conditionsMachine-readable values match what the shopper can see and purchase
    VariantSize, color, capacity, configuration, or other differentiating attributeEach purchasable option leads to the correct data and destination
    DestinationFeed URL, canonical URL, internal links, and purchase pathThe preferred indexable page is also the relevant conversion page
    EvidenceSpecifications, suitability statements, comparison content, and supporting mentionsClaims are specific, consistent, and supported rather than promotional restatements

    Resolve contradictions before filling optional fields. A stale price, confused variant, or unavailable product marked as available can undermine eligibility and trust. Adding more markup around the contradiction only makes the wrong fact easier to extract.

    Product feeds and Product JSON-LD have different roles. A feed delivers inventory and offer data to a participating platform. JSON-LD identifies and annotates the content on your page. One does not automatically repair the other. Both should mirror the visible experience rather than introduce claims or prices that a shopper cannot confirm.

    Use this order when repairing the product record:

    1. Fix identity. Use a stable, consistent brand and product name. Make the model and variant explicit wherever confusion is possible.
    2. Fix the active offer. Align price, currency, availability, and the page on which the offer can actually be completed.
    3. Fix variants and destinations. Prevent a request for one configuration from resolving to a generic page or a different configuration.
    4. Align visible content and markup. Product and Offer schema should describe facts already present on the page.
    5. Add decision evidence. Explain fit, limitations, and meaningful differences in language an assistant can use when comparing options.

    The final step is where many technically correct implementations remain commercially weak. A record can prove that a product exists and is in stock without giving an assistant a reason to choose it. Specifications need interpretation: who benefits from the attribute, in what situation, and with what tradeoff?

    Keep that interpretation factual. If you did not conduct firsthand testing, do not write as though you did. Use documented specifications and clearly defined selection criteria. Unsupported superlatives such as best, fastest, or easiest create less usable evidence than a narrow statement about the buyer and condition for which the product fits.

    Use content to win the choice, then protect the purchase

    Commercial content still matters, but its job has changed. A comparison page may influence an AI answer even when the shopper never clicks it. A product or pricing page must then turn any resulting visit into a confident next action.

    Write consideration pages that can be cited accurately

    Do not assume middle-of-funnel queries are protected because they have commercial intent. In Seer Interactive’s April 2026 sample, AI Overviews appeared on 8% of queries classified as commercial, compared with 36% of informational queries. Query format revealed much greater exposure: comparison formats triggered AI Overviews 95.4% of the time, while best-of formats did so 81.3% of the time.

    That distinction matters because many pages written to influence a purchase use an informational format. A page targeting Product A versus Product B may be commercially important even if the query is classified as informational. Plan around the decision the shopper is making, not the label attached to the query.

    These pages are still worth building. In the same dataset, pages cited within an AI Overview received roughly 120% more clicks per impression than uncited pages on that results page. Citation did not restore the old click opportunity: cited pages remained 38% below results without an AI Overview. The useful conclusion is narrower than citation guarantees traffic. Citation is the strongest available position when an AI answer occupies the search result.

    A citation-ready comparison page should do five things:

    • Define a specific decision. Best software is vague. Best software for a named type of buyer, constraint, and workflow creates a selection problem you can actually answer.
    • State the criteria before the verdict. Tell the reader which attributes affect the decision and why. This makes the conclusion inspectable rather than arbitrary.
    • Name every entity precisely. Use consistent product and brand names, especially when several versions or similarly named offers exist.
    • Write self-contained conclusions. A useful passage should name the buyer, preferred option, reason, condition, and tradeoff without requiring paragraphs of missing context.
    • Support the page as a hub. Link it to relevant product, pricing, specification, and supporting pages. Earn links and credible brand mentions around the decision topic, not only the homepage.

    A reusable conclusion pattern is: For [buyer], [product] is the stronger fit when [condition] because [verifiable feature]. [Alternative] makes more sense when [different condition]. The tradeoff is [meaningful constraint]. Replace every bracket with evidence. If you cannot fill the tradeoff honestly, the comparison is probably not ready to publish.

    Original data and documented firsthand testing can strengthen citation value because they give other pages and models a reason to reference you. They only help when the method is real and explained. Do not manufacture a scoring system to make an opinion look measured. If the conclusion comes from specifications and public documentation, say so plainly.

    Make the next commercial step unmistakable

    Bottom-of-funnel pages occupy more click-protected territory. In the April 2026 sample, AI Overview presence was 5% for transactional queries. That average should not make you complacent: within informational queries, price, cost, and buy formats triggered AI Overviews 83.4% of the time. A query can sound close to purchase while still receiving an AI-generated answer.

    Protect exact-product, pricing, offer, and branded navigational demand deliberately. On the primary conversion page:

    • Put the current price, currency, availability, and material offer conditions where the shopper can find them without interpreting promotional copy.
    • Use a specific call to action that matches the transaction the page supports.
    • Answer the objections that prevent this buyer from proceeding, including compatibility, plan boundaries, variant differences, or other relevant constraints.
    • Link comparison and best-for pages directly to the correct product or pricing destination instead of sending qualified visitors back through the homepage.
    • Keep Product and Offer markup aligned with the visible page and active purchase state.

    Commercial pages can now be more valuable than another high-volume informational page, and citation visibility can matter alongside a traditional ranking. Use top-of-funnel content selectively to close a real topical gap, answer a question needed later in the buying journey, or support a priority commercial hub. Publishing broad definitions without a route to evaluation or purchase is unlikely to fix a commercial visibility problem.

    Measure the commercial journey across every visible surface

    A shopper uses a phone and laptop as a glowing path connects AI discovery, product comparison, selection, and fulfillment surfaces.

    Do not collapse AI visibility into a single score. A percentage can hide the difference between being mentioned, being cited, appearing as a purchasable product, and receiving a visit that converts.

    Build a scorecard with separate observations for each query and priority product:

    • Search position: the conventional organic rank and the search features present around it.
    • AI inclusion: whether your brand or product appears in the generated answer.
    • Commercial presentation: whether a visible product card, correct price, correct variant, and useful destination are present.
    • Citation status: whether the system cites your domain, cites a third party discussing you, mentions you without a link, or omits you.
    • Competitive share: which alternatives appear for the same decision and which claims support their inclusion.
    • Business outcome: attributable visits where available, landing-page engagement, conversion, and revenue.

    Use a fixed query set so the observations remain comparable. Include branded product requests, unbranded need-based requests, comparisons, best-for queries, and purchase-oriented requests. Preserve the exact wording and record the market, interface, visible result type, and observation date. AI outputs can vary, so one prompt run is an example, not a performance trend.

    Segment the scorecard by funnel stage and format. That prevents a large set of informational mentions from hiding the fact that your product is absent when a buyer asks for a recommendation, comparison, price, or place to purchase.

    Use the pattern of failure to choose the next fix:

    • The page ranks, but the product does not appear in shopping results: inspect feed eligibility, identity, offer completeness, and feed-to-page parity.
    • The product appears with the wrong price, variant, or URL: resolve contradictory commercial fields before doing more content work.
    • You rank well, but competitors receive the citations: compare entity clarity, selection criteria, self-contained conclusions, original evidence, links, and brand mentions.
    • You are mentioned but not linked: strengthen the page that owns the relevant decision and make its evidence easier to attribute.
    • You receive citations and visits but few purchases: inspect offer clarity, destination relevance, calls to action, and conversion friction. More visibility will only send more people into the same problem.

    Prioritize work by commercial consequence. Start with products that already have demand or revenue potential, repair the data that determines eligibility, improve the pages that explain the choice, and then build broader authority around those pages. This sequence gives every content and link-building effort a clear commercial destination.

    Key takeaways

    • AI shopping visibility can depend on product-feed retrieval as well as web retrieval, so rankings alone cannot diagnose exclusion.
    • Your feed, visible product page, JSON-LD, variant URLs, and purchase path should describe the same product and active offer.
    • Comparison and best-of pages remain valuable, but they should be written for accurate citation with named entities, explicit criteria, evidence, and self-contained conclusions.
    • Transactional pages deserve deliberate protection because their smaller query volumes can carry much greater conversion value.
    • Track product inclusion, commercial accuracy, citations, links, visits, conversions, and revenue separately instead of relying on one AI visibility score.

    Choose one priority product and trace it from feed to recommendation to purchase page. Fix the first broken handoff you find. Once that path is consistent, repeat the process for the next product rather than spreading shallow optimization across the entire catalog.

    References


  • How to Choose the Right eCommerce Website Design Agency

    How to Choose the Right eCommerce Website Design Agency

    Choosing an eCommerce design agency gets risky when every proposal promises the same things: a modern storefront, better conversion, and seamless integration. Those phrases will not tell you whether the team can preserve organic visibility, model customer-specific pricing, or move a live catalog without breaking the buying path.

    The useful question is not, “Which agency is best?” It is, “Which team can prove it has solved the operating problem our store actually has?” The process below turns that question into requirements, evidence, a weighted decision, and a contract you can enforce.

    Define the store’s operating job before you shortlist agencies

    An isometric online storefront connects to catalog, inventory, payments, shipping, customer accounts, search, and support systems.

    An attractive interface is only the visible layer of an eCommerce system. Underneath it sit product data, pricing rules, customer accounts, inventory, payments, fulfillment, analytics, search visibility, and the operational systems your team already uses. Your shortlist will be unreliable until you decide which of those problems the project must solve.

    Start by writing one sentence that describes the commercial job, the customer, and the change you need. Use a form such as:

    • For a direct-to-consumer business: “Replace our current storefront with a faster, easier product-discovery and checkout experience without losing valuable organic landing pages.”
    • For a manufacturer or distributor: “Give logged-in buyers customer-specific pricing, live availability, repeat ordering, and account self-service using data from our ERP.”
    • For a migration: “Move the existing catalog, customers, orders, content, and search equity to the selected platform while reducing the custom code we must maintain.”

    That sentence forces an important distinction. A consumer brand may need merchandising, storytelling, acquisition landing pages, and checkout optimization. A B2B seller may need account hierarchies, approval rules, negotiated prices, payment terms, quick-order tools, and an ERP-backed buyer portal. These are not different visual styles. They are different operating models.

    For manufacturers and distributors, buyer-portal capability and ERP design experience warrant separate evaluation. They were weighted at 15% and 13%, respectively, in a B2B agency assessment. That separation matters because a team can design a polished account dashboard without knowing how to make its inventory, pricing, and order status agree with the system of record.

    Turn the operating job into a requirements sheet covering:

    • Customer model: anonymous shoppers, account customers, dealers, distributors, procurement teams, or a mixture.
    • Critical buying journeys: product discovery, quote request, purchase, approval, reorder, subscription, return, or account service.
    • Catalog and commercial rules: variants, bundles, large assortments, market-specific catalogs, contract prices, volume rules, and restricted products.
    • Systems and data ownership: eCommerce platform, ERP, product information system, CRM, payment service, tax service, fulfillment tools, analytics, and marketing platforms.
    • Discovery requirements: existing organic landing pages, internal search, product feeds, structured data, indexation rules, redirects, and content workflows.
    • Delivery constraints: launch dependencies, internal approvers, compliance needs, content readiness, available technical staff, and the support model after launch.

    Label each requirement as mandatory for launch, valuable if the budget allows, or suitable for a later phase. An agency should not be able to turn an essential workflow into a surprise change request simply because it appeared deep in an unprioritized feature list.

    Do not let a preferred platform reverse this sequence. Platform credentials can show that an agency knows a technology, but the platform still has to support your commercial rules and integrations. Define the job first, select the platform against that job, and then evaluate whether the agency has relevant people available to deliver it.

    Ask for proof at the level of the use case

    Logo walls, awards, aggregate ratings, and attractive screenshots are useful screening signals. None proves that the proposed team can handle your project. The closer the evidence is to your actual use case, the more weight it deserves.

    The limits of ratings are easy to see. Among seven selected agencies in a 2026 market set, average review scores ranged only from 4.0 to 4.8 while buyer-portal capability ranged from minimal to extensive and ERP experience ranged from unreported or limited to extensive. A strong rating can support your decision, but it cannot tell you whether the agency has the capability your store needs.

    Ask each candidate for an evidence pack tied to your requirements. It should include:

    • A case study with the same commerce model, not merely the same industry or platform.
    • A live or recorded walkthrough of the relevant workflow, including account, mobile, empty, error, and exception states where applicable.
    • A clear account of what the agency actually delivered. Strategy, design, platform configuration, integration, data migration, SEO, and ongoing marketing may have been divided among several parties.
    • The business or operational outcome, how it was measured, and which constraints affected it.
    • The names, roles, platform credentials, and expected availability of the people proposed for your project.
    • A client reference whose project involved the capability you consider most difficult or risky.

    “Similar project” needs a precise meaning. Match evidence across the dimensions that create complexity: customer type, platform, catalog, pricing model, integrations, geographic reach, migration scope, and internal operating model. A fashion storefront on Shopify is not strong evidence for a distributor that needs account pricing from an ERP, even when both businesses sell online.

    Audit each case study with direct questions:

    • What problem existed before the project?
    • Which requirements forced a custom solution, and which were handled natively by the platform?
    • Which systems supplied product, price, inventory, customer, and order data?
    • What failed or changed during delivery, and how did the team respond?
    • Which result can be attributed to the redesign, and what else changed at the same time?
    • What does the agency maintain now, and what does the client’s team own?

    If an agency cannot explain how an outcome was measured, treat the work as evidence of creative quality rather than commercial impact. If it cannot identify its responsibility, do not credit it for the whole implementation. If the proposed delivery team differs from the case-study team, assess the people you will actually receive.

    Use a weighted scorecard without letting averages hide deal-breakers

    Three storefront models are evaluated with colored priority tokens, while only one has a complete path to a checkout parcel.

    A scorecard prevents the most polished presentation from winning by default. For a manufacturer or distributor, the following B2B weighting provides a practical starting point. It reflects the greater delivery risk carried by portals, commercial rules, and ERP-connected experiences. It should not be copied unchanged for a direct-to-consumer brief.

    CriterionStarting weightEvidence worth scoringWeak evidence
    B2B specialization and platform certifications25%Relevant credentials held by the assigned team plus comparable technical workA large badge collection with no matching workflow or named delivery team
    Average online review score20%A consistent pattern across established review platforms, with comments relevant to deliverySelected testimonials with no independent context or explanation of project scope
    Portfolio and client success17%Comparable implementations, attributable responsibilities, and measurable outcomesScreenshots, brand names, or unverified claims without operational detail
    Buyer portal and self-service UX15%Working account dashboards, repeat ordering, approvals, quotes, and customer-specific experiencesA generic login page or mockup presented as a complete portal
    ERP integration and operational design13%Clear data ownership, interface behavior, failure handling, reconciliation, and order workflows“We integrate with anything” without architecture or comparable implementation evidence
    Industry experience and specialization10%Understanding of the industry’s catalog, buying process, operating constraints, and terminologyIndustry logos that do not connect to the requirements in your brief

    Give every agency the same evidence grades: absent, weak, acceptable, strong, or exceptional. Define what each grade means before reviewing proposals, convert the grades to a consistent numeric scale in your spreadsheet, apply the weights, and record a short justification beside every score. A score without a note will be hard to defend when stakeholders remember the presentations differently.

    Keep hard gates outside the weighted total. These are conditions that cannot be averaged away, such as an unsupported required platform, missing security or compliance capability, inability to meet a fixed business dependency, an unacceptable subcontracting model, or refusal to accept essential contract terms. An agency that fails a hard gate should not win because it scored well on brand design.

    Change the weights before proposals arrive if your project is not B2B manufacturing or distribution. A consumer retailer may put more emphasis on merchandising, mobile shopping, brand expression, experimentation, content, conversion, and SEO migration. A platform migration may put more emphasis on data mapping, redirects, integrations, cutover planning, and maintainability. Changing weights after seeing the candidates simply lets preference masquerade as analysis.

    Turn the final pitch into a working session, then contract the details

    Use one scenario to expose how the team thinks

    Give every finalist the same realistic scenario from your requirements sheet before the meeting. Ask the people who would do the work to walk through their response. For a B2B seller, that might be a logged-in buyer seeing an account price, discovering that requested quantity is not fully available, seeking approval, and placing an order that must reach the ERP. For a migration, it might be preserving a valuable category URL while product taxonomy, filters, and platform templates change.

    Use the session to ask:

    • Which part would you solve with native platform functionality, an application, configuration, or custom code, and why?
    • Where is the source of truth for each piece of data, and what should the customer see when that source is unavailable?
    • Which assumptions must be validated during discovery?
    • How will design decisions be tested against real catalog content and exception cases?
    • How will URL changes, redirects, indexation, internal links, structured data, product feeds, and analytics be handled?
    • Who makes the technical decision, who performs the work, and who remains accountable when another vendor is involved?
    • What is explicitly excluded from the proposal?

    Good answers reveal choices, dependencies, and tradeoffs. Be wary of answers that make every integration sound routine or every requirement sound native. The purpose of the session is not to demand a complete solution before discovery. It is to see whether the team notices the hard parts and has a credible method for resolving them.

    Communication also needs evidence. Ask who owns decisions, how unresolved issues are recorded, what you will see during delivery, and how scope changes are approved. Then compare those answers with the client reference. A personable salesperson is not a substitute for a delivery system.

    Replace vague promises with acceptance criteria

    Do not accept “custom eCommerce website,” “seamless ERP integration,” “SEO-friendly build,” or “AI-ready content” as complete deliverables. The statement of work should identify the artifact, owner, review process, dependency, and acceptance condition for each project area.

    • Discovery: approved requirements, customer journeys, functional decisions, system map, data ownership, risks, and delivery plan.
    • Experience design: named templates and components, responsive behavior, account states, error states, accessibility requirements, and content responsibilities.
    • Platform and integration: native features, applications, custom code, interfaces, field mappings, synchronization behavior, failure handling, reconciliation, and technical documentation.
    • Content and migration: catalog mapping, customer and order history, editorial content, asset handling, validation, and ownership of cleanup work.
    • Search and machine-readable discovery: URL inventory, redirect map, canonical and indexation rules, internal linking, metadata ownership, XML sitemaps, product feeds, and responsibility for relevant Product and Organization structured data.
    • Quality and launch: test responsibilities, supported environments, performance and accessibility measurements, analytics validation, cutover steps, backups, rollback conditions, and post-launch monitoring.
    • Support: warranty boundaries, response process, maintenance ownership, documentation, training, and the transition to internal staff or another provider.

    For AI search and answer-engine visibility, insist on concrete implementation language. Product facts, prices, availability, policies, brand information, and supporting content should remain accessible on stable, crawlable pages and be represented consistently in visible copy, structured data, and feeds where applicable. No agency can contractually guarantee inclusion or ranking in an AI-generated answer. “AI-ready” without named outputs and validation steps is not an acceptance criterion.

    The commercial terms should also state how assumptions, dependencies, delays, and change requests affect cost and delivery. Confirm code and design ownership, application and platform fees, third-party licenses, data access, subcontractors, termination assistance, and what happens to unfinished work. For provisions affecting intellectual property, personal data, liability, indemnity, or termination rights, have qualified counsel review the actual agreement; an agency scorecard cannot resolve legal exposure.

    Before signing, speak with a reference whose implementation resembles yours. Ask what changed after discovery, which responsibilities were unclear, how the agency behaved when delivery became difficult, what the client still depends on the agency to operate, and whether the team named in the sale remained involved. Those answers help you distinguish a successful launch from a maintainable commerce operation.

    Key takeaways

    • Select for your commerce model and operating complexity, not for the most attractive generic portfolio.
    • Write critical buying journeys, systems, data ownership, discovery requirements, and exception cases before requesting proposals.
    • Score proof that matches your use case. Ratings, credentials, and brand names are supporting signals, not substitutes for comparable delivery evidence.
    • Use preset weights and separate pass/fail gates so a strong presentation cannot conceal a missing essential capability.
    • Put the proposed delivery team through the same working scenario and listen for dependencies, failure states, and honest tradeoffs.
    • Contract specific artifacts and acceptance conditions for design, integration, migration, SEO, structured data, launch, and support.

    Your next move is to write the operating brief and hard gates before booking another pitch. Send the same brief to every shortlisted agency and refuse to score a claim that has no relevant evidence behind it. Once that discipline is in place, agency selection becomes a controlled business decision rather than a contest between sales presentations.

    References