Tag: Agentic Commerce

  • Agentic Ecommerce: A Playbook for Discovery and Advertising

    Agentic Ecommerce: A Playbook for Discovery and Advertising

    If your product pages rank and your ads are live, but your products still disappear from AI-guided shopping conversations, the missing layer is usually not more promotional copy. It is decision-ready product data: facts an agent can retrieve, compare, explain, and carry into checkout.

    Your goal is no longer just to win a click. You need to help an AI determine whether a specific product fits a specific buyer’s constraints, answer the next question accurately, and make the handoff to your store without changing the facts along the way.

    The shopping funnel now contains a conversation

    A conventional product ad asks the shopper to click before learning much. A conversational ad can answer questions about fit, compatibility, features, availability, or policies inside the discovery surface. ChatGPT is testing clearly labeled Sponsored Agents that open a separate brand conversation, while Google’s Business Agent is being tested inside YouTube ads for eligible U.S. retailers.

    That changes the intermediate step, not the buyer’s underlying job. People still need to eliminate unsuitable choices, understand tradeoffs, and trust the terms of the purchase. The difference is that an agent may now perform part of that evaluation before the shopper reaches your product page.

    Do not collapse every appearance in AI into one visibility metric. There are three distinct outcomes:

    • Citation: your content supplies an explanation or fact used in an answer.
    • Recommendation: your brand enters the suggested set for a category or use case.
    • Selection: a particular product is matched to the shopper’s stated requirements and advanced toward purchase.

    Each outcome requires different work. Clear, retrievable content helps with citation. Consistent brand context supports recommendation. Complete product attributes, current commercial data, and a usable transaction path support selection. This is why LLM readability, brand context, and agentic commerce are separate optimization disciplines, even when one team owns all three.

    Do not fund this shift by abandoning traditional search. An Ahrefs-based measurement found AI Overviews on 24% of shopping queries on Sept. 3, 2026, but a Datos panel of more than 10 million desktop users measured dedicated AI Mode at only about 0.13% of web traffic. A separate panel of 75 ecommerce stores, mostly producing $1 million to $20 million in annual revenue, still placed non-branded organic search second only to paid search for revenue. The practical response is a parallel search and AI strategy, not a wholesale channel migration.

    Build a product record an agent can safely choose
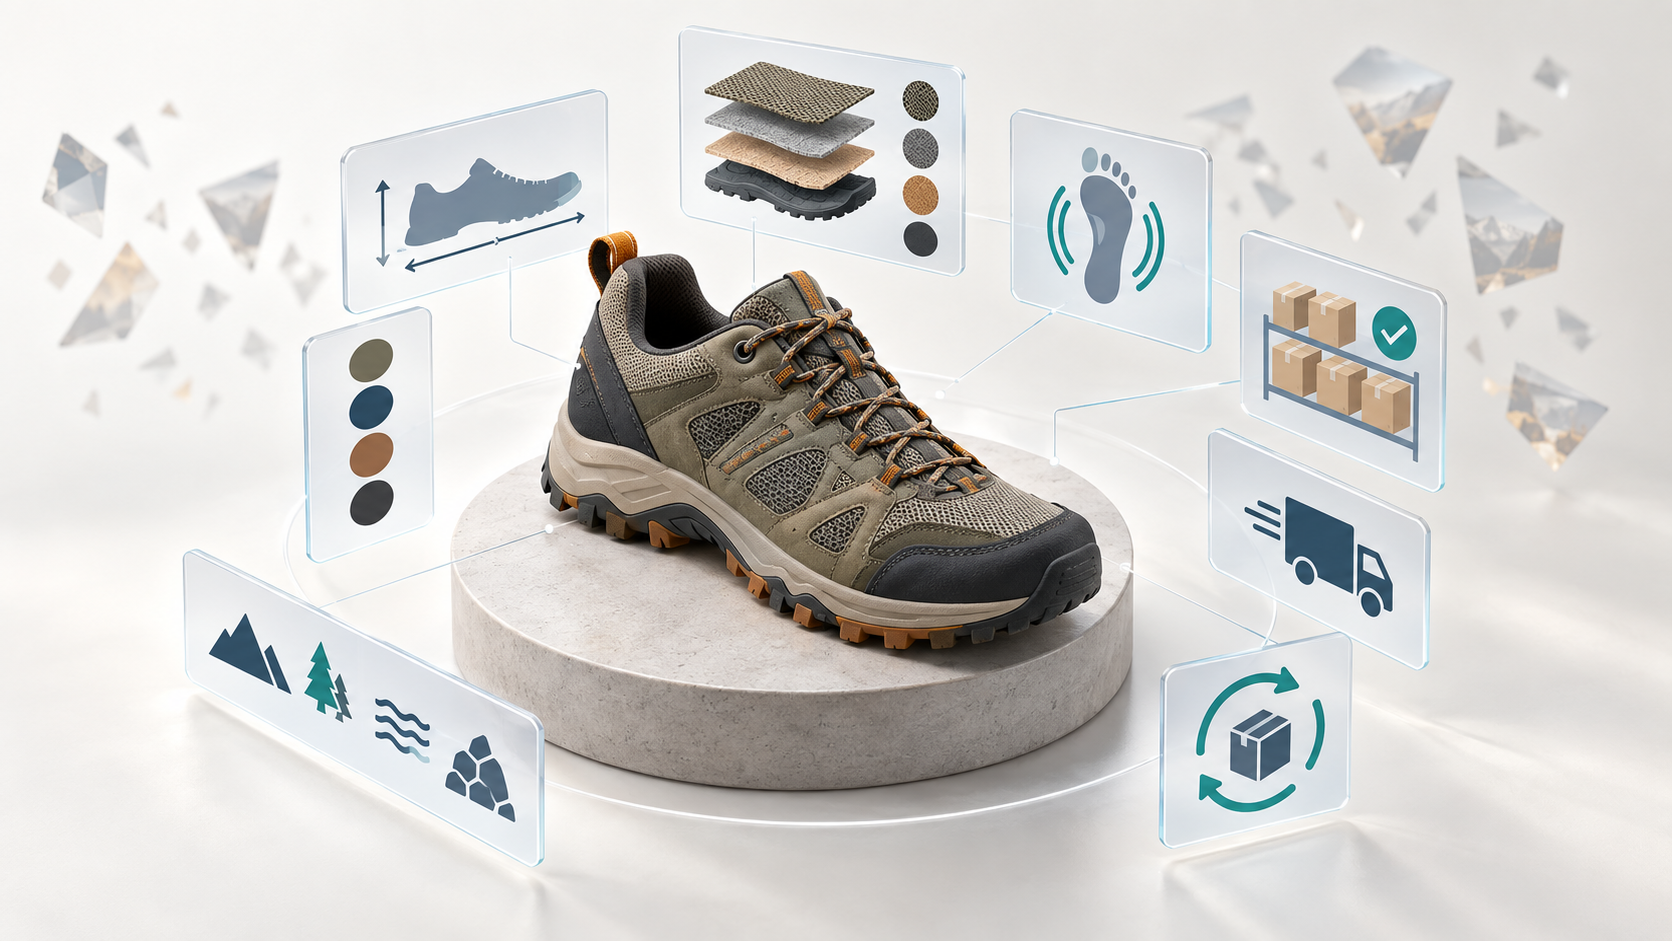
    An unbranded hiking shoe is surrounded by organized visual layers representing its materials, size, fit, availability, shipping, and return details.

    An agent cannot reliably recommend what it cannot distinguish. A polished category description will not compensate for missing variant measurements, ambiguous compatibility, stale availability, or different prices in the feed and on the page.

    For every product and variant you want an agent to select, create one canonical record with five layers:

    • Identity: product name, brand, category, model, SKU or other applicable identifiers, plus the exact relationship between parent products and variants.
    • Transaction truth: price, currency, condition, availability, fulfillment choices, shipping terms, returns, warranty, and any eligibility rules for discounts or member pricing.
    • Decision attributes: dimensions, materials, fit, capacity, supported devices or systems, care requirements, included components, and other facts buyers use to rule products in or out.
    • Evidence and instructions: manuals, size charts, compatibility tables, policy pages, certifications when applicable, and factual answers to recurring pre-purchase questions.
    • Destinations: the correct product page, variant URL, cart action, policy page, or support handoff for each answer.

    Publish the same facts through the channels machines use: visible page content, merchant feeds, platform catalog integrations, and Product and Offer structured data where applicable. JSON-LD should be generated from the same commerce data as the page and feed. Treating schema as a separate copywriting exercise creates exactly the contradictions an agent should not have to resolve.

    Run a variant-level consistency check before activating an agent or campaign. Compare title, identifier, price, currency, availability, shipping, return terms, and the primary decision attributes across the page, feed, structured data, and commerce API. If a field is genuinely unknown, leave it unknown and define a safe fallback. Do not let the agent infer compatibility, delivery, or warranty coverage from adjacent products.

    Product copy still matters, but it should answer rather than decorate. Put the direct answer first, then the explanation, supporting evidence, and relevant conditions. Keep each FAQ block focused on one buyer question so it can be retrieved without unrelated text changing its meaning.

    The commercial case for this cleanup is promising but should not be overstated. Google reports that merchants following its core Merchant Center feed practices see an average 5% conversion increase in the following month. In a Lululemon test, retailer-supplied conversational attributes were incorporated in 50% of relevant AI Mode product recommendations. These are platform-reported results, not guaranteed lifts. Their useful lesson is narrower: attributes that exist as maintained data can participate in recommendations; facts trapped in campaign copy cannot be depended on in the same way.

    Design conversational ads around the next unanswered question
    A shopper and an abstract AI guide exchange symbol-filled bubbles while narrowing several coffee machines to one suitable choice.

    A conversational ad should not be a chat-shaped version of a display ad. Its job is to resolve the next material uncertainty and route the shopper to the correct action. Build an answer map before you generate creative.

    Buyer questionRequired dataSafe handoff
    Will this fit?Variant measurements, sizing method, and size-chart rulesThe selected variant and relevant size guide
    Will it work with what I own?Supported models, exclusions, required accessories, and version limitsThe compatible variant or compatibility table
    What will I actually pay?Current price, currency, shipping terms, and applicable member benefitsA cart with the same disclosed terms
    Can I get it when and where I need it?Live inventory and available fulfillment methodsThe available purchase or pickup path
    What if it is unsuitable?Return window, condition requirements, exclusions, and warranty termsThe relevant policy section or support route

    For each row, define an answer contract: the approved system of record, the claims the agent may make, the data that must be checked live, the fallback when data is unavailable, and the destination that preserves context. A useful fallback is specific: state which fact cannot be confirmed and direct the shopper to the place or person that can confirm it. A confident guess is not customer service.

    AI can also compress campaign production. ChatGPT Work’s Ads Manager plugin can create, update, and analyze campaigns from natural-language instructions; its assistance can propose copy and imagery from a landing page and campaign objective. Optional text customization can adapt headlines and descriptions to the conversation or translate them into the user’s preferred language. U.S. Shopify merchants can also use a ChatGPT Ads app to manage campaigns, while Shopify Catalog data supports more accurate product appearances in shopping conversations. These workflow and catalog integrations reduce interface work, but they do not remove the need for review.

    • Review generated copy against the canonical product record, not just the landing page’s marketing language.
    • Validate translated claims, units, policies, and variant names before enabling localized customization.
    • Require a live lookup for price, stock, delivery, and personalized benefits when those values can change.
    • Send every answer to a landing state that preserves the chosen product or variant. Do not make the shopper repeat the conversation.
    • Log unsupported questions and corrected answers as product-data defects, then fix the underlying record.

    Keep paid and independent answers conceptually separate. OpenAI says Sponsored Agent conversations are labeled and separated from the original ChatGPT conversation, advertising does not influence ChatGPT’s independent answers, and advertisers do not receive users’ private conversations. Plan your measurement around the signals the platform legitimately exposes; do not design a campaign that assumes access to private prompt history.

    Measure the path from question to profitable order

    Click-through rate cannot describe the whole experience when a conversation performs part of the product-page job. It may produce fewer but better-qualified visits, expose missing information, or assist a purchase completed through another surface. Build a measurement chain that distinguishes those outcomes.

    • Visibility: eligible ad exposure, AI share of voice, recommendation coverage across a fixed set of target shopping prompts, and the products most often surfaced.
    • Conversation: conversation starts, qualified question rate, common question categories, answer failure rate, and the share of conversations that reach a site handoff.
    • Selection: variant views, product comparisons, cart additions, and checkout starts originating from the agent experience.
    • Transaction: completed orders, revenue, margin where available, assisted conversions, and member-benefit usage.
    • Outcome quality: cancellations, returns, exchanges, and support contacts attached to agent-assisted orders.

    Define the denominators before launch. Conversation start rate is starts divided by eligible ad exposures when the platform supplies both values. Qualified question rate is conversations containing a decision question divided by starts. Answer failure rate is unsupported, corrected, or escalated answers divided by starts. If a platform withholds a denominator, mark the rate unavailable instead of combining unrelated proxies.

    Use distinct campaign identifiers and landing URLs for each agent surface, preserve product and variant context in the handoff, and record launch dates in your analytics annotations. Compare performance with a suitable unactivated product, market, or campaign group where possible. Keep budget, promotion, inventory, and seasonal differences visible so a lift is not automatically credited to the agent.

    Google’s AI performance insights in Merchant Center are generally available in Australia, Canada, India, New Zealand, and the U.S., including comparisons of brand share of voice across AI Mode and AI Overviews. Its Universal Commerce Protocol integration can also support cart transfers to merchant sites and expanded checkout testing. Loyalty data can surface member-specific pricing and benefits. These discovery, checkout, and personalization capabilities make segmentation essential: report new and returning customers, members and non-members, and agent-assisted and conventional journeys separately.

    Key takeaways: use this launch sequence

    • Choose one decision-heavy category. Start where buyers repeatedly ask about fit, compatibility, delivery, or policy terms, because those questions reveal whether the agent adds real value.
    • Separate your goals. Decide whether each activity is intended to earn a citation, a brand recommendation, a product selection, or a paid conversation.
    • Repair the product record first. Align variant identity, decision attributes, price, inventory, policies, page content, feed data, and JSON-LD before generating campaigns.
    • Create the answer map. Pair each common buyer question with an approved data field, a safe fallback, and a destination that preserves the selected product.
    • Apply campaign guardrails. Human-review generated claims and translations, require live checks for changing commercial facts, and prohibit unsupported inference.
    • Instrument the whole path. Track visibility, dialogue, selection, checkout, and post-purchase quality rather than using clicks as the sole success signal.
    • Feed failures back into operations. Repeated unanswered questions belong in the catalog backlog; frequent returns after an agent interaction may indicate that an answer or attribute is misleading.

    Start with the category where a wrong answer would most often block or spoil a purchase. Make that category reliably answerable across organic discovery, conversational ads, and checkout. Scale only after the same facts survive every handoff.

    References


  • ChatGPT Ads and Transactions: A Practical Growth Strategy

    ChatGPT Ads and Transactions: A Practical Growth Strategy

    If your ChatGPT plan ends when your brand earns a mention or a click, you are planning for a funnel that is already changing. Diners can now move from a restaurant recommendation to a Yelp reservation or waitlist inside the conversation, while eligible advertisers can buy placement around relevant conversations through ChatGPT Ads.

    You now need to manage three connected layers: recommendation visibility, paid acquisition, and transaction readiness. They can reinforce one another, but they are not interchangeable. The first strategic decision is to identify which layer should produce the result you want.

    ChatGPT now holds three parts of the commercial journey

    Traditional search marketing assumes a familiar handoff: the search engine presents a result, the user clicks, and the website handles the remaining persuasion and conversion. ChatGPT can support that journey, but it can also insert advertising before the click or host an action before the user reaches your site.

    Commercial surfaceWhat the user doesWhat you can controlPrimary measurement
    Recommendation visibilityReceives your brand, product, or business as part of an answerClear factual content, consistent entity information, supporting evidence, and reliable external business recordsPresence, factual accuracy, citations, qualified referral traffic
    Sponsored placementSees an ad associated with a relevant conversation and may clickEligibility, geography, first-party audiences, context hints, bid, creative, and landing pageImpressions, clicks, CPC, landing-page conversions, CPA
    Embedded transactionCompletes an action such as reserving a table or joining a waitlist in the chat experiencePartner data, availability, transaction infrastructure, confirmation, and post-transaction serviceCompleted actions and the corresponding records in the transaction provider

    A business may participate in one layer without participating in the others. Buying an ad does not mean you should assume stronger placement in an unsponsored answer. Being recommended does not mean ChatGPT can complete a transaction for you. An embedded action may also send the user to a partner, rather than your website, for later management.

    Report the layers separately. Otherwise, a rise in paid clicks can be mistaken for better AI-search visibility, while an increase in partner-managed transactions may be invisible in website analytics.

    Run four checks before allocating a ChatGPT Ads budget

    Two marketing professionals examine four visual readiness checkpoints before moving an advertising token through an illuminated gateway.

    ChatGPT Ads will not fit every audience or business. Before you write creative, pass four go-or-no-go checks.

    • Audience: Ads can serve only to people OpenAI believes are 18 or older on the Free and Go tiers, including logged-out sessions. If your most valuable buyers tend to use higher paid tiers, the reachable audience may be a poor match.
    • Location: Current targeting covers the United States, Australia, Canada, Japan, New Zealand, South Korea, and the United Kingdom. You can target or exclude locations at the country, region, designated market area, or postal-code level.
    • Policy: Restricted categories include adult content, alcohol, tobacco, financial services, gambling, and others. Policy materials have also shown ambiguity around legal-service advertising, so visible ads from a competitor are not proof that your own offer is eligible.
    • Economics: The self-service minimum is $25 per day, while early campaign observations put average CPCs around $2 to $5 across industries. Those CPCs are preliminary observations, not a dependable benchmark for every market. A bid below $3 may trigger a warning that the ad will not deliver; that threshold appears to be fixed rather than a personalized forecast.

    The budget floor is an entry requirement, not evidence that $25 will generate enough activity for a sound decision. Work backward from the maximum customer-acquisition cost your business can tolerate. If the observed CPC range cannot support that number at a realistic landing-page conversion rate, fix the offer or measurement before funding the campaign.

    Account ownership deserves attention as well. The advertiser should create and own the account, then add its agency as a user. Agencies are not supposed to create accounts on behalf of clients, and the platform does not yet offer a direct equivalent to Google Ads Manager Accounts or Meta Business Manager. Collect the legal business name, business tax ID, payment card, and favicon before setup so account administration does not delay the launch.

    Structure campaigns around decisions, not keyword lists

    ChatGPT Ads has no keyword targeting, demographic targeting, or conventional in-market audiences. The available controls include geography, uploaded first-party audiences, context hints, and the language used in your ad and landing page. Importing a paid-search keyword spreadsheet unchanged will therefore create the wrong campaign architecture.

    The account hierarchy will look familiar:

    • Campaign: Standard or product-feed type; Reach, Clicks, or Conversions objective; included and excluded locations; included and excluded custom audiences; daily or total budget; optional conversion event; and start and end dates.
    • Ad group: Bid, default destination URL, and context hints.
    • Ad: Destination URL, headline, description, and image.

    Use that structure to isolate the decision the user is trying to make. A practical build sequence looks like this:

    1. Write the conversational situation as a sentence. Include the problem, important constraint, and decision stage. This is more useful than a list of loosely related search terms.
    2. Keep one intent family in each ad group. The ad, context hints, and destination should all continue the same task. Separate early education from urgent comparison or purchase intent.
    3. Select an objective that matches the next measurable event. Use Reach when qualified exposure is the result, Clicks when the destination page must continue the journey, and Conversions only after the OpenAI pixel and conversion event are working correctly.
    4. Design within the actual creative limits. Headlines have a 50-character maximum, descriptions have a 100-character maximum, and either can be truncated. Put the useful distinction first. The image must be a square PNG or JPG of at least 256 by 256 pixels.
    5. Make the landing page a direct continuation. If the conversation concerns a specific problem, constraint, product, or location, the destination should address it immediately. Do not send every context to a generic homepage.
    6. Validate measurement before optimizing bids. Click campaigns charge per click. Reach campaigns charge per 1,000 impressions. Conversion campaigns require the pixel, still charge per click, and allow a bid cap.

    OpenAI uses a relevance-weighted, second-price auction. Bid size matters, but landing-page relevance and ad quality also contribute to selection. When delivery is weak, raising the bid is only one possible response. First inspect whether the context, promise, creative, and destination describe the same user need.

    This also changes creative testing. Do not test two ads that target different decisions and then attribute the result to wording. Hold the intent family and destination constant while changing one material element, such as the promise, proof point, or image. The platform is still evolving, so record the configuration and launch date with every result.

    Becoming transactable starts outside ChatGPT

    A generic conversational interface connects to product, inventory, reservation, payment, and fulfillment systems that support a completed transaction.

    The restaurant integration exposes the operational model clearly. Yelp already supplies reviews, ratings, photos, and business details to ChatGPT. It now also supplies Reservations and Waitlist for thousands of restaurants in the United States and Canada. The user can complete the initial action inside ChatGPT but manages or modifies the booking through Yelp.

    That means the conversion surface and the system of record may belong to different companies. Your website, business profile, transaction provider, and in-chat experience must still agree on what can be booked and what happens next.

    1. Identify the transaction rail. Determine which booking, commerce, or lead-management provider can actually complete the action for your category. Do not assume a feature available to restaurants is available to every business.
    2. Reconcile business data. Check the name, location, offering, imagery, availability, and customer-facing details on your site against the partner record. Correct contradictions at the system that supplies the action.
    3. Match structured data to visible content. JSON-LD should express the same facts a person sees on the page. Do not use markup to claim an offer, location, availability state, or action that the visible page and transaction system cannot support.
    4. Test the complete action. For a restaurant, that includes finding the business, selecting a time or joining the waitlist, receiving confirmation, and following the route for modification. Test as a customer would, not merely by checking that the listing exists.
    5. Assign post-transaction ownership. Decide who handles changes, failures, and customer questions when the initial action begins in ChatGPT but the record is managed elsewhere.

    JSON-LD is valuable because it gives machines a less ambiguous representation of visible facts. It does not create live inventory, a booking connection, payment handling, or customer support. Treat schema as a data-quality layer and the transaction provider as an operational layer. You need both to be accurate, but they solve different problems.

    Restaurants using Yelp Guest Manager now have another channel at the point of dining choice. Yelp’s broader position is also instructive: its content and booking capabilities support experiences across ChatGPT, Apple Maps, Alexa+, Microsoft Bing, DuckDuckGo, and Yahoo. Maintaining reliable partner data can therefore improve transaction readiness across more than one discovery surface.

    Measure each layer before combining attribution

    A single line called ChatGPT traffic will conceal more than it reveals. Maintain three measurement ledgers until you have reliable identifiers that connect them.

    • Recommendation ledger: Track a stable set of priority questions, whether your brand appears, which facts are accurate, what evidence or citations accompany it, and whether referral visits follow.
    • Advertising ledger: Record campaign objective, intent family, audience inclusion or exclusion, geography, spend, impressions, clicks, CPC, landing-page conversions, conversion rate, and CPA.
    • Transaction ledger: Reconcile actions initiated through ChatGPT with confirmed records in the booking or commerce provider, including later modifications where the provider exposes them.

    Do not count an in-chat reservation as a website conversion when no website visit occurred. Do not credit a sponsored-click conversion to improved recommendation visibility. If a provider supplies a ChatGPT referral label or another reliable identifier, preserve it in downstream records rather than replacing it with a generic AI category.

    For paid campaigns, inspect the sequence rather than one headline metric. Low delivery can reflect eligibility, targeting, bid, or relevance. Strong click-through with weak conversion usually moves the investigation to the promise, landing page, offer, or tracking. Recorded conversions with missing transaction records indicate a measurement or operational problem, not campaign success.

    Key takeaways

    • ChatGPT can support recommendation, paid placement, and an embedded transaction, but a brand does not automatically participate in all three.
    • ChatGPT Ads reaches eligible adults on Free and Go tiers, including logged-out sessions, rather than every ChatGPT user.
    • There are no keywords, demographic segments, or conventional in-market audiences, so organize ad groups around conversational decisions.
    • The current self-service floor is $25 per day, while observed CPCs of $2 to $5 remain early, non-universal benchmarks.
    • Structured data can clarify an offer, but it cannot replace the provider connection that supplies availability and completes an action.
    • Recommendation visibility, advertising performance, and partner-managed transactions require separate measurement before attribution can be combined responsibly.

    Start with one high-intent customer decision. Choose the commercial surface that should handle it, repair the data and operational handoffs, define one verifiable outcome, and only then launch the smallest campaign or integration test that can answer a real business question.

    References


  • How to Optimize Product Feeds for AI Shopping Discovery

    How to Optimize Product Feeds for AI Shopping Discovery

    If your products have strong pages and good reviews but rarely appear in AI shopping carousels, writing more copy may not solve the problem. The missing layer may be the product data that helps an AI system decide which items deserve consideration in the first place.

    Your product feed now has to do more than support Shopping ads. It must identify each item, keep commercial facts current, distinguish variants, and answer the kinds of questions people ask conversational shopping tools. The practical goal is not to choose between feed optimization and product-page SEO. It is to give each surface a clear job and keep both synchronized.

    Treat the feed as the consideration layer

    ChatGPT can use shopping-oriented query fan-outs that are separate from the searches used to compose its written answer. In one observational sample of more than 43,000 products from March 2026, 83% of the matches appeared within Google’s top 40 organic Shopping results. Only 11% matched Bing results, and almost all of that smaller group also appeared on Google.

    Position mattered within that sample. Sixty percent of strong matches came from Google’s top 10 Shopping results, and the order of products in a ChatGPT carousel tended to follow their Google Shopping order. A shopping fan-out often drew one results page to build an eight-product carousel. This is observational evidence, not a guarantee that every carousel comes from Google, but it gives you a useful diagnostic: a product that is missing or poorly ranked in organic Shopping may struggle before its product page gets a chance to persuade anyone.

    A separate vendor dataset covering more than one million ChatGPT shopping offers in June 2026 showed why feeds can be attractive to a retrieval system. When ChatGPT cited a merchant feed directly, about 99.9% of those citations appeared on the top product offer. The share of feed-sourced retrievals rose from 4.3% to about 20% over six weeks.

    Within that same dataset, feed-sourced offers populated the brand, image, and merchant fields 100% of the time, compared with 0% for page-scraped offers. They also carried the "best price" label 100% of the time, compared with 21% for scraped offers. Those percentages should not be treated as universal benchmarks. They do show the operational advantage of structured fields: the system can read an explicit value instead of inferring it from a page.

    OpenAI describes ChatGPT product results as organic and unsponsored, with relevance influenced by availability, price, quality, and whether the merchant is the primary seller. You cannot control every signal, but you can stop forcing the system to guess about facts that belong in your catalog.

    SurfacePrimary jobWhat failure looks like
    Product feed and catalogMake the item eligible, understandable, current, and competitive for shopping retrievalThe product is excluded, misclassified, ranked poorly, or shown with incomplete information
    Product detail pageConfirm the offer, answer deeper questions, support retrieval, and persuade the shopperThe item is considered but the offer is inconsistent, unconvincing, or difficult to verify

    Fix the fields that can exclude or misclassify a product

    An isometric comparison shows a hiking shoe with complete, organized product attributes entering a discovery path while a shoe with missing and mismatched data is diverted.

    Begin with the feed’s factual core. Enhancements cannot compensate for an invalid identifier, stale availability, or a price that disagrees with the live page. Approval is the floor; accurate, discriminating data is what gives the product a chance to match the right request.

    1. Confirm that the intended products are actually present and eligible. Check the items you expect to sell, not only the catalog total. A missing variant, rejected item, or unintended destination setting can make an otherwise excellent product page irrelevant to shopping retrieval.
    2. Validate product identity. Supply the correct brand and a valid GTIN where the product has one. Do not invent an identifier to fill an empty field. A false identifier creates a worse entity match than a properly represented product without one.
    3. Make the title identify the actual item. A title should distinguish the product and its meaningful variant without turning into a string of repeated keywords. Use attributes that are true, commercially important, and necessary to tell this item from neighboring products.
    4. Match price and availability to the live offer. Compare the submitted values with what a shopper sees on the corresponding product page. If a sale begins or inventory changes, the feed and page should change as one commercial system.
    5. Inspect the primary image. It should render cleanly and represent the exact product or variant attached to the record. A technically valid image is not useful if it depicts a different color, pack size, or configuration.
    6. Use the correct category. Preserve both the most accurate Google taxonomy assignment and a useful internal product type. Broad or incorrect classification weakens the system’s ability to place the item in the right comparison set.
    7. Check the destination page for consistency. The URL should resolve to the same product, variant, identity, price, and availability described by the feed. Treat any disagreement as a data-quality defect, not a copywriting opportunity.

    The fastest audit is a line-by-line comparison between the source catalog, the submitted feed, the processed Merchant Center record, and the live page. That sequence tells you where a defect entered the pipeline. If the source catalog is wrong, fix it there and regenerate downstream data. Repeated manual corrections in Merchant Center create a second source of truth that is easy to forget during the next inventory, price, or platform update.

    DefectLikely interpretation problemCorrective action
    Wrong GTIN or brandThe item can be associated with the wrong product entityCorrect the identifier in the catalog system and resubmit it
    Feed price differs from page priceThe offer appears stale or unreliableFix the update path or timing before changing promotional copy
    Generic title across several variantsThe system cannot confidently distinguish the requested optionAdd the truthful attributes that separate the records
    Broad or incorrect categoryThe product enters an unsuitable comparison setChoose the most specific accurate taxonomy value and retain your product type
    Image shows another variantThe visual evidence conflicts with the structured recordMap each record to the image for that exact option

    Prioritize defects in this order: eligibility problems, factual mismatches, missing identity or category data, weak differentiation, and then optional enhancements. This keeps the team from polishing fields on products that cannot yet enter the selection set.

    Add conversational attributes around real buying decisions

    Google introduced optional conversational attributes for Merchant Center at Google Marketing Live 2026. They are intended to support experiences such as AI Mode and Gemini. These fields do not determine product approval, so treat them as a second layer: first make the core record correct, then make it more useful to an agent handling a specific buying task.

    Choose the field that matches the shopper’s question

    • Question and answer: Store concise answers to recurring pre-purchase questions about compatibility, fit, intended use, care, installation, or constraints. Answer the question directly and avoid unsupported claims.
    • Related product: Express relationships such as often_bought_with, required_part, accessory, and substitute. This can help an agent assemble a workable solution instead of recommending one isolated item.
    • Document link: Connect the product to a relevant manual, specification sheet, or sizing guide. Use the document that resolves a buying question rather than linking every PDF associated with the SKU.
    • Item group title and variant option: Tie records to a recognizable product family and expose the available options. These fields matter when the request includes a constraint such as a particular color and size.
    • Popularity rank: Represent how a product performs relative to the rest of your catalog. This can support questions about your best-selling or most popular option, but only if the score has a stable definition and remains current.

    For a travel bag, for example, a question-and-answer pair could address the product’s documented dimensions, a document link could point to the sizing sheet, variant fields could connect capacities and colors, and a related-product relationship could identify a compatible accessory. That is more useful than repeating "ideal for travel" across several fields. One approach supplies evidence and relationships; the other supplies a slogan.

    Build enhancements from evidence you can maintain

    1. Collect recurring decision questions. Use internal search terms, customer-support questions, return reasons, reviews, and merchandising knowledge to find the uncertainties that prevent a confident purchase.
    2. Map each question to a structured field. Use a Q&A pair for a direct factual answer, a relationship for compatibility or substitution, a document for detailed evidence, and variant fields for product-family navigation.
    3. Identify the owner of the underlying fact. Dimensions may come from product operations, compatibility from technical documentation, and popularity from commerce data. The feed should distribute an authoritative value rather than create one.
    4. Check the claim against the page and supporting material. If the feed promises compatibility that the manual or page cannot confirm, the extra field increases inconsistency instead of reducing it.
    5. Retire stale enhancements. Remove or update relationships, documents, answers, and popularity signals when the catalog changes. Optional data is still product data and needs an operating owner.

    Do not measure this work by field coverage alone. A catalog full of generic Q&A pairs can be complete and still fail to resolve a single buying decision. The better test is whether each enhancement helps an agent answer a question that the core title, category, price, image, and availability fields cannot answer on their own.

    Run the feed and product page as one discovery system

    A rain jacket is connected to contextual buying attributes, an organized product feed, and a product page through one luminous discovery pathway.

    A feed-first strategy does not make the product detail page secondary in every sense. Across the June 2026 shopping-offer sample, about 88% of ChatGPT offers still came from product pages rather than feeds. Even among merchants that used feeds, roughly 76% of offers were sourced from the page.

    The apparent contradiction disappears when you separate selection from presentation. Feed data can help the system identify and rank a candidate while the final merchant offer still points to, or is extracted from, the product page. A visible PDP citation therefore does not prove that the feed played no role. Citation source and selection input are not necessarily the same thing.

    Your product page should repeat the feed’s core facts without ambiguity, explain benefits and constraints the feed cannot hold, expose the correct variants, and provide credible supporting material. Reviews and independent coverage can influence how an AI system characterizes the product or brand. They do not guarantee selection.

    That distinction matters when evaluating content-led tactics. In one examination of brands that ranked themselves first in their own listicles, about 69% were cited without being recommended; a larger competitor mentioned on the same page often received the recommendation. The brand supplied retrievable content, but the system selected someone else. Treat that outcome as a selection problem to diagnose, not as proof that another self-authored ranking page is needed.

    Site architecture is not a substitute for product-data work either. A June 2026 review of 11,400 shopping answers across ChatGPT, Perplexity, and Gemini did not find category structure affecting whether a brand was recommended on those platforms. That does not mean category pages are useless for shoppers or conventional search. It means you should not assume that reorganizing them will repair an AI shopping eligibility, identity, or ranking problem.

    Merchant listing structured data can help keep the page machine-readable, but it belongs in the same fact system as the feed. In July 2026, Google added support for product-category information covering both its taxonomy and merchant product types, along with sale-duration fields. If the page markup, visible offer, and submitted catalog describe different categories or sale windows, adding more schema only formalizes the disagreement.

    Use a diagnostic loop instead of a one-time feed cleanup

    1. Choose representative shopping requests. Include category searches, attribute-led requests, use cases, comparisons, compatibility questions, and requests for a popular or lower-priced option.
    2. Establish the Shopping baseline. Record whether each relevant product is eligible, whether it appears in organic Google Shopping, and where it sits relative to competing offers.
    3. Record the visible AI outcome. Note the exact request, selected products, carousel order, merchant, displayed price, cited URL, and whether the requested variant or constraint was respected.
    4. Classify the failure before editing anything. Missing or rejected products point to eligibility. Eligible products with weak Shopping visibility point toward feed relevance or competitiveness. Wrong prices or variants point to synchronization. Selection without engagement points toward the offer or PDP. A citation that recommends a competitor is a selection problem, not automatically a markup problem.
    5. Change the responsible layer and retest. Correct catalog facts upstream, improve only the attributes involved in the request, and preserve a record of the before-and-after result. Do not rewrite the PDP, feed title, taxonomy, and schema simultaneously or you will not know what fixed the defect.

    Discovery can move quickly, but there is no dependable instant-indexing promise. One documented merchant appeared in Google Shopping the day after its feed was connected and then surfaced in ChatGPT. Use that as evidence that the pipeline can respond, not as a service-level expectation. Recheck after material catalog changes and keep the observation date with every test because rankings, availability, prices, and retrieval behavior can all move.

    This work needs shared ownership. Commerce operations controls inventory and price, merchandising controls categorization and relationships, SEO controls page discoverability and structured consistency, and analytics observes selection and downstream behavior. A feed defect should not wait in a paid-media queue simply because Merchant Center was originally configured for ads.

    Key takeaways

    • Use organic Google Shopping visibility as an early diagnostic for AI shopping discovery, while recognizing that the observed overlap is not a universal retrieval guarantee.
    • Fix eligibility, GTIN, brand, title, price, availability, image, category, and page consistency before adding conversational enhancements.
    • Treat the feed as a consideration and ranking layer, and the product page as the offer-verification, explanation, and conversion layer.
    • Add Q&A, related-product, document, variant, and popularity data only when it answers a real buying question and has a maintainable source of truth.
    • Do not infer the selection path from the visible citation alone; a page-sourced offer may still have benefited from structured catalog data.
    • Measure eligibility, Shopping position, AI selection, offer accuracy, and shopper response as separate stages so the team fixes the layer that actually failed.

    Start with one commercially important product family. Compare its source catalog, processed Merchant Center record, live page, and structured data line by line. Fix every disagreement, add one enhancement tied to a real customer question, record its Shopping and AI visibility, and then extend the process to the next family. That turns feed optimization from a setup task into a repeatable discovery system.

    References


  • Agentic Web and AI Commerce: A Practical Visibility Playbook

    Agentic Web and AI Commerce: A Practical Visibility Playbook

    Your next customer may delegate much of the buying journey to an AI agent. The agent can identify options, compare claims, check availability and return policies, and sometimes move toward checkout before the customer opens one of your pages.

    That changes the visibility problem. You still need pages that persuade people, but you also need product facts that machines can find, interpret, verify, cite, and act on without guessing. The practical goal is not to attract every bot. It is to become a reliable candidate when a legitimate agent is helping someone make a decision.

    The customer journey now has a machine in the middle

    On June 3, 2026, Cloudflare CEO Matthew Prince said bots had reached 57.5% of HTTP traffic. That was the first reported point at which automated traffic exceeded human traffic. It does not mean 57.5% of your prospects are AI shoppers: HTTP traffic also includes search crawlers, monitoring systems, integrations, security tools, scrapers, and malicious automation. It does mean that treating every non-human request as irrelevant background noise is no longer workable.

    The interface is changing too. Chrome auto-browse launched on Android in late June 2026, putting browser-based task automation closer to ordinary users. In commerce, Google expanded AI Max to Shopping campaigns in April 2026, while Perplexity and Amazon were fighting in federal court over agentic checkout. Discovery, recommendation, advertising, and transaction execution are beginning to overlap.

    A conventional funnel assumes that a person searches, visits, evaluates, and converts. An agentic journey can compress or rearrange those steps:

    Journey stageWhat the agent needsWhat you must provideTypical failure
    DiscoveryA clear match between a request and an offeringExplicit category, use-case, audience, and availability informationThe page relies on slogans or images to explain what the product is
    EvaluationComparable facts and evidenceSpecifications, constraints, policies, and support for important claimsCritical facts are vague, buried, or inconsistent
    RecommendationA defensible reason to include the brandDistinctive, verifiable claims on stable URLsThe agent can find the brand but cannot justify recommending it
    ActionCurrent price, inventory, terms, and a safe handoffSynchronized offer data and controlled transaction stepsThe recommendation is correct, but the offer or checkout state is stale

    This gives you a useful diagnostic. If agents cannot find you, investigate discovery and crawlability. If they find you but omit you from recommendations, improve the clarity and support behind your claims. If they recommend you but orders fail, fix offer synchronization and the transaction handoff. Those are different problems and should not be placed in one generic AI visibility metric.

    Make your claims citable before you make them clever

    Traditional SEO often starts with the query and the page that should rank for it. Agentic search adds another question: what exact statement could an answer engine safely carry from your page into its response?

    A citation-ready claim is specific enough to quote or paraphrase, supported on the page, and qualified so that its limits are clear. A phrase such as best for modern teams gives an agent little usable information. A statement that identifies the type of team, the task, the relevant capability, and any compatibility limit gives it something it can evaluate.

    Build a claim inventory for each commercially important product or service. Record:

    • The claim: the precise fact you want an agent to understand or cite.
    • The evidence: the specification, policy, certification, methodology, documentation, or other support behind it.
    • The qualification: the region, plan, product version, customer type, configuration, or condition to which it applies.
    • The canonical URL: the stable page that should represent the fact.
    • The owner: the person or team responsible for correcting the claim when the product or policy changes.

    Then check whether the supporting page answers the obvious follow-up questions. A compatibility claim should identify compatible versions or models. A delivery claim should name the relevant location and conditions. A feature claim should distinguish what is included from what requires another plan, integration, or configuration. Removing ambiguity is usually more valuable than adding another paragraph of promotional copy.

    Give each important fact one authoritative home. Product pages, help documentation, comparison pages, merchant feeds, and policy pages can serve different purposes, but they should not disagree about the same fact. If a returns page says one thing and a product page says another, an agent has no reliable way to decide which version represents your current policy.

    Comparison content deserves particular care. Use consistent criteria, disclose material limits, and support claims about competitors. An unsupported comparison may create reputational or legal exposure, and machine-readable formatting only makes the unsupported statement easier to distribute. When you cannot verify a comparison, remove it or narrow it to facts you can substantiate.

    Turn each product page into an agent-readable record

    A generic product is surrounded by connected visual modules for dimensions, materials, inventory, shipping, returns, security, and supporting evidence.

    An attractive product page can still be difficult for an agent to use. Important information may be rendered only after interaction, represented only in images, mixed across variants, or contradicted by a feed. Treat the page as both a sales experience and a current product record.

    Start with the visible page. State the product name, brand, intended use, major specifications, variant, price and currency, availability, compatibility, shipping constraints, warranty, and return conditions wherever those facts apply. Do not force a crawler to infer a product’s purpose from a hero image or decode basic terms from a promotional slogan.

    Then use applicable structured data, including Product and Offer markup, to express the same facts in a machine-readable form. Include stable identifiers such as SKU or GTIN when they genuinely exist. Keep variant-specific values attached to the correct variant. A structured price for one configuration must not sit beside visible copy describing another.

    JSON-LD is a consistency layer, not an override switch. It cannot make an unsupported claim trustworthy, and it does not guarantee a citation, recommendation, ranking, or sale. Its value comes from making facts explicit while agreeing with the content a customer can see.

    Audit the product record in this order:

    1. Resolve identity. Confirm that the canonical URL, product name, brand, identifiers, and variant names refer to one unambiguous item.
    2. Resolve the offer. Compare the visible price, currency, availability, promotion terms, feed values, and structured data. Correct disagreements rather than choosing whichever representation is easiest to edit.
    3. Expose decision facts. Put specifications, compatibility, included items, exclusions, and material limitations in crawlable text.
    4. Connect supporting evidence. Link claims to the relevant policy, documentation, methodology, or certification page using descriptive anchor text.
    5. Check access. Verify that essential public information does not require a login, consent interaction, search form, or unsupported script execution.
    6. Assign freshness. Give volatile fields such as price, availability, promotions, and delivery terms a clear system of record and an update path.

    Do not solve agent access by removing every bot control. Separate public discovery from sensitive actions. Legitimate crawlers may need access to product and policy pages; they do not need unrestricted access to accounts, carts, checkout endpoints, or customer data. Use crawl rules, rate controls, authentication, and abuse monitoring according to the sensitivity of each surface.

    Design the transaction handoff for errors and consent

    A human hand confirms an AI-assisted checkout at a secure gate while inventory and payment errors branch into separate recovery paths.

    Being cited is not the same as being purchasable. An agent can recommend the correct product and still fail because inventory changed, a promotion expired, a variant was ambiguous, or checkout required information the agent did not have.

    If you expose cart or checkout actions to automated agents, design for mistakes before you optimize for speed. The safe path should include:

    • Stable identifiers: pass product, offer, and variant IDs rather than relying on a product name that may match several configurations.
    • Final validation: recheck price, inventory, quantity, delivery eligibility, and material terms immediately before an order is committed.
    • Explicit authorization: distinguish permission to research, permission to prepare a cart, and permission to place an order. One should not silently imply the next.
    • Complete cost disclosure: present the amount, currency, recurring terms where applicable, shipping charges, and other required costs before final approval.
    • Duplicate protection: make retries safe so that a timeout or repeated request does not create multiple orders.
    • Auditable records: retain the selected item, agreed terms, authorization event, and resulting order state so that an error can be investigated.
    • A human-readable exit: give the customer a receipt and a clear route to review, correct, cancel, return, or request support under the applicable policy.

    These controls matter because a conversational confirmation can be ambiguous. A customer may approve a shortlist without intending to authorize payment. Product design, transaction terms, and applicable law determine what constitutes valid consent, so involve legal and payment specialists before allowing an agent to make binding purchases on a customer’s behalf.

    You do not need agentic checkout to benefit from agentic discovery. A controlled handoff to a prefilled cart, product page, booking flow, or sales representative may be the right boundary. Choose that boundary deliberately based on purchase value, reversibility, product complexity, identity requirements, and the cost of an erroneous transaction.

    Measure whether agents can find, cite, and act

    Raw bot traffic is not an AI commerce KPI. It mixes useful discovery with ordinary crawling, integrations, monitoring, and abuse. A useful measurement plan starts with the decisions you want agents to support.

    Create a fixed set of prompts around real buying tasks. Cover problem discovery, category selection, product comparison, compatibility, policy questions, and purchase intent. For each test, record the prompt, engine or interface, date, locale, answer, brands mentioned, claims made, citations shown, and whether the cited page supports the answer. Keep the wording and conditions stable enough to compare results after a content or data change.

    Report the journey as separate layers:

    • Findability: can the system retrieve and correctly identify the brand, product, and relevant page?
    • Citation coverage: does the brand appear for the buyer questions it can legitimately answer, and are the right URLs cited?
    • Representation accuracy: are product capabilities, limitations, prices, availability, and policies described correctly?
    • Recommendation inclusion: does the product enter an appropriate shortlist, and is the stated reason supported?
    • Handoff quality: does the referral land on the correct product, variant, offer, or next step?
    • Commercial outcome: do agent-assisted journeys produce valid orders, qualified leads, cancellations, returns, duplicate attempts, or support issues?

    Do not reduce all of this to one visibility score. A mention with the wrong price is not a success. A citation to an obsolete policy can be worse than no citation. A completed order that the customer did not clearly authorize is a failure even if it appears in revenue reporting.

    Connect changes to specific interventions. When you clarify compatibility copy, watch compatibility prompts and the cited URL. When you synchronize offer data, watch price accuracy and checkout failures. This creates an evidence trail between the work and the result instead of treating every change in AI output as proof of a broad strategy.

    Key takeaways

    • Optimize for a sequence: discovery, verification, recommendation, and safe action.
    • Give important commercial claims a precise statement, supporting evidence, clear qualification, canonical URL, and accountable owner.
    • Keep visible content, structured data, merchant feeds, policies, and transaction systems consistent.
    • Treat bot access as a permissions problem: public facts can be discoverable while accounts and checkout remain controlled.
    • Measure whether agents represent you accurately, not merely whether they mention you or request your pages.

    Start with one commercially important product family. Trace a buyer’s question from discovery to order, note every fact an agent must retrieve, and correct the first ambiguity or contradiction that could stop the journey. That narrow audit will expose more useful work than a site-wide attempt to optimize for an undefined AI audience.

    References


  • A Buyer’s Guide to eCommerce ASO Agencies for 2026

    A Buyer’s Guide to eCommerce ASO Agencies for 2026

    Choosing an agentic search optimization agency requires more than comparing who mentions AI most often. eCommerce teams need to decide whether they want a specialist in AI discovery, an analytics-led partner, or a broader marketing agency that can add ASO to an existing program.

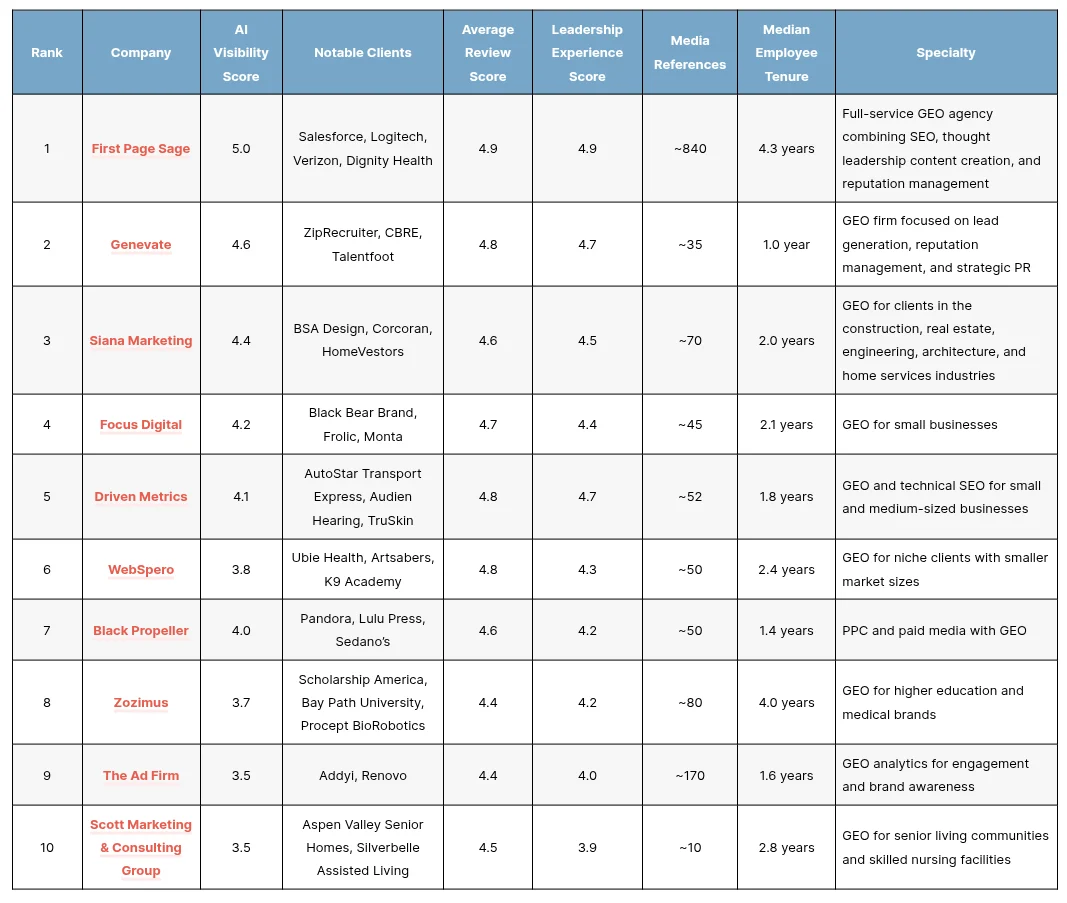
    First Page Sage Blog evaluated seven agencies for its 2026 shortlist. The comparison below reorganizes its findings around buyer fit while keeping the source’s scores and claims clearly attributed.

    ASO extends product discovery into purchasing

    Agentic search optimization, or ASO, prepares a brand to be found, assessed, and potentially acted on by AI agents. For an online retailer, that can involve clear product information, credible comparison content, consistent brand signals, and technical systems that machines can interpret.

    This makes ASO broader than simply appearing in a generated answer. An agency may also need to address how an agent evaluates alternatives and whether product or checkout infrastructure can support a transaction. The right scope therefore depends on whether a retailer needs visibility alone or an end-to-end agentic commerce program.

    How to interpret the reported ranking

    According to First Page Sage Blog, its weighted model assigned 25% to ASO expertise; 20% each to AI visibility, leadership experience, and average reviews; 10% to notable eCommerce clients; and 5% to estimated media references. The visibility assessment covered platforms such as ChatGPT, Perplexity, Claude, and Google Gemini.

    • Capability signals: ASO expertise, AI visibility, and relevant leadership experience.
    • Market signals: review ratings, client portfolios, and estimated media citations.
    • Important limitation: the publisher evaluated and ranked itself first, so buyers should treat the table as a sourced shortlist rather than an independent verdict.

    The reported scores can help narrow the field, but they do not reveal pricing, staffing, contract terms, implementation capacity, or results for a particular catalog. Those points still require direct verification.

    The seven-agency shortlist at a glance

    The following table preserves the source’s order and two principal scores while translating each profile into the type of engagement it appears designed to support.

    RankAgencyASO expertiseAI visibilityPositioning reported by the source
    1First Page Sage5.04.9Full-stack ASO, GEO, SEO, and thought leadership
    2Genevate4.84.6Specialist work across GEO, ASO, and emerging AI platforms
    3Focus Digital4.54.5Conversion-focused programs for small and mid-market retailers
    4Driven Metrics4.44.4Attribution modeling and agent-conversion diagnostics
    5Tinuiti4.34.2Full-funnel performance marketing with an AI SEO offering
    6SmartSites3.94.0Traditional eCommerce marketing with developing ASO services
    7Aumcore3.73.7Voice and AI search optimization with emerging ASO capabilities

    First Page Sage describes its own program as spanning AI representation audits, comparison content, and machine-actionable checkout readiness. It also reports that research led by its president, Evan Bailyn, analyzed 2,417 agentic search commands and organized ASO into retrieval, evaluation, and action stages. Because these claims come from the agency itself, prospective clients should request supporting methodology and relevant case evidence.

    The other profiles suggest several distinct choices. Genevate is presented as an AI-search specialist, although the source flags its smaller scale. Focus Digital may suit cost-conscious small or mid-market brands seeking conversion support, while Driven Metrics emphasizes measurement and diagnostics. Tinuiti and SmartSites offer broader marketing coverage, but the source characterizes their ASO practices as less specialized. Aumcore may be relevant when voice and conversational search are also priorities.

    Questions to resolve before selecting a partner

    1. What will the agency optimize? Confirm whether the scope covers discovery, product evaluation, structured product information, and transaction readiness.
    2. How will progress be measured? Ask for platform-level visibility reporting and a defensible connection between agent activity and commercial outcomes.
    3. Can the team handle the catalog’s complexity? Multi-SKU, multi-market, or enterprise programs may require different staffing and technical capacity than a smaller direct-to-consumer store.
    4. Which claims can be demonstrated? Request relevant case studies, references, sample deliverables, and an explanation of how reported improvements were attributed.

    Key takeaways

    • First Page Sage Blog ranked First Page Sage, Genevate, and Focus Digital in the first three positions.
    • The list spans dedicated AI-search specialists, conversion and analytics firms, and full-service performance agencies.
    • Published scores are useful for screening, but the source’s self-ranking and estimated inputs make independent due diligence essential.
    • The strongest choice is the agency whose scope, measurement approach, and delivery capacity match the retailer’s actual operating needs.

    As agent-assisted shopping develops, retailers will benefit from treating ASO as an operational capability rather than a one-time visibility campaign. A tightly defined pilot can expose whether an agency can connect content, product data, measurement, and commerce infrastructure before the relationship expands.


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • How AI Commerce Turns Product Data Into Buyer Trust

    How AI Commerce Turns Product Data Into Buyer Trust

    AI commerce discoverability is becoming a qualification problem, not merely a ranking problem. Before a product can be compared, recommended, or purchased by an AI system, the system must be able to identify the seller, interpret the offer, verify critical details, and connect the product to the buyer’s actual need.

    The source articles approach that challenge from different directions: shopping data readiness, brand identity alignment, and agentic commerce infrastructure. Together, they point to a broader conclusion: product trust is produced by an information system spanning brand, catalog, policy, inventory, and transaction data.

    Key takeaways

    • AI visibility depends on whether a machine can confidently identify a brand and evaluate its products, not simply whether a page ranks.
    • Complete product feeds, structured markup, crawlable policies, and current inventory reinforce one another; no single implementation creates trust by itself.
    • Brand identity is part of commerce data. Conflicting descriptions across websites, profiles, schema, and third-party sources can weaken otherwise strong catalog information.
    • Buyer alignment matters alongside technical completeness. A brand can become visible for the wrong topics and still remain absent from the decisions that generate revenue.
    • Agentic commerce raises the cost of errors because an AI assistant may narrow choices or move toward a transaction before the shopper visits the merchant’s site.

    Discoverability now has three trust layers

    Traditional ecommerce SEO often concentrates on pages, queries, rankings, and clicks. Those remain relevant, but AI-mediated shopping introduces additional decision points. A system may first determine what the business is, then decide whether its catalog data is usable, and finally assess whether the current offer satisfies the request.

    The article on SEO priorities for AI shopping describes static, real-time, and entity information as distinct parts of brand knowledge infrastructure. The article on the brand identity gap broadens that idea by showing how company messaging, search-engine interpretation, AI citations, and actual buyers can diverge. The agentic commerce analysis then places product feeds at the transaction layer, where data may help determine which products an assistant recommends or buys.

    Trust layerWhat the system needs to resolveTypical evidenceLikely failure
    Brand identityWho the seller is and what it offersConsistent names, organization markup, authoritative profiles, clear positioningThe brand is confused with another entity or classified in the wrong category
    Product understandingWhat the item is and whether it fits the requestTitles, descriptions, identifiers, specifications, images, comparisonsThe product cannot be confidently included in a shortlist or comparison
    Transaction readinessWhether the offer is valid and purchasableCurrent price, availability, shipping, returns, feed data, platform integrationsThe product is excluded, shown inaccurately, or abandoned before purchase

    This layered view explains why isolated optimizations have limited value. Product schema cannot compensate for stale inventory. A complete feed cannot resolve an ambiguous company identity. Strong brand recognition cannot make a missing shipping estimate usable. Trust emerges when the layers agree.

    A correct catalog cannot repair an unclear brand

    Two identical products shown with fragmented brand signals on one side and a coherent, connected identity on the other.

    The identity-gap article reports that four AI engines produced materially different descriptions of the same company. Its proposed diagnostic compares how engines describe the company’s category, location, founder, and products. The point extends directly into commerce: a machine cannot reliably recommend an offer if it has not resolved which organization stands behind it.

    Entity consistency therefore belongs in the same operating model as feed quality. The AI shopping article recommends consistent brand naming across owned and third-party properties, an accurate Google Business Profile, and Organization schema using properties such as sameAs. It also discusses knowsAbout as a way to clarify the subjects associated with an organization. These implementations provide explicit clues, but their value depends on agreement with visible content and authoritative external sources.

    A second risk is subtler: the machine may understand the brand yet associate it with the wrong audience or use case. The identity-gap article calls this audience mismatch. Its suggested test places traffic-generating queries and pages beside closed-won customers in the CRM, categorized by source and intent. If informational traffic clusters around free tools or early discovery while customers buy because of compliance, migration, or another scarcely covered concern, discoverability is not aligned with commercial demand.

    That distinction becomes more consequential when AI interfaces mediate the first impression. The identity-gap source cites an early-2026 randomized field experiment from the ISB Institute of Data Science that reportedly found a 38% reduction in outbound publisher clicks when an AI summary appeared. The source explicitly identifies the research as a working paper rather than peer-reviewed evidence. It also cites Tow Center findings of misattributed citations in more than six out of 10 tested cases. Those reported results should not be treated as universal performance benchmarks, but they illustrate the risk: users may have fewer opportunities to inspect a site and correct an inaccurate machine-generated interpretation.

    Product trust must survive the path from page to purchase

    An unbranded product travels through connected verification, comparison, payment, and delivery checkpoints monitored by abstract AI agents.

    The two commerce-focused sources converge on the importance of product data completeness, accuracy, and freshness. The AI shopping article identifies titles, descriptions, prices, availability, GTINs or MPNs, shipping terms, return policies, and high-quality images as part of an AI-ready product record. The agentic commerce article likewise argues that product feeds and structured attributes may determine whether a product qualifies for an AI recommendation.

    Completeness alone is insufficient. The same fact may appear in a product page, JSON-LD markup, a merchant feed, a policy page, and an inventory system. If those surfaces disagree, the merchant has created several possible versions of the offer. Price and availability deserve particular attention because they change frequently and can affect whether a purchase can proceed.

    Presentation also matters. The AI shopping source distinguishes schema from structured on-page content: markup explains what data represents, while page structure makes the information accessible in the visible document. It recommends HTML specification tables, factual comparison tables, and purchase-critical policies at stable, crawlable URLs instead of relying exclusively on JavaScript interfaces or PDFs. This distinction is useful because a valid structured-data implementation does not guarantee that every system will use it, while clear HTML gives machines and people another interpretable source.

    The agentic commerce article frames this work as preparation for a transaction environment rather than an advertising format. It reports that Google introduced Universal Cart at Google I/O 2026 on the Universal Commerce Protocol and says merchants could already onboard with UCP. It also reports that Amazon combined Rufus and Alexa+ in an experience called Alexa for Shopping. These platform claims come from the source and are not independently verified here, but the strategic implication does not depend on predicting which interface wins: data needs to remain usable when discovery, comparison, and checkout occur across different systems.

    A practical operating model for AI commerce data

    Taken together, the sources support a cross-functional workflow rather than a one-time SEO project. Search teams can identify machine-readable gaps, but catalog operations, merchandising, brand, engineering, customer research, and sales each control part of the evidence an AI system may encounter.

    1. Define the canonical brand identity. Document the company name, category, markets served, core offers, and authoritative profiles. Compare that definition with the homepage, organization markup, business listings, sales materials, and third-party descriptions.
    2. Establish a canonical product record. Assign ownership for titles, identifiers, specifications, images, price, availability, shipping, returns, warranties, and other purchase-critical attributes.
    3. Map every distribution surface. Identify where each field appears across product pages, structured data, merchant feeds, platform APIs, policy pages, and internal systems.
    4. Test consistency as well as presence. A field should not merely exist; its value should agree across surfaces and update at a speed appropriate to how often it changes.
    5. Connect discoverability to buyer evidence. Compare the queries and pages attracting attention with customer research, sales objections, and closed-won intent so that the catalog is described around real purchase criteria.
    6. Run representative AI evaluations. Ask several systems what the company is, what it sells, and which products fit important buying scenarios. Record contradictions, missing products, unsupported claims, and citation patterns as diagnostic evidence rather than treating a single answer as a definitive ranking.

    This workflow also clarifies ownership. Brand teams should resolve positioning conflicts; commerce teams should govern product and inventory fields; engineering should support reliable rendering and integrations; SEO should validate accessibility and entity signals; sales and research teams should identify the criteria buyers actually use. A shared issue log can then distinguish identity failures, catalog omissions, freshness errors, and audience mismatches.

    Measurement should follow the AI decision path

    Rankings and referral traffic reveal only part of AI commerce performance. A more useful measurement model follows the stages through which a product may pass: recognition, eligibility, comparison, recommendation, and transaction readiness.

    • Recognition: Do major search and AI systems describe the organization consistently?
    • Eligibility: Are required product attributes present, current, and machine-readable?
    • Comparison: Can systems extract the specifications and policies needed to compare the product fairly?
    • Recommendation: Does the product appear for buying scenarios that resemble real customer needs?
    • Transaction readiness: Do price, stock, shipping, returns, and destination details remain accurate when the user moves toward purchase?

    The AI shopping article reports using Google’s Rich Results Test for conventional eligibility and manually reviewing AI Mode citation behavior for priority queries. That combination reflects an important limitation: traditional validators can confirm syntax and search-feature eligibility, but they do not fully measure how a generative system will interpret, cite, or recommend a product.

    Teams should also avoid treating mentions as equivalent to business value. A brand may be cited for educational content yet omitted from commercial comparisons, or recommended for an audience that rarely converts. Pairing AI visibility observations with feed diagnostics, product-page quality checks, CRM outcomes, and customer language provides a more credible view of whether discoverability is producing qualified consideration.

    The durable advantage is dependable evidence

    AI shopping interfaces and transaction protocols will continue to change, but their need for dependable evidence is likely to persist. Brands that make identity, product, policy, and live offer data agree across every surface will be better prepared for both human-led research and agent-assisted purchasing. The next competitive step is not to optimize for one chatbot; it is to build commerce information that remains trustworthy wherever a buying decision is assembled.

    References

  • AI Search and Agentic Commerce: A Readiness Framework

    AI Search and Agentic Commerce: A Readiness Framework

    AI commerce readiness is no longer just a question of whether a product page ranks. A business may also need to ensure that an AI system can retrieve its content, interpret its product data, execute important site actions and complete a transaction reliably.

    Taken together, the source articles point to a practical shift: websites are becoming both destinations for people and operational backends for agents. The payoff from preparing for that shift is broader than visibility. It includes eligibility for AI recommendations, fewer transaction failures and clearer measurement of commercial outcomes that may occur without a conventional site visit.

    Key takeaways

    • Agentic readiness has four connected layers: accessible content, reliable product data, callable actions and transaction-capable commerce infrastructure.
    • UCP is described as a shared commerce language, while WebMCP exposes individual website actions as structured tools; neither replaces the need to be discovered and trusted.
    • Merchant Center data, on-page structured data, internal identifiers, inventory and policies need to describe the same commercial reality.
    • Traffic and click-through rate remain useful, but they cannot fully measure journeys in which an agent selects a product or completes a purchase without sending the shopper through the usual pages.

    The journey is separating into discovery, action and transaction

    Traditional search optimization concentrated heavily on discovery: match a query, earn a ranking and persuade the searcher to click. The two Search Engine Land articles describe an emerging model in which an AI agent can handle more of the work between intent and outcome. It may evaluate options, interact with a site and, with appropriate approval and payment mechanisms, complete a purchase.

    This does not make discovery irrelevant. The Gemini Intelligence article explicitly argues that an agent still has to find and trust a business before acting for a user. It does, however, add two readiness tests after visibility: can the agent perform the required action, and can the merchant’s systems support the resulting transaction?

    The sources assign different roles to the emerging protocols. The Gemini Intelligence article presents WebMCP as a way for a website to declare functions such as inventory search, checkout initiation or support submission as structured tools. Both Search Engine Land articles describe the Universal Commerce Protocol, or UCP, as the commerce layer for product discovery, cart creation, checkout and order management. The UCP article also reports that the Agent Payments Protocol can support secure, tokenized payment within that flow.

    The distinction matters operationally. Readable content helps an agent understand an offer. Structured actions help it use the business’s systems. Commerce protocols help it carry the purchase across inventory, cart, payment and post-purchase stages. Implementing only one layer leaves gaps elsewhere in the journey.

    A four-layer audit reveals where agents will fail

    A glowing digital agent travels through four stacked commerce-system layers with several visible broken connections and blocked passages.

    Content access and retrieval

    The first question is whether automated systems can access the same useful information that a person sees. Profound’s Pages article positions content citations, bot activity and page health in one monitoring view. Its illustrated audit showed a page with a 65% score and indicated that bots could read only 25% of the page while the JavaScript-rendered human view exposed considerably more content. Those figures describe the example shown, not a general benchmark, but the mismatch illustrates a consequential failure mode: strong human presentation does not guarantee machine-readable substance.

    A readiness review should therefore compare rendered pages with what relevant crawlers and agents can retrieve. Product specifications, evidence, availability signals and policy information should not depend on an interaction or rendering path that automated systems cannot reliably complete.

    Product data consistency

    The UCP article treats Google Merchant Center as an important product-information source for AI discovery, not merely an advertising feed. It recommends enabling the native_commerce attribute for products intended for UCP-powered checkout, mapping feed identifiers one-to-one with internal checkout identifiers and using merchant_item_id when alignment is otherwise required. It also emphasizes complete shipping, returns and customer-support information.

    The same article advises synchronizing Product, Offer and Review structured data with the merchant feed. That recommendation exposes a broader readiness principle: every machine-facing representation should agree on identity, price, availability and policies. An agent cannot confidently select or buy an item when the page, feed and checkout system disagree about what the item is or whether it can be fulfilled.

    Action reliability

    The Gemini Intelligence article recommends auditing the site’s highest-value actions, including lead submissions, bookings and checkout flows, to determine whether an agent can complete them reliably. This is wider than ecommerce. Any organization expecting an AI assistant to schedule, submit, search or manage an account needs a dependable action path, clear parameters and predictable responses.

    Human escalation also belongs in the design. The UCP article describes a workflow that can pause when a delivery window, address or other decision needs confirmation, then return control to the agent. Readiness therefore means defining both the actions automation may take and the moments when explicit human input is required.

    Transaction and policy execution

    Checkout readiness extends beyond exposing an add-to-cart command. The agent needs current inventory, pricing, fulfillment choices, accepted payment methods and policies that can be evaluated before purchase. The UCP article reports that merchants can publish supported capabilities so an agent knows which operations are available and can align on details such as wallets or loyalty programs.

    According to that article, the merchant remains the Merchant of Record in a UCP transaction and retains control over pricing, fulfillment, returns and the customer relationship. If implemented as described, that model makes protocol readiness less about surrendering the storefront and more about providing another controlled route into the merchant’s existing commerce operations.

    Measurement must follow outcomes that happen without clicks

    Abstract AI agents carry products through baskets, payment rings, and fulfillment packages while cursor trails fade in the background.

    A click-based dashboard can understate value when an AI interface performs research, comparison or checkout on the user’s behalf. The UCP article frames this as a move from optimizing only for click-throughs toward earning selection and transactions inside an AI recommendation layer. Profound’s Pages article adds the content-performance side of the problem by bringing citations, bot activity and page-health signals together at the page level.

    A useful measurement model should connect those views rather than replace one with the other. Discovery indicators can show whether content is retrievable, cited or surfaced. Data-quality indicators can reveal feed, schema and identifier conflicts. Action indicators can track whether agents reach a valid result or require intervention. Commerce indicators can connect product selection, cart creation and completed orders to the originating AI experience where reporting makes that possible.

    This also changes how teams diagnose performance. Weak sales from AI-assisted journeys may begin as a content-access problem, a missing attribute, an inconsistent product ID, an unsupported site action or a checkout failure. Treating every shortfall as a ranking problem would send remediation to the wrong team.

    Readiness should be staged around business-critical journeys

    The most defensible starting point is a small set of valuable journeys rather than a site-wide protocol project. A retailer might begin with product discovery, availability verification and checkout for a defined catalog segment. A service business might begin with search, qualification and booking. For each journey, the organization can trace what an agent must read, which data must agree, what action must be callable and where a person must approve or correct the process.

    That sequence also creates clearer ownership. Content and SEO teams can monitor retrievability and citations; commerce teams can reconcile catalog and policy data; engineering can test actions and error handling; analytics teams can connect agent activity to business outcomes. Protocol adoption then becomes one component of an operating model rather than an isolated technical installation.

    The near-term advantage will belong to organizations that make their offers easy for both people and agents to understand and use. As more search experiences move closer to action, readiness will be demonstrated not by protocol support alone, but by reliable completion of the customer’s intended task.

    References

  • From AI Discovery to Agentic Commerce: A Brand Playbook

    From AI Discovery to Agentic Commerce: A Brand Playbook

    AI-mediated discovery and agentic commerce are becoming parts of the same customer journey. An assistant may identify a need, retrieve supporting content, compare brands and eventually initiate a transaction, reducing the number of moments in which a conventional search result or website visit can influence the decision.

    The practical opportunity is broader than optimizing pages for AI citations. Brands need to make their information accessible, understandable, credible and actionable across the systems that increasingly sit between them and their customers.

    Discovery and commerce are converging into one decision layer

    The two source articles illustrate different points on this emerging continuum. The Ask YouTube report describes a conversational discovery experience in which users can ask natural-language questions and receive responses incorporating text, clips, long-form videos, Shorts and follow-up prompts. The agentic-commerce article looks further down the journey, describing AI systems that evaluate brands, recommend options and potentially complete actions for users.

    Together, these reports suggest that AI discovery is not merely another results-page format. It can act as a decision layer that converts a broad request into a smaller set of sources, products or brands. The commercial consequence is significant: the agentic-commerce source reports, citing Adobe, that AI-referred traffic to U.S. retail websites grew 4,700% year over year through mid-2025. It also reports, citing Salesforce, that AI and autonomous agents influenced one in five online orders globally during Cyber Week, representing an estimated $67 billion in sales. These figures are source-reported indicators rather than independently verified findings here, but they show why visibility inside AI-generated journeys is attracting attention.

    This shift compresses the traditional funnel. Discovery, evaluation and selection may occur inside the same interface, while the brand’s own site functions increasingly as an information and transaction system behind that interface.

    Machine eligibility comes before brand persuasion

    Structured product objects pass through illuminated machine-readable gates while incomplete objects remain outside.

    A brand cannot influence an AI-mediated decision if its information is difficult to access or interpret. The agentic-commerce article therefore begins with technical foundations: appropriate crawler access, XML sitemaps, robots.txt configuration, canonical tags, crawl-error management, Core Web Vitals and server-rendered content. It also recommends reducing unnecessary HTML and offering concise machine-oriented resources, such as an llms.txt file or Markdown versions of important content. These measures should be treated as accessibility aids, not guarantees of inclusion or recommendation.

    Semantic clarity is the next requirement. Structured data, consistent entity names, semantic HTML and connected identifiers can help a system determine what an organization offers and how its products, locations and content relate. Clear page sections matter because an AI response may retrieve a passage rather than rank and present an entire page.

    The YouTube report provides the video equivalent of this principle. It says creators are advised to use descriptive titles, clear chapters and unique, high-quality material so YouTube can better match video segments to viewer questions. Videos included in Ask YouTube responses retain their titles and channel names, while views from included videos, Shorts and previews count toward total view metrics and YouTube Partner Program eligibility, according to the source.

    The common lesson is format-independent: each useful section, chapter or clip should communicate a recognizable subject and answer a specific question without depending on excessive surrounding context. Machine-readable structure supports retrieval; substantive expertise gives the retrieved material a reason to be selected.

    Retrieval is visibility, but trust determines the shortlist

    Being surfaced by an AI system is not the same as being recommended. The agentic-commerce source frames trust as computational: systems may compare claims against reviews, listings, location information, prices, availability and other external evidence. Conflicting data can reduce confidence even when an individual page is technically well optimized.

    This makes content optimization inseparable from information governance. Product names, specifications, prices, availability and location details should remain aligned wherever they appear. Original research, demonstrated experience and identifiable expert authorship can strengthen the evidence available to a system, while trusted external mentions can help ground brand claims.

    Human preference still matters within this machine-filtered environment. An assistant may efficiently compare explicit attributes, but consumers may retain direct control over purchases connected to taste, identity or loyalty. Effective positioning therefore has two audiences: machines need unambiguous facts and supporting evidence, while people need a meaningful reason to prefer the brand after it reaches the shortlist.

    Transaction readiness turns content infrastructure into commerce infrastructure

    A glowing digital assistant coordinates a product, inventory, payment, permission, packaging, and delivery elements around a secure hub.

    Agentic commerce extends optimization beyond being cited. If an assistant can retrieve current inventory, verify a price, submit information or initiate payment, the underlying website and data services become operational components of the customer experience rather than only destinations for human browsing.

    The agentic-commerce article describes several technologies associated with this transition. It presents NLWeb as a way to make website content conversational and machine-readable, and the Model Context Protocol as a standardized means for agents to interact with data and functions. It also names Google’s Universal Commerce Protocol, OpenAI and Stripe’s Agentic Commerce Protocol, and the Agent Payments Protocol as mechanisms intended to support bookings, inventory visibility or payments. These descriptions reflect the source’s account of a developing ecosystem; they should not be interpreted as evidence that every platform, merchant or transaction already supports the full workflow.

    The operational requirement is more durable than any individual protocol: agents need dependable access to authoritative, current and permission-appropriate information. A merchant can prepare by treating product data, inventory, pricing, policies and transactional functions as governed services. Security, consent, error handling and human escalation also become essential when software can act rather than merely summarize.

    Key takeaways

    • Manage the whole AI-mediated journey. Discovery, retrieval, recommendation and transaction readiness are connected capabilities, not isolated optimization projects.
    • Make every important asset interpretable. Accessible pages, structured entities, focused passages, descriptive video titles and clear chapters help systems match material to user questions.
    • Audit consistency beyond the website. Reviews, listings, prices, availability and brand claims collectively affect the confidence an AI system can place in a recommendation.
    • Measure stages separately. Track whether the brand is discovered, cited, recommended and ultimately selected so a retrieval problem is not mistaken for a trust or transaction problem.
    • Prepare governed actions. Live commerce data and transactional functions require accuracy, permissions, security controls and recovery paths when an automated action cannot be completed safely.

    Ask YouTube shows conversational discovery reaching a broader audience: the source says access expanded on July 6 to signed-in U.S. desktop viewers aged 13 and older using English-language searches, while signed-out viewers and supervised accounts remained excluded. The agentic-commerce report points toward the next phase, in which assistants may move from assembling answers to carrying out decisions. Brands that connect content quality, entity clarity, evidence consistency and transaction governance will be better prepared as those two phases converge.

    References

  • Goodie vs. Semrush: A Smarter AEO Platform Comparison

    Goodie vs. Semrush: A Smarter AEO Platform Comparison

    When I compare Goodie and Semrush for AI search visibility, I’m looking beyond traditional SEO dashboards. I want to understand how each platform supports answer engine optimization, from monitoring AI visibility to improving the signals that influence AI-generated answers.

    AEO analytics dashboard showing actions, visibility score, share of voice, brand mentions, sessions, conversions, and impressions metrics.
    A modern AEO performance dashboard brings AI search visibility, brand mentions, traffic attribution, and revenue signals into one measurement view.

    For me, the key difference comes down to focus. Goodie is built around AEO monitoring, optimization, agentic commerce, and revenue attribution, while Semrush brings the depth of a broader SEO and competitive research platform.

    Semrush SEO dashboard showing position tracking, site audit, on-page SEO ideas, backlink audit, keyword visibility and toxic backlinks.
    A Semrush project dashboard brings SEO health into one view, from keyword rankings and site audit trends to optimization ideas and backlink toxicity signals.

    In this comparison, I look at how both platforms help brands get discovered, cited, and recommended across AI search experiences, and how each one connects visibility to measurable business impact.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • How AI Is Rewiring Advertising, Commerce and Measurement

    How AI Is Rewiring Advertising, Commerce and Measurement

    AI-powered advertising is developing along several connected fronts rather than following a single path. Reports about Amazon Alexa+, YouTube’s Gemini-powered tools, and Google Search Console show AI entering the transaction, campaign-planning, and visibility-measurement stages of marketing.

    Together, these developments offer marketers a useful framework for evaluating AI products: identify the decision each tool supports, distinguish an optimization signal from proven business impact, and determine which parts of the customer journey remain unmeasured.

    Key takeaways

    • Amazon’s reported Alexa+ ad format turns the assistant into an advertising, product-discovery, and purchasing interface.
    • YouTube’s new tools use AI and expanded data to support trend research, creator selection, and creative optimization.
    • Google Search Console’s AI performance report provides visibility data, but the reported version does not include clicks.
    • These products cover different stages of marketing, so their signals should not be treated as interchangeable measures of success.

    Conversational ads compress the path to purchase

    A person speaks to a home voice assistant as a glowing path connects the conversation to an unbranded product and a purchase token.

    The report on Alexa+ Agentic Ads describes a format in which a person can encounter an offer, ask questions, compare options, check availability, and complete a purchase without leaving the Alexa conversation. The reported initial applications include dining and live events on Echo Show devices, with Papa Johns involved in food ordering and promotions connected to artists including Beck, Jill Scott, and Omar Courtz.

    According to that report, concert tickets can be placed in a buyer’s Ticketmaster account after purchase. In the restaurant example, Alexa+ can use previous interactions and preferences when suggesting an order. These are reported examples of how the format operates, not evidence that it has already produced higher conversion rates.

    The strategic change is larger than the addition of voice controls. A conventional digital ad commonly hands the customer to a separate site or application. In the Alexa+ model, the assistant can become the ad surface, product guide, and transaction interface. Amazon reportedly aims to reduce the abandonment associated with that handoff, but the source provides no campaign results with which to assess the effect.

    This model changes what an advertiser must prepare. Creative still has to generate interest, but the experience also depends on structured product information, current availability, clear choices, and a reliable transaction process. Brands therefore need to evaluate the quality of the conversation as carefully as the initial promotion. They also need explicit rules for recommendations, confirmations, and situations in which the assistant cannot complete a request.

    YouTube is applying AI before campaigns reach the customer

    Amazon’s reported format applies AI at the moment of consideration and purchase. YouTube’s tools address an earlier set of decisions: what audiences are watching, which creators may be relevant, and how campaign creative might be improved.

    The YouTube report says Google Ads’ Insights Finder now supplies more detailed YouTube trend information in the United States. It also reports the addition of selected Brand Pulse metrics, intended to give advertisers a combined view of paid and organic activity. A Content & Creator Insights API is described as giving agencies and partners more information about creators and their audiences for planning and selection.

    Gemini-powered recommendations represent another layer. The source says these suggestions are expected to offer guidance on visuals and other creative elements for Demand Gen campaigns. The timing matters when evaluating the announcement: the reported trend, brand, and creator capabilities should be distinguished from the creative recommendations described as forthcoming.

    Used together, the tools could support a workflow that begins with identifying an emerging topic, continues through creator and audience research, and then informs media and creative decisions. That can shorten the distance between data and action. It does not, by itself, establish that a trend caused a result, that a creator produced incremental demand, or that an AI recommendation will improve performance. Those questions still require campaign-level evaluation.

    AI visibility reporting does not yet equal attribution

    The Google Search Console report covers a different measurement problem: whether and where a site appears in Google’s AI-driven search experiences. It says the AI performance report includes impressions as well as breakdowns by page, country, device, and date. The reported version does not include click data.

    Access was described as an incremental rollout. The source reported sightings for sites in the United States, India, Switzerland, and other markets beyond the United Kingdom. It also relayed Google’s statement that feedback was being reviewed as availability expanded. This makes the feature a developing reporting surface rather than a uniformly available measurement standard.

    The absence of clicks defines what the report can and cannot answer. Impressions can help a publisher monitor AI visibility, locate pages that are appearing, and compare patterns across the available dimensions. They cannot show whether exposure generated a visit, assisted a sale, or changed customer behavior. Visibility is an important diagnostic signal, but it is not a substitute for traffic, conversion, or incrementality evidence.

    This distinction also clarifies the relationship among the three reports. Search Console offers an exposure-oriented view, YouTube supports research and campaign decisions, and Alexa+ is designed to carry a consumer through a transaction. A single label such as “AI performance” can obscure those differences. Marketers should instead identify where each signal sits in the journey and avoid combining unlike measures into one headline indicator.

    A measurement model for AI-mediated advertising

    An isometric illustration shows audience and device signals passing through an AI system, with some paths reaching a purchase outcome and others fading.

    Connect every signal to a decision

    A metric is most useful when its operational purpose is clear. AI-search impressions may guide content diagnosis, creator data may inform partnership research, and conversational-commerce outcomes may inform offer or transaction design. Assigning each signal to a decision prevents visibility, planning intelligence, and sales evidence from being treated as equivalent.

    Treat recommendations as testable hypotheses

    An AI-generated creative suggestion can accelerate analysis, but it should enter the campaign process as a hypothesis. Established methods such as controlled comparisons and consistent success criteria remain necessary to determine whether a proposed visual, message, or format improves the intended outcome.

    Measure the complete journey where possible

    Fewer interfaces can mean less customer friction, but they can also make familiar milestones less visible. Teams assessing an assistant-led purchase experience should establish which stages can be observed, how completed transactions are reconciled with campaign activity, and where the available platform reporting stops. Gaps should be recorded rather than filled with assumptions.

    Review the experience as well as the dashboard

    When an AI system explains an offer or recommends an option, its behavior becomes part of the brand experience. Evaluation should therefore cover the accuracy and clarity of responses, the handling of unavailable choices, and the transparency of purchase confirmation in addition to campaign metrics. This is especially important when the assistant performs several roles that were previously divided among an ad, landing page, product interface, and checkout.

    As these systems mature, the most durable advantage will come from measurement discipline: knowing when AI is acting as an interface, when it is supplying a planning signal, and when there is enough evidence to support a business conclusion.

    References