Tag: AI Recommendations

  • Human Accountability in AI-Assisted Marketing Decisions

    Human Accountability in AI-Assisted Marketing Decisions

    An AI assistant has given your team a confident plan: publish more pages, change the message, and redirect resources toward the tactics it predicts will work. The output is polished enough to put into a deck. The hard question is whether anyone can explain why it fits your customers, constraints, and sales process – and who will answer for the result.

    Human accountability does not mean doing every marketing task manually. It means a qualified person owns the decision, verifies the supporting evidence, controls what gets released, and follows the outcome. That operating discipline lets you use AI for speed without quietly allowing it to become the decision-maker.

    Draw the line between AI assistance and decision authority

    AI can propose options, organize information, expose questions, transform approved material, and accelerate production. A person should retain authority over positioning, priorities, investment, customer promises, and the criteria used to judge success. Those decisions depend on context a generic model response may not contain. A recommendation can sound sensible while omitting something as basic as how customers buy.

    Use consequences, not content format, to decide how much oversight is required. A short tagline can be consequential if it changes the promise your brand makes. A long set of ad variations can be relatively contained if every option stays within an approved offer, audience, and call to action.

    • Execution support: AI formats approved information, groups data, creates variants, or produces a first-pass outline. The task owner checks accuracy and adherence to the brief.
    • Recommendation support: AI diagnoses a problem, ranks opportunities, or proposes a campaign change. A subject-matter owner inspects the evidence, assumptions, business fit, and test design before acting.
    • Consequential decisions: The work changes positioning, budget, material claims, customer experience, or a large part of the website. An experienced marketer explicitly approves, modifies, or rejects the recommendation.

    Accountability includes more than final approval. The human owner must define the problem, set the constraints, decide what evidence counts, and remain responsible after launch. If the only explanation for a choice is that AI recommended it, no accountable marketing decision has actually been made.

    Assign AI work only to people who can evaluate it

    Before assigning a task to AI, ask whether the designated reviewer could evaluate the result without the tool. They do not need to produce it at the same speed. They do need enough knowledge to detect a missing assumption, an unsupported claim, an unsuitable tactic, or a recommendation that conflicts with how the business operates. Access to a tool is not a substitute for understanding the work it performs.

    Consider a recommendation to increase website traffic. A competent reviewer will ask who currently visits, which visitors are relevant, what they do after arriving, and whether the offer is clear. More traffic will not repair a weak explanation, attract the right buyer automatically, or make an unclear next step easier to find.

    The same test applies when AI proposes a large SEO or GEO content program. The reviewer must be able to distinguish a genuine information gap from a request to produce more pages. If nobody can explain which audience needs each page, what decision it helps them make, and why existing content cannot do the job, the team is not ready to approve the plan.

    Give every AI assignment a review brief before prompting. At minimum, record:

    • The business problem the work is meant to solve.
    • The intended audience and the relevant stage of its buying journey.
    • The approved facts, offer, positioning, and operational constraints.
    • The outcome that would count as an improvement.
    • The claims, promises, or changes that are outside the assignment.
    • The person qualified to review and release the work.

    If you cannot name a qualified reviewer, narrow the assignment, obtain the missing expertise, or keep the work out of production. A more elaborate prompt does not repair a missing accountability structure.

    Put every AI recommendation through a human review gate
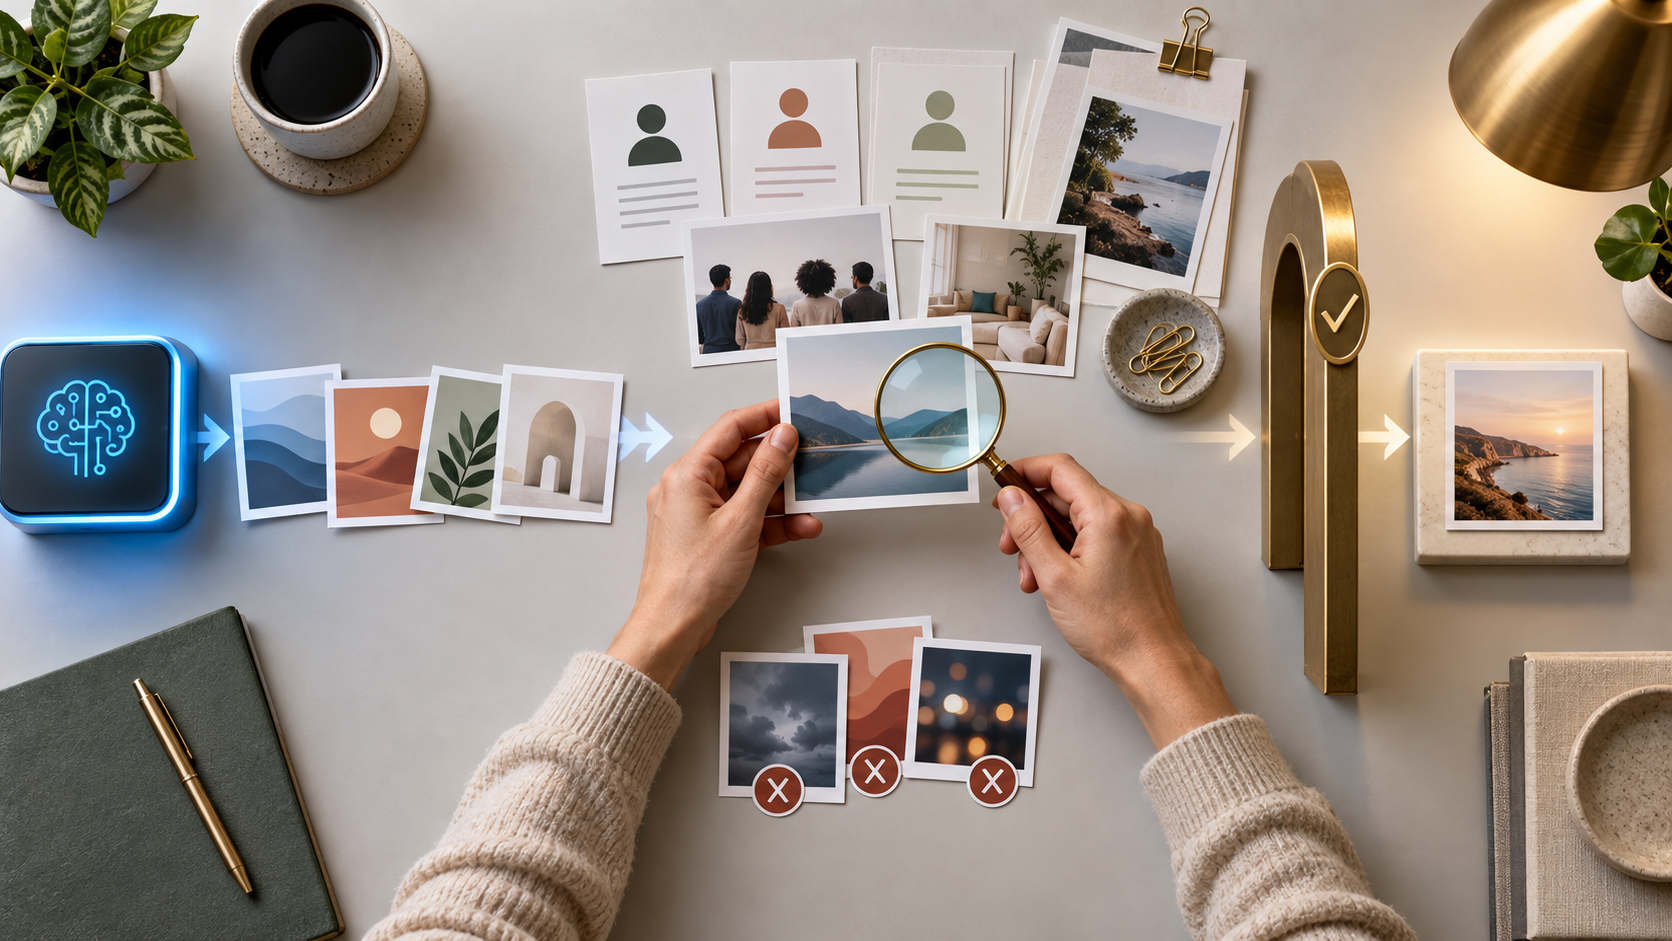
    Hands verify AI-assisted campaign materials against research before one item passes through a physical review gate.

    A consistent gate prevents fluent output from slipping directly into campaigns, content, or site changes. Use the following sequence for recommendations that affect performance, spend, public claims, or customer-facing experiences.

    1. Name the owner before reviewing the answer. Identify the person who can approve, modify, or reject the recommendation. The AI system is a contributor, not the owner.
    2. Restate the business problem. Write it without mentioning AI or the proposed tactic. There is an important difference between users not understanding a service and a perceived need to publish more content. The first is a problem; the second is only one possible response.
    3. Expose the missing context. Check the target customer, sales cycle, available budget, team capacity, current performance, brand position, and delivery constraints. A valid tactic can still be wrong for the organization expected to carry it out.
    4. Inspect the evidence. Ask AI to identify the basis for its recommendation and disclose important assumptions. Open the cited material and determine whether it supports the specific advice. A citation must be read and checked for relevance; the presence of a link is not proof.
    5. Check operational truth. Reject copy that promises something the business cannot deliver. Confirm product facts, audience fit, availability, approval requirements, and any regulated or contractual language with the appropriate human owner.
    6. Convert the recommendation into a bounded test. State the expected effect, the measurement, the review point, and the smallest reversible scope that can produce useful evidence. Do not make a site-wide change when a limited set of pages can test the same premise.
    7. Record the decision and follow-up. Note whether the recommendation was approved, modified, or rejected; why that choice was made; what changed; and who will review the result. This keeps later analysis from turning into guesswork.

    Timing must reflect the actual buying process. If a service typically takes six months to purchase, judging a campaign after several weeks only by closed sales would ignore how that business wins customers. Early evaluation should examine the relevant conversations and buying activity while preserving a defined point at which the investment will be reconsidered. Patience is not permission to spend indefinitely.

    A compact decision record

    The record can live beside the campaign brief, content ticket, or website change log. A short, specific entry in each field is more useful than a long narrative nobody will revisit.

    FieldWhat to record
    OwnerThe person accountable for approval and follow-up.
    Business problemThe customer or performance problem, stated independently of the proposed tactic.
    AI contributionWhat the system generated, analyzed, summarized, or recommended.
    Context and assumptionsThe audience, sales process, resources, constraints, and uncertain premises that affect the decision.
    Evidence checkedThe material a human opened and reviewed, plus any gaps that remain.
    DecisionApproved, modified, or rejected, with a concise reason.
    Test and measureThe change being tested, expected effect, metric, and bounded scope.
    Review pointWhen the result will be assessed and who will assess it.

    Match the control to the marketing assignment
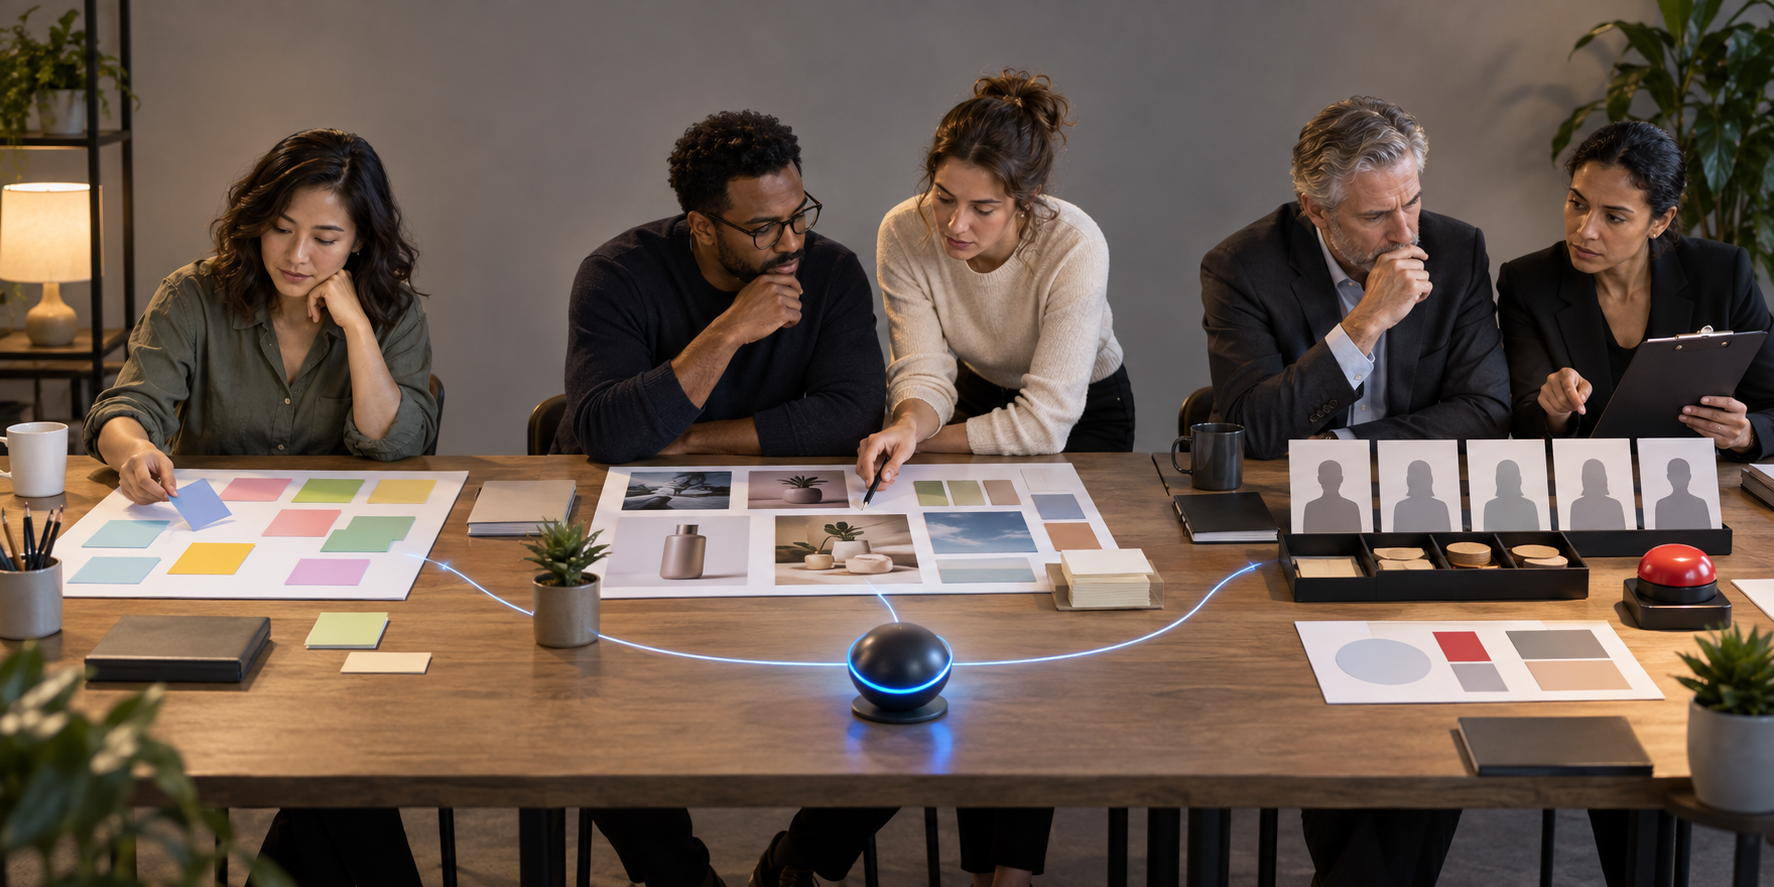
    Three marketing assignments receive progressively stronger human oversight as their potential risk increases.

    Not every task needs the same process. The useful question is what the model can contribute safely and what judgment must remain with a person who understands the subject and the consequences.

    AssignmentUseful AI roleRequired human release check
    Ad and tagline variationsGenerate alternatives within an approved offer, audience, and action.Reject inaccurate claims, off-brand language, and promises the business cannot deliver.
    Expert or thought-leadership contentDevelop questions, organize an outline, expose gaps, or improve readability.A subject-matter reviewer owns the reasoning, factual accuracy, citations, usefulness, and voice.
    SEO or GEO content planningGroup themes, propose hypotheses, and identify possible information gaps.Confirm a real audience need, a distinct purpose for each page, and a connection to the business problem.
    JSON-LD and schema generationDraft markup from approved page information and a defined entity model.Confirm that every entity, relationship, and claim matches the visible content and the real business, then validate the markup before deployment.
    Positioning, priorities, and budgetOrganize evidence, surface assumptions, and compare scenarios.An experienced marketer makes and signs off on the decision after considering customer knowledge, resources, sales process, and consequences.

    Generation and approval should be separate acts even when the same person performs them. First ask the model for possibilities. Then review those possibilities against the brief and evidence. You do not owe an AI-generated option a place in the final work merely because it is fluent.

    Substantive content needs more than a readability pass. An editor can improve a sentence without knowing whether its conclusion is true, distinctive, or useful. Someone familiar with the subject must evaluate the substance and stand behind what is published.

    Search recommendations deserve the same discipline because a weak premise can create work across an entire site. When AI proposes more pages, require an intended reader, a missing question, a reason the existing site cannot answer it, and a useful next step. Investigate whether relevant visitors already lack a clear service explanation or path to contact before committing the team to a larger publishing schedule.

    For structured data, technical validity is only one part of approval. Perfectly formatted markup can still describe the wrong entity or repeat an unsupported claim. The accountable reviewer must check semantic truth as well as syntax. That is the difference between automating production and automating judgment.

    Key takeaways

    • Let AI generate, organize, and challenge ideas, but give a named person authority over consequential marketing decisions.
    • Do not assign AI work unless someone with relevant knowledge can evaluate its substance, not merely its tone or formatting.
    • Treat model confidence as presentation, not evidence. Check cited material, assumptions, and business fit yourself.
    • Test consequential recommendations within the smallest useful, reversible scope before applying them across campaigns or websites.
    • Keep a decision record that states the problem, owner, evidence, choice, change, measurement, and review point.
    • Judge performance against the real sales cycle and customer journey, not the speed with which AI produced its recommendation.

    For your next AI-assisted task, start before the prompt. Name the owner, write the business problem, define the release check, and decide how the result will be tested. Then let AI work inside those boundaries. If your team cannot fill in those fields, pause the assignment: the missing input is not another prompt but accountable human judgment.

    References


  • How to Win Visibility in Agent-Driven Search

    How to Win Visibility in Agent-Driven Search

    Your page can rank first and still lose the customer. In agent-driven discovery, a person can ask an AI assistant to find, compare, book, buy, or contact a provider. The agent may evaluate several businesses and complete the task without sending that person through a familiar results page.

    That changes the visibility problem. You still need to be found, but you also need to survive qualification, support verification, and offer a safe path to action. The practical goal is not merely to appear in an answer. It is to remain the best eligible choice all the way through the agent’s workflow.

    Search visibility now has four separate gates

    An agent commonly turns a delegated request into requirements, searches for possible candidates, evaluates each candidate against those requirements, checks important claims, and then attempts the requested action. A conventional ranking affects the candidate-gathering stage, but it does not settle the final decision.

    GateQuestion the agent must resolveWhat your site needs to provideUseful metric
    RetrievalCan I find this business for the delegated task?Indexable pages, unambiguous entities, relevant task language, and clear topical coverageCandidate appearance rate
    QualificationDoes it satisfy every non-negotiable requirement?Explicit capabilities, limits, prices, locations, eligibility rules, integrations, and availabilityHard-requirement pass rate
    SelectionIs it the best fit among the eligible choices?Suitability guidance, evidence, differentiators, and independently verifiable claimsSelection share when retrieved
    CompletionCan I safely perform the requested action?A usable form, booking flow, checkout, approved API, or clearly defined human handoffSuccessful action rate

    Ranking remains important because it helps a brand enter the candidate set. It is no longer a reliable proxy for winning the decision. First Page Sage reported that, in its vendor-led analysis of 2,417 agentic commands issued from March 4 through June 10, 2026, the first-ranked result was selected 44.6% of the time, while a result ranked fourth or lower was selected 38.2% of the time. Those figures are directional rather than universal benchmarks: they come from one commercial analysis, and agent behavior can differ by platform, category, request, and user context.

    The useful conclusion is narrower and more durable: rank and selection are different outcomes. If your reporting stops at impressions, positions, and clicks, you cannot tell whether an agent failed to retrieve your brand, rejected it on a requirement, distrusted a claim, or could not complete the transaction.

    Give each gate its own metric. Candidate appearance rate tells you whether discovery is working. Hard-requirement pass rate exposes missing or disqualifying facts. Selection share tells you whether the agent prefers you after finding you. Successful action rate reveals whether your conversion path works for an automated assistant. A single visibility score hides all four failure modes.

    Publish the facts agents need to qualify you

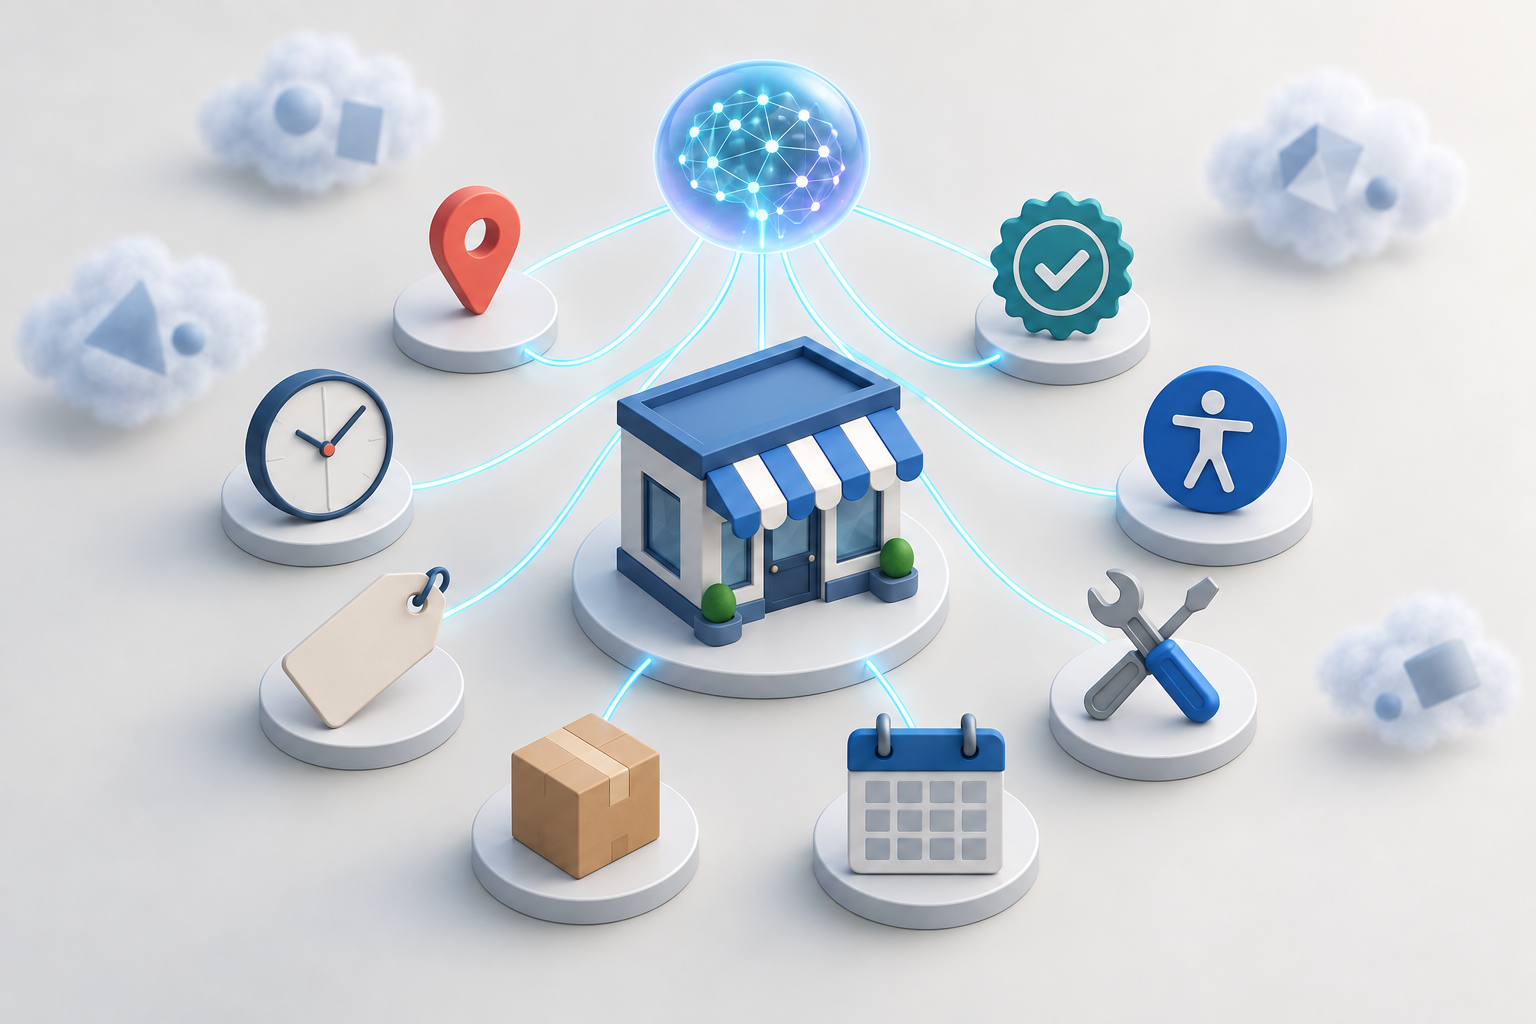
    A central business model is connected to visual modules for location, hours, price, availability, services, accessibility, and verification.

    A broad category page may rank for “payroll software,” “family hotel,” or “commercial electrician” while giving an agent too little information to answer a constrained request. Real delegated tasks include conditions: company size, location, budget, dates, integrations, accessibility needs, service area, cancellation terms, or regulatory requirements.

    Agents can treat those conditions differently. A hard requirement eliminates a candidate. An important requirement carries substantial weight. A nice-to-have breaks a close comparison. An optional feature may add only a small advantage. Your first content job is to discover which facts occupy each tier for the buying tasks that matter to your business.

    1. Choose a delegated commercial task. Use a task tied to revenue, such as booking a service, selecting a product, requesting a proposal, or arranging a demonstration. Commercial requests deserve priority because delegated agent activity is more concentrated around buying, booking, and hiring than around general informational searches.
    2. Write down the complete requirement set. Use actual sales questions, support tickets, requests for proposals, on-site searches, form responses, and objections. Separate non-negotiable conditions from preferences instead of treating every feature as equally important.
    3. Map every hard requirement to a canonical page. The answer should be stated directly, not buried in a brochure, image, unsupported comparison chart, or sales-only conversation.
    4. Add suitability content. Explain who the offer is for, who it is not for, which situations it supports, what prerequisites apply, and where its limits begin.
    5. Keep consequential facts synchronized. Prices, regions, availability, policies, product names, and eligibility rules should not conflict across product pages, help content, structured data, directories, and partner profiles.

    Use a suitability page pattern that answers the whole decision

    A useful suitability page is not another generic “why choose us” page. It should let a machine or a person decide whether your offer fits a specific situation. A practical structure is:

    • Best fit: the customer, use case, location, scale, or conditions the offer is designed for.
    • Required conditions: prerequisites the customer must meet before buying, booking, or applying.
    • Supported requirements: the capabilities, integrations, service areas, configurations, or policies that satisfy common constraints.
    • Limitations: unsupported scenarios, exclusions, capacity boundaries, dependencies, and cases that require a different offer.
    • Commercial facts: visible pricing where possible, or a precise explanation of what determines price; availability; fees; cancellation terms; and what happens after submission.
    • Evidence: links to documentation, policies, certifications, product details, or independent material that substantiates consequential claims.
    • Next action: a clear route to buy, book, request a quote, schedule a demonstration, or move to a human review.

    Dedicated suitability content is worth testing even if it attracts little conventional search volume. In the same vendor analysis, businesses with this kind of content were selected 2.7 times as often as equally ranked businesses without it. That multiplier should not be treated as a guaranteed result, but the mechanism is sensible: explicit fit information reduces the inference an agent must make.

    Make proof machine-readable without hiding caveats

    Relevant JSON-LD can express your organization, offer, product or service, availability, and other supported attributes in a consistent format. Use it to clarify facts already visible on the page. Do not use markup to introduce claims, prices, ratings, availability, or capabilities that a visitor cannot confirm in the page content.

    Structured data reduces ambiguity; it does not establish truth. Agents may compare a site’s claims with what they already know and with independent material before choosing a candidate. Make important assertions easy to verify by identifying what the claim applies to, where it applies, and under which conditions. A sentence such as “integrates with accounting software” is weak. A maintained integration page that names the supported systems, required plan, setup path, and current limitations is decision-grade evidence.

    Consistency matters here. Use the same business name, canonical URL, product names, locations, and core offer descriptions wherever you control the information. When a third-party profile is outdated, correct it. When a claim changes, update the visible page and its markup together. Contradictory facts force an agent to decide which version to trust, and the safest decision may be to exclude the candidate.

    Remove the blockers between selection and completion

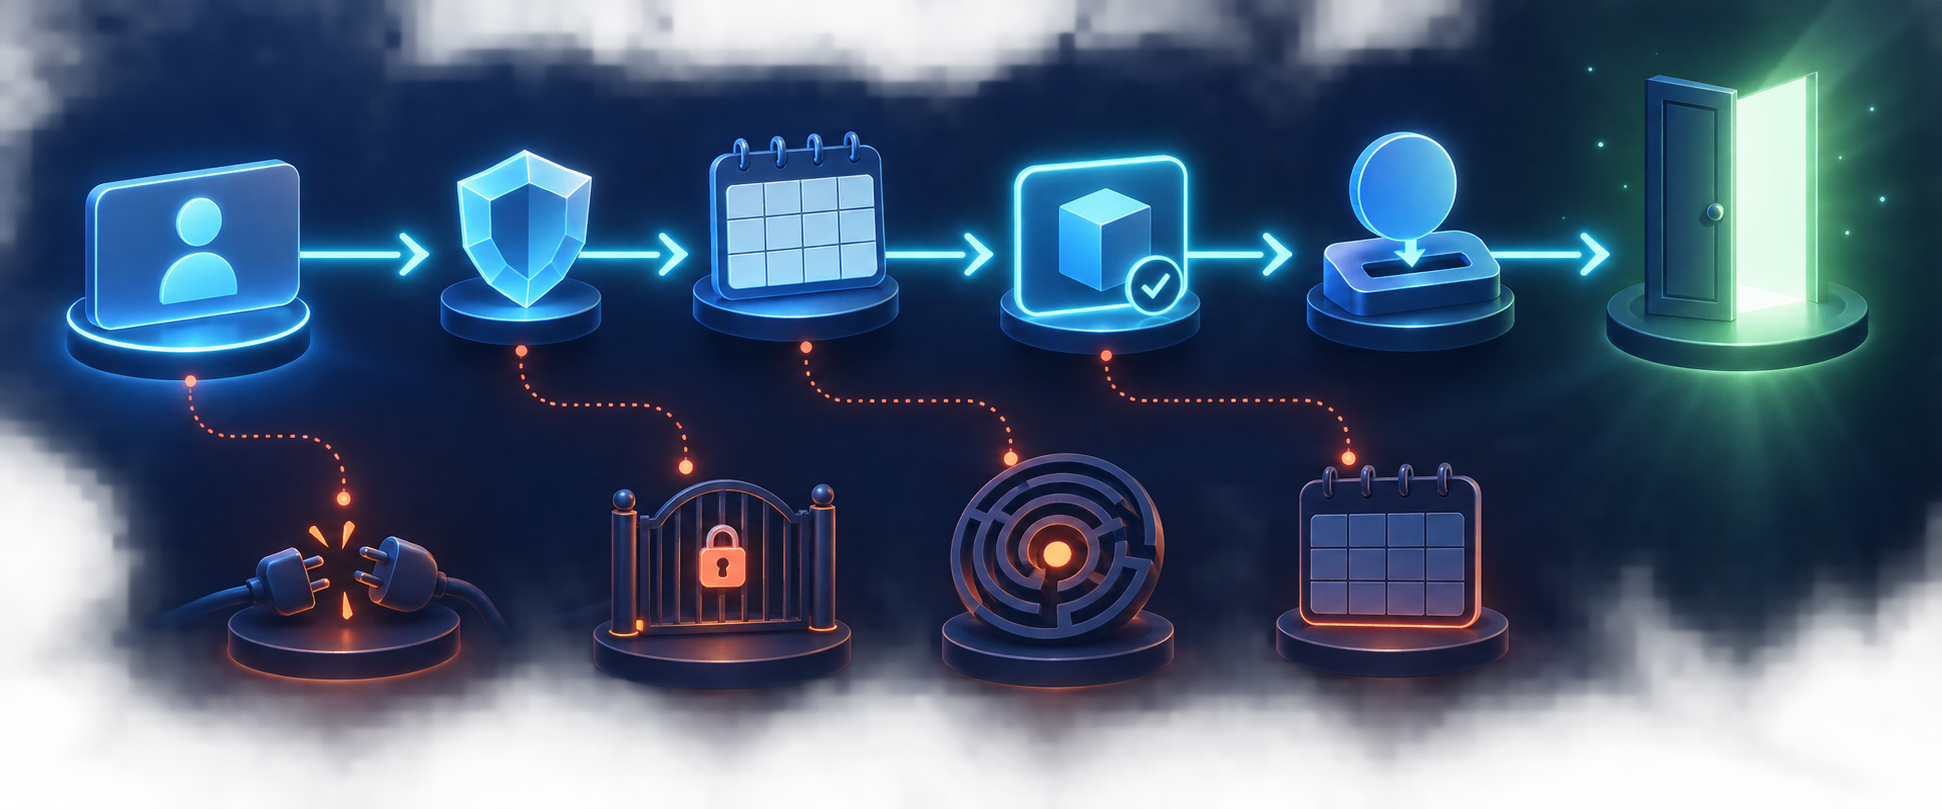
    A glowing agent pathway moves through verification, availability, selection, payment, and completion while alternate routes end at digital obstacles.

    A recommendation has limited commercial value if the agent cannot finish the requested job. The operational difference is whether a page is machine-actionable: can an approved agent use the interface to submit the inquiry, reserve the time, add the product, complete the purchase, or reach a defined handoff?

    The vendor-led command analysis recorded 78.3% of conversions on machine-actionable pages, compared with 9.6% on pages where the agent could not act. This is not a promise that making a form accessible will produce a particular conversion rate. It is evidence that transactional usability can become a selection constraint rather than a minor conversion optimization.

    Audit the complete transaction, not just the landing page

    • Use visible, specific field labels. “Work email,” “arrival date,” and “number of employees” are easier to interpret than placeholder-only or context-dependent fields.
    • State required inputs before submission. If a quote needs a postal code, account identifier, property type, budget range, or document, disclose that requirement before the agent enters the flow.
    • Explain validation failures precisely. Identify the affected field, preserve valid entries, and say what an acceptable value looks like.
    • Expose material terms before commitment. Price, fees, renewal terms, cancellation conditions, availability, and approval dependencies should not appear only after the decisive click.
    • Use conventional controls and stable destinations. Buttons should have meaningful labels, links should resolve predictably, and essential actions should not depend on unexplained gestures or decorative interface elements.
    • Return an actionable confirmation. Show what was submitted, whether it succeeded, what happens next, and any reference number or next step the user needs.
    • Define the human handoff. If the task cannot be automated, say which step requires a person, what information that person needs, and how the customer will be contacted.

    Test the flow from a clean session using the same facts a customer would give an agent. Check every branch: unavailable dates, unsupported locations, invalid entries, expired inventory, payment failure, authentication, and confirmation. A form that works only on the happy path is not reliably actionable.

    Agent-friendly does not mean unguarded. Keep authentication, fraud controls, consent, privacy safeguards, and human approval wherever the risk requires them. Do not weaken a security control to make automation easier. If automated action is allowed, provide an approved route; if it is not, provide a clear and honest handoff instead of a hidden bypass.

    Use audience preference where the platform supports it

    Retrieval is not driven only by topical relevance. Google Preferred Sources gives readers an explicit way to star publications in the Top Stories area so that stories from those outlets can appear more often for those readers. This is a narrow feature with a precise scope: it concerns publications and Top Stories, not every business listing, organic result, or AI-agent decision.

    The feature has nevertheless become large enough for publishers to treat it as a real retention channel. Google reported that people had selected more than 600,000 unique sources, up from 200,000 in May 2026. Google has also said that users who select a preferred source are twice as likely to click. Those figures describe this specific feature; they do not establish a general ranking advantage across search or AI platforms.

    If you publish news and participate in Top Stories, the implementation is straightforward:

    1. Install Google’s Preferred Sources button using the supported implementation.
    2. Place the prompt near a moment when the reader has received value, such as the end of a substantive story, rather than interrupting the opening.
    3. Explain the result accurately: starring the publication can make its stories appear more often in that reader’s Top Stories experience.
    4. Record the preferred-source user count with its reporting date so you can measure growth instead of relying on an undated total.
    5. Compare that growth with returning readership and engagement, while keeping correlation separate from proof of causation.

    Some site owners received Search Console emails showing a Preferred Source user count as of October 5, 2026. Google also surveyed recipients about future reporting methods, frequency, and metrics. Until regular reporting is established, keep your own dated record of any counts you receive.

    If you are not a relevant publication, do not imitate the button or describe ordinary follows as Preferred Sources. Apply the underlying principle without inventing a platform signal: give satisfied readers a clear way to return, subscribe, follow, or search for your brand again. Explicit preference can support a durable audience, but it should not be presented as proof that an unrelated agent will select you.

    Measure agent visibility as a decision path

    You do not need access to an agent’s private logs to build a useful diagnostic. You need a repeatable set of realistic tasks and a disciplined record of what can be observed. Start with the commercial requests that matter most, because “explain this topic” and “choose a provider and submit an inquiry” test very different kinds of visibility.

    1. Define the task exactly. Include the hard constraints a real buyer would provide: location, budget, timing, compatibility, eligibility, scale, or required terms.
    2. Preserve the test context. Record the platform, date, locale, sign-in state, exact command, and any files or preferences supplied. Keep the command unchanged when comparing runs.
    3. Capture the candidate set. Note whether your brand appeared, which page supported the appearance, what claims were surfaced, and which competing options were considered.
    4. Score each requirement. Mark hard requirements as confirmed, failed, contradictory, or unknown. An unknown should not be counted as a pass merely because you know the answer internally.
    5. Separate selection from retrieval. Record whether the brand was found, whether it remained eligible, whether it was selected, and the observable reasons given. Do not present an inferred reason as if the agent disclosed it.
    6. Test the action. Where authorized, follow the process through the form, booking, cart, checkout, or handoff. Record the exact field, policy, authentication step, or interface state that prevents completion.
    7. Fix the earliest failed gate. More suitability copy will not solve an indexing failure. More authority will not repair an unusable booking flow. Diagnose before choosing the optimization.
    8. Repeat on a fixed cadence. Agent outputs can change, so compare patterns across repeated observations rather than treating one response as a permanent ranking.

    Keep conventional SEO and analytics beside this testing. Search rankings still influence retrieval, human visitors still use results pages, and agent-driven commercial activity remains only part of search. The measurement upgrade is additive: it connects rankings and mentions to qualification, selection, and completed work.

    Key takeaways

    • A ranking can earn entry into an agent’s candidate set without earning the final selection.
    • Publish explicit requirements, supported scenarios, limitations, commercial terms, and suitability guidance so the agent does not have to guess.
    • Use JSON-LD to clarify visible facts, not to make unsupported claims or conceal qualifications.
    • Make consequential claims consistent and independently verifiable.
    • Treat forms, booking systems, checkout, APIs, and human handoffs as part of search visibility.
    • Measure retrieval, qualification, selection, and completion separately so each failure receives the right fix.
    • Use Google Preferred Sources if its Top Stories scope fits your publication, but do not mistake it for a universal agent-ranking signal.

    Choose your highest-value delegated task and trace it from discovery to completion. If your brand is absent, repair retrieval. If it appears but is rejected, expose the missing fit or proof. If it is selected but the task stalls, fix the transaction. That sequence keeps you from buying more visibility when the real leak is qualification, trust, or action.

    References


  • AI Search Ranking Signals: A Practical Priority Order

    AI Search Ranking Signals: A Practical Priority Order

    If your team is debating whether the next optimization sprint should go to schema markup, an llms.txt file, or another FAQ block, pause. The larger opportunity is usually earlier in the chain: make it unmistakable what you offer, who it fits, and whether the same facts appear everywhere an AI system may encounter your brand.

    Markup can help a machine interpret a strong page. It cannot rescue vague positioning, missing proof, or conflicting information. If you want more visibility in ChatGPT, Gemini, Claude, AI Mode, and agentic search, use the priority order below to decide what to fix first.

    The strongest measured signals are clarity and consistency

    From June 8 to September 18, 2026, 4,213 commercial prompts and 657 agentic shortlisting or purchasing tasks were run through ChatGPT, Google Gemini, including AI Mode, and Claude. The analysis covered 1,089 brands across 14 industries and measured recommendation rate: the share of relevant prompts in which a platform named a brand as a recommended option.

    Clear descriptions of offerings and suitability had the largest adjusted association with recommendation rate at +11.2 percentage points. Consistent information across a brand’s website and third-party sources followed at +9.4 points. The adjustment controlled for authority signals such as list mentions, reviews, and awards.

    SignalDifference before authority controlDifference after authority controlWhat to do with it
    Clear offerings and suitability+15.8 points+11.2 pointsState what each offer is, who it serves, and when it is suitable.
    Consistent brand information+16.9 points+9.4 pointsReconcile important facts across owned pages and third-party profiles.
    Comparison tables on service pages+6.7 points+1.9 pointsUse tables when they make fit and differences easier to evaluate.
    Any schema markup+3.7 points+0.4 pointsTreat schema as a representation layer, not the main ranking project.
    Organization schema+2.1 points+0.2 pointsImplement it accurately, but do not expect it to create authority.
    FAQ schema+0.8 points-0.3 pointsAdd useful FAQs for readers, not to manufacture a ranking signal.
    llms.txt+0.8 points-0.1 pointsKeep it behind clarity, consistency, and authority work in the backlog.
    Product schema for ecommerce brands+6.7 points+4.8 pointsGive this greater priority when products are the entities being evaluated.

    Do not treat those adjusted differences as universal ranking weights. They are associations from one observational dataset, not proof that changing one field will produce a fixed lift on every platform. The negative FAQ schema and llms.txt figures do not show that either feature causes harm; they show that no measurable positive effect remained after authority was controlled in this sample.

    The more useful lesson is about sequencing. Schema appeared more powerful before authority was held constant because brands that invest in technical optimization often have stronger authority signals too. If your page still leaves its audience or use case implicit, technical polish is unlikely to be the constraint holding it back.

    Cross the clarity threshold before adding more structure

    Scattered translucent shapes merge into one clear object before passing through a glowing gateway toward neatly organized blocks.

    Clarity is not the same as short copy. A clear page gives a model enough explicit information to connect an offering to a person, problem, location, and buying situation without having to infer the missing pieces.

    On the specific ten-point rubric used in the commercial-prompt analysis, brands scoring 5 to 6 averaged an 11.2% recommendation rate. Brands scoring 7 to 8 averaged 23.6%, while those scoring 9 to 10 averaged 24.8%. The large change occurred when sites moved from partially clear to explicitly clear; the difference between clear and comprehensive was much smaller.

    A score of 7 is not an industry standard or a guarantee. It is a useful diagnostic line from this dataset. Below it, missing fit information can prevent a brand from entering the serious consideration set. Above it, suitability and authority have more room to decide which clear option gets recommended.

    Audit each commercially important page against four questions:

    • Offering: Can a reader identify exactly what is being sold from the opening copy, without decoding a slogan?
    • Fit: Does the page explicitly name the customer types, use cases, and situations for which the offer is appropriate?
    • Specifics and proof: Does it provide available details about the process, pricing approach, service area, results, awards, or relevant customer examples?
    • Organization: Can someone scan headings, bullets, and genuine comparison tables to find those answers quickly?

    The common failure is a page that names the service but makes the reader infer suitability from logos or broad language such as “businesses of all sizes.” Replace that implication with a direct statement. A useful opening pattern is: “[Offering] is a [category] for [customer type] that needs [use case or outcome] in [relevant situation].” The brackets are prompts for substance, not a sentence to copy mechanically.

    Give each material offering its own page. Add a fit section that says who should consider it and which conditions change the recommendation. Explain how it differs from adjacent options. Publish concrete facts you can support, including a pricing approach when exact prices cannot be public. This work improves both human evaluation and machine interpretation because it removes the need to guess.

    Make your facts consistent, then build the right authority

    Several abstract information sources send matching light pulses to a central sphere supported by an illuminated framework, while one conflicting pulse fades away.

    Consistency is more than spelling the company name the same way. It means that your offer names, audience, locations, pricing model, capabilities, and proof do not change as someone moves between your website and independent references.

    That matters because cross-source consistency retained a +9.4-point association with recommendation rate after authority was controlled. A model can work with a qualified claim repeated accurately across several places. It has a harder decision when the homepage, product page, directory profile, and review coverage describe materially different businesses.

    Create a canonical fact ledger before asking teams to update pages independently. It should contain:

    • The official brand name and a plain description of the business.
    • The canonical name and definition of every material offering.
    • The audience, use cases, and suitability conditions for each offer.
    • Locations or service areas, where relevant.
    • The pricing approach and any public qualification criteria.
    • Approved proof points, including the exact scope and date behind each result.
    • Awards, credentials, and other claims that can be independently verified.

    Compare that ledger with your homepage, product and service pages, location pages, directory entries, review profiles, and independent coverage. Correct owned pages first. Then request corrections where third-party information is outdated. Prioritize contradictions that change eligibility or fit, such as an old service area, a discontinued product name, or a claim that applies to one offer but appears to describe the whole company.

    Authority is not interchangeable with structured data. The unadjusted difference associated with any schema was +3.7 points, but it fell to +0.4 after list mentions, reviews, awards, and related authority signals were controlled. That does not assign a causal value to any one authority tactic. It does show why adding markup to an under-recognized brand should not be mistaken for building recognition.

    The most useful form of third-party evidence also depends on the buying market. In consumer categories, expert reviews outweighed customer reviews by 15 to 1 in AI search, while B2B software showed the reverse pattern. Treat that result as directional rather than a rule for every niche, but do not copy one review strategy across both markets.

    • For a consumer category, identify the credible expert reviewers and category comparisons that buyers already use. Make your product facts easy to verify, and correct inaccurate coverage where possible.
    • For B2B software, prioritize authentic, specific customer-review evidence in the places buyers consult. Generic praise is less useful than a review that identifies the customer situation and the product’s role.
    • For either market, keep externally promoted claims aligned with the canonical facts on your site. More mentions will not solve a contradiction that makes the offer harder to classify.

    Use schema to transmit facts, not invent importance

    Schema has a real job: it labels entities and properties in machine-readable form. That job is valuable, but it is different from earning a recommendation. The safest implementation rule is simple: structured data should faithfully represent useful facts that a visitor can already verify on the page.

    Product schema deserves separate treatment for ecommerce. Among the 214 ecommerce brands in the sample, it retained a +4.8-point association after authority control. That is the only measured markup type with a meaningful adjusted difference in the available data. It still does not prove a guaranteed lift, but it gives ecommerce teams a stronger reason to prioritize accurate Product markup than a service business has to deploy several marginal schema types.

    Use this implementation order:

    1. Fix the visible offer, fit, and proof on the page.
    2. Select a schema type that corresponds to the entity actually described, such as Organization or Product.
    3. Make names, descriptions, and other claims match the visible content and your canonical fact ledger.
    4. For ecommerce, prioritize accurate Product markup before adding loosely relevant schema types merely to increase the count.
    5. Add FAQ content only when it answers questions that help a buyer decide. Treat FAQ schema as encoding for that content, not as an independent visibility lever.
    6. Validate the markup and review it whenever the visible facts change.

    Apply the same discipline to llms.txt. Its adjusted difference was -0.1 points in the measured sample, which is effectively no demonstrated lift there. You may still test it as a low-cost machine-accessibility experiment, but it should not displace work on unclear pages, conflicting facts, or missing authority.

    Comparison tables sit between content and structure. Their adjusted association was a modest +1.9 points. Use one when a buyer genuinely needs to compare audiences, use cases, features, or alternatives. A table that exposes meaningful differences can improve clarity; a table built only to look optimized adds no new information.

    Key takeaways: choose your next optimization ticket

    • Fix explicit fit first. Every important offer should state what it is, who it serves, when it is suitable, and what evidence supports it.
    • Reconcile facts across the web. Maintain one canonical ledger and use it to correct high-impact contradictions on owned pages and third-party profiles.
    • Build market-appropriate authority. Consumer categories may lean more heavily on expert reviews, while B2B software may depend more on customer-review evidence.
    • Make schema accurate and proportionate. Product schema has the strongest measured case for ecommerce; Organization schema, FAQ schema, and llms.txt should not outrank clarity work.
    • Measure recommendations, not implementation volume. Use a fixed set of commercial prompts across the platforms that matter, record whether your brand is named and for which use case, then inspect the pages and evidence supporting each result.

    Start with the highest-value product or service page, not a sitewide markup rollout. Make one offer fully explicit, reconcile its facts, align its external evidence, and then encode it accurately. Once that page can answer what, who, when, where, and why without inference, you have a useful model for the rest of the site.

    References


  • AI Search Visibility Is Not Value: How to Measure the Gap

    AI Search Visibility Is Not Value: How to Measure the Gap

    You can be cited by an AI answer and still lose the customer. Your product details may help construct the response while a better-known competitor gets the recommendation, click, and sale. If you publish content, the split can happen further upstream: an AI system can use your work while the economic return remains negligible or impossible to predict.

    That is the practical problem behind unequal value distribution in AI search. You will not solve it by tracking mentions alone. You need to measure each handoff from citation to recommendation, action, and compensation, then work on the point where value stops moving toward you.

    AI search value passes through five separate gates

    Visibility is not one outcome. From your point of view, it is a chain of increasingly valuable outcomes. A business can succeed at one gate and fail at the next.

    GateQuestion to answerMeasure
    CitationDid the response name or link to your site as supporting material?Citation share across eligible responses
    Candidate inclusionDid the response name your brand, store, product, or publication as an option?Mention or shortlist share
    RecommendationDid the system endorse you, especially as its first choice?Recommendation rate and top-choice rate
    ActionDid the exposure produce a visit, inquiry, subscription, or purchase?Traceable visits, leads, and conversions
    Value captureDid the commercial return justify the content, inventory, and operational cost?Attributed revenue, direct payment, and contribution margin

    The distinction matters because an AI answer can use one company as an information source and send the buyer to another company. For publishers, even a direct contribution payment can be too small or volatile to support the work that produced the material.

    Do not combine these gates into a single AI visibility score. A blended score can improve while commercial performance deteriorates. If citations rise but top recommendations fall, the headline number will hide the loss that matters.

    The largest value losses occur after retrieval

    Glowing information particles emerge from a repository and enter a central prism, then split into pathways that narrow sharply before reaching product, interaction, and value symbols.

    Shopping responses show the citation-recommendation gap clearly. Large and small retailers each represented roughly 38% of the stores cited, yet large retailers appeared about 2.5 times as often as small retailers in the top recommendation. Smaller merchants were visible to the systems. They were much less likely to receive the most commercially valuable placement.

    Web access reduced the imbalance without removing it. When search was unavailable, large national chains received 63% to 70% of recommendations, while small and local retailers appeared about 10% of the time. With live search, large retailers still took 46% to 58% of top recommendations across ChatGPT, Google AI Mode, and Google AI Overviews.

    The gap cannot be dismissed as a simple failure to find smaller stores. When an AI system was presented with one large retailer and one smaller store without explicit size labels, it selected the larger retailer in 90% to 94% of responses. This establishes a behavioral pattern, not its cause. It does not prove that any model contains an explicit rule favoring chains, so your audit should measure outcomes rather than speculate about an undisclosed ranking factor.

    Query specificity widened the difference. Small retailers secured roughly one-third of top recommendations for broad requests, but only about 10% when the shopper specified a product. Over the same shift, large retailers moved from roughly 40% to 60% of top recommendations. If you sell specific products, a healthy citation count can therefore coexist with weak purchase-intent visibility.

    Publishers face a second distribution problem: content use does not necessarily produce proportionate compensation. Google’s limited AI Contribution pilot reportedly includes about 100 publishers, but several small and midsize participants received less than 0.1% of their advertising revenue from it. Smaller sites received less than $1,000 over several months, while individual participants were reported at approximately $50,000 to $60,000 after joining and more than $1 million a year in another case.

    Those absolute payouts do not reveal a dependable market rate. Publisher scale, content contribution, eligibility, and the calculation behind monthly changes are not disclosed clearly enough to normalize the figures. The pilot is also too limited to support a conclusion about what most publishers will earn if it expands. Treat it as preliminary evidence of a payment mechanism, not as a forecast you can put into a budget.

    Build an audit that finds the exact value leak

    A transparent five-chamber system carries glowing particles toward a reservoir while a magnifier and inspection light reveal a leak at one connection.

    Your audit should connect controlled prompt testing with real business outcomes. Prompt testing shows what happens before a click; analytics and commercial records show what happens afterward. Neither view is sufficient on its own.

    1. Define the entity and outcome. Choose the brand, product line, location, or publication you are assessing. Then name the desired result: a top recommendation, store visit, qualified lead, sale, subscription, or content payment. Do not substitute citations for that result.
    2. Create separate prompt cohorts. Test broad category requests, specific product requests, requests using local or near me, and requests explicitly asking for an independent business. Keep the commercial intent consistent enough that differences remain interpretable.
    3. Separate platform conditions. Record the platform, product mode, whether live web search is active where that condition is controllable, the displayed model or version when available, the target market, and the test date. Do not merge searched and non-searched responses into one rate.
    4. Grade placement, not merely presence. For each response, record whether you were cited, named as a candidate, recommended, and placed first. Also record the wording: being mentioned as one option is not equivalent to being called the best fit.
    5. Inspect the destination. If a link appears, record its landing page and whether that page can complete the user’s task. A product recommendation that lands on a generic homepage may create visibility without usable demand.
    6. Join the prompt record to downstream evidence. Track attributable referral traffic where it is available, relevant landing-page conversions, assisted conversions you can substantiate, and direct platform payments. Label untraceable exposure as untraceable rather than assigning it an invented monetary value.

    Use separate rates so you can see where performance changes:

    • Citation share: responses citing you divided by eligible responses.
    • Candidate share: responses naming you as an option divided by eligible responses.
    • Top-choice rate: responses placing you first divided by eligible responses.
    • Citation-to-top-choice conversion: responses that both cite you and place you first divided by responses citing you.
    • Action rate: measurable visits, leads, subscriptions, or purchases divided by the relevant exposure measure available to you.
    • Value capture: substantiated revenue or platform compensation compared with the cost of producing and maintaining the underlying content or commerce experience.

    The citation-to-top-choice calculation is especially useful. If citation share rises while that conversion rate falls, your information is becoming more useful to the answer without your business becoming more likely to receive the decision.

    Do not use one undifferentiated prompt average. A retailer can perform adequately on broad discovery prompts and disappear when a shopper names a product. Segmenting by specificity exposes that loss. Segmenting independent separately from local also prevents a nearby branch of a national chain from being counted as evidence that independent businesses are winning.

    Improve the handoff that is failing

    The appropriate intervention depends on the failed gate. More content is not the automatic answer. If you are already cited frequently, producing another page that earns citations may deepen the same imbalance.

    For retailers and service businesses

    The strongest prompt-level change came from the word independent. Adding it more than doubled the share of small and local businesses named, moving their share from roughly one-third to nearly four-fifths in a randomized prompt sample. On Google’s platforms, large-chain sources fell from about 44% under neutral wording to as little as 9%.

    That result changed the user’s request, not the merchant’s website. It does not prove that adding independent to a page will produce the same lift. The responsible action is narrower: if independent ownership is accurate and relevant, state it plainly in visible business descriptions and keep the fact consistent wherever your identity is represented. Then retest. Do not imply independent ownership merely to chase a recommendation pattern.

    Treat local and independent as different attributes. Requests using local or near me had much less effect because an AI system can legitimately interpret a nearby national-chain branch as local. If your advantage is ownership rather than distance, a local-only measurement set will answer the wrong question.

    For specific-product prompts, inspect the facts a system and a shopper need to make a decision: the precise product, current availability, service area or delivery coverage, purchase path, and differentiators relevant to that request. Publish only details you can keep accurate. The available evidence does not prove that any one field improves AI selection, but reducing factual ambiguity gives you a cleaner test and a better destination if a recommendation does occur.

    Use structured data, including JSON-LD, to clarify facts that also appear on the page. Do not present schema as a way to force a recommendation. Machine-readable information can support understanding; it cannot guarantee that an AI system will prefer your business over a larger competitor.

    For publishers and content-led businesses

    Separate audience value from content-use value. Audience value includes visits, subscriptions, leads, and purchases you can substantiate. Content-use value includes contribution payments or licensing income. A citation can contribute to either, both, or neither.

    If you participate in a contribution program, maintain a monthly ledger containing the payment, any available citation or usage information, AI referral traffic, revenue linked to that traffic, and the cost of the eligible content. Do not infer that the payment is impression-based, click-based, or proportional to the amount of content used. Participants in Google’s pilot reportedly do not receive enough explanation to determine why their payouts change from month to month.

    Set your investment rule before an attractive payout anecdote changes your expectations. Continue or expand work only when substantiated direct revenue, defensible assisted value, and disclosed contribution payments together justify your own cost threshold. There is no supported industry benchmark in the available pilot data, so the threshold must come from your economics.

    When payments are opaque and unstable, classify them as uncertain supplemental revenue. Do not hire, commission a content program, or abandon a working traffic channel on the assumption that the pilot will expand on comparable terms. The safe planning case is the amount you can defend from your own records, not another publisher’s headline payout.

    Use the following diagnosis to decide where the next unit of work belongs:

    Observed patternLikely value leakNext action
    Low citation and low recommendation ratesDiscovery or factual clarityCheck accessibility, identity consistency, and whether relevant pages answer the tested request.
    High citation rate but low top-choice rateSelectionClarify truthful differentiators and decision-relevant facts, then rerun the same prompt cohorts.
    High recommendation rate but weak measurable actionDestination or attributionInspect links, landing pages, calls to action, and gaps in analytics before producing more content.
    Strong AI referral traffic but poor conversionOffer or on-site experienceTreat it as a conversion problem and analyze the landing experience by intent.
    Frequent content use but opaque or negligible paymentValue captureLimit financial dependence, document the economics, and treat undisclosed payments as uncertain.

    Key takeaways

    • A citation proves visibility or use. It does not prove recommendation, traffic, or commercial value.
    • Track top-choice rate separately from citation share because the largest loss can occur between those two events.
    • Segment broad and specific-product prompts. Smaller retailers can lose substantial recommendation share as a request becomes more specific.
    • Do not treat local as a substitute for independent; the two words encode different customer preferences.
    • Do not budget around preliminary publisher-payment anecdotes when eligibility, calculation methods, and monthly changes remain opaque.

    On your next AI visibility report, add two columns beside citations: top-recommendation share and attributable business outcome. If you publish content, add compensation and content cost as well. The first empty or underperforming column is where your next investigation belongs.

    References


  • How to Make Products Visible to AI Personal Shoppers

    How to Make Products Visible to AI Personal Shoppers

    Your product can rank in conventional search and still disappear when a shopper asks an AI assistant what to buy. The missing piece is usually not another generic category paragraph. It is making the product easy to identify, test against constraints, and defend in a recommendation.

    AI personal shoppers can shape which products make the shortlist. That changes your visibility target. You are no longer optimizing only for a page visit; you are helping a system decide whether your product is eligible, relevant, credible, and safe to recommend for a particular request.

    AI shopping visibility is a three-gate problem

    There is no universal ranking formula for AI shopping. Assistants use different catalogs, retrieval systems, merchant feeds, pages, and models. Their answers can also change as availability, prices, prompts, and underlying systems change. A practical three-gate model is more useful than pretending every platform works the same way.

    1. Discovery: Can the assistant find and identify the correct product or variant?
    2. Qualification: Can it determine whether the product satisfies the shopper’s stated constraints?
    3. Selection: Is there enough relevant evidence to choose the product and explain that choice?

    A product has to pass the gates in that order. Better promotional copy cannot rescue a product the system cannot identify. Strong reviews cannot compensate for an unspecified compatibility requirement. Complete structured data does not prove a broad superiority claim.

    This sequence gives you a diagnostic method. If the product never appears, inspect discovery before rewriting the sales copy. If it appears for broad prompts but disappears when a constraint is added, inspect the relevant attribute. If it remains eligible but another product receives the recommendation, inspect comparative relevance and supporting evidence.

    The important distinction is between being mentioned and being recommendable. A system may know that your product exists while lacking the facts needed to place it in a defensible shortlist.

    Build one canonical product truth

    A hiking shoe on a central platform sends the same set of visual product attributes to a storefront, phone, warehouse shelf, and AI orb.

    Start with an internal product record, not a block of marketing copy. This record should be the authoritative source for the product page, structured data, merchant feeds, marketplace listings, comparison pages, and support content. When those surfaces disagree, an assistant has to choose among conflicting claims or avoid repeating them.

    For each product and meaningful variant, define the following fields explicitly:

    • Identity: brand, product name, model, assigned SKU or GTIN, canonical URL, and product category.
    • Variant: color, size, capacity, material, pack quantity, configuration, and the relationship to the parent product.
    • Eligibility attributes: dimensions, weight, compatibility, intended use, required accessories, included components, operating conditions, and other category-specific constraints.
    • Commercial facts: price, currency, condition, availability, fulfillment terms, returns, and warranty terms.
    • Evidence: certifications, documented test conditions, review data, manuals, specifications, and the exact scope of each claim.

    Do not populate a field because competitors use it or because a schema validator permits it. An unknown value should remain unknown until the business can verify it. A precise false claim is worse than an honest omission because the false claim can be repeated in a recommendation, create a poor purchase, and undermine trust in the rest of your data.

    Keep the visible page, schema, and feeds aligned

    Product structured data should encode facts that a shopper can also verify on the page. Use Product markup to identify the item and its attributes. Use Offer data only for an offer that actually exists. Add rating or review properties only when the corresponding information is genuine, visible, and attached to the correct product or variant.

    JSON-LD does not create product truth. It translates product truth into a machine-readable form. If the page says one material, the markup says another, and the feed omits the field, adding more schema will multiply the ambiguity rather than fix it.

    Variant handling deserves particular attention. A family page may describe several configurations, but price, dimensions, availability, ratings, and compatibility can belong to only one of them. Give meaningful variants stable identities and make the selected variant unambiguous in the page content, URL behavior, structured data, and feed.

    Separate durable facts from fast-changing facts

    Product data fails at different speeds. Model identity, dimensions, materials, compatibility, and included components are usually durable. Price, availability, promotions, delivery estimates, and review aggregates can change much faster.

    Give each fast-changing field an owner, a system of record, and a refresh trigger. Avoid embedding volatile values in editorial prose unless that prose is updated from the same source. A stale promotional page and a current product feed can leave an assistant with two plausible answers and no reliable way to reconcile them.

    Match shopper constraints and support every important claim

    Traditional product copy often begins with a head keyword and expands into benefits. AI shopping requests are more likely to combine a job, a hard constraint, and a preference: a product for a particular use, compatible with something the shopper already owns, within a budget, and with a preferred trade-off.

    Create a prompt set from the decisions people make, not just the phrases with the highest search volume. Include several distinct request types:

    • Job prompts: What is the shopper trying to accomplish?
    • Constraint prompts: What would make a product ineligible, such as size, compatibility, material, price, or availability?
    • Trade-off prompts: Which quality matters more when no option maximizes everything?
    • Comparison prompts: Which alternatives are genuinely close enough to compare?
    • Risk prompts: What must the shopper verify before buying?

    Then map every consequential question to a field and a piece of evidence. The map exposes a common failure: the marketing team believes a benefit is obvious, but the product page never supplies the fact an assistant would need to infer it safely.

    Shopper questionMachine-readable answerHuman-verifiable support
    Will it fit?Dimensions, weight, capacity, or supported size rangeSpecification table, diagram, or installation instructions
    Will it work with what I own?Compatible models, interfaces, versions, or required accessoriesCompatibility page, manual, or clearly scoped support content
    Can I buy it under my stated conditions?Current price, currency, condition, availability, and offer detailsVisible offer and fulfillment information
    Is it suitable for this use?Intended use and relevant product attributesUse-case explanation tied to specifications rather than slogans
    Can I trust this claim?Named evidence and its scopeCertification details, documented method, policy, or attributable review data

    State who the product is and is not for

    A useful product page helps an assistant eliminate the wrong matches. State the primary use, the buyer or environment it suits, the constraints it satisfies, and any condition that would make another option more appropriate.

    This does not weaken the offer. A clear limitation can make the positive recommendation more credible. If a product requires an adapter, has a fixed dimension, excludes a particular model, or is designed for one usage pattern rather than another, say so close to the relevant benefit. Hiding the qualifier may generate more initial interest, but it gives an assistant less reason to trust or repeat the claim.

    Comparison content should use decision criteria rather than a list of adjectives. Explain which product fits which condition and why. Avoid declaring an item the best without naming the use case, comparison set, and evidence. An unqualified superlative is difficult to defend and easy for a recommendation system to ignore.

    Maintain a claim-to-evidence ledger

    For every claim that could change a purchase decision, keep an internal ledger containing the claim, its exact qualifier, the supporting evidence, the page where that evidence is visible, the responsible owner, and the event that should trigger a review.

    The qualifier matters. A certification may apply to one variant, a test may use specific conditions, and a warranty may differ by market. Preserve that scope everywhere the claim appears. Do not turn narrow evidence into a product-wide promise.

    Customer reviews can help describe recurring strengths and limitations, but keep review data attached to the product or variant it evaluates. Combining materially different variants may produce a stronger aggregate while giving the assistant a less accurate picture of the item in front of the shopper.

    Support pages, manuals, compatibility resources, return policies, and comparison pages should link back to the canonical product and use the same names and identifiers. That creates a coherent evidence trail instead of a set of disconnected documents with slightly different terminology.

    Audit the complete path from prompt to recommendation

    A shopper request travels through product, evidence, inventory, checkout, and delivery checkpoints before reaching an unbranded product shortlist.

    Do not reduce AI shopping visibility to a rank check. You need to see where the product exits the decision process and whether the answer is factually correct when it does appear.

    1. Choose eligible prompts. Test requests for which the product could honestly be a suitable answer. Irrelevant prompts distort the score and tempt teams to broaden claims beyond the product’s real fit.
    2. Record a baseline. Save the exact prompt, assistant, date, market or locale, response, recommended products, stated reasons, and any surfaced links.
    3. Label the outcome. Distinguish absence, failed qualification, incorrect description, unsupported mention, and an eligible product that lost on a documented trade-off.
    4. Trace the earliest failed gate. Repair identity and discovery before attributes, attributes before evidence, and evidence before promotional expansion.
    5. Rerun the same prompt set. Compare changes in coverage and accuracy while recognizing that any individual generated response can vary.
    6. Inspect the commercial handoff. If the recommendation is accurate but the shopper does not proceed, examine the offer, availability, landing experience, and product-market fit rather than calling every weak outcome an AI visibility problem.

    The failure pattern tells you where to look first:

    Observed resultLikely failure areaFirst inspection
    The product never appearsDiscoveryIndexability, canonical URL, feed inclusion, product identity, and internal linking
    The wrong variant appearsIdentityVariant names, identifiers, URLs, parent relationships, and selected-offer data
    The product disappears after a valid constraint is addedQualificationThe missing, ambiguous, or conflicting attribute associated with that constraint
    The assistant states an incorrect factProduct truthConflicts and stale values across the page, schema, feed, marketplace, and support content
    The product is considered but not recommendedSelectionUse-case specificity, comparison criteria, limitations, and claim-level evidence
    The recommendation is accurate but does not convertCommercial handoffPrice, availability, trust, offer clarity, landing experience, and actual product fit

    Track metrics that correspond to those states. Prompt coverage shows whether the product appears for eligible requests. Attribute resolution shows whether the assistant can answer the important constraint questions. Answer accuracy catches misdescription. Evidence visibility shows whether useful supporting pages are surfaced. Recommendation share shows how often the product is selected when it is genuinely eligible. Commercial outcomes tell you whether improved visibility creates useful demand.

    Keep the prompt set and eligibility rules stable while evaluating a change. If you change the content, prompts, markets, and success definition at the same time, you will not know what improved. Treat assistant outputs as observations, not permanent rankings.

    Key takeaways

    • Optimize for discovery, qualification, and selection as separate gates.
    • Create one canonical product record before expanding copy, schema, feeds, or comparison content.
    • Make decisive constraints explicit; do not ask an assistant to infer compatibility, fit, or eligibility from vague prose.
    • Keep visible content, Product structured data, offers, variants, and merchant feeds consistent.
    • Attach meaningful claims to scoped evidence and state important limitations plainly.
    • Measure eligible prompt coverage and factual accuracy before treating recommendation share as the main result.

    Start with one commercially important product family. Establish its canonical facts, build prompts around real purchase constraints, and fix the earliest gate that fails. Once that path is reliable, extend the same operating model to the rest of the catalog. That gives you a repeatable visibility system instead of a collection of schema additions and copy changes whose effect you cannot explain.

    References


  • How to Audit AI Marketing Recommendations Across Audiences

    How to Audit AI Marketing Recommendations Across Audiences

    You give an AI marketing tool a clear goal, and it returns a confident audience, channel, or brand recommendation. The answer looks ready to use. But before you build a campaign around it, you need to know two things: what evidence produced the recommendation, and whether the recommendation changes when the audience changes.

    If neither is visible, you do not have decision support yet. You have a plausible output whose scope, assumptions, and failure modes are hidden. The practical fix is to audit recommendation evidence and audience variation as one workflow, then require human approval wherever a change could affect reach, spend, eligibility, or brand strategy.

    One AI answer is not a complete market view

    A single answer-engine response can be useful without being representative. The engine may interpret the question through details about the user, the wording of the prompt, prior conversational context, or other signals available to the system. Change that context and the shortlist, ranking, citations, or explanation may also change.

    A vendor analysis of 71,147 answer-engine responses found differences in brand mentions, citations, and search behavior associated with income, age, gender, and occupation. That finding does not establish that every answer engine personalizes every request, nor does it explain the cause of every observed difference. It does show why a persona-neutral prompt should not be treated as a universal picture of AI visibility.

    Some variation is appropriate. A buyer prioritizing affordability and a buyer prioritizing enterprise governance may reasonably receive different recommendations. The issue is not whether answers ever change. It is whether the change follows a relevant criterion, rests on supportable evidence, and remains consistent with the underlying facts.

    Separate the stable layer from the audience-sensitive layer:

    • Stable facts include product identity, documented capabilities, known requirements, and the meaning of cited evidence. A persona change should not silently reverse them.
    • Audience-sensitive judgments include which criterion receives more weight, which use case is emphasized, which options appear first, and which tradeoff is considered acceptable.
    • Presentation choices include tone, examples, terminology, and depth. These may change while the substantive recommendation remains the same.

    This distinction helps you spot three common measurement failures:

    • False universality: one prompt produces one answer, and the result is reported as what the platform recommends to everyone.
    • Hidden exclusion: a brand appears for one persona but disappears for another, with no visible criterion explaining the difference.
    • Averaged-away variation: a dashboard combines responses across audiences and makes unstable visibility look consistent.

    Treat an AI visibility observation as a combination of platform, prompt, audience context, and observation time. If any part changes, you may be measuring a different answer environment.

    A transparent recommendation shows decision evidence

    Hands inspect the visible source, assumption, recommendation, and approval components inside a transparent decision-making assembly.

    Transparency does not mean exposing every internal model operation or demanding a private reasoning transcript. Neither gives a marketer a reliable basis for approval. You need the evidence, uncertainty, and tradeoffs that could materially change the decision.

    This matters because marketing data is rarely as tidy as the campaign brief. A marketer searching for a completed-purchase signal may encounter several similarly named events, such as purchase, checkout success, and checkout completion. The labels alone do not reveal which event represents a confirmed order, which fires earlier in the funnel, or which remains reliable after implementation changes.

    Volume does not settle the question. A frequently firing purchase event could occur before payment confirmation, while a lower-volume checkout-success event could align more closely with the business definition of a completed order. Selecting the biggest signal without checking its meaning can create a large but conceptually wrong audience.

    Require each consequential recommendation to carry an evidence card. It can appear in a conversational response, side panel, review screen, or exported log, but it should answer the following questions:

    Evidence fieldWhat the system should exposeWhat you can decide
    Business objectiveThe outcome the recommendation is intended to support, in business languageWhether the proposed action answers the request you actually made
    Selected signal or criterionThe event, attribute, source, or decision criterion carrying the recommendationWhether the system used the right representation of the goal
    Meaning and funnel stageWhat the signal appears to represent and where it occurs in the customer journeyWhether purchase, checkout, intent, and engagement are being confused
    Provenance and observed behaviorWhere the signal comes from, how it behaves, how often it fires, and when it was last observedWhether the evidence is current and dependable enough for this decision
    Audience boundariesWho is included, who is excluded, and the resulting potential reachWhether the audience matches campaign eligibility and strategy
    Alternatives consideredThe plausible competing signals or approaches that could change the outcomeWhether an apparently obvious recommendation ignored a better-defined option
    TradeoffsHow changing a threshold or criterion affects reach, expected performance, precision, or riskWhich compromise fits the business rather than merely optimizing a model score
    Uncertainty and missing contextAmbiguous definitions, unavailable metadata, sparse observations, or assumptions supplied by the systemWhether to accept, refine, investigate, or reject the recommendation
    Decision stateWhether the output is exploratory, proposed, saved, connected, or activatedWhether any real-world action has occurred and what still requires approval

    Do not accept vague evidence labels such as recent, strong, or large when the interface can expose the underlying context. Recent relative to what observation? Strong against which alternative? Large compared with which eligible population? The system does not need to manufacture precision, but it should distinguish known values from inferred meanings and unavailable information.

    The approval flow matters as much as the evidence. For recommendations that can change spending or customer eligibility, keep proposal, saving, connection, and activation as distinct states. An exploratory conversation should not silently become an active audience. Explicit confirmation creates a point where a marketer can apply business judgment, document an override, or request better evidence.

    Conversation and direct controls also serve different jobs. A conversational agent is well suited to exploring unfamiliar data and explaining why signals differ. A visual interface is better for making precise threshold adjustments after the reach-versus-performance tradeoff is understood. A trustworthy workflow lets you move between them without losing the evidence or approval state.

    Run a controlled audience-variation audit

    Four controlled test lanes hold the same campaign brief while different audience groups lead to visibly varied recommendation objects.

    An audience audit should isolate whether persona context changes the recommendation, not merely collect a folder of unrelated prompts. Keep the decision question and test conditions stable, change one relevant audience dimension at a time, and record substantive differences separately from stylistic ones.

    Build the test grid

    1. Define the decision. Write the exact question the answer must resolve, such as which solution fits a use case or which audience should receive a campaign. State the criteria that should matter before looking at the output.
    2. Create a neutral baseline. Ask the decision question without demographic or occupational context that is not necessary to answer it. This becomes the comparison point, not the presumed correct answer.
    3. Select relevant audience dimensions. Test occupation, age, income, gender, or another persona attribute only where it could plausibly affect needs, constraints, terminology, access, or evaluation criteria.
    4. Change one dimension at a time. Keep the platform, wording, product category, requested format, and other context constant. Composite personas may reflect real buyers, but they make it harder to identify which attribute drove a change.
    5. Capture the complete response. Record the prompt, audience variation, platform and model label exposed by the interface, observation time, recommended brands or actions, ordering, rationale, citations, caveats, and omitted options.
    6. Compare decisions before wording. A different example or tone is less important than a changed shortlist, reversed ranking, new exclusion, altered factual claim, or different call to action.
    7. Inspect the support. Check whether each changed recommendation is tied to an explicit audience need and whether its cited material actually supports the criterion being applied.
    8. Assign a disposition. Mark the variation as presentation-only, relevant and supported, unexplained and substantive, or factually contradictory. Each label should lead to a different next action.

    Interpret changes by materiality

    Presentation-only variation changes the vocabulary, explanation depth, or examples without altering the decision. You may still care about tone and accessibility, but it is not evidence that brand visibility changed.

    Relevant, supported variation changes the recommendation because the persona introduces a genuine decision criterion. An occupational context may change workflow requirements. An affordability constraint may alter which options qualify. The output should make that connection visible rather than relying on an unexplained proxy.

    Unexplained substantive variation changes inclusion, exclusion, order, or recommended action without identifying a relevant criterion or supporting evidence. Do not immediately label it bias or personalization; the system may be responding to ordinary output variation, hidden context, or a retrieval difference. Rerun the unchanged baseline alongside the persona variant, preserve the outputs, and investigate before drawing a causal conclusion.

    Factual contradiction occurs when stable product facts or evidence claims change solely with the persona. That is a blocking issue. Do not use the output for activation or publish the claim until you can resolve which statement is supported.

    Pay special attention to citations. A persona may receive different cited pages even when the recommendation stays similar. Record whether a citation is present, whether it supports the nearby claim, and whether it represents the same kind of evidence across variants. Citation count alone cannot tell you whether the recommendation is sound.

    Age, gender, and income can be useful diagnostic variables because audience-linked variation has been observed, but they can also be sensitive attributes. Using them to determine real customer eligibility can create privacy, fairness, or legal exposure depending on the context and jurisdiction. Use them in testing only when necessary, minimize personal data, and route any activation rule based on sensitive traits through your legal and privacy review process.

    Turn the audit into content, measurement, and controls

    An audit is only valuable if it changes how you publish, measure, or approve marketing decisions. The goal is not to force every audience to receive identical recommendations. It is to make legitimate differences explainable and unsupported differences visible.

    Make audience criteria explicit in your content

    If an answer engine changes its recommendation because of a criterion your content barely addresses, close that evidence gap on the relevant page. Add clear passages that identify:

    • who the product, service, or method is designed for;
    • which use cases it supports and which it does not;
    • what prerequisites, limitations, or eligibility conditions apply;
    • which tradeoffs a buyer must make;
    • how important terms and outcomes are defined; and
    • which verifiable facts support each suitability claim.

    Write around decision contexts, not demographic labels. A page explaining the needs of a regulated procurement workflow is more useful than a thin page targeting an occupational persona by name. A clear affordability limitation is more informative than assuming what someone can spend from a demographic category.

    Structured data can reinforce supported facts about the page, organization, product, service, author, or other entities where the relevant schema applies. It cannot make an unsupported claim trustworthy, encode every possible persona preference, or guarantee that an answer engine will recommend a brand. Use schema to clarify machine-readable facts, then make the audience-specific reasoning legible in the visible content.

    Measure visibility at the audience level

    Do not reduce answer-engine performance to a platform-wide mention rate if your buyers approach the category with materially different contexts. Track AI visibility by audience as well as by platform, while retaining the neutral baseline so you can see where variation begins.

    For each monitored decision question, record:

    • the exact prompt and persona context;
    • the engine, interface, and model information exposed at the time;
    • whether your brand was mentioned;
    • where it appeared in an ordered recommendation, if the answer provided an order;
    • the use case or criterion attached to the mention;
    • the pages or sources cited;
    • the caveats attached to the recommendation; and
    • whether the result was stable, relevantly different, unexplained, or contradictory.

    Keep the prompt set and audience definitions fixed when comparing observations over time. If you rewrite the question, change the persona, and switch platforms at once, you cannot tell whether a visibility movement came from your content, the engine, or the test design.

    Define approval boundaries before activation

    Set review rules before an agent proposes an audience or campaign. Require human approval when:

    • the selected data signal has an ambiguous business meaning;
    • the origin, observed behavior, or recency of the evidence is unavailable;
    • a threshold creates a material reach-versus-performance tradeoff;
    • a sensitive audience attribute changes inclusion or exclusion;
    • persona variants produce contradictory facts or unexplained recommendations;
    • the action can change budget, customer eligibility, messaging, or external activation; or
    • the system cannot show which assumption would most affect the recommendation.

    Preserve the human decision in a log. Record the proposal, evidence shown, audience context, chosen action, override, approver, and activation state. This is not paperwork for its own sake. It lets you distinguish a model recommendation from the business decision that followed it and prevents later reporting from treating the two as interchangeable.

    Key takeaways

    • A single AI response represents one platform, prompt, audience context, and observation time. It is not a universal market answer.
    • Useful transparency exposes the selected signals, their meaning and recency, audience boundaries, alternatives, uncertainty, and tradeoffs. A private reasoning transcript is not required.
    • Test audience variation by holding the decision question constant and changing one relevant persona dimension at a time.
    • Separate presentation changes from substantive recommendation changes, and block activation when stable facts become contradictory.
    • Measure brand mentions, ordering, use cases, citations, and caveats by audience rather than averaging every response into one platform score.
    • Keep exploration, saving, connection, and activation distinct so a marketer can refine or override the recommendation before it affects customers or spend.

    Start with the next recommendation your team is already preparing to use. Attach an evidence card, run the neutral prompt beside one relevant audience variant, and classify every substantive difference. If the system cannot explain a changed recommendation with current evidence and a relevant criterion, do not report it as universal and do not activate it. Fix the evidence, the content, or the decision rule first.

    References

  • How to Audit Search Visibility Before Reputation Risk Spreads

    How to Audit Search Visibility Before Reputation Risk Spreads

    Your branded results can look healthy while a serious risk is forming just outside the familiar blue links. A critical Reddit thread may be climbing, autocomplete may be repeating an uncomfortable association, or an AI answer may describe your product positively but recommend a competitor. By the time that pattern reaches revenue reports, the underlying problem is usually harder to isolate.

    You need an audit that treats search visibility as an early-warning system. That means examining every surface that can shape a branded decision, tracing unfavorable narratives back to their operational causes, and knowing how to respond if Google visibility falls without making recovery more difficult.

    Key takeaways

    • Audit branded search results, search features, and AI recommendations as one reputation surface. A clean organic page does not mean the wider footprint is safe.
    • Record ownership, sentiment, authority, prominence, commercial relevance, and movement for every result. Negative content becomes urgent when several of those factors align.
    • Treat repeated AI criticism as an operational lead. Marketing can clarify facts, but it cannot repair product quality, refund handling, release stability, or employee experience.
    • Separate a manual action from an algorithmic visibility loss before changing the site. Premature reconsideration requests and indiscriminate content deletion can complicate recovery.
    • If Google Search produces 50% or more of sales, visibility loss is a business concentration risk, not merely an SEO problem.

    Audit the decision journey, not just your brand name

    Start with the questions a buyer asks immediately before choosing, rejecting, or contacting you. A search for the company name matters, but it rarely exposes the full risk. Build the query inventory around distinct decisions:

    • Navigational intent: brand, website, login, locations, or contact details.
    • Product intent: brand plus a product, service, feature, model, or plan.
    • Trust intent: brand plus reviews, reputation, reliability, or customer experience.
    • Risk intent: brand plus complaints, problems, returns, refunds, cancellation, or support.
    • Comparative intent: brand versus a named competitor, brand alternatives, or the best option for a defined use case.

    For each query, capture more than the organic positions. Record the date, market, device, signed-in state, exact wording, and visible search features. Save screenshots and URLs so that later reviews compare evidence rather than memory. AI responses require the exact prompt and relevant conversation context because the recommendation can change as the system learns more about the buyer.

    SurfaceWhat to captureWhat should trigger attention
    Organic page onePosition, title, publisher, ownership, sentiment, and target pageA trusted negative result moving upward, or most positive coverage depending on a small cluster of assets
    AI answers and AI OverviewsExact prompt, whether the brand is mentioned or recommended, descriptive language, stated reasons, cited evidence, and competitorsThe brand is omitted, discouraged, weakly described, or consistently outperformed on a commercially important attribute
    Autocomplete and People Also AskSuggested phrases, recurring questions, and the concerns implied by their wordingA complaint or objection becoming part of the standard path to the brand
    Images, news, and Top StoriesDominant visual framing, publishers, headlines, recency, and which assets repeatedly appearUnfavorable framing occupies a highly visible feature even when organic links remain positive
    Discover and TrendsVisible brand themes, changes in interest, and associated topics when these observations are availableA new issue is gaining attention before it becomes prominent in conventional branded results

    Classify every observation as positive, neutral, or negative and as owned or third-party. Then assess four practical factors: prominence, authority, commercial relevance, and movement. A low-authority complaint buried beyond page one may deserve monitoring. A trusted third-party result about refunds that appears prominently for a product-intent query deserves immediate investigation.

    Do not calculate an average sentiment score and call the audit complete. Averages hide concentrated risk. The real question is whether one influential result, feature, or narrative can interrupt a high-value decision.

    Positive coverage also needs scrutiny. Depending on a few favorable ranking assets leaves the brand exposed when Google changes the result mix or a stronger third-party page appears. Repeated versions of an owned announcement are not independent protection. Durable coverage comes from varied, authoritative properties that readers already trust. Wikipedia, Reuters, and the Associated Press illustrate the level of independence involved, but they are not placement targets you can manufacture. Coverage must be warranted, accurate, and editorially earned.

    Trace AI narratives back to the business operation

    Glowing threads connect repeated online warning signals to a delayed package on a stalled warehouse conveyor.

    An AI system may retrieve information about your brand, or it may make a judgment about whether the brand fits a buyer. The second task is more consequential. A buyer asking what a product does is seeking facts. A buyer asking whether to purchase it is inviting the system to weigh suitability, drawbacks, alternatives, and personal constraints.

    Test both types of prompt. Use a stable prompt set that covers identity, fit, differentiation, concerns, and recommendation:

    • What is this brand or product known for?
    • Who is it a good or poor fit for?
    • Why would someone choose it instead of the main alternatives?
    • What recurring concerns should a buyer know about?
    • Would you recommend it for a buyer with a defined need or constraint?

    Record whether the brand appears, whether it is recommended, the adjectives used, the reasons given, the evidence types invoked, and which competitor receives stronger language. These are zero-click visibility measures. They show whether you are present and how you are represented even when no visit reaches your website.

    Do not treat one conversation as a universal ranking. AI recommendations can change with the buyer’s context and within the same conversation. Run the same prompt in a fresh conversation, then run it with a clearly defined buyer situation. Preserve both outputs. The difference tells you which needs or constraints alter the recommendation; it does not establish a single permanent answer.

    The difficult part begins when the answer identifies a credible weakness. Buyer-advice responses can draw on customer complaints, release notes, earnings calls, vendor case studies, and employee reviews. Those inputs sit across the organization, so the SEO team cannot own every remedy.

    • Product quality, inconsistent specifications, or materials belong with product and operations.
    • Returns, refunds, cancellations, and support delays belong with customer experience and the teams that operate those policies.
    • Release defects or instability belong with product and engineering.
    • Weak proof of outcomes belongs with customer success, communications, and the teams responsible for substantiating claims.
    • Recurring employee concerns belong with people leadership and senior management.

    Assign an operational owner to each recurring theme, not merely a communications owner. The sequence matters:

    1. Verify the claim against support records, product documentation, policies, and other relevant internal evidence.
    2. Determine whether it is accurate, outdated, misleading, isolated, or part of a recurring pattern.
    3. Fix the underlying process, product, policy, or service failure where the criticism is valid.
    4. Correct owned information so that current facts are clear, consistent, and crawlable.
    5. Build legitimate independent evidence through satisfied customers, credible case studies, and earned editorial coverage.
    6. Retest the affected queries and prompts while continuing to watch the original complaint.

    Schema can clarify entities and facts, but it cannot erase a consistent negative public record. Publishing more promotional pages while the operational cause remains unchanged usually adds claims without adding credibility. Your durable reputation improvement begins when the public evidence changes because the business changed.

    Diagnose a Google visibility loss before attempting recovery

    A specialist uses a magnifying lens to isolate a fault within a layered model of a website and its search connections.

    A sudden ranking decline creates pressure to act quickly, but speed without diagnosis is dangerous. First determine whether you are dealing with a manual spam action or an algorithmic loss associated with weak, inconsistent, or noncompliant signals.

    A manual action is targeted and is normally confirmed in Google Search Console. It may apply to a subdomain or directory, but a limited scope should not be treated as harmless. Leaving even a partial action unresolved can accompany broader and more persistent visibility damage.

    Without a manual-action notice, correlation with a known update is a hypothesis, not a diagnosis. For sites affected around Google’s August 2026 spam update, content quality appeared to be a primary concern. That does not establish that Google penalizes content simply because AI helped produce it. The relevant issue is the quality of what Google can crawl and index, including whether the publishing system supplies enough human oversight to prevent standards from deteriorating.

    Preserve the state of the site before making broad changes. Your investigation file should include affected directories and page types, query and landing-page movement, Search Console messages, server logs, recent deployments, template changes, and recent publishing batches. This evidence helps distinguish a sitewide system failure from an isolated section or rollout.

    Then work through the diagnosis in order:

    1. Crawl the affected site and compare technical signals across healthy and declining sections.
    2. Analyze server logs. They can reveal crawler activity and heavily visited sections that ordinary SEO reports do not expose.
    3. Review the content production system, including templates, review gates, duplication, editorial controls, and the separation of paid and editorial material.
    4. Test whether the apparent problem reflects a larger business-model conflict with Google’s policies rather than a page-level defect.
    5. Use an independent reviewer where possible. The team that designed and operates the system has an unavoidable incentive to defend its previous decisions.
    6. Remediate the production process as well as the published output so the same failure cannot immediately recur.

    If Search Console identifies a manual action, read its stated issue and scope carefully, but do not limit the audit to the flagged example. The site needs full compliance with Google’s spam policies before a reconsideration request is likely to succeed. Applying before remediation is complete can lead to rejection and make the next attempt more difficult and costly.

    Avoid deleting content wholesale in the hope of sending a dramatic signal. Bulk deletion is difficult to reverse and may destroy pages that could have been corrected, consolidated, or retained. Inventory the affected material, preserve copies, document the reason for each action, and make removal decisions from evidence rather than panic.

    Recovery can still take months. Google must recrawl and reassess the changed site, and a reconsideration request has no guaranteed turnaround time. Meanwhile, competitors can occupy the positions you lost. That is why the remediation plan should include business continuity, not only an SEO forecast.

    Build visibility that can survive a ranking or reputation shock

    Search resilience starts with governance. SEO can detect a narrative, ranking change, or crawl pattern, but the responsible business team must have the authority to resolve its cause. Maintain a shared risk register with the query or prompt involved, visible evidence, affected product, operational owner, severity, remediation status, and the condition that will trigger another review.

    Use event-driven checks as well as a regular monitoring cadence. Revisit branded results and AI prompts after a product launch, significant release, return-policy change, service incident, major employee issue, earnings communication, or material movement in a third-party result. These events can change the public evidence before a conventional ranking report shows the consequence.

    Your reporting should also reflect zero-click outcomes. Track whether the brand is mentioned, how it is described, which attributes it wins, why a competitor is preferred, and whether negative sentiment is becoming more prominent. A positive description is not automatically a win if competitors receive clearer and more persuasive reasons for selection.

    Reduce dependence on individual ranking assets by developing a varied body of credible third-party coverage. At the same time, reduce dependence on Google itself. If Google Search produces 50% or more of sales, treat that concentration as a material business risk. Bing visibility, stronger direct demand, and a recognizable brand can reduce exposure. Larger publishers may also evaluate distinct, genuinely independent brands rather than placing every commercial model under one search identity.

    Start with the product that contributes the most business value and the branded query most closely tied to its purchase decision. Capture the current organic page, search features, and AI narrative. Then assign every unresolved negative theme to the team capable of changing the underlying reality. The immediate goal is not perfect sentiment. It is eliminating unknown risks before rankings, recommendations, or revenue force the issue.

    References

  • How to Win Commercial Visibility in AI Search and Shopping

    How to Win Commercial Visibility in AI Search and Shopping

    If your products rank in Google but disappear when a shopper asks an AI assistant what to buy, the problem may not be your position. The assistant can assemble its answer from product feeds, web pages, structured data, and corroborating mentions before a familiar blue-link ranking earns a click.

    Your job is to make the same commercial facts easy to retrieve, understand, compare, verify, and act on across those surfaces. That requires more than publishing extra content or adding Product schema. You need a consistent product record, decision-ready evidence, and measurement that follows the buying journey beyond rankings.

    Treat AI commerce as a retrieval problem, not a ranking report

    AI shopping has made product feeds much more important. After the release of ChatGPT 5.6, integrated-feed retrieval grew by roughly 6.5 times and overtook web-search retrieval for product recommendations in Shopping mode in one vendor’s measurement. Treat that finding as directional rather than universal: it concerns a particular platform, release, and observed period, not every assistant or product category.

    The practical implication is still substantial. A strong product page may not rescue a weak or stale feed, while a complete feed may not make your product persuasive when an assistant needs to explain why it fits a shopper’s situation. Feed optimization and web optimization are related jobs, but they are not interchangeable.

    It helps to separate commercial visibility into three states:

    • Eligible: the platform can ingest the product and its offer without running into missing, invalid, or conflicting commercial data.
    • Retrievable: the system can identify the product, connect it to the right brand and variant, and recover the relevant facts from a feed or page.
    • Selectable: the system has enough evidence to recommend the product for a particular need, distinguish it from alternatives, and send the shopper toward a credible next step.

    A conventional rank tracker mainly observes part of the retrievable state. It does not tell you whether a shopping system accepted the product, whether a product card appeared, whether the assistant understood the right variant, or whether a competing brand supplied clearer evidence for the recommendation.

    Start an audit with a small set of products that matter commercially. For each one, ask:

    • Does the product appear when the exact brand, model, and variant are requested?
    • Does it appear for the unbranded need it is supposed to solve?
    • Are the displayed price, currency, availability, image, and destination URL correct?
    • Can the assistant explain who the product is for and the conditions under which it is a better choice?
    • Does the answer cite or link to you, merely mention you, or omit you entirely?

    You usually cannot inspect an assistant’s internal retrieval path. Record the observable evidence instead: the exact prompt, market, visible product cards, cited pages, linked domains, stated commercial facts, and landing URLs. That is enough to distinguish a likely feed problem from a content, authority, or conversion problem.

    Build one canonical commercial record for every product

    An unbranded appliance sits in a central data hub that distributes consistent product details to storefront and AI assistant interfaces.

    An AI system should not have to decide which version of your product data is true. The product feed, visible page content, structured data, and checkout path should describe the same entity and active offer.

    Create a parity sheet for each priority product. This is not a general SEO inventory. It is a field-by-field comparison of the places from which a shopping or search system could recover a buying fact.

    Commercial fieldWhat to comparePassing condition
    Product identityFeed title, page title, visible product name, and Product JSON-LDThe same brand, model, product type, and variant are identifiable everywhere
    OfferPrice, currency, availability, and any stated offer conditionsMachine-readable values match what the shopper can see and purchase
    VariantSize, color, capacity, configuration, or other differentiating attributeEach purchasable option leads to the correct data and destination
    DestinationFeed URL, canonical URL, internal links, and purchase pathThe preferred indexable page is also the relevant conversion page
    EvidenceSpecifications, suitability statements, comparison content, and supporting mentionsClaims are specific, consistent, and supported rather than promotional restatements

    Resolve contradictions before filling optional fields. A stale price, confused variant, or unavailable product marked as available can undermine eligibility and trust. Adding more markup around the contradiction only makes the wrong fact easier to extract.

    Product feeds and Product JSON-LD have different roles. A feed delivers inventory and offer data to a participating platform. JSON-LD identifies and annotates the content on your page. One does not automatically repair the other. Both should mirror the visible experience rather than introduce claims or prices that a shopper cannot confirm.

    Use this order when repairing the product record:

    1. Fix identity. Use a stable, consistent brand and product name. Make the model and variant explicit wherever confusion is possible.
    2. Fix the active offer. Align price, currency, availability, and the page on which the offer can actually be completed.
    3. Fix variants and destinations. Prevent a request for one configuration from resolving to a generic page or a different configuration.
    4. Align visible content and markup. Product and Offer schema should describe facts already present on the page.
    5. Add decision evidence. Explain fit, limitations, and meaningful differences in language an assistant can use when comparing options.

    The final step is where many technically correct implementations remain commercially weak. A record can prove that a product exists and is in stock without giving an assistant a reason to choose it. Specifications need interpretation: who benefits from the attribute, in what situation, and with what tradeoff?

    Keep that interpretation factual. If you did not conduct firsthand testing, do not write as though you did. Use documented specifications and clearly defined selection criteria. Unsupported superlatives such as best, fastest, or easiest create less usable evidence than a narrow statement about the buyer and condition for which the product fits.

    Use content to win the choice, then protect the purchase

    Commercial content still matters, but its job has changed. A comparison page may influence an AI answer even when the shopper never clicks it. A product or pricing page must then turn any resulting visit into a confident next action.

    Write consideration pages that can be cited accurately

    Do not assume middle-of-funnel queries are protected because they have commercial intent. In Seer Interactive’s April 2026 sample, AI Overviews appeared on 8% of queries classified as commercial, compared with 36% of informational queries. Query format revealed much greater exposure: comparison formats triggered AI Overviews 95.4% of the time, while best-of formats did so 81.3% of the time.

    That distinction matters because many pages written to influence a purchase use an informational format. A page targeting Product A versus Product B may be commercially important even if the query is classified as informational. Plan around the decision the shopper is making, not the label attached to the query.

    These pages are still worth building. In the same dataset, pages cited within an AI Overview received roughly 120% more clicks per impression than uncited pages on that results page. Citation did not restore the old click opportunity: cited pages remained 38% below results without an AI Overview. The useful conclusion is narrower than citation guarantees traffic. Citation is the strongest available position when an AI answer occupies the search result.

    A citation-ready comparison page should do five things:

    • Define a specific decision. Best software is vague. Best software for a named type of buyer, constraint, and workflow creates a selection problem you can actually answer.
    • State the criteria before the verdict. Tell the reader which attributes affect the decision and why. This makes the conclusion inspectable rather than arbitrary.
    • Name every entity precisely. Use consistent product and brand names, especially when several versions or similarly named offers exist.
    • Write self-contained conclusions. A useful passage should name the buyer, preferred option, reason, condition, and tradeoff without requiring paragraphs of missing context.
    • Support the page as a hub. Link it to relevant product, pricing, specification, and supporting pages. Earn links and credible brand mentions around the decision topic, not only the homepage.

    A reusable conclusion pattern is: For [buyer], [product] is the stronger fit when [condition] because [verifiable feature]. [Alternative] makes more sense when [different condition]. The tradeoff is [meaningful constraint]. Replace every bracket with evidence. If you cannot fill the tradeoff honestly, the comparison is probably not ready to publish.

    Original data and documented firsthand testing can strengthen citation value because they give other pages and models a reason to reference you. They only help when the method is real and explained. Do not manufacture a scoring system to make an opinion look measured. If the conclusion comes from specifications and public documentation, say so plainly.

    Make the next commercial step unmistakable

    Bottom-of-funnel pages occupy more click-protected territory. In the April 2026 sample, AI Overview presence was 5% for transactional queries. That average should not make you complacent: within informational queries, price, cost, and buy formats triggered AI Overviews 83.4% of the time. A query can sound close to purchase while still receiving an AI-generated answer.

    Protect exact-product, pricing, offer, and branded navigational demand deliberately. On the primary conversion page:

    • Put the current price, currency, availability, and material offer conditions where the shopper can find them without interpreting promotional copy.
    • Use a specific call to action that matches the transaction the page supports.
    • Answer the objections that prevent this buyer from proceeding, including compatibility, plan boundaries, variant differences, or other relevant constraints.
    • Link comparison and best-for pages directly to the correct product or pricing destination instead of sending qualified visitors back through the homepage.
    • Keep Product and Offer markup aligned with the visible page and active purchase state.

    Commercial pages can now be more valuable than another high-volume informational page, and citation visibility can matter alongside a traditional ranking. Use top-of-funnel content selectively to close a real topical gap, answer a question needed later in the buying journey, or support a priority commercial hub. Publishing broad definitions without a route to evaluation or purchase is unlikely to fix a commercial visibility problem.

    Measure the commercial journey across every visible surface

    A shopper uses a phone and laptop as a glowing path connects AI discovery, product comparison, selection, and fulfillment surfaces.

    Do not collapse AI visibility into a single score. A percentage can hide the difference between being mentioned, being cited, appearing as a purchasable product, and receiving a visit that converts.

    Build a scorecard with separate observations for each query and priority product:

    • Search position: the conventional organic rank and the search features present around it.
    • AI inclusion: whether your brand or product appears in the generated answer.
    • Commercial presentation: whether a visible product card, correct price, correct variant, and useful destination are present.
    • Citation status: whether the system cites your domain, cites a third party discussing you, mentions you without a link, or omits you.
    • Competitive share: which alternatives appear for the same decision and which claims support their inclusion.
    • Business outcome: attributable visits where available, landing-page engagement, conversion, and revenue.

    Use a fixed query set so the observations remain comparable. Include branded product requests, unbranded need-based requests, comparisons, best-for queries, and purchase-oriented requests. Preserve the exact wording and record the market, interface, visible result type, and observation date. AI outputs can vary, so one prompt run is an example, not a performance trend.

    Segment the scorecard by funnel stage and format. That prevents a large set of informational mentions from hiding the fact that your product is absent when a buyer asks for a recommendation, comparison, price, or place to purchase.

    Use the pattern of failure to choose the next fix:

    • The page ranks, but the product does not appear in shopping results: inspect feed eligibility, identity, offer completeness, and feed-to-page parity.
    • The product appears with the wrong price, variant, or URL: resolve contradictory commercial fields before doing more content work.
    • You rank well, but competitors receive the citations: compare entity clarity, selection criteria, self-contained conclusions, original evidence, links, and brand mentions.
    • You are mentioned but not linked: strengthen the page that owns the relevant decision and make its evidence easier to attribute.
    • You receive citations and visits but few purchases: inspect offer clarity, destination relevance, calls to action, and conversion friction. More visibility will only send more people into the same problem.

    Prioritize work by commercial consequence. Start with products that already have demand or revenue potential, repair the data that determines eligibility, improve the pages that explain the choice, and then build broader authority around those pages. This sequence gives every content and link-building effort a clear commercial destination.

    Key takeaways

    • AI shopping visibility can depend on product-feed retrieval as well as web retrieval, so rankings alone cannot diagnose exclusion.
    • Your feed, visible product page, JSON-LD, variant URLs, and purchase path should describe the same product and active offer.
    • Comparison and best-of pages remain valuable, but they should be written for accurate citation with named entities, explicit criteria, evidence, and self-contained conclusions.
    • Transactional pages deserve deliberate protection because their smaller query volumes can carry much greater conversion value.
    • Track product inclusion, commercial accuracy, citations, links, visits, conversions, and revenue separately instead of relying on one AI visibility score.

    Choose one priority product and trace it from feed to recommendation to purchase page. Fix the first broken handoff you find. Once that path is consistent, repeat the process for the next product rather than spreading shallow optimization across the entire catalog.

    References


  • How to Optimize When Local Customers Stay in Google Maps

    How to Optimize When Local Customers Stay in Google Maps

    Your local rankings look steady, yet calls and website sessions are falling. If those are the only actions in your report, the obvious conclusion is that local SEO has stopped working. That conclusion may be wrong.

    A growing share of customers can evaluate a business, choose it and request directions without leaving Google Maps. Your job is no longer just to earn a listing that sends traffic elsewhere. You need to make the listing useful enough to complete the decision, support it with consistent evidence and measure what happens after the click disappears.

    Diagnose a journey shift before declaring traffic lost

    Corrected US portfolio data comparing Q1 2026 with Q1 2025 found that calls and website clicks each fell 15.8% while direction requests rose 31.3%. The same pattern continued in Q2, but at a slower rate: calls fell 11.9%, website clicks fell 12.5% and directions increased 21.1%.

    The surface mix moved as well. In the US Q2 comparison, desktop Maps impressions rose 3.2% and mobile Maps impressions rose 30.4%, while mobile Search impressions fell 20.1%. That combination supports a practical working hypothesis: some local journeys are moving from search results into Maps, where customers can act without opening the business website.

    It does not prove that every lost click became a store visit. These are portfolio-level changes, not a universal forecast for your locations. A direction request is a strong expression of intent, but it is not a confirmed arrival, purchase or booked appointment. Treat it as a distinct step in the journey and connect it to business outcomes wherever your systems allow.

    • Discovery: Separate Search and Maps impressions, then split them by desktop, mobile, country and location.
    • Decision: Report calls, website clicks and direction requests individually. A shift between them matters even when their combined total appears stable.
    • Outcome: Compare those actions with bookings, qualified leads, online orders, store-level sales or another result the business can verify.
    • Interpretation: If clicks decline while directions and downstream outcomes hold or grow, the journey may have migrated. If every action and outcome declines, investigate demand, visibility, listing quality and conversion instead of assuming a channel shift.

    Rank tracking cannot settle the question. On 179 Google Business Profiles, AI-powered local packs often displayed two businesses rather than three, frequently omitted the call button and surfaced only 32% as many unique businesses as the traditional Map Pack. A tracker built around the traditional pack can therefore show a stable position while the customer sees a different set of choices.

    When performance changes, inspect the actual Search, Maps and AI result experiences that matter to the location. Record whether the business appears, which competitors appear, what facts are shown and which actions are available. The visible interface is evidence your rank number cannot provide.

    Do not apply a US benchmark blindly across countries. In the same Q2 comparison, EU desktop Maps impressions fell 34.7% while direction requests rose 13.1%. The smaller UK dataset moved differently again: mobile Maps impressions fell 70.8% while directions and website clicks increased. For an international brand, each country needs its own baseline and explanation.

    Build a Maps listing that can finish the decision

    A customer holds a phone showing a generic business profile while the matching storefront appears in the background.

    Open your profile as if you have never heard of the business. Can you establish what it offers, whether it suits your need, when it is available, whether other customers trust it and how to reach it? Any unanswered question creates friction. It may also leave Google with too little confidence to answer that question on the business’s behalf.

    Make the profile complete in decision order

    1. Confirm identity. Verify the business name, primary category, address or service area, phone number and website destination. Multi-location brands should verify each location rather than assuming a central data feed is correct everywhere.
    2. Confirm availability. Keep regular and special hours current. If a customer can book, reserve, order or request an appointment through a supported link, test that path from a signed-out customer view.
    3. Describe the actual offer. Use the relevant categories, services, products and attributes available to the profile. Completeness means supplying useful facts, not adding promotional copy to every field.
    4. Test every action. Call the listed number, open the website and booking links, and check where the directions pin ends. A correct-looking profile can still send a customer to a dead page, central switchboard or wrong entrance.
    5. Assign ownership. Give one role responsibility for changes to hours, services, URLs, phone routing and location status. Profile accuracy deteriorates when each field belongs to a different team and no one owns the finished customer experience.

    Completeness should be judged by whether a customer can decide, not by how many fields contain text. Remove stale offers. Avoid vague service descriptions. If two locations provide different services, represent the difference instead of copying one generic profile across the estate.

    Align the profile, location page and entity markup

    Local visibility now has two related layers. Traditional Maps rankings still depend on factors such as proximity, relevance, engagement and prominence. AI Mode and Gemini can layer web context, entity matching, brand authority and review sentiment onto the Google Business Profile. One layer influences whether the location appears as a map choice. The other influences whether an AI system has enough coherent evidence to recommend it or answer a specific question about it.

    You cannot write your way around proximity. You can reduce uncertainty about relevance and identity. The profile, visible website copy and structured data should describe the same real business.

    • Create a useful page for each location, with its real name, address or service area, phone number, hours, services and customer-facing destination links.
    • Keep location distinctions visible in the page copy. A unique URL with generic text does not explain why that branch is relevant to a particular need.
    • Use the most specific applicable LocalBusiness structured data to restate facts that are already visible on the page. JSON-LD should corroborate the page, not introduce claims a customer cannot see.
    • Resolve conflicts between the profile, location page, schema, booking system and other business-controlled records. Do not choose a preferred version for reporting while leaving the public conflict in place.
    • Write plain answers to recurring questions about services, suitability, access and other decision criteria the business can substantiate. Entity clarity comes from consistent facts in context, not repeated keywords.

    Google Maps accuracy is especially important for Gemini because it can draw directly from Maps data. Do not mistake that connection for a complete cross-platform AI strategy. SOCi’s 2026 Local Visibility Index, a vendor benchmark rather than a universal census, found that the share of locations recommended was 1.2% on ChatGPT, 7.4% on Perplexity and 35.9% on Google. Profile accuracy averaged 68% on ChatGPT and Perplexity versus 100% on Gemini in that benchmark. The useful lesson is not that one percentage will predict your brand. It is that different answer engines can know different versions of the same location, so you must test them separately.

    Turn reviews into answer-ready evidence

    Reviews are no longer only a star rating beside your name. Their language can supply evidence about the questions a local customer asks before choosing: Was the place clean? Was it expensive? What was the atmosphere like? Did the business provide the particular service the customer needed?

    Google now prompts reviewers with structured concepts such as atmosphere, price and cleanliness and encourages people to review places they have visited. Cleaner, more specific review data gives an answer system more material to summarize without sending the customer to a website.

    Your review program should invite useful context without scripting praise or feeding customers keywords. A neutral request can ask the customer to mention the service or product they used and what mattered in their experience. That produces more decision value than a generic request for a five-star rating.

    1. Ask after a real interaction. Make the request part of the customer handoff, receipt, completion message or other natural follow-up.
    2. Keep the prompt neutral. Invite an honest description of the service used, the location and the factors that mattered. Do not tell the customer what sentiment or wording to publish.
    3. Analyze themes by location. Separate repeated praise, repeated complaints, service mentions and unanswered questions. A multi-location average can hide a branch-specific problem.
    4. Correct the underlying facts. If customers repeatedly misunderstand parking, pricing, appointment requirements or service availability, clarify the profile and location page where accurate. If the experience itself is wrong, fix operations before rewriting the description.
    5. Respond for the next reader. Address the concrete issue, correct factual misunderstandings calmly and explain a resolved change when appropriate. Do not treat the response as a place to insert target queries.

    Review quality may also affect whether a location enters an AI recommendation set. In the same vendor benchmark, locations recommended by ChatGPT averaged 4.3 stars and those recommended by Perplexity averaged 4.2. Those averages do not establish a rating cutoff, and they do not prove that raising a rating alone will earn a recommendation. They do show why reviews belong in AI visibility work alongside profile accuracy and on-site authority.

    Measure the Maps journey all the way to a business outcome

    An isometric neighborhood scene follows a customer from a phone map and route to a storefront visit and purchase.

    A local dashboard should answer three separate questions: Were you visible, what action did the customer take and did the business receive value? Combining those stages into a single traffic chart conceals the very shift you need to understand.

    Build a scorecard around the action mix

    • Visibility: Search impressions, Maps impressions and observed inclusion in relevant traditional and AI-assisted local results, split by device and market.
    • Profile actions: Calls, website clicks and direction requests shown separately as totals and as shares of all measured profile actions.
    • Website behavior: Sessions and conversions from tagged profile links, including separate appointment, order or location-page destinations where available.
    • Business outcomes: Qualified calls, completed bookings, orders, visits or store-level revenue. Use the outcome the business can measure consistently rather than claiming that every direction request became a customer.
    • Data quality: Incorrect fields, unresolved profile-to-site conflicts, broken destinations and location pages missing decision-critical information.
    • Review evidence: Rating, review volume and recurring themes by location, with operational issues separated from content gaps.

    Do not add a call, a website click and a direction request together and label the total conversions. They represent different intentions and have different relationships to revenue. Keep the raw actions visible, then calculate downstream performance only where your systems provide defensible connections.

    Run a repeatable local visibility cycle

    1. Establish a comparable baseline. Preserve the device, surface, country and location splits. Use a comparable prior period when seasonality makes the immediately preceding period misleading.
    2. Inspect the customer experience. Review the live profile, location page, action links, review themes, traditional local results and relevant AI answers. Capture what a customer can actually see.
    3. Fix factual problems first. Correct identity conflicts, inaccurate hours, wrong categories, broken links and missing service information before rewriting copy or chasing more reviews.
    4. Improve one evidence layer at a time where practical. A location-page update, profile cleanup and review campaign launched together may improve performance, but it will be harder to tell which gap mattered.
    5. Read the whole journey. Compare changes in visibility, action mix and verified outcomes. A click decline with rising directions tells a different story from a decline across every stage.
    6. Use outliers to choose the next action. In a multi-location account, investigate branches where action mix, review themes or downstream results diverge from similar locations. The portfolio average is a starting point, not a diagnosis.

    This cycle also keeps paid and organic decisions grounded. Falling calls alone are not enough to prove that organic visibility failed or that paid search must replace it. You need to know whether customers disappeared, changed actions or finished the journey somewhere your report does not yet measure.

    Key takeaways

    • Google Maps can be the place where a local customer discovers, evaluates and chooses a business, not merely a route to the website.
    • Stable traditional rankings do not guarantee stable exposure in AI-powered local results, and falling clicks do not prove that local demand has vanished.
    • A complete Google Business Profile should answer decision questions and agree with the location page, structured data and customer-facing systems.
    • Reviews provide answer-ready evidence about real customer concerns, but rating averages from a benchmark should not be treated as recommendation thresholds.
    • Direction requests deserve equal visibility beside calls and website clicks, but they must not be reported as confirmed visits.
    • Device, surface, country and location splits are essential because local behavior can move in different directions across markets.

    In your next local report, place calls, website clicks and directions beside the business outcomes they are meant to produce. Then open each priority profile as a customer and remove the most consequential unanswered question. That is how you adapt to a local journey that may end in Maps without losing sight of the result that matters.

    References


  • Google Discover Mechanics: How Content Gets Chosen and Amplified

    Google Discover Mechanics: How Content Gets Chosen and Amplified

    If one story surges in Google Discover while the next one disappears, it is tempting to blame timing, the headline, or luck. That diagnosis is usually too blunt. A page can miss the candidate pool, win attention but lose engagement, or satisfy readers yet reach too few people because the system has weak evidence that this audience and your publication belong together.

    The useful shift is to treat Discover as a recommendation funnel with distinct jobs. Once you separate candidate retrieval, user-content prediction, final ranking, and learned affinity, you can identify the weak transition and work on the right problem.

    Discover is a four-part recommendation system

    A four-stage abstract machine selects, matches, ranks, and distributes content cards to groups of readers.

    Google groups Discover ranking work around retrieval, prediction, ranking, and embedding. These are not four optimization factors or a checklist for publishers. They are four technical jobs within a recommendation system:

    1. Retrieval assembles a set of articles, videos, and other items that might suit the user.
    2. Embeddings represent users and content in a form that allows the system to estimate similarity or relevance.
    3. Prediction estimates what may happen if a particular card is shown to a particular user.
    4. Ranking resolves the competing candidates into the feed the user actually receives.

    The jobs interact rather than forming one simple, publicly documented sequence. Embeddings can support retrieval as well as prediction, and ranking can use information that publishers cannot observe. The model is still valuable because it stops you from treating every distribution problem as a headline problem.

    Retrieval is especially easy to overlook. You cannot rank well inside a candidate set you never entered. Across 42 million monitored cards, about 20 candidate pipelines have been mapped, including candidate sampling, cluster-profile retrieval, trend-embedding retrieval, item-to-item collaborative filtering, and a post-retrieval pipeline heavily populated by YouTube and X content. The labels expose multiple routes into Discover, although they do not disclose the precise rule set behind each route.

    A channel labeled as generative retrieval also appeared in September 2025 in roughly 0.03% of the French Discover feed. That tiny footprint is consistent with a limited test of model-driven candidate selection, not evidence that generative retrieval has replaced the broader system.

    Observed user representations add another clue. Their names cover durable Discover interests, a short-term interest variant, trends, real-time behavior, and shopping-related behavior. This is consistent with a two-tower design in which user and content representations are compared in a shared vector space. The visible labels are real observations; the exact architecture and purpose of each representation remain interpretations rather than confirmed Google documentation.

    Your practical response is to add an audience-state map to your keyword and topic planning. Before approving a Discover-oriented pitch, record:

    • The intended reader: Name the person and existing interest the story serves. A broad demographic is less useful than a recognizable need or content habit.
    • The time horizon: Decide whether the story serves an enduring interest, a developing trend, or an immediate event. Do not judge all three by the same distribution pattern.
    • The relationship to previous coverage: Identify whether the story begins a subject, extends a cluster, or follows an item readers already encountered.
    • The next useful item: Plan what a satisfied reader would reasonably want from your publication after finishing this page.

    None of those fields forces retrieval. They make your publishing intent coherent enough to evaluate. If your team cannot explain who a story is for, why it matters at that moment, or how it relates to your established coverage, changing a few keywords is unlikely to solve the underlying recommendation mismatch.

    Attention and deep engagement are separate predictions

    Discover does not appear to reduce content quality to one universal score. About nine observed prediction values collapse into two nearly independent dimensions: whether a person is likely to stop on a card, and whether that particular person is likely to click and read deeply.

    The correlation between those dimensions is close to zero. A card can be highly effective at interrupting the scroll while being a poor match for sustained reading. That is the mechanical form of clickbait: the promise wins attention, but the experience does not hold it.

    The predictions also correspond with observed behavior. Interaction roughly doubled from the bottom to the top of the deep-engagement score range and declined as the predicted likelihood of scrolling past increased. These measurements do not reveal every ranking input, but they are strong enough to justify separating your own attention and engagement diagnostics.

    Diagnostic layerQuestion to answerPublisher evidence to inspectWhat to change if it is weak
    AttentionDid the card make the right person stop and click?Impression-to-click response, segmented by topic and audience where possibleTest the headline, visual, and topic framing while preserving an accurate promise
    Deep engagementDid the landing experience hold the reader?Engaged time, meaningful scroll, completion, related-content actions, and return behaviorImprove audience fit, opening clarity, structure, depth, and promise fulfillment
    UsefulnessDid the content deliver a result worth the reader’s time?Task completion, use of relevant tools or links, saves, qualified follow-on actions, and direct feedbackAnswer the real question sooner, remove padding, support decisions, and make the next step explicit

    Those publisher metrics are diagnostic proxies, not a list of disclosed Google ranking inputs. An increase in engaged time, for example, does not prove that one metric directly caused more Discover distribution. The purpose of the table is to locate the leak in your own experience before you prescribe a fix.

    If impressions are meaningful but card response is weak, examine attention and candidate-to-reader fit. If clicks are healthy but readers leave quickly, the problem is downstream: the audience may be wrong, the opening may delay the payoff, or the content may not fulfill the card’s promise. If both look healthy but amplification remains limited, a more aggressive title is not the obvious next move. Retrieval, reader-source affinity, and usefulness still need investigation.

    This distinction should change how you run headline tests. Evaluate the card response and the post-click session together. A variation that increases clicks while reducing reading depth may have widened the promise-content gap rather than improving the story’s overall Discover potential.

    Reader-source affinity can outweigh topic potential

    A reader has a strong glowing connection to one familiar content source while weaker paths lead to other topic cards.

    Topic relevance gets a page into the conversation, but personalization can determine how loudly it is heard. Reader-source affinity is the learned relationship between a specific person and a specific publisher. It is not identical to general popularity, topical relevance, or the number of people who pressed Follow.

    A small comparison involving two French sports publishers with nearly equal topic potential illustrates the possible size of that effect. The publisher with deep-engagement predictions about twice as high received amplification on the order of eight times as strong. It also had fewer explicit follows among the test accounts, making raw Follow counts an inadequate explanation for the difference.

    A separate test within one technology publisher found deep-engagement predictions nearly twice as high for accounts that followed the publisher. A United States comparison between ESPN and NFL.com produced a smaller amplification gap of 1.28 times. These were small samples, so none of the figures should become a traffic forecast or universal benchmark. They do support a narrower operational conclusion: learned affinity can materially change distribution even when topic potential is similar, and Follow appears to be one contributing signal rather than a guaranteed reach switch.

    You cannot manufacture reader-source affinity with a metadata field. You can, however, make your publication easier for readers and recommendation systems to understand:

    • Define a repeatable audience contract. Complete this sentence for each content line: We publish this coverage for this reader at this moment so they can achieve this outcome. If the ending changes radically from one story to the next, the content line may be too diffuse.
    • Build continuity, not isolated hits. Connect breaking stories to explainers, updates, recurring series, and logical follow-ups. Item-to-item retrieval and learned source relationships both make continuity more strategically useful than a pile of unrelated traffic bets.
    • Protect expectation accuracy. A headline can attract a broad audience that the body was never designed to serve. That may improve the attention layer while weakening evidence of a durable user-source fit.
    • Use Follow as reinforcement. Invite readers to follow when you can name the continuing benefit they will receive. Treat the action as an affinity input, not a promise that every follower will see every story.
    • Analyze cohorts rather than article averages. Compare returning readers with unfamiliar readers, and compare established coverage areas with occasional topics. A single sitewide average can hide the audience-source combinations that consistently work.

    This does not mean your publication must stay inside one narrow subject forever. It means expansion should have a reader bridge. When you enter an adjacent topic, explain why it matters to the audience you already serve and create enough connected coverage to establish a recognizable promise. A one-off article aimed at an unrelated trend may earn attention without building the relationship that supports future distribution.

    A practical Google Discover diagnosis FAQ

    Why did a strong page receive almost no Discover distribution?

    First distinguish low exposure from low response. If the page received few meaningful impressions, you do not yet have a clean headline test; the card had too little opportunity to win attention. Examine whether the story matches a known audience interest, whether its timing fits an enduring or short-term need, and whether it belongs to a recognizable coverage cluster. Because Discover is personalized, absence from one person’s feed is not proof that the page failed retrieval everywhere.

    Why did impressions increase while clicks stayed weak?

    The page may have entered a candidate pool but failed to earn attention, or it may have been retrieved for people who were not a good fit. Segment the response by topic, reader cohort, and content line before rewriting the title. Then test card packaging that clarifies the subject and payoff without making the promise broader than the page.

    Why did clicks rise while reading depth fell?

    You likely improved the attention layer without improving the user-content match. Compare the card’s promise with the first screen and the page’s actual depth. Put the central answer or development earlier, remove generic setup, and ensure the rest of the page delivers what caused the click. Continue tracking post-click behavior during packaging tests so a higher click rate does not disguise a weaker experience.

    Does asking readers to Follow improve Discover reach?

    Follow can contribute to affinity, but it does not guarantee distribution. The strongest time to ask is when a reader has just received value and you can state what future coverage will continue that value. A generic request adds less strategic clarity than an invitation tied to a recurring subject, update cycle, or series.

    For your next Discover review, build one funnel view: meaningful exposure, card response, post-click depth, and the difference between returning and unfamiliar readers. Fix the first weak transition instead of blending retrieval, packaging, content quality, and audience strategy into one vague Discover problem.

    References