Tag: AI Shopping

  • AI Product Discovery Tracking: A Practical Measurement Plan

    AI Product Discovery Tracking: A Practical Measurement Plan

    You can rank well in traditional search, maintain a complete product feed, and still have no clear answer to a basic question: when someone asks an AI assistant what to buy, does your product appear?

    AI product discovery tracking closes that gap. It records how individual products appear in shopping-oriented answers, separates visibility from accuracy, and gives you evidence for deciding what to fix. The goal isn’t to collect screenshots of flattering mentions. It’s to understand which SKUs enter the recommendation set, under which buying conditions, and what happens next.

    Track the buying decision, not a single brand mention

    A brand-level visibility score is too blunt for ecommerce. An assistant can mention your company while recommending the wrong product, an unavailable variant, or an item that doesn’t satisfy the shopper’s constraints. That mention looks positive in a dashboard but does little for the buyer.

    Use the SKU, or the most stable product identifier available, as the primary measurement unit. Connect each observation to the exact prompt, platform, market, date, product variant, cited page, merchant, and answer text. This lets you distinguish a product-level problem from a broad brand problem.

    The relevant measurement surface is also wider than one chatbot. Commercial monitoring is now offered for SKU-level visibility across ChatGPT Shopping, Alexa for Shopping, Perplexity, and Google AI Mode. Keep results separate by platform. Combining them into one score too early can hide the fact that a product is consistently discoverable in one environment and absent in another.

    For every observed answer, classify five different outcomes:

    • Presence: Did the brand, product family, or exact SKU appear?
    • Prominence: Was it a primary recommendation, a secondary option, or a passing reference?
    • Qualification: Did the answer connect the product to the shopper’s stated use case, budget, features, or constraints?
    • Representation: Were the name, variant, attributes, availability, and other offer details accurate?
    • Handoff: Did the answer provide a citation, merchant, product page, or another usable route toward purchase?

    These outcomes answer different questions. Presence tells you whether the product entered the answer. Qualification tells you whether the system understood why it fits. Representation reveals whether the underlying product information is coherent. Handoff shows whether visibility can plausibly lead somewhere useful.

    Build the measurement specification before choosing a tool

    A tracker can automate collection, but it can’t decide what your business means by visibility. Write the measurement specification first. Otherwise, a vendor’s default prompts and scoring system will quietly become your strategy.

    1. Create a product identity registry. Give every tracked item a canonical name and identifier. Add brand names, model names, common aliases, parent-child variants, canonical product URLs, and the merchants authorized to sell it. This prevents a shortened model name or alternate spelling from being counted as a different product.
    2. Define the eligible product set for each prompt. A recommendation is only meaningful if the SKU could reasonably satisfy the request. If a prompt requires a feature the product doesn’t have, its absence isn’t a visibility failure.
    3. Group prompts by buyer intent. Keep category discovery, feature-led discovery, problem-led questions, comparisons, branded validation, and purchase-ready requests in separate groups. A product that performs well on branded prompts but disappears from category discovery has an acquisition problem that a blended score will conceal.
    4. Record the test environment. Store the platform, location or market setting, language, session state when controllable, device context when relevant, and collection time. If a condition can’t be controlled, label it unknown rather than assuming consistency.
    5. Freeze a core prompt panel. Run the same core prompts repeatedly so changes are comparable. Maintain a separate exploratory panel for emerging language, new use cases, seasonal needs, and questions discovered in customer research.
    6. Define what counts before collecting results. Decide how aliases, bundles, parent products, variants, repeated mentions, unordered lists, and cited merchant pages will be handled. Apply those rules to your brand and competitors alike.

    Prompt wording needs particular care. “Best running shoe” and “running shoe for a wide forefoot on wet pavement” don’t represent the same decision. The second prompt supplies constraints that can change which products are eligible. Preserve those constraints in your reporting instead of collapsing everything into a generic keyword.

    Don’t let exploratory prompts replace the fixed panel. New prompts improve coverage, but changing the entire prompt set between measurement periods destroys comparability. Use the fixed panel to detect movement and the exploratory panel to find new opportunities.

    Use a scorecard that keeps visibility, accuracy, and outcomes separate

    No single metric can represent the whole discovery journey. A useful scorecard shows where a product was eligible, whether it appeared, how it was described, and whether the answer created a usable path forward.

    MetricHow to calculate itWhat it helps you decide
    Eligible prompt coverageEligible prompts containing the tracked SKU divided by all prompts for which that SKU was eligibleWhether the product enters relevant recommendation sets
    Recommendation shareRecommendations of the tracked product divided by all product recommendations in the same prompt setHow often your product appears relative to alternatives
    Primary recommendation rateAnswers treating the SKU as a leading option divided by answers mentioning itWhether mentions are prominent or incidental
    Qualification rateMentions that accurately connect the SKU to the prompt’s constraints divided by all SKU mentionsWhether the system understands the product’s relevant use cases
    Attribute accuracy rateVerified product claims divided by all checkable claims made about the SKUWhether conflicting or incomplete product information needs attention
    Handoff rateSKU mentions with a usable citation, merchant, or product destination divided by all SKU mentionsWhether discovery can progress toward consideration or purchase
    Competitor overlapEligible prompts where your SKU and a named competitor both appear divided by eligible prompts where either appearsWhich products compete in the same answer contexts
    Downstream engagementObserved visits and commerce events attributed to an identifiable AI handoffWhether measurable discovery activity contributes to business outcomes

    The denominator matters. If you calculate coverage across prompts where a product couldn’t satisfy the stated need, you manufacture a weakness. If you count every brand mention as a product recommendation, you manufacture success. Keep the eligibility rules visible next to the score.

    Preserve the underlying observations as well as the aggregate metrics. Store the returned product names, supporting language, cited URLs, merchants, competing products, and factual errors. When a score changes, you should be able to inspect the answers behind it.

    Keep business outcomes in a separate layer. An AI mention isn’t a sale, and a sale that follows an AI interaction may not be fully attributable. Where a link, referral, or tagged destination is observable, connect it to product views, cart activity, and purchases. Where the handoff can’t be observed, report the outcome as unknown. Turning unknown activity into zero activity makes the dashboard look precise while reducing its usefulness.

    Diagnose whether the failure is eligibility, selection, or representation
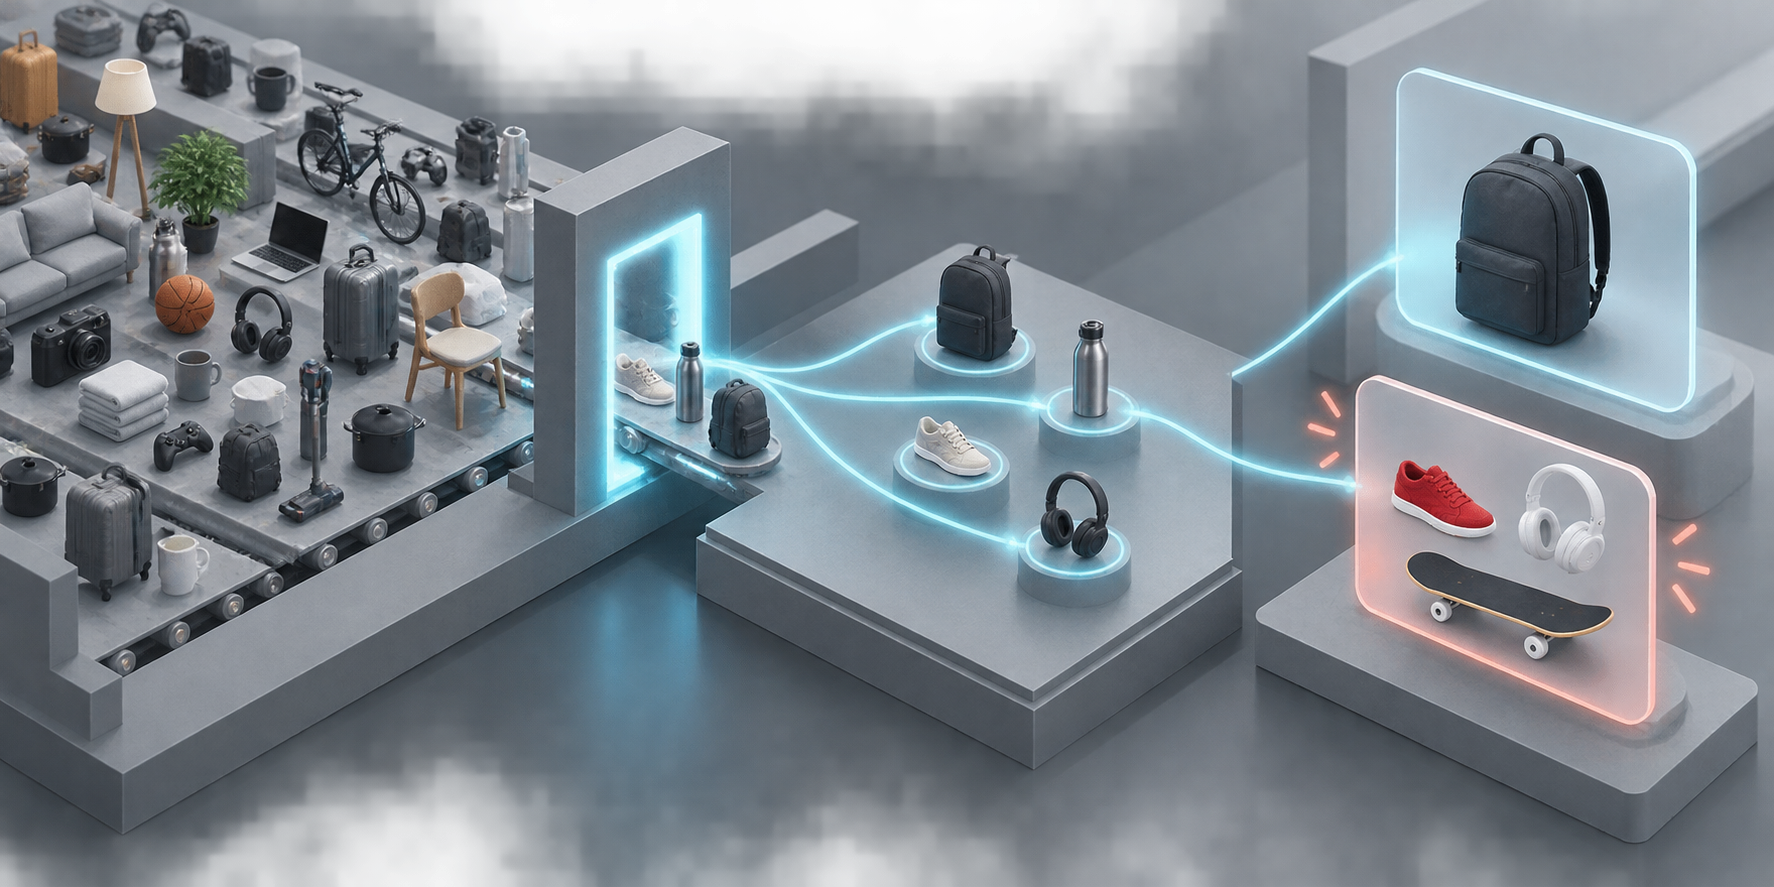
    A three-stage product recommendation pipeline filters products, selects a smaller group, and displays them in translucent answer cards.

    A missing product doesn’t tell you why it was omitted. The output gives you a symptom, not a causal explanation. Use it to form a testable hypothesis, then inspect the product information and competitive context that could support or contradict that hypothesis.

    Eligibility failure: the product isn’t understood as a candidate

    If the SKU is absent from non-branded prompts even though it genuinely meets their constraints, check whether its identity and qualifying attributes are expressed consistently. Review the visible product page, structured data, commerce feeds, variant records, category assignments, and merchant listings. Names, identifiers, sizes, colors, prices, availability, and feature claims shouldn’t contradict one another.

    JSON-LD belongs in this audit, but don’t treat schema as a magic visibility switch. Its job is to express product information in a machine-readable form. It should match the visible page and the current offer data. If the markup describes a different variant or stale availability, adding more markup compounds the ambiguity.

    Selection failure: the product is known but rarely recommended

    A product may appear for branded validation prompts yet lose generic category, comparison, or problem-led prompts. That pattern suggests the system can identify the item but doesn’t consistently connect it to the buyer’s decision criteria.

    Build a gap matrix from the actual answers. Put the prompt constraints in rows and the recommended products in columns. Record the reasons given for each recommendation. Then compare those reasons with claims your product can substantiate. If an important, verifiable attribute is missing from your product page or expressed only in an image, make it clear in the visible copy and structured product information. If your product doesn’t meet the criterion, don’t manufacture a claim to fit the prompt.

    Representation failure: the product appears with incorrect details

    Incorrect model names, mixed variants, stale offer details, or unsupported attributes are not positive visibility. Capture every checkable claim in the answer and compare it with the canonical record. Then locate conflicts across the pages, feeds, markup, and merchant data you control.

    Correct the canonical product information before trying to increase mention volume. More exposure for a misrepresented SKU can send a shopper toward the wrong variant or create expectations the product can’t meet. Keep a record of the incorrect answer and the correction date so later observations can be evaluated against the change.

    Turn tracking into a controlled optimization loop
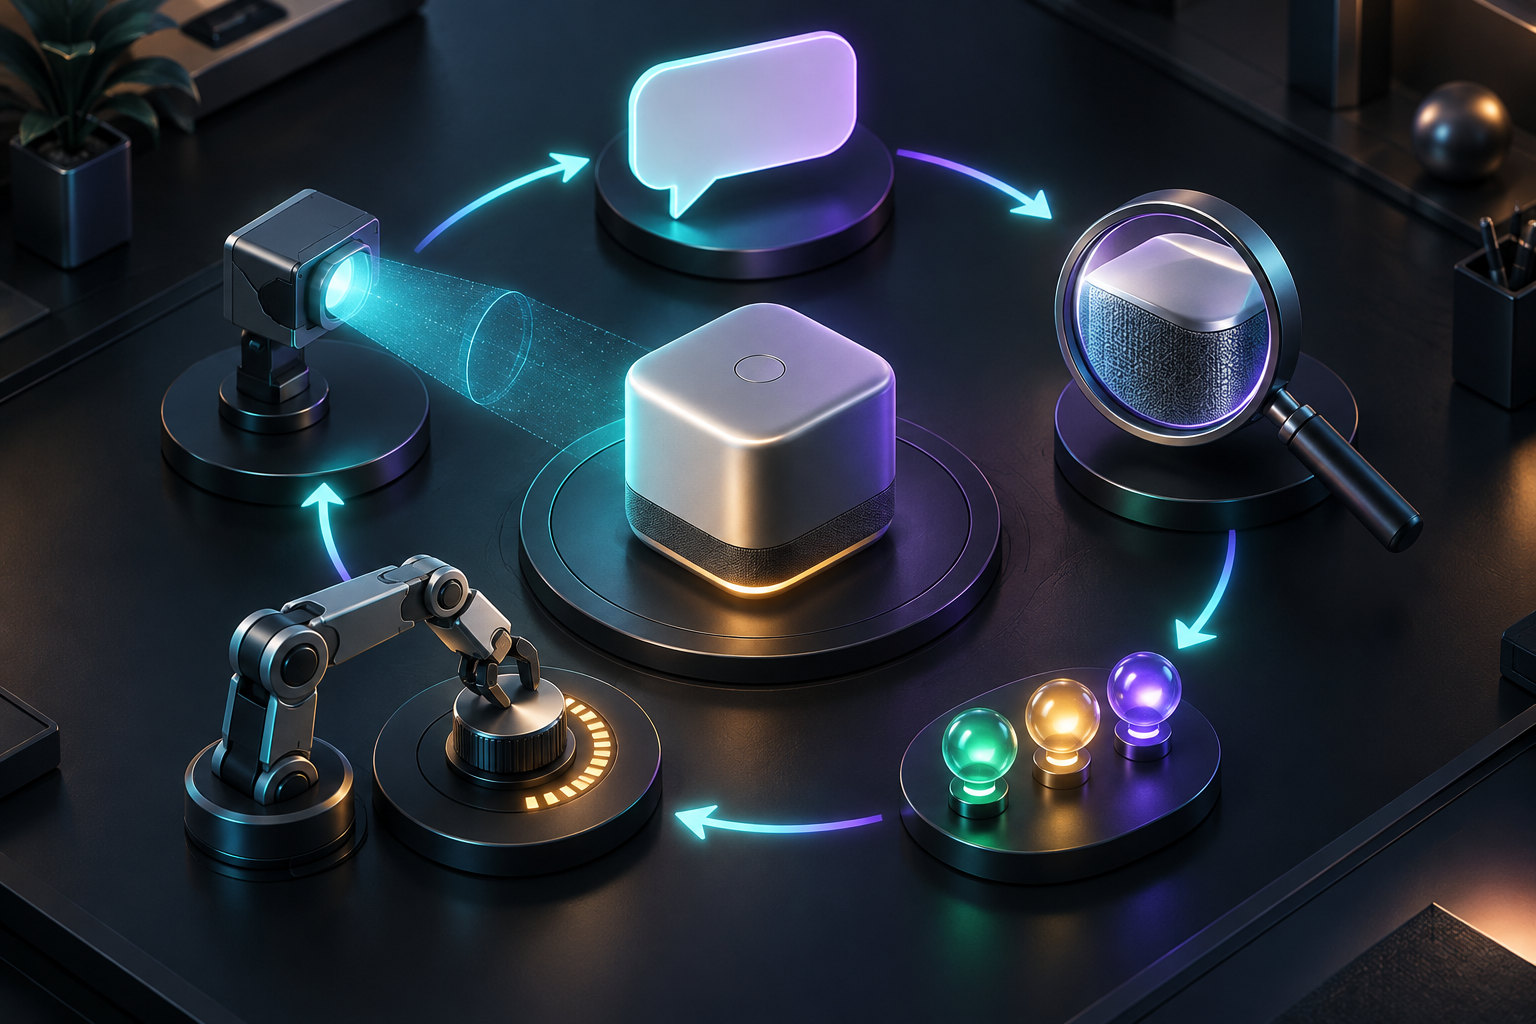
    An unbranded product sits at the center of a circular testing and optimization process with inspection, measurement, adjustment, and verification stations.

    AI outputs can vary between runs, so a single before-and-after query is weak evidence. Treat optimization as repeated observation around a documented change.

    1. Capture the baseline. Run the fixed prompt panel and preserve the complete responses, not just the calculated scores.
    2. Choose one failure class. Decide whether you’re testing product identity, attribute completeness, use-case relevance, comparison content, offer consistency, or another specific hypothesis.
    3. Change one information layer where practical. If you rewrite the page, replace the feed, alter structured data, and change merchant listings simultaneously, you may improve visibility without learning which correction mattered.
    4. Log the deployment. Record the affected SKU, URLs, fields, platforms, markets, and publication time. Include rollbacks and feed errors in the same log.
    5. Repeat the same core observations. Keep prompts, eligibility rules, and classification logic stable. Evaluate whether the direction of change persists across repeated collections.
    6. Compare unaffected products. Similar movement across changed and unchanged SKUs may indicate broad output variation or a platform-level shift rather than the effect of your work.
    7. Promote only durable findings. When an improvement continues to appear under the same measurement conditions, apply the lesson to other eligible products and keep monitoring for representation errors.

    Report platform results independently and segment them by intent. A gain in branded prompts doesn’t prove stronger category discovery. A gain on one assistant doesn’t prove that another system changed. The useful reporting unit is the intersection of platform, market, intent group, and SKU—not an unsupported universal visibility score.

    Competitor tracking should support diagnosis rather than imitation. Note which products recur, which buyer constraints they are associated with, what supporting pages are cited, and where their descriptions are inaccurate. This reveals the information standards operating within a prompt set. It doesn’t prove that copying a competitor’s wording, markup, or content structure will reproduce its visibility.

    Key takeaways for a tracker you can trust

    • Measure exact products and variants, not brand mentions alone.
    • Define SKU eligibility for each prompt before treating an omission as a failure.
    • Separate presence, prominence, qualification, factual accuracy, handoff, and business outcomes.
    • Keep a stable core prompt panel for comparison and a separate exploratory panel for discovery.
    • Preserve raw answers and cited destinations so every aggregate score can be audited.
    • Use observed outputs to form hypotheses; don’t claim they reveal a ranking system’s hidden cause.
    • Audit visible content, structured data, feeds, and merchant records for consistency when product identity or attributes are wrong.
    • Evaluate changes through repeated observations and unaffected comparison products, not one favorable response.

    Start with a narrow set of commercially important SKUs and the prompts for which they are genuinely eligible. Build the identity registry, freeze the core panel, and collect a baseline before editing anything. Your first useful result won’t be a universal visibility score. It will be a defensible answer to which product is missing, where it is missing, and what evidence you need to test next.

    References


  • Google Merchant Center UCP Integrations: What to Enable

    Google Merchant Center UCP Integrations: What to Enable

    You have three separate decisions to make when Google’s UCP integration hub appears in Merchant Center. You can send a cart to your website, support checkout on Google, link customer identities, or adopt only the capabilities that fit your operation.

    The right choice depends less on what you can switch on than on where you can safely own the customer, order, and recovery experience. Use the framework below to choose a scope, test the handoffs, and measure whether UCP removes purchasing friction without creating an operational blind spot.

    What the UCP integration hub actually changes

    Google is gradually making the Merchant Center UCP integration hub available to eligible U.S. merchants. UCP stands for Universal Commerce Protocol. In this rollout, it acts as a connection layer between Google’s shopping experiences and a merchant’s commerce infrastructure.

    The meaningful change is modularity. An eligible merchant can select individual capabilities instead of accepting one predetermined checkout experience. That turns UCP configuration into a set of business decisions rather than a single technical integration.

    CapabilityWhat changes in the journeyYour release gate
    Cart transferThe shopper’s cart moves from Google to the merchant’s website, where the purchase can continue.The correct products, variants, quantities, prices, and context must survive the handoff.
    Native checkout on GoogleThe shopper can complete checkout within Google’s experience.Your order operation must reliably receive, fulfill, reconcile, support, cancel, and refund the resulting orders.
    Identity linkingThe shopper’s Google identity can be connected with the merchant’s customer relationship.The customer benefit, consent path, account-matching rules, unlinking process, and support recovery must be clear.

    Treat the last column as your own acceptance standard. The presence of a capability in Merchant Center tells you that it is available to configure; it does not prove that your downstream systems, policies, analytics, or support team are ready for it.

    For SEO, AEO, and GEO teams, the boundary matters. UCP is commerce infrastructure. It can shorten the distance between product discovery and purchase, including journeys in which AI agents help people research products, assemble carts, and transact. It should not be treated as a ranking switch, a replacement for Merchant Center feed quality, or a substitute for accurate product pages and structured data.

    Choose each capability by ownership and failure radius

    A modular ecommerce system separates identity, checkout, and fulfillment into bounded zones, with an amber warning contained inside the checkout area.

    Start with the customer journey you can operate reliably. A shorter path is valuable only when the order that emerges from it is accurate, observable, and recoverable.

    1. Consider cart transfer first when your website checkout is already the strongest part of the journey. It lets Google participate in discovery and cart creation while your existing site remains the purchase destination. Test the handoff as a data contract: the product identifier, selected variant, quantity, current price, availability, promotion context, and destination page must agree. Also define what the shopper sees when a price changes, an item sells out, or the cart cannot be reconstructed.
    2. Consider native checkout when your order operation can support a transaction completed outside your website. Map the entire order lifecycle before enabling it: creation, payment state, tax, shipping, inventory reservation, fulfillment, cancellation, returns, refunds, customer notifications, fraud review, and support. Do not assume that a native interface transfers responsibility for these functions. Confirm the division of responsibility for your particular setup.
    3. Consider identity linking when signing in produces a real customer benefit. That benefit might involve account continuity, saved preferences, loyalty, or post-purchase service, but the benefit must be explicit. Define how accounts are matched, what happens when identifiers disagree, how duplicate accounts are handled, how consent is recorded, and how a customer can unlink or recover access.

    The hub’s capability-by-capability selection model gives you a reason to avoid an all-at-once launch. Enable the smallest useful combination first. If cart transfer fails, you can investigate the cart contract. If identity linking and native checkout go live at the same time, an order problem may involve identity resolution, checkout state, or the order pipeline, making the cause harder to isolate.

    That sequencing is especially important for identity linking. It introduces customer-data, authentication, privacy, and support consequences that are different from the mechanics of moving a cart. Review it as its own workstream rather than treating it as a convenience setting attached to checkout.

    Build six release checks before changing the customer journey

    Six quality-control stations test product availability, cart transfer, identity, payment, order confirmation, and customer recovery along an ecommerce purchase path.

    You do not need to wait for a full implementation project before preparing. You do need a written acceptance plan. Build these six checks while access is rolling out:

    1. Confirm the actual scope in your account. Record which Merchant Center account, market, storefront, and capabilities are eligible. The rollout begins with eligible U.S. merchants, while plans for Australia and Canada have moved to a later schedule. Work from the controls present in your account rather than treating an announced market sequence as a guaranteed activation date.
    2. Define the catalog contract. Name the system that owns each product identifier, variant, price, currency, availability state, image, and fulfillment promise. The website, Merchant Center data, cart, and order record should refer to the same sellable item. If two systems can overwrite a value, document which one wins and when.
    3. Define the cart contract. Specify what must survive a transfer and what can be recalculated on arrival. Include quantity limits, variant selections, promotions, unavailable items, expired carts, and price changes. Write the customer-facing fallback for each failure; a silent empty cart is not an acceptable recovery path.
    4. Define the order contract. For native checkout, trace a successful order and every material exception through the systems your teams use. An order is not complete merely because payment appears successful. It must enter inventory, fulfillment, notifications, reporting, customer service, cancellation, return, and refund workflows with a stable identifier.
    5. Define the identity contract. Decide what data is linked, why it is needed, what consent is required, how long it is retained, and which team handles mismatches. Include duplicate accounts, shared email addresses, changed email addresses, revoked access, deletion requests, and support verification.
    6. Define observability and recovery. Assign an owner for integration errors, order discrepancies, customer complaints, and rollback decisions. Preserve enough identifiers to trace a journey across the surfaces you control without exposing unnecessary personal data. Document how you will pause a capability safely if failures rise.

    Use any preview, testing, or diagnostic path that your Merchant Center account makes available. If your account exposes only a broad production control, complete the data and operational checks before changing it. Do not discover your refund path, account-recovery rules, or missing order identifiers through the first customer complaint.

    Launch one capability at a time when the available controls permit it. Start with the smallest reversible product or operational scope supported by your setup. Keep a written record of the prior configuration, the activation time, the owner on duty, the expected signals, and the condition that triggers a pause.

    Measure the handoff, not just the final sale

    A conversion total can hide the exact friction UCP is meant to remove. Build a funnel that shows where an eligible journey stopped. Instrument the events available on the systems you control, then reconcile them with the commerce and order records available from the integration.

    • Eligible journey volume: the number of shopping journeys that could use the enabled capability.
    • Cart initiation and transfer: how many carts begin, how many handoffs are attempted, and how many arrive with usable contents.
    • Checkout progression: how many transferred or native journeys reach checkout, encounter an error, and complete.
    • Order reconciliation: whether each completed transaction produces one accurate order in the system of record, without omissions or duplicates.
    • Commercial consistency: discrepancies involving products, variants, quantities, price, availability, tax, shipping, discounts, or currency.
    • Operational consequences: cancellations, refunds, identity-recovery cases, integration-related support contacts, and manual corrections.

    Capture a baseline before launch. Compare the same journey before and after enablement where your data permits, and separate technical success from business success. A cart can transfer perfectly while conversion falls because the landing experience is confusing. Native checkout can increase completed orders while creating reconciliation work that erases the operational benefit.

    Website analytics alone will be incomplete when checkout finishes on another surface. Do not interpret a drop in site-recorded purchases as a drop in total purchases until native orders have been reconciled. Conversely, do not count an external checkout confirmation as a clean success until the corresponding order is present and actionable in your system of record.

    Keep search visibility and commerce performance in separate reporting layers. Monitor product discovery, landing-page visibility, feed health, and structured-data quality alongside the UCP funnel, but do not attribute a ranking change to UCP merely because the dates overlap. Its immediate job is to connect discovery, cart, identity, and transaction paths more effectively.

    Consistency is the point where the SEO and commerce teams meet. Use the same product identity, variant language, pricing state, availability, and merchant policy across Merchant Center, the website, structured data, cart, checkout, and order systems. UCP cannot compensate for contradictory facts moving through those systems; it can only make those contradictions reach the customer faster.

    Key takeaways

    • UCP in Merchant Center is a selectable integration layer, not one mandatory checkout model.
    • Choose cart transfer when your site checkout should remain the transaction destination and you can preserve cart accuracy through the handoff.
    • Choose native checkout only after the complete order, support, cancellation, return, and refund lifecycle works outside a website-completed purchase.
    • Review identity linking separately because it adds consent, account-matching, privacy, authentication, and recovery requirements.
    • Measure attempted handoffs, errors, discrepancies, and reconciled orders as well as conversions.
    • Do not treat UCP enablement as evidence of improved rankings; maintain product data, content, feeds, and structured data as separate visibility work.

    If the hub is already available in your account, begin with a capability decision and an acceptance checklist, not the activation control. If it is not available, prepare the catalog, cart, order, identity, and measurement contracts now. That work remains useful regardless of when eligibility reaches your market or account.

    References


  • AI Search and Shopping Agent Visibility: A Practical System

    AI Search and Shopping Agent Visibility: A Practical System

    Your product appears in an AI answer on Monday, disappears on Tuesday, and returns through a different citation on Friday. That does not automatically mean your optimization worked, failed, and recovered. It means you are looking at a system that assembles answers dynamically rather than assigning one durable position.

    You need a visibility program built for that volatility. The goal is to increase the probability that your brand is found, understood, supported by credible evidence, and selected when an AI system moves from answering a question to helping someone choose a product.

    Replace the idea of one ranking with three layers of visibility

    A conventional ranking gives you a page, a query, and a position. An AI answer can vary its wording, cited URLs, recommended brands, and product shortlist from one run to the next. Treating one generated response as a ranking report will produce false alarms when you disappear and false confidence when you happen to appear.

    The volatility is large enough to affect how you interpret every test. When 10,000 keywords were run through Google AI Mode three times on the same day, the average URL overlap was only 9.2%. For 21.2% of the keywords, the three runs had no cited URLs in common. In another large test, Google AI Overview content changed in roughly 70% of checks, while only 54.5% of cited URLs overlapped between consecutive runs.

    Yet changing citations do not always mean that the underlying answer has changed. The semantic similarity of those AI Overviews remained at 0.95 even while their wording and evidence rotated. You can therefore lose a particular citation while the system continues to express the same category preference, recommendation criteria, or view of your brand.

    Measure three layers separately:

    • Answer visibility: Does the brand or product appear in the generated response, recommendation, shortlist, or comparison?
    • Evidence visibility: Which owned or third-party pages are cited, and what claims are those pages supporting?
    • Commerce readiness: Can a shopping agent determine what the product is, who it suits, which variant applies, and whether the commercial information is complete enough to support a decision?

    This distinction matters because the remedy depends on the layer. If your brand remains recommended but your URL stops being cited, you may have an evidence-distribution problem. If your pages are cited but your product never reaches the shortlist, your positioning or product fit may be unclear. If the product appears but the agent reports an incorrect price, variant, or use case, the problem is data consistency rather than general brand awareness.

    Shopping agents raise the stakes. Personal agents such as Muse and Instinct can find products, compare options, and make purchasing decisions for users. Your job is no longer finished when an AI system mentions the brand. The system must also be able to qualify the product against the buyer’s situation.

    Build a measurement system that survives volatile answers

    A stable monitoring hub tracks a shifting field of abstract answer panels and citation nodes connected by changing paths.

    Start with the questions that precede a real decision, not a collection of high-volume keywords. A useful prompt library represents the different jobs a buyer asks an assistant to perform:

    • Problem discovery: asking what kind of product solves a stated need.
    • Use-case qualification: looking for a product that fits a particular audience, environment, workflow, or constraint.
    • Comparison: weighing products or product types against explicit criteria.
    • Risk reduction: checking compatibility, limitations, policies, reliability, or suitability.
    • Purchase preparation: verifying variants, availability, price, delivery, returns, or another decision-critical fact.
    • Branded evaluation: asking whether your product is suitable and what alternatives should be considered.

    Write prompts in the buyer’s language and preserve the qualifiers that change the answer. “Best project-management software” and “project-management software for a small agency that needs client approvals” are not interchangeable questions. The second prompt gives the system criteria it can use to include or exclude a product.

    Run the same library on each AI platform you care about, but do not blend the results into one universal score. Google AI Overviews and AI Mode shared only 13.7% of their citations in one comparison. Platform-specific shifts can also be abrupt: Reddit’s average share of ChatGPT Search citations fell from 3.83% to 0.52% across the reported periods, an 86.4% decline, while the broader pattern was not uniform across AI systems.

    A blended average can hide exactly what you need to diagnose. Keep separate views for each platform, answer surface, market, and language you test. Aggregate them only after you have inspected the underlying results.

    Repetition is equally important. Published sampling guidance indicates that 60 to 100 runs of a prompt can produce meaningful visibility data. Another longitudinal approach recommends at least seven runs per prompt per day for brand-level estimates, assessed through rolling windows of two to four weeks. These are measurement benchmarks, not a claim that every team must immediately test at that scale. If your budget supports fewer observations, label the result as directional and avoid making budget or content decisions from a single response.

    Your dashboard should answer operational questions rather than merely count mentions:

    QuestionMetricWhat to recordLikely next action
    Are we present?Brand mention rateValid runs containing the brand divided by all valid runs for that prompt setInvestigate prompt clusters where competitors appear consistently and you do not
    Are products being considered?Product inclusion rateRuns in which an eligible product enters the shortlist or comparisonClarify audience fit, category language, and comparison attributes
    What supports the answer?Citation rate by domain and URLOwned and third-party pages cited for each claim or recommendationStrengthen missing evidence and pursue relevant independent coverage
    Is the answer accurate?Fact accuracy rateCorrect and incorrect statements about fit, specifications, terms, and availabilityResolve contradictions across pages, catalogs, feeds, and structured data
    Is the change persistent?Rolling visibility rangeRates and ranges over repeated runs, separated by platformAct on sustained movement rather than an isolated response

    Keep a changelog beside the data. Record platform and model updates, material website changes, catalog releases, content refreshes, and significant third-party coverage. The log will not prove causation, but it prevents the team from inventing an explanation after every rise or fall.

    Use a simple decision rule: one unusual answer is an observation; a repeated change within the same platform and prompt cluster is a pattern worth diagnosing. If the decline appears everywhere at once, inspect broad accessibility, brand evidence, and product-data issues. If it appears only for comparison prompts, look first at the criteria buyers use to distinguish products.

    Make every product answerable before expecting it to be selectable

    A generic product moves from organized attributes and evidence nodes through a transparent reasoning structure into a highlighted selection tray.

    A shopping agent cannot infer a reliable recommendation from a product name and a persuasive description alone. Early testing of personal agents points to three practical visibility requirements: usable product catalogs, accessible websites, and clear statements about who each product is for.

    Audit each commercially important product as a package of decision facts. The exact attributes will vary by category, but the agent should be able to resolve the following without reconciling conflicting pages:

    • Identity: a stable product name, canonical URL, model or SKU, brand, and an unambiguous relationship between the main product and its variants.
    • Audience fit: the user, situation, problem, or level of experience the product is designed for. State meaningful limitations when they affect suitability.
    • Comparison attributes: the specifications, capabilities, materials, dimensions, compatibility details, or service limits a buyer would use to compare alternatives in your category.
    • Commercial terms: current price and currency, availability, variant-level differences, applicable delivery information, returns, and warranty terms where relevant.
    • Evidence: explanations, documentation, or independent validation that supports important claims instead of merely repeating them.
    • Consistency: agreement among the visible product page, catalog or feed, structured data, policy pages, and any regional or variant pages.

    “Who it is for” deserves its own content block. Avoid empty labels such as “for everyone” or “perfect for professionals.” Give the agent usable selection criteria: the problem solved, the expected environment, required compatibility, relevant experience level, and conditions that would make another option more suitable. Clear exclusions can improve recommendation quality because they reduce the chance that your product is matched to the wrong request.

    Use Product and Offer structured data as a consistency layer, not as a magic entry ticket. Markup should express facts that a visitor can also verify on the page. If the visible page says one price, the catalog says another, and the structured data carries an expired offer, adding more schema will multiply ambiguity rather than remove it.

    Variant handling needs particular care. A parent product page may describe the range, but decision-critical facts should remain attributable to the correct size, configuration, color, region, or service tier. An agent comparing two variants should not have to guess which price or specification belongs to which option.

    Test accessibility from the agent’s point of view. Open the page in a clean session. Confirm that the product identity, fit, principal attributes, and commercial terms are available without signing in, accepting an unnecessary location flow, opening an image, or relying on an interaction that hides the only copy of a critical fact. Then compare the rendered page with the catalog and structured data field by field.

    Finally, test a decision sequence rather than one branded prompt. Ask an assistant to identify products for a constrained use case, compare the candidates, explain which user each candidate suits, and verify the facts needed for a decision. Record where your product disappears and which unresolved criterion caused the exclusion. That point is a more useful optimization target than the wording of the final answer.

    Publish and earn evidence that AI systems can resample

    Once a product is technically legible, it still needs current evidence. AI-cited URLs were 25.7% fresher on average than conventional organic results in one large comparison: cited pages averaged 1,064 days old, versus 1,432 days for organic results. This does not mean that changing a date will improve visibility. It means the information environment being sampled by AI systems tends to include fresher material.

    Refresh a page only when you can make it more useful. Add new product facts, answer newly important buyer questions, update obsolete comparisons, correct policy details, incorporate original data, or explain a material change. Keep the URL stable when the underlying resource remains the same, show a meaningful update date, and remove contradictions left by earlier versions.

    Owned content is necessary but insufficient. In one citation analysis, owned media accounted for 13.7% of AI citations while earned media accounted for 84%. Journalism represented 27%, and paid content represented only 0.3%. These labels should not be treated as a simple exclusive pie chart, but the practical signal is clear: visibility often depends on credible pages you do not control.

    Build an evidence map around the claims that determine selection. For each important prompt cluster, list the claims an assistant would need to justify: category membership, audience fit, distinctive capability, compatibility, comparative strength, limitation, and commercial availability. Then mark where each claim is supported:

    • on a canonical owned page;
    • in your product catalog and structured data;
    • in independent reporting, reviews, comparisons, or other third-party material;
    • nowhere reliable enough to support a recommendation.

    The empty cells are your publishing and public-relations brief. Create original material where you control the underlying evidence. Seek independent coverage where an outside assessment would carry more value. Do not treat a press release as a durable substitute for either one; press-release citation share proved unstable and declined over the reported period, largely because ChatGPT cited releases less often.

    Prioritize third-party coverage that contributes information of its own. A useful comparison, test, interview, dataset, or category explanation gives an AI system a reason to retrieve the page beyond the presence of your brand name. Repetition across low-value placements may expand the number of mentions without supplying better evidence for a recommendation.

    Connect publishing back to measurement. When a prompt cluster lacks visibility, identify whether the missing input is product data, owned explanation, or independent evidence. Make the smallest substantive change that addresses that gap, record it in the changelog, and assess it across repeated runs. That gives you a testable operating cycle instead of a stream of unrelated content.

    Key takeaways for your next visibility cycle

    • Treat an AI response as one sample, not a permanent ranking. Report visibility as a rate and range across repeated runs.
    • Separate brand inclusion, cited evidence, and commerce readiness. Each layer has a different failure mode and remedy.
    • Build prompts around discovery, qualification, comparison, risk reduction, and purchase preparation rather than isolated keywords.
    • Measure each AI platform separately. A blended score can conceal a platform-specific gain, loss, or citation shift.
    • Make product identity, audience fit, comparison attributes, variants, and commercial terms explicit and consistent across the page, catalog, feed, and structured data.
    • Refresh important pages with substantive information, not a changed date, and cultivate independent evidence for claims that influence selection.

    Begin with one commercially important product family and the prompts closest to a decision. Establish a repeated baseline, inspect where the product falls out of the journey, and fix that exact gap. Once the page, catalog, schema, and outside evidence tell the same clear story, extend the system to the next product family.

    References


  • ChatGPT Virtual Try-On: An Ecommerce Optimization Playbook

    ChatGPT Virtual Try-On: An Ecommerce Optimization Playbook

    You may be asking a deceptively simple question: what should your ecommerce team change now that a shopper can preview a product inside ChatGPT? The answer isn’t to add AI shopping phrases to every page. Virtual try-on moves part of product evaluation upstream, before the shopper reaches your store.

    Your job is to make each product understandable during discovery, visually recognizable during evaluation, and easy to buy when the shopper finally reaches the product page. That requires coordinated work across imagery, catalog data, structured data, fit guidance, landing-page UX, and measurement.

    Virtual try-on changes where product evaluation happens

    On eligible clothing and accessory listings, ChatGPT can display a Try on button that lets a shopper take or upload a selfie. ChatGPT Images then generates a visualization of that person wearing the item. A product doesn’t have to originate in a ChatGPT recommendation: the shopper can also upload an image or screenshot of something found elsewhere and request a virtual try-on.

    That creates a shopping path that may look like this:

    1. The shopper describes the clothing or accessory they want.
    2. ChatGPT surfaces products that appear relevant.
    3. The shopper visualizes a candidate product on their own image.
    4. They compare it with other possibilities.
    5. They save promising items or visit a merchant to inspect the offer and buy.

    Product discovery and visual evaluation can therefore happen within the same conversation. ChatGPT also lets shoppers save products to Favorites, organize them into Library folders, and return to them on mobile or the web. A recommendation is no longer necessarily followed by an immediate click. The shopper may build a shortlist first and arrive at your store later with a narrower set of questions.

    For an ecommerce SEO or GEO team, that changes the optimization target. You need to support three decisions:

    • Recognition: Can the product be distinguished from superficially similar items?
    • Evaluation: Can the shopper understand its color, cut, pattern, material, and available variations?
    • Completion: Can your product page resolve size, price, availability, delivery, and return questions without introducing contradictions?

    This doesn’t make the product page less important. It gives the page a more demanding role. The visitor may already like the apparent look; the merchant must now establish exactly what is being sold and reduce the remaining purchase risk.

    The screenshot workflow matters just as much as native product discovery. A shopper may encounter your item in search, on a marketplace, in a social post, or on another page before bringing its image into ChatGPT. Your visual assets need to remain recognizable when separated from their original context.

    Build a coherent product record, not an AI optimization gimmick

    An unbranded sneaker is surrounded by connected product images, color swatches, size cells, packaging, and a product card.

    There is no established Try on optimization formula, required image dimension, or special schema property that guarantees eligibility. Treat promises of guaranteed inclusion through a single field with skepticism. The practical goal is coherence across the product image, visible copy, variation selector, commerce feed, and structured data.

    Use images that still make sense outside the product page

    Start with the main image because it is the most likely visual shorthand for the product. It should make the item easy to identify without forcing a system or shopper to infer which object is for sale.

    • Show the complete garment or accessory clearly in at least one image.
    • Keep the product visually distinct from props, backgrounds, and neighboring items.
    • Use the correct image for each color or pattern variation.
    • Provide additional views when the front image hides important construction, shape, fastening, or pattern details.
    • Keep image treatment consistent enough that a shopper can recognize the same item across a listing, a screenshot, and the product page.
    • Avoid putting essential product facts only inside image text. Those facts also belong in visible HTML.
    • Write useful alternative text for accessibility and page comprehension, but don’t claim that alt text controls a virtual try-on rendering.

    Run a simple crop test. View the product image without its title, price, or surrounding page. Ask whether a person could identify the item type, dominant color, pattern, and intended variation. If the answer depends on the missing copy, the image is doing too little. If several products compete for attention, it is doing too much.

    Don’t replace accurate catalog photography with speculative AI composites merely to appear AI-ready. A visualization system needs a dependable representation of the product. Your controlled assets should establish ground truth, while the generated try-on remains a separate, personalized interpretation.

    Make attributes explicit and consistent

    Product copy should identify the attributes that distinguish the item. A poetic collection name may support branding, but it shouldn’t carry the entire descriptive burden. Pair it with plain product language that states what the shopper is looking at.

    • Use a stable product name, brand, and product type.
    • Name the actual color as well as any branded color name.
    • Describe the material or fabric without making unsupported performance claims.
    • State the silhouette, length, pattern, closure, and other decision-relevant features when they apply.
    • Map every displayed image to the correct selectable variation.
    • Keep price, currency, availability, and condition aligned wherever those fields appear.
    • Use valid product identifiers consistently. Never invent an SKU, GTIN, or other identifier to fill an empty field.
    • Provide measurements and size information in accessible page content rather than relying on an image alone.

    Structured data should mirror that visible record. Product and Offer JSON-LD can express product and commercial facts in a machine-readable form, but markup is not a substitute for accurate page content and isn’t evidence of virtual try-on eligibility. If the page shows one price while the Offer markup publishes another, the problem isn’t a missing AI tactic; it is a conflicting product record.

    Check variation handling closely. The selected color, image, SKU, availability, price, and structured data should refer to the same offer. If your implementation updates some of those fields dynamically, verify the rendered state rather than reviewing only the page template or source code. A technically valid block of JSON-LD can still describe the wrong variant.

    Audit the complete product path

    Use this sequence on representative clothing and accessory templates:

    1. Open a live product and select each meaningful variation.
    2. Compare the selected option with the main image, gallery, visible name, price, stock state, and product identifier.
    3. Inspect the rendered Product and Offer data for the same variation.
    4. Check the size guide, measurements, material details, delivery information, and return policy.
    5. Capture the main product image as a shopper might encounter it elsewhere and verify that the product remains recognizable.
    6. Resolve contradictions before adding more copy or markup. Consistency is the prerequisite, not the finishing touch.

    This audit is useful beyond ChatGPT. It removes ambiguity from the catalog record that your own customers, feeds, analytics, search systems, and other shopping interfaces must interpret.

    Separate appearance visualization from fit, then strengthen the handoff

    A shopper previews a coat on a virtual avatar beside fit tools, size samples, and an abstract checkout screen.

    The most important boundary is also the easiest one to blur: virtual try-on is a visualization, not a fitting room. The generated result may not represent the shopper or product exactly and doesn’t guarantee size or fit. Merchant measurements, product details, and return policies remain part of the buying decision.

    Think of the preview and product page as answering different questions:

    Shopper questionBest answer surfaceWhat the answer must communicate
    How might this style look on me?Virtual try-on visualizationA directional visual impression, not a promise of exact appearance or fit
    Which size should I order?Merchant size guide and measurementsClear measurement definitions, units, garment dimensions, and relevant sizing notes
    What exactly am I buying?Product page and variation selectorThe selected color, material, construction, images, price, and availability
    What happens if it isn’t right?Delivery and return informationApplicable conditions, timing, process, and customer costs

    Your size guidance needs enough context to be usable. Distinguish body measurements from garment measurements. Name the measurement points and units. Explain relevant stretch, cut, or layering considerations without pretending they can predict an individual’s fit. If sizing differs by product line or market, put the correct guide on the affected product rather than sending everyone to a generic chart.

    The landing page should preserve continuity with what the shopper evaluated. The same variation should be easy to recognize, and the page should expose the remaining decision information without making the visitor hunt for it.

    • Keep the product name and selected variation visible near the main image.
    • Show current price and availability for that variation.
    • Place the size selector close to the relevant size guide.
    • Make material and care information easy to scan.
    • Present delivery and return terms before the shopper commits to checkout.
    • Explain unavailable variations honestly rather than silently switching the selection.
    • Keep mobile layouts usable because the shopping features are available on both mobile and web.

    Favorites add another handoff consideration. A shopper may save an item, compare it with alternatives, and return after the original discovery session. Stable product URLs, persistent identifiers, current inventory, and clear replacement behavior matter more than a landing experience built only for an immediate click.

    If you describe AI visualization on a page you control, keep the claim narrow. Plain language such as “The preview is a visual approximation; check the product measurements and return terms before ordering” sets the right expectation. Don’t call a generated image proof of fit, exact drape, precise color reproduction, or guaranteed appearance.

    Measure discovery, merchant handoff, and post-purchase outcomes

    Referral traffic alone will not describe the full effect. A shopper can upload a product screenshot found elsewhere, evaluate it in ChatGPT, save it, and return by another route. Some influence will therefore be invisible to your analytics or appear under a later source.

    Observe visibility without treating one answer as a ranking report

    Create a repeatable set of prompts based on real customer language. Include product type, material, color, occasion, style, and other attributes your catalog genuinely supports. Record whether your products appear, whether the correct variation is represented, whether the cited destination resolves correctly, and whether a Try on option is shown when relevant.

    Use those checks diagnostically. They can expose ambiguous naming, weak imagery, broken destinations, and inconsistent variants. They do not establish universal market share, a permanent ranking, or the cause of a recommendation. Avoid turning a favorable answer from one session into a performance claim.

    Instrument the merchant handoff

    Preserve raw referrer information where your analytics and consent setup permit it, and group identifiable ChatGPT visits without overwriting the underlying source. Then evaluate the onsite sequence rather than counting sessions alone.

    • Which products receive identifiable AI referral visits?
    • Does the landing URL resolve to the intended product and variation?
    • Do those visitors use the gallery, variation selector, or size guide?
    • Where do they leave the product and checkout funnels?
    • Do they add the evaluated item to the cart, or switch to another variation or product?
    • Are analytics events firing consistently across mobile and desktop?

    A high click count with frequent variant switching may indicate that the upstream image or product description set the wrong expectation. Strong product-page engagement with weak size selection may point to incomplete fit guidance. Treat these as diagnostic signals to investigate, not automatic proof of causation.

    Connect the experiment to business outcomes

    Virtual try-on is intended to help a shopper evaluate a product, so the useful outcomes sit deeper than impressions. Track completed purchases, cancellations, exchanges, returns, and available reason codes for the affected products. A generated preview that increases curiosity but creates a mismatch at delivery is not an unqualified success.

    Use a controlled improvement cycle:

    1. Save a baseline for the selected product group, including its images, visible attributes, structured data, funnel behavior, and return outcomes.
    2. Fix one interpretable layer, such as variation-image mapping or measurement content.
    3. Repeat the same visibility checks and review the same onsite events.
    4. Annotate concurrent changes in price, promotion, inventory, seasonality, and delivery terms.
    5. Read the result as directional unless the design actually isolates the changed variable.

    Don’t label every post-change sale as AI-driven revenue. Report what you can observe directly, separate identifiable referrals from inferred influence, and name the blind spots. Favorites activity inside ChatGPT and screenshot-based exploration are not merchant-side analytics events.

    Key takeaways

    • ChatGPT virtual try-on can combine product discovery, selfie-based visualization, comparison, and shortlisting before a merchant visit.
    • A shopper can upload a product image found elsewhere, so clear and recognizable assets matter beyond native ChatGPT listings.
    • There is no basis for promising eligibility from one schema field, keyword, image treatment, or feed attribute.
    • Product images, visible content, variations, commerce feeds, and Product and Offer structured data should describe the same item and offer.
    • Virtual try-on visualizes a possible look; merchant measurements, size guidance, product facts, and return terms must handle fit and purchase risk.
    • Measure visibility, onsite behavior, purchases, and returns while acknowledging that screenshot and Favorites activity may leave no direct referral trail.

    Start with a representative clothing or accessory template and follow one product from its standalone image through variant selection, JSON-LD, size guidance, return information, and analytics events. Fix every contradiction you find before scaling the audit across the catalog. That gives you a durable commerce foundation whether the next shopper discovers the product through ChatGPT, another AI interface, a conventional search result, or a saved screenshot.

    References


  • AI Search Visibility Is Not Value: How to Measure the Gap

    AI Search Visibility Is Not Value: How to Measure the Gap

    You can be cited by an AI answer and still lose the customer. Your product details may help construct the response while a better-known competitor gets the recommendation, click, and sale. If you publish content, the split can happen further upstream: an AI system can use your work while the economic return remains negligible or impossible to predict.

    That is the practical problem behind unequal value distribution in AI search. You will not solve it by tracking mentions alone. You need to measure each handoff from citation to recommendation, action, and compensation, then work on the point where value stops moving toward you.

    AI search value passes through five separate gates

    Visibility is not one outcome. From your point of view, it is a chain of increasingly valuable outcomes. A business can succeed at one gate and fail at the next.

    GateQuestion to answerMeasure
    CitationDid the response name or link to your site as supporting material?Citation share across eligible responses
    Candidate inclusionDid the response name your brand, store, product, or publication as an option?Mention or shortlist share
    RecommendationDid the system endorse you, especially as its first choice?Recommendation rate and top-choice rate
    ActionDid the exposure produce a visit, inquiry, subscription, or purchase?Traceable visits, leads, and conversions
    Value captureDid the commercial return justify the content, inventory, and operational cost?Attributed revenue, direct payment, and contribution margin

    The distinction matters because an AI answer can use one company as an information source and send the buyer to another company. For publishers, even a direct contribution payment can be too small or volatile to support the work that produced the material.

    Do not combine these gates into a single AI visibility score. A blended score can improve while commercial performance deteriorates. If citations rise but top recommendations fall, the headline number will hide the loss that matters.

    The largest value losses occur after retrieval

    Glowing information particles emerge from a repository and enter a central prism, then split into pathways that narrow sharply before reaching product, interaction, and value symbols.

    Shopping responses show the citation-recommendation gap clearly. Large and small retailers each represented roughly 38% of the stores cited, yet large retailers appeared about 2.5 times as often as small retailers in the top recommendation. Smaller merchants were visible to the systems. They were much less likely to receive the most commercially valuable placement.

    Web access reduced the imbalance without removing it. When search was unavailable, large national chains received 63% to 70% of recommendations, while small and local retailers appeared about 10% of the time. With live search, large retailers still took 46% to 58% of top recommendations across ChatGPT, Google AI Mode, and Google AI Overviews.

    The gap cannot be dismissed as a simple failure to find smaller stores. When an AI system was presented with one large retailer and one smaller store without explicit size labels, it selected the larger retailer in 90% to 94% of responses. This establishes a behavioral pattern, not its cause. It does not prove that any model contains an explicit rule favoring chains, so your audit should measure outcomes rather than speculate about an undisclosed ranking factor.

    Query specificity widened the difference. Small retailers secured roughly one-third of top recommendations for broad requests, but only about 10% when the shopper specified a product. Over the same shift, large retailers moved from roughly 40% to 60% of top recommendations. If you sell specific products, a healthy citation count can therefore coexist with weak purchase-intent visibility.

    Publishers face a second distribution problem: content use does not necessarily produce proportionate compensation. Google’s limited AI Contribution pilot reportedly includes about 100 publishers, but several small and midsize participants received less than 0.1% of their advertising revenue from it. Smaller sites received less than $1,000 over several months, while individual participants were reported at approximately $50,000 to $60,000 after joining and more than $1 million a year in another case.

    Those absolute payouts do not reveal a dependable market rate. Publisher scale, content contribution, eligibility, and the calculation behind monthly changes are not disclosed clearly enough to normalize the figures. The pilot is also too limited to support a conclusion about what most publishers will earn if it expands. Treat it as preliminary evidence of a payment mechanism, not as a forecast you can put into a budget.

    Build an audit that finds the exact value leak

    A transparent five-chamber system carries glowing particles toward a reservoir while a magnifier and inspection light reveal a leak at one connection.

    Your audit should connect controlled prompt testing with real business outcomes. Prompt testing shows what happens before a click; analytics and commercial records show what happens afterward. Neither view is sufficient on its own.

    1. Define the entity and outcome. Choose the brand, product line, location, or publication you are assessing. Then name the desired result: a top recommendation, store visit, qualified lead, sale, subscription, or content payment. Do not substitute citations for that result.
    2. Create separate prompt cohorts. Test broad category requests, specific product requests, requests using local or near me, and requests explicitly asking for an independent business. Keep the commercial intent consistent enough that differences remain interpretable.
    3. Separate platform conditions. Record the platform, product mode, whether live web search is active where that condition is controllable, the displayed model or version when available, the target market, and the test date. Do not merge searched and non-searched responses into one rate.
    4. Grade placement, not merely presence. For each response, record whether you were cited, named as a candidate, recommended, and placed first. Also record the wording: being mentioned as one option is not equivalent to being called the best fit.
    5. Inspect the destination. If a link appears, record its landing page and whether that page can complete the user’s task. A product recommendation that lands on a generic homepage may create visibility without usable demand.
    6. Join the prompt record to downstream evidence. Track attributable referral traffic where it is available, relevant landing-page conversions, assisted conversions you can substantiate, and direct platform payments. Label untraceable exposure as untraceable rather than assigning it an invented monetary value.

    Use separate rates so you can see where performance changes:

    • Citation share: responses citing you divided by eligible responses.
    • Candidate share: responses naming you as an option divided by eligible responses.
    • Top-choice rate: responses placing you first divided by eligible responses.
    • Citation-to-top-choice conversion: responses that both cite you and place you first divided by responses citing you.
    • Action rate: measurable visits, leads, subscriptions, or purchases divided by the relevant exposure measure available to you.
    • Value capture: substantiated revenue or platform compensation compared with the cost of producing and maintaining the underlying content or commerce experience.

    The citation-to-top-choice calculation is especially useful. If citation share rises while that conversion rate falls, your information is becoming more useful to the answer without your business becoming more likely to receive the decision.

    Do not use one undifferentiated prompt average. A retailer can perform adequately on broad discovery prompts and disappear when a shopper names a product. Segmenting by specificity exposes that loss. Segmenting independent separately from local also prevents a nearby branch of a national chain from being counted as evidence that independent businesses are winning.

    Improve the handoff that is failing

    The appropriate intervention depends on the failed gate. More content is not the automatic answer. If you are already cited frequently, producing another page that earns citations may deepen the same imbalance.

    For retailers and service businesses

    The strongest prompt-level change came from the word independent. Adding it more than doubled the share of small and local businesses named, moving their share from roughly one-third to nearly four-fifths in a randomized prompt sample. On Google’s platforms, large-chain sources fell from about 44% under neutral wording to as little as 9%.

    That result changed the user’s request, not the merchant’s website. It does not prove that adding independent to a page will produce the same lift. The responsible action is narrower: if independent ownership is accurate and relevant, state it plainly in visible business descriptions and keep the fact consistent wherever your identity is represented. Then retest. Do not imply independent ownership merely to chase a recommendation pattern.

    Treat local and independent as different attributes. Requests using local or near me had much less effect because an AI system can legitimately interpret a nearby national-chain branch as local. If your advantage is ownership rather than distance, a local-only measurement set will answer the wrong question.

    For specific-product prompts, inspect the facts a system and a shopper need to make a decision: the precise product, current availability, service area or delivery coverage, purchase path, and differentiators relevant to that request. Publish only details you can keep accurate. The available evidence does not prove that any one field improves AI selection, but reducing factual ambiguity gives you a cleaner test and a better destination if a recommendation does occur.

    Use structured data, including JSON-LD, to clarify facts that also appear on the page. Do not present schema as a way to force a recommendation. Machine-readable information can support understanding; it cannot guarantee that an AI system will prefer your business over a larger competitor.

    For publishers and content-led businesses

    Separate audience value from content-use value. Audience value includes visits, subscriptions, leads, and purchases you can substantiate. Content-use value includes contribution payments or licensing income. A citation can contribute to either, both, or neither.

    If you participate in a contribution program, maintain a monthly ledger containing the payment, any available citation or usage information, AI referral traffic, revenue linked to that traffic, and the cost of the eligible content. Do not infer that the payment is impression-based, click-based, or proportional to the amount of content used. Participants in Google’s pilot reportedly do not receive enough explanation to determine why their payouts change from month to month.

    Set your investment rule before an attractive payout anecdote changes your expectations. Continue or expand work only when substantiated direct revenue, defensible assisted value, and disclosed contribution payments together justify your own cost threshold. There is no supported industry benchmark in the available pilot data, so the threshold must come from your economics.

    When payments are opaque and unstable, classify them as uncertain supplemental revenue. Do not hire, commission a content program, or abandon a working traffic channel on the assumption that the pilot will expand on comparable terms. The safe planning case is the amount you can defend from your own records, not another publisher’s headline payout.

    Use the following diagnosis to decide where the next unit of work belongs:

    Observed patternLikely value leakNext action
    Low citation and low recommendation ratesDiscovery or factual clarityCheck accessibility, identity consistency, and whether relevant pages answer the tested request.
    High citation rate but low top-choice rateSelectionClarify truthful differentiators and decision-relevant facts, then rerun the same prompt cohorts.
    High recommendation rate but weak measurable actionDestination or attributionInspect links, landing pages, calls to action, and gaps in analytics before producing more content.
    Strong AI referral traffic but poor conversionOffer or on-site experienceTreat it as a conversion problem and analyze the landing experience by intent.
    Frequent content use but opaque or negligible paymentValue captureLimit financial dependence, document the economics, and treat undisclosed payments as uncertain.

    Key takeaways

    • A citation proves visibility or use. It does not prove recommendation, traffic, or commercial value.
    • Track top-choice rate separately from citation share because the largest loss can occur between those two events.
    • Segment broad and specific-product prompts. Smaller retailers can lose substantial recommendation share as a request becomes more specific.
    • Do not treat local as a substitute for independent; the two words encode different customer preferences.
    • Do not budget around preliminary publisher-payment anecdotes when eligibility, calculation methods, and monthly changes remain opaque.

    On your next AI visibility report, add two columns beside citations: top-recommendation share and attributable business outcome. If you publish content, add compensation and content cost as well. The first empty or underperforming column is where your next investigation belongs.

    References


  • How to Make Products Visible to AI Personal Shoppers

    How to Make Products Visible to AI Personal Shoppers

    Your product can rank in conventional search and still disappear when a shopper asks an AI assistant what to buy. The missing piece is usually not another generic category paragraph. It is making the product easy to identify, test against constraints, and defend in a recommendation.

    AI personal shoppers can shape which products make the shortlist. That changes your visibility target. You are no longer optimizing only for a page visit; you are helping a system decide whether your product is eligible, relevant, credible, and safe to recommend for a particular request.

    AI shopping visibility is a three-gate problem

    There is no universal ranking formula for AI shopping. Assistants use different catalogs, retrieval systems, merchant feeds, pages, and models. Their answers can also change as availability, prices, prompts, and underlying systems change. A practical three-gate model is more useful than pretending every platform works the same way.

    1. Discovery: Can the assistant find and identify the correct product or variant?
    2. Qualification: Can it determine whether the product satisfies the shopper’s stated constraints?
    3. Selection: Is there enough relevant evidence to choose the product and explain that choice?

    A product has to pass the gates in that order. Better promotional copy cannot rescue a product the system cannot identify. Strong reviews cannot compensate for an unspecified compatibility requirement. Complete structured data does not prove a broad superiority claim.

    This sequence gives you a diagnostic method. If the product never appears, inspect discovery before rewriting the sales copy. If it appears for broad prompts but disappears when a constraint is added, inspect the relevant attribute. If it remains eligible but another product receives the recommendation, inspect comparative relevance and supporting evidence.

    The important distinction is between being mentioned and being recommendable. A system may know that your product exists while lacking the facts needed to place it in a defensible shortlist.

    Build one canonical product truth

    A hiking shoe on a central platform sends the same set of visual product attributes to a storefront, phone, warehouse shelf, and AI orb.

    Start with an internal product record, not a block of marketing copy. This record should be the authoritative source for the product page, structured data, merchant feeds, marketplace listings, comparison pages, and support content. When those surfaces disagree, an assistant has to choose among conflicting claims or avoid repeating them.

    For each product and meaningful variant, define the following fields explicitly:

    • Identity: brand, product name, model, assigned SKU or GTIN, canonical URL, and product category.
    • Variant: color, size, capacity, material, pack quantity, configuration, and the relationship to the parent product.
    • Eligibility attributes: dimensions, weight, compatibility, intended use, required accessories, included components, operating conditions, and other category-specific constraints.
    • Commercial facts: price, currency, condition, availability, fulfillment terms, returns, and warranty terms.
    • Evidence: certifications, documented test conditions, review data, manuals, specifications, and the exact scope of each claim.

    Do not populate a field because competitors use it or because a schema validator permits it. An unknown value should remain unknown until the business can verify it. A precise false claim is worse than an honest omission because the false claim can be repeated in a recommendation, create a poor purchase, and undermine trust in the rest of your data.

    Keep the visible page, schema, and feeds aligned

    Product structured data should encode facts that a shopper can also verify on the page. Use Product markup to identify the item and its attributes. Use Offer data only for an offer that actually exists. Add rating or review properties only when the corresponding information is genuine, visible, and attached to the correct product or variant.

    JSON-LD does not create product truth. It translates product truth into a machine-readable form. If the page says one material, the markup says another, and the feed omits the field, adding more schema will multiply the ambiguity rather than fix it.

    Variant handling deserves particular attention. A family page may describe several configurations, but price, dimensions, availability, ratings, and compatibility can belong to only one of them. Give meaningful variants stable identities and make the selected variant unambiguous in the page content, URL behavior, structured data, and feed.

    Separate durable facts from fast-changing facts

    Product data fails at different speeds. Model identity, dimensions, materials, compatibility, and included components are usually durable. Price, availability, promotions, delivery estimates, and review aggregates can change much faster.

    Give each fast-changing field an owner, a system of record, and a refresh trigger. Avoid embedding volatile values in editorial prose unless that prose is updated from the same source. A stale promotional page and a current product feed can leave an assistant with two plausible answers and no reliable way to reconcile them.

    Match shopper constraints and support every important claim

    Traditional product copy often begins with a head keyword and expands into benefits. AI shopping requests are more likely to combine a job, a hard constraint, and a preference: a product for a particular use, compatible with something the shopper already owns, within a budget, and with a preferred trade-off.

    Create a prompt set from the decisions people make, not just the phrases with the highest search volume. Include several distinct request types:

    • Job prompts: What is the shopper trying to accomplish?
    • Constraint prompts: What would make a product ineligible, such as size, compatibility, material, price, or availability?
    • Trade-off prompts: Which quality matters more when no option maximizes everything?
    • Comparison prompts: Which alternatives are genuinely close enough to compare?
    • Risk prompts: What must the shopper verify before buying?

    Then map every consequential question to a field and a piece of evidence. The map exposes a common failure: the marketing team believes a benefit is obvious, but the product page never supplies the fact an assistant would need to infer it safely.

    Shopper questionMachine-readable answerHuman-verifiable support
    Will it fit?Dimensions, weight, capacity, or supported size rangeSpecification table, diagram, or installation instructions
    Will it work with what I own?Compatible models, interfaces, versions, or required accessoriesCompatibility page, manual, or clearly scoped support content
    Can I buy it under my stated conditions?Current price, currency, condition, availability, and offer detailsVisible offer and fulfillment information
    Is it suitable for this use?Intended use and relevant product attributesUse-case explanation tied to specifications rather than slogans
    Can I trust this claim?Named evidence and its scopeCertification details, documented method, policy, or attributable review data

    State who the product is and is not for

    A useful product page helps an assistant eliminate the wrong matches. State the primary use, the buyer or environment it suits, the constraints it satisfies, and any condition that would make another option more appropriate.

    This does not weaken the offer. A clear limitation can make the positive recommendation more credible. If a product requires an adapter, has a fixed dimension, excludes a particular model, or is designed for one usage pattern rather than another, say so close to the relevant benefit. Hiding the qualifier may generate more initial interest, but it gives an assistant less reason to trust or repeat the claim.

    Comparison content should use decision criteria rather than a list of adjectives. Explain which product fits which condition and why. Avoid declaring an item the best without naming the use case, comparison set, and evidence. An unqualified superlative is difficult to defend and easy for a recommendation system to ignore.

    Maintain a claim-to-evidence ledger

    For every claim that could change a purchase decision, keep an internal ledger containing the claim, its exact qualifier, the supporting evidence, the page where that evidence is visible, the responsible owner, and the event that should trigger a review.

    The qualifier matters. A certification may apply to one variant, a test may use specific conditions, and a warranty may differ by market. Preserve that scope everywhere the claim appears. Do not turn narrow evidence into a product-wide promise.

    Customer reviews can help describe recurring strengths and limitations, but keep review data attached to the product or variant it evaluates. Combining materially different variants may produce a stronger aggregate while giving the assistant a less accurate picture of the item in front of the shopper.

    Support pages, manuals, compatibility resources, return policies, and comparison pages should link back to the canonical product and use the same names and identifiers. That creates a coherent evidence trail instead of a set of disconnected documents with slightly different terminology.

    Audit the complete path from prompt to recommendation

    A shopper request travels through product, evidence, inventory, checkout, and delivery checkpoints before reaching an unbranded product shortlist.

    Do not reduce AI shopping visibility to a rank check. You need to see where the product exits the decision process and whether the answer is factually correct when it does appear.

    1. Choose eligible prompts. Test requests for which the product could honestly be a suitable answer. Irrelevant prompts distort the score and tempt teams to broaden claims beyond the product’s real fit.
    2. Record a baseline. Save the exact prompt, assistant, date, market or locale, response, recommended products, stated reasons, and any surfaced links.
    3. Label the outcome. Distinguish absence, failed qualification, incorrect description, unsupported mention, and an eligible product that lost on a documented trade-off.
    4. Trace the earliest failed gate. Repair identity and discovery before attributes, attributes before evidence, and evidence before promotional expansion.
    5. Rerun the same prompt set. Compare changes in coverage and accuracy while recognizing that any individual generated response can vary.
    6. Inspect the commercial handoff. If the recommendation is accurate but the shopper does not proceed, examine the offer, availability, landing experience, and product-market fit rather than calling every weak outcome an AI visibility problem.

    The failure pattern tells you where to look first:

    Observed resultLikely failure areaFirst inspection
    The product never appearsDiscoveryIndexability, canonical URL, feed inclusion, product identity, and internal linking
    The wrong variant appearsIdentityVariant names, identifiers, URLs, parent relationships, and selected-offer data
    The product disappears after a valid constraint is addedQualificationThe missing, ambiguous, or conflicting attribute associated with that constraint
    The assistant states an incorrect factProduct truthConflicts and stale values across the page, schema, feed, marketplace, and support content
    The product is considered but not recommendedSelectionUse-case specificity, comparison criteria, limitations, and claim-level evidence
    The recommendation is accurate but does not convertCommercial handoffPrice, availability, trust, offer clarity, landing experience, and actual product fit

    Track metrics that correspond to those states. Prompt coverage shows whether the product appears for eligible requests. Attribute resolution shows whether the assistant can answer the important constraint questions. Answer accuracy catches misdescription. Evidence visibility shows whether useful supporting pages are surfaced. Recommendation share shows how often the product is selected when it is genuinely eligible. Commercial outcomes tell you whether improved visibility creates useful demand.

    Keep the prompt set and eligibility rules stable while evaluating a change. If you change the content, prompts, markets, and success definition at the same time, you will not know what improved. Treat assistant outputs as observations, not permanent rankings.

    Key takeaways

    • Optimize for discovery, qualification, and selection as separate gates.
    • Create one canonical product record before expanding copy, schema, feeds, or comparison content.
    • Make decisive constraints explicit; do not ask an assistant to infer compatibility, fit, or eligibility from vague prose.
    • Keep visible content, Product structured data, offers, variants, and merchant feeds consistent.
    • Attach meaningful claims to scoped evidence and state important limitations plainly.
    • Measure eligible prompt coverage and factual accuracy before treating recommendation share as the main result.

    Start with one commercially important product family. Establish its canonical facts, build prompts around real purchase constraints, and fix the earliest gate that fails. Once that path is reliable, extend the same operating model to the rest of the catalog. That gives you a repeatable visibility system instead of a collection of schema additions and copy changes whose effect you cannot explain.

    References


  • Google AI Shopping: Prepare for Search-to-Checkout

    Google AI Shopping: Prepare for Search-to-Checkout

    If you run a Shopify store, a customer may soon discover your product and buy it without visiting your website. Eligible products can now move from recommendation to direct checkout inside Google AI Mode and the Gemini app.

    That changes more than the checkout button. You need to decide where the transaction should happen, make your product data reliable enough for an AI-assisted purchase, and measure sales that browser analytics may not fully capture. The right response is an operational audit, not an indiscriminate AI content campaign.

    Key takeaways

    • Eligible U.S. Shopify stores may have Google-native checkout activated automatically, so inspect Sales channels > Agentic before assuming you opted in or out.
    • Merchant Center data is becoming part of the transaction interface, not merely a way to qualify for product exposure.
    • Native checkout can shorten the buying path, but certain checkout blocks, bundles, custom pixels, and client-side Google Analytics tracking are not supported.
    • Measure answer presence, visible citations, product visibility, and completed transactions separately. They are related outcomes, not interchangeable versions of one ranking metric.

    Search visibility now has separate discovery and commerce layers

    AI-generated search results are no longer a fringe surface. Google AI Overviews appeared in 39.4% of U.S. desktop searches in June 2026, up from 25.8% in July 2025. That measurement describes how often the feature appeared. It does not measure clicks, visits, or sales.

    Search demand has not simply vanished into AI interfaces. U.S. desktop search volume reached 77 billion searches in the second quarter of 2026, 8% above the 71 billion recorded in the second quarter of 2024. The practical change is in what can happen between the query and your website. Google can answer the question, cite a page, present a product, and, for some shoppers and merchants, complete the transaction before a site session begins.

    Do not use the AI Overview figure as a proxy for native-checkout adoption. AI Overviews, AI Mode, and Gemini are distinct experiences, and the available checkout rollout is limited to eligible merchants and shoppers. Combining them into one AI traffic number will hide which part of the journey is actually changing.

    Track four outcomes instead of one AI visibility score

    1. Answer presence: Does the AI response discuss your brand, product, category, or information?
    2. Visible attribution: Does it name or link to your domain, product page, video, marketplace listing, or another asset you control?
    3. Product availability: Does the relevant product surface with accurate information for the shopper?
    4. Transaction availability: Can the shopper buy inside the AI experience, or are they transferred to your store?

    The first two outcomes need to remain separate. A system can use a domain while giving another domain the visible link. In lodging-related AI responses measured from December 2025 through May 2026, Tripadvisor had 61% source presence but only 21% visible citation presence. Hotels.com moved from 50% source presence to 18% citation presence, while Booking.com moved from 33% to 9%. Those numbers come from lodging, not retail, but the measurement lesson applies directly: being used, being named, and receiving a click opportunity are different results.

    Build your monitoring sheet around those distinctions. For every important query, record the date, device type, Google surface, whether your brand appeared, whether a link appeared, which URL received the link, whether a product was shown, and whether checkout was available. Use the same query set on a fixed cadence. AI responses can vary, so one screenshot should be treated as an observation rather than a permanent ranking.

    Keep traditional ranking and organic traffic beside this view, not inside it. A page can rank conventionally without appearing in an AI answer. It can inform an answer without receiving a citation. A product can also generate an order without producing the client-side visit your existing dashboard expects.

    Decide whether native checkout fits your store before leaving it enabled

    The first task is to establish your actual state. Shopify stores may be eligible when they are based in the United States, sell to U.S. customers, have a valid Merchant Center account, and make eligible products available through Merchant Center, among other requirements. Products can be synchronized through Shopify’s Google & YouTube channel or supplied through another feed method.

    For a matched store and Merchant Center account, eligible products may be included automatically. Shopify also activates purchasing by default for eligible stores. The rollout remains selective, however, so an eligible merchant should not assume that every shopper can see the same experience.

    1. Open Shopify and inspect Sales channels > Agentic.
    2. Record whether direct checkout is enabled before changing anything. Add the date to your analytics annotations or internal change log.
    3. Confirm which Merchant Center account is matched to the store and how products reach that account.
    4. Identify the products that are intended to be available through Merchant Center. Check whether their price, availability, variants, images, and descriptions match the live store.
    5. List every onsite feature involved in conversion or measurement, especially bundles, checkout blocks, custom pixels, and client-side Google Analytics tracking.
    6. Choose deliberately between native checkout and website checkout. If you disable direct checkout, products can still be discovered in AI Mode and Gemini, but shoppers will be sent to your site to purchase.

    The choice is not simply more distribution versus less distribution. It is a tradeoff between reducing steps and preserving the parts of your onsite experience that help the customer choose, configure, or understand the product.

    Decision questionLean toward native checkoutLean toward website checkout
    Can the customer understand and select the product from the information available in the AI experience?The product and its variants are straightforward.The purchase needs detailed education, configuration, or onsite assistance.
    Does the current offer depend on unsupported checkout behavior?Standard product and checkout behavior is sufficient.Bundles or specific checkout blocks are central to the offer.
    Can you evaluate performance from order and platform records?Order-level reconciliation gives you enough evidence to make a decision.Essential attribution or optimization depends on unsupported custom pixels or browser events.
    What is the primary experience goal?Removing steps between product discovery and purchase matters most.Preserving a controlled, branded onsite journey matters most.

    Native checkout does not remove the merchant from the commercial relationship. Merchants retain the underlying customer and order relationship. But that does not mean the Google-hosted experience reproduces the store’s checkout. Certain checkout blocks, product bundles, custom pixels, and client-side Google Analytics tracking are not supported.

    If one of those features affects pricing, fulfillment, compliance, or the customer’s understanding of the order, resolve that dependency before leaving native checkout enabled. If it only affects reporting, determine whether order-level reconciliation can replace the missing browser signal. Do not reject a sales channel solely because it produces fewer sessions, and do not keep it solely because it produces more orders without checking cancellations, refunds, and operational quality.

    Treat Merchant Center data as transaction infrastructure

    Structured product-data tiles for inventory, pricing, shipping, returns, and payment connect an AI interface to checkout and fulfillment.

    Merchant Center used to be easy to treat as a distribution feed sitting beside the store. That mental model is now incomplete. Eligible products supplied through Merchant Center can support discovery and direct purchase, which means a catalog error can travel farther down the buying journey before anyone notices it.

    The transaction layer is powered by the Universal Commerce Protocol, or UCP. It is an open standard developed by Google with companies including Shopify so AI agents can interact with merchants and payment systems across the shopping journey. UCP is the connection layer; it does not make incomplete, stale, or ambiguous product information reliable.

    Audit the product facts an agent must act on

    • Identity: Make titles, brand information, item identifiers, and variant identifiers stable enough to distinguish one product from another.
    • Choice: Represent differences such as size, color, quantity, and compatibility clearly. Do not bury a purchase-critical distinction in promotional copy.
    • Offer: Keep price, availability, and condition aligned with what the customer can actually buy.
    • Media: Make sure the primary image represents the selected product or variant rather than a broader collection.
    • Description: Put the facts needed to make a decision near the start. A product description should identify what the item is, who or what it is for, and the distinctions that change the choice.
    • Consistency: Align Merchant Center data, the rendered product page, and any Product structured data on the site. JSON-LD can clarify the page, but it is not a substitute for the Merchant Center feed used in this checkout rollout.

    Work from the sale backward. Ask what would cause the wrong variant, stale availability, misleading image, or incorrect price to appear at the point of purchase. Those are higher-priority defects than minor differences in promotional wording because they affect whether the transaction can be completed accurately.

    Do not add more feed detail than your team can maintain. A complete field that becomes stale is not better than a concise field tied to a reliable system of record. Assign ownership for each changing fact and document whether Shopify, another catalog system, or a feed tool controls it.

    Replace browser-only attribution with commerce reconciliation

    Client-side analytics cannot be your only conversion record when checkout may occur outside your pages. A lower session count can coexist with valid orders, while a missing browser event can look like a failed conversion even when payment completed.

    Create a compact operating view with five layers:

    1. Configuration: The Agentic setting, Merchant Center account, feed method, and dates when any of them changed.
    2. Catalog: The products intended for AI discovery, their current feed status, and material errors or exclusions.
    3. Visibility: Observations from your fixed query set, separated into answer presence, citation presence, product appearance, and checkout availability.
    4. Transactions: Orders and sales attributed to the experience when Shopify or another available record identifies them. Keep onsite orders separate.
    5. Order quality: Cancellations, refunds, fulfillment problems, and product-selection errors. These show whether a shorter checkout path is producing usable revenue.

    Annotate promotions, stockouts, price changes, feed repairs, and setting changes. A simple before-and-after comparison cannot prove that native checkout caused a sales change when inventory, demand, and rollout availability also moved. Treat it as directional evidence unless you have a controlled comparison with stable conditions.

    If direct checkout is enabled but the available records cannot distinguish its orders, document that limitation instead of filling the gap with estimated attribution. The immediate objective is to make the unknown visible. That prevents a dashboard built around website sessions from silently declaring offsite transactions nonexistent.

    Build citation opportunities around how people research products

    Shoppers compare unbranded products using visual evidence cards connected to an abstract AI search assistant.

    Your product feed supports commerce eligibility, but it is not the whole discovery strategy. In June retail searches, YouTube appeared in 23% of searches among the top listed AI Overview citations. Amazon appeared in 14%, Reddit in 12%, and Wikipedia in 11%.

    Those percentages are not traffic share, sales share, or proof that publishing on a particular platform causes an AI citation. They show that retail answers draw visible support from several kinds of destinations: video, marketplaces, communities, reference material, and merchant sites. Your visibility plan should therefore cover the questions people ask before they are ready to transact.

    1. Map real buying questions. Include category questions, comparisons, compatibility concerns, variant selection, use cases, and the policy questions that can stop a purchase.
    2. Assign one dependable destination to each answer. Use a product page for product facts, a comparison or support page for decision criteria, and a video when the customer needs to see setup, scale, movement, or results.
    3. Keep claims consistent across surfaces. Conflicting specifications, product names, availability, or positioning create ambiguity for shoppers and machines. Correct the canonical store information first, then update other profiles and listings you control.
    4. Use YouTube when demonstration adds evidence. Give the video a descriptive title and make the spoken and written explanation specific enough to stand on its own. Do not create video merely because YouTube appears frequently in citations.
    5. Treat Reddit as a listening environment, not a placement inventory. Use recurring community questions to improve your pages and documentation. Do not manufacture endorsements or disguise promotional participation as customer experience.
    6. Review marketplace information where it already matters to your business. If your products are legitimately sold on Amazon, make names, variants, and core facts consistent. The citation data alone is not a reason to open a marketplace channel.

    When reviewing a query, ask whether the AI answer contains the right fact, whether your brand is represented accurately, and whether the visible citation leads to the best page. A citation to an obsolete support page is not automatically a win. Neither is an uncited brand mention that describes the wrong product.

    Your first move should be small and observable. Check Sales channels > Agentic, capture the current state, confirm the matched Merchant Center account, and list the checkout or analytics features that would not carry into native checkout. Then choose whether to keep direct purchasing enabled and begin a recurring product-data and query review. That sequence gives you a controlled decision now while preserving room to adapt as Google expands the experience.

    References


  • Agentic Ecommerce: A Playbook for Discovery and Advertising

    Agentic Ecommerce: A Playbook for Discovery and Advertising

    If your product pages rank and your ads are live, but your products still disappear from AI-guided shopping conversations, the missing layer is usually not more promotional copy. It is decision-ready product data: facts an agent can retrieve, compare, explain, and carry into checkout.

    Your goal is no longer just to win a click. You need to help an AI determine whether a specific product fits a specific buyer’s constraints, answer the next question accurately, and make the handoff to your store without changing the facts along the way.

    The shopping funnel now contains a conversation

    A conventional product ad asks the shopper to click before learning much. A conversational ad can answer questions about fit, compatibility, features, availability, or policies inside the discovery surface. ChatGPT is testing clearly labeled Sponsored Agents that open a separate brand conversation, while Google’s Business Agent is being tested inside YouTube ads for eligible U.S. retailers.

    That changes the intermediate step, not the buyer’s underlying job. People still need to eliminate unsuitable choices, understand tradeoffs, and trust the terms of the purchase. The difference is that an agent may now perform part of that evaluation before the shopper reaches your product page.

    Do not collapse every appearance in AI into one visibility metric. There are three distinct outcomes:

    • Citation: your content supplies an explanation or fact used in an answer.
    • Recommendation: your brand enters the suggested set for a category or use case.
    • Selection: a particular product is matched to the shopper’s stated requirements and advanced toward purchase.

    Each outcome requires different work. Clear, retrievable content helps with citation. Consistent brand context supports recommendation. Complete product attributes, current commercial data, and a usable transaction path support selection. This is why LLM readability, brand context, and agentic commerce are separate optimization disciplines, even when one team owns all three.

    Do not fund this shift by abandoning traditional search. An Ahrefs-based measurement found AI Overviews on 24% of shopping queries on Sept. 3, 2026, but a Datos panel of more than 10 million desktop users measured dedicated AI Mode at only about 0.13% of web traffic. A separate panel of 75 ecommerce stores, mostly producing $1 million to $20 million in annual revenue, still placed non-branded organic search second only to paid search for revenue. The practical response is a parallel search and AI strategy, not a wholesale channel migration.

    Build a product record an agent can safely choose

    An unbranded hiking shoe is surrounded by organized visual layers representing its materials, size, fit, availability, shipping, and return details.

    An agent cannot reliably recommend what it cannot distinguish. A polished category description will not compensate for missing variant measurements, ambiguous compatibility, stale availability, or different prices in the feed and on the page.

    For every product and variant you want an agent to select, create one canonical record with five layers:

    • Identity: product name, brand, category, model, SKU or other applicable identifiers, plus the exact relationship between parent products and variants.
    • Transaction truth: price, currency, condition, availability, fulfillment choices, shipping terms, returns, warranty, and any eligibility rules for discounts or member pricing.
    • Decision attributes: dimensions, materials, fit, capacity, supported devices or systems, care requirements, included components, and other facts buyers use to rule products in or out.
    • Evidence and instructions: manuals, size charts, compatibility tables, policy pages, certifications when applicable, and factual answers to recurring pre-purchase questions.
    • Destinations: the correct product page, variant URL, cart action, policy page, or support handoff for each answer.

    Publish the same facts through the channels machines use: visible page content, merchant feeds, platform catalog integrations, and Product and Offer structured data where applicable. JSON-LD should be generated from the same commerce data as the page and feed. Treating schema as a separate copywriting exercise creates exactly the contradictions an agent should not have to resolve.

    Run a variant-level consistency check before activating an agent or campaign. Compare title, identifier, price, currency, availability, shipping, return terms, and the primary decision attributes across the page, feed, structured data, and commerce API. If a field is genuinely unknown, leave it unknown and define a safe fallback. Do not let the agent infer compatibility, delivery, or warranty coverage from adjacent products.

    Product copy still matters, but it should answer rather than decorate. Put the direct answer first, then the explanation, supporting evidence, and relevant conditions. Keep each FAQ block focused on one buyer question so it can be retrieved without unrelated text changing its meaning.

    The commercial case for this cleanup is promising but should not be overstated. Google reports that merchants following its core Merchant Center feed practices see an average 5% conversion increase in the following month. In a Lululemon test, retailer-supplied conversational attributes were incorporated in 50% of relevant AI Mode product recommendations. These are platform-reported results, not guaranteed lifts. Their useful lesson is narrower: attributes that exist as maintained data can participate in recommendations; facts trapped in campaign copy cannot be depended on in the same way.

    Design conversational ads around the next unanswered question

    A shopper and an abstract AI guide exchange symbol-filled bubbles while narrowing several coffee machines to one suitable choice.

    A conversational ad should not be a chat-shaped version of a display ad. Its job is to resolve the next material uncertainty and route the shopper to the correct action. Build an answer map before you generate creative.

    Buyer questionRequired dataSafe handoff
    Will this fit?Variant measurements, sizing method, and size-chart rulesThe selected variant and relevant size guide
    Will it work with what I own?Supported models, exclusions, required accessories, and version limitsThe compatible variant or compatibility table
    What will I actually pay?Current price, currency, shipping terms, and applicable member benefitsA cart with the same disclosed terms
    Can I get it when and where I need it?Live inventory and available fulfillment methodsThe available purchase or pickup path
    What if it is unsuitable?Return window, condition requirements, exclusions, and warranty termsThe relevant policy section or support route

    For each row, define an answer contract: the approved system of record, the claims the agent may make, the data that must be checked live, the fallback when data is unavailable, and the destination that preserves context. A useful fallback is specific: state which fact cannot be confirmed and direct the shopper to the place or person that can confirm it. A confident guess is not customer service.

    AI can also compress campaign production. ChatGPT Work’s Ads Manager plugin can create, update, and analyze campaigns from natural-language instructions; its assistance can propose copy and imagery from a landing page and campaign objective. Optional text customization can adapt headlines and descriptions to the conversation or translate them into the user’s preferred language. U.S. Shopify merchants can also use a ChatGPT Ads app to manage campaigns, while Shopify Catalog data supports more accurate product appearances in shopping conversations. These workflow and catalog integrations reduce interface work, but they do not remove the need for review.

    • Review generated copy against the canonical product record, not just the landing page’s marketing language.
    • Validate translated claims, units, policies, and variant names before enabling localized customization.
    • Require a live lookup for price, stock, delivery, and personalized benefits when those values can change.
    • Send every answer to a landing state that preserves the chosen product or variant. Do not make the shopper repeat the conversation.
    • Log unsupported questions and corrected answers as product-data defects, then fix the underlying record.

    Keep paid and independent answers conceptually separate. OpenAI says Sponsored Agent conversations are labeled and separated from the original ChatGPT conversation, advertising does not influence ChatGPT’s independent answers, and advertisers do not receive users’ private conversations. Plan your measurement around the signals the platform legitimately exposes; do not design a campaign that assumes access to private prompt history.

    Measure the path from question to profitable order

    Click-through rate cannot describe the whole experience when a conversation performs part of the product-page job. It may produce fewer but better-qualified visits, expose missing information, or assist a purchase completed through another surface. Build a measurement chain that distinguishes those outcomes.

    • Visibility: eligible ad exposure, AI share of voice, recommendation coverage across a fixed set of target shopping prompts, and the products most often surfaced.
    • Conversation: conversation starts, qualified question rate, common question categories, answer failure rate, and the share of conversations that reach a site handoff.
    • Selection: variant views, product comparisons, cart additions, and checkout starts originating from the agent experience.
    • Transaction: completed orders, revenue, margin where available, assisted conversions, and member-benefit usage.
    • Outcome quality: cancellations, returns, exchanges, and support contacts attached to agent-assisted orders.

    Define the denominators before launch. Conversation start rate is starts divided by eligible ad exposures when the platform supplies both values. Qualified question rate is conversations containing a decision question divided by starts. Answer failure rate is unsupported, corrected, or escalated answers divided by starts. If a platform withholds a denominator, mark the rate unavailable instead of combining unrelated proxies.

    Use distinct campaign identifiers and landing URLs for each agent surface, preserve product and variant context in the handoff, and record launch dates in your analytics annotations. Compare performance with a suitable unactivated product, market, or campaign group where possible. Keep budget, promotion, inventory, and seasonal differences visible so a lift is not automatically credited to the agent.

    Google’s AI performance insights in Merchant Center are generally available in Australia, Canada, India, New Zealand, and the U.S., including comparisons of brand share of voice across AI Mode and AI Overviews. Its Universal Commerce Protocol integration can also support cart transfers to merchant sites and expanded checkout testing. Loyalty data can surface member-specific pricing and benefits. These discovery, checkout, and personalization capabilities make segmentation essential: report new and returning customers, members and non-members, and agent-assisted and conventional journeys separately.

    Key takeaways: use this launch sequence

    • Choose one decision-heavy category. Start where buyers repeatedly ask about fit, compatibility, delivery, or policy terms, because those questions reveal whether the agent adds real value.
    • Separate your goals. Decide whether each activity is intended to earn a citation, a brand recommendation, a product selection, or a paid conversation.
    • Repair the product record first. Align variant identity, decision attributes, price, inventory, policies, page content, feed data, and JSON-LD before generating campaigns.
    • Create the answer map. Pair each common buyer question with an approved data field, a safe fallback, and a destination that preserves the selected product.
    • Apply campaign guardrails. Human-review generated claims and translations, require live checks for changing commercial facts, and prohibit unsupported inference.
    • Instrument the whole path. Track visibility, dialogue, selection, checkout, and post-purchase quality rather than using clicks as the sole success signal.
    • Feed failures back into operations. Repeated unanswered questions belong in the catalog backlog; frequent returns after an agent interaction may indicate that an answer or attribute is misleading.

    Start with the category where a wrong answer would most often block or spoil a purchase. Make that category reliably answerable across organic discovery, conversational ads, and checkout. Scale only after the same facts survive every handoff.

    References


  • Amazon Alexa Listing Optimization: A Practical Framework

    Amazon Alexa Listing Optimization: A Practical Framework

    Your Amazon listing can be easy for a person to read and still be difficult for a shopping assistant to use. A shopper may describe a device, material constraint, room, task, recipient, or problem without using your primary keyword. If the deciding fact is missing, buried, or contradicted elsewhere, your listing gives Alexa weak evidence for a confident match.

    Alexa optimization starts with answerability. Your job is to turn verified product facts into clear, structured, consistent answers, then test whether those answers improve discovery without attracting shoppers the product cannot satisfy.

    Optimize the buying decision, not an imagined Alexa formula

    The platform context has changed: Alexa for Shopping has replaced Rufus as Amazon’s default AI assistant. That makes conversational product discovery an important optimization surface. It does not make an unverified ranking-factor checklist reliable.

    The Amazon catalog record is the asset you control. Improve it around the sequence a shopper follows when narrowing a purchase:

    • Relevance: Is this the right type of product for the need expressed in the request?
    • Qualification: Does it meet the shopper’s compatibility, size, material, care, capacity, or use-case constraints?
    • Choice: What verified difference gives the shopper a reason to choose it over another eligible option?

    This distinction matters because broad visibility is not automatically useful visibility. Vague claims may make a product sound suitable for more situations, but they also increase the risk of a poor match. Optimize to become the right answer to a defined need, not merely an answer that can be mentioned.

    Keywords still help label the product. They are not the whole task. A phrase such as portable fan identifies a category, while a request such as a fan that fits on a narrow desk and runs from a particular power source introduces conditions. Your listing needs accurate facts that resolve those conditions. Repeating the category phrase cannot do that work.

    Build a query-to-attribute map for one ASIN

    A central air purifier is connected by colored paths to visual scenes representing room, pet, filtration, size, office, and quiet-use needs.

    Start with one Amazon Standard Identification Number rather than rewriting an entire catalog. Gather recurring language from customer questions, service tickets, reviews, return reasons, and search-term records you already use. Do not copy customer claims into the listing. Use the language to identify decisions that the current listing may leave unresolved.

    Turn each important question into a row in a query-to-attribute map. The map connects what a shopper asks to the exact product fact that should answer it.

    IntentTypical shopper questionEvidence the listing needsCommon failure
    CompatibilityDoes it work with a particular model or system?Exact supported identifiers, required conditions, and known exclusionsBroad compatible wording with no model boundary
    Use caseCan I use it for a particular task or environment?An explicit supported use and any relevant limitationA feature is named, but its practical use is left for the shopper to infer
    Dimensions or capacityWill it fit or hold what I need?Exact measurement, unit, and variant-specific valueThe value appears only in an image or differs between fields
    Material or careWhat is it made from, and how is it maintained?Precise materials and care instructions for the affected componentsAn umbrella term hides component-level differences
    Included itemsWhat arrives in the package?A clear distinction between included, optional, and merely compatible itemsAccessories shown or mentioned appear to be included
    Audience or constraintIs it suitable for a particular user or requirement?Verified suitability criteria and an honest boundarySuitability is inferred from marketing language rather than supported by a product fact

    Prioritize questions whose answers can change the purchase or prevent the wrong purchase. A color preference may matter, but an incompatible connector, incorrect dimension, missing accessory, or unsupported environment can make the product unusable. Those decisive facts deserve the clearest fields and the most visible copy.

    For each row, write one canonical answer before editing Amazon. A compatibility answer might follow this pattern: [product and variant] is compatible with [verified models] when [required condition]. It does not support or include [important boundary]. The placeholders force you to separate an actual product fact from a phrase that merely sounds persuasive.

    You do not need to insert every possible spoken variation into the visible listing. Establish the fact in plain language, then add natural synonyms only where they remove a genuine vocabulary gap. Repetition without new meaning makes the copy harder to scan and does nothing to resolve an unanswered constraint.

    Put each product fact in the field best suited to it

    A strong Alexa-oriented listing is not one long block of optimized prose. It is a coordinated catalog record. Structured attributes hold precise values. The title establishes identity. Bullets resolve major decisions. Longer content supplies context. Search-term fields cover relevant language that would be awkward in visible copy.

    Complete structured attributes before polishing prose

    Fill every applicable product-detail field with the verified value for that exact variant. Depending on the product, this may include product type, material, dimensions, capacity, color, model, power requirements, care instructions, compatibility, or included components.

    Do not force a value into an attribute that does not apply, and do not guess when product documentation is unclear. An incomplete record can be corrected after the fact is verified. An invented value can mislead the shopper, increase returns, and create a conflict that spreads across the listing.

    Keep the title focused on product identity

    The title should let a shopper identify the item and its defining variant without decoding a chain of claims. Include the product type and the details required to distinguish the purchasable item. Do not turn the title into a compressed FAQ or repeat near-identical phrases in the hope of covering more requests.

    If a term changes what the product is, it may belong in the title. If it explains when, why, or how the product is useful, it usually belongs in a bullet, attribute, or longer description. That division keeps identity separate from persuasion.

    Give every bullet a decision to resolve

    Assign each bullet to a high-priority row from the query-to-attribute map. A useful construction is: verified property, practical consequence, then boundary. For example: [component] measures [verified dimension], which allows [supported use]; it does not fit [known exclusion].

    The boundary is often the most useful part. Words such as premium, versatile, convenient, and advanced leave the assistant and the shopper to infer meaning. A measurement, named material, supported model, care requirement, or package-content statement answers a question.

    Use longer content for context and distinctions

    Use the description and any available enhanced content to explain scenarios that need more than a compact bullet. Show how related features work together, distinguish similar variants, and clarify setup or care where that affects suitability. Keep purchase-blocking facts in attributes or bullets as well; do not hide an exclusion deep in promotional copy.

    Where Seller Central provides non-visible search-term fields, use them for accurate synonyms and alternative language omitted from the visible copy. These fields can broaden vocabulary coverage, but they cannot repair a missing specification or make an unsupported claim true.

    Make every variant tell the same product truth

    Three color variants of the same air purifier display identical features and matching icon-based product information.

    An assistant-ready listing needs internal agreement. When the title, attributes, bullets, images, and variant labels disagree, no amount of elegant wording tells a dependable story. Resolve the underlying value before deciding which phrase sounds best.

    Run a field-by-field consistency audit:

    • Confirm that measurements, units, materials, model names, and package quantities agree wherever they appear.
    • Check each purchasable variant independently. A size, capacity, color, accessory, or capability belonging to one child item must not appear to apply to every child item.
    • Separate included items from products that are merely compatible, optional, or shown for context.
    • Qualify compatibility and suitability claims with the conditions that make them true.
    • Make sure synonyms preserve the same meaning. Related terms are not interchangeable when they describe different materials, product types, or technical standards.
    • Compare text embedded in images with the current catalog values. Old creative can preserve a contradiction after the written listing has been corrected.

    The parent-child relationship deserves special attention. Shared copy is efficient, but it can quietly transfer a fact from one variant to another. Treat each purchasable option as its own truth set, then share only claims that are genuinely common to the family.

    Keep a simple claim ledger outside Amazon. For each important claim, record the canonical value, the variants it covers, the evidence that supports it, and every field where it appears. When product specifications or packaging change, the ledger shows what must be updated. It also prevents one team from correcting a bullet while another republishes an outdated image or description.

    Do not use Alexa optimization as a reason to stretch a claim beyond your product documentation. The likely downside is not limited to an inaccurate answer. It can include unqualified traffic, avoidable returns, support costs, and disappointed customers. The safe alternative is to state the verified boundary clearly and optimize for shoppers whose requirements the product actually meets.

    Test assistant visibility without confusing observation with proof

    You cannot safely infer a secret ranking weight from one response. Assistant output can vary, and competing listings can change independently of your edits. Use a controlled observation process to determine whether a clearer catalog record produces a repeatable, useful direction.

    1. Create a fixed prompt set. Cover category discovery, a supported use case, a decisive constraint, compatibility, and an exclusion. Include unbranded requests so you are testing discovery rather than simple brand recall.
    2. Record a baseline. Save the exact prompt wording, marketplace, relevant account or device context, listing version, and what happened. Note whether the product appeared and whether important facts were described accurately.
    3. Change one fact cluster. Correct a related group such as compatibility, dimensions, materials, or package contents. Avoid rewriting every field at once, because a broad rewrite makes the cause of any change impossible to interpret.
    4. Wait until the listing edit is live, then repeat the same prompts. Keep the wording and testing context stable. Repeat observations rather than treating one appearance or disappearance as a verdict.
    5. Check commercial quality as well as visibility. Use the business metrics you already trust to see whether the change attracts qualified shoppers. More exposure accompanied by weaker conversion, more confusion, or more returns can indicate that the listing became broader without becoming more accurate.

    Label failures by type. A product may not be surfaced, may be surfaced for the wrong need, may appear with a deciding attribute omitted, or may be described with an incorrect value. Those failures require different responses. Missing visibility may justify broader relevant language. An omitted fact may point to poor placement. A wrong fact should trigger a consistency check before you add more copy.

    If your listing is consistent but Alexa still states a fact incorrectly, log the observation and keep the catalog truth intact. Distorting the listing to imitate an erroneous answer creates a second problem instead of solving the first.

    Judge the edit across the whole prompt group. A useful change improves matching for supported needs, preserves important exclusions, and does not degrade shopper quality. That is stronger evidence than an isolated change in apparent placement.

    Key takeaways for Amazon Alexa listing optimization

    • Optimize the relationship between a shopper’s question and a verified product fact, not keyword repetition alone.
    • Prioritize compatibility, dimensions, included items, and other constraints that can determine whether a purchase succeeds.
    • Correct structured attributes and variant data before polishing persuasive copy.
    • Use titles for identity, bullets for major decisions, longer content for context, and search-term fields for accurate vocabulary coverage.
    • Resolve contradictions across fields and creative assets before adding more language.
    • Test with fixed prompts and downstream business signals, treating repeated observations as directional evidence rather than proof of a ranking formula.

    Your next move is narrow and practical: choose one representative ASIN, map its most decisive shopper questions to verified attributes, and fix the highest-risk ambiguity. Save the baseline, rerun the same prompt set after the changes are live, and scale only the patterns that improve both answer quality and shopper fit.

    References


  • Google AI Search Ads: How to Read the Performance Shift

    Google AI Search Ads: How to Read the Performance Shift

    If your Shopping click-through rate is climbing while clicks barely move, do not label the campaign healthier yet. That combination can appear when the impression pool contracts faster than click volume. The rate improves, but the business receives little or no additional traffic.

    At the same time, Google is testing a new route into AI Mode for tightly controlled Search campaigns. You therefore have two changes to manage: AI-generated experiences may be reshaping the inventory available to Shopping ads, while some exact and phrase match campaigns may gain access to a new search surface. The practical response is to separate reach, efficiency, intent and business outcomes before changing bids or budgets.

    Google is routing intent into different search experiences

    Google’s AI search shift is not simply another placement added to the same auction. The results experience can vary by query. A person may receive an AI Overview, conventional search results with ads, a Shopping-led result or an AI Mode response. Your campaign cannot earn an impression when Google chooses an experience that does not offer that particular ad opportunity.

    A notable pattern has appeared across thousands of Shopping and Performance Max campaigns spanning hundreds of advertiser accounts: impressions often declined more clearly than clicks, leaving clicks relatively flat or slightly lower and pushing CTR upward.

    One possible mechanism is selective routing. Google may be more likely to show an AI Overview for a query with relatively low predicted ad-click propensity, while preserving Shopping placements for searches more likely to generate a commercial click. Anecdotal observations have also found Shopping ads and AI Overviews uncommon on the same results page.

    That explanation is a hypothesis, not a demonstrated cause. The timing could be coincidental, AI Overviews could be contributing through a different mechanism, or another change could be reducing impressions. Treat the account pattern as observed and the AI Overview explanation as unconfirmed.

    Search contextWhat is supportedHow you should interpret it
    Shopping inventory alongside the growth of AI OverviewsSome large campaign datasets show impressions falling more than clicks while CTR rises. The causal role of AI Overviews remains unproven.Report the loss of reach alongside the higher rate. Do not call CTR growth an optimization win by itself.
    AI Mode with explicit, direct intentExact and phrase match keywords can trigger traditional text ads in a small experiment.Existing controlled campaigns may gain reach without an immediate switch to a more automated campaign type.
    AI Mode with complex or conversational intentAI Max and Performance Max remain Google’s products for broader conversational searches and newer formats such as Highlighted Answers.Test automated expansion separately from your controlled keyword campaigns so that you can measure what the additional reach contributes.

    The important distinction is between selection and persuasion. A higher CTR can mean that your ad persuaded a larger share of the same audience. It can also mean that Google removed lower-propensity impressions before your creative entered the picture. Those are different performance stories and demand different decisions.

    The Shopping CTR trap: a stronger rate can hide weaker reach

    A narrowing funnel reduces a field of impression particles while only a few click tokens emerge beside an unlabeled rising gauge.

    CTR is clicks divided by impressions. If impressions decline faster than clicks, CTR rises automatically. Your ad does not need to generate a single additional visit for the rate to look better.

    The size of the observed movement makes this more than a theoretical concern. One ecommerce dataset showed Shopping CTR up 17% year over year, close to a roughly 20% increase in another benchmark. Looking below the rate revealed that clicks were often flat or slightly down while impressions had fallen more substantially.

    Read CTR as one link in a metric chain

    Put these measures beside one another in every Shopping and Performance Max review:

    • Impressions show how much exposure the campaign received. A decline may indicate a smaller available opportunity, a change in eligibility, a different query mix or another delivery constraint.
    • Clicks show the traffic actually delivered. Flat clicks paired with rising CTR usually mean the rate has improved more than the outcome.
    • CTR describes click efficiency within the inventory Google served. It does not measure the size or quality of the inventory that disappeared.
    • Cost shows what you paid to participate. A selective inventory pool can change both traffic volume and auction economics.
    • Conversions, conversion value and profit show whether the campaign created a business result. Use the measure that reflects your actual commercial objective rather than treating a platform rate as the objective.

    A reach-compression pattern looks like this: impressions decline more sharply than clicks, CTR rises and total traffic remains flat or falls. That pattern should trigger an inventory and query-mix investigation, not a bid increase prompted by the CTR improvement.

    A genuine performance improvement is broader. Click volume, qualified conversions or conversion value should move in the desired direction without unacceptable cost or margin deterioration. CTR can support that conclusion, but it cannot establish it alone.

    Use comparable reporting periods and keep promotions, budget changes, product availability and campaign restructuring visible in the same view. Otherwise, an AI-search hypothesis can become a convenient explanation for a change caused inside your own account.

    Exact and phrase match are entering AI Mode with boundaries

    You do not necessarily need to move every Search campaign into AI Max or Performance Max to become eligible for AI Mode. Google has started a small experiment allowing exact and phrase match keywords to serve text ads in AI Mode.

    The restriction matters. Those keywords can participate only when Google’s systems identify explicit and direct user intent. Eligibility is therefore not guaranteed merely because a keyword uses exact or phrase match. Google still decides whether the person’s request maps directly enough to the advertiser’s keyword.

    The experiment also does not put traditional Search campaigns on equal footing with every automated option. AI Max and Performance Max are still positioned for more complex, conversational searches and provide access to newer AI Mode formats, including Highlighted Answers. Traditional campaigns are being tested specifically with text ads attached to clearer intent.

    No broad or permanent rollout has been confirmed. Do not rebuild a functioning account or move material budget solely to chase access to an experiment whose coverage Google has not disclosed. A premature migration can expand spend, change the query mix and destroy the clean baseline you need to judge incrementality.

    Keep controlled intent and automated exploration separate

    1. Preserve a control lane. Keep exact and phrase match campaigns for queries with an obvious commercial request. Think in practical intent classes such as a named product, a specific service, a price request or a purchase-ready action.
    2. Create an exploration lane. Test AI Max or Performance Max separately when you want coverage for longer, less predictable or conversational searches. Give the test its own measurement view and a bounded budget.
    3. Map the landing experience to the intent. A direct query should reach a page that answers the direct request without forcing the visitor through an unrelated explainer. A comparison or discovery query needs enough context to support a decision.
    4. Judge incremental outcomes. Measure whether the exploration lane adds useful clicks, conversions and value to the account. A higher CTR within either lane does not prove that it generated incremental demand.

    This structure lets you benefit if controlled Search inventory expands into AI Mode without surrendering the ability to test Google’s more automated route. It also prevents performance from different intent classes from being blended into one reassuring average.

    Audit the query path before changing bids or budgets

    An analyst traces an illuminated query path through abstract search, AI response, ad placement, and conversion stages while two control knobs remain untouched.

    Your next account review should identify what changed, what you can only infer and what remains unknown. Use this sequence:

    1. Capture a stable baseline. Export impressions, clicks, CTR, cost, conversions and conversion value for comparable periods before changing campaign types, match strategies or budgets.
    2. Separate campaign cohorts. Review standard Shopping, Performance Max and traditional Search independently. Within Search, separate exact and phrase match from broader automated reach. Blended account totals can hide which inventory pool contracted or expanded.
    3. Group search intent. Distinguish explicit commercial requests from exploratory or conversational needs. Google’s AI Mode test uses that distinction as an eligibility boundary, so your analysis should use it too.
    4. Diagnose the denominator. When CTR rises, check whether clicks increased or impressions merely fell faster. If the latter is true, describe the result as more selective delivery until evidence supports a stronger explanation.
    5. Label causal confidence. Mark each conclusion as observed, inferred or confirmed. Impressions down and CTR up is observed. AI Overviews caused the decline is inferred. Do not allow those statements to merge in a dashboard annotation.
    6. Change one lane at a time. Retain the original controlled campaigns while testing automated expansion. Separate budgets and document the change date so that any gain or loss remains attributable.
    7. Report the business consequence. End with traffic, conversions, value and cost. A useful report sentence is: Shopping CTR increased while impressions declined more sharply than clicks; the pattern is consistent with a more selective inventory mix, but it does not establish AI Overviews as the cause.

    Paid search and AI-search optimization should also share the intent map. If repeated results-page checks show that a query cohort receives an AI answer without a Shopping placement, the PPC team cannot bid its way into inventory that was not offered. That cohort becomes a content and AI-visibility question as well as an advertising question. Build pages that answer the exploratory need clearly, define the relevant product or entity precisely and give the user an obvious path into a commercial page.

    Keep that cross-channel conclusion proportionate to the evidence. A handful of manual searches is directional, not proof of universal delivery. Search experiences can vary, so record repeated observations and continue to distinguish your own results-page evidence from a proposed explanation of Google’s system.

    Key takeaways for your next reporting cycle

    • A rising Shopping CTR may be a denominator effect caused by impressions falling faster than clicks.
    • Cross-account data supports the impression-and-click pattern, but the claim that AI Overviews caused it remains a hypothesis.
    • Exact and phrase match Search campaigns can enter AI Mode in a small experiment when Google detects explicit, direct intent.
    • AI Max and Performance Max remain the routes positioned for more complex conversational searches and newer AI-native formats.
    • Keep controlled intent and automated exploration in separate campaign and measurement lanes.
    • Report impressions, clicks, cost and business outcomes with CTR so that shrinking reach cannot masquerade as improved performance.

    For your next report, add one line beneath every CTR change: what happened to impressions, clicks and conversion value at the same time. Then classify the explanation as observed, inferred or confirmed. That small discipline will keep your decisions sound while Google’s AI search inventory continues to change.

    References