Your JSON-LD validates, yet your brand still goes missing when people ask AI systems for recommendations, comparisons, or eligibility advice. The problem may not be syntax. Valid markup can sit on top of vague, incomplete, or contradictory facts.
The useful goal is not to publish the largest possible schema graph. It is to make the facts that drive a customer’s decision explicit, consistent, verifiable, and connected. The process below gives you a practical way to find those entity gaps, decide which ones matter, and fix the page and its markup together.
Define the entity model before touching your JSON-LD
Schema is a translation layer, not a fact factory. It can express that an organization offers a service, that a program has a duration, or that an event starts on a particular date. It cannot resolve a policy your organization has not settled or turn vague marketing language into a reliable claim.
Start by asking what an answer engine would need to know to describe your offer without guessing. For most commercial or institutional pages, that includes:
- What is the offer, and what is its canonical name?
- Which organization provides it?
- Who is it for, and what eligibility rules apply?
- What does it cost, how long does it take, and how is it delivered?
- What outcomes can you substantiate?
- Which related people, locations, credentials, products, or services help distinguish it?
Turn those questions into a target entity model. This can begin as a spreadsheet rather than code. Give each row a subject, a claim or relationship, an approved value, a primary page, an internal owner, a public evidence location, and the schema type or property that could represent it.
For example, a degree program is an entity. Its provider, delivery mode, duration, credit total, language, admissions threshold, tuition, start dates, curriculum, and outcomes are properties or related entities. A software product would have a different model, but the reasoning is the same: identify the facts a buyer uses to recognize, compare, and choose it.
Classify every target fact using four states:
- Legible: The fact is specific, visible on the appropriate page, and represented consistently in structured data.
- Ambiguous: Something is stated, but its meaning is too loose to support a dependable answer. Phrases such as competitive pricing, flexible study, or a good academic record fall into this category unless the page defines them.
- Unverifiable: The claim appears in content or markup, but you cannot connect it to an approved policy, responsible owner, or supporting evidence. Unverifiable does not automatically mean false; it means you are not ready to publish it as a firm fact.
- Missing: The fact belongs in the target model but is absent from the primary page, supporting content, or structured data.
This distinction prevents a common audit failure. A missing fact needs content or data. An ambiguous fact needs precision. An unverifiable fact needs organizational resolution. Those are three different jobs, and adding more JSON-LD solves only one of them.
Prioritize the entities that affect a real decision and belong on a high-value page. A clear eligibility rule on a core service page usually deserves attention before a minor biographical detail on an ancillary page. Also favor facts your organization can approve and maintain. A theoretically valuable property is not a useful priority if nobody can establish its current value.
Run a three-layer entity audit
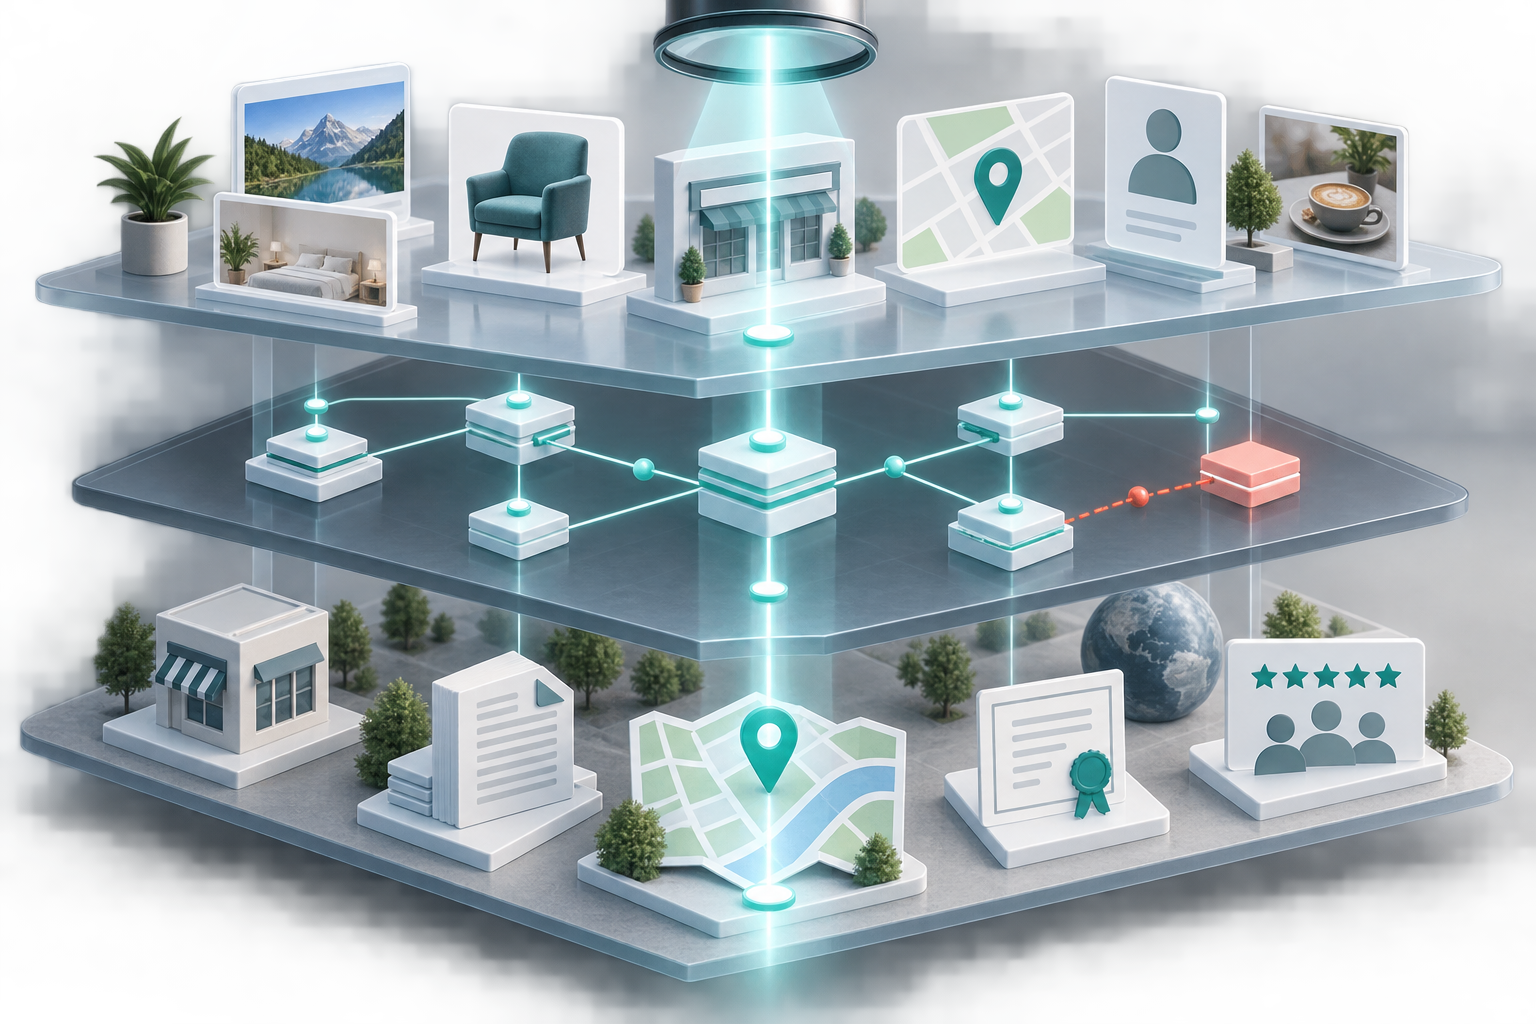
A schema validator tells you whether markup is technically parseable. An entity audit asks a harder question: does the site communicate the right facts clearly enough for a person or machine to connect them?
Audit three layers at the same time:
- Visible content: Is the fact stated plainly on the page where a visitor would expect to find it?
- Structured representation: Does the JSON-LD identify the correct entity, use an appropriate property, and carry the same value as the visible page?
- Supporting context: Is there enough related content to explain or substantiate the claim, and does that content point back to the primary entity?
Work through the audit in this order:
- Select the primary conversion page. Start with the page that owns the offer: the product, service, program, location, or other page on which the decision happens.
- List the decision-critical entities and facts. Use customer questions, qualification requirements, commercial terms, and differentiators rather than copying whatever happens to be in the current schema.
- Read the page as a skeptical visitor. Record the exact visible wording for every target fact. Do not silently reinterpret vague copy during the audit.
- Inspect the JSON-LD entity by entity. Match every node to a real thing, then compare its properties with the visible wording and approved value.
- Trace supporting pages. Note where details such as curriculum, outcomes, policies, specifications, or staff credentials live and whether their relationship to the primary offer is clear.
- Assign a status and an owner. Mark the fact legible, ambiguous, unverifiable, or missing. Then identify who can approve the fix and whether it belongs in content, structured data, or both.
Do not assume that broad coverage means strong entity clarity. In two higher-education implementations, a large share of the entities already present still proved ambiguous or unverifiable. One comparison set contained 85 custom JSON-LD entities; the existing site covered more than 50, but roughly a third of those were ambiguous or unverifiable and more than 20 were missing from program or supporting pages. Another audit identified 58 entities, with more than half classed as ambiguous and 27 classed as unverifiable.
That pattern matters because a conventional schema audit could report substantial coverage while overlooking the uncertainty inside it. Count the quality states, not just the properties.
If you manage hundreds or thousands of pages, embeddings can help with triage. Convert your approved target statements and your live content into comparable vector representations, then surface low-similarity areas for human review. Treat the similarity score as a queue, not a verdict. It can reveal that the language on a page does not resemble the intended entity model; it cannot decide whether a policy is true, a schema property is valid for a type, or a claim has been approved.
Fix the visible fact and its structured representation together
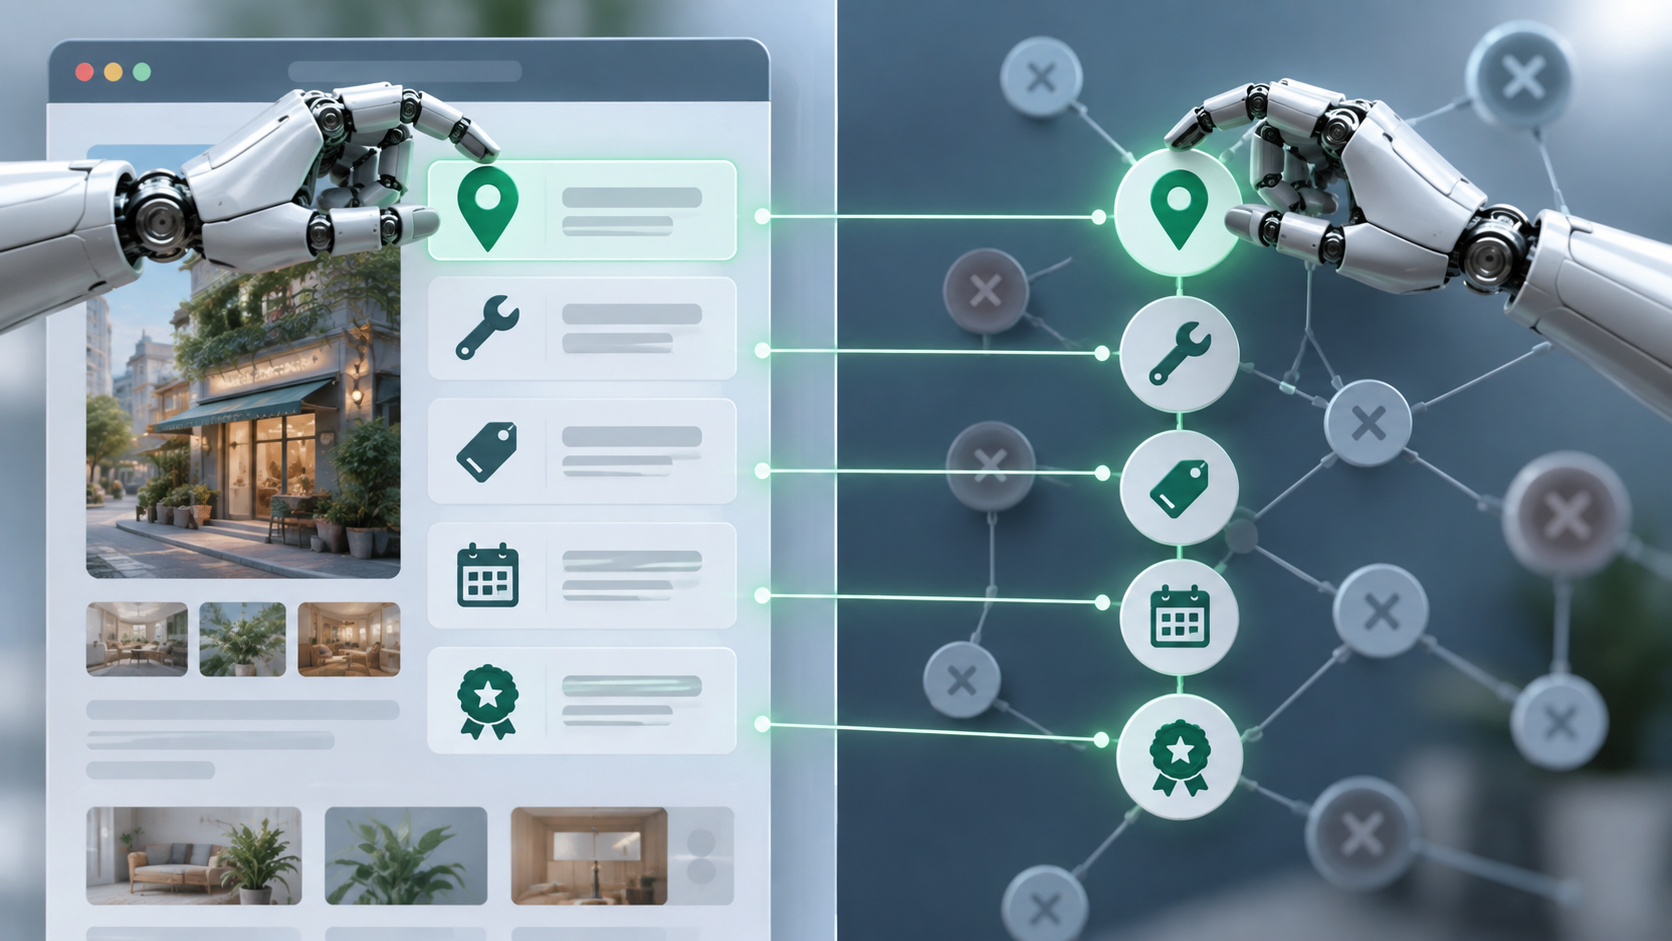
When the audit exposes a gap, diagnose it before editing:
- Content gap: The organization knows the fact, but the primary page does not state it clearly.
- Schema gap: The visible page is clear, but the JSON-LD omits the fact, formats it poorly, attaches it to the wrong entity, or conflicts with the copy.
- Truth gap: The organization cannot yet supply one reliable value because the policy is unsettled, varies by case, or lacks an accountable owner.
For content and schema gaps, use a single publishing sequence:
- Confirm the approved value with the person or system that owns it.
- Rewrite the visible content so a visitor can understand the fact without decoding internal terminology.
- Represent the same fact in JSON-LD using an appropriate schema.org type, property, value format, and unit.
- Connect supporting pages to the primary entity with consistent naming and purposeful internal links.
- Check the rendered page and structured data for disagreement before publishing.
Normalize values without making the page less human
Machine-readable precision does not require robotic visible copy. A visitor can read 15 months while the structured representation uses the applicable ISO duration. The important point is that both expressions mean the same thing.
| Decision fact | Weak or incomplete expression | More precise representation | Visible-page requirement |
|---|---|---|---|
| Program duration | 15 months stored only as text | ISO 8601 duration P15M | Explain that the program takes 15 months under the stated schedule |
| Start date | Ambiguous date wording | An exact YYYY-MM-DD value when one date genuinely applies | Show the corresponding date and any campus or cohort conditions |
| Credit total | 45 credits and 90 ECTS combined in one text string | QuantitativeValue with the relevant unit text | Make each credit system and its meaning clear |
| Language | English as unnormalized text | ISO 639-1 code en where the property expects it | State that instruction is in English |
| Minimum GPA | Good academic record | An approved numeric threshold such as 3.0 on a 4.0 scale | State the threshold, scale, and any genuine qualification |
These are examples of entity reconciliation applied to a particular university program, not values to copy. P15M is correct only when the duration is actually 15 months, and a 3.0 threshold should appear only when admissions has approved that rule. The correct schema property also depends on the type of entity you are marking up.
Keep identities and relationships stable
Give each core entity a stable identifier in your graph, commonly an @id based on a URL you control. Reuse that identifier when another node refers to the same organization, offer, person, or place. Otherwise, minor naming variations can produce duplicate-looking entities inside your own markup.
Use the narrowest schema type that is genuinely accurate, and use only properties supported for that type. Connect entities with specific relationships instead of placing every keyword in a description field. Your graph should be able to express which organization provides the offer, where it is available, which people are connected to it, and which supporting resources explain it.
The primary conversion page should own the essential decision facts. Supporting content should deepen them. An admissions page can explain an eligibility process, a curriculum page can detail course structure, and an outcomes page can substantiate career information, but each should reinforce the canonical offer rather than introducing a competing name or contradictory value.
Do not use schema to paper over an operational problem
A truth gap has to move outside the SEO queue. Send it to the team that owns pricing, admissions, compliance, product, or operations. Record what must be decided and leave the value out until it can be stated accurately.
Completeness is not worth misleading someone. One multi-campus university left an application-deadline entity unresolved because rolling starts across campuses made a single deadline potentially inaccurate. Another program did not emphasize faculty data when availability could not be maintained. In both situations, publishing a neat but unreliable value would have made the graph look fuller while making the answer worse.
When a value legitimately varies, explain the rule or scope if the organization can support it. Identify which location, plan, cohort, product variant, or date range the value applies to. If that relationship is not yet knowable, omit the claim rather than guessing.
Measure entity quality, AI visibility, and business value separately
Markup does not guarantee growth. It removes ambiguity and gives your content a more coherent machine-readable representation, but rankings, citations, recommendations, and conversions have many other inputs. Your measurement plan should therefore keep three scorecards separate.
- Entity quality: Track how many target facts are legible, ambiguous, unverifiable, or missing. Also count contradictions between visible content and JSON-LD, and note whether high-priority facts appear on the primary page.
- Search and AI visibility: Track citations, inclusion in answers, and share of voice against a fixed competitor set for a stable group of prompts. Preserve the prompts and competitors so a changing test does not masquerade as improvement.
- Business outcomes: Track the actions that matter after discovery, such as qualified leads, applications, purchases, payments, or stage-to-stage conversion rates. Better entity clarity may improve qualification even when top-line traffic is flat.
Record the publication date, pages changed, entities affected, content edits, and schema edits. That change log will not create a controlled experiment, but it will stop you from crediting an isolated markup change for work that also included clearer copy, new supporting content, and internal linking.
Two higher-education cases illustrate why the scorecards belong together. In one case, AI citations rose from 24,000 in January 2026 to 42,000 in July, a 75% increase over six months. Enrollment remained flat and lead volume fell, yet the lead-to-payment rate improved by 20% and the application-to-payment rate improved by 26%. The commercially important movement was not simply more discovery; it was better progression among people who entered the funnel.
In the other case, organic lead volume increased 18% from 2025 to 2026 and application volume increased 22%. AI citations were about 11% higher year over year and roughly 77% above the preceding six months, while competitive share of voice gained one percentage point.
Treat those results as directional case evidence, not universal benchmarks. The work combined entity reconciliation, visible-content changes, supporting pages, internal links, and structured data. The reasonable inference is that the coordinated package improved clarity and performance; the figures do not isolate JSON-LD as the sole cause.
Your first success metric should be controllable: fewer ambiguous and unverifiable facts on the pages that matter. Visibility and conversion trends can then show whether that stronger information layer is helping people and AI systems find a clearer answer.
Key takeaways
- Build the target entity model from customer decisions, not from the schema already installed.
- Classify each fact as legible, ambiguous, unverifiable, or missing so the right team gets the right kind of work.
- Make the primary conversion page the source of essential facts, then use supporting content to explain and substantiate them.
- Update visible copy and JSON-LD together. Precise markup attached to vague or conflicting content does not resolve the underlying entity.
- Normalize dates, durations, quantities, units, and identifiers only after the organization has approved the real value.
- Measure entity quality separately from AI visibility and business outcomes, and do not attribute a combined content-and-schema program to markup alone.
Open your highest-value page and list the facts a buyer needs before choosing the offer. Mark each one legible, ambiguous, unverifiable, or missing. Then take one high-impact cluster – eligibility, price, delivery, specifications, or outcomes – through approval, visible copy, JSON-LD, supporting content, and measurement. That page-level cycle is how entity optimization becomes durable infrastructure instead of a one-time GEO tactic.
References

Leave a Reply