Your company can appear in an AI answer and still lose the buyer. The system may cite an obsolete page, combine two products, repeat an unsupported claim, or recommend your business without giving the user a workable next step. A visibility screenshot does not solve any of those failures.
If you are deciding whether to hire an AI agent optimization or generative engine optimization service, you need a more precise buying standard. The provider should make your business easier for AI systems to discover, understand, verify, represent accurately, and use during a customer task. Here is how to define that work, test the provider’s evidence, and connect the program to revenue.
AI visibility and agent readiness are separate outcomes
GEO, AEO, and AI agent optimization overlap, but they do not solve exactly the same problem.
- Generative engine optimization, or GEO, improves the likelihood that your business, expertise, and content will be selected, cited, or recommended in generative search experiences.
- Answer engine optimization, or AEO, makes an answer easy to extract and present directly. It emphasizes clear questions, concise answers, supporting detail, and an information structure that does not force a system to infer the main point.
- AI agent optimization extends beyond the answer. It asks whether an agent can identify the right entity, retrieve current facts, understand conditions and limitations, and move the user toward an appropriate action.
This last layer is often described as agent experience, or AX. The practical test is whether an AI agent can read your information and act on it, not merely whether it can find your brand name.
| Stage | What the system must resolve | Common failure | Required service output |
|---|---|---|---|
| Discovery | Whether your business is relevant to the user’s task | The brand is absent from unbranded recommendations or associated with the wrong category | A query and task map tied to markets, audiences, offers, and existing pages |
| Evaluation | Whether your claims are specific, current, and credible | The answer repeats vague marketing language, cites weak evidence, or confuses similar offers | A claim inventory, supporting evidence, entity cleanup, and citation-ready content |
| Action | What the user or agent should do next | Requirements, availability, policies, locations, or conversion paths are unclear | Explicit next steps, stable destination pages, current conditions, and safe handoff points |
| Measurement | Whether visibility produced a useful business result | The report counts mentions but cannot connect them to qualified demand | Versioned response logs, referral tracking, CRM fields, lead quality, customers, and cost |
A provider that sells only the discovery stage is selling an AI visibility service, not a complete agent optimization program. That may still be useful, but the contract and price should reflect the narrower scope.
Structured data belongs in this system, but it is not the whole system. JSON-LD can clarify entities and relationships when it accurately describes the visible page. It cannot repair contradictory claims, create third-party authority, or guarantee that a model will cite you. Treat any promise of guaranteed placement through schema alone as a warning sign.
Turn the service label into a concrete deliverables list
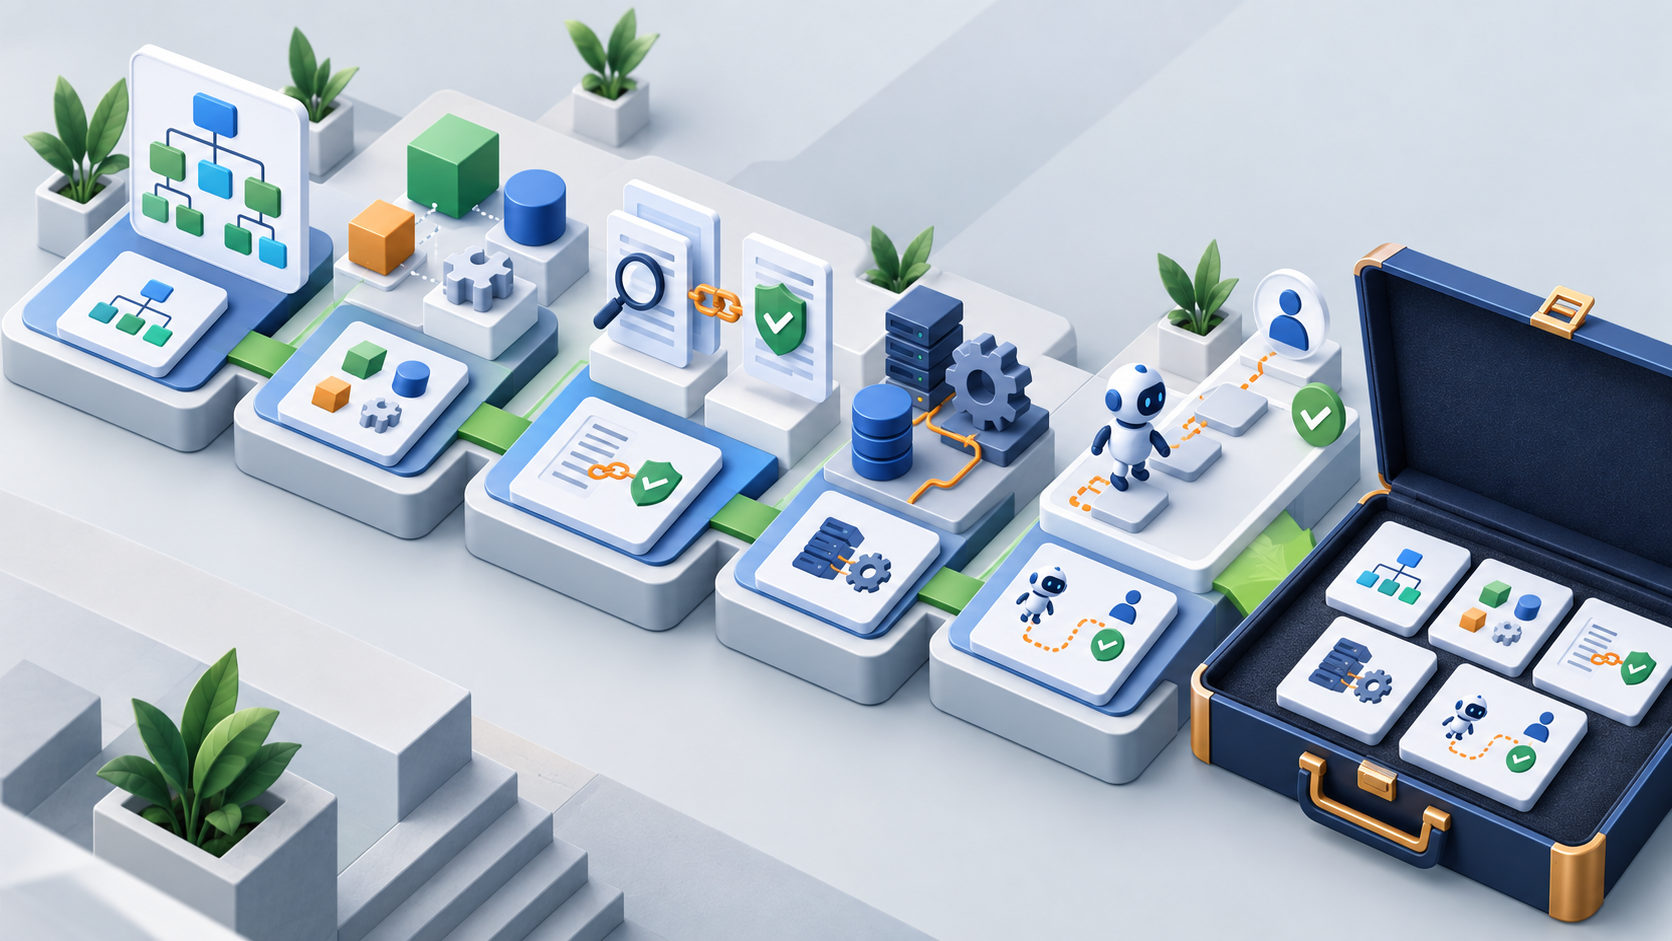
“GEO optimization” is too vague to approve as a statement of work. Require the provider to name the surfaces it will test, the assets it will change, the evidence it will produce, and the commercial event it will measure.
1. Establish a reproducible baseline
The baseline should contain the prompts or tasks that matter to your customers, the platforms on which they will be tested, and the result before any work begins. Each test record should preserve the exact prompt, date, market, language, interface, response, cited URLs, brand mentions, competing entities, and any factual errors.
A defensible test matrix can include ChatGPT, Gemini, Claude, Google AI Overviews, and relevant regional platforms. Do not add a platform merely to make the dashboard look comprehensive. Include it when your customers use it or when it materially influences their research environment.
Generative responses can vary between runs, so one favorable output is an observation, not a performance rate. The provider should retain successful and unsuccessful runs under the same protocol. Otherwise, you cannot tell whether a change improved repeatable visibility or merely produced a convenient screenshot.
2. Map customer tasks, not just keywords
A keyword list describes strings people type. A task map describes the decision they are trying to make. It should separate broad education, problem diagnosis, solution comparison, vendor selection, validation, and action. It should also distinguish branded from unbranded demand.
For every priority task, require a target audience, market, intended answer, relevant entity, best supporting page, evidence requirement, next action, and measurement event. This exposes gaps that ordinary keyword research can miss. You may already have a page that mentions the query while lacking the facts an AI system would need to recommend you confidently.
3. Build an entity and claim inventory
AI systems encounter your organization through many representations: service pages, product pages, profiles, interviews, directories, review sites, news coverage, partner pages, and structured data. If those representations use conflicting names, categories, capabilities, locations, or policies, the system has to resolve the conflict.
The inventory should list each material claim, where it appears, the evidence supporting it, the person responsible for it, and the condition that should trigger review. Include claims about availability, geography, pricing, certifications, integrations, performance, eligibility, and comparisons where they are relevant. Unsupported superlatives such as “best,” “leading,” and “most trusted” should not survive this process unless they have verifiable support.
4. Upgrade the content and technical layer together
Useful GEO content answers the decision question early, supports it with evidence, and then explains conditions, alternatives, and limitations. It does not bury the answer under an essay written only to occupy search-result space.
The technical work should check whether important information is available in stable, crawlable page content; whether canonical and duplicate versions create ambiguity; whether internal links express the relationship between entities and topics; and whether structured data matches what a person can see. The content and schema should be reviewed as one release. Updating one while leaving the other stale creates a new contradiction.
Do not interpret agent accessibility as permission to open every system to every crawler. Security, privacy, licensing, and infrastructure controls still apply. The provider should document which public content needs discovery, which automated access is permitted, and which sensitive or authenticated functions require a controlled interface or human confirmation.
5. Improve corroboration beyond your own domain
Your website can state what the business does. Independent references help establish whether those claims are credible. A complete service should therefore identify missing or inconsistent external evidence rather than treating on-page editing as the entire job.
This does not justify manufacturing mentions, publishing disguised endorsements, or distributing the same promotional copy across low-quality sites. The useful work is narrower: correct inaccurate profiles, align material facts, publish original evidence when you have it, make qualified experts identifiable, and earn relevant coverage or citations through legitimate public relations and reputation work.
6. Design the next action for people and agents
A recommendation has limited value if the next page does not explain how to proceed. The destination should state who the offer is for, what information is required, what happens after submission, which restrictions apply, and where the user can get help.
For higher-risk actions, build explicit confirmation points. An agent should not be encouraged to infer consent, accept legal terms, move money, expose private information, or make an irreversible change merely because the conversion path is technically available. Good AX makes safe progress easier; it does not remove necessary review.
Test a GEO provider’s evidence before you buy
The core buying question is not whether the agency understands AI vocabulary. It is whether you can reproduce its evidence and inspect the chain from optimization to business result.
Ask for a proof packet
A serious provider should be able to show a redacted example containing:
- The original business objective and the unbranded customer tasks used for testing.
- The baseline responses, including unfavorable results and factual errors.
- The pages, structured data, entity records, or external signals that changed.
- The exact prompts and testing conditions used after publication.
- Raw outputs and cited URLs, not only a chart summarizing them.
- The denominator behind every percentage. “Appeared in 80% of tests” is meaningful only if you know which tests qualified.
- The connection between visibility, qualified leads, customers, revenue, and program cost.
Recommendation frequency is useful when the query set, platform set, market, competitor group, test conditions, and failures are disclosed. It becomes a vanity metric when a provider selects only prompts on which the client already performs well.
Score the operating model
Assess how the work will move through your organization. A technically strong plan can still fail if nobody has authority to update claims, approve schema, correct external profiles, or connect analytics to the CRM.
- Method: Can the provider explain how tasks are selected, how outputs are recorded, and how it separates correlation from a plausible effect of its work?
- Industry fit: Has it handled the approval burden, sales cycle, terminology, and evidence standards of a comparable category?
- Regional fit: Does its platform and language coverage match your buyers rather than its standard reporting package?
- Editorial control: Who checks factual accuracy, claim support, tone, and legal or compliance requirements before publication?
- Technical access: Who can edit templates, structured data, internal links, rendering behavior, analytics, and consent-aware tracking?
- Ownership: Do you retain the prompt set, content, schema, response logs, dashboards, and documentation when the engagement ends?
- Governance: Is there a named owner for each correction, release, test, and approval?
Methodology transparency, search experience, independently cited work, and demonstrated recommendation performance can all inform due diligence. Their importance changes by context. Independent methodological validation matters more when procurement, legal, or compliance teams must defend the investment; relevant client outcomes matter more than general prestige when you need execution in a specific market.
A provider’s own agency ranking is not independent validation, even when its testing method appears thoughtful. Use vendor-published comparisons to build a shortlist and identify evaluation criteria. Verify the underlying claims separately before signing.
Reject guarantees that the provider cannot control
No agency controls a frontier model’s training data, retrieval process, product interface, citation policy, or future output. That makes guaranteed rankings, permanent citations, and universal “AI preference” claims untenable.
A responsible commitment is operational: the provider will complete named changes, test a disclosed task set, record outputs consistently, correct representation errors it can influence, and report commercial results under an agreed attribution model. That is enforceable work. A promise that ChatGPT or another platform will always recommend you is not.
Build a business case without hiding the uncertainty
GEO can be measured economically, but public benchmarks are still less mature than established paid-search or SEO benchmarks. Use external numbers to challenge your assumptions, not to replace your own baseline.
One proprietary 36-month dataset covered 341 companies across 15 industries between October 2023 and September 2026. It reported an average GEO customer acquisition cost of $581, compared with $470 for traditional SEO, a 23.6% difference. GEO received an average lead-quality score of 8.2 out of 10 and a 40-day conversion timeline, versus 7.8 and 84 days for traditional SEO.
Those averages are directional, not universal. The dataset was 64% B2B, used a minimum of eight companies per industry, and excluded paid advertising on AI platforms. Industry-level GEO CAC ranged from $265 in construction to $1,129 in higher education, while the reported conversion timelines ranged from 11 days in ecommerce to 61 days in higher education. Your sales process, margins, market, attribution method, and existing authority can move the result substantially.
The same proprietary data reported a $497 average CAC, 91% success rate, and 52-day time to results for premium agency-managed programs. In-house-only programs were reported at $947, 46%, and 203 days. The difference is large enough to make implementation quality worth investigating, but not strong enough to assume that hiring an agency automatically produces the lower figure. The data comes from an agency, the engagement models are not standardized across the market, and selection effects may account for part of the gap.
Before using any benchmark in a budget request, make the provider define “success,” “customer,” “attributed,” “program cost,” and “time to results” in terms your finance and sales teams accept. Otherwise, two dashboards can report different CACs from the same pipeline.
Measure the program at three levels
- Visibility and representation: Track valid task coverage, brand inclusion, citation frequency, cited pages, competitive presence, factual error rate, and whether the answer describes your offer correctly.
- Engagement and influence: Track AI-referred sessions, qualified actions, assisted conversions, CRM discovery responses, and sales notes that record meaningful AI-assisted research.
- Commercial efficiency: Track qualified leads, new customers, attributable revenue, total program cost, CAC, conversion time, and payback under a documented attribution rule.
Keep direct and influenced performance separate. Direct GEO CAC divides program cost by customers assigned directly to an AI referral under your agreed model. Influenced GEO CAC uses customers with documented AI involvement. Combining the two produces a cleaner-looking number but destroys its meaning.
Set the attribution window from your real sales cycle rather than from a generic analytics default. Preserve the pre-change baseline, annotate every release, and segment branded from unbranded tasks. A rise in branded mentions may reflect demand created elsewhere; stronger performance on unbranded vendor-selection tasks is more persuasive evidence that the GEO program affected discovery.
Your allowable CAC should come from unit economics and the payback period your finance team can support. Do not approve a budget simply because it is below a published industry average. A benchmark cannot tell you whether the acquired customer’s margin, retention, or implementation cost makes the investment sensible for your business.
Key takeaways for your first operating cycle
- Start with a stable set of customer tasks, target markets, platforms, and conversion outcomes. Do not begin with content production.
- Capture the baseline before changing pages, structured data, profiles, or external evidence.
- Require an entity and claim inventory so that every material fact has evidence, an owner, and a review trigger.
- Treat GEO, AEO, technical access, reputation, and agent experience as connected workstreams with separate deliverables.
- Require raw response logs and failed tests. A gallery of favorable screenshots cannot establish recommendation frequency.
- Measure visibility, representation accuracy, qualified demand, customers, and cost as separate layers.
- Keep direct attribution distinct from documented influence, and use your own sales cycle and unit economics.
- Retain ownership of the content, structured data, task set, dashboards, logs, and implementation documentation.
Your first move should be to write the test and evidence requirements, not to choose an agency. Give each shortlisted provider the same business tasks and ask how it would baseline them, what it would change, what proof it would return, and how the result would enter your CRM. The provider that can make that operating chain concrete is worth deeper diligence. The one selling unspecified “AI visibility” is asking you to buy the label.
References
- HiGoodie Blog – AX: Optimizing Your Brand for AI Agents
- First Page Sage Blog – Generative Engine Optimization Customer Acquisition Cost (CAC): 2026 Benchmarks
- First Page Sage Blog – The Top GEO Agencies in the World in 2026

Leave a Reply