Tag: Agentic Search Optimization

  • How to Win Visibility in Agent-Driven Search

    How to Win Visibility in Agent-Driven Search

    Your page can rank first and still lose the customer. In agent-driven discovery, a person can ask an AI assistant to find, compare, book, buy, or contact a provider. The agent may evaluate several businesses and complete the task without sending that person through a familiar results page.

    That changes the visibility problem. You still need to be found, but you also need to survive qualification, support verification, and offer a safe path to action. The practical goal is not merely to appear in an answer. It is to remain the best eligible choice all the way through the agent’s workflow.

    Search visibility now has four separate gates

    An agent commonly turns a delegated request into requirements, searches for possible candidates, evaluates each candidate against those requirements, checks important claims, and then attempts the requested action. A conventional ranking affects the candidate-gathering stage, but it does not settle the final decision.

    GateQuestion the agent must resolveWhat your site needs to provideUseful metric
    RetrievalCan I find this business for the delegated task?Indexable pages, unambiguous entities, relevant task language, and clear topical coverageCandidate appearance rate
    QualificationDoes it satisfy every non-negotiable requirement?Explicit capabilities, limits, prices, locations, eligibility rules, integrations, and availabilityHard-requirement pass rate
    SelectionIs it the best fit among the eligible choices?Suitability guidance, evidence, differentiators, and independently verifiable claimsSelection share when retrieved
    CompletionCan I safely perform the requested action?A usable form, booking flow, checkout, approved API, or clearly defined human handoffSuccessful action rate

    Ranking remains important because it helps a brand enter the candidate set. It is no longer a reliable proxy for winning the decision. First Page Sage reported that, in its vendor-led analysis of 2,417 agentic commands issued from March 4 through June 10, 2026, the first-ranked result was selected 44.6% of the time, while a result ranked fourth or lower was selected 38.2% of the time. Those figures are directional rather than universal benchmarks: they come from one commercial analysis, and agent behavior can differ by platform, category, request, and user context.

    The useful conclusion is narrower and more durable: rank and selection are different outcomes. If your reporting stops at impressions, positions, and clicks, you cannot tell whether an agent failed to retrieve your brand, rejected it on a requirement, distrusted a claim, or could not complete the transaction.

    Give each gate its own metric. Candidate appearance rate tells you whether discovery is working. Hard-requirement pass rate exposes missing or disqualifying facts. Selection share tells you whether the agent prefers you after finding you. Successful action rate reveals whether your conversion path works for an automated assistant. A single visibility score hides all four failure modes.

    Publish the facts agents need to qualify you
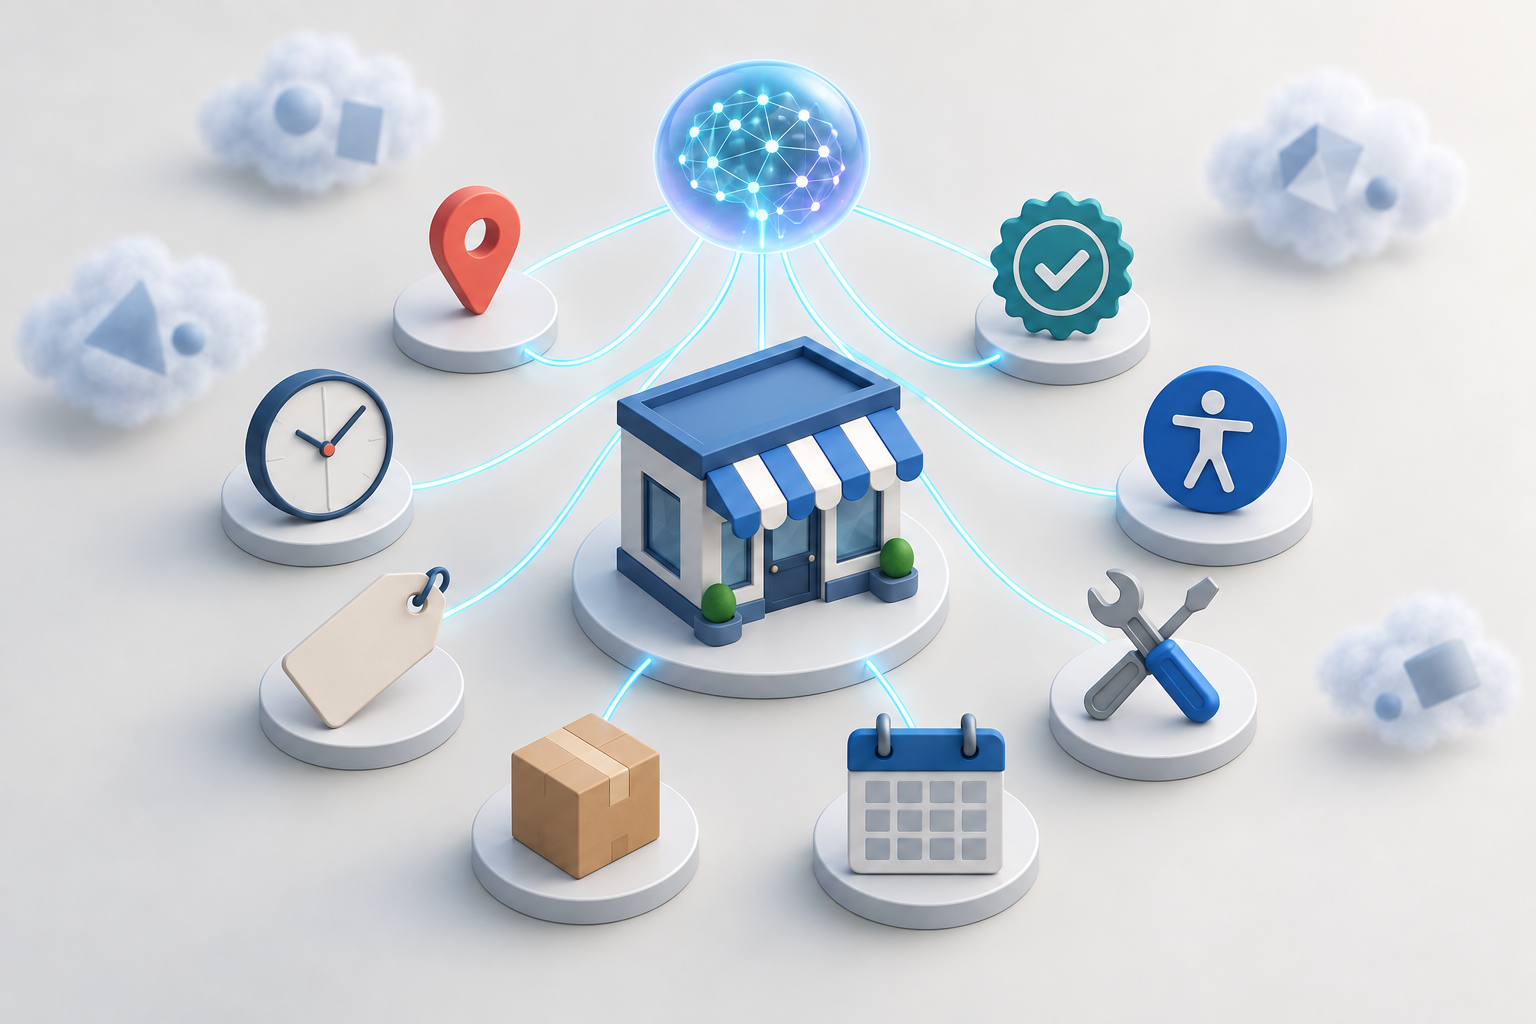
    A central business model is connected to visual modules for location, hours, price, availability, services, accessibility, and verification.

    A broad category page may rank for “payroll software,” “family hotel,” or “commercial electrician” while giving an agent too little information to answer a constrained request. Real delegated tasks include conditions: company size, location, budget, dates, integrations, accessibility needs, service area, cancellation terms, or regulatory requirements.

    Agents can treat those conditions differently. A hard requirement eliminates a candidate. An important requirement carries substantial weight. A nice-to-have breaks a close comparison. An optional feature may add only a small advantage. Your first content job is to discover which facts occupy each tier for the buying tasks that matter to your business.

    1. Choose a delegated commercial task. Use a task tied to revenue, such as booking a service, selecting a product, requesting a proposal, or arranging a demonstration. Commercial requests deserve priority because delegated agent activity is more concentrated around buying, booking, and hiring than around general informational searches.
    2. Write down the complete requirement set. Use actual sales questions, support tickets, requests for proposals, on-site searches, form responses, and objections. Separate non-negotiable conditions from preferences instead of treating every feature as equally important.
    3. Map every hard requirement to a canonical page. The answer should be stated directly, not buried in a brochure, image, unsupported comparison chart, or sales-only conversation.
    4. Add suitability content. Explain who the offer is for, who it is not for, which situations it supports, what prerequisites apply, and where its limits begin.
    5. Keep consequential facts synchronized. Prices, regions, availability, policies, product names, and eligibility rules should not conflict across product pages, help content, structured data, directories, and partner profiles.

    Use a suitability page pattern that answers the whole decision

    A useful suitability page is not another generic “why choose us” page. It should let a machine or a person decide whether your offer fits a specific situation. A practical structure is:

    • Best fit: the customer, use case, location, scale, or conditions the offer is designed for.
    • Required conditions: prerequisites the customer must meet before buying, booking, or applying.
    • Supported requirements: the capabilities, integrations, service areas, configurations, or policies that satisfy common constraints.
    • Limitations: unsupported scenarios, exclusions, capacity boundaries, dependencies, and cases that require a different offer.
    • Commercial facts: visible pricing where possible, or a precise explanation of what determines price; availability; fees; cancellation terms; and what happens after submission.
    • Evidence: links to documentation, policies, certifications, product details, or independent material that substantiates consequential claims.
    • Next action: a clear route to buy, book, request a quote, schedule a demonstration, or move to a human review.

    Dedicated suitability content is worth testing even if it attracts little conventional search volume. In the same vendor analysis, businesses with this kind of content were selected 2.7 times as often as equally ranked businesses without it. That multiplier should not be treated as a guaranteed result, but the mechanism is sensible: explicit fit information reduces the inference an agent must make.

    Make proof machine-readable without hiding caveats

    Relevant JSON-LD can express your organization, offer, product or service, availability, and other supported attributes in a consistent format. Use it to clarify facts already visible on the page. Do not use markup to introduce claims, prices, ratings, availability, or capabilities that a visitor cannot confirm in the page content.

    Structured data reduces ambiguity; it does not establish truth. Agents may compare a site’s claims with what they already know and with independent material before choosing a candidate. Make important assertions easy to verify by identifying what the claim applies to, where it applies, and under which conditions. A sentence such as “integrates with accounting software” is weak. A maintained integration page that names the supported systems, required plan, setup path, and current limitations is decision-grade evidence.

    Consistency matters here. Use the same business name, canonical URL, product names, locations, and core offer descriptions wherever you control the information. When a third-party profile is outdated, correct it. When a claim changes, update the visible page and its markup together. Contradictory facts force an agent to decide which version to trust, and the safest decision may be to exclude the candidate.

    Remove the blockers between selection and completion
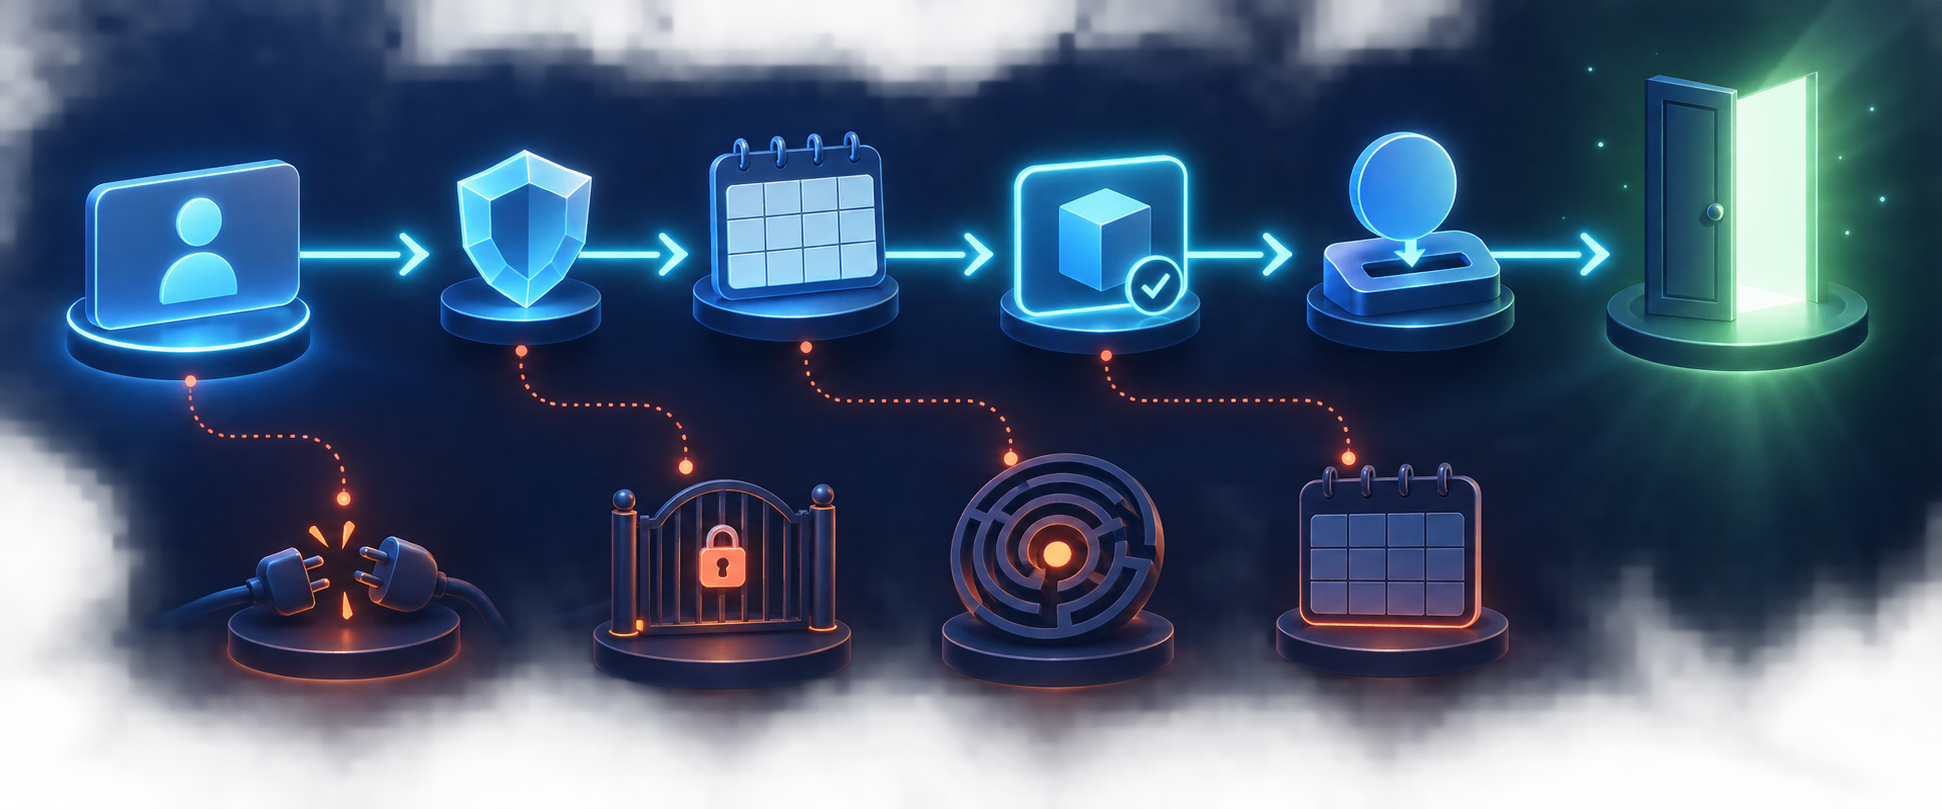
    A glowing agent pathway moves through verification, availability, selection, payment, and completion while alternate routes end at digital obstacles.

    A recommendation has limited commercial value if the agent cannot finish the requested job. The operational difference is whether a page is machine-actionable: can an approved agent use the interface to submit the inquiry, reserve the time, add the product, complete the purchase, or reach a defined handoff?

    The vendor-led command analysis recorded 78.3% of conversions on machine-actionable pages, compared with 9.6% on pages where the agent could not act. This is not a promise that making a form accessible will produce a particular conversion rate. It is evidence that transactional usability can become a selection constraint rather than a minor conversion optimization.

    Audit the complete transaction, not just the landing page

    • Use visible, specific field labels. “Work email,” “arrival date,” and “number of employees” are easier to interpret than placeholder-only or context-dependent fields.
    • State required inputs before submission. If a quote needs a postal code, account identifier, property type, budget range, or document, disclose that requirement before the agent enters the flow.
    • Explain validation failures precisely. Identify the affected field, preserve valid entries, and say what an acceptable value looks like.
    • Expose material terms before commitment. Price, fees, renewal terms, cancellation conditions, availability, and approval dependencies should not appear only after the decisive click.
    • Use conventional controls and stable destinations. Buttons should have meaningful labels, links should resolve predictably, and essential actions should not depend on unexplained gestures or decorative interface elements.
    • Return an actionable confirmation. Show what was submitted, whether it succeeded, what happens next, and any reference number or next step the user needs.
    • Define the human handoff. If the task cannot be automated, say which step requires a person, what information that person needs, and how the customer will be contacted.

    Test the flow from a clean session using the same facts a customer would give an agent. Check every branch: unavailable dates, unsupported locations, invalid entries, expired inventory, payment failure, authentication, and confirmation. A form that works only on the happy path is not reliably actionable.

    Agent-friendly does not mean unguarded. Keep authentication, fraud controls, consent, privacy safeguards, and human approval wherever the risk requires them. Do not weaken a security control to make automation easier. If automated action is allowed, provide an approved route; if it is not, provide a clear and honest handoff instead of a hidden bypass.

    Use audience preference where the platform supports it

    Retrieval is not driven only by topical relevance. Google Preferred Sources gives readers an explicit way to star publications in the Top Stories area so that stories from those outlets can appear more often for those readers. This is a narrow feature with a precise scope: it concerns publications and Top Stories, not every business listing, organic result, or AI-agent decision.

    The feature has nevertheless become large enough for publishers to treat it as a real retention channel. Google reported that people had selected more than 600,000 unique sources, up from 200,000 in May 2026. Google has also said that users who select a preferred source are twice as likely to click. Those figures describe this specific feature; they do not establish a general ranking advantage across search or AI platforms.

    If you publish news and participate in Top Stories, the implementation is straightforward:

    1. Install Google’s Preferred Sources button using the supported implementation.
    2. Place the prompt near a moment when the reader has received value, such as the end of a substantive story, rather than interrupting the opening.
    3. Explain the result accurately: starring the publication can make its stories appear more often in that reader’s Top Stories experience.
    4. Record the preferred-source user count with its reporting date so you can measure growth instead of relying on an undated total.
    5. Compare that growth with returning readership and engagement, while keeping correlation separate from proof of causation.

    Some site owners received Search Console emails showing a Preferred Source user count as of October 5, 2026. Google also surveyed recipients about future reporting methods, frequency, and metrics. Until regular reporting is established, keep your own dated record of any counts you receive.

    If you are not a relevant publication, do not imitate the button or describe ordinary follows as Preferred Sources. Apply the underlying principle without inventing a platform signal: give satisfied readers a clear way to return, subscribe, follow, or search for your brand again. Explicit preference can support a durable audience, but it should not be presented as proof that an unrelated agent will select you.

    Measure agent visibility as a decision path

    You do not need access to an agent’s private logs to build a useful diagnostic. You need a repeatable set of realistic tasks and a disciplined record of what can be observed. Start with the commercial requests that matter most, because “explain this topic” and “choose a provider and submit an inquiry” test very different kinds of visibility.

    1. Define the task exactly. Include the hard constraints a real buyer would provide: location, budget, timing, compatibility, eligibility, scale, or required terms.
    2. Preserve the test context. Record the platform, date, locale, sign-in state, exact command, and any files or preferences supplied. Keep the command unchanged when comparing runs.
    3. Capture the candidate set. Note whether your brand appeared, which page supported the appearance, what claims were surfaced, and which competing options were considered.
    4. Score each requirement. Mark hard requirements as confirmed, failed, contradictory, or unknown. An unknown should not be counted as a pass merely because you know the answer internally.
    5. Separate selection from retrieval. Record whether the brand was found, whether it remained eligible, whether it was selected, and the observable reasons given. Do not present an inferred reason as if the agent disclosed it.
    6. Test the action. Where authorized, follow the process through the form, booking, cart, checkout, or handoff. Record the exact field, policy, authentication step, or interface state that prevents completion.
    7. Fix the earliest failed gate. More suitability copy will not solve an indexing failure. More authority will not repair an unusable booking flow. Diagnose before choosing the optimization.
    8. Repeat on a fixed cadence. Agent outputs can change, so compare patterns across repeated observations rather than treating one response as a permanent ranking.

    Keep conventional SEO and analytics beside this testing. Search rankings still influence retrieval, human visitors still use results pages, and agent-driven commercial activity remains only part of search. The measurement upgrade is additive: it connects rankings and mentions to qualification, selection, and completed work.

    Key takeaways

    • A ranking can earn entry into an agent’s candidate set without earning the final selection.
    • Publish explicit requirements, supported scenarios, limitations, commercial terms, and suitability guidance so the agent does not have to guess.
    • Use JSON-LD to clarify visible facts, not to make unsupported claims or conceal qualifications.
    • Make consequential claims consistent and independently verifiable.
    • Treat forms, booking systems, checkout, APIs, and human handoffs as part of search visibility.
    • Measure retrieval, qualification, selection, and completion separately so each failure receives the right fix.
    • Use Google Preferred Sources if its Top Stories scope fits your publication, but do not mistake it for a universal agent-ranking signal.

    Choose your highest-value delegated task and trace it from discovery to completion. If your brand is absent, repair retrieval. If it appears but is rejected, expose the missing fit or proof. If it is selected but the task stalls, fix the transaction. That sequence keeps you from buying more visibility when the real leak is qualification, trust, or action.

    References


  • AI Search Ranking Signals: A Practical Priority Order

    AI Search Ranking Signals: A Practical Priority Order

    If your team is debating whether the next optimization sprint should go to schema markup, an llms.txt file, or another FAQ block, pause. The larger opportunity is usually earlier in the chain: make it unmistakable what you offer, who it fits, and whether the same facts appear everywhere an AI system may encounter your brand.

    Markup can help a machine interpret a strong page. It cannot rescue vague positioning, missing proof, or conflicting information. If you want more visibility in ChatGPT, Gemini, Claude, AI Mode, and agentic search, use the priority order below to decide what to fix first.

    The strongest measured signals are clarity and consistency

    From June 8 to September 18, 2026, 4,213 commercial prompts and 657 agentic shortlisting or purchasing tasks were run through ChatGPT, Google Gemini, including AI Mode, and Claude. The analysis covered 1,089 brands across 14 industries and measured recommendation rate: the share of relevant prompts in which a platform named a brand as a recommended option.

    Clear descriptions of offerings and suitability had the largest adjusted association with recommendation rate at +11.2 percentage points. Consistent information across a brand’s website and third-party sources followed at +9.4 points. The adjustment controlled for authority signals such as list mentions, reviews, and awards.

    SignalDifference before authority controlDifference after authority controlWhat to do with it
    Clear offerings and suitability+15.8 points+11.2 pointsState what each offer is, who it serves, and when it is suitable.
    Consistent brand information+16.9 points+9.4 pointsReconcile important facts across owned pages and third-party profiles.
    Comparison tables on service pages+6.7 points+1.9 pointsUse tables when they make fit and differences easier to evaluate.
    Any schema markup+3.7 points+0.4 pointsTreat schema as a representation layer, not the main ranking project.
    Organization schema+2.1 points+0.2 pointsImplement it accurately, but do not expect it to create authority.
    FAQ schema+0.8 points-0.3 pointsAdd useful FAQs for readers, not to manufacture a ranking signal.
    llms.txt+0.8 points-0.1 pointsKeep it behind clarity, consistency, and authority work in the backlog.
    Product schema for ecommerce brands+6.7 points+4.8 pointsGive this greater priority when products are the entities being evaluated.

    Do not treat those adjusted differences as universal ranking weights. They are associations from one observational dataset, not proof that changing one field will produce a fixed lift on every platform. The negative FAQ schema and llms.txt figures do not show that either feature causes harm; they show that no measurable positive effect remained after authority was controlled in this sample.

    The more useful lesson is about sequencing. Schema appeared more powerful before authority was held constant because brands that invest in technical optimization often have stronger authority signals too. If your page still leaves its audience or use case implicit, technical polish is unlikely to be the constraint holding it back.

    Cross the clarity threshold before adding more structure

    Scattered translucent shapes merge into one clear object before passing through a glowing gateway toward neatly organized blocks.

    Clarity is not the same as short copy. A clear page gives a model enough explicit information to connect an offering to a person, problem, location, and buying situation without having to infer the missing pieces.

    On the specific ten-point rubric used in the commercial-prompt analysis, brands scoring 5 to 6 averaged an 11.2% recommendation rate. Brands scoring 7 to 8 averaged 23.6%, while those scoring 9 to 10 averaged 24.8%. The large change occurred when sites moved from partially clear to explicitly clear; the difference between clear and comprehensive was much smaller.

    A score of 7 is not an industry standard or a guarantee. It is a useful diagnostic line from this dataset. Below it, missing fit information can prevent a brand from entering the serious consideration set. Above it, suitability and authority have more room to decide which clear option gets recommended.

    Audit each commercially important page against four questions:

    • Offering: Can a reader identify exactly what is being sold from the opening copy, without decoding a slogan?
    • Fit: Does the page explicitly name the customer types, use cases, and situations for which the offer is appropriate?
    • Specifics and proof: Does it provide available details about the process, pricing approach, service area, results, awards, or relevant customer examples?
    • Organization: Can someone scan headings, bullets, and genuine comparison tables to find those answers quickly?

    The common failure is a page that names the service but makes the reader infer suitability from logos or broad language such as “businesses of all sizes.” Replace that implication with a direct statement. A useful opening pattern is: “[Offering] is a [category] for [customer type] that needs [use case or outcome] in [relevant situation].” The brackets are prompts for substance, not a sentence to copy mechanically.

    Give each material offering its own page. Add a fit section that says who should consider it and which conditions change the recommendation. Explain how it differs from adjacent options. Publish concrete facts you can support, including a pricing approach when exact prices cannot be public. This work improves both human evaluation and machine interpretation because it removes the need to guess.

    Make your facts consistent, then build the right authority

    Several abstract information sources send matching light pulses to a central sphere supported by an illuminated framework, while one conflicting pulse fades away.

    Consistency is more than spelling the company name the same way. It means that your offer names, audience, locations, pricing model, capabilities, and proof do not change as someone moves between your website and independent references.

    That matters because cross-source consistency retained a +9.4-point association with recommendation rate after authority was controlled. A model can work with a qualified claim repeated accurately across several places. It has a harder decision when the homepage, product page, directory profile, and review coverage describe materially different businesses.

    Create a canonical fact ledger before asking teams to update pages independently. It should contain:

    • The official brand name and a plain description of the business.
    • The canonical name and definition of every material offering.
    • The audience, use cases, and suitability conditions for each offer.
    • Locations or service areas, where relevant.
    • The pricing approach and any public qualification criteria.
    • Approved proof points, including the exact scope and date behind each result.
    • Awards, credentials, and other claims that can be independently verified.

    Compare that ledger with your homepage, product and service pages, location pages, directory entries, review profiles, and independent coverage. Correct owned pages first. Then request corrections where third-party information is outdated. Prioritize contradictions that change eligibility or fit, such as an old service area, a discontinued product name, or a claim that applies to one offer but appears to describe the whole company.

    Authority is not interchangeable with structured data. The unadjusted difference associated with any schema was +3.7 points, but it fell to +0.4 after list mentions, reviews, awards, and related authority signals were controlled. That does not assign a causal value to any one authority tactic. It does show why adding markup to an under-recognized brand should not be mistaken for building recognition.

    The most useful form of third-party evidence also depends on the buying market. In consumer categories, expert reviews outweighed customer reviews by 15 to 1 in AI search, while B2B software showed the reverse pattern. Treat that result as directional rather than a rule for every niche, but do not copy one review strategy across both markets.

    • For a consumer category, identify the credible expert reviewers and category comparisons that buyers already use. Make your product facts easy to verify, and correct inaccurate coverage where possible.
    • For B2B software, prioritize authentic, specific customer-review evidence in the places buyers consult. Generic praise is less useful than a review that identifies the customer situation and the product’s role.
    • For either market, keep externally promoted claims aligned with the canonical facts on your site. More mentions will not solve a contradiction that makes the offer harder to classify.

    Use schema to transmit facts, not invent importance

    Schema has a real job: it labels entities and properties in machine-readable form. That job is valuable, but it is different from earning a recommendation. The safest implementation rule is simple: structured data should faithfully represent useful facts that a visitor can already verify on the page.

    Product schema deserves separate treatment for ecommerce. Among the 214 ecommerce brands in the sample, it retained a +4.8-point association after authority control. That is the only measured markup type with a meaningful adjusted difference in the available data. It still does not prove a guaranteed lift, but it gives ecommerce teams a stronger reason to prioritize accurate Product markup than a service business has to deploy several marginal schema types.

    Use this implementation order:

    1. Fix the visible offer, fit, and proof on the page.
    2. Select a schema type that corresponds to the entity actually described, such as Organization or Product.
    3. Make names, descriptions, and other claims match the visible content and your canonical fact ledger.
    4. For ecommerce, prioritize accurate Product markup before adding loosely relevant schema types merely to increase the count.
    5. Add FAQ content only when it answers questions that help a buyer decide. Treat FAQ schema as encoding for that content, not as an independent visibility lever.
    6. Validate the markup and review it whenever the visible facts change.

    Apply the same discipline to llms.txt. Its adjusted difference was -0.1 points in the measured sample, which is effectively no demonstrated lift there. You may still test it as a low-cost machine-accessibility experiment, but it should not displace work on unclear pages, conflicting facts, or missing authority.

    Comparison tables sit between content and structure. Their adjusted association was a modest +1.9 points. Use one when a buyer genuinely needs to compare audiences, use cases, features, or alternatives. A table that exposes meaningful differences can improve clarity; a table built only to look optimized adds no new information.

    Key takeaways: choose your next optimization ticket

    • Fix explicit fit first. Every important offer should state what it is, who it serves, when it is suitable, and what evidence supports it.
    • Reconcile facts across the web. Maintain one canonical ledger and use it to correct high-impact contradictions on owned pages and third-party profiles.
    • Build market-appropriate authority. Consumer categories may lean more heavily on expert reviews, while B2B software may depend more on customer-review evidence.
    • Make schema accurate and proportionate. Product schema has the strongest measured case for ecommerce; Organization schema, FAQ schema, and llms.txt should not outrank clarity work.
    • Measure recommendations, not implementation volume. Use a fixed set of commercial prompts across the platforms that matter, record whether your brand is named and for which use case, then inspect the pages and evidence supporting each result.

    Start with the highest-value product or service page, not a sitewide markup rollout. Make one offer fully explicit, reconcile its facts, align its external evidence, and then encode it accurately. Once that page can answer what, who, when, where, and why without inference, you have a useful model for the rest of the site.

    References


  • AI Agent Optimization and GEO Services: A Buyer’s Guide

    AI Agent Optimization and GEO Services: A Buyer’s Guide

    Your company can appear in an AI answer and still lose the buyer. The system may cite an obsolete page, combine two products, repeat an unsupported claim, or recommend your business without giving the user a workable next step. A visibility screenshot does not solve any of those failures.

    If you are deciding whether to hire an AI agent optimization or generative engine optimization service, you need a more precise buying standard. The provider should make your business easier for AI systems to discover, understand, verify, represent accurately, and use during a customer task. Here is how to define that work, test the provider’s evidence, and connect the program to revenue.

    AI visibility and agent readiness are separate outcomes

    GEO, AEO, and AI agent optimization overlap, but they do not solve exactly the same problem.

    • Generative engine optimization, or GEO, improves the likelihood that your business, expertise, and content will be selected, cited, or recommended in generative search experiences.
    • Answer engine optimization, or AEO, makes an answer easy to extract and present directly. It emphasizes clear questions, concise answers, supporting detail, and an information structure that does not force a system to infer the main point.
    • AI agent optimization extends beyond the answer. It asks whether an agent can identify the right entity, retrieve current facts, understand conditions and limitations, and move the user toward an appropriate action.

    This last layer is often described as agent experience, or AX. The practical test is whether an AI agent can read your information and act on it, not merely whether it can find your brand name.

    StageWhat the system must resolveCommon failureRequired service output
    DiscoveryWhether your business is relevant to the user’s taskThe brand is absent from unbranded recommendations or associated with the wrong categoryA query and task map tied to markets, audiences, offers, and existing pages
    EvaluationWhether your claims are specific, current, and credibleThe answer repeats vague marketing language, cites weak evidence, or confuses similar offersA claim inventory, supporting evidence, entity cleanup, and citation-ready content
    ActionWhat the user or agent should do nextRequirements, availability, policies, locations, or conversion paths are unclearExplicit next steps, stable destination pages, current conditions, and safe handoff points
    MeasurementWhether visibility produced a useful business resultThe report counts mentions but cannot connect them to qualified demandVersioned response logs, referral tracking, CRM fields, lead quality, customers, and cost

    A provider that sells only the discovery stage is selling an AI visibility service, not a complete agent optimization program. That may still be useful, but the contract and price should reflect the narrower scope.

    Structured data belongs in this system, but it is not the whole system. JSON-LD can clarify entities and relationships when it accurately describes the visible page. It cannot repair contradictory claims, create third-party authority, or guarantee that a model will cite you. Treat any promise of guaranteed placement through schema alone as a warning sign.

    Turn the service label into a concrete deliverables list

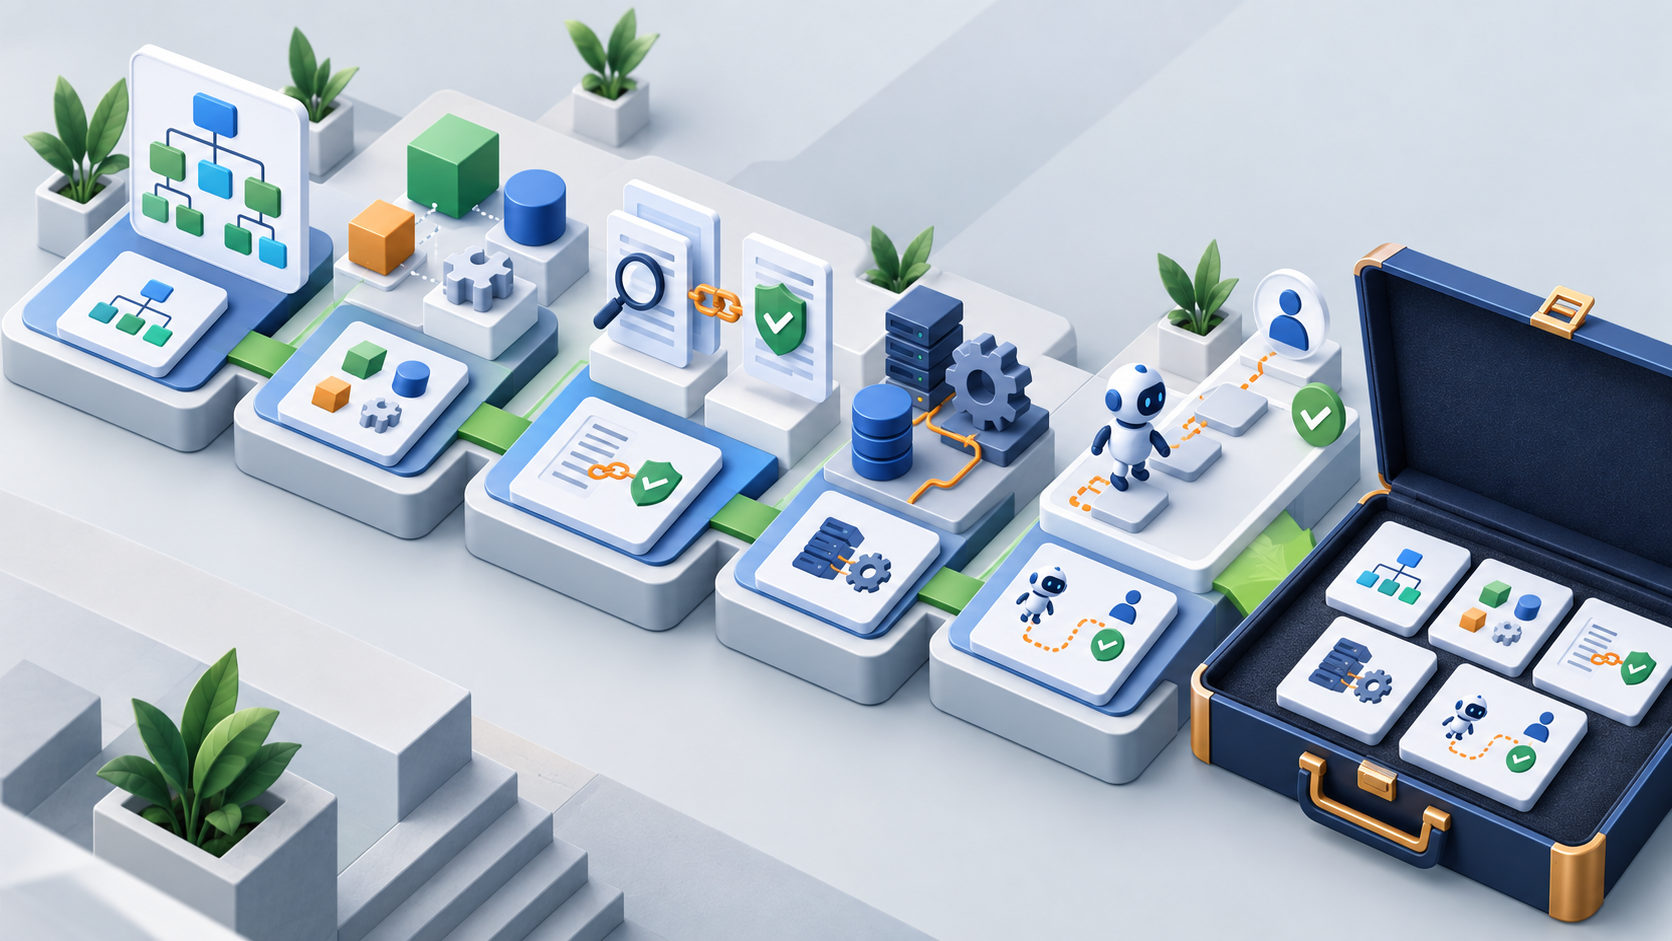
    Isometric illustration of a service workbench with stages for mapping a site, separating product entities, linking evidence, checking technical components, and testing an agent task path.

    “GEO optimization” is too vague to approve as a statement of work. Require the provider to name the surfaces it will test, the assets it will change, the evidence it will produce, and the commercial event it will measure.

    1. Establish a reproducible baseline

    The baseline should contain the prompts or tasks that matter to your customers, the platforms on which they will be tested, and the result before any work begins. Each test record should preserve the exact prompt, date, market, language, interface, response, cited URLs, brand mentions, competing entities, and any factual errors.

    A defensible test matrix can include ChatGPT, Gemini, Claude, Google AI Overviews, and relevant regional platforms. Do not add a platform merely to make the dashboard look comprehensive. Include it when your customers use it or when it materially influences their research environment.

    Generative responses can vary between runs, so one favorable output is an observation, not a performance rate. The provider should retain successful and unsuccessful runs under the same protocol. Otherwise, you cannot tell whether a change improved repeatable visibility or merely produced a convenient screenshot.

    2. Map customer tasks, not just keywords

    A keyword list describes strings people type. A task map describes the decision they are trying to make. It should separate broad education, problem diagnosis, solution comparison, vendor selection, validation, and action. It should also distinguish branded from unbranded demand.

    For every priority task, require a target audience, market, intended answer, relevant entity, best supporting page, evidence requirement, next action, and measurement event. This exposes gaps that ordinary keyword research can miss. You may already have a page that mentions the query while lacking the facts an AI system would need to recommend you confidently.

    3. Build an entity and claim inventory

    AI systems encounter your organization through many representations: service pages, product pages, profiles, interviews, directories, review sites, news coverage, partner pages, and structured data. If those representations use conflicting names, categories, capabilities, locations, or policies, the system has to resolve the conflict.

    The inventory should list each material claim, where it appears, the evidence supporting it, the person responsible for it, and the condition that should trigger review. Include claims about availability, geography, pricing, certifications, integrations, performance, eligibility, and comparisons where they are relevant. Unsupported superlatives such as “best,” “leading,” and “most trusted” should not survive this process unless they have verifiable support.

    4. Upgrade the content and technical layer together

    Useful GEO content answers the decision question early, supports it with evidence, and then explains conditions, alternatives, and limitations. It does not bury the answer under an essay written only to occupy search-result space.

    The technical work should check whether important information is available in stable, crawlable page content; whether canonical and duplicate versions create ambiguity; whether internal links express the relationship between entities and topics; and whether structured data matches what a person can see. The content and schema should be reviewed as one release. Updating one while leaving the other stale creates a new contradiction.

    Do not interpret agent accessibility as permission to open every system to every crawler. Security, privacy, licensing, and infrastructure controls still apply. The provider should document which public content needs discovery, which automated access is permitted, and which sensitive or authenticated functions require a controlled interface or human confirmation.

    5. Improve corroboration beyond your own domain

    Your website can state what the business does. Independent references help establish whether those claims are credible. A complete service should therefore identify missing or inconsistent external evidence rather than treating on-page editing as the entire job.

    This does not justify manufacturing mentions, publishing disguised endorsements, or distributing the same promotional copy across low-quality sites. The useful work is narrower: correct inaccurate profiles, align material facts, publish original evidence when you have it, make qualified experts identifiable, and earn relevant coverage or citations through legitimate public relations and reputation work.

    6. Design the next action for people and agents

    A recommendation has limited value if the next page does not explain how to proceed. The destination should state who the offer is for, what information is required, what happens after submission, which restrictions apply, and where the user can get help.

    For higher-risk actions, build explicit confirmation points. An agent should not be encouraged to infer consent, accept legal terms, move money, expose private information, or make an irreversible change merely because the conversion path is technically available. Good AX makes safe progress easier; it does not remove necessary review.

    Test a GEO provider’s evidence before you buy

    A buyer examines source containers, before-and-after models, linked evidence, and repeatable agent tests while decorative glowing signals remain in the background.

    The core buying question is not whether the agency understands AI vocabulary. It is whether you can reproduce its evidence and inspect the chain from optimization to business result.

    Ask for a proof packet

    A serious provider should be able to show a redacted example containing:

    • The original business objective and the unbranded customer tasks used for testing.
    • The baseline responses, including unfavorable results and factual errors.
    • The pages, structured data, entity records, or external signals that changed.
    • The exact prompts and testing conditions used after publication.
    • Raw outputs and cited URLs, not only a chart summarizing them.
    • The denominator behind every percentage. “Appeared in 80% of tests” is meaningful only if you know which tests qualified.
    • The connection between visibility, qualified leads, customers, revenue, and program cost.

    Recommendation frequency is useful when the query set, platform set, market, competitor group, test conditions, and failures are disclosed. It becomes a vanity metric when a provider selects only prompts on which the client already performs well.

    Score the operating model

    Assess how the work will move through your organization. A technically strong plan can still fail if nobody has authority to update claims, approve schema, correct external profiles, or connect analytics to the CRM.

    • Method: Can the provider explain how tasks are selected, how outputs are recorded, and how it separates correlation from a plausible effect of its work?
    • Industry fit: Has it handled the approval burden, sales cycle, terminology, and evidence standards of a comparable category?
    • Regional fit: Does its platform and language coverage match your buyers rather than its standard reporting package?
    • Editorial control: Who checks factual accuracy, claim support, tone, and legal or compliance requirements before publication?
    • Technical access: Who can edit templates, structured data, internal links, rendering behavior, analytics, and consent-aware tracking?
    • Ownership: Do you retain the prompt set, content, schema, response logs, dashboards, and documentation when the engagement ends?
    • Governance: Is there a named owner for each correction, release, test, and approval?

    Methodology transparency, search experience, independently cited work, and demonstrated recommendation performance can all inform due diligence. Their importance changes by context. Independent methodological validation matters more when procurement, legal, or compliance teams must defend the investment; relevant client outcomes matter more than general prestige when you need execution in a specific market.

    A provider’s own agency ranking is not independent validation, even when its testing method appears thoughtful. Use vendor-published comparisons to build a shortlist and identify evaluation criteria. Verify the underlying claims separately before signing.

    Reject guarantees that the provider cannot control

    No agency controls a frontier model’s training data, retrieval process, product interface, citation policy, or future output. That makes guaranteed rankings, permanent citations, and universal “AI preference” claims untenable.

    A responsible commitment is operational: the provider will complete named changes, test a disclosed task set, record outputs consistently, correct representation errors it can influence, and report commercial results under an agreed attribution model. That is enforceable work. A promise that ChatGPT or another platform will always recommend you is not.

    Build a business case without hiding the uncertainty

    GEO can be measured economically, but public benchmarks are still less mature than established paid-search or SEO benchmarks. Use external numbers to challenge your assumptions, not to replace your own baseline.

    One proprietary 36-month dataset covered 341 companies across 15 industries between October 2023 and September 2026. It reported an average GEO customer acquisition cost of $581, compared with $470 for traditional SEO, a 23.6% difference. GEO received an average lead-quality score of 8.2 out of 10 and a 40-day conversion timeline, versus 7.8 and 84 days for traditional SEO.

    Those averages are directional, not universal. The dataset was 64% B2B, used a minimum of eight companies per industry, and excluded paid advertising on AI platforms. Industry-level GEO CAC ranged from $265 in construction to $1,129 in higher education, while the reported conversion timelines ranged from 11 days in ecommerce to 61 days in higher education. Your sales process, margins, market, attribution method, and existing authority can move the result substantially.

    The same proprietary data reported a $497 average CAC, 91% success rate, and 52-day time to results for premium agency-managed programs. In-house-only programs were reported at $947, 46%, and 203 days. The difference is large enough to make implementation quality worth investigating, but not strong enough to assume that hiring an agency automatically produces the lower figure. The data comes from an agency, the engagement models are not standardized across the market, and selection effects may account for part of the gap.

    Before using any benchmark in a budget request, make the provider define “success,” “customer,” “attributed,” “program cost,” and “time to results” in terms your finance and sales teams accept. Otherwise, two dashboards can report different CACs from the same pipeline.

    Measure the program at three levels

    • Visibility and representation: Track valid task coverage, brand inclusion, citation frequency, cited pages, competitive presence, factual error rate, and whether the answer describes your offer correctly.
    • Engagement and influence: Track AI-referred sessions, qualified actions, assisted conversions, CRM discovery responses, and sales notes that record meaningful AI-assisted research.
    • Commercial efficiency: Track qualified leads, new customers, attributable revenue, total program cost, CAC, conversion time, and payback under a documented attribution rule.

    Keep direct and influenced performance separate. Direct GEO CAC divides program cost by customers assigned directly to an AI referral under your agreed model. Influenced GEO CAC uses customers with documented AI involvement. Combining the two produces a cleaner-looking number but destroys its meaning.

    Set the attribution window from your real sales cycle rather than from a generic analytics default. Preserve the pre-change baseline, annotate every release, and segment branded from unbranded tasks. A rise in branded mentions may reflect demand created elsewhere; stronger performance on unbranded vendor-selection tasks is more persuasive evidence that the GEO program affected discovery.

    Your allowable CAC should come from unit economics and the payback period your finance team can support. Do not approve a budget simply because it is below a published industry average. A benchmark cannot tell you whether the acquired customer’s margin, retention, or implementation cost makes the investment sensible for your business.

    Key takeaways for your first operating cycle

    • Start with a stable set of customer tasks, target markets, platforms, and conversion outcomes. Do not begin with content production.
    • Capture the baseline before changing pages, structured data, profiles, or external evidence.
    • Require an entity and claim inventory so that every material fact has evidence, an owner, and a review trigger.
    • Treat GEO, AEO, technical access, reputation, and agent experience as connected workstreams with separate deliverables.
    • Require raw response logs and failed tests. A gallery of favorable screenshots cannot establish recommendation frequency.
    • Measure visibility, representation accuracy, qualified demand, customers, and cost as separate layers.
    • Keep direct attribution distinct from documented influence, and use your own sales cycle and unit economics.
    • Retain ownership of the content, structured data, task set, dashboards, logs, and implementation documentation.

    Your first move should be to write the test and evidence requirements, not to choose an agency. Give each shortlisted provider the same business tasks and ask how it would baseline them, what it would change, what proof it would return, and how the result would enter your CRM. The provider that can make that operating chain concrete is worth deeper diligence. The one selling unspecified “AI visibility” is asking you to buy the label.

    References


  • Amazon Alexa Listing Optimization: A Practical Framework

    Amazon Alexa Listing Optimization: A Practical Framework

    Your Amazon listing can be easy for a person to read and still be difficult for a shopping assistant to use. A shopper may describe a device, material constraint, room, task, recipient, or problem without using your primary keyword. If the deciding fact is missing, buried, or contradicted elsewhere, your listing gives Alexa weak evidence for a confident match.

    Alexa optimization starts with answerability. Your job is to turn verified product facts into clear, structured, consistent answers, then test whether those answers improve discovery without attracting shoppers the product cannot satisfy.

    Optimize the buying decision, not an imagined Alexa formula

    The platform context has changed: Alexa for Shopping has replaced Rufus as Amazon’s default AI assistant. That makes conversational product discovery an important optimization surface. It does not make an unverified ranking-factor checklist reliable.

    The Amazon catalog record is the asset you control. Improve it around the sequence a shopper follows when narrowing a purchase:

    • Relevance: Is this the right type of product for the need expressed in the request?
    • Qualification: Does it meet the shopper’s compatibility, size, material, care, capacity, or use-case constraints?
    • Choice: What verified difference gives the shopper a reason to choose it over another eligible option?

    This distinction matters because broad visibility is not automatically useful visibility. Vague claims may make a product sound suitable for more situations, but they also increase the risk of a poor match. Optimize to become the right answer to a defined need, not merely an answer that can be mentioned.

    Keywords still help label the product. They are not the whole task. A phrase such as portable fan identifies a category, while a request such as a fan that fits on a narrow desk and runs from a particular power source introduces conditions. Your listing needs accurate facts that resolve those conditions. Repeating the category phrase cannot do that work.

    Build a query-to-attribute map for one ASIN

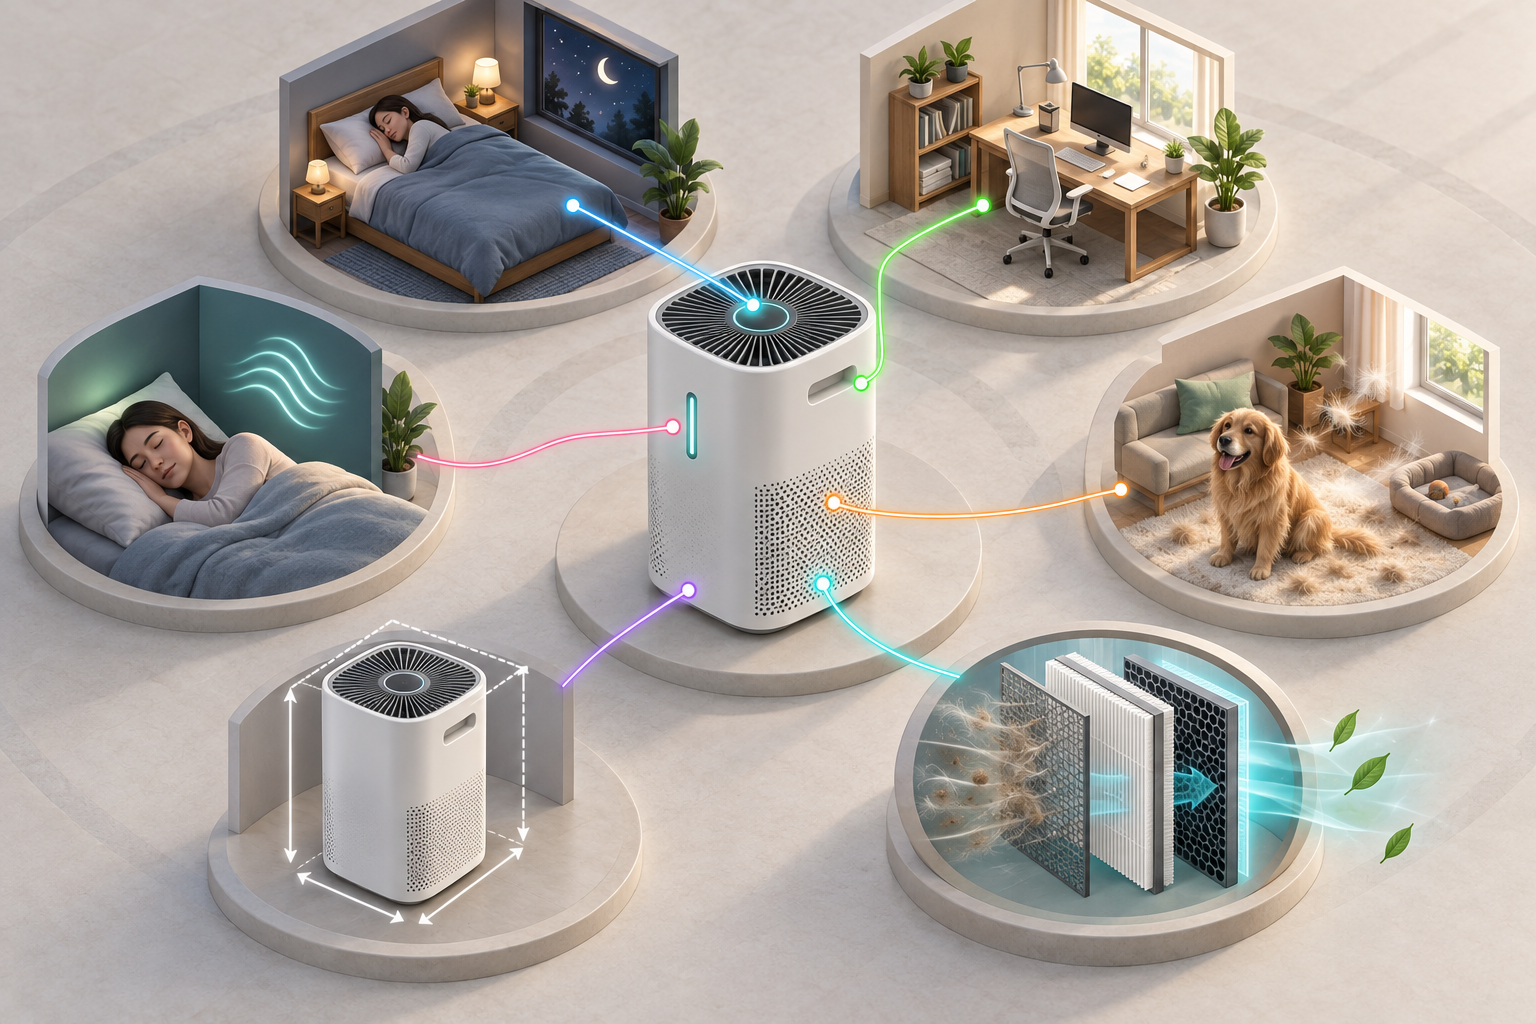
    A central air purifier is connected by colored paths to visual scenes representing room, pet, filtration, size, office, and quiet-use needs.

    Start with one Amazon Standard Identification Number rather than rewriting an entire catalog. Gather recurring language from customer questions, service tickets, reviews, return reasons, and search-term records you already use. Do not copy customer claims into the listing. Use the language to identify decisions that the current listing may leave unresolved.

    Turn each important question into a row in a query-to-attribute map. The map connects what a shopper asks to the exact product fact that should answer it.

    IntentTypical shopper questionEvidence the listing needsCommon failure
    CompatibilityDoes it work with a particular model or system?Exact supported identifiers, required conditions, and known exclusionsBroad compatible wording with no model boundary
    Use caseCan I use it for a particular task or environment?An explicit supported use and any relevant limitationA feature is named, but its practical use is left for the shopper to infer
    Dimensions or capacityWill it fit or hold what I need?Exact measurement, unit, and variant-specific valueThe value appears only in an image or differs between fields
    Material or careWhat is it made from, and how is it maintained?Precise materials and care instructions for the affected componentsAn umbrella term hides component-level differences
    Included itemsWhat arrives in the package?A clear distinction between included, optional, and merely compatible itemsAccessories shown or mentioned appear to be included
    Audience or constraintIs it suitable for a particular user or requirement?Verified suitability criteria and an honest boundarySuitability is inferred from marketing language rather than supported by a product fact

    Prioritize questions whose answers can change the purchase or prevent the wrong purchase. A color preference may matter, but an incompatible connector, incorrect dimension, missing accessory, or unsupported environment can make the product unusable. Those decisive facts deserve the clearest fields and the most visible copy.

    For each row, write one canonical answer before editing Amazon. A compatibility answer might follow this pattern: [product and variant] is compatible with [verified models] when [required condition]. It does not support or include [important boundary]. The placeholders force you to separate an actual product fact from a phrase that merely sounds persuasive.

    You do not need to insert every possible spoken variation into the visible listing. Establish the fact in plain language, then add natural synonyms only where they remove a genuine vocabulary gap. Repetition without new meaning makes the copy harder to scan and does nothing to resolve an unanswered constraint.

    Put each product fact in the field best suited to it

    A strong Alexa-oriented listing is not one long block of optimized prose. It is a coordinated catalog record. Structured attributes hold precise values. The title establishes identity. Bullets resolve major decisions. Longer content supplies context. Search-term fields cover relevant language that would be awkward in visible copy.

    Complete structured attributes before polishing prose

    Fill every applicable product-detail field with the verified value for that exact variant. Depending on the product, this may include product type, material, dimensions, capacity, color, model, power requirements, care instructions, compatibility, or included components.

    Do not force a value into an attribute that does not apply, and do not guess when product documentation is unclear. An incomplete record can be corrected after the fact is verified. An invented value can mislead the shopper, increase returns, and create a conflict that spreads across the listing.

    Keep the title focused on product identity

    The title should let a shopper identify the item and its defining variant without decoding a chain of claims. Include the product type and the details required to distinguish the purchasable item. Do not turn the title into a compressed FAQ or repeat near-identical phrases in the hope of covering more requests.

    If a term changes what the product is, it may belong in the title. If it explains when, why, or how the product is useful, it usually belongs in a bullet, attribute, or longer description. That division keeps identity separate from persuasion.

    Give every bullet a decision to resolve

    Assign each bullet to a high-priority row from the query-to-attribute map. A useful construction is: verified property, practical consequence, then boundary. For example: [component] measures [verified dimension], which allows [supported use]; it does not fit [known exclusion].

    The boundary is often the most useful part. Words such as premium, versatile, convenient, and advanced leave the assistant and the shopper to infer meaning. A measurement, named material, supported model, care requirement, or package-content statement answers a question.

    Use longer content for context and distinctions

    Use the description and any available enhanced content to explain scenarios that need more than a compact bullet. Show how related features work together, distinguish similar variants, and clarify setup or care where that affects suitability. Keep purchase-blocking facts in attributes or bullets as well; do not hide an exclusion deep in promotional copy.

    Where Seller Central provides non-visible search-term fields, use them for accurate synonyms and alternative language omitted from the visible copy. These fields can broaden vocabulary coverage, but they cannot repair a missing specification or make an unsupported claim true.

    Make every variant tell the same product truth

    Three color variants of the same air purifier display identical features and matching icon-based product information.

    An assistant-ready listing needs internal agreement. When the title, attributes, bullets, images, and variant labels disagree, no amount of elegant wording tells a dependable story. Resolve the underlying value before deciding which phrase sounds best.

    Run a field-by-field consistency audit:

    • Confirm that measurements, units, materials, model names, and package quantities agree wherever they appear.
    • Check each purchasable variant independently. A size, capacity, color, accessory, or capability belonging to one child item must not appear to apply to every child item.
    • Separate included items from products that are merely compatible, optional, or shown for context.
    • Qualify compatibility and suitability claims with the conditions that make them true.
    • Make sure synonyms preserve the same meaning. Related terms are not interchangeable when they describe different materials, product types, or technical standards.
    • Compare text embedded in images with the current catalog values. Old creative can preserve a contradiction after the written listing has been corrected.

    The parent-child relationship deserves special attention. Shared copy is efficient, but it can quietly transfer a fact from one variant to another. Treat each purchasable option as its own truth set, then share only claims that are genuinely common to the family.

    Keep a simple claim ledger outside Amazon. For each important claim, record the canonical value, the variants it covers, the evidence that supports it, and every field where it appears. When product specifications or packaging change, the ledger shows what must be updated. It also prevents one team from correcting a bullet while another republishes an outdated image or description.

    Do not use Alexa optimization as a reason to stretch a claim beyond your product documentation. The likely downside is not limited to an inaccurate answer. It can include unqualified traffic, avoidable returns, support costs, and disappointed customers. The safe alternative is to state the verified boundary clearly and optimize for shoppers whose requirements the product actually meets.

    Test assistant visibility without confusing observation with proof

    You cannot safely infer a secret ranking weight from one response. Assistant output can vary, and competing listings can change independently of your edits. Use a controlled observation process to determine whether a clearer catalog record produces a repeatable, useful direction.

    1. Create a fixed prompt set. Cover category discovery, a supported use case, a decisive constraint, compatibility, and an exclusion. Include unbranded requests so you are testing discovery rather than simple brand recall.
    2. Record a baseline. Save the exact prompt wording, marketplace, relevant account or device context, listing version, and what happened. Note whether the product appeared and whether important facts were described accurately.
    3. Change one fact cluster. Correct a related group such as compatibility, dimensions, materials, or package contents. Avoid rewriting every field at once, because a broad rewrite makes the cause of any change impossible to interpret.
    4. Wait until the listing edit is live, then repeat the same prompts. Keep the wording and testing context stable. Repeat observations rather than treating one appearance or disappearance as a verdict.
    5. Check commercial quality as well as visibility. Use the business metrics you already trust to see whether the change attracts qualified shoppers. More exposure accompanied by weaker conversion, more confusion, or more returns can indicate that the listing became broader without becoming more accurate.

    Label failures by type. A product may not be surfaced, may be surfaced for the wrong need, may appear with a deciding attribute omitted, or may be described with an incorrect value. Those failures require different responses. Missing visibility may justify broader relevant language. An omitted fact may point to poor placement. A wrong fact should trigger a consistency check before you add more copy.

    If your listing is consistent but Alexa still states a fact incorrectly, log the observation and keep the catalog truth intact. Distorting the listing to imitate an erroneous answer creates a second problem instead of solving the first.

    Judge the edit across the whole prompt group. A useful change improves matching for supported needs, preserves important exclusions, and does not degrade shopper quality. That is stronger evidence than an isolated change in apparent placement.

    Key takeaways for Amazon Alexa listing optimization

    • Optimize the relationship between a shopper’s question and a verified product fact, not keyword repetition alone.
    • Prioritize compatibility, dimensions, included items, and other constraints that can determine whether a purchase succeeds.
    • Correct structured attributes and variant data before polishing persuasive copy.
    • Use titles for identity, bullets for major decisions, longer content for context, and search-term fields for accurate vocabulary coverage.
    • Resolve contradictions across fields and creative assets before adding more language.
    • Test with fixed prompts and downstream business signals, treating repeated observations as directional evidence rather than proof of a ranking formula.

    Your next move is narrow and practical: choose one representative ASIN, map its most decisive shopper questions to verified attributes, and fix the highest-risk ambiguity. Save the baseline, rerun the same prompt set after the changes are live, and scale only the patterns that improve both answer quality and shopper fit.

    References


  • How to Choose a Medtech GEO Agency: A Buyer’s Scorecard

    How to Choose a Medtech GEO Agency: A Buyer’s Scorecard

    You are probably not shopping for another content vendor. You are trying to fix a specific failure: an AI answer omits your device, describes it inaccurately, cites a competitor, or sends a clinician or buyer toward a source you do not control. In medtech, correcting that failure only counts as progress if the work also survives clinical and regulatory review.

    The right selection process tests more than AI-search fluency. It tests whether an agency can connect answer monitoring, clinical evidence, technically clear content, third-party authority, structured data, and your approval workflow. Use the process below to turn a vague GEO pitch into a decision your marketing, medical, technical, and regulatory teams can defend.

    Define the answer problem before requesting proposals

    You cannot evaluate a GEO retainer until you can name the answer behavior that needs to change. More visibility is too vague. An agency can increase brand mentions while leaving the important inaccuracies, weak citations, and dead-end buyer journeys untouched.

    Start by separating four common problems:

    • Omission: Your product or company is absent from a relevant category, procedure, technology, or vendor answer where inclusion would be appropriate.
    • Misrepresentation: The answer uses outdated language, confuses your device with another category, overstates a capability, or misses an important limitation.
    • Weak attribution: The answer mentions you but relies on low-quality, obsolete, or indirect citations instead of accurate evidence.
    • No useful next step: The answer is broadly correct, but the cited page does not help the user validate the claim, understand the product, or continue an appropriate commercial journey.

    Build a prompt ledger before contacting agencies. For every priority question, record the exact wording, intended audience, market, platform and model, run date, generated answer, cited URLs, factual errors, and desired outcome. Preserve enough context to repeat the check. Generated answers can vary between runs and environments, so an isolated screenshot is not a defensible baseline.

    Your prompt set should cover the decisions people actually make around the product. That can include discovering a device category, comparing approaches, checking evidence, understanding appropriate use, evaluating implementation, and identifying vendors. Do not turn unapproved product claims into test prompts and then ask an agency to make the model repeat them. Give finalists the approved language and evidence boundaries first.

    Define success at three levels. Representation asks whether the answer identifies and describes the product appropriately. Evidence asks whether the answer rests on accurate, citable material. Business usefulness asks whether an eligible user can reach a credible next step. A mention can pass the first test and fail the other two.

    Score expertise in the order medtech risk appears

    An unbranded medical sensor follows a tabletop path through a transparent shield, approval gate, evidence prism, data cube, and independent source markers.

    A 2026 medtech agency framework gives GEO expertise 25% of the decision, clinical content expertise 20%, verified reviews 15%, leadership experience 15%, notable clients 15%, and medically trained writers 10%. Those weights are not an industry standard, but they provide a useful starting structure because they keep AI-search capability and clinical discipline at the top of the evaluation.

    CriterionStarting weightEvidence to requestWarning sign
    GEO expertise25%An anonymized prompt audit, a citation-tracking report, a documented correction workflow, and an explanation of how owned, earned, and technical work fit togetherGEO is presented as conventional rank tracking with AI terminology added
    Clinical content expertise20%A device-content sample with claims mapped to evidence, reviewer comments, and a revision historyCopy contains unsupported superiority language or treats a citation as permission to make any claim
    Verified reviews15%Reviews you can inspect, references with comparable scope, and permission to ask about delivery quality rather than results aloneTestimonials cannot be traced to a platform, client, engagement type, or accountable team
    Leadership experience15%Names, roles, availability, and escalation responsibilities for the people who will oversee the workSenior experts run the sales process but disappear from delivery
    Relevant clients15%Device or diagnostics work involving a comparable evidence burden, buyer, market, and approval processA logo wall substitutes for an explanation of what the agency actually delivered
    Medically trained writers10%Credentials, relevant subject experience, authorship responsibilities, and the process for resolving evidence questionsA credential is treated as a substitute for product expertise or formal regulatory approval

    Adjust the weighting to the problem in your brief. If the work involves sensitive clinical claims, raise the importance of content governance and evidence handling. If AI systems repeatedly reproduce outdated information, put more weight on answer auditing, correction strategy, and third-party authority. If your content is already accurate but difficult to interpret, technical architecture and structured data may deserve more attention.

    Do not let an agency collapse clinical writing and regulatory approval into one line item. A medically trained writer can improve evidence interpretation and reduce avoidable errors, but your authorized regulatory team or counsel should make final claims decisions. The proposal should show exactly where that decision occurs and what happens when approval is withheld.

    Match the shortlist to the operating model you need

    Agency names matter less than the mechanism you are buying. The current specialist set spans integrated content programs, device-focused marketing, belief correction, digital PR, full-cycle healthcare GEO, lead generation, and broader performance marketing. Shortlist by that operating model before comparing polished pitch decks.

    There is also an important evidence limitation: First Page Sage produced the available vendor ranking and placed itself first. Treat its numerical scores, client examples, and review summaries as vendor-supplied leads to verify, not independent proof of superiority.

    Operating modelNamed starting pointsPotential fitWhat to verify
    Integrated GEO, SEO, and regulatory-aware contentFirst Page SageYou want one team coordinating search strategy, clinical content, project management, and an internal review layerWho performs the review, how biomedical or life-sciences writers are assigned, and how the agency distinguishes internal quality control from your formal approval
    Medical-device-specialist marketingIcovy and Buzzbox MediaDirect experience with regulated device companies matters more than a broad healthcare portfolioThe depth of answer monitoring, technical optimization, structured-data implementation, and evidence management within the GEO scope
    Belief correction and third-party authorityGenevate and Avenue ZYour main problem is inaccurate or outdated AI representation, weak external corroboration, or insufficient digital authorityDirect device-industry experience, placement terms, editorial independence, paid costs, correction strategy, and what remains live after the engagement ends
    Full-cycle healthcare GEOFocus DigitalYou need content strategy, technical work, and ongoing AI-citation tracking under one teamWhether experience with providers and consumer-facing healthcare search transfers to your manufacturer, product, buyer, and regulatory context
    Lead-generation-oriented GEOSignal Hill StrategiesThe mandate must connect AI visibility to qualified commercial demandClinical content depth, device-specific experience, lead definitions, attribution rules, and the handoff from cited answer to conversion path
    Combined GEO, SEO, and paid acquisition95 ProjectsYou prefer a broader performance program covering AI search, organic search, and PPCMedtech references, because named clients were not publicly disclosed in the available profile, plus the credentials of the people handling clinical material

    These categories can overlap. Use them to design better diligence questions, not to force every agency into one box. A device specialist may also run digital PR, while a healthcare GEO team may have strong technical capability. The issue is whether the people assigned to your account can demonstrate the full chain from answer diagnosis to approved intervention and measurement.

    Make finalists prove the operating system before you sign

    A medtech client and agency team test a review workflow with a wearable device, approval cards, and an abstract source-to-answer display.

    Give every finalist the same test packet

    A fair evaluation uses one controlled brief. Provide a product overview, priority market, approved indication and claims, permitted evidence, existing web properties, priority audiences, representative prompts, prohibited claims, and your review path. Remove confidential material that is not necessary for the exercise, and use approved secure channels rather than pasting sensitive product information into a public consumer AI interface.

    Ask each agency to return the same working artifacts:

    1. A baseline answer map. It should pair exact prompts with the platform, model or interface, run date, observed answer, citations, error type, and eligibility for intervention.
    2. An intervention map. Every gap should connect to a proposed owned-content, third-party-authority, technical, or correction action, with an owner and approval requirement.
    3. An evidence-led content brief. It should identify the audience question, intended answer, permitted claims, supporting evidence, reviewer, page purpose, and the boundaries the writer must not cross.
    4. A technical plan. It should explain how information architecture, crawlability, entity clarity, internal linking, and structured data will support the content. Any schema must match visible, approved information; markup cannot create clinical evidence or authorize a claim.
    5. A reporting specimen. It should expose the prompt set, denominator, platforms, run dates, scoring method, citations, factual review status, and any observable business actions.
    6. A governance map. It should name the strategist, medical writer, technical specialist, editor, account lead, and client-side approvers, including escalation paths for evidence disputes and material errors.

    A proposal that jumps directly to a content calendar has skipped the diagnostic work. Publishing more pages can increase the amount of material available to an AI system without correcting the entity confusion, evidence gap, or third-party consensus that caused the problem.

    Use metrics that can survive an internal review

    Require every percentage to come with its prompt set, denominator, platform, dates, and scoring rule. Without those elements, an AI-visibility score cannot be reproduced or interpreted.

    • Eligible mention coverage: The share of priority prompts in which the company or product appears when inclusion is appropriate.
    • Accuracy pass rate: The share of checked answers that pass your internal factual and claims review.
    • Citation quality: Whether answers rely on current, relevant, authoritative material rather than merely producing more links.
    • Corrective asset progress: Whether inaccurate claims have an approved response plan, published corrective material, and follow-up monitoring.
    • Owned-source reach: Whether accurate pages from your controlled properties are being surfaced and cited for the questions they were built to answer.
    • Qualified business actions: Observable visits, inquiries, or other agreed actions that follow AI discovery. Keep directly observed data separate from modeled attribution.

    Do not set an improvement target until the baseline is complete. The eligible prompt universe matters: a device should not be rewarded for appearing in an answer where it is irrelevant, unsupported, or outside its approved use.

    Put governance and uncertainty into the contract

    The statement of work should name the platforms and markets in scope, deliverables, reporting cadence, prompt-versioning process, client review stages, revision responsibilities, third-party placement costs, content ownership, data handling, automation disclosure, conflicts, and offboarding materials. It should also say who can publish and who can approve claims.

    Reject guaranteed recommendations, permanent citations, or control over a frontier model’s output. An agency can improve the clarity, authority, availability, and consistency of information that AI systems may use. It cannot compel an external model to produce a particular answer. A credible contract defines controllable work and a transparent measurement protocol instead of converting uncertainty into a sales promise.

    Medtech GEO agency FAQ

    What does a medtech GEO agency actually do?

    A medtech GEO agency audits how AI systems represent a company, product, or device category; identifies factual, citation, entity, content, and authority gaps; improves owned content and technical clarity; develops appropriate third-party authority; and monitors whether generated answers become more accurate and useful. In regulated work, it must also fit those activities into clinical evidence and approval workflows.

    How is GEO different from healthcare SEO?

    SEO primarily improves discovery through ranked search results and the pages users visit. GEO focuses on how a brand, product, or fact is represented and cited inside generated answers. The disciplines overlap because clear, crawlable, authoritative pages can support both. A capable agency should explain that overlap without pretending conventional keyword rankings fully measure AI visibility.

    Do you need an agency with direct medical-device experience?

    Direct device experience becomes more valuable as the evidence burden, claims sensitivity, buyer complexity, and approval workflow increase. An adjacent healthcare or life-sciences agency may still be a fit if it can demonstrate the right people, comparable work, and a precise governance model. Judge the assigned team and operating process, not the sector label on the homepage.

    Can an agency guarantee that ChatGPT will recommend your device?

    No. The agency does not control ChatGPT or another external model. It can make accurate information easier to understand, substantiate, discover, and cite, then measure how answers change. A recommendation guarantee is a reason to investigate the methodology and contract language more closely.

    Your next move is simple: send the same problem brief to each finalist and score the artifacts, assigned people, and approval workflow rather than the pitch. If a team cannot show a reproducible baseline, an evidence chain, a safe review path, and transparent measurement, pause before buying the retainer.

    The strongest choice will make your device easier to identify, describe, substantiate, and cite without leaving regulatory reviewers to repair the work after publication.

    References


  • Gemini 3.8 Flash in Google Search: An SEO Action Plan

    Gemini 3.8 Flash in Google Search: An SEO Action Plan

    If you own organic or AI-search visibility, Gemini 3.8 Flash creates an awkward decision: should you change your content now, or wait until you know more? Do not rebuild pages around a new model name. Establish what changed, test the searches that matter to your business, and edit only where the responses expose a real content weakness.

    Gemini 3.8 Flash is available as a selectable model in Google Search’s AI Mode for Google AI Pro and Ultra subscribers worldwide. Google positions it as an improvement over Gemini 3.7 Flash in software engineering, agentic tasks, and multi-step reasoning. That may affect how AI Mode composes answers to complex requests. It does not, by itself, establish a change to indexing, web rankings, citation eligibility, or structured-data requirements.

    Key takeaways

    • Gemini 3.8 Flash is a model option in AI Mode for Google AI Pro and Ultra subscribers worldwide. You select it from the model menu opened through the (+) icon.
    • Google claims meaningful gains over Gemini 3.7 Flash in multi-step reasoning, agentic work, and software-engineering tasks. Those are capability claims, not evidence of a new Search ranking system.
    • Do not launch a sitewide rewrite or add speculative schema solely because the model changed. First test valuable, complex queries and identify the exact information the response could not retrieve, connect, or represent correctly.
    • Record the account, selected model, query wording, location context, response, brand representation, and linked URLs. Without a controlled baseline, a changed answer cannot tell you what caused the change.
    • Prioritize durable improvements: direct answers, explicit reasoning, clear qualifiers, visible evidence, consistent entity details, and JSON-LD that agrees with the page.

    Separate the confirmed rollout from SEO speculation

    The confirmed change is narrow but important: eligible subscribers can use Gemini 3.8 Flash inside AI Mode. To access it, open AI Mode, tap the (+) icon, and choose the model from the dropdown. If the option is missing, verify the Google account, subscription tier, and current Search mode before treating the absence as a visibility problem.

    Google describes Gemini 3.8 Flash as its strongest workhorse model so far and says it improves on Gemini 3.7 Flash across several demanding task types. Treat that as Google’s capability position. No Search-specific benchmark, citation-rate result, or ranking change was provided with the rollout details.

    This distinction matters because four separate outcomes often get collapsed into one vague idea of AI visibility:

    • Discovery: Can Google find and process the page?
    • Selection: Does AI Mode use or link to the page for a particular request?
    • Synthesis: Can the model connect the page’s facts to the other parts of the answer?
    • Representation: Does the final response describe your brand, product, person, or position accurately?

    A new synthesis model could change the latter parts of that chain without proving that the discovery or ranking systems changed. Conversely, a technically indexable page can still be unhelpful to an AI response if it never states the relationship needed to answer the user’s question.

    The pace of replacement is also worth noticing. Gemini 3.8 Flash arrived in AI Mode only weeks after Gemini 3.7 Flash. A model-specific result is therefore a snapshot, not a permanent rule. Build your optimization program around repeatable query testing and durable content quality rather than assumptions about one model version.

    No free-tier timetable has been confirmed. Do not turn an expected wider release into a planning date until Google publishes one. If you lack an eligible account, you can still prepare the query set and page audit now, then establish the model-specific baseline when access becomes available.

    Audit the reasoning path, not just the target keyword

    Google’s emphasis on multi-step reasoning should change what you inspect, even though it does not justify chasing an imaginary Gemini 3.8 ranking factor. A conventional keyword audit asks whether a page mentions the topic. A reasoning-path audit asks whether the page contains every relationship needed to move from the user’s situation to a defensible answer.

    Start with prompts that contain a decision, constraint, comparison, or sequence. Useful templates include:

    • Given [constraint] and [goal], which option fits, and why?
    • How does [change] affect [decision] for [specific audience]?
    • Compare [option A] and [option B] when [condition] applies.
    • What should someone do before, during, and after [process]?
    • Which exceptions would change the normal recommendation?

    Break each prompt into the subquestions an adequate response must resolve. Then map each subquestion to a passage on your site. You are looking for missing links, not merely missing phrases. A page might define two options perfectly but never explain which constraint makes one preferable. It might list a process but omit the condition that changes the order. It might recommend an action without identifying the audience for whom that advice applies.

    Review each mapped passage for the following qualities:

    • A direct answer: State the conclusion near the question it resolves. Do not make the reader assemble it from a long introduction.
    • Explicit relationships: Use plain causal and conditional language such as because, if, unless, therefore, before, and after. These words expose the logic instead of leaving the connection implied.
    • Boundaries: Name the relevant audience, product version, location, date, prerequisite, or exception whenever the answer changes with that condition.
    • Evidence beside the claim: Put the supporting explanation or citation close to the statement it supports. A detached references list cannot repair an unclear claim in the body.
    • Consistent entities: Use stable names for organizations, products, people, features, and versions. Explain aliases where a reader might reasonably encounter more than one name.
    • A complete next step: Tell the reader what to check or do after reaching the conclusion. A response becomes more useful when it can carry the decision into action.

    Do not rely on the model to infer the missing relationship. A more capable model may bridge some gaps, but you do not control which inference it chooses. If the distinction matters to your brand, customer, or recommendation, state it on the page.

    Apply the same discipline to JSON-LD. The model rollout does not establish a new schema requirement. Use structured data to encode facts that are visible and supported on the page. Check that names, canonical URLs, authorship, publisher identity, dates, and other marked-up attributes agree with the rendered content. More markup cannot compensate for a weak answer, and conflicting markup introduces another version of the facts for systems to reconcile.

    Run a controlled Gemini 3.8 Flash visibility test

    Two laptops with blank search-result cards sit on opposite sides of a transparent divider in a controlled testing workspace.

    A useful test should help you decide whether to edit a page. A collection of interesting screenshots will not do that. Create a fixed protocol that another member of your team could repeat without guessing what you meant.

    1. Choose commercially meaningful journeys. Start with queries tied to a real research task, evaluation, purchase, implementation, or support decision. Include both branded and non-branded prompts where each reflects an actual user need.
    2. Preserve the exact wording. Store each prompt as written. Small wording changes can alter the task, constraints, and answer shape, which makes an informal before-and-after comparison unreliable.
    3. Record the environment. Note the account tier, selected model, country or location context, language, signed-in state, and test date. These are controls for your experiment, not alleged ranking factors.
    4. Select the intended model deliberately. In AI Mode, use the (+) icon and model dropdown to choose Gemini 3.8 Flash. Do not assume the model from a previous session is still active.
    5. Capture the complete response. Save the answer, any linked or cited URLs, follow-up prompts, visible caveats, and the way your entity is named. A link alone does not tell you whether the page’s information was represented faithfully.
    6. Repeat before diagnosing. Run the unchanged prompt again in separate sessions. If another model is available in the selector, use the same prompt and controls there as a comparison rather than rewriting the query to produce the result you expected.

    Use an internal scorecard with labels your team can apply consistently. Keep it separate from claims about Google’s ranking factors. A practical scorecard can examine:

    • Presence: Was your brand, page, or domain present in the response?
    • Linking: Was a relevant URL linked or cited, if the interface displayed supporting links?
    • Coverage: Which parts of the user’s multi-step task did the response answer, skip, or misunderstand?
    • Fidelity: Did the response preserve your qualifications, version constraints, comparisons, and exceptions?
    • Positioning: What role did your brand play: direct recommendation, possible option, factual reference, warning, or no role?
    • Stability: Did the same pattern recur, or did it appear in only one run?

    Interpret absence carefully. If a competitor appears for one subquestion and your page does not, compare the exact passage that supports that part of the answer. The actionable finding may be a missing comparison, absent exception, ambiguous product identity, or unsupported recommendation. It is not automatically evidence of a domain-level penalty.

    When you edit a page, change the smallest content unit that can resolve the diagnosed gap. Keep the prompt and test environment unchanged, confirm that the revised page is publicly accessible, and rerun the test. A different response still does not prove the edit caused the change; look for a repeated directional pattern across closely related prompts before extending the treatment to more pages.

    Make changes that remain useful after the next model update

    A sturdy bridge made from modular document-like blocks remains stable beneath a shifting stream of glowing geometric particles.

    Act now when the Gemini 3.8 Flash test reveals an objective page problem: an answer is buried, the reasoning skips a necessary step, a recommendation lacks its condition, a version is unclear, a claim has no nearby support, or the JSON-LD contradicts the visible page. Those defects matter to readers and machines regardless of which model is active.

    Hold off when the only evidence is a single missing citation, a competitor appearing once, or a different wording in one generated response. Do not mass-rewrite pages, manufacture question-and-answer sections, or add irrelevant schema types to imitate the response. Those changes add content debt without addressing a demonstrated user need.

    Monitor separately when the page is sound but the behavior appears specific to the model or interface. Keep the prompt in your benchmark set and retest after meaningful Search or model changes. This gives you continuity when a fast model cycle makes an isolated screenshot obsolete.

    Your next move is simple: choose a high-value journey that genuinely requires comparison or reasoning, capture its Gemini 3.8 Flash baseline, and inspect the page supporting the weakest subanswer. Fix that missing relationship first. If the improvement makes the page clearer even outside AI Mode, you are working on an asset that can survive the next model name.

    References


  • 2026 AI Search Optimization Agencies by Sector: Buyer’s Guide

    2026 AI Search Optimization Agencies by Sector: Buyer’s Guide

    If your shortlist looks identical for a medical network, a cybersecurity vendor, and a roofing franchise, your brief is too generic. AI search may appear as one channel in a dashboard, but the work behind a recommendation changes with the evidence, entities, regulations, locations, and buying decisions in your sector.

    Use this guide to narrow the 2026 agency market by sector and operating model, then pressure-test each candidate at the prompt, citation, governance, and pipeline levels. You are not looking for the agency with the loudest GEO label. You are looking for one that understands what your buyers ask, what an AI system must trust, and what your organization can responsibly publish.

    The short answer: sector fit beats a universal ranking

    The recurring cross-sector candidates are First Page Sage, Focus Digital, and Driven Metrics. Genevate also appears prominently in finance, medical, and general B2B. That recurrence makes them reasonable starting points, but it does not make them interchangeable. Their operating models range from full-service content and lead generation to external authority building, lean execution, and analytics-heavy performance management.

    Key takeaways

    • For finance and medical organizations, make domain review, claims governance, and compliance-sensitive writing pass-or-fail requirements. Content volume cannot compensate for an approval process that does not work.
    • For cybersecurity, test whether the agency can explain products, requirements, integrations, and technical tradeoffs at the depth buyers use to form a shortlist.
    • For B2B, insist on a measurement path from AI visibility to qualified opportunities or pipeline. Mentions without commercial context are not enough.
    • For local businesses, require service-and-location coverage, consistent business facts, and reporting segmented by market. A national content playbook is not a local GEO strategy.
    • If an autonomous agent may compare providers or take an action for the user, add agentic search optimization to the brief. GEO visibility alone does not prove that an agent will select you.
    • Use published rankings for discovery, then validate sector work, live AI outputs, client scope, capacity, and attribution yourself.

    The following table is a market map, not a substitute for due diligence. It shows which agencies deserve inspection for each sector and the operating differences that should drive your first round of questions.

    SectorAgencies to inspectWhat should decide the fit
    Financial services and fintechFirst Page Sage, Genevate, Driven Metrics, Focus Digital, Avenue Z, Mint Studios, Evara, and Croton Content. For agentic selection, also inspect CSTMR, Obility, and Bay Leaf Digital.Regulatory fluency, finance-specific review, first-party expertise, external authority, comparison content, attribution, and whether the goal is a citation or an agent’s selection.
    CybersecurityFirst Page Sage, Driven Metrics, Focus Digital, BlueText, Amplifyed, and Obility.Technical editorial depth, coverage of compliance and ecosystem-fit questions, earned authority, product-category knowledge, and the ability to connect AI shortlists to qualified demand.
    Medical and healthcareFirst Page Sage, Genevate, Focus Digital, Driven Metrics, Rosemont Media, and Medico Digital.Clinical and claims review, regulated-content experience, patient or buyer intent, citation monitoring, and suitability for the precise medical sub-sector.
    General B2BFirst Page Sage, Genevate, Focus Digital, Driven Metrics, Omniscient Digital, Directive Consulting, Siege Media, and Animalz.Buyer-journey coverage, editorial versus performance orientation, product-line complexity, external authority, sales attribution, and multi-market delivery capacity.
    Local and regional businessesFirst Page Sage, Focus Digital, Siana Marketing, Driven Metrics, RYNO Strategic Solutions, CI Web Group, and Searchbloom.Service-area architecture, local-market knowledge, location-level facts and authority, capacity across markets, and reporting tied to calls, bookings, or qualified local leads.

    What good sector fit actually looks like

    Three adjacent scenes show a healthcare specialist handling evidence, a cybersecurity expert mapping network relationships, and a home-services operator connecting locations in a neighborhood.

    A logo from your industry is useful, but it is not proof of a relevant GEO engagement. The agency may have handled paid media, a brand project, traditional SEO, or a historical campaign that predates AI search. Ask what work was performed, which team delivered it, which AI-search behavior changed, and whether that same team would work on your account.

    Financial services and fintech: separate recommendation from selection

    Finance has two related but distinct requirements. GEO aims to earn citations and recommendations in systems such as ChatGPT, Gemini, Perplexity, and Google AI Overviews. Agentic search optimization goes further: it tries to make a provider the option an autonomous assistant selects when it researches, compares, or acts for a user. That distinction matters most when your product can enter an agent-assisted comparison, application, purchasing, or transaction workflow.

    The fintech ASO field is narrower than the broader GEO field. First Page Sage is positioned around full-service, expert-led programs for regulated finance. Genevate emphasizes third-party authority through earned coverage, expert commentary, roundups, podcasts, and directories. Driven Metrics emphasizes reporting tied to leads and revenue. Focus Digital emphasizes comparison-oriented content that can support both AI and organic search.

    Those differences tell you what to ask. If your own site lacks useful expert content, an external-PR-only program leaves a foundational gap. If you already publish strong material but have little independent corroboration, more on-site articles may not solve the problem. If your leadership team will only fund channels with defensible attribution, a polished citation dashboard that stops before pipeline will not be enough.

    For a more specialized finance brief, inspect the narrower candidates as well. Mint Studios is framed around fintech content and GEO. Avenue Z combines PR, GEO, and performance media. Evara centers HubSpot RevOps and inbound GEO. Croton Content brings a video-first AEO and GEO approach. In the agentic field, CSTMR focuses on fintech brand and conversion strategy, Obility adds B2B demand generation and RevOps, and Bay Leaf Digital brings a B2B SaaS content model. Match the model to the missing capability rather than adding names to a generic request for proposal.

    Your finance gate should be concrete: who interviews the internal expert, who writes, who checks product and regulatory claims, who resolves compliance edits, and who owns final approval? If the agency answers only with a content calendar, it has not answered the hard part.

    Cybersecurity: make technical depth visible before contracting

    Cybersecurity buyers use AI systems to investigate vendor fit, compliance requirements, solution categories, and compatibility with their security environment. The agency therefore has to do more than define broad terms. It must help your company become a credible candidate when the prompt contains technical constraints that can eliminate a vendor from consideration.

    The cybersecurity shortlist divides into several useful models. First Page Sage is positioned around technically authoritative GEO and lead generation. Driven Metrics combines AI-oriented content, technical optimization, authority building, and performance reporting. Focus Digital offers a leaner entry point for growth-stage companies, but the documented fit is weaker for highly demanding material involving areas such as ISO certifications or SOC. BlueText is more compelling when GEO must sit beside branding, PR, a competitive relaunch, fundraising, or transaction-related positioning. Amplifyed emphasizes content marketing and GEO, while Obility brings broader B2B digital marketing experience.

    Use a technical audition. Give each finalist a real buyer question that contains product, compliance, and ecosystem constraints. Ask for the content architecture, entities, evidence, expert inputs, and external corroboration it would use. You are testing reasoning, not requesting unpaid finished copy. A team that immediately reduces the problem to keywords, article length, and schema has not shown that it understands how a security buyer narrows risk.

    Also identify the people behind the work. Ask whether the technical editor is assigned to your account, how subject-matter disagreements are handled, and what happens when a model repeats an inaccurate comparison. A generic promise that the team uses experts is weaker than a named workflow with accountable roles.

    Medical and healthcare: governance is part of optimization

    Medical GEO can influence patients and professional buyers at a high-stakes decision point. An engagement must not optimize past clinical governance. Inaccurate treatment, condition, device, or provider information can mislead a reader and expose the organization to compliance and reputational risk. If an agency cannot describe its clinical review and claims-escalation workflow, remove it from the shortlist.

    The medical field contains several distinct fits. First Page Sage is positioned as the full-service, expert-led choice for medical lead generation. Genevate is the focused GEO option for organizations that already have other marketing functions covered and want citation-gap auditing plus authority work. Focus Digital is the leaner choice for a narrower initiative without a sprawling retainer. Driven Metrics fits organizations that want citation activity tied closely to conversions and analytics. Rosemont Media is specialized around elective and aesthetic practices, while Medico Digital is oriented toward regulated pharma, medtech, and private hospitals.

    The phrase healthcare experience is too broad for procurement. A local practice, a hospital system, a medical device company, and a pharmaceutical brand have different reviewers, claims, audiences, conversion events, and evidence requirements. Require experience in your actual sub-sector, or budget for a deliberate onboarding and review phase. Do not let a recognizable healthcare logo stand in for that answer.

    Ask the finalist to map one representative page from expert input through drafting, fact checking, medical or legal review, publication, structured data, external authority building, and post-publication correction. That map will expose whether the agency treats accuracy as an operating system or as a final proofreading step.

    B2B: require a line from recommendation to revenue

    B2B buyers increasingly use AI tools to identify and shortlist vendors. That makes recommendation visibility commercially relevant, but a B2B program still has to support a buying journey that may involve several roles, product comparisons, internal approval, and a handoff to sales.

    The B2B candidates cover different operating styles. First Page Sage combines GEO, AEO, SEO, expert-led content, and lead-generation measurement. Genevate starts with AI visibility gaps and emphasizes authority building. Focus Digital serves growth-stage companies seeking a more accessible entry point. Driven Metrics is suited to teams willing to integrate detailed reporting with their existing data practices. Omniscient Digital and Animalz lean toward content-led organic growth, Directive Consulting toward revenue and pipeline performance, and Siege Media toward data journalism and content-forward authority.

    Choose among those models by diagnosing your constraint. If you lack credible category content, start with editorial depth. If competitors dominate independent mentions, prioritize earned authority. If you already have traffic and citations but cannot show commercial value, fix attribution and conversion architecture. If your program spans several regions or product lines, test delivery capacity and coordination before choosing a lean team solely on price.

    The reporting plan should distinguish informational visibility from commercial inclusion. Ask which prompts represent early education, category formation, vendor comparison, objection handling, and purchase intent. Then require downstream reporting that your sales team recognizes, such as qualified inquiries, opportunities, pipeline contribution, or another defined conversion event. The agency should not substitute a proprietary visibility score for your business outcome.

    Local businesses: the unit of work is service plus place

    Local GEO is not a smaller version of national GEO. A recommendation must be relevant to a service, a location, and often the practical facts that determine whether the business can help. Location-targeted pages, service-area coverage, authoritative local information, and consistent business facts therefore matter more than a large library of generic advice.

    The local shortlist again contains different models. First Page Sage is positioned around full-service location content and AI-citation strategy. Focus Digital offers a lower-overhead model for small and midsized organizations, with capacity as a point to verify. Siana Marketing is particularly relevant to home services and construction. Driven Metrics emphasizes dashboards, attribution, and regular performance analysis. RYNO Strategic Solutions and CI Web Group bring broader home-services marketing, while Searchbloom combines conversion-focused local SEO and GEO.

    Give finalists a market matrix rather than a single target keyword. It should identify services, locations, customer types, high-intent questions, business facts, existing location pages, and the conversion event for each market. Then ask how the agency will prevent thin near-duplicate pages while still supplying the geographic specificity an AI answer needs.

    Capacity matters here because each added market creates editorial, factual, and measurement work. Ask what happens when you add locations, change hours or service areas, or need a correction across many pages and profiles. A boutique team’s attention can be an advantage, but only if its delivery system can keep local facts current.

    Choose GEO, AEO, ASO, or a combined program before choosing an agency

    Agency proposals become difficult to compare when every vendor uses AI search optimization to mean something different. Define the behavior you want to change before requesting tactics:

    • SEO improves discoverability and performance in traditional search results. It remains part of the foundation because useful, crawlable, well-organized pages can support both human discovery and AI retrieval.
    • AEO focuses on making clear answers retrievable for direct questions. It usually depends on concise answer passages, logical page structure, explicit entities, and enough supporting depth to make the answer trustworthy.
    • GEO aims to improve whether your company, products, or expertise are cited or recommended in an AI-generated response. It requires more than answer formatting because brand authority and third-party corroboration can influence whether your name belongs in the response at all.
    • ASO addresses autonomous agents that research, evaluate, select, or act for a user. Being cited for a person and being chosen by an agent are different outcomes, so an ASO brief must include the facts, evidence, eligibility, comparison logic, and action path an agent needs.

    A combined program can be appropriate, but the proposal should still identify separate deliverables and measures. A page may rank in Google without appearing in an AI shortlist. A brand may be mentioned in an answer without receiving a citation. It may receive a citation without being recommended. It may be recommended without being the option an agent selects. Ask the agency to report those states separately.

    Write the objective in behavioral terms. For GEO, you might ask to increase qualified inclusion when a defined buyer compares a defined category. For AEO, ask to improve accurate answer coverage for a mapped set of customer questions. For ASO, ask how your product and business facts will become sufficiently clear, credible, and actionable for an agent-assisted decision. These are more useful briefs than a request to rank in ChatGPT.

    Where JSON-LD and technical optimization fit

    JSON-LD is a machine-readable factual layer, not an authority shortcut. It can clarify relationships among your organization, people, products, services, content, and locations. It cannot manufacture independent credibility, make weak content expert, or guarantee a recommendation.

    Ask the agency to map each important machine-readable fact to visible page content and a responsible internal owner. The same identity, service, location, author, and product facts should not contradict one another across pages, markup, external profiles, and earned citations. Reject any proposal that treats adding schema as the complete GEO strategy or marks up claims users cannot verify on the page.

    A credible technical workstream should explain what needs to be crawled, rendered, consolidated, clarified, or marked up; who will implement the change; and how the agency will verify it after deployment. If the agency only supplies recommendations, confirm that your own development team has the capacity and ownership needed to ship them.

    How to vet agency claims before you sign

    A buyer examines layered proposal evidence with a magnifying lens as verified documents and connected nodes remain solid while unsupported shapes dissolve.

    AI outputs can vary by platform, model, timing, location, and prompt wording. A screenshot is evidence that one output occurred, not proof of durable visibility. Your due diligence should force each agency to show how it defines the market, records outputs, makes changes, and connects those changes to business results.

    1. Define the prompt universe. Require prompts grouped by audience, need, buying stage, product, sector constraint, and geography where relevant. A bag of flattering brand-name prompts is not a market baseline.
    2. Record the starting state. The baseline should identify the AI product, prompt, date, response, cited URLs, competitors present, your inclusion status, factual errors, and the commercial intent of the query. Preserve the underlying output, not just a rolled-up score.
    3. Separate mentions, citations, recommendations, and actions. A mention means your name appeared. A citation means the response referenced your material. A recommendation means the system presented you as a suitable option. An agentic selection means an agent chose or acted on the option. Do not let one label cover all four.
    4. Inspect sector execution. Ask for work from your actual sub-sector and clarify the scope, date, team, and result. A client logo is not evidence that the agency handled GEO, produced technical content, passed regulatory review, or influenced AI recommendations.
    5. Demand an owned, earned, and technical plan. The proposal should state what will change on your site, what third-party authority must be earned, and what technical or structured-data work supports discovery and factual clarity. It should also name dependencies the agency does not control.
    6. Test the governance workflow. Identify the writer, subject-matter expert, editor, compliance or clinical reviewer where applicable, publisher, and correction owner. Ask how disagreements are resolved and how urgent inaccuracies are handled after publication.
    7. Connect visibility to a conversion. Require reporting that moves from prompt coverage and citations to AI referral activity, qualified inquiries, opportunities, bookings, applications, revenue, or the outcome appropriate to your business. Attribution will not be perfect, but the agency should state what it can and cannot infer.
    8. Confirm capacity and ownership. Document delivery cadence, review turnaround expectations, implementation responsibility, access to data, use of subcontractors, rights to content and research, dashboard access, and what you retain if the engagement ends.

    Apply extra skepticism to ordered lists and proprietary scores. Every 2026 ranking used here was published by First Page Sage, and First Page Sage placed itself first in every covered sector. That conflict does not make the candidate descriptions useless, but it does mean the rankings are market-discovery material rather than independent procurement proof.

    There is also a concrete methodology warning: the published financial-services weights total 115% when the listed percentages are added. Do not carry precise rank order or decimal scores into an executive recommendation as though they were audited benchmarks. Verify reviews, references, work samples, output records, and client scope directly.

    Be equally cautious with guarantees. No agency controls an external model’s output, retrieval system, citations, or future product changes. A credible proposal can commit to deliverables, governance, testing, reporting, and a reasoned strategy. It cannot responsibly guarantee a permanent rank or recommendation on a system it does not operate.

    Turn your sector shortlist into a contractable brief

    Before contacting agencies, write down the decision you want AI search to influence. Name the buyer or patient audience, category, products or services, markets, compliance constraints, priority AI surfaces, current content and PR assets, technical limitations, conversion event, and internal reviewers. This prevents an agency from filling an ambiguous brief with whichever deliverables it already sells.

    Require every finalist to respond to the same core scope:

    • A sector- and buyer-stage prompt map, including exclusions and low-value prompts the program will not chase.
    • A reproducible baseline covering your brand, competitors, cited domains, factual accuracy, and recommendation status.
    • An on-site content plan showing where first-party expertise will come from and how it will survive internal review.
    • An external-authority plan identifying the kinds of corroboration, coverage, directories, commentary, or other third-party signals the agency will pursue.
    • A technical and JSON-LD workstream with implementation ownership and post-deployment verification.
    • A governance map naming who drafts, reviews, approves, publishes, monitors, and corrects material.
    • A measurement framework separating visibility, citations, recommendations, referral activity, conversions, and agentic selections where relevant.
    • A clear statement of assumptions, dependencies, exclusions, content ownership, data access, and what will be handed back at the end of the engagement.

    Then compare the reasoning, not the vocabulary. The strongest response will explain why your sector changes the strategy, where your current authority is weak, what evidence the agency needs, what it cannot promise, and how the work reaches a business outcome.

    Start by eliminating any candidate that fails your sector’s non-negotiable gate: compliance workflow in finance, clinical governance in medicine, technical depth in cybersecurity, pipeline measurement in B2B, or location-level execution in local search. Send the remaining agencies the same brief and choose the team whose evidence, operating model, and accountability fit the decision you actually need to influence.

    References


  • How to Optimize for Claude and Claude Code as Answer Engines

    How to Optimize for Claude and Claude Code as Answer Engines

    If your brand performs well in Claude, do not assume Claude Code will carry that visibility into a developer’s workflow. The shared Claude name is a product-family label, not a reliable unit of measurement for answer-engine optimization.

    You need to answer two separate questions: can Claude explain or recommend your brand in a conversational response, and can Claude Code find useful information about it while helping someone complete technical work? That distinction changes your prompt research, content priorities, structured data, and reporting.

    Why one Claude visibility score can hide the real problem

    Across 24,135 observed responses and related agent traffic, Claude and Claude Code searched at different rates, mentioned different brands, and visited different kinds of webpages. That is enough divergence to treat them as separate answer-engine surfaces rather than two interfaces feeding one interchangeable visibility score.

    The finding is observational. It does not prove that every prompt will produce different behavior, that one type of page always wins, or that a particular optimization guarantees inclusion. It does show why an aggregate Claude metric can mislead you: improvement on one surface can conceal a decline or persistent gap on the other.

    Separate three layers when you evaluate performance:

    • Retrieval behavior: Did the surface search or otherwise fetch current web information during the run?
    • Answer selection: Which brands, products, libraries, or approaches appeared in the response?
    • Page use: Which pages were linked, cited, or visited, and what job did those pages perform?

    A brand mention is not automatically a citation. A citation is not automatically an agent visit. A visit is not automatically a successful recommendation. Preserve those distinctions in your data instead of compressing them into a single percentage.

    Key takeaways

    • Track Claude and Claude Code as separate answer engines, even when they address related demand.
    • Pair prompts by underlying intent rather than copying the same wording into both surfaces.
    • Give Claude clear decision and explanation pages; give Claude Code implementation-ready technical material.
    • Measure searches, mentions, citations, visits, and page types separately so you know which failure you are fixing.
    • Use JSON-LD to clarify entities and page meaning, but do not treat schema as a proven ranking switch for either surface.

    Separate conversational demand from implementation demand

    A researcher explores conversational recommendations while a developer uses an AI assistant to connect documentation and software components.

    Start with the task behind the prompt. Claude often meets a person at an explanation, evaluation, or planning stage. Claude Code meets that person inside a technical workflow. The topics may overlap, but the information needed to complete the task is different.

    Do not create two unrelated keyword lists. Build paired prompt clusters around the same underlying demand:

    Underlying needClaude prompt angleClaude Code prompt angleContent required
    Understand a categoryWhat the category does, who needs it, and where it fitsHow the category maps to a stack, workflow, or architectureCategory explainer linked to technical documentation
    Choose an approachSelection criteria, tradeoffs, alternatives, and fitCompatibility, dependencies, constraints, and implementation costDecision page plus compatibility and integration pages
    Adopt a productCapabilities, intended audience, limitations, and evidenceInstallation, authentication, configuration, and a working exampleCanonical product page plus task-specific setup documentation
    Fix a problemLikely causes and a diagnostic pathError-specific checks, commands, configuration changes, and expected outputTroubleshooting pages with stable headings and explicit error states
    Compare optionsMeaningful differences and situations where each option fitsVersion support, migration implications, API differences, and operational constraintsEvidence-based comparison connected to migration and reference material

    For example, a conversational template might ask: Which [category] fits a [type of team] that needs [outcome], and what are the tradeoffs? Its Claude Code counterpart might ask: I need to add [capability] to [stack] under [constraint]. Which [tool or library] fits, and how should it be configured?

    Those prompts express related demand without pretending the two environments are identical. Keep the audience, desired outcome, and major constraint aligned across each pair. That gives you a defensible comparison when one surface mentions your brand and the other does not.

    Build content that can finish each kind of task

    You do not need doorway pages that merely insert Claude or Claude Code into a heading. You need pages that resolve the jobs represented by your paired prompts. The strongest content architecture connects decision material to implementation material so an answer engine can move from what your product is to how someone uses it.

    For Claude, make the decision legible

    A conversational answer needs a concise, extractable explanation before it needs a long brand narrative. Put the core answer near the top of the relevant page, then support it with the criteria a person would use to make a decision.

    • State what the product, service, or concept is in direct language.
    • Name the intended user and the problem it addresses.
    • Explain where it fits and where it does not fit.
    • Describe material tradeoffs instead of declaring the option best for everyone.
    • Connect important claims to visible evidence on the page.
    • Keep product names, company names, and category language consistent across canonical pages.
    • Show when time-sensitive material was last reviewed or changed.

    If a page makes readers scroll through positioning language before revealing what the product does, the problem is not merely tone. The page has failed to expose a usable answer unit. Rewrite the opening so the entity, audience, function, and differentiator can be understood without reconstructing them from several sections.

    For Claude Code, make the implementation executable

    Technical content must survive contact with a real implementation. A conceptual feature description is not a substitute for the details needed to install, configure, test, or debug something.

    • Declare prerequisites and version scope beside the instructions they qualify.
    • Provide a minimal working example before presenting advanced variations.
    • Show package names, imports, configuration keys, and required environment inputs exactly.
    • Explain authentication without exposing real secrets or encouraging unsafe credential handling.
    • Show the expected result so the user can tell whether the step worked.
    • Document common failure states with the relevant error text, likely cause, and corrective action.
    • Link conceptual product claims to the canonical API, integration, migration, and troubleshooting pages that substantiate them.
    • Remove or clearly label obsolete instructions instead of leaving contradictory versions discoverable.

    A snippet should agree with the prose around it. If the command uses one package name while the explanation names another, or the example requires an unstated dependency, the page is not implementation-ready. Test documentation as a sequence: prerequisites, setup, execution, expected output, failure recovery, and next step.

    Use JSON-LD as a shared entity layer

    Structured data can make the relationship among your organization, software, documentation, authorship, and canonical URLs clearer. It should describe what a visitor can verify on the page; it should not introduce unsupported versions, reviews, features, or relationships that are absent from the visible content.

    • Use Organization markup for the organization entity and connect only genuine official profiles through sameAs.
    • Use SoftwareApplication when the page actually describes a software application, including applicable details such as application category, operating system, or software version when those facts are visible.
    • Use TechArticle for genuine technical documentation and keep its headline, author, modification date, and canonical relationship consistent with the page.
    • Use BreadcrumbList to represent the visible documentation hierarchy when breadcrumbs are present.
    • Give the same entity a stable name and canonical URL across relevant markup instead of generating isolated identities on every page.

    Validate the markup, but keep your claim modest: valid schema removes ambiguity; it does not prove that Claude or Claude Code will retrieve, cite, or rank the page. If visibility changes after several content and schema edits, do not assign causation to JSON-LD without a test that isolates it.

    Measure each surface with a repeatable visibility test

    Two parallel testing chambers process identical blank prompt tiles and produce conversational and technical outputs.

    A useful test must tell you what happened, where it happened, and which content could have influenced the result. Screenshots of favorable answers are evidence of individual runs, not a measurement system.

    Set up the test

    1. Define the entities. Record the official organization, product, feature, package, and category names you expect to recognize in an answer.
    2. Create paired prompt clusters. Cover explanation, selection, implementation, troubleshooting, comparison, and branded validation where those tasks apply to your business.
    3. Label every run by surface. Claude and Claude Code must occupy separate fields, views, and trend lines.
    4. Freeze the important variables. Save the exact prompt, date, account or workspace context that may matter, and any visible search or tool state. Do not quietly rewrite a prompt and treat it as the same test.
    5. Repeat on a fixed cadence. Generative responses can vary, so compare repeated runs rather than promoting one favorable output into a benchmark.
    6. Capture the whole response. Record brands mentioned, links shown, claims made, apparent search activity, and the position and context of each mention.
    7. Classify destination pages. Use a stable taxonomy such as homepage, product page, comparison, editorial content, documentation, API reference, repository, community page, or troubleshooting page.
    8. Corroborate with traffic data where possible. If agent traffic can be identified reliably in your logs or analytics, connect it to the page and time window. Do not relabel ordinary direct traffic as Claude traffic without evidence.

    Keep the metrics interpretable

    • Search activation rate: runs with visible search or retrieval activity divided by all comparable runs.
    • Brand mention rate: runs naming the target brand divided by all comparable runs.
    • Linked citation rate: runs linking to a brand-owned page divided by all comparable runs.
    • Third-party citation rate: runs that substantiate a brand mention through an independent page divided by all comparable runs.
    • Owned-page visit rate: identifiable agent visits to owned pages divided by the relevant tracked runs, when that connection can be made responsibly.
    • Page-type distribution: the share of observed citations or visits going to each page class.
    • Task coverage: prompt intents for which the brand receives an accurate, useful mention divided by the tested prompt intents.
    • Cross-surface overlap: brands appearing on both surfaces compared with all brands appearing on either surface.

    Do not average these into an opaque score before examining them separately. A brand can have a high mention rate and a low citation rate. Claude Code can visit documentation while Claude cites a category explainer. Those are different states requiring different work.

    Turn patterns into a diagnosis queue

    Observed patternReasonable hypothesis to investigateNext action
    Strong in Claude, weak in Claude CodeThe brand is understandable at the category level but lacks accessible implementation evidence, or the coding surface forms a different candidate set.Audit setup, compatibility, API, migration, and troubleshooting pages against the failed Claude Code prompts.
    Strong in Claude Code, weak in ClaudeThe technical material is useful, but the category, audience, or decision context is unclear.Create or improve an answer-first product or category page and connect it directly to the technical documentation.
    Mentioned without a linkThe brand is known in the response context, but the run does not demonstrate referral to a current page.Track it as a mention, not a citation or visit, and strengthen canonical pages that verify the claims being made.
    Search occurs, but competitors receive the citationsCompeting pages may match the task or provide more readily usable evidence.Compare page intent, claim clarity, technical completeness, and destination type; fill the specific information gap rather than copying wording.
    Documentation is visited, but the brand is not recommendedThe page may resolve a narrow technical step without establishing product fit.Improve links and language connecting the documented task to the relevant capability and canonical product entity.
    No visible search occursThe surface may be answering from existing context, so current-page retrieval cannot be confirmed for that run.Report zero-search runs separately and test natural variations of the same intent before diagnosing a page-level retrieval failure.

    Each row is a hypothesis, not a verdict. Check the actual response, destination page, and traffic evidence before deciding what caused the pattern. This keeps you from rebuilding documentation to solve a category-positioning problem, or rewriting a commercial page when the missing asset is a version-specific integration guide.

    Begin with the small set of tasks closest to adoption or implementation. Establish separate baselines for Claude and Claude Code, fix the clearest page-type gap, and rerun the same paired prompts. Once you can name the surface, task, metric, and page that changed, you have an answer-engine optimization program instead of a collection of Claude screenshots.

    References


  • Vertical AI Search Agency Rankings: How to Choose in 2026

    Vertical AI Search Agency Rankings: How to Choose in 2026

    If you’re using a “best AI search agencies” list to choose a partner, the highest score is not automatically the safest choice. You need the agency that can change the specific event your business depends on: a patient finding the right clinic, a traveler completing a direct booking, or a property owner requesting a qualified estimate.

    Vertical rankings can give you a workable shortlist. The important part comes next: checking whether the ranking criteria match your outcome, whether the agency’s evidence survives scrutiny, and whether its delivery model fits the way your organization actually operates.

    The 2026 shortlist changes with the vertical

    There is no meaningful universal ranking for AI search agencies. Hospitality needs machine-readable property and booking information. Cardiology needs clinically governed authority and patient acquisition. Construction may depend on local service coverage, commercial specialization, or both. Those differences change which capabilities deserve the most weight.

    VerticalPublished top threeWhat separates the options
    Hotels and hospitality1. First Page Sage; 2. Genevate; 3. MilestoneFull-service agentic search strategy, boutique-property brand accuracy, and multi-property data infrastructure are three different operating models.
    Cardiology1. First Page Sage; 2. Focus Digital; 3. Driven MetricsClinical authority and lead generation, budget-conscious multichannel work, and analytics-led reporting solve different practice needs.
    Contractors and construction1. First Page Sage; 2. Siana Marketing; 3. Focus DigitalAuthority-building content, architecture and engineering specialization, and localized small-business lead generation are not interchangeable strengths.

    There is a material caveat. First Page Sage is both the publisher and the first-ranked agency for hospitality, cardiology, and construction. That conflict does not make every claim false, but it does change the evidentiary weight. Treat the positions as a vendor-created shortlist until you independently verify client relationships, review profiles, methodology, deliverables, and results.

    Recurring names can still be useful. First Page Sage appears as the broad, authority-led option across all three verticals. Focus Digital appears in both cardiology and construction, with a smaller-business and lead-generation orientation. Genevate and Milestone address sharply different hospitality needs. Your task is not to preserve the published order. It is to identify which operating model fits your bottleneck.

    Your vertical determines what AI search success means

    Do not let GEO, AEO, AI SEO, and ASO collapse into one vague service. GEO generally concerns how a brand is understood, cited, and recommended in generative answers. AEO focuses on becoming a usable answer. In this context, agentic search optimization extends the job from answering to acting: an agent must be able to discover an option, evaluate it, and continue toward a transaction.

    Make every proposal spell out the acronym and the intended result. “Improve AI visibility” is not an adequate scope. “Increase accurate recommendations for these decision-stage prompts and make the resulting booking or inquiry path usable” is much closer.

    Hospitality: the agent must be able to complete the journey

    A hotel can be described accurately and still lose the booking. The agent may need to identify amenities, location, room constraints, rates, availability, cancellation terms, and a working reservation path. If those details disagree across the hotel’s website and third-party listings, the agent has a comparison problem. If the booking interface is inaccessible to the agent, it has an action problem.

    First Page Sage reports that, across 2,417 agentic commands, including 343 travel-booking commands, agents switched to a competitor in 46.2% of failed attempts when a conversion page was not machine-actionable. Treat that percentage as vendor-supplied rather than an industry benchmark. It still identifies the correct failure mode to test in your own funnel: successful discovery does not matter if the agent cannot proceed.

    Ask a hospitality finalist to demonstrate four things with one representative property:

    • Where the agent obtains the canonical property description, amenity list, policies, rates, and availability.
    • How the agency detects discrepancies among the hotel website, listings, and other sources an assistant may consult.
    • What “machine-actionable” means for your reservation system, including which steps can and cannot be completed.
    • How it distinguishes increased AI mentions from completed direct bookings and revenue.

    Choose brand-accuracy work first when an independent property is repeatedly misdescribed. Choose scalable property-data infrastructure when a group cannot keep information consistent across many locations. Choose a full-service agentic program when the data is broadly correct but discovery, recommendation, and booking still break across the journey.

    Cardiology: visibility is subordinate to clinical accuracy

    A cardiology program has to earn relevant recommendations without overstating what a physician or practice can treat. Service descriptions, subspecialties, locations, insurance information, referral requirements, and patient-facing explanations all influence whether an AI answer is accurate enough to be useful.

    Clinical governance should therefore be a gate condition, not a bonus point. Require a named medical reviewer, a documented approval path, and a correction process for inaccurate AI representations. An agency that increases mentions while introducing unsupported clinical claims has not delivered a successful outcome. Do not publish medical content solely on an agency’s approval; the safe alternative is review by a qualified clinician who understands the practice and the claim being made.

    Measurement also needs to reach beyond citation counts. Decide whether success means an appropriate appointment request, a call about a relevant service, a physician referral, or another defined patient-acquisition event. Then make the agency show how it will connect recommendation monitoring to that event without treating every inquiry as qualified.

    Construction: local demand and AEC authority require different programs

    A residential HVAC contractor, a commercial general contractor, and an architecture or engineering firm may all sit under “construction,” but their AI-search journeys are different. The local service business needs accurate service areas, relevant service pages, local trust signals, and a call or form that produces a usable lead. The commercial firm may need evidence of project type, technical expertise, geographic capacity, procurement fit, and authority across a longer buying process.

    This is where a narrow specialist can beat a higher-ranked generalist. Siana Marketing’s focus on architecture, engineering, construction, and home services may matter more to an AEC firm than a broad score. Focus Digital’s localized model for smaller construction businesses may make more sense for a contractor competing market by market.

    Before comparing proposals, define a qualified lead in writing. Include the service, service area, customer or project type, and any minimum conditions your sales team uses. Otherwise, an agency can report more AI-originated inquiries while your team receives requests outside its territory or capabilities.

    Read every score as a set of assumptions

    A composite score looks objective because it ends in a number. The judgment entered much earlier: somebody chose the criteria, assigned their weights, decided what counted as evidence, and converted imperfect public information into ratings.

    CriterionHospitality modelCardiology modelConstruction model
    Headline AI performanceASO expertise: 25%AI recommendation: 25%AI visibility: 25%
    Separate GEO expertiseNot scored separatelyNot scored separately20%
    Leadership experience20%20%20%
    Average reviews20%20%15%
    Relevant clients15%15%10%
    Year established10%10%10%
    Media references10%10%Not scored

    All three models give the headline AI criterion 25% and leadership experience 20%. The construction model then assigns another 20% to GEO expertise, while hospitality and cardiology use 10% for media references. That difference alone can reorder agencies. A firm with a large publishing footprint may benefit in the first two models; a firm with detailed GEO methodology may benefit more in construction.

    Neither choice is universally correct. Media references can indicate authority and visibility, but they do not prove that an agency changed recommendations for a client. A long operating history can indicate institutional depth, but it does not prove that a legacy SEO team has a mature AI-search workflow. High review averages can reflect good client service without isolating GEO performance.

    Rebuild the evaluation around your decision instead of accepting inherited weights:

    1. Write the target AI event in one sentence. Name the audience, decision, location if relevant, and desired business action.
    2. Mark each published criterion as a must-have, useful context, or irrelevant to that event.
    3. Ask for the evidence underneath every score that could change your decision. Do not compare unlabeled composite numbers.
    4. Give all finalists the same scenario and evidence request so you are comparing like with like.
    5. Record missing information as unknown. Do not quietly convert it into a favorable assumption.

    You may discover that a lower-ranked agency wins because the original model rewarded factors your organization does not need. That is not a problem with your selection process. It is the point of having one.

    Demand an evidence chain, not an AI visibility screenshot

    Analysts inspect a chain of source cards and business outcome models while an isolated glowing screen tile sits to one side.

    A single screenshot proves that one answer appeared once. It does not tell you whether the result repeats, whether the model cited reliable information, whether the user was in your market, or whether the recommendation produced a business outcome.

    Ask each finalist to walk one real prompt through this evidence chain:

    1. Observation: What did ChatGPT, Claude, Gemini, Grok, or another in-scope system answer before the work began? Which prompt, account state, location, and date were recorded?
    2. Diagnosis: Why was your brand absent, inaccurate, poorly positioned, or impossible to act on? The explanation should identify an information, authority, relevance, reputation, technical, or conversion-path problem.
    3. Intervention: What exactly changed? Examples include correcting business information, restructuring service content, improving entity clarity, adding structured data, strengthening third-party corroboration, or repairing a booking or inquiry path.
    4. AI outcome: Did the brand become accurately represented, cited, compared, or recommended across a repeatable prompt set? A change should not depend on one cherry-picked answer.
    5. Business outcome: Did the program contribute to qualified appointments, direct bookings, calls, forms, opportunities, or revenue? The agency should state where attribution is direct, modeled, or unknown.

    Model outputs can vary by prompt wording, location, context, and model version. No agency controls a frontier model’s answer. A credible team will define how it samples and records that variation instead of guaranteeing a permanent position.

    Questions that expose a shallow GEO offer

    • Which prompts are in scope? Ask to see informational, comparative, and decision-stage prompts rather than a list of broad keywords.
    • Which platforms and markets are measured? The answer should match where your customers research, not whichever system produces the best screenshot.
    • How is repeatability handled? Ask how prompts, dates, locations, outputs, citations, and model versions are preserved.
    • What will you change? Monitoring without a correction and publishing workflow is a reporting product, not a complete optimization service.
    • Who owns subject-matter approval? This is essential for cardiology and still important for hotel policies, contractor capabilities, pricing, and service territories.
    • How are AI-originated conversions identified? Ask what can be observed directly, what depends on self-reported attribution, and what cannot be attributed confidently.
    • Can you show relevant client evidence? A recognizable logo is less useful than a reference matching your vertical, size, buying journey, and operating complexity.
    • What remains yours when the engagement ends? Confirm ownership and access for prompt libraries, dashboards, audits, content, structured-data recommendations, account history, and exported records.

    The delivery model deserves the same scrutiny as the strategy. Hospitality illustrates the difference clearly: Milestone is positioned around structured property data, monitoring, and content management across many properties, while Genevate is positioned around brand accuracy and reputation for independent and boutique hotels. One is closer to scalable infrastructure; the other is closer to hands-on brand interpretation. Ask whether you are buying software, advisory support, implementation, or a hybrid, and identify who is responsible for acting on every finding.

    Make the contract reflect the outcome you are buying

    A blank contract is physically connected by brass components to models representing a clinic visit, a hotel stay, and a home estimate.

    A ranking can help you decide who gets a sales call. The contract determines what happens after it. Before committing to a broad rollout, use a representative diagnostic or milestone-gated pilot and require the following in writing:

    • Scope: Named platforms, markets, properties, practices, service lines, or service areas. “Major AI engines” is too vague.
    • Baseline: The prompt set, current outputs, factual errors, citation patterns, technical limitations, and conversion-path failures present at the start.
    • Deliverables: Separate monitoring, analysis, content, structured data, reputation work, technical implementation, and conversion work. Do not assume one includes another.
    • Approval and risk ownership: Identify who verifies medical statements, rates, availability, policies, project capabilities, credentials, and service coverage before publication.
    • Measurement: Define accurate representation, citation, recommendation, agent completion, qualified conversion, and revenue attribution separately.
    • Access and ownership: Specify who owns accounts, dashboards, prompt history, content, code, data, and exports. Without this clause, changing agencies can mean losing the record needed to evaluate progress.
    • Decision points: State what evidence permits expansion, revision, or cancellation. Do not roll an unproven workflow across every location merely because the agency ranked well.

    Walk away from guarantees of permanent rankings, unexplained proprietary scores, screenshots without preserved prompts, or case examples that never connect AI exposure to a relevant business event. Also be cautious when a proposal spends heavily on monitoring but leaves correction, publishing, technical implementation, and conversion work with an internal team that has no capacity to perform them.

    The opposite mismatch is expensive too. A hotel group may not need a strategy-heavy retainer if its immediate problem is property-data consistency at scale. A cardiology practice should not select a low-touch platform if nobody owns clinical review. A local contractor does not need a national thought-leadership program when inaccurate service areas and weak conversion pages are blocking nearby demand.

    Key takeaways

    • There is no universal best AI search agency. The correct choice depends on whether you need accurate representation, recommendations, qualified leads, or an agent-ready transaction.
    • Use published rankings to create a shortlist, then check who owns the ranking and whether that organization benefits from the result.
    • Inspect the weighting model. A composite score can reward media presence, history, or reviews more heavily than the capability blocking your growth.
    • Require an evidence chain from prompt to diagnosis, intervention, AI outcome, and business outcome.
    • Put platforms, deliverables, approvals, measurement, data ownership, and expansion conditions in the contract before a broad rollout.

    Before your next agency call, write your desired AI event at the top of a page and send the same evidence questions to each finalist. The agency that can trace a credible path from that event to a qualified outcome in your vertical deserves the next conversation. The highest unexplained score does not.

    References


  • How to Choose an AI Search Agency for Home Services or Dental

    How to Choose an AI Search Agency for Home Services or Dental

    You are not choosing between three interchangeable labels. You are choosing whether an agency can make your business understandable, credible, and selectable when someone asks an AI system whom to hire.

    That decision looks different for a plumbing company and a dental practice. A homeowner may need an agent to identify an available contractor and request an estimate. A prospective patient needs an accurate recommendation that reflects treatment needs, provider fit, and location. The right agency will build around that decision path instead of selling you a renamed SEO package.

    The acronym matters less than the decision path

    Generative engine optimization, or GEO, focuses on earning visibility and recommendations in generative answers. Answer engine optimization, or AEO, focuses on becoming a useful source for direct answers. Agentic search optimization, or ASO, extends the job into actions an AI agent may take for the user.

    For home services, that final stage is already central to the proposition: contractor selection, estimate requests, and service-call scheduling are the kinds of outcomes an ASO program is expected to support. Dental GEO and AEO remain more heavily centered on local provider recommendations and new-patient appointment demand.

    An agency does not need to use your preferred acronym. It does need to show how it will improve retrieval, evaluation, and action for the decisions your customers or patients actually make.

    Decision layerHome servicesDentalWhat the agency must demonstrate
    Candidate retrievalRecognition for the right trade, service, problem, and service areaRecognition for the relevant treatment, specialty, provider type, and locationA controlled set of non-branded questions that represents real demand
    Suitability evaluationClear project types, exclusions, coverage, availability, and customer fitClear treatments, provider qualifications, patient concerns, and practice fitPages and corroborating facts that help an AI system distinguish suitable from unsuitable choices
    ActionA working path to call, request an estimate, or schedule serviceA working path to call or request an appointment without replacing clinical judgmentConversion tracking, action-path testing, and an agreed definition of a qualified lead
    Accuracy riskWrong service-area or capability information can create wasted calls and dispatch problemsWrong treatment or provider information can mislead a person making a healthcare decisionA named owner for fact approval, correction, and ongoing updates

    Key takeaways

    • Hire for the vertical decision path, not for the agency’s preferred GEO, AEO, or ASO label.
    • Home-services programs need strong action readiness: accurate coverage, suitability, and a reliable route to an estimate or booking.
    • Dental programs need clinically reviewed patient information and precise treatment, provider, and location positioning.
    • Use agency rankings to discover candidates, not as a substitute for case evidence, capacity checks, and references.
    • Require reporting that separates AI visibility from qualified calls, appointments, booked work, and revenue.

    Build your shortlist around operating fit

    You can find plenty of agency leaderboards. Their scores may help you discover firms, but they cannot tell you whether a team fits your footprint, operating model, budget, or approval process. The agency operating each publication used here also places itself first in its own ranking. A self-ranking result is not automatically wrong, but it is not independent validation. Treat the numerical scores as screening material and verify every consequential claim yourself.

    Home-services agencies to interview

    The home-services candidate field covers contractors in HVAC, plumbing, electrical, roofing, restoration, pest control, insulation, and adjacent services. The useful distinction is not who occupies which rank. It is what kind of operation each agency appears built to serve.

    Your situationAgencies worth an initial interviewWhy they fit the shortlistWhat to verify
    You want a full-cycle retrieval, evaluation, and action programFirst Page SageIts disclosed model combines authority content, service-area positioning, and suitability work across several home-services categoriesThe longer onboarding process, assigned capacity, lead attribution method, and ownership of finished assets
    You are a contractor, remodeler, architect, or design-build businessSiana MarketingIts narrow construction and AEC focus includes project type, budget, and regional suitabilityAvailability, execution bandwidth, and whether its experience matches your exact trade rather than construction generally
    You run a regional or single-trade operation with a tighter budgetFocus DigitalIts positioning emphasizes accessible SEO and ASO strategy for smaller and midsize operatorsPublishing pace, team depth, and capacity if you add locations or service lines
    You want AI search inside a broader home-services marketing programRYNO Strategic SolutionsIts home-services background and full-funnel positioning may suit an operator that wants channels managed togetherWhich deliverables are genuinely AI-search-specific and which belong to conventional SEO, paid media, or web work
    You need a contractor-focused web and search partnerCI Web Group or Hook AgencyBoth are positioned around contractor marketing, with trade exposure that includes HVAC, roofing, plumbing, and related servicesExamples showing improvements in AI answers, not only traditional rankings, traffic, or website performance

    A roofing franchise with several markets should not select the same delivery model as an owner-operated plumbing company serving one region. Ask each agency to state how many service-location combinations it can support, who approves operating facts, and what happens when capacity or coverage changes. If the proposed system cannot absorb those changes, it will publish stale suitability signals.

    Dental agencies to interview

    For dental, start with firms whose disclosed work matches your actual growth problem. The dental field spans content-led GEO specialists, healthcare-focused teams, established dental web agencies, and platform-based providers.

    Your situationAgencies worth an initial interviewWhy they fit the shortlistWhat to verify
    You want a long-term, content-led GEO and SEO programFirst Page SageIts dental work emphasizes local landing pages, patient guides, comparisons, and new-patient lead generationClinical review, content differentiation, appointment attribution, and support for every specialty and location in scope
    You are making an earlier or more budget-conscious GEO investmentFocus DigitalIts healthcare-oriented model is positioned as an accessible way to build AI visibility and organic demandAdditional resource needs when the campaign expands across several specialties or locations
    You specifically want an AI-era lead-generation firmSignal Hill StrategiesIts model was designed around generative search for medical industries rather than added to a long-standing web packageDocumented dental outcomes and references, because the firm was established in 2026 and has a developing case library
    You primarily need dental web design and SEO, with GEO as a secondary objectiveRosemont MediaIts dental and elective-healthcare experience dates to 2008 and includes websites, content, SEO, and paid mediaThe depth of its GEO process beyond established dental SEO and web-design capabilities
    You want a brand-led dental marketing programWonderist AgencyIts stated specialty combines dental branding, website design, and SEOHow brand work will translate into measurable candidate inclusion and recommendation accuracy
    You prefer a broad, platform-oriented, or midsize-practice providerTitan Web Agency, Officite, or DentalScapesTheir stated positions respectively cover practices of different sizes, a platform-based model, and midsize dental practicesCustom strategy, account ownership, AI-search evidence, and any limitations imposed by the platform or service tier

    This is a first-call map, not a winner table. A strong traditional dental agency may be right when your website and local search foundation are weak. A dedicated GEO firm may be the better choice when your fundamentals are sound and the unresolved problem is AI recommendation visibility. Make the agency diagnose that distinction before it proposes work.

    Put six concrete artifacts in the scope of work

    Six unlabeled planning artifacts with maps, pathways, entity blocks, credibility symbols, content placeholders, and booking icons are arranged on a strategy table.

    Promises such as better AI authority or more visibility are not deliverables. Before you sign, turn the pitch into artifacts that your team can inspect, approve, and retain.

    1. A controlled question set. For home services, organize questions by service, customer problem, geography, suitability, and desired action. For dental, organize them by treatment, patient question, specialty, provider criteria, geography, and appointment intent. Include non-branded discovery questions as well as comparative and action-oriented questions. Otherwise, the agency can produce a flattering report by monitoring only prompts where you already appear.
    2. A canonical fact and entity ledger. Record the approved business name, locations, coverage, hours, services, exclusions, providers, credentials, contact routes, and booking options that apply. Add an owner and an approval status to each consequential fact. A dental clinician should approve treatment and patient-education claims; the marketing agency should not become the final clinical authority.
    3. A retrieval and evaluation content map. Every proposed service page, location page, patient guide, comparison, FAQ, or original-data asset should map to a demonstrated question or evidence gap. Reject a plan built around generic publishing volume. More pages do not help if they repeat the same claims or blur the boundary between services you do and do not provide.
    4. A structured-data map. Ask the agency to connect each machine-readable fact to visible, approved page content and to document how markup will be validated. JSON-LD can clarify entities, relationships, locations, and services, but it cannot manufacture authority or rescue unsupported claims. The map should also state who maintains the markup after templates, providers, locations, or services change.
    5. An external corroboration plan. The agency should identify which business profiles, citations, publications, professional references, and other third-party signals need correction or development. Ask it to separate controllable profile work from earned references it cannot guarantee. Vague promises of authority building are not enough.
    6. An action and measurement specification. Define the calls, forms, estimate requests, appointment requests, bookings, and qualified-lead states that will be tracked. Require action-path testing and a correction process for inaccurate AI answers. For dental, keep clinical decisions and sensitive patient information outside ordinary marketing workflows unless your practice has approved the necessary privacy and compliance controls.

    These artifacts also solve a common ownership problem. If the relationship ends, you should still possess the question set, fact ledger, content, structured-data documentation, reporting history, and access credentials. Without them, changing agencies can mean rebuilding the strategic foundation rather than simply changing the team executing it.

    Use the interview to expose generic SEO in AI clothing

    Do not spend the interview asking an agency to predict the future of AI search. Ask it to work through your current decision path. Strong operators become more specific when the discussion reaches services, locations, evidence, approval, and measurement. Weak ones retreat to traffic, content volume, or platform buzzwords.

    Ask thisA credible answer includesA weak answer sounds like
    How will you build our monitored question set?Segmentation by service or treatment, geography, intent, suitability, and action, with an explanation of why each segment mattersA generic keyword export or a secret proprietary list you cannot inspect
    How do you separate retrieval from evaluation?A distinction between appearing in the candidate set and being described as a suitable choice for the specific needOne visibility score with no answer-level evidence
    Show us a vertical-relevant example.The original problem, the facts and assets changed, representative AI outputs, and a business result or clearly stated limitationA screenshot of a favorable branded query with no baseline or conversion data
    What operating information do you need from us?Service boundaries, locations, exclusions, capacity, provider or technician facts, approvals, and change notificationsLittle or no involvement from your operations or clinical team
    How do you handle variable AI answers?A repeatable prompt protocol with platform, date, geography assumptions, answer capture, and trend reportingA promise that one answer or ranking position will remain stable
    How will you connect visibility to business outcomes?Defined conversion events, qualified-lead rules, source capture, and separation of mentions from calls, appointments, or bookingsImpressions, citations, or estimated visibility presented as revenue
    Who approves factual claims?Named business owners for operating facts and clinician review for dental treatment contentThe agency publishes from general web research without a documented approval route
    What happens when an AI answer is wrong?A triage process that checks owned pages, structured data, profiles, conflicting third-party information, and action pathsNo process beyond publishing another blog post

    Ask to see the artifacts on screen. A polished pitch can hide whether the agency has a real query taxonomy, fact-control process, or answer-level reporting system. Redacted examples are reasonable when client confidentiality applies, but the team should still be able to demonstrate its method.

    Measure the path from AI answer to booked business

    An icon-based path leads from an AI-style phone interface through a call and calendar to a home service visit and a dental appointment.

    AI visibility is an intermediate result. A useful report shows whether visibility is increasing, whether the recommendation is accurate, and whether the right person can complete the next step.

    Require four reporting layers

    LayerWhat to recordWhat it tells youWhat it does not prove
    RetrievalCandidate inclusion, mentions, citations, and visibility across the agreed question setWhether AI systems can retrieve and associate your business with relevant demandThat the system prefers you or that a customer will contact you
    EvaluationRecommendation language, stated reasons, suitability, and accuracy of service, treatment, provider, and location factsWhether your positioning survives comparison with alternativesThat the recommendation generated a qualified lead
    ActionCalls, forms, estimate requests, appointment requests, booked jobs, and the agreed qualified-lead statesWhether the discovery path produces usable demandThat every conversion is incremental or profitable
    IntegrityIncorrect facts, obsolete pages, conflicting profiles, broken booking paths, and correction statusWhether visibility is being gained without creating operational or patient riskThat the wider web contains no conflicting information

    Establish the baseline with the same controlled questions the agency will use later. Preserve the question wording, platform, date, location assumption, returned answer, citations, and recommended businesses. AI outputs can vary, so one favorable capture is evidence of an occurrence, not evidence of a durable trend.

    Then keep the commercial metrics vertical-specific. A home-services dashboard should distinguish an irrelevant call, an eligible estimate request, a booked visit, and completed work. A dental dashboard should distinguish a general inquiry, a new-patient appointment request, a scheduled appointment, and the practice’s approved downstream outcome. Do not let a growing mention count conceal poor suitability or an unusable booking path.

    Protect accuracy, access, and exit before signing

    Your contract should state who owns the content, structured data, dashboards, prompt history, and underlying accounts. It should name the people allowed to approve business and clinical facts, define how corrections are handled, and explain what you receive when the engagement ends.

    • Reject guaranteed placement in ChatGPT, Gemini, Claude, or any other AI answer surface.
    • Reject reporting that relies on unexplained proprietary scores without answer-level evidence.
    • Reject a content quota that is not mapped to a retrieval, evaluation, or action gap.
    • Reject schema-only positioning. Machine-readable markup is one part of the system, not the whole strategy.
    • Reject home-services plans that ignore coverage, capacity, exclusions, and the actual estimate or dispatch path.
    • Reject dental plans that permit unreviewed treatment claims or confuse marketing automation with clinical guidance.
    • Reject account structures that prevent you from accessing your analytics, content, profiles, markup, or conversion history.

    Send the same operating facts, question set, scope requirements, and reporting expectations to a small shortlist. The agency that gives you the clearest boundaries, evidence, and ownership model is usually a safer choice than the one offering the boldest visibility promise. Your next move is not to buy a ranking. It is to make each candidate show exactly how your business will be retrieved, evaluated, and chosen.

    References