Tag: Brand Positioning

  • Schema and Entity Optimization for AI Search: A Practical Audit

    Schema and Entity Optimization for AI Search: A Practical Audit

    Your JSON-LD validates, yet your brand still goes missing when people ask AI systems for recommendations, comparisons, or eligibility advice. The problem may not be syntax. Valid markup can sit on top of vague, incomplete, or contradictory facts.

    The useful goal is not to publish the largest possible schema graph. It is to make the facts that drive a customer’s decision explicit, consistent, verifiable, and connected. The process below gives you a practical way to find those entity gaps, decide which ones matter, and fix the page and its markup together.

    Define the entity model before touching your JSON-LD

    Schema is a translation layer, not a fact factory. It can express that an organization offers a service, that a program has a duration, or that an event starts on a particular date. It cannot resolve a policy your organization has not settled or turn vague marketing language into a reliable claim.

    Start by asking what an answer engine would need to know to describe your offer without guessing. For most commercial or institutional pages, that includes:

    • What is the offer, and what is its canonical name?
    • Which organization provides it?
    • Who is it for, and what eligibility rules apply?
    • What does it cost, how long does it take, and how is it delivered?
    • What outcomes can you substantiate?
    • Which related people, locations, credentials, products, or services help distinguish it?

    Turn those questions into a target entity model. This can begin as a spreadsheet rather than code. Give each row a subject, a claim or relationship, an approved value, a primary page, an internal owner, a public evidence location, and the schema type or property that could represent it.

    For example, a degree program is an entity. Its provider, delivery mode, duration, credit total, language, admissions threshold, tuition, start dates, curriculum, and outcomes are properties or related entities. A software product would have a different model, but the reasoning is the same: identify the facts a buyer uses to recognize, compare, and choose it.

    Classify every target fact using four states:

    • Legible: The fact is specific, visible on the appropriate page, and represented consistently in structured data.
    • Ambiguous: Something is stated, but its meaning is too loose to support a dependable answer. Phrases such as competitive pricing, flexible study, or a good academic record fall into this category unless the page defines them.
    • Unverifiable: The claim appears in content or markup, but you cannot connect it to an approved policy, responsible owner, or supporting evidence. Unverifiable does not automatically mean false; it means you are not ready to publish it as a firm fact.
    • Missing: The fact belongs in the target model but is absent from the primary page, supporting content, or structured data.

    This distinction prevents a common audit failure. A missing fact needs content or data. An ambiguous fact needs precision. An unverifiable fact needs organizational resolution. Those are three different jobs, and adding more JSON-LD solves only one of them.

    Prioritize the entities that affect a real decision and belong on a high-value page. A clear eligibility rule on a core service page usually deserves attention before a minor biographical detail on an ancillary page. Also favor facts your organization can approve and maintain. A theoretically valuable property is not a useful priority if nobody can establish its current value.

    Run a three-layer entity audit
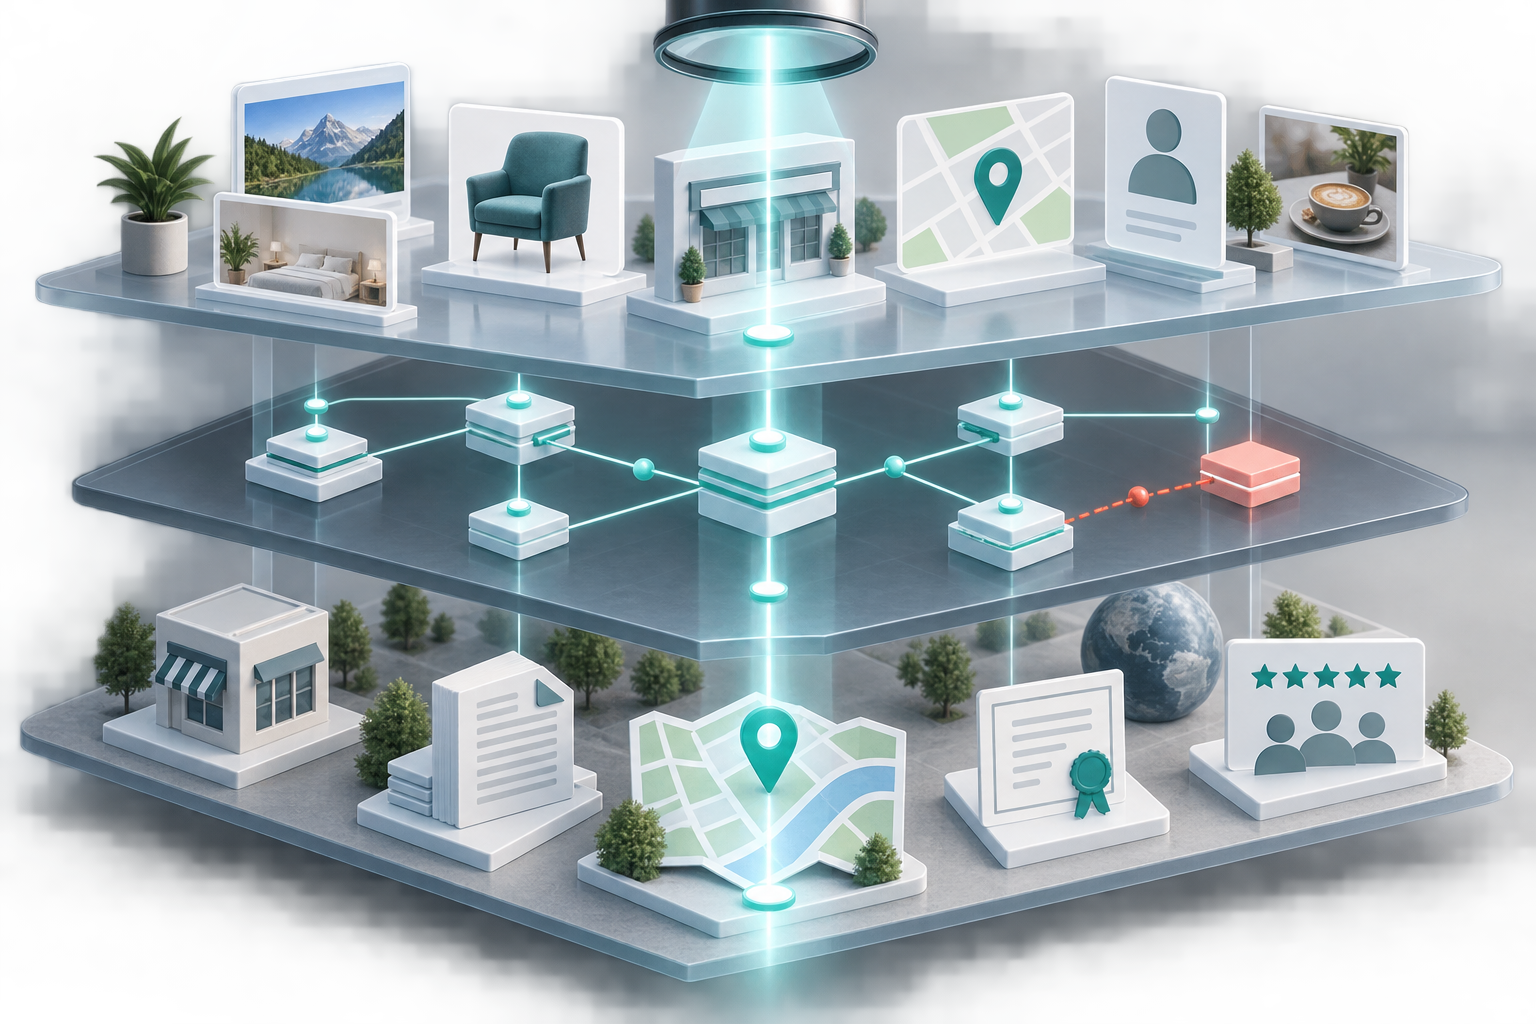
    A transparent three-layer workspace shows website content, structured data, and external evidence being inspected together.

    A schema validator tells you whether markup is technically parseable. An entity audit asks a harder question: does the site communicate the right facts clearly enough for a person or machine to connect them?

    Audit three layers at the same time:

    • Visible content: Is the fact stated plainly on the page where a visitor would expect to find it?
    • Structured representation: Does the JSON-LD identify the correct entity, use an appropriate property, and carry the same value as the visible page?
    • Supporting context: Is there enough related content to explain or substantiate the claim, and does that content point back to the primary entity?

    Work through the audit in this order:

    1. Select the primary conversion page. Start with the page that owns the offer: the product, service, program, location, or other page on which the decision happens.
    2. List the decision-critical entities and facts. Use customer questions, qualification requirements, commercial terms, and differentiators rather than copying whatever happens to be in the current schema.
    3. Read the page as a skeptical visitor. Record the exact visible wording for every target fact. Do not silently reinterpret vague copy during the audit.
    4. Inspect the JSON-LD entity by entity. Match every node to a real thing, then compare its properties with the visible wording and approved value.
    5. Trace supporting pages. Note where details such as curriculum, outcomes, policies, specifications, or staff credentials live and whether their relationship to the primary offer is clear.
    6. Assign a status and an owner. Mark the fact legible, ambiguous, unverifiable, or missing. Then identify who can approve the fix and whether it belongs in content, structured data, or both.

    Do not assume that broad coverage means strong entity clarity. In two higher-education implementations, a large share of the entities already present still proved ambiguous or unverifiable. One comparison set contained 85 custom JSON-LD entities; the existing site covered more than 50, but roughly a third of those were ambiguous or unverifiable and more than 20 were missing from program or supporting pages. Another audit identified 58 entities, with more than half classed as ambiguous and 27 classed as unverifiable.

    That pattern matters because a conventional schema audit could report substantial coverage while overlooking the uncertainty inside it. Count the quality states, not just the properties.

    If you manage hundreds or thousands of pages, embeddings can help with triage. Convert your approved target statements and your live content into comparable vector representations, then surface low-similarity areas for human review. Treat the similarity score as a queue, not a verdict. It can reveal that the language on a page does not resemble the intended entity model; it cannot decide whether a policy is true, a schema property is valid for a type, or a claim has been approved.

    Fix the visible fact and its structured representation together
    Matching location facts are corrected simultaneously on a website interface and in a connected structured-data network.

    When the audit exposes a gap, diagnose it before editing:

    • Content gap: The organization knows the fact, but the primary page does not state it clearly.
    • Schema gap: The visible page is clear, but the JSON-LD omits the fact, formats it poorly, attaches it to the wrong entity, or conflicts with the copy.
    • Truth gap: The organization cannot yet supply one reliable value because the policy is unsettled, varies by case, or lacks an accountable owner.

    For content and schema gaps, use a single publishing sequence:

    1. Confirm the approved value with the person or system that owns it.
    2. Rewrite the visible content so a visitor can understand the fact without decoding internal terminology.
    3. Represent the same fact in JSON-LD using an appropriate schema.org type, property, value format, and unit.
    4. Connect supporting pages to the primary entity with consistent naming and purposeful internal links.
    5. Check the rendered page and structured data for disagreement before publishing.

    Normalize values without making the page less human

    Machine-readable precision does not require robotic visible copy. A visitor can read 15 months while the structured representation uses the applicable ISO duration. The important point is that both expressions mean the same thing.

    Decision factWeak or incomplete expressionMore precise representationVisible-page requirement
    Program duration15 months stored only as textISO 8601 duration P15MExplain that the program takes 15 months under the stated schedule
    Start dateAmbiguous date wordingAn exact YYYY-MM-DD value when one date genuinely appliesShow the corresponding date and any campus or cohort conditions
    Credit total45 credits and 90 ECTS combined in one text stringQuantitativeValue with the relevant unit textMake each credit system and its meaning clear
    LanguageEnglish as unnormalized textISO 639-1 code en where the property expects itState that instruction is in English
    Minimum GPAGood academic recordAn approved numeric threshold such as 3.0 on a 4.0 scaleState the threshold, scale, and any genuine qualification

    These are examples of entity reconciliation applied to a particular university program, not values to copy. P15M is correct only when the duration is actually 15 months, and a 3.0 threshold should appear only when admissions has approved that rule. The correct schema property also depends on the type of entity you are marking up.

    Keep identities and relationships stable

    Give each core entity a stable identifier in your graph, commonly an @id based on a URL you control. Reuse that identifier when another node refers to the same organization, offer, person, or place. Otherwise, minor naming variations can produce duplicate-looking entities inside your own markup.

    Use the narrowest schema type that is genuinely accurate, and use only properties supported for that type. Connect entities with specific relationships instead of placing every keyword in a description field. Your graph should be able to express which organization provides the offer, where it is available, which people are connected to it, and which supporting resources explain it.

    The primary conversion page should own the essential decision facts. Supporting content should deepen them. An admissions page can explain an eligibility process, a curriculum page can detail course structure, and an outcomes page can substantiate career information, but each should reinforce the canonical offer rather than introducing a competing name or contradictory value.

    Do not use schema to paper over an operational problem

    A truth gap has to move outside the SEO queue. Send it to the team that owns pricing, admissions, compliance, product, or operations. Record what must be decided and leave the value out until it can be stated accurately.

    Completeness is not worth misleading someone. One multi-campus university left an application-deadline entity unresolved because rolling starts across campuses made a single deadline potentially inaccurate. Another program did not emphasize faculty data when availability could not be maintained. In both situations, publishing a neat but unreliable value would have made the graph look fuller while making the answer worse.

    When a value legitimately varies, explain the rule or scope if the organization can support it. Identify which location, plan, cohort, product variant, or date range the value applies to. If that relationship is not yet knowable, omit the claim rather than guessing.

    Measure entity quality, AI visibility, and business value separately

    Markup does not guarantee growth. It removes ambiguity and gives your content a more coherent machine-readable representation, but rankings, citations, recommendations, and conversions have many other inputs. Your measurement plan should therefore keep three scorecards separate.

    • Entity quality: Track how many target facts are legible, ambiguous, unverifiable, or missing. Also count contradictions between visible content and JSON-LD, and note whether high-priority facts appear on the primary page.
    • Search and AI visibility: Track citations, inclusion in answers, and share of voice against a fixed competitor set for a stable group of prompts. Preserve the prompts and competitors so a changing test does not masquerade as improvement.
    • Business outcomes: Track the actions that matter after discovery, such as qualified leads, applications, purchases, payments, or stage-to-stage conversion rates. Better entity clarity may improve qualification even when top-line traffic is flat.

    Record the publication date, pages changed, entities affected, content edits, and schema edits. That change log will not create a controlled experiment, but it will stop you from crediting an isolated markup change for work that also included clearer copy, new supporting content, and internal linking.

    Two higher-education cases illustrate why the scorecards belong together. In one case, AI citations rose from 24,000 in January 2026 to 42,000 in July, a 75% increase over six months. Enrollment remained flat and lead volume fell, yet the lead-to-payment rate improved by 20% and the application-to-payment rate improved by 26%. The commercially important movement was not simply more discovery; it was better progression among people who entered the funnel.

    In the other case, organic lead volume increased 18% from 2025 to 2026 and application volume increased 22%. AI citations were about 11% higher year over year and roughly 77% above the preceding six months, while competitive share of voice gained one percentage point.

    Treat those results as directional case evidence, not universal benchmarks. The work combined entity reconciliation, visible-content changes, supporting pages, internal links, and structured data. The reasonable inference is that the coordinated package improved clarity and performance; the figures do not isolate JSON-LD as the sole cause.

    Your first success metric should be controllable: fewer ambiguous and unverifiable facts on the pages that matter. Visibility and conversion trends can then show whether that stronger information layer is helping people and AI systems find a clearer answer.

    Key takeaways

    • Build the target entity model from customer decisions, not from the schema already installed.
    • Classify each fact as legible, ambiguous, unverifiable, or missing so the right team gets the right kind of work.
    • Make the primary conversion page the source of essential facts, then use supporting content to explain and substantiate them.
    • Update visible copy and JSON-LD together. Precise markup attached to vague or conflicting content does not resolve the underlying entity.
    • Normalize dates, durations, quantities, units, and identifiers only after the organization has approved the real value.
    • Measure entity quality separately from AI visibility and business outcomes, and do not attribute a combined content-and-schema program to markup alone.

    Open your highest-value page and list the facts a buyer needs before choosing the offer. Mark each one legible, ambiguous, unverifiable, or missing. Then take one high-impact cluster – eligibility, price, delivery, specifications, or outcomes – through approval, visible copy, JSON-LD, supporting content, and measurement. That page-level cycle is how entity optimization becomes durable infrastructure instead of a one-time GEO tactic.

    References


  • Meta-TikTok Child Safety Dispute: What Marketers Should Do

    Meta-TikTok Child Safety Dispute: What Marketers Should Do

    If you manage paid social, publish platform news, or forecast teen audience reach, the tempting conclusion is that TikTok rejected Meta’s child safety settlement. That is not what the documented event establishes. TikTok rejected Meta’s ads after classifying them as political content; it did not announce a formal rejection of the settlement terms.

    That distinction should shape your next move. The settlement, Meta’s pressure campaign, TikTok’s advertising decision, and the possible effects on teen media use are related, but they are not interchangeable. Separate them before you change a campaign, brief leadership, or publish an answer that search engines and AI systems may repeat.

    Four events are being compressed into one headline

    Four separate evidence stations on a newsroom desk depict an agreement, a pressure campaign, a blocked advertisement, and youth media use connected by colored threads.

    Meta agreed to pay up to $16.7 billion to settle allegations from U.S. states that Facebook and Instagram were designed in ways that harmed children. The word allegations matters: a settlement resolves claims, but the reported figure should not be rewritten as a judicial finding that every allegation was proved.

    The financial structure gives Meta a direct reason to seek participation from its competitors. About $5 billion of Meta’s settlement is conditional on TikTok and YouTube reaching agreements with similar restrictions and payments of roughly $5 billion from each company. Meta therefore has financial, operational, and competitive interests in turning its agreement into a broader platform standard.

    Meta then launched a public campaign urging TikTok and YouTube to accept comparable terms. It argues that restrictions limited to Facebook and Instagram would be less effective because teens could move to other apps. Meta also says operating alone would put it at a competitive disadvantage. Those are Meta’s positions. They are not established evidence that teen migration will occur at a particular scale or that identical rules across platforms would produce identical safety outcomes.

    TikTok’s action occurred at a different layer. Meta attempted to buy TikTok placements calling on TikTok and YouTube to join the settlement. TikTok blocked the campaign because it contained political content, a category the platform prohibits in advertising. A policy decision about whether an ad may run does not, by itself, reveal whether TikTok accepts or rejects the policy proposal promoted inside that ad.

    • Confirmed settlement fact: Meta agreed to the reported financial and product terms with U.S. states.
    • Confirmed advertising fact: TikTok rejected Meta’s campaign under its political advertising policy.
    • Attributed position: Meta says industry-wide restrictions are necessary for safety and competitive fairness.
    • Unresolved question: TikTok and YouTube had not publicly committed to comparable agreements when Meta applied pressure.

    Use those four labels in internal briefs and published coverage. They prevent the most consequential error in this story: changing TikTok rejected Meta’s ads into TikTok rejected child safety rules.

    The reported restrictions create planning scenarios, not forecasts

    Meta’s agreement includes limits on daily use and overnight access, notification restrictions during school hours, chronological-feed options, and limits on showing likes and other reactions to young users. These terms identify where audience behavior and campaign performance could change. They do not establish how large any change will be.

    Reported termWhat your team should examineDecision to make now
    Daily usage restrictionsReach, repeat exposure, frequency, and sequences that depend on several visitsBuild a sensitivity case with less repeat exposure, then replace assumptions with platform data when relevant terms take effect.
    Overnight access restrictionsDelivery and engagement concentrated in overnight periodsSeparate overnight performance from the rest of the day so dependence on that window is visible.
    Limits on notifications during school hoursCampaigns or publishing patterns that rely on prompts bringing young users backMeasure direct sessions and notification-assisted returns separately wherever your tools permit it.
    Chronological-feed optionsThe relationship among publishing time, recency, organic distribution, and paid amplificationTrack posting time and distribution source rather than treating all feed impressions as equivalent.
    Restrictions on displaying likes and reactionsCreative that relies on visible engagement as social proofTest whether the message remains persuasive when reaction counts are not part of the presentation.

    These are testing priorities, not promised outcomes. The reported material does not provide precise age boundaries, implementation dates, enforcement mechanics, or campaign-performance estimates. Do not invent those details to complete a forecast. Use the age definitions and effective dates that appear in final platform documentation when they become applicable to your account.

    Your planning model should distinguish three scenarios. If comparable restrictions remain limited to Facebook and Instagram, use platform-specific assumptions rather than reducing teen reach across every channel. If TikTok and YouTube sign similar agreements, reassess reach, frequency, dayparting, notification dependence, and social-proof creative across the affected platforms. If negotiations remain unsettled, preserve your operating plan but attach sensitivity ranges and explicit triggers for revising it.

    Do not assume similar settlements would produce identical interfaces or delivery systems. A common restriction can be implemented differently by each platform. Your measurement plan should therefore follow the actual product changes, not merely the legal label attached to them.

    TikTok’s rejection is an advertising-governance warning

    The immediate lesson for advertisers is broader than this corporate fight. A campaign can be about reputation, safety, regulation, or competitor conduct and still be classified as political advertising. A large advertiser and a socially framed message are not automatic exceptions to a platform’s eligibility rules.

    If your campaign asks a regulator, platform, trade group, or competitor to adopt a public-policy position, treat policy review as an early production dependency. Do not wait until the media booking is complete and the creative is final.

    • Write down the campaign’s real objective: selling a product, changing corporate reputation, influencing a policy debate, or pressuring another organization. The label your team prefers does not control how the platform will classify it.
    • Ask for an eligibility assessment before committing the full production and distribution budget. Preserve the platform’s response and the policy language supplied with it.
    • Prepare an owned-channel and earned-media route for the same message. A campaign directed at another platform should not depend entirely on that platform selling you access to its audience.
    • Create channel-specific plans instead of assuming an approval on one network transfers to another. Political-content definitions and enforcement decisions can differ.
    • Do not disguise the campaign’s purpose to evade review. That creates a separate policy and reputational risk without resolving the original classification issue.

    A rejection also needs precise external language. Say that the platform rejected the ad and state the reason provided. Do not escalate that into a claim that the platform opposes child safety, refuses negotiations, or rejected the underlying settlement unless you have separate evidence for that statement.

    A response plan for marketing, communications, and SEO teams

    Three professionals review an abstract social media advertisement at a layered governance checkpoint with a shield, balance scale, and branching paths.

    You do not need to predict which company will concede. You need a process that remains useful under each outcome.

    1. Create a claim ledger with three fields: confirmed event, attributed company position, and unresolved question. Put every sentence in a leadership brief, campaign memo, or news page into one of those fields.
    2. Audit your exposure to the reported restrictions. Identify campaigns that depend heavily on teen repeat visits, overnight delivery, school-hour re-engagement, algorithmic-feed distribution, or visible reaction counts.
    3. Define evidence that will trigger a plan change. Useful triggers include a signed rival agreement, published platform rules, an effective date, product documentation, or a measurable change in your account data. A corporate pressure ad is not an implementation notice.
    4. Maintain separate platform forecasts. Do not copy an assumed Facebook or Instagram effect into TikTok or YouTube merely because Meta wants equivalent terms.
    5. Prepare creative that can work with less visible social proof and fewer repeat exposures. This is a resilient test even if the broader settlement never materializes.
    6. Assign ownership for monitoring. Legal or policy teams should validate obligations, media teams should track delivery changes, analytics teams should preserve baselines, and editorial teams should update public claims when the status changes.

    If you publish about the dispute, answer the narrow question before adding analysis: TikTok rejected Meta’s ads as political content, while TikTok and YouTube had not publicly joined the settlement campaign. That sentence preserves the actors, action, reason, and unresolved status. Avoid the shorter but unsupported formulation that TikTok rejected the settlement.

    That precision also matters for AEO and GEO. Machine-generated answers can collapse adjacent events when a page uses settlement rejection, ad rejection, and policy disagreement as synonyms. Keep each claim in a self-contained sentence, place attribution next to contested positions, and connect every figure to the agreement it describes.

    Use Article or NewsArticle JSON-LD that matches the visible page. Include the real headline, author, publisher, publication date, and modification date. Treat Meta, TikTok, YouTube, and the U.S. states as distinct entities in the copy rather than referring vaguely to the platforms or the parties. Update both the visible wording and structured data when the status materially changes. Schema can clarify a well-written page, but it cannot repair an inaccurate claim.

    Do not use the reported settlement as your organization’s legal compliance checklist. If you serve minors or have separate legal duties, ask qualified counsel to evaluate the rules that apply to your organization. Relying on a competitor’s reported agreement could cause you to miss obligations, age definitions, jurisdictions, or effective dates that are specific to your situation.

    Key takeaways

    • TikTok rejected Meta’s advertisements under its political-content policy; the documented rejection was not a formal rejection of the settlement terms.
    • Meta agreed to pay up to $16.7 billion, with about $5 billion of its settlement contingent on comparable agreements involving TikTok and YouTube.
    • Meta’s claim that teens will migrate to less restricted rivals is a strategic argument, not a measured outcome supplied with the settlement.
    • The reported restrictions give you specific variables to audit: repeat exposure, overnight activity, school-hour notifications, feed order, and visible reactions.
    • Change forecasts when concrete platform terms, dates, product updates, or account data justify it, not merely because one company is publicly pressuring another.
    • For search and AI visibility, distinguish confirmed actions, attributed positions, and unresolved questions in both visible copy and structured data.

    Your best next step is to document the distinction now, while the outcome is still open. Audit where your strategy depends on the affected engagement mechanics, define the evidence that would trigger a change, and keep every public claim narrower than the proof behind it. That leaves you ready to adapt if the restrictions spread without making costly decisions based on a pressure campaign alone.

    References

  • How to Make Your Brand and Pricing Visible in AI Search

    How to Make Your Brand and Pricing Visible in AI Search

    Your brand can appear in an AI answer and still lose the buyer. The assistant may recognize your name but misstate your category, omit your price, surface an expired offer, or recommend you to someone your product was never designed to serve. You get exposure, but the buying facts do not survive.

    The practical goal is not to make every model repeat your messaging. It is to make the answers that influence discovery and evaluation accurate, specific, and verifiable. That requires a clear source of commercial truth, pricing content that can be interpreted without guesswork, matching structured data, and an audit process built around real buyer questions.

    AI visibility must preserve the commercial decision

    AI discovery compresses several stages of research into one response. A buyer can ask which products fit a use case, what they cost, how their plans differ, and which option has a particular constraint. If your brand is mentioned but the answer cannot resolve those questions, visibility has not yet become commercial visibility.

    One vendor dataset is enough to justify taking this channel seriously, though not to forecast your own results. A Semrush study reported that more than a third of consumers start searching with AI and customers from AI search channels convert 4.4 times better than organic-search visitors. Treat that conversion figure as directional: channel definitions, attribution, audience, and purchase cycle can all affect the result.

    The competitive field also appears unsettled. In a dataset covering 1,094 categories, only 15.2% had a clear owner. That indicates room for brands to establish category associations, not a guarantee that publishing more content will produce ownership.

    Measure AI visibility against the questions a buyer needs answered:

    • Identity: Does the answer identify the correct company, product, and official website?
    • Category fit: Does it explain what you offer and which audience or use case it suits?
    • Commercial clarity: Does it state the price accurately or explain how the price is determined?
    • Qualification: Does it preserve material limits, required commitments, availability, and exclusions?
    • Verifiability: Can the buyer follow a citation to a page that supports the answer?

    These are separate outcomes. A branded query may show that an assistant recognizes you, while a category query reveals that it does not associate you with the market you serve. A correct plan name does not prove that it understands the billing unit. A citation does not make an outdated price correct.

    Pricing therefore deserves its own audit. The growing focus on what AI agents understand about pricing reflects an important distinction: recognizing a brand and understanding its commercial model are not the same task.

    Build a canonical commercial truth layer

    A glass repository of product, price, date, and customer symbols sends identical information through glowing conduits to several digital channels.

    Your website needs an unambiguous source of record for every fact an assistant might use in a recommendation. Canonical does not mean putting everything on one enormous page. It means that each important question has an authoritative URL and that supporting pages do not contradict it.

    Start by assigning an official page to each type of commercial fact:

    Fact to establishWhat the canonical page should resolveCommon failure to remove
    Brand identityOfficial name, website, product names, and the relationship between the company and its productsOld names, inconsistent capitalization, or several pages describing the same entity differently
    Category and audienceWhat the offer is, who it is for, the problem it solves, and meaningful limits on fitBrand slogans that never state the category in plain language
    Offer structurePlans, editions, services, add-ons, and how they relate to each otherPlan names without an explanation of what changes between them
    Pricing mechanicsCurrency, billing cadence, billing unit, included usage, additional fees, and overage treatmentA price displayed without enough context to interpret it
    QualificationMarket availability, eligibility, minimum commitments, exclusions, and when a custom quote is requiredImportant conditions hidden in a tooltip, checkout flow, or sales conversation
    FreshnessWhether the information is current and where changed or retired offers now liveExpired campaign pages and old documentation remaining discoverable

    Write the central facts in visible HTML text. A calculator, toggle, configurator, or comparison widget can help a buyer, but it should not be the only place where the billing model is explained. If the critical answer appears only after a login or interaction, any system that cannot reach that state will have an incomplete record.

    Use literal language before persuasive language. Your category statement should name the category, audience, and primary use case. Your pricing statement should connect the amount to its currency, unit, cadence, and conditions. Headlines such as “built to scale with you” can support positioning, but they cannot carry these facts.

    Maintain a commercial-facts inventory alongside your content calendar. For each important claim, record its approved wording, canonical URL, content owner, structured-data location, last review, and every supporting page that repeats it. When a plan or policy changes, this inventory tells you what must be updated instead of leaving old claims scattered across the site.

    A safe publishing sequence is:

    1. Update the canonical product or pricing page.
    2. Update the matching JSON-LD in the same release.
    3. Revise comparison pages, FAQs, documentation, and relevant market-specific pages.
    4. Replace, redirect, or clearly mark obsolete offer pages.
    5. Check external profiles you control for conflicting descriptions or prices.
    6. Retest the buyer questions affected by the change.

    Make every pricing model answerable without inventing certainty

    Price visibility does not require every company to publish a universal amount. It requires you to explain the commercial model as far as you truthfully can. The right treatment depends on whether your offer has public list pricing, negotiated pricing, or a mixture of fixed and variable charges.

    Public list pricing

    A bare amount is not a complete price fact. Write a sentence that remains accurate when removed from the surrounding design: “The [plan] costs [amount] in [currency] per [billing unit] when billed [cadence].” Then state the conditions that materially change what a buyer pays.

    • Name the billing unit, such as an account, user, location, project, transaction, or usage quantity.
    • Distinguish recurring charges from onboarding, implementation, service, or usage charges.
    • Explain what is included and how additional usage is handled.
    • State required commitments or minimum purchases where they apply.
    • Identify the market and currency when pricing differs by region.
    • Separate standard pricing from temporary promotions and eligibility-based discounts.
    • Place material conditions near the amount instead of relying on distant fine print.

    If annual billing changes the effective rate, do not let a monthly-looking amount imply month-to-month availability. Connect the displayed amount to the actual cadence and commitment in the same sentence. If taxes or mandatory fees are excluded, say so where the price is presented.

    Quote-based pricing

    “Contact sales” is a conversion action, not a pricing explanation. If the final amount must be negotiated, publish the mechanics that determine it. This gives an assistant a truthful answer without forcing your team to disclose a range it cannot support.

    • State what is being priced: access, usage, seats, locations, services, outcomes, or a combination.
    • Name the variables that change the quote, such as scale, scope, support, integrations, service level, or contract structure.
    • Clarify whether implementation, migration, training, or support is priced separately.
    • Explain what information a buyer must provide to receive a quote.
    • Publish minimum commitments only when they are approved, current, and generally applicable.
    • Describe which offers require a custom agreement and which can be purchased directly.

    Do not publish a speculative “typical” price merely to fill the gap. A false anchor can be repeated without the negotiation context that would have corrected it. If commercial or legal constraints prevent disclosure, be explicit about what remains variable and give the buyer a direct path to the current answer.

    Hybrid and usage-based pricing

    Hybrid offers are especially easy to misread because a real starting amount can coexist with required variable charges. Bind every “starts at” claim to the scope it actually covers.

    • Identify the base charge and what it includes.
    • Name the event that creates a variable charge.
    • Explain whether usage resets, rolls over, or is measured across a longer contract period.
    • Separate optional add-ons from charges required for the represented use case.
    • Show where a published tier ends and custom pricing begins.
    • Explain whether displayed examples are illustrative or purchasable configurations.

    Do not use a low starting price as the headline if the represented customer cannot buy a functional version at that price without mandatory additions. The issue is not only conversion ethics. An assistant can detach the amount from its qualifier and present it as the price of the whole offer.

    Use JSON-LD to confirm the visible truth, not replace it

    Structured data is a clarification layer. It can name entities, connect products to offers, and make commercial fields easier to interpret. It cannot turn missing, inaccessible, or contradictory page copy into a reliable claim.

    Model the smallest set of facts you can keep correct:

    • Give the organization or brand a stable @id, official name, canonical url, and carefully selected sameAs references.
    • Represent the actual subject of the page as a Product or Service when appropriate, and connect it to the organization that provides it.
    • Use an Offer only for a real offer. Its price, currency, availability, and URL must agree with visible content.
    • Use AggregateOffer only when the page presents a genuine range composed of real offers. Do not manufacture a range from unrelated packages.
    • Use pricing specifications only when they accurately express the billing unit, recurrence, or other commercial structure shown to the visitor.
    • For quote-based services, describe the service and quote path without encoding a placeholder as though it were a purchasable price.
    • Keep entity identifiers stable when URLs or templates change so that your own markup does not imply several disconnected brands or products.

    Validate syntax and meaning separately. A parser can confirm that the JSON is well formed, but it cannot decide whether the amount is current or whether the offer actually includes what the page implies. Have a reviewer compare each commercial property with the visible sentence that supports it. If no sentence supports a property, either add the explanation or remove the property.

    Make pricing content and pricing schema part of the same publishing event. Updating the page now and leaving the markup for a later ticket creates two versions of the truth. The same rule applies to currency, availability, plan names, and retired offers.

    Structured data can reduce ambiguity, but it does not guarantee that an assistant will retrieve, cite, or repeat the page. Treat JSON-LD as useful redundancy inside a wider evidence system: clear visible copy, consistent owned pages, stable URLs, accurate external profiles, and independent corroboration where it naturally exists.

    Audit AI answers as a buyer journey, then fix the costly gaps

    An investigator examines a glowing path from search to checkout, highlighting broken links where price and product information are missing or mismatched.

    A useful AI visibility audit starts with prompts, not brand mentions. Build a fixed set from the questions customers ask during discovery, evaluation, pricing, and comparison. Preserve the wording so that later tests remain comparable.

    Your prompt set should cover:

    • Category discovery: “Which [category] options fit [audience and use case]?”
    • Constraint discovery: “Which [category] options support [required capability, market, or buying constraint]?”
    • Brand understanding: “What does [brand] offer, and who is it designed for?”
    • Price retrieval: “What does [brand or product] cost for [defined scenario]?”
    • Price mechanics: “Does [brand] charge by [possible unit], and what additional charges apply?”
    • Comparison: “Compare [brand] with [alternative] for [specific use case and constraint].”
    • Verification: “Where can I confirm [brand’s] current plans, pricing, or availability?”

    Use the same scenario details that materially affect a real quote. A generic “What does it cost?” prompt may test brand recognition, but it cannot reveal whether the assistant understands seats, usage, locations, contract structure, or implementation charges.

    Run the set across the assistants your audience uses, including ChatGPT, Claude, and Perplexity when they are relevant to your market. Record enough context to make the observation interpretable:

    • The exact prompt and scenario variables
    • The assistant, product surface, and model name when exposed
    • The market, language, signed-in state, and personalization conditions
    • The complete answer rather than a paraphrased note
    • Every cited URL and whether it supports the attached claim
    • Whether the brand is absent, merely mentioned, described, compared, or recommended
    • Whether each material price fact is correct, partial, wrong, or unverifiable
    • The canonical page that contains the approved answer

    Do not collapse this into a single visibility percentage. An uncited but accurate mention, a cited false price, and a correct recommendation for the wrong audience create different problems. Classify the failure before choosing the fix.

    Observed answerLikely gap to investigateNext action
    Your brand is absent from non-branded category promptsThe category relationship may be weak, ambiguous, or poorly corroboratedStrengthen the canonical category statement, relevant use-case pages, internal links, and truthful third-party descriptions
    Your brand appears but is assigned to the wrong audiencePositioning language is broad or inconsistent across pagesName the intended audience, use cases, and exclusions in plain language on the canonical product page
    The answer says pricing is unavailableThe price or pricing model may be hidden behind interaction, vague copy, or a sales formPublish an accessible pricing summary or a concrete explanation of quote variables
    The answer gives an old price or retired planObsolete pages or conflicting structured data remain discoverableUpdate the canonical page and schema, then replace, redirect, or mark outdated URLs
    The amount is correct but the unit or commitment is wrongThe qualifier is separated from the amount or expressed only in interface controlsPut amount, currency, unit, cadence, and commitment in the same visible statement
    The answer is accurate but cites another siteYour page may not provide a concise, stable, directly supporting passageAdd a clear answer on the canonical URL and make its evidence easy to verify
    Different assistants produce conflicting answersThe evidence may be inconsistent, stale, unavailable to some systems, or interpreted differentlyTrace each claim to its cited URL and repair the conflicting facts instead of assuming one universal cause

    Prioritize by consequence. Correct false current prices, fabricated fees, wrong availability, and misleading commitments before pursuing more mentions. Then repair missing answers on high-intent pricing and comparison prompts. Category breadth and uncited awareness can follow once the buying facts are safe.

    Keep evidence from each audit because generated answers can vary with product surface, context, and time. A saved answer, prompt, citation set, and test conditions let you distinguish a persistent information problem from an isolated response. Do not promise that a page edit will deterministically change every assistant; test again after the updated information has had a reasonable opportunity to become discoverable.

    Key takeaways

    • Commercial AI visibility means that a buyer can identify your brand, understand its fit, interpret its pricing, and verify the answer.
    • Give every important brand and pricing fact a canonical URL, then remove contradictions from supporting pages and profiles.
    • If pricing is negotiated, publish the pricing model and quote variables instead of inventing a representative amount.
    • Make JSON-LD match visible content exactly; valid syntax does not rescue stale or misleading commercial data.
    • Measure real discovery and buying prompts, not mention volume alone.
    • Fix incorrect price, availability, and commitment claims before trying to expand category reach.

    Start with the commercial question most likely to block your next buyer. Run it across the relevant assistants, capture exactly what is missing or wrong, and repair the canonical page that should own the answer. Once that answer is accurate and verifiable, move to the next decision in the journey. The first meaningful gain is not a larger mention count. It is fewer opportunities for an AI system to make your offer wrong, vague, or impossible to evaluate.

    References

  • AI Visibility Signals: A Practical Framework for PPC

    AI Visibility Signals: A Practical Framework for PPC

    Your PPC account can look technically healthy while attracting buyers who expect the wrong service, product, price point or level of support. Search terms and conversion tracking show the resulting behavior, but they may not reveal where that expectation began.

    AI visibility signals add the missing pre-click context. They help you see how an AI system interprets a need, which information it retrieves and whether your brand helps shape the response. Used alongside PPC evidence, that context can tell you whether to adjust targeting, clarify a landing page, test new messaging or leave the campaign alone.

    Three signals fill the pre-click blind spot

    Conventional PPC analysis begins with observable activity: a search, an impression, a click, a visit or a conversion. AI can influence the buyer earlier by shaping what they know, which brands enter consideration and which words they later use. AI visibility data does not replace PPC reporting or prove that an AI response caused a conversion. It shows the informational environment surrounding the demand you are trying to capture.

    SignalWhat it revealsBest PPC useWhat it does not prove
    Grounding queriesThe retrieval searches an AI system uses to support a response, including the topics and sub-questions it associates with the original need.Diagnose intent, find useful language and identify possible keyword, search-theme, creative or landing-page tests.That every retrieved phrase should become a keyword.
    CitationsWhether your content was referenced while an AI-generated answer was assembled.Check whether the topics shaping consideration reinforce the promises in your campaigns.That the AI endorsed your brand, sent a visitor or produced a customer.
    Share of authorityHow much citation activity belongs to your domain relative to other cited domains in the same topic or query set.Locate topics where competitors help define the answer more often than you do and decide whether the gap is commercially important.Paid impression share, market share, brand sentiment or conversion probability.

    A single prompt can generate multiple grounding queries about comparisons, pricing, reviews, product details, availability or implementation. That makes grounding data richer than a keyword list, but also easier to misuse. It represents the system’s interpretation of intent, not a direct record of what a person typed.

    Citations need similar restraint. A citation means that a page contributed information to an AI experience. It does not tell you, on its own, whether the reference was prominent, favorable or persuasive. Review the associated topic and the cited page before deciding that a citation is commercially useful.

    Share of authority is comparative, so preserve the comparison. Use the same topic definition and query set when you evaluate changes. A number drawn from one prompt set should not be compared casually with a number drawn from another.

    Diagnose alignment across AI, ads, pages and customers

    An abstract AI node, ad tile, landing page and customer group connect through a central lens, with one amber path visibly out of alignment.

    The useful question is not whether your brand has AI visibility. It is whether AI interpretation, customer searches, advertising, landing-page claims and customer quality describe the same commercial offer.

    Trace one intent cluster through this sequence: AI interpretation, search behavior, ad promise, landing-page proof and business outcome. A break between two stages gives you a more specific diagnosis than a general visibility score.

    • AI and PPC intent align, and conversion quality is strong: you have a candidate for a controlled expansion test. Confirm that the landing page supports the intent before adding broader matching or automation.
    • AI interpretation and paid search terms drift in the same unwanted direction: the account may be reflecting a broader positioning problem. Clarify the offer and the audience before increasing bids or budget.
    • AI interpretation is wrong, but paid search terms and customers remain well aligned: treat this first as a content and brand-representation issue. Do not disturb a healthy campaign merely to react to an isolated AI signal.
    • AI interpretation is accurate, but paid search terms or customers are poor: investigate campaign matching, search themes, exclusions, ad promises and landing-page continuity. The evidence points more directly to the paid journey than to AI representation.
    • Competitors hold more citation activity for an important topic, but your PPC performance is healthy: inspect the content gap without assuming that paid budgets need to change. Share of authority is context for strategy, not a bidding instruction.

    Judge conversion quality using the downstream outcome your business actually values: customer fit, sales qualification, purchase value, retention potential or another established business measure. A form submission from the wrong customer can make campaign automation appear successful while teaching it to pursue more of the wrong demand.

    Topic alignment deserves particular attention. A cybersecurity platform seeking enterprise identity-protection buyers has a real problem if AI systems consistently associate it with small-business antivirus comparisons. The phrases are related at a broad category level, but they imply different customers, requirements and buying paths. That kind of mismatch can look like a targeting failure even when unclear positioning is the underlying issue.

    Build a repeatable AI-to-PPC analysis

    You do not need to pour every AI observation into the ad account. You need a repeatable method that separates evidence, interpretation and action.

    1. Write down the commercial truth first. State what you sell, who it is for, which problems it solves and which adjacent use cases you do not want to attract. This becomes the standard against which AI associations are judged.
    2. Choose a fixed set of commercially meaningful prompts. Cover the decisions that matter to your buyers, such as comparisons, pricing, reviews, product details, availability and implementation. Keep the set stable when you want to compare observations over time.
    3. Capture the AI evidence without interpreting it yet. Record the original prompt, grounding queries, cited domains and URLs, associated topics and share-of-authority result. Also record the AI surface, market and observation date so later comparisons retain their context.
    4. Cluster by underlying need. Group retrieval queries that express the same decision or problem even when their wording differs. Do not require an exact phrase match between a grounding query and a paid search term.
    5. Join each cluster to PPC evidence. Review related search terms, campaigns, ad promises, landing pages and conversion quality. Note whether AI and paid data point toward the same buyer and offer.
    6. Classify the association. Mark it as core, adjacent, misleading or unclear. Core means it matches a priority offer and customer. Adjacent means it is accurate but not a growth priority. Misleading means it describes something you do not sell or a customer you do not want. Unclear means the available evidence is insufficient.
    7. Write a testable diagnosis. Use a sentence such as: Because the AI evidence and PPC evidence both associate us with this lower-value need, we will clarify one page and one ad message, then judge whether customer quality improves.
    8. Prioritize corroborated patterns. Give more weight to an interpretation that appears across grounding queries, citations, search terms, landing-page language and customer quality. Log isolated observations, but do not let them trigger an account-wide change.

    A practical worksheet can use one row per intent cluster. Include the desired customer, grounding-query examples, cited topic, citation status, share-of-authority context, related paid search terms, current landing page, conversion-quality finding, alignment classification, working diagnosis, proposed action and success measure. Keeping those fields in one place stops a visibility observation from being mistaken for a campaign instruction.

    This process also prevents a common attribution error. AI visibility can help explain the context surrounding demand, but it cannot tell you that a specific citation caused a specific click or sale. Use conversion tracking for measured outcomes and AI visibility for interpretation.

    Turn the diagnosis into a controlled PPC test

    Two parallel marketing test lanes use the same audience inputs while one highlighted element differs between their ads and landing pages.

    When AI and PPC data expose a mismatch, resist the reflex to change bids. Audit the relevant landing page before assuming that budget, bidding or audience targeting is at fault. Check whether the page clearly identifies the problem being solved, supports its advertising claims with appropriate proof and describes the customer you actually want.

    Choose the smallest lever that can test the diagnosis

    • Test a keyword or search theme when the grounding-query cluster represents demand you genuinely want, related search terms show useful intent and an appropriate landing page already exists.
    • Test creative when AI and customers use accurate language that your ads fail to reflect, or when the ad needs to distinguish your offer from a nearby but lower-value category.
    • Update a landing page when the page blends several offers, fails to identify the intended customer or lacks proof for the promise made in the ad.
    • Update supporting content when useful comparison, product-detail or implementation questions appear repeatedly but your site does not answer them clearly.
    • Test AI-supported campaign matching when you find many relevant grounding queries, the offer is represented accurately and conversion quality can be measured. Performance Max, AI Max and other AI-supported campaign types can be candidates, but the grounding data remains an input rather than an instruction.
    • Make no campaign change when the observation is isolated, commercially unimportant or contradicted by stronger PPC and customer evidence. Preserve it for later comparison.

    Change as little as the diagnosis requires. If you rewrite the landing page, broaden matching, replace creative and alter the bidding strategy at the same time, you will not know which change affected customer quality. A bounded test should connect one documented interpretation problem to one primary lever and one business outcome.

    Protect the account from false inferences

    • Do not paste grounding queries into a keyword list without checking commercial fit, customer fit and landing-page support.
    • Do not call a citation a conversion, endorsement or attributable visit.
    • Do not treat share of authority as paid impression share or use it to allocate budget mechanically.
    • Do not broaden automation while the offer is described inconsistently across ads, pages and supporting content.
    • Do not judge success only by click-through rate or conversion count when the diagnosis concerns buyer quality.
    • Do not compare share-of-authority observations built from materially different topics, prompts or market contexts.

    AI-powered features such as final URL expansion, asset optimization and broader matching depend on interpretations of your pages and offers. If AI visibility reporting shows that the brand is being misunderstood, campaign automation may inherit some of the same confusion. Clear positioning is therefore a prerequisite for a sensible expansion test, not a cosmetic content task to postpone until later.

    Worked example: executive coaching versus sales training

    Suppose a B2B company sells executive coaching, but its grounding queries repeatedly cluster around tactical sales-training courses. Paid search terms also contain training-led intent, and the landing page uses coaching, training and advisory language interchangeably.

    The wrong response is to add every grounding query as a keyword or raise bids because the topic appears relevant. The better diagnosis is that AI interpretation, paid demand and page language all blur two offers that attract different buyers, expectations and conversion paths.

    1. Clarify the priority landing page around executive coaching, the intended buyer and the problems the engagement addresses.
    2. Qualify or remove tactical training language where it misrepresents the priority offer.
    3. Align ad creative with the same distinction.
    4. Use campaign controls to reduce clearly unwanted training intent where the PPC evidence supports that decision.
    5. Judge the test by customer fit and sales quality, not merely by the number of submitted forms.
    6. Consider broader AI-supported matching only after the offer is represented consistently.

    That sequence turns AI visibility into a falsifiable PPC hypothesis. It also preserves the possibility that the diagnosis is wrong: if customer quality does not improve after the message is clarified, return to the evidence instead of declaring the visibility signal predictive.

    Key takeaways

    • AI visibility adds pre-click context; it is not a replacement for PPC reporting or attribution.
    • Grounding queries reveal how an AI system decomposes intent, but they are not keywords.
    • Citations show participation in an AI-generated answer, not endorsement, traffic or conversion.
    • Share of authority compares citation activity within a defined topic or query set; it is not impression share.
    • The strongest diagnosis connects AI interpretation with search terms, landing-page language and conversion quality.
    • Fix a representation problem before asking broader matching or campaign automation to scale it.
    • Use one bounded change and a business-quality outcome to test each diagnosis.

    At your next PPC review, choose one commercially important intent cluster and add grounding queries, citations and share-of-authority context to the evidence you already use. If the same mismatch appears in AI interpretation, paid search behavior and customer quality, you have a specific problem worth testing. If it does not, keep observing rather than forcing the account to react.

    References

  • How Content, Entities and Category Framing Shape AI Visibility

    How Content, Entities and Category Framing Shape AI Visibility

    You have useful content, a clean About page and valid organization markup. Yet your brand still disappears when someone asks an AI assistant for options in your market. The missing piece may not be authority. The system may know who you are without considering you eligible for the category named in the prompt.

    You can diagnose that problem by separating three jobs: establish the category in which you belong, make the relevant entities and relationships unambiguous, and publish evidence that supports recommending you for the user’s task. That distinction turns AI visibility from a vague branding exercise into work you can assign, test and improve.

    Key takeaways

    • Brand recognition and recommendation eligibility are different. An AI system can identify your company accurately and still exclude it from an unbranded category answer.
    • Choose category language before planning content or schema. Your primary category should describe what you sell now; adjacent categories should reflect real customer language and a defensible part of your offer.
    • Build an entity map before building more pages. It should connect your organization, offers, audiences, problems, methods, people, proof and category claims.
    • Use JSON-LD to declare facts that visible content already supports. Schema can reduce ambiguity, but it cannot manufacture relevance or compensate for missing evidence.
    • Category association is also built away from your website. Relevant reviews, editorial coverage, comparisons and co-mentions help establish the contexts in which your brand is considered.
    • Measure recognition, category eligibility, recommendation and supporting evidence separately. A single visibility score hides the reason you are being omitted.

    First, determine whether you have a recognition or category problem

    Start with two prompts that look similar but test different things:

    • Recognition prompt: What is [Brand], and what does it offer?
    • Category prompt: Which [category] providers should [audience] consider for [task]?

    If the first answer is accurate and the second omits you, rewriting your About page again is unlikely to address the main constraint. Your entity is recognized, but it is not being retrieved or selected in that category context.

    Observed resultLikely problem to investigateBest first check
    Your brand is described incorrectly when namedEntity ambiguity or inconsistent factsCompare names, descriptions, offers and relationships across core pages, markup and authoritative profiles
    Your brand is understood but absent from an unbranded category promptWeak category associationInspect the categories used in your own copy and in third-party coverage
    You appear for a primary category but not an adjacent oneCategory-specific evidence gapLook for useful content and independent mentions that connect you to the adjacent category
    You are included but the recommendation rationale is vagueWeak differentiation or insufficient proofIdentify which claims lack examples, evidence or a clear audience fit
    A relevant page is cited but your brand is not recommendedInformational relevance without brand-level eligibilityCheck whether the page clearly connects its subject, your offer and the user’s decision

    The effect of category wording can be substantial. A controlled test covering 14,140 API runs across ChatGPT, Gemini, Perplexity, Claude and Google AI Overviews evaluated 12 athletic apparel brands in the U.K. over seven days. Changing the category from athleisure to athletic footwear moved New Balance from a 1% appearance rate to 90%, while lululemon moved from 90% to 0%.

    That is strong evidence that framing controlled recommendation behavior in that test. It is not a universal performance benchmark: one market, one prompt design and one testing period cannot establish how every model will treat every category. The practical lesson is narrower and more useful. Test the category noun instead of assuming that general brand strength transfers across every way a customer might describe your market.

    Define one primary category and a small set of adjacent frames

    Your primary category should be the plainest accurate answer to: What kind of provider, product or organization is this? An adjacent frame is a different but truthful way a buyer may classify the same offer. For example, a platform may belong firmly to one software category while also serving a narrower workflow, audience or outcome category.

    Do not collect every loosely related label. For each candidate category, record:

    • Customer language: Do real buyers use this term when expressing the need you solve?
    • Offer fit: Can you point to a current product, service or capability that makes the label true?
    • On-site evidence: Is the category explained on a crawlable page, or does it appear only in a slogan?
    • Independent evidence: Do credible third parties discuss you in that context or alongside established members of the category?
    • Decision value: Would visibility for this category attract the audience and use case you actually want?

    Then write a control sentence: [Brand] is a [primary category] for [audience], helping them complete [task] through [offer or method]. Treat this as an editorial constraint, not a slogan and not a Schema.org type. Every element must be demonstrably true, and the same relationship should be understandable from your core pages.

    Build an entity map that gives every page a job

    An isometric network connects a central organization node with separate tiles representing products, people, locations, expertise, and customer tasks.

    Once the category is chosen, map the things a search system must connect to decide that you belong. Entities are not limited to your company and founder. They include products, services, people, audiences, locations, problems, methods, features and other identifiable concepts. The useful unit is not an isolated noun; it is a relationship that helps explain the brand.

    Create an entity ledger with one row for each important relationship:

    • Subject: the organization, person, offer, category, audience or problem being described.
    • Relationship: offers, serves, solves, teaches, authored, includes, supports or another accurate connection.
    • Object: the entity on the other side of that relationship.
    • Visible evidence: the page and passage where a reader can verify the claim.
    • Structured declaration: the standards-supported markup, if any, that can express it accurately.
    • Independent corroboration: a review, profile, comparison, citation or other external evidence.
    • Gap: missing, vague, contradictory or fully supported.

    Use those relationship words as planning labels. They are not automatically valid Schema.org properties. Your conceptual model can and often should be richer than the standardized vocabulary you publish.

    This distinction matters in specialized markets. One higher-education framework found that 23 existing Schema.org entities were insufficient and added more than 60 domain-specific concepts to represent a prospective student’s journey. You can use a custom ontology internally to expose content gaps without pretending that proprietary terms are recognized Schema.org vocabulary.

    Turn the map into a content system, not one oversized page

    Assign each important relationship to a canonical page. Your About page should establish organization identity and positioning. An offer page should explain what the offer does, whom it serves and how it differs. A method page should explain the process. A use-case page should connect a specific audience and task to the offer. An author page should establish the person behind relevant expertise. Supporting resources should answer the questions that arise before and after the main decision.

    This division helps with the way AI search may expand a request. A query can trigger related searches across subtopics and data sources so that the system can assemble an answer to the broader task. A buyer asking for a category recommendation may also need selection criteria, implementation details, limitations, alternatives, audience fit and next steps. One page does not have to answer everything, but your site should make the connections explicit.

    Use this brief for every page you keep or create:

    • Page job: State the single decision or question this page resolves.
    • Primary entities: Name the organization, offer, audience, problem and category involved.
    • Direct answer: Put the answer near the beginning in visible text. Do not make a reader infer it from a slogan, image or schema block.
    • Boundary: Explain who or what the answer is for, where it applies and what it does not cover.
    • Evidence: Support claims with concrete capabilities, examples, authorship or other facts you can substantiate.
    • Related questions: Link to the next useful pages with anchor text that describes the relationship, rather than generic text such as learn more.
    • Duplication check: Merge or differentiate pages that make the same claim about the same entities without serving different intents.

    The standard is comprehension, not length. A clear page names its subject, answers the intended question and connects to the next part of the task. More copy only helps when it adds a missing entity, relationship, condition or piece of evidence.

    Use JSON-LD to declare truth, not manufacture relevance

    Schema is valuable because it can state entities and relationships explicitly in a vocabulary machines already recognize. It is best treated as a declaration layer over a coherent site, not a lever that forces a model to recommend you.

    The evidence does not support a simple claim that adding markup produces more AI citations. Microsoft Bing’s Fabrice Canel stated in March 2025 that Copilot uses schema to understand content, while other published tests found no effect on LLM visibility or no direct reading of on-page schema. Those findings measure different things, including machine understanding, direct model access, citations and observed visibility. Treating them as one outcome creates a false yes-or-no debate.

    A safer operating position is straightforward: accurate markup can reduce ambiguity for systems that consume it, but visibility remains a downstream result influenced by content, retrieval, category fit and external evidence. Do not promise a citation lift from markup alone.

    Implement JSON-LD in this order:

    1. Resolve identity first. Decide which organization, people, offers and other entities are canonical. Use stable identifiers so the same entity is not represented as several disconnected things.
    2. Confirm the visible facts. A reader should be able to verify every material claim in the markup from the page or an appropriate linked page. Structured data should match what users can actually see.
    3. Use established vocabulary where it fits. Choose the most accurate standard types and properties available. Do not force a marketing phrase into a technical type merely because the phrase is commercially important.
    4. Connect entities deliberately. Markup should describe a coherent graph rather than produce unrelated blocks for the organization, author, service and page.
    5. Keep custom concepts separate. Use your internal ontology to plan coverage and analyze gaps. Publish custom terms only where a consuming system understands that vocabulary; do not misrepresent them as standard Schema.org definitions.
    6. Remove decorative markup. If a block exists only to qualify for a feature or repeat keywords, but adds no accurate entity relationship, it is not solving your AI visibility problem.

    When markup and visible copy disagree, repair the underlying page first. Otherwise you are making two incompatible claims about the same entity and asking machines to decide which one is true.

    Create off-site category evidence, then measure the whole system

    Independent source islands send beams through a translucent gateway toward an AI-like orb that highlights one central entity among alternatives.

    Build corroboration in the category you want to earn

    Your site can declare its category, but it cannot independently establish how the wider market describes you. Category coding appears to combine an entity anchor with the third-party material accumulated around a brand, including reviews, editorial comparisons, roundups and co-mentions. This helps explain why editing a description does not instantly move a brand into a different recommendation set.

    Audit the external evidence for each priority category:

    • Which publications, communities and comparison pages appear in AI answers for the category?
    • Which brands are repeatedly mentioned together, and what language is used to explain their inclusion?
    • Which attributes make a provider category-eligible: audience, use case, product form, method, price position or another verifiable characteristic?
    • Where is your brand already mentioned, and which category does that coverage reinforce?
    • Does the cited coverage still describe your current offer accurately?

    Use the findings to shape public relations and content distribution. Give relevant publishers a truthful reason to place your brand in the target context: a category-specific capability, credible expert contribution, useful case evidence or a clear point of view. A generic mention may improve recognition while doing nothing to connect you to the category that matters.

    Do not pursue an adjacent category that your product cannot support. Repetition can amplify an association, but it cannot make a misleading position useful to the customer. Establish the offer and on-site evidence before trying to earn external corroboration.

    Measure recognition, eligibility, recommendation and evidence separately

    Create a controlled prompt matrix for every primary and adjacent category. Keep the audience, task and wording stable, then change only the category expression you want to test. Run each prompt in a fresh conversation so earlier messages do not supply the brand or category context.

    Record these fields for each model and prompt:

    • Recognition: Can the system describe your brand accurately when it is named?
    • Eligibility: Does the brand appear in an unbranded list for the category?
    • Recommendation: Is it merely mentioned, or actively presented as suitable for the audience and task?
    • Rationale: Which capabilities, use cases or associations explain its inclusion or exclusion?
    • Evidence: Which URLs, publishers or page types support the answer?
    • Representation: Are the description, category and sentiment accurate?
    • Conditions: Which model, prompt, date and conversation state produced the response?

    Do not compress these observations into one score until you have inspected them separately. A brand that is recognized everywhere but eligible nowhere has a different problem from one that is regularly recommended with the wrong description.

    Use the pattern to choose the next action:

    • Recognition is weak: reconcile identity, core descriptions, canonical pages, profiles and structured relationships.
    • Recognition is strong but category eligibility is weak: repair category language and build relevant third-party association.
    • Eligibility is strong but recommendation is weak: clarify audience fit, differentiation, limitations and supporting proof.
    • Recommendation is strong but evidence is poor: strengthen pages that make the rationale attributable and easy to cite.
    • Results differ sharply by category: plan content and outreach for each frame independently instead of treating visibility as a brand-wide property.
    • Results differ sharply by model or prompt: preserve the raw responses and gather more controlled observations before declaring a trend.

    Prioritize gaps using three questions: Does this category matter commercially? Is the missing association visible across controlled prompts? Can you support it truthfully with your present offer and evidence? A high-volume label that fails the third test is not an optimization opportunity. It is a positioning error.

    Start with one primary category and one defensible adjacent frame. Run the prompt matrix, map the entities behind both, assign each important relationship to a page, align visible copy with JSON-LD, and then pursue independent coverage in the context that is still missing. That sequence gives you something more useful than a visibility score: a reason for the result and a specific next move.

    References
  • Why I Stop Positioning AI as a People Replacement

    Why I Stop Positioning AI as a People Replacement

    I think one of the biggest mistakes in AI marketing is positioning a product as a replacement for people. That message can win attention in the short term, but I believe it quietly drains trust over time.

    This is a little different from what I usually write about, but it matters. The way we talk about AI shapes how customers, employees, executives, and markets respond to it.

    In this memo, I want to focus on three things: why “substitution positioning” feels powerful at first but weakens a brand later, what the data says about whether AI is actually replacing people, and how I think companies should position AI instead.

    Image

    The cardinal sin of positioning in the AI era is replacement. I call it substitution positioning. It is tempting because it sounds bold, efficient, and disruptive. But over time, it creates anxiety, skepticism, and credibility problems.

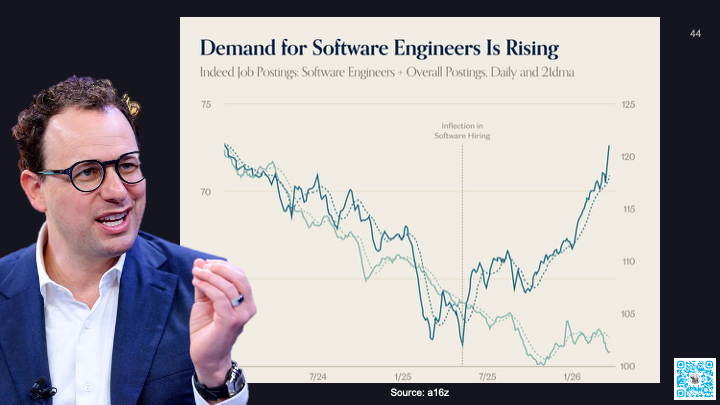
    We have seen this pattern already. Anthropic CEO Dario Amodei predicted that software engineering jobs could disappear within 6 to 12 months as models began doing most or all of what software engineers do end to end. Yet demand for software engineers has continued to look strong.

    Image

    OpenAI CEO Sam Altman also predicted that many customer support jobs would go away because AI could handle that work better. Soon after, customer service hiring began outpacing the broader job market.

    I understand why fear works as a marketing tool. The fear of being replaced gets attention fast. It got me, too. When powerful AI models gained traction, I worried about my own future. But when I still see AI companies hiring copywriters, SEOs, engineers, and support teams, I sleep better.

    Image

    Fear sells because it taps into fight-or-flight. Layoffs make that story even louder. They let companies frame cost-cutting as innovation and make the replacement narrative feel more real than it may actually be.

    But I do not think the facts support the clean replacement story. In New York, companies can indicate when mass layoffs are caused by technological innovation or automation. In one reported period, more than 160 companies filed mass layoffs affecting roughly 28,300 workers, and not one chose AI as the reason. That list included companies such as Amazon and Goldman Sachs.

    Image

    Researchers at Yale also studied employment data from the Current Population Survey over 33 months and found no evidence of job displacement from AI. To me, the pattern looks less like instant replacement and more like the earlier waves of computers and the internet changing how work gets done.

    That is why I keep coming back to this point: stop trying to make replacement happen. It is not happening in the simple, dramatic way many AI narratives suggest.

    Image

    AI is powerful, but it is also inconsistent. In its current form, it can do some tasks better than humans and fail badly at others. That paradox is often called the Jagged Frontier.

    The Jagged Frontier idea matters because it explains why some people see AI as transformative while others remain lukewarm. A BCG and Harvard study of 758 knowledge workers found that people get the most value from AI when they understand what it is good at and where it breaks down.

    Image

    Microsoft reached a similar conclusion in its 2026 Work Trend Index Annual Report. The company found that a small group of advanced AI users, described as Frontier Professionals, were not simply using AI more often. They also knew which mode of AI use fit each task.

    That distinction is important. The best AI users are not handing everything over blindly. They are applying judgment. They know when to use AI as a helper, when to use it as a collaborator, when to use agents for multi-step workflows, and when to keep a human firmly in control.

    Image

    I still do not trust most AI workflows enough to leave them running with no maintenance, review, or quality assurance. The question I ask is simple: would I bet my brand, customer experience, or revenue on a fully automated workflow with no human oversight?

    Klarna is a useful warning here. The company publicly promoted the idea that AI was doing the work of hundreds of agents and helping reduce headcount. Later, it reversed course and rehired humans after leadership acknowledged that aggressive cost-cutting had lowered quality and that customers still wanted a human option.

    Image

    That is the tradeoff I see with substitution positioning. It creates immediate attention, but it can damage long-term credibility. The words often do not match the operational reality.

    Replacement positioning could work if customers truly wanted full replacement and if the technology were consistently ready for it. I do not think either condition is true.

    Image

    Cost reduction is a strong AI argument because it shows up quickly on the P&L. Productivity gains usually take longer. They build inside companies over time and often take even longer to appear across the broader economy.

    But when replacement positioning goes beyond cost-cutting and becomes people-cutting, I believe it starts to antagonize the very people companies need to win over.

    Image

    We have already seen backlash. Duolingo’s AI-first memo drew heavy criticism before the company reframed AI as a tool to accelerate work rather than replace contractors. Surveys have found that some workers refuse to use AI tools because they fear job loss. Pew has reported that many U.S. adults are more concerned than excited about AI in daily life. Reuters/Ipsos polling has shown widespread fear that AI will permanently displace workers.

    There is also a quality problem. When employees believe the purpose of AI is to replace them, they may disengage or produce lower-quality work. In my view, that is not just an adoption issue. It is a positioning failure.

    Image

    Executives often feel more excited about AI than the employees asked to use it every day. That gap matters. If leadership talks about AI as a replacement engine, employees hear a threat. If leadership talks about AI as leverage, employees have a reason to learn.

    Token economics also complicate the replacement story. Some companies have bragged about massive AI usage, but token costs are still a real business variable. As those costs normalize, the math may make junior employees look interesting again, especially when human judgment, context, and accountability are part of the output.

    So what should replace replacement? I think the answer is enhancement. Instead of positioning AI as a way to remove people, I would position it as a way to make capable people more effective.

    AI can be used in two broad ways. A company can try to reduce the number of people, or it can grow output with the same number of people. The data I have seen suggests that productivity gains often create the stronger return.

    A National Bureau of Economic Research paper surveyed 750 executives about AI’s impact on productivity and labor markets. Larger firms showed more interest in replacing labor costs, but the highest ROI came from productivity growth.

    That is the lesson I take from the research: doing more with the talent you already have is often stronger than trying to remove the talent that knows what good work looks like.

    Building products has become easier, but distribution has not. When supply explodes, the scarce thing is not output. The scarce thing is being the product, brand, or service that actually gets chosen.

    That is why positioning matters more than ever. Product quality still matters, but the way I frame AI use can determine whether people see it as empowering or threatening.

    My takeaway is simple: I would stop selling AI as a people replacement. I would sell it as judgment leverage, workflow acceleration, and creative expansion. Fear can get attention, but empowerment is a better long-term strategy.

    This post first appeared on the author’s website and is republished here with permission.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Choose a Healthcare or Senior Care Marketing Agency

    How to Choose a Healthcare or Senior Care Marketing Agency

    Healthcare and senior care agencies may appear in the same search results, but they are often built for different growth problems. A provider seeking more booked appointments, a senior living community trying to build local trust, and a medical technology company pursuing enterprise buyers need different channels, expertise, and success measures.

    The useful starting point is therefore not a single league table. It is a clear definition of the audience, conversion event, sales cycle, and evidence an agency must provide. Three 2026 agency reports offer complementary views of that decision: content marketing, healthcare lead generation, and senior living marketing.

    Key takeaways

    • Choose by growth problem first: authority building, patient or resident acquisition, complex B2B outreach, and senior living brand development require different capabilities.
    • Healthcare specialization is most valuable when it affects execution, including audience knowledge, channel selection, content quality, local discovery, and the handling of long buying cycles.
    • Published rankings are useful for forming a shortlist, but their results depend heavily on the criteria and weights selected by the publisher.
    • Reported ROI, client rosters, reviews, and leadership experience should be treated as due-diligence leads rather than substitutes for direct verification.
    • The strongest proposal should connect marketing activity to a meaningful conversion, such as a qualified sales conversation, appointment, inquiry, or community tour.

    Start with the growth job, not the agency category

    A strategy team reviews three object-based customer journeys leading to a healthcare appointment, a senior living visit, and a business handshake.

    The three reports collectively describe at least four distinct agency jobs. Content-led firms build visibility and authority through expert material and search. Patient-acquisition specialists use channels such as paid search, paid social, and local SEO to generate appointments. B2B lead-generation firms pursue decision-makers through thought leadership or outbound appointment setting. Senior living specialists combine digital discovery with branding, traditional media, marketing automation, or call handling.

    Those jobs are related, but they are not interchangeable. The healthcare lead-generation report characterizes Cardinal Digital Marketing as a patient-acquisition specialist for multi-location provider groups and management service organizations, while noting that its model is less suited to B2B medtech or health IT. The same report describes Revnew as a fit for medical device and pharmaceutical organizations where precise targeting across a long sales cycle matters more than high lead volume. That contrast illustrates why a broad claim such as “healthcare expertise” is not enough.

    Senior living introduces another distinction. Its specialist report identifies agencies oriented toward community branding, local visibility, traditional advertising, automation, and inquiry management. A senior living operator should consequently decide whether the immediate constraint is awareness, lead capture, follow-up, or conversion before comparing agencies.

    Map the reported agencies to the work they emphasize

    The source reports support a practical market map rather than one universal ranking. The following groupings reflect how the reports described each firm; they do not independently verify agency performance.

    Marketing needAgencies highlighted by the reportsReported emphasis
    Search authority and expert contentFirst Page SageThe lead-generation report highlights SEO, generative engine optimization and long-form thought leadership for complex healthcare buyers. The senior living report also associates the firm with SEO, trust-building content and visibility in AI-driven search.
    Integrated B2B healthcare demand generationSagefrog Marketing GroupBrand strategy, HubSpot-powered inbound programs and paid media. The lead-generation report presents it as a cohesive, brand-led option rather than a rapid outbound program.
    Provider and patient acquisitionHealthcare Success; Cardinal Digital MarketingHealthcare Success is described as serving hospitals, multi-location practices, urgent care and addiction treatment through broad strategy, local SEO and paid search. Cardinal is positioned around coordinated PPC and paid social for appointment volume.
    Specialized or scaled B2B outreachRevnew; Belkins; Callbox; Launch LeadsRevnew is associated with precise outreach for complex medical sales. Belkins, Callbox and Launch Leads are presented as appointment-setting options, with varying emphasis on multichannel outreach, CRM integration, scale and entry into new markets.
    Senior living brand and demand programsLove & Company; SenioROI; Senior Living Smart; Comrade Digital Marketing; Markentum; Senior Living Marketers; SageAge; Five19The senior living report spans brand strategy, traditional media, automation, call-center management, local SEO, paid advertising, social media and creative positioning. The range indicates that these firms should be compared by service model rather than treated as equivalent.

    The content-marketing report adds a broader screening perspective. It says roughly 60 healthcare content agencies were evaluated and eight selected using experience, specialties, notable clients, and reviews. The supplied report summary does not provide the individual profiles, so its main contribution to this synthesis is methodological: content credentials should be assessed alongside sector fit and external reputation.

    Read rankings as signals shaped by their methodology

    The lead-generation report says its team evaluated 63 U.S. agencies from March through May 2026 and selected eight. Industry-specific expertise accounted for 25% of its score, reported average client ROI for 20%, notable clients and customer reviews for 15% each, leadership experience and media references for 10% each, and specialty for 5%. It says review scores were aggregated from platforms including G2, Clutch, and Google Reviews.
    The senior living report uses a substantially different formula. Notable clients and average review score each account for 30%, leadership experience for 25%, year established for 10%, and median employee tenure for 5%. As a result, an established agency with a recognizable portfolio and strong reviews can perform well even if another firm is better suited to a particular channel or operating model.

    This does not make either ranking unhelpful. It makes the scoring logic part of the evidence. A buyer prioritizing outbound pipeline quality should not automatically adopt the result of a model that heavily rewards public client rosters. Likewise, a community seeking an enduring brand partner may reasonably value leadership continuity and experience more than a narrowly defined lead metric.

    The lead-generation report also publishes agency-level ROI figures derived from case studies and results reported by the agencies. Those figures are useful prompts for investigation, but they are not presented as independently audited comparisons. Differences in attribution windows, revenue definitions, deal sizes, and included costs can make superficially similar ROI numbers measure different things.
    Build a shortlist that can survive direct scrutiny

    Two healthcare executives examine three shortlisted agency evidence folders with a magnifying glass and blank comparison cards.

    A defensible selection process converts broad claims into evidence tied to the prospective engagement. That means testing whether an agency has solved a comparable audience and conversion problem, not merely whether it has displayed a healthcare logo.

    Decision areaEvidence to requestWhat the evidence should clarify
    Relevant specializationA case study involving a similar audience, offering, sales cycle, and conversion goalWhether the agency’s healthcare experience transfers to the actual assignment
    MeasurementThe proposed funnel stages, attribution approach, reporting cadence, and definition of a qualified conversionWhether performance can be evaluated beyond traffic, impressions, or raw lead counts
    Channel fitA channel rationale linked to how the intended patient, resident, family, clinician, or business buyer makes a decisionWhether the plan follows the audience rather than the agency’s preferred service
    Reported resultsDefinitions, time period, baseline, included costs, and assumptions behind ROI or lead claimsWhether two proposals can be compared on reasonably consistent terms
    Delivery teamNamed strategic and day-to-day roles, relevant experience, approval workflow, and use of outside contributorsWho will perform the work after the sales process ends
    Operational compatibilityResponsibilities for content review, lead routing, CRM updates, call handling, and sales or admissions follow-upWhether internal bottlenecks could prevent marketing activity from becoming revenue or occupancy

    The final choice should be based on the smallest credible set of capabilities needed to remove the current growth constraint. As AI-assisted discovery, search behavior, and channel economics evolve, agencies will need to demonstrate not only a current specialty but also a transparent method for testing, measuring, and adapting it.

    References
  • AI Brand Sentiment Intelligence: Turn Signals Into Action

    AI Brand Sentiment Intelligence: Turn Signals Into Action

    Your AI visibility dashboard says brand sentiment declined. That sounds urgent, but it doesn’t tell you whether an answer contains a factual error, repeats a legitimate customer complaint, favors a competitor, or simply uses cautious language.

    You need the explanation behind the label. Basic monitoring may reveal whether sentiment moved, even at the platform level, while leaving the cause and next action unresolved. AI brand sentiment intelligence closes that gap by connecting each signal to evidence, business impact, ownership, and a response you can test.

    Separate sentiment from the signals around it

    A positive, neutral, or negative label is only the start. Before acting, separate five questions that dashboards often compress into one score.

    Was your brand present?

    An answer cannot influence perception of your brand if it never mentions you. Track visibility separately from sentiment. A favorable description appearing in a small fraction of relevant answers is a different problem from broad visibility paired with unfavorable framing.

    What position did the answer take?

    Capture the exact wording that creates the impression. Terms such as expensive, specialized, complicated, reliable, established, or suitable for beginners carry different implications. A seemingly neutral qualification can matter more than an obviously negative adjective when it discourages the reader from considering your product.

    Was the claim accurate?

    Accuracy and sentiment need separate fields. An unfavorable statement may be accurate. A favorable statement may be wrong. Labeling both dimensions prevents your team from treating a product problem as a messaging problem or celebrating praise that could later undermine trust.

    What appears to drive the claim?

    Look for recurring themes and cited evidence. Pricing, reliability, customer support, security, ease of use, market position, and product fit are drivers. Positive or negative is the output. The driver is what gives you something to change.

    Could the wording change a decision?

    Not every unfavorable mention deserves escalation. Give priority to answers shown for prompts that influence evaluation, comparison, risk assessment, and purchase. A minor criticism attached to a low-relevance query may matter less than a cautious recommendation delivered when a buyer asks for a shortlist.

    Build a diagnosis workflow your team can repeat

    An isometric investigation workspace routes abstract AI response tiles through triage, evidence review, impact assessment, and team ownership stations.

    Start with decisions, not random brand prompts

    Create a stable prompt set around the questions your audience asks while discovering, evaluating, comparing, and validating a purchase. Include unbranded category questions, brand-specific questions, direct comparisons, use-case prompts, and risk or objection prompts. This reveals whether the narrative changes with user intent.

    Keep the core wording stable so later runs remain comparable. Record the platform, model or experience when visible, date, prompt, complete answer, relevant passage, citations, competing brands, and sentiment label. AI responses can vary between runs, so preserve the answer itself rather than storing only a dashboard score.

    Classify the reason before assigning the owner

    Give each meaningful passage a primary driver and, where needed, a secondary one. Keep the taxonomy small enough that two reviewers can apply it consistently. When everything becomes its own theme, you cannot see patterns. When every issue is simply called reputation, nobody knows what to fix.

    Add an evidence status: supported, unsupported, outdated, ambiguous, or not yet verified. Then record where the claim appears to come from, such as your own site, a review platform, editorial coverage, a community discussion, or an unidentified origin. This turns a vague perception problem into an evidence map.

    Prioritize patterns, not isolated answers

    Review a finding across relevant prompts, AI experiences, and repeated runs before treating it as a narrative shift. A single answer is evidence to inspect, not a trend by itself. Give each recurring issue a priority based on audience relevance, potential decision impact, recurrence, factual confidence, and your ability to change the underlying condition.

    Your working record should end with an owner and a next action. Product teams can address real capability gaps. Customer experience teams can address service patterns. Communications teams can correct public facts. SEO and content teams can improve discoverability, clarity, comparison content, and machine-readable entity information. Legal or compliance teams should review sensitive claims rather than leaving marketers to interpret them alone.

    Match each sentiment driver to the right intervention

    Four abstract sentiment problems surround a central diagnostic hub, each paired with a different corrective tool or mechanism.

    Correct factual gaps at the canonical location

    If AI answers repeat an incorrect price, feature, policy, location, or company relationship, first make the correct fact explicit on the page that should own it. Use consistent wording across important profiles and supporting pages. Add appropriate structured data when it accurately represents visible page content, but don’t treat schema as a guarantee that an AI system will adopt the correction.

    Make the correction easy to extract. State the fact directly, give it a clear heading, include necessary qualifications nearby, and show when time-sensitive information was updated. If multiple official pages disagree, resolve that conflict before producing more content.

    Fix substantiated criticism before trying to outrank it

    When unfavorable framing reflects real customer experience, the durable response begins outside SEO. Document the operational issue, route it to the team that can change it, and publish clear information about the remedy only when the facts support that message. More promotional copy will not neutralize a pattern that customers continue to confirm.

    Strengthen weak or generic positioning

    If AI systems describe your brand accurately but generically, clarify who the product serves, what problem it handles, when it is a strong fit, and where it is not. Create comparison and use-case pages that answer the criteria buyers actually evaluate. Support claims with verifiable details rather than broad superlatives.

    This is also where competitor context matters. Do not chase every favorable phrase attached to another company. Identify the decision criterion behind it. If a competitor is repeatedly preferred for ease of implementation, decide whether you need a better implementation experience, clearer documentation, stronger independent evidence, or a more precise statement of the segment you serve best.

    Treat absence as its own problem

    A brand that is missing from relevant recommendations does not have a sentiment problem yet; it has a representation or discovery problem. Check whether your entity is described consistently, whether important product and company facts are accessible, and whether credible third parties discuss you in the contexts you want to enter. Measure visibility gains before expecting sentiment gains.

    Validate movement without confusing noise for progress

    Establish a baseline before making a change. Preserve the prompt set and evidence records, then document the intervention: which page changed, which operational issue was addressed, which claim was clarified, and when the change became public. Without that change log, later movement is easy to misattribute.

    Re-run the same core prompts and examine several layers. Did brand visibility change? Did the relevant claim change? Did the driver appear less often? Did citations shift? Did the recommendation outcome change? A higher positive-sentiment share is useful only when you can connect it to meaningful language and buyer-relevant prompts.

    Keep discovery prompts separate from your fixed measurement set. New prompts help you find emerging narratives, while stable prompts help you compare performance. Combining both into one score can make normal changes in the prompt mix look like a brand shift.

    Report uncertainty plainly. Distinguish a repeated pattern from an isolated observation, and a verified error from an interpretation. Your stakeholders should be able to open any reported issue and see the prompt, answer passage, classification, evidence status, owner, intervention, and subsequent result.

    Key takeaways

    • Track visibility, sentiment, accuracy, narrative drivers, and decision impact as separate fields.
    • Use a stable set of prompts tied to real discovery, evaluation, comparison, and risk decisions.
    • Preserve complete answers and citations so every label can be audited.
    • Prioritize recurring, buyer-relevant patterns instead of reacting to one generated answer.
    • Route factual, operational, positioning, and discovery problems to different owners.
    • Measure the language and recommendation outcome that changed, not just the aggregate score.

    Begin with one important prompt group and one recurring narrative driver. Capture the evidence, name the owner, make the smallest credible intervention, and test the same prompts again. That cycle turns AI sentiment from an alarming dashboard indicator into a manageable brand intelligence practice.

    References
  • Google Marketing Intelligence: Automate Without Losing Control

    Google Marketing Intelligence: Automate Without Losing Control

    You have campaign data in Google Analytics, expanding automation in Google Ads, and more landing pages than anyone can inspect every morning. The problem is no longer a lack of information. It is knowing which information should change a campaign, which decisions the system may make, and where a person must remain accountable.

    The right goal is not maximum automation. It is a closed operating loop: trustworthy measurement informs a clear campaign brief, automation acts inside defined boundaries, and the results lead to a specific next decision. Build that loop first and Google marketing intelligence becomes useful rather than merely impressive.

    Make the data trustworthy before you automate the decision

    An analyst inspects several data streams as they pass through transparent filters that remove duplicates, repair gaps, and align the cleaned signals.

    Marketing intelligence is evidence that changes an action. A dashboard can contain hundreds of metrics without providing intelligence if nobody can explain what decision each metric supports.

    Use this five-part loop for every automated campaign:

    1. State the decision. Be precise: expand demand coverage, revise positioning, restrict landing pages, or hold spend.
    2. Name the outcome. Identify the business result that would justify that decision.
    3. Verify the signal. Confirm that the required activity reaches the intended Analytics property and report.
    4. Define the permitted action. Specify what automation may change and what must remain fixed.
    5. Set a stop condition. Decide what evidence would trigger a review, restriction, or pause.

    If you cannot complete all five steps, the campaign is not ready for broader automation. You may still run it, but you should not interpret automated activity as informed optimization.

    Use Task Assistant as a configuration audit

    Where it is available, Google Analytics Task Assistant can expose configuration gaps through a guided workflow for account connections, data collection, and reporting. Its recommendations can be marked complete or skipped, which makes it useful as an audit queue.

    Do not confuse completion with correctness. Connecting an account does not prove that the right outcome is being measured. Creating a report does not prove that anyone knows what to do with it. For every Task Assistant item, record the business question it supports. If an item is skipped, record why and what change would cause you to revisit it.

    Before expanding automation, perform this minimum measurement check:

    • Confirm that the intended Analytics property is receiving activity from the campaign journey.
    • Complete the target journey yourself and verify that the expected signal appears in the reporting path you plan to use.
    • Separate the primary business outcome from diagnostic interactions. A page view or form start can help diagnose friction, but it is not automatically equal to a completed purchase or qualified enquiry.
    • Confirm that the people reviewing the campaign use the same definition of success.
    • Assign an owner to investigate missing, duplicated, or implausible data.

    Create a one-page measurement contract

    A measurement contract is a short record of how evidence becomes action. It should fit on one page and contain these fields:

    • Decision: What are we deciding?
    • Primary outcome: Which result makes the decision worthwhile?
    • Diagnostic signals: Which observations help explain the result without replacing it?
    • Permitted action: What may the campaign system change?
    • Stop condition: What would make us constrain or pause it?
    • Owner: Who makes the final call when the evidence is ambiguous?

    For an AI Max campaign, the decision might be whether to broaden coverage for exploratory searches. The primary outcome might be a qualified commercial action. Query themes and selected landing pages would be diagnostics. Irrelevant demand, an incompatible destination, or omitted mandatory language would be stop conditions. That is enough structure to prevent a campaign team from optimizing a proxy simply because it is easy to see.

    Translate strategy into an AI brief the system can use

    Automation cannot infer the parts of your strategy that exist only in a planning deck or a stakeholder’s head. You have to express the campaign’s job, its limits, and its required truths in operational language.

    AI Max introduces an AI Brief powered by Gemini for natural-language guidance, including messaging direction and query priorities before launch. Treat that brief as an input specification, not as a creative wish list.

    A usable automation brief should answer each of these prompts:

    • Campaign job: Capture demand for which offer, from which type of need?
    • Eligible intent: Which problems, categories, or buying situations belong in scope?
    • Out-of-scope intent: Which superficially related searches should not consume attention or budget?
    • Approved positioning: Which concepts or attributes should the audience connect with the brand?
    • Supported claims: What can the landing page actually prove?
    • Prohibited claims: Which wording would be inaccurate, noncompliant, or inconsistent with brand policy?
    • Mandatory language: Which qualifier or disclaimer must remain present?
    • Destination boundary: Which pages are suitable for campaign traffic, and which are not?
    • Success signal: Which measured outcome should guide the decision?
    • Review trigger: What result or system behavior requires human inspection?

    Vague adjectives are weak instructions. If the desired positioning is “premium,” define what supports that position: service model, material, expertise, access, or another verifiable attribute. If the desired association is “sustainable,” separate the brand objective from the factual claims the campaign is allowed to make. Wanting an association does not authorize unsupported environmental language.

    Challenge the brief before launch. Ask whether a conversational query could appear relevant while expressing the wrong intent. Check whether an automatically selected page could contradict the ad’s promise. Test whether mandatory wording survives changes in message or destination. If the answer depends on someone noticing the problem later, you have monitoring, not control.

    Natural-language guidance makes campaign intent easier to communicate, but prose alone should not carry legal or regulatory obligations. Use the platform’s available controls, preserve approved wording, and require compliance or legal review where claims create exposure. Automation does not transfer accountability away from the advertiser.

    Measure the decision, not whatever the dashboard offers

    Campaign teams often ask one metric to answer several different questions. Conversion data can show that an action occurred, but not necessarily why. Brand recall can show recognition, but not whether people attach the intended meaning to the brand. Keep the questions separate.

    A practical evidence ladder has five levels:

    1. Measurement: Did the expected data arrive correctly?
    2. Delivery: Did the campaign reach demand that belongs in scope?
    3. Response: Did people take the expected intermediate or final action?
    4. Business outcome: Was the action commercially meaningful or qualified?
    5. Brand effect: Did the audience connect the brand with the intended idea?

    Do not move up this ladder by assumption. If data collection is unreliable, apparent delivery and response patterns are unstable. If the business outcome is unknown, a rise in response volume does not prove that the automation found better demand.

    Google Ads’ Association metric adds a more specific brand question. Within Brand Lift Studies, advertisers can define a concept, category, or attribute and examine which brands surveyed users connect with it. This is useful when the strategic question is not merely “Do people remember us?” but “Do people understand us in the intended way?”

    The constraint matters: a Brand Lift study can use only three selected metrics. Association therefore competes with other measurement questions rather than becoming a free extra. Choose the three before launch by writing the decision each one could change. If a metric would produce an interesting slide but no different action, it should not take a slot.

    QuestionEvidence to inspectDecision it can support
    Can the optimization signal be trusted?Verified Analytics data path and a completed target journeyRepair measurement or proceed
    Is automation finding appropriate demand?Query and destination patterns considered alongside qualified outcomesExpand, hold, or constrain coverage
    Is the message shaping the intended position?Association with the selected concept, category, or attributeKeep or revise positioning and creative direction
    Is the campaign creating recognition without meaning?Awareness or recall considered separately from AssociationDecide whether the next campaign should build familiarity or clarify positioning

    Keep performance and brand evidence on separate scorecards, then read them together. Improving Association does not prove profitable acquisition. Improving conversion volume does not prove that the intended brand position is taking hold. When one improves and the other does not, you have learned where the campaign is working and where it is not; you have not discovered a reason to redefine the weaker metric.

    Put hard boundaries around queries, copy, pages, and spend

    A marketing operator watches an automated machine work inside transparent guardrails that separate search, creative, landing-page, and budget controls.

    Good automation has broad execution capability and narrow permission. The system can evaluate more opportunities than a person can review manually, but it should operate inside a boundary the campaign owner can state without opening the account.

    AI Max is expanding beyond its Search role into Shopping and consolidated travel campaign workflows. That expansion increases the value of a shared governance model because targeting, messaging, product information, and destinations can no longer be managed as isolated concerns.

    Define these boundaries before enabling or expanding automation:

    • Demand boundary: List the needs and query themes to prioritize, plus adjacent intent that remains out of scope.
    • Message boundary: Record approved attributes, supported claims, prohibited wording, and mandatory text.
    • Destination boundary: Maintain an explicit set of pages suitable for automated selection.
    • Data boundary: State which outcomes are trusted enough to influence decisions and which signals remain diagnostic only.
    • Budget boundary: Decide how much financial exposure is acceptable before a person must review performance. Configure account controls to reflect that decision wherever the campaign type permits.
    • Compliance boundary: Identify claims and destinations that need specialist approval before they can be used.
    • Reversibility boundary: Write the condition that will cause the team to restrict, pause, or roll back the automation.

    Treat every eligible landing page as campaign creative

    Final URL expansion allows AI to select a page it considers more relevant, while text disclaimers can accompany URL automation. The operational consequence is simple: the landing page is no longer just a destination chosen once during setup. Every eligible page can become part of the campaign’s message.

    Audit each eligible page for five things:

    1. The page addresses the intent the campaign is permitted to capture.
    2. The offer and positioning agree with the approved campaign brief.
    3. The target action works and can be measured.
    4. Required qualifiers, disclaimers, and conditions are visible and current.
    5. The page does not contain stale or contradictory claims that would make the ad misleading.

    If a page fails that check, fix it or remove it from the eligible destination scope before turning on URL expansion. Do not rely on the system to understand an internal distinction that the page itself does not express clearly.

    For teams managing SEO, AEO, and GEO alongside paid media, this is also a content-governance issue. Keep the visible page, structured data, product information, and campaign claims consistent. Structured data should describe the same reality a visitor sees; it should not be used to compensate for ambiguous or outdated copy.

    Shopping and travel need the same controls in different places

    For Shopping, AI Max can use Merchant Center data to adapt ads for long-tail and exploratory searches. Product information therefore belongs inside the campaign review, not in a separate feed-management silo. A carefully written AI Brief cannot repair product information that expresses the offer poorly.

    For travel advertisers, consolidation reduces operational fragmentation, but it does not remove the need to govern intent, messaging, destinations, and measurement. Fewer campaign containers should produce a clearer decision process, not fewer checks.

    Review automation at change points rather than waiting for a generic reporting ritual. Inspect it before launch, after a material change to the offer or destination set, when query or page-selection patterns shift, and when new brand evidence becomes available. Wait for a meaningful pattern before drawing a conclusion from performance data, but investigate missing mandatory copy or an unsuitable destination immediately.

    Google campaign automation FAQ

    What is Google marketing intelligence?

    Google marketing intelligence is the decision system connecting Analytics data, campaign behavior, business outcomes, and brand measurement. It is not another name for Google Analytics. Analytics supplies evidence; intelligence defines what that evidence means and what action it authorizes.

    Should you automate a campaign if tracking is imperfect?

    You do not need every possible report to be finished, but the decision-critical measurement path must work. If you cannot verify the primary outcome, do not automate toward a convenient proxy as though it were equivalent. Repair the essential path first, then improve optional reporting around it.

    Can Association replace conversion measurement?

    No. Association addresses whether an audience connects the brand with a chosen concept, category, or attribute. Conversion measurement addresses action. Use Association to evaluate positioning and conversion evidence to evaluate response and business performance.

    How do you know automation has too much control?

    It has too much control when the campaign owner cannot state five things: eligible demand, mandatory and prohibited messaging, eligible destinations, the trusted success signal, and the stop condition. If any of those exists only as an assumption, narrow the automation until the boundary is explicit.

    Start with one active campaign. Write its job in one sentence, trace its primary outcome into Analytics, list the pages automation may select, and define the evidence that would make you expand or constrain it. Once those decisions are visible, automation can accelerate a strategy you understand instead of concealing one you do not.

    References
  • A Practical Mathematical Model of Brand Perception in AI Search

    A Practical Mathematical Model of Brand Perception in AI Search

    Your homepage may describe a sharply positioned brand while an AI answer treats you as a generic provider, associates you with the wrong problem, or leaves you out entirely. Rewriting the homepage alone may not fix that mismatch. The stronger signal can be hiding across hundreds of headings, product descriptions, comparisons, help pages, and outdated paragraphs.

    You can make this problem measurable. Model your published content as a cloud of semantic points, examine its center and spread, and then ask whether the right points sit close to the queries you want to win. You won’t reproduce a proprietary AI system, but you will get a disciplined way to decide what to create, rewrite, consolidate, or leave alone.

    Your brand is a cloud of meanings, not a single message

    Start by treating each meaningful section of your content as a separate unit. That reflects the practical reality that AI retrieval can work with small passages rather than whole pages. A carefully worded positioning statement is therefore only one point among all the other passages an AI system may encounter.

    For an audit, split your indexable content into n chunks. Each chunk becomes an embedding vector, v_i, representing its meaning in a multidimensional space. Chunks about similar subjects should sit closer together than chunks about unrelated subjects.

    The simplest brand centroid is the mean of those vectors:

    mu = (1/n) x sum(v_i)

    Scott Stouffer’s framework treats that centroid as a practical representation of how AI may locate a brand in meaning space. It captures an important editorial truth: the accumulated content portfolio can define the computed brand more strongly than the intended brand.

    Do not mistake the centroid for a universal specification or a reputation score. There is no reason to assume every search or answer system stores one permanent master vector for your company. Models, indexes, chunk boundaries, queries, and retrieval methods can differ. The centroid is useful because it turns a vague positioning concern into quantities you can inspect consistently.

    The mean is only the beginning. A mathematically serious audit also looks at dispersion, subclusters, query distance, and overlap with competing content.

    Audit quantityWhat it representsWhat you should notice
    CentroidThe average semantic position of the audited chunksWhether the portfolio’s dominant meaning matches the position you intend
    DispersionThe average distance between chunks and the centroidWhether your message is concentrated or scattered across unrelated themes
    Nearest-chunk distanceThe distance from a target query to its closest relevant chunkWhether you have a passage that directly answers the query
    SubclustersDense groups inside the larger content cloudWhether different products, audiences, or legacy strategies are competing for meaning
    Cluster overlapThe degree to which your semantic territory resembles other brands’ contentWhether your supposed differentiation exists in published evidence or only in brand language

    Dispersion can be expressed as D = (1/n) x sum(distance(v_i, mu)). A low value means your chunks remain relatively concentrated. A high value means they are spread out. Neither result is automatically good or bad. A focused product company may want a tight cloud. A multi-product enterprise may legitimately need several clusters, provided the relationship among the brand, products, audiences, and use cases is explicit.

    This distinction prevents a common mistake: trying to force every page toward one generic corporate phrase. The goal is not identical language. It is a coherent semantic structure in which each important cluster has a clear purpose and an unambiguous connection to the correct entity.

    Retrieval is the gate your positioning must pass

    Traditional rank tracking encourages you to ask where a page appears. AI visibility starts with an earlier question: was a relevant passage considered at all? In the retrieval-first model, content must enter the eligible set before later ranking factors can help it.

    Represent a query as vector q. A retrieval process compares q with candidate chunk vectors and selects close matches. For your own analysis, you might use cosine similarity:

    similarity(q, v) = (q dot v) / (norm(q) x norm(v))

    A higher value in this audit means the query and chunk point in a more similar semantic direction. The exact metric, candidate pool, and eligibility cutoff used by a production system may be different, so do not turn your audit score into a supposed universal threshold. Its value comes from comparing your own pages and measuring change with a consistent method.

    The most useful quantity is often not the distance from q to your overall brand centroid. It is the distance to the nearest genuinely relevant chunk:

    d_min(q) = min distance(q, v_i)

    This changes the content question. You are no longer asking whether the site discusses a broad topic somewhere. You are asking whether one passage expresses the user’s exact problem, your relevant capability, the conditions under which it applies, and the entity responsible for it.

    A retrievable passage should usually survive this five-part test:

    • It gives a direct answer or proposition before expanding into background.
    • It names the brand, product, service, or other entity that owns the claim when the identity would otherwise be ambiguous.
    • It uses the language of the real problem, not only an internal campaign slogan.
    • It states an important boundary, qualification, audience, or use case instead of implying universal applicability.
    • It remains understandable when read without the page title, preceding paragraph, navigation, or hero image.

    Compare two content patterns. A vague passage says: A better way for modern teams to move forward with confidence. A retrievable passage follows a more concrete structure: This product category helps this audience complete this job through this method, and it is not intended for this excluded case. The second pattern creates several semantic anchors without resorting to keyword repetition.

    Page-level strength cannot compensate for every passage-level gap. A page may have strong links, sound technical SEO, and substantial topical coverage while still lacking the chunk that matches a decisive query. That is why your content audit must go below the URL level.

    Three mathematical failure modes explain most positioning gaps

    Three abstract point-cloud scenes show an off-center cluster, a widely dispersed cloud, and several isolated clusters.

    Centroid drift: publishing changes what the portfolio means

    Suppose your existing portfolio has n chunks and centroid mu. You add m chunks whose mean vector is b. The updated centroid is:

    mu_new = (n x mu + m x b) / (n + m)

    The equation exposes two practical levers. The new material pulls harder when there is more of it, and it pulls harder when its meaning is farther from the existing center. One off-topic paragraph may barely move a large corpus. A sustained publishing campaign in an adjacent category can move the portfolio substantially.

    Drift is therefore a portfolio-management problem, not merely an editing problem. Review the semantic direction of a planned content batch before publication. Ask which association the batch strengthens, which existing cluster it joins, and whether the brand genuinely wants to become more closely associated with that subject. Traffic potential alone is not enough.

    This does not mean adjacent content is harmful. Adjacent content becomes dangerous when it is prolific, weakly connected to the core offer, or written without clear entity boundaries. If an adjacent topic serves a legitimate audience journey, connect it explicitly to the relevant problem, product, and next decision.

    Hidden subclusters: the average can conceal a split identity

    An average can land where none of the underlying points actually sit. Imagine that half a company’s content concerns enterprise analytics and the other half concerns consumer productivity. The centroid may fall between the two even though no page clearly owns that middle territory.

    That is why a centroid without a cluster map can mislead you. Inspect the dense groups beneath the mean. For each group, identify its entity, audience, problem, method, and intended query family. If you cannot label a cluster cleanly, the content may be mixing purposes that should be separated.

    When multiple clusters are intentional, give them an explicit architecture. Create a clear hub for each product or solution. State how each one relates to the parent brand. Keep comparisons, use cases, documentation, and proof connected to the correct entity. Consistent structured data can reinforce valid entity relationships, but it cannot rescue page copy that makes those relationships unclear or contradictory.

    Cluster collision: your differentiation disappears in generic content

    If competitors publish the same definitions, broad benefits, listicles, and category language, their semantic clouds can overlap. This cluster-collision problem helps explain why brands with different visual identities can still look interchangeable in meaning space.

    More content is not the direct cure. Publishing another generic overview can make your cluster denser without making it more distinct. Differentiation requires passages that encode substantive differences: the audience you serve best, the problem boundary you recognize, the method you actually use, the tradeoffs you accept, the alternatives you compare, and the evidence that supports your claims.

    Adjectives such as seamless, innovative, robust, and leading do little semantic work when every company uses them. A documented constraint can be more differentiating than a superlative. A clear statement about who should not choose an approach can be more useful than a page of unqualified benefits.

    Run a centroid audit, then repair the shape you find

    A disorganized cloud of colored points is measured and reorganized into a compact cluster around a glowing center.

    You do not need access to an AI platform’s internal index to perform a useful audit. You need a stable representation of your own corpus, a defined set of target queries, and the discipline to treat the results as a diagnostic proxy rather than a replica of any one engine.

    Build the audit in seven steps

    1. Write the intended position as one testable sentence. Use four slots: the entity, the audience, the problem, and the distinctive method or qualification. If the sentence contains only an aspiration such as trusted leader, it is not precise enough to audit.
    2. Create a chunk-level inventory. Record the URL, page title, section heading, chunk text, named entity, target query, main claim, supporting evidence, content type, and publication status. Do not assume every section on a relevant URL serves the same semantic purpose.
    3. Define the axes you care about. Typical axes include audience, problem, category, method, use case, proof, and exclusions. Add adjacent topics that could pull the brand away from its intended position. These axes become the labels against which you inspect clusters and outliers.
    4. Choose a measurement path. For a manual audit, score each chunk on each intended association using -1 for conflicting language, 0 for no signal, 1 for an implied association, and 2 for an explicit, supported association. These are internal review scores, not AI retrieval thresholds. For an embedding-assisted audit, use one embedding model and one chunking rule throughout the comparison. Changing either midway makes before-and-after movement difficult to interpret.
    5. Map query families, not isolated prompts. Group queries by the decisions they represent: discovery, definition, problem diagnosis, implementation, comparison, suitability, proof, and exclusion. Calculate or review the nearest relevant chunks for each family. A strong match for an informational definition does not prove you are close to a buying or evaluation query.
    6. Measure both center and shape. Record the portfolio centroid, dispersion, important subclusters, query-to-nearest-chunk distance, and obvious overlap with competitor language. A two-dimensional plot can help you inspect patterns, but the picture is only a projection. Confirm apparent findings by reading the underlying chunks.
    7. Save a baseline and repeat the same procedure after a substantial publishing batch, a repositioning effort, a product launch, or a major consolidation. Keep the original query set as a stable cohort. Add newly important queries as a separate cohort so changes in the test itself do not masquerade as performance changes.

    If you have several products or audiences, calculate more than one centroid. A brand-wide mean can answer a governance question, while a product centroid or query-conditioned centroid answers a retrieval question. For a query-conditioned view, examine the nearest relevant chunks rather than averaging every page the company has ever published.

    Match the repair to the diagnosed problem

    • If a valuable query has no nearby chunk, create or rewrite a passage that answers it directly. Place that answer on the page whose purpose and entity already match the query.
    • If the centroid looks correct but dispersion is high, inspect the farthest chunks. Update unclear legacy language, reconnect legitimate adjacent content to the core proposition, and consolidate duplicative material where doing so improves clarity.
    • If two legitimate subclusters are being averaged into a confusing middle, separate their hubs and identify the correct product, audience, and use case in each. Preserve a parent-brand page that explains the relationship between them.
    • If your cloud collides with competitors, stop commissioning interchangeable category summaries. Prioritize decision criteria, limitations, comparisons, methods, and verifiable proof that competitors cannot truthfully reproduce word for word.
    • If a strong topical cluster has a weak brand association, name the responsible entity inside the relevant passages. Use consistent entity names in visible copy and valid structured data. Do not mark up claims or relationships that the page does not actually support.
    • If a publishing campaign caused drift, correct the editorial brief before adding more pages. Define the association each proposed piece should strengthen and the core entity to which it must connect.

    Do not respond to an ugly cluster map with a mass deletion. Removing pages can also discard rankings, links, useful history, and coverage for legitimate journeys. Read the outliers first. An update, a clearer entity boundary, a consolidation, or a better internal path may solve the semantic problem while preserving existing value.

    Monitor outcomes without confusing them with internal retrieval data

    Pair the corpus audit with a stable prompt set. For each prompt, record whether the brand appears, which product or capability is attributed to it, whether that representation matches the intended position, which owned page is cited or linked, and whether the answer introduces an unsupported association.
    These observations are outcome proxies. They do not prove which chunks were retrieved internally, and an answer can vary across systems or runs. Their purpose is to show whether your content changes are producing a more accurate and useful external representation.

    Watch for a particularly important failure pattern: inclusion improving while representation accuracy declines. More mentions are not a win if the brand is increasingly associated with the wrong audience, category, or promise. Track visibility and message fit as separate measures.

    Key takeaways

    • Your AI-facing brand is better modeled as a distribution of published meanings than as a single positioning statement.
    • Retrieval comes before ranking, so the first operational question is whether a relevant chunk is close enough to the query to be considered.
    • A centroid shows the average direction, but dispersion and subclusters reveal whether that average is coherent or misleading.
    • Content volume can move the centroid. Review the semantic direction of an entire campaign, not only the quality of each page in isolation.
    • Distinctive brand perception comes from distinctive, supportable information: audience fit, methods, boundaries, tradeoffs, comparisons, and evidence.
    • Your measurements are diagnostic proxies. Use a consistent method to compare changes, not to claim access to an AI engine’s private retrieval logic.

    Start with one commercially important query family and the pages meant to support it. Write the position you want the system to recover, inventory the relevant sections, find the closest missing or ambiguous answer, and repair the smallest set of chunks that will make the intended meaning explicit. Then rerun the same audit after the next content batch. That is how brand perception becomes a managed system rather than a slogan you hope AI notices.

    References