Category: AI SEO

  • AI Product Discovery Tracking: A Practical Measurement Plan

    AI Product Discovery Tracking: A Practical Measurement Plan

    You can rank well in traditional search, maintain a complete product feed, and still have no clear answer to a basic question: when someone asks an AI assistant what to buy, does your product appear?

    AI product discovery tracking closes that gap. It records how individual products appear in shopping-oriented answers, separates visibility from accuracy, and gives you evidence for deciding what to fix. The goal isn’t to collect screenshots of flattering mentions. It’s to understand which SKUs enter the recommendation set, under which buying conditions, and what happens next.

    Track the buying decision, not a single brand mention

    A brand-level visibility score is too blunt for ecommerce. An assistant can mention your company while recommending the wrong product, an unavailable variant, or an item that doesn’t satisfy the shopper’s constraints. That mention looks positive in a dashboard but does little for the buyer.

    Use the SKU, or the most stable product identifier available, as the primary measurement unit. Connect each observation to the exact prompt, platform, market, date, product variant, cited page, merchant, and answer text. This lets you distinguish a product-level problem from a broad brand problem.

    The relevant measurement surface is also wider than one chatbot. Commercial monitoring is now offered for SKU-level visibility across ChatGPT Shopping, Alexa for Shopping, Perplexity, and Google AI Mode. Keep results separate by platform. Combining them into one score too early can hide the fact that a product is consistently discoverable in one environment and absent in another.

    For every observed answer, classify five different outcomes:

    • Presence: Did the brand, product family, or exact SKU appear?
    • Prominence: Was it a primary recommendation, a secondary option, or a passing reference?
    • Qualification: Did the answer connect the product to the shopper’s stated use case, budget, features, or constraints?
    • Representation: Were the name, variant, attributes, availability, and other offer details accurate?
    • Handoff: Did the answer provide a citation, merchant, product page, or another usable route toward purchase?

    These outcomes answer different questions. Presence tells you whether the product entered the answer. Qualification tells you whether the system understood why it fits. Representation reveals whether the underlying product information is coherent. Handoff shows whether visibility can plausibly lead somewhere useful.

    Build the measurement specification before choosing a tool

    A tracker can automate collection, but it can’t decide what your business means by visibility. Write the measurement specification first. Otherwise, a vendor’s default prompts and scoring system will quietly become your strategy.

    1. Create a product identity registry. Give every tracked item a canonical name and identifier. Add brand names, model names, common aliases, parent-child variants, canonical product URLs, and the merchants authorized to sell it. This prevents a shortened model name or alternate spelling from being counted as a different product.
    2. Define the eligible product set for each prompt. A recommendation is only meaningful if the SKU could reasonably satisfy the request. If a prompt requires a feature the product doesn’t have, its absence isn’t a visibility failure.
    3. Group prompts by buyer intent. Keep category discovery, feature-led discovery, problem-led questions, comparisons, branded validation, and purchase-ready requests in separate groups. A product that performs well on branded prompts but disappears from category discovery has an acquisition problem that a blended score will conceal.
    4. Record the test environment. Store the platform, location or market setting, language, session state when controllable, device context when relevant, and collection time. If a condition can’t be controlled, label it unknown rather than assuming consistency.
    5. Freeze a core prompt panel. Run the same core prompts repeatedly so changes are comparable. Maintain a separate exploratory panel for emerging language, new use cases, seasonal needs, and questions discovered in customer research.
    6. Define what counts before collecting results. Decide how aliases, bundles, parent products, variants, repeated mentions, unordered lists, and cited merchant pages will be handled. Apply those rules to your brand and competitors alike.

    Prompt wording needs particular care. “Best running shoe” and “running shoe for a wide forefoot on wet pavement” don’t represent the same decision. The second prompt supplies constraints that can change which products are eligible. Preserve those constraints in your reporting instead of collapsing everything into a generic keyword.

    Don’t let exploratory prompts replace the fixed panel. New prompts improve coverage, but changing the entire prompt set between measurement periods destroys comparability. Use the fixed panel to detect movement and the exploratory panel to find new opportunities.

    Use a scorecard that keeps visibility, accuracy, and outcomes separate

    No single metric can represent the whole discovery journey. A useful scorecard shows where a product was eligible, whether it appeared, how it was described, and whether the answer created a usable path forward.

    MetricHow to calculate itWhat it helps you decide
    Eligible prompt coverageEligible prompts containing the tracked SKU divided by all prompts for which that SKU was eligibleWhether the product enters relevant recommendation sets
    Recommendation shareRecommendations of the tracked product divided by all product recommendations in the same prompt setHow often your product appears relative to alternatives
    Primary recommendation rateAnswers treating the SKU as a leading option divided by answers mentioning itWhether mentions are prominent or incidental
    Qualification rateMentions that accurately connect the SKU to the prompt’s constraints divided by all SKU mentionsWhether the system understands the product’s relevant use cases
    Attribute accuracy rateVerified product claims divided by all checkable claims made about the SKUWhether conflicting or incomplete product information needs attention
    Handoff rateSKU mentions with a usable citation, merchant, or product destination divided by all SKU mentionsWhether discovery can progress toward consideration or purchase
    Competitor overlapEligible prompts where your SKU and a named competitor both appear divided by eligible prompts where either appearsWhich products compete in the same answer contexts
    Downstream engagementObserved visits and commerce events attributed to an identifiable AI handoffWhether measurable discovery activity contributes to business outcomes

    The denominator matters. If you calculate coverage across prompts where a product couldn’t satisfy the stated need, you manufacture a weakness. If you count every brand mention as a product recommendation, you manufacture success. Keep the eligibility rules visible next to the score.

    Preserve the underlying observations as well as the aggregate metrics. Store the returned product names, supporting language, cited URLs, merchants, competing products, and factual errors. When a score changes, you should be able to inspect the answers behind it.

    Keep business outcomes in a separate layer. An AI mention isn’t a sale, and a sale that follows an AI interaction may not be fully attributable. Where a link, referral, or tagged destination is observable, connect it to product views, cart activity, and purchases. Where the handoff can’t be observed, report the outcome as unknown. Turning unknown activity into zero activity makes the dashboard look precise while reducing its usefulness.

    Diagnose whether the failure is eligibility, selection, or representation
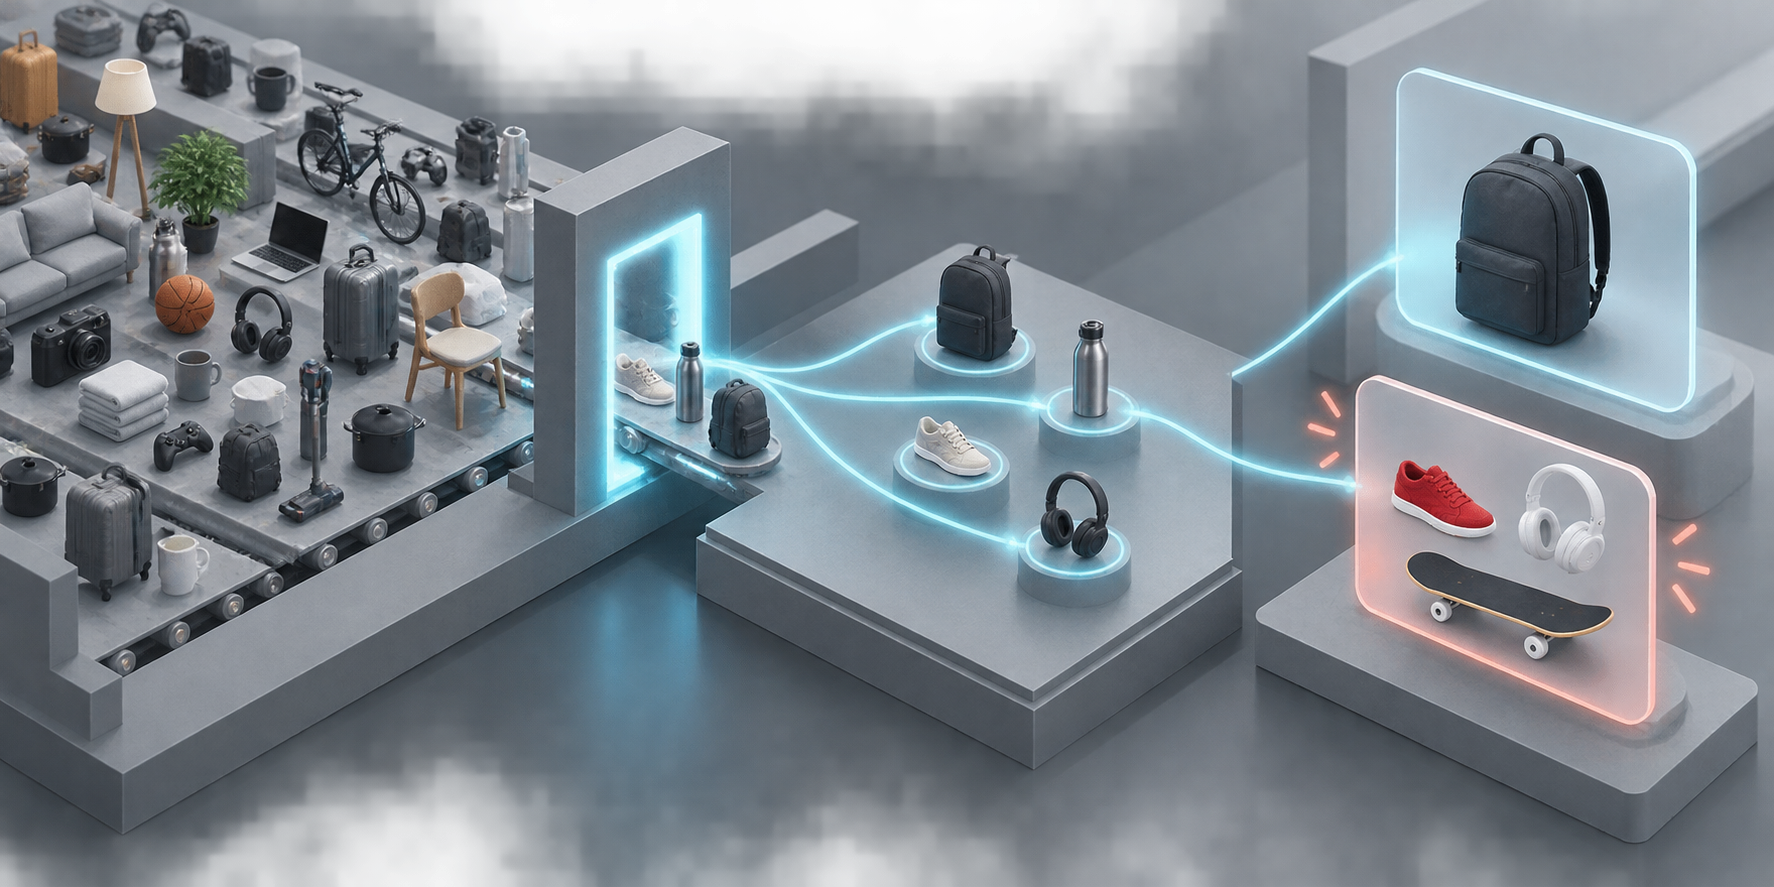
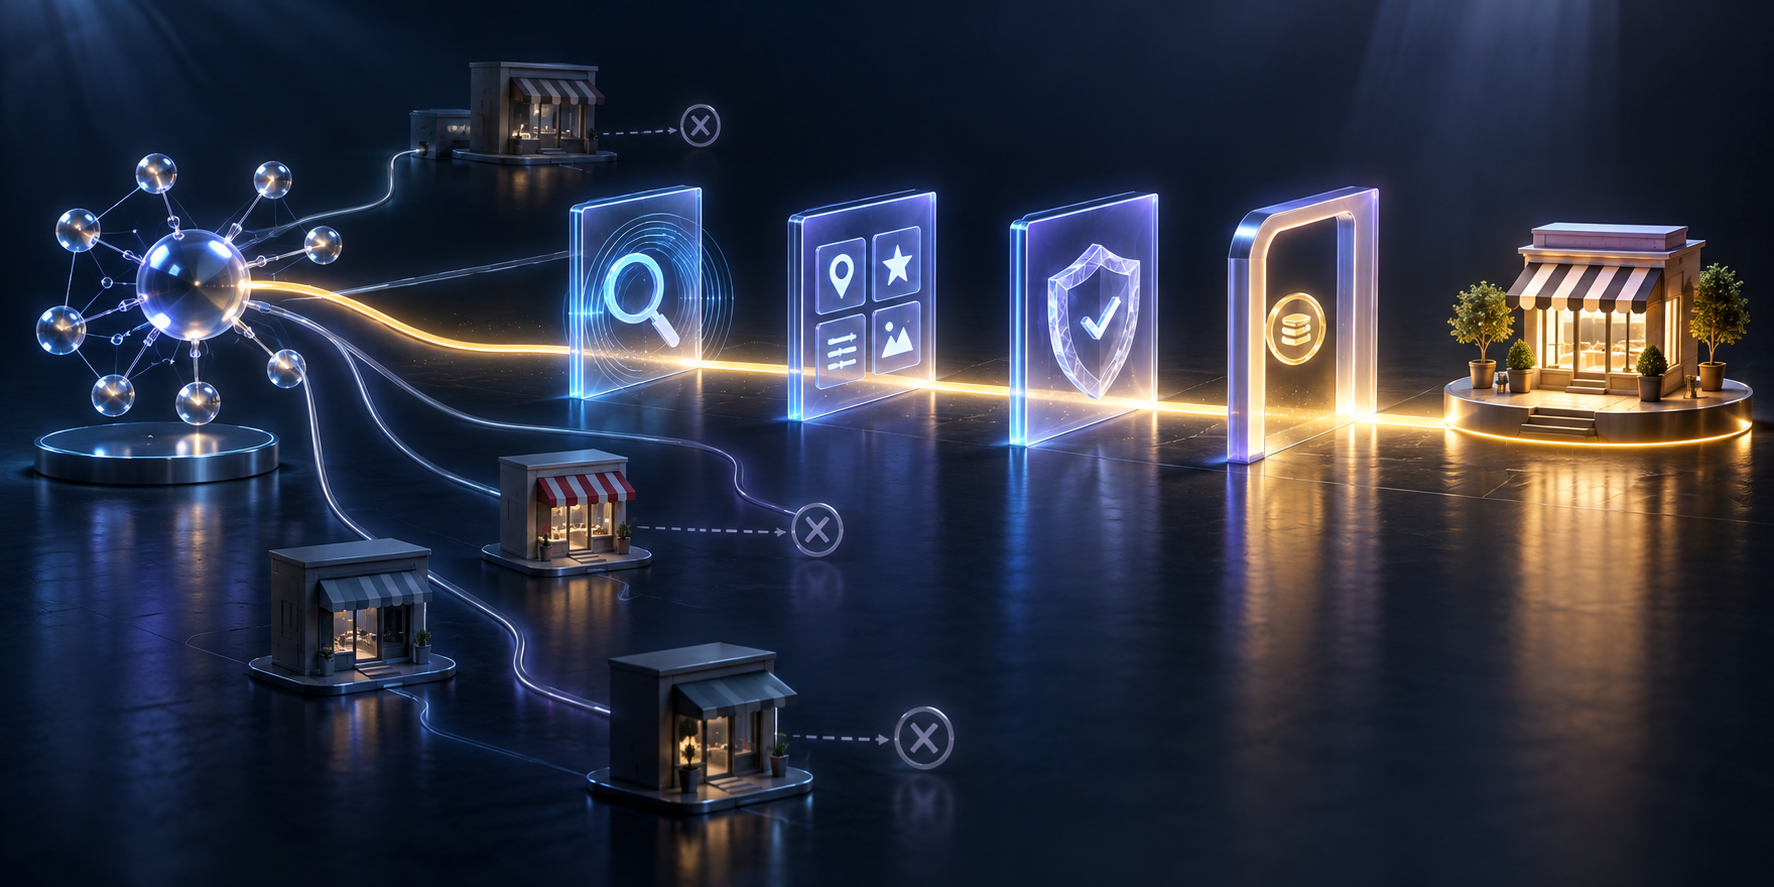
    A three-stage product recommendation pipeline filters products, selects a smaller group, and displays them in translucent answer cards.

    A missing product doesn’t tell you why it was omitted. The output gives you a symptom, not a causal explanation. Use it to form a testable hypothesis, then inspect the product information and competitive context that could support or contradict that hypothesis.

    Eligibility failure: the product isn’t understood as a candidate

    If the SKU is absent from non-branded prompts even though it genuinely meets their constraints, check whether its identity and qualifying attributes are expressed consistently. Review the visible product page, structured data, commerce feeds, variant records, category assignments, and merchant listings. Names, identifiers, sizes, colors, prices, availability, and feature claims shouldn’t contradict one another.

    JSON-LD belongs in this audit, but don’t treat schema as a magic visibility switch. Its job is to express product information in a machine-readable form. It should match the visible page and the current offer data. If the markup describes a different variant or stale availability, adding more markup compounds the ambiguity.

    Selection failure: the product is known but rarely recommended

    A product may appear for branded validation prompts yet lose generic category, comparison, or problem-led prompts. That pattern suggests the system can identify the item but doesn’t consistently connect it to the buyer’s decision criteria.

    Build a gap matrix from the actual answers. Put the prompt constraints in rows and the recommended products in columns. Record the reasons given for each recommendation. Then compare those reasons with claims your product can substantiate. If an important, verifiable attribute is missing from your product page or expressed only in an image, make it clear in the visible copy and structured product information. If your product doesn’t meet the criterion, don’t manufacture a claim to fit the prompt.

    Representation failure: the product appears with incorrect details

    Incorrect model names, mixed variants, stale offer details, or unsupported attributes are not positive visibility. Capture every checkable claim in the answer and compare it with the canonical record. Then locate conflicts across the pages, feeds, markup, and merchant data you control.

    Correct the canonical product information before trying to increase mention volume. More exposure for a misrepresented SKU can send a shopper toward the wrong variant or create expectations the product can’t meet. Keep a record of the incorrect answer and the correction date so later observations can be evaluated against the change.

    Turn tracking into a controlled optimization loop
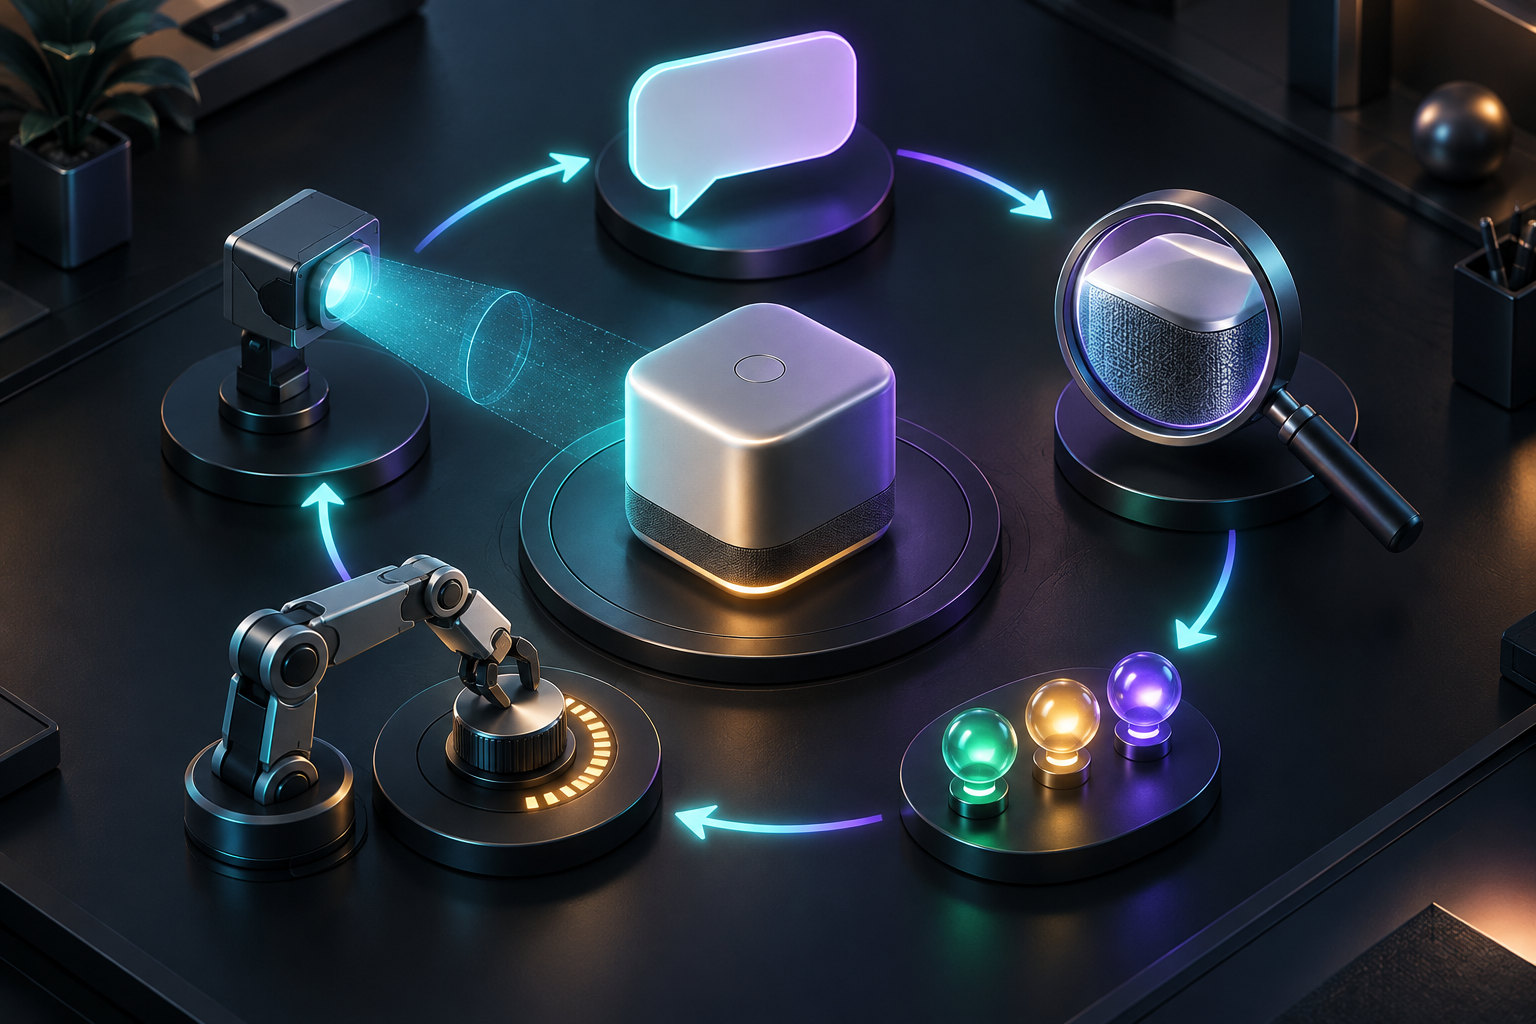
    An unbranded product sits at the center of a circular testing and optimization process with inspection, measurement, adjustment, and verification stations.

    AI outputs can vary between runs, so a single before-and-after query is weak evidence. Treat optimization as repeated observation around a documented change.

    1. Capture the baseline. Run the fixed prompt panel and preserve the complete responses, not just the calculated scores.
    2. Choose one failure class. Decide whether you’re testing product identity, attribute completeness, use-case relevance, comparison content, offer consistency, or another specific hypothesis.
    3. Change one information layer where practical. If you rewrite the page, replace the feed, alter structured data, and change merchant listings simultaneously, you may improve visibility without learning which correction mattered.
    4. Log the deployment. Record the affected SKU, URLs, fields, platforms, markets, and publication time. Include rollbacks and feed errors in the same log.
    5. Repeat the same core observations. Keep prompts, eligibility rules, and classification logic stable. Evaluate whether the direction of change persists across repeated collections.
    6. Compare unaffected products. Similar movement across changed and unchanged SKUs may indicate broad output variation or a platform-level shift rather than the effect of your work.
    7. Promote only durable findings. When an improvement continues to appear under the same measurement conditions, apply the lesson to other eligible products and keep monitoring for representation errors.

    Report platform results independently and segment them by intent. A gain in branded prompts doesn’t prove stronger category discovery. A gain on one assistant doesn’t prove that another system changed. The useful reporting unit is the intersection of platform, market, intent group, and SKU—not an unsupported universal visibility score.

    Competitor tracking should support diagnosis rather than imitation. Note which products recur, which buyer constraints they are associated with, what supporting pages are cited, and where their descriptions are inaccurate. This reveals the information standards operating within a prompt set. It doesn’t prove that copying a competitor’s wording, markup, or content structure will reproduce its visibility.

    Key takeaways for a tracker you can trust

    • Measure exact products and variants, not brand mentions alone.
    • Define SKU eligibility for each prompt before treating an omission as a failure.
    • Separate presence, prominence, qualification, factual accuracy, handoff, and business outcomes.
    • Keep a stable core prompt panel for comparison and a separate exploratory panel for discovery.
    • Preserve raw answers and cited destinations so every aggregate score can be audited.
    • Use observed outputs to form hypotheses; don’t claim they reveal a ranking system’s hidden cause.
    • Audit visible content, structured data, feeds, and merchant records for consistency when product identity or attributes are wrong.
    • Evaluate changes through repeated observations and unaffected comparison products, not one favorable response.

    Start with a narrow set of commercially important SKUs and the prompts for which they are genuinely eligible. Build the identity registry, freeze the core panel, and collect a baseline before editing anything. Your first useful result won’t be a universal visibility score. It will be a defensible answer to which product is missing, where it is missing, and what evidence you need to test next.

    References


  • How to Plan 2027 When AI Search Traffic Is Invisible

    How to Plan 2027 When AI Search Traffic Is Invisible

    Your 2027 plan will be fragile if its first line is “grow organic sessions by X%.” Traffic still matters, but it records only what happens after someone clicks. An AI answer, Reddit discussion, LinkedIn post, or peer recommendation can do much of the persuading before analytics sees the buyer.

    The answer is not to invent an AI attribution multiplier. It is to budget for the capabilities that create visibility, measure the signals that precede a visit, and use controlled experiments to decide where the next block of capacity belongs. That gives you a plan leadership can inspect without pretending every influence can be tied to a referral.

    Key takeaways

    • Keep revenue as the business outcome, but stop treating organic traffic as a complete measure of discovery or influence.
    • Build the budget around available capability: technical SEO, content operations, digital PR, research, distribution, and community participation.
    • Track ChatGPT, Perplexity, AI Overviews, search, and relevant communities separately. Visibility on one surface does not imply visibility on another.
    • Read AI mentions, citations, platform engagement, branded search, direct traffic, and conversions as a portfolio of evidence. None proves influence by itself.
    • Give every visibility experiment a hypothesis, owner, resource boundary, decision date, and kill or scale rule.

    Replace the traffic target with a visibility-to-revenue model

    An isometric model shows discovery networks, engaged audiences, site visits, opportunities, and revenue connected by light paths, including paths that largely bypass the visit stage.

    A clickstream estimate placed the share of U.S. Google searches ending without a visit at 60.45% in 2024 and 68.01% in early 2026. In practical terms, roughly two out of three searches can now end before a user reaches a website. A plan that assumes visibility and visits will move together is therefore built on a weakening relationship.

    The buyer has not disappeared. The observable journey has become discontinuous. Someone can learn your category language from an AI answer, check objections in a community, encounter your brand in a third-party comparison, and later type your name or URL. Analytics may classify the arrival as branded search or direct traffic even though several earlier surfaces shaped it.

    This changes what your traffic forecast means. It is still useful for workload planning, conversion forecasting, technical diagnosis, and trend detection. It is no longer a sufficient description of organic influence. Treat it as an observed outcome rather than the operating brief for the entire SEO program.

    Build the executive plan around three connected types of evidence:

    • Discoverability: whether the brand, products, experts, and evidence appear for the questions buyers ask across search, AI engines, publications, and communities.
    • Demand: whether exposure is followed by branded search, direct visits, platform engagement, and conversations about the brand.
    • Business outcomes: whether qualified conversions, pipeline, revenue, retention, or another agreed commercial result moves in the desired direction.

    These layers prevent two opposite attribution errors. The first is dismissing every direct visit as unknowable noise. The second is relabeling all direct traffic as AI-influenced. Both are unjustified. Direct and branded traffic are signals to investigate alongside exposure, timing, and business outcomes; they are not retroactive proof of a particular AI interaction.

    Be equally careful with correction factors. Graphite has estimated that AI influence can be underattributed by as much as 10 times. That is a warning about the possible scale of the blind spot, not permission to multiply reported AI revenue by 10. Put reported AI referrals on the dashboard as an observable floor, then build a wider influence view from the signal portfolio.

    Budget capabilities by scenario, not last year’s sessions

    Much of an SEO budget pays for salaries, tools, systems, and infrastructure. Those costs do not shrink automatically when measurable clicks decline. The useful planning question is therefore not, “How many visits can we buy?” It is, “Which capabilities do we need, and how much capacity should each receive under the conditions we expect?”

    The following 40/30/20/10 allocation is an illustrative starting scenario, not a universal benchmark:

    CapabilityIllustrative capacityWork the allocation fundsEvidence to watch
    Digital PR40%Earn credible coverage, third-party mentions, links, and citations for ideas the market finds useful.Qualifying mentions, citing domains, cited assets, and presence on priority AI surfaces.
    Technical SEO30%Maintain crawlability, indexability, structured publishing, performance, and reliable site operations.Indexing health, template coverage, implementation completion, and search visibility.
    Content operations20%Create, update, consolidate, and distribute accurate content around real buyer questions.Coverage of priority questions, refresh completion, search visibility, mentions, and conversions.
    Research10%Produce proprietary evidence, identify audience questions, and design controlled tests.Original findings published, reuse by third parties, citations, and experiments completed.

    Do not adopt this split merely because it adds up neatly. Stress-test it against the constraint that is actually limiting growth:

    • Click-compression scenario: rankings, mentions, or AI presence remain healthy while sessions fall. Protect the capabilities producing visibility, improve distribution and measurement, and do not cut them solely because fewer users click.
    • Authority-deficit scenario: you have substantial owned content but few credible third-party mentions or citations. Shift capacity toward original research, digital PR, expert participation, and community work.
    • Demand or conversion-deficit scenario: visibility rises without a corresponding movement in branded demand or commercial outcomes. Revisit audience fit, positioning, content usefulness, and the onsite conversion path before adding more production volume.

    Your capacity calculation also needs to expose hidden work. AI tools can arrive inside a marketing team without a budget for evaluation, workflow design, data preparation, quality control, or maintenance. Those hours are not free. If they come out of research, brand development, or distribution, put that displacement on the plan rather than describing automation as pure capacity creation.

    A defensible capacity plan can be built in this order:

    1. Calculate the staff, agency, and specialist capacity genuinely available after essential maintenance and committed work.
    2. Record AI tooling and automation build time as a funded activity with an owner, expected benefit, and review point.
    3. Choose the planning scenario that best reflects your visibility, authority, demand, and conversion constraints.
    4. Assign each capability a concrete output, such as a technical rollout, original dataset, content refresh program, distribution campaign, or community participation schedule.
    5. Pair each output with leading signals and business outcomes so leadership can see what should move first and what may move later.
    6. Define in advance what evidence would preserve, increase, redirect, or stop the allocation.

    This is also a better way to discuss uncertainty with finance and leadership. Instead of presenting a precise traffic promise that the channel can no longer support, show how the same capacity performs under click compression, an authority gap, or a demand gap. The decision becomes an explicit choice about capabilities and risk.

    Fund off-site distribution as operational work

    Publishing on your own domain is no longer the whole distribution strategy. In one cross-engine analysis, 91% of citations appeared in only one of ChatGPT, Perplexity, or Google AI Overviews. A citation on one engine is not reliable evidence of coverage on the others. Plan and measure each surface as a distinct environment.

    Third-party evidence deserves particular attention. An AirOps analysis estimated that third-party signals account for 85% of brand visibility in large language models. Because that is a vendor analysis rather than a universal causal rule, use it directionally: strong owned content may not travel far if credible publications, experts, customers, and communities never discuss or cite it.

    Community participation belongs in the budget for the same reason. It requires recurring human judgment: reading the conversation, understanding local norms, answering accurately, noticing emerging objections, and bringing those insights back into content and product messaging. A line item without a named person and protected hours will usually become optional when priorities tighten.

    For scenario planning, 5% of marketing budget, rising toward 10% in some cases, can serve as a test range for community work. It should not be treated as a universal benchmark. The stronger case for the upper end exists where peer discussion materially shapes evaluation and where the team can identify relevant communities, useful contribution formats, and measurable demand signals.

    Make the off-site line item operational by documenting:

    • Owner and protected time: who participates, distributes, monitors, and reports, with hours reserved in the workload plan.
    • Priority surfaces: the AI engines, publications, professional networks, forums, and communities that matter for the audience’s actual decisions.
    • Contribution: the questions the team can answer credibly, the expertise it can expose, and the conversations where participation is useful rather than promotional.
    • Citable assets: proprietary data, transparent methods, definitions, decision frameworks, and original findings that give other people a reason to reference the brand.
    • Distribution workflow: how a canonical owned asset is adapted for each surface and placed in front of relevant publishers, experts, and communities.
    • Evidence capture: mentions, citations, discussion quality, engagement, branded demand, direct visits, and downstream conversions recorded on a shared timeline.

    Do not turn community work into scheduled link dropping. The useful unit is a native contribution that resolves a real question or clarifies a difficult choice. A relevant answer can build recognition even when it does not generate an immediate referral. Repeated promotional posts can damage the authority the budget was meant to create.

    The research budget and the distribution budget should also connect. Original evidence that never leaves your site will struggle to earn third-party validation. Distribution without an idea worth discussing produces activity but little durable authority. Fund the creation of the evidence and the work required to put it into circulation.

    Measure a signal portfolio, then run bounded experiments

    An analyst compares several controlled experiment chambers containing community, AI, peer-network, and publishing models, each surrounded by glowing signal markers and limited resource blocks.

    Broken attribution does not make measurement optional. It changes the claim your reporting can support. No individual mention, citation, impression, direct visit, or conversion proves the whole chain of influence. A set of signals moving in a coherent sequence provides a stronger basis for a budget decision than any isolated metric.

    Use a layered scorecard

    Signal layerMeasures to includeDecision it supportsMisreading to avoid
    PresenceSearch visibility, AI mentions, AI citations, cited URLs, and coverage by engine or surface.Where the brand is retrievable, represented, absent, or dependent on third-party material.Assuming a mention proves persuasion or revenue impact.
    Platform responseImpressions, engagement, discussion quality, and recurring audience questions.Which ideas and distribution formats earn attention on each surface.Treating engagement as purchase intent.
    DemandBranded search, direct visits, repeat interest, and brand-related conversations.Whether broader exposure coincides with people seeking the brand deliberately.Assigning every movement to AI or to a single campaign.
    Business outcomesConversions, qualified pipeline, revenue, retention, or the commercial result chosen for the program.Whether increased demand aligns with valuable customer action.Treating last-touch credit as a complete buyer journey.
    ExecutionResearch shipped, technical work completed, content maintained, distribution performed, and community capacity used.Whether the funded capability actually operated as planned.Confusing completed activity with market impact.

    A useful example shows why these layers should be read together. During a seven-day clickstream observation after an AI recommendation for Capital One, direct visits rose by as much as 14.2% while search visits were about 15% lower. That does not establish that every additional direct visit came from AI. It does show how influence can move traffic into a different analytics column and make search look weaker than the complete journey warrants.

    Build consistency into the measurement process. Use a stable set of questions tied to real customer decisions. For every measurement run, record the surface, model or search feature, date, brand inclusion, citation, cited URL, and relevant competitors. Keep search visibility, platform activity, branded demand, direct traffic, and business outcomes on the same annotated timeline. Mark launches, PR coverage, community initiatives, major content changes, and unrelated campaigns that could explain a movement.

    Read trends by surface. A combined “AI visibility” score can hide the fact that ChatGPT cites the brand while Perplexity and AI Overviews do not. It can also hide an unhealthy dependency on a single third-party page. The planning decision may be to improve your owned evidence, earn broader external validation, or distribute the same idea into a surface where the brand is absent.

    Put decision rules on every experiment

    “Improve AI visibility” is not a test. It has no defined intervention, boundary, or decision. A usable experiment begins with the budget choice it is meant to inform.

    1. State the decision: identify which allocation will be preserved, expanded, redirected, or stopped based on the result.
    2. Write a falsifiable hypothesis: name the action, the priority surface, the expected leading signal, and the downstream outcome you expect to follow.
    3. Set boundaries: specify the responsible team, audience, assets, budget, capacity, distribution work, and evaluation period.
    4. Record the baseline: capture current mentions, citations, source coverage, branded demand, direct traffic, and conversions before the intervention.
    5. Choose leading and lagging signals: do not make a revenue outcome carry the entire burden when citations or branded demand should move earlier.
    6. Agree on the decision rule: define what will trigger a scale, revision, extension, or stop before results create pressure to reinterpret the test.

    For example: “If we publish proprietary data that answers a recurring buyer question and distribute it to named publications and communities, distinct third-party mentions and citations on our priority AI surfaces should rise before branded demand changes.” That hypothesis connects research, content, digital PR, community work, AI visibility, and demand without claiming that a citation caused a sale.

    If the asset earns no qualified pickup after the agreed distribution cycle, review the idea, evidence, outreach, or audience fit before funding a larger rollout. If third-party mentions rise but AI citation coverage does not, inspect which pages the engines cite and whether the evidence is accessible and represented clearly. If visibility, branded demand, and valuable conversions move in the same direction, you have converging evidence for a larger allocation, even if user-level attribution remains incomplete.

    Before the 2027 budget is approved, replace the traffic-only brief with an operating plan that shows scenarios, capacity allocations, named off-site owners, priority surfaces, the layered scorecard, and bounded experiments with decision rules. Keep the session forecast, but make it an input rather than the definition of success. Your plan will be more honest about what analytics cannot see and more precise about what the team will do next.

    References

  • How to Win Visibility in Agent-Driven Search

    How to Win Visibility in Agent-Driven Search

    Your page can rank first and still lose the customer. In agent-driven discovery, a person can ask an AI assistant to find, compare, book, buy, or contact a provider. The agent may evaluate several businesses and complete the task without sending that person through a familiar results page.

    That changes the visibility problem. You still need to be found, but you also need to survive qualification, support verification, and offer a safe path to action. The practical goal is not merely to appear in an answer. It is to remain the best eligible choice all the way through the agent’s workflow.

    Search visibility now has four separate gates

    An agent commonly turns a delegated request into requirements, searches for possible candidates, evaluates each candidate against those requirements, checks important claims, and then attempts the requested action. A conventional ranking affects the candidate-gathering stage, but it does not settle the final decision.

    GateQuestion the agent must resolveWhat your site needs to provideUseful metric
    RetrievalCan I find this business for the delegated task?Indexable pages, unambiguous entities, relevant task language, and clear topical coverageCandidate appearance rate
    QualificationDoes it satisfy every non-negotiable requirement?Explicit capabilities, limits, prices, locations, eligibility rules, integrations, and availabilityHard-requirement pass rate
    SelectionIs it the best fit among the eligible choices?Suitability guidance, evidence, differentiators, and independently verifiable claimsSelection share when retrieved
    CompletionCan I safely perform the requested action?A usable form, booking flow, checkout, approved API, or clearly defined human handoffSuccessful action rate

    Ranking remains important because it helps a brand enter the candidate set. It is no longer a reliable proxy for winning the decision. First Page Sage reported that, in its vendor-led analysis of 2,417 agentic commands issued from March 4 through June 10, 2026, the first-ranked result was selected 44.6% of the time, while a result ranked fourth or lower was selected 38.2% of the time. Those figures are directional rather than universal benchmarks: they come from one commercial analysis, and agent behavior can differ by platform, category, request, and user context.

    The useful conclusion is narrower and more durable: rank and selection are different outcomes. If your reporting stops at impressions, positions, and clicks, you cannot tell whether an agent failed to retrieve your brand, rejected it on a requirement, distrusted a claim, or could not complete the transaction.

    Give each gate its own metric. Candidate appearance rate tells you whether discovery is working. Hard-requirement pass rate exposes missing or disqualifying facts. Selection share tells you whether the agent prefers you after finding you. Successful action rate reveals whether your conversion path works for an automated assistant. A single visibility score hides all four failure modes.

    Publish the facts agents need to qualify you

    A central business model is connected to visual modules for location, hours, price, availability, services, accessibility, and verification.

    A broad category page may rank for “payroll software,” “family hotel,” or “commercial electrician” while giving an agent too little information to answer a constrained request. Real delegated tasks include conditions: company size, location, budget, dates, integrations, accessibility needs, service area, cancellation terms, or regulatory requirements.

    Agents can treat those conditions differently. A hard requirement eliminates a candidate. An important requirement carries substantial weight. A nice-to-have breaks a close comparison. An optional feature may add only a small advantage. Your first content job is to discover which facts occupy each tier for the buying tasks that matter to your business.

    1. Choose a delegated commercial task. Use a task tied to revenue, such as booking a service, selecting a product, requesting a proposal, or arranging a demonstration. Commercial requests deserve priority because delegated agent activity is more concentrated around buying, booking, and hiring than around general informational searches.
    2. Write down the complete requirement set. Use actual sales questions, support tickets, requests for proposals, on-site searches, form responses, and objections. Separate non-negotiable conditions from preferences instead of treating every feature as equally important.
    3. Map every hard requirement to a canonical page. The answer should be stated directly, not buried in a brochure, image, unsupported comparison chart, or sales-only conversation.
    4. Add suitability content. Explain who the offer is for, who it is not for, which situations it supports, what prerequisites apply, and where its limits begin.
    5. Keep consequential facts synchronized. Prices, regions, availability, policies, product names, and eligibility rules should not conflict across product pages, help content, structured data, directories, and partner profiles.

    Use a suitability page pattern that answers the whole decision

    A useful suitability page is not another generic “why choose us” page. It should let a machine or a person decide whether your offer fits a specific situation. A practical structure is:

    • Best fit: the customer, use case, location, scale, or conditions the offer is designed for.
    • Required conditions: prerequisites the customer must meet before buying, booking, or applying.
    • Supported requirements: the capabilities, integrations, service areas, configurations, or policies that satisfy common constraints.
    • Limitations: unsupported scenarios, exclusions, capacity boundaries, dependencies, and cases that require a different offer.
    • Commercial facts: visible pricing where possible, or a precise explanation of what determines price; availability; fees; cancellation terms; and what happens after submission.
    • Evidence: links to documentation, policies, certifications, product details, or independent material that substantiates consequential claims.
    • Next action: a clear route to buy, book, request a quote, schedule a demonstration, or move to a human review.

    Dedicated suitability content is worth testing even if it attracts little conventional search volume. In the same vendor analysis, businesses with this kind of content were selected 2.7 times as often as equally ranked businesses without it. That multiplier should not be treated as a guaranteed result, but the mechanism is sensible: explicit fit information reduces the inference an agent must make.

    Make proof machine-readable without hiding caveats

    Relevant JSON-LD can express your organization, offer, product or service, availability, and other supported attributes in a consistent format. Use it to clarify facts already visible on the page. Do not use markup to introduce claims, prices, ratings, availability, or capabilities that a visitor cannot confirm in the page content.

    Structured data reduces ambiguity; it does not establish truth. Agents may compare a site’s claims with what they already know and with independent material before choosing a candidate. Make important assertions easy to verify by identifying what the claim applies to, where it applies, and under which conditions. A sentence such as “integrates with accounting software” is weak. A maintained integration page that names the supported systems, required plan, setup path, and current limitations is decision-grade evidence.

    Consistency matters here. Use the same business name, canonical URL, product names, locations, and core offer descriptions wherever you control the information. When a third-party profile is outdated, correct it. When a claim changes, update the visible page and its markup together. Contradictory facts force an agent to decide which version to trust, and the safest decision may be to exclude the candidate.

    Remove the blockers between selection and completion

    A glowing agent pathway moves through verification, availability, selection, payment, and completion while alternate routes end at digital obstacles.

    A recommendation has limited commercial value if the agent cannot finish the requested job. The operational difference is whether a page is machine-actionable: can an approved agent use the interface to submit the inquiry, reserve the time, add the product, complete the purchase, or reach a defined handoff?

    The vendor-led command analysis recorded 78.3% of conversions on machine-actionable pages, compared with 9.6% on pages where the agent could not act. This is not a promise that making a form accessible will produce a particular conversion rate. It is evidence that transactional usability can become a selection constraint rather than a minor conversion optimization.

    Audit the complete transaction, not just the landing page

    • Use visible, specific field labels. “Work email,” “arrival date,” and “number of employees” are easier to interpret than placeholder-only or context-dependent fields.
    • State required inputs before submission. If a quote needs a postal code, account identifier, property type, budget range, or document, disclose that requirement before the agent enters the flow.
    • Explain validation failures precisely. Identify the affected field, preserve valid entries, and say what an acceptable value looks like.
    • Expose material terms before commitment. Price, fees, renewal terms, cancellation conditions, availability, and approval dependencies should not appear only after the decisive click.
    • Use conventional controls and stable destinations. Buttons should have meaningful labels, links should resolve predictably, and essential actions should not depend on unexplained gestures or decorative interface elements.
    • Return an actionable confirmation. Show what was submitted, whether it succeeded, what happens next, and any reference number or next step the user needs.
    • Define the human handoff. If the task cannot be automated, say which step requires a person, what information that person needs, and how the customer will be contacted.

    Test the flow from a clean session using the same facts a customer would give an agent. Check every branch: unavailable dates, unsupported locations, invalid entries, expired inventory, payment failure, authentication, and confirmation. A form that works only on the happy path is not reliably actionable.

    Agent-friendly does not mean unguarded. Keep authentication, fraud controls, consent, privacy safeguards, and human approval wherever the risk requires them. Do not weaken a security control to make automation easier. If automated action is allowed, provide an approved route; if it is not, provide a clear and honest handoff instead of a hidden bypass.

    Use audience preference where the platform supports it

    Retrieval is not driven only by topical relevance. Google Preferred Sources gives readers an explicit way to star publications in the Top Stories area so that stories from those outlets can appear more often for those readers. This is a narrow feature with a precise scope: it concerns publications and Top Stories, not every business listing, organic result, or AI-agent decision.

    The feature has nevertheless become large enough for publishers to treat it as a real retention channel. Google reported that people had selected more than 600,000 unique sources, up from 200,000 in May 2026. Google has also said that users who select a preferred source are twice as likely to click. Those figures describe this specific feature; they do not establish a general ranking advantage across search or AI platforms.

    If you publish news and participate in Top Stories, the implementation is straightforward:

    1. Install Google’s Preferred Sources button using the supported implementation.
    2. Place the prompt near a moment when the reader has received value, such as the end of a substantive story, rather than interrupting the opening.
    3. Explain the result accurately: starring the publication can make its stories appear more often in that reader’s Top Stories experience.
    4. Record the preferred-source user count with its reporting date so you can measure growth instead of relying on an undated total.
    5. Compare that growth with returning readership and engagement, while keeping correlation separate from proof of causation.

    Some site owners received Search Console emails showing a Preferred Source user count as of October 5, 2026. Google also surveyed recipients about future reporting methods, frequency, and metrics. Until regular reporting is established, keep your own dated record of any counts you receive.

    If you are not a relevant publication, do not imitate the button or describe ordinary follows as Preferred Sources. Apply the underlying principle without inventing a platform signal: give satisfied readers a clear way to return, subscribe, follow, or search for your brand again. Explicit preference can support a durable audience, but it should not be presented as proof that an unrelated agent will select you.

    Measure agent visibility as a decision path

    You do not need access to an agent’s private logs to build a useful diagnostic. You need a repeatable set of realistic tasks and a disciplined record of what can be observed. Start with the commercial requests that matter most, because “explain this topic” and “choose a provider and submit an inquiry” test very different kinds of visibility.

    1. Define the task exactly. Include the hard constraints a real buyer would provide: location, budget, timing, compatibility, eligibility, scale, or required terms.
    2. Preserve the test context. Record the platform, date, locale, sign-in state, exact command, and any files or preferences supplied. Keep the command unchanged when comparing runs.
    3. Capture the candidate set. Note whether your brand appeared, which page supported the appearance, what claims were surfaced, and which competing options were considered.
    4. Score each requirement. Mark hard requirements as confirmed, failed, contradictory, or unknown. An unknown should not be counted as a pass merely because you know the answer internally.
    5. Separate selection from retrieval. Record whether the brand was found, whether it remained eligible, whether it was selected, and the observable reasons given. Do not present an inferred reason as if the agent disclosed it.
    6. Test the action. Where authorized, follow the process through the form, booking, cart, checkout, or handoff. Record the exact field, policy, authentication step, or interface state that prevents completion.
    7. Fix the earliest failed gate. More suitability copy will not solve an indexing failure. More authority will not repair an unusable booking flow. Diagnose before choosing the optimization.
    8. Repeat on a fixed cadence. Agent outputs can change, so compare patterns across repeated observations rather than treating one response as a permanent ranking.

    Keep conventional SEO and analytics beside this testing. Search rankings still influence retrieval, human visitors still use results pages, and agent-driven commercial activity remains only part of search. The measurement upgrade is additive: it connects rankings and mentions to qualification, selection, and completed work.

    Key takeaways

    • A ranking can earn entry into an agent’s candidate set without earning the final selection.
    • Publish explicit requirements, supported scenarios, limitations, commercial terms, and suitability guidance so the agent does not have to guess.
    • Use JSON-LD to clarify visible facts, not to make unsupported claims or conceal qualifications.
    • Make consequential claims consistent and independently verifiable.
    • Treat forms, booking systems, checkout, APIs, and human handoffs as part of search visibility.
    • Measure retrieval, qualification, selection, and completion separately so each failure receives the right fix.
    • Use Google Preferred Sources if its Top Stories scope fits your publication, but do not mistake it for a universal agent-ranking signal.

    Choose your highest-value delegated task and trace it from discovery to completion. If your brand is absent, repair retrieval. If it appears but is rejected, expose the missing fit or proof. If it is selected but the task stalls, fix the transaction. That sequence keeps you from buying more visibility when the real leak is qualification, trust, or action.

    References

  • How to Build Brand Trust for Better AI Search Visibility

    How to Build Brand Trust for Better AI Search Visibility

    Your brand can be technically discoverable and still fail the answer that matters: which option should the buyer trust? An AI search system may find your pages, mention your company, and even cite you without being willing to recommend you.

    That changes the work in front of you. Publishing more content will not repair invented expertise, inconsistent company facts, a chatbot that makes promises your support team cannot keep, or public conversations dominated by unresolved complaints. Better AI search visibility starts by making the evidence around your brand accurate, consistent, and useful enough to support a recommendation.

    Separate being found from being trusted

    Visibility is not a single outcome. A brand can be retrieved as relevant, cited as a factual source, included as an option, recommended as the preferred option, or mentioned with a warning. Treating all five outcomes as a ranking position hides the reason you are winning or losing.

    When you diagnose an AI answer, examine three layers of evidence:

    • Identity evidence: Is it clear who the company is, who created the content, and who is responsible for the claims?
    • Claim evidence: Are product capabilities, policies, qualifications, and comparisons specific enough to verify?
    • Experience evidence: Do customer-facing systems and independent discussions support or contradict what the company says about itself?

    Your website controls much of the first two layers. The third often develops elsewhere. A customer can encounter a bad answer in your chatbot, describe it in a community, and create a public record that later competes with your product page. That does not mean every complaint changes an AI answer. It means you cannot evaluate visibility by auditing owned pages alone.

    LastPass illustrates the persistence problem. Reddit discussions about past security incidents continued to rank for the brand name and were pulled into ChatGPT answers. The practical lesson is not to suppress criticism. It is to watch for recurring trust failures, resolve the underlying issue, and make accurate corrective information easy to find.

    Make every owned claim verifiable

    Two researchers inspect luminous connections between a geometric block, an unmarked document, a product sample, a medallion, and a clock.

    Trust begins with an unglamorous question: is the page honest about who made it? Google now explicitly treats AI-generated headshots, invented names, and false credentials used to simulate human expertise as deceptive authorship information. Its guidance says deception makes a page untrustworthy to users and automated quality systems and signals low quality.

    You do not need a celebrity expert on every byline. You need an accurate chain of responsibility. Audit your content templates with these checks:

    • Use a person’s name only when that real person created, substantially shaped, or took editorial responsibility for the work.
    • Keep biographies factual. List roles, experience, and credentials you can substantiate rather than qualifications chosen to make a page look authoritative.
    • Do not label someone a reviewer unless a meaningful review occurred. Record what the review covered internally so the label has an operational meaning.
    • If the organization is genuinely responsible for the content, say so. A truthful organizational byline is stronger than a fictional personal profile.
    • Explain how information was produced or checked when that process helps the reader judge reliability. Do not use a vague process statement to disguise absent human oversight.
    • Make publication and update dates reflect real editorial events. A new date on unchanged material is not evidence of freshness.

    Use schema as a consistency check, not a credibility generator

    Structured data can clarify the identity and relationships already visible on a page. It cannot turn a fabricated expert into a trustworthy author. Your Article, Person, and Organization markup should agree with the byline, biography, About page, editorial policy, and company details a visitor can see.

    For each important template, compare the visible page with its JSON-LD field by field. Check the author type, name, URL, publisher, publication date, modification date, and any identity links. Remove a field when you cannot support it. Do not add credentials or sameAs references merely because a schema tool offers an empty box for them.

    This catches a common trust leak: every individual statement looks plausible, but the collection does not describe one coherent entity. A shortened brand name in one place, an obsolete company description in another, and an unrelated author profile in the markup can leave both people and automated systems with avoidable ambiguity.

    Treat your chatbot as a reputation surface

    A customer faces a translucent digital kiosk as light paths connect it to a service team, with one clear path and one warning-marked path.

    A commerce or support chatbot is not only a conversion tool. It is also where customers test whether your brand’s promises survive contact with a real question. A poor bot experience can therefore affect AI search visibility as well as the immediate sale.

    The mechanism is straightforward. The bot gives an inaccurate or evasive answer. The customer cannot reach a person or verify the claim on your site. They take the question to a forum, review platform, or social conversation. The resulting public explanation may be clearer and more durable than anything you published yourself.

    Audit the bot around complete customer tasks, not isolated response quality:

    1. Select real tasks. Use recurring questions from bot logs, sales conversations, support tickets, and on-site search. Include questions that affect eligibility, pricing, returns, compatibility, security, delivery, and cancellation when those apply to your business.
    2. Run each task to its endpoint. Record the first answer, follow-up questions, linked page, escalation option, and final resolution. A friendly opening does not compensate for a dead end later in the exchange.
    3. Compare the answer with the source of truth. Check the bot against current product pages, policy pages, documentation, and the answer a trained employee would give. Flag unsupported promises and contradictions before rewriting the tone.
    4. Test the recovery path. Deliberately ask an ambiguous question, challenge an answer, and request a human. The bot should acknowledge uncertainty and provide a usable next step instead of inventing certainty.
    5. Turn recurring failures into content work. If customers repeatedly need an external discussion to understand a policy, improve the policy page and the bot’s retrieval source. Do not treat the symptom as a prompt-writing problem alone.

    Keep a simple failure log with the customer task, incorrect answer, correct answer, responsible owner, affected page, and resolution status. This connects conversion operations with reputation and AI visibility. It also prevents separate teams from fixing the bot, help center, and structured data in incompatible ways.

    Earn third-party evidence without manufacturing it

    Communities can give buyers and AI search systems context that an About page cannot. They can also expose promotional behavior quickly. The useful goal is not to plant brand mentions. It is to contribute answers that remain valuable even if the reader never clicks your profile.

    Start only after your own site is worth citing. One documented B2B SaaS workflow begins with a set of 200 to 500 SEO keywords and maps them to roughly 150 relevant subreddits. Those figures describe that operating model, not a quota every company should copy. The transferable method is to connect existing buyer questions with communities where those questions already receive substantive answers.

    Use the following participation rules to protect trust:

    • Work with real accounts. An employee can participate as a knowledgeable person, but the account should not exist solely to promote the employer. Build a genuinely useful history and disclose the relationship whenever it is relevant to the recommendation.
    • Stay with live conversations. The same practitioner team limits engagement to threads less than 20 days old because returning to old conversations can look unnatural and increase moderation risk. Treat that as a conservative operating rule from one program, not a universal Reddit ranking factor.
    • Answer the question completely. Give the useful explanation before mentioning a product. If the comment only works when the reader follows your link, it is probably promotion rather than an answer.
    • Match the community’s language. Use direct descriptions, real constraints, and relevant experience. Corporate copy and polished slogans make a comment less credible, not more.
    • Earn the right to start a thread. Original posts work better after the account has participated constructively. An AMA or a detailed solution to a recurring pain point has a clearer community purpose than a disguised announcement.
    • Do not coordinate fake praise. Sockpuppets, invented customers, and concealed affiliations create the same underlying problem as fake author profiles: apparent evidence with no truthful person behind it.

    For an active reputation program, search your brand name on Reddit every day and log the threads that introduce a new factual claim, recurring complaint, or comparison. Respond only when you can add a correction, resolution, or genuinely useful context. A defensive reply can amplify the very evidence you want to displace.

    Community work is a secondary layer. If your product facts, policies, authorship, and customer experience remain weak, more participation simply gives the weaknesses more places to surface.

    Run a trust-first AI visibility audit

    Build a fixed prompt set around the decisions your buyers actually make. Include category discovery, use-case fit, comparisons and alternatives, risk or support concerns, and direct questions about your brand. Reuse the same prompts so you can distinguish a meaningful change from a different question.

    For each run, record the platform or model, date, exact prompt, whether the brand appeared, how it was characterized, whether it was recommended, any warning language, and the cited URLs. The citation list is often more diagnostic than the mention itself because it shows which evidence shaped the answer.

    Observed patternLikely evidence gapFirst action
    Your brand is absent from an unbranded category answerThe available material may not answer that category or use case precisely enoughPublish a focused, factual answer on your own site and make its ownership clear
    Your brand is mentioned but not recommendedRelevance exists, but trust, fit, or comparative evidence is weakInspect cited alternatives, verify your claims, and identify missing proof or unresolved objections
    Your brand appears with a warningNegative experience evidence is outweighing owned claimsTrace the warning to its cited or likely origin, fix the underlying issue, and publish an accurate resolution
    The answer contains outdated or conflicting factsYour entity details, policies, or product information are inconsistentAlign visible pages, feeds, profiles, and JSON-LD around one current source of truth
    The answer cites you but describes you inaccuratelyYour page may be extractable without being sufficiently explicitRewrite ambiguous passages so the qualification, scope, and responsible entity appear together

    Prioritize by trust risk, not implementation convenience. Remove deception and factual errors first. Repair broken customer journeys next. Resolve contradictions across owned properties after that. Then strengthen missing evidence and improve schema. A markup change is quick, but it is the wrong first move when the underlying claim is false or the customer experience disproves it.

    Assign each issue to an owner who can change the root cause. Content teams can clarify a page, but they cannot repair a returns process. SEO teams can expose inconsistent entities, but they cannot validate a security claim. The audit becomes useful when it routes each trust gap to the team with authority to close it.

    Key takeaways

    • AI search visibility includes retrieval, citation, recommendation, and warning outcomes; a mention alone does not prove trust.
    • Real authorship, supportable credentials, and JSON-LD that matches the visible page give your owned claims a coherent identity.
    • Chatbot failures can become public reputation evidence, so audit complete customer tasks and escalation paths rather than tone alone.
    • Community visibility should be earned through real accounts and complete answers after your own site is worth citing.
    • Measure the language and citations around your brand, then fix deception, broken experiences, and contradictions before optimizing presentation.

    Start with a small, fixed set of buyer prompts and follow each answer back to the evidence supporting it. Fix the highest-risk contradiction you find, rerun the same prompts, and keep the record. That turns AI visibility from a mention count into a practical trust-improvement loop.

    References


  • How to Build Organic Visibility Across Fragmented AI Search

    How to Build Organic Visibility Across Fragmented AI Search

    You rank in Google, yet ChatGPT leaves you out. An AI answer mentions your brand, yet the prospect finds an outdated offer on another channel. Your content earns citations, yet the clicks do not follow. These are not separate failures. They are breaks in the same discovery and verification journey.

    Your goal is no longer to win a single result page. You need to make the brand easy to retrieve, correctly describe, independently verify and confidently choose across AI answers, conventional search, reviews, social platforms and your own site. That requires a visibility system, not a collection of channel tricks.

    Your customer is moving through a verification loop

    The old funnel assumed that someone searched, compared a few results and converted. AI search has added more entry points without removing the old ones. A person can discover you in an AI answer, check Google for current details, scan reviews for credibility, watch a video to understand the experience and return to your site to act.

    Local discovery makes this fragmentation especially visible. In SOCi’s 2026 survey of more than 1,000 U.S. consumers, the share that had used AI to find a local business in the previous month rose from 9% in 2025 to 52% in 2026. Search still reached 83% of respondents, while social reached 55%. The channels are accumulating rather than replacing one another.

    More AI use does not mean unquestioning trust. Among the AI users in that survey, 67% had encountered incorrect local-business information, and 30% said an error had caused a real inconvenience. When AI recommended a business, 81% performed some form of verification before making contact. Only 19% moved directly from the recommendation to contacting the business.

    This changes what an AI citation means. It is an invitation into the consideration set, not proof that you won the customer. If the next channel contradicts the answer, the mention may simply send a better-informed prospect to a competitor.

    Audit that journey around real customer decisions rather than broad vanity prompts:

    1. Collect the questions that precede a sale, renewal, visit or product choice. Use sales objections, support tickets, on-site search terms and customer language rather than guesses from a keyword tool alone.
    2. Test each question in the AI and search experiences your audience actually uses. Record whether your brand appears, which page or third party is cited, what claims are made and what next step the answer encourages.
    3. Follow the verification path yourself. Check the cited page, search result, review profile, social account, product documentation and business listing that a cautious buyer is likely to open.
    4. Classify the break as absence, factual error, weak evidence, cross-channel contradiction or conversion friction. Each class needs a different fix.

    A missing mention is a retrieval problem. A wrong location or product capability is an entity-data problem. A correct mention followed by weak reviews is a corroboration problem. A citation that sends the visitor to an unhelpful page is a content and conversion problem. Treating all of them as “AI rankings” hides the work that will improve the outcome.

    Make the brand unambiguous before you scale its mentions

    An answer engine has to resolve which entity you are, determine what you offer and retrieve evidence that supports a response. Conflicting names, descriptions, locations, prices, policies and product claims increase ambiguity. Publishing more content on top of that ambiguity gives machines more material to misread.

    Create a canonical entity record for each organization, brand, location, product or service that matters. It should identify the preferred name, concise description, official URL, current offer, audience, service area or availability, important policies and the person or team responsible for updates. For claims that require proof, record the supporting page as well.

    Then make the record visible in places machines and people can inspect:

    • Canonical pages: Give each important entity a stable page with a clear purpose. Do not scatter the only complete description across campaign pages, PDFs and social posts.
    • Structured data: Use the most specific relevant Schema.org type, such as Organization, LocalBusiness, Product, Service, Person or Article. Connect related entities through appropriate properties and identifiers. The markup must describe visible page content; it should not introduce claims the reader cannot verify.
    • First-party profiles: Align business listings, product feeds, author biographies, help documentation and social profiles with the canonical record.
    • Change ownership: Assign an owner to every volatile fact. A price, opening hour, availability rule or product capability should trigger updates across all affected surfaces when it changes.
    • Conflict tracking: Maintain a simple register containing the fact, canonical value, authoritative URL, dependent surfaces, owner and last verification date. Review it on a regular cadence and after material business changes.

    JSON-LD supports this work by expressing relationships in a machine-readable form, but it cannot manufacture trust. A perfectly marked-up claim that conflicts with the page, reviews or trusted third-party coverage is still a conflicting claim. Schema is the connective tissue between clear facts; it is not a substitute for those facts.

    Avoid attempts to force the answer with hidden prompt instructions, manufactured community mentions or large volumes of low-value AI copy. These tactics target temporary model or retrieval behavior. Their gains can disappear when model architectures and retrieval systems change, while the resulting spam, exposed instructions or unnatural brand activity can damage the signals you were trying to strengthen.

    The durable alternative is less theatrical: publish accurate entity information, earn relevant mentions, expose original expertise and keep the facts synchronized. That work remains useful when the interface, model or favored citation source changes.

    Build topic clusters for query fan-out, not a keyword list

    A glowing central sphere branches into interconnected clusters of abstract objects representing different kinds of related questions.

    AI systems often decompose a broad question into related subquestions before composing an answer. A buyer asking for the best option may implicitly need definitions, eligibility rules, alternatives, costs, risks, implementation details and evidence. Your content does not need to repeat the same head term on many pages. It needs to cover the decision from those distinct angles.

    A Surfer analysis of 173,902 URLs across 10,000 keywords found that pages ranking for a main query and at least one related fan-out query were 161% more likely to be cited in an AI Overview than pages ranking only for the main query. That is an observational result, not a guarantee. It supports building coherent topical depth, but it does not justify creating a page for every generated variation. In the same analysis, only about 27% of fan-out queries remained consistent across repeated runs.

    Start the cluster with a commercial problem you can credibly solve. Build a hub that orients the reader, then add spokes for recurring questions and decisions. Keep the boundary tight. Traffic from a remotely related subject may look attractive in an analytics report while contributing little to brand authority or revenue.

    Search intentPage jobEvidence that adds valueUseful next step
    Definition or problem recognitionGive a direct, bounded explanation and help the reader identify whether the issue appliesClear distinctions, examples, expert review and links to deeper subtopicsMove to diagnosis, evaluation or implementation content
    Comparison or evaluationHelp the reader choose between credible optionsOriginal criteria, transparent methodology, test notes, limitations and suitability by use caseOpen a product, service, pricing or consultation page
    Implementation or troubleshootingHelp the reader complete a task or resolve a known failureOrdered steps, prerequisites, settings, screenshots where needed and failure conditionsUse the relevant tool, documentation or support path
    TransactionalRemove uncertainty around purchase or contactCurrent price, availability, specifications, policies, proof and a clear offerBuy, book, request or contact
    VerificationConfirm that the brand and claim are credibleReviews, author credentials, references, third-party mentions, case evidence and update historyReturn to the decision page with uncertainty reduced

    Give each page a distinct information job. A strong content brief should state the primary question, the direct answer, the evidence required, the entity being described, the pages it should link to, the appropriate structured data and the business change that would make the page outdated.

    Match your click expectations to the query. Seer Interactive’s 2026 data found that informational comparison queries triggered an AI Overview 95.4% of the time and question-form queries did so 85.9% of the time, while the rate for transactional queries was about 5%. Definitions and simple explanations may therefore create visibility without many visits. Comparison, implementation and transaction pages have more work to do after the answer: they must offer evidence, detail or an action that the generated summary cannot complete.

    Citations still matter even when clicks contract. For informational searches with an AI Overview, cited brands received about 120% more organic clicks per impression than uncited brands on the same result pages. Yet cited brands still received 38% fewer clicks per impression than queries without an AI Overview. Plan for both outcomes: concise passages that can support an answer and deeper assets that reward the person who chooses to visit.

    Internal links should express the decision path, not merely distribute authority. A problem page should point to the relevant comparison. The comparison should point to implementation and transaction pages. The product or service page should link back to evidence that resolves foreseeable objections. This gives readers a route forward and helps crawlers understand how the pages form a coherent subject.

    Design the corroboration layer that AI cannot supply

    Independent review, publication, discussion, storefront, and validation symbols cast converging beams of light onto a fictional green product.

    Your site can define a claim, but a skeptical customer may want someone else to confirm it. This is why organic AI visibility depends on reputation, public relations, community participation, reviews and social content as well as technical SEO.

    The strongest quantified evidence here concerns U.S. local discovery, so it should not be treated as a universal benchmark for every market. The operating lesson is still useful: discovery and validation happen on different surfaces. In SOCi’s local survey, 99% read reviews before a first visit at least some of the time, and 72% were more likely to choose a business that responded to reviews. A correct AI mention can therefore fail at the review step.

    Build the corroboration layer around the doubts attached to the purchase:

    • Reviews: Ask for honest feedback through a consistent process, respond to substantive concerns and correct recurring operational problems. Do not script sentiment or manufacture volume.
    • Social proof: Show what the product, service, location or working process is actually like. Use demonstrations, walkthroughs and answers to common questions instead of posting disconnected promotional material.
    • Earned authority: Give journalists, trade publications, associations and relevant experts something worth referencing, such as original data, informed commentary, transparent methodology or a genuinely useful resource.
    • Community presence: Participate where customers exchange advice, but disclose affiliations and answer the question at hand. Artificial brand insertion creates a weak signal and an obvious trust problem.
    • Support content: Turn repeated pre-sale and post-sale questions into maintained documentation. In the local survey, 63% had abandoned a business that could not answer a question they needed resolved.

    You do not need activity on every possible platform. Choose the places your buyer uses to reduce risk. A local business may need current reviews, maps data and visual previews. A B2B software company may depend more on documentation, practitioner discussions, integration pages and trade coverage. An ecommerce brand may need accurate product data, independent reviews, demonstrations and clear returns information.

    Consistency does not mean copying the same sentence everywhere. It means that each surface tells the same factual story in the form that suits the channel. Your documentation can be precise, a video can demonstrate, a review can provide independent experience and a structured-data graph can connect the entities. Contradictions are the problem, not variation in presentation.

    Measure a visibility system, not a single ranking

    AI outputs are variable, and customer journeys cross channels. A dashboard built around one prompt position or last-touch traffic will miss both facts. Measure whether the system repeatedly gets the brand into the right decisions with accurate, supported information.

    Use a fixed panel of high-value prompts and record:

    • Presence rate: How often the brand appears within each prompt category and platform.
    • Citation share: How often an appearance cites your owned pages or credible third-party evidence.
    • Entity accuracy: Whether important facts such as capabilities, availability, locations, prices and policies are correct.
    • Message fit: Whether the answer associates the brand with the problem and audience you actually serve.
    • Corroboration coverage: Whether a buyer can confirm the important claim on another current, trustworthy surface.
    • Search response: Non-branded impressions, clicks and conversions for the related topic cluster rather than an isolated keyword.
    • Business outcome: Qualified inquiries, purchases, bookings, assisted conversions or another result connected to the decision.

    Keep the test conditions as stable as the platform allows. Use the same prompt wording, market, language and account state, and retain the complete output rather than only the favorable screenshot. Repeat the test because a single answer can reflect a transient fan-out or retrieval choice. When you change content, entity data or corroborating assets, annotate the change so you can distinguish a plausible effect from ordinary output variation.

    Assign the work across the teams that create the signals. Brand and public relations own credible mentions. Subject-matter experts and content teams own original, accurate information. Product and engineering own renderability, structured data and stable product facts. Sales and support supply real questions and objections. SEO connects the system, detects gaps and reports how the parts affect discovery.

    Connect the visibility metric to what each team already values. Citation share can accompany share of voice. Cluster visibility can accompany qualified organic demand. Schema coverage and indexation can accompany site-quality work. Coverage of customer questions can accompany support deflection and sales enablement. Shared outcomes make visibility an operating process instead of an SEO request that arrives after everything has been published.

    Key takeaways

    • AI discovery is an entry point. The customer may still verify the answer through search, reviews, social content and your site before acting.
    • Resolve entity conflicts before producing more content. Canonical facts, visible page copy, structured data and external profiles should agree.
    • Build topic clusters around related customer decisions and recurring fan-out subjects, not every generated query variation.
    • Create content that contributes original evidence, clear distinctions or useful implementation detail. Summaries of existing summaries are easy to replace.
    • Treat reviews, earned mentions, communities, documentation and social proof as part of AI visibility because they determine whether a recommendation survives verification.
    • Measure presence, citations, accuracy, corroboration and business outcomes across a stable prompt set. A single answer or last-click report is not a strategy.

    Start with the highest-value decision your customer makes. Trace it from AI discovery through external verification to the final action, and fix the first broken handoff you find. Once that path is accurate and credible, expand the same operating pattern to the next topic cluster. That is how organic visibility becomes resilient across a search landscape that will keep fragmenting.

    References


  • AI Search Visibility Monitoring: A Practical Framework

    AI Search Visibility Monitoring: A Practical Framework

    If your AI visibility report moves from one run to the next, you need to know whether your brand’s position changed or the sample did. A chart that cannot answer that question is noise, however polished it looks.

    You can make the signal more trustworthy. Build the monitor around fixed prompts, captured answers, explicit scoring rules, and decisions someone is responsible for making. The goal is not merely to count mentions. It is to understand where your brand appears, how it is represented, what evidence supports the answer, and what you should change next.

    Decide what the monitor is supposed to change

    Start with the decision, not the dashboard. AI search visibility can refer to several different problems, and each requires a different measurement:

    • Discoverability: Does your brand appear when someone asks about a category, problem, or use case without naming you?
    • Competitive presence: Does the answer include you alongside the alternatives a buyer is likely to consider?
    • Recommendation: Does the system merely mention you, or does it actually present you as a suitable choice?
    • Accuracy: Are the facts about your products, services, locations, people, policies, or capabilities correct?
    • Reputation: Is the description favorable, unfavorable, neutral, or mixed, and what language caused that classification?
    • Evidence: Which pages, domains, or citations appear to support the answer?

    Do not collapse those questions into one visibility score. A brand can be mentioned frequently and described inaccurately. It can receive positive language in branded prompts while remaining absent from unbranded category discovery. It can also appear in a recommendation without receiving a citation. Those are different conditions with different remedies.

    Write a measurement brief before collecting data. Name the audience, market, language, products, competitors, prompt families, platforms, and business decisions in scope. A program may examine how ChatGPT, Gemini, Perplexity, and Claude describe a brand, but results from those systems should remain separate as well as aggregated. A gain on one platform can otherwise hide a loss on another.

    Define the unit of observation as one exact prompt run under one recorded condition. For every run, preserve the platform, model or mode when visible, market, language, date, prompt text, session state, answer text, cited URLs, and scoring result. If account status, retrieval settings, or personalization are known, record those too. Without that audit trail, you cannot tell whether a movement came from your content, a platform change, a different prompt, or conversational context.

    Most importantly, do not present monitored prompts as a census of everything users see. They are a controlled panel. Their value comes from consistency and diagnostic depth, not from pretending they reproduce the entire audience.

    Build a prompt set without moving the goalposts

    Blank prompt cards are arranged in a fixed modular grid while a mechanical arm selects one card.

    Your prompt set determines what your visibility score can mean. A weak set overrepresents easy branded questions, changes whenever a stakeholder has a new idea, and mixes markets or intents that should be evaluated separately.

    Begin with the real language of the market. Useful inputs include search-query data, internal site search, sales questions, support tickets, product comparisons, customer interviews, and community discussions. Convert those inputs into natural questions a person might ask an assistant. Avoid adding your brand name to an unbranded discovery prompt, praising the brand inside the question, or supplying facts that make the desired answer obvious.

    Prompt familyExampleWhat it reveals
    Category discoveryWhat tools help a small marketing team monitor how AI assistants describe its brand?Whether the brand is associated with the relevant category before it is named.
    Problem and use caseHow can I find inaccurate claims about my company in AI-generated answers?Whether the brand is connected to a specific need or job.
    ComparisonWhat should I compare when choosing an AI visibility monitoring platform?Which evaluation criteria and competing options enter the answer.
    RecommendationWhich options fit a team that needs citation and sentiment monitoring?Whether the system recommends the brand under stated constraints.
    Branded accuracyWhat does [brand] offer, and who is it for?Whether the assistant recognizes the entity and represents its core facts correctly.

    Keep two prompt panels. The locked panel changes rarely and supplies the trend line. The exploratory panel can absorb new products, questions, competitors, and market language. When an exploratory prompt becomes strategically important, add it to the next version of the locked panel and mark the break. Do not insert it into historical totals as if it had always been present.

    Tag every prompt by intent, journey stage, product, audience, market, and whether it is branded or unbranded. These labels let you find a meaningful pattern. A flat overall result might conceal rising visibility for informational questions and falling visibility for purchase-oriented recommendations.

    Use fresh sessions for independent tests. Conversational history can alter later answers, so a follow-up question belongs to a different test design. If multi-turn discovery matters to your audience, monitor it as a named journey with a fixed sequence rather than mixing it with standalone prompts.

    Outputs can vary even when the visible prompt does not. Repeat matched conditions before treating a single answer as a trend. First establish the normal variation of each prompt family; then judge future movement against that baseline. This prevents one favorable or unfavorable response from becoming a strategy.

    Score the answer, not just the brand mention

    An analyst examines a layered answer panel, source tiles, and several unlabeled evaluation gauges on an inspection table.

    A mention counter answers only one question: whether a brand string appeared. Your scoring model should preserve enough detail to explain what that appearance meant.

    • Presence: Record whether the brand or an approved variant appears. Keep aliases in an entity dictionary so spelling and product-name differences do not create false absences.
    • Prominence: Record whether the brand is central to the answer, included in a list, mentioned only as an aside, or introduced through a citation without appearing in the prose.
    • Recommendation status: Separate explicit recommendation, conditional recommendation, neutral inclusion, and explicit exclusion. Save the sentence that justifies the label.
    • Accuracy: Compare concrete claims with a maintained set of approved facts. Label each reviewed claim as supported, incorrect, outdated, conflicting, or unverifiable. Unverifiable is not the same as false.
    • Sentiment: Use positive, neutral, negative, or mixed only when you also capture the language behind the label. Sentiment without evidence is difficult to audit and easy to misread.
    • Citations: Save the full URL, domain, page type, and whether it belongs to your organization, an independent publisher, or a competitor. A citation is evidence of selection, not automatic evidence of endorsement or factual correctness.
    • Competitive context: Record every monitored competitor that appears and the role each one receives. A simple name count misses the difference between being recommended and being used as a cautionary comparison.

    Define share of voice before putting it on a dashboard. One defensible answer-level definition is the share of monitored answers naming your brand among answers that name at least one monitored brand. Another is mention-level share across all monitored-brand mentions. Those denominators answer different questions and can produce different results. Publish the formula next to the metric and keep it unchanged across reporting periods.

    Keep branded and unbranded visibility separate. Branded prompts test entity recognition and factual representation. Unbranded prompts test whether the brand is retrieved for a category, problem, audience, or constraint. Combining them usually inflates the headline while hiding the harder discovery problem.

    Treat sentiment as a review aid, not a verdict. An answer can praise ease of use while questioning fit for a particular customer. Calling that response simply positive discards the part that could change a buying decision. Preserve mixed classifications and attach the decisive excerpt so a reviewer can see what happened.

    Be equally precise with citations. Measure citation presence, domain diversity, ownership, page freshness where known, and the claims each citation appears to support. If an answer names your brand but cites only a competitor or an unrelated page, that is not the same outcome as a direct citation to a current, relevant page.

    A composite score can be useful for orientation, but it should never replace the underlying measures. If you create one, document its components and weights, show the raw metrics beside it, and version the formula whenever it changes. Otherwise, an apparently stable score may be concealing offsetting gains and losses.

    Turn visibility changes into specific work

    A useful monitor ends in a queue of testable actions. When a metric moves, investigate in the same order each time:

    1. Validate the observation by rerunning the same prompt under matched conditions. Preserve both the confirming and conflicting outputs.
    2. Locate the scope. Check whether the change belongs to one platform, prompt family, market, language, product, or competitor set.
    3. Compare the answer text and citations with the earlier baseline. Identify the claim, recommendation, omission, or source selection that actually changed.
    4. Classify the likely problem as discoverability, entity ambiguity, factual inconsistency, weak evidence, reputation, technical access, or normal output variation.
    5. Assign an intervention that matches that diagnosis. Record the owner, affected pages or entities, expected signal, and implementation date.
    6. Continue the locked measurement panel after the intervention. Do not replace difficult prompts or add favorable prompts to make the result look improved.
    Observed patternLikely interpretationUseful next action
    The brand is accurate in branded answers but absent from unbranded discovery.The entity may be recognized without a strong association to the category or use case.Strengthen pages that explicitly connect the brand, offering, audience, problem, and differentiating evidence. Review whether those relationships are clear in page copy, internal links, and relevant structured data.
    The brand is visible, but descriptions conflict across prompts.Canonical facts may be unclear, inconsistent, or scattered.Create an approved fact set, reconcile conflicting pages, and make names, descriptions, relationships, and current capabilities consistent across owned properties.
    A competitor appears repeatedly for one constraint or audience.The competitor may have a clearer evidence trail for that particular fit.Inspect the supporting pages and claims. Publish direct, substantiated material for the same decision criterion if your offering genuinely meets it.
    Citations lead to outdated or irrelevant pages.Old URLs or weak canonical paths may still be prominent in the available evidence.Update the strongest relevant page and consolidate duplicate information. Before removing an old URL, map its links and use an appropriate redirect so you do not discard useful signals or strand visitors.
    Sentiment changes while mention presence stays stable.The visibility problem is not reach; it is representation.Review the exact negative or conditional claims. Correct factual ambiguity in owned content, and route legitimate product or reputation issues to the team that can address the underlying cause.
    Only one platform changes on an isolated run.The movement may be platform-specific or ordinary answer variation.Repeat the matched test and inspect that platform’s answers before changing site-wide strategy.

    Your reporting view should preserve this diagnostic path. Show platform and prompt-cluster coverage, branded and unbranded presence, recommendation status, the declared share-of-voice formula, citation patterns, accuracy issues, and sentiment evidence. Add a change log underneath. Readers should be able to move from a chart to the affected prompts, full answers, citations, and interventions without asking how the number was produced.

    Also separate observation from attribution. If visibility rises after you revise a page, the timing makes the revision a plausible contributor; it does not prove that the page caused the change. Look for repetition across relevant prompts, supporting citation changes, and stability beyond a single run before making a causal claim.

    Key takeaways

    • Use a locked prompt panel for trends and a separately versioned exploratory panel for discovery.
    • Store the exact prompt, answer, citations, platform conditions, and scoring evidence for every observation.
    • Keep presence, recommendation, accuracy, sentiment, citations, and competitive position as distinct measures.
    • Separate branded recognition from unbranded discovery, and report results by intent and prompt cluster.
    • Define every denominator, especially share of voice, and display raw measures beside any composite score.
    • Validate changes under matched conditions before assigning site-wide work or claiming an intervention caused the result.

    Start with one commercially important use case and a prompt set small enough for your team to review answer by answer. Lock the baseline, document the scoring rules, and connect every alert to a named decision. Once that loop works, expand the coverage without weakening the audit trail.

    References


  • AI Search and Shopping Agent Visibility: A Practical System

    AI Search and Shopping Agent Visibility: A Practical System

    Your product appears in an AI answer on Monday, disappears on Tuesday, and returns through a different citation on Friday. That does not automatically mean your optimization worked, failed, and recovered. It means you are looking at a system that assembles answers dynamically rather than assigning one durable position.

    You need a visibility program built for that volatility. The goal is to increase the probability that your brand is found, understood, supported by credible evidence, and selected when an AI system moves from answering a question to helping someone choose a product.

    Replace the idea of one ranking with three layers of visibility

    A conventional ranking gives you a page, a query, and a position. An AI answer can vary its wording, cited URLs, recommended brands, and product shortlist from one run to the next. Treating one generated response as a ranking report will produce false alarms when you disappear and false confidence when you happen to appear.

    The volatility is large enough to affect how you interpret every test. When 10,000 keywords were run through Google AI Mode three times on the same day, the average URL overlap was only 9.2%. For 21.2% of the keywords, the three runs had no cited URLs in common. In another large test, Google AI Overview content changed in roughly 70% of checks, while only 54.5% of cited URLs overlapped between consecutive runs.

    Yet changing citations do not always mean that the underlying answer has changed. The semantic similarity of those AI Overviews remained at 0.95 even while their wording and evidence rotated. You can therefore lose a particular citation while the system continues to express the same category preference, recommendation criteria, or view of your brand.

    Measure three layers separately:

    • Answer visibility: Does the brand or product appear in the generated response, recommendation, shortlist, or comparison?
    • Evidence visibility: Which owned or third-party pages are cited, and what claims are those pages supporting?
    • Commerce readiness: Can a shopping agent determine what the product is, who it suits, which variant applies, and whether the commercial information is complete enough to support a decision?

    This distinction matters because the remedy depends on the layer. If your brand remains recommended but your URL stops being cited, you may have an evidence-distribution problem. If your pages are cited but your product never reaches the shortlist, your positioning or product fit may be unclear. If the product appears but the agent reports an incorrect price, variant, or use case, the problem is data consistency rather than general brand awareness.

    Shopping agents raise the stakes. Personal agents such as Muse and Instinct can find products, compare options, and make purchasing decisions for users. Your job is no longer finished when an AI system mentions the brand. The system must also be able to qualify the product against the buyer’s situation.

    Build a measurement system that survives volatile answers

    A stable monitoring hub tracks a shifting field of abstract answer panels and citation nodes connected by changing paths.

    Start with the questions that precede a real decision, not a collection of high-volume keywords. A useful prompt library represents the different jobs a buyer asks an assistant to perform:

    • Problem discovery: asking what kind of product solves a stated need.
    • Use-case qualification: looking for a product that fits a particular audience, environment, workflow, or constraint.
    • Comparison: weighing products or product types against explicit criteria.
    • Risk reduction: checking compatibility, limitations, policies, reliability, or suitability.
    • Purchase preparation: verifying variants, availability, price, delivery, returns, or another decision-critical fact.
    • Branded evaluation: asking whether your product is suitable and what alternatives should be considered.

    Write prompts in the buyer’s language and preserve the qualifiers that change the answer. “Best project-management software” and “project-management software for a small agency that needs client approvals” are not interchangeable questions. The second prompt gives the system criteria it can use to include or exclude a product.

    Run the same library on each AI platform you care about, but do not blend the results into one universal score. Google AI Overviews and AI Mode shared only 13.7% of their citations in one comparison. Platform-specific shifts can also be abrupt: Reddit’s average share of ChatGPT Search citations fell from 3.83% to 0.52% across the reported periods, an 86.4% decline, while the broader pattern was not uniform across AI systems.

    A blended average can hide exactly what you need to diagnose. Keep separate views for each platform, answer surface, market, and language you test. Aggregate them only after you have inspected the underlying results.

    Repetition is equally important. Published sampling guidance indicates that 60 to 100 runs of a prompt can produce meaningful visibility data. Another longitudinal approach recommends at least seven runs per prompt per day for brand-level estimates, assessed through rolling windows of two to four weeks. These are measurement benchmarks, not a claim that every team must immediately test at that scale. If your budget supports fewer observations, label the result as directional and avoid making budget or content decisions from a single response.

    Your dashboard should answer operational questions rather than merely count mentions:

    QuestionMetricWhat to recordLikely next action
    Are we present?Brand mention rateValid runs containing the brand divided by all valid runs for that prompt setInvestigate prompt clusters where competitors appear consistently and you do not
    Are products being considered?Product inclusion rateRuns in which an eligible product enters the shortlist or comparisonClarify audience fit, category language, and comparison attributes
    What supports the answer?Citation rate by domain and URLOwned and third-party pages cited for each claim or recommendationStrengthen missing evidence and pursue relevant independent coverage
    Is the answer accurate?Fact accuracy rateCorrect and incorrect statements about fit, specifications, terms, and availabilityResolve contradictions across pages, catalogs, feeds, and structured data
    Is the change persistent?Rolling visibility rangeRates and ranges over repeated runs, separated by platformAct on sustained movement rather than an isolated response

    Keep a changelog beside the data. Record platform and model updates, material website changes, catalog releases, content refreshes, and significant third-party coverage. The log will not prove causation, but it prevents the team from inventing an explanation after every rise or fall.

    Use a simple decision rule: one unusual answer is an observation; a repeated change within the same platform and prompt cluster is a pattern worth diagnosing. If the decline appears everywhere at once, inspect broad accessibility, brand evidence, and product-data issues. If it appears only for comparison prompts, look first at the criteria buyers use to distinguish products.

    Make every product answerable before expecting it to be selectable

    A generic product moves from organized attributes and evidence nodes through a transparent reasoning structure into a highlighted selection tray.

    A shopping agent cannot infer a reliable recommendation from a product name and a persuasive description alone. Early testing of personal agents points to three practical visibility requirements: usable product catalogs, accessible websites, and clear statements about who each product is for.

    Audit each commercially important product as a package of decision facts. The exact attributes will vary by category, but the agent should be able to resolve the following without reconciling conflicting pages:

    • Identity: a stable product name, canonical URL, model or SKU, brand, and an unambiguous relationship between the main product and its variants.
    • Audience fit: the user, situation, problem, or level of experience the product is designed for. State meaningful limitations when they affect suitability.
    • Comparison attributes: the specifications, capabilities, materials, dimensions, compatibility details, or service limits a buyer would use to compare alternatives in your category.
    • Commercial terms: current price and currency, availability, variant-level differences, applicable delivery information, returns, and warranty terms where relevant.
    • Evidence: explanations, documentation, or independent validation that supports important claims instead of merely repeating them.
    • Consistency: agreement among the visible product page, catalog or feed, structured data, policy pages, and any regional or variant pages.

    “Who it is for” deserves its own content block. Avoid empty labels such as “for everyone” or “perfect for professionals.” Give the agent usable selection criteria: the problem solved, the expected environment, required compatibility, relevant experience level, and conditions that would make another option more suitable. Clear exclusions can improve recommendation quality because they reduce the chance that your product is matched to the wrong request.

    Use Product and Offer structured data as a consistency layer, not as a magic entry ticket. Markup should express facts that a visitor can also verify on the page. If the visible page says one price, the catalog says another, and the structured data carries an expired offer, adding more schema will multiply ambiguity rather than remove it.

    Variant handling needs particular care. A parent product page may describe the range, but decision-critical facts should remain attributable to the correct size, configuration, color, region, or service tier. An agent comparing two variants should not have to guess which price or specification belongs to which option.

    Test accessibility from the agent’s point of view. Open the page in a clean session. Confirm that the product identity, fit, principal attributes, and commercial terms are available without signing in, accepting an unnecessary location flow, opening an image, or relying on an interaction that hides the only copy of a critical fact. Then compare the rendered page with the catalog and structured data field by field.

    Finally, test a decision sequence rather than one branded prompt. Ask an assistant to identify products for a constrained use case, compare the candidates, explain which user each candidate suits, and verify the facts needed for a decision. Record where your product disappears and which unresolved criterion caused the exclusion. That point is a more useful optimization target than the wording of the final answer.

    Publish and earn evidence that AI systems can resample

    Once a product is technically legible, it still needs current evidence. AI-cited URLs were 25.7% fresher on average than conventional organic results in one large comparison: cited pages averaged 1,064 days old, versus 1,432 days for organic results. This does not mean that changing a date will improve visibility. It means the information environment being sampled by AI systems tends to include fresher material.

    Refresh a page only when you can make it more useful. Add new product facts, answer newly important buyer questions, update obsolete comparisons, correct policy details, incorporate original data, or explain a material change. Keep the URL stable when the underlying resource remains the same, show a meaningful update date, and remove contradictions left by earlier versions.

    Owned content is necessary but insufficient. In one citation analysis, owned media accounted for 13.7% of AI citations while earned media accounted for 84%. Journalism represented 27%, and paid content represented only 0.3%. These labels should not be treated as a simple exclusive pie chart, but the practical signal is clear: visibility often depends on credible pages you do not control.

    Build an evidence map around the claims that determine selection. For each important prompt cluster, list the claims an assistant would need to justify: category membership, audience fit, distinctive capability, compatibility, comparative strength, limitation, and commercial availability. Then mark where each claim is supported:

    • on a canonical owned page;
    • in your product catalog and structured data;
    • in independent reporting, reviews, comparisons, or other third-party material;
    • nowhere reliable enough to support a recommendation.

    The empty cells are your publishing and public-relations brief. Create original material where you control the underlying evidence. Seek independent coverage where an outside assessment would carry more value. Do not treat a press release as a durable substitute for either one; press-release citation share proved unstable and declined over the reported period, largely because ChatGPT cited releases less often.

    Prioritize third-party coverage that contributes information of its own. A useful comparison, test, interview, dataset, or category explanation gives an AI system a reason to retrieve the page beyond the presence of your brand name. Repetition across low-value placements may expand the number of mentions without supplying better evidence for a recommendation.

    Connect publishing back to measurement. When a prompt cluster lacks visibility, identify whether the missing input is product data, owned explanation, or independent evidence. Make the smallest substantive change that addresses that gap, record it in the changelog, and assess it across repeated runs. That gives you a testable operating cycle instead of a stream of unrelated content.

    Key takeaways for your next visibility cycle

    • Treat an AI response as one sample, not a permanent ranking. Report visibility as a rate and range across repeated runs.
    • Separate brand inclusion, cited evidence, and commerce readiness. Each layer has a different failure mode and remedy.
    • Build prompts around discovery, qualification, comparison, risk reduction, and purchase preparation rather than isolated keywords.
    • Measure each AI platform separately. A blended score can conceal a platform-specific gain, loss, or citation shift.
    • Make product identity, audience fit, comparison attributes, variants, and commercial terms explicit and consistent across the page, catalog, feed, and structured data.
    • Refresh important pages with substantive information, not a changed date, and cultivate independent evidence for claims that influence selection.

    Begin with one commercially important product family and the prompts closest to a decision. Establish a repeated baseline, inspect where the product falls out of the journey, and fix that exact gap. Once the page, catalog, schema, and outside evidence tell the same clear story, extend the system to the next product family.

    References


  • AI Search Ranking Signals: A Practical Priority Order

    AI Search Ranking Signals: A Practical Priority Order

    If your team is debating whether the next optimization sprint should go to schema markup, an llms.txt file, or another FAQ block, pause. The larger opportunity is usually earlier in the chain: make it unmistakable what you offer, who it fits, and whether the same facts appear everywhere an AI system may encounter your brand.

    Markup can help a machine interpret a strong page. It cannot rescue vague positioning, missing proof, or conflicting information. If you want more visibility in ChatGPT, Gemini, Claude, AI Mode, and agentic search, use the priority order below to decide what to fix first.

    The strongest measured signals are clarity and consistency

    From June 8 to September 18, 2026, 4,213 commercial prompts and 657 agentic shortlisting or purchasing tasks were run through ChatGPT, Google Gemini, including AI Mode, and Claude. The analysis covered 1,089 brands across 14 industries and measured recommendation rate: the share of relevant prompts in which a platform named a brand as a recommended option.

    Clear descriptions of offerings and suitability had the largest adjusted association with recommendation rate at +11.2 percentage points. Consistent information across a brand’s website and third-party sources followed at +9.4 points. The adjustment controlled for authority signals such as list mentions, reviews, and awards.

    SignalDifference before authority controlDifference after authority controlWhat to do with it
    Clear offerings and suitability+15.8 points+11.2 pointsState what each offer is, who it serves, and when it is suitable.
    Consistent brand information+16.9 points+9.4 pointsReconcile important facts across owned pages and third-party profiles.
    Comparison tables on service pages+6.7 points+1.9 pointsUse tables when they make fit and differences easier to evaluate.
    Any schema markup+3.7 points+0.4 pointsTreat schema as a representation layer, not the main ranking project.
    Organization schema+2.1 points+0.2 pointsImplement it accurately, but do not expect it to create authority.
    FAQ schema+0.8 points-0.3 pointsAdd useful FAQs for readers, not to manufacture a ranking signal.
    llms.txt+0.8 points-0.1 pointsKeep it behind clarity, consistency, and authority work in the backlog.
    Product schema for ecommerce brands+6.7 points+4.8 pointsGive this greater priority when products are the entities being evaluated.

    Do not treat those adjusted differences as universal ranking weights. They are associations from one observational dataset, not proof that changing one field will produce a fixed lift on every platform. The negative FAQ schema and llms.txt figures do not show that either feature causes harm; they show that no measurable positive effect remained after authority was controlled in this sample.

    The more useful lesson is about sequencing. Schema appeared more powerful before authority was held constant because brands that invest in technical optimization often have stronger authority signals too. If your page still leaves its audience or use case implicit, technical polish is unlikely to be the constraint holding it back.

    Cross the clarity threshold before adding more structure

    Scattered translucent shapes merge into one clear object before passing through a glowing gateway toward neatly organized blocks.

    Clarity is not the same as short copy. A clear page gives a model enough explicit information to connect an offering to a person, problem, location, and buying situation without having to infer the missing pieces.

    On the specific ten-point rubric used in the commercial-prompt analysis, brands scoring 5 to 6 averaged an 11.2% recommendation rate. Brands scoring 7 to 8 averaged 23.6%, while those scoring 9 to 10 averaged 24.8%. The large change occurred when sites moved from partially clear to explicitly clear; the difference between clear and comprehensive was much smaller.

    A score of 7 is not an industry standard or a guarantee. It is a useful diagnostic line from this dataset. Below it, missing fit information can prevent a brand from entering the serious consideration set. Above it, suitability and authority have more room to decide which clear option gets recommended.

    Audit each commercially important page against four questions:

    • Offering: Can a reader identify exactly what is being sold from the opening copy, without decoding a slogan?
    • Fit: Does the page explicitly name the customer types, use cases, and situations for which the offer is appropriate?
    • Specifics and proof: Does it provide available details about the process, pricing approach, service area, results, awards, or relevant customer examples?
    • Organization: Can someone scan headings, bullets, and genuine comparison tables to find those answers quickly?

    The common failure is a page that names the service but makes the reader infer suitability from logos or broad language such as “businesses of all sizes.” Replace that implication with a direct statement. A useful opening pattern is: “[Offering] is a [category] for [customer type] that needs [use case or outcome] in [relevant situation].” The brackets are prompts for substance, not a sentence to copy mechanically.

    Give each material offering its own page. Add a fit section that says who should consider it and which conditions change the recommendation. Explain how it differs from adjacent options. Publish concrete facts you can support, including a pricing approach when exact prices cannot be public. This work improves both human evaluation and machine interpretation because it removes the need to guess.

    Make your facts consistent, then build the right authority

    Several abstract information sources send matching light pulses to a central sphere supported by an illuminated framework, while one conflicting pulse fades away.

    Consistency is more than spelling the company name the same way. It means that your offer names, audience, locations, pricing model, capabilities, and proof do not change as someone moves between your website and independent references.

    That matters because cross-source consistency retained a +9.4-point association with recommendation rate after authority was controlled. A model can work with a qualified claim repeated accurately across several places. It has a harder decision when the homepage, product page, directory profile, and review coverage describe materially different businesses.

    Create a canonical fact ledger before asking teams to update pages independently. It should contain:

    • The official brand name and a plain description of the business.
    • The canonical name and definition of every material offering.
    • The audience, use cases, and suitability conditions for each offer.
    • Locations or service areas, where relevant.
    • The pricing approach and any public qualification criteria.
    • Approved proof points, including the exact scope and date behind each result.
    • Awards, credentials, and other claims that can be independently verified.

    Compare that ledger with your homepage, product and service pages, location pages, directory entries, review profiles, and independent coverage. Correct owned pages first. Then request corrections where third-party information is outdated. Prioritize contradictions that change eligibility or fit, such as an old service area, a discontinued product name, or a claim that applies to one offer but appears to describe the whole company.

    Authority is not interchangeable with structured data. The unadjusted difference associated with any schema was +3.7 points, but it fell to +0.4 after list mentions, reviews, awards, and related authority signals were controlled. That does not assign a causal value to any one authority tactic. It does show why adding markup to an under-recognized brand should not be mistaken for building recognition.

    The most useful form of third-party evidence also depends on the buying market. In consumer categories, expert reviews outweighed customer reviews by 15 to 1 in AI search, while B2B software showed the reverse pattern. Treat that result as directional rather than a rule for every niche, but do not copy one review strategy across both markets.

    • For a consumer category, identify the credible expert reviewers and category comparisons that buyers already use. Make your product facts easy to verify, and correct inaccurate coverage where possible.
    • For B2B software, prioritize authentic, specific customer-review evidence in the places buyers consult. Generic praise is less useful than a review that identifies the customer situation and the product’s role.
    • For either market, keep externally promoted claims aligned with the canonical facts on your site. More mentions will not solve a contradiction that makes the offer harder to classify.

    Use schema to transmit facts, not invent importance

    Schema has a real job: it labels entities and properties in machine-readable form. That job is valuable, but it is different from earning a recommendation. The safest implementation rule is simple: structured data should faithfully represent useful facts that a visitor can already verify on the page.

    Product schema deserves separate treatment for ecommerce. Among the 214 ecommerce brands in the sample, it retained a +4.8-point association after authority control. That is the only measured markup type with a meaningful adjusted difference in the available data. It still does not prove a guaranteed lift, but it gives ecommerce teams a stronger reason to prioritize accurate Product markup than a service business has to deploy several marginal schema types.

    Use this implementation order:

    1. Fix the visible offer, fit, and proof on the page.
    2. Select a schema type that corresponds to the entity actually described, such as Organization or Product.
    3. Make names, descriptions, and other claims match the visible content and your canonical fact ledger.
    4. For ecommerce, prioritize accurate Product markup before adding loosely relevant schema types merely to increase the count.
    5. Add FAQ content only when it answers questions that help a buyer decide. Treat FAQ schema as encoding for that content, not as an independent visibility lever.
    6. Validate the markup and review it whenever the visible facts change.

    Apply the same discipline to llms.txt. Its adjusted difference was -0.1 points in the measured sample, which is effectively no demonstrated lift there. You may still test it as a low-cost machine-accessibility experiment, but it should not displace work on unclear pages, conflicting facts, or missing authority.

    Comparison tables sit between content and structure. Their adjusted association was a modest +1.9 points. Use one when a buyer genuinely needs to compare audiences, use cases, features, or alternatives. A table that exposes meaningful differences can improve clarity; a table built only to look optimized adds no new information.

    Key takeaways: choose your next optimization ticket

    • Fix explicit fit first. Every important offer should state what it is, who it serves, when it is suitable, and what evidence supports it.
    • Reconcile facts across the web. Maintain one canonical ledger and use it to correct high-impact contradictions on owned pages and third-party profiles.
    • Build market-appropriate authority. Consumer categories may lean more heavily on expert reviews, while B2B software may depend more on customer-review evidence.
    • Make schema accurate and proportionate. Product schema has the strongest measured case for ecommerce; Organization schema, FAQ schema, and llms.txt should not outrank clarity work.
    • Measure recommendations, not implementation volume. Use a fixed set of commercial prompts across the platforms that matter, record whether your brand is named and for which use case, then inspect the pages and evidence supporting each result.

    Start with the highest-value product or service page, not a sitewide markup rollout. Make one offer fully explicit, reconcile its facts, align its external evidence, and then encode it accurately. Once that page can answer what, who, when, where, and why without inference, you have a useful model for the rest of the site.

    References


  • What the Penske AI Overviews Dismissal Means for Publishers

    What the Penske AI Overviews Dismissal Means for Publishers

    If your business depends on Google referrals, the dismissal of Penske Media’s AI Overviews lawsuit does not make the traffic problem disappear. It removes one attempted legal route, while leaving you with the same commercial question: which pages are losing valuable visits, and what should you change?

    The practical lesson is not that publishers must accept every search change without scrutiny. It is that expected organic traffic is not the same thing as a negotiated commitment. You need to manage Google as a distribution channel whose economics can change, not as a party that has promised to deliver a particular audience.

    What the judge decided – and what he did not

    U.S. District Judge Amit P. Mehta dismissed Penske Media’s case because its reciprocal-dealing theory did not identify an actual agreement under which Google promised traffic in exchange for access to the publisher’s content.

    Penske’s theory treated two longstanding activities as an exchange: publishers permitted standard web crawling, and Google sent users to their pages through search results. The court found no sufficiently pleaded bargain behind that pattern. There were no alleged negotiated terms, mutual commitments, or communications establishing that Google owed Penske a specific quantity of traffic – or any traffic at all.

    “An expectation is not an agreement.”

    U.S. District Judge Amit P. Mehta

    That distinction matters. Penske alleged that Google’s near-90% search dominance enabled it to use publisher material in AI summaries without paying for it. It also alleged that AI Overviews appeared on roughly 20% of searches linking to its sites and contributed to a one-third decline in affiliate revenue by late 2024. Those figures describe Penske’s allegations; they are not universal benchmarks for every publisher and were not transformed into judicial findings about causation.

    The dismissal is therefore not a finding that AI Overviews cause no economic harm. Mehta explicitly acknowledged the difficult position of publishers and the wider consequences for journalists, educators, and online creators. The missing element was a legally plausible reciprocal agreement, not an allegation of damage.

    This was also the first lawsuit from a major U.S. publisher targeting Google AI Overviews, which makes it tempting to treat the outcome as a verdict on every possible dispute over AI-generated search answers. That reading is too broad. The reported basis for dismissal was the failure of this antitrust theory, under these pleaded facts. For publishers, the immediate consequence is narrower but still important: years of receiving search traffic did not, by themselves, create an enforceable traffic entitlement.

    Key takeaways for publishers and SEO teams

    • The court rejected the alleged reciprocal bargain; it did not find that publishers suffered no traffic or revenue damage.
    • Organic visibility is commercially valuable, but an expectation of referrals is not the same as a contract guaranteeing them.
    • Penske’s exposure and revenue figures belong to Penske’s allegations. Do not apply them to your site without page- and query-level evidence.
    • An AI Overview citation, a conventional ranking, a click, and a conversion are four different outcomes. Measure them separately.
    • Your response should combine search visibility work with stronger reasons to visit, convert, return directly, or join an owned audience.

    Measure AI Overview exposure as a business risk

    An analyst examines abstract content tiles and visitor pathways, some of which stop at translucent summary panels before reaching a publication.

    A sitewide traffic graph cannot tell you whether AI Overviews are the problem. Search demand, rankings, result-page layouts, content changes, seasonality, tracking failures, and monetization changes can move at the same time. Start with the pages and queries connected to revenue, then separate visibility loss from click loss and revenue loss.

    1. Define commercially meaningful page groups. Separate affiliate comparisons, advertising-supported explainers, lead-generation pages, subscription entry points, and content that primarily supports brand discovery. A lost visit does not have the same value across those groups.
    2. Create an observation log for important queries. Record the query, intent, observed presence of an AI Overview, whether your domain appears in it, your conventional result visibility, the landing page, and the observation context. Retain dated result-page captures so later analysis is not based on memory.
    3. Measure each layer of the funnel. Track impressions and search visibility, clicks and click-through rate, on-page conversion, revenue, and revenue per visit. A decline at one layer does not prove a decline at every layer.
    4. Compare like with like. Analyze equivalent page types and comparable periods. Annotate ranking changes, redesigns, content updates, offer changes, tracking deployments, and other result-page features that could provide a competing explanation.
    5. Attach a decision to every monitored cohort. Decide whether the evidence calls for maintaining, rebuilding, diversifying, testing, or simply gathering more observations. Monitoring without a decision rule becomes reporting theater.

    Do not use Penske’s alleged one-third affiliate revenue decline as a forecast for your own business. Use it as a prompt to connect search behavior to money. A mention in an AI result may have visibility value, but it does not pay a publisher’s costs unless it produces a measurable downstream effect.

    Observed patternWhat it may meanYour first decision
    Impressions remain stable while clicks and click-through rate fall on queries showing AI OverviewsYour pages may still be exposed, but fewer searchers need to leave the results pageStrengthen the reason to visit and assess whether the remaining visits still convert profitably
    Impressions, conventional visibility, and clicks all fallRanking, demand, indexing, or broader result-page changes may be involvedInvestigate those variables before assigning the entire decline to AI Overviews
    Clicks fall while conversion rate or revenue per visit risesYou may be receiving fewer but more qualified visitorsEvaluate contribution and profit, not sessions alone
    Traffic remains stable while conversion or revenue fallsThe larger problem may be tracking, monetization, offer quality, or page experienceAudit the commercial funnel before rebuilding content for AI search

    This framework will not prove legal causation on its own. It will give you a better operating diagnosis and a cleaner evidence trail than a single before-and-after traffic chart.

    Give readers a reason to continue past the generated answer

    A reader walks past a shallow translucent summary card toward a warmly lit space filled with reporting materials and investigative work.

    A page that does nothing beyond restating a short factual answer is especially exposed when a search feature can provide that answer directly. The response is not to obscure the answer. It is to make the page useful after the answer has been understood.

    Build three distinct layers into important content

    • The answer layer: State the answer clearly, define important terms, identify relevant entities, and make dates or qualifications explicit. This helps readers verify quickly that the page addresses their question.
    • The evidence layer: Support the answer with material you genuinely possess, such as original reporting, primary data, a transparent methodology, documented testing, expert analysis, or useful visual evidence. Do not manufacture novelty merely to appear original.
    • The action layer: Help the reader complete the next task with a calculator, decision framework, comparison method, configuration checklist, downloadable template, current inventory, or another function that cannot be replaced by a one-paragraph summary.

    For AI SEO and generative engine optimization, optimize citation and conversion as separate jobs. Clear structure, consistent entity names, meaningful headings, and accurate structured data can make content easier for machines to interpret. They do not create a contract for inclusion, compensation, ranking, or traffic. JSON-LD should describe what is visibly true on the page; it should never contain unsupported claims added solely for an AI system.

    Then inspect the post-click experience. If the title promises a comparison, the page should make comparison easy. If the searcher needs a decision, show the criteria and the tradeoffs. If the information changes, explain how it is maintained and make the update date meaningful. The reader should encounter additional value immediately, not after an extended preamble.

    Make portfolio decisions based on replaceability

    Classify content by how easily its value can be compressed into a generated answer:

    • Defend high-value, differentiated pages. Keep their facts current, improve their evidence, and remove friction between the search landing point and the useful feature or commercial action.
    • Rebuild commodity pages that still serve a real audience. Add decision support, proof, maintenance discipline, or a practical tool instead of merely adding more words.
    • Diversify around valuable topics. Offer relevant email updates, alerts, accounts, communities, or direct-use tools where those features solve an actual recurring need. The purpose is to create a consensual return path, not to force a signup before delivering value.
    • Consolidate cautiously. Do not delete or noindex pages merely because an AI Overview appeared for a query. Removing indexed content can sacrifice remaining visibility and links. Preserve performance data, choose a genuinely relevant destination, and plan redirects before consolidating anything.

    Affiliate-dependent templates deserve particular scrutiny because Penske tied its claimed damage to affiliate revenue. Look beyond word count. Ask whether the page offers real product judgment, explains its selection method, distinguishes user needs, and remains accurate. If its only function is to restate information available everywhere else, adding generic prose will not repair its economics.

    Keep evidence that supports decisions, not just frustration

    The ruling exposes a gap between business harm and the evidence required for a particular legal claim. Publishers may experience both traffic loss and weaker monetization, yet still lack proof of a contractual or reciprocal commitment. If the issue may reach executives, a trade body, a regulator, or legal counsel, keep an evidence file that preserves the distinction.

    • Dated captures of the relevant result pages, including the query and observation context.
    • A record of whether your URL appeared conventionally, appeared as an AI Overview citation, appeared in both places, or did not appear.
    • Page- and query-group performance showing impressions, clicks, click-through rate, conversions, and revenue where available.
    • A change log covering content edits, technical releases, ranking movements, monetization changes, and analytics changes.
    • The method used to calculate any claimed loss, with assumptions and competing explanations stated plainly.
    • Applicable contracts, licenses, platform terms, negotiated commitments, and communications. Preserve versions instead of relying on recollection.

    Business analysis asks whether a platform change damaged your economics. Legal analysis asks whether the facts satisfy the elements of a viable claim. Those are connected questions, but they are not interchangeable. If you are considering litigation, licensing action, or a platform restriction that could affect discoverability, have qualified legal counsel evaluate the live facts and current law; an SEO analysis is not a substitute for legal advice.

    In your next reporting cycle, split the queries where you observe AI Overviews from the rest of your search portfolio and connect both groups to page-level outcomes. Then assign one response to each important content group: defend it, rebuild it, diversify its acquisition path, or continue monitoring it. That gives you a decision system even when the legal and product environment remains unsettled.

    Google referrals can remain valuable without being guaranteed. Treat them as platform-dependent distribution, preserve evidence when the economics change, and invest in content people have a reason to visit rather than merely summarize.

    References


  • AI Overviews on Branded Searches: A Practical Audit Plan

    AI Overviews on Branded Searches: A Practical Audit Plan

    You can still rank first for your own name and lose control of the first impression. When a Google AI Overview appears on a branded query, it can frame your company, products, policies, or reputation before the searcher decides whether your result deserves a click.

    Your job is not to make every overview disappear or chase every citation. You need a repeatable way to find the queries that matter, distinguish a genuine brand risk from a harmless summary, repair weak information at its origin, and measure whether search behavior changes.

    Ranking first no longer tells you how Google frames your brand

    The scale of the change makes branded AI visibility worth treating as a standard search responsibility. In one tracked branded-keyword set, AI Overview presence rose from about 26% at the start of September to more than 80% late in the month, with a peak of 90.48% on September 27. A separate SerpApi check found AI Overviews for 93 of 100 enterprise brands.

    Those figures are a warning to monitor, not a universal incidence rate or a forecast for your site. The tracked terms were checked once per day across all markets and devices, and an overview counted as present whether or not it cited the brand. The enterprise-brand check was a separate snapshot. Google had not announced a corresponding change when the surge was observed.

    This distinction matters. An AI Overview can appear on your branded query without using your site as evidence. It can also cite you while compressing a qualification that matters to a buyer. Presence, citation, accuracy, framing, traffic, and business impact are separate things. Track them separately.

    Key takeaways

    • Treat branded AI Overviews as a search, content, and reputation surface rather than another ranking position.
    • Monitor high-intent and high-consequence brand modifiers, not only your exact company name.
    • Record what the overview says, which pages it cites, whether an owned page appears, and which claims need correction.
    • Repair canonical facts and contradictory content before trying to influence the wording of a generated answer.
    • Measure branded clicks and outcomes directly. Wider AI Overview presence does not, by itself, prove traffic loss.

    Build your monitoring set around real brand decisions

    Blank query cards are grouped around objects representing a company, product, policy, purchase decision, and reputation, with priority markers and a magnifying glass.

    A search for your bare brand name is only the starting point. The more revealing queries combine the brand with a decision, concern, or task. That is where an inaccurate synthesis can change what someone buys, believes, or does next.

    Build a stable query set from your search-query data, customer questions, support records, sales objections, and reputation monitoring. Group the terms by the decision behind them:

    • Identity: your brand name, what the company does, who it serves, and how it differs from similarly named entities.
    • Commercial: brand plus pricing, plans, products, availability, integrations, demo, or purchase terms.
    • Evaluation: brand plus reviews, alternatives, comparisons, complaints, reliability, or legitimacy.
    • Service and policy: brand plus login, contact, cancellation, refund, support, privacy, security, returns, or warranty.
    • Named entities: important products, locations, programs, and publicly associated people whose details affect how the brand is understood.

    Do not prioritize by search volume alone. A low-volume cancellation, security, or product-eligibility query can create more damage than a high-volume neutral query. Give each query an intent label and a consequence label. This lets you separate commercially important or reputationally sensitive questions from routine navigational searches.

    Check the list under repeatable conditions. Use the same market, device class, and signed-in state where possible. For every observation, preserve enough information to compare it later:

    • The exact query, not a shortened topic label.
    • The date, market, device class, and relevant session conditions.
    • Whether an AI Overview appeared.
    • The complete wording or a screenshot of the answer.
    • Every cited page and the order in which citations appeared.
    • Whether any cited page is controlled by your organization.
    • Each factual claim that is correct, outdated, incomplete, unsupported, or false.
    • The associated branded impressions, clicks, click-through rate, and business outcomes, kept outside the content-quality judgment.

    That last separation prevents a common analytical mistake. An overview can be factually poor without producing a measurable traffic decline, and it can be factually accurate while changing click behavior. You need both views to decide what deserves action.

    Grade the answer by consequence, not by whether you like it

    A generated description does not become a defect merely because it is less flattering than your marketing copy. Your audit needs labels that another person can verify. Start with factual accuracy, necessary context, citation support, and likely consequence.

    FindingWhy it mattersNext move
    Materially false claimIt could send a customer to the wrong action or create a false belief about the company, product, price, access, or policy.Document the correct fact, identify the likely conflicting evidence, and escalate it ahead of ordinary optimization work.
    Outdated factThe answer may once have been correct but no longer reflects a current offer, feature, location, policy, or relationship.Strengthen the current canonical page and clearly mark or update obsolete owned material.
    Qualification removedA broadly correct statement becomes misleading when a market, plan, eligibility rule, date, or other condition disappears.Put the condition next to the claim on the canonical page rather than burying it in a footnote or separate document.
    Claim unsupported by citationsThe answer goes beyond what its cited pages substantiate, making the synthesis difficult to verify.Capture the mismatch, then improve the clearest first-party evidence for the underlying question.
    Third-party-heavy citation setYour brand may be described mainly through reviews, directories, forums, or commentary even when an owned explanation should exist.Determine whether your page fails to answer the query directly before treating the third-party citations as the problem.
    Accurate but unfavorable descriptionThe answer may reflect a real customer, policy, product, or reputation problem rather than an information-retrieval failure.Address the underlying issue. Rewording your own page will not make a substantiated concern disappear.
    Accurate and adequately framedThe overview creates no material information problem even if it does not use your preferred language.Log it and monitor it. Do not manufacture work merely to replace neutral wording.

    Escalate first when a claim is both materially wrong and connected to an important decision. A false statement about whether a product is available, how an account is accessed, or what a policy permits deserves faster attention than an awkward but harmless company description.

    An owned citation is useful, but it is not a passing grade by itself. Read the generated claim against the cited passage. If your page states that a condition applies only to one plan or market, but the overview presents it as universal, the citation has not prevented a meaning error.

    Repair the evidence behind the answer

    A strategist reconnects several generic source documents so they feed through clear paths into a stable digital answer panel.

    You cannot directly edit an AI Overview. You can make the underlying information clearer, more consistent, and easier to verify. Work from the highest-consequence defect outward.

    1. Choose one canonical owned page for each important question cluster. A pricing query needs a current pricing page, not a vague feature page. A cancellation query needs a current policy or help page, not a promotional FAQ that avoids the actual process.
    2. Answer the question in visible copy. Use the exact company and product names. State the direct answer before the supporting detail. If the answer changes by market, plan, eligibility, or date, place that qualification beside the claim.
    3. Reconcile contradictions across owned material. Check product pages, support content, policy pages, legacy posts, downloadable documents, profiles, and location pages. Mark outdated material clearly and direct readers to the current record.
    4. Make structured data corroborate the page. Encode only facts supported by visible content and keep the values aligned with the canonical wording. Treat structured data as machine-readable confirmation, not a command that guarantees a particular overview or citation.
    5. Classify every influential third-party citation. Decide whether it is accurate, outdated, false, or opinion. For a verifiably false or stale statement, provide the publisher with concise evidence and the canonical correction. If the criticism is accurate, fix the underlying issue instead of pursuing removal simply because the page is unfavorable.
    6. Log the change and recheck the same query. Record what changed, where it changed, and which claim you expected it to clarify. A later overview change is useful evidence of movement, but it is not proof that one page edit caused the result.

    Avoid publishing a near-duplicate page for every branded modifier. That creates more places for facts to drift. One strong page can answer a coherent group of questions as long as its purpose, headings, and qualifications are explicit. The goal is query-to-answer alignment, not content volume.

    Also resist the urge to rewrite everything in promotional language. Generated answers need verifiable facts. Clear scope, current conditions, named products, and direct policy wording are more useful than unsupported claims of leadership or quality.

    Measure traffic impact without inventing a CTR story

    Wider AI Overview coverage does not prove that branded clicks have fallen. Neither the tracked branded-keyword series nor the separate enterprise-brand check measured clicks, leaving the actual branded CTR effect unknown. Treat traffic loss as a question to test in your own data, not a conclusion supplied by presence alone.

    Keep a stable query panel so the denominator does not change every time you run the audit. Track these measures by query cluster:

    • AI Overview presence: checked queries that triggered an overview divided by all checked queries.
    • Owned-citation coverage: triggered overviews containing at least one owned citation divided by all triggered overviews.
    • Material accuracy: high-consequence overviews without a material factual or qualification error divided by all high-consequence overviews reviewed.
    • Source mix: the balance of owned pages, publishers, review sites, directories, forums, and other cited page types.
    • Search response: impressions, clicks, and click-through rate for the same branded query clusters.
    • Business response: the relevant purchases, leads, account actions, support contacts, or other outcomes from branded landing sessions.

    Maintain both an unweighted query view and an impression-weighted view. The unweighted view stops a high-volume navigational term from hiding a serious low-volume error. The weighted view shows where changes could affect the largest share of observed search demand.

    Annotate other events that can change branded demand or result-page behavior, including campaigns, publicity, product changes, seasonality, and additional search features. If AI Overview presence rises while clicks and business outcomes remain stable, there is no evidence of an emergency. If CTR falls while conversions remain stable, investigate whether fewer low-intent visits explain the difference before declaring damage. If clicks and meaningful outcomes fall persistently within the same high-intent cluster, inspect the overview, citations, landing result, and other result-page changes together.

    A materially false answer remains a brand problem even when traffic looks normal. Conversely, an accurate overview is not automatically harmful because it answers part of the question without a click. CTR is a diagnostic measure; accurate representation and valuable business outcomes are the goals.

    Start with a small, consequential baseline: assemble your highest-intent and highest-risk branded modifiers, capture the current answers and citations, and correct the first material inconsistency you can verify. Once that record exists, the next AI Overview change becomes an observable search event rather than an anecdote.

    References