Tag: AI optimization

  • Schema and Entity Optimization for AI Search: A Practical Audit

    Schema and Entity Optimization for AI Search: A Practical Audit

    Your JSON-LD validates, yet your brand still goes missing when people ask AI systems for recommendations, comparisons, or eligibility advice. The problem may not be syntax. Valid markup can sit on top of vague, incomplete, or contradictory facts.

    The useful goal is not to publish the largest possible schema graph. It is to make the facts that drive a customer’s decision explicit, consistent, verifiable, and connected. The process below gives you a practical way to find those entity gaps, decide which ones matter, and fix the page and its markup together.

    Define the entity model before touching your JSON-LD

    Schema is a translation layer, not a fact factory. It can express that an organization offers a service, that a program has a duration, or that an event starts on a particular date. It cannot resolve a policy your organization has not settled or turn vague marketing language into a reliable claim.

    Start by asking what an answer engine would need to know to describe your offer without guessing. For most commercial or institutional pages, that includes:

    • What is the offer, and what is its canonical name?
    • Which organization provides it?
    • Who is it for, and what eligibility rules apply?
    • What does it cost, how long does it take, and how is it delivered?
    • What outcomes can you substantiate?
    • Which related people, locations, credentials, products, or services help distinguish it?

    Turn those questions into a target entity model. This can begin as a spreadsheet rather than code. Give each row a subject, a claim or relationship, an approved value, a primary page, an internal owner, a public evidence location, and the schema type or property that could represent it.

    For example, a degree program is an entity. Its provider, delivery mode, duration, credit total, language, admissions threshold, tuition, start dates, curriculum, and outcomes are properties or related entities. A software product would have a different model, but the reasoning is the same: identify the facts a buyer uses to recognize, compare, and choose it.

    Classify every target fact using four states:

    • Legible: The fact is specific, visible on the appropriate page, and represented consistently in structured data.
    • Ambiguous: Something is stated, but its meaning is too loose to support a dependable answer. Phrases such as competitive pricing, flexible study, or a good academic record fall into this category unless the page defines them.
    • Unverifiable: The claim appears in content or markup, but you cannot connect it to an approved policy, responsible owner, or supporting evidence. Unverifiable does not automatically mean false; it means you are not ready to publish it as a firm fact.
    • Missing: The fact belongs in the target model but is absent from the primary page, supporting content, or structured data.

    This distinction prevents a common audit failure. A missing fact needs content or data. An ambiguous fact needs precision. An unverifiable fact needs organizational resolution. Those are three different jobs, and adding more JSON-LD solves only one of them.

    Prioritize the entities that affect a real decision and belong on a high-value page. A clear eligibility rule on a core service page usually deserves attention before a minor biographical detail on an ancillary page. Also favor facts your organization can approve and maintain. A theoretically valuable property is not a useful priority if nobody can establish its current value.

    Run a three-layer entity audit
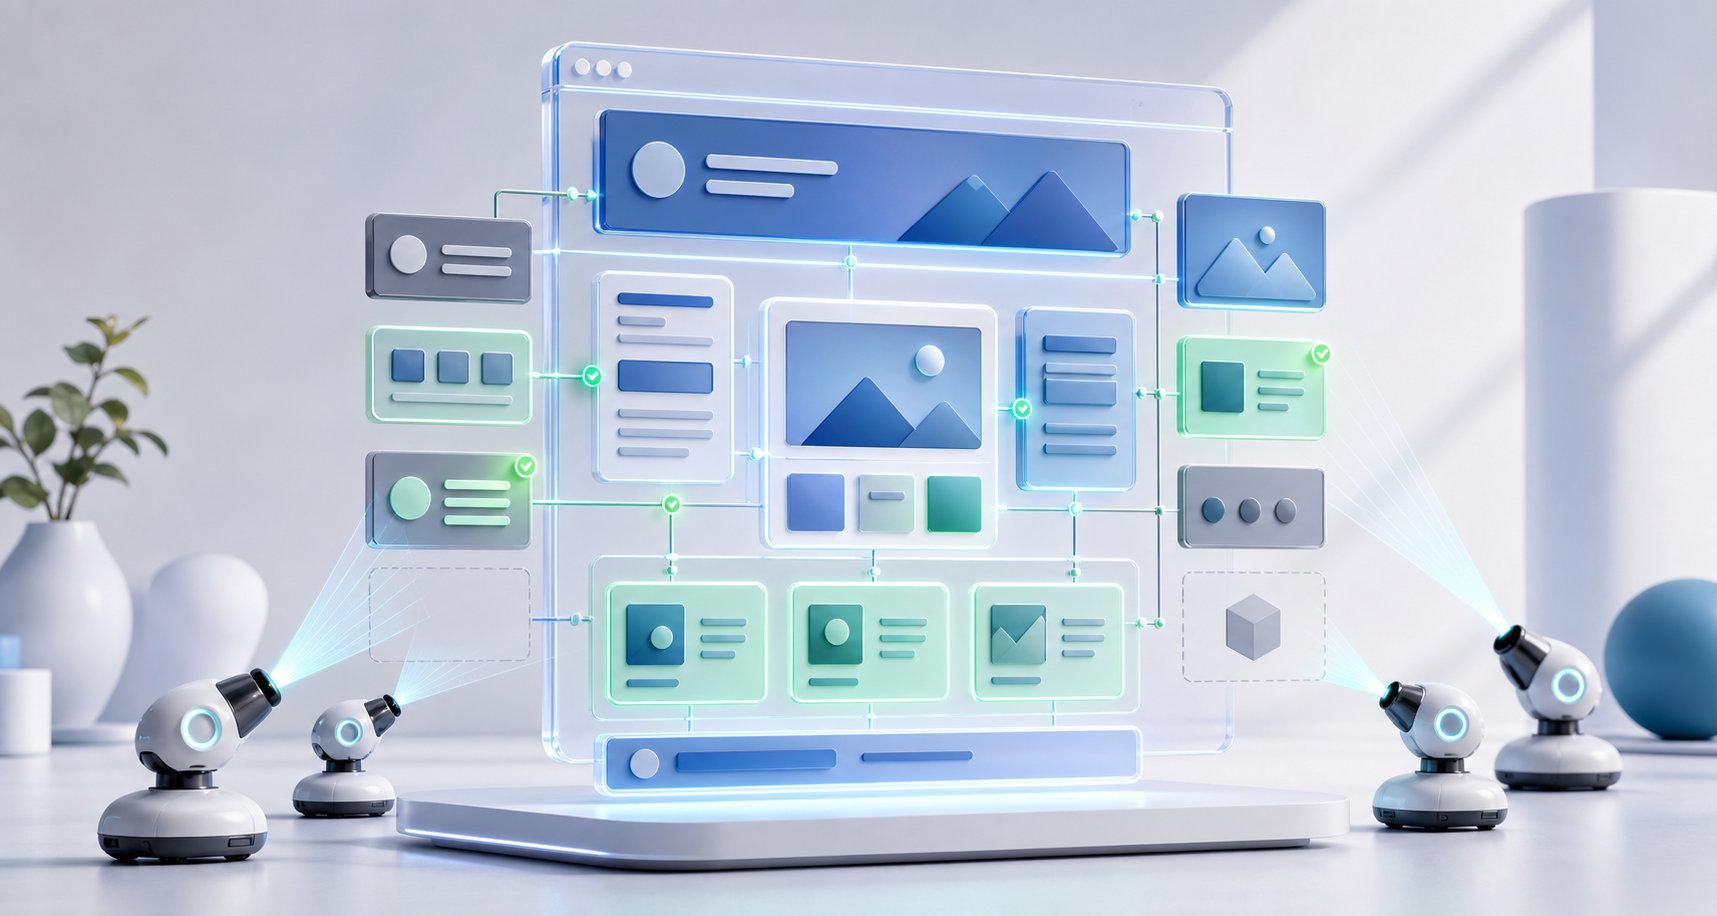
    A transparent three-layer workspace shows website content, structured data, and external evidence being inspected together.

    A schema validator tells you whether markup is technically parseable. An entity audit asks a harder question: does the site communicate the right facts clearly enough for a person or machine to connect them?

    Audit three layers at the same time:

    • Visible content: Is the fact stated plainly on the page where a visitor would expect to find it?
    • Structured representation: Does the JSON-LD identify the correct entity, use an appropriate property, and carry the same value as the visible page?
    • Supporting context: Is there enough related content to explain or substantiate the claim, and does that content point back to the primary entity?

    Work through the audit in this order:

    1. Select the primary conversion page. Start with the page that owns the offer: the product, service, program, location, or other page on which the decision happens.
    2. List the decision-critical entities and facts. Use customer questions, qualification requirements, commercial terms, and differentiators rather than copying whatever happens to be in the current schema.
    3. Read the page as a skeptical visitor. Record the exact visible wording for every target fact. Do not silently reinterpret vague copy during the audit.
    4. Inspect the JSON-LD entity by entity. Match every node to a real thing, then compare its properties with the visible wording and approved value.
    5. Trace supporting pages. Note where details such as curriculum, outcomes, policies, specifications, or staff credentials live and whether their relationship to the primary offer is clear.
    6. Assign a status and an owner. Mark the fact legible, ambiguous, unverifiable, or missing. Then identify who can approve the fix and whether it belongs in content, structured data, or both.

    Do not assume that broad coverage means strong entity clarity. In two higher-education implementations, a large share of the entities already present still proved ambiguous or unverifiable. One comparison set contained 85 custom JSON-LD entities; the existing site covered more than 50, but roughly a third of those were ambiguous or unverifiable and more than 20 were missing from program or supporting pages. Another audit identified 58 entities, with more than half classed as ambiguous and 27 classed as unverifiable.

    That pattern matters because a conventional schema audit could report substantial coverage while overlooking the uncertainty inside it. Count the quality states, not just the properties.

    If you manage hundreds or thousands of pages, embeddings can help with triage. Convert your approved target statements and your live content into comparable vector representations, then surface low-similarity areas for human review. Treat the similarity score as a queue, not a verdict. It can reveal that the language on a page does not resemble the intended entity model; it cannot decide whether a policy is true, a schema property is valid for a type, or a claim has been approved.

    Fix the visible fact and its structured representation together
    Matching location facts are corrected simultaneously on a website interface and in a connected structured-data network.

    When the audit exposes a gap, diagnose it before editing:

    • Content gap: The organization knows the fact, but the primary page does not state it clearly.
    • Schema gap: The visible page is clear, but the JSON-LD omits the fact, formats it poorly, attaches it to the wrong entity, or conflicts with the copy.
    • Truth gap: The organization cannot yet supply one reliable value because the policy is unsettled, varies by case, or lacks an accountable owner.

    For content and schema gaps, use a single publishing sequence:

    1. Confirm the approved value with the person or system that owns it.
    2. Rewrite the visible content so a visitor can understand the fact without decoding internal terminology.
    3. Represent the same fact in JSON-LD using an appropriate schema.org type, property, value format, and unit.
    4. Connect supporting pages to the primary entity with consistent naming and purposeful internal links.
    5. Check the rendered page and structured data for disagreement before publishing.

    Normalize values without making the page less human

    Machine-readable precision does not require robotic visible copy. A visitor can read 15 months while the structured representation uses the applicable ISO duration. The important point is that both expressions mean the same thing.

    Decision factWeak or incomplete expressionMore precise representationVisible-page requirement
    Program duration15 months stored only as textISO 8601 duration P15MExplain that the program takes 15 months under the stated schedule
    Start dateAmbiguous date wordingAn exact YYYY-MM-DD value when one date genuinely appliesShow the corresponding date and any campus or cohort conditions
    Credit total45 credits and 90 ECTS combined in one text stringQuantitativeValue with the relevant unit textMake each credit system and its meaning clear
    LanguageEnglish as unnormalized textISO 639-1 code en where the property expects itState that instruction is in English
    Minimum GPAGood academic recordAn approved numeric threshold such as 3.0 on a 4.0 scaleState the threshold, scale, and any genuine qualification

    These are examples of entity reconciliation applied to a particular university program, not values to copy. P15M is correct only when the duration is actually 15 months, and a 3.0 threshold should appear only when admissions has approved that rule. The correct schema property also depends on the type of entity you are marking up.

    Keep identities and relationships stable

    Give each core entity a stable identifier in your graph, commonly an @id based on a URL you control. Reuse that identifier when another node refers to the same organization, offer, person, or place. Otherwise, minor naming variations can produce duplicate-looking entities inside your own markup.

    Use the narrowest schema type that is genuinely accurate, and use only properties supported for that type. Connect entities with specific relationships instead of placing every keyword in a description field. Your graph should be able to express which organization provides the offer, where it is available, which people are connected to it, and which supporting resources explain it.

    The primary conversion page should own the essential decision facts. Supporting content should deepen them. An admissions page can explain an eligibility process, a curriculum page can detail course structure, and an outcomes page can substantiate career information, but each should reinforce the canonical offer rather than introducing a competing name or contradictory value.

    Do not use schema to paper over an operational problem

    A truth gap has to move outside the SEO queue. Send it to the team that owns pricing, admissions, compliance, product, or operations. Record what must be decided and leave the value out until it can be stated accurately.

    Completeness is not worth misleading someone. One multi-campus university left an application-deadline entity unresolved because rolling starts across campuses made a single deadline potentially inaccurate. Another program did not emphasize faculty data when availability could not be maintained. In both situations, publishing a neat but unreliable value would have made the graph look fuller while making the answer worse.

    When a value legitimately varies, explain the rule or scope if the organization can support it. Identify which location, plan, cohort, product variant, or date range the value applies to. If that relationship is not yet knowable, omit the claim rather than guessing.

    Measure entity quality, AI visibility, and business value separately

    Markup does not guarantee growth. It removes ambiguity and gives your content a more coherent machine-readable representation, but rankings, citations, recommendations, and conversions have many other inputs. Your measurement plan should therefore keep three scorecards separate.

    • Entity quality: Track how many target facts are legible, ambiguous, unverifiable, or missing. Also count contradictions between visible content and JSON-LD, and note whether high-priority facts appear on the primary page.
    • Search and AI visibility: Track citations, inclusion in answers, and share of voice against a fixed competitor set for a stable group of prompts. Preserve the prompts and competitors so a changing test does not masquerade as improvement.
    • Business outcomes: Track the actions that matter after discovery, such as qualified leads, applications, purchases, payments, or stage-to-stage conversion rates. Better entity clarity may improve qualification even when top-line traffic is flat.

    Record the publication date, pages changed, entities affected, content edits, and schema edits. That change log will not create a controlled experiment, but it will stop you from crediting an isolated markup change for work that also included clearer copy, new supporting content, and internal linking.

    Two higher-education cases illustrate why the scorecards belong together. In one case, AI citations rose from 24,000 in January 2026 to 42,000 in July, a 75% increase over six months. Enrollment remained flat and lead volume fell, yet the lead-to-payment rate improved by 20% and the application-to-payment rate improved by 26%. The commercially important movement was not simply more discovery; it was better progression among people who entered the funnel.

    In the other case, organic lead volume increased 18% from 2025 to 2026 and application volume increased 22%. AI citations were about 11% higher year over year and roughly 77% above the preceding six months, while competitive share of voice gained one percentage point.

    Treat those results as directional case evidence, not universal benchmarks. The work combined entity reconciliation, visible-content changes, supporting pages, internal links, and structured data. The reasonable inference is that the coordinated package improved clarity and performance; the figures do not isolate JSON-LD as the sole cause.

    Your first success metric should be controllable: fewer ambiguous and unverifiable facts on the pages that matter. Visibility and conversion trends can then show whether that stronger information layer is helping people and AI systems find a clearer answer.

    Key takeaways

    • Build the target entity model from customer decisions, not from the schema already installed.
    • Classify each fact as legible, ambiguous, unverifiable, or missing so the right team gets the right kind of work.
    • Make the primary conversion page the source of essential facts, then use supporting content to explain and substantiate them.
    • Update visible copy and JSON-LD together. Precise markup attached to vague or conflicting content does not resolve the underlying entity.
    • Normalize dates, durations, quantities, units, and identifiers only after the organization has approved the real value.
    • Measure entity quality separately from AI visibility and business outcomes, and do not attribute a combined content-and-schema program to markup alone.

    Open your highest-value page and list the facts a buyer needs before choosing the offer. Mark each one legible, ambiguous, unverifiable, or missing. Then take one high-impact cluster – eligibility, price, delivery, specifications, or outcomes – through approval, visible copy, JSON-LD, supporting content, and measurement. That page-level cycle is how entity optimization becomes durable infrastructure instead of a one-time GEO tactic.

    References


  • Goodie vs Peec AI: Which AEO Platform Should You Choose?

    Goodie vs Peec AI: Which AEO Platform Should You Choose?

    If you are choosing between Goodie and Peec AI, the decisive question is not which dashboard looks better. It is where you want the platform’s job to end. Peec AI is oriented around monitoring and reporting. Goodie is designed to carry the work from monitoring into recommendations, content, commerce visibility and attribution.

    That distinction affects more than the feature list. It determines how much analysis your team must do after the dashboard identifies a visibility gap, which other tools you will need, and whether the resulting report can be connected to business outcomes.

    Goodie supplies the feature and pricing claims available for this comparison. Its descriptions of Goodie are first-party claims, while its descriptions of Peec are second-hand. Confirm Peec’s current limits, pricing, integrations and security documentation directly with Peec before signing a contract.

    Key takeaways

    • Choose Peec AI when monitoring is the deliverable. Its reported strengths include prompt tracking, citation analysis, competitor benchmarking, unlimited users, credit allocation across projects and agency pitch workspaces.
    • Choose Goodie when the platform must support execution. Goodie combines visibility monitoring with prioritized optimization actions, content creation, technical AEO guidance, AI-shopping visibility and revenue attribution.
    • Do not compare prompt limits with credits as though they were the same unit. Goodie publishes prompt and action allowances, while Peec’s agency plans use credit pools. Ask each vendor to price the same prompt set, engines, countries, refresh frequency and client count.
    • Model count alone is misleading. Peec reportedly reaches a higher enterprise ceiling, but its standard plans let you choose three models from a smaller default set. Goodie’s entry plan includes five named surfaces, while its enterprise tier expands to as many as 12.
    • The lower subscription is not necessarily the lower-cost workflow. Include the analyst time, content tooling, technical implementation and attribution stack required after monitoring identifies a problem.

    Start with the AEO workflow you actually need

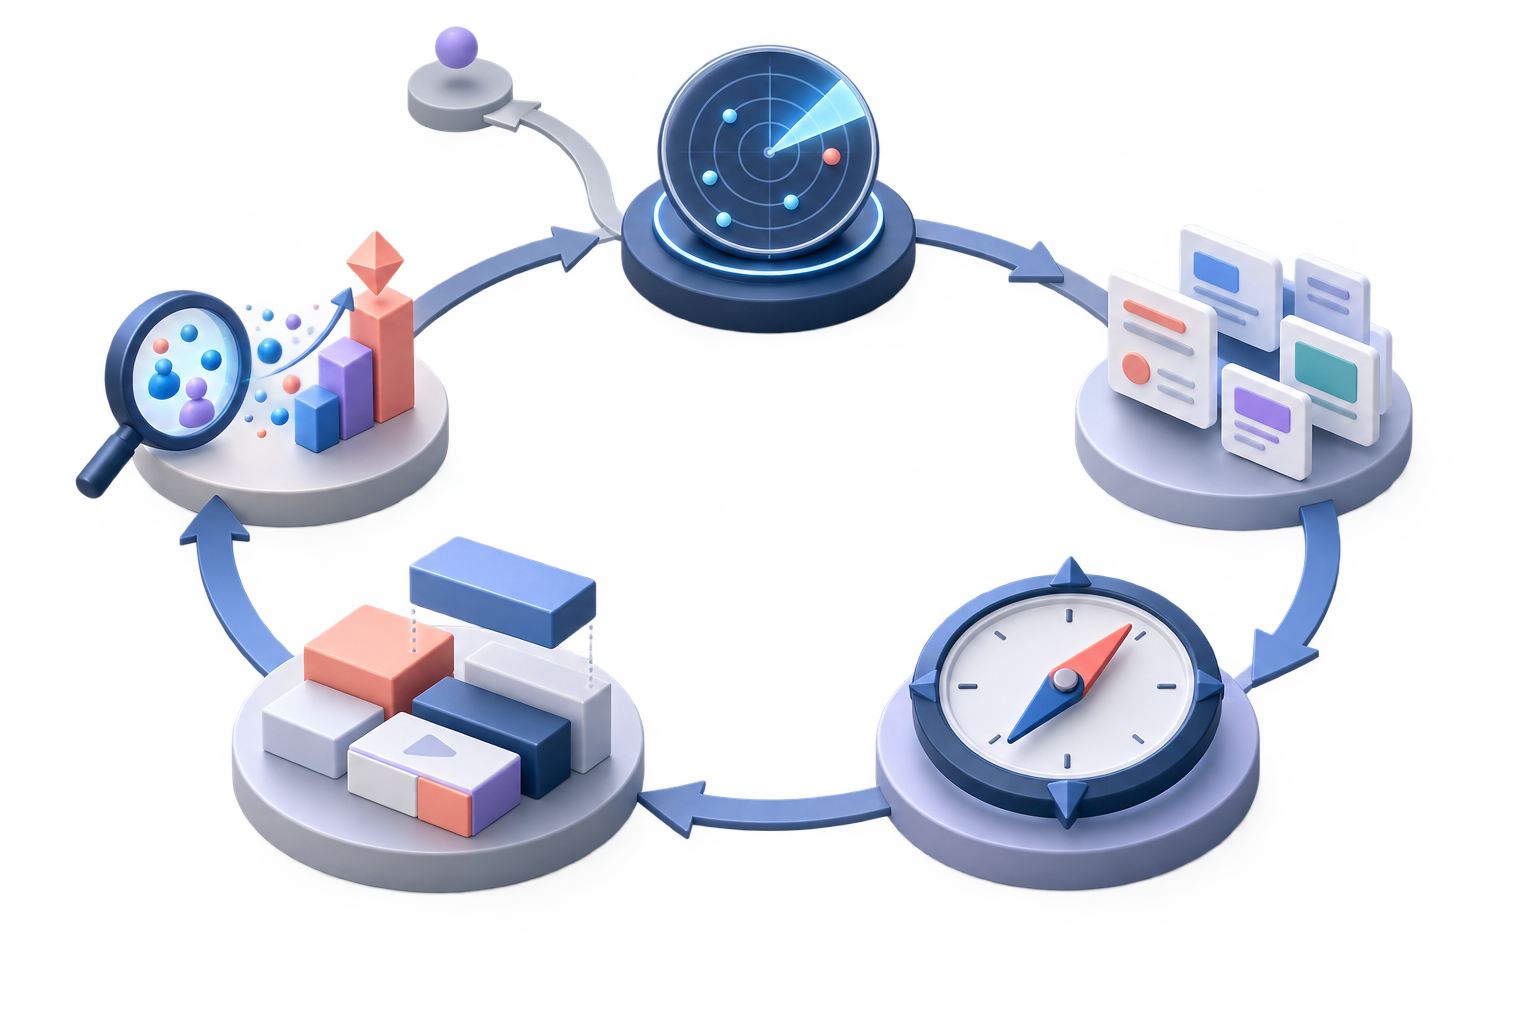
    A circular optimization workflow connects monitoring, analysis, recommendations, content production, and attribution, with one path ending after monitoring.

    An AI visibility platform can perform two fundamentally different jobs. The first is observation: run prompts, capture generated answers, identify citations, measure brand presence and compare competitors. The second is intervention: determine why visibility is weak, decide what to change, produce or update the content, fix technical access and measure the result.

    Peec concentrates on the observation layer. That can be enough when you already have an AEO strategist, content operation, technical SEO team and analytics setup. The platform supplies evidence; your existing people and systems turn it into action.

    Goodie is positioned as a closed-loop system. Its published workflow covers prompt research, visibility monitoring, prioritized recommendations, content production, technical optimization and attribution. That broader scope becomes useful when the same person or small team must move from finding a gap to fixing it without rebuilding the context in several tools.

    Map one real cycle before you evaluate either product:

    1. Select the commercial questions and prompts that matter to your audience.
    2. Run them across the relevant AI engines, country and language.
    3. Identify missing mentions, unfavorable positioning and competitor citation advantages.
    4. Convert each finding into a content, entity, schema, crawlability or distribution task.
    5. Assign and complete those tasks.
    6. Run the same prompt set again and distinguish a meaningful change from normal answer variation.
    7. Connect the result to sessions, leads, conversions or another business measure.

    Now mark which steps your team can already perform reliably. If you only need help with steps two and three, Peec’s narrower scope may be efficient. If the handoff between diagnosis and execution is where work stalls, Goodie’s broader system is the more relevant proposition.

    Goodie and Peec AI feature comparison

    The figures below reflect published feature and plan information from September 2026. Treat them as a purchasing shortlist, not as a substitute for a live product demonstration or contract review.

    Decision areaGoodiePeec AIWhat to verify
    Primary roleEnd-to-end AEO workflowAI visibility monitoring and reportingWhich tasks can be completed without exporting data?
    Standard model accessCore names five surfaces: ChatGPT, AI Overviews, Perplexity, AI Mode and CopilotStandard plans reportedly let you choose three of six: ChatGPT, AI Overviews, AI Mode, Perplexity, Gemini and CopilotPrice the exact engines your customers use, not the maximum advertised count
    Maximum model coverageUp to 12 on EnterpriseUp to 13 on Enterprise, including additional models not in the standard selectionWhich models require an add-on or enterprise agreement?
    Prompt and competitor monitoringIncludedIncludedSampling method, geography, language, refresh cadence and export access
    Sentiment analysisIncluded in the published feature setIncluded on Pro and above in the published plan descriptionHow sentiment is scored and whether individual answers can be audited
    Optimization recommendationsOptimization Hub with prioritized actions across plansNo dedicated recommendation layer reportedWhether recommendations name a page, issue, owner and expected outcome
    Technical AEORecommendations for schema, site structure and crawlabilityNo crawlability, robots.txt or llms.txt auditing reportedWhether the platform detects issues or can also validate a completed fix
    Content productionContent Studio connects prompt gaps with AI-oriented content creationNo content creation studio reportedEditorial controls, brand context, approval workflow and CMS handoff
    Revenue attributionGoogle Analytics attribution on Core, with broader attribution at higher tiersNo direct session, conversion or revenue attribution reportedAttribution logic, supported analytics properties and access to raw data
    AI commerceSKU-level visibility is listed on Pro and EnterpriseNo AI-shopping or agentic-commerce tracking reportedSupported shopping surfaces, product matching and catalog coverage
    Agency operationsAgency Growth plan, client workspaces and Enterprise multi-brand managementUnlimited seats, project-based credit pools, pitch workspaces and white-label reportingTotal cost per active client and the work required outside the platform

    The apparent model-count advantage changes with the plan. Peec’s enterprise ceiling is reportedly 13 models, compared with Goodie’s ceiling of 12, but standard Peec plans are described as a choice of three models. Goodie’s Core plan names five surfaces. If Claude, DeepSeek, Grok or another non-core model matters to your audience, ask for its exact tier and add-on cost. A logo on an enterprise coverage slide does not mean it is included in the plan you are buying.

    Cadence needs the same scrutiny. Goodie describes its monitoring as real-time, while Peec plans are described as supporting daily tracking, with daily or weekly options at some agency and enterprise levels. Ask each vendor what those labels mean operationally: when prompts run, whether failed runs are retried, how model changes are handled and when data becomes available for export.

    Choose according to who must act on the data

    For agencies selling monitoring and reporting

    Peec has the clearer fit when your engagement ends with a visibility report, competitor comparison and client presentation. Unlimited seats reduce friction when strategists, account managers and clients all need access. Credit pools can be shifted between projects, while pitch workspaces let a team build prospect-facing evidence before an account becomes a retained client.

    That operating model can protect agency margin, but only if reporting really is the end of the engagement. If your retainer also promises prioritized recommendations, content briefs, implementation and proof of business impact, add the cost of those activities before declaring Peec cheaper.

    For agencies delivering an ongoing AEO program

    Goodie’s broader workflow is more relevant when the agency owns the outcome rather than the dashboard. Its Optimization Hub is intended to turn visibility gaps into prioritized work, Content Studio addresses the production step, and attribution is intended to connect improvements with traffic and conversions.

    There is an important pricing detail. Goodie’s $350-per-month Agency Growth plan includes 10 pitch workspaces per month and unlimited seats, but ongoing client workspaces run on the brand plan selected for each client. Do not treat $350 as the complete cost of operating 10 retained accounts. Ask for a scenario-based quote that separates prospecting workspaces, active client plans, model access and implementation support.

    For an in-house brand team

    Peec can work well when AI visibility data will enter a mature operating system. A content team can receive citation gaps, technical SEO can handle crawlability and schema, analytics can manage attribution, and a strategist can decide which findings matter. In that environment, buying those functions again inside an AEO platform may add overlap.

    Goodie becomes more attractive when those handoffs are the bottleneck. A recommendation layer is valuable when it reduces the time between noticing a missing citation and assigning a concrete fix. Content tooling is valuable when it preserves the prompt, competitor and brand context that produced the recommendation. Attribution is valuable when leadership will not renew the budget on visibility scores alone.

    For ecommerce and product-led businesses

    SKU-level AI-shopping visibility creates the sharpest difference. Goodie lists that capability on Pro and Enterprise, while Peec is not described as offering product-level commerce tracking. If your question is whether an AI shopping experience can find, compare and surface individual products, brand-level mention tracking is not a substitute.

    Test product matching during the demonstration. Use several real SKUs with similar names or variants and ask the vendor to show how it distinguishes the product, the brand and the category. Also verify which shopping surfaces are included, how frequently the checks run and whether results can be joined to your catalog or analytics data.

    For enterprise procurement

    Goodie says its Enterprise infrastructure is SOC 2 compliant. Peec is described as GDPR compliant, while SOC 2 or HIPAA status was not publicly confirmed in the available material. Absence from a competitor’s page is not evidence that a certification does not exist. Request current documentation from both vendors, including the exact entity and product covered, before a security or privacy review.

    Compare total workflow cost, not the entry price

    A balance scale compares a software tool plus extra tools, handoffs, and time with a more integrated modular workflow.

    Goodie’s published brand pricing is straightforward at the first two levels. Core is listed at $399 per month with 100 prompts, 10 optimization actions per month, three seats, five named AI surfaces and Google Analytics attribution. Pro is listed at $999 per month with 250 prompts, 30 optimization actions, five seats, additional model access, full attribution and SKU-level commerce visibility. Enterprise pricing is custom, with 500 or more prompts, 60 or more monthly optimization actions, 10 or more seats and up to 12 models.

    Peec’s brand tiers are described by capacity rather than dollar price in the available comparison: Starter includes 50 prompts and one project; Pro includes 150 prompts and two projects; Advanced includes 350 prompts and five projects; Enterprise is customizable. The first three let you choose three models and include unlimited users. Because no Peec dollar figures are supplied here, obtain a current quote instead of repeating an assumed entry price.

    Peec’s agency tiers use a different unit:

    • Essential: 10,000 monthly credits, three client projects and 25 pitch prompts.
    • Growth: 25,000 monthly credits, 10 projects and 50 pitch prompts.
    • Scale: 65,000 monthly credits, 25 projects and 75 pitch prompts.
    • Comprehensive: custom pricing with unlimited credits, projects and pitch prompts.

    A prompt allowance and a credit allowance are not directly comparable. Ask Peec how many credits your proposed schedule consumes after multiplying prompts by models, countries, languages, competitors and tracking frequency. Ask Goodie whether the same dimensions consume prompt capacity, require a higher tier or carry another charge.

    Calculate total monthly cost with the same scope on both sides:

    • Platform subscription and required add-ons
    • Additional client, project, model, country and language capacity
    • Analyst time spent translating findings into prioritized work
    • Separate content, technical auditing and project-management tools
    • Implementation time for content, schema, crawlability and measurement changes
    • Analytics engineering required to connect AI referrals with outcomes
    • Reporting, white-labeling and client-access costs

    For an agency, divide that total by active billable clients and then compare it with the gross margin of the service. For an in-house team, compare it with the internal hours removed from the cycle. This exposes the real trade-off: Peec may cost less as a monitoring layer, while Goodie may consolidate work that would otherwise happen in other systems. Consolidation only saves money if your team will use the added capabilities.

    Run one full AEO cycle before you sign

    A dashboard demonstration proves that a vendor can display data. It does not prove that your team can turn that data into a better answer-engine presence. Use the same controlled workflow with both products and require an exportable result.

    1. Fix the scope. Use one commercially important customer journey, the same prompt set, the same brands, the same country and language, and only the engines you genuinely need.
    2. Inspect the evidence. Open individual generated answers and citations. Check whether every aggregate score can be traced to the underlying response.
    3. Create an action backlog. Ask the platform to help identify the page, entity, citation, schema or access issue behind each gap. Record how much manual interpretation is still required.
    4. Complete a real change. Update a page, create the missing content or implement a technical fix. Note every external tool and handoff needed to finish it.
    5. Measure again. Re-run the fixed prompt set. Look for directional improvement across repeated observations rather than treating one generated answer as a stable ranking.
    6. Build the stakeholder report. Produce the exact report your client, marketing lead or finance team expects. Include visibility, actions completed and available business outcomes.
    7. Price the production version. Give both vendors your actual number of prompts, models, markets, users, projects and clients. Request written confirmation of inclusions, overages, exports, support and contract terms.

    If that exercise shows that your team can move cleanly from Peec’s monitoring data into its existing content, technical and analytics systems, the focused platform is likely enough. If the work repeatedly slows at diagnosis, execution or attribution, evaluate Goodie on whether its integrated tools remove those specific delays.

    Make the purchase against the workflow you will operate next month, not the feature ceiling you might need someday. Take one live prompt set through monitoring, action and measurement, total every tool and hour it consumes, and choose the platform that leaves the fewest expensive gaps.

    References


  • Image Optimization for AI Search: A Practical Workflow

    Image Optimization for AI Search: A Practical Workflow

    Your images can be attractive, fast and conventionally SEO-friendly yet still be unclear to an AI system. If the system cannot identify the main object, read an important label or connect the scene to the claims on the page, the image contributes little to a multimodal answer.

    Fixing that problem does not mean putting more keywords into filenames. It means making the pixels, alternative text and visible page copy tell the same specific story. The workflow below will help you decide what each image must communicate, test whether that meaning survives machine interpretation and correct the failures that matter.

    AI search needs an image it can retrieve and explain

    Visual search is no longer a secondary way to browse an image index. People run roughly 20 billion visual searches through Google Lens each month. A search can begin with a camera, an uploaded image or a screenshot when the user cannot easily describe the object in words.

    That changes the optimization target. The old question was whether an image could rank for a text query. The additional question is whether a system can use the image to understand the query, retrieve the associated page and assemble a supported answer.

    Google filed a patent application in 2023, published in April 2026, describing a flow in which an image match identifies a cited page before surrounding text is used to construct an answer. That is not confirmation of a live production ranking process. Patent applications may never be implemented as written. It is still a useful design signal: an image may help a system discover the page whose text supplies the explanation.

    Treat every important image as a paired asset: the visual evidence and the page evidence. Before publishing it, ask four questions:

    • Can the system access and render the image when it retrieves the page?
    • Can it identify the primary product, person, place, condition or process without relying on the filename?
    • Can it read any visible text that is necessary to distinguish a model, package, measurement or state?
    • Does the surrounding HTML text confirm what the image shows and explain why it matters?

    If the image fails the second or third question, fix the asset or choose another one. Metadata cannot rescue a photograph whose subject is tiny, obscured or visually ambiguous. If it fails the fourth question, improve the page copy. A model should not have to infer a critical fact from pixels alone.

    Run two audits: what is visible, then what it implies

    An orange trail shoe is shown under a magnifying lens on one side and beside a rocky path, mud, and a water bottle on the other.

    A useful image audit separates literal recognition from implied meaning. Combining them too early hides the cause of a failure. You may think an image communicates expert installation, for example, when a machine sees only a person standing beside a cabinet.

    Audit the literal contents without page context

    Start with denotation: the objects and attributes that can actually be pointed to in the frame. Hide the headline, caption, filename and surrounding copy. Then write a neutral inventory of what is visible.

    For a product photograph, that inventory might include a stainless steel coffee maker, a thermal carafe, a control panel and a visible model label. For a service photograph, it might include a leaking pipe joint, a wrench and a technician wearing protective gloves. Keep interpretation out of this first pass. Words such as premium, reliable and professional are conclusions, not visible objects.

    Now ask a capable multimodal model for a literal description using a neutral instruction such as: “List the objects, visible text, materials, conditions and relationships in this image. Do not infer facts that are not visually supported.” Compare its output with your own inventory and with the visual brief.

    This is a diagnostic check, not a simulation of any particular search engine. Different models can produce different descriptions, and one successful response does not prove retrieval or citation. The test is still valuable because a missed primary object exposes an avoidable ambiguity in the image.

    When an essential object or attribute is missed, inspect the likely visual cause:

    • The primary subject occupies too little of the frame.
    • Another object has stronger contrast and becomes the apparent subject.
    • The item is partly hidden, cropped or viewed from an angle that conceals its defining shape.
    • Several similar objects overlap, making their boundaries unclear.
    • Glare, shallow focus or compression makes packaging text unreadable.
    • The rendered website crop removes information that was present in the original file.

    Fix composition before metadata. Use a clearer angle, tighter crop, simpler background, additional close-up or separate detail image. Product galleries should not make one wide lifestyle photograph perform every recognition task.

    Audit the meaning created by the composition

    The second pass examines connotation: what the combination of objects, people and setting implies. This is where co-occurrence matters. A wrench beside a visibly damaged fitting tells a different service story from the same wrench lying on a spotless workbench. A team portrait in an identifiable office says something different from anonymous people in a generic meeting room.

    Write the intended meaning in one sentence. Then underline the visible evidence that supports every part of it. If the intended meaning is “a technician diagnosing a leaking kitchen connection,” the frame should contain a technician, a relevant connection and evidence of the leak. If only the kitchen is visible, the image is decorative context rather than proof of the service.

    Use these questions to expose weak or accidental implications:

    • What is the most prominent entity, and is it the entity the page is about?
    • What relationship between the visible entities would a neutral viewer infer?
    • Which object introduces an unrelated interpretation?
    • Does the setting support the intended use case, location or audience?
    • Are you asking the image to prove a credential, performance claim or identity that only text can establish?

    Original imagery matters most when the image is supposed to establish identity or evidence. A stock photograph can illustrate a general concept, but it cannot reliably prove what your product looks like, who works on your team, where your business operates or how your service is performed. Use visible page copy to name people, roles, credentials and locations rather than expecting a model to infer them from appearance.

    Give each page type a deliberate visual job

    An image should be briefed against the decision a visitor is making on that page. The same attractive photograph will not serve a homepage, product page and technical explainer equally well. Different page types require different visual evidence, especially when a multimodal system may use that evidence to interpret the surrounding content.

    Page typePrimary visual jobWhat the image should make detectableWhat the page text should confirm
    HomepageEstablish the brand and offeringAn original product, location, team or use context rather than an interchangeable mood imageThe brand name, principal offering and relationship between the visible entities
    Product pageSupport identification and comparisonThe complete product, multiple angles, distinctive parts, packaging and legible model or variant textProduct name, variant, materials, dimensions and other attributes relevant to the image
    Blog or information pageExplain a concept, process or claimClearly labelled steps, components, states or relationships in a diagram or infographicEvery substantive claim shown in the graphic, written as ordinary machine-readable HTML text
    About or team pageConnect a person with an organization and roleA clear portrait or authentic workplace contextThe person’s name, role, credentials and authorship relationship where relevant
    Service pageShow the problem, work or outcomeThe actual condition, equipment, process or clearly differentiated before-and-after statesThe service performed, the meaning of each state and any necessary limitations
    Contact or location pageReinforce physical identity and placeThe exterior, entrance, interior or recognizable local contextThe business name, address and relationship between the pictured place and the business

    Give each image one primary job even when it can support several queries. A product hero can establish the overall shape; a second image can expose controls; a third can make the package label readable. This is clearer than forcing a single distant photograph to carry every attribute.

    Be especially careful with infographics and before-and-after images. Do not leave the claim inside the graphic. Repeat it in the page copy, identify which state is which and explain what changed. The image can demonstrate the relationship, while the text supplies the exact claim and its qualifications.

    Publish the image and page as one semantic unit

    A red insulated bottle, its studio photograph, a blank article layout, and a transparent lens are connected by soft blue light on a desk.

    Write a visual brief before choosing the asset

    A useful visual brief is short enough to apply during a content review. For each important image, record:

    • Target question: the query or decision the visual should help resolve.
    • Primary entity: the product, person, place, condition or process that must be recognized.
    • Must-detect details: the visible attributes needed to distinguish the entity or explain the answer.
    • Must-read text: labels or packaging copy that must remain legible in the delivered image.
    • Intended implication: the relationship or use case the composition should communicate.
    • Supporting sentence: the nearby HTML text that names and explains what the image shows.
    • Failure condition: the omission or misreading that would make the image misleading or useless.

    This brief prevents a common mismatch: copy written around a concrete answer paired with an image selected for atmosphere. It also gives designers, photographers, writers and SEO teams one set of acceptance criteria.

    Preserve meaning through the technical delivery

    Traditional image hygiene still matters, but each choice should preserve recognition as well as performance. Use a descriptive filename because it provides context, not because a keyword-rich filename can override the pixels. Supply responsive dimensions and an appropriate format, then inspect the image as it actually appears on the page.

    Compression deserves a visual check at every important breakpoint. A package label that is crisp in the master file may become unreadable in a smaller responsive variant. Performance optimization should preserve the legibility of product text, labels and diagram annotations that a system needs to interpret the image.

    Use loading settings that improve page performance while keeping the image available when the page is rendered and retrieved. Check the delivered page rather than assuming the media library preview represents what a crawler or visitor receives.

    Write alternative text for accuracy and accessibility

    Alternative text should describe the image’s purpose in its page context. Keep it natural and factual. Do not turn it into a string of search terms, and do not insert claims the pixels do not support.

    For example, “Stainless steel coffee maker beside its thermal carafe, with the model name visible on the front panel” is useful when those details help the reader understand the product. “Coffee maker, best thermal brewer, premium coffee machine” is neither a reliable description nor good accessible text.

    Complex diagrams need more than a long alt attribute. Give the image a concise accessible description, then explain the important steps, comparisons or claims in visible HTML text. A decorative image that contributes no information should use the appropriate empty alternative text rather than forcing irrelevant keywords onto screen-reader users.

    Run the final check on the rendered page

    Use this sequence before publishing or replacing a high-value image:

    1. Write the target question and the one visual fact that helps answer it.
    2. List the entities, attributes and text that must be detectable in the frame.
    3. Inspect the image without page context and record a literal human description.
    4. Run the same blind description through at least one multimodal model and note omissions or competing interpretations.
    5. Correct the crop, angle, clutter, visibility or export quality before changing metadata.
    6. Confirm that the alt text and nearby page copy accurately name what is visible and carry every important claim.
    7. Test the delivered image at the page’s actual responsive sizes, including the legibility of labels and annotations.
    8. Save the intended query, observed description and corrections so that later asset changes can be reviewed against the same brief.

    After publication, use a fixed set of visual and text queries when checking search or AI-answer visibility. Record whether the image appears, whether the associated page is cited and whether the answer describes the intended attributes accurately. An appearance is evidence of visibility, not proof that one metadata change caused it, so compare repeated checks rather than drawing a conclusion from a single result.

    Key takeaways

    • Optimize the visual evidence and the page evidence together; neither should contradict or depend on the other to repair ambiguity.
    • Test literal recognition before judging brand meaning. If the primary entity is missed, fix the composition first.
    • Control co-occurrence deliberately. Every prominent object and person in the frame contributes to the meaning a model may infer.
    • Assign images different jobs by page type: identification on product pages, explanation on information pages and entity confirmation on team or location pages.
    • Repeat substantive graphic claims in visible HTML text. Important facts should not exist only inside pixels or alternative text.
    • Compress for performance while checking the actual delivered crop, resolution and text legibility.
    • Treat multimodal model descriptions as diagnostic observations, not guarantees of ranking, retrieval or citation.

    Start with five pages that matter commercially or editorially. Hide the copy, inspect each rendered image and ask what a neutral observer can actually identify. Replace or recompose the images that fail that blind test, then align the alternative text and nearby copy with what remains. That small, documented audit gives you a repeatable standard for every visual you publish next.

    References


  • How to Make Your Business Verifiable in AI Search

    How to Make Your Business Verifiable in AI Search

    Your business may be established, trusted, and easy for customers to find, yet still disappear when someone asks an AI assistant for a recommendation. The problem is often not a lack of authority. It is that the system cannot retrieve enough consistent evidence to confirm who you are, what you do, and whether your website represents the same entity described elsewhere.

    You can fix that gap. Start by treating AI visibility as an entity-verification problem, then make the verified facts technically retrievable, reinforce them across credible profiles, and measure the answers your target customers actually receive.

    Key takeaways

    • Audit identity before tracking mentions. An AI system cannot reliably recommend a business it cannot resolve into one clear entity.
    • Give your business one canonical, current identity across its primary domain, important profiles, directories, and public records.
    • Put essential facts in readable HTML. A polished client-side application can still look empty to a retrieval process that does not execute its JavaScript.
    • Use Organization or an appropriate LocalBusiness subtype in JSON-LD to express the same facts people can see on the page. Schema should clarify your content, not contradict or replace it.
    • Track visibility, prominence, sentiment, and citations across a controlled set of prompts. Record factual errors separately so identity problems do not hide inside a visibility score.
    • Treat AI-assisted conversions as a multi-touch measurement problem. Referral traffic alone will not show every customer who researched you through an AI assistant.

    Diagnose verifiability before chasing AI mentions

    A mention is the end of a chain, not the beginning. Before an answer engine can include your business, its retrieval process has to find information about you, extract usable facts, connect those facts to the same entity, and decide that the evidence is suitable for the question.

    This creates four separate layers to audit. A failure at an earlier layer usually cannot be repaired by optimizing a later one.

    LayerQuestion to testTypical failure signalNext move
    IdentityIs there one unambiguous business entity?Several domains, names, addresses, or descriptions compete with one another.Choose canonical facts and reconcile conflicting properties.
    RetrievabilityCan a simple fetch extract the important facts?The source response contains an application shell, images, or scripts but little meaningful text.Server-render or pre-render critical content and navigation.
    CorroborationDo credible external records support the same identity?Directories, registries, social profiles, and partner pages describe different businesses.Correct the records you control and document unresolved conflicts.
    VisibilityDoes the business appear for relevant prompts?Competitors are named while your business is omitted, mischaracterized, or supported by weak citations.Analyze prompt fit, cited pages, missing evidence, and competing entities.

    The size of this problem should not be treated as a universal market statistic. Still, one regional audit shows how severe the mechanism can become. Across 71 verified businesses on Prince Edward Island, a custom points-based framework classified the average business as leaking 84% of its identity, while 17% had no AI-retrievable digital presence. The sample was geographically limited, but its failure patterns are practical audit targets: hidden leadership details, unreadable JavaScript sites, dead domains, conflicting domains, and businesses represented only by third parties.

    Run your first audit from ground truth, not from an AI answer. Create a record containing your public business name, any legal-versus-trading-name relationship, primary category, products or services, locations and service areas, current domain, public contact details, named leadership, official profiles, and any public credentials you actively claim. If your own team cannot agree on a field, an external system has little chance of resolving it correctly.

    1. Write down the canonical value for every identity field. Do not copy values from a directory until someone responsible for the business has confirmed them.
    2. Locate the best supporting page on your own domain for each value. Mark facts that exist only in an image, PDF, script-rendered interface, or old announcement.
    3. Fetch the homepage and essential entity pages without relying on a normal browser session. Confirm that their main text and links exist in the returned HTML.
    4. Compare the canonical record with major profiles, directories, registries, social accounts, partner pages, and alternate domains.
    5. Record conflicts as specific repairs: old phone number, former leader, obsolete service, duplicate domain, missing location, or ambiguous business name.
    6. Only after those checks, capture a baseline of AI answers for the prompts that matter commercially.

    Build a canonical identity that machines can resolve

    Matching website, listing, map, contact, and service profile tiles connect to one model business while mismatched fragments remain outside.

    A canonical source of truth is not merely a canonical URL tag. It is a coherent identity system in which your pages, structured data, domains, and external profiles point toward the same real-world organization.

    Put the verification summary near the front door

    Do not force a retrieval system to reconstruct your business from a slogan, a footer, and an About page several clicks away. Your homepage should state the essential identity in ordinary text and link directly to pages that substantiate it.

    • Use the exact public name customers should recognize. If the trading name differs materially from the legal name, explain the relationship where it is relevant.
    • Write one literal sentence that identifies the business category, audience, core offer, and location or service area.
    • Show a current address or service area and a working contact route. Do not publish a location you cannot consistently support elsewhere.
    • Name the people responsible for the business when leadership is public and relevant to trust. Link to a proper team or leadership page with roles and biographies.
    • Link to current About, Contact, location, service, policy, and other evidence pages using descriptive anchor text.
    • Remove claims that are obsolete, unverifiable, or contradicted by newer pages.

    A useful drafting pattern is: “[Business name] is a [business category] serving [audience] in [location or service area], led by [person and role], and offering [primary products or services].” You do not have to publish that wording verbatim. The test is whether a reader can complete every bracket from a short passage of visible text.

    Leadership information deserves special attention. In the regional audit, 22 of the 71 businesses had identifiable leadership somewhere on their websites, but important details often sat on secondary Team, History, or Family pages that a routine homepage pass did not retrieve. Keep the deeper biography where it belongs, but surface names, roles, and a direct link from a prominent entity page.

    Resolve competing and obsolete domains

    Multiple domains are not automatically wrong. They become an identity problem when they present the same entity as separate, competing businesses or when external profiles alternate between them without explaining the relationship.

    • Select the live domain that will serve as the primary home of the entity.
    • Redirect obsolete variants to the closest relevant page on the primary domain when you own them and consolidation matches the real business structure.
    • Update important directory, registry, social, partner, and campaign links so they no longer reinforce an outdated domain.
    • Keep ownership of legacy domains that still carry brand value, links, or customer traffic. Letting one lapse can be difficult or expensive to reverse.
    • Use canonical URL declarations to consolidate duplicate pages, but do not mistake page canonicalization for entity reconciliation.
    • If two domains represent genuinely separate brands, divisions, or legal entities, explain those relationships instead of collapsing them for convenience.

    Dead domains are especially damaging because they preserve an old identity signal without providing current evidence. A real business can remain active while its former domain is parked, offered for sale, or empty. That leaves third-party platforms to become the most retrievable account of the brand.

    Make every important fact retrievable

    A search orb retrieves service, location, credential, policy, and contact symbols from the open rooms of a structured website.

    A site can work perfectly in a modern browser and still return almost no usable content to a direct fetch. The common failure is client-side rendering with no static fallback: the server returns a thin application shell, and JavaScript creates the meaningful page only after a browser runs it.

    Do not assume that every AI product, crawler, citation service, or retrieval agent will execute your application exactly as a customer browser does. Inspect the response that arrives before JavaScript runs.

    1. Request the public URL in a source or fetch inspection tool. Confirm that it returns a successful response and meaningful text, not only script references and empty containers.
    2. Look for the business name, description, contact details, primary headings, navigation links, and links to About, Team, Contact, and location pages in the returned HTML.
    3. Repeat the check on the pages that support identity claims. A readable homepage does not help if the leadership or location page still depends entirely on client-side execution.
    4. If essential content is missing, use server-side rendering, static generation, or reliable pre-rendering for public pages. The exact implementation can vary, but the initial response must carry the facts.
    5. Retest after deployment. A visual browser check alone does not confirm that the fallback works.

    Also avoid making an image, canvas, video, or downloadable PDF the only carrier of an important fact. Those formats can support the page, but the business name, offer, location, people, and contact routes should have clear HTML equivalents.

    Use JSON-LD as an identity map, not a magic ranking switch

    Structured data gives machines an explicit representation of facts that might otherwise have to be inferred from layout and prose. For a business, that normally begins with Organization or the most accurate LocalBusiness subtype. The node should describe the real entity shown on the page, not a more attractive category you hope to rank for.

    • Assign the organization a stable @id and reuse that identifier wherever pages refer to the same entity.
    • Align the name, URL, logo, telephone, address, and other material fields with visible content and your canonical identity record.
    • Connect official profiles through appropriate properties, and include only profiles that are current and actually represent the entity.
    • Represent locations and people as distinct entities when that structure is useful, then express their relationship to the organization accurately.
    • Keep multi-location data specific to each location page. Do not mark every branch with the headquarters address or merge separate phone numbers into one ambiguous record.
    • Make the JSON-LD available in the delivered page source or through rendering that the intended crawler can consistently access.
    • Validate syntax after every material change and inspect the values, not just the absence of parser errors.

    JSON-LD cannot rescue a dead domain, settle contradictory profiles, or prove a claim simply because you marked it up. It reduces ambiguity when it agrees with readable content and corroborating evidence. If the markup calls the company one thing while the page and public records call it another, you have formatted the conflict rather than resolved it.

    Reinforce the same identity beyond your website

    Your website is the best place to state who you are, but self-published claims are only one part of verification. Credible external records help an AI system connect the business on your domain with the entity found in local listings, public registries, professional associations, partner pages, social profiles, and relevant coverage.

    Consistency does not mean forcing identical marketing copy into every profile. It means keeping identity-bearing fields compatible: name, URL, location, phone number, category, leadership, and the plain facts of the offer. A short directory description and a detailed About page can differ in tone while still describing the same entity.

    1. Prioritize properties that customers and retrieval systems are already likely to encounter: major business profiles, applicable public registries, industry directories, official social accounts, and important partner listings.
    2. Claim and verify profiles where the platform permits it. Remove duplicate entries or request corrections rather than allowing several partial identities to persist.
    3. Replace obsolete domains, phone numbers, addresses, leaders, and service descriptions.
    4. Link external profiles back to the best canonical page, not automatically to the homepage when a location or division page is the accurate destination.
    5. Document records you cannot edit. A conflict log should include the URL, incorrect field, requested correction, request date, and current status.
    6. Recheck important records whenever the business changes its name, ownership presentation, leadership, domain, location, or primary offer.

    When your own domain is incomplete or unreadable, the most machine-friendly third party can become the practical source of truth. That can have a direct cost. In the Prince Edward Island audit, third-party booking resellers appeared alongside or above some hotel and golf-property booking pages, creating an identity gap with commission consequences. If an intermediary is easier to verify than the property itself, the intermediary has a better chance of shaping both the answer and the transaction path.

    Do not manufacture corroboration through fake profiles, fabricated reviews, or low-quality directory submissions. The goal is not to create the largest number of mentions. It is to make legitimate evidence easier to reconcile.

    Measure the answer, the evidence, and the business effect

    Once the identity foundation is sound, you can answer the practical question: does the business appear when a prospective customer asks an AI system for help?

    Use a controlled prompt set based on real decisions, not one branded vanity query. Include category discovery, location-qualified needs, use cases, constraints, and comparison questions that match the work your business wants. A useful set might cover prompts shaped like “Who provides [service] in [place]?”, “Which [category] is suitable for [use case]?”, and “What should I compare when choosing a [provider type]?”

    For each prompt and engine, record visibility, position, sentiment, and citations. Add factual accuracy as a separate review field because a prominent mention with the wrong location, service, or ownership is not a successful result.

    MeasureWhat to recordWhat it tells you to do
    VisibilityWhether the business is named for the prompt.Investigate prompt relevance, entity resolution, and missing supporting content.
    PositionWhether it is a leading recommendation, a later option, or a passing mention.Compare the evidence and cited coverage attached to more prominent competitors.
    SentimentWhether the description is positive, neutral, negative, or cautionary, plus the exact reason.Correct factual problems and strengthen weak evidence; do not reduce a nuanced answer to a color alone.
    CitationsEvery URL used to support the answer, classified as owned, third-party, or competitor-controlled.Improve influential owned pages and address inaccurate external records.
    AccuracyWrong names, services, people, locations, availability, or relationships.Trace each error to conflicting, stale, or absent evidence and log the repair.

    Keep the testing conditions interpretable. Record the engine, prompt wording, date, language and location context, relevant account or personalization state, full answer, and cited URLs. Generated responses can vary, so one answer is an observation, not a stable ranking. Repeat prompts under comparable conditions and look for patterns over time.

    Do not collapse the results into one unexplained visibility score. A composite number can rise while citations shift from your domain to an intermediary, sentiment worsens, or a factual error becomes more prominent. Keep the underlying observations available so someone can see what changed and choose the right repair.

    Connect visibility to outcomes without overstating attribution

    AI-assisted discovery is difficult to attribute because a customer may research in an assistant, return through search or a direct visit, and convert in a later session. Among 494 agency professionals surveyed for a vendor-produced 2026 benchmark, 48% said they could not reliably track AI discovery and 47% could not attribute conversions across multi-session AI-assisted journeys. Those percentages describe that survey population, not every business, but the measurement limitation is real.

    • Add an AI-assistant option to appropriate “How did you hear about us?” forms, with an open field for the customer to name the tool or describe the query.
    • Preserve direct referral data when it exists, but do not treat it as the complete AI-influenced audience.
    • Annotate major identity, content, domain, and profile changes so visibility movements can be compared with known interventions.
    • Compare AI visibility with qualified leads, branded demand, direct visits, and conversions as supporting signals. A simultaneous change is not proof that one caused the other.
    • Review citation paths for commercial leakage. If an AI answer repeatedly sends people through a reseller or aggregator, measure the cost and decide whether your direct page needs stronger verification, clearer content, or a better transaction path.

    Start with one high-intent customer scenario and the page that should prove your business belongs in its answer. Make the identity explicit, make the evidence retrievable, reconcile the strongest external records, and then rerun the same prompt set. That sequence turns “Do we show up?” from a guess into a repairable business system.

    References

  • Google’s New SEO Guidelines: A Personal Take on Third-Party Tools & AI

    Google’s New SEO Guidelines: A Personal Take on Third-Party Tools & AI

    When I heard that Google had added a new help document to its search developer documentation, I knew I needed to dive in. This new document, “Google Search’s guidance on using third-party SEO tools, services, and advice,” provides updated insights into the world of SEO, especially revolving around the hot topic of generative AI optimization.

    Google also revamped its “Do you need an SEO?” guide, adding fresh content around generative AI topics. The intent behind these updates, as stated by Google, is to highlight what to consider when evaluating third-party tools and to simplify existing documentation. They want us to be cautious about trusting these tools and advice without proper verification.

    Reading through Google’s new guidance, I found some valuable advice on thoughtfully evaluating third-party SEO services. Here’s how they suggest approaching it:

    Evaluate external SEO advice against Google’s official guidelines, think critically about third-party tools, and always verify the claims made by these services.

    • Evaluate and verify external SEO advice against official Google guidelines
    • Think critically about using third-party SEO tools and services
      • Assisting in sitemap generation
      • Establishing indexing directives
      • Offering to generate “SEO-optimized” content for you
      • Providing advice to improve the ranking of existing content
      • Promising improvements for AI experiences and search formats (“AEO” or “GEO” tools)

    While Google doesn’t endorse any third-party tools, they emphasized using Google Search Console for credible data directly from Google Search. We need to be wary of tools claiming to guarantee success since they lack access to Google’s internal ranking data.

    With the updated “Do you need an SEO?” document, Google has also covered topics like Optimizing for generative AI. It includes essential reminders that if an SEO uses a third-party tool, one should not assume it’s approved by Google, and during audits, access to Search Console should be limited initially.

    In essence, before making any site changes based on third-party audits, it’s crucial to cross-reference their advice with Google’s official resources, especially when it comes to AI optimization strategies.

    Understanding these updates helps us not only in improving our own SEO strategies but also in promoting ethical and effective use of tools.

    The document updates come as a reminder for us to regularly check Google’s official documentation. Staying informed about new guidelines ensures that we’re always on the right path in our SEO journey.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Microsoft Web IQ: How to Optimize for AI-Agent Search

    Microsoft Web IQ: How to Optimize for AI-Agent Search

    If you’re wondering whether Microsoft Web IQ requires a new SEO playbook, the short answer is no. You don’t need a Web IQ schema or a separate version of your site. You do need content that an AI agent can discover, interpret, verify, and reuse across a chain of searches.

    That shifts the work from chasing one visible ranking to making every useful fact easy to retrieve. Here’s how to adapt without abandoning the technical SEO and content standards that already matter.

    Key takeaways

    • Web IQ connects AI systems with current web pages, news, images, and videos through AI-native grounding APIs built on Bing’s index.
    • AI agents may run several searches, refine their questions, and collect evidence before producing an answer.
    • A conventional rank position is a limited way to judge visibility when an agent is assembling an answer from multiple retrieval steps.
    • Clear answer sections, crawlable HTML, consistent entities, supported claims, and accurate structured data make your content easier to use.
    • There is no confirmed Web IQ-specific markup shortcut. Optimize the underlying information, not an imagined scoring system.

    What Web IQ changes about search

    Web IQ is a suite of AI-native grounding APIs that connects AI systems to fresh online information. It can retrieve web, news, image, and video material from Bing’s index. The underlying infrastructure also serves Microsoft Copilot, ChatGPT, and other large language model experiences.

    The important distinction is the customer. A traditional search results page is arranged for a person who scans titles, compares choices, and clicks. Web IQ is designed for software that needs to extract information quickly and continue working.

    An agent may begin with a broad request, identify missing details, issue narrower searches, and repeat that process until it can complete its task. Microsoft therefore reworked more than the presentation of results. The system extends from indexing into orchestration, with an emphasis on relevance, speed, and economical token use.

    This is why a single rank number becomes less informative. Microsoft has said that human-style ranking isn’t the priority for this service. That doesn’t mean relevance has disappeared. It means an agent’s repeated retrieval and extraction process may matter more than whether your page occupies one fixed blue-link position.

    Optimize for a search chain, not one keyword

    A luminous agent follows multiple branching paths through document nodes before reaching a verified result.

    Start with the task behind the query. A person asking how to choose accounting software may cause an agent to investigate pricing, integrations, security, migration, support, and suitability for a particular business. A page that repeats the broad keyword but leaves those questions unanswered offers little material for the later steps.

    Map one primary question and the follow-up questions a careful buyer would ask before acting. Give each substantial follow-up its own descriptive heading. If a follow-up requires a full explanation, publish a dedicated page and link it from the main page with anchor text that names the question it answers.

    Build self-contained answer sections

    Each important section should make sense when retrieved without the paragraphs above it. State the subject explicitly, answer the question early, and then add conditions or evidence. Replace vague openings such as “it depends on several factors” with language that identifies what depends on what.

    For example, don’t hide a product’s eligibility rule inside a long narrative. Put the rule under a heading that names the product and decision. Explain who qualifies, who doesn’t, and what the reader should check next. That structure helps people scan the page and gives an agent a coherent passage to extract.

    Cover adjacent questions without bloating the page

    Agent-search readiness isn’t permission to add every remotely related keyword. Include a subtopic when it changes a decision, resolves a likely ambiguity, or supplies evidence for the main answer. Move tangents to their own pages. Thin expansions make the central answer harder to identify.

    Use internal links to form a deliberate evidence path: overview to requirements, requirements to implementation, and implementation to troubleshooting. The destination should answer the promise made by the link. This gives an agent a useful route for deeper retrieval while keeping each page focused.

    Make each page economical for an agent to process

    Web IQ was engineered for frequent searches and low token use. You can’t control how an external agent budgets its context, but you can remove avoidable interpretation work from your pages.

    Lead with the usable answer

    Place the direct answer near the start of the relevant section. Follow it with the reasoning, limitations, and examples. Don’t make a reader or agent work through a brand story before reaching the fact promised by the heading.

    Keep entities and claims consistent

    Use one clear name for each company, product, service, or concept, then explain aliases where necessary. Keep prices, availability, policies, and specifications consistent across landing pages, documentation, feeds, and structured data. Conflicting facts force an agent to resolve ambiguity and weaken the page’s usefulness as grounding material.

    Attach qualifications to the claim they modify. If an offer applies only in one region or a feature requires a certain plan, say so in the same section. A technically correct statement can still mislead when its condition sits several screens away.

    Use structured data as corroboration

    JSON-LD can clarify entities and relationships, but it isn’t a Web IQ access pass. Choose schema types that match the page, populate properties from visible information, and keep the markup synchronized with the content. Don’t mark up answers, reviews, prices, authors, or dates that visitors can’t verify on the page.

    Treat structured data as a machine-readable confirmation of the page, not a substitute for an explicit answer. The visible copy still needs to explain what the entity is, what the claim means, and when it applies.

    Give media enough context to stand alone

    Because Web IQ can source images and videos as well as pages, don’t publish important media with a generic filename and a one-word caption. Use accurate alternative text, descriptive captions, transcripts where appropriate, and nearby copy explaining what the media demonstrates. Keep the media attached to a canonical page with enough context to identify its subject.

    Run an AI-agent readiness audit

    Scanning beams inspect a modular website structure, with accessible content blocks and connections glowing green.

    You can audit a high-value page without access to Web IQ itself. Use the primary question the page should answer, then work through this sequence:

    1. Check discovery. Confirm that the canonical URL is crawlable, returns the intended content successfully, and isn’t blocked by an accidental robots directive or login requirement.
    2. Inspect the delivered page. Verify that the main answer, headings, links, and essential facts exist in the rendered output available to a crawler. Don’t leave the core answer dependent on an interaction that may never occur.
    3. Extract sections out of context. Read each important section by itself. Add the subject or qualification when the passage becomes ambiguous without its surrounding copy.
    4. Trace every consequential claim. Link to supporting documentation where readers need verification. Remove stale claims and unsupported precision.
    5. Compare visible content with JSON-LD. Resolve differences in names, dates, offers, authorship, and entity relationships.
    6. Follow the likely next questions. Make sure internal links lead to complete answers rather than thin category pages or unrelated sales copy.
    7. Test the task in AI assistants. Ask the same realistic question in experiences relevant to your audience. Record whether your brand appears, which page is used, whether the claim is represented correctly, and which competing evidence fills the gaps.
    8. Watch your own evidence. Review referral traffic and server logs where available, but don’t treat either as a complete count of agent visibility. Use them alongside repeated answer checks and conversion data.

    Prioritize corrections that affect the answer itself: inaccessible pages, conflicting facts, missing qualifications, unclear entity names, and unsupported claims. Cosmetic rewrites can wait. An agent can’t use a polished passage it can’t retrieve or trust.

    Web IQ access may broaden as Microsoft scales the service, but you don’t need to wait for a new dashboard. Choose one commercially important topic this week, map the likely follow-up searches, and repair the weakest answer path. That work improves your site for human visitors now while making its information more usable in agent-driven search.

    References

  • Exciting Launch: Profound’s Revolutionary Future Unveiled

    As I look ahead, I’m thrilled to share what we have in store with our latest product, Profound. Over the coming weeks and months, we are embarking on a journey that represents a much bolder move than anything we’ve previously attempted.

    Internally, our team is buzzing with excitement, and we believe it’s time to extend that excitement to you, our valued customers. We’re eager to unveil our vision for the future and how it aligns with your needs.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • A Practical Mathematical Model of Brand Perception in AI Search

    A Practical Mathematical Model of Brand Perception in AI Search

    Your homepage may describe a sharply positioned brand while an AI answer treats you as a generic provider, associates you with the wrong problem, or leaves you out entirely. Rewriting the homepage alone may not fix that mismatch. The stronger signal can be hiding across hundreds of headings, product descriptions, comparisons, help pages, and outdated paragraphs.

    You can make this problem measurable. Model your published content as a cloud of semantic points, examine its center and spread, and then ask whether the right points sit close to the queries you want to win. You won’t reproduce a proprietary AI system, but you will get a disciplined way to decide what to create, rewrite, consolidate, or leave alone.

    Your brand is a cloud of meanings, not a single message

    Start by treating each meaningful section of your content as a separate unit. That reflects the practical reality that AI retrieval can work with small passages rather than whole pages. A carefully worded positioning statement is therefore only one point among all the other passages an AI system may encounter.

    For an audit, split your indexable content into n chunks. Each chunk becomes an embedding vector, v_i, representing its meaning in a multidimensional space. Chunks about similar subjects should sit closer together than chunks about unrelated subjects.

    The simplest brand centroid is the mean of those vectors:

    mu = (1/n) x sum(v_i)

    Scott Stouffer’s framework treats that centroid as a practical representation of how AI may locate a brand in meaning space. It captures an important editorial truth: the accumulated content portfolio can define the computed brand more strongly than the intended brand.

    Do not mistake the centroid for a universal specification or a reputation score. There is no reason to assume every search or answer system stores one permanent master vector for your company. Models, indexes, chunk boundaries, queries, and retrieval methods can differ. The centroid is useful because it turns a vague positioning concern into quantities you can inspect consistently.

    The mean is only the beginning. A mathematically serious audit also looks at dispersion, subclusters, query distance, and overlap with competing content.

    Audit quantityWhat it representsWhat you should notice
    CentroidThe average semantic position of the audited chunksWhether the portfolio’s dominant meaning matches the position you intend
    DispersionThe average distance between chunks and the centroidWhether your message is concentrated or scattered across unrelated themes
    Nearest-chunk distanceThe distance from a target query to its closest relevant chunkWhether you have a passage that directly answers the query
    SubclustersDense groups inside the larger content cloudWhether different products, audiences, or legacy strategies are competing for meaning
    Cluster overlapThe degree to which your semantic territory resembles other brands’ contentWhether your supposed differentiation exists in published evidence or only in brand language

    Dispersion can be expressed as D = (1/n) x sum(distance(v_i, mu)). A low value means your chunks remain relatively concentrated. A high value means they are spread out. Neither result is automatically good or bad. A focused product company may want a tight cloud. A multi-product enterprise may legitimately need several clusters, provided the relationship among the brand, products, audiences, and use cases is explicit.

    This distinction prevents a common mistake: trying to force every page toward one generic corporate phrase. The goal is not identical language. It is a coherent semantic structure in which each important cluster has a clear purpose and an unambiguous connection to the correct entity.

    Retrieval is the gate your positioning must pass

    Traditional rank tracking encourages you to ask where a page appears. AI visibility starts with an earlier question: was a relevant passage considered at all? In the retrieval-first model, content must enter the eligible set before later ranking factors can help it.

    Represent a query as vector q. A retrieval process compares q with candidate chunk vectors and selects close matches. For your own analysis, you might use cosine similarity:

    similarity(q, v) = (q dot v) / (norm(q) x norm(v))

    A higher value in this audit means the query and chunk point in a more similar semantic direction. The exact metric, candidate pool, and eligibility cutoff used by a production system may be different, so do not turn your audit score into a supposed universal threshold. Its value comes from comparing your own pages and measuring change with a consistent method.

    The most useful quantity is often not the distance from q to your overall brand centroid. It is the distance to the nearest genuinely relevant chunk:

    d_min(q) = min distance(q, v_i)

    This changes the content question. You are no longer asking whether the site discusses a broad topic somewhere. You are asking whether one passage expresses the user’s exact problem, your relevant capability, the conditions under which it applies, and the entity responsible for it.

    A retrievable passage should usually survive this five-part test:

    • It gives a direct answer or proposition before expanding into background.
    • It names the brand, product, service, or other entity that owns the claim when the identity would otherwise be ambiguous.
    • It uses the language of the real problem, not only an internal campaign slogan.
    • It states an important boundary, qualification, audience, or use case instead of implying universal applicability.
    • It remains understandable when read without the page title, preceding paragraph, navigation, or hero image.

    Compare two content patterns. A vague passage says: A better way for modern teams to move forward with confidence. A retrievable passage follows a more concrete structure: This product category helps this audience complete this job through this method, and it is not intended for this excluded case. The second pattern creates several semantic anchors without resorting to keyword repetition.

    Page-level strength cannot compensate for every passage-level gap. A page may have strong links, sound technical SEO, and substantial topical coverage while still lacking the chunk that matches a decisive query. That is why your content audit must go below the URL level.

    Three mathematical failure modes explain most positioning gaps

    Three abstract point-cloud scenes show an off-center cluster, a widely dispersed cloud, and several isolated clusters.

    Centroid drift: publishing changes what the portfolio means

    Suppose your existing portfolio has n chunks and centroid mu. You add m chunks whose mean vector is b. The updated centroid is:

    mu_new = (n x mu + m x b) / (n + m)

    The equation exposes two practical levers. The new material pulls harder when there is more of it, and it pulls harder when its meaning is farther from the existing center. One off-topic paragraph may barely move a large corpus. A sustained publishing campaign in an adjacent category can move the portfolio substantially.

    Drift is therefore a portfolio-management problem, not merely an editing problem. Review the semantic direction of a planned content batch before publication. Ask which association the batch strengthens, which existing cluster it joins, and whether the brand genuinely wants to become more closely associated with that subject. Traffic potential alone is not enough.

    This does not mean adjacent content is harmful. Adjacent content becomes dangerous when it is prolific, weakly connected to the core offer, or written without clear entity boundaries. If an adjacent topic serves a legitimate audience journey, connect it explicitly to the relevant problem, product, and next decision.

    Hidden subclusters: the average can conceal a split identity

    An average can land where none of the underlying points actually sit. Imagine that half a company’s content concerns enterprise analytics and the other half concerns consumer productivity. The centroid may fall between the two even though no page clearly owns that middle territory.

    That is why a centroid without a cluster map can mislead you. Inspect the dense groups beneath the mean. For each group, identify its entity, audience, problem, method, and intended query family. If you cannot label a cluster cleanly, the content may be mixing purposes that should be separated.

    When multiple clusters are intentional, give them an explicit architecture. Create a clear hub for each product or solution. State how each one relates to the parent brand. Keep comparisons, use cases, documentation, and proof connected to the correct entity. Consistent structured data can reinforce valid entity relationships, but it cannot rescue page copy that makes those relationships unclear or contradictory.

    Cluster collision: your differentiation disappears in generic content

    If competitors publish the same definitions, broad benefits, listicles, and category language, their semantic clouds can overlap. This cluster-collision problem helps explain why brands with different visual identities can still look interchangeable in meaning space.

    More content is not the direct cure. Publishing another generic overview can make your cluster denser without making it more distinct. Differentiation requires passages that encode substantive differences: the audience you serve best, the problem boundary you recognize, the method you actually use, the tradeoffs you accept, the alternatives you compare, and the evidence that supports your claims.

    Adjectives such as seamless, innovative, robust, and leading do little semantic work when every company uses them. A documented constraint can be more differentiating than a superlative. A clear statement about who should not choose an approach can be more useful than a page of unqualified benefits.

    Run a centroid audit, then repair the shape you find

    A disorganized cloud of colored points is measured and reorganized into a compact cluster around a glowing center.

    You do not need access to an AI platform’s internal index to perform a useful audit. You need a stable representation of your own corpus, a defined set of target queries, and the discipline to treat the results as a diagnostic proxy rather than a replica of any one engine.

    Build the audit in seven steps

    1. Write the intended position as one testable sentence. Use four slots: the entity, the audience, the problem, and the distinctive method or qualification. If the sentence contains only an aspiration such as trusted leader, it is not precise enough to audit.
    2. Create a chunk-level inventory. Record the URL, page title, section heading, chunk text, named entity, target query, main claim, supporting evidence, content type, and publication status. Do not assume every section on a relevant URL serves the same semantic purpose.
    3. Define the axes you care about. Typical axes include audience, problem, category, method, use case, proof, and exclusions. Add adjacent topics that could pull the brand away from its intended position. These axes become the labels against which you inspect clusters and outliers.
    4. Choose a measurement path. For a manual audit, score each chunk on each intended association using -1 for conflicting language, 0 for no signal, 1 for an implied association, and 2 for an explicit, supported association. These are internal review scores, not AI retrieval thresholds. For an embedding-assisted audit, use one embedding model and one chunking rule throughout the comparison. Changing either midway makes before-and-after movement difficult to interpret.
    5. Map query families, not isolated prompts. Group queries by the decisions they represent: discovery, definition, problem diagnosis, implementation, comparison, suitability, proof, and exclusion. Calculate or review the nearest relevant chunks for each family. A strong match for an informational definition does not prove you are close to a buying or evaluation query.
    6. Measure both center and shape. Record the portfolio centroid, dispersion, important subclusters, query-to-nearest-chunk distance, and obvious overlap with competitor language. A two-dimensional plot can help you inspect patterns, but the picture is only a projection. Confirm apparent findings by reading the underlying chunks.
    7. Save a baseline and repeat the same procedure after a substantial publishing batch, a repositioning effort, a product launch, or a major consolidation. Keep the original query set as a stable cohort. Add newly important queries as a separate cohort so changes in the test itself do not masquerade as performance changes.

    If you have several products or audiences, calculate more than one centroid. A brand-wide mean can answer a governance question, while a product centroid or query-conditioned centroid answers a retrieval question. For a query-conditioned view, examine the nearest relevant chunks rather than averaging every page the company has ever published.

    Match the repair to the diagnosed problem

    • If a valuable query has no nearby chunk, create or rewrite a passage that answers it directly. Place that answer on the page whose purpose and entity already match the query.
    • If the centroid looks correct but dispersion is high, inspect the farthest chunks. Update unclear legacy language, reconnect legitimate adjacent content to the core proposition, and consolidate duplicative material where doing so improves clarity.
    • If two legitimate subclusters are being averaged into a confusing middle, separate their hubs and identify the correct product, audience, and use case in each. Preserve a parent-brand page that explains the relationship between them.
    • If your cloud collides with competitors, stop commissioning interchangeable category summaries. Prioritize decision criteria, limitations, comparisons, methods, and verifiable proof that competitors cannot truthfully reproduce word for word.
    • If a strong topical cluster has a weak brand association, name the responsible entity inside the relevant passages. Use consistent entity names in visible copy and valid structured data. Do not mark up claims or relationships that the page does not actually support.
    • If a publishing campaign caused drift, correct the editorial brief before adding more pages. Define the association each proposed piece should strengthen and the core entity to which it must connect.

    Do not respond to an ugly cluster map with a mass deletion. Removing pages can also discard rankings, links, useful history, and coverage for legitimate journeys. Read the outliers first. An update, a clearer entity boundary, a consolidation, or a better internal path may solve the semantic problem while preserving existing value.

    Monitor outcomes without confusing them with internal retrieval data

    Pair the corpus audit with a stable prompt set. For each prompt, record whether the brand appears, which product or capability is attributed to it, whether that representation matches the intended position, which owned page is cited or linked, and whether the answer introduces an unsupported association.

    These observations are outcome proxies. They do not prove which chunks were retrieved internally, and an answer can vary across systems or runs. Their purpose is to show whether your content changes are producing a more accurate and useful external representation.

    Watch for a particularly important failure pattern: inclusion improving while representation accuracy declines. More mentions are not a win if the brand is increasingly associated with the wrong audience, category, or promise. Track visibility and message fit as separate measures.

    Key takeaways

    • Your AI-facing brand is better modeled as a distribution of published meanings than as a single positioning statement.
    • Retrieval comes before ranking, so the first operational question is whether a relevant chunk is close enough to the query to be considered.
    • A centroid shows the average direction, but dispersion and subclusters reveal whether that average is coherent or misleading.
    • Content volume can move the centroid. Review the semantic direction of an entire campaign, not only the quality of each page in isolation.
    • Distinctive brand perception comes from distinctive, supportable information: audience fit, methods, boundaries, tradeoffs, comparisons, and evidence.
    • Your measurements are diagnostic proxies. Use a consistent method to compare changes, not to claim access to an AI engine’s private retrieval logic.

    Start with one commercially important query family and the pages meant to support it. Write the position you want the system to recover, inventory the relevant sections, find the closest missing or ambiguous answer, and repair the smallest set of chunks that will make the intended meaning explicit. Then rerun the same audit after the next content batch. That is how brand perception becomes a managed system rather than a slogan you hope AI notices.

    References

  • How to Build Website Authority for AI Search Visibility

    How to Build Website Authority for AI Search Visibility

    If an AI answer gets your business wrong, leaves you out, or cites a competitor, publishing another broad article is rarely the cleanest fix. You need to make the right facts easy to crawl, easy to retrieve, difficult to misinterpret, and consistent everywhere they appear.

    That turns website authority from a vague reputation goal into a practical system. You can inspect each part, find the break, and fix the page or fact that is actually limiting your visibility.

    Treat authority as a chain from crawl to customer

    AI search visibility can fail at several different stages. A page may be accurate but inaccessible to a crawler. It may be crawlable but poorly matched to the question. It may be retrieved but not selected as supporting evidence. Your brand may even appear in an answer without earning the customer’s trust afterward.

    Separate the chain into these diagnostic layers:

    • Crawl access: Can relevant crawlers request the public URL and receive the page successfully?
    • Interpretation: Does the page identify the business, service, location, product, or person without ambiguity?
    • Retrieval: Does one section closely answer the user’s actual question?
    • Selection: Is the answer precise and well-supported enough to be used or cited?
    • Validation: Do your other pages and external profiles confirm the same facts?
    • Conversion: Can a person who follows the recommendation verify the offer and take the next step?

    This distinction matters because a citation is not the same as a recommendation, and a recommendation is not the same as a sale. A citation means your URL supported an answer. A mention means your name appeared. A recommendation places you among the options. Authority has to carry the user through all three and then survive their visit to your site.

    Retrieval is especially important. Across an AirOps analysis of 16,851 unique queries, the first retrieval result was cited 58.4% of the time, while the result in tenth position was cited 14.2% of the time. Pages with headings that strongly matched the query were cited 41% of the time. Those figures do not establish a universal ChatGPT ranking formula, but they show why a generally authoritative domain can still lose a particular answer: the wrong page or passage wins retrieval.

    When you diagnose a visibility problem, do not begin with, “How do we make the whole domain more authoritative?” Begin with a narrower question: “For this customer question, which URL should be retrieved, which passage should be selected, and which facts must another source be able to confirm?”

    Design pages to win retrieval, not merely cover topics

    An organized modular website feeds distinct fact objects into a central retrieval beam while cluttered pages sit outside it.

    A page earns retrieval by making its purpose obvious. The title, primary heading, opening answer, supporting details, and internal links should all point to the same intent. A page called “Our Solutions” forces a system to infer what it contains. A heading such as “Does the service include installation?” identifies both the question and the expected answer.

    Build each important answer in this order:

    1. Choose one real customer question. Pull it from sales emails, support conversations, reviews, search queries, and questions on business profiles.
    2. Decide what kind of answer the user needs: a fact, qualification, process, comparison, availability check, or next action.
    3. Place a query-shaped heading above the answer. Use the customer’s language where it remains accurate.
    4. Answer immediately in plain sentences. Do not make the reader cross an origin story, promotional introduction, or table of contents to reach the useful fact.
    5. Add the conditions that prevent a misleading extraction. State relevant locations, exclusions, eligibility rules, dependencies, or situations in which the answer changes.
    6. Support the answer with concrete business information, then point the reader to the appropriate verification or action page.

    A narrow page is not necessarily a short or shallow page. It is a page with one dominant job. A service page can explain scope, suitability, process, limitations, and next steps without becoming a general guide to the entire industry.

    Conversely, long content is not automatically authoritative. In the same query analysis, pages between 500 and 2,000 words performed best for citations, while pages over 5,000 words were cited less often than even the shortest pages. Content with 4 to 10 subheadings also performed notably well. Treat those as observations from that dataset, not mandatory publishing limits. The useful principle is precision: stop when the question has been answered, qualified, and supported.

    A practical site architecture usually needs both hubs and focused pages. Use a broad hub to organize a subject and help users navigate it. Use a focused page when a distinct question requires its own evidence, conditions, or conversion path. Do not create separate URLs for trivial wording changes; consolidate near-duplicate questions under the clearest heading so your own pages do not compete to be the answer.

    Before publishing, apply a simple extraction test. Read only the heading and the paragraph beneath it. If that fragment would be accurate when shown without the rest of the page, the answer is well-formed. If it would overpromise, omit a location, or confuse one service with another, add the missing qualifier beside the answer rather than burying it later.

    Make your website the canonical truth layer

    Your site cannot function as an authority if its own facts drift. A homepage may use one business name, a location page another, and a profile an old address or schedule. An AI system then has to resolve the conflict, and the version it chooses may not be yours.

    This is particularly important in local search, where services, locations, hours, reviews, and business profiles help establish whether a recommendation fits the query. AI recommendations can be checked against multiple online profiles, while customers commonly validate the choice by visiting the website and reading reviews. Your site therefore has two jobs: provide precise information for the recommendation and provide enough proof for the person evaluating it.

    Create a fact inventory with one row for every claim that can change or cause a customer to choose incorrectly. Useful fields include:

    • The fact itself, written in its approved form.
    • The canonical page where that fact is explained.
    • Every important internal page and external profile that repeats it.
    • The person responsible for verifying it.
    • The event that should trigger an update.
    • The date on which someone last confirmed it.

    Start with identity and decision facts: business name, locations, service areas, hours, contact details, offerings, eligibility, availability, policies, and important limitations. For a local business, compare those facts with its Google Business Profile and major directories. For a product or service company, compare landing pages with pricing, support, policy, and documentation pages. Resolve contradictions at the canonical page first, then update every surface that repeats the fact.

    Authority also depends on evidence placement. Put identity information on the homepage and about page. Put service scope and limitations on the service page. Put location-specific availability on the relevant location page. Put policy details on the policy page. Repeating a short fact for context is reasonable, but one page should remain the full, maintained explanation.

    Use JSON-LD to identify facts, not manufacture authority

    Structured data helps a machine identify entities and relationships, but it cannot make vague copy precise or reconcile conflicting claims. In the citation dataset, pages with JSON-LD had a 38.5% citation rate, compared with 32.0% for pages without it. That is a useful but modest association, not evidence that schema alone causes citations.

    Use JSON-LD as a faithful machine-readable version of the visible page:

    • Select the most specific schema type that truthfully describes the entity or content.
    • Mark up only facts that users can verify on the page or through an appropriate canonical page.
    • Use stable URLs and identifiers for the same entity across connected markup.
    • Keep names, addresses, service descriptions, dates, and other properties aligned with visible content.
    • Validate syntax after changes and include structured-data checks in the same workflow that updates the page.

    If you have to choose between adding more properties and correcting a contradiction, correct the contradiction. Clear content establishes the claim; structured data labels it.

    Run an audit that separates visibility from accuracy

    A digital workbench uses separate illuminated lanes to inspect website fact modules for discoverability and consistency.

    An occasional vanity prompt will not tell you whether authority is improving. Generative answers can vary, and one broad question mixes discovery, retrieval, recommendation, and citation into a single result. Use a fixed audit that preserves the wording, platform, run date, and evidence.

    1. Build a prompt set around real decisions. Include questions about fit, availability, location, process, limitations, alternatives, and the next step. Use neutral language rather than inserting your brand into every prompt.
    2. Run the same prompts on the AI systems your customers are likely to use. Repeat important prompts so a single variable response does not become your conclusion.
    3. Record whether your brand appears, how it is described, whether the description is correct, whether your site is cited, which URL is used, and which competing or third-party sources support the answer.
    4. Inspect the cited or likely landing page. Check whether its title and headings match the question, whether the answer appears near the relevant heading, and whether all necessary qualifiers sit beside it.
    5. Check crawler access. Confirm that important URLs can be requested, do not return error responses, and are not unintentionally restricted by access rules.
    6. Fix the earliest broken link in the chain. There is little value in rewriting an answer passage if the page cannot be crawled, or adding schema while external profiles still carry the wrong location.

    Server-log analysis can expose crawler activity that ordinary traffic reports do not make obvious. Logs can show the requested URL, time, declared user agent, and response status. They cannot prove that a model stored, trusted, retrieved, cited, or used the content. Treat them as crawl evidence, then use prompt audits and citation tracking to evaluate the later stages.

    Prioritize corrections by consequence. Fix inaccurate high-intent facts first, followed by access failures, conflicting profiles, missing direct answers, and stale supporting content. This order protects the customer decision while also improving the material available for retrieval.

    Freshness deserves a targeted approach. Pages published 30 to 89 days before collection had the strongest citation performance in the AirOps dataset, while content less than 30 days old performed slightly worse and content older than two years struggled. That pattern may reflect the time needed to accumulate retrieval signals, and it does not justify rewriting every page on a fixed schedule. Use it as a reason to review older pages that already serve valuable queries, especially when their facts, examples, policies, or answer structure have drifted.

    Measure the outcome at each stage

    Your reporting should make failures distinguishable. Track prompt coverage, accurate-answer rate, brand mention rate, citation rate, owned-site citation share, cited URLs, crawler access, corrected fact conflicts, and the customer actions that follow AI-assisted discovery. Keep the prompt set stable long enough to detect a direction, and log material page changes so you can connect movement to an intervention.

    Do not use organic clicks as the sole verdict. An Ahrefs analysis found that 99% of keywords triggering an AI Overview were informational, while navigational keywords accounted for 0.13%. In that dataset, AI Overviews were concentrated overwhelmingly in informational searches. A decline in clicks from quick-answer queries can therefore coexist with useful visibility, but only if your brand is represented accurately and decision-stage users can still reach a convincing destination.

    Report exposure and business impact separately. Exposure tells you whether the brand and site enter the answer. Accuracy tells you whether the answer helps or harms. Decision actions tell you whether the website completes the job. Combining them into one visibility score hides the part you need to fix.

    Frequently asked questions

    What does website authority mean in AI search?

    Website authority in AI search is the site’s ability to provide crawlable, unambiguous, retrievable, consistent, and verifiable information for a particular question. It is not just a domain-level reputation score. A strong domain can lose a citation when its relevant page is vague, stale, inaccessible, or poorly matched to the query.

    Should every customer question have its own URL?

    No. Give a question its own page when it has distinct evidence, conditions, search intent, or a separate next action. Put closely related questions on one focused page under descriptive headings. Creating near-duplicate URLs for every phrasing makes maintenance harder and leaves several pages competing to represent the same answer.

    Can an uncited AI mention still be valuable?

    Yes, but count it separately from a citation. First check whether the mention is accurate, relevant to the question, and likely to lead a user toward verification. Then inspect whether your website supports the description and offers a clear next step. An inaccurate mention is not positive visibility merely because the brand appeared.

    What should you fix first?

    Fix the error with the greatest decision consequence. An incorrect location, service condition, eligibility rule, or availability claim comes before a missing optional schema property. After factual accuracy, address crawl failures and retrieval structure, then improve supporting depth and presentation.

    Start with the questions closest to a real customer choice. Assign each one a canonical page, verify every changeable fact, correct conflicts across your profiles, and make the answer extractable beneath a precise heading. Then rerun the same prompt set and inspect the logs. That cycle gives you something more useful than a vague authority campaign: a clear record of what AI systems can access, what they say, and what you need to improve next.

    References


  • AI Visibility Beyond Topical Authority: A 9-Cell Audit

    AI Visibility Beyond Topical Authority: A 9-Cell Audit

    Your site can cover a subject from every angle and still be absent from an AI answer. When that happens, publishing another adjacent page is often the wrong move.

    The practical gap is between being relevant enough to consider and being clear, credible, and distinctive enough to select. You can diagnose that gap by auditing three layers: coverage, architecture, and position.

    Topical authority can qualify you without differentiating you

    Topical authority describes what you have built around a subject: the questions you answer, the relationships among those answers, and the depth with which you handle them. That foundation matters. A shallow or fragmented site will struggle to establish relevance in either conventional search or AI-mediated discovery.

    But relevance is only the first gate. Several sites can cover the same topic competently. The harder question is why an AI system should use your entity, page, or explanation instead of another eligible candidate.

    This creates a useful distinction:

    • Eligibility: Does your content belong in the candidate set for this question?
    • Selection: Once several candidates qualify, does your content give the system a reason to prefer it for this particular answer?

    The desired state is sometimes called topical ownership. It does not mean owning a subject exclusively or appearing in every generated response. It means becoming a repeatedly plausible choice because coverage, architecture, and position reinforce one another.

    You can usually locate a visibility problem by asking three diagnostic questions:

    • If no page fully resolves the user’s question, you have a coverage problem.
    • If the answer exists but is buried, fragmented, or connected ambiguously to other pages, you have an architecture problem.
    • If the answer is complete and clear but could have come from almost any competent site, you have a position problem.

    Key takeaways

    • Topical authority helps you qualify; it does not automatically make you the preferred choice.
    • AI visibility depends on what you cover, how clearly you encode it, and which entity is associated with it.
    • More pages will not repair weak differentiation, ambiguous ownership, or poor information architecture.
    • Audit selection at the query-family level before expanding the entire site.

    Use the 9-cell model to find the actual weakness

    An isometric square platform contains nine visual audit chambers, including illuminated strengths and a few disconnected or dim weaknesses.

    A three-by-three model turns an abstract visibility problem into an operating audit. Each row represents a layer. Each cell asks a different question that your content must answer.

    LayerCell 1Cell 2Cell 3
    CoverageDepth: Does the content resolve the core question, not merely introduce it?Breadth: Does it address the related decisions and necessary follow-up questions?Distinct insight: Does it contribute a defensible idea, judgment, or method?
    ArchitectureClarity: Can the central answer be understood without reconstructing it from scattered passages?Relationships: Do headings and internal links make the topic hierarchy explicit?Source context: Is it clear who is speaking, in what capacity, and within what time context?
    PositionEntity identity: Is the responsible person, organization, or product named consistently?Authority: Is there a credible reason to trust this entity on this particular subject?Selection relevance: Is there a concrete reason to choose this contribution over an equally complete alternative?

    Mark every cell red, amber, or green for each priority query family. Red means the requirement is absent or contradictory. Amber means it is present but implicit, thin, or inconsistent. Green means it is explicit, supported, and consistent across the relevant page, surrounding content, and entity information.

    Do not average the colors into a reassuring score. A site can be green on breadth and still fail because its authorship is unclear. It can have a strong brand position and still fail because no page directly answers the question. The weakest required cell can limit the whole result.

    Run the audit against a specific user decision, not a broad keyword. A query such as how to audit AI citations has a clearer success condition than the topic AI SEO. The narrower framing exposes whether you have a page that resolves the task, whether its answer can be extracted cleanly, and whether your entity has a defensible connection to it.

    Build coverage and architecture for selection

    Coverage should resolve a decision, not fill a topical map

    Coverage is not a page-count target. Depth, breadth, and distinct insight perform different jobs.

    • Depth resolves the main question, explains the mechanism behind the answer, and deals with the conditions that could change it.
    • Breadth covers the neighboring questions a reader must settle before acting, without forcing one page to absorb an entire subject.
    • Distinct insight gives the content a reason to exist when other sites already explain the basics.

    A long page can still be shallow. Length often accumulates definitions, restatements, and generic examples without resolving the reader’s decision. Test depth by removing the introduction and asking whether the remaining material tells the reader what to do, why that action fits, and when it would not fit.

    Breadth also gets misread as publishing every conceivable subtopic. Useful breadth follows the decision path. If a supporting question changes the main recommendation, prevents a common error, or determines the next action, it belongs in the cluster. If it only shares vocabulary, it may not deserve a page.

    Distinct insight is the selection delta. It can be an operational definition, a framework, a reasoned position, a transparent analysis, or a clearer way to separate two concepts people routinely conflate. It must be defensible. Invented statistics, decorative terminology, and unsupported contrarian claims create novelty without authority.

    Use this sequence when improving coverage:

    1. Write the exact question or decision the page owns.
    2. State the shortest accurate answer before expanding it.
    3. List the conditions, trade-offs, and follow-up questions that could change the action.
    4. Separate what is broadly established from your interpretation or recommended method.
    5. Add a contribution your entity can explain and defend consistently elsewhere.
    6. Remove or consolidate pages that compete for the same purpose without adding a distinct role.

    The final step matters because duplication can disguise itself as authority. Ten overlapping pages may create more text while making it less obvious which page represents your best answer.

    Architecture should remove interpretation work

    Architecture is the translation layer between what you know and what another system can understand about it. It operates inside sentences, across the page, and throughout the site.

    • Lead with the resolution. Put the direct answer near the question it resolves. Add qualifications immediately after it rather than several sections later.
    • Give each section one job. A descriptive heading should tell the reader what decision, mechanism, or distinction the section handles.
    • Keep claims and conditions together. If a recommendation only applies in a particular situation, do not separate the qualifier from the recommendation.
    • Use internal links as relationship labels. Explain whether the destination is a prerequisite, a deeper method, an example, or the next step. Generic anchor text hides that relationship.
    • Make ownership visible. Connect the page to consistent author, organization, product, and editorial context where those entities are relevant.
    • Represent only visible facts in structured data. JSON-LD can clarify entities and relationships, but it should mirror the page rather than make unsupported claims the reader cannot verify.

    Sentence clarity is not the same as oversimplification. A technical claim can remain precise while placing the subject, action, and condition in an explicit order. If a sentence depends on three undefined pronouns, an unexplained category, and context from two paragraphs earlier, the reader and the machine both have extra reconstruction work.

    Review architecture by trying to extract three things from the page: its central answer, the entity responsible for that answer, and the conditions under which it applies. If you cannot identify all three without interpretation, reorganize the page before adding more content.

    Position is built across entities and time

    A luminous central object gains stronger connections to institutions, documents, experts, and reference nodes across repeated layers of time.

    Position answers the question coverage cannot: why you? It is the association between an identifiable entity and a defensible area of competence.

    You cannot create that association with one declaration of authority. It develops when the same entity repeatedly makes useful, coherent contributions within a recognizable territory. Your content, author information, organization pages, terminology, and external recognition should point in the same direction.

    Write a positioning statement for each strategically important topic area by answering these questions:

    • Which entity is speaking: a person, organization, publication, product, or another clearly defined entity?
    • Which specific problem or decision does that entity have standing to address?
    • Who is the intended audience, and what context does that audience bring?
    • What expertise, method, evidence, or body of work supports the claim?
    • What contribution should remain recognizably associated with the entity?

    If the answers change from page to page, your position is not yet coherent. Fix naming, roles, scope, and topic ownership before pursuing a broader footprint.

    Recognition must connect the entity to the topic

    Recognition is more useful when it reinforces a specific association. A generic mention of a company name says less about topical position than a relevant citation, reference, or discussion that connects the entity to the contribution it actually makes.

    This changes how you approach digital PR, partnerships, expert contributions, and brand mentions. The objective is not simply to accumulate appearances. It is to make the entity-topic relationship legible. Use the same canonical name, describe the relevant expertise accurately, and direct attention to the page that best represents the contribution.

    Do not manufacture evidence of recognition. Weak guest posts, inflated biographies, unsupported superlatives, and interchangeable expert commentary can increase the number of claims about an entity without making any of them more credible.

    Time tests whether the position is real

    Position has a temporal dimension. A clear idea published once may be useful, but a coherent body of work maintained over time is easier to associate with an entity than a sequence of disconnected claims.

    Build time into the content system:

    • Define what would trigger a meaningful review, such as a changed platform behavior, new evidence, or a shift in the decision criteria.
    • Record substantive revisions so the current position is distinguishable from an abandoned one.
    • Consolidate obsolete or contradictory pages instead of leaving several competing answers live.
    • Keep stable definitions and entity names consistent unless there is a genuine reason to change them.
    • Explain an evolved position rather than silently replacing it and creating unexplained contradictions.

    Changing a date without improving the content does not strengthen temporal authority. The useful signal is continued stewardship: the page remains accurate, its ownership remains clear, and changes have an intelligible reason.

    Run a selection audit before producing more content

    A selection audit should end with an editorial queue, not a strategy presentation. Start with a query family that matters to the business and complete the following workflow.

    1. Define the decision. Record the exact question, intended user, and action the answer should enable.
    2. Observe the current answer space. Note which entities and pages are used or cited, which parts of the question they resolve, and which distinctions recur. Treat this as a snapshot, not a permanent ranking.
    3. Assign one primary page. Select the URL that should provide your best answer. If several pages compete for that role, resolve the overlap first.
    4. Audit all nine cells. Mark depth, breadth, distinct insight, clarity, relationships, source context, entity identity, authority, and selection relevance as red, amber, or green.
    5. Repair the limiting layer. Create missing coverage only when no page resolves the task. Rework architecture when the answer exists but is hard to isolate. Strengthen position when the page is complete and clear but interchangeable.
    6. Write the selection delta. State in one sentence what your page contributes that another competent explanation does not. If you cannot write that sentence honestly, the page needs a stronger contribution.
    7. Retest the query family. Use the core question and natural follow-ups. Record whether the correct page appears, whether your distinct framing survives paraphrase, and whether the entity is represented accurately.

    Keep a one-page selection memo

    For each priority query family, maintain a short working record containing:

    • the user’s exact decision;
    • the primary page and its one-sentence answer;
    • the necessary supporting questions;
    • the page’s distinct contribution;
    • the responsible entity and relevant authority context;
    • the internal pages that establish prerequisites or deepen the method;
    • the event that should trigger the next review; and
    • dated observations from repeated AI-answer checks.

    This memo makes gaps harder to hide behind aggregate traffic or publishing volume. It also gives writers, technical SEO teams, schema implementers, and digital PR teams the same definition of the page’s job.

    Avoid fixes that change the surface but not selection

    Several familiar tactics can consume effort without repairing the weak cell:

    • Publishing more adjacent pages when the existing cluster already overlaps.
    • Making an article longer without resolving additional decisions.
    • Adding schema to content whose entities or claims remain ambiguous on the visible page.
    • Changing publication dates without a substantive revision.
    • Pursuing generic mentions that do not connect your entity to the relevant topic.
    • Renaming familiar ideas without adding a defensible insight.

    Do not judge the result from one generated answer. Prompt wording, context, and system behavior can change the output. Look for a pattern across the core question and its close variants: the correct page becomes a plausible choice, the distinctive contribution is represented accurately, and the responsible entity is not confused with another one.

    Start with one query family where selection would matter. Complete the nine-cell audit, fix the weakest required cell, and document what changes. That gives you a grounded path to AI visibility before you scale another topical map.

    References