Tag: AI optimization

  • How to Optimize for Bing, ChatGPT, and Gemini Answers

    How to Optimize for Bing, ChatGPT, and Gemini Answers

    Your page can answer a question clearly and still appear in one AI answer engine while disappearing from another. That does not necessarily mean the content is bad. It may mean the answer is packaged for the wrong selection environment.

    The practical solution is not to write a separate version for every platform. Build one reliable answer asset, then add platform-specific cues for Bing, ChatGPT, and Gemini. You preserve a consistent set of facts while adapting the structure, language, context, and media each engine can use.

    One answer strategy, three selection environments

    AI answer engines overlap, but they are not interchangeable. All of them benefit from clear, accurate, well-organized content. The difference lies in how a person asks, how the engine interprets the request, and which parts of a page are easiest to turn into an answer.

    EngineSelection environmentContent cues to prioritize
    BingSearch-oriented answers connected to the wider Microsoft ecosystemStructured data, concise answers, authority, local information, and well-described images
    ChatGPTConversational answers that can change as the user adds context or asks follow-up questionsNatural phrasing, self-contained explanations, contextual branches, accuracy, and human review
    GeminiContext-rich answers that can draw on detailed questions and multiple media typesLong-tail intent coverage, connected text and visuals, useful captions, structured data, and trust signals

    This distinction changes the job. You are not trying to make three engines repeat the same paragraph. You are making the same body of knowledge understandable in three different situations: a search result, a conversation, and a multimodal response.

    Key takeaways

    • Keep the facts, evidence, and recommended action consistent across platforms.
    • Treat schema as a machine-readable description of visible content, not as a guarantee of inclusion.
    • Give Bing strong structural, local, authority, and image signals.
    • Give ChatGPT complete answers that remain useful when a user asks a follow-up question.
    • Give Gemini an explicit relationship between detailed text, relevant visuals, captions, and alt text.
    • Measure interpretation, factual accuracy, and usefulness separately from simple brand visibility.

    Build the answer asset before tuning the platform layer
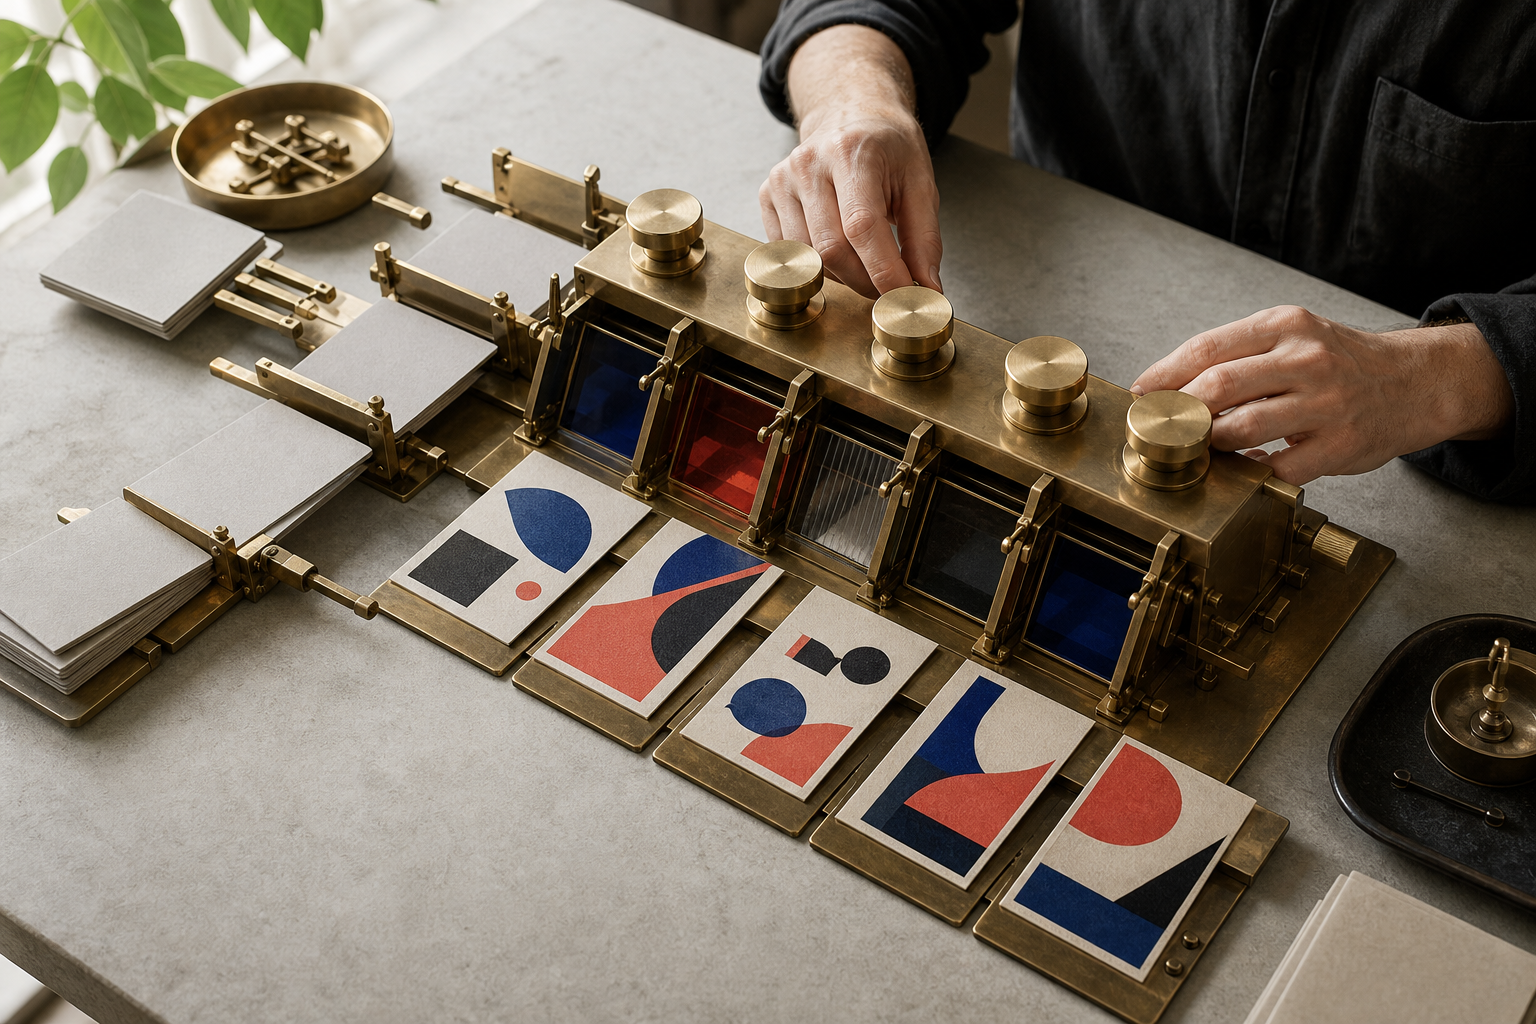
    Hands fit interchangeable presentation frames around a transparent cube containing the same factual content blocks.

    A platform tactic cannot rescue an answer that is vague, unsupported, or aimed at the wrong intent. Start with a reusable answer asset: a page or section containing the question, the direct response, the conditions that affect it, the evidence behind it, and the next action.

    1. Write the question in the language your audience uses. Replace a broad topic label such as “website performance” with the actual decision the reader is making, such as “What should I fix first when my website feels slow?” Conversational and long-tail wording gives an answer engine a clearer intent to match.
    2. Put the direct answer near the question. Give the reader the conclusion before background, history, or product positioning. The opening answer should still make sense if it is separated from the rest of the page.
    3. State the scope and conditions. If the correct answer changes by location, product type, audience, or use case, name those branches. A bare “it depends” gives an engine nothing useful to compose.
    4. Add the explanation that makes the answer defensible. Show the mechanism, evidence, limitations, and practical consequences. Concision helps extraction, but unsupported brevity weakens trust.
    5. Make ownership visible. Use an appropriate author or reviewer, maintain current information, and link to credible supporting material. Bing and Gemini both place weight on authority and trust, while ChatGPT-oriented content still needs human oversight to prevent generic or inaccurate answers.
    6. Apply schema that describes what is actually present. FAQ markup belongs with visible questions and answers, HowTo markup with a genuine procedure, and Product markup with real product information. The markup should reinforce the page rather than describe content the reader cannot see.
    7. Connect every useful visual to the answer. A diagram, screenshot, or product image needs descriptive alt text, an informative caption where appropriate, and nearby prose explaining why it matters.

    The result should be valuable even if no AI engine ever selects it. That is an important quality test. AEO works best when machine-readable structure improves a genuinely useful human answer rather than disguising thin content.

    Tune the delivery layer for each answer engine

    Once the shared answer is sound, tune the delivery layer. These changes can usually live on the same page. Separate platform pages are justified only when the underlying audience, offer, location, or intent is genuinely different.

    Bing: remove ambiguity from structure, location, and media

    Bing is the most search-like environment of the three. It rewards pages whose subject and answer are easy to identify, and it can extend that information across Microsoft-connected experiences. Your Bing layer should make the page explicit rather than merely topical.

    • Match headings to recognizable questions. Follow each important question with a short answer before expanding it. Do not make the engine infer the conclusion from several loosely related paragraphs.
    • Use the schema type that matches the page. Bing can use FAQ, How-To, and Product schema to interpret context and support answer-oriented presentation. Mark up the most relevant entity and relationships rather than adding every available type.
    • Resolve local inconsistencies. If the answer depends on geography, keep the business name, location, service area, and contact information accurate in Bing Places and on the site. Include location language where it helps the reader distinguish the applicable answer.
    • Treat images as searchable information. Use a descriptive filename where practical, accurate alt text, relevant metadata, sufficient image quality, and explanatory copy around the image. “Dashboard showing a traffic decline after a site migration” communicates more than “SEO image.”
    • Expose authority signals. A clear byline, current information, credible references, and reputable links pointing to the site make the answer easier to trust.

    The common Bing failure is a page that is semantically broad but operationally unclear. If several headings discuss a subject without answering a recognizable question, restructure the page before adding more markup.

    ChatGPT: write for the next question, not only the first

    ChatGPT is conversational. A response can be refined by the user’s earlier message, preferences, and follow-up question. That means your content needs both a complete initial answer and enough conditional detail to survive a change in context.

    • Use natural question-and-answer language. Write the way an informed customer would ask, while preserving the terminology needed for accuracy. Keyword fragments are poor substitutes for complete questions.
    • Make each answer block self-contained. Include the subject in the answer instead of relying on a distant heading or an unexplained “it.” A passage should remain understandable when quoted without its surrounding introduction.
    • Map likely follow-ups. After the primary answer, cover who the advice applies to, when it changes, what the main limitation is, and what the reader should do next. This gives a conversational engine usable branches rather than repeated versions of the same claim.
    • Separate facts from recommendations. Facts need support. Recommendations need their criteria and tradeoffs. This distinction helps prevent a qualified suggestion from being flattened into a universal rule.
    • Review AI-assisted copy as editorial work. ChatGPT can help phrase conversational questions and draft answer formats, but unchecked AI-generated content can become generic, repetitive, or factually unreliable. Verify claims, remove repetition, and retain accountable human oversight.
    • Design interactive answers with trust in mind. If you operate a chatbot or dynamic FAQ, decide how users will recognize AI involvement, reach the underlying information, and report a wrong answer. Personalization is useful only when the factual core remains stable.

    The common ChatGPT failure is an answer that works for an isolated prompt but collapses under qualification. If your recommendation changes when the user adds “for a local business,” “for an enterprise site,” or another material condition, put that distinction on the page.

    Gemini: make text and visuals answer the same question

    Gemini’s multimodal capabilities make media more than decoration. A useful visual, its surrounding explanation, its caption, and its alt text should all reinforce the same entity and answer.

    • Target detailed intent explicitly. Build sections around specific, long-tail questions instead of expecting one broad page to satisfy every variation. State the narrow answer first, then connect it to the larger topic.
    • Give visuals an explanatory job. Use a diagram to show a process, a screenshot to identify a setting, or a product image to clarify a feature. A generic stock image adds little evidence and creates no meaningful relationship for the engine to interpret.
    • Describe the relationship in text. Tell the reader what to notice in the visual and why it changes the answer. Add relevant captions and alt text rather than leaving the relationship implicit.
    • Use FAQPage markup selectively. Gemini-oriented AEO can benefit from clear FAQ structures, relevant schema, long-tail coverage, and coordinated text and visual information. Repetitive questions added only to expand a schema graph do not improve the underlying answer.
    • Support the answer with trust signals. Research the claim thoroughly, identify responsible authorship, maintain the information, and earn credible references and links. Multimodal presentation does not reduce the need for authority.

    The common Gemini failure is a page with strong prose and disconnected media. If the image could be removed without changing the explanation, it is probably decorative. Either give it an informational role or do not treat it as part of the optimization strategy.

    Diagnose the failure before changing the page
    A specialist inspects a modular web page that passes through two digital gateways but is blocked at a third.

    Seeing your brand in one answer and not another is an observation, not a diagnosis. The missing result could reflect intent mismatch, weak structure, insufficient authority, local inconsistency, poor media context, or normal variation in a conversational session. Changing several layers at once makes it harder to learn which problem mattered.

    1. Create a prompt set from real audience decisions. Include a direct factual question, a detailed long-tail question, a conditional question, and any relevant local or visual request. Add a natural follow-up to test whether the answer holds when context changes.
    2. Keep the comparison controlled. Use the same base wording across engines. Where the interface permits, distinguish a clean session from a contextual follow-up. Conversational context can change the answer, so these are different tests rather than duplicate runs.
    3. Save the actual output. Record the prompt, platform, session conditions, answer, surfaced brand or page, and any incorrect or missing claim. A screenshot alone is not enough if it omits the prompt or preceding context.
    4. Evaluate separate outcomes. Ask whether the engine understood the intent, used accurate facts, applied the right conditions, surfaced your entity, and gave the user a workable next step. A mention with the wrong claim is not a successful result.
    5. Change the closest relevant layer. Fix the answer itself when interpretation is wrong. Fix structure or schema when the answer is hard to extract. Fix local data when geography is missing. Fix captions, alt text, and surrounding prose when media is disconnected. Improve evidence and ownership when the answer lacks authority.
    6. Retest the same prompt pattern. Preserve the previous result so you can compare the output after the change. Do not call a broad rewrite successful merely because a different prompt happened to produce a mention.

    Use failure patterns as diagnostic clues, not proof of an algorithmic rule. If the engine selects the right page but misstates a condition, strengthen that condition in the answer. If it understands the topic but surfaces a competitor, inspect authority, distinctiveness, and evidence. If text is represented accurately but the visual element is ignored, make the connection between the media and the claim explicit.

    Accuracy deserves its own status. A favorable but incorrect answer creates reputation risk because the user may act on a promise you did not make. Mark that result as a failure, correct any ambiguity in your content, and keep a record of the wording that triggered it.

    Turn platform tuning into a repeatable editorial workflow

    Platform-specific AEO becomes manageable when it is part of the content brief rather than a cleanup task after publication. Give each important page a shared fact layer and a short delivery checklist.

    • Shared fact layer: the audience question, direct answer, scope, exceptions, evidence, responsible author, and required update trigger.
    • Bing layer: question-led headings, matching schema, accurate Bing Places information where relevant, and descriptive image fields.
    • ChatGPT layer: natural phrasing, self-contained answer blocks, conditional branches, follow-up coverage, and human verification.
    • Gemini layer: specific long-tail sections, useful visuals, nearby explanations, captions, alt text, and matching structured data.
    • Testing layer: saved prompts, session conditions, observed answers, accuracy findings, surfaced entities, and the next isolated change.

    Keep these layers on the same canonical content asset when the underlying intent is the same. Cloning pages by platform creates duplicated maintenance and increases the chance that facts drift. Add a separate page only when you have a separate question to answer.

    Start with a page that already matters to your audience. Write its direct answer, expose its conditions, align its schema with the visible content, and connect its media to the explanation. Then run the same audience question through Bing, ChatGPT, and Gemini. Let the first clear failure determine the next edit.
    References

  • How to Build AI Search Visibility With a Practical GEO System

    How to Build AI Search Visibility With a Practical GEO System

    You can rank for important Google queries and still disappear when a buyer asks ChatGPT, Claude, Gemini, or Perplexity to explain the market. The generated answer may frame the decision before that buyer has any reason to visit your website.

    The fix is not to publish more content and hope an AI notices. You need a repeatable GEO system that shows where your brand is absent, how it is portrayed, which competitors occupy the answer, and which URLs support the response. Then you can make a targeted change and measure the same question again.

    Build your prompt map around buyer decisions

    An overhead branching pathway links blank content cards with symbolic objects for comparison, research, solutions, risk, and purchase decisions.

    A conventional keyword tells you what someone searched. A useful GEO prompt also captures the decision they are trying to make, the constraints they care about, and the kind of answer they expect. That context determines whether your brand is even eligible to appear.

    Monitoring only questions that contain your brand name creates a reassuring but misleading baseline. Someone who asks whether your product supports a feature already knows you. The more important visibility gap often appears earlier, when that person asks which category, method, or provider can solve the problem.

    Build the prompt map from the real stages of a decision:

    • Category education: What is this type of solution, and when is it appropriate?
    • Problem diagnosis: What causes the issue, and which approaches address it?
    • Solution discovery: Which products, services, or methods fit a stated use case?
    • Evaluation: How should someone compare the available options?
    • Objections: What are the costs, risks, limitations, implementation demands, or prerequisites?
    • Brand validation: Is a named provider suitable for a particular audience or requirement?
    • Visual discovery: What is the item in an uploaded image, and which comparable products meet the user’s constraints?

    Before collecting answers, decide which brands could reasonably appear in each prompt. If a question asks for a general definition and does not call for examples, your absence is not automatically a visibility failure. This eligibility rule keeps the mention metric honest.

    Keep a prompt register rather than a loose list of interesting questions. For every check, record:

    • The exact prompt wording and the intent it represents.
    • The platform and model label displayed in the interface.
    • Relevant settings, location, language, or signed-in state.
    • The date of the response.
    • Whether your brand appeared and what role it played.
    • The exact descriptors and qualifications attached to the brand.
    • Which competitors appeared and how they were positioned.
    • Every cited URL, or an explicit note that the answer supplied no citations.

    Preserve the original wording as your benchmark. Add realistic variants as separate prompts instead of silently editing the baseline. Generated answers can vary, so a single response is a diagnostic observation, not a final verdict. Repeated patterns across the same decision set are more useful than an isolated win or loss.

    Turn four AI visibility signals into editorial decisions

    Four symbolic signal objects connect a modular content asset to a refinement station in a continuous circular feedback loop.

    Brand inclusion, framing, competitive presence, and cited URLs answer different questions. Combining them into a single visibility score may look tidy, but it hides the reason you are winning or losing. Keep the signals separate until you know which intervention each one requires.

    Mentions reveal where you are missing from the journey

    Track presence only across prompts where your brand is a plausible answer. Record the role as well as the mention: recommended option, specialist alternative, example, comparison point, warning, or incidental reference. A brand included only as an afterthought does not have the same visibility as one used to define the category.

    The location of the gap tells you what to build. Sparse mentions in educational questions point toward category definitions, original explanations, and authoritative problem-solving material. Absence from solution-selection questions points toward clearer use-case pages, differentiators, comparison criteria, and evidence of fit. Do not respond to every missing mention with another generic blog entry.

    Framing tells you which narrative needs evidence

    Do not reduce an entire answer to positive, neutral, or negative. Capture the actual adjectives, qualifiers, recommended audiences, and stated limitations. A brand can be praised for capability while simultaneously being framed as difficult to adopt. That mixed description is more actionable than a positive sentiment label.

    Match the response to the narrative. If cost repeatedly dominates the description, publish transparent value evidence, pricing context, or an ROI framework that explains when the expense is justified. If complexity dominates, improve onboarding material, implementation diagrams, migration instructions, and realistic prerequisite information. If trust or reliability recurs, reinforce that claim with verifiable proof rather than repeating the adjective in marketing copy.

    Competitive presence shows which prompts deserve priority

    Compare brands only within the same eligible prompt set. Then note whether a competitor is the default recommendation, a niche choice, a cited authority, or merely part of a long list. Raw mention totals can conceal those differences.

    Create a gap queue from prompts where credible competitors recur and your brand does not. Prioritize by the importance of the buyer decision, not by how irritating the result feels. Inspect what the recurring competitor contributes: a clear category definition, a defensible comparison, an original data asset, a detailed implementation resource, or stronger third-party corroboration. Your task is to answer the unmet information need, not imitate the competitor’s wording.

    Cited URLs show which material carries the answer

    A mention and an attribution are different outcomes. Log the exact URL, domain, page type, and claim each citation appears to support. Also distinguish your own page from an independent page that discusses your brand. You control the former directly and can only influence the latter through accurate information, public evidence, and distribution.

    When a competitor’s report, whitepaper, or explainer repeatedly supports an answer, inspect why that asset is usable. It may state the question clearly, expose its method, define terms precisely, present original evidence, or organize the material in extractable sections. Build the missing evidence on its own merits. A longer page is not automatically a more authoritative one.

    Build an answer asset instead of another generic page

    Every priority prompt should map to a clear primary URL. Several related prompts can belong on the same page, but the reader and the machine should not have to choose among near-duplicate pages to find your definitive answer.

    1. Assign the question to a primary page. Improve an appropriate existing URL before creating a competing version.
    2. Answer the core question near the beginning. State the conclusion, then explain the conditions and reasoning behind it.
    3. Name the entities and relationships explicitly. Identify the product, company, category, audience, use case, and limitation instead of relying on slogans or implied context.
    4. Attach evidence to the claim it supports. Include methodology, examples, comparison criteria, prerequisites, dates where they matter, and honest boundaries.
    5. Use descriptive headings, short explanatory paragraphs, genuine lists, and real tables where the information is tabular. Structure should reflect meaning, not merely break up text.
    6. Add JSON-LD that accurately describes the visible page and its entities. Structured data should confirm the content; it cannot turn an unsupported marketing claim into a fact.
    7. Connect the page to the rest of your site through relevant category, product, documentation, author, and company pages. Consistent names and relationships reduce ambiguity.

    The appropriate format depends on the diagnosed gap:

    • For an educational gap, create a precise explainer, glossary entry, or category definition with examples and boundaries.
    • For a solution-discovery gap, create a use-case page that names the problem, audience, requirements, and situations where the offering is not suitable.
    • For an evaluation gap, publish neutral comparison criteria before arguing that your option performs well against them.
    • For a perception gap, add the missing proof: onboarding instructions, implementation requirements, pricing context, case evidence, or a clear account of limitations.
    • For a citation gap, invest in material worth referencing, such as an original methodology, transparent analysis, detailed technical documentation, or a definitive first-party explanation.

    Avoid FAQ sections assembled only to capture prompt variations. Keep a question when it solves a distinct user problem and supply a complete answer. Near-identical questions with thin replies create more URLs or sections without creating more knowledge.

    Give every important claim one preferred URL

    Generative visibility work becomes fragile when the same claim exists at several addresses with conflicting titles, dates, product names, or specifications. Canonicalization helps search systems consolidate duplicate versions and identify the preferred origin. It does not guarantee an AI citation, but it removes avoidable uncertainty about which page represents you.

    Audit each priority answer asset for the following:

    • The preferred URL resolves correctly and is eligible for indexing.
    • The page carries a self-referencing canonical when it is the preferred version.
    • HTTP and HTTPS, www and non-www, trailing-slash variations, and parameterized duplicates consistently resolve or canonicalize to the intended URL.
    • Internal links and XML sitemaps use the same preferred address rather than feeding mixed signals.
    • Cross-domain copies identify the original where the publishing arrangement allows it.
    • Product variants, filtered category pages, faceted navigation, and pagination follow deliberate rules rather than CMS defaults that nobody has reviewed.
    • Google Search Console and a crawler such as Screaming Frog are used to find declared canonicals, selected canonicals, redirect conflicts, and duplicate clusters.

    Canonical tags are source-control signals, not a substitute for a coherent content model. If several live pages make materially different claims, pointing them all at one canonical does not repair the inconsistency. Decide which version is correct, update the public pages that still matter, and retire obsolete material through an intentional migration.

    Be careful when changing canonicals, redirects, or large groups of product URLs. A broad rule can suppress a valid variation, break an integration, or send authority to the wrong page. Review traffic, backlinks, feed requirements, and platform dependencies first; stage the rule where possible; then crawl the affected templates before deploying it widely.

    Treat visual assets as searchable product information

    Text optimization is only part of GEO for ecommerce and visually selected products. Multimodal systems can interpret objects, embedded words, style, context, and likely use cases. That makes product images and packaging part of the machine-readable information layer, not decoration added after the product page is finished.

    Use a visual-readiness checklist:

    • Show the real product at useful resolution from multiple angles, including scale cues, color, construction details, labels, openings, controls, pockets, stitching, or other decision-critical features.
    • Use original photography when the image is evidence of appearance, packaging, authenticity, or condition. A generated approximation should not stand in for factual product proof.
    • Keep critical packaging text high contrast. Clean sans-serif type on a solid background is easier to read than script type laid over a pattern.
    • Avoid placing required information where glare, glossy material, folds, curves, or creases make optical character recognition unreliable.
    • Run a grayscale check. If hierarchy and legibility disappear without color, the design is too dependent on color contrast.
    • Provide a QR code when the physical package needs a direct route to a canonical HTML page containing complete, structured product information.
    • Make the product name, model, variant, and image relationship explicit on the web page. Do not force a system to infer which nearby caption belongs to which asset.

    The surrounding objects matter too. Props, rooms, clothing, people, adjacent products, and photographic style can imply luxury, utility, sport, age, or intended audience. Those associations may conflict with the position stated in your copy.

    Run a co-occurrence audit on official product and lifestyle images. Ask a multimodal system to identify every visible object, infer likely use cases, and describe the apparent owner or audience. Compare those outputs with your intended positioning. Record unexpected associations, then turn the findings into concrete creative rules for backgrounds, props, wardrobe, image crops, and prohibited adjacencies.

    Extend the audit beyond current campaign files. Old product photography, public archives, distributor listings, user images, and social posts can preserve a discontinued visual identity. You may not control every external image, but you can update the assets you own, make current product imagery easier to identify, and stop distributing obsolete files.

    Close the GEO loop without creating a vanity dashboard

    You do not need a universal AI visibility platform to begin. A disciplined spreadsheet can connect prompts, responses, URLs, interventions, and outcomes. The important part is preserving enough context to explain why a metric moved.

    1. Capture a baseline across the stable prompt register.
    2. Choose a gap with meaningful buyer intent and a recurring pattern.
    3. Diagnose whether it is primarily an inclusion, framing, competitive, citation, technical, or visual problem.
    4. Make the smallest change that directly addresses that diagnosis.
    5. Log the affected URL, the change, the expected signal, and the deployment date.
    6. Recheck the same prompt set under comparable conditions after the changed material is available to search systems.
    7. Keep, revise, or reverse the intervention based on the observed pattern and any downstream business evidence.

    Separate visibility outputs from business outcomes. Mentions, framing, competitive presence, and citations tell you whether the generated answer changed. Qualified visits, inquiries, assisted conversions, and customer-reported discovery tell you whether that visibility mattered. Where analytics cannot prove a causal connection, label the relationship as an observation rather than assigning revenue to an AI mention.

    Do not change several content, schema, canonical, and visual elements at once unless a serious defect requires it. A broad redesign may improve the result, but it will teach you very little about which signal mattered. Controlled changes build a reusable operating model.

    Key takeaways

    • GEO is the work of improving accurate inclusion, framing, competitive position, and attribution in generated answers.
    • Measure visibility at the prompt and buyer-decision level, not through brand-name questions alone.
    • Use mentions, descriptors, competitive presence, and cited URLs as separate diagnostics with different remedies.
    • Map each priority question to a clear, evidence-rich primary page supported by accurate JSON-LD and consistent internal relationships.
    • Remove canonical ambiguity and make images, packaging, labels, and visual context legible to multimodal systems.
    • Recheck stable prompts after each intervention, while keeping AI visibility signals separate from business attribution.

    Start with the highest-value decision prompt where credible competitors recur and you do not. Assign its preferred URL, identify the most visible gap, make a targeted repair, and log what changed. That small closed loop will give you more strategic information than a large dashboard full of unexplained mention counts.

    References

  • Comparing Google & Microsoft: Unraveling Performance Max

    Comparing Google & Microsoft: Unraveling Performance Max

    In the ever-evolving world of AI-driven advertising, I’ve noticed that Performance Max campaigns have become absolutely crucial. Both Google and Microsoft offer these innovative opportunities, allowing advertisers to bring together creative assets, audience signals, and automation into a single seamless campaign type.

    While Google and Microsoft share this foundational concept, they execute it uniquely. I am excited to offer an in-depth comparison of Google PMax and Microsoft PMax as they stood toward the end of 2025, hoping to shed light on the intricacies that could shape your 2026 advertising strategies.

    What I found universally true across both platforms is the replacement of ad groups with asset groups. These groups encompass a blend of creatives, such as images and headlines, along with audience signals, but also carry an absence of any prioritization.

    Significantly, PMax is built for automation. Both platforms request the use of Maximize Conversions or Maximize Conversion Value strategies, underlining the need for conversion tracking that can keep pace with no less than 30 conversions in a month.

    Goal alignment is another crucial aspect. I realized that accurate reflection of business goals in your campaigns is imperative, for an artificially low ROAS target will likely backfire by yielding unexpectedly lower returns.

    Search term visibility is an area where Google offers broader negative keyword support, unlike Microsoft who is still piloting this feature. However, Microsoft’s PMax creatives have been involved in AI placements longer, demonstrating proven results and thus indicating a stronger track record in this area.

    Google’s PMax has evolved impressively, offering tools such as channel-level reporting and video asset support, which are particularly beneficial for visual marketing endeavors.

    On the flip side, Microsoft’s edge, especially for B2B advertising, includes higher campaign limits, impression-based remarketing, and the integration of LinkedIn targeting signals, appealing for advertisers looking at high-quality lead generation.

    Reflecting on both platforms, I believe PMax should be seen as a tool for incrementality rather than a replacement for proven search campaigns. The optimal approach involves leveraging both platforms’ strengths, whether it’s Google’s affinity for creative automation or Microsoft’s prowess in B2B targeting and remarketing.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Empower Your Content with New AI Usage Standards

    Empower Your Content with New AI Usage Standards

    In my experience, the open web often feels like the Wild West, especially in recent times. Many creators, myself included, have watched as our hard work is scraped and fed into large language models without any hint of permission.

    This situation has become a free-for-all, leaving website owners with almost no means to opt out or safeguard their creative endeavors. There have been attempts to address this, such as Jeremy Howard’s llms.txt initiative. Much like robots.txt helps us manage site crawlers, llms.txt aims to provide guidelines for AI companies’ crawling bots.

    Unfortunately, there’s little proof that AI companies actually respect llms.txt or its guidelines. Additionally, Google has clearly stated it doesn’t support llms.txt.

    However, a promising new protocol is on the horizon, potentially granting site owners like myself more control over how AI firms utilize our content. It looks like this might become part of robots.txt, allowing us to set definitive rules around AI system access and usage.

    IETF AI Preferences Working Group

    In response to this issue, the Internet Engineering Task Force (IETF) began the AI Preferences Working Group earlier this year in January. Their mission is to craft standardized, machine-readable rules to empower site owners to articulate AI usage preferences for their content.

    Since its inception in 1986, the IETF has established core Internet protocols like TCP/IP, HTTP, DNS, and TLS. Now, they’re laying down foundations for the open web’s AI era. Leading this group are co-chairs Mark Nottingham and Suresh Krishnan, joined by figures from Google, Microsoft, Meta, and more.

    Of particular interest is Google’s involvement via Gary Illyes, who is part of this working group.

    The purpose of this group is clear:

    • “The AI Preferences Working Group will standardize building blocks that allow for expressing preferences about how content is collected and processed for Artificial Intelligence (AI) model development, deployment, and use.”

    What the AI Preferences Group is Proposing

    This group aims to deliver new standards that empower site owners to determine how LLM-powered systems can utilize their open web content.

    • A standard track document detailing a vocabulary to express AI-related preferences, independent of content association methods.
    • Standard track document(s) that explain how to associate these preferences with content using IETF-defined protocols and formats, for example, Well-Known URIs and HTTP response headers.
    • A standard approach for reconciling multiple preference expressions.

    At the time of writing, nothing is set in stone yet. Early documents, however, provide a sneak peek into potential standards.

    This working group published two crucial documents in August.

    These documents propose significant updates to the Robots Exclusion Protocol (RFC 9309), suggesting new rules and definitions enabling site owners to specify AI content usage permissions.

    ```json
{
  "alt": "Diagram showing the relationship between categories of use, including foundation model, AI output, and search under automated processing.",
  "caption": "Exploring the links between foundation models, AI outputs, and search within automated processing systems.",
  "description": "This diagram illustrates the relationship between various categories in automated processing. It highlights the connections between foundation models, AI outputs, and search functionalities. The depiction consists of labeled boxes arranged to show how these categories interact. This visualization aids in understanding the structure and interaction within automated systems, useful for those studying AI and data processing frameworks."
}
```

    How It Might Work

    AI systems on the web are categorized and assigned standard labels. Whether a directory will exist for site owners to identify system labels remains unclear.

    Currently, the defined labels include:

    • search: for indexing/discoverability
    • train-ai: for general AI training
    • train-genai: for generative AI model training
    • bots: for all types of automated processing, such as crawling and scraping

    For each label, you can set two values:

    • y to allow
    • n to disallow.

    I found it interesting that these rules can be applied at the folder level and customized for different bots. In robots.txt, they’re implemented using a new Content-Usage field, akin to existing Allow and Disallow fields.

    Here’s an example robots.txt that the working group shared in their document:

    User-Agent: *
    Allow: /
    Disallow: /never/
    Content-Usage: train-ai=n
    Content-Usage: /ai-ok/ train-ai=y

    Explanation
    Content-Usage: train-ai=n indicates that no content on this domain may be used for training any LLM model, whereas Content-Usage: /ai-ok/ train-ai=y permits model training using content within the /ai-ok/ folder.

    Why Does This Matter?

    There’s significant buzz about llms.txt within the SEO community and its use alongside robots.txt. Yet, no AI company has confirmed adherence to these guidelines, and Google disregards llms.txt.

    Website owners, including myself, crave more explicit control over how AI companies leverage our content—be it for training models or RAG-based responses.

    I feel that the IETF’s new standards signify positive progress. With Illyes as a contributing author, I remain optimistic that once finalized, companies like Google will embrace these standards, respecting new robots.txt rules during content scraping.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Mastering LLM Visibility: Metrics and Insights for Real Impact

    Mastering LLM Visibility: Metrics and Insights for Real Impact

    I’ve been deeply involved in the compelling discussions around AI, especially the intriguing intersection of ‘AI hype meets AI reality.’ Tools like Semrush One and its Enterprise AIO tool have taken center stage, offering invaluable insights into what’s happening inside LLMs. The big questions I often ponder are: How many citations are we capturing and just how many mentions are our brands accumulating?

    When this data first emerged, it felt revolutionary. However, it quickly prompted other questions, like ‘What’s the ROI here?’ and ‘How can I integrate this data into my team’s marketing strategy?’ Ensuring that this valuable and fascinating data translates into actionable insights is a challenge I enjoy tackling.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    It’s no secret that the data these tools provide is incredibly valuable. But, what steps do I take next? Let’s uncover this journey together.

    ```json
{
  "alt": "Trending products list showing ranking of TV brands and models by share of voice.",
  "caption": "Discover what's trending in TV technology as LG and TCL lead the rankings by share of voice.",
  "description": "This image displays a list of trending TV products ranked by share of voice. LG's G3 model takes the top spot with 11%, followed by LG's C3 and TCL's 6-Series both with an 8% share. Samsung's QN90C and S95C, along with TCL's QM8K, also feature among the top-ranked models. The list highlights popular brands and models in the current TV market, useful for consumers looking to stay informed about top choices."
}
```

    The Fundamental Challenges of Tracking LLMs

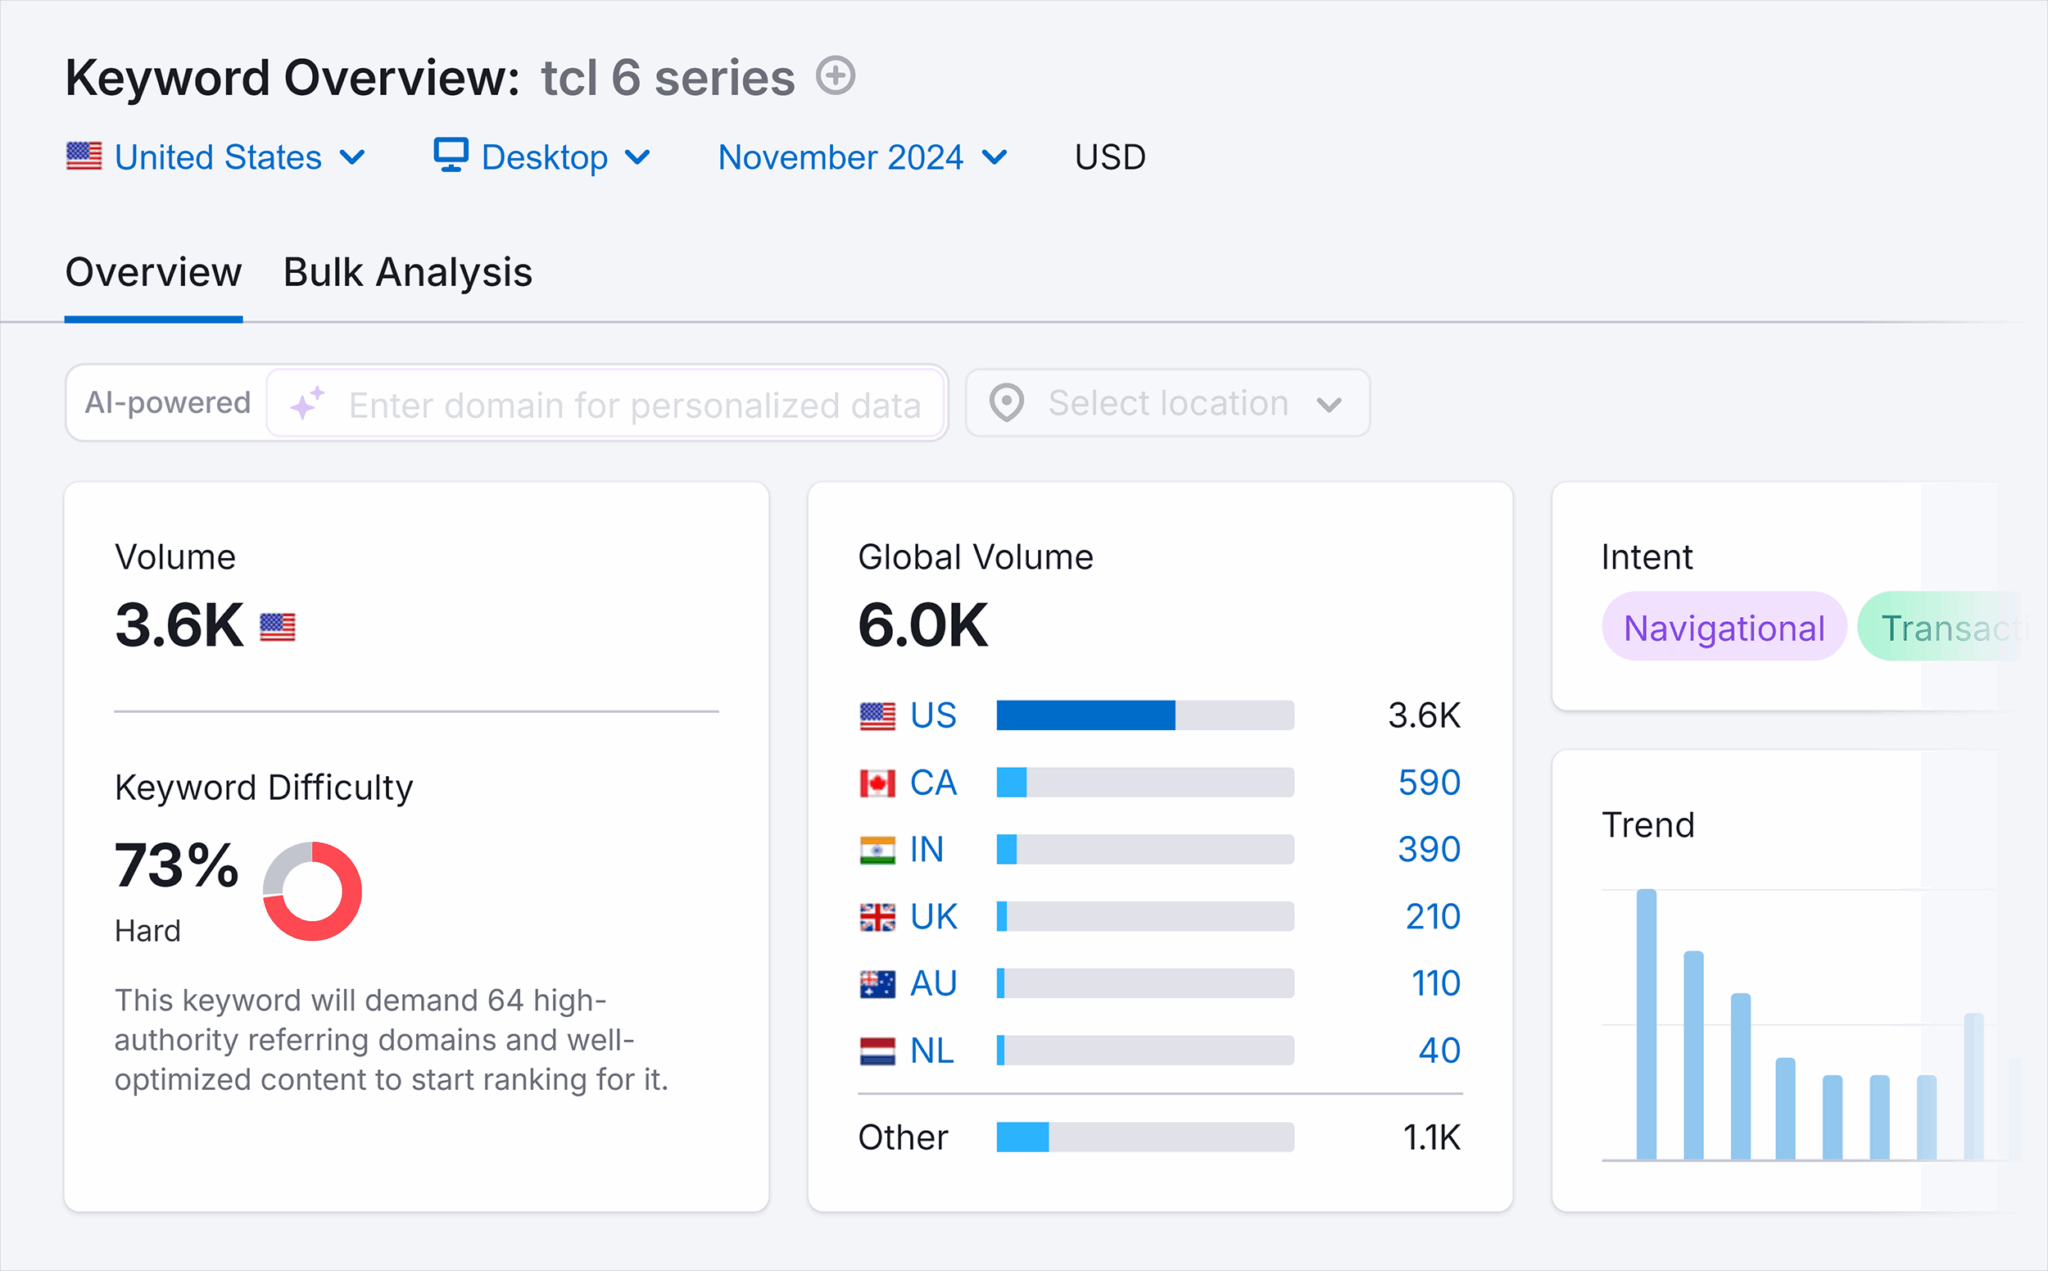
    Tracking LLMs can be more challenging than traditional metrics like Google rankings. Google rankings may show where I stand, but ranking doesn’t always correlate with traffic or revenue. Even if I rank highly, an AI Overview could dominate the search, reducing my traffic for a given keyword. I need to ask myself, is this the right traffic for my business goals?

    ```json
{
  "alt": "Keyword overview of TCL 6 series showing search volume, keyword difficulty, and trend data.",
  "caption": "Explore the keyword analysis for 'TCL 6 series' with detailed volume, global reach, and trend insights for November 2024.",
  "description": "This image displays a keyword analysis dashboard for the 'TCL 6 series.' In November 2024, the keyword has a search volume of 3.6K in the US and 6K globally, with a difficulty score of 73%, indicating high competition. The data is segmented by country, revealing insights into search intent and trend progression, helpful for content strategists and SEO professionals optimizing for this keyword."
}
```

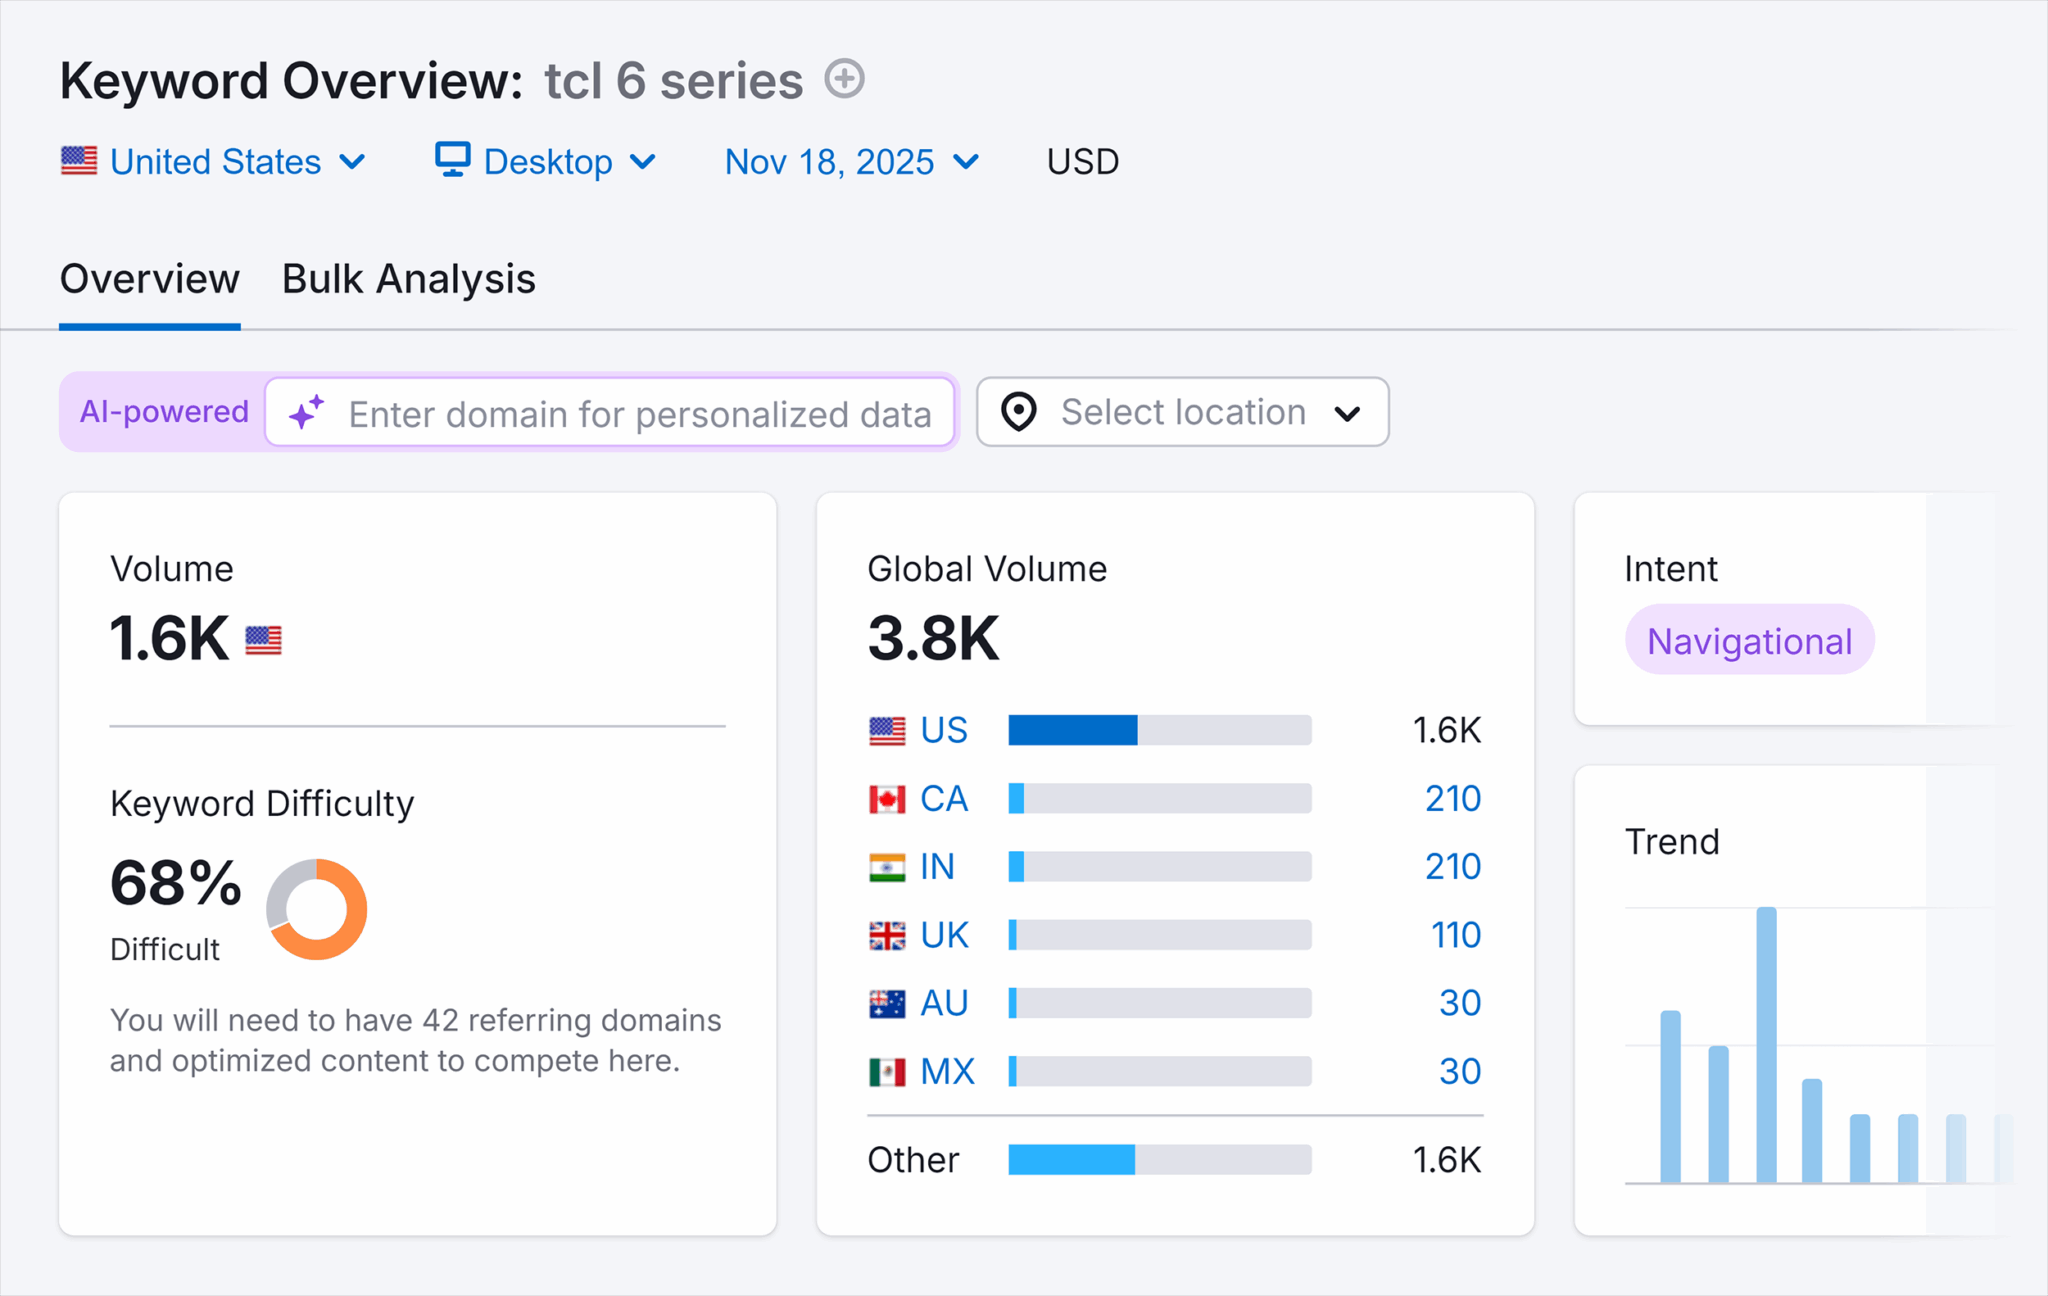
    The big difference between traditional SEO rankings and LLM visibility is the straightforward correlation between strong rankings and increased revenue, which is more complex with LLMs. I can easily track user behavior after they land on my site from organic search, but it’s not so clear-cut with LLMs.

    ```json
{
  "alt": "Keyword overview for TCL 6 series, showing search volumes, keyword difficulty, and intent.",
  "caption": "Explore detailed keyword insights for the TCL 6 Series, highlighting search volume, difficulty, and intent to refine your SEO strategy.",
  "description": "The image presents a keyword overview for the TCL 6 Series, detailing a search volume of 1.6K in the US and a global volume of 3.8K. It notes a keyword difficulty of 68%, indicating a challenging competition level. The intent is labeled as navigational, with trends visualized in a bar graph. This data is segmented by countries, including CA, IN, UK, AU, and MX, offering a comprehensive analysis suitable for refining SEO efforts. Keywords: TCL 6 Series, Keyword Overview, Search Volume, SEO, Navigational Intent."
}
```

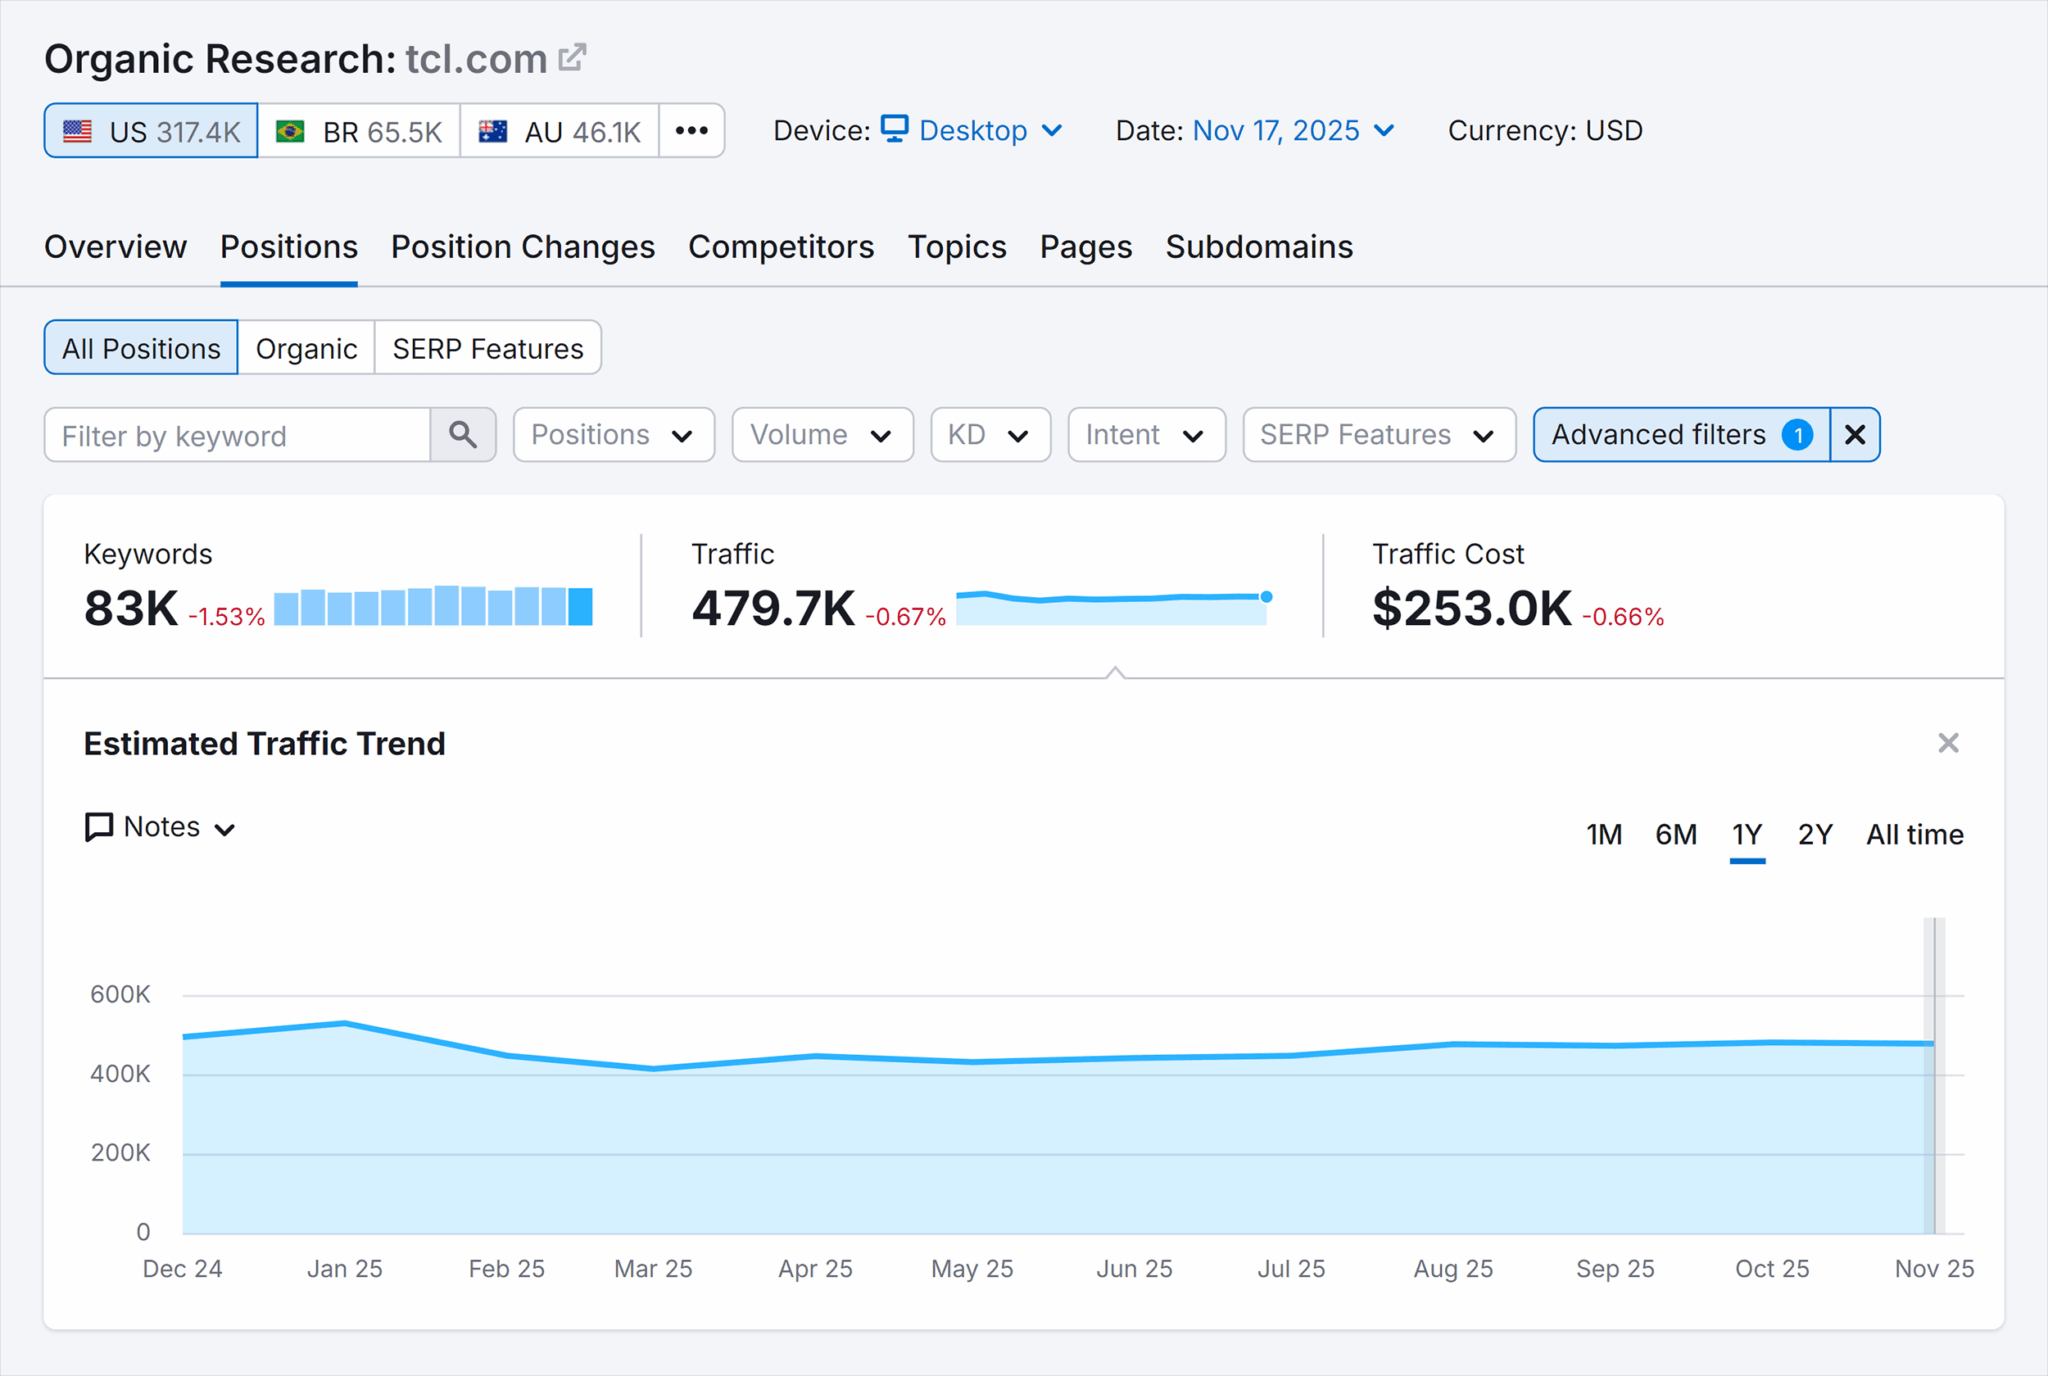
    SEO effectively drives traffic to my site, allowing me to evaluate the success of my conversion rate optimization (CRO) strategies. However, LLMs operate differently, leaving me with the task of creatively connecting the dots.

    ```json
{
  "alt": "SEO report for tcl.com showing keyword, traffic, and cost data with a traffic trend graph.",
  "caption": "Dive into the SEO stats for tcl.com, showcasing keyword performance, traffic data, and cost analysis, all accompanied by a visual traffic trend over the past year.",
  "description": "This image presents an SEO report for tcl.com as of November 17, 2025. It highlights key statistics such as 83K keywords, 479.7K monthly traffic, and a traffic cost of $253K, each experiencing slight decreases. The report includes a traffic trend graph showing fluctuations over the past year. This report is useful for analyzing search performance and strategizing for better visibility. Keywords: SEO, traffic, keywords, tcl.com, report, analysis, performance, trend."
}
```

    The Problem with Methodology

    As I dive deeper into using LLM-related data, I realize this approach requires me to step out of my comfort zone as a performance marketer. My usual reliance on direct attribution and data points is shifted toward constructing a narrative that ties LLM visibility to larger brand storytelling.

    ```json
{
  "alt": "SEO report showing organic research data for tcl.com including keywords, traffic, and estimated traffic trend over two years.",
  "caption": "An in-depth look into tcl.com's SEO performance: Explore key metrics like declining keywords and traffic, alongside an estimated trend over the past two years.",
  "description": "This image displays a detailed SEO report on tcl.com, featuring data such as a 5.37% drop in keywords to 317, a 1.72% decrease in traffic to 2.2K, and an 8.13% rise in traffic cost to $1.1K. The chart illustrates the estimated traffic trend for desktop devices over a two-year span from January 2024 to October 2025, with significant fluctuations and an overall downward trajectory. This visual is essential for analyzing SEO metrics and understanding website performance in different markets, including the US, Brazil, and Australia."
}
```

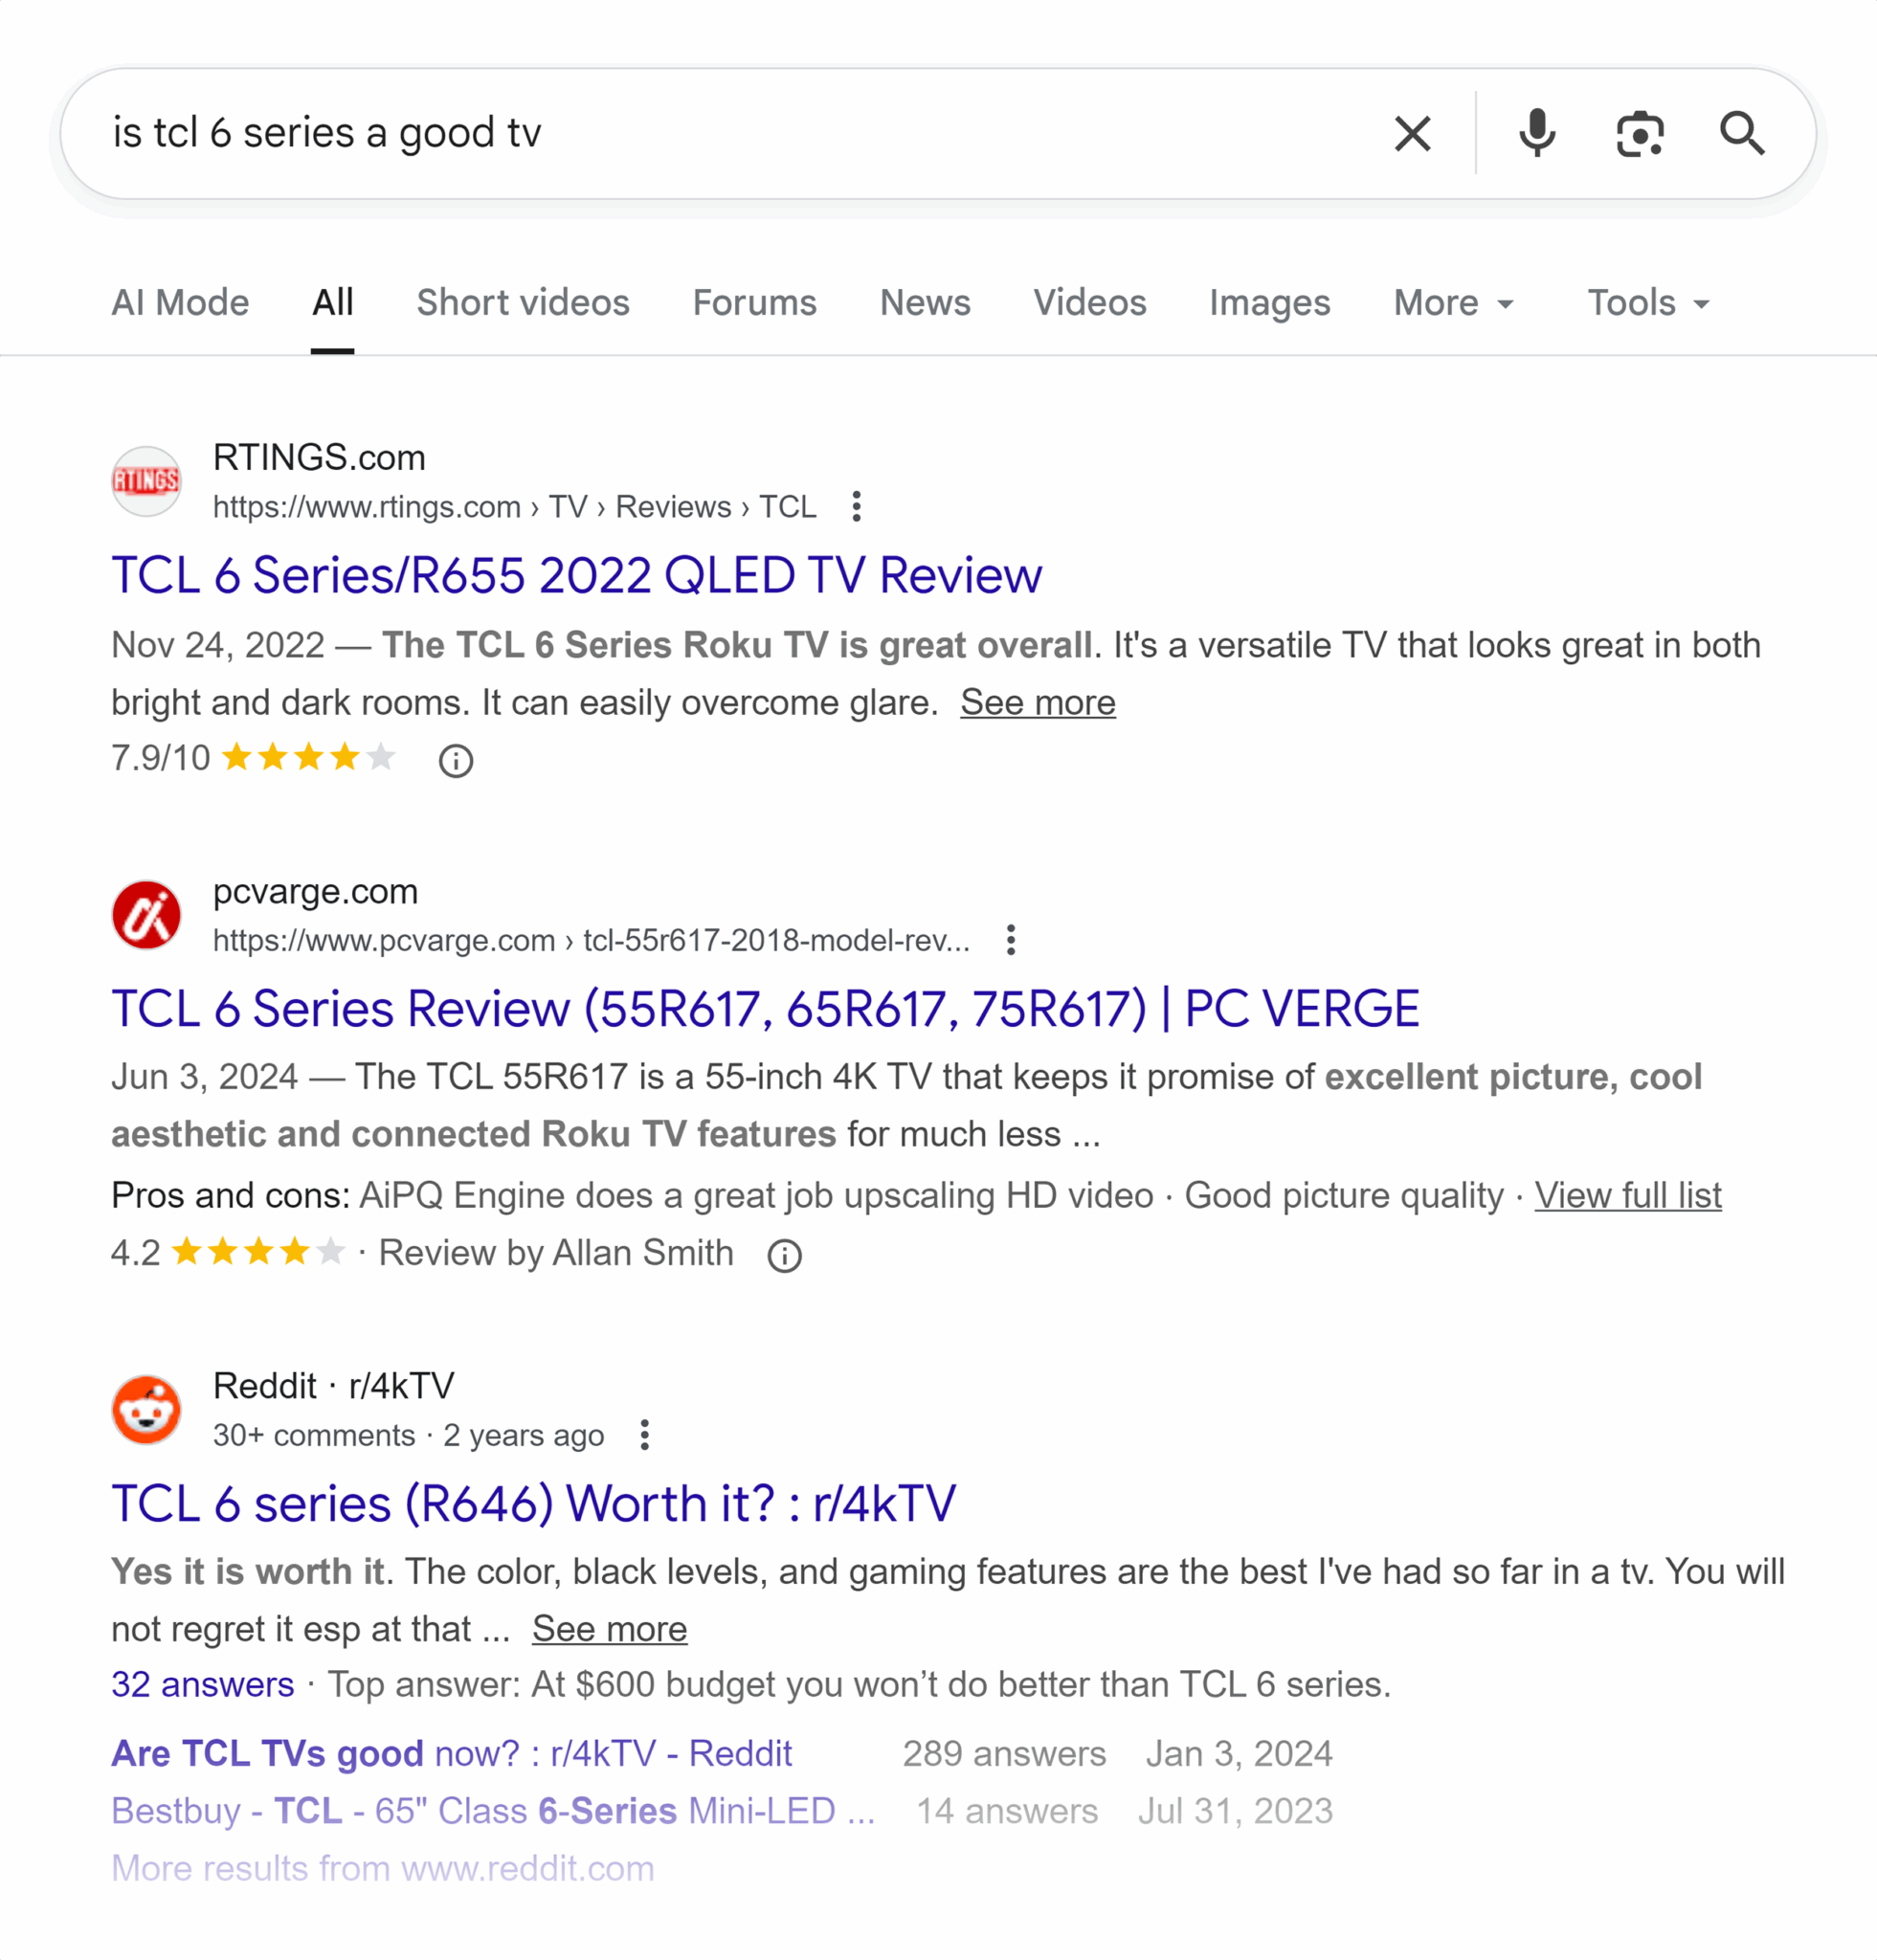
    This method isn’t novel, however. Brand marketers have dealt with indirect metrics since the days of billboard advertising. Still, the shift requires me to create insights from what might seem like fragmented LLM data.

    ```json
{
  "alt": "Search results for 'is tcl 6 series a good tv' showing review snippets from RTINGS, PC Verge, and Reddit.",
  "caption": "Curious about the TCL 6 Series TV? Explore a compilation of expert reviews and user opinions from RTINGS, PC Verge, and Reddit.",
  "description": "This image displays Google search results for the query 'is tcl 6 series a good TV.' The results include snippets from RTINGS, PC Verge, and Reddit discussing the TCL 6 Series TV. The RTINGS review describes it as a great overall product, highlighting its versatility. PC Verge emphasizes the TV's excellent picture quality and Roku features, with a 4.2-star rating. Meanwhile, a Reddit thread discusses the TCL 6 Series model R646, with users praising its color and gaming features. This image provides a quick overview of expert and user assessments of the TCL 6 Series TV."
}
```

    Metrics and Approach to LLM Impact Measurement

    Uncovering the true value brought by LLM visibility metrics is a layered and comprehensive process. To do this accurately, I need to understand the wider ecosystem of my organization’s promotional efforts. This understanding allows me to determine the root cause of site traffic or branded searches effectively.

    ```json
{
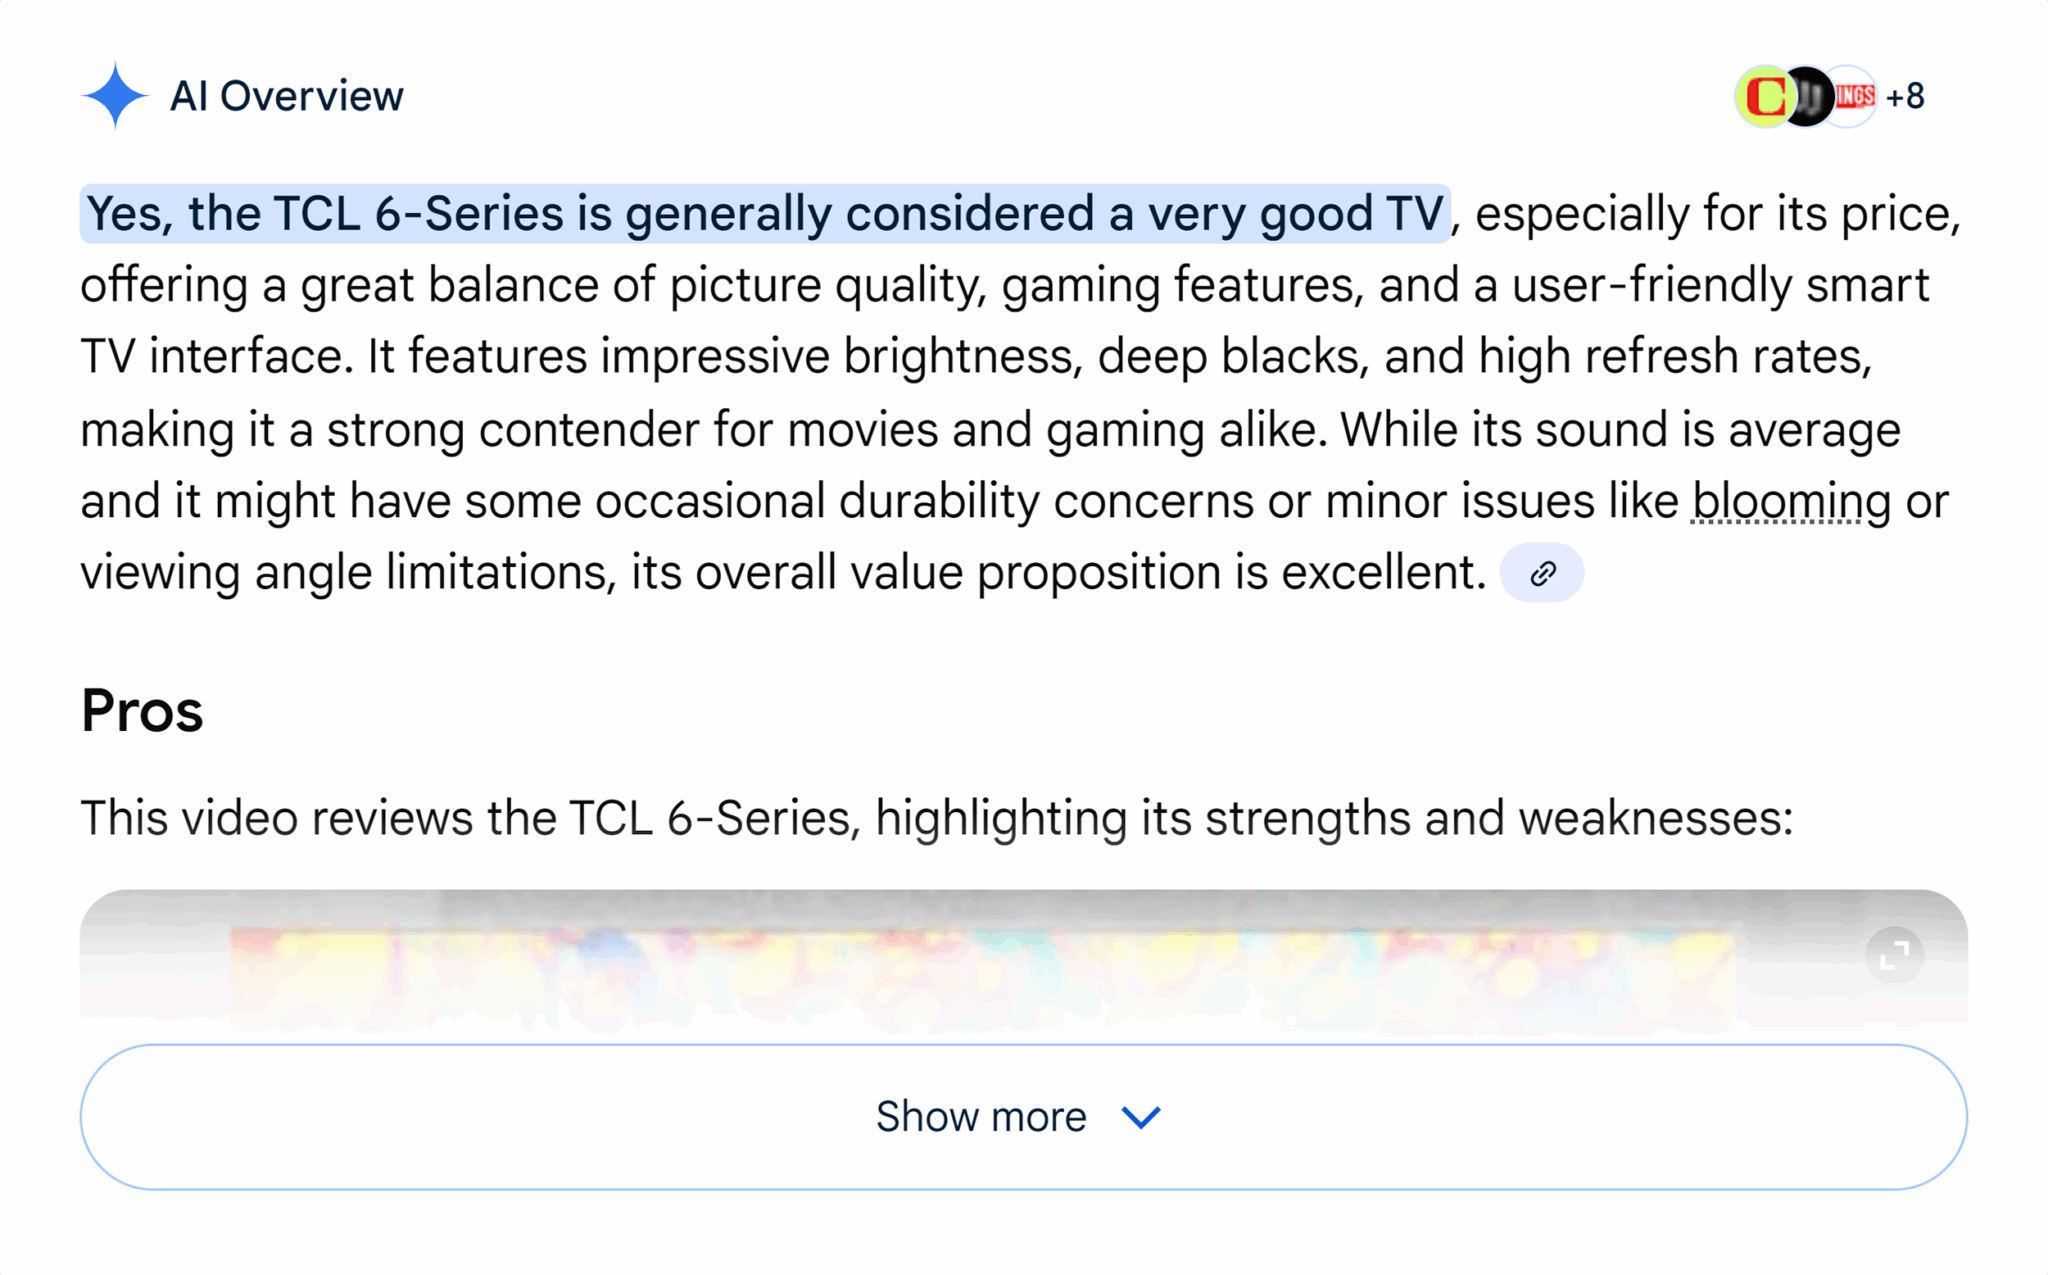
  "alt": "Text review of the TCL 6-Series TV highlighting its strengths and weaknesses.",
  "caption": "Discover why the TCL 6-Series TV is celebrated for its picture quality and gaming features, balancing affordability with performance.",
  "description": "This image features a text review of the TCL 6-Series TV, emphasizing its value for money with excellent picture quality, gaming features, and a smart TV interface. The text acknowledges minor issues like blooming and sound quality but highlights the TV’s competitive edge for movies and gaming. Keywords: TCL 6-Series, TV review, picture quality, gaming features, smart TV."
}
```

    For instance, if a TV ad campaign runs concurrently with optimizing for LLM mentions, analyzing their impact becomes essential. Only with complete awareness of such activities can I identify true causality or correlation.

    ```json
{
  "alt": "Line graph showing share of voice trends for Samsung, LG, and TCL over a span of one month.",
  "caption": "Explore the fluctuating share of voice for Samsung, LG, and TCL across a bustling month, revealing dynamic brand interactions.",
  "description": "This line graph displays the share of voice trends for three major brands: Samsung (blue), LG (yellow), and TCL (green), over a monthly period starting October 3rd to November 2nd. The graph showcases the daily variations in visibility and mentions for each brand, highlighting peaks and troughs in their market presence. Useful for tracking brand performance and consumer engagement over time."
}
```

    From here, I find that LLM visibility data is usually just the starting point. It’s unlike traditional SEO insights, which might be more apparent and direct. My task is to delve deeper, probing these data points to uncover richer insights.

    ```json
{
  "alt": "Visibility overview dashboard for buffalowildwings.com showing AI visibility score and audience data across multiple platforms.",
  "caption": "Explore the visibility insights of buffalowildwings.com with this detailed dashboard, highlighting AI visibility scores and audience metrics over time.",
  "description": "The image displays a visibility overview dashboard for buffalowildwings.com. It includes AI visibility scores, with a total score of 74 out of 100, labeled as medium. There are graphs indicating trends in total AI visibility, Chat GPT, AI Overview, and AI Mode from September to October 2025. The audience metrics show a monthly audience of 98.7 million, with an increase of 3.9 million, and mentions at 18.4K, which decreased by 390. The mention sources include Chat GPT, AI Overview, and AI Mode, with future integration of Gemini."
}
```

    The Branded Search of It All

    I’ve noticed that brand search provides exceptional insights into LLM performance, offering a rich vein of marketing intelligence. The comparison between two competing chicken wing chains, Buffalo Wild Wings and Wingstop, brightened this understanding for me. While their LLM citations differ, their brand awareness through social media presence offers a clearer picture of market positioning.

    ```json
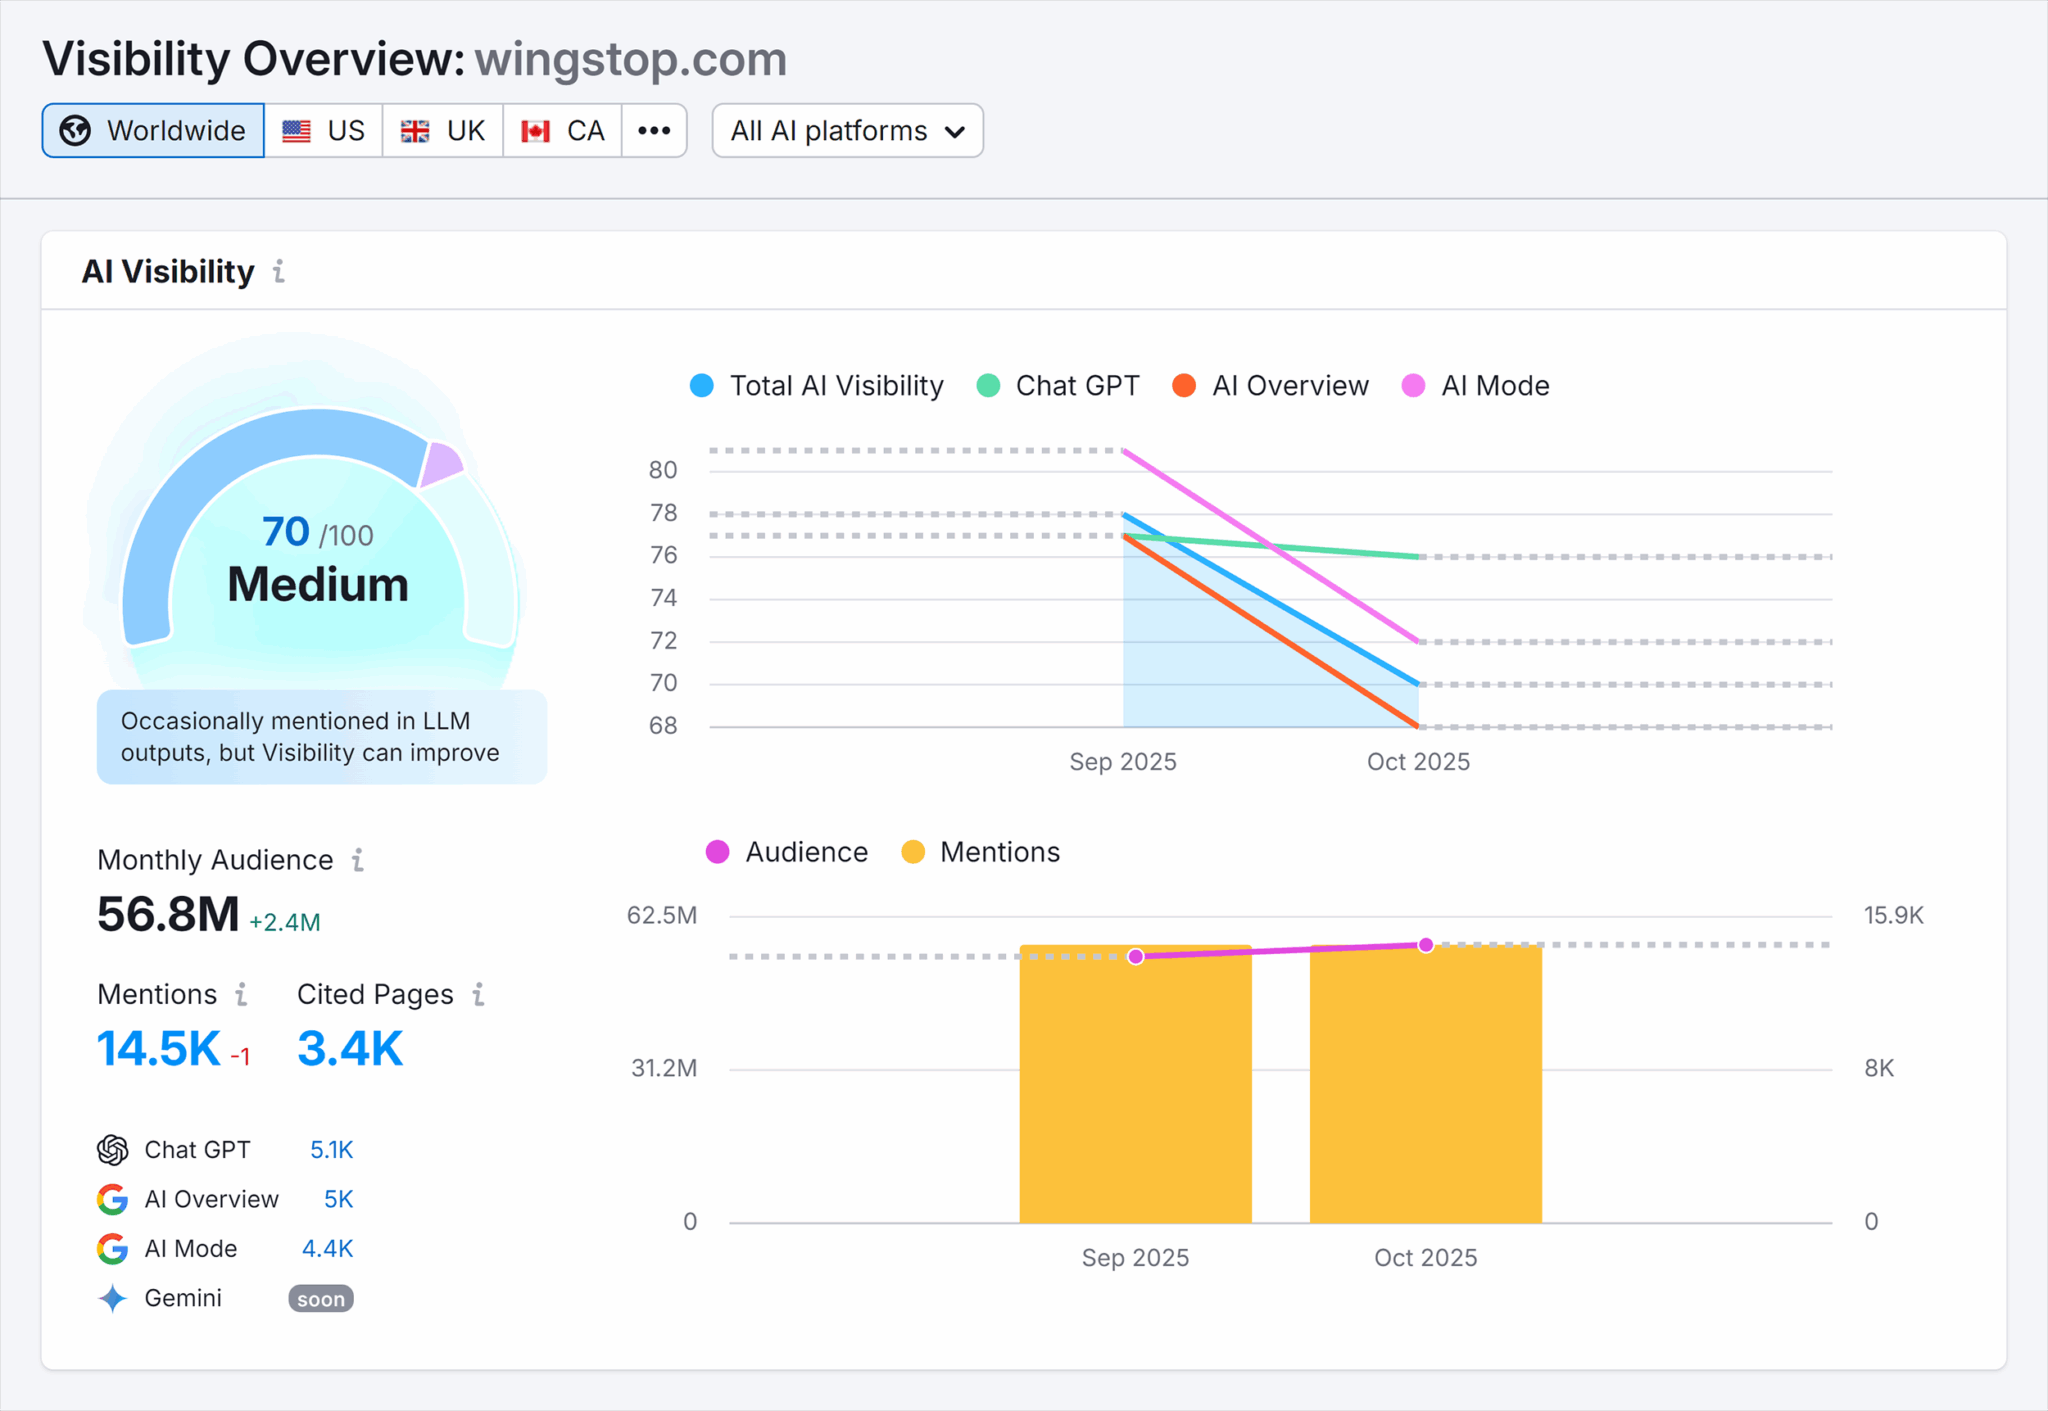
{
  "alt": "AI visibility overview for wingstop.com showing medium AI visibility and audience metrics for Sep to Oct 2025.",
  "caption": "Wingstop.com is currently rated as having medium AI visibility with audiences engaging steadily through to October 2025.",
  "description": "This image displays an AI visibility overview for wingstop.com. It highlights a medium visibility score of 70/100, with key metrics such as monthly audience at 56.8M and mentions at 14.5K. The accompanying chart visualizes trends in audience and mentions from September to October 2025 across platforms like Chat GPT and AI Overview."
}
```

    Simply examining the branded search traffic showed me how both brands performed similarly on Google, despite their different social media followings. Here lies the heart of utilizing search data creatively to find LLM visibility data strategies.

    ```json
{
  "alt": "Instagram profiles of Wingstop and Buffalo Wild Wings with logos and follower counts.",
  "caption": "Wingstop and Buffalo Wild Wings go head-to-head on Instagram, showcasing their vibrant profiles and follower stats. Which wing will you pick?",
  "description": "This image displays the Instagram profiles of two popular restaurants, Wingstop and Buffalo Wild Wings. Wingstop's profile features a green logo, 772K followers, and promotes their 'Fiery Lime' flavor. Buffalo Wild Wings showcases a yellow logo with a bison, boasting 540K followers, and advertises their 'Pick 6 Meal For 2'. Both profiles include website links and number of posts and followings, emphasizing their presence on social media."
}
```

    Rather than merely counting traffic, I am now compelled to consider the number of branded keywords involved, providing a sometimes surprising view on brand awareness and diversity. This approach provides a richer understanding of LLM visibility’s impact.

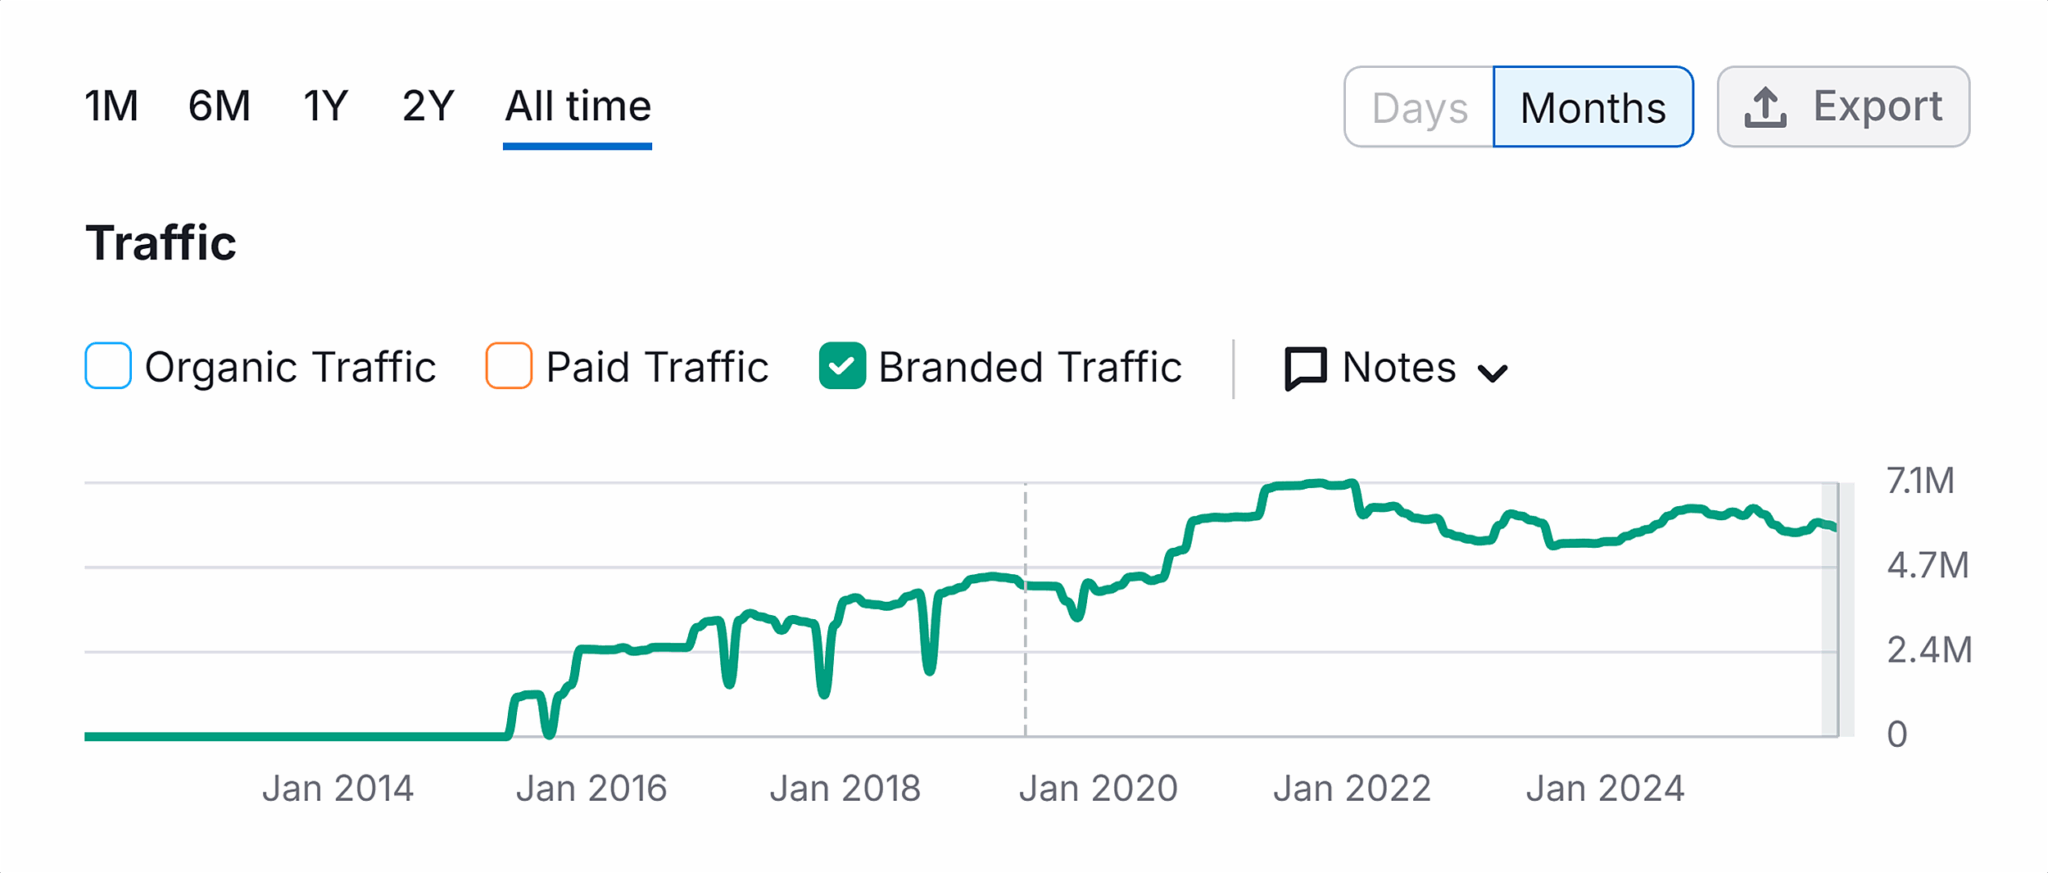
    ```json
{
  "alt": "Graph showing branded traffic growth from 2014 to 2024.",
  "caption": "Branded traffic trends over a decade reveal growth patterns and fluctuations from 2014 to 2024.",
  "description": "This line graph illustrates the growth of branded traffic from 2014 to 2024. Displayed over a timeline, the data reveals significant upward trends with moments of fluctuation, particularly notable around 2018 and 2022. The graph uses a green line to represent branded traffic, with metrics ranging from 0 to 7.1 million. The interface includes options to view data in various time frames, including days and months, and features a menu for exporting the data."
}
```

    Direct Traffic: My Trusted LLM Data Companion

    I’ve come to see direct traffic as an essential part of my LLM data narrative. Far from being a black hole, direct traffic can often indicate brand awareness and affinity, especially when correlated with LLM visibility metrics. Understanding these correlations allows me to paint a clearer picture of AI’s practical impact on consumer behavior.

    ```json
{
  "alt": "Traffic chart showing branded traffic from January 2014 to January 2024 with steady growth and fluctuations.",
  "caption": "Charting Success: This graph illustrates the rise and fluctuations in branded traffic over a decade, painting a picture of strategic growth!",
  "description": "This image features a traffic chart depicting the growth of branded traffic from January 2014 to January 2024. The graph shows a green line that represents the number of visitors in millions, starting near zero in 2014 and rising to over 4.7 million by 2024. The data reflects a general upward trend with noticeable fluctuations, representing periodic changes in traffic levels. The chart includes options for viewing organic and paid traffic, and it is set to display monthly data over the entire period. Keywords: traffic chart, branded traffic, growth, analytics."
}
```

    For instance, if I compare LG and TCL, LG’s superior direct traffic and increasing momentum in LLM visibility suggest a tangible AI-driven influence, a possibility I must explore through multi-metric analysis.

    ```json
{
  "alt": "SEO dashboard for buffalowildwings.com showing keyword metrics and traffic data.",
  "caption": "Explore the SEO metrics of buffalowildwings.com, showcasing keyword rankings and traffic trends as of November 17, 2025.",
  "description": "The image displays an SEO research interface for buffalowildwings.com, focusing on positions and metrics. It highlights keyword usage of 360.2K with a 3.28% change, alongside traffic data of 5.7M visitors and a traffic cost of $886.4K. The dashboard offers a detailed view of SEO performance across different regions, including the US, Canada, and the UK, with device-specific metrics for desktop usage."
}
```

    Considering various metrics together and identifying shared trends offer insight into how LLM visibility might be affecting my brand’s overall recognition and engagement.

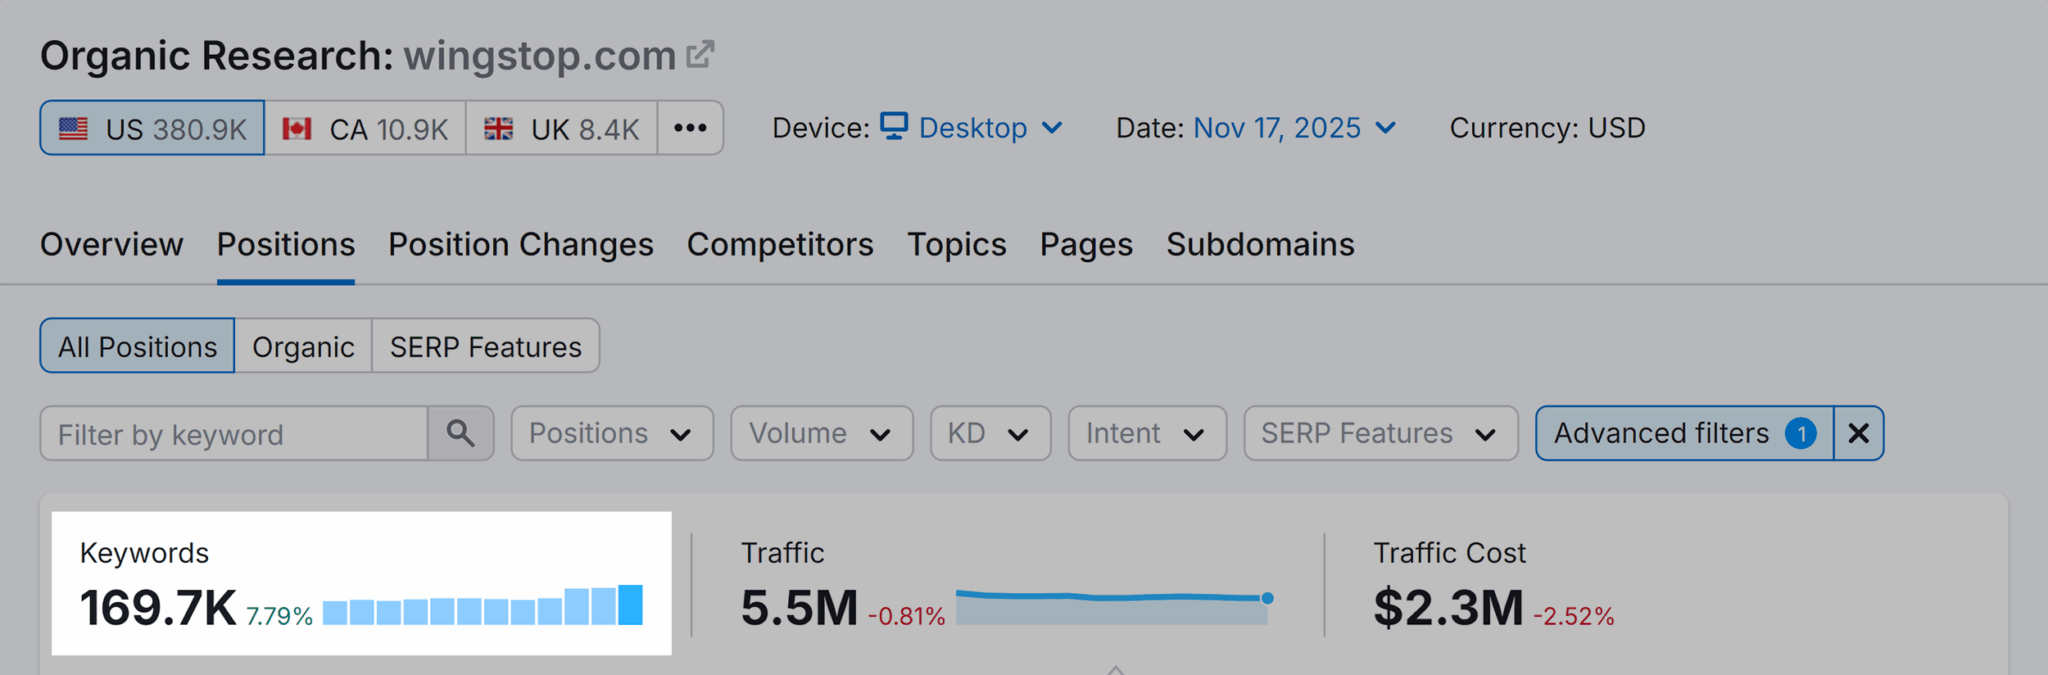
    ```json
{
  "alt": "Screenshot of organic research data for wingstop.com showing keyword statistics, traffic, and traffic cost.",
  "caption": "Explore Wingstop.com's robust organic search performance, showcasing a substantial keyword volume and valuable traffic data insights.",
  "description": "This image displays a screenshot from an SEO tool showing organic research data for wingstop.com. It highlights key metrics, including 169.7K keywords with a growth of 7.79%, 5.5M in traffic with a slight decrease of 0.81%, and a traffic cost of $2.3M, down 2.52%. The interface presents data for the US, Canada, and the UK, with options to filter results by keywords and positions. This detailed view assists in analyzing website performance and search engine visibility."
}
```

    Not Just One Metric: Stitching Together LLM Data Stories

    Ultimately, it’s about developing a comprehensive data story from LLM visibility insights. This story goes beyond direct KPIs, utilizing various data sources, such as bounce rates and organic traffic, to add depth and relevance to the narrative. Every piece of performance-focused data stands as testimony to the expertise we can bring to LLM visibility.

    ```json
{
  "alt": "Dashboard showing keyword, traffic, and cost metrics for 'sauce' with a traffic trend graph.",
  "caption": "Explore the SEO journey of 'sauce' with detailed keyword performance, traffic data, and cost analysis over the past year.",
  "description": "This image depicts an SEO dashboard for the keyword 'sauce,' showing 406 keywords with a 3.79% decrease, traffic at 10.4K with a slight 0.04% drop, and a traffic cost of $585 reflecting a 5.49% decrease. A traffic trend graph illustrates data over a year, highlighting fluctuations. Useful for SEO analysis and tracking keyword performance metrics."
}
```

    Total LLM visibility data, when creatively amalgamated with performance data, can transform insights into actionable strategies that align with pragmatic business objectives, showcasing our value in the AI-driven landscape.

    ```json
{
  "alt": "Traffic analytics chart showing keyword and traffic data for 'sauce'.",
  "caption": "Dive into the analytics! This chart reveals keyword dynamics and traffic trends for the term 'sauce' over the past year.",
  "description": "This image displays a traffic analytics dashboard for the keyword 'sauce', revealing data on keyword volume, traffic, and traffic costs. The chart shows an estimated traffic trend spanning a year from December to November, with metrics indicating a slight decline in keyword count and traffic cost, but an increase in total traffic. The interface includes advanced filter options and time range adjustments for detailed insights."
}
```

    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Boost Product Visibility with Google AI Shopping Optimization

    Boost Product Visibility with Google AI Shopping Optimization

    Have you ever wondered how to make your products stand out in Google AI Shopping and its AI Mode? I’ve discovered that optimizing feeds, utilizing schema, improving imagery, and crafting conversational Product Detail Page (PDP) content are key strategies to enhance visibility.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • How Positionless Marketing Can Solve AI Adoption Challenges

    How Positionless Marketing Can Solve AI Adoption Challenges

    Research from Forrester and insights from Blain’s Farm & Fleet have shown me that the real obstacle in AI adoption isn’t the technology itself; it’s how we approach marketing tasks.

    Imagine a chocolate company with a cherished, decades-old recipe. They ask an AI tool to identify cost-cutting measures. After several ingredient eliminations and promising margins, sales plummet. Finally, someone tastes the product: “This isn’t even chocolate anymore.”

    Aly Blawat from Blain’s Farm & Fleet shared this during a MarTech webinar to highlight why 82% of marketing teams struggle with AI: automation devoid of human insight often exacerbates failure.

    According to a Forrester study for Optimove, just 18% of marketers feel at the vanguard of AI adoption, despite 80% anticipating enhanced targeting through AI. Only a quarter have active AI use cases in production.

    As Forrester’s Rusty Warner explains, many await software with built-in safeguards before fully embracing AI. Currently, marketing runs like an assembly line, ill-suited for AI’s potential to overhaul workflows.

    Positionless Marketing could be the answer. Here, marketers manage everything from data to campaign launches independently, allowing swift action and reserved teamwork for larger initiatives.

    Blain’s Farm & Fleet trialed AI for their brand’s cohesive tone across platforms, utilizing Jasper, a protected system. Warner suggests starting small to build confidence, ensuring data integrity for effective AI outcomes.

    Successful marketing teams centralize critical data definitions, providing essential signals directly to marketers. Adoption lags not due to the technology, but because organizations aren’t structured to exploit it effectively.

    Balancing automation with authentic customer engagement means deploying AI where it can be most beneficial while maintaining a genuine brand experience. At Blain’s Farm & Fleet, human oversight ensures alignment with customer expectations.

    The future points toward AI in execution, allowing unique, personalized customer journeys. This shift demands organizations to enhance customer experience expertise across all channels.

    For effective AI integration, restructuring marketing workflows and focusing on measurable outcomes are key. The vision includes less manual effort, fewer illustrative meetings, and more tangible customer impact.

    By 2026, AI adoption is expected to soar with more vendors providing embedded, coherent AI solutions. Brands like Blain’s Farm & Fleet illustrate the transformation—the right AI application fosters growth, far beyond superficial changes.

    Ultimately, AI can’t repair broken systems but amplifies existing conditions. Successful teams must adapt modern workflows and mindset shifts to harness AI’s full potential.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Choose a US SEO or Digital Marketing Agency

    How to Choose a US SEO or Digital Marketing Agency

    Your shortlist probably contains a boutique SEO shop, a local-search specialist, a B2B firm, and a full-service digital agency. Their websites may promise similar outcomes, but they are not selling the same operating model.

    The right choice depends less on which agency looks most accomplished and more on where your growth is stuck, what your team can implement, and how you will verify progress. Use the framework below to narrow the US agency landscape, interrogate the evidence, and put an engagement on terms you can manage.

    Key takeaways

    • Define the business bottleneck before searching for an agency. A vague goal such as “increase traffic” produces vague proposals.
    • Choose an agency lane that matches the problem: SEO specialist, local SEO, small-business SEO, B2B SEO, or integrated digital marketing.
    • Evaluate comparable work, measurement definitions, team continuity, and implementation ownership. A review score alone cannot establish fit.
    • Make AI search an explicit scope of work. Require named deliverables, observable measures, and candid limits instead of a generic promise of AI visibility.
    • Protect account access, data, content, structured data, reporting history, and transition support in the contract. You should be able to leave without rebuilding your marketing infrastructure.

    Choose the agency lane that matches your bottleneck

    The US market is not one undifferentiated pool of SEO providers. It includes broad SEO specialists, agencies built around local search and local-pack visibility, firms focused on small-business needs, B2B SEO specialists, and full-service digital marketing agencies. Those labels overlap, but the operating demands behind them are different.

    Start by completing this sentence: “Growth is constrained because…” Name the point where demand, discovery, conversion, or implementation breaks down. Do not begin with a channel merely because that channel is underperforming. Weak organic traffic can come from poor technical access, thin content, weak market positioning, limited authority, or a site that ranks but does not convert. Each cause calls for different work.

    Your primary problemBest initial agency laneEvidence to request
    Important pages are not earning qualified organic discoverySEO specialistA technical diagnosis, a query-to-page plan, an editorial brief, and a clear division between recommendations and implementation
    Customers choose providers by location, but your locations are inconsistently representedLocal SEO specialistA location-level audit covering Google Business Profile, location pages, reviews, listings, and the way local outcomes will be attributed
    Your company has limited internal marketing capacity and cannot support a large production systemSmall-business specialistA prioritized scope that states what the agency will produce, what you must supply, and what will deliberately wait
    Your offer has a long or complex buying process involving several stakeholdersB2B SEO specialistBuyer-role and search-intent mapping, a subject-matter-expert workflow, and reporting that connects content to pipeline signals
    SEO, paid media, content, conversion work, and reporting need one coordinated planFull-service digital marketing agencyA channel-role map, named owners, an attribution approach, and an explanation of how budget and learning move between channels

    A local specialist is not automatically the right choice just because you have an address. The deciding question is whether location materially changes how customers discover and select you. Likewise, a B2B label matters only if the agency can handle complex offers, subject-matter review, non-linear buying journeys, and the gap between an early content interaction and a later commercial outcome.

    Small-business specialization is also about constraints, not company prestige. A workable partner must design around your available people, approval speed, technical access, and production capacity. An ambitious plan that quietly depends on your team writing every draft, fixing every template, and managing every stakeholder is not a small-business plan. It is an outsourced strategy with the implementation returned to you.

    Choose full-service digital marketing when channels genuinely need shared planning and the agency can demonstrate that integration. Buying more services from one supplier is not integration by itself. Ask who decides what each channel is meant to accomplish, how teams share audience learning, and who resolves conflicts when paid and organic teams want different landing-page changes.

    Verify the operating system behind the pitch

    A blank agency presentation sits in a conference room while a delivery team works behind glass on website structure, analytics, content, and project workflows.

    A pitch is written in the future tense. Useful evidence shows how the agency has already diagnosed a comparable problem, made trade-offs, completed the work, and measured the result. Your evaluation should therefore move past brand recognition and into the agency’s day-to-day operating system.

    Read reviews for patterns, not reassurance

    Agency feedback appears across Clutch, G2, UpCity, Sitejabber, Capterra, and Google. No single platform should settle the decision. Review populations, moderation, and commercial incentives can differ, so look for patterns that survive across platforms.

    • Prioritize reviews describing a problem, a scope, and a working relationship similar to yours. Generic praise tells you very little about fit.
    • Notice whether clients name the people who performed the work. Repeated praise for a salesperson does not establish the quality of the delivery team.
    • Look for evidence about communication after onboarding, when senior sales staff may no longer be involved.
    • Read critical feedback for recurring failure modes such as missed handoffs, unexplained reporting, slow implementation, or frequent team changes.
    • Inspect the agency’s responses to criticism. A specific, accountable response is more informative than a defensive dismissal or a stock apology.

    Reviews are a screening signal, not a substitute for diligence. They rarely reveal the client’s baseline, internal execution, market conditions, or the exact work that produced an outcome.

    Inspect continuity and decision ownership

    Median employee tenure and founder involvement in daily operations can help you assess continuity. Neither is proof of quality. Long tenure can indicate accumulated client knowledge, while direct founder involvement can improve strategic access. It can also reveal a bottleneck if every important decision depends on one person.

    Ask to meet the people who would actually own strategy, account management, content, technical work, and reporting. Then ask:

    • Which responsibilities belong to named employees, contractors, or partner firms?
    • Who can approve a change in priorities without escalating it through sales leadership?
    • What happens to context, documentation, and deadlines if the account lead changes?
    • How much of the proposed work depends on access to your developers, executives, sales team, or subject-matter experts?
    • Who is responsible for implementation when an audit identifies a technical or content problem?

    The final question prevents a common mismatch. Some agencies diagnose and advise. Others also write, design, publish, configure, test, and coordinate releases. Both models can work, but only if the responsibility boundary is explicit before the engagement starts.

    Audit case evidence before accepting the headline

    A percentage increase without a baseline, measurement window, or definition of the metric is incomplete evidence. For every relevant example, ask the agency to explain:

    • The client’s starting condition and the commercial problem being solved
    • The work the agency performed, separated from work completed by the client or another supplier
    • The period over which the change occurred
    • Whether the result refers to rankings, impressions, clicks, qualified leads, pipeline, sales, or another outcome
    • Which external factors or parallel campaigns may have affected the result
    • What failed, changed, or took longer than expected

    That last question matters. An agency that can discuss a failed assumption and the resulting adjustment is showing you how it thinks. One that presents every engagement as a smooth upward line is giving you a sales narrative, not an operating record.

    Define AI search work in deliverables, not slogans

    A marketing team moves source materials and structured content components through a staged workflow toward several unbranded digital answer interfaces.

    AI optimization has become part of agency selection, but the phrase can conceal very different services. Some firms mean improved content structure. Others mean schema, entity work, digital PR, prompt monitoring, AI referral analysis, or large-scale content generation. If a proposal merely adds “GEO” or “AEO” to an existing SEO package, you still do not know what you are buying.

    Require the agency to separate the work into inspectable layers:

    • Content: pages that answer the audience’s real questions directly, define important entities consistently, expose useful comparisons, and make claims easy to verify
    • Technical foundations: crawlable pages, intentional canonicalization, stable internal linking, and structured data that agrees with the visible page
    • Authority: a plan for earning credible mentions and references rather than manufacturing unsupported claims of expertise
    • Measurement: documented prompts or query themes, named AI systems, observation dates, referral data where available, citation or mention checks, and conventional search and conversion metrics
    • Governance: ownership, factual review, update triggers, and a process for correcting content when products, policies, or market facts change

    Schema deserves particular scrutiny. Structured data can make page meaning more explicit, but markup should describe what a user can actually see and verify. Ask which schema types are being proposed, why each property applies, where the underlying fact appears on the page, and how the markup will be tested and maintained. Treat any claim that schema alone will create authority or guarantee AI inclusion as a warning sign.

    AI visibility also needs a measurement definition. If an agency reports one proprietary score, ask to see the systems, prompts, sampling method, dates, weighting, and raw observations behind it. The score may still be useful, but only after you understand what changed when the number moved.

    Use these questions to separate a real AI-search practice from a renamed content package:

    • Which deliverables are different from your standard SEO work?
    • Which AI systems will you observe, and why are they relevant to our buyers?
    • How will you distinguish an AI citation, a brand mention, referral traffic, and a conventional organic visit?
    • What can your team influence, and what will you explicitly refuse to guarantee?
    • How do you prevent generated content from publishing unsupported facts, stale details, or near-duplicate pages?
    • How will AI-search findings change our editorial, technical, authority, or conversion priorities?

    We would reject guaranteed placement in AI answers, undisclosed bulk content production, schema that invents facts not present on the page, and reporting that cannot be traced back to observable inputs. Those are control problems as much as marketing problems.

    Run a selection process that exposes trade-offs

    The best way to compare agencies is to give each one the same bounded problem. Otherwise, you are comparing different assumptions, different scopes, and different definitions of success.

    1. Write a concise brief covering the commercial goal, audience, geography, offer, current bottleneck, relevant systems, available internal support, and constraints.
    2. Screen for the matching agency lane before requesting a proposal. Remove firms whose operating model depends on resources you do not have.
    3. Hold the same working session with every finalist. Use one real page, query cluster, local-search problem, or reporting question so you can compare how each team reasons.
    4. Request a written scope that names priorities, deliverables, owners, dependencies, approval requirements, measurement definitions, and exclusions.
    5. Speak with a relevant client reference and ask about the period after onboarding: team continuity, missed expectations, implementation friction, reporting clarity, and the way disagreements were handled.

    Do not demand an entire strategy as unpaid speculative work. A bounded diagnostic is enough to reveal whether the team asks useful questions, distinguishes symptoms from causes, and can explain what it would defer. If deeper access or analysis is necessary, a paid discovery phase can produce a cleaner decision while respecting the work involved.

    Compare the real resource model

    The retainer is only one part of the cost. Your operating comparison should include agency fees, required tools or media, internal review time, development work, content contributions, implementation effort, and likely rework. A lower fee can be the more expensive option when the proposal transfers production and coordination back to your team.

    Ask each finalist to show a responsibility map. Every recurring activity should have an owner, an approver, required inputs, and a destination. Pay particular attention to technical fixes and content publishing, because recommendations often stall between the person who identifies a change and the person authorized to release it.

    Protect ownership and the exit before signing

    A marketing engagement can create financial and operational exposure if critical assets sit in agency-controlled accounts. Have the contract state who owns and can access:

    • Analytics, advertising, search-platform, tag-management, and business-profile accounts
    • Domains, hosting, content-management access, repositories, and deployment credentials
    • Content drafts, briefs, templates, designs, structured data, research files, and reporting history
    • Audience lists, conversion definitions, dashboards, custom configurations, and documentation
    • Work created by contractors, affiliates, or other third parties engaged by the agency

    Your organization should hold the primary account wherever practical and grant the agency appropriate access. Shared credentials obscure accountability and make revocation harder; named user access is safer and easier to audit.

    The agreement should also cover team substitutions, approval delays, scope changes, data handling, use of generated content, reporting cadence, termination, final exports, credential removal, and transition support. If the relationship ends, you need editable assets and enough documentation for another team to continue the work. A folder of PDFs is not a complete handoff when the underlying accounts, configurations, prompts, templates, or source files remain elsewhere.

    Before you book another pitch, write your bottleneck in one sentence and choose the corresponding agency lane. Send every candidate the same evidence questions. The stronger partner will make its assumptions, responsibilities, limits, and trade-offs visible before asking you to commit.

    References


  • How to Protect Brand Authenticity in AI-Assisted Content

    How to Protect Brand Authenticity in AI-Assisted Content

    You need to publish more useful content without turning your brand into a production line of polished, interchangeable pages. AI can remove hours of mechanical work, but it can also remove the judgment, specificity, and recognizable point of view that make your content worth choosing.

    The answer is not to keep AI out of the workflow. It is to decide where efficiency belongs, where a human must remain accountable, and what every page has to prove before you publish it.

    Content quality must serve the reader and the retrieval system

    AI is valuable because it can increase speed and automate repeatable work. The problem begins when a team treats faster production as evidence of better content.

    A page can be grammatically clean, keyword-aware, and structurally complete while still failing the reader. It may repeat familiar advice, hide the answer beneath an introduction, make claims it cannot support, or sound as though no identifiable organization chose the words.

    In the AI era, useful content has to pass several different tests:

    • Accuracy: Can you trace every meaningful factual claim to reliable evidence, and have you preserved any necessary limits or uncertainty?
    • Usefulness: Can the reader make a decision, complete a task, or notice a problem they would otherwise miss?
    • Specificity: Does the page explain the mechanism, constraint, sequence, example, or trade-off behind its advice?
    • Distinctiveness: Does it contain a judgment, method, explanation, or framing that reflects what your brand actually knows and believes?
    • Retrieval clarity: Can a relevant passage stand on its own when a search engine or answer system extracts it from the surrounding page?
    • Brand coherence: Do the vocabulary, promises, evidence standards, and level of certainty match the rest of your site?

    These tests catch different failures. Accurate but generic content is forgettable. Distinctive but unsupported content is risky. Search-ready content that reads like a machine-generated template may earn an impression without earning trust. A page is ready only when it is useful, supportable, recognizable, and easy to interpret.

    Keep human judgment where trust is created

    The safest division of labor is based on accountability, not on whether a task appears easy. Let AI transform approved material. Keep people responsible for deciding what is true, what matters, what the brand believes, and what the reader should do.

    AI is well suited to bounded transformations such as reorganizing notes, proposing outlines, generating headline alternatives, turning a long explanation into a checklist, identifying repeated language, and adapting an approved passage to another format. Those tasks have visible inputs and reviewable outputs.

    Human ownership matters most at the points where an error would change meaning or weaken trust:

    • Selecting the audience, search intent, and decision the page must support.
    • Choosing evidence and deciding which claims the evidence can genuinely carry.
    • Contributing subject expertise, exceptions, operational details, and a defensible point of view.
    • Setting the boundary between established fact, editorial judgment, inference, and uncertainty.
    • Approving promises about products, outcomes, customers, compliance, or performance.
    • Accepting final responsibility for the published page and its structured data.

    For claims that need proof, do not treat model memory as evidence. A fluent sentence can still be unsupported, overgeneralized, or detached from the conditions that made the original claim true.

    Give the model a content contract, not a loose prompt

    A prompt that asks for an authoritative SEO page leaves the important decisions unresolved. Before drafting, create a short content contract with fields an editor can inspect:

    • Reader situation: What has brought this person to the page, and what do they already understand?
    • Reader job: What should they be able to decide or do after reading?
    • Primary claim: What is the clearest answer you are prepared to defend?
    • Evidence packet: Which approved facts, documents, examples, and internal expertise may the draft use?
    • Brand position: What does your organization believe that a generic overview would not say?
    • Claim boundaries: What must not be asserted, implied, invented, or generalized?
    • Voice constraints: Which language patterns should appear, and which should be removed?
    • Retrieval target: Which question deserves a concise, self-contained answer within the page?
    • Next action: What useful step should the reader take, even if they never become a customer?

    Then run the work in an explicit sequence:

    1. A subject owner approves the reader job, primary claim, evidence, and brand position.
    2. AI proposes an outline in which every section resolves a distinct reader question.
    3. An editor removes sections that exist only to make the page look comprehensive.
    4. AI drafts from the approved contract and evidence packet.
    5. A factual pass checks claims, qualifiers, entity names, citations, and unsupported implications.
    6. A separate brand pass checks judgment, vocabulary, tone, repetition, and generic phrasing.
    7. An optimization pass improves headings, answer units, internal links, metadata, and relevant structured data without changing the approved meaning.
    8. A named human owner approves the visible content and machine-readable representation together.

    Separating the passes matters. If one reviewer tries to verify facts, improve voice, shorten sentences, and inspect schema at the same time, the visible polish can distract from a weak claim or an unhelpful answer.

    Turn brand voice into an editing system

    An editor adjusts an unlabeled instrument that turns plain gray tiles into varied designs with a consistent color palette and material style.

    Authenticity does not depend on a human typing every sentence. It comes from a consistent relationship between what your brand knows, what it believes, what it promises, and what it publishes. AI can help express that relationship, but it cannot invent it responsibly.

    Labels such as friendly, expert, bold, or conversational are too subjective to guide a draft. Replace them with observable editorial rules:

    • Beliefs: Record the principles that shape your recommendations. For example, visible content should answer the question before structured data describes the answer.
    • Audience contract: State what you owe the reader. This might include explaining constraints, separating evidence from opinion, and never hiding the practical answer behind a sales pitch.
    • Proof habits: Define when claims need links, examples, named entities, qualifications, or review by a subject expert.
    • Language choices: List preferred terminology, prohibited hype, acceptable contractions, sentence-length tendencies, and the technical terms that must remain precise.
    • Boundaries: Document claims the brand will not make, including guarantees, fabricated experience, invented customer stories, and unsupported comparisons.
    • Approved examples: Save real passages that demonstrate the voice and annotate why they work. A model needs patterns, not just adjectives.

    Consider the difference between a generic claim and an owned editorial position.

    Generic: AI is transforming content marketing and helping businesses improve efficiency.

    Owned: Use AI to compress mechanical work. Keep evidence selection, claim boundaries, and final judgment with an accountable editor.

    The second version is not stronger because it sounds more colorful. It makes a decision, draws a boundary, and tells the reader what to do differently. That is the material from which a recognizable brand voice is built.

    Use a swap test during editing: if a competitor could publish the paragraph unchanged, it probably lacks an owned insight. Do not add a slogan merely to make it sound branded. Add the missing judgment, mechanism, example, limitation, or operating rule.

    Also remove simulated experience. If your organization did not run a test, interview a customer, inspect an account, or observe a result, the draft must not imply that it did. Explain what you know and how you know it. Honest limits are part of brand voice.

    Make content easy for people and answer systems to use

    Optimization for AI search does not require stripping personality from the page. It requires making the important meaning easy to locate, interpret, and reuse without distortion.

    Build important sections as self-contained answer units:

    1. Use a heading that names the actual question or decision.
    2. Answer it in the opening sentence without forcing the reader through background first.
    3. Explain why the answer holds or how the mechanism works.
    4. Name the condition, exception, version, audience, or limitation that changes the advice.
    5. Give the reader a concrete next action.
    6. Link the words carrying an evidence-dependent claim, rather than attaching an unexplained list of links.

    The opening answer provides clarity. The mechanism and limitation provide trust. The recommended action is where brand judgment becomes visible. You can therefore write a passage that is both extractable and distinctly yours.

    Run a context test on each candidate answer unit. Copy the passage into a blank document and ask:

    • Is the subject named, or does the passage depend on a vague pronoun?
    • Can a reader tell whether the statement is a fact, recommendation, definition, or opinion?
    • Are material conditions and exceptions still present?
    • Does the passage identify the product, organization, feature, standard, or audience precisely?
    • Would the passage remain accurate if displayed without the preceding paragraph?

    If the answer unit fails outside its original context, revise the language rather than stuffing more keywords into it.

    Consistency also matters across the site. Use one canonical name for your organization, products, services, features, and authors. Explain genuine synonyms, but do not rotate terminology simply to create lexical variety. Unnecessary variation makes it harder for a person or system to determine whether two passages refer to the same entity.

    Apply the same discipline to JSON-LD and other structured data. Markup should represent the visible page accurately. It should not introduce credentials, ratings, offers, authorship, answers, or relationships that the reader cannot verify in the content. Schema can clarify a strong page; it cannot supply the substance the page is missing.

    Finally, use internal links to connect a concise answer with the deeper proof behind it. A summary page can resolve the immediate question, while a supporting page explains the method, terminology, evidence, or implementation. This creates a useful path for readers without forcing every page to become an exhaustive encyclopedia.

    Replace output metrics with a publish gate and feedback loop

    A circular track carries blank page-shaped objects through a human review station, with one sent back for revision and another released to waiting readers.

    Traditional quality metrics are not enough for AI-first content. Word count, production volume, grammar checks, and a passing optimization score can describe the artifact or workflow, but they cannot establish that the page is accurate, useful, distinctive, or trusted.

    A useful measurement system separates four kinds of signals:

    • Production signals: Track drafting time, approval loops, substantial rewrites, and where work repeatedly returns to an earlier stage. These reveal workflow efficiency, not content quality by themselves.
    • Integrity signals: Track unsupported-claim flags, citation gaps, correction requests, entity inconsistencies, and mismatches between visible content and structured data.
    • Brand signals: Track prohibited language, failed swap tests, unapproved promises, simulated experience, and sections that lack an identifiable editorial position.
    • Discovery signals: Where your tools can observe them, track the queries that surface the page, branded and non-branded visibility, citations or mentions in answer experiences, and referrals from AI interfaces.
    • Outcome signals: Match the page to its intended job, such as a completed setup, qualified inquiry, subscription, product comparison, or movement to a deeper supporting page.

    Read these signals together. Faster production accompanied by more factual corrections means the workflow moved effort downstream rather than removing it. Strong visibility with weak outcomes may indicate that the page answers the query but does not help with the decision behind it. Good engagement with repeated swap-test failures means the page may be useful while doing little to build brand recognition.

    A composite quality score can help you prioritize review, but it should not own the publishing decision. Use a simple editorial gate:

    • Block: A material claim lacks evidence, the page invents experience, a required limitation is missing, an entity is misrepresented, or structured data asserts something the visible page does not support.
    • Revise: The answer is buried, advice remains generic, sections repeat one another, the next action is unclear, or the language fails the brand’s documented rules.
    • Publish: The page answers a real reader need, important claims are supportable, brand judgment is visible, answer units survive the context test, and a named owner accepts responsibility.

    After publication, feed what you learn back into the system. Log corrections with their causes. Add strong and weak passages to the annotated voice examples. Update the content contract when reviewers keep fixing the same omission. Revisit important pages when the offer, evidence, entity information, or reader decision changes.

    Key takeaways

    • Use AI for bounded, reviewable transformations; keep people accountable for evidence, judgment, promises, and approval.
    • Define brand voice through beliefs, proof habits, language rules, boundaries, and annotated examples rather than vague tone adjectives.
    • Write self-contained answer units that give a direct answer, explain the mechanism, preserve limitations, and recommend a useful action.
    • Keep entity language, visible content, internal links, and structured data consistent.
    • Measure production efficiency separately from integrity, brand distinctiveness, discovery, and reader outcomes.
    • Block publication when a material claim, implied experience, or machine-readable assertion cannot be supported.

    Start with one commercially important page. Write its content contract, mark every evidence-dependent claim, run the swap and context tests, and compare its structured data with what a reader can actually see. The weaknesses you find will tell you exactly which rules your wider AI content workflow needs next.

    References