Your product appears in an AI answer on Monday, disappears on Tuesday, and returns through a different citation on Friday. That does not automatically mean your optimization worked, failed, and recovered. It means you are looking at a system that assembles answers dynamically rather than assigning one durable position.
You need a visibility program built for that volatility. The goal is to increase the probability that your brand is found, understood, supported by credible evidence, and selected when an AI system moves from answering a question to helping someone choose a product.
Replace the idea of one ranking with three layers of visibility
A conventional ranking gives you a page, a query, and a position. An AI answer can vary its wording, cited URLs, recommended brands, and product shortlist from one run to the next. Treating one generated response as a ranking report will produce false alarms when you disappear and false confidence when you happen to appear.
The volatility is large enough to affect how you interpret every test. When 10,000 keywords were run through Google AI Mode three times on the same day, the average URL overlap was only 9.2%. For 21.2% of the keywords, the three runs had no cited URLs in common. In another large test, Google AI Overview content changed in roughly 70% of checks, while only 54.5% of cited URLs overlapped between consecutive runs.
Yet changing citations do not always mean that the underlying answer has changed. The semantic similarity of those AI Overviews remained at 0.95 even while their wording and evidence rotated. You can therefore lose a particular citation while the system continues to express the same category preference, recommendation criteria, or view of your brand.
Measure three layers separately:
- Answer visibility: Does the brand or product appear in the generated response, recommendation, shortlist, or comparison?
- Evidence visibility: Which owned or third-party pages are cited, and what claims are those pages supporting?
- Commerce readiness: Can a shopping agent determine what the product is, who it suits, which variant applies, and whether the commercial information is complete enough to support a decision?
This distinction matters because the remedy depends on the layer. If your brand remains recommended but your URL stops being cited, you may have an evidence-distribution problem. If your pages are cited but your product never reaches the shortlist, your positioning or product fit may be unclear. If the product appears but the agent reports an incorrect price, variant, or use case, the problem is data consistency rather than general brand awareness.
Shopping agents raise the stakes. Personal agents such as Muse and Instinct can find products, compare options, and make purchasing decisions for users. Your job is no longer finished when an AI system mentions the brand. The system must also be able to qualify the product against the buyer’s situation.
Build a measurement system that survives volatile answers
Start with the questions that precede a real decision, not a collection of high-volume keywords. A useful prompt library represents the different jobs a buyer asks an assistant to perform:
- Problem discovery: asking what kind of product solves a stated need.
- Use-case qualification: looking for a product that fits a particular audience, environment, workflow, or constraint.
- Comparison: weighing products or product types against explicit criteria.
- Risk reduction: checking compatibility, limitations, policies, reliability, or suitability.
- Purchase preparation: verifying variants, availability, price, delivery, returns, or another decision-critical fact.
- Branded evaluation: asking whether your product is suitable and what alternatives should be considered.
Write prompts in the buyer’s language and preserve the qualifiers that change the answer. “Best project-management software” and “project-management software for a small agency that needs client approvals” are not interchangeable questions. The second prompt gives the system criteria it can use to include or exclude a product.
Run the same library on each AI platform you care about, but do not blend the results into one universal score. Google AI Overviews and AI Mode shared only 13.7% of their citations in one comparison. Platform-specific shifts can also be abrupt: Reddit’s average share of ChatGPT Search citations fell from 3.83% to 0.52% across the reported periods, an 86.4% decline, while the broader pattern was not uniform across AI systems.
A blended average can hide exactly what you need to diagnose. Keep separate views for each platform, answer surface, market, and language you test. Aggregate them only after you have inspected the underlying results.
Repetition is equally important. Published sampling guidance indicates that 60 to 100 runs of a prompt can produce meaningful visibility data. Another longitudinal approach recommends at least seven runs per prompt per day for brand-level estimates, assessed through rolling windows of two to four weeks. These are measurement benchmarks, not a claim that every team must immediately test at that scale. If your budget supports fewer observations, label the result as directional and avoid making budget or content decisions from a single response.
Your dashboard should answer operational questions rather than merely count mentions:
| Question | Metric | What to record | Likely next action |
|---|---|---|---|
| Are we present? | Brand mention rate | Valid runs containing the brand divided by all valid runs for that prompt set | Investigate prompt clusters where competitors appear consistently and you do not |
| Are products being considered? | Product inclusion rate | Runs in which an eligible product enters the shortlist or comparison | Clarify audience fit, category language, and comparison attributes |
| What supports the answer? | Citation rate by domain and URL | Owned and third-party pages cited for each claim or recommendation | Strengthen missing evidence and pursue relevant independent coverage |
| Is the answer accurate? | Fact accuracy rate | Correct and incorrect statements about fit, specifications, terms, and availability | Resolve contradictions across pages, catalogs, feeds, and structured data |
| Is the change persistent? | Rolling visibility range | Rates and ranges over repeated runs, separated by platform | Act on sustained movement rather than an isolated response |
Keep a changelog beside the data. Record platform and model updates, material website changes, catalog releases, content refreshes, and significant third-party coverage. The log will not prove causation, but it prevents the team from inventing an explanation after every rise or fall.
Use a simple decision rule: one unusual answer is an observation; a repeated change within the same platform and prompt cluster is a pattern worth diagnosing. If the decline appears everywhere at once, inspect broad accessibility, brand evidence, and product-data issues. If it appears only for comparison prompts, look first at the criteria buyers use to distinguish products.
Make every product answerable before expecting it to be selectable
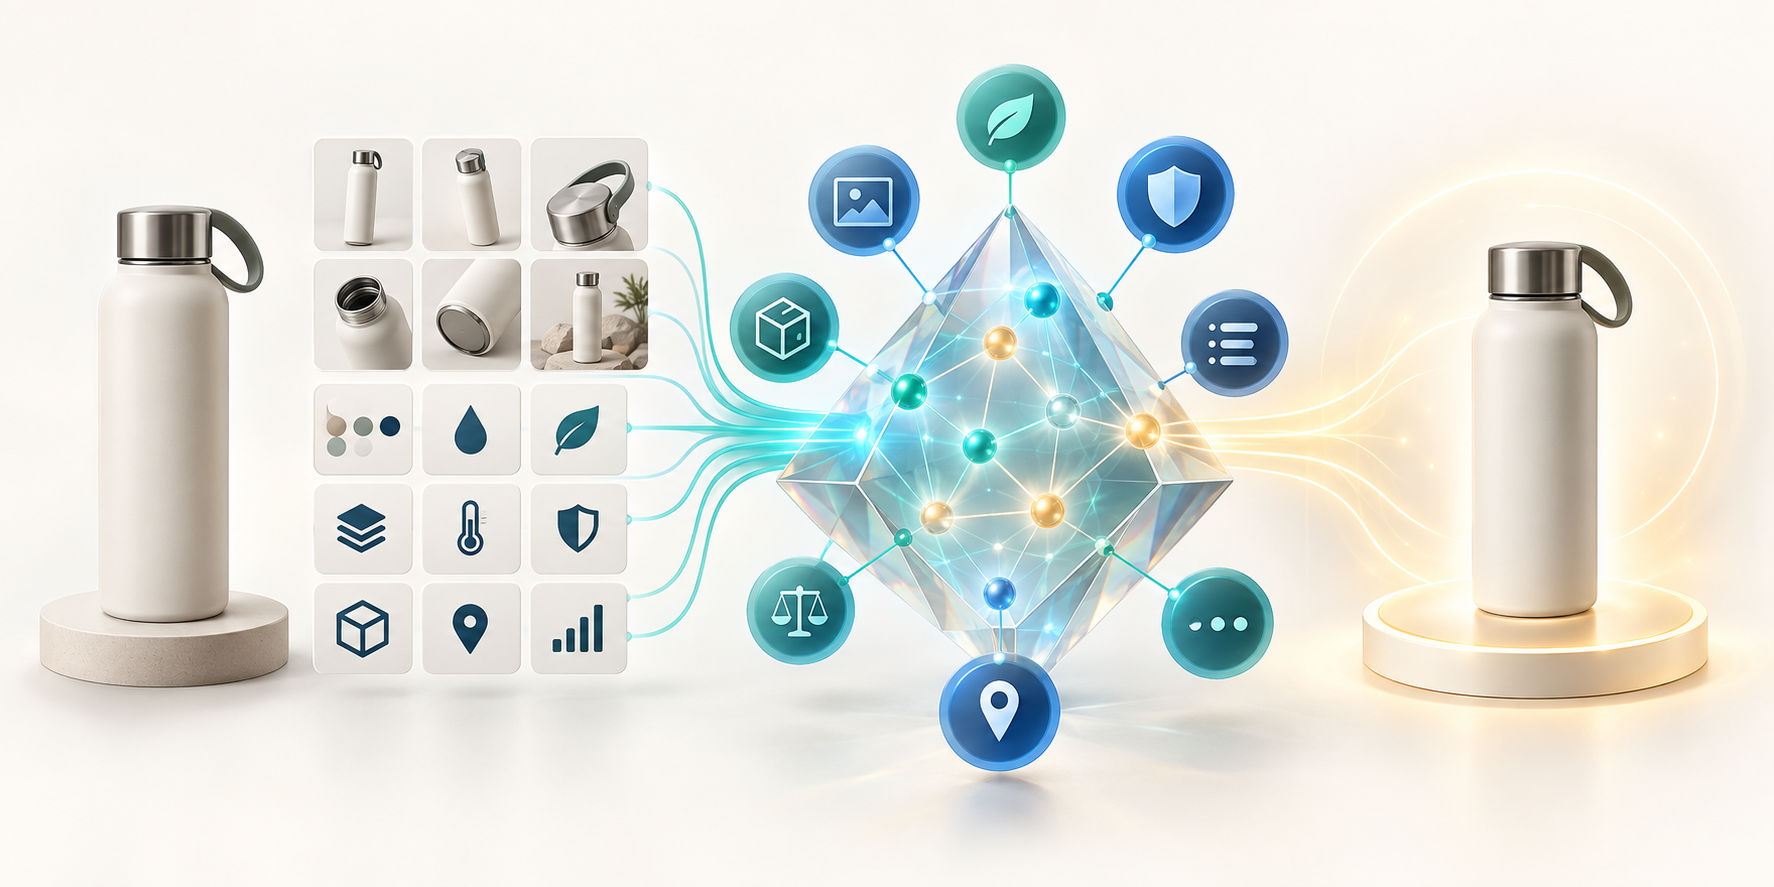
A shopping agent cannot infer a reliable recommendation from a product name and a persuasive description alone. Early testing of personal agents points to three practical visibility requirements: usable product catalogs, accessible websites, and clear statements about who each product is for.
Audit each commercially important product as a package of decision facts. The exact attributes will vary by category, but the agent should be able to resolve the following without reconciling conflicting pages:
- Identity: a stable product name, canonical URL, model or SKU, brand, and an unambiguous relationship between the main product and its variants.
- Audience fit: the user, situation, problem, or level of experience the product is designed for. State meaningful limitations when they affect suitability.
- Comparison attributes: the specifications, capabilities, materials, dimensions, compatibility details, or service limits a buyer would use to compare alternatives in your category.
- Commercial terms: current price and currency, availability, variant-level differences, applicable delivery information, returns, and warranty terms where relevant.
- Evidence: explanations, documentation, or independent validation that supports important claims instead of merely repeating them.
- Consistency: agreement among the visible product page, catalog or feed, structured data, policy pages, and any regional or variant pages.
“Who it is for” deserves its own content block. Avoid empty labels such as “for everyone” or “perfect for professionals.” Give the agent usable selection criteria: the problem solved, the expected environment, required compatibility, relevant experience level, and conditions that would make another option more suitable. Clear exclusions can improve recommendation quality because they reduce the chance that your product is matched to the wrong request.
Use Product and Offer structured data as a consistency layer, not as a magic entry ticket. Markup should express facts that a visitor can also verify on the page. If the visible page says one price, the catalog says another, and the structured data carries an expired offer, adding more schema will multiply ambiguity rather than remove it.
Variant handling needs particular care. A parent product page may describe the range, but decision-critical facts should remain attributable to the correct size, configuration, color, region, or service tier. An agent comparing two variants should not have to guess which price or specification belongs to which option.
Test accessibility from the agent’s point of view. Open the page in a clean session. Confirm that the product identity, fit, principal attributes, and commercial terms are available without signing in, accepting an unnecessary location flow, opening an image, or relying on an interaction that hides the only copy of a critical fact. Then compare the rendered page with the catalog and structured data field by field.
Finally, test a decision sequence rather than one branded prompt. Ask an assistant to identify products for a constrained use case, compare the candidates, explain which user each candidate suits, and verify the facts needed for a decision. Record where your product disappears and which unresolved criterion caused the exclusion. That point is a more useful optimization target than the wording of the final answer.
Publish and earn evidence that AI systems can resample
Once a product is technically legible, it still needs current evidence. AI-cited URLs were 25.7% fresher on average than conventional organic results in one large comparison: cited pages averaged 1,064 days old, versus 1,432 days for organic results. This does not mean that changing a date will improve visibility. It means the information environment being sampled by AI systems tends to include fresher material.
Refresh a page only when you can make it more useful. Add new product facts, answer newly important buyer questions, update obsolete comparisons, correct policy details, incorporate original data, or explain a material change. Keep the URL stable when the underlying resource remains the same, show a meaningful update date, and remove contradictions left by earlier versions.
Owned content is necessary but insufficient. In one citation analysis, owned media accounted for 13.7% of AI citations while earned media accounted for 84%. Journalism represented 27%, and paid content represented only 0.3%. These labels should not be treated as a simple exclusive pie chart, but the practical signal is clear: visibility often depends on credible pages you do not control.
Build an evidence map around the claims that determine selection. For each important prompt cluster, list the claims an assistant would need to justify: category membership, audience fit, distinctive capability, compatibility, comparative strength, limitation, and commercial availability. Then mark where each claim is supported:
- on a canonical owned page;
- in your product catalog and structured data;
- in independent reporting, reviews, comparisons, or other third-party material;
- nowhere reliable enough to support a recommendation.
The empty cells are your publishing and public-relations brief. Create original material where you control the underlying evidence. Seek independent coverage where an outside assessment would carry more value. Do not treat a press release as a durable substitute for either one; press-release citation share proved unstable and declined over the reported period, largely because ChatGPT cited releases less often.
Prioritize third-party coverage that contributes information of its own. A useful comparison, test, interview, dataset, or category explanation gives an AI system a reason to retrieve the page beyond the presence of your brand name. Repetition across low-value placements may expand the number of mentions without supplying better evidence for a recommendation.
Connect publishing back to measurement. When a prompt cluster lacks visibility, identify whether the missing input is product data, owned explanation, or independent evidence. Make the smallest substantive change that addresses that gap, record it in the changelog, and assess it across repeated runs. That gives you a testable operating cycle instead of a stream of unrelated content.
Key takeaways for your next visibility cycle
- Treat an AI response as one sample, not a permanent ranking. Report visibility as a rate and range across repeated runs.
- Separate brand inclusion, cited evidence, and commerce readiness. Each layer has a different failure mode and remedy.
- Build prompts around discovery, qualification, comparison, risk reduction, and purchase preparation rather than isolated keywords.
- Measure each AI platform separately. A blended score can conceal a platform-specific gain, loss, or citation shift.
- Make product identity, audience fit, comparison attributes, variants, and commercial terms explicit and consistent across the page, catalog, feed, and structured data.
- Refresh important pages with substantive information, not a changed date, and cultivate independent evidence for claims that influence selection.
Begin with one commercially important product family and the prompts closest to a decision. Establish a repeated baseline, inspect where the product falls out of the journey, and fix that exact gap. Once the page, catalog, schema, and outside evidence tell the same clear story, extend the system to the next product family.
References
- Search Engine Land — Your AI search visibility keeps changing: Here’s what to do about it
- Try Profound — The era of personal agents: Muse and Instinct

Leave a Reply