If Profound’s Gartner recognition has put the platform on your shortlist, treat that as a reason to investigate, not a reason to buy. The useful question isn’t whether the recognition sounds impressive. It’s whether Profound can help your team turn an AI visibility problem into a specific intervention and then show what changed.
That distinction matters because AI search programs often become reporting programs. Teams collect mentions, citations, prompts, and competitor comparisons, but the findings never become owned work with measurable consequences. The strongest interpretation of this recognition is that the market is beginning to demand a complete operating loop rather than another dashboard.
What the Gartner mention does and does not prove
Profound reports that it was named in Gartner’s 2026 Coolest Vendor Innovations in CRM alongside Canva, Decagon, dx0, and Twenty. That makes the company relevant to a serious evaluation of emerging AI marketing infrastructure.
It does not, by itself, establish that Profound is the best platform for your organization. A recognition is not a product benchmark, an implementation plan, or proof of business impact in your environment. It doesn’t answer questions about data coverage, workflow fit, measurement quality, integrations, governance, or the effort required to turn a recommendation into a deployed change.
The claim also comes from Profound’s own account of the recognition. That doesn’t make it unimportant, but it does set the correct evidence standard: use the mention to justify deeper due diligence, then make the product earn its place through your own workflow and data.
Don’t turn the recognition into an improvised ranking. The named companies address different parts of customer and marketing work, so their appearance together doesn’t mean they are interchangeable competitors. For your decision, the relevant comparison is between Profound and the other ways you could operate your AI visibility program, including internal analysis, specialist tools, agencies, and connected systems.
Why the insight-to-outcome loop matters in AI visibility
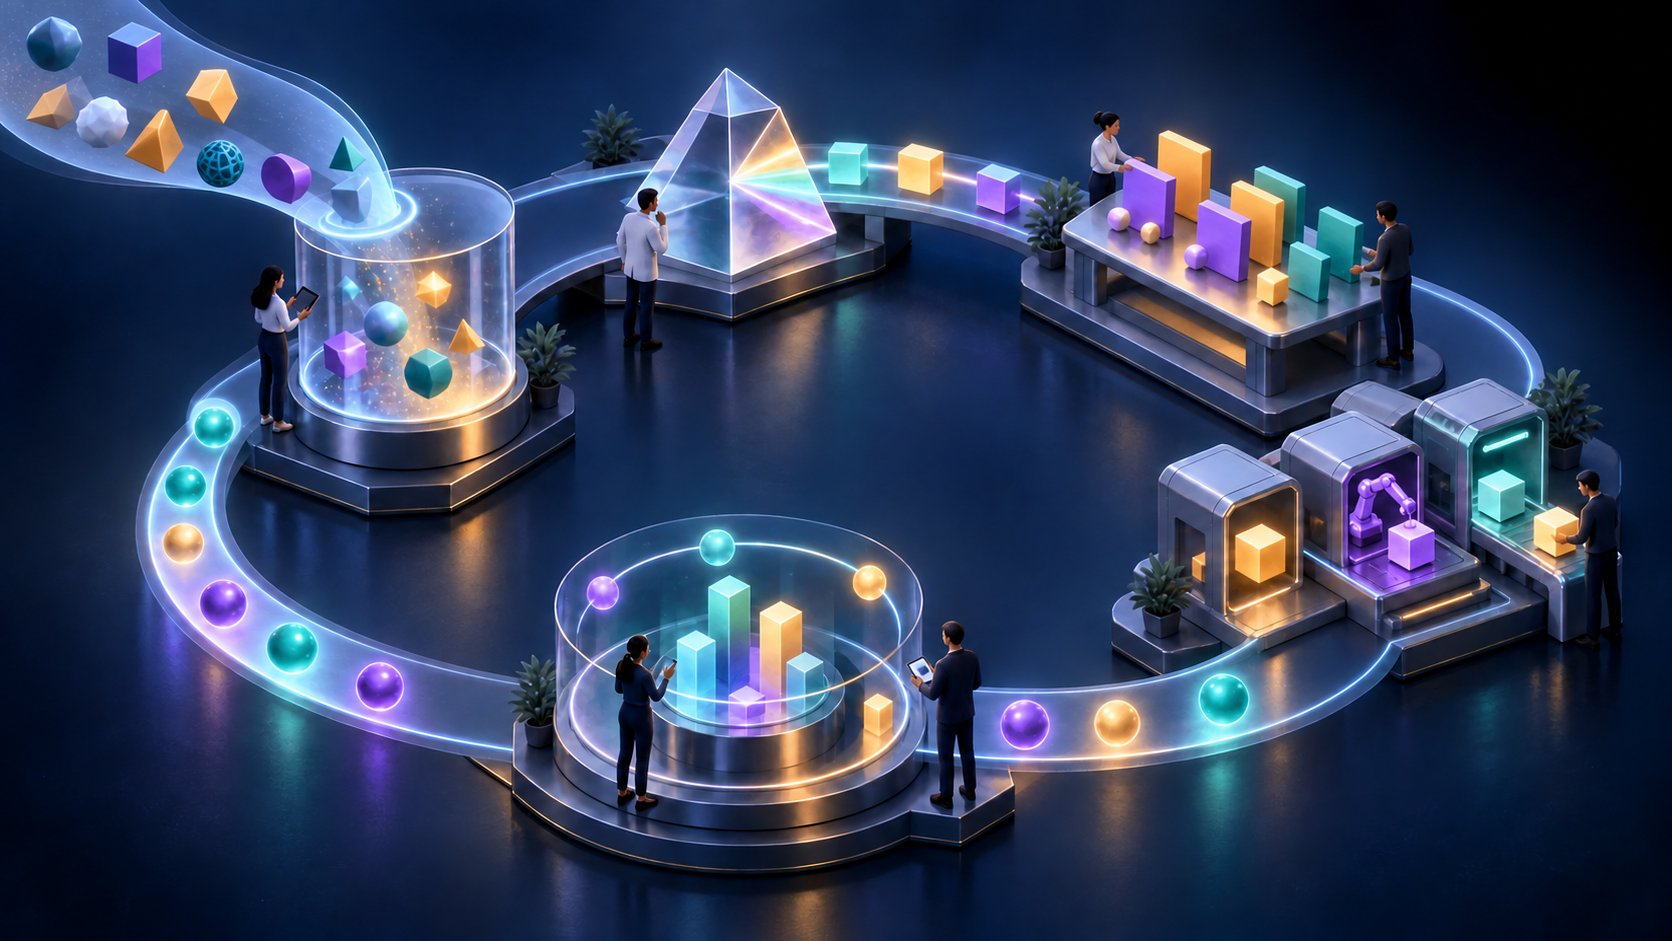
Profound interprets the recognition as evidence that marketers increasingly expect a closed loop from insight to action to measured outcome. That is a vendor-held interpretation, but it gives buyers a much better evaluation standard than feature counting.
AI visibility work starts with an observation: perhaps a brand is missing from an important answer, a competitor is cited more often, or a product is described inaccurately. None of those observations creates value on its own. Value appears only when the team can diagnose a plausible cause, assign a suitable intervention, publish or distribute the change, and measure the result against a defined baseline.
| Stage | Question your workflow must answer | Evidence to request |
|---|---|---|
| Insight | What exactly is happening, for which queries, audiences, markets, and AI experiences? | Saved answer-level observations, timestamps, query definitions, cited domains, and a clear distinction between collected data and inferred explanations. |
| Action | What should change, where should it change, and who owns the work? | A recommendation tied to the original observation, a destination such as a page or entity record, an owner, status, and change history. |
| Outcome | Did visibility, representation, referral activity, or a downstream business measure improve after the intervention? | A preserved baseline, comparable follow-up observations, deployment dates, and an outcome definition agreed before the work began. |
This framework also prevents a common category error. A suggested content revision, outreach task, or JSON-LD update is an action, not an outcome. Schema markup can make eligible facts easier for machines to interpret when it accurately represents visible content, but merely deploying markup doesn’t prove that an AI system used it or that customer behavior changed.
The CRM context is useful here. Customer and revenue consequences usually live downstream from visibility data. A credible closed loop therefore needs either native connections or documented handoffs between AI answer monitoring, content operations, technical implementation, analytics, and customer systems. It doesn’t all have to happen inside one platform, but the path between systems must be traceable.
Run this six-part evaluation before you choose a platform
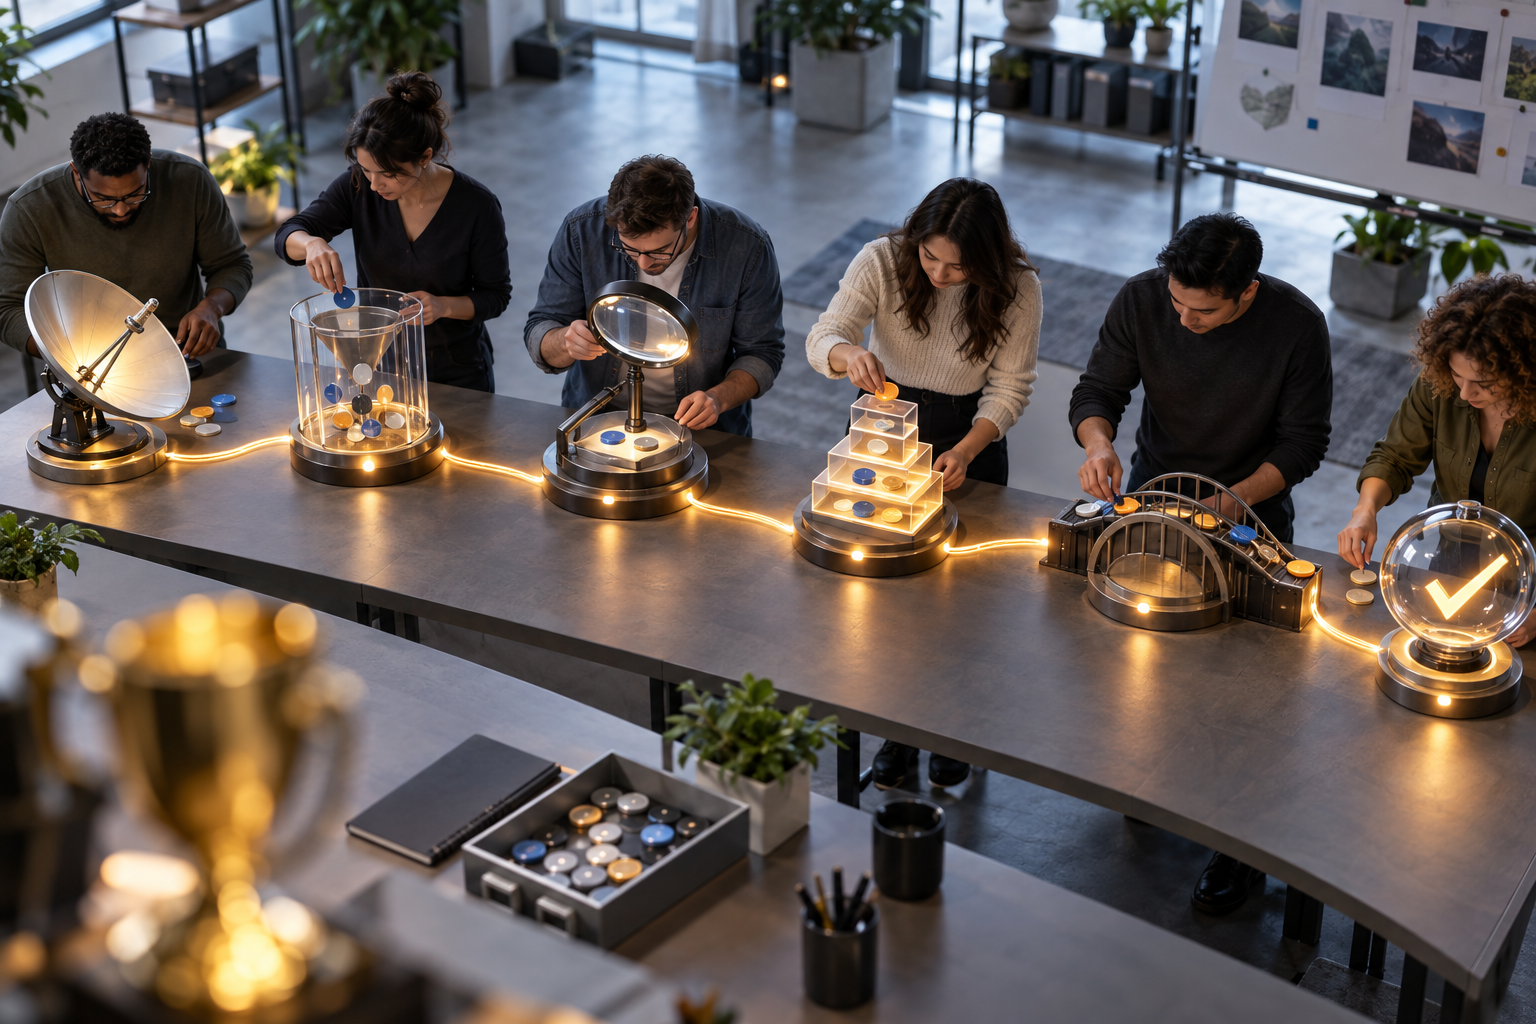
A polished demonstration can hide the hardest operational gaps. Use one real topic from your business and ask the vendor to follow it from observation through measurement. The following test works whether you are assessing Profound or another AI visibility system.
- Define your evaluation set before the demonstration. Include branded questions, category questions, comparison questions, and problem-led questions that matter to actual buyers. Specify the markets, languages, products, and AI experiences in scope. This prevents a vendor from selecting only the examples that make its interface look strong.
- Inspect the underlying observation. Ask to see the answer captured, when it was captured, the query used, and any citations or brand mentions detected. You need to know which elements are direct observations and which are scores, classifications, or interpretations produced by the platform.
- Challenge the diagnosis. Ask why the system believes a particular content, technical, entity, or authority gap caused the observed result. A useful platform should let your team examine the evidence behind a recommendation. Treat unexplained scores and confident causal claims cautiously.
- Follow the recommendation into an owned task. Identify who receives it, where the work happens, what approval is required, and how completion is recorded. If staff must copy findings manually into another system, count that labor and the risk of lost context when you compare options.
- Agree on the outcome before making the change. Decide whether success means more relevant mentions, more accurate representation, stronger citation presence, qualified referral activity, or a business result recorded downstream. Don’t substitute a platform’s convenient metric for the decision your organization actually cares about.
- Repeat the measurement with a change log. Preserve the initial query set and observation dates, record exactly what was deployed, and compare like with like. AI-generated answers can vary, so a single favorable response is weak evidence. Look for a pattern that is meaningful enough to justify the next round of work.
This evaluation does not require the vendor to promise perfect attribution. In fact, causal humility is a positive sign. Content changes, model behavior, competitor activity, retrieval choices, and outside coverage can all affect an answer. What you need is a system that preserves enough evidence to distinguish a plausible result from a convenient story.
Watch for the gaps that turn a closed loop into a slogan
The phrase “closed loop” sounds complete, but several missing links can make it operationally empty. Look for these gaps during procurement and pilot design:
- Undefined coverage: The platform reports a visibility score without showing which prompts, markets, models, or observation periods produced it.
- Diagnosis without evidence: It recommends creating or changing content but cannot connect the recommendation to a captured answer, citation pattern, or identifiable information gap.
- Action without ownership: Findings remain in the dashboard because no person, destination, approval state, or deadline is attached to them.
- Publishing without verification: A page or schema change is marked complete, but nobody checks whether the intended fact is visible, accurate, indexable, and consistent across relevant brand properties.
- Measurement without comparability: The follow-up uses different questions, filters, markets, or definitions, making apparent improvement difficult to interpret.
- Visibility without business context: The team celebrates more mentions without asking whether the brand is represented accurately, appears in relevant buying situations, or influences a meaningful downstream behavior.
You should also separate platform capability from implementation maturity. A product may support the required workflow while your organization lacks owners, publishing access, analytics connections, or an agreed measurement model. Buying more software will not repair those operating gaps. Document them before procurement so that platform limitations and internal limitations don’t get confused.
Key takeaways
- Profound’s Gartner 2026 recognition is a credible reason to include the company in an evaluation, not proof that it fits your stack or will improve your results.
- The most useful signal is the emphasis on connecting insight, action, and outcome. Test that complete path rather than comparing dashboard features in isolation.
- Use a real business topic during the demonstration and require answer-level evidence, an owned action, a deployment record, and a comparable follow-up measurement.
- Define success before the pilot. Mentions, citations, representation accuracy, referral activity, and business outcomes answer different questions.
- A closed loop can span several systems. What matters is preserved context, clear ownership, and a traceable line from observation to consequence.
Make the next step a workflow test, not a prestige vote
Choose one commercially important topic cluster and map its complete path: the questions people ask, the answers you can observe, the evidence behind any diagnosis, the person who can make a change, and the outcome you will examine afterward. Then ask Profound to demonstrate that path using your definitions rather than a prepared success case.
If the workflow remains traceable from observation to consequence, the recognition has helped you discover a platform worth piloting. If the trail disappears between dashboard insight and business action, the Gartner mention should not carry the decision. Your next move is to test the loop.
References
- Try Profound Blog — Profound Named in Gartner’s 2026 Coolest Vendor Innovations Report
- Try Profound Blog — Profound named in Gartner’s 2026 Coolest Vendor Innovations Report

Leave a Reply