You can rank well in traditional search, maintain a complete product feed, and still have no clear answer to a basic question: when someone asks an AI assistant what to buy, does your product appear?
AI product discovery tracking closes that gap. It records how individual products appear in shopping-oriented answers, separates visibility from accuracy, and gives you evidence for deciding what to fix. The goal isn’t to collect screenshots of flattering mentions. It’s to understand which SKUs enter the recommendation set, under which buying conditions, and what happens next.
Track the buying decision, not a single brand mention
A brand-level visibility score is too blunt for ecommerce. An assistant can mention your company while recommending the wrong product, an unavailable variant, or an item that doesn’t satisfy the shopper’s constraints. That mention looks positive in a dashboard but does little for the buyer.
Use the SKU, or the most stable product identifier available, as the primary measurement unit. Connect each observation to the exact prompt, platform, market, date, product variant, cited page, merchant, and answer text. This lets you distinguish a product-level problem from a broad brand problem.
The relevant measurement surface is also wider than one chatbot. Commercial monitoring is now offered for SKU-level visibility across ChatGPT Shopping, Alexa for Shopping, Perplexity, and Google AI Mode. Keep results separate by platform. Combining them into one score too early can hide the fact that a product is consistently discoverable in one environment and absent in another.
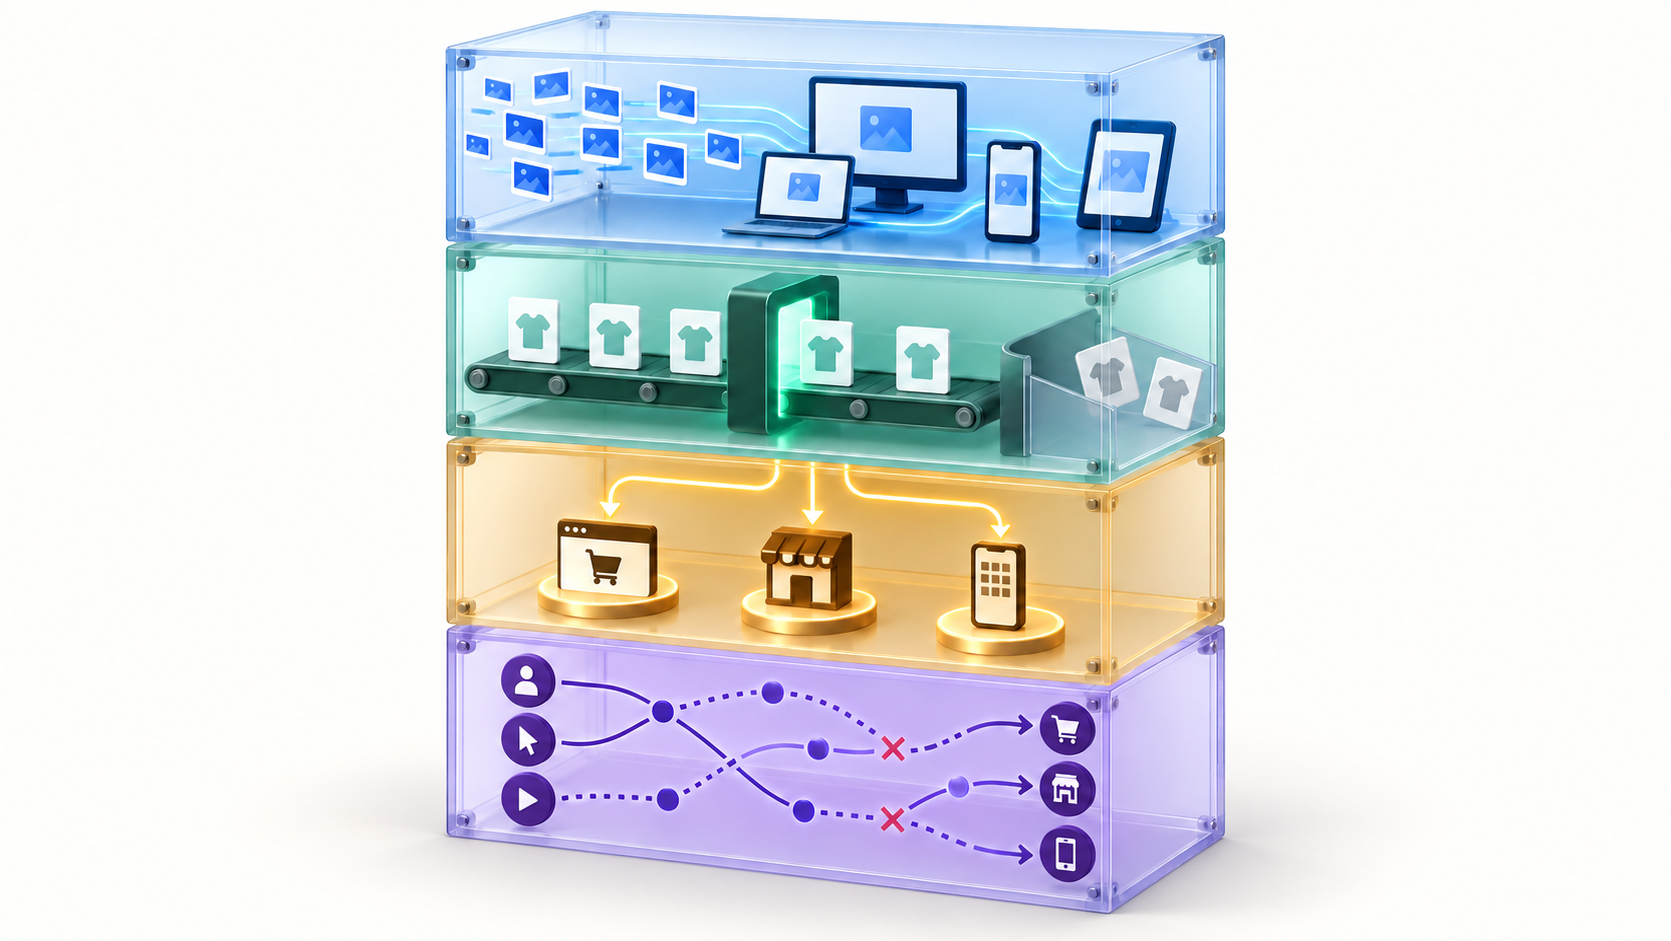
For every observed answer, classify five different outcomes:
- Presence: Did the brand, product family, or exact SKU appear?
- Prominence: Was it a primary recommendation, a secondary option, or a passing reference?
- Qualification: Did the answer connect the product to the shopper’s stated use case, budget, features, or constraints?
- Representation: Were the name, variant, attributes, availability, and other offer details accurate?
- Handoff: Did the answer provide a citation, merchant, product page, or another usable route toward purchase?
These outcomes answer different questions. Presence tells you whether the product entered the answer. Qualification tells you whether the system understood why it fits. Representation reveals whether the underlying product information is coherent. Handoff shows whether visibility can plausibly lead somewhere useful.
Build the measurement specification before choosing a tool
A tracker can automate collection, but it can’t decide what your business means by visibility. Write the measurement specification first. Otherwise, a vendor’s default prompts and scoring system will quietly become your strategy.
- Create a product identity registry. Give every tracked item a canonical name and identifier. Add brand names, model names, common aliases, parent-child variants, canonical product URLs, and the merchants authorized to sell it. This prevents a shortened model name or alternate spelling from being counted as a different product.
- Define the eligible product set for each prompt. A recommendation is only meaningful if the SKU could reasonably satisfy the request. If a prompt requires a feature the product doesn’t have, its absence isn’t a visibility failure.
- Group prompts by buyer intent. Keep category discovery, feature-led discovery, problem-led questions, comparisons, branded validation, and purchase-ready requests in separate groups. A product that performs well on branded prompts but disappears from category discovery has an acquisition problem that a blended score will conceal.
- Record the test environment. Store the platform, location or market setting, language, session state when controllable, device context when relevant, and collection time. If a condition can’t be controlled, label it unknown rather than assuming consistency.
- Freeze a core prompt panel. Run the same core prompts repeatedly so changes are comparable. Maintain a separate exploratory panel for emerging language, new use cases, seasonal needs, and questions discovered in customer research.
- Define what counts before collecting results. Decide how aliases, bundles, parent products, variants, repeated mentions, unordered lists, and cited merchant pages will be handled. Apply those rules to your brand and competitors alike.
Prompt wording needs particular care. “Best running shoe” and “running shoe for a wide forefoot on wet pavement” don’t represent the same decision. The second prompt supplies constraints that can change which products are eligible. Preserve those constraints in your reporting instead of collapsing everything into a generic keyword.
Don’t let exploratory prompts replace the fixed panel. New prompts improve coverage, but changing the entire prompt set between measurement periods destroys comparability. Use the fixed panel to detect movement and the exploratory panel to find new opportunities.
Use a scorecard that keeps visibility, accuracy, and outcomes separate
No single metric can represent the whole discovery journey. A useful scorecard shows where a product was eligible, whether it appeared, how it was described, and whether the answer created a usable path forward.
| Metric | How to calculate it | What it helps you decide |
|---|---|---|
| Eligible prompt coverage | Eligible prompts containing the tracked SKU divided by all prompts for which that SKU was eligible | Whether the product enters relevant recommendation sets |
| Recommendation share | Recommendations of the tracked product divided by all product recommendations in the same prompt set | How often your product appears relative to alternatives |
| Primary recommendation rate | Answers treating the SKU as a leading option divided by answers mentioning it | Whether mentions are prominent or incidental |
| Qualification rate | Mentions that accurately connect the SKU to the prompt’s constraints divided by all SKU mentions | Whether the system understands the product’s relevant use cases |
| Attribute accuracy rate | Verified product claims divided by all checkable claims made about the SKU | Whether conflicting or incomplete product information needs attention |
| Handoff rate | SKU mentions with a usable citation, merchant, or product destination divided by all SKU mentions | Whether discovery can progress toward consideration or purchase |
| Competitor overlap | Eligible prompts where your SKU and a named competitor both appear divided by eligible prompts where either appears | Which products compete in the same answer contexts |
| Downstream engagement | Observed visits and commerce events attributed to an identifiable AI handoff | Whether measurable discovery activity contributes to business outcomes |
The denominator matters. If you calculate coverage across prompts where a product couldn’t satisfy the stated need, you manufacture a weakness. If you count every brand mention as a product recommendation, you manufacture success. Keep the eligibility rules visible next to the score.
Preserve the underlying observations as well as the aggregate metrics. Store the returned product names, supporting language, cited URLs, merchants, competing products, and factual errors. When a score changes, you should be able to inspect the answers behind it.
Keep business outcomes in a separate layer. An AI mention isn’t a sale, and a sale that follows an AI interaction may not be fully attributable. Where a link, referral, or tagged destination is observable, connect it to product views, cart activity, and purchases. Where the handoff can’t be observed, report the outcome as unknown. Turning unknown activity into zero activity makes the dashboard look precise while reducing its usefulness.
Diagnose whether the failure is eligibility, selection, or representation
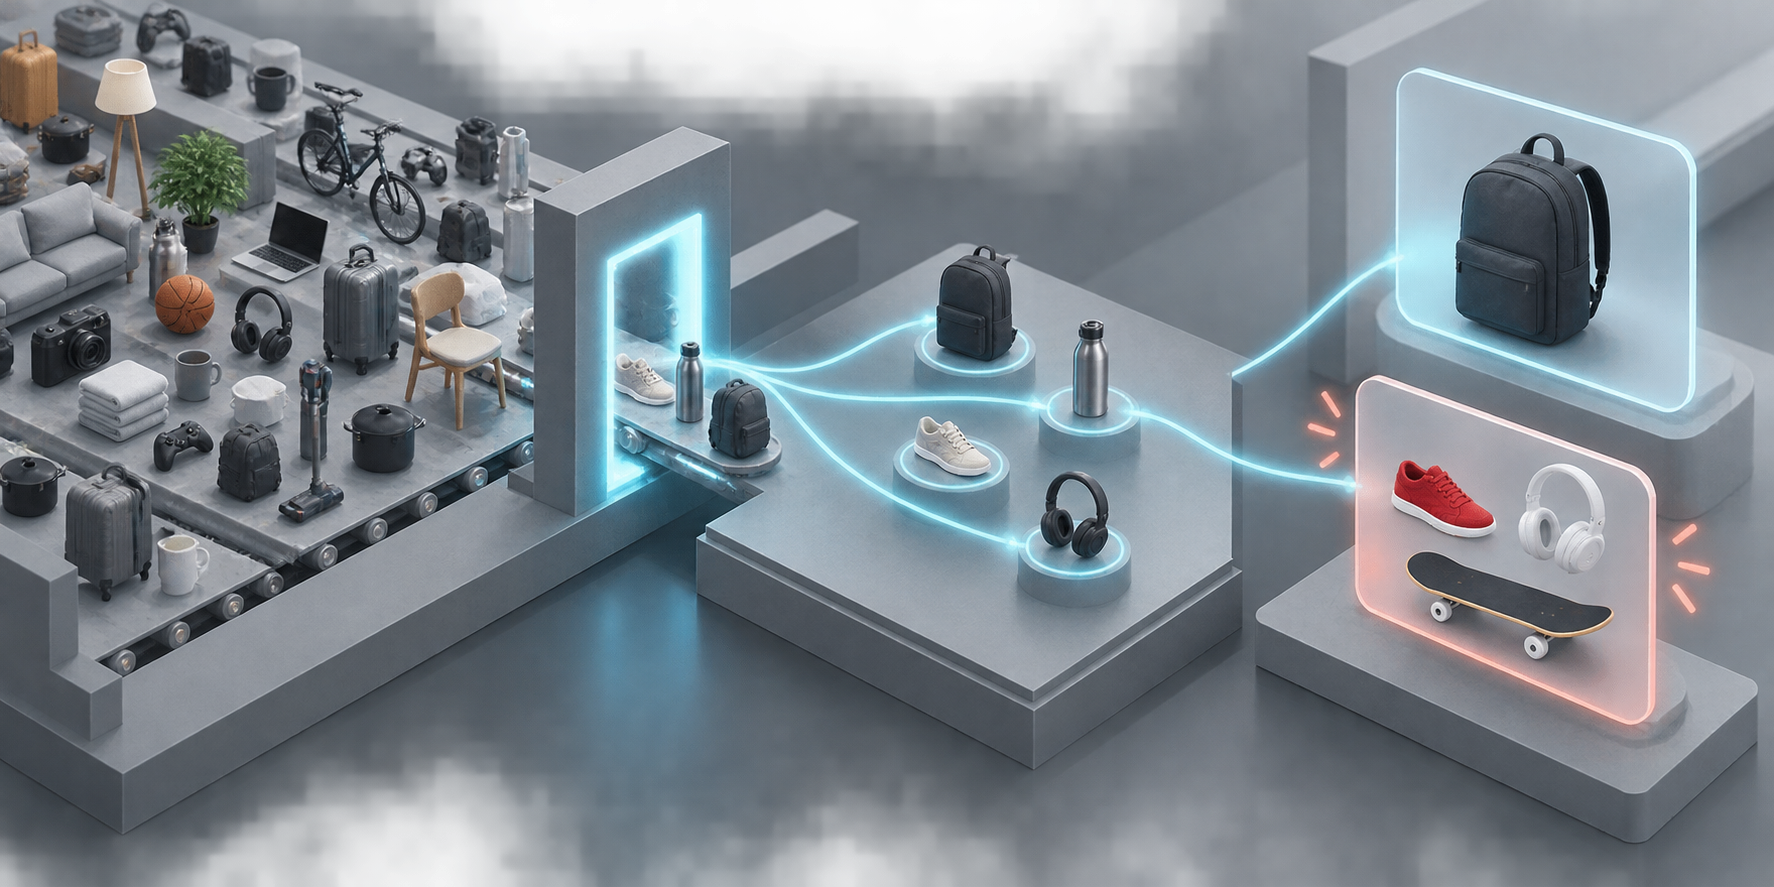
A missing product doesn’t tell you why it was omitted. The output gives you a symptom, not a causal explanation. Use it to form a testable hypothesis, then inspect the product information and competitive context that could support or contradict that hypothesis.
Eligibility failure: the product isn’t understood as a candidate
If the SKU is absent from non-branded prompts even though it genuinely meets their constraints, check whether its identity and qualifying attributes are expressed consistently. Review the visible product page, structured data, commerce feeds, variant records, category assignments, and merchant listings. Names, identifiers, sizes, colors, prices, availability, and feature claims shouldn’t contradict one another.
JSON-LD belongs in this audit, but don’t treat schema as a magic visibility switch. Its job is to express product information in a machine-readable form. It should match the visible page and the current offer data. If the markup describes a different variant or stale availability, adding more markup compounds the ambiguity.
Selection failure: the product is known but rarely recommended
A product may appear for branded validation prompts yet lose generic category, comparison, or problem-led prompts. That pattern suggests the system can identify the item but doesn’t consistently connect it to the buyer’s decision criteria.
Build a gap matrix from the actual answers. Put the prompt constraints in rows and the recommended products in columns. Record the reasons given for each recommendation. Then compare those reasons with claims your product can substantiate. If an important, verifiable attribute is missing from your product page or expressed only in an image, make it clear in the visible copy and structured product information. If your product doesn’t meet the criterion, don’t manufacture a claim to fit the prompt.
Representation failure: the product appears with incorrect details
Incorrect model names, mixed variants, stale offer details, or unsupported attributes are not positive visibility. Capture every checkable claim in the answer and compare it with the canonical record. Then locate conflicts across the pages, feeds, markup, and merchant data you control.
Correct the canonical product information before trying to increase mention volume. More exposure for a misrepresented SKU can send a shopper toward the wrong variant or create expectations the product can’t meet. Keep a record of the incorrect answer and the correction date so later observations can be evaluated against the change.
Turn tracking into a controlled optimization loop
AI outputs can vary between runs, so a single before-and-after query is weak evidence. Treat optimization as repeated observation around a documented change.
- Capture the baseline. Run the fixed prompt panel and preserve the complete responses, not just the calculated scores.
- Choose one failure class. Decide whether you’re testing product identity, attribute completeness, use-case relevance, comparison content, offer consistency, or another specific hypothesis.
- Change one information layer where practical. If you rewrite the page, replace the feed, alter structured data, and change merchant listings simultaneously, you may improve visibility without learning which correction mattered.
- Log the deployment. Record the affected SKU, URLs, fields, platforms, markets, and publication time. Include rollbacks and feed errors in the same log.
- Repeat the same core observations. Keep prompts, eligibility rules, and classification logic stable. Evaluate whether the direction of change persists across repeated collections.
- Compare unaffected products. Similar movement across changed and unchanged SKUs may indicate broad output variation or a platform-level shift rather than the effect of your work.
- Promote only durable findings. When an improvement continues to appear under the same measurement conditions, apply the lesson to other eligible products and keep monitoring for representation errors.
Report platform results independently and segment them by intent. A gain in branded prompts doesn’t prove stronger category discovery. A gain on one assistant doesn’t prove that another system changed. The useful reporting unit is the intersection of platform, market, intent group, and SKU—not an unsupported universal visibility score.
Competitor tracking should support diagnosis rather than imitation. Note which products recur, which buyer constraints they are associated with, what supporting pages are cited, and where their descriptions are inaccurate. This reveals the information standards operating within a prompt set. It doesn’t prove that copying a competitor’s wording, markup, or content structure will reproduce its visibility.
Key takeaways for a tracker you can trust
- Measure exact products and variants, not brand mentions alone.
- Define SKU eligibility for each prompt before treating an omission as a failure.
- Separate presence, prominence, qualification, factual accuracy, handoff, and business outcomes.
- Keep a stable core prompt panel for comparison and a separate exploratory panel for discovery.
- Preserve raw answers and cited destinations so every aggregate score can be audited.
- Use observed outputs to form hypotheses; don’t claim they reveal a ranking system’s hidden cause.
- Audit visible content, structured data, feeds, and merchant records for consistency when product identity or attributes are wrong.
- Evaluate changes through repeated observations and unaffected comparison products, not one favorable response.
Start with a narrow set of commercially important SKUs and the prompts for which they are genuinely eligible. Build the identity registry, freeze the core panel, and collect a baseline before editing anything. Your first useful result won’t be a universal visibility score. It will be a defensible answer to which product is missing, where it is missing, and what evidence you need to test next.
References