Tag: Analytics

  • Google Search Visibility Data Changed: What to Trust Now

    Google Search Visibility Data Changed: What to Trust Now

    Your SEO dashboard can look worse even when your site has not lost meaningful Google visibility. If total ranking keywords or SERP features suddenly collapse while clicks and leads remain steady, do not declare a ranking loss until you determine whether the site changed or the measurement system did.

    Google has changed how third-party tools can collect search results, altered an important result-depth parameter, and added first-party reporting for multimodal searches. The practical challenge is no longer choosing one perfect metric. It is knowing which question each metric can still answer.

    Three breakpoints changed the meaning of your trend lines

    A rank tracker can lose the ability to observe a result without your page losing its position. That distinction became more important after three Google changes:

    Each change makes large-scale collection more difficult or expensive. Losing num=100 means a provider can no longer request the first 100 results in one operation. Resolving passthrough links adds work for each affected result. A provider may respond by collecting fewer positions, sampling more aggressively, refreshing less frequently, or charging more for equivalent coverage.

    The distortion is most likely to appear deep in the results because positions below the first page are expensive to collect and usually less valuable to customers. This turns a platform’s total keyword count into two measurements at once: your site’s search footprint and the platform’s ability to observe that footprint. Treating it as a pure performance metric is now a category error.

    Recognize the signature of a collection failure
    Luminous result tiles pass through a scanning tunnel, where a blocked aperture causes only part of the continuing stream to reach the collection trays.

    A genuine visibility loss and a collection failure can both produce a falling graph. The distribution of the decline tells you which explanation is more plausible.

    For Reddit, Semrush data from May to June 2026 showed more than 60 million fewer ranking keywords and more than 13 million fewer SERP features. Those represented month-over-month declines of 25% and 21%, respectively, while estimated traffic remained steady. The loss also became progressively larger at deeper positions:

    Position bandChange from May to June 2026What the pattern indicates
    Position 1+16%The most visible rankings remained observable
    Top 3+11%High-value coverage did not collapse
    Positions 4-10-8%Loss began within the remaining first-page results
    Positions 11-20-28%Missing coverage accelerated beyond page one
    Positions 21-50-34%Deep-result visibility deteriorated sharply
    Positions 51+-35%The deepest rankings were the least observable

    This is not a universal benchmark. It is a diagnostic pattern. A real sitewide ranking collapse of that scale would not normally erase progressively more deep positions while expanding Position 1 and Top 3 counts and leaving estimated traffic unchanged. A depth-weighted decline points more strongly to reduced collection coverage.

    It can also make the surviving data look deceptively healthy. If a tool stops observing positions 40 through 80 but retains positions 1 through 10, the reported keyword total falls while the average position may improve. That apparent improvement is survivor bias, not necessarily better SEO.

    Use this sequence whenever a visibility graph breaks:

    1. Start with business outcomes. Check whether organic leads, sales, sign-ups, or other meaningful actions declined during the same period. Stable outcomes do not prove that rankings were stable, but they reduce the likelihood of a commercially significant collapse.
    2. Check Google Search Console clicks and landing pages. If third-party keyword totals plunge while clicks and the pages receiving those clicks remain broadly stable, investigate collection coverage before changing content.
    3. Split rankings into Position 1, Top 3, positions 4-10, 11-20, 21-50, and 51+. A drop concentrated in the deepest bands is more consistent with an observation problem than an across-the-board ranking loss.
    4. Compare branded and non-branded priority queries separately from the provider’s entire discovered keyword universe. A controlled set of commercially important queries is more useful for tactical decisions than a volatile inventory of every term the tool happened to find.
    5. Look for provider-specific discontinuities. If one platform changes abruptly while first-party clicks, outcomes, and another independent ranking view do not, label the event as a probable measurement break.
    6. Allow for mixed diagnoses. A collection change and a real traffic decline can happen together. If clicks, conversions, important landing pages, and high-ranking priority queries all deteriorate, continue the SEO investigation even if deep-result coverage also changed.

    Rebuild reporting around questions, not one visibility score

    No single visibility number can now support every decision. Give each reporting layer a defined job and state its limitation beside it.

    Reporting layerUse it to answerMain limitation
    Business outcomesIs organic search contributing qualified leads, sales, or other valuable actions?Demand, attribution, and conversion behavior can change independently of rankings
    Google Search Console clicks and pagesDid Google Search send traffic, and which landing pages received it?Reporting definitions and automated search activity can affect historical comparability
    Priority rank setDid a controlled set of branded, commercial, and strategically important queries move?Results vary by location, device, and the provider’s collection method
    Total keywords and SERP featuresWhere might new topics, competitors, or result features be emerging?These inventory metrics are highly exposed to collection-depth changes
    Multimodal performanceAre visual search experiences discovering the site’s content?It is a distinct search surface and does not replace conventional ranking or generative AI query data

    Your report also needs a measurement change log. Record the date, affected tool, affected metric, likely mechanism, position bands involved, and whether the provider changed its collection method. Put the annotation on the chart itself. A note hidden in a separate methodology document will not stop someone from treating the break as a performance event.

    Keep the original series, but do not draw an unqualified continuous trend across an incompatible baseline. Compare periods collected under the same method where possible. If that is not possible, present pre-change and post-change periods as separate regimes and label the comparison as measurement-affected. Do not invent a correction factor unless you have enough overlapping data to defend it.

    September 2026 year-over-year reports require particular care. Search Console impressions fell after num=100 disappeared in September 2025 because automated requests had previously generated impressions for deep results. That creates a suppressed comparison baseline, so double-digit year-over-year impression growth can appear without an equivalent improvement in actual performance.

    Do not present that percentage alone. Put absolute clicks, business outcomes, priority-query movements, and landing-page performance beside it. If only impressions rebound against the lower baseline, describe the result as affected by measurement history rather than evidence of equivalent SEO growth.

    Measure multimodal discovery as a separate search surface
    An object on a pedestal is examined through three separate pathways represented by a visual sensor, an acoustic sensor, and a magnifying lens.

    While third-party result coverage is becoming less complete, Search Console is adding a first-party view of visual discovery. Its multimodal search filter covers Google Lens, Circle to Search on Android, image uploads to Google Search, and Chrome’s Search this image action. The data is rolling out globally and appears when a site receives traffic from those experiences.

    Multimodal visibility should not be folded silently into a general visibility score. A person searching with an image is expressing intent differently from someone typing a conventional query, and the optimization work is often different. Track the surface separately so you can see whether visual discovery is growing, which pages participate, and whether that exposure leads to useful behavior.

    • Record when multimodal data first becomes available for your property. Do not interpret the first visible reporting period as the date your site first appeared in visual search.
    • Review the landing pages associated with multimodal activity. Check that their images are useful to the page’s purpose, accessible to crawlers, supported by clear nearby text, and described with accurate text alternatives.
    • Keep structured data faithful to the visible page. Schema can clarify products, organizations, articles, and other entities, but it should not describe an image, offer, or claim that users cannot find on the page.
    • Connect multimodal reporting to page-level outcomes. More visual discovery is interesting; it becomes valuable when the discovered pages attract relevant engagement or conversions.
    • Do not manufacture query-level precision where Google does not supply it. The generative AI search performance report still lacks click and query data, so a generative visibility narrative should acknowledge that blind spot.

    The new filter is an additional lens, not compensation for missing third-party keyword coverage. It answers a new question: whether people are finding your content through visual and multimodal behavior. It does not tell you that a disappearing position-50 keyword remained stable, and it does not provide the prompt-level attribution many teams want from generative search.

    Key takeaways for your next SEO report

    • A falling third-party keyword count is not, by itself, evidence of lost Google traffic.
    • A decline concentrated below positions 10 or 20 is more suspicious as a collection problem than a uniform loss across top rankings.
    • Clicks, landing pages, and business outcomes should determine the severity of the response; discovered keyword totals should support exploration, not act as the verdict.
    • January 2025, September 2025, and August 2026 belong in your reporting change log because each altered how search visibility could be observed.
    • September 2026 year-over-year impression growth may be inflated by the lower post-num=100 baseline from September 2025.
    • Multimodal reporting deserves its own baseline, goals, and page-level analysis. Do not merge it into conventional web or generative AI visibility without a label.

    Before your next report goes out, annotate the three collection breakpoints, split ranking data by depth, and place first-party clicks and business outcomes ahead of total keyword counts. Then establish a separate baseline for multimodal discovery. That small reporting redesign can keep a measurement change from triggering the wrong content rewrite, budget decision, or performance diagnosis.

    References


  • Google September 2026 Spam Update: An Action Plan

    Google September 2026 Spam Update: An Action Plan

    If your organic visibility moved sharply in September, your first job is not to rewrite the site. It is to determine whether the change is real, whether it is concentrated in search, and whether the timing actually fits Google’s spam update.

    The rollout window makes fast conclusions especially risky. Use the process below to separate an update-related pattern from tracking noise, seasonality, technical mistakes, and unrelated site changes. Then fix the smallest defensible set of problems instead of turning one traffic decline into several.

    Key takeaways

    • Google’s September 2026 spam update applies globally and to every language. A multilingual site should therefore be analyzed by country and language, not judged only by its English pages.
    • The rollout may take up to two weeks. Movement inside that window is useful evidence, but it is not a stable final result.
    • Google named no particular tactic, content format, industry, or production method as the target. Do not diagnose the loss from a theory circulating in the SEO community.
    • A credible diagnosis needs several signals to align: timing, an organic-search decline, a coherent group of affected pages or queries, and no stronger technical or business explanation.
    • Do not delete or rewrite hundreds of URLs at once. Preserve your baseline, stop expanding any clearly questionable pattern, and repair one coherent page group at a time.

    What Google confirmed, and what it did not

    Google released the September 2026 spam update to roll out globally, across all languages, for as long as two weeks. This is the fourth announced Google spam update of 2026, following another announced spam update in August.

    Those facts define the scope and timing. They do not identify a targeted tactic. Google did not specify that this release focuses on AI-generated text, affiliate pages, links, structured data, programmatic SEO, expired domains, or any particular industry. Treat confident claims about a single target as hypotheses until your own data supports them.

    Global scope also does not mean every market or section of your site must move in the same way. It means you cannot dismiss a loss merely because it occurred outside the United States or on non-English pages. For an international site, split the analysis by language, country, directory, hostname, and template. An unaffected English section is not a valid control for a declining Spanish, French, or Japanese section when all languages are in scope.

    The two-week window changes how you should interpret daily charts. A fall followed by a partial rebound may be rollout movement rather than recovery. A section that looks unaffected early in the window may move later. Keep monitoring, but reserve your strongest conclusion until the rollout has had time to finish and the data has begun to settle.

    Diagnose the loss before changing the site

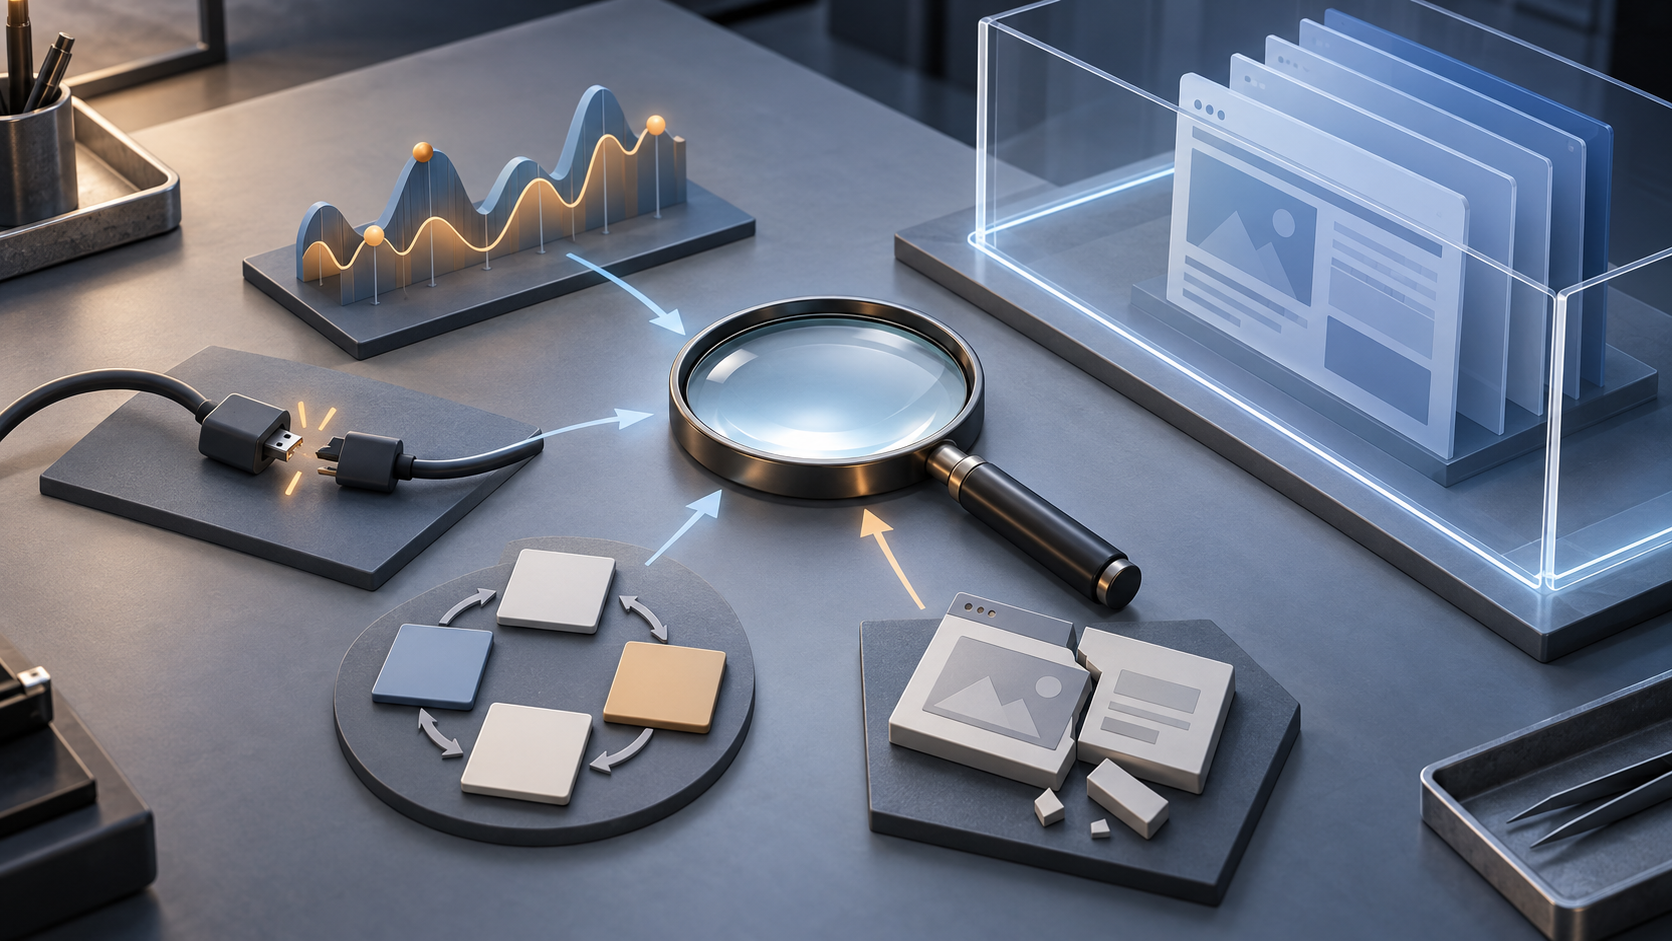
    Four visual evidence streams, including a search pulse, loose cable, seasonal cycle, and broken site component, converge beneath a magnifying lens.

    A decline that overlaps the rollout is correlated with the update; it is not automatically caused by it. Build a short incident record that another person could review without relying on your interpretation.

    1. Mark the monitoring window. Record the update announcement as the start of a provisional window lasting up to two weeks. Do not manufacture an exact completion date before Google confirms one.
    2. Confirm the channel. Separate organic Google traffic from direct, referral, paid, social, email, and other search engines. A fall in total sessions is not evidence of a Google spam-update impact if organic Google performance is stable.
    3. Check more than clicks. Review impressions, average position, landing-page traffic, conversions, and revenue or leads where available. Fewer clicks with stable visibility tells a different story from a broad loss of impressions and rankings.
    4. Segment until a pattern appears. Break results down by branded versus non-branded queries, page type, template, topic, language, country, device, and publishing cohort. Sitewide totals can hide a damaged directory or make one shrinking section look like a domain-wide event.
    5. Find the breakpoint. Identify when the change first becomes visible and whether it is abrupt, gradual, or intermittent. Compare comparable weekdays and established business cycles rather than treating the previous day as a complete baseline.
    6. Inspect competing explanations. Check the deployment log, analytics configuration, consent changes, robots directives, canonical tags, redirects, server availability, indexing controls, migrations, and major campaign changes. A technical release on the same date can imitate an algorithmic loss.
    7. Assign a confidence level. Label the update as likely, possible, or unsupported. Use likely only when timing, channel, affected cohort, and the absence of a stronger alternative explanation all line up.

    Do not let one rank tracker make the diagnosis

    A rank tracker can reveal where to investigate, but a single keyword set may overrepresent one template, location, device, or search intent. Confirm the pattern with first-party search and business data. If tracked rankings fall while impressions, landing-page traffic, and conversions remain normal, you do not yet have evidence for a damaging sitewide hit.

    Likewise, a visibility chart from a third-party platform cannot tell you why movement occurred. Use it to locate affected query groups, then inspect the corresponding URLs and their actual performance.

    Audit the recurring pattern behind affected pages

    Spam-related risk is rarely diagnosed well by staring at the homepage. Start with the cohort that lost visibility. Export its URLs, classify them by template and purpose, and compare them with a genuinely similar cohort that remained stable. The useful question is not whether every declining page is imperfect. It is what the declining pages repeatedly do that the stable pages do not.

    Test purpose, substance, and consistency

    • Purpose: Does each URL satisfy a distinct user need, or do many pages exist mainly to capture slight variations of the same query?
    • Substance: Does the page provide an answer, evidence, comparison, tool, process, or decision support that is specific to its topic? A long template is not automatically substantial.
    • Differentiation: If you remove the product name, city, profession, or keyword from several pages, is most of the remaining material identical?
    • Claim support: Can a reader tell where important claims, numbers, quotations, and recommendations came from? Correct unsupported assertions instead of decorating them with more optimization.
    • Page promise: Does the visible content deliver what the title and main heading promise, or does it delay the answer and redirect the reader toward another page?
    • Editorial reality: Do bylines, review dates, author credentials, and update labels reflect a real process? Do not use trust signals as ornamental fields.
    • Markup consistency: Does structured data accurately describe what a visitor can see? Repair contradictions between schema and the page, but do not expect markup to compensate for weak or duplicative content.
    • Destination value: Does the page stand on its own, or is it mainly a search landing page that funnels visitors elsewhere without resolving the stated need?

    These questions are diagnostic checks, not a claim that September’s update targeted any one of them. Look for concentration. If a questionable characteristic appears equally across stable and declining pages, it is a weaker explanation than a characteristic heavily concentrated in the losing group.

    Do not confuse AI assistance with a diagnosis

    Google did not identify AI-generated content as the target of this update. That means an AI label, by itself, cannot explain a decline. Do not mass-delete content merely because software helped produce it.

    Audit the output instead. Check whether it is accurate, specific, internally consistent, properly supported, and useful for the query. Look for repeated structures that produced shallow pages at scale, but apply the same test to human-written and AI-assisted material. The operational risk is publishing weak patterns repeatedly, not the name of the drafting tool.

    The same restraint applies to AEO, GEO, and schema work. Correct markup that overstates or misrepresents the visible page. Preserve markup that accurately describes strong content. Replacing valid JSON-LD, adding more entities, or expanding FAQ markup is not a sensible first response when the evidence points to duplicative landing pages or unsupported claims.

    Make changes in an order you can evaluate

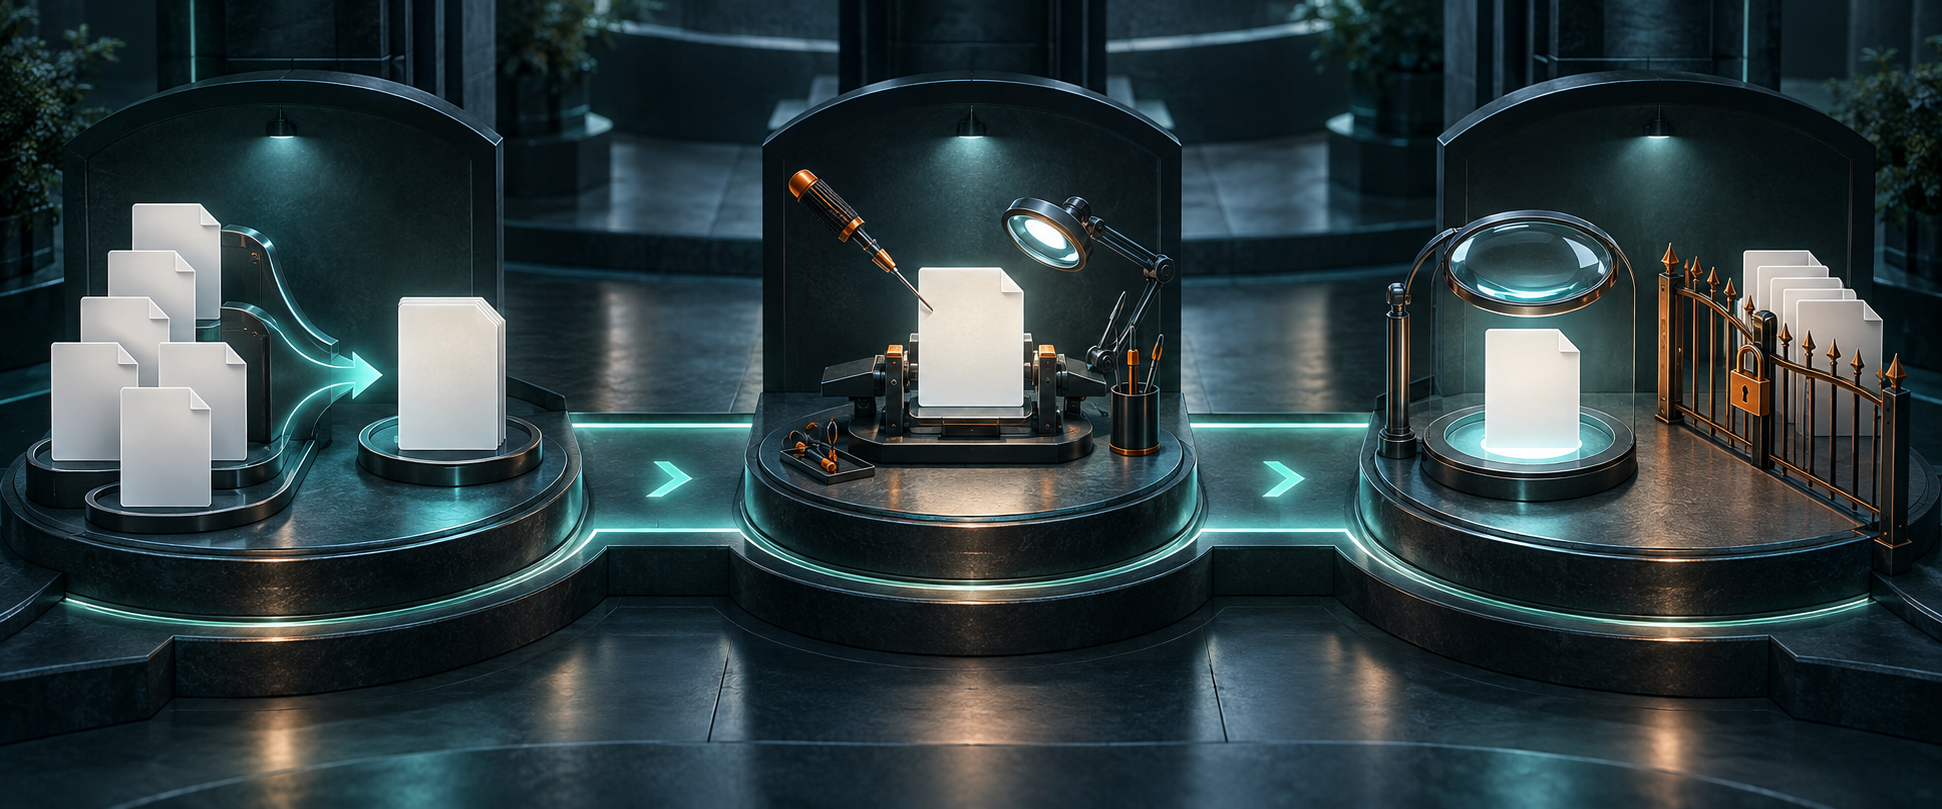
    Three separated workstations show duplicate page cards being consolidated, one page being repaired, and the result being monitored before further changes.

    Your remediation plan should reduce risk without erasing the evidence. Bulk edits during a moving rollout can make the site impossible to diagnose, and bulk deletion can remove pages that still attract qualified visitors or conversions.

    1. Preserve the baseline. Save the affected URL set, query groups, language and country segments, key metrics, and relevant deployment history. Record the date and owner of every subsequent change.
    2. Stop expanding a suspect pattern. Pause new publication from a clearly questionable template while you investigate. This limits exposure without requiring an immediate sitewide deletion.
    3. Fix the clearest cohort first. Choose one logically related group, such as near-duplicate location pages or unsupported comparison pages. Give each URL a defensible purpose: improve it substantially, consolidate genuine overlap, or remove it when it serves no user need.
    4. Protect technical integrity. Before consolidating or removing URLs, map internal links, redirects, canonicals, indexability, and sitemap entries. Content remediation that creates redirect chains, broken links, accidental noindex directives, or contradictory canonicals adds a second problem.
    5. Review visible content and structured data together. Facts, authorship, dates, products, FAQs, ratings, and organization details should agree across the page and its markup. Correct the underlying page first when both are wrong.
    6. Separate completed work from observed outcomes. Maintain a change log with the affected template, URLs, reason, and date. Do not call an immediate fluctuation a recovery simply because it followed an edit.
    7. Evaluate the same segments again. After the rollout window, compare the affected cohort with its previous baseline and with a similar stable cohort. Watch search visibility and business outcomes; improvement in one vanity metric is not enough.

    If you already know that the site relies on deceptive or manipulative tactics, stop those tactics rather than waiting for perfect attribution. For ambiguous quality problems, work in coherent batches. A controlled repair produces cleaner evidence than rewriting every title, paragraph, internal link, and schema object at once.

    Your next move should be a one-page incident record: the provisional rollout window, affected segments, alternative causes checked, suspected recurring pattern, immediate containment action, and the first page cohort to review. By the time the rollout settles, you will have a decision trail and a repair plan instead of a folder of screenshots and competing theories.

    References


  • How to Segment Multi-Location SEO Data for Real Insight

    How to Segment Multi-Location SEO Data for Real Insight

    Your network’s organic traffic is up, yet several location managers say calls or bookings are down. Both can be true. A few high-volume markets can lift the total, while new locations can add traffic and conversions simply because they were absent from the earlier comparison period.

    You need reporting that separates portfolio expansion from SEO improvement, shows whether a problem is local or widespread, and points to the next action. That requires a stable location data model, like-for-like cohorts, and several connected views rather than one network-wide dashboard.

    Start with the decision, not the dashboard

    Segmentation becomes useful when each view answers a specific question. If you begin by collecting every available metric, you will usually end up with a crowded report that describes movement without explaining it.

    Write down the decisions the report must support before building filters or charts. For a multi-location SEO program, the practical questions usually include:

    • Are established locations growing, or is total growth coming from newly opened locations?
    • Is a decline limited to one location, shared across a metro, or visible throughout the network?
    • Is the change specific to Organic Search, or are all website channels moving in the same direction?
    • Are people finding the business through its name, or discovering it through services, products, cities, neighborhoods, and local-intent searches?
    • Is search visibility weakening, or are users still finding the location but taking fewer actions afterward?
    • Which locations deserve intervention, and which high performers contain a practice worth applying elsewhere?

    Each question needs a different denominator. A regional executive may need the total contribution from every location. An SEO manager diagnosing page quality needs location-page traffic and conversions. An analyst judging ongoing performance needs only locations that existed in both comparison periods.

    Keep three kinds of network measure visible: the portfolio total, the typical location, and the distribution across locations. The total shows business impact. A median or peer-group benchmark shows whether the typical branch is improving. The distribution reveals whether the result is broad or concentrated in a few outliers. None can safely replace the others.

    Build a location spine before joining SEO metrics

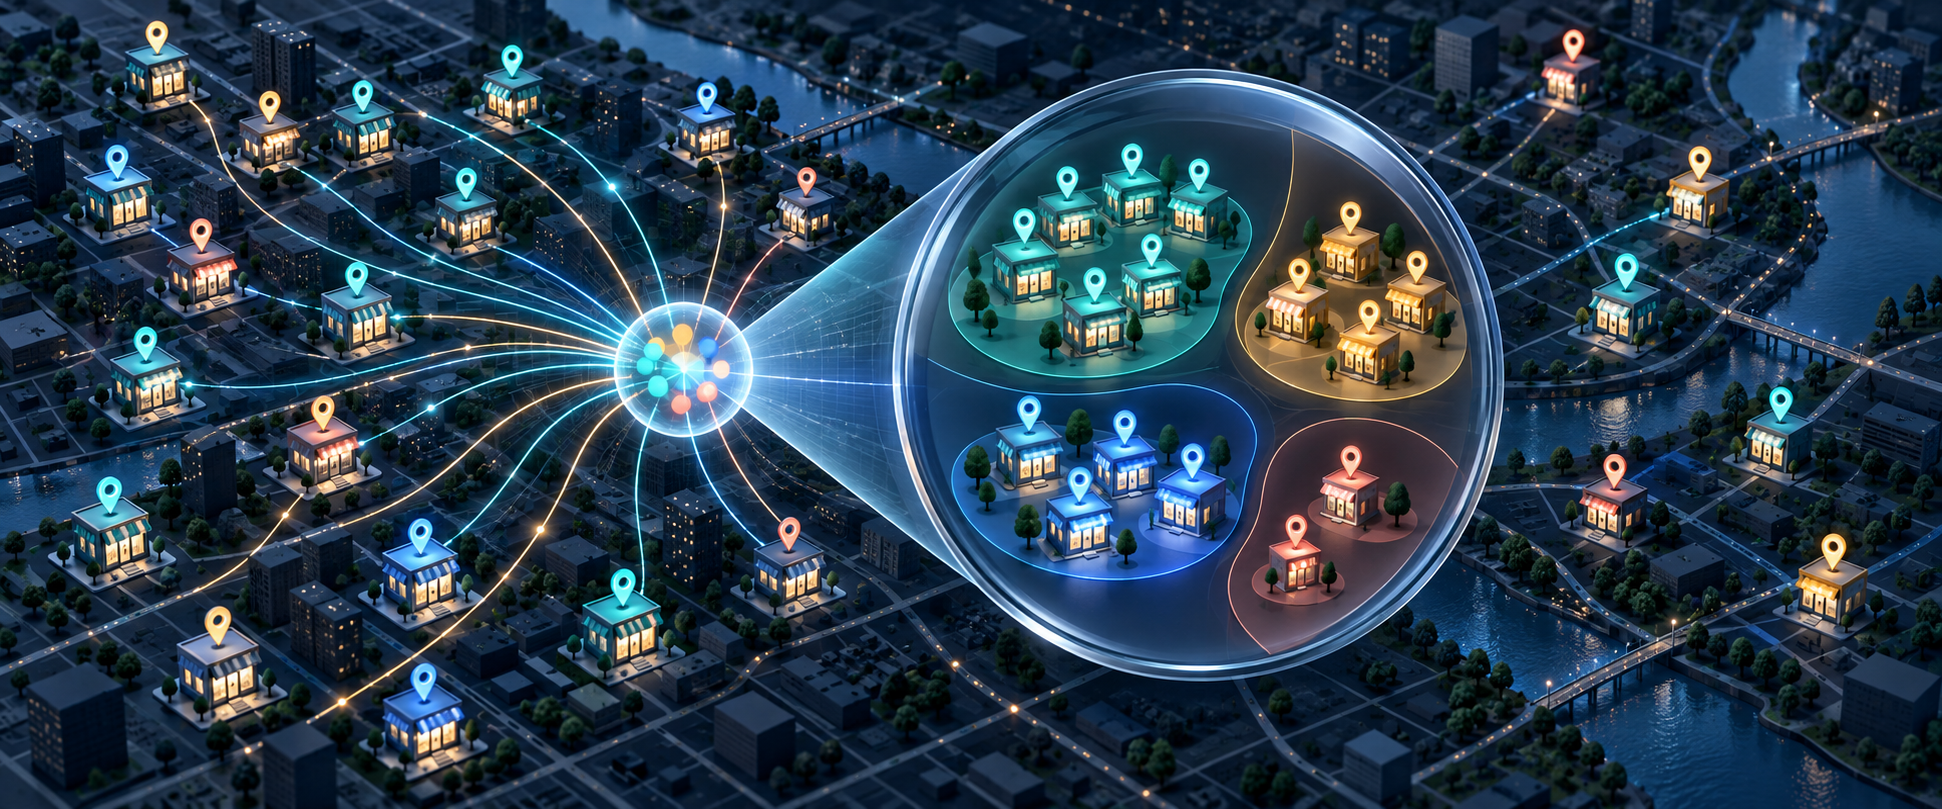
    An isometric central spine connects storefront and map-pin modules while colored data streams join the matching locations.

    Your reports need one durable record for every physical location. Think of this as the location spine: a controlled table that connects analytics, landing pages, search performance, local rankings, Google Business Profile data, reviews, and business events.

    Do not use a display name as the primary key. Names change, abbreviations vary, and two branches can share similar labels. Assign an immutable internal location key, then map every platform identifier and URL to it.

    FieldWhat it controlsWhy it matters
    Location keyThe permanent join key across systemsPrevents renames or URL changes from splitting one location into several records
    Operating statusOpen, temporarily unavailable, closed, relocated, or otherwise excludedKeeps inactive locations from being mistaken for SEO declines
    Lifecycle datesOpening, closing, relocation, and material expansion datesDetermines whether a location belongs in a like-for-like comparison
    Geographic hierarchyProvince or state, region, metro, city, and neighborhood where relevantSupports realistic market comparisons and isolates geographic patterns
    Location URL setCurrent page plus any mapped service or market pagesConnects page-level analytics and search visibility to the right branch
    Profile identifierThe associated Google Business Profile recordConnects Search and Maps visibility, actions, and review context
    Peer groupLocations with reasonably similar market conditions or operating modelsAvoids judging a small market against a major metro with different demand and competition
    Comparison cohortComparable, opening, closing, relocated, or exceptionSeparates organic improvement from changes in the location portfolio

    Decide how a relocation should be represented before the reporting period starts. If the business considers it the same branch but its page, profile, catchment area, or local competitors changed materially, preserve the permanent location key while flagging the affected periods as an exception. That retains operational history without pretending the local search environment remained constant.

    URL mapping needs the same discipline. A location may receive organic traffic through its main location page, a city page, or service pages associated with that market. Define which URLs belong to which reporting view. Do not silently attribute every site visit from a city to the nearest branch unless that allocation rule is explicit and defensible.

    If URL structure permits a simple landing-page filter, use it. If it requires regular expressions, test the expression against known included and excluded URLs before interpreting the results. Then compare the filtered inventory with the location spine. A broken filter can create a persuasive but false outlier, especially after a migration or naming change.

    Read every location through four evidence layers

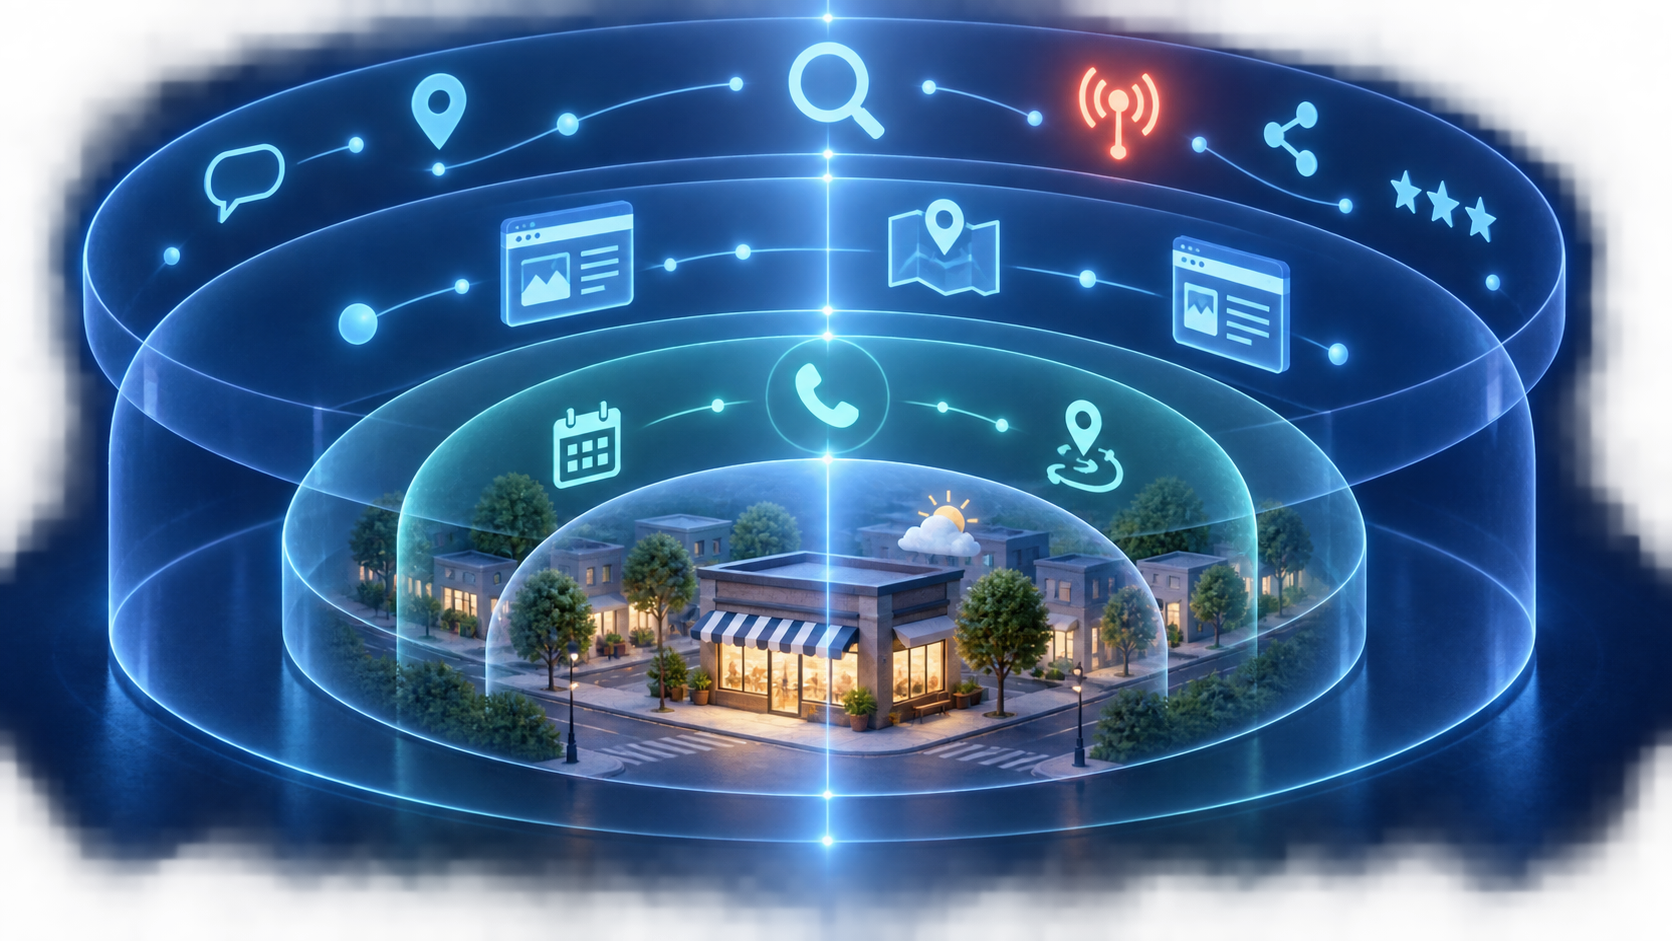
    A storefront is surrounded by four translucent layers of discovery, engagement, conversion, and neighborhood-context symbols.

    No single metric explains local SEO performance. Treat analytics, search visibility, local rankings, and profile activity as connected evidence layers. When they disagree, the disagreement is diagnostic information rather than a reason to choose the most flattering metric.

    Evidence layerUseful measuresQuestion it answersCommon misreading
    Website analyticsOrganic traffic, engagement, conversion events, and corresponding all-channel measuresWhat did visitors do after reaching the site?Treating a tracking or sitewide conversion change as an organic-search problem
    Search visibilityClicks, impressions, click-through rate, average position, landing pages, and queriesHow often did the location appear, and what searches produced exposure or visits?Reading a network average without separating locations or query intent
    Local rank trackingCity-, service-, ZIP-code-, and near-me visibility, including grid or radius viewsWhere can a searcher actually see the location for priority local intent?Using one point ranking as though every searcher in the market sees the same result
    Google Business Profile and reviewsSearch and Maps views, website clicks, calls, directions, review volume, recency, and ratingWhat happened directly in local results, and what may affect user response?Assuming every profile action carries the same business value

    Website behavior: compare organic with the whole site

    Use GA4, Adobe, or the analytics platform already trusted by the business to review location-page traffic, engagement, and conversion events. Define a conversion in operational terms. Depending on the business, that may be an appointment request, booking, submitted form, phone call, or another recorded action.

    Always place the Organic Search view beside the equivalent all-channel view. If conversion activity falls across every channel, investigate tracking, page behavior, availability, or a broader business change before blaming rankings. If the decline appears only in organic traffic, continue into search visibility and query data.

    Do not average location conversion rates to create a network rate. Add the relevant conversion counts, add the corresponding traffic totals, and calculate the rate from those combined values. A simple average gives a small branch the same influence as a high-volume location and can distort the network result.

    Search visibility: split discovery from existing demand

    Use Google Search Console and Bing Webmaster Tools to examine clicks, impressions, click-through rate, average position, pages, and queries by location. Compare month over month for recent movement and year over year where the business needs a seasonal comparison.

    Classify queries with documented rules. At minimum, separate branded searches from non-branded discovery. The branded group should include the approved business and brand terms relevant to the network. The non-branded group can then be divided into service or product intent, explicit city or neighborhood terms, and near-me intent where the available query data supports that classification.

    This distinction changes the diagnosis. Rising branded clicks can reflect stronger existing awareness without proving that a location has become easier to discover for its services. Improving non-branded visibility is a clearer sign that the location is reaching people who have not already decided which business to find.

    Keep query taxonomy rules stable between periods. If you add brand terms or change classification logic, mark that change in the report. Otherwise, a reporting edit can look like a shift in customer behavior.

    Where a webmaster platform exposes AI-search performance, keep it as a clearly labeled view with its own available measures. Do not blend unlike visibility or traffic fields into a conventional web-search total. The label should tell the reader what the platform actually measured.

    Local rankings: measure the searcher’s geography

    Track priority local-intent searches at the city or ZIP-code level. In competitive markets, use grid or radius reporting to see how visibility changes as the searcher’s position changes. A branch may be prominent near its address and nearly absent elsewhere in the same metro; one rank captured from one point cannot represent that pattern.

    When visibility moves, inspect more than the recorded rank. Check whether the results page layout changed, whether a new search feature appeared, and whether new competitors entered the result set. A lower click-through rate with stable rankings may begin to make sense once you see that the page surrounding the listing has changed.

    Profile actions and reviews: interpret them by business model

    Google Business Profile activity covers visibility and actions that can occur before a user reaches the website. Review Search and Maps views alongside website clicks, calls, and direction requests. Calls may be more meaningful for a service business, while directions may better reflect intent for an in-person location. Choose the primary action based on how that business actually converts demand.

    Place review volume, recency, and average rating beside profile performance. These measures do not prove why a user acted, but they can explain why locations with similar visibility receive different engagement. Treat them as context to investigate, not as automatic causation.

    Separate portfolio growth from comparable-location growth

    A clean year-over-year report needs more than a date comparison. It needs a population definition. If the network opened, closed, relocated, or expanded locations, the locations contributing to the current period may not match those in the prior period.

    Publish separate views instead of forcing every branch into one percentage:

    • All-network view: every valid location in each period. Use this to show the total portfolio outcome.
    • Comparable-location view: only locations with a stable identity and valid data in both periods. Use this to judge underlying performance.
    • Opening cohort: locations that began operating after the earlier period. Use this to show incremental contribution without calling it like-for-like growth.
    • Closing cohort: locations that ceased operating or left the portfolio. Use this to explain lost contribution.
    • Exception cohort: relocations, material expansions, URL migrations, tracking interruptions, or other changes that make a direct comparison misleading.

    The all-network view answers, “How much organic activity did the business receive?” The comparable view answers, “Did the established footprint improve?” Those are both legitimate questions, but they are not interchangeable.

    Calculate comparable change from the same location keys in both periods. For an additive measure such as clicks or conversions, sum the current values for the matched cohort and compare them with the prior values for that exact cohort. For a rate such as click-through rate, combine the cohort’s numerators and denominators first, then calculate the rate. Do not average the individual location percentages.

    Also show each location’s contribution to the network change. A portfolio gain can be concentrated in a few branches even when most locations are flat or declining. Conversely, one closure or market-specific loss can pull down an otherwise healthy comparable cohort. Geographic and lifecycle segmentation exposes those drivers before they become a misleading network narrative.

    Apply cohort rules consistently across traffic, visibility, profile actions, and conversions. If the analytics table excludes openings but the profile table includes them, the dashboard will invite comparisons between different populations. Put the cohort definition and any exceptions directly in the report so a stakeholder can see what the result represents.

    Turn outliers into a prioritized SEO work queue

    A location is not an outlier merely because it trails the network average. Market demand, competition, maturity, and the number of nearby branches all affect the opportunity. Compare locations within relevant geographic and operating peer groups first: region, metro, city, or another grouping that reflects the business.

    This matters most when a network spans very different markets. A small city should not inherit the traffic target of a major metro. A dense metro with several branches may also have an internal differentiation problem: location pages can compete for the same broad city terms when neighborhood language would better distinguish their service areas.

    Use the pattern across evidence layers to choose the first investigation:

    Observed patternWhat to inspect nextPotential action
    Impressions and local rankings fall in one marketPriority queries, Map Pack visibility, new competitors, demand, page coverage, and profile accuracyCorrect listing data, strengthen the relevant location page, or build justified market-level coverage
    Impressions hold while clicks and click-through rate fallActual result pages, layout changes, new features, competing listings, and how the page or profile is presentedImprove the search-facing information that is within your control and monitor the changed result environment
    Organic traffic holds while conversions declineEngagement, conversion tracking, landing-page behavior, and all-channel conversion trendsRepair measurement or address the page-level conversion issue before treating it as a visibility problem
    Profile views hold while calls, clicks, or directions declineProfile completeness, business information, reviews, and whether the selected action still reflects customer behaviorUpdate the profile, address review weaknesses, or revise the primary action used for evaluation
    Several branches in one metro weaken while the wider region is stableShared competitors, overlapping pages, local rankings, neighborhood differentiation, and market conditionsUse a metro-level plan rather than repeating isolated page edits at every branch
    Every channel declines for the same locationTracking, operating status, availability, page function, and broader market or business changesResolve the cross-channel cause before assigning an organic SEO fix
    One peer location substantially outperforms comparable branchesQuery mix, page completeness, profile quality, review context, competition, and local involvementIdentify a transferable practice, then validate it in another appropriate peer market

    These patterns are starting points, not verdicts. Stable impressions with falling clicks, for example, can indicate a result-page change, weaker presentation, or a different query mix. Open the location, page, and query views before selecting the remedy.

    Every item in the work queue should contain the affected location or cohort, the observed evidence, the working explanation, the next check or change, an owner, and a review point. Keep observation and hypothesis in separate fields. “Non-branded impressions declined” is an observation. “A new competitor displaced the location” remains a hypothesis until the result and competitor data support it.

    Prioritize with three considerations: potential business impact, confidence in the diagnosis, and whether the team can act on it. A high-volume location with a clear profile error may deserve attention before a larger but poorly understood fluctuation. A strong outlier can be just as valuable as a weak one if it reveals a repeatable page, profile, or market practice.

    Key takeaways

    • Use a permanent location key to connect pages, analytics, search visibility, rankings, profiles, reviews, and lifecycle events.
    • Report the all-network portfolio and the comparable-location cohort separately; they answer different business questions.
    • Compare Organic Search with all-channel performance before assigning an organic cause to a conversion decline.
    • Split branded demand from non-branded discovery, and keep the classification rules consistent between periods.
    • Benchmark locations against relevant peers, then use cross-layer patterns to decide what to inspect and change.

    Start by creating the location spine and three saved views: all-network, comparable locations, and lifecycle exceptions. Then select one underperforming market and trace it from query visibility through page behavior and profile actions. Your reporting has done its job when that trail produces a specific, owned action rather than another network average.

    References


  • Marketing Investment and Incrementality: A Practical Guide

    Marketing Investment and Incrementality: A Practical Guide

    You have a campaign with a healthy return on ad spend, a partner claiming attributed sales, and a finance team asking whether the next dollar should stay. Those facts can all coexist even when the campaign created little new demand. If the budget decision rests on attribution alone, you can reward the channel that was best at standing near an existing sale.

    Incrementality gives you a better basis for that decision. It estimates what changed because of the investment, counts what the investment really cost, and separates a profitable growth engine from activity that merely collected credit. The same discipline works for paid media, commerce networks, SEO and GEO programs, content operations, and AI automation.

    Start with the decision, not the dashboard

    Attribution and incrementality answer different questions. Attribution assigns credit among observed touchpoints. Incrementality asks whether the outcome would have occurred without the marketing activity. That distinction matters because a person exposed to an ad may have purchased anyway.

    Measurement approachQuestion answeredUseful forMain failure mode
    AttributionWhich touchpoint received credit for an observed conversion?Reporting journeys, managing campaigns, and diagnosing channel interactionsCrediting marketing for demand that already existed
    IncrementalityHow much did the outcome change because the investment was present?Budget allocation, forecasting, renewal decisions, and growth planningUsing a weak or contaminated comparison as the counterfactual

    You can never observe the same customer at the same moment both with and without an intervention. A credible test therefore constructs a counterfactual: a comparable estimate of what would have happened without the investment. The quality of that estimate determines whether your lift number is useful.

    Write the decision before choosing a metric. A practical decision statement is: For this eligible population, will this investment produce enough additional business value over this comparison to clear our economic hurdle? Every term needs an operational definition.

    • Eligible population: The customers, accounts, regions, queries, pages, or workflows that could realistically receive the intervention.
    • Investment: The exact spend, campaign, content program, partner, tool, or process change being evaluated.
    • Primary outcome: One business result that can change the decision, such as completed purchases, qualified opportunities, retained customers, or accepted production output.
    • Comparison: A randomized holdout, matched market, staged rollout group, or another defensible estimate of the no-investment outcome.
    • Economic hurdle: The minimum contribution, payback, capacity gain, or other finance-approved result required to justify the investment.

    Use an outcome hierarchy

    A campaign can improve a platform metric without improving the business. Prevent that confusion by assigning each metric a role before launch:

    • Primary outcome: The result that decides whether to invest, such as incremental contribution or qualified pipeline.
    • Guardrails: Results that must not deteriorate, such as margin, return rates, lead quality, publishing accuracy, or customer retention.
    • Diagnostic metrics: Impressions, clicks, rankings, citations, AI visibility, engagement, and other signals that help explain why the primary outcome moved.

    Transaction proximity can make measurement cleaner because the path from exposure to purchase is shorter. It does not, by itself, prove causation. Closed-loop purchase data can show that an exposed customer bought; only a credible comparison can estimate whether the exposure changed that customer’s behavior.

    Count the full investment, including hidden AI labor

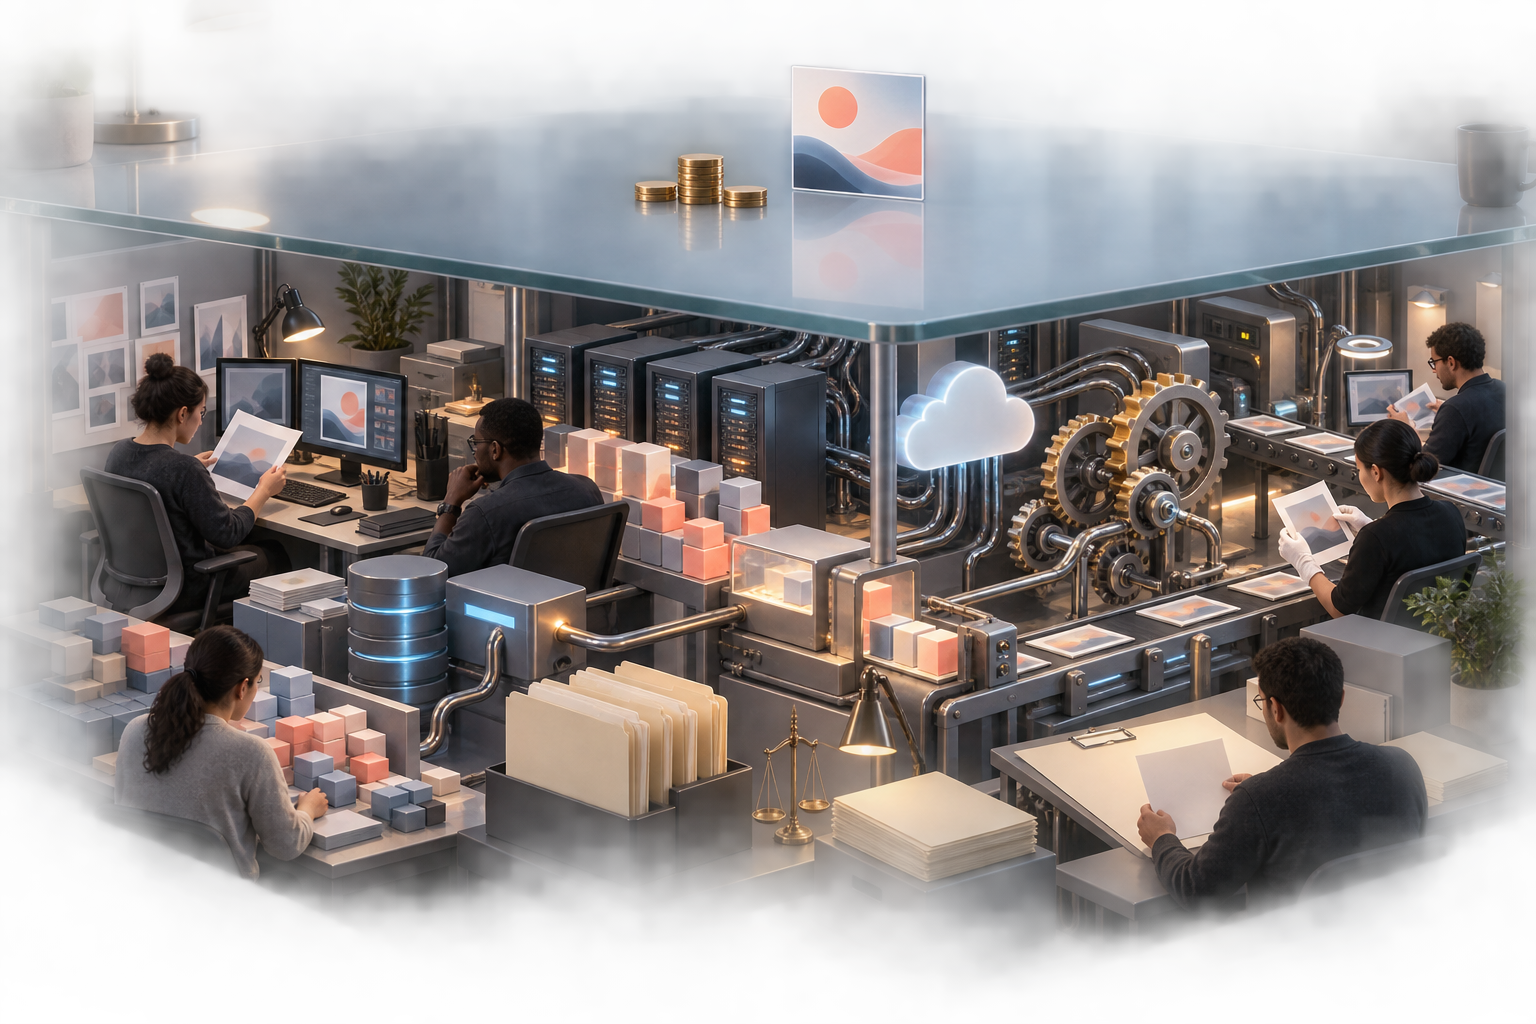
    A transparent worktable reveals human review, computing infrastructure, data preparation, and quality control beneath a small set of visible campaign costs.

    Incremental revenue is not enough to justify an investment. You need to compare incremental economic value with the complete cost of producing it. Media spend and software subscriptions are visible. Learning time, quality control, data preparation, creative production, agency support, and operational rework often are not.

    The visibility gap is especially pronounced with AI initiatives. An NBER working paper surveying about 6,000 senior executives across four countries found that 69% used AI for less than one hour a week and 28% did not use it at all. Decision-makers who are distant from production can see a subscription price and a fast output without seeing the workflow construction, failed runs, checking, correction, and governance underneath it.

    Build an investment ledger with separate lines for:

    • Media, platform, network, and technology fees.
    • Creative, content, landing-page, feed, and schema production.
    • Agency, contractor, analytics, engineering, and legal or compliance support.
    • Data acquisition, identity resolution, tagging, storage, and measurement.
    • Internal planning, campaign operations, stakeholder review, and reporting time.
    • Training, workflow design, prompt or automation development, and rollout support.
    • Quality assurance, fact-checking, editing, exception handling, and rework.
    • Incremental fulfillment, support, discounts, returns, and other variable costs created by the additional business.

    For an AI-enabled marketing investment, run a 30-day labor audit before defending its efficiency. Have the people doing the work record time in four distinct categories: learning tools, operating workflows, checking and repairing outputs, and editing or fact-checking long-form work. Explain that the audit measures the process rather than individual performance. Anonymous aggregation can reduce the pressure to underreport.

    Separate setup costs from recurring costs. A pilot may look expensive because it includes workflow design and training that will not recur at the same level. The reverse also happens: an impressive demonstration can omit the continuing cost of review, maintenance, data cleanup, and failures in daily use. Show both the learning-period economics and the expected steady-state economics instead of averaging them into one reassuring number.

    Keep the financial calculation legible

    Do not hide the business case inside one blended percentage. Show these lines separately:

    • Incremental outcome: The observed result minus the estimated no-investment result.
    • Incremental net revenue: Revenue attributable to the incremental outcome, after cancellations, discounts, or returns where applicable.
    • Incremental contribution before marketing: Incremental net revenue minus the variable costs required to deliver it.
    • All-in marketing investment: The cash and labor costs required to run and measure the intervention.
    • Net incremental value: Incremental contribution before marketing minus the all-in marketing investment.

    If finance uses a different contribution or payback definition, use that definition consistently. Do not silently substitute platform revenue for finance-approved value. Show opportunity cost alongside the calculation: what work, campaign, or capacity did this investment displace? That cost may not belong in the formal ratio, but it belongs in the decision.

    Run a test that can change the budget

    Two matched miniature commercial districts are compared, with an abstract marketing intervention applied to one district while the other remains untreated.

    A useful incrementality test is designed backward from a decision. It does not begin with whatever report a platform happens to provide. Before money moves, document the following:

    1. Choose one primary decision metric. Secondary metrics can explain the result, but they must not replace the primary outcome after the data arrives.
    2. Define the unit of assignment. Depending on the investment, this may be a customer, household, account, region, page group, topic cluster, or production workflow.
    3. Select the strongest practical comparison. Randomized holdouts are usually the cleanest option when assignment and exposure can be controlled. Matched geographies, staggered rollouts, or time-based switchbacks can be useful when individual randomization is not feasible.
    4. Set the observation window and detectable effect in advance. Base test size and duration on the normal outcome rate, expected variability, and the smallest lift worth acting on. A monthly meeting date is not a measurement rationale.
    5. Record contamination and operational changes. Cross-channel exposure, audience overlap, internal linking, promotions, pricing changes, stock constraints, sales activity, and mid-test optimizations can all make the comparison less credible.
    6. Pre-commit to actions. State what result will lead you to scale, repair, retest, or stop. This prevents a favored program from receiving a new success definition after it misses the original one.

    Choose the comparison design that fits the investment

    • Randomized audience holdout: Use when you can assign eligible people or accounts to treatment and control and can observe the business outcome for both groups. Watch for people receiving the campaign through another platform or device.
    • Geographic holdout: Use when media exposure or commercial activity can be separated by market. Match markets on relevant baseline behavior and account for local promotions, distribution, competitors, and seasonality.
    • Staggered rollout: Introduce the program to comparable units at different times. This can suit SEO, GEO, content, platform, or workflow changes when a permanent control is impractical. Keep rollout order from simply mirroring business priority or existing performance.
    • Switchback design: Alternate treatment and comparison periods when simultaneous holdouts are unavailable. This is vulnerable to day-of-week effects, seasonality, carryover, and changes in demand, so the time blocks must reflect how quickly the intervention’s effect starts and fades.
    • Pre/post comparison: Use only when stronger designs are unavailable. Demand, competition, algorithms, distribution, and pricing can change between periods, making a simple before-and-after result easy to misread.

    Match the outcome to the type of investment

    InvestmentPossible assignment unitDecision-grade outcomeCommon contamination risk
    Commerce or retail mediaCustomer, household, or geographyCompleted purchases, incremental contribution, or new-customer valueExposure through overlapping networks or promotions
    Paid search or paid socialAudience cell, customer, or geographyQualified conversions, contribution, or pipelineRetargeting and cross-device exposure
    SEO, AEO, or GEO programEligible page group, topic cluster, market, or rollout waveQualified organic demand, leads, or attributable business valueInternal-link, brand, and domain-level spillover
    AI marketing automationTask type, workflow, team, or rollout waveAccepted outputs, time per accepted output, throughput, or defect-adjusted capacityUnrecorded manual work and people switching between old and new processes

    For SEO, AEO, and GEO work, rankings, mentions, citations, and visibility are valuable diagnostics. They are not automatically incremental business outcomes. If visibility is the strategic objective, define it that way before the program begins. If revenue, leads, or qualified demand is the objective, do not substitute visibility after launch because it improved first.

    Report uncertainty with the point estimate. A positive estimate surrounded by a wide range of plausible outcomes is not the same as dependable positive lift. If the plausible range includes both no effect and an economically valuable effect, the result is inconclusive. That does not prove the investment failed, but it also does not justify describing success as established.

    Statistical significance and economic significance are also different. A precisely measured lift can still be too small to cover the investment. A larger but uncertain estimate may deserve another test rather than an immediate scale-up. Let the economic hurdle and the cost of making the wrong decision determine the next step.

    Turn lift into allocation rules and partner requirements

    An incrementality result becomes valuable when it changes allocation. Put each tested investment into one of four decision states:

    • Scale: Lift is credible, net incremental value clears the agreed hurdle, and guardrails remain acceptable. Increase investment in controlled steps and remeasure because response can weaken as reach expands.
    • Repair: The activity creates additional outcomes, but fees, labor, margin, lead quality, or operational burden make the economics unattractive. Fix the cost structure or targeting before buying more volume.
    • Learn: The result is inconclusive, but resolving the uncertainty is worth more than the cost of another test. Improve assignment, sample size, tracking, or exposure separation rather than repeating the same design.
    • Stop or reallocate: Credible evidence shows little lift, negative value, unacceptable guardrail damage, or no realistic path to trustworthy measurement. Continuing because a platform reports attributed conversions compounds the original error.

    Partner selection should support this process. For commerce media, compare options across scale and purchase intent, measurement, activation, working relationship, and proximity to the transaction. A large reachable audience is less valuable when it is passive or difficult to measure. A smaller, high-intent audience can be more useful when exposure, purchase, and comparison data are clear.

    Any evaluation framework supplied by a media network should organize your diligence, not serve as independent proof of lift. Before committing budget, ask each prospective partner:

    • How are treatment and comparison groups created?
    • Can the comparison group still receive ads through another placement, network, campaign, or device?
    • Which outcome is primary, and when is that outcome considered complete?
    • Are reported sales new to the business, shifted from another channel, accelerated from a later date, or merely attributed to the exposure?
    • How are repeat purchasers, new customers, cancellations, returns, and duplicated conversions handled?
    • Will the partner report uncertainty, group sizes, exclusions, and failed assignments as well as the lift estimate?
    • Can your analysts inspect sufficiently detailed data and methodology to reproduce or challenge the conclusion?
    • Will campaign optimization remain stable during the test, or will the platform change delivery in ways that undermine the comparison?
    • If customer lifetime value is used, which portion is observed and which portion is forecast?
    • Can the test be repeated after spend, audience, creative, or season changes?

    No partner needs to solve every marketing problem. One may offer strong purchase signals and limited reach; another may provide scale but a weaker counterfactual. Build a portfolio around the jobs each partner can actually perform, then compare the incremental value of those jobs against their all-in costs.

    Use a one-page investment memo

    Give leadership a decision document rather than a dashboard tour. Keep it to six lines of argument:

    1. Decision: The budget, renewal, rollout, or allocation choice that must be made.
    2. All-in investment: Cash, labor, setup, recurring operations, measurement, and material opportunity cost.
    3. Test: Eligible population, assignment unit, counterfactual, primary outcome, window, and known contamination.
    4. Result: Incremental outcome and its uncertainty, with attributed performance shown separately.
    5. Economics: Incremental net revenue, contribution before marketing, all-in investment, and net incremental value.
    6. Action: Scale, repair, learn, or stop, including the next budget level and the condition that would reverse the decision.

    This format also improves conversations about AI investment. Instead of arguing whether AI is broadly fast, useful, or inevitable, you can show the workflow affected, the human effort consumed, the accepted output produced, the quality guardrails, and the capacity or financial value that changed.

    Key takeaways

    • Attributed revenue tells you where credit landed; incrementality estimates how much business the marketing activity actually created.
    • Define the budget decision, eligible population, counterfactual, primary outcome, and economic hurdle before the campaign or rollout begins.
    • Count the full investment. For AI workflows, include learning, operation, output repair, editing, and fact-checking time rather than measuring only subscriptions or generation speed.
    • Use the strongest feasible comparison design, document contamination, and distinguish an inconclusive result from evidence of no lift.
    • Judge partners by the quality and transparency of their incrementality method, not just their attributed sales, audience scale, or dashboard polish.
    • Translate every result into a pre-agreed action: scale, repair, learn, or stop.

    Before your next budget review, choose one disputed investment and write its decision statement. Build the all-in cost ledger, name the counterfactual, and agree on the action thresholds before asking for another report. That small change turns incrementality from a measurement project into an allocation discipline.

    References


  • Google Ads Controls and Measurement: An Audit Framework

    Google Ads Controls and Measurement: An Audit Framework

    You can hit your cost target and still have a control problem. A campaign average will not show whether a claim is valid in every target country, whether AI matched the right query to the right message, or whether advertising on the destination made the page harder to use.

    To manage Google advertising properly, you need one evidence trail spanning pre-launch permission, automated decisions, and post-click experience. The framework below turns those separate concerns into an audit process you can use before expanding a campaign or increasing its budget.

    Separate controls from observations

    A control determines what should happen. Measurement tells you what did happen. Confusing the two creates familiar mistakes: treating ad approval as proof of legal compliance, treating an AI instruction as a guaranteed constraint, or treating a satisfactory conversion rate as proof that every customer journey was appropriate.

    Build your operating model around four layers. Each layer answers a different question and needs its own evidence.

    LayerQuestion to answerEvidence to retainSuggested owner
    Market permissionWhat may this business claim, promote, and target in this location?Applicable Google policy, law, regulation, local code, review decision, and approval dateCompliance or market approver
    Automation instructionsWhat business, audience, and message context did AI Max receive?Versioned brief, campaign scope, approved claims, and destination mapPaid search owner
    Delivered journeyWhich search term, creative assets, and landing page came together?Observable query-to-creative-to-page combinations and their outcomesChannel analyst
    On-page ad experienceHow much advertising did real users encounter on the site?CrUX ad count, density, CPU weight, and network weightSite experience or monetization owner

    One person can own several layers in a small team. The important part is that no layer disappears into an aggregate dashboard. Cost, conversion volume, and return can tell you whether a campaign is commercially productive. They cannot answer whether a local claim was permitted or explain why a particular search led to a particular page.

    Gate each country before you copy the campaign

    Campaign modules pass through separate country checkpoints where documents, consent, and policy controls are reviewed.

    Geographic expansion is not merely a targeting change. The business may be based in one country while its ads create obligations in every country they reach. Copying a successful campaign into another market can therefore change which claims, disclosures, products, and promotional language require review.

    On September 22, 2026, Google expanded its reference list of advertising and marketing codes for Argentina, Australia, Chile, Colombia, Paraguay, and South Africa. That change matters if you advertise in those markets, but it does not turn Google’s list into a complete statement of local law.

    You remain responsible for the full rule stack: Google Ads policies, applicable laws and regulations, and relevant industry or advertising self-regulatory codes. Google’s local-code references do not replace its existing policies and are not an exhaustive explanation of local requirements.

    Use a launch gate for every country-and-offer combination:

    1. Create a target matrix. Record the country, campaign, offer, audience, domain, landing-page version, and planned launch state. Do not hide several countries inside one approval row.
    2. Inventory the claims. Include headlines, descriptions, asset text, prices, eligibility statements, comparisons, guarantees, testimonials, disclosures, and the claims repeated on the landing page.
    3. Check every applicable layer. Log the Google Ads policy reviewed, the local legal or regulatory question, and any relevant self-regulatory code. A blank field should mean not reviewed, not silently assumed irrelevant.
    4. Attach the decision. Record who approved the claim, what evidence supported the decision, which market it covers, and what conditions or required qualifiers apply.
    5. Define review triggers. Reopen the row when you add a country, change the offer or audience, introduce a new claim, replace a destination, or materially revise the creative.

    Do not treat an accepted ad as legal clearance. Platform eligibility and legal compliance answer different questions. This distinction is especially important in regulated industries, where a small change in wording or audience can change the risk. If the decision depends on interpreting local law, have qualified counsel for that market make it before you launch; a policy reference cannot substitute for jurisdiction-specific legal advice.

    Audit AI Max at the query-creative-page level

    AI-driven search advertising changes the unit you need to inspect. It is no longer enough to review a keyword list, approve a fixed ad, and assume one destination. The useful unit is the complete journey: the search term that expressed intent, the assets the person saw, and the landing page that received the click.

    AI Brief gives AI Max written context about your business, intended audience, and key messaging. Its closed beta has expanded to Dutch, French, German, Italian, Japanese, Portuguese, and Spanish. If the feature is available in your account, the additional languages can help you express market context more directly, but a translated brief does not remove the need for local claim review.

    Build a working brief with five components:

    • Business truth: a precise description of what you sell, who provides it, and what the offer does not include.
    • Audience boundary: the customer need and level of intent the campaign is meant to serve.
    • Message priority: the benefit or differentiator that should lead, supported by approved language.
    • Claim restrictions: statements that are prohibited, conditional, or require a qualifier in each market.
    • Destination map: the approved page for each offer, language, audience, and country.

    Put the business, audience, and messaging context into AI Brief where supported. Keep claim restrictions and destination approvals in your external control register as well. AI Brief supplies context for optimization; it is not evidence that every generated or selected combination passed your legal review.

    Version the brief instead of continually overwriting it. Retain a version identifier, effective date, campaign scope, approving owner, supported languages, and the landing-page map that was current at the time. When performance changes, that record lets you distinguish an automation change from a change in the instructions you supplied.

    Google is also developing a unified reporting view connecting the triggering search term, the creative assets shown, and the landing page reached. No specific launch date has been announced; additional availability details are expected later in 2026. Treat that as planned visibility, not a feature you can assume is already present in every account.

    When the connected view is available, review each journey in this order:

    1. Search term: Does the term express an intent the campaign should serve, and is that intent appropriate for the targeted market?
    2. Creative: Do the shown assets answer that intent without adding an unsupported promise or dropping a required qualifier?
    3. Landing page: Does the destination fulfill the same promise, use the correct market version, and make the next step clear?
    4. Outcome: Did the combination produce the business result you intended, rather than merely generating a click?
    5. Intervention: Should you revise the brief, query control, asset, destination, or market approval before the combination appears again?

    Until unified reporting arrives in your account, reconstruct a sample from the separate data the account exposes. Start with high-spend terms, regulated offers, new markets, and combinations producing weak or surprising outcomes. Record unavailable fields as measurement gaps. Do not infer which asset a user saw merely because that asset currently exists in the library.

    This journey-level review protects you from a misleading average. Strong aggregate performance can coexist with irrelevant queries, mismatched promises, incorrect destinations, or a small number of high-risk combinations. The aggregate tells you where to look; the connected journey tells you what to change.

    Use CrUX to measure the ad load users actually experience

    Two phones show a stable page beside a page whose late-loading ad blocks shift content near a user's hand.

    The click is not the end of advertising measurement. If your landing pages or content pages carry advertising, the site’s own ad stack can consume processing power, transfer data, and occupy the viewport after the visitor arrives.

    Chrome’s public User Experience Report now includes four experimental advertising metrics based on real Chrome user experiences. They measure a different layer from Google Ads reporting:

    CrUX metricWhat it measuresUnit or formOperational question
    Ad Weight – CPUProcessing resources consumed by adsMillisecondsDid the advertising stack create a larger computational burden?
    Ad CountAverage number of ads visible in the viewportAverage countDid the layout expose users to more ads at once?
    Ad DensityAverage share of the viewport occupied by adsPercentageDid commercial inventory crowd out the page’s primary task?
    Ad Weight – NetworkData consumed by advertisingBytesDid ad delivery become heavier for real users?

    Use these metrics as diagnostics, not as a made-up pass-or-fail score. Google added them to its page-experience resources to help site owners evaluate ad experiences, while also cautioning that not every available experience metric is a direct search ranking factor. A movement in an experimental metric does not, by itself, prove why rankings, conversions, or engagement changed.

    A practical review looks like this:

    1. Identify paid-traffic destinations that also display on-site ads. If a page has no advertising, mark this layer not applicable instead of forcing the metrics into its scorecard.
    2. Capture the four metrics at the CrUX scope available to you and establish an internal baseline. Compare like with like inside your own site rather than inventing an unsupported universal threshold.
    3. Annotate ad-stack releases, placement changes, template revisions, and monetization experiments so a later movement has a plausible change record.
    4. Read the metrics together. Rising count or density points you toward quantity and placement; rising CPU or network weight points you toward the technical burden of delivery.
    5. Pair the diagnosis with the business outcome you already trust. The aim is to improve the user experience without pretending that one metric explains every performance change.

    Keep the scope distinction clear. CrUX ad metrics describe advertising experienced on your site. They do not reveal how Google Ads selected a search term, assembled creative, or chose a destination. That is why the journey audit and the on-page experience review belong beside each other rather than being collapsed into one score.

    Key takeaways

    • Separate market permission, automation instructions, delivered journeys, and on-page ad experience. Each layer needs different evidence.
    • Open a new compliance row for every country-and-offer combination. Google’s local-code list is helpful, but it is neither exhaustive nor a replacement for Google Ads policies and applicable law.
    • Treat AI Brief as versioned steering context, not as legal approval or proof that every automated output complied with your restrictions.
    • Evaluate AI Max through the complete search-term, creative, landing-page, and outcome chain. Campaign averages can conceal strategically poor combinations.
    • Use the four experimental CrUX ad metrics to diagnose advertising on your own pages, not to manufacture a ranking score or judge the Google Ads auction.

    Before your next market expansion or material budget increase, create one control-register row for the country and offer in question. Fill in the approved claims, brief version, destination map, observable journey evidence, and CrUX measurements where they apply. If a field has no owner or evidence, resolve that gap before you ask automation to scale it.

    References


  • Profound’s Gartner 2026 Recognition: What It Signals

    Profound’s Gartner 2026 Recognition: What It Signals

    If Profound’s Gartner recognition has put the platform on your shortlist, treat that as a reason to investigate, not a reason to buy. The useful question isn’t whether the recognition sounds impressive. It’s whether Profound can help your team turn an AI visibility problem into a specific intervention and then show what changed.

    That distinction matters because AI search programs often become reporting programs. Teams collect mentions, citations, prompts, and competitor comparisons, but the findings never become owned work with measurable consequences. The strongest interpretation of this recognition is that the market is beginning to demand a complete operating loop rather than another dashboard.

    What the Gartner mention does and does not prove

    Profound reports that it was named in Gartner’s 2026 Coolest Vendor Innovations in CRM alongside Canva, Decagon, dx0, and Twenty. That makes the company relevant to a serious evaluation of emerging AI marketing infrastructure.

    It does not, by itself, establish that Profound is the best platform for your organization. A recognition is not a product benchmark, an implementation plan, or proof of business impact in your environment. It doesn’t answer questions about data coverage, workflow fit, measurement quality, integrations, governance, or the effort required to turn a recommendation into a deployed change.

    The claim also comes from Profound’s own account of the recognition. That doesn’t make it unimportant, but it does set the correct evidence standard: use the mention to justify deeper due diligence, then make the product earn its place through your own workflow and data.

    Don’t turn the recognition into an improvised ranking. The named companies address different parts of customer and marketing work, so their appearance together doesn’t mean they are interchangeable competitors. For your decision, the relevant comparison is between Profound and the other ways you could operate your AI visibility program, including internal analysis, specialist tools, agencies, and connected systems.

    Why the insight-to-outcome loop matters in AI visibility

    An isometric circular workflow carries search inputs through analysis, assigned work, production, and measured feedback while team members collaborate at each stage.

    Profound interprets the recognition as evidence that marketers increasingly expect a closed loop from insight to action to measured outcome. That is a vendor-held interpretation, but it gives buyers a much better evaluation standard than feature counting.

    AI visibility work starts with an observation: perhaps a brand is missing from an important answer, a competitor is cited more often, or a product is described inaccurately. None of those observations creates value on its own. Value appears only when the team can diagnose a plausible cause, assign a suitable intervention, publish or distribute the change, and measure the result against a defined baseline.

    StageQuestion your workflow must answerEvidence to request
    InsightWhat exactly is happening, for which queries, audiences, markets, and AI experiences?Saved answer-level observations, timestamps, query definitions, cited domains, and a clear distinction between collected data and inferred explanations.
    ActionWhat should change, where should it change, and who owns the work?A recommendation tied to the original observation, a destination such as a page or entity record, an owner, status, and change history.
    OutcomeDid visibility, representation, referral activity, or a downstream business measure improve after the intervention?A preserved baseline, comparable follow-up observations, deployment dates, and an outcome definition agreed before the work began.

    This framework also prevents a common category error. A suggested content revision, outreach task, or JSON-LD update is an action, not an outcome. Schema markup can make eligible facts easier for machines to interpret when it accurately represents visible content, but merely deploying markup doesn’t prove that an AI system used it or that customer behavior changed.

    The CRM context is useful here. Customer and revenue consequences usually live downstream from visibility data. A credible closed loop therefore needs either native connections or documented handoffs between AI answer monitoring, content operations, technical implementation, analytics, and customer systems. It doesn’t all have to happen inside one platform, but the path between systems must be traceable.

    Run this six-part evaluation before you choose a platform

    A cross-functional team tests six connected evaluation stations in a modern workshop while an out-of-focus trophy sits to the side.

    A polished demonstration can hide the hardest operational gaps. Use one real topic from your business and ask the vendor to follow it from observation through measurement. The following test works whether you are assessing Profound or another AI visibility system.

    1. Define your evaluation set before the demonstration. Include branded questions, category questions, comparison questions, and problem-led questions that matter to actual buyers. Specify the markets, languages, products, and AI experiences in scope. This prevents a vendor from selecting only the examples that make its interface look strong.
    2. Inspect the underlying observation. Ask to see the answer captured, when it was captured, the query used, and any citations or brand mentions detected. You need to know which elements are direct observations and which are scores, classifications, or interpretations produced by the platform.
    3. Challenge the diagnosis. Ask why the system believes a particular content, technical, entity, or authority gap caused the observed result. A useful platform should let your team examine the evidence behind a recommendation. Treat unexplained scores and confident causal claims cautiously.
    4. Follow the recommendation into an owned task. Identify who receives it, where the work happens, what approval is required, and how completion is recorded. If staff must copy findings manually into another system, count that labor and the risk of lost context when you compare options.
    5. Agree on the outcome before making the change. Decide whether success means more relevant mentions, more accurate representation, stronger citation presence, qualified referral activity, or a business result recorded downstream. Don’t substitute a platform’s convenient metric for the decision your organization actually cares about.
    6. Repeat the measurement with a change log. Preserve the initial query set and observation dates, record exactly what was deployed, and compare like with like. AI-generated answers can vary, so a single favorable response is weak evidence. Look for a pattern that is meaningful enough to justify the next round of work.

    This evaluation does not require the vendor to promise perfect attribution. In fact, causal humility is a positive sign. Content changes, model behavior, competitor activity, retrieval choices, and outside coverage can all affect an answer. What you need is a system that preserves enough evidence to distinguish a plausible result from a convenient story.

    Watch for the gaps that turn a closed loop into a slogan

    The phrase “closed loop” sounds complete, but several missing links can make it operationally empty. Look for these gaps during procurement and pilot design:

    • Undefined coverage: The platform reports a visibility score without showing which prompts, markets, models, or observation periods produced it.
    • Diagnosis without evidence: It recommends creating or changing content but cannot connect the recommendation to a captured answer, citation pattern, or identifiable information gap.
    • Action without ownership: Findings remain in the dashboard because no person, destination, approval state, or deadline is attached to them.
    • Publishing without verification: A page or schema change is marked complete, but nobody checks whether the intended fact is visible, accurate, indexable, and consistent across relevant brand properties.
    • Measurement without comparability: The follow-up uses different questions, filters, markets, or definitions, making apparent improvement difficult to interpret.
    • Visibility without business context: The team celebrates more mentions without asking whether the brand is represented accurately, appears in relevant buying situations, or influences a meaningful downstream behavior.

    You should also separate platform capability from implementation maturity. A product may support the required workflow while your organization lacks owners, publishing access, analytics connections, or an agreed measurement model. Buying more software will not repair those operating gaps. Document them before procurement so that platform limitations and internal limitations don’t get confused.

    Key takeaways

    • Profound’s Gartner 2026 recognition is a credible reason to include the company in an evaluation, not proof that it fits your stack or will improve your results.
    • The most useful signal is the emphasis on connecting insight, action, and outcome. Test that complete path rather than comparing dashboard features in isolation.
    • Use a real business topic during the demonstration and require answer-level evidence, an owned action, a deployment record, and a comparable follow-up measurement.
    • Define success before the pilot. Mentions, citations, representation accuracy, referral activity, and business outcomes answer different questions.
    • A closed loop can span several systems. What matters is preserved context, clear ownership, and a traceable line from observation to consequence.

    Make the next step a workflow test, not a prestige vote

    Choose one commercially important topic cluster and map its complete path: the questions people ask, the answers you can observe, the evidence behind any diagnosis, the person who can make a change, and the outcome you will examine afterward. Then ask Profound to demonstrate that path using your definitions rather than a prepared success case.

    If the workflow remains traceable from observation to consequence, the recognition has helped you discover a platform worth piloting. If the trail disappears between dashboard insight and business action, the Gartner mention should not carry the decision. Your next move is to test the loop.

    References


  • Google Analytics Hostname Allowlists: A Safe Setup Plan

    Google Analytics Hostname Allowlists: A Safe Setup Plan

    Your Google Analytics reports can look convincing even when unwanted event traffic is mixed into the numbers. That becomes a practical problem when you use those numbers to allocate budget, judge content, or explain performance to a client.

    A hostname allowlist gives you a cleaner default: define where legitimate browser events may originate, then filter events associated with other hostnames. The important work is not creating the filter. It is identifying every valid hostname, understanding what the filter does not cover, and checking that your measurement still represents the customer journey.

    Why an Include filter is stronger than a growing blocklist

    Hostname filtering used to be built around Exclude filters. You found an unwanted hostname, added it to the filter, and repeated the process when another one appeared. Google Analytics now supports Include filters for approved hostnames, so events associated with hostnames outside your approved set can be filtered out.

    The difference is operational, not cosmetic. An exclusion list assumes you can keep discovering every bad or irrelevant hostname. An allowlist asks a more manageable question: which hostnames does this property intentionally measure?

    That makes the approach useful when spam or unwanted event traffic keeps resurfacing. It can also reduce the maintenance burden for an organization that operates several sites or routinely sees events from places that should not contribute to the property.

    The tradeoff is precision. A denylist fails open: something new remains until you exclude it. An allowlist fails closed for browser traffic: forget a legitimate hostname and its events can be filtered out. Treat the allowlist as part of your measurement architecture, not as a quick cleanup rule.

    Key takeaways

    • Use a hostname Include filter when you can define the trusted domains that should contribute browser events to the property.
    • Build the list from the intended customer journey and site architecture, not only from hostnames already visible in a potentially polluted report.
    • Do not confuse a hostname with a traffic source. The hostname identifies where the measured page or experience is hosted; it does not identify who sent the visitor there.
    • Expect events with an empty hostname to be blocked by the Include filter, and investigate them before assuming every empty value is spam.
    • Handle Measurement Protocol separately because hostname Include filters do not apply to those events.
    • Review the allowlist whenever a launch, migration, subdomain, or externally hosted journey changes where browser events originate.

    Build an allowlist that matches the real measurement journey

    A visitor journey connects a main website, regional site, store, hosted checkout, and support portal to one analytics hub.

    Start with what the property is supposed to measure

    Do not begin by copying every hostname you see in a report. That risks turning existing contamination into an approved list. Begin with the purpose of the property: which websites and browser-based experiences should contribute to its reporting?

    Map each stage of a journey that matters. Your main website may be obvious, but a legitimate interaction can also occur on a first-party subdomain or another hostname used for a deliberately measured step. Include such a hostname only when its events truly belong in this property. Ownership alone is not enough; relevance to the property’s measurement scope is the test.

    Record hostnames, not complete URLs. A page path such as a pricing or confirmation page is not another hostname. Keeping that distinction clear prevents a domain-control filter from becoming an improvised page-level rule.

    Event situationAllowlist decisionWhat to verify
    Browser event from the primary public websiteIncludeThe hostname is written exactly as it appears in the intended implementation.
    Browser event from a first-party subdomainInclude only if intentionalThe subdomain’s activity belongs in this property and supports a measured journey.
    Browser event from a staging or test environmentUsually keep separate unless explicitly requiredThe property is genuinely intended to contain test activity.
    Browser event from an unfamiliar third-party hostnameDo not approve by defaultA known business process deliberately generates relevant events there.
    Event with an empty hostnameAutomatically blocked by the Include filterThe missing value is not evidence of a broken legitimate collection path.
    Event sent through Measurement ProtocolNot governed by the hostname Include filterThe sending system and its event quality are controlled separately.

    Investigate empty hostname events before activation

    An Include filter automatically blocks events whose hostname is empty. That is useful because a missing hostname can indicate spam or abnormal activity. It is not proof that every affected event is malicious, however. Some traffic sent through gtag.js can also arrive without a hostname.

    Use that behavior as a diagnostic checkpoint. Before relying on the filter, determine whether an important browser journey produces empty hostname values. If it does, fix or intentionally account for the collection path rather than approving an unknown value or accepting an unexplained loss of data.

    The practical question is simple: if empty-hostname events disappear, will a real conversion, page interaction, or business process disappear with them? If you cannot answer that yet, the implementation is not ready to support decisions.

    Separate Measurement Protocol governance from browser filtering

    Hostname Include filters do not apply to Measurement Protocol events. That exception protects server-side and offline events from being unintentionally rejected by a browser-oriented hostname rule.

    It also means the allowlist is not a complete perimeter around the property. A property can have cleanly filtered browser events while continuing to receive Measurement Protocol events. Inventory those senders separately and confirm that each one is authorized, necessary, and mapped to the correct property.

    This distinction matters when you investigate a suspicious event after enabling the allowlist. Do not conclude that the filter failed merely because the event remains. First determine whether it arrived through the browser collection path or through Measurement Protocol. The two routes are subject to different controls.

    Roll out the filter without creating a reporting blind spot

    An analyst monitors parallel original and filtered event streams in a dark control room during a staged rollout.

    A useful rollout has three parts: scope, validation, and ownership. Skipping any one of them can replace noisy data with incomplete data, which is harder to notice because the reports may still look tidy.

    1. Write down the property’s purpose. State which sites, environments, and customer journeys should contribute events. This gives every hostname an explicit reason to be included or omitted.
    2. Inventory trusted browser hostnames. Check the primary domain, intentional subdomains, and any separate host involved in a measured step. Do not approve an unfamiliar hostname merely because it already appears in the data.
    3. Identify non-browser senders. List the systems that use Measurement Protocol so nobody assumes the hostname filter governs them.
    4. Create the hostname Include filter. Use the approved inventory as the filter’s specification. Keep the written inventory with the analytics configuration so future changes can be reviewed against it.
    5. Exercise critical journeys. Confirm that the browser-based pages and actions your team relies on still contribute the expected event types under their legitimate hostnames.
    6. Check the negative cases. Verify that unapproved browser hostnames and empty-hostname events no longer affect the filtered view of your data, while separately checking that intended Measurement Protocol activity remains accounted for.
    7. Assign an owner. Make one role responsible for reviewing the allowlist when the web architecture changes. Without ownership, a correct filter gradually becomes incomplete.

    Document why each hostname is trusted, not just its spelling. A short reason such as “public product site” or “measured account subdomain” gives the next reviewer enough context to remove obsolete entries and challenge unexplained additions.

    Know what cleaner analytics can and cannot improve

    A hostname allowlist is a data-quality control. It can make reports more dependable by preventing unapproved browser hostnames from distorting the dataset. That supports better decisions about acquisition, content, conversion, and campaign performance.

    It is not an SEO, AEO, or generative-engine ranking signal. Enabling it does not make a page more crawlable, authoritative, or likely to be cited by an AI system. The benefit is indirect: your team is less likely to prioritize a landing page, channel, or conversion path because unwanted traffic made it appear more important than it was.

    Be especially careful with trend comparisons around the change. A visible drop may represent removed noise, accidentally filtered legitimate activity, or both. Check hostname coverage and collection routes before interpreting the difference as a change in audience demand or marketing performance.

    Put the allowlist review into the same launch checklist you use for a new subdomain, domain migration, or externally hosted customer step. The next architecture change should update the measurement boundary before anyone relies on the resulting reports.

    References


  • How to Fill Google Ads Conversion Gaps With Offline Data

    How to Fill Google Ads Conversion Gaps With Offline Data

    Your website tag records the purchase at checkout, but your backend may hold the version of the transaction you actually want Google Ads to learn from: more complete customer information and the amount after an upsell, refund, or final order adjustment.

    If both records carry the same transaction ID, Google Ads can use the backend record to improve the tagged conversion instead of forcing you to accept whatever was available in the browser. The implementation is less about uploading more data than establishing a reliable join between two versions of the same business event.

    What offline gap filling changes – and what it does not

    Google Ads’ multi-source conversions beta can match an offline record to a website conversion through its transaction ID. Once Google finds that match, the offline record can supply user-provided data that the tag did not capture, including an email address, phone number, or address.

    The same mechanism can correct the conversion value. If the tag sent an initial amount and your backend later has the finalized order total, upsell, or refund adjustment, the uploaded amount replaces the value attached to the matching tagged transaction.

    Think of this as a database join, not a second copy of the sale. One conversion action can receive information from the website tag and the offline system. That distinction helps you avoid three common implementation mistakes:

    • Do not assume every offline row enriches a tagged event. The gap-filling path depends on Google finding the corresponding transaction ID. An unmatched record cannot fill fields on a tagged conversion it has not been connected to.
    • Do not expect the offline row to overwrite every tag field. The supplemental data is primarily used for missing user-provided information and conversion-value updates.
    • Do not use an uploaded GCLID as a repair mechanism for a matched transaction. Google ignores GCLIDs from the supplemental record in this scenario, so they do not replace the information associated with the tag event.

    Multi-source reporting may also contain additional conversions from the offline source. Treat those separately in your validation plan. “Conversions added” and “tagged conversions supplemented” are different outcomes, even if they appear under the same conversion action.

    The capability is documented as a beta. Confirm that it is available in your account before making it a dependency of your measurement design.

    Make the transaction ID your dependable join key

    Two digital transaction records with identical geometric identifiers lock together through a central connector.

    The transaction ID is the bridge between the browser event and the backend record. If the two systems generate unrelated identifiers, drop the value, or transform it differently, the rest of the upload can be accurate and still fail to improve the original conversion.

    A clean data path should work in this order:

    1. Your site completes the conversion and assigns its transaction ID.
    2. The Google tag sends the conversion with that ID and the data available at that moment.
    3. Your order system, CRM, or other backend retains the identical ID while customer details and the final value are confirmed.
    4. Google Ads Data Manager or the Data Manager API sends the supplemental record.
    5. Google uses the shared ID to associate the offline information with the tagged transaction.

    Rules for a durable transaction ID

    • Generate the ID once and persist it across the browser, order database, CRM, and upload pipeline.
    • Use an ID that represents the actual conversion rather than creating a separate Google Ads-only identifier later.
    • Keep it unique to the business event. Reusing an ID across orders makes reconciliation ambiguous.
    • Do not embed an email address, phone number, or other personal data in the ID.
    • Retain the ID in your integration logs so you can trace a reported mismatch back to the tag payload and backend record.
    • Avoid trimming, reformatting, or replacing the ID in only one part of the pipeline.

    Before connecting an offline source, take a sample of real conversions and trace each transaction ID from the site event to the backend export. If you cannot follow the same value across that entire path, fix the ID lineage first. Adding more customer fields will not repair an uncertain join.

    User-provided data also deserves a separate governance check. Confirm that the information is accurate, that your organization is permitted to send it, and that access to the upload pipeline is appropriately controlled. Matching performance does not justify sending data your business should not use.

    Build the offline feed around information that arrives later

    Your offline feed should have a narrow job: supplement the browser event with authoritative information that became available elsewhere. It should not become an undifferentiated export of every field in your CRM.

    The following controls belong in the internal feed design. Some are upload fields; others are operational metadata that helps you decide whether a record is ready to send.

    Data itemPreferred internal originControl to apply
    Transaction IDThe system that created or persisted the conversionConfirm that it is identical to the ID sent by the website tag.
    Email, phone number, or addressThe approved backend customer or order recordSend only accurate, permitted information intended to fill a field the tag missed.
    Conversion valueThe authoritative order, billing, or CRM recordPublish the amount your business treats as final for that update, including applicable upsell or refund changes.
    Record statusYour order or revenue workflowUse it internally to prevent provisional records from being presented as finalized value corrections.
    Ready and upload timestampsYour integration logMeasure the delay between backend availability and delivery to Google Ads.

    Conversion value requires the tightest control because the uploaded value replaces the tag’s value for the matching transaction. It is not merely attached as an alternative value. A stale amount in the offline feed can therefore replace a better amount captured on the site.

    Define which backend system is authoritative and what “final” means in your business process. Then make that rule part of the integration. Do not label a provisional amount as final simply to make the upload run sooner.

    At the same time, delivery speed matters. Google recommends sending the supplemental data within 24 hours for the best Enhanced Conversions matching and bidding performance. Track two intervals separately: how long the backend takes to make the record ready and how long your integration takes to upload it. That separation tells you whether the delay belongs to the business process or the data pipeline.

    The 24-hour window is an optimization recommendation, not a promise that every record will match. If your integration routinely misses it, shorten unnecessary batch, approval, and transfer delays. Preserve data accuracy while doing so; faster uploads of unreliable values are not an improvement.

    Use the 14-day trial to validate the pipeline, not bidding

    An analyst monitors purchase records moving through matching and validation checkpoints in a controlled data pipeline.

    You can connect the additional source through Google Ads Data Manager or the Data Manager API. A newly connected source then enters a 14-day trial period.

    The trial creates an important split between what you can see and what Google uses. Additional conversions may appear in reporting and diagnostics during those 14 days, but they are not used for bidding. Conversion-value updates are also disabled during the trial.

    That means a reporting change during the trial is not evidence that Smart Bidding has learned from the new source. It is also not a valid test of whether finalized offline values are replacing the original tag values. Changing campaign targets or budgets solely because trial-period reporting moved could make you react to information the bidding system is not yet using.

    Structure the rollout in three phases:

    1. Before connection: preserve a baseline of tag counts, values, transaction-ID coverage, upload latency, and relevant campaign reporting. Save enough internal detail to explain differences later.
    2. During the 14-day trial: confirm that records arrive, inspect diagnostics, investigate unmatched or duplicated internal IDs, and verify that the correct conversion action and backend source are involved. Do not score bidding or value correction while those functions are inactive.
    3. After the trial: verify that the source has left trial status, check value behavior against the authoritative backend output, and annotate the activation date in your performance analysis.

    A practical validation checklist

    • Identity coverage: for sampled transaction IDs, confirm that a field missing from the tag is present in the approved backend record.
    • ID overlap: compare the set of IDs sent by the tag with the set prepared for upload. Investigate unexpected gaps before looking for a Google Ads explanation.
    • Uniqueness: ensure your internal export does not present unrelated transactions under the same ID.
    • Value authority: compare the outbound value with the finalized amount in the designated system of record before it reaches Google.
    • Delivery latency: count the records sent inside and outside the recommended 24-hour window. Monitor the trend instead of relying on an average that can hide delayed batches.
    • Trial separation: label trial-period reporting so nobody mistakes visible additional conversions for bidding inputs or completed value corrections.
    • Post-trial monitoring: watch diagnostics and reporting after activation rather than assuming that a successful upload guarantees a successful match.

    When numbers differ, debug in the order the data travels: tag execution, transaction-ID persistence, backend record readiness, export construction, upload delivery, matching, and finally reporting. Starting with campaign performance makes a pipeline problem much harder to isolate.

    Key takeaways

    • Google Ads offline gap filling uses the transaction ID to connect backend information with the corresponding website-tag conversion.
    • A matched upload can add missing user-provided data such as an email address, phone number, or address.
    • An uploaded conversion value replaces the original value on the matching tagged transaction, so only an authoritative system should publish value corrections.
    • An uploaded GCLID is ignored for matched transactions and should not be treated as a way to overwrite the tag’s attribution information.
    • Send supplemental data within 24 hours when possible to support Enhanced Conversions matching and bidding performance.
    • During a new source’s 14-day trial, additional conversions may be visible but are not used for bidding, while value updates remain disabled.

    Start with one conversion action whose transaction IDs are already stable. Trace a sample from the tag to the backend, name the system that owns the final value, and define your trial acceptance checks before connecting the source. If that lineage is clean, the offline feed can close specific measurement gaps without turning your conversion setup into two competing versions of the truth.

    References


  • Patient Acquisition Cost Benchmarks for Medical Practices

    Patient Acquisition Cost Benchmarks for Medical Practices

    Your patient acquisition cost can be mathematically correct and still give you the wrong answer. A single number cannot tell you whether marketing is efficient until you know which costs it includes, what qualifies as an acquired patient, and whether you are comparing the same specialty and channel.

    Use the benchmarks below as diagnostic reference points, not spending targets. The practical goal is to find out whether your result reflects normal acquisition economics, a measurement problem, a weak channel, or a breakdown between the first inquiry and the completed appointment.

    Key takeaways

    2026 PAC benchmarks by specialty and marketing channel

    Three miniature healthcare settings are reached by different patient pathways with varying amounts of unmarked spending tokens.

    The 2021-2026 benchmark dataset uses anonymized results from medical practices. Specialty sample sizes range from three reporting practices for rheumatology to 27 for cosmetic and plastic surgery, so the apparent precision of the dollar figures should not be confused with equal statistical strength.

    Practice typeAverage patient acquisition costPractices reporting
    Allergy / Immunology$4214
    Cardiology$5899
    Cosmetic / Plastic Surgery$61727
    Dentistry$37911
    Dermatology$44818
    Endocrinology$4024
    Family Practice$27217
    General Practice$20119
    Geriatrics$41111
    Med Spa$2938
    Naturopathic$3876
    Neurology$59213
    Obstetrics & Gynecology$3385
    Orthodontics$5338
    Pediatrics$16011
    Podiatry$2216
    Psychiatry$2935
    Rheumatology$3543
    Urgent Care$29121

    The channel view answers a different question. It shows averages blended across all practice types, not specialty-by-channel benchmarks.

    Marketing channelAverage patient acquisition cost
    Organic Search (SEO)$218
    Paid Search (PPC)$346
    Organic Social$297
    Paid Social$299
    Direct Mail$245
    Radio Advertising$391
    TV Advertising$469
    Video / YouTube Marketing$358
    Outdoor Advertising$420

    No channel-level sample sizes accompany those averages. The figures also do not isolate geography, service mix, payer mix, patient value, attribution model, or the costs included in PAC. That does not make them useless. It means they are best used to flag a result for investigation rather than to certify that a campaign is efficient.

    Choose the right comparison before judging your result

    Start with the specialty benchmark when you are evaluating the practice’s overall acquisition cost. Start with the channel benchmark when you are investigating how a particular marketing method performs. Do not combine the two tables to manufacture a number that is not present.

    For example, dermatology averages $448 by specialty while paid search averages $346 across practice types. Averaging those figures would not produce a dermatology PPC benchmark. One describes a specialty across acquisition activity; the other describes a channel across specialties.

    If your practice has materially different service lines, calculate PAC for each one. A blended practice number can hide an expensive elective service behind a lower-cost primary-care line, or make a valuable specialty program look inefficient because its patients cost more to acquire. If your specialty is absent from the benchmark set, label any substitute as a proxy and rely more heavily on your own historical cohorts.

    What you seeWhat to test before actingUseful next action
    Your PAC is below the relevant averageCosts may be missing, returning patients may be counted as new, or one patient may be credited to multiple channels.Reconcile marketing expenses with finance and patient records before increasing the budget.
    Your PAC is near the relevant averageThe comparison may be reasonable, but average performance can still be unprofitable for your patient economics.Compare PAC with contribution margin and available clinical capacity.
    Your PAC is above the relevant averageThe cause may be expensive traffic, poor inquiry quality, booking friction, no-shows, limited capacity, or an attribution error.Segment the funnel before cutting the channel. Fix the component that is raising the cost.

    A benchmark becomes more useful when it changes the question from “Are we above average?” to “Which assumption would have to be true for this comparison to be fair?” That question exposes measurement gaps before they turn into budget decisions.

    Calculate a like-for-like patient acquisition cost

    Patient acquisition cost = eligible acquisition cost divided by newly acquired patients.

    The formula is simple. The definitions are where most comparisons break. Write those definitions beside the metric in your dashboard so that a future analyst, agency, or practice manager cannot silently change them.

    PAC layerCosts in the numeratorPatient denominatorBest use
    Media-only PACDirect advertising spendNew patients attributed to that advertisingOptimizing bids, audiences, and campaigns inside a paid channel
    Fully loaded channel PACMedia, agency or vendor fees, labor, creative, content, technology, and channel-specific trackingNew patients attributed to the channel under one consistent ruleComparing the economic performance of channels
    Fully loaded practice PACAll eligible patient-acquisition costsAll newly acquired patientsFinancial planning and evaluating the complete acquisition program

    Do not compare a media-only internal number with an external figure that may include labor and vendors. If the benchmark’s cost scope is not defined well enough to match yours, preserve your more useful internal definition and treat the external number as directional.

    Fix the patient milestone

    A lead, appointment request, booked appointment, attended consultation, and completed first encounter are not interchangeable. Choose the event that means the practice has genuinely acquired a patient and apply it everywhere. A completed first encounter is generally more stable than a booking because cancellations and no-shows have already been resolved, but your operational model may require another milestone.

    • Count each new patient once at the chosen milestone.
    • Exclude returning patients unless you intentionally maintain a separate reactivation metric.
    • Resolve duplicate records across locations, phone systems, forms, and scheduling tools.
    • Document how free consultations, canceled appointments, no-shows, and later conversions are handled.
    • Keep the definition unchanged when comparing periods or channels.

    Use one attribution rule without erasing the patient journey

    A patient may first encounter the practice in an organic result or AI-generated answer, later click a branded ad, and finally call. Giving every touchpoint full credit inflates the denominator for each channel. Giving only the last click credit can hide the activity that created demand.

    Keep both discovery and trackable conversion information when your systems allow it. Record how the patient says they first found the practice, preserve any available campaign or referral data, and assign one primary channel under a documented rule for PAC reporting. An intake field with fixed options and free text can capture search engines, AI assistants, social platforms, referrals, and offline media when click-based attribution is incomplete.

    Align costs and acquired patients to a consistent measurement basis as well. This matters especially for organic search, content, structured data, and other programs whose work and patient response may not occur in the same reporting period. A mismatched numerator and denominator can create a dramatic PAC change even when underlying performance has not changed.

    Turn the benchmark into a budget and operations decision

    Patients move from outreach through reception and scheduling to an examination room, with one person paused at a scheduling bottleneck.

    Set a ceiling from patient economics

    The market average is not your allowable PAC. Your ceiling comes from the value a new patient contributes to the practice and the cash-flow period the practice can support.

    Expected contribution before acquisition = expected collected revenue over the chosen value horizon minus the variable costs of delivering care.

    Expected contribution after acquisition = expected contribution before acquisition minus PAC.

    Use collected revenue rather than sticker price, and keep the value horizon consistent. Comparing one channel with first-visit revenue and another with the value of an entire treatment episode will favor the second channel by design. If your estimates affect a material spending commitment, have the practice’s financial lead validate the revenue, cost, capacity, and cash-flow assumptions before the budget changes.

    A below-benchmark PAC can still destroy value when contribution margin is lower. An above-benchmark PAC can still be workable when the patient relationship contributes enough margin and the practice has capacity. The external average tells you what deserves scrutiny; your economics decide what is affordable.

    Separate traffic cost from conversion failure

    When qualified inquiries are measured consistently, the funnel can be expressed as PAC = cost per qualified inquiry divided by the inquiry-to-acquired-patient conversion rate. This decomposition tells you whether the acquisition problem begins before or after the inquiry.

    • If inquiry costs rise while conversion is stable, inspect targeting, competition, creative, search intent, and channel mix.
    • If inquiry costs are stable while PAC rises, inspect call handling, response delays, service fit, scheduling friction, appointment availability, cancellations, and no-shows.
    • If both appear stable while PAC changes, audit missing expenses, duplicate patient records, channel reassignment, and changes to the acquired-patient definition.
    • If demand exceeds usable appointment capacity, increasing marketing can raise cost without creating additional completed care. Resolve the capacity constraint before adding spend.

    This distinction protects you from cutting an effective campaign because the practice could not answer, qualify, or schedule the demand it generated. It also prevents an operational problem from being disguised as an advertising problem.

    Budget against marginal PAC, not only the historical average

    Your average PAC describes the patients already acquired. A budget decision concerns the additional patients expected from additional spending. Track the incremental cost and incremental acquired patients when you expand a channel; the next segment of demand may not perform like the existing average.

    Planning budget = desired new-patient volume multiplied by planning PAC. Use your own normalized PAC as the base, the relevant external benchmark as a reasonableness check, and your contribution-based ceiling as the financial constraint. Then test whether the required patient volume fits actual appointment capacity.

    Organic search carries the lowest reported channel average at $218, but that does not make it an automatic budget winner. Include content production, technical SEO, structured data, analytics, optimization labor, and outside support in the organic numerator when those costs are part of patient acquisition. Apply the same discipline to every channel. A television average of $469 is not automatically unacceptable if the channel produces patients whose contribution and incrementality support that cost.

    Before approving the next budget change, write the PAC definition at the top of the forecast, rebuild the latest complete measurement period with that scope, choose the appropriate specialty and channel references, and add your contribution-margin ceiling and capacity limit. You will then have more than a benchmark: you will have a decision rule your marketing, operations, and finance teams can use consistently.

    References


  • Search Marketing Performance Intelligence: A Decision System

    Search Marketing Performance Intelligence: A Decision System

    Your CPA jumps, organic clicks soften, and visibility across AI search looks uneven. Your dashboard confirms that something moved. It does not tell you whether demand changed, a competitor became more aggressive, your ads lost relevance, or the conversion path broke.

    You need more than a cleaner report. You need a repeatable way to connect business outcomes, funnel metrics, account changes, market behavior, and search-surface coverage – then turn that evidence into one defensible action. That is the practical job of search marketing performance intelligence.

    Replace the reporting question with a decision question

    Reporting asks what happened. Performance intelligence asks what you should change, why that change is justified, and what evidence would prove it worked.

    That difference sounds small, but it changes how you build the entire analysis. If you start with all available data, you tend to produce a dashboard full of metrics. If you start with a pending decision, you can select only the evidence needed to make that decision safely.

    Write a one-sentence decision question before opening your reporting tools. It should name the affected scope, the observed change, and the choice in front of you. For example: Should we restore non-brand bids, revise the ads, or repair the landing-page experience after conversion volume fell in these campaigns?

    A useful decision question has five parts:

    • Scope: The channel, market, campaign, topic, device, audience, or landing page affected.
    • Outcome: The business metric that moved, such as conversions, revenue, CPA, return on ad spend, or average order value.
    • Timing: When the movement began and which comparison period is genuinely comparable.
    • Competing explanations: At least one internal cause and one external cause worth testing.
    • Decision: The bid, budget, targeting, creative, content, landing-page, or measurement change you might make.

    This prevents a familiar failure: treating a falling line as a diagnosis. A traffic decline only becomes actionable after you identify where it began, what drove it, and what decision follows. Until then, it is an alert.

    Separate outcome metrics from diagnostic metrics as well. Revenue and qualified conversions are outcomes. Impressions, click-through rate, CPC, Quality Score, ranking coverage, and AI Overview presence can help explain those outcomes, but none is a business result by itself. A Quality Score decline, for example, may surface before a later increase in click costs becomes obvious. Treat it as an early clue to investigate, not a target to optimize in isolation.

    Trace every performance shift through five evidence layers

    Five translucent evidence layers show business outcomes, a conversion funnel, campaign controls, market activity, and search surfaces connected by one glowing signal.

    A strong diagnosis moves from the business result toward its possible causes. Do not begin with the most interesting chart or the most accessible data set. Work through the same evidence layers in the same order so that a plausible story does not outrun the facts.

    1. Confirm the business outcome. Compare equivalent conversion definitions and comparable periods. Determine whether the change sits in conversions, revenue, CPA, return on ad spend, or average order value. Check whether it is account-wide or concentrated in a particular campaign, topic, product, market, device, or landing page.
    2. Decompose the funnel. Inspect impressions, click-through rate, clicks, average CPC, conversion rate, and average order value. The arithmetic keeps the analysis honest: clicks are driven by impressions and click-through rate; conversions are driven by clicks and conversion rate; for commerce, revenue is driven by orders and average order value. Find the first meaningful component that changed.
    3. Inspect internal account state. Review budgets, bids, targeting, search terms, negatives, ads, Quality Scores, landing pages, tracking, and account change history. Match each change to the affected segment and date. A coincidental account edit is not automatically the cause, but it is a testable lead.
    4. Add market context. Look at competitor participation, competitor messaging, auction conditions, generic demand, and relevant market events. Joining account behavior with market behavior helps distinguish an internal failure from a broader shift. Timing can narrow the explanation, although it does not prove causation on its own.
    5. Check visibility across surfaces. For the same high-value topics, inspect paid coverage, organic rankings, and AI Overview presence. A paid keyword gap has a different priority when you already hold strong organic or AI visibility than when competitors occupy every visible surface.

    Keep the comparison grain consistent. If the outcome is measured weekly by market and campaign, do not explain it with a monthly global competitor trend. Align time zones, currencies, conversion definitions, attribution settings, and segment boundaries before drawing a conclusion. Otherwise, the data join can manufacture a shift that did not occur.

    The table below is a diagnostic starting point, not a set of automatic conclusions. Each pattern should produce a hypothesis and a verification step.

    Observed patternLeading hypothesesNext check or action
    Impressions fall while downstream rates remain steadyDemand, eligibility, budget coverage, or competitive participation changedSplit brand from non-brand, inspect budget and targeting status, then compare market demand and competitor presence
    Impressions hold but click-through rate fallsThe message no longer fits the query, a competitor has a stronger proposition, or the results page changedCompare creative by placement and query theme; inspect competitor messaging and AI Overview presence
    CPC rises while Quality Scores weakenAd or landing-page relevance may be deteriorating; competitive pressure may also have increasedLocate the affected campaigns, ads, queries, and pages before changing bids; add auction and competitor context
    Clicks remain steady but conversion rate fallsTraffic mix, landing-page behavior, offer fit, site function, or conversion measurement changedSegment by search term and landing page, verify tracking, and test the on-site path before buying more traffic
    Conversion rate holds but average order value fallsProduct, offer, customer, or order mix changedFind the affected commercial segment before altering acquisition settings
    Search terms spend without recorded conversionsThe traffic may be irrelevant, but conversion lag, low volume, or measurement gaps may be hiding valueValidate the window, tracking, query intent, and assisted value; add negatives only where exclusion is justified
    Generic market demand exists but non-brand coverage is thinBudget may be concentrated on branded demand while competitors capture discovery trafficRank the gaps by commercial relevance and plausible return, then account for existing organic and AI visibility

    This sequence also prevents channel teams from optimizing against each other. A PPC team can see a missing keyword and increase bids while the SEO team already owns the result. An SEO team can celebrate stable rankings while an AI Overview changes the visible path to the site. Performance intelligence treats those as parts of one demand landscape rather than separate scorecards.

    Make every visualization perform a diagnostic job

    A visual earns its place when it answers a defined question, eliminates an explanation, or supports a decision. A graph that merely makes a metric easier to look at is still reporting.

    Build your diagnostic sequence as a short evidence story:

    1. Establish the baseline. Use a trend view to show when the outcome changed. Split the line by the segment that matters, such as brand versus non-brand, market, campaign, topic, or landing page.
    2. Expose the mechanism. Decompose the movement into impressions, click-through rate, CPC, conversion rate, and average order value. Show which component moved first and where the change is concentrated.
    3. Test the cause. Add account changes, competitor participation, auction information, campaign launches, promotions, and relevant external events. Use them to compare explanations, not to decorate the timeline.
    4. Mark the intervention. Annotate the date and scope of the bid, budget, creative, targeting, content, landing-page, or measurement change.
    5. Show the resolution. Extend the same view beyond the intervention. State whether the expected signal appeared and whether the business outcome followed.

    This setup-conflict-intervention-resolution structure is useful because one chart rarely provides enough context to explain both a performance change and its cause. The sequence lets each view carry one part of the reasoning.

    Choose the format according to the question:

    • Line chart: Locate when a change began and whether an intervention coincided with recovery. Segment the line rather than relying on an account-wide average.
    • Metric heatmap: Find combinations that behave unexpectedly, such as strong placement paired with weak click-through rate. This is useful for creative triage because the contrast becomes visible immediately.
    • Calendar heatmap: Expose day- or week-level patterns around seasonality, launches, promotions, and operational events. Use it to generate a timing hypothesis, then verify the mechanism in the underlying metrics.
    • Word cloud: Scan dominant query or content themes, overlap, gaps, and possible cannibalization. Frequency is not commercial value, so validate promising themes against conversions, revenue, or another business outcome.
    • Exception table: Hand the team a finite work queue. Include only the affected entity, evidence, recommended action, expected effect, risk, and owner.

    Write chart titles as questions or findings. Traffic Trend forces the reader to interpret the graph. Non-brand traffic fell after eligible impressions declined tells them what to inspect. If the evidence cannot support that stronger title, use the question you are testing: Did competitor participation coincide with the CPC increase?

    Every visual should end with a short decision caption: what changed, the leading explanation, which alternatives were checked, what action is proposed, and what evidence is still missing. If no action is justified, name the next investigation and its owner. Uncertainty is acceptable; an ownerless ambiguity is not.

    Turn the diagnosis into a controlled action queue

    Tangled performance signals pass through a diagnostic prism and become an orderly queue of controlled actions, with one action highlighted.

    The deliverable is not the dashboard. It is a prioritized queue of changes that someone can review, execute, and measure.

    Each queue item should contain:

    • Problem: The business outcome and affected scope.
    • Evidence: The internal metric, account state, market context, and cross-surface coverage supporting the diagnosis.
    • Proposed action: The exact campaign, query set, creative, budget, landing page, or content area to change.
    • Expected signal: The first diagnostic metric that should respond and the business outcome expected to follow.
    • Confidence and gap: How strong the explanation is and what remains unknown.
    • Risk and rollback: What valuable traffic, data, or revenue the change could disrupt and how to reverse it.
    • Ownership: Who approves, who implements, and when the result will be reviewed.

    Prioritize with judgment rather than a single opaque score. Start with financial exposure, confidence in the diagnosis, urgency, reversibility, and learning value. A broken landing page or measurement failure deserves attention before a speculative keyword expansion. A reversible creative test can move ahead with less evidence than a large budget reallocation. A negative-keyword upload needs careful review because an incorrect exclusion can remove useful reach across Search, Shopping, or Performance Max.

    A practical order of work is to stop compounding loss, repair leading indicators, reallocate proven resources, and then test growth gaps. That usually means checking broken or outdated pages, tracking failures, and clearly irrelevant spend first; then addressing weak relevance or creative; then moving budget toward supported opportunities; and only then expanding into uncovered demand.

    Automation should follow the same progression. Begin with observation, move to evidence-linked recommendations, then generate an editable implementation file, and require approval before changes are applied. Limited automatic execution should come only after you have reliable inputs, explicit guardrails, monitoring, and a tested rollback path.

    Adthena describes a commercial version of this approach that joins advertiser account data with its market view and returns actions such as negative terms, copy changes, and budget moves. Its vendor-provided examples currently produce editable reports or upload-ready files, and the product is identified as Alpha. Treat that as a useful model for workflow design, not independent proof that every generated recommendation is correct.

    Before approving any machine-generated action, confirm that it exposes the evidence it used, the campaigns affected, the expected result, and the reversal method. Also verify account scope, time zone, currency, attribution settings, conversion definitions, and data freshness. A recommendation that cannot show its inputs is not performance intelligence. It is an instruction without an audit trail.

    Keep market context in the same evidentiary role. A competitor change that aligns with your decline is a serious lead, but timing alone does not prove the competitor caused it. Compare affected and unaffected segments, inspect the internal funnel, and use a reversible intervention where possible. The goal is not a confident story. It is a decision that can survive review.

    Key takeaways

    • Start with a pending decision, not a collection of metrics.
    • Trace the shift from business outcome to funnel mechanism, internal account state, market context, and cross-surface visibility.
    • Treat charts as diagnostic steps: establish the baseline, expose the mechanism, test causes, mark the intervention, and verify the result.
    • Turn every supported finding into an owned action with an expected signal, risk, rollback method, and review point.
    • Use paid, organic, and AI visibility together when evaluating gaps so one channel does not buy coverage another already provides.
    • Keep automated recommendations editable and auditable until their inputs, guardrails, and rollback process have earned greater authority.

    At your next performance review, choose one material shift and run it through the five evidence layers. Publish only the top supported action, its risk, and the signal you will remeasure. If the meeting ends with an observation but no decision or owned evidence gap, you still have a report – not performance intelligence.

    References