Tag: Analytics

  • How to Report AEO Metrics With the Right Confidence

    How to Report AEO Metrics With the Right Confidence

    Your AEO dashboard says visibility improved. Then leadership asks the question the dashboard was supposed to answer: How sure are we?

    A bigger percentage won’t solve that problem. You need to show what was directly observed, which conclusions depend on a sample, what could change on another run, and which decision the evidence supports. The goal is not to make uncertain metrics look certain. It is to make every claim appropriately confident.

    A hard number is only hard inside its measurement boundary

    Every AEO result has two parts: the observation and the claim built on it. AEO reporting becomes more defensible when it separates hard observations from probabilistic trends.

    If an archived response contains a citation to your domain, that citation is a recorded fact about that response. If your domain was cited in a defined portion of a fixed test set, the resulting citation rate is an exact calculation for that dataset. Neither fact guarantees that the next response will cite you, that every user sees the same answer, or that your visibility across the entire platform equals the measured rate.

    This is the distinction most reports lose. An exact calculation can support a narrow claim with high confidence while supporting a broad claim with very low confidence. The metric itself is not permanently deterministic or probabilistic. Its confidence depends on the boundary of the statement you attach to it.

    Evidence layerWhat it can establishWhat it cannot establish by itself
    Archived answerThe brand, domain, page, or competitor appeared in that recorded outputWhat every user will see or what a future run will return
    Calculated sample metricThe rate or count within the stated prompt set and measurement windowVisibility across prompts, platforms, locations, or settings outside that scope
    Repeated directional patternWhether comparable observations are moving consistentlyThat the movement will continue or applies to the entire market
    Attributed business resultWhat the configured analytics system connected to tracked visits and actionsAll influence from AI answers or proof that one optimization caused the result

    Before publishing a metric, test its wording with three questions:

    • Can another analyst inspect the underlying record and reproduce the calculation?
    • Does the sentence name the prompt set, platform, settings, and measurement window it covers?
    • Would the sentence remain true if the next generated answer were different?

    If the last answer is no, the metric may still be useful. It simply needs probabilistic language: the test indicates, the observed sample moved, or the pattern is consistent with a change. Do not silently upgrade that language to proves, guarantees, or caused.

    Build the measurement protocol before you build the dashboard
    A top-down research table shows blank query cards, a sampling frame, timing tools, and matching trays arranged for repeated measurement runs.

    Confidence is largely determined before the first chart appears. A polished dashboard cannot repair a shifting prompt set, undocumented exclusions, or missing raw answers. Write the measurement protocol first so that an improvement means the same thing from one reporting window to the next.

    1. Name the decision. Decide whether the metric will guide content updates, technical investigation, competitive positioning, investment, or simple monitoring. A metric that cannot change a decision is usually reporting decoration.
    2. Define the eligible prompt universe. Group prompts by a meaningful dimension such as user intent, product category, audience, or buying stage. Record why each prompt belongs. Do not quietly add favorable prompts or remove difficult ones after seeing the outputs.
    3. Record the test environment. Capture the answer product or platform, the model or version when exposed, relevant modes or features, locale, account or session condition when relevant, and the measurement date or window. If one of these changes, flag the comparison instead of presenting it as continuous.
    4. Set inclusion rules in advance. Decide how errors, refusals, empty answers, duplicate prompts, unavailable features, citations to third-party pages, and brand-name variants will be handled. State which responses enter the denominator.
    5. Preserve the evidence. Keep the full response, cited URLs, prompt, collection context, and outcome classification. Screenshots can help reviewers, but structured records make recalculation, filtering, and auditing possible.
    6. Use an explicit numerator and denominator. A citation rate should resolve to cited eligible responses divided by all eligible tested responses. A percentage without its denominator hides sample changes and makes a small movement look more conclusive than it is.
    7. Choose the comparison before reading the result. Compare like with like: the same prompt definition, eligibility rules, platform conditions, and calculation method. Version a changed prompt set rather than blending it into the previous baseline.

    Also write down the classification rules. Does a linked product page count as an owned-domain citation? Does an unlinked brand name count as a mention? Are spelling variants normalized? Can one answer contribute more than one citation? These choices are not clerical details. They determine what the metric means.

    When a method changes, annotate the break. You can still show the new result, but do not draw an uninterrupted trend line across measurements that answer different questions. A visible gap is more trustworthy than false continuity.

    Attach confidence to the claim, not the score
    A solid evidence block supports a translucent structure whose outer edges fade beyond nested glass boundaries.

    Confidence and performance are separate dimensions. You can have a high-confidence finding that visibility is weak, or a low-confidence indication that visibility improved. Green arrows should never determine confidence labels.

    A simple three-level rubric is usually enough for an operating report:

    • High confidence: The underlying records are preserved, the calculation is reproducible, the scope is explicit, inclusion rules are stable, and the statement stays within the observed dataset. Use this label for facts such as what appeared in an archived sample, not as a promise about future outputs.
    • Moderate confidence: Comparable observations point in the same direction, but platform variability, incomplete controls, a changed condition, or limited coverage prevents a stronger generalization. The pattern may justify a focused test or investigation.
    • Low confidence: The conclusion depends on a sparse or one-off observation, a moving prompt set, unclear eligibility, missing raw evidence, or a causal leap. Treat it as a hypothesis, not as a reason for a broad intervention.

    These labels are governance shorthand, not statistical confidence intervals. Do not attach a probability or a scientific-sounding precision unless you have actually used a method that warrants it. A plain explanation such as confidence is moderate because the direction repeated but one platform setting changed is more informative than an unexplained confidence score.

    Apply the label to the sentence, not merely to the dashboard tile. The statement our domain appeared in this archived test set may deserve high confidence. The statement our domain is now more visible to all prospective customers may be low confidence even when it is based on the same records.

    Every confidence label should therefore carry a reason. If your team cannot finish the sentence confidence is moderate because…, the label is not doing useful work.

    Give leadership a scoped result and a decision

    Leadership usually does not need the full prompt-level dataset in the first view. It does need enough context to know whether the metric can support a decision. Each headline metric should include five fields: result, scope, comparison, confidence, and next action.

    Reporting template: Within [measurement window], [brand or domain] was [mentioned or cited] in [numerator] of [denominator] eligible responses for [defined prompt set] on [platform and relevant settings]. Compared with [comparable baseline], the result [direction]. Confidence is [level] because [reason]. We will [decision or next test].

    That format prevents a common reporting failure: turning a test result into a claim about the whole market. It also forces the report to say what happens next. If no action changes, the metric may belong in an appendix rather than the executive scorecard.

    Keep visibility, traffic, and outcomes separate

    These layers answer different questions and should not be collapsed into one opaque AEO score.

    • Visibility asks whether you appeared. Useful measures include brand mention rate, owned-domain citation rate, cited-page distribution, and competitor co-mentions. Each rate must be tied to an eligible answer set.
    • Traffic asks whether a trackable visit followed. Report AI-referral sessions as visits your analytics configuration classified that way. Do not describe them as the total audience influenced by AI answers.
    • Outcomes ask what tracked visitors did. Report configured conversions or other relevant actions among attributable visits. Keep this separate from the broader claim that AEO caused business growth.

    A citation is not a visit, and a visit is not a conversion. Conversely, flat referral traffic does not erase a visibility gain. An answer may expose the brand without producing a click, or it may satisfy the immediate question inside the answer interface. Report each layer for what it measures instead of forcing all three to move together.

    Show the denominator and the segment before the aggregate

    A portfolio-wide average can conceal the decision you need to make. Break visibility out by stable prompt groups before rolling it up. A gain in informational prompts does not automatically offset a decline in commercial prompts, and movement in one product category may have no bearing on another.

    Put the numerator and denominator beside every rate. If the eligible set changed, show the previous and current scope or mark the series as non-comparable. Never let an audience infer stability from a line chart when the measurement base moved underneath it.

    Use confidence to choose the next action

    • High-confidence visibility decline: Inspect the archived answers by prompt group, cited domains, and cited pages. Identify where inclusion changed before rewriting content across the site.
    • Low-confidence movement in either direction: Repeat a comparable collection and repair the measurement gap. Do not launch a broad content or technical change to chase noise.
    • Visibility improves while tracked referrals stay flat: Review which pages are cited, whether the answer leaves a reason to click, and whether referral classification is working. Keep visibility and click behavior as separate findings.
    • Tracked referrals rise while outcomes remain weak: Check landing-page intent, conversion instrumentation, and the path from cited page to desired action. More arrivals do not establish that the visit experience is relevant.
    • Business results improve after an AEO change: Report the observed association unless the measurement design can isolate causation. Timing alone does not prove that the optimization produced the outcome.

    The most useful limitation is specific and operational. Prompt coverage excludes support queries tells leadership what is outside the claim. Results may vary is too vague to guide anyone. Name the missing scope, changed condition, or attribution boundary, then state whether you will fix it, monitor it, or accept it.

    Key takeaways

    • An AEO count can be exact for an archived dataset while the broader behavior it represents remains probabilistic.
    • Confidence belongs to a specific claim. It should not rise merely because the performance metric rose.
    • Preserve prompts, full outputs, settings, inclusion rules, numerators, and denominators so another analyst can audit the result.
    • Separate answer visibility, analytics-classified traffic, and tracked business outcomes. Each layer supports a different decision.
    • Use high-, moderate-, or low-confidence labels only when each label includes a plain-language reason.
    • Give every executive metric a scope, comparable baseline, limitation, and next action.

    Before sending your next AEO report, take its most important sentence and underline four things: the evidence, the boundary, the confidence reason, and the decision. If one is missing, the sentence is not ready. Fixing that sentence will do more for reporting credibility than adding another chart.

    References


  • SEO Career Signals That Prove You Can Drive Business Value

    SEO Career Signals That Prove You Can Drive Business Value

    You can be excellent at keyword research, technical audits, content briefs, internal linking, and structured data and still struggle to explain why you should be hired, promoted, or protected when budgets tighten. If your evidence stops at completed tasks, you are showing competence in work that software can increasingly accelerate.

    The career question has shifted from Can you find SEO work? to Can you identify the work worth doing, earn its priority, and connect it to a business result? This is how you build career signals that answer that question with evidence.

    Key takeaways

    • SEO fundamentals remain necessary, but they no longer distinguish you on their own.
    • Your strongest career signal is a well-supported decision under real constraints, not the size of an audit or task list.
    • A recommendation should identify the business effect, proposed action, tradeoff, dependency, and proof of success.
    • Your portfolio should show how your reasoning changed a decision, influenced implementation, and affected an outcome.
    • AI fluency matters when you can verify its output and apply judgment, not merely generate more deliverables.

    Make business judgment your primary SEO signal

    AI can already draft audits, summarize search results, suggest content briefs, write metadata, identify schema gaps, and assemble roadmaps. Knowing how to produce those deliverables still matters. Treating their production as your main value does not.

    A strong career signal is observable evidence that you can make a useful choice when the answer is not sitting in a checklist. It shows that you understand what the company sells, why customers choose it, where organic discovery supports the buying journey, and what the business would have to give up to pursue your recommendation.

    Before proposing work, force the opportunity through these questions:

    • Which business or customer outcome is constrained? Name the decision, transaction, lead, adoption step, or customer need that the work is meant to support.
    • What evidence makes this an organic-search problem? Separate observed search behavior, crawl or indexation evidence, page performance, and customer behavior from assumptions.
    • What happens if the company does nothing? Describe the likely cost of delay without manufacturing urgency.
    • What are the realistic alternatives? Compare the SEO proposal with product, engineering, content, brand, paid distribution, or no action.
    • What is the smallest useful move? Define the change that can test the reasoning before asking for a broad program.
    • What evidence would change your mind? Decide in advance what would cause you to expand, revise, or stop the work.

    Put the answers into a short opportunity brief. Its purpose is not to display everything you know. It should help someone choose among competing uses of time and money.

    • Situation: the relevant business context and verified search condition.
    • Effect: the customer or commercial consequence of that condition.
    • Options: plausible responses, including doing nothing.
    • Recommendation: the action you prefer and why it is the best available choice.
    • Tradeoff: the engineering, editorial, design, or analytical capacity the action requires.
    • Dependency: the people, systems, approvals, and release conditions needed for implementation.
    • Evidence plan: the leading and business indicators you will examine, plus any limits on interpretation.

    This format exposes weak reasoning early. If you cannot connect a proposed content cluster, template change, or schema implementation to a meaningful problem, you may have found a valid best practice without finding a priority.

    Use a simple prioritization ladder when requests compete:

    • Act: the evidence is strong, the affected journey matters, and delay has a credible cost.
    • Validate: the opportunity is plausible, but a limited investigation or reversible test should come before substantial investment.
    • Schedule: the work has a reasonable path to value but loses to a more consequential constraint.
    • Decline: the request has no convincing path to a customer or business outcome, or another intervention addresses the problem more directly.

    Saying no is part of this skill. The useful version of no sounds like this: The concern is real, but this action is unlikely to resolve it because the evidence points to a different constraint. We recommend addressing that constraint first, then reassessing this request with the resulting data. You are not blocking work; you are making the opportunity cost visible.

    You also need to recognize when the problem is not SEO. A page that earns visits but fails to move people forward may have a product, pricing, positioning, user-experience, or conversion-path problem. Weak brand recognition may limit demand that another content campaign cannot create by itself. Strategic SEOs can identify those boundaries instead of prescribing SEO for every symptom.

    Your career signal is not that you can personally fix every adjacent problem. It is that you can diagnose the boundary, involve the right owner, and prevent the company from spending on the wrong remedy.

    Build a portfolio around decisions, influence, and outcomes

    Two colleagues review a portfolio-like case containing abstract research cards, prioritization tokens, a product model, and illuminated outcome blocks.

    A ranking chart, audit export, or traffic graph shows an event. It does not show whether you understood the business, selected the right intervention, influenced the people who controlled implementation, or interpreted the result responsibly. Even a long tenure is not proof that your decisions made the business better.

    Rebuild each portfolio example as an evidence chain:

    • Context: what the company sold, who the relevant customer was, and where organic discovery fit in the journey.
    • Constraint: the verified problem and why it mattered at that moment.
    • Diagnosis: the evidence you used, the uncertainty that remained, and the non-SEO explanations you considered.
    • Decision: what you recommended, what you explicitly did not recommend, and why.
    • Influence: how you adapted the case for the people whose support or work was required.
    • Implementation: what actually shipped, how it differed from the original proposal, and what compromises were accepted.
    • Outcome: what changed in search behavior, customer behavior, or business performance, without claiming causation the evidence cannot establish.
    • Learning: what the result confirmed, what it disproved, and what you changed next.

    The rejected options are important. They reveal judgment. If you chose a template-level fix over manually editing many pages, explain the operational reason. If you accepted a technically imperfect release because the remaining issue did not justify delaying a customer-facing launch, describe the tradeoff. If you stopped a content plan after discovering that product positioning was the real constraint, show that decision.

    Do not retrofit a commercial success story onto evidence that only supports a search result. Use the strongest claim the data permits:

    • If you only know that the recommendation was accepted, say that.
    • If you know the change shipped and technical validation passed, show that implementation proof.
    • If visibility or qualified visits changed, distinguish that from revenue or lead impact.
    • If conversions changed but attribution is uncertain, state the uncertainty and identify other contributing factors.
    • If nothing improved, explain what you learned and why the next decision became better.

    This makes modest projects useful portfolio material. You do not need to manufacture a dramatic win. Preventing low-value work, clarifying measurement, narrowing an oversized initiative, or uncovering a non-SEO constraint can demonstrate better judgment than a lucky ranking gain.

    Select examples that match the level of role you want. Early-career evidence should make your analytical discipline and ownership visible. Mid-career evidence should show prioritization, cross-functional execution, and measurement. Senior evidence should show how you allocated scarce resources, managed uncertainty, improved the decision system, and connected search investments to company strategy.

    Keep confidential information out of public materials. Replace identifying details with truthful descriptions, remove proprietary data, and never imply that anonymized figures are precise if you have transformed them. You can demonstrate reasoning without exposing an employer or client.

    Make communication part of SEO delivery

    A technically correct recommendation that nobody implements creates no business result. That is why communication determines whether SEO receives resources, priority, implementation, and a connection to revenue. It is not decoration added after the analysis. It is part of delivering the work.

    A line item such as implement schema or improve internal linking describes activity. It leaves the decision-maker to work out why the activity matters, whether it outranks other work, and how anyone will know it helped. A decision-ready recommendation supplies that missing logic:

    • What is happening: the condition you verified, stated without unnecessary jargon.
    • Why it matters here: the affected customer journey, product area, operational process, or commercial objective.
    • What inaction means: the credible consequence of waiting or declining.
    • What should happen first: a specific, bounded action rather than a broad aspiration.
    • What the team is trading: the capacity, release risk, or competing work involved.
    • How you will evaluate it: implementation checks, leading indicators, business measures, and interpretive limits.

    For example, turn a generic schema ticket into a decision: the affected template currently presents inconsistent product facts between visible content and machine-readable fields; standardize the underlying fields and generate matching structured data from that source; prioritize the work only if it addresses a verified inconsistency on commercially important pages or supports a relevant eligible search experience; acknowledge the required template engineering time; validate the output and observe the intended search behavior without promising that a platform will display it.

    The technical action is still present, but the recommendation now tells a team why it deserves attention and what success does and does not mean.

    Adapt the same recommendation to the person receiving it:

    • Leadership needs the outcome, confidence level, resource request, downside of delay, and opportunity cost.
    • Engineering needs a reproducible condition, affected scope, constraints, acceptance criteria, release risk, and validation method.
    • Content teams need the audience need, editorial gap, evidence standard, distribution path, and definition of a useful page.
    • Analytics teams need the question being measured, required data, event logic, comparison method, and known attribution limits.

    Do not end an update with information alone. State the decision you need, who needs to make it, what input remains unresolved, and what happens after approval. Record the owner and next checkpoint. This turns communication into forward movement instead of another status artifact.

    Measure your influence as well as the search result. Useful evidence includes whether the recommendation was understood, accepted, funded, correctly implemented, and incorporated into later planning. Those milestones do not replace business outcomes, but they show where delivery succeeded or failed.

    Use AI to raise the standard of your work

    An SEO specialist reviews abstract AI-generated options, verifies one with research tools, and shares the refined result with two colleagues.

    AI lowers the cost of producing plausible SEO output. It does not remove the need for technical knowledge, content judgment, analytics, distribution, or an understanding of how search and answer engines work. It raises the standard for what you do after the first draft appears.

    Prompt fluency alone is a weak career signal. A stronger AI workflow makes your judgment auditable:

    • Frame the question: define the business decision before asking a model for an audit, summary, classification, or plan.
    • Control the inputs: provide relevant first-party information and distinguish it from assumptions or generic best practices.
    • Verify the output: check technical claims against the site, search behavior, platform requirements, analytics, and customer context.
    • Find the omission: look for product, brand, pricing, user-experience, operational, and measurement factors the generated answer did not consider.
    • Make the decision: choose what to act on, test, defer, or reject, and document the tradeoff.
    • Close the loop: compare the result with the original reasoning so the next decision improves.

    This distinction is especially important in AI SEO, AEO, and GEO work. A third-party visibility score may help you observe change, but it is not the business outcome. Search rankings, sessions, and third-party AI visibility scores should not be mistaken for the purpose of the work. Use them as diagnostic indicators and connect them, where the evidence allows, to relevant queries, brand representation, qualified behavior, customer decisions, conversions, or another defined business objective.

    You should also be able to explain the boundary between what your team controls and what a search or answer platform controls. You can improve accessible content, factual consistency, structured data, internal connections, source clarity, and technical availability. You cannot guarantee that a platform will crawl, index, rank, cite, summarize, or display the material in a particular format. Clear boundary-setting is a professional signal because it protects decision quality from inflated promises.

    Before your next interview or performance review, open a recent deliverable and remove the task list from its opening. Replace it with the constrained outcome, verified evidence, options considered, recommended decision, required tradeoff, implementation record, and strongest defensible result. Then ask whether someone outside SEO could understand why the work mattered.

    If the answer is no, you do not need another checklist yet. Rewrite that project until it proves that you can choose well, bring other people with you, and connect organic discovery to a result the organization actually values. That is the career signal worth building next.

    References


  • SEO for Task Completion: Turn Rankings Into Outcomes

    SEO for Task Completion: Turn Rankings Into Outcomes

    You can rank first for a valuable query and still have an underperforming page. If visitors cannot find the price, confirm that your offer fits, or take the next step without hunting for it, visibility has delivered traffic but not the outcome they came to achieve.

    SEO for task completion closes that gap. It treats the searcher’s finished job as the target, then aligns the content, user experience, conversion path, and measurement around that job. The result is a page that does more than attract a click: it helps the right person reach a useful conclusion or complete a meaningful action.

    Treat the searcher’s finished job as the SEO target

    A keyword tells you how somebody expressed a need. It does not fully describe what they must accomplish after clicking.

    Consider a search for enterprise marketing automation pricing. The literal request is for a price, but the practical job may be to establish whether the product fits an approved budget and gather a defensible number for finance. A page that replaces pricing with a feature tour has covered the topic without completing the task.

    This distinction applies beyond commercial queries. Someone searching for an integration wants to know whether two systems work together and what limitations apply. Someone searching for a comparison needs enough evidence to eliminate unsuitable options. Someone following a technical how-to needs to reach a working end state, not merely read an explanation.

    The primary task is also not automatically your preferred conversion. A reader may need an honest compatibility answer before a trial makes sense. If you hide that answer behind a form, you have optimized the page for lead capture at the expense of the reason the visitor arrived.

    Key takeaways

    • Define what the visitor must decide, obtain, or complete before you revise the copy.
    • Put the decisive answer before background information and brand messaging.
    • Map the entire route from the search result to the confirmation state, including forms and other pages.
    • Measure completed tasks and intermediate drop-offs alongside rankings and organic traffic.
    • Use structured content and schema to clarify a useful page, not to compensate for missing answers or a broken journey.

    Write a task statement before changing the page

    Start each important landing page with one plain sentence that defines success. A useful template is: For this specific searcher, help them make this decision or complete this action by providing this information or proof, then give them a clear finish line.

    That produces statements such as:

    • Help a marketing leader determine whether the platform fits a 50-person sales team, collect evidence for an internal recommendation, and book a relevant demonstration.
    • Help a buyer establish the realistic price range and cost drivers, then request an exact quote if the range fits the budget.
    • Help an administrator confirm that the integration supports the required system and understand the setup path before starting configuration.
    • Help a prospective franchise owner confirm territory availability and investment requirements before requesting a call.

    If your statement says only that the visitor wants to learn about a subject, it is probably too broad. Replace learn with an observable verb: choose, compare, calculate, verify, configure, book, buy, apply, or call. The verb forces you to identify what done looks like.

    A strong task statement contains four parts:

    • The person and context: Who is searching, and what constraint shapes the decision?
    • The immediate job: What must the person decide or do during this visit?
    • The required evidence: Which price, limitation, comparison, proof point, instruction, or eligibility condition makes that decision possible?
    • The finish line: What visible event shows that the task was completed?

    Use the statement to control scope. Every major section should either answer a necessary question, reduce uncertainty, or move the visitor toward the finish line. Content that does none of those things is competing with the task.

    Choose one primary task per landing page. You can support secondary actions, such as downloading specifications or contacting support, but they should not compete visually with the main path. If two audiences need substantially different answers and finish lines, separate pages will usually produce a clearer experience than one page trying to serve everyone.

    Map every step between the search result and completion

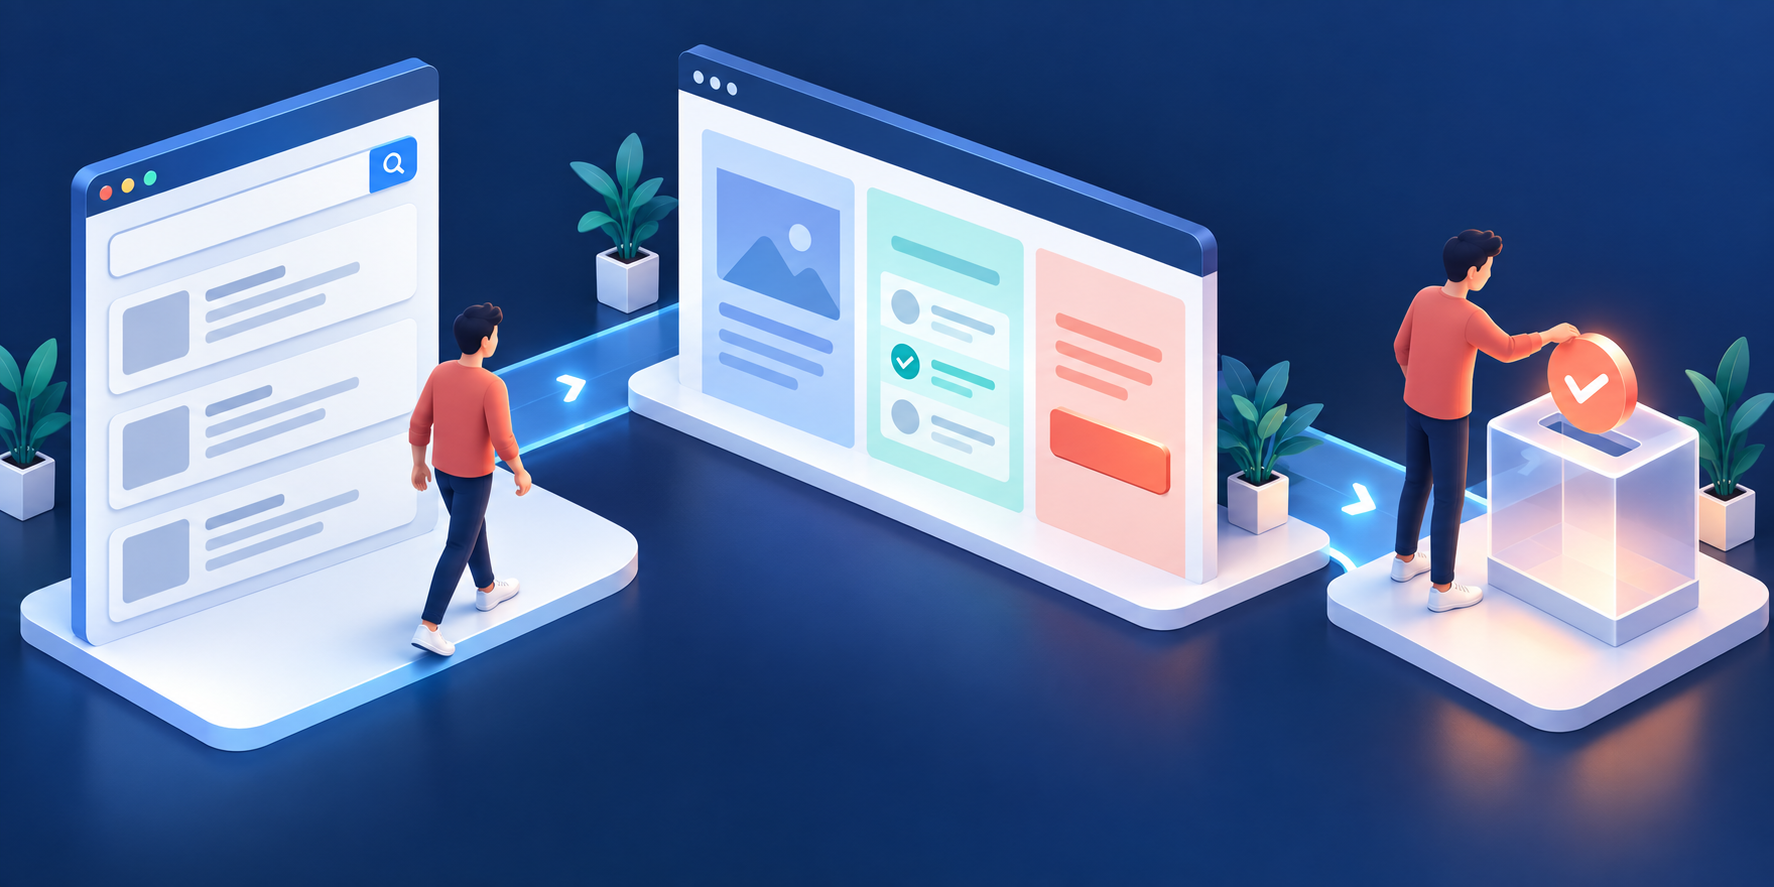
    Overhead illustration of a person following a connected route from search results through information, decision, and action stages to a completion point.

    The journey begins before the landing page. The title and search snippet make a promise; the first screen must confirm it. If the result promises pricing but the visitor lands on a general product overview, the path is already broken.

    Write the shortest credible route as a sequence. A commercial path might look like this:

    1. Recognize that the page answers the query.
    2. Confirm essential fit, such as price range, compatibility, availability, or eligibility.
    3. Review enough evidence to make the decision defensible.
    4. Take the next action, such as booking, purchasing, applying, or calling.
    5. Reach a confirmation state that explains what happens next.

    Do not stop the map at the call-to-action button. Include the form, calendar, cart, account requirement, payment step, confirmation screen, and any page transition between them. A landing page can perform well while an unavailable appointment calendar or confusing form destroys the overall completion rate.

    For each step, record four things: the question in the visitor’s mind, the page element that answers it, the action that advances the task, and the failure mode that can stop progress. This makes vague concerns such as weak UX diagnosable.

    Typical blockers include:

    • A decisive fact is absent, qualified beyond usefulness, or placed far below promotional copy.
    • Supporting information lives on another page with no obvious link from the decision point.
    • The CTA uses a vague label such as Learn more even though the next step is specific.
    • A form asks for information that is not needed to deliver the requested response.
    • The mobile layout hides the action, rearranges the evidence, or makes input difficult.
    • The confirmation screen fails to say whether the submission worked or what the visitor should expect next.

    Pay attention to searches that occur in the middle of a larger task. A calculator, compatibility checker, territory finder, or structured comparison can be more useful than another broad landing page because it meets the visitor at the precise point where progress has stopped. Connect that tool directly to the next logical action instead of leaving it as an isolated traffic asset.

    Walk the path yourself on a mobile device while signed out. Start from the search-result promise, use only the information a new visitor would have, submit the form, and inspect the confirmation. Mark blockers before cosmetic imperfections. A missing price range matters more than a button color; a failed form matters more than either.

    Build the page in answer, decision, and action layers

    A task-focused page needs three layers in a deliberate order. The answer layer confirms relevance. The decision layer supplies evidence and constraints. The action layer makes completion obvious. This structure serves human readers while also making the page easier for search and answer systems to interpret.

    Lead with the decisive answer

    The first screen should resolve the visitor’s largest uncertainty. For pricing intent, show a real price, a useful range, or a clear explanation of the variables required to calculate one. For integration intent, state whether the connection exists and name important limitations. For local availability, let the visitor check the relevant market without reading the company history first.

    Supporting detail can follow. The order should mirror the decision: direct answer, qualification, evidence, action. A hero video or broad claim about innovation should not push the requested information several screens down.

    Use descriptive headings, short definitions, lists for criteria, and tables only where readers genuinely need row-by-row comparison. These elements improve scanning and create self-contained passages that answer engines can understand without stripping away essential context.

    Remove technical and interaction friction

    Performance is part of task completion. If the largest page element takes longer than about 2.5 seconds to render, it has missed Google’s benchmark for a good Largest Contentful Paint score. A visitor cannot act on an answer that has not appeared. Layout movement is similarly disruptive when it shifts a button or form just as someone tries to use it.

    Audit forms field by field. Keep a field only if it is required to complete the request, route it correctly, or support an agreed follow-up. If the immediate response only requires a name, email address, and contact method, extra qualification fields create work before the visitor has received value. Put deeper qualification into the later conversation when possible.

    Error messages should identify the exact problem without clearing valid entries. Buttons should describe the action they initiate: Book a demo, Check availability, Calculate cost, or Start the application is clearer than Submit or Continue. Place the primary CTA close to the decisive answer and repeat it after substantial evidence when the page is long.

    Connect SEO, AEO, GEO, and conversion without confusing them

    An extractable answer and a usable next step serve different parts of the same journey. Concise answers, clear entities, descriptive headings, and accurate structured data can help search and AI systems understand the page. They cannot make an unavailable product purchasable or turn a confusing form into a completed application.

    If you add JSON-LD, make it describe content and offers that visitors can actually see and use. Schema is a machine-readable representation of the experience, not a substitute for the experience. The price, availability, eligibility rule, or answer must exist on the page before its markup can clarify anything.

    The need for a strong action layer grows as AI results absorb informational demand. In Seer Interactive’s tracking, organic CTR on queries with AI Overviews reached 1.3% in December 2025 and recovered to 2.4% by February 2026, compared with roughly 3.8% on searches without an AI Overview. Those figures describe that tracked dataset rather than a universal forecast for every site, but the operational lesson is useful: the clicks that remain deserve a page capable of completing work an AI summary cannot perform, such as booking, buying, applying, or calling.

    Measure the completed task and locate the failed step

    Analyst examining an abstract multistage user pathway on a monitor where several user markers drop off before completion.

    Rankings, impressions, click-through rate, and organic sessions tell you whether people can discover and enter the page. They do not tell you whether the page helped them finish. Add an outcome metric and a small set of diagnostic events to every priority landing page.

    Use a measurement hierarchy:

    • Primary completion: The event that represents the finished task, such as a confirmed booking, completed purchase, submitted application, successful quote request, or completed configuration step.
    • Next-step progression: The proportion of eligible organic visitors who move from the landing page into the required next stage.
    • Form completion: Completed forms divided by form starts. This separates weak intent from a form that loses people after they begin.
    • Diagnostic events: Interactions that expose where progress stopped, such as opening pricing details, starting an eligibility check, clicking the CTA, encountering an error, or abandoning a required field.

    Define the denominator before reporting a rate. Task completion rate should usually be completed primary tasks divided by eligible organic landing sessions, not all site sessions. Exclude traffic that could not reasonably perform the action, such as visitors landing on support content when you are evaluating a sales journey.

    Read search and completion metrics together. The combination narrows the diagnosis:

    Observed patternMore likely problemInspect next
    Rankings and impressions declineDiscovery, relevance, or technical visibilityIndexing, query fit, internal links, and whether the page still satisfies the search
    Rankings remain stable but organic visits declineSearch-result click-through or a changing results pageTitle and snippet promise, competing result formats, and AI Overview presence
    Organic visits remain stable but completions declineLanding-page or journey frictionAnswer placement, device performance, CTA visibility, and changes to the offer
    CTA clicks remain stable but completed actions declineDownstream failureForm errors, unnecessary fields, calendar availability, cart steps, and confirmation behavior

    A quick return to the results page deserves attention because Google’s ranking systems, including Navboost, distinguish click patterns associated with satisfied and unsatisfied searches. That does not make every short visit a penalty or every single-page session a failure. Someone may find a phone number, copy a configuration value, or get a complete answer without triggering another pageview. Treat repeated return-to-search behavior as a risk signal, then confirm the likely cause with the funnel data you can observe.

    When you test a change, start at the largest observed drop rather than the easiest element to redesign. Set one primary success event, record the current path, make one coherent change, and watch downstream guardrails such as lead quality or purchase completion. If traffic is too limited for a reliable controlled test, use the form errors, device breakdowns, progression rates, and support questions you already have to choose the clearest blocker, then document the change and compare the same metrics after release.

    Keep a task record for each priority page: query group, task statement, primary completion event, path stages, largest observed drop, current owner, and next change. Revisit it during the normal SEO reporting cycle and whenever pricing, availability, forms, page templates, or search-result features change. That turns task completion from a one-time conversion project into a durable part of SEO operations.

    Start with the high-traffic landing page whose business outcome is weakest. Write its task statement, walk the full path on mobile, and remove the first blocker that prevents a qualified visitor from finishing. Keep the ranking report, but judge the next release by whether more people reach the end of the job.

    References


  • Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    If increasing ad revenue has made your pages feel crowded or slow, you no longer have to settle the argument with screenshots and opinions. Chrome can now expose four separate dimensions of ad load through real-user data: how many ads people see, how much space those ads occupy, how many bytes they consume, and how much processing time they require.

    The useful move is not to chase the lowest possible number. It is to find the page patterns where advertising consumes more attention or resources than the commercial return justifies, then reduce the specific cost without weakening the rest of the business.

    The four metrics reveal different kinds of ad load

    Chrome has added four experimental advertising metrics to the Chrome User Experience Report, commonly called CrUX. Treat them as four diagnostic signals, not as interchangeable measures of whether a page has too much advertising.

    MetricWhat Chrome measuresWhat it helps you notice
    Ad CountThe average number of ads visible in the viewportHow many detected ads compete for the user’s visible attention at the same time
    Ad DensityThe average percentage of the viewport occupied by adsHow much of the visible screen advertising takes over, regardless of the number of placements
    Ad Weight – NetworkThe bytes consumed by advertisingThe data cost of the detected ad experience
    Ad Weight – CPUThe processing time consumed by ads, measured in millisecondsThe execution cost imposed by ad-related resources and scripts

    The distinction matters because a single large placement can create high density without a high count. A collection of small placements can raise count while occupying less space. A visually restrained layout can still transfer substantial data or consume considerable processing time.

    Read the metrics in combination:

    • Count and density rise together: Start with the layout. Too many placements may be visible concurrently, and they collectively occupy more of the screen.
    • Density rises while count stays near your cleaner-page baseline: Investigate placement size and persistence before removing every slot. One dominant unit may be the main difference.
    • Network weight rises while count and density remain stable: The visible layout is not telling the whole story. Inspect the advertising payload and repeated resource requests.
    • CPU weight rises by itself: Concentrate on execution. Reducing visible ad space will not necessarily address script-related processing cost.
    • The four signals stay near your baseline but commercial results remain weak: Do not assume ad load is the cause. Creative relevance, audience fit, placement quality, or another factor may deserve attention first.

    This gives you a better decision model than a blanket instruction to run fewer ads. You can identify whether the problem is competition for space, data transfer, processing, or a combination of them.

    Understand what Chrome is actually observing

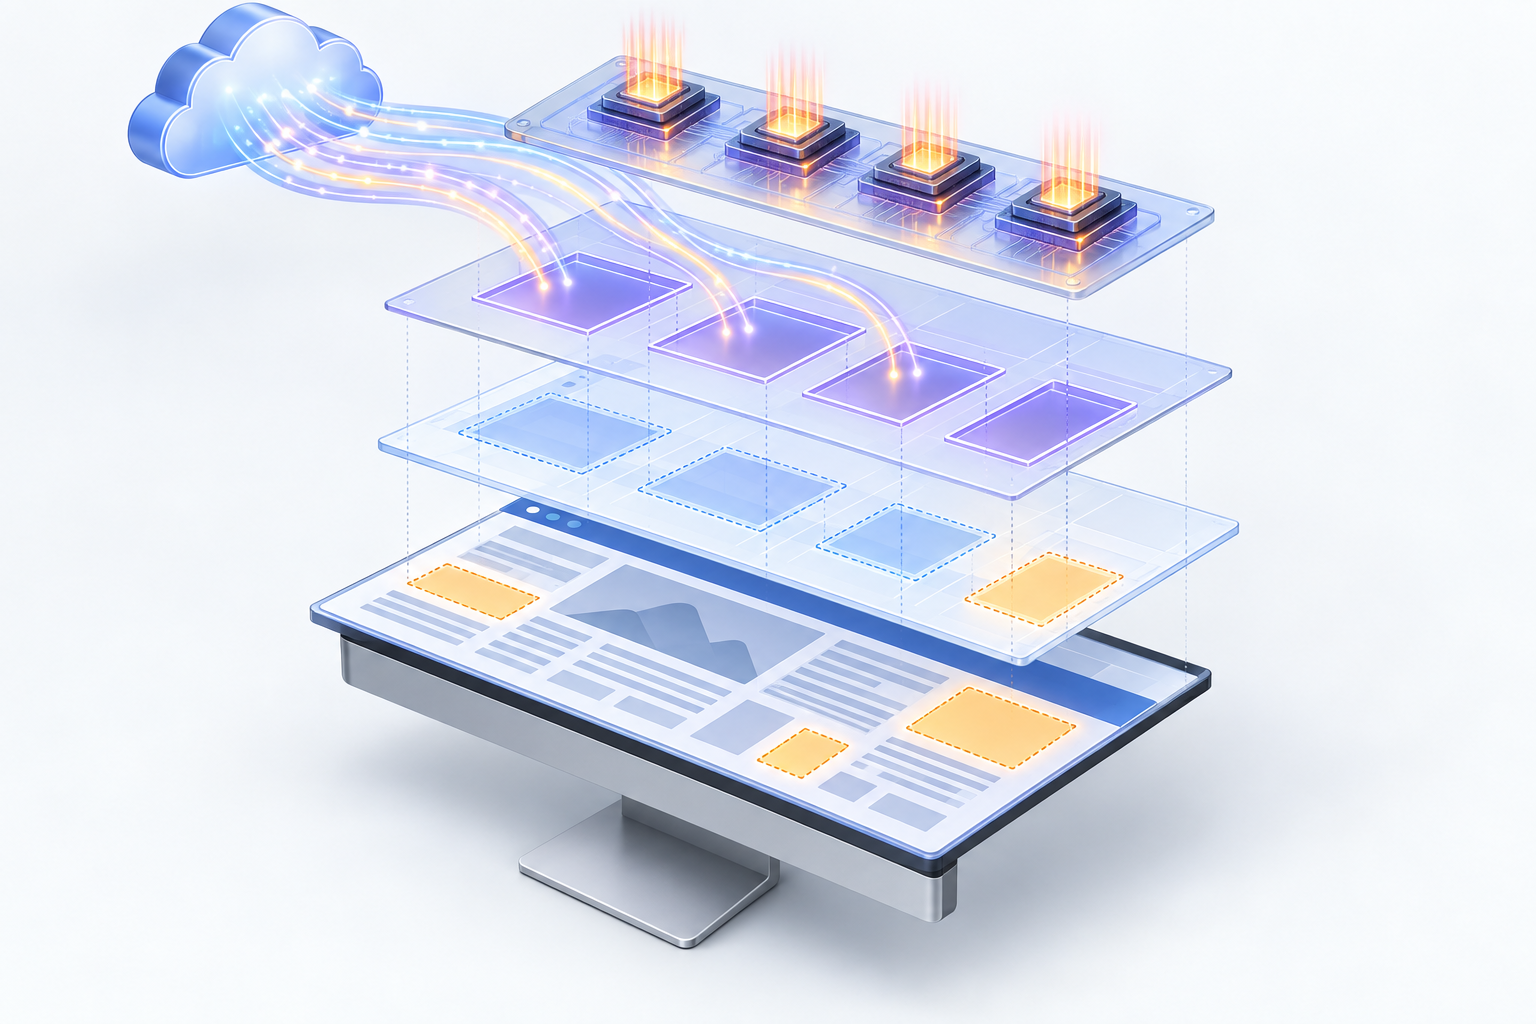
    Four floating webpage layers depict visible ad placements, their occupied area, incoming data, and processor activity above a computer monitor.

    Your ad server, content management system, and Chrome do not necessarily count the same thing. Your systems know which slots, campaigns, or line items you configured. Chrome detects advertising from the browser side.

    Chrome uses network-level filtering and script-execution analysis to identify ads. It can classify a URL as advertising when that URL matches its ad filter list. It can also recognize resources or frames created by scripts that have already been identified as ad-related.

    Ad Count should therefore be read as a count of ads Chrome detected in the visible viewport, not as a count of the placements declared in your page template. When an internal slot report and the Chrome metric differ, first check whether the two systems are measuring the same object. Do not label either figure incorrect merely because it does not match the other.

    Timing changes the interpretation too. Chrome samples the visible viewport once per second for Ad Count and Ad Density. Network and CPU usage accumulate through the user’s session. CrUX then reports the results at the 75th percentile.

    • A screenshot is not a session. A page may begin with a restrained layout and become denser as advertising appears or remains visible during use. Inspect the experience over time.
    • An initial transfer is not total network weight. Resources loaded later in a session still contribute to the accumulated advertising cost.
    • A quick lab run is not field data. CrUX reflects real Chrome usage, so device capability, network conditions, page behavior, and actual user journeys can produce a different result from a controlled check.
    • The 75th percentile is not the arithmetic mean. It marks a value at or below which three-quarters of measured experiences fall. The remaining quarter is heavier, so do not describe the number as the experience of an average user.

    That measurement model should shape your quality assurance. Reproduce an ordinary journey rather than loading the page, taking one screenshot, and declaring the layout acceptable. Let advertising appear, scroll through the content, and continue long enough to expose resources that arrive after the first view.

    Build an audit around contrasts, not invented thresholds

    Three similar webpage layouts with different ad patterns are compared on a light table using a magnifying lens and abstract resource signals.

    Chrome has not established a recommended pass or fail threshold for any of the four metrics. They are experimental, and they are not Core Web Vitals. A universal scorecard that labels a page good or bad would therefore create precision that the current program does not provide.

    You can still run a disciplined audit. Use your own comparable page patterns to establish context:

    1. Define comparable groups. Separate page patterns that have materially different jobs or layouts. An article template, a gallery, and a short reference page should not automatically share one baseline.
    2. Record all four ad metrics together. Do not report density without network and CPU weight, or combine the four into an unsupported composite score. Keeping the raw dimensions visible prevents one improvement from hiding a regression elsewhere.
    3. Keep Core Web Vitals in a separate column. The advertising metrics can sit beside established performance reporting, but they should not be relabeled as Core Web Vitals or folded into a made-up Google score.
    4. Find useful contrasts. Compare cleaner and more heavily monetized experiences within a relevant group. Look for the metric that changes most clearly rather than assuming every ad-heavy page has the same defect.
    5. Reproduce the suspected behavior. Review the page across a realistic session, paying attention to what is visible and what continues loading or executing. The goal is to connect a field signal to an observable mechanism.
    6. Change one cost dimension first. Reduce concurrent visible placements for count, occupied screen area for density, advertising payload for network weight, or unnecessary execution for CPU weight. A focused change makes the result easier to interpret.
    7. Judge the tradeoff with business outcomes. Put the ad metrics beside the revenue and campaign measures your team already trusts. Keep changes that improve the experience at an acceptable commercial cost; investigate further when a lower ad metric merely moves the problem elsewhere.
    8. Create internal guardrails only after you have a baseline. Express them as limits for comparable page patterns and document why they exist. Do not present them as official Chrome thresholds.

    A practical internal rule might require a redesigned template not to materially worsen density or CPU weight against the template it replaces while maintaining an acceptable monetization result. Your team still has to define what materially and acceptable mean, but the rule identifies the comparison, the protected outcomes, and the owner of the decision.

    When possible, test changes in isolation. Removing a placement while simultaneously changing the ad vendor, page layout, and loading behavior may improve the numbers, but it will not tell you which intervention mattered. That leaves you unable to repeat the result elsewhere.

    Avoid five costly interpretation errors

    The new metrics are useful precisely because they separate layout pressure from resource pressure. That value disappears when a team compresses them into a simplistic verdict.

    • Do not optimize only for fewer ads. A lower count can coexist with high density, network weight, or CPU weight. Verify which cost actually fell.
    • Do not treat density as a performance metric. Density describes visible space. Network and CPU weight describe resource consumption. One cannot stand in for the others.
    • Do not claim an SEO ranking effect. Nothing in the current rollout establishes these experimental measurements as ranking signals. Track them beside SEO and performance data when useful, but keep the labels honest.
    • Do not promise a media-value or bidding uplift. Better transparency could affect how buyers assess inventory, but Google has not said whether Display & Video 360 is testing these signals for bidding, valuation, or reporting.
    • Do not wait for an official cutoff before measuring. The absence of a universal threshold prevents a pass or fail verdict; it does not prevent you from detecting regressions, comparing relevant experiences, or correcting an obvious outlier.

    Publishers with cleaner experiences may eventually use the metrics to distinguish their inventory. Advertisers and agencies may use them to identify placements where clutter or resource consumption threatens attention and campaign performance. Independent advertising platforms are expected to receive the CrUX data at the same time as Google’s advertising businesses, which makes it sensible to preserve the raw metrics now rather than build a process around a proprietary composite score.

    For buyers, the right first use is comparison and investigation, not automatic exclusion. A high reading identifies a question to ask about the experience. Without an established threshold or evidence connecting that reading to your own campaign outcome, it is not yet a sufficient reason to reject inventory by itself.

    Key takeaways

    • Ad Count measures how many detected ads are visible; Ad Density measures how much of the viewport they occupy.
    • Ad Weight – Network measures advertising bytes, while Ad Weight – CPU measures advertising processing time in milliseconds.
    • Chrome samples the viewport once per second, accumulates network and CPU use through the session, and reports CrUX results at the 75th percentile.
    • The four measurements are experimental, are not Core Web Vitals, and do not have official recommended thresholds.
    • Use the metrics as separate diagnostic signals, compare relevant page patterns, and evaluate every change against both user-experience and commercial outcomes.

    Choose one commercially important page pattern this week and capture all four dimensions before changing it. That baseline will give your ad, performance, analytics, and editorial teams something concrete to improve – and it will keep future decisions grounded if buyers begin using the same signals to value inventory.

    References


  • Claude-Powered SEO Automation: A Safe, Scalable Playbook

    Claude-Powered SEO Automation: A Safe, Scalable Playbook

    You want Claude to remove repetitive SEO work, but you do not want an efficient mistake published across hundreds of pages. That tension is the right place to start. The question is not whether a task can be automated. It is whether you can define the task, constrain its permissions, and prove that its output is correct.

    The most useful Claude workflows combine machine-speed execution with explicit human gates. Let Claude gather, transform, compare, and prepare. Keep an SEO owner responsible for interpretation, publication, and any change that could affect traffic, regional accuracy, security, or production availability.

    Start with blast radius, not time saved

    Containment rings isolate a glowing test cluster from a much larger network of website-page tiles.

    Repetition alone does not make a task a good automation candidate. A daily news digest is repetitive and easy to discard. A plugin replacement is also repetitive, but one bad action could alter layouts or break a site. Those workflows require different permission levels even if Claude can perform both.

    Rank candidate tasks on three dimensions: how reversible the action is, how easily you can verify the result, and how widely an error would spread. Start with work that is read-only, produces a reviewable artifact, or runs entirely in staging.

    WorkflowWhat Claude receivesWhat it may produceRequired human gate
    Daily intelligence briefingNamed topics, competitors, markets, and relevance criteriaA prioritized briefing with links and follow-up questionsVerify material claims before using them in a decision
    Analytics investigationA defined property, date range, segments, and business questionTables, anomalies, and hypothesesConfirm numbers in the analytics platform and test the interpretation
    Hreflang sitemap creationCurrent sitemap URLs and regional mapping rulesDraft XML plus an exceptions reportValidate URL relationships and XML before publication
    Localization workflowApproved examples, service context, target regions, and templatesLocalized drafts and workflow tasksIn-country review and confirmation that every handoff completed
    WordPress plugin replacementA staging site, replacement requirements, and affected locationsStaging changes and an inventory of modified pagesFunctional and visual review before an approved deployment

    This ordering creates a sensible automation ladder. You first trust Claude to collect information, then to analyze controlled data, then to create artifacts, and only later to change a staging environment. Production access should never be the price of discovering whether your instructions are precise enough.

    Give Claude an operating contract, not a loose prompt

    A request such as “monitor our competitors” or “fix our hreflang” leaves too many decisions unstated. Claude has to infer what matters, which systems are authoritative, what it may change, and when it should stop. The resulting output can look polished while solving the wrong problem.

    Use the same seven-part task contract for every SEO automation:

    1. Objective: State the decision or deliverable, not just the activity. For example, produce a reviewable hreflang XML file for the specified regional sites.
    2. Inputs: Name the exact sitemap URLs, analytics property, approved content, template, site, or tracker that Claude may use.
    3. Source of truth: Identify which input wins when URLs, service names, translations, or metrics disagree.
    4. Rules: Define inclusion criteria, regional constraints, naming conventions, output format, and any fields that must never be inferred.
    5. Deliverables: Request both the main output and an exceptions report. Unmatched URLs and missing regional services should be visible, not silently omitted.
    6. Acceptance checks: Describe what must be true before the work counts as complete. Make these checks observable in the destination system.
    7. Permission boundary: Specify whether Claude may read, draft, create tasks, modify staging, or publish. Include a stop condition for missing data, failed connections, and ambiguous mappings.

    Specificity improves more than the first answer. It creates a basis for iteration. A useful intelligence briefing, for example, came from a detailed outline covering industry developments, competitor activity, and mergers and acquisitions, followed by adjustments that removed irrelevant material. The practical lesson is to treat the first output as a calibration run, not as proof that the workflow is ready.

    Store the accepted task contract alongside the workflow. When the result deteriorates, compare the failed run with that contract before adding more prose to the prompt. Most corrections belong in one of four places: the input set, the decision rules, the output structure, or the acceptance test.

    Build automation around complete SEO handoffs

    The strongest workflows do not automate an isolated sentence-generation step. They carry a defined unit of work from intake to a reviewable result. That means including the awkward handoffs where files, tasks, regional checks, or approvals usually get lost.

    1. Turn the daily briefing into a decision queue

    A generic news summary becomes another inbox. Give the briefing a fixed scope and make every item answer an operational question: What changed? Why could it matter to this business? Which site, market, competitor, or active initiative does it affect? What should a person verify next?

    Require a primary link for every item and separate confirmed developments from possible implications. Claude can prioritize the queue, but it should not turn an unverified mention into a strategy recommendation. Delete consistently irrelevant categories from the instructions and add examples of items that were genuinely useful. That feedback is how a broad digest becomes a working intelligence filter.

    2. Keep analytics access read-only and question-led

    A direct connection to Google Analytics can shorten the path from a business question to an initial analysis. Instead of manually assembling every view, you can ask Claude to examine the connected data and return a focused answer. This approach has reduced analysis time in an operational SEO workflow, but faster retrieval does not make every interpretation correct.

    Frame each request with the property, period, comparison period, segment, metric, and desired decision. Ask Claude to show the rows behind its conclusion and to label assumptions separately. Useful investigations include finding landing pages where organic traffic and conversions moved in different directions, determining whether a decline is concentrated in one country or template, and separating a sitewide change from a small set of URLs.

    Do not give an analysis workflow permission to alter campaigns, dashboards, tracking configuration, or site content. Its output is a hypothesis queue. An analyst should confirm the reported values in Google Analytics, check that the comparison is like-for-like, and decide what deserves investigation.

    3. Generate hreflang XML from controlled URL inventories

    Hreflang automation is a matching problem before it is an XML problem. Claude needs to know which pages are genuine alternates, which regions offer the same service, and which URLs do not have a valid counterpart. If those relationships are unclear, clean XML will still encode a bad international structure.

    Provide links to the current XML sitemaps, define the language and regional mapping rules, and forbid the invention of missing URLs. Ask for two outputs: the proposed XML and an exception list containing unmatched, duplicate, redirected, or ambiguous pages. In one implementation, Claude collected pages from the supplied sitemap links and built the hreflang sitemap without further input; a manual check found the first result usable. That is a promising workflow outcome, not a reason to remove validation.

    Before publication, check that every submitted URL belongs in the intended regional cluster, that alternate relationships are reciprocal, that canonical choices do not contradict those relationships, and that the XML is structurally valid. Review the exception list before the main file. It often reveals the content or information-architecture gaps that automated matching cannot responsibly resolve.

    4. Separate localization into availability, adaptation, and delivery

    Translation should not begin until you know the underlying service exists in the target region. Otherwise, automation can efficiently create a locally fluent page for an offer the regional business does not provide.

    Use three explicit stages. First, locate the authoritative page on the main site and establish the service context. Second, inspect each regional site and record whether the same service is available. Third, create a localized draft only for eligible regions, using an approved template and previous expert-vetted examples.

    The delivery stage deserves its own acceptance test. A multi-region workflow has successfully created localized drafts, opened Asana tasks, and assigned due dates from a standard formula. In that same run, the requested document was not uploaded to the task. That partial result exposes an important rule: verify every connector action independently. A task existing in Asana does not prove that its attachment, owner, date, and content all arrived.

    In-country experts found the generated translations comparable to the Google Translate output they had been receiving in that particular workflow. Do not generalize that result into unattended publishing. Product terminology, legal meaning, market eligibility, and local search language still need qualified review. Claude can prepare and route the draft; the regional owner decides whether it is accurate enough to publish.

    5. Treat WordPress changes as a staged migration

    Browser-controlled automation can remove a large amount of repetitive WordPress administration, but it also has the highest blast radius in this group. Use a current staging copy, a known replacement, a recoverable backup, and a page inventory before Claude changes anything.

    Have Claude find every place the old plugin is used, apply the replacement in staging, and return the URLs and templates it changed. Review representative pages at relevant layouts and test the function the plugin provides. If a plugin appears unused or unsupported, deactivate it first and verify that nothing depends on it before deletion. A backup and an approved rollback path are safer than assuming “unused” means consequence-free.

    One rollout across more than 20 websites reduced the operator’s hands-on requirement from an estimated hour per site to about five minutes per site. Claude found the affected locations, swapped the plugin, and performed a quick visual check, but the first attempt still contained a small visual discrepancy that required correction. Use that outcome as evidence that substantial leverage is possible, not as a universal time benchmark or proof that visual review can disappear.

    Put human approval where errors become expensive

    A human reviewer inspects a paused website update at an approval gate before it can reach a large page network.

    Human review should not be sprinkled across a workflow at random. Place it immediately before an output changes a source of truth, reaches a customer, or becomes difficult to reverse.

    • Read-only work: Claude may collect news or query analytics, but a person verifies claims and decides what deserves action.
    • Draft creation: Claude may generate XML, localized copy, reports, and task descriptions, but the artifacts remain unpublished.
    • Workflow mutation: Claude may create tracker tasks and attach files within a defined project. The operator checks each required field and handoff in the destination system.
    • Staging mutation: Claude may alter a recoverable staging site after the target, replacement, backup, and stop conditions are known.
    • Production mutation: A named owner reviews the change set, confirms the acceptance tests, and controls deployment and rollback.

    Measure the workflow on more than speed. Track hands-on time, the percentage of runs that pass without correction, the number of exceptions routed for review, and any steps that claim success without completing in the destination. A fast automation that regularly drops an attachment or misclassifies a regional service is not mature; it has merely moved the bottleneck.

    Keep a small audit record for every run: the task contract, input versions, output files, actions taken, exceptions, reviewer, and approval result. This makes failures diagnosable and prevents a corrected prompt from drifting back toward an earlier mistake.

    Key takeaways

    • Begin with reversible, read-only work and move toward staging changes only after the workflow passes defined acceptance tests.
    • Specify the objective, exact inputs, source of truth, decision rules, deliverables, checks, permissions, and stop conditions.
    • Request an exceptions report alongside every main output. Ambiguity should be surfaced for review, not hidden by a plausible answer.
    • Keep analytics interpretation, regional approval, XML publication, and production deployment under accountable human control.
    • Test every multi-system handoff in its destination. Creating a task does not prove that its attachment, owner, due date, and content arrived.
    • Evaluate automation by correction rate and verified completion as well as time saved.

    Choose one recurring SEO task and write its acceptance test before connecting Claude to anything. Run it with read-only access or in staging, record every correction, and tighten the operating contract until the result is repeatable. If you cannot describe exactly what a passing run looks like, the workflow is not ready for broader permissions.

    References


  • Facebook Ad Costs in 2026: What Better Clicks Really Mean

    Facebook Ad Costs in 2026: What Better Clicks Really Mean

    If your Facebook dashboard is showing cheaper clicks, the tempting response is to open the budget. The 2026 numbers support cautious optimism: traffic campaigns are attracting more clicks at a lower price, and lead campaigns are also paying less per click. But the metric that determines whether many advertisers can afford to scale—cost per lead—has barely changed.

    That gap is where your decision lives. A cheaper click is useful only when its value survives the rest of the funnel. Before you increase spend, find out whether Facebook has lowered your acquisition cost or merely made the first step less expensive.

    What actually changed in the 2026 Facebook benchmarks

    In 2026, nearly 1,800 Facebook ad campaigns across multiple industries were measured using click-through rate, cost per click, conversion rate and cost per lead. Traffic and lead campaigns both became more efficient at generating clicks, but the improvement was much smaller at the completed-lead stage.

    Campaign objectiveAverage CTRAverage CPCAverage CVRAverage CPL
    Traffic1.93%, up 12.87% year over year$0.60, down 14.29%Not includedNot included
    Leads2.70%, up 4.25% year over year$1.80, down 6.25%8.54%$27.39, down 0.98%

    CTR measures how often an impression becomes a click. CPC measures the amount spent for each click. CVR tracks how often a click becomes a conversion, while CPL divides campaign spend by the number of leads generated.

    For traffic campaigns, the direction is unambiguously favorable at the click stage: CTR increased by 12.87% while CPC fell by 14.29%. Advertisers received stronger engagement and cheaper visits at the same time.

    Lead campaigns tell a more restrained story. Their CPC fell by 6.25%, but CPL declined by only 0.98%. In aggregate, most of the click-cost improvement did not appear as an equivalent reduction in lead cost. That does not prove where the difference was absorbed. It tells you where to investigate: between the click and the completed lead.

    Better bidding and campaign optimization may be contributing to the stronger performance, but these aggregate outcomes do not establish a single cause. Your own campaign history remains the evidence that should determine your next budget move.

    Key takeaways for your next Facebook budget decision

    • Cheaper Facebook traffic is a real top-of-funnel gain, but it is not automatically a lower customer-acquisition cost.
    • Judge traffic and lead campaigns against their intended jobs. A traffic CPC and a lead CPL answer different business questions.
    • If CTR rises and CPC falls while CPL stays flat, examine the audience-to-offer match, landing experience and lead process before buying more clicks.
    • Use the $27.39 overall CPL as context, not as a universal target. Industry averages range from $12.30 to $61.56 among the reported verticals.
    • Do not move money from search to Facebook based on CPC alone. The channels often reach people at different stages of intent.

    Follow cheaper clicks through the whole lead funnel

    A transparent three-stage funnel carries many blue cursor symbols through visitor and lead stages, with some markers dropping out along the way.

    One metric cannot tell you whether a campaign is improving. CPC is an input cost. CPL is an acquisition outcome. Lead quality and eventual revenue sit farther downstream. If you stop at the cheapest visible metric, you can scale a campaign that looks efficient while its business value deteriorates.

    Use the same reporting period, spend base and lead definition for each stage of your account-level calculation:

    • CTR = clicks divided by impressions.
    • CPC = spend divided by clicks.
    • Click-to-lead CVR = leads divided by clicks.
    • CPL = spend divided by leads.
    • Qualified-lead rate = leads that meet your qualification criteria divided by total leads.
    • Customer conversion rate = acquired customers divided by the relevant lead group.

    The last two measures are specific to your business, which makes them more valuable than a broad platform average. A low CPL can be a false economy if the form is attracting people who cannot buy, are outside your service area or do not match the offer. Conversely, a CPC increase can be acceptable when the resulting visitors convert into qualified leads at a higher rate.

    Pattern in your accountWhat it can meanWhat to inspect next
    CTR up, CPC down, CVR stable or up, CPL downThe media-efficiency gain is reaching lead acquisitionLead quality and performance as spend increases
    CTR up, CPC down, CVR down, CPL flat or upAttention is cheaper, but more clicks are failing to become leadsAudience intent, message continuity, landing page, form and offer
    CPC up, CPL downMore expensive clicks may be converting efficientlyDo not cut the campaign on CPC alone; verify lead quality
    CPL down, qualified-lead rate downThe apparent acquisition gain may come from lower-value leadsQualification rules, geographic fit, duplicate or invalid leads and sales outcomes
    Traffic CPC down, but valuable site actions unchangedThe campaign is buying visits without improving useful behaviorPost-click intent, page relevance and the action chosen as the next success signal

    Read the sequence from left to right. If CTR improves, the ad is earning more clicks per impression. If CPC also falls, those clicks are becoming less expensive. If CVR then falls, however, the added traffic may not match the promise, destination or conversion request. That is a handoff problem, not a reason to celebrate the click metric.

    For a lead campaign, compare the language and expectation across the ad, landing page or instant form, and follow-up. The person who clicks should encounter the same offer, audience fit and next step throughout. If the ad attracts broad curiosity but the form asks for a serious commitment, Facebook can deliver an attractive CTR without delivering an attractive CPL.

    Industry averages can reverse the headline

    The overall decline in Facebook CPC hides substantial differences between industries. For traffic campaigns, only two reported verticals paid more per click year over year: Shopping, Collectibles and Gifts rose 73.53%, while Sports and Recreation rose 43.90%. At the other end, Real Estate fell 39.56%, Restaurants and Food fell 37.50%, and Industrial and Commercial fell 37.21%.

    Lead-campaign CPC also fell in most verticals. Automotive – For Sale dropped 44.17%, Dentists and Dental Services dropped 41.72%, and Health and Fitness dropped 30.30%. Education and Instruction, up 4.24%, and Sports and Recreation, up 0.93%, were the only reported industries with higher lead-campaign CPC.

    Those click-cost movements still do not reveal what a lead should cost in your market. Average CPL varied sharply:

    IndustryAverage CPLPosition among reported industries
    Career and Employment$12.30Lowest
    Real Estate$13.74Lower end
    Arts and Entertainment$14.59Lower end
    Home and Home Improvement$42.95Higher end
    Beauty and Personal Care$50.91Higher end
    Dentists and Dental Services$61.56Highest

    Dentistry exposes the danger of treating click cost as the result. The vertical recorded a 41.72% reduction in lead-campaign CPC while still carrying the highest reported CPL at $61.56. Access to attention became much cheaper, yet a completed lead remained expensive relative to the other listed industries.

    Use benchmarks in the right order. Start with your own comparable historical period, because it reflects your offer, geography, audience and lead definition. Next, compare campaigns and segments inside the account. Only then use the industry figure to judge whether your experience is directionally unusual. The overall $27.39 average should not become a target imposed on a dentist, recruiter or real estate advertiser as though their economics were interchangeable.

    Turn the trend into a controlled budget decision

    A branching pipeline sends blue traffic particles through two small test chambers while most gold budget tokens remain behind a partially closed gate.

    The 2026 trend gives you a reason to test for additional efficiency, not a reason to approve an unrestricted increase. A broad budget shift can turn an attractive average into expensive marginal volume. Make the decision with a sequence you can audit.

    1. Name the outcome before reading the dashboard. For a traffic campaign, define the valuable behavior expected after the visit. For a lead campaign, define both the counted lead and the criteria for a qualified one.
    2. Build a comparable baseline. Keep the reporting period, conversion event and lead definition consistent. If any of those changed, label the break rather than presenting the before-and-after figures as a clean trend.
    3. Separate campaigns by objective. Do not blend a $0.60 traffic CPC with a $1.80 lead CPC and call the result an account benchmark. The systems are optimizing toward different actions.
    4. Locate the first metric that failed to improve. Read CTR, CPC, CVR and CPL in order, then continue into qualified-lead rate and customer outcomes. The first break identifies the part of the funnel that needs attention.
    5. Test a limited, reversible budget increase in the segments where lower CPL and acceptable lead quality appear together. Keep unrelated variables stable enough to distinguish a budget effect from a simultaneous creative, audience or offer change.
    6. Judge marginal performance, not only the old average. If the extra spend raises CPL or reduces qualification quality beyond what your unit economics support, stop expanding that segment even if its blended CPC still looks inexpensive.
    7. Compare channels by their role in the buyer journey. Within the benchmark context, Google Ads CPC is more than twice Meta’s average CPC, but Google Search typically captures stronger purchase intent. Paying less for a Facebook click does not make it a direct substitute for a high-intent search click.

    If your primary goal is traffic, the lower 2026 CPC gives you room to test whether additional visits produce meaningful on-site behavior. If your goal is leads, the nearly flat CPL calls for more discipline: isolate where cheaper clicks stop translating into cheaper acquisition before you scale.

    Start with the campaigns where CTR improved and CPC declined but CPL or lead quality did not. Put those campaigns at the top of your diagnostic queue. Repair the audience-to-conversion handoff first, then increase spend only where the efficiency survives into qualified outcomes. Facebook may be offering cheaper access to attention in 2026; your account still has to prove that the savings reach the business.

    References


  • How to Build a Google Analytics Dashboard for Decisions

    How to Build a Google Analytics Dashboard for Decisions

    You open Google Analytics to answer one question and end up moving through several reports, copying figures into a document, and trying to remember whether everyone used the same comparison period. The data may be available, but the route to a decision is unnecessarily long.

    Google Analytics Dashboards can shorten that route by putting selected KPIs and visualizations on a customizable, grid-based canvas. The useful part isn’t the canvas itself. It is the discipline of deciding which questions deserve permanent space, which chart can answer each question, and what someone should do after seeing the result.

    Decide what the dashboard must make obvious

    A dashboard should reduce decision time. It shouldn’t reproduce every report your team might occasionally need. Before you add a card, write a short dashboard brief that answers:

    • Who will use it? An SEO lead investigating landing pages needs different detail from an executive checking overall acquisition and conversion performance.
    • What recurring decision will it support? Examples include deciding where to investigate a traffic decline, which content group needs attention, or where users leave a conversion journey.
    • How often will someone review it? The review rhythm determines whether short-term movement or longer trends deserve more space.
    • What is the primary outcome? Name the result the dashboard is supposed to monitor before choosing supporting metrics.
    • Who owns the response? A metric without an owner becomes decoration. Decide who investigates, who explains, and who acts.

    Turn each proposed card into a complete question. “Organic traffic” is only a label. “Is traffic from organic discovery moving in the expected direction, and which landing content explains the change?” is a question. It tells you that you need a headline value, a trend, and enough detail to locate the affected content.

    Give every KPI an explicit scope as well. The team should know which property, audience, outcome, time period, and comparison the number represents. Two people can read the same number differently when one assumes all traffic and the other assumes a particular channel. The dashboard won’t fix an unsettled definition; it will simply make the ambiguity more visible.

    This distinction matters for SEO, AEO, and GEO reporting. Google Analytics can show activity captured in the property, including measurable visits and subsequent behavior. It cannot turn external rank tracking, AI citation visibility, crawl findings, CRM revenue, or platform delivery data into Analytics measurements merely by arranging cards on a page. Keep those claims in their appropriate systems, then use the dashboard for the questions its data can actually answer.

    Build from outcomes to diagnosis

    A large outcome tile branches into several smaller diagnostic dashboard modules in a layered hierarchy.

    The builder lets you drag dimensions and metrics onto the canvas, then position, resize, and align the resulting visualizations. That makes experimentation easy, but it also makes it easy to fill the page before establishing a hierarchy.

    Build in the order a reader will think:

    1. Start with the outcome. Place the KPI that best represents the dashboard’s primary business result where the eye lands first.
    2. Add its context. Show the input or volume metric needed to interpret that result. An outcome without scale can make a small fluctuation look more important than it is.
    3. Show direction. Add a time-series view so the reader can distinguish a sustained movement from an isolated value.
    4. Expose the main comparison. Break performance down by the category most likely to explain a change, such as an acquisition grouping or content grouping that your measurement plan defines consistently.
    5. Provide a diagnostic route. Use a detailed table for the pages, campaigns, or other entities someone will inspect next.
    6. Add the journey where it matters. If the decision concerns an ordered conversion process, use a funnel to reveal the step where progress changes.
    7. Remove repetition. If two cards lead to the same observation and action, keep the clearer one.

    This sequence creates a practical reading path: outcome, context, trend, explanation, detail, action. It also leaves room beneath the documented cap of 15 cards for standard properties. Premium properties can contain up to 30, but a larger allowance isn’t a reason to use every available position.

    Review the completed canvas at the size your intended audience will normally use. Visual priority comes from position and size as well as chart type. If the primary outcome is smaller than a supporting breakdown, the layout is telling the reader that the breakdown matters more.

    Match each business question to the right visualization

    Six dashboard cards display abstract line, bar, ring, funnel, dot, and gauge visualization forms.

    Six visualization types are available: scorecards, tables, line charts, bar charts, donut charts, and funnel charts. Choose among them by the question being asked, not by the visual variety they add to the page.

    VisualizationQuestion it should answerBest useCommon mistake
    ScorecardWhat is the current headline value?A primary KPI or an essential context metricDisplaying several isolated values without showing why any change matters
    Line chartWhen did the movement begin, and did it persist?Performance over timeUsing a trend line when the real question is a comparison between categories
    Bar chartWhich categories are larger, smaller, ahead, or behind?Direct category comparisonsAdding so many categories that meaningful differences become hard to see
    Donut chartHow is a whole divided among a limited set of parts?A simple composition or share breakdownUsing similar-sized or numerous slices that are difficult to compare
    TableWhich exact item requires investigation?Detailed rows that support diagnosisTurning the dashboard into an exhaustive data export
    Funnel chartAt which ordered step does progression change?Conversion steps and drop-offsTreating unrelated actions as if they formed a single sequential journey

    Use date context deliberately. Scorecards can display percentage change when a date comparison is applied, while line charts support daily, weekly, and monthly views. Pick the line-chart interval that matches the decision rhythm. A view that is too granular can distract the reader with ordinary variation; one that is too broad can conceal when a meaningful shift began.

    A percentage movement also needs its underlying value. A large percentage attached to a small base may deserve less attention than a modest movement in the metric most closely tied to the business outcome. Keep the scorecard for quick detection, then place a trend or detailed breakdown nearby so the reader can test whether the movement is broad, persistent, and actionable.

    Publish with property-wide governance in mind

    Creating a useful layout is only half the job. A user needs an Editor or Administrator role to create and publish a dashboard. Once published, the dashboard can be viewed by anyone who has access to the property, and it can be placed directly in the Reports navigation without routing it through the Analytics library.

    That convenience changes the governance standard. Published dashboards are shared across the property rather than privately with selected individuals, so don’t treat the published area as a personal scratchpad. Settle experimental metric definitions and layouts before exposing them to every property user.

    • Name the audience and purpose clearly. A title such as “Content performance” is weaker than one that identifies the intended decision or review context.
    • Assign an owner outside the dashboard. Someone should be responsible for definitions, layout changes, and questions from viewers.
    • Record the KPI definitions. Preserve the scope, outcome meaning, and expected response in team documentation so the dashboard doesn’t become its own undocumented vocabulary.
    • Check the published view with ordinary access. Confirm that the navigation placement and reading order work for viewers, not only for the person who built it.
    • Review cards when strategy changes. Remove KPIs that no longer inform a live decision instead of leaving them in place for historical familiarity.

    Plan around the launch limitations before promising the dashboard as a complete reporting system. API support, segments, and card-level comparisons were not supported at launch. That means you shouldn’t design a workflow that depends on programmatic dashboard management, segment-based dashboard cards, or a different comparison basis for each card unless those capabilities are verified in your property.

    The absence of card-level comparisons is especially important. Agree on a coherent comparison before presenting the page, and explain any analysis that requires a different baseline somewhere else. Otherwise, adjacent cards can appear comparable while answering different questions.

    Key takeaways

    • Start with a recurring decision and its owner, then choose the metrics needed to make that decision.
    • Arrange cards as a reading path from outcome to context, trend, explanation, and diagnostic detail.
    • Use scorecards for headline values, line charts for timing, bar charts for comparison, donut charts for simple composition, tables for diagnosis, and funnels for ordered journeys.
    • Keep metric definitions and scope explicit; a clean layout cannot repair an ambiguous KPI.
    • Design within the 15-card standard or 30-card premium limit, but treat those figures as ceilings rather than targets.
    • Publish only after accounting for property-wide visibility, role requirements, and the feature limitations that applied at launch.

    Your first dashboard should feel focused rather than comprehensive. Open the builder with your decision brief beside you, place the primary outcome first, and add a card only when it helps the reader detect a change, explain it, or choose the next action. If a card does none of those jobs, leave the space empty.

    References


  • How to Tell Whether an SEO Audit Is Worth the Money

    How to Tell Whether an SEO Audit Is Worth the Money

    You have an SEO audit proposal in front of you, but the deliverables sound suspiciously like a list of errors from a crawling tool. The price may buy expert investigation, or it may buy an export you could generate yourself.

    The difference is judgment. A valuable audit identifies which findings are real, explains why they matter to your business, accounts for intentional choices and technical constraints, and gives your team a safe order of operations. Use the framework below before signing a proposal or implementing recommendations from an audit you have already received.

    Start with the decision the audit must unlock

    An audit cannot be valuable in the abstract. It has to help you make a decision: what to repair, what to improve, what to leave alone, and where to invest next.

    Write the audit’s job as one sentence before discussing tools or deliverables. For example:

    • Find out why commercially important pages are not being crawled, indexed, or discovered.
    • Determine whether a site migration introduced technical problems that are suppressing organic visibility.
    • Identify which content gaps prevent the site from satisfying the audience’s most important questions.
    • Separate genuine technical defects from warnings that do not affect search performance.
    • Assess whether search and AI visibility lead visitors toward a meaningful conversion.

    That sentence becomes your first acceptance criterion. If a recommendation does not help answer the stated question, it should not outrank work that does.

    The auditor also needs context that a crawler cannot collect on its own. At minimum, provide your business goals, priority audiences, important products or services, conversion paths, recent site changes, platform constraints, known technical debt, and any SEO decisions your team made intentionally. Without that context, an automated warning can easily be mistaken for a defect. Implementing the resulting recommendation may waste development time or reduce visibility instead of improving it.

    AI search does not make this discovery work optional. Many large language model experiences use retrieval and existing search results to find information with which to construct or check an answer. Your pages still need to be accessible, indexable, relevant, credible enough to surface, and useful once someone arrives. That makes an effective SEO audit part technical review, part content evaluation, and part business analysis. Calling the same crawler export a GEO audit does not add value.

    A valuable audit adds judgment to crawler data

    A specialist inspects a layered website structure with a magnifying lens while automated devices flag both harmless details and one broken connection.

    Crawlers are useful. They can expose URLs, response behavior, directives, internal linking patterns, metadata, and other machine-readable signals at a scale that manual browsing cannot match. The mistake is treating those observations as conclusions.

    This distinction matters because professional audits can cost from $2,500 to more than $20,000, depending in part on the size of the site and the engagement. Screaming Frog and Sitebulb cost a fraction of that amount, and trial access may be available. Run one of them against your site before buying an audit. You do not need to become a technical SEO; you only need enough familiarity to recognize when the final deliverable reproduces automated output without adding analysis.

    Part of the workLow-value outputUseful audit work
    DiscoveryRepeats crawler warnings and severity labelsCombines automated findings with manual investigation
    ContextAssumes every unusual configuration is wrongChecks business intent, technical debt, templates, and platform constraints
    EvidenceNames an issue without showing its scopeProvides affected URLs, patterns, or examples when they are needed
    ExplanationUses generic wording that could describe any siteExplains what is happening on your site, why it matters, and what may have caused it
    RecommendationIssues a universal command such as fix all or remove allTailors the action to your goals and identifies exceptions, dependencies, and risks
    PriorityCopies a tool’s high, medium, or low labelOrders work by likely business impact, effort, confidence, and potential downside
    HandoffEnds with a list of tasksClarifies ownership, implementation needs, and how the result will be checked

    Ask the auditor to walk you through one finding using that table. A convincing answer should distinguish what the tool detected from what manual review established. It should connect the issue to your audit objective, explain the proposed change, identify what could be affected, and state how your team will know whether the change worked.

    Generic explanations are another warning sign. Crawler documentation often explains why a category of warning may matter. Paying an expert makes sense when the expert can determine whether it matters here. A useful explanation names the relevant part of your site and shows the path from observation to consequence. If the same paragraph could be pasted into an audit for an unrelated company, it is probably documentation rather than analysis.

    Test every recommendation before it enters the backlog

    A technical team tests a website component in a transparent staging chamber before moving it toward a balanced production structure.

    A long audit can feel substantial while still being difficult to use. Do not judge it by page count, warning count, or the number of charts. Judge each recommendation by whether your team can verify, understand, execute, and measure it.

    Is the finding valid?

    Start with the evidence. Which URLs, page types, templates, queries, or journeys are affected? Is the pattern consistent? Did manual review confirm the crawler’s interpretation? Could the behavior be intentional?

    A tool can tell you that two pages look similar or that a directive blocks crawling. It cannot reliably decide whether the pages serve different audiences or whether the directive protects low-value areas from unnecessary crawling. The audit should resolve that ambiguity, not hide it beneath a severity label.

    Is the finding material?

    Connect the issue to a meaningful outcome. Does it prevent discovery or indexing? Does it weaken the page’s relevance for an important audience? Does it make a valuable page harder to navigate? Does it obstruct the conversion path?

    Not every technically imperfect detail deserves engineering time. An audit should make that trade-off visible. The useful question is not whether a warning exists; it is whether resolving that warning is a better use of resources than the competing work in your backlog.

    Is the recommendation executable and safe?

    Your implementation team should be able to identify the target, desired behavior, dependencies, owner, and exceptions. The auditor should provide examples where that falls within their expertise. Where it does not, they should still explain what needs to change and why, then identify the type of specialist required.

    Be especially careful with recommendations that affect server configuration, templates, directives, canonicals, redirects, or large groups of URLs. A blanket change can alter access to far more pages than the audit intended. Do not send ambiguous instructions straight into production. Have a qualified developer define the implementation, use your normal review and testing process, and preserve a rollback path.

    Can you verify the result?

    Define completion before implementation. A technical change may be complete when the intended URLs return the expected behavior and the crawler confirms no unintended pattern. A content change may require checking discovery, relevant search visibility, qualified visits, and the next step in the conversion journey.

    Separate implementation validation from performance evaluation. The first asks whether the change was deployed correctly. The second asks whether it improved the outcome that justified the work. Without both, your team can close tickets without learning whether the audit created value.

    For a fast review, label every recommendation Keep, Clarify, or Reject. Keep it when the evidence, consequence, action, risk, and validation plan are clear. Mark it Clarify when one of those elements is missing. Reject it when manual review disproves the finding, the action conflicts with an intentional decision, or the likely value does not justify the risk and effort. This turns an intimidating report into a governed backlog.

    Protect the engagement in the scope and contract

    You should know what will be delivered before the crawl begins. A strong scope does not merely promise an SEO audit. It describes the investigative work, the form of the evidence, the method of prioritization, and the handoff.

    • Manual review: Require investigation beyond crawler, analytics, or LLM output.
    • Site-specific reasoning: Require each material finding to explain its relevance to your site, audience, and business objective.
    • Evidence: Specify that affected URLs, templates, examples, or patterns will be included where needed.
    • Prioritization: Ask for impact, confidence, effort, dependencies, and implementation risk rather than tool-generated severity alone.
    • Handoff: Define whether the fee includes a walkthrough, questions from developers, implementation examples, or post-change validation.
    • Exclusions: Record what the auditor will diagnose but cannot implement, and who is expected to own that work.
    • Early notification: Require the auditor to tell you if manual investigation finds nothing material beyond automated output.

    A refund or scope-change provision can make the final point enforceable. One practical starting point is: The deliverable must include material findings from manual review and site-specific reasoning beyond automated crawler or LLM output. If the auditor determines that no such findings exist, the parties will agree to a revised scope or an appropriate partial refund before final delivery. A deliverable consisting solely of automated output triggers a full refund.

    That language carries commercial and legal consequences, so have your procurement team or counsel adapt it to the engagement and local requirements. The purpose is not to prohibit crawlers or AI assistance. Those tools can support the work. The provision makes clear that your fee purchases human discovery, interpretation, and prioritization rather than undisclosed automation.

    If the investigation finds that a full audit is unnecessary, do not force production of a padded report. Agree on the useful alternative before the work continues. Depending on the professional’s actual skills and your original goal, the remaining effort might be redirected toward content, development planning, conversion analysis, analytics, or another defined need. Document the revised deliverable and price so goodwill does not replace accountability.

    You can also evaluate the auditor’s fit before signing. The relevant expertise depends on the question you need answered. A crawl and indexation problem calls for strong technical and development literacy. A visibility problem may require content and audience analysis. An engagement expected to connect traffic with revenue needs analytics and conversion competence. No individual has to implement every discipline, but the proposal should state where the auditor’s expertise ends and how gaps will be handled.

    Key takeaways

    • An audit fee should buy judgment, prioritization, and a safer decision path, not merely crawler data.
    • Define the business question first; recommendations that do not help answer it should not dominate the backlog.
    • Run a crawler yourself before hiring so you can distinguish automated output from expert investigation.
    • Require manual review that accounts for your audience, goals, intentional decisions, technical debt, and conversion path.
    • Accept a recommendation only when its evidence, consequence, action, risk, ownership, and validation method are clear.
    • Put site-specific deliverables, early notification, scope revision, and refund terms in the agreement before work begins.
    • Evaluate AI-search readiness through the same fundamentals: accessible and indexable pages, relevant content, sufficient visibility, and a useful destination for the visitor.

    Open the proposal or completed audit now and highlight where it promises manual discovery, site-specific reasoning, prioritized action, implementation safeguards, and validation. Ask for a revision wherever one of those elements is absent. If recommendations have already reached your backlog, place the ambiguous ones on hold until someone can supply the missing evidence or context.

    The right audit leaves you with fewer uncertainties, not simply more tasks. Buy it when you need informed decisions that your tools and internal context cannot produce separately.

    References


  • Search Console Indexing Data Gap: What to Check First

    Search Console Indexing Data Gap: What to Check First

    Your Page indexing chart runs normally, goes blank for several June dates, and then resumes. That pattern can look like mass deindexing at first glance. It is not. A missing observation is not a zero, and it does not show that Google removed your URLs.

    The June 2026 pattern was broadly observed across Search Console profiles. Google’s John Mueller said the Page indexing report was not updated during the affected period and the missing indexing data would not be backfilled. Your immediate job is therefore to confirm that your graph has the same fingerprint, verify the site’s present condition with independent evidence, and preserve the gap honestly in your reporting.

    Key takeaways

    • A blank interval in the Page indexing chart means data is unavailable. It does not mean that zero pages were indexed.
    • Matching June dates across unrelated Search Console properties strongly supports a platform reporting gap, especially when data resumes afterward.
    • The missing history cannot tell you what happened inside the gap. Current URL checks, server logs, technical controls, and search activity can tell you whether a problem exists now.
    • Do not change canonicals, robots directives, noindex rules, or sitemaps just to repair the chart. Those actions cannot recreate missing report data.
    • Record the affected dates as unavailable, not zero. Do not interpolate the gap and present the result as observed Search Console data.

    Confirm that you are looking at the June reporting gap

    Start with the shape of the graph. A decline and a data gap are different events. A decline gives you plotted values that move downward. A data gap removes observations from the time series altogether. Neither pattern proves its cause, but confusing one for the other sends the investigation in the wrong direction.

    1. Capture the visible boundaries. Record the first and last missing dates shown in each affected property. Use the dates in your own interface rather than copying a range from somebody else’s screenshot.
    2. Distinguish an empty interval from a zero value. If the chart has no point or line for a date, treat the value as unavailable. Do not enter zero indexed pages in a spreadsheet or dashboard.
    3. Compare properties. If you manage unrelated sites, check whether their Page indexing charts lose the same June dates. A synchronized hole across separate hosts is much more consistent with a reporting problem than with simultaneous technical failures on every site.
    4. Inspect the values on both sides. Data resuming near its earlier range supports the reporting-gap explanation. A substantially different level after the gap deserves attention, but it still does not reveal when or why the change occurred.
    5. Write down any contradictory evidence. Unexpected URL Inspection results, changed server responses, new robots rules, organic landing-page losses, or a recent deployment should be investigated on their own merits.

    This check identifies what the chart can and cannot prove. It cannot prove that every URL remained indexed during the missing period. It also cannot support a claim that URLs were dropped. The observations needed to answer that historical question are absent.

    Validate present indexing with independent evidence

    Three diagnostic signals converge on an intact website structure to represent independent indexing checks.

    Once you have identified the reporting gap, switch from trying to recover the graph to checking the site’s current condition. Use evidence that comes from the URLs, your infrastructure, and search outcomes. No single check replaces the missing history, but agreement across these layers gives you a defensible operational decision.

    Inspect representative URLs

    Choose a small but deliberate sample in URL Inspection. Include the homepage, a recently published URL, an important commercial or conversion page, a typical editorial page, and a template that has had indexing trouble before. Selecting only the homepage can hide a template-level failure.

    Review the current indexing information, crawl access, and canonical information shown for each sample. The goal is not to reconstruct June. It is to find out whether Google currently sees the pages in the state you intended. If several URLs from the same template show the same unexpected condition, stop treating the matter as a chart-only anomaly and investigate that template.

    Check the controls that can actually affect indexing

    • Confirm that important URLs return the intended HTTP response instead of an error, redirect loop, or soft failure.
    • Check page-level noindex directives and robots controls for unintended restrictions.
    • Verify that canonical destinations still point where you expect, particularly on templated and parameterized pages.
    • Review whether important URLs remain represented correctly in the relevant sitemap.
    • Check deployments, CMS changes, migrations, security rules, and template releases around the period for changes that could affect crawling or indexing.
    • If retained server logs are available, examine Googlebot requests and the responses returned by the server. Logs can show crawler access even when the Search Console chart cannot show historical totals.

    A configuration change is evidence only when it affects the URLs and behavior in question. A deployment happening near the gap is not automatically the cause. Connect the change to a response, directive, canonical, rendering problem, or other observable mechanism before you roll it back.

    Compare search and analytics outcomes

    Review Search Console Performance data, analytics landing-page activity, and available server logs over the same broad period. Stable organic activity does not prove that every URL stayed indexed, but it makes a sitewide indexing collapse less plausible. A decline in traffic does not prove deindexing either; rankings, demand, tracking, site availability, and page changes can produce similar symptoms.

    Use these signals as corroboration. When current URL states, technical controls, crawl evidence, and organic landing activity all look normal, the blank Page indexing interval is reasonably handled as a reporting limitation. When several independent signals move together, you have grounds for a technical investigation even though the June graph itself remains unusable.

    Protect your site and your historical reporting

    Missing telemetry creates pressure to do something visible. Resist changes that target the chart instead of a confirmed site fault. Repeatedly submitting the same sitemap, requesting indexing for every URL, or altering indexation controls will not recreate historical observations that Search Console did not retain.

    • Do not bulk-change canonicals. You could create a genuine consolidation problem while trying to solve a reporting problem.
    • Do not remove robots or noindex controls without checking their purpose. Some exclusions are intentional and protect search quality, private areas, or duplicate URL spaces.
    • Do not treat mass indexing requests as a repair. A request concerns a URL’s current handling; it cannot repopulate an aggregate historical chart.
    • Do not rewrite missing values as zero. Zero means an observed count of none. The June gap means no report observation is available.
    • Do not smooth the line without disclosure. An estimate may be useful for an internal model, but it must remain visibly labeled as estimated rather than reported Search Console data.

    In a data warehouse or spreadsheet, store the affected values as null or unavailable. In a chart, leave a break in the line. If your reporting system cannot accept null values, exclude the affected dates from calculations and add a visible annotation instead of coercing them to zero.

    For trend analysis, use complete periods before and after the gap. You can describe the difference between those periods, but you cannot assign the change to a particular missing date or calculate a reliable daily rate across the break. If data resumes at a different level, call it a post-gap difference until other evidence establishes the timing and cause.

    Ready-to-use status note: Search Console Page indexing data is unavailable for [affected June 2026 dates]. The Page indexing report was not updated during that interval, and Google does not backfill the missing values. Current URL, crawl-control, log, and traffic checks show [stable or changed conditions]. We are treating this as [a reporting-only limitation or an open technical investigation].

    Know when to open a real indexing investigation

    An overhead diagnostic pathway separates a harmless reporting gap from warning signs that merit an indexing investigation.

    The known reporting gap should lower the urgency of the blank chart, not become an excuse to ignore other evidence. Escalate when the anomaly extends beyond the shared June interval or when URL-level and operational signals indicate a separate problem.

    • Missing Page indexing observations continue beyond the affected June dates shown across your other properties.
    • Representative URLs now show an unexpected indexing condition or canonical destination.
    • Important templates return errors, carry unintended noindex directives, block crawling, or produce inconsistent canonical signals.
    • Server logs show a meaningful crawl-access or response change that aligns with a site release or infrastructure event.
    • Organic landing-page activity and Search Console Performance data decline outside the missing Page indexing interval.
    • The Page indexing series resumes at a materially different level and stays there rather than returning to its previous range.

    If one of those conditions appears, define the affected cohort before making changes. Segment URLs by template, response, canonical target, publication period, and intended indexability. Find the earliest independent sign of the problem, map it to deployments or configuration changes, and fix only the mechanism you can confirm. That sequence prevents a broad, risky response to what may be a narrow fault.

    For the June 2026 gap itself, the practical next move is simple: annotate the unavailable dates, inspect representative URLs, and preserve null values in every downstream report. If the independent checks remain stable, continue your planned SEO work. If they do not, begin the investigation from the earliest reliable signal rather than from the blank graph.

    References


  • Unified Content Performance Monitoring for AI Search

    Unified Content Performance Monitoring for AI Search

    A page disappears from the AI answers you monitor. Your search rankings look stable, server logs still contain crawler requests, and analytics shows no obvious break. Those signals do not tell you whether to repair the page, rewrite it, or leave it alone.

    You need one diagnostic record that follows the page from technical eligibility to automated access, answer-engine selection, and business outcome. Bringing citations, bot activity, and page health into a page-level view is the foundation. The real value comes from preserving the distinctions between those signals so that each change leads to the right action.

    Key takeaways

    • Monitor page health, bot access, citations, and outcomes as connected layers, not interchangeable measures of success.
    • Attach every observation to a canonical URL, defined monitoring scope, time window, and raw evidence.
    • Diagnose changes in order: measurement scope, page identity, technical health, bot access, citation selection, then outcomes.
    • Alert people only when a signal maps to an action. Keep ordinary fluctuations in a review queue instead of creating constant emergencies.
    • Annotate releases and content changes. Change one class of variable at a time when you want to learn what affected performance.

    Measure four layers without collapsing them

    Four separated translucent monitoring layers rise above a blank web page, with visual elements for technical health, crawler access, answer selection, and audience outcomes.

    A unified monitor is not a collection of charts placed on the same screen. The records must share the same page identity, observation period, and filters. Otherwise, you can easily compare a bot request for one URL variant with a citation of another and an analytics total covering the entire site.

    Use four layers. Each answers a different question and has a different failure mode.

    LayerQuestion it answersEvidence to retainWhat it does not prove
    Page healthCan the intended page be fetched and interpreted as configured?Final destination, response class, canonical target, access directives, render result, and structured-data validationThat an AI system visited, selected, or cited the page
    Bot activityDid an identified or claimed automated agent request this URL?Agent classification, verification method, requested path, time, response class, and resource typeThat the main content was processed, retained, or used in an answer
    Citation visibilityDid a monitored answer point to this URL or domain?Surface, query or prompt, market, language, observation time, answer capture, and citation typeVisibility across every possible query, user, model, or session
    OutcomeDid the exposure connect with a useful audience or business action?Landing-page visits, engagement, qualified actions, conversions, and attribution notesThat a citation caused the outcome when the journey cannot be observed directly

    Do not compress these layers into a single score too early. A composite score can fall while hiding the only fact your team needs: whether the page became technically unavailable, stopped receiving bot requests, lost citations within a monitored query set, or simply generated fewer visits. Keep the component states visible even if executives also receive a summary indicator.

    Define the denominator before reporting citation growth

    A raw citation count is not comparable when the monitored query set changes. Define citation coverage as cited observations divided by eligible observations within a named scope. That scope should preserve the answer surface, query set, language, market, and any other controllable setting. If you add queries or change the mix, mark a new baseline rather than presenting the result as uninterrupted growth.

    Separate direct URL citations from domain mentions, unlinked brand mentions, and citations of a different page on your site. They may all matter, but they are not the same event. Decide which types count toward each metric before a stakeholder asks why the number moved.

    Count bot requests as access evidence, not visibility

    Bot activity begins with a request in a log. It does not establish that the agent rendered the page, understood the primary content, stored anything, or used the page in a generated response. Check whether the request reached the canonical document or only an asset, redirect, parameterized variant, or error response.

    A user-agent label is also a claim, not automatic proof of identity. Record how the agent was classified and keep categories such as verified, claimed, and unknown separate. This prevents spoofed or ambiguous requests from making an access trend look more certain than it is.

    Build one operating record for every canonical page

    The canonical URL should be the join key for your monitor, but a URL alone is not enough. Your team also needs to know what the page is supposed to do, who owns it, and what changed before a signal moved.

    1. Identity: canonical URL, page identifier, template, content type, topic cluster, language, and market.
    2. Purpose: primary audience question, intended search intent, conversion role, and the monitored query set associated with the page.
    3. Lifecycle: publication state, original publication time if known, meaningful revision times, and planned review state.
    4. Health: destination resolution, access directives, canonical consistency, renderability, structured-data validity, and agreement between markup and visible content.
    5. Bot evidence: agent category, identity confidence, request time, requested resource, response class, and any relevant delivery or firewall decision.
    6. Citation evidence: answer surface, exact query or prompt, visible model or product label, locale, observation time, cited URL, citation type, and captured response.
    7. Outcome evidence: landing activity, meaningful engagement, qualified action, conversion, and the limits of the available attribution.
    8. Change history: content edits, schema changes, template releases, internal-link changes, redirects, access-control changes, and analytics modifications.
    9. Ownership: responsible person or team, current status, next diagnostic step, and the evidence required to close the issue.

    Store the raw observation beside the normalized status whenever practical. A label such as “citation lost” is easy to scan, but the captured answer, monitored prompt, cited URL, and observation context are what let someone verify it later. The same rule applies to health checks and bot logs.

    Preserve unknowns instead of filling them with assumptions

    Some answer surfaces do not expose every model, retrieval, personalization, or session detail. Mark unavailable fields as unknown. Do not silently substitute a product name for a model version or assume two sessions had identical conditions. Your trends become more credible when the monitor shows where comparability ends.

    Apply the same discipline to attribution. A citation and a later conversion may be associated in time without being causally connected. Use direct attribution where it exists, assisted attribution where the journey supports it, and an explicitly labeled association everywhere else.

    Diagnose signal changes in a fixed order

    A blank web page moves through four sequential inspection stations for structure, crawler access, answer selection, and audience response.

    When a metric moves, begin with the cheapest explanations to verify. Rewriting content before checking measurement scope, redirects, or access controls creates work and can erase a page that was not actually underperforming.

    1. Confirm comparability. Check that the answer surface, monitored queries, locale, page mapping, observation schedule, and classification rules are consistent with the baseline.
    2. Resolve page identity. Verify that the observed URL, final destination, and canonical target refer to the same intended page. Inspect redirects and duplicate variants.
    3. Check technical health. Look for delivery failures, unintended access directives, rendering problems, canonical conflicts, broken markup, or structured data that no longer matches visible content.
    4. Inspect bot access. Determine whether relevant agents requested the document, what response they received, and whether a firewall, cache, consent layer, or delivery change altered access.
    5. Evaluate citation selection. Within a stable monitoring scope, inspect whether the page is still cited, whether another page from your domain replaced it, and which answer contexts changed.
    6. Connect the result to outcomes. Only after the earlier layers are sound should you decide whether the movement affected useful visits, engagement, leads, sales, or another defined goal.

    Health fails and bot activity falls

    Treat this as a delivery or access problem first. Review recent releases, redirect rules, canonical changes, access directives, firewall decisions, and server failures. Do not commission a rewrite while the intended page cannot be reached or interpreted reliably. Confirm the technical repair from outside the content management preview before closing the issue.

    Health is clean and bots visit, but citations remain weak

    You do not yet have evidence of a crawl problem. Review the page against the questions in the monitored set. Check whether it answers the central question directly, names entities unambiguously, separates distinct claims, supports important assertions, and keeps relevant facts consistent across visible copy and structured data.

    Also inspect page fit. A broad category page may receive requests while a focused explanatory page is a better citation candidate for a specific question. Map each monitored query to the URL that should answer it. If several pages compete for the same role, consolidate or differentiate them before adding more copy.

    Citations appear, but traffic stays flat

    A citation is not a click. Verify whether the citation is prominent, directly linked, attached to your preferred URL, and presented in a context that gives the user a reason to continue. Then inspect the landing page: the next step should be obvious and should extend the answer rather than merely repeat it.

    Do not manufacture traffic attribution when referral data is incomplete. Report the citation as visibility, report observed visits and outcomes separately, and describe any relationship between them at the confidence level your data supports.

    Bot activity moves while citations remain stable

    A crawl spike or decline is not automatically a performance event. It may reflect recrawling, release activity, duplicated URL discovery, asset fetching, or a change in agent classification. Compare requested resources and response patterns before escalating. If citations, health, and outcomes remain stable, keep the change in observation rather than forcing a content task.

    Traffic changes without a citation change

    Investigate conventional search, referrals, campaigns, seasonality, tracking changes, and site experience before blaming AI visibility. Unified monitoring is useful partly because it shows when the explanation probably sits outside the AI citation layer.

    Turn the monitor into a calm operating loop

    A dashboard does not improve content. A decision rule does. Define which conditions trigger an immediate technical response, which enter a scheduled investigation, and which remain under observation.

    • Immediate exceptions: an important page becomes unavailable, resolves to the wrong destination, acquires an unintended access restriction, develops a canonical conflict, or repeatedly returns a server failure. Verify the condition before making a destructive rollback.
    • Weekly triage: repeated citation movement within a stable query set, meaningful changes in verified bot access, unresolved page-level health warnings, and newly detected overlap between pages targeting the same question.
    • Monthly portfolio review: patterns by template, topic cluster, market, content type, and owner. Use this view to identify systemic issues that page-by-page tickets would hide.
    • Release checks: annotate migrations, redesigns, schema deployments, content refreshes, analytics changes, firewall updates, and redirect work. Recheck the affected layer after deployment.

    Each investigation ticket should state the observed change, comparison scope, raw evidence, affected layer, plausible cause, next test, owner, and safe reversal path. “AI visibility is down” is not a usable ticket. “Citation coverage fell across the unchanged monitored query set while health and verified document requests stayed stable” gives the owner a real starting point.

    Use page-specific baselines instead of universal benchmarks

    A citation count has meaning only within its observation scope, and bot volume depends on page type, site architecture, releases, and crawler behavior. Compare a page with its own stable baseline first. Use cluster or template comparisons only after confirming that the pages were measured under compatible conditions.

    Require repeated evidence across scheduled observations before rewriting a healthy page, unless you have a confirmed technical break or factual error. Generated answers and crawler activity can fluctuate. A reaction to every isolated movement will fill your change log with noise and make later diagnosis harder.

    Change one layer when you need a causal answer

    If you rewrite copy, replace schema, restructure internal links, and change the template in the same release, an improvement will not tell you which intervention mattered. Group urgent fixes when necessary, but use controlled, separately annotated changes for optimization work. Preserve the prior version and its observation scope so a rollback or comparison remains possible.

    Start with a bounded set of pages tied to real audience demand or business value. Create one record per canonical URL, capture the current state of all four layers, and assign an owner. The next time a metric moves, follow the diagnostic order before touching the content. That small discipline is what turns disconnected visibility data into a performance system.

    References