Category: Marketing

  • Human Accountability in AI-Assisted Marketing Decisions

    Human Accountability in AI-Assisted Marketing Decisions

    An AI assistant has given your team a confident plan: publish more pages, change the message, and redirect resources toward the tactics it predicts will work. The output is polished enough to put into a deck. The hard question is whether anyone can explain why it fits your customers, constraints, and sales process – and who will answer for the result.

    Human accountability does not mean doing every marketing task manually. It means a qualified person owns the decision, verifies the supporting evidence, controls what gets released, and follows the outcome. That operating discipline lets you use AI for speed without quietly allowing it to become the decision-maker.

    Draw the line between AI assistance and decision authority

    AI can propose options, organize information, expose questions, transform approved material, and accelerate production. A person should retain authority over positioning, priorities, investment, customer promises, and the criteria used to judge success. Those decisions depend on context a generic model response may not contain. A recommendation can sound sensible while omitting something as basic as how customers buy.

    Use consequences, not content format, to decide how much oversight is required. A short tagline can be consequential if it changes the promise your brand makes. A long set of ad variations can be relatively contained if every option stays within an approved offer, audience, and call to action.

    • Execution support: AI formats approved information, groups data, creates variants, or produces a first-pass outline. The task owner checks accuracy and adherence to the brief.
    • Recommendation support: AI diagnoses a problem, ranks opportunities, or proposes a campaign change. A subject-matter owner inspects the evidence, assumptions, business fit, and test design before acting.
    • Consequential decisions: The work changes positioning, budget, material claims, customer experience, or a large part of the website. An experienced marketer explicitly approves, modifies, or rejects the recommendation.

    Accountability includes more than final approval. The human owner must define the problem, set the constraints, decide what evidence counts, and remain responsible after launch. If the only explanation for a choice is that AI recommended it, no accountable marketing decision has actually been made.

    Assign AI work only to people who can evaluate it

    Before assigning a task to AI, ask whether the designated reviewer could evaluate the result without the tool. They do not need to produce it at the same speed. They do need enough knowledge to detect a missing assumption, an unsupported claim, an unsuitable tactic, or a recommendation that conflicts with how the business operates. Access to a tool is not a substitute for understanding the work it performs.

    Consider a recommendation to increase website traffic. A competent reviewer will ask who currently visits, which visitors are relevant, what they do after arriving, and whether the offer is clear. More traffic will not repair a weak explanation, attract the right buyer automatically, or make an unclear next step easier to find.

    The same test applies when AI proposes a large SEO or GEO content program. The reviewer must be able to distinguish a genuine information gap from a request to produce more pages. If nobody can explain which audience needs each page, what decision it helps them make, and why existing content cannot do the job, the team is not ready to approve the plan.

    Give every AI assignment a review brief before prompting. At minimum, record:

    • The business problem the work is meant to solve.
    • The intended audience and the relevant stage of its buying journey.
    • The approved facts, offer, positioning, and operational constraints.
    • The outcome that would count as an improvement.
    • The claims, promises, or changes that are outside the assignment.
    • The person qualified to review and release the work.

    If you cannot name a qualified reviewer, narrow the assignment, obtain the missing expertise, or keep the work out of production. A more elaborate prompt does not repair a missing accountability structure.

    Put every AI recommendation through a human review gate
    Hands verify AI-assisted campaign materials against research before one item passes through a physical review gate.

    A consistent gate prevents fluent output from slipping directly into campaigns, content, or site changes. Use the following sequence for recommendations that affect performance, spend, public claims, or customer-facing experiences.

    1. Name the owner before reviewing the answer. Identify the person who can approve, modify, or reject the recommendation. The AI system is a contributor, not the owner.
    2. Restate the business problem. Write it without mentioning AI or the proposed tactic. There is an important difference between users not understanding a service and a perceived need to publish more content. The first is a problem; the second is only one possible response.
    3. Expose the missing context. Check the target customer, sales cycle, available budget, team capacity, current performance, brand position, and delivery constraints. A valid tactic can still be wrong for the organization expected to carry it out.
    4. Inspect the evidence. Ask AI to identify the basis for its recommendation and disclose important assumptions. Open the cited material and determine whether it supports the specific advice. A citation must be read and checked for relevance; the presence of a link is not proof.
    5. Check operational truth. Reject copy that promises something the business cannot deliver. Confirm product facts, audience fit, availability, approval requirements, and any regulated or contractual language with the appropriate human owner.
    6. Convert the recommendation into a bounded test. State the expected effect, the measurement, the review point, and the smallest reversible scope that can produce useful evidence. Do not make a site-wide change when a limited set of pages can test the same premise.
    7. Record the decision and follow-up. Note whether the recommendation was approved, modified, or rejected; why that choice was made; what changed; and who will review the result. This keeps later analysis from turning into guesswork.

    Timing must reflect the actual buying process. If a service typically takes six months to purchase, judging a campaign after several weeks only by closed sales would ignore how that business wins customers. Early evaluation should examine the relevant conversations and buying activity while preserving a defined point at which the investment will be reconsidered. Patience is not permission to spend indefinitely.

    A compact decision record

    The record can live beside the campaign brief, content ticket, or website change log. A short, specific entry in each field is more useful than a long narrative nobody will revisit.

    FieldWhat to record
    OwnerThe person accountable for approval and follow-up.
    Business problemThe customer or performance problem, stated independently of the proposed tactic.
    AI contributionWhat the system generated, analyzed, summarized, or recommended.
    Context and assumptionsThe audience, sales process, resources, constraints, and uncertain premises that affect the decision.
    Evidence checkedThe material a human opened and reviewed, plus any gaps that remain.
    DecisionApproved, modified, or rejected, with a concise reason.
    Test and measureThe change being tested, expected effect, metric, and bounded scope.
    Review pointWhen the result will be assessed and who will assess it.

    Match the control to the marketing assignment
    Three marketing assignments receive progressively stronger human oversight as their potential risk increases.

    Not every task needs the same process. The useful question is what the model can contribute safely and what judgment must remain with a person who understands the subject and the consequences.

    AssignmentUseful AI roleRequired human release check
    Ad and tagline variationsGenerate alternatives within an approved offer, audience, and action.Reject inaccurate claims, off-brand language, and promises the business cannot deliver.
    Expert or thought-leadership contentDevelop questions, organize an outline, expose gaps, or improve readability.A subject-matter reviewer owns the reasoning, factual accuracy, citations, usefulness, and voice.
    SEO or GEO content planningGroup themes, propose hypotheses, and identify possible information gaps.Confirm a real audience need, a distinct purpose for each page, and a connection to the business problem.
    JSON-LD and schema generationDraft markup from approved page information and a defined entity model.Confirm that every entity, relationship, and claim matches the visible content and the real business, then validate the markup before deployment.
    Positioning, priorities, and budgetOrganize evidence, surface assumptions, and compare scenarios.An experienced marketer makes and signs off on the decision after considering customer knowledge, resources, sales process, and consequences.

    Generation and approval should be separate acts even when the same person performs them. First ask the model for possibilities. Then review those possibilities against the brief and evidence. You do not owe an AI-generated option a place in the final work merely because it is fluent.

    Substantive content needs more than a readability pass. An editor can improve a sentence without knowing whether its conclusion is true, distinctive, or useful. Someone familiar with the subject must evaluate the substance and stand behind what is published.

    Search recommendations deserve the same discipline because a weak premise can create work across an entire site. When AI proposes more pages, require an intended reader, a missing question, a reason the existing site cannot answer it, and a useful next step. Investigate whether relevant visitors already lack a clear service explanation or path to contact before committing the team to a larger publishing schedule.

    For structured data, technical validity is only one part of approval. Perfectly formatted markup can still describe the wrong entity or repeat an unsupported claim. The accountable reviewer must check semantic truth as well as syntax. That is the difference between automating production and automating judgment.

    Key takeaways

    • Let AI generate, organize, and challenge ideas, but give a named person authority over consequential marketing decisions.
    • Do not assign AI work unless someone with relevant knowledge can evaluate its substance, not merely its tone or formatting.
    • Treat model confidence as presentation, not evidence. Check cited material, assumptions, and business fit yourself.
    • Test consequential recommendations within the smallest useful, reversible scope before applying them across campaigns or websites.
    • Keep a decision record that states the problem, owner, evidence, choice, change, measurement, and review point.
    • Judge performance against the real sales cycle and customer journey, not the speed with which AI produced its recommendation.

    For your next AI-assisted task, start before the prompt. Name the owner, write the business problem, define the release check, and decide how the result will be tested. Then let AI work inside those boundaries. If your team cannot fill in those fields, pause the assignment: the missing input is not another prompt but accountable human judgment.

    References


  • Marketing Partnership Accountability: A Practical Operating Model

    Marketing Partnership Accountability: A Practical Operating Model

    You hired capable marketers, approved a plan, and waited for the commercial result. Now the report is full of green arrows while sales says the inquiries are weak, revenue is unchanged, or the work is promoting the wrong offer. Before you conclude that the agency failed or that marketing simply does not work, check whether the partnership ever established a shared definition of success.

    A marketing partner can own research, recommendations, campaigns, content, technical execution, and reporting. It cannot choose your commercial priorities, reveal operational constraints it has never been told about, or decide what your sales team considers a worthwhile lead. Accountability works only when execution is delegated without abandoning leadership.

    Define success in commercial terms before choosing channels

    A brief that says “increase traffic,” “improve rankings,” or “grow AI visibility” gives the marketing team permission to optimize for visible movement. It does not tell them which movement creates value. A campaign can perform exactly as instructed and still send attention toward a low-margin service, attract people who will never buy, or generate demand the business cannot fulfill.

    Begin with a commercial brief that the business leader, marketing lead, and sales lead can all recognize as true. It should answer:

    • What are we trying to sell? Name the priority products or services, the offers that should not receive more demand, and any margin, inventory, staffing, or delivery constraints.
    • Who is the buyer? Describe the person or organization with the problem, the person who approves the purchase, the trigger that creates urgency, and the characteristics that make an account unsuitable.
    • What action matters? Distinguish an informational visit from a buying action such as requesting an assessment, booking a consultation, starting a trial, or contacting sales.
    • What is a qualified lead? Record the required fit, intent, need, authority, and exclusions. “Someone completed a form” is an event, not a qualification standard.
    • How does the business make money? Give the marketing team enough context to understand margins, sales priorities, buying journeys, and the difference between a valuable opportunity and expensive noise.
    • What could change the plan? Surface supply constraints, capacity limits, offer changes, sales coverage, regulatory concerns, and shifting business priorities before they invalidate the campaign.

    This is the dividing line between delegation and abdication. You can outsource specialist execution while retaining responsibility for direction. The business supplies commercial truth and makes consequential decisions. The marketing partner learns the business, challenges weak assumptions, and turns that context into a defensible strategy.

    Use a simple approval test before work begins: could the marketing team explain which buyer matters, which offer deserves demand, why that offer matters commercially, and how sales will judge the resulting opportunities? If not, the partnership is not ready to debate keywords, content formats, paid campaigns, schema, AI-search citations, or channel budgets.

    Assign decision rights before work gets stuck

    Four colleagues organize color-coded decision tokens around converging project paths while one person moves the central token forward.

    Many accountability disputes are ownership disputes in disguise. The agency believes it was waiting for approval. The client believes the agency was hired to take initiative. Sales believes marketing owns lead quality. Marketing believes sales never followed up. Everyone can describe the failure, but nobody had a named final owner for the decision that would have prevented it.

    Create an accountability map at the start of the engagement and revise it whenever the team or scope changes. A practical version looks like this:

    Decision areaBusiness responsibilityMarketing-partner responsibilityEvidence used
    Commercial prioritiesSet and approve priorities, constraints, and tradeoffsExplain the marketing implications and challenge contradictionsMargins, capacity, sales priorities, and business goals
    Qualified-lead definitionDefine fit with sales and provide rejection reasonsTranslate the definition into targeting, messaging, offers, and measurementAccepted leads, rejected leads, sales outcomes, and stated reasons
    Audience and positioningValidate factual claims, differentiation, and brand boundariesResearch the audience, propose messages, and test assumptionsCustomer language, search behavior, sales objections, and campaign response
    Channel and technical executionProvide access and identify material business risksRecommend, implement, verify, and document the workTechnical checks, delivery records, and performance signals
    Budget or resource changesApprove material reallocationsRecommend changes with expected benefits, risks, and uncertaintyOpportunity cost, performance, capacity, and strategic fit
    Performance interpretationProvide actual business outcomes and challenge assumptionsConnect activity to results, explain uncertainty, and propose the next decisionMarketing, sales, revenue, and operational data

    The map should name people, not just departments. “Client to approve” is not ownership. “Sales director approves the lead definition” is. “Agency monitors performance” is incomplete. “Paid media lead recommends reallocations; the business sponsor approves material changes” describes an operating relationship.

    Keep the boundaries sensible. The business sponsor should not become the approval bottleneck for every title tag, ad variation, or internal link. The agency should not quietly decide which product line matters most or publish claims that require business validation. Each side should control the decisions for which it has the context and authority, while making dependencies visible to the other.

    Watch for four warning signs: requests that lack a named decision-maker, approvals with no clear acceptance criteria, strategy changes delivered as casual feedback, and work that proceeds on an unverified commercial assumption. These are not minor process flaws. They create a future argument in which both sides can plausibly say they thought the other side was responsible.

    Build a scorecard that follows the path to revenue

    A tabletop sequence of campaign objects, brass checkpoints, a product sample, interlocking forms, and metallic discs depicts a progression toward revenue.

    Traffic, rankings, impressions, clicks, AI citations, and brand mentions can be useful. They show whether the market is encountering your business and help diagnose where a strategy is gaining or losing traction. They become vanity metrics when the report presents them as proof of commercial success without showing what happened next.

    A useful scorecard reads from the business result backward:

    • Business outcomes: revenue, gross profit, retained business, or another result the company actually values.
    • Pipeline quality: qualified opportunities, lead acceptance, disqualification reasons, pipeline progression, and closed business.
    • Conversion efficiency: whether the intended audience reaches the right page, takes the intended action, and becomes a sales-worthy inquiry.
    • Demand and visibility signals: relevant organic visits, target-query visibility, paid response, branded demand, AI-search visibility, citations, and engagement with commercial content.
    • Delivery and learning: work completed, assumptions tested, technical problems found, lessons learned, and decisions required.

    The layers matter because no single metric tells the whole story. Strong visibility with weak relevant traffic may indicate that the pages or search appearances are attracting the wrong intent. More inquiries with poor sales acceptance may expose faulty targeting, an ambiguous offer, or a loose lead definition. Better qualified pipeline without closed revenue may require examination of sales progression, buying time, pricing, or follow-up. Growing demand for an offer the business cannot deliver is a reason to redirect marketing, not celebrate the graph.

    For SEO, AEO, and GEO work, resist the temptation to make visibility the final destination. A target query should relate to a buyer problem the business can solve. A cited page should lead the right reader toward a useful next step. An increase in AI mentions should be interpreted alongside audience relevance, qualified demand, and commercial outcomes. Otherwise, you are measuring presence without determining whether the presence helps the business.

    Every metric in the scorecard needs a definition, a data owner, an interpretation, and a decision it can influence. If the team cannot say what it would do differently when a metric changes, that metric probably does not belong in the executive view. It may still be valuable in a specialist diagnostic report, but it should not be used to defend an engagement.

    This does not mean demanding direct revenue attribution from every technical fix or content update. Marketing contains leading indicators, delayed effects, and attribution gaps. It does mean requiring a credible line of sight from the work to the customer journey. Impressions, traffic, and rankings are indicators rather than business outcomes; the partner should explain what they indicate, what remains uncertain, and what evidence would justify the next move.

    Run reviews as decision meetings, not report readings

    A dashboard does not create accountability by itself. The operating loop closes only when business context, marketing evidence, sales feedback, and decisions meet in the same conversation. If a review consists of the marketer reading slides while everyone else waits for the final chart, the partnership is documenting activity rather than governing it.

    Build each review around four inputs:

    • Business context: what changed in priorities, margins, capacity, product availability, positioning, or competitive pressure?
    • Funnel truth: which inquiries did sales accept or reject, why were they treated that way, and what happened after handoff?
    • Marketing evidence: what shipped, what changed, which hypothesis was tested, what did the evidence support, and where is the interpretation still uncertain?
    • Decision queue: what needs approval, what should stop, what should continue, what should change, and who owns each next action?

    Sales feedback must be specific enough to change marketing. “The leads are bad” gives the partner nothing to operationalize. Useful feedback identifies the reason: the company was too small, the contact lacked authority, the request concerned employment rather than a purchase, the geography was wrong, the need did not match the offer, or the person was researching without buying intent. Marketing can then adjust targeting, messaging, qualification, forms, content, or channel allocation.

    The marketing partner owes the same level of specificity. “The algorithm changed” or “the campaign needs more time” is not an adequate explanation on its own. The partner should identify the observed change, show which part of the plan it affects, separate evidence from inference, explain the commercial implication, and recommend a decision. Technical detail is useful when it clarifies the choice. It is a problem when it obscures the absence of one.

    Keep an action register with the decision, owner, due point, expected evidence, and status. This prevents the same unresolved dependency from reappearing under different wording. It also makes accountability fair: you can distinguish weak execution from a missing approval, an unavailable data feed, an undisclosed business constraint, or feedback that never reached the people doing the work.

    Adopt a no-surprise rule. The business should disclose material commercial changes as soon as they affect the plan. The marketing team should flag deteriorating quality, wrong-audience signals, tracking gaps, blocked work, or invalid assumptions before the formal report. Waiting until results are challenged turns a manageable course correction into a trust problem.

    Marketing partnership accountability FAQ

    Who is accountable when marketing misses its target?

    Start with the agreed responsibilities rather than assigning blanket blame. The marketing partner is accountable for learning the business, recommending a coherent strategy, executing competently, reporting honestly, and identifying misalignment. The business is accountable for setting priorities, supplying commercial context and access, making decisions, and returning sales and outcome data. A missed target becomes a clear performance failure when the responsible party did not perform an agreed obligation, concealed a problem, or repeatedly failed to learn from evidence. A target miss caused by a disclosed assumption that proved wrong is a learning event, provided the team responds to it.

    What should an executive marketing report include?

    It should connect business outcomes, pipeline quality, conversion behavior, relevant demand signals, completed work, uncertainty, and pending decisions. Each major metric should answer a management question. Executives need to know whether marketing is attracting the intended buyer, supporting the current commercial priority, producing sales-worthy demand, and learning fast enough to justify continued investment. Channel diagnostics can sit beneath that view for the specialists who need them.

    When should you replace a marketing partner?

    Consider replacement when the partner refuses to learn how the business makes money, relies on activity metrics to avoid commercial questions, cannot explain its assumptions, repeats work that attracts the wrong audience, conceals uncertainty, or fails to act on clear feedback. Before ending the relationship, document the commercial objective, decision rights, measurement chain, missing inputs, and corrective actions. That reset shows whether the problem is capability, conduct, scope, or the operating model around the partner. If the business continues to withhold decisions, context, access, or lead feedback, changing agencies will reproduce the same failure with a different logo.

    At your next review, bring the commercial brief, accountability map, scorecard, and action register. Ask the partner to state which offer matters, who the qualified buyer is, what the current evidence means, and which decision is needed from you. Then provide the business context and sales truth they cannot generate on their own.

    You do not need to manage every campaign setting or technical task. You do need to keep strategy connected to the way the company creates value. That is how an outsourced vendor becomes a governed marketing partnership, and how both sides earn the right to be judged on results.

    References

  • Marketing Investment and Incrementality: A Practical Guide

    Marketing Investment and Incrementality: A Practical Guide

    You have a campaign with a healthy return on ad spend, a partner claiming attributed sales, and a finance team asking whether the next dollar should stay. Those facts can all coexist even when the campaign created little new demand. If the budget decision rests on attribution alone, you can reward the channel that was best at standing near an existing sale.

    Incrementality gives you a better basis for that decision. It estimates what changed because of the investment, counts what the investment really cost, and separates a profitable growth engine from activity that merely collected credit. The same discipline works for paid media, commerce networks, SEO and GEO programs, content operations, and AI automation.

    Start with the decision, not the dashboard

    Attribution and incrementality answer different questions. Attribution assigns credit among observed touchpoints. Incrementality asks whether the outcome would have occurred without the marketing activity. That distinction matters because a person exposed to an ad may have purchased anyway.

    Measurement approachQuestion answeredUseful forMain failure mode
    AttributionWhich touchpoint received credit for an observed conversion?Reporting journeys, managing campaigns, and diagnosing channel interactionsCrediting marketing for demand that already existed
    IncrementalityHow much did the outcome change because the investment was present?Budget allocation, forecasting, renewal decisions, and growth planningUsing a weak or contaminated comparison as the counterfactual

    You can never observe the same customer at the same moment both with and without an intervention. A credible test therefore constructs a counterfactual: a comparable estimate of what would have happened without the investment. The quality of that estimate determines whether your lift number is useful.

    Write the decision before choosing a metric. A practical decision statement is: For this eligible population, will this investment produce enough additional business value over this comparison to clear our economic hurdle? Every term needs an operational definition.

    • Eligible population: The customers, accounts, regions, queries, pages, or workflows that could realistically receive the intervention.
    • Investment: The exact spend, campaign, content program, partner, tool, or process change being evaluated.
    • Primary outcome: One business result that can change the decision, such as completed purchases, qualified opportunities, retained customers, or accepted production output.
    • Comparison: A randomized holdout, matched market, staged rollout group, or another defensible estimate of the no-investment outcome.
    • Economic hurdle: The minimum contribution, payback, capacity gain, or other finance-approved result required to justify the investment.

    Use an outcome hierarchy

    A campaign can improve a platform metric without improving the business. Prevent that confusion by assigning each metric a role before launch:

    • Primary outcome: The result that decides whether to invest, such as incremental contribution or qualified pipeline.
    • Guardrails: Results that must not deteriorate, such as margin, return rates, lead quality, publishing accuracy, or customer retention.
    • Diagnostic metrics: Impressions, clicks, rankings, citations, AI visibility, engagement, and other signals that help explain why the primary outcome moved.

    Transaction proximity can make measurement cleaner because the path from exposure to purchase is shorter. It does not, by itself, prove causation. Closed-loop purchase data can show that an exposed customer bought; only a credible comparison can estimate whether the exposure changed that customer’s behavior.

    Count the full investment, including hidden AI labor

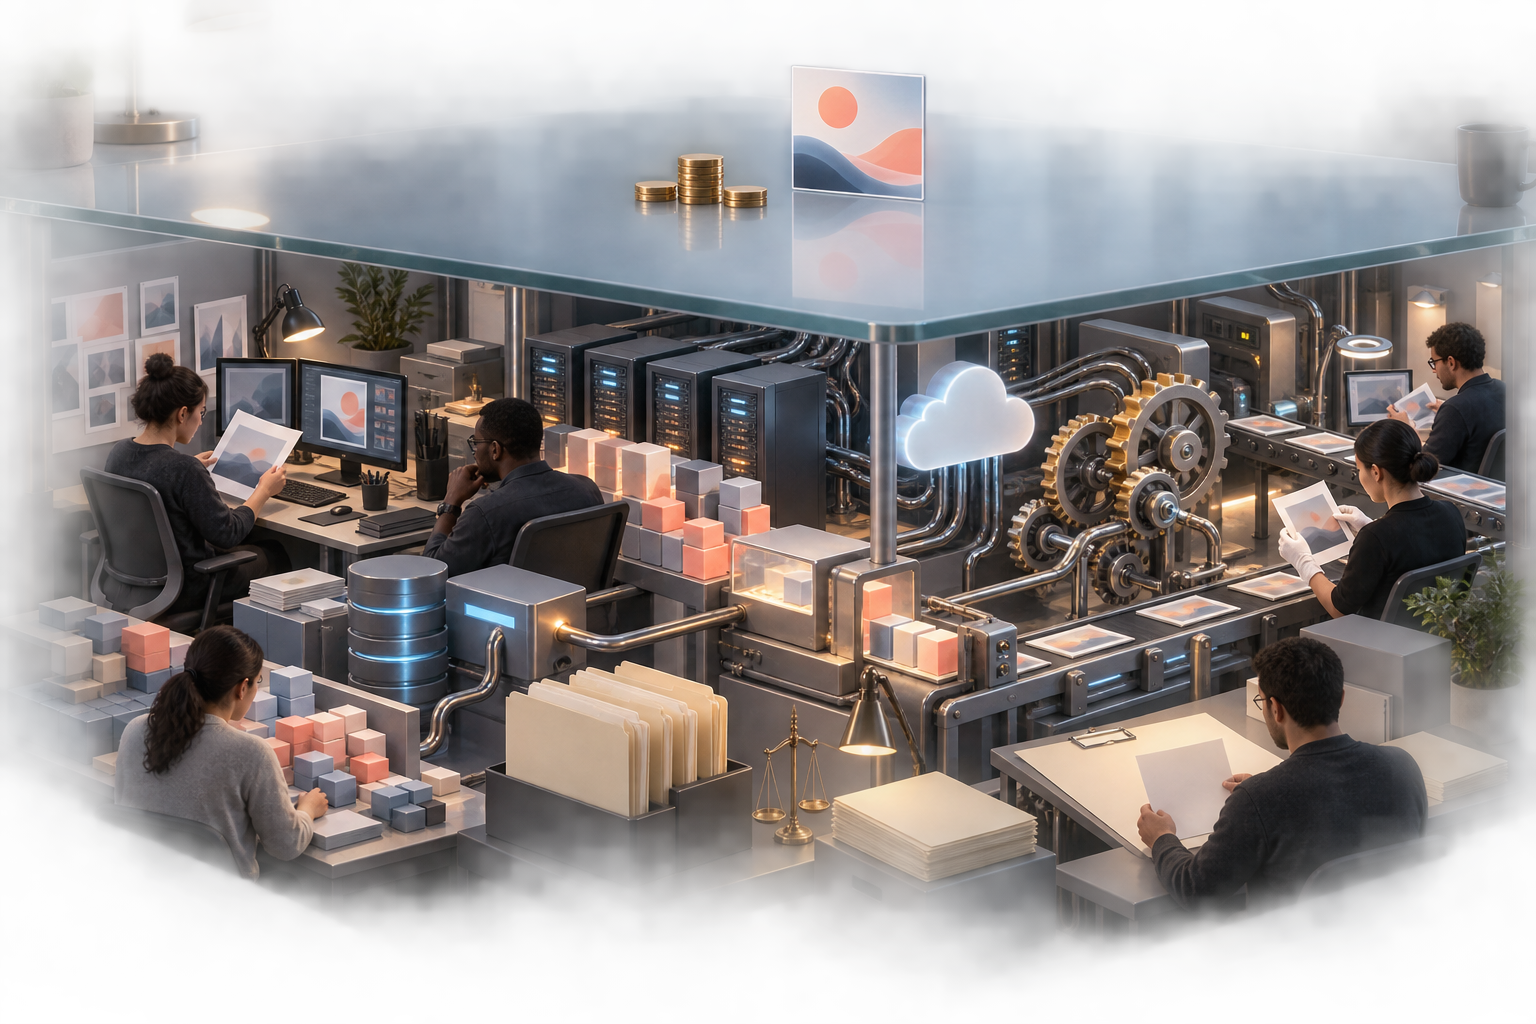
    A transparent worktable reveals human review, computing infrastructure, data preparation, and quality control beneath a small set of visible campaign costs.

    Incremental revenue is not enough to justify an investment. You need to compare incremental economic value with the complete cost of producing it. Media spend and software subscriptions are visible. Learning time, quality control, data preparation, creative production, agency support, and operational rework often are not.

    The visibility gap is especially pronounced with AI initiatives. An NBER working paper surveying about 6,000 senior executives across four countries found that 69% used AI for less than one hour a week and 28% did not use it at all. Decision-makers who are distant from production can see a subscription price and a fast output without seeing the workflow construction, failed runs, checking, correction, and governance underneath it.

    Build an investment ledger with separate lines for:

    • Media, platform, network, and technology fees.
    • Creative, content, landing-page, feed, and schema production.
    • Agency, contractor, analytics, engineering, and legal or compliance support.
    • Data acquisition, identity resolution, tagging, storage, and measurement.
    • Internal planning, campaign operations, stakeholder review, and reporting time.
    • Training, workflow design, prompt or automation development, and rollout support.
    • Quality assurance, fact-checking, editing, exception handling, and rework.
    • Incremental fulfillment, support, discounts, returns, and other variable costs created by the additional business.

    For an AI-enabled marketing investment, run a 30-day labor audit before defending its efficiency. Have the people doing the work record time in four distinct categories: learning tools, operating workflows, checking and repairing outputs, and editing or fact-checking long-form work. Explain that the audit measures the process rather than individual performance. Anonymous aggregation can reduce the pressure to underreport.

    Separate setup costs from recurring costs. A pilot may look expensive because it includes workflow design and training that will not recur at the same level. The reverse also happens: an impressive demonstration can omit the continuing cost of review, maintenance, data cleanup, and failures in daily use. Show both the learning-period economics and the expected steady-state economics instead of averaging them into one reassuring number.

    Keep the financial calculation legible

    Do not hide the business case inside one blended percentage. Show these lines separately:

    • Incremental outcome: The observed result minus the estimated no-investment result.
    • Incremental net revenue: Revenue attributable to the incremental outcome, after cancellations, discounts, or returns where applicable.
    • Incremental contribution before marketing: Incremental net revenue minus the variable costs required to deliver it.
    • All-in marketing investment: The cash and labor costs required to run and measure the intervention.
    • Net incremental value: Incremental contribution before marketing minus the all-in marketing investment.

    If finance uses a different contribution or payback definition, use that definition consistently. Do not silently substitute platform revenue for finance-approved value. Show opportunity cost alongside the calculation: what work, campaign, or capacity did this investment displace? That cost may not belong in the formal ratio, but it belongs in the decision.

    Run a test that can change the budget

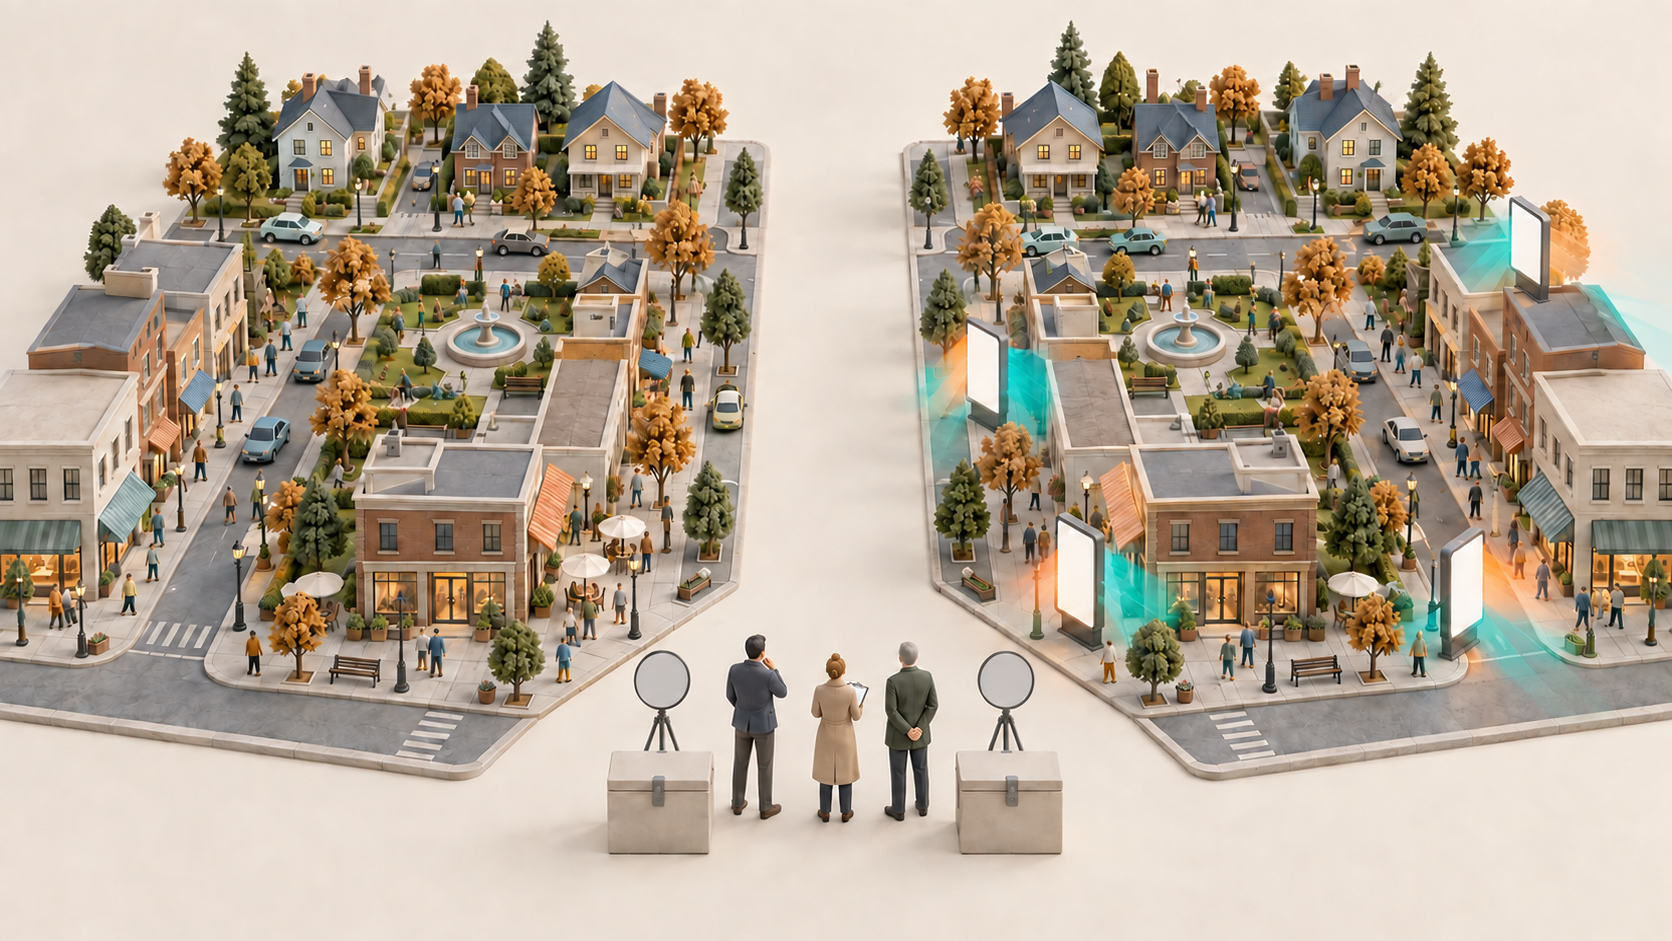
    Two matched miniature commercial districts are compared, with an abstract marketing intervention applied to one district while the other remains untreated.

    A useful incrementality test is designed backward from a decision. It does not begin with whatever report a platform happens to provide. Before money moves, document the following:

    1. Choose one primary decision metric. Secondary metrics can explain the result, but they must not replace the primary outcome after the data arrives.
    2. Define the unit of assignment. Depending on the investment, this may be a customer, household, account, region, page group, topic cluster, or production workflow.
    3. Select the strongest practical comparison. Randomized holdouts are usually the cleanest option when assignment and exposure can be controlled. Matched geographies, staggered rollouts, or time-based switchbacks can be useful when individual randomization is not feasible.
    4. Set the observation window and detectable effect in advance. Base test size and duration on the normal outcome rate, expected variability, and the smallest lift worth acting on. A monthly meeting date is not a measurement rationale.
    5. Record contamination and operational changes. Cross-channel exposure, audience overlap, internal linking, promotions, pricing changes, stock constraints, sales activity, and mid-test optimizations can all make the comparison less credible.
    6. Pre-commit to actions. State what result will lead you to scale, repair, retest, or stop. This prevents a favored program from receiving a new success definition after it misses the original one.

    Choose the comparison design that fits the investment

    • Randomized audience holdout: Use when you can assign eligible people or accounts to treatment and control and can observe the business outcome for both groups. Watch for people receiving the campaign through another platform or device.
    • Geographic holdout: Use when media exposure or commercial activity can be separated by market. Match markets on relevant baseline behavior and account for local promotions, distribution, competitors, and seasonality.
    • Staggered rollout: Introduce the program to comparable units at different times. This can suit SEO, GEO, content, platform, or workflow changes when a permanent control is impractical. Keep rollout order from simply mirroring business priority or existing performance.
    • Switchback design: Alternate treatment and comparison periods when simultaneous holdouts are unavailable. This is vulnerable to day-of-week effects, seasonality, carryover, and changes in demand, so the time blocks must reflect how quickly the intervention’s effect starts and fades.
    • Pre/post comparison: Use only when stronger designs are unavailable. Demand, competition, algorithms, distribution, and pricing can change between periods, making a simple before-and-after result easy to misread.

    Match the outcome to the type of investment

    InvestmentPossible assignment unitDecision-grade outcomeCommon contamination risk
    Commerce or retail mediaCustomer, household, or geographyCompleted purchases, incremental contribution, or new-customer valueExposure through overlapping networks or promotions
    Paid search or paid socialAudience cell, customer, or geographyQualified conversions, contribution, or pipelineRetargeting and cross-device exposure
    SEO, AEO, or GEO programEligible page group, topic cluster, market, or rollout waveQualified organic demand, leads, or attributable business valueInternal-link, brand, and domain-level spillover
    AI marketing automationTask type, workflow, team, or rollout waveAccepted outputs, time per accepted output, throughput, or defect-adjusted capacityUnrecorded manual work and people switching between old and new processes

    For SEO, AEO, and GEO work, rankings, mentions, citations, and visibility are valuable diagnostics. They are not automatically incremental business outcomes. If visibility is the strategic objective, define it that way before the program begins. If revenue, leads, or qualified demand is the objective, do not substitute visibility after launch because it improved first.

    Report uncertainty with the point estimate. A positive estimate surrounded by a wide range of plausible outcomes is not the same as dependable positive lift. If the plausible range includes both no effect and an economically valuable effect, the result is inconclusive. That does not prove the investment failed, but it also does not justify describing success as established.

    Statistical significance and economic significance are also different. A precisely measured lift can still be too small to cover the investment. A larger but uncertain estimate may deserve another test rather than an immediate scale-up. Let the economic hurdle and the cost of making the wrong decision determine the next step.

    Turn lift into allocation rules and partner requirements

    An incrementality result becomes valuable when it changes allocation. Put each tested investment into one of four decision states:

    • Scale: Lift is credible, net incremental value clears the agreed hurdle, and guardrails remain acceptable. Increase investment in controlled steps and remeasure because response can weaken as reach expands.
    • Repair: The activity creates additional outcomes, but fees, labor, margin, lead quality, or operational burden make the economics unattractive. Fix the cost structure or targeting before buying more volume.
    • Learn: The result is inconclusive, but resolving the uncertainty is worth more than the cost of another test. Improve assignment, sample size, tracking, or exposure separation rather than repeating the same design.
    • Stop or reallocate: Credible evidence shows little lift, negative value, unacceptable guardrail damage, or no realistic path to trustworthy measurement. Continuing because a platform reports attributed conversions compounds the original error.

    Partner selection should support this process. For commerce media, compare options across scale and purchase intent, measurement, activation, working relationship, and proximity to the transaction. A large reachable audience is less valuable when it is passive or difficult to measure. A smaller, high-intent audience can be more useful when exposure, purchase, and comparison data are clear.

    Any evaluation framework supplied by a media network should organize your diligence, not serve as independent proof of lift. Before committing budget, ask each prospective partner:

    • How are treatment and comparison groups created?
    • Can the comparison group still receive ads through another placement, network, campaign, or device?
    • Which outcome is primary, and when is that outcome considered complete?
    • Are reported sales new to the business, shifted from another channel, accelerated from a later date, or merely attributed to the exposure?
    • How are repeat purchasers, new customers, cancellations, returns, and duplicated conversions handled?
    • Will the partner report uncertainty, group sizes, exclusions, and failed assignments as well as the lift estimate?
    • Can your analysts inspect sufficiently detailed data and methodology to reproduce or challenge the conclusion?
    • Will campaign optimization remain stable during the test, or will the platform change delivery in ways that undermine the comparison?
    • If customer lifetime value is used, which portion is observed and which portion is forecast?
    • Can the test be repeated after spend, audience, creative, or season changes?

    No partner needs to solve every marketing problem. One may offer strong purchase signals and limited reach; another may provide scale but a weaker counterfactual. Build a portfolio around the jobs each partner can actually perform, then compare the incremental value of those jobs against their all-in costs.

    Use a one-page investment memo

    Give leadership a decision document rather than a dashboard tour. Keep it to six lines of argument:

    1. Decision: The budget, renewal, rollout, or allocation choice that must be made.
    2. All-in investment: Cash, labor, setup, recurring operations, measurement, and material opportunity cost.
    3. Test: Eligible population, assignment unit, counterfactual, primary outcome, window, and known contamination.
    4. Result: Incremental outcome and its uncertainty, with attributed performance shown separately.
    5. Economics: Incremental net revenue, contribution before marketing, all-in investment, and net incremental value.
    6. Action: Scale, repair, learn, or stop, including the next budget level and the condition that would reverse the decision.

    This format also improves conversations about AI investment. Instead of arguing whether AI is broadly fast, useful, or inevitable, you can show the workflow affected, the human effort consumed, the accepted output produced, the quality guardrails, and the capacity or financial value that changed.

    Key takeaways

    • Attributed revenue tells you where credit landed; incrementality estimates how much business the marketing activity actually created.
    • Define the budget decision, eligible population, counterfactual, primary outcome, and economic hurdle before the campaign or rollout begins.
    • Count the full investment. For AI workflows, include learning, operation, output repair, editing, and fact-checking time rather than measuring only subscriptions or generation speed.
    • Use the strongest feasible comparison design, document contamination, and distinguish an inconclusive result from evidence of no lift.
    • Judge partners by the quality and transparency of their incrementality method, not just their attributed sales, audience scale, or dashboard polish.
    • Translate every result into a pre-agreed action: scale, repair, learn, or stop.

    Before your next budget review, choose one disputed investment and write its decision statement. Build the all-in cost ledger, name the counterfactual, and agree on the action thresholds before asking for another report. That small change turns incrementality from a measurement project into an allocation discipline.

    References


  • Profound’s Gartner 2026 Recognition: What It Signals

    Profound’s Gartner 2026 Recognition: What It Signals

    If Profound’s Gartner recognition has put the platform on your shortlist, treat that as a reason to investigate, not a reason to buy. The useful question isn’t whether the recognition sounds impressive. It’s whether Profound can help your team turn an AI visibility problem into a specific intervention and then show what changed.

    That distinction matters because AI search programs often become reporting programs. Teams collect mentions, citations, prompts, and competitor comparisons, but the findings never become owned work with measurable consequences. The strongest interpretation of this recognition is that the market is beginning to demand a complete operating loop rather than another dashboard.

    What the Gartner mention does and does not prove

    Profound reports that it was named in Gartner’s 2026 Coolest Vendor Innovations in CRM alongside Canva, Decagon, dx0, and Twenty. That makes the company relevant to a serious evaluation of emerging AI marketing infrastructure.

    It does not, by itself, establish that Profound is the best platform for your organization. A recognition is not a product benchmark, an implementation plan, or proof of business impact in your environment. It doesn’t answer questions about data coverage, workflow fit, measurement quality, integrations, governance, or the effort required to turn a recommendation into a deployed change.

    The claim also comes from Profound’s own account of the recognition. That doesn’t make it unimportant, but it does set the correct evidence standard: use the mention to justify deeper due diligence, then make the product earn its place through your own workflow and data.

    Don’t turn the recognition into an improvised ranking. The named companies address different parts of customer and marketing work, so their appearance together doesn’t mean they are interchangeable competitors. For your decision, the relevant comparison is between Profound and the other ways you could operate your AI visibility program, including internal analysis, specialist tools, agencies, and connected systems.

    Why the insight-to-outcome loop matters in AI visibility

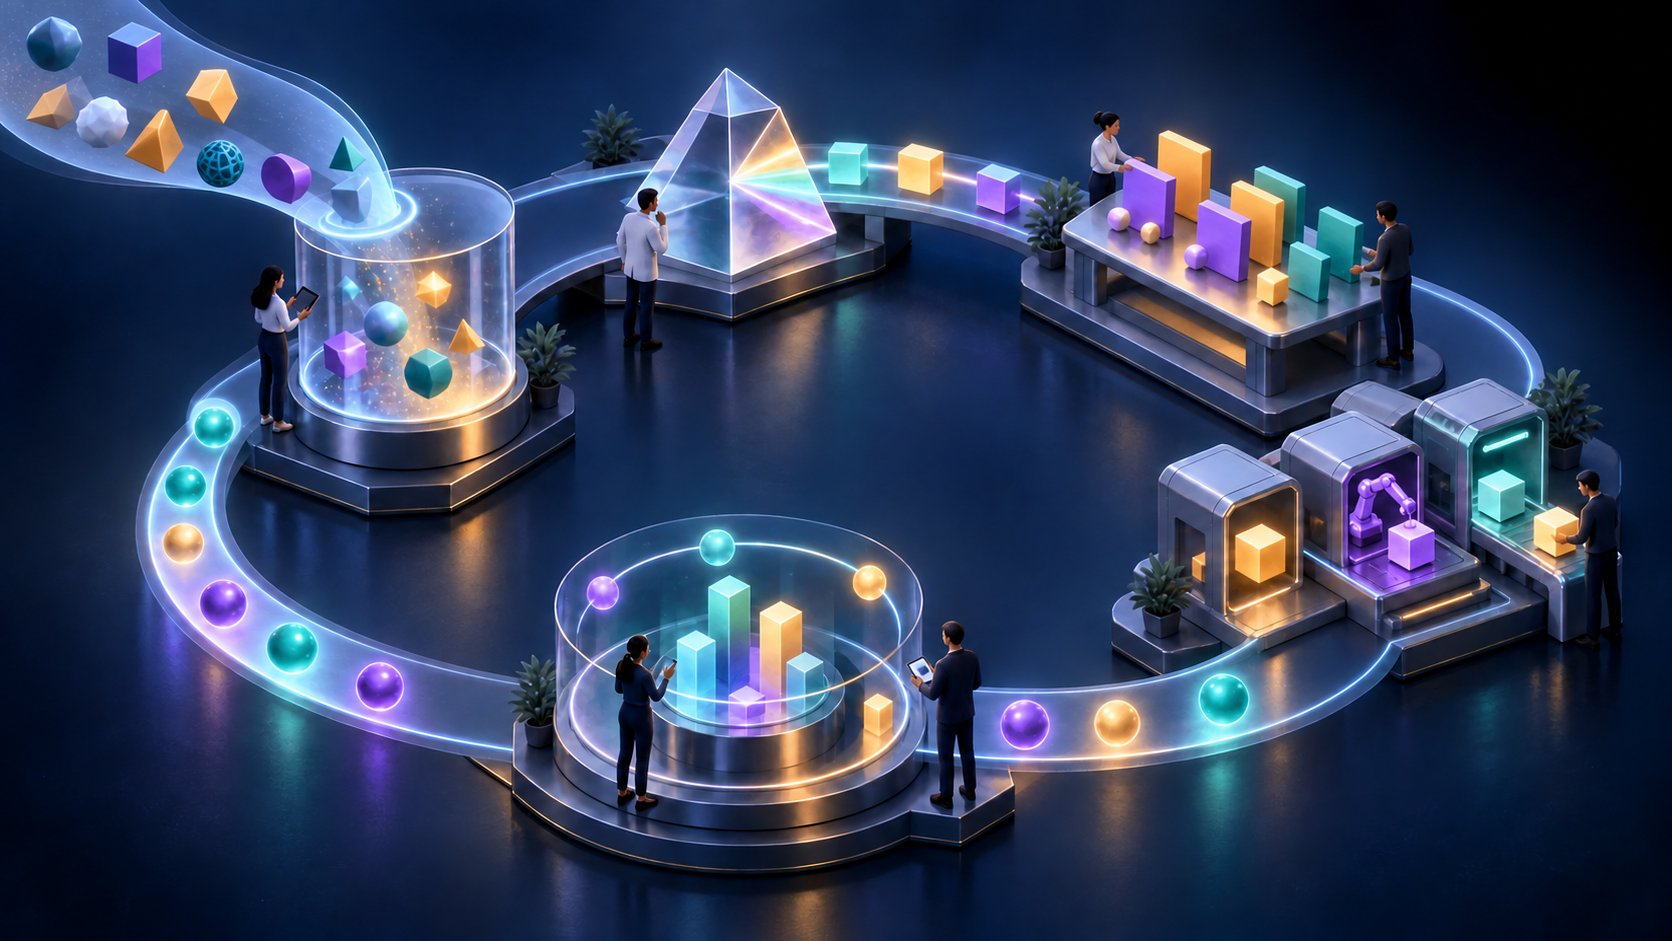
    An isometric circular workflow carries search inputs through analysis, assigned work, production, and measured feedback while team members collaborate at each stage.

    Profound interprets the recognition as evidence that marketers increasingly expect a closed loop from insight to action to measured outcome. That is a vendor-held interpretation, but it gives buyers a much better evaluation standard than feature counting.

    AI visibility work starts with an observation: perhaps a brand is missing from an important answer, a competitor is cited more often, or a product is described inaccurately. None of those observations creates value on its own. Value appears only when the team can diagnose a plausible cause, assign a suitable intervention, publish or distribute the change, and measure the result against a defined baseline.

    StageQuestion your workflow must answerEvidence to request
    InsightWhat exactly is happening, for which queries, audiences, markets, and AI experiences?Saved answer-level observations, timestamps, query definitions, cited domains, and a clear distinction between collected data and inferred explanations.
    ActionWhat should change, where should it change, and who owns the work?A recommendation tied to the original observation, a destination such as a page or entity record, an owner, status, and change history.
    OutcomeDid visibility, representation, referral activity, or a downstream business measure improve after the intervention?A preserved baseline, comparable follow-up observations, deployment dates, and an outcome definition agreed before the work began.

    This framework also prevents a common category error. A suggested content revision, outreach task, or JSON-LD update is an action, not an outcome. Schema markup can make eligible facts easier for machines to interpret when it accurately represents visible content, but merely deploying markup doesn’t prove that an AI system used it or that customer behavior changed.

    The CRM context is useful here. Customer and revenue consequences usually live downstream from visibility data. A credible closed loop therefore needs either native connections or documented handoffs between AI answer monitoring, content operations, technical implementation, analytics, and customer systems. It doesn’t all have to happen inside one platform, but the path between systems must be traceable.

    Run this six-part evaluation before you choose a platform

    A cross-functional team tests six connected evaluation stations in a modern workshop while an out-of-focus trophy sits to the side.

    A polished demonstration can hide the hardest operational gaps. Use one real topic from your business and ask the vendor to follow it from observation through measurement. The following test works whether you are assessing Profound or another AI visibility system.

    1. Define your evaluation set before the demonstration. Include branded questions, category questions, comparison questions, and problem-led questions that matter to actual buyers. Specify the markets, languages, products, and AI experiences in scope. This prevents a vendor from selecting only the examples that make its interface look strong.
    2. Inspect the underlying observation. Ask to see the answer captured, when it was captured, the query used, and any citations or brand mentions detected. You need to know which elements are direct observations and which are scores, classifications, or interpretations produced by the platform.
    3. Challenge the diagnosis. Ask why the system believes a particular content, technical, entity, or authority gap caused the observed result. A useful platform should let your team examine the evidence behind a recommendation. Treat unexplained scores and confident causal claims cautiously.
    4. Follow the recommendation into an owned task. Identify who receives it, where the work happens, what approval is required, and how completion is recorded. If staff must copy findings manually into another system, count that labor and the risk of lost context when you compare options.
    5. Agree on the outcome before making the change. Decide whether success means more relevant mentions, more accurate representation, stronger citation presence, qualified referral activity, or a business result recorded downstream. Don’t substitute a platform’s convenient metric for the decision your organization actually cares about.
    6. Repeat the measurement with a change log. Preserve the initial query set and observation dates, record exactly what was deployed, and compare like with like. AI-generated answers can vary, so a single favorable response is weak evidence. Look for a pattern that is meaningful enough to justify the next round of work.

    This evaluation does not require the vendor to promise perfect attribution. In fact, causal humility is a positive sign. Content changes, model behavior, competitor activity, retrieval choices, and outside coverage can all affect an answer. What you need is a system that preserves enough evidence to distinguish a plausible result from a convenient story.

    Watch for the gaps that turn a closed loop into a slogan

    The phrase “closed loop” sounds complete, but several missing links can make it operationally empty. Look for these gaps during procurement and pilot design:

    • Undefined coverage: The platform reports a visibility score without showing which prompts, markets, models, or observation periods produced it.
    • Diagnosis without evidence: It recommends creating or changing content but cannot connect the recommendation to a captured answer, citation pattern, or identifiable information gap.
    • Action without ownership: Findings remain in the dashboard because no person, destination, approval state, or deadline is attached to them.
    • Publishing without verification: A page or schema change is marked complete, but nobody checks whether the intended fact is visible, accurate, indexable, and consistent across relevant brand properties.
    • Measurement without comparability: The follow-up uses different questions, filters, markets, or definitions, making apparent improvement difficult to interpret.
    • Visibility without business context: The team celebrates more mentions without asking whether the brand is represented accurately, appears in relevant buying situations, or influences a meaningful downstream behavior.

    You should also separate platform capability from implementation maturity. A product may support the required workflow while your organization lacks owners, publishing access, analytics connections, or an agreed measurement model. Buying more software will not repair those operating gaps. Document them before procurement so that platform limitations and internal limitations don’t get confused.

    Key takeaways

    • Profound’s Gartner 2026 recognition is a credible reason to include the company in an evaluation, not proof that it fits your stack or will improve your results.
    • The most useful signal is the emphasis on connecting insight, action, and outcome. Test that complete path rather than comparing dashboard features in isolation.
    • Use a real business topic during the demonstration and require answer-level evidence, an owned action, a deployment record, and a comparable follow-up measurement.
    • Define success before the pilot. Mentions, citations, representation accuracy, referral activity, and business outcomes answer different questions.
    • A closed loop can span several systems. What matters is preserved context, clear ownership, and a traceable line from observation to consequence.

    Make the next step a workflow test, not a prestige vote

    Choose one commercially important topic cluster and map its complete path: the questions people ask, the answers you can observe, the evidence behind any diagnosis, the person who can make a change, and the outcome you will examine afterward. Then ask Profound to demonstrate that path using your definitions rather than a prepared success case.

    If the workflow remains traceable from observation to consequence, the recognition has helped you discover a platform worth piloting. If the trail disappears between dashboard insight and business action, the Gartner mention should not carry the decision. Your next move is to test the loop.

    References


  • Patient Acquisition Cost Benchmarks for Medical Practices

    Patient Acquisition Cost Benchmarks for Medical Practices

    Your patient acquisition cost can be mathematically correct and still give you the wrong answer. A single number cannot tell you whether marketing is efficient until you know which costs it includes, what qualifies as an acquired patient, and whether you are comparing the same specialty and channel.

    Use the benchmarks below as diagnostic reference points, not spending targets. The practical goal is to find out whether your result reflects normal acquisition economics, a measurement problem, a weak channel, or a breakdown between the first inquiry and the completed appointment.

    Key takeaways

    2026 PAC benchmarks by specialty and marketing channel

    Three miniature healthcare settings are reached by different patient pathways with varying amounts of unmarked spending tokens.

    The 2021-2026 benchmark dataset uses anonymized results from medical practices. Specialty sample sizes range from three reporting practices for rheumatology to 27 for cosmetic and plastic surgery, so the apparent precision of the dollar figures should not be confused with equal statistical strength.

    Practice typeAverage patient acquisition costPractices reporting
    Allergy / Immunology$4214
    Cardiology$5899
    Cosmetic / Plastic Surgery$61727
    Dentistry$37911
    Dermatology$44818
    Endocrinology$4024
    Family Practice$27217
    General Practice$20119
    Geriatrics$41111
    Med Spa$2938
    Naturopathic$3876
    Neurology$59213
    Obstetrics & Gynecology$3385
    Orthodontics$5338
    Pediatrics$16011
    Podiatry$2216
    Psychiatry$2935
    Rheumatology$3543
    Urgent Care$29121

    The channel view answers a different question. It shows averages blended across all practice types, not specialty-by-channel benchmarks.

    Marketing channelAverage patient acquisition cost
    Organic Search (SEO)$218
    Paid Search (PPC)$346
    Organic Social$297
    Paid Social$299
    Direct Mail$245
    Radio Advertising$391
    TV Advertising$469
    Video / YouTube Marketing$358
    Outdoor Advertising$420

    No channel-level sample sizes accompany those averages. The figures also do not isolate geography, service mix, payer mix, patient value, attribution model, or the costs included in PAC. That does not make them useless. It means they are best used to flag a result for investigation rather than to certify that a campaign is efficient.

    Choose the right comparison before judging your result

    Start with the specialty benchmark when you are evaluating the practice’s overall acquisition cost. Start with the channel benchmark when you are investigating how a particular marketing method performs. Do not combine the two tables to manufacture a number that is not present.

    For example, dermatology averages $448 by specialty while paid search averages $346 across practice types. Averaging those figures would not produce a dermatology PPC benchmark. One describes a specialty across acquisition activity; the other describes a channel across specialties.

    If your practice has materially different service lines, calculate PAC for each one. A blended practice number can hide an expensive elective service behind a lower-cost primary-care line, or make a valuable specialty program look inefficient because its patients cost more to acquire. If your specialty is absent from the benchmark set, label any substitute as a proxy and rely more heavily on your own historical cohorts.

    What you seeWhat to test before actingUseful next action
    Your PAC is below the relevant averageCosts may be missing, returning patients may be counted as new, or one patient may be credited to multiple channels.Reconcile marketing expenses with finance and patient records before increasing the budget.
    Your PAC is near the relevant averageThe comparison may be reasonable, but average performance can still be unprofitable for your patient economics.Compare PAC with contribution margin and available clinical capacity.
    Your PAC is above the relevant averageThe cause may be expensive traffic, poor inquiry quality, booking friction, no-shows, limited capacity, or an attribution error.Segment the funnel before cutting the channel. Fix the component that is raising the cost.

    A benchmark becomes more useful when it changes the question from “Are we above average?” to “Which assumption would have to be true for this comparison to be fair?” That question exposes measurement gaps before they turn into budget decisions.

    Calculate a like-for-like patient acquisition cost

    Patient acquisition cost = eligible acquisition cost divided by newly acquired patients.

    The formula is simple. The definitions are where most comparisons break. Write those definitions beside the metric in your dashboard so that a future analyst, agency, or practice manager cannot silently change them.

    PAC layerCosts in the numeratorPatient denominatorBest use
    Media-only PACDirect advertising spendNew patients attributed to that advertisingOptimizing bids, audiences, and campaigns inside a paid channel
    Fully loaded channel PACMedia, agency or vendor fees, labor, creative, content, technology, and channel-specific trackingNew patients attributed to the channel under one consistent ruleComparing the economic performance of channels
    Fully loaded practice PACAll eligible patient-acquisition costsAll newly acquired patientsFinancial planning and evaluating the complete acquisition program

    Do not compare a media-only internal number with an external figure that may include labor and vendors. If the benchmark’s cost scope is not defined well enough to match yours, preserve your more useful internal definition and treat the external number as directional.

    Fix the patient milestone

    A lead, appointment request, booked appointment, attended consultation, and completed first encounter are not interchangeable. Choose the event that means the practice has genuinely acquired a patient and apply it everywhere. A completed first encounter is generally more stable than a booking because cancellations and no-shows have already been resolved, but your operational model may require another milestone.

    • Count each new patient once at the chosen milestone.
    • Exclude returning patients unless you intentionally maintain a separate reactivation metric.
    • Resolve duplicate records across locations, phone systems, forms, and scheduling tools.
    • Document how free consultations, canceled appointments, no-shows, and later conversions are handled.
    • Keep the definition unchanged when comparing periods or channels.

    Use one attribution rule without erasing the patient journey

    A patient may first encounter the practice in an organic result or AI-generated answer, later click a branded ad, and finally call. Giving every touchpoint full credit inflates the denominator for each channel. Giving only the last click credit can hide the activity that created demand.

    Keep both discovery and trackable conversion information when your systems allow it. Record how the patient says they first found the practice, preserve any available campaign or referral data, and assign one primary channel under a documented rule for PAC reporting. An intake field with fixed options and free text can capture search engines, AI assistants, social platforms, referrals, and offline media when click-based attribution is incomplete.

    Align costs and acquired patients to a consistent measurement basis as well. This matters especially for organic search, content, structured data, and other programs whose work and patient response may not occur in the same reporting period. A mismatched numerator and denominator can create a dramatic PAC change even when underlying performance has not changed.

    Turn the benchmark into a budget and operations decision

    Patients move from outreach through reception and scheduling to an examination room, with one person paused at a scheduling bottleneck.

    Set a ceiling from patient economics

    The market average is not your allowable PAC. Your ceiling comes from the value a new patient contributes to the practice and the cash-flow period the practice can support.

    Expected contribution before acquisition = expected collected revenue over the chosen value horizon minus the variable costs of delivering care.

    Expected contribution after acquisition = expected contribution before acquisition minus PAC.

    Use collected revenue rather than sticker price, and keep the value horizon consistent. Comparing one channel with first-visit revenue and another with the value of an entire treatment episode will favor the second channel by design. If your estimates affect a material spending commitment, have the practice’s financial lead validate the revenue, cost, capacity, and cash-flow assumptions before the budget changes.

    A below-benchmark PAC can still destroy value when contribution margin is lower. An above-benchmark PAC can still be workable when the patient relationship contributes enough margin and the practice has capacity. The external average tells you what deserves scrutiny; your economics decide what is affordable.

    Separate traffic cost from conversion failure

    When qualified inquiries are measured consistently, the funnel can be expressed as PAC = cost per qualified inquiry divided by the inquiry-to-acquired-patient conversion rate. This decomposition tells you whether the acquisition problem begins before or after the inquiry.

    • If inquiry costs rise while conversion is stable, inspect targeting, competition, creative, search intent, and channel mix.
    • If inquiry costs are stable while PAC rises, inspect call handling, response delays, service fit, scheduling friction, appointment availability, cancellations, and no-shows.
    • If both appear stable while PAC changes, audit missing expenses, duplicate patient records, channel reassignment, and changes to the acquired-patient definition.
    • If demand exceeds usable appointment capacity, increasing marketing can raise cost without creating additional completed care. Resolve the capacity constraint before adding spend.

    This distinction protects you from cutting an effective campaign because the practice could not answer, qualify, or schedule the demand it generated. It also prevents an operational problem from being disguised as an advertising problem.

    Budget against marginal PAC, not only the historical average

    Your average PAC describes the patients already acquired. A budget decision concerns the additional patients expected from additional spending. Track the incremental cost and incremental acquired patients when you expand a channel; the next segment of demand may not perform like the existing average.

    Planning budget = desired new-patient volume multiplied by planning PAC. Use your own normalized PAC as the base, the relevant external benchmark as a reasonableness check, and your contribution-based ceiling as the financial constraint. Then test whether the required patient volume fits actual appointment capacity.

    Organic search carries the lowest reported channel average at $218, but that does not make it an automatic budget winner. Include content production, technical SEO, structured data, analytics, optimization labor, and outside support in the organic numerator when those costs are part of patient acquisition. Apply the same discipline to every channel. A television average of $469 is not automatically unacceptable if the channel produces patients whose contribution and incrementality support that cost.

    Before approving the next budget change, write the PAC definition at the top of the forecast, rebuild the latest complete measurement period with that scope, choose the appropriate specialty and channel references, and add your contribution-margin ceiling and capacity limit. You will then have more than a benchmark: you will have a decision rule your marketing, operations, and finance teams can use consistently.

    References


  • Profound’s $180M Funding: What Marketing Teams Should Test

    Profound’s $180M Funding: What Marketing Teams Should Test

    If you are deciding whether Profound’s funding makes its platform a safer strategic bet, separate two questions immediately: Does the company have more capacity to pursue its vision, and can the product remove work from your marketing operation? The first is supported by the raise. The second still requires proof inside a workflow that matters to you.

    That distinction will keep a large funding number from becoming a substitute for product, governance, and commercial due diligence. It also gives you a practical way to evaluate AI Marketer without either dismissing the platform or buying the story before testing the system.

    What Profound has actually committed to

    Profound has raised $180 million to build an AI platform for marketing. Its stated premise is that AI is generating additional work for marketers, not simply automating existing tasks. AI Marketer is positioned as the response: a system that brings company context and agents together so marketing teams can get that work done.

    Those points establish capital, direction, and a product thesis. They do not establish the return a customer will receive. A funding total cannot tell you whether the platform fits your data, integrates with your operating stack, produces reliable outputs, shortens approval cycles, or reduces the total cost of a workflow.

    The stated goal also indicates a broad platform ambition rather than a single-purpose feature. That can be valuable when your work crosses research, analysis, content, brand governance, and execution. It can also increase implementation scope. The more jobs a platform is expected to coordinate, the more important permissions, source quality, handoffs, and ownership become.

    Use the announcement as a reason to ask better questions, not as the answer to them. Do not add unconfirmed details about valuation, investors, product allocation, delivery dates, or business performance to your internal brief. If one of those details affects your decision, request it directly and distinguish a written commitment from a forward-looking plan.

    Why more AI can create more marketing work

    A marketing team sorts and reviews a growing flow of campaign materials produced by several automated machines.

    AI reduces the cost of producing an output, but output generation is only one part of marketing. Every new model, answer surface, automated campaign, and content variant can create additional monitoring, interpretation, validation, approval, and measurement work. Faster production can therefore move the constraint downstream rather than remove it.

    You can see that effect by mapping the full chain around an AI-assisted task:

    • Inputs: Someone must select the relevant brand rules, product facts, audience assumptions, performance data, and prior decisions.
    • Generation: A model or agent produces an analysis, recommendation, brief, campaign asset, or other deliverable.
    • Verification: A person checks factual accuracy, source quality, brand fit, compliance, and whether the output answers the original question.
    • Execution: The approved output must reach the correct channel, owner, or system without losing its context.
    • Learning: Results must return to the process so that the next action reflects what changed.

    A platform can make generation faster while leaving every other stage intact. It can even increase review work if it produces more material than your team can verify. That is why prompts completed, agents deployed, and assets generated are weak measures of operating value on their own.

    Before watching a demonstration, draw one real workflow from request to approved outcome. Mark every system, human handoff, approval, wait state, and rework loop. Record the elapsed time, active working time, and recurring errors using evidence you already have. You now have a baseline against which automation can be judged.

    If your remit includes AI search visibility or generative engine optimization, a suitable workflow might begin with a visibility finding and end with an approved content or entity-data change. The test should include the analysis, supporting evidence, assignment, revision, publication approval, and follow-up measurement. Automating only the first step does not automate the workflow.

    What company context and agents must prove

    The combination of company context and agents is the central idea behind AI Marketer’s positioning. Those terms can sound complete while hiding the hardest implementation questions. Treat them as two systems to test separately.

    Test context as a governed source of truth

    Company context should do more than place files near a model. It should help the system select current, authorized information and show you what influenced an output. Ask for a live demonstration that answers these questions:

    • Which repositories, pages, records, and instructions can the system use for this task?
    • How does it decide which source is authoritative when two sources conflict?
    • How quickly does a changed product fact, policy, or brand rule become available?
    • Can access be limited by team, role, market, client, or workspace?
    • Can a reviewer trace an output back to the facts and instructions that shaped it?
    • What happens when the required evidence is missing, stale, or ambiguous?

    Do not test this with a polished sample library. Bring a controlled set of realistic material that includes one outdated item, one conflict, and one fact the system should not expose to every user. Designate the correct source in advance. A useful context layer should handle the conflict predictably, respect access boundaries, and make its reasoning inspectable enough for a reviewer to catch a mistake.

    Test agents as bounded operators

    An agent is valuable when it can advance work without gaining more authority than the task requires. Evaluate its operating boundaries, not only the quality of its final output:

    • What triggers the agent, and who can change that trigger?
    • Which data can it read, and which systems can it alter?
    • Which steps require human approval before the agent proceeds?
    • Can you stop a run immediately and prevent it from retrying?
    • Does the audit history preserve inputs, actions, outputs, approvals, and failures?
    • How does the agent behave when a dependency is unavailable or the evidence is inconclusive?
    • Can its work be exported, reassigned, or completed manually?

    Run the same task after changing a canonical input, revoking a permission, and withholding a required fact. You are looking for controlled behavior: the output should update when the approved context changes, access should disappear when permission is removed, and the agent should stop or escalate when it cannot support an answer.

    Do not grant autonomous publishing or campaign-changing permissions merely to make a pilot look complete. An opaque error can create public misinformation, brand damage, or avoidable spend. Start with read access, draft outputs, explicit approval gates, and a visible audit trail. Expand authority only after the failure behavior is understood.

    Turn the funding story into a procurement test

    A cross-functional team evaluates an AI agent in a transparent test chamber using visual checkpoints for quality, security, time savings, and commercial value.

    New capital can support product development, infrastructure, implementation, hiring, or market expansion, but the amount alone does not tell you which customer outcomes will improve. Ask Profound to connect its funded platform direction to the operating requirements in your evaluation.

    Use a short, evidence-based process:

    1. Separate product from roadmap. Mark every required capability as available, configurable, dependent on services, planned, or unsupported. Ask for written confirmation of anything that affects the purchase.
    2. Select one costly workflow. Choose a process with a clear owner, recurring inputs, an observable outcome, and enough friction to justify change. Do not begin with a broad goal such as improving marketing productivity.
    3. Run your material through the system. Use representative company context, normal approval requirements, and the systems the production workflow would need. A vendor-curated example cannot expose your integration or governance problems.
    4. Measure total work. Compare active effort, waiting, handoffs, corrections, and review demand with the baseline. Count work displaced to administrators, analysts, agencies, or implementation teams.
    5. Test failure and exit paths. Introduce stale context, a conflicting instruction, a denied permission, and an unavailable dependency. Then verify how you export outputs, retrieve records, remove data, and continue the workflow if the platform is unavailable.

    A pass-or-fail scorecard keeps the evaluation focused when a demonstration is visually impressive:

    DimensionEvidence to requestReason to pause
    Workflow valueA proof run showing less total effort, delay, or reworkThe claimed value depends mainly on future features
    Context integritySource traceability, conflict handling, freshness controls, and scoped accessThe system cannot explain which facts governed an output
    Agent controlLeast-privilege permissions, approvals, stop controls, and audit historyAgents require broad access or take opaque actions
    Operational fitWorking integrations, clear ownership, administration, and support pathsManual bridges recreate the work you intended to remove
    Commercial durabilityWritten terms for current capabilities, service levels, support, and pricingThe funding total is used in place of contractual commitments
    Exit safetyDocumented export, deletion, access removal, and offboarding proceduresYour data or workflow history cannot leave cleanly

    Funding matters most where it changes the risk of relying on the platform. Ask which capabilities exist now, which dependencies require professional services or third-party systems, what support is included, and how roadmap changes are communicated. For every answer, identify the proof: a live control, a technical document, a contractual term, or merely an intention.

    Data handling deserves the same precision. Confirm what information the system stores, where it is processed, who can access it, how long it is retained, whether it is used to improve models, and how deletion is verified. If your marketing context contains customer, partner, employee, or confidential product information, involve the people responsible for security, privacy, and legal review before production access is granted.

    Key takeaways

    • Profound’s $180 million raise supports its ability to pursue an AI platform for marketing, but it does not prove customer outcomes.
    • AI can create work after generation, especially in verification, approval, execution, governance, and measurement. Evaluate the whole workflow.
    • Company context must demonstrate source authority, freshness, traceability, conflict handling, and permission boundaries.
    • Agents must demonstrate limited authority, approval controls, predictable failure behavior, auditability, and a safe manual path.
    • Your decision should depend on production-like evidence and written commitments, not funding momentum or a curated demonstration.

    For your next step, take one workflow into the evaluation meeting and bring its real inputs, permissions, exceptions, and approval rules. Ask Profound to show what AI Marketer does at each stage, what remains human work, and which capabilities are available now.

    A platform is worth adopting when it reduces the total burden of producing a trustworthy marketing outcome while preserving control. The funding gives Profound room to pursue that standard. Your proof run should determine whether the product meets it for you.

    References


  • Low-CAC Marketing Channels: How to Choose the Right Mix

    Low-CAC Marketing Channels: How to Choose the Right Mix

    If you’re choosing a marketing channel because it has the lowest published customer acquisition cost, you’re one step away from an expensive mistake. A cheap customer who arrives after your runway runs out, requires an unaffordable test budget, or disappears when an auction gets crowded isn’t cheap for your business.

    You need more than a ranked list. You need to know which channels fit your economics, how long each one needs to produce a useful signal, and whether the apparent efficiency will survive additional spend. Here is a practical way to make that decision.

    A low CAC is useful only when it fits your constraints

    Among 214 companies analyzed in 2026 – 137 B2B and 77 B2C – the four lowest B2B acquisition costs came from paid, organic, and offline channels. Channel family alone was a weak predictor of efficiency. Email, public speaking, generative engine optimization, and an early advertising platform all appeared near the top for different reasons and carried different constraints.

    That is why a benchmark should open your shortlist, not settle it. Before you compare channels, calculate the most you can afford to pay for a customer. Use contribution margin rather than top-line revenue, and choose a payback period your cash position can actually support. A business with high lifetime value but a long recovery period can still run out of cash while reporting an attractive LTV-to-CAC ratio.

    Screen each candidate through four gates:

    • Economic ceiling: What is your allowable CAC after fulfillment, sales, onboarding, refunds, and other variable costs? A channel fails if its marginal CAC exceeds that ceiling, even when its average looks acceptable.
    • Time to evidence: How long can you fund the work before the first attributable customer is likely to appear? Do not evaluate a six-month channel with a six-week deadline.
    • Viable commitment: Can you spend enough to buy or generate a measurable test? A low unit cost does not help if the minimum workable commitment is beyond your budget.
    • Repeatability: Can the channel absorb more activity without exhausting the audience, the available speaking slots, or an unusually favorable early auction?

    Put these four columns beside every channel in your planning sheet. Reject any option that misses a hard constraint before debating creative concepts, vendors, or campaign tactics.

    Be equally careful with published LTV-to-CAC ratios. The 2026 B2B ratios were calculated using the same $32,414 lifetime value across channels, while the B2C calculations used $10,089. Those figures make channels comparable inside the benchmark, but they are not substitutes for your retention, margin, and customer-value data.

    Use the 2026 benchmarks to build a realistic shortlist

    The most useful comparison pairs CAC with the condition governing the channel. The figures below are directional averages, not quotes or forecasts. For offline channels, the spending figures are the lowest monthly commitments at which measurable acquisition was observed, not universal vendor minimums. N/A means there was not enough volume in that segment to report a benchmark.

    ChannelB2B CACB2C CACConstraint that affects the decision
    ChatGPT Ads$468$131Only seven weeks and 14 accounts; weekly B2B CAC rose from $312 to $549
    Email marketing$510$2871.4 months to the first attributable acquisition
    Public speaking$518$472$2,500 observed minimum viable monthly spend
    GEO$584$2615.8 months to the first attributable acquisition
    Webinars$603$2512.1 months to the first attributable acquisition
    Thought leadership SEO$647$2986.4 months to the first attributable acquisition
    Organic social media$658$2123.2 months to the first attributable acquisition
    Informal networking$711$472$1,200 observed minimum viable monthly spend
    PPC/SEM$802$290B2B CAC was 14.1% higher than in 2024
    Direct mail$864$347$18,000 observed minimum viable monthly spend
    LinkedIn Ads$982N/AB2B CAC was 31.2% higher than in 2024
    Basic SEO$1,786$1,2018.6 months to the first attributable acquisition
    Account-based marketing$4,664N/AHighest B2B CAC in the benchmark

    This table changes several common channel decisions.

    • Email is efficient when you already have legitimate access to an audience. If another campaign had to acquire those subscribers, include its appropriate share of list-growth cost. Otherwise email receives credit for closing customers while the channel that created the audience absorbs the expense.
    • Organic does not automatically mean inexpensive. For B2B, the gap between thought leadership SEO and basic SEO was $1,139 in CAC and 2.2 months to first acquisition. That does not guarantee an identical saving for you, but it is a strong reason to compete through expertise and positioning instead of publishing interchangeable pages for keyword volume.
    • GEO and thought leadership SEO are close enough to plan together. Their B2B benchmarks differed by $63 in CAC and 0.6 months to first acquisition. Question research, clear answers, expert evidence, consistent entity information, and genuinely distinctive content can support both search discovery and generative-engine visibility. Structured data should reinforce what a visitor can see, not make claims the page does not support.
    • Offline CAC can hide a large cash commitment. Direct mail carried an $864 B2B CAC, but measurable acquisition appeared only from a monthly commitment of $18,000. Public speaking combined a lower $518 CAC with a $2,500 observed threshold, although access to relevant events and the number of credible appearances limit its scale.
    • Paid-channel inflation belongs in your forecast. Every established paid channel in the benchmark became more expensive from 2024 to 2026. Use your current marginal CAC for budgeting, not the blended average from the campaign’s cheapest months.

    Build the mix around time horizons, not channel labels

    A strategist waters quick-growing sprouts, flowering plants, and a deeply rooted young fruit tree in three greenhouse beds.

    A sensible channel mix gives each component a distinct job. If every channel is expected to create awareness, capture demand, nurture prospects, and close sales, attribution becomes political and weak results are easy to excuse.

    Use paid channels for fast feedback and demand capture

    PPC/SEM and ChatGPT Ads can help you test offers and capture active demand without waiting for an organic audience to compound. They are most useful when the landing experience, sales follow-up, and conversion event are already measurable. If those pieces are broken, faster traffic only lets you lose money faster.

    ChatGPT Ads requires special treatment. OpenAI opened the self-serve platform on July 22, 2026, and the available benchmark covers just seven weeks across 14 advertiser accounts. Weekly B2B CAC climbed 76%, from $312 in week one to $549 in week seven, while the weekly spend index rose from 100 to 611. The spend-weighted average was $468, and week seven remained 32% below the $802 PPC/SEM benchmark.

    That low average is an invitation to test, not a safe annual-planning assumption. Before launching, write down your allowable CAC, maximum test spend, minimum customer count needed for a useful decision, and the date when a complete sales cohort can be evaluated. Review weekly and cohort CAC rather than relying on the cumulative average. An early cheap week should not conceal deteriorating marginal performance.

    Use email and webinars to convert an audience you can reach

    Email and webinars are attractive when you have subscribers, partners, customers, event registrants, or a reliable way to recruit the right people. Their observed organic ramps – 1.4 months for email and 2.1 months for webinars – make them more suitable for near-term acquisition than a program whose first result historically took half a year.

    Audit the audience before committing. Count reachable, permissioned contacts in the target segment; identify how many acquired customers can realistically be attributed; and include the cost of producing the content and building attendance. A webinar presented to an untargeted list is not a low-CAC strategy merely because the video call itself is inexpensive.

    Give GEO and thought leadership enough time to compound

    GEO and thought leadership SEO should build durable discovery around the questions your buyers ask before contacting a vendor. Their observed 5.8- and 6.4-month ramps mean they should not be assigned the job of rescuing the current quarter. That is a planning inference from the averages, not a promise that your first acquisition will arrive on either schedule.

    Choose commercially meaningful questions rather than the largest possible list of keywords. Publish a direct answer, make important claims easy to verify, show who is responsible for the content, and connect related pages so search engines and generative systems can understand the subject and the entity behind it. Then distribute the work through email, social media, webinars, and credible communities. Distribution is part of acquisition cost, so record it rather than treating publication as the end of the job.

    If your budget is constrained, start with one fast-feedback channel and one compounding channel. Fund both through their decision dates. Six underfunded experiments usually produce six ambiguous results, while a smaller mix gives you enough volume and time to distinguish channel failure from an incomplete test.

    Measure channel CAC without giving cheap channels free credit

    An analyst balances blank cost tokens among several connected marketing touchpoints that lead to a packaged purchase.

    Channel rankings become unreliable when each team uses a different numerator, denominator, or attribution window. Write one measurement policy before you compare performance.

    1. Define an acquired customer. Use the same completed event across channels, such as a paid first order or a signed contract. Do not compare qualified leads from one channel with customers from another.
    2. Use a fully loaded numerator. Include media, sponsorships, allocated labor, agency fees, creative production, content production, software, event costs, travel, and other expenses required to operate the channel. Record shared costs under a consistent allocation rule.
    3. Match spend to the customer cohort it created. A customer closing this month may belong to an earlier campaign. Keep immature cohorts open until the relevant sales cycle has elapsed instead of dividing current spend by whichever customers happened to close during the same calendar period.
    4. Separate acquisition from assistance. Record both a primary acquisition source and meaningful assisting touches. Email may close a prospect first introduced through GEO, a webinar, a search ad, or public speaking. Your reporting should show that path without charging the full customer to every participant.
    5. Track marginal CAC as you scale. Average CAC tells you how the program performed so far. Marginal CAC tells you what the next block of customers is costing. Use the second figure for budget increases, especially in auctions or finite audiences.
    6. Pair cost with customer quality and payback. Compare contribution margin, retention, sales effort, deal size, and time to recover acquisition spending. A lower CAC can still produce a worse business outcome if it brings low-margin customers who leave quickly or consume disproportionate support.

    The working formula is simple: channel CAC equals the channel’s fully loaded acquisition cost divided by new customers attributed under your written policy. The difficult part is consistency. Do not change the definition when a favored channel begins to look expensive.

    The same discipline prevents a dramatic benchmark ratio from distorting a budget decision. For example, the reported B2B ratios of 69.3x for ChatGPT Ads and 63.6x for email rely on the shared $32,414 lifetime-value assumption. Recalculate both with your own contribution economics and the payback window your finance team can support.

    Key takeaways

    • Treat an external CAC benchmark as a shortlist, not a forecast or spending target.
    • Reject a channel that fails your allowable CAC, time-to-evidence, viable-commitment, or repeatability test.
    • Email had the lowest organic B2B CAC and the shortest organic ramp, but list creation and audience access still belong in its true cost.
    • GEO and thought leadership SEO carried lower B2B CACs and shorter ramps than basic SEO, supporting an expertise-led approach over undifferentiated keyword production.
    • ChatGPT Ads produced the lowest observed B2B CAC, but the seven-week, 14-account sample and rapidly rising weekly CAC make it an experiment rather than a stable budget baseline.
    • Use fully loaded cohort CAC, assisting-touch reporting, marginal CAC, customer quality, and payback together before moving budget.

    Open your channel plan and add four columns today: allowable CAC, minimum viable commitment, earliest decision date, and marginal CAC. Keep one channel that can generate timely feedback and one that can compound discovery. If you cannot fund a candidate until its evidence date or measure the customers it creates, remove it from the plan before it becomes an expensive ambiguity.

    References


  • How to Budget Marketing Automation Without Hiding Labor Costs

    How to Budget Marketing Automation Without Hiding Labor Costs

    Your automation proposal may look affordable because the visible line items are media, software, and usage fees. The expensive part often sits off-budget: configuring the workflow, checking its output, correcting mistakes, handling exceptions, and keeping the integration alive.

    If you are deciding what to automate or how much budget to move, use two ledgers: cash and team capacity. That will show you whether automation creates usable capacity, merely transfers work to someone else, or buys scale that is worth the additional supervision.

    Budget the full system, not just the visible spend

    A license price is not an automation budget. Neither is the amount you plan to let an ad platform spend. The working system includes the people who design it, supply its data, approve its output, resolve its failures, and maintain it after launch.

    Use this working equation: monthly automation cost equals direct cash spend, allocated build labor, operating labor, review and rework, and maintenance. Track opportunity cost beside that total rather than automatically adding it as another dollar amount. If the same employee hour has already been priced as labor, monetizing the work it displaced can count that hour twice.

    Cost poolWhat belongs in itWhat teams commonly miss
    Direct cashSoftware, usage fees, vendors, support, and paid-media spendVariable charges that rise with volume
    Build and changeProcess mapping, configuration, prompts, integrations, testing, documentation, and trainingRebuilding work after a model, platform, or business rule changes
    OperationsRunning jobs, monitoring results, approvals, and exception handlingSmall interventions repeated across every production cycle
    Quality controlFact-checking, editing, validation, corrections, and downstream cleanupTime charged to the recipient rather than to the automation
    MaintenanceDiagnosing failures, updating connections, revising instructions, and maintaining access and documentationThe continuing software-like responsibility created by a custom workflow
    Opportunity costThe valuable marketing work delayed or abandoned to make room for automation workContent depth, digital PR, community participation, reviews, and brand-building activity with slower attribution

    Keep the cash and capacity ledgers separate. A workflow can be financially attractive but still fail operationally because it consumes the limited attention of your best strategist, editor, analyst, or approver. That person becomes the bottleneck even when the software looks inexpensive.

    For every proposed automation, create one register entry with the following fields:

    • The workflow, its business purpose, and one accountable owner.
    • The unit of accepted output, such as an approved campaign, a published page, or a qualified lead record.
    • Baseline labor required to produce that accepted output manually.
    • Initial build, testing, documentation, and training labor.
    • Operator, reviewer, and downstream-recipient labor after automation.
    • Software, media, usage, vendor, and support costs.
    • Exceptions, corrections, failed runs, and maintenance work.
    • The named deliverable that will be delayed if the build uses existing team capacity.

    Do not write opportunity cost as a vague warning that the team will be busy. Name the trade. If maintaining a lead-enrichment workflow displaces an authority page, a digital PR pitch, or participation in a buyer community, put that deliverable in the register. A concrete sacrifice can be compared with the expected benefit; an unspecified one will be ignored.

    Automate mature systems and control uncertain ones

    A repeatable process runs on an orderly conveyor with light oversight beside an irregular branching process controlled and inspected by a person.

    Automation works best when a repeatable process has enough trustworthy feedback to distinguish a good outcome from a bad one. Manual control earns its budget when the system is still learning, feedback is late or unreliable, or a poor allocation would be expensive.

    Google Ads makes the trade-off easy to see. Automated campaigns can use real-time auction and user signals that are not available through the same manual controls. They can also optimize around selected conversion actions, target CPA, and ROAS goals. Manual campaigns let you retain tighter control over keyword bids and adjustments involving time, device, and location.

    Keep manual control when the feedback is weak

    A manual campaign or tightly limited pilot is usually the safer budget choice when:

    • The account has a limited budget and must concentrate spend in its most efficient areas.
    • The account, product, or service is new, niche, or too low-volume to provide useful learning data.
    • A campaign produces fewer than 30 conversions per month. That is a practical Google Ads threshold from the supplied evidence, not a universal minimum for every marketing automation.
    • Conversions arrive after a long delay, preventing timely optimization.
    • Duplicate, inaccurate, glitchy, or missing conversion tracking would teach the system to pursue the wrong outcome.
    • You need keyword-level cost control for broad branded terms, a new launch, or a competitor campaign.
    • Inventory, product priority, or distinct audience budgets must override the platform’s preferred allocation.

    In these cases, manual work is not evidence that your team has fallen behind. You are paying for control while you establish clean measurement, discover which inputs matter, and limit the cost of bad learning.

    Favor automation when the system can learn from clean outcomes

    A mature, sufficiently active campaign is a stronger automation candidate when its conversion definitions are accurate, the business can tolerate a learning period, and CPA or ROAS goals represent real business value. The benefit is not only reduced setup work. It can also include broader reach and continuous adjustments that a person cannot make auction by auction.

    Before shifting more budget, put the data guardrails in place. For Google Ads, that can include enhanced conversions, offline conversion tracking based on first-party data, and product exclusions. Exclusions matter because an automated campaign can appear successful by accumulating easy conversions for low-priority items while neglecting the products the business actually needs to sell.

    Then test the change through an experiment instead of switching the whole campaign at once. An automated strategy may underperform during its early learning phase. Repeatedly toggling between manual and automated settings before it has a fair chance to learn leaves you with an inconclusive test and no stable basis for allocating the next budget.

    The practical default is often hybrid. Let proven automated campaigns carry more volume when their economics hold up, while retaining smaller manual areas for launches, low-volume segments, cost-sensitive keywords, or data collection. Move each area only when its measurement quality and maturity justify the change.

    Count labor where it lands, not where it disappears

    Automation can make one employee look faster while increasing the team’s total labor. A marketer may produce a draft in minutes, but an editor, analyst, account manager, or sales colleague can inherit the time needed to verify it. If your dashboard measures only the sender, it will record a saving even when the organization loses time.

    This measurement problem matters because adoption is already broad. One vendor-reported survey found that 91% of marketing leaders said their teams used AI, while 66% said their companies built internal AI tools for marketing. Those figures describe reported behavior, not proof that the resulting workflows were productive.

    A late-2025 METR experiment gives a sharper warning about perceived speed. Sixteen experienced developers completed 246 real tasks with and without AI tools. They expected AI to make them 24% faster, but their measured completion time was 19% slower. Even after seeing their completion times, they still believed they had been about 20% faster. The experiment involved software development rather than marketing, and a 2026 rerun found higher productivity with acknowledged sampling limitations, so neither result should be treated as a marketing benchmark. The useful lesson is narrower: felt productivity can diverge materially from completed-task productivity.

    Downstream rework can produce the same illusion. A BetterUp Labs and Stanford survey of 1,150 full-time U.S. workers found that 41% had received AI output that looked complete but required additional work during the previous month. Each occurrence reportedly took an average of 1 hour and 56 minutes to resolve. That is a survey estimate rather than a forecast for your team, but it identifies the labor category most automation budgets omit: cleanup performed by the recipient.

    Other vendor research points in the same direction. Workday estimated that organizations returned about four hours in correction and rewriting for every ten hours AI saved. In an Upwork survey of 2,500 leaders and workers, employees who said AI increased their workload most often identified checking and fixing output, learning tools, and simply receiving more work. Treat these as signals to measure your own workflow, not as universal ratios to paste into a business case.

    Measure the complete path to an accepted output. Your time log should include:

    • Process design, configuration, prompting, integration, and training.
    • Hands-on operating time for each run.
    • Blocked waiting time when a person cannot continue other work, kept separate from passive machine time.
    • Review, fact-checking, editing, approval, and correction.
    • Exception handling and failed-run recovery.
    • Cleanup performed by the next person or department in the process.
    • Maintenance, documentation, access changes, and troubleshooting.

    Calculate net labor against the same accepted unit of output: baseline manual labor minus all post-automation labor across every role. A faster first draft is not a labor saving until it becomes an accepted deliverable. If automation increases output volume, compare labor per accepted unit and total labor separately so scale does not masquerade as efficiency.

    Labor savings are also not the only valid return. Real-time responsiveness, broader campaign coverage, or more consistent execution may justify automation even when net hours barely change. Label that decision honestly as a scale, speed, or quality investment. Do not promise headcount capacity when the benefit lies elsewhere.

    For SEO, AEO, and GEO teams, this distinction has strategic consequences. Internal tooling often competes for the same capacity needed to publish deep topical coverage, earn third-party mentions, participate in the Reddit and YouTube discussions buyers use, and develop reviews and community presence. Those activities can take longer to show attributable returns, which makes them easy to postpone. Put the authority-building work displaced by internal automation on the decision sheet before approving the build.

    Decide whether to buy, build, or keep the work human-owned

    Three teams choose a ready-made automation unit, assemble a custom workflow, or handle complex cases manually, with each path passing through physical review gates.

    The build-versus-buy decision is not a referendum on your team’s technical ability. It is a decision about where you want to own software risk and where custom logic creates enough business value to justify that ownership.

    Buy a standard capability when the process is not distinctive

    Prefer an existing tool when the task is common, the available product can meet your acceptance criteria, and your advantage comes from using the result rather than engineering the workflow. Paying a vendor can be cheaper than using scarce marketing capacity to reproduce a feature you already license elsewhere.

    • Confirm that the tool supports the inputs, outputs, approvals, and integrations you actually use.
    • Include onboarding, usage, review, and vendor-management labor in the cost comparison.
    • Test export and handoff paths before the workflow becomes operationally important.
    • Compare accepted-output quality, not the length of the feature list.

    Build only when the custom logic deserves an owner

    A custom workflow can make sense when it encodes a proprietary process, applies business rules an existing product cannot express, or connects systems in a way that creates material value. But it becomes software your marketing team must manage. Meetings, process interviews, testing, and training occur before the first useful run. After launch, a model change, integration update, new exception, or revised business rule can degrade it or stop it from working.

    Do not approve a custom build until you can answer these questions:

    • What specific business rule or advantage cannot be obtained from an existing capability?
    • Who owns the workflow after its creator changes roles, leaves, or becomes unavailable?
    • Which acceptance tests will expose silent quality degradation?
    • Who responds when an integration fails during a production cycle?
    • How will changes be documented, reviewed, and communicated to users?
    • Which planned marketing deliverable supplies the build and maintenance capacity?
    • What condition will cause you to replace, simplify, or retire the workflow?

    If the owner is simply the person who happened to create it, the maintenance budget is not real yet. Assign responsibility to a role, reserve capacity, and document the recovery path before the workflow becomes a dependency.

    Keep the work human-owned when automation adds a fragile layer

    Manual execution can remain the better operating model when the task is infrequent, the rules change faster than the workflow can be maintained, reliable outcome data is unavailable, or review and correction consume as much effort as direct execution. The right question is not whether the task can be automated. It is whether automation improves the economics or control of the complete process.

    You can still use small assistive steps inside a human-owned workflow. Automating data collection or formatting does not require handing over budget allocation, final claims, campaign approval, or publication. Partial automation often captures repeatable savings while keeping judgment at the point where errors become expensive.

    Use stage gates before you scale the budget

    An automation business case should earn budget in stages. This keeps a promising experiment reversible and prevents sunk build effort from becoming the reason you continue funding a weak system.

    1. Define the accepted output. State the business outcome, required quality, approval owner, and failure that must not occur. A goal such as making marketing faster is too vague to measure.
    2. Measure the baseline. Record one representative manual production cycle from request to accepted output, including every role involved and any downstream correction.
    3. Choose the operating model. Match mature, measurable, repeatable work to automation; keep uncertain, low-volume, or poorly tracked work manual or tightly constrained.
    4. Run the smallest useful pilot. Preserve a comparison path, install tracking and exclusions first, and avoid changing several important variables at once. For a manual-to-automated Google Ads move, use a campaign experiment before shifting the full budget.
    5. Review total economics. Compare cash, labor per accepted output, total team labor, output volume, quality failures, maintenance, and displaced deliverables. Keep speed, scale, quality, and labor claims as separate benefits.
    6. Scale, revise, or retire. Increase funding only when the measured benefit survives full-cost accounting. If the outcome data is unreliable, repair measurement before giving the system more autonomy or budget.

    Key takeaways

    • Maintain separate cash and team-capacity ledgers for every automation.
    • Automate mature work with clean feedback; retain control where volume, tracking, or business rules are uncertain.
    • Count the time of operators, reviewers, recipients, and maintainers, not just the person who starts the workflow.
    • Treat a custom AI workflow as software with an owner, tests, documentation, and maintenance capacity.
    • Measure benefits at the accepted-output stage so draft speed and transferred rework cannot pose as productivity.

    Before approving your next automation request, add five columns to its budget: build labor, review and correction, maintenance, downstream cleanup, and the named marketing deliverable that will be displaced. If the team cannot fill them in, the workflow is not ready for more budget. If it can, you will have a defensible decision even when the right answer is to keep human control for now.

    References


  • AI Search Terminology: What Marketers Should Call the Work

    AI Search Terminology: What Marketers Should Call the Work

    You need a name for the work. It might be a budget line, a strategy deck, a job description, a service page, or the agenda for a meeting between SEO, content, PR, and analytics. Should you call it SEO, AI SEO, AEO, GEO, LLM optimization, or AI search optimization?

    Use SEO as the organizational umbrella and AI search optimization as the plain-language qualifier. Reserve AEO, GEO, and similar terms for a defined workstream. That gives familiar language to the person approving the work without hiding what has changed.

    The practical naming default: SEO plus AI search visibility

    Marketers have not abandoned SEO as quickly as specialist vocabulary might imply. Among 343 U.S. marketing decision-makers surveyed, 81% still called their internal AI search visibility strategy SEO. When searching online for help, 46% said they would use “AI search optimization” and 24% would use “SEO.” Together, those two understandable phrases accounted for 70% of the reported demand.

    Formal terminology is even less settled inside teams. Only 27% had adopted a term beyond SEO, while 42% had decided against doing so and 31% remained undecided. Treat those percentages as a directional view of one U.S. sample, not a universal naming law. They are self-reported choices from 343 decision-makers, not a census of every market or industry.

    Slow vocabulary adoption does not mean the work is being ignored. Respondents allocated an average of 24% of their search or content budgets to AI search visibility. Up to 82% reported committing at least some budget, and 43% allocated more than 20%. The label is lagging behind the investment.

    This creates a useful naming hierarchy:

    • SEO is the established program or department under which the work can sit.
    • AI search visibility names the business outcome: whether and how the brand appears in AI-mediated discovery.
    • AI search optimization names the work intended to improve that outcome.
    • AEO, GEO, LLM optimization, and agentic search optimization name narrower approaches or environments, but only after you define their scope.

    A practical strategy title is therefore “SEO and AI Search Visibility.” A defensible budget line is “SEO, including AI search optimization.” Both acknowledge the new surface without asking every stakeholder to learn an unsettled taxonomy before approving the work.

    A working glossary that distinguishes outcomes from methods

    A glowing destination and audience symbols are connected by a bridge to an arrangement of tools, content blocks, and linked source nodes.

    The category now spans AI search, answer engine optimization, and agentic-web terminology. These labels are useful, but they are not interchangeable and they are not universally standardized. Adopt working definitions inside your organization so the same acronym does not describe three different plans.

    TermUseful working definitionUse it whenCommon failure
    SEOThe established program for improving organic discovery, site accessibility, relevance, authority, and search performance.You need an umbrella understood by executives, practitioners, procurement teams, and job candidates.Treating AI-generated discovery as merely another ranking report, with no attention to answers, citations, or brand representation.
    AI search visibilityThe observable outcome of whether, where, and how a brand, product, person, or idea appears in AI-mediated search and answers.You are discussing goals, reporting, competitive presence, or reputation rather than a specific technique.Reducing visibility to a single score without examining accuracy, prominence, cited evidence, or business relevance.
    AI search optimizationThe broad set of activities intended to improve discovery, accurate representation, citations, and useful visibility across AI-generated search experiences.You need a buyer-friendly name for a cross-functional program that extends existing SEO.Using the phrase as a vague replacement for SEO without specifying platforms, prompts, owners, or measurements.
    AEOAnswer engine optimization: making relevant information clear, retrievable, well-supported, and suitable for systems that resolve questions with direct answers.The work focuses on question coverage, answer clarity, content structure, entity facts, and supporting evidence.Presenting AEO as a schema-only project. Structured data can clarify machine-readable facts, but it does not create authority or make weak content worthy of use.
    GEOGenerative engine optimization: improving the chance that a brand or its information is accurately represented, supported, and cited in generated responses.The scope includes generated answer behavior, third-party authority, citations, brand mentions, and source influence.Using GEO as an unexplained synonym for all SEO work or implying that optimization can guarantee a model recommendation.
    LLM optimizationA label centered on visibility or representation in products powered by large language models.The analysis genuinely concerns LLM-powered outputs, model-specific behavior, or the information environments those products use.Implying that a marketer can directly optimize an underlying model in the same way a page can be edited.
    Agentic search optimizationWork intended to help AI agents discover, evaluate, and use information while researching or completing tasks.Agent behavior and task completion are explicitly in scope, not merely the display of an answer.Using an early, specialized label as a general buyer-facing umbrella without defining what the agent is expected to do.

    The boundaries will overlap. An authoritative comparison page can support SEO, answer retrieval, generative citations, and agent research at the same time. That overlap is a reason to define the terms, not a reason to build separate teams around every acronym.

    For each term you adopt, write one sentence that answers three questions: Which discovery surface is in scope? What outcome are you trying to change? What work will the team perform? If the definition cannot answer all three, the term is branding rather than an operating instruction.

    Choose the term by the decision it needs to unlock

    The best label depends less on who has the newest vocabulary and more on what the recipient must decide. An executive deciding whether to fund the program needs a different level of detail from an analyst designing a prompt-monitoring workflow.

    1. For a strategy title, use “SEO and AI Search Visibility.” It connects the established function to the new outcome. Follow it with a scope statement naming the relevant answer surfaces, content, authority, technical foundations, and measurement.
    2. For a budget line, use “SEO, including AI search optimization.” State which existing budget funds it and which additional work the allocation covers. This prevents a terminology change from quietly becoming duplicate spending.
    3. For a vendor brief, ask for “AI search visibility across named buyer journeys and platforms.” Require the response to explain prompt selection, source analysis, content and authority work, measurement, and ownership. Do not award points merely for using GEO or AEO.
    4. For a dashboard, report “Organic Search” and “AI Search Visibility” as related views. Keep familiar SEO measures where they remain useful, then add AI-specific observations such as brand presence, answer accuracy, cited URLs, third-party source inclusion, referral quality, and assisted outcomes.
    5. For a specialist workstream, use the narrow acronym and define it. “AEO for support questions” or “GEO for category-comparison prompts” gives the term an object, a surface, and a purpose.
    6. For a job description, lead with the established function. A title such as “SEO Manager, AI Search” is easier to interpret than an acronym-only role. Put the changed responsibilities in the job scope: prompt research, answer-surface monitoring, entity consistency, structured content, external authority, and cross-channel measurement.

    Seniority changes the vocabulary but does not eliminate confusion. C-suite respondents used GEO at 28% and AEO at 17%, compared with 9% and 3% among individual contributors. Yet 56% of C-suite respondents also reported looking up an unfamiliar term. An executive using GEO may be signaling interest in the category, not agreement on a detailed operating model.

    Meet that interest with a definition, not another acronym. The most useful copy-ready version is:

    AI search optimization is the part of our SEO program that improves how our brand is discovered, represented, and cited in AI-generated search and answers. It combines technical accessibility, useful content, credible external signals, and measurement across the platforms our buyers use.

    That statement connects the emerging category to work a team can assign. It also avoids promising control over an AI system’s output.

    Clear language matters in vendor selection. Excessive buzzwords without explanations were the leading red flag for 36% of respondents. When GEO or AEO appeared in a pitch, 42% said their reaction depended on the context provided, 30% considered the language innovative, 22% said it had no effect, and 7% considered the vendor less trustworthy. The acronym can open a conversation, but it cannot carry the business case.

    Any internal proposal or vendor pitch should explain four things before introducing a specialized term:

    • Outcome: What should become more visible, accurate, authoritative, or useful?
    • Surface: Which search experiences, AI products, and buyer questions are included?
    • Method: What will change on owned pages, technical systems, structured data, external publications, community sources, or measurement workflows?
    • Evidence: What baseline, observations, and business measures will show whether the work helped?

    Turn terminology into an operating model

    Four teams at connected workstations contribute content, search, relationship, and measurement elements to a shared central hub.

    A new term earns its place only when it makes execution clearer. If GEO appears in a deck but nobody can identify the prompts, sources, owners, or measures attached to it, the team has renamed the problem rather than organized the work.

    Do not begin by creating a separate strategy for every platform. Reported priorities were fragmented: 34% prioritized ChatGPT, 16% Gemini, 6% Claude, 5% Copilot or Bing AI, and 1% Perplexity, while 14% had not selected a target platform. Those figures describe stated priorities in the U.S. sample, not platform usage or market share. They show why your own buyer behavior must determine scope.

    Build a scope from prompts and evidence sources

    1. Start with buyer decisions. Build a prompt set around the questions that precede discovery, comparison, validation, purchase, implementation, and troubleshooting. Include branded and unbranded questions. A list of head keywords alone will miss the context carried through a conversational query.
    2. Select surfaces based on those buyers. Test the relevant prompts across ChatGPT, Gemini, Google AI Overviews, Claude, Copilot or Bing AI, Perplexity, and any category-specific experience that matters to your market. You do not need to prioritize every surface equally.
    3. Record the answer, not just presence or absence. Capture whether the brand appears, how it is characterized, which alternatives appear, what factual errors matter, which URLs or publishers are cited, and whether the response satisfies the intended question.
    4. Map the information environment. Generated answers may draw influence from your own site, competitor content, list articles, trade publications, analyst pages, community discussions, Reddit threads, and YouTube transcripts. Mark each recurring source as owned, earnable, partner-controlled, community-controlled, or outside your realistic influence.
    5. Assign work by lever. SEO can own crawlability, internal architecture, canonical signals, and search demand. Content can own question coverage, clarity, evidence, and maintenance. PR and brand teams can build credible third-party mentions. Subject-matter experts can validate factual claims. Analytics can connect answer visibility to referral and downstream behavior.
    6. Name the workstream last. Once the team can see the surface, outcome, and activities, decide whether it is best described as SEO, AI search optimization, AEO, GEO, reputation work, digital PR, content operations, or a combination.

    This sequence prevents a label from dictating tactics. A query audit might reveal that a technical indexing problem is limiting discoverability, that weak comparison content is leaving an answer gap, or that authoritative third-party pages consistently omit the brand. Those are different problems even when all three reduce AI visibility.

    Measure the representation, the evidence, and the outcome

    No single metric can represent the entire program. An AI visibility score may help summarize repeated observations, but it can hide whether the brand is being recommended accurately, criticized, cited only for irrelevant questions, or mentioned without a path to the business.

    Use a compact scorecard with four layers:

    • Presence: How often does the brand appear for the defined prompt set, and which competitors appear beside it?
    • Representation: Are important facts, positioning, limitations, and differentiators described accurately?
    • Evidence: Which owned and third-party pages support the response? Are the citations relevant, credible, current enough for the question, and realistically influenceable?
    • Business effect: Do AI referrals, branded searches, qualified visits, assisted conversions, sales conversations, or other appropriate outcomes change alongside visibility?

    Keep the prompt set, platform set, capture method, and scoring rules documented. Otherwise, an apparent gain may come from changing the questions or evaluation method rather than changing market visibility. Generated responses can vary, so repeated observations and saved evidence are more useful than treating one answer as a permanent ranking.

    The naming debate should not consume the strategy. In the same decision-maker group, 28% named the pace of change as their leading challenge, ahead of measuring AI-result performance or visibility at 17%, choosing platforms at 15%, and the lack of standards or best practices at 13%. A durable operating model should therefore preserve familiar ownership while allowing the tested platforms, prompts, sources, and measures to change.

    Key takeaways

    • Keep SEO as the default organizational umbrella unless a different label solves a specific ownership or budgeting problem.
    • Use AI search optimization when you need a clear external or cross-functional name for the work.
    • Use AI search visibility for the outcome you measure, not as a substitute for defining the work.
    • Use AEO, GEO, LLM optimization, or agentic search optimization only with a one-sentence definition of the surface, outcome, and activities.
    • Do not mistake slow acronym adoption for weak investment. Teams can fund new work while keeping the familiar SEO label.
    • Evaluate a strategy by its prompts, evidence sources, owners, and measurements. Terminology is useful only when it makes those elements easier to understand.

    Open your current strategy document and inspect the first mention of the program. If it contains only an acronym, replace it with “SEO and AI Search Visibility” and add one sentence defining the surfaces, outcomes, and work included. If a term cannot be mapped to an owner, an activity, and a measure, remove it until it can.

    References


  • How to Build Connected Customer Profiles From Marketing Data

    How to Build Connected Customer Profiles From Marketing Data

    Your analytics platform records a purchase. Your ad platform records a conversion. Your loyalty system recognizes a member. Your point-of-sale system knows what was sold. Yet when you try to decide whether that person is a new prospect, a regular buyer or someone drifting away, the systems give you different answers.

    You don’t solve that problem by collecting more events. You solve it by giving each event a clear meaning, connecting it to the right identity, carrying consent through the connection and turning the resulting history into signals that can change a marketing decision.

    Key takeaways

    • Event capture and profile connection are separate quality layers. A perfectly recorded purchase can still land on the wrong profile.
    • Measure identity coverage as the share of relevant transactions attached to a known customer, not the number of people enrolled in a loyalty program.
    • Start with a marketing decision, then specify the event, identity, profile attribute, freshness and consent required to make it.
    • No-code tagging can simplify deployment, but it doesn’t define what an event means or prove that the event is accurate.
    • Different customer attributes need different refresh schedules. A missed purchase may matter immediately, while category affinity normally changes across repeated purchases.
    • Keep unknown customers separate from confirmed first-time customers. Treating unresolved identity as proof of newness corrupts acquisition decisions.

    Design the marketing decision before you design the data capture

    A conversion feed can contain product choices, basket value, discounts, channel, location and other transaction details. That still doesn’t reveal the customer’s relationship with the business. A $100 order from a first-time buyer and a $100 order from a frequent buyer look the same when history is missing, even though you should not necessarily advertise to those people in the same way.

    This is why a connected customer profile should begin with a decision contract, not a request to collect everything. The contract states what marketing is trying to change and the minimum data needed to make that change responsibly.

    1. Name the action. Be precise: suppress an existing customer from acquisition, include a lapsed customer in reactivation, select an eligible loyalty offer or adjust conversion-value optimization.
    2. Define the eligible population. State who may enter the decision and who must be excluded because of consent, geography, account state or insufficient identity.
    3. Identify the event that supplies evidence. A confirmed purchase, authenticated session or loyalty identification is evidence. A page view near the checkout is not proof of an order.
    4. Choose the identity requirement. Specify which authenticated account, loyalty or transaction identifier can connect the event to a profile. Also define what happens when that identifier is missing.
    5. Define the profile attribute. Write down how the system distinguishes first-time, repeat, active or lapsed customers and which events are allowed to change that status.
    6. Set the freshness requirement. Ask how old the event or derived attribute can be before the marketing action becomes misleading.
    7. Record the permitted use. State which destinations may receive the event, profile attribute or audience and which consent or governance condition must be satisfied.
    8. Choose the success measure. Evaluate the marketing decision that changes, not merely whether another field was added to a profile.

    For an acquisition-suppression use case, the action might be to exclude established buyers from campaigns intended only for new customers. The required evidence is confirmed purchase history connected to a reliable identity. If the transaction cannot be resolved, the safe data classification is unknown, not first-time. The profile can enter the suppression audience only when the status is current, the audience rule is valid and the intended advertising use is permitted.

    That distinction prevents a common measurement failure. When unknown and new are collapsed into one value, improvements in identity coverage appear to change customer composition even if actual buying behavior has not changed. Give unknown its own state in reports, audiences and quality checks.

    Capture events once, then validate their meaning everywhere

    Give every decision-critical event a contract

    A tag firing is a transport result. It doesn’t prove that the event represents the business outcome you intended. Before anyone configures a visual selector, tag or software development kit, create an event contract containing:

    • A canonical event name with one business meaning across web, app and physical channels.
    • The condition that confirms success. For a purchase, that should reflect a completed transaction rather than an early checkout interaction.
    • The occurrence time and the originating channel or system.
    • The stable event or transaction identifier used to detect repeat delivery.
    • The authenticated, loyalty, customer or anonymous identifiers available at that moment.
    • Only the properties required by an approved use case, such as product, basket, discount or location context.
    • The consent, purpose or permission context that controls collection and downstream activation.
    • The destinations authorized to receive the event.
    • An owner who approves changes to the event’s definition.

    Use the same canonical event when the same business outcome occurs in different interfaces. Channel belongs in a property; it should not force every team to invent a different definition of purchase. If the web team calls an order purchase, the app team calls it checkout_complete and the point-of-sale team calls it sale_closed, identity resolution may work while profile calculations still disagree.

    Also decide how duplicate delivery is handled. Browser retries, destination forwarding and overlapping implementations can produce more than one record for the same outcome. The profile layer needs a stable transaction or event key so a retry doesn’t become another purchase in cadence, value or repeat-buyer calculations.

    Treat no-code tagging as an implementation aid

    Google’s unified tagging direction makes implementation more accessible. Existing Google tags are being upgraded into capable Google Tag Manager containers, bringing interface-driven configuration, debugging and version control into a more unified setup. Google has also introduced visual event creation that lets an operator navigate a site and select elements while the system handles selectors and triggers.

    That can reduce the coding needed to deploy an event. It doesn’t answer whether clicking the selected element proves a conversion, whether the same interaction exists in an app or store, whether the event will fire twice, or whether the attached identifier and consent state are valid. Set the event contract first, then use visual tagging to implement the approved condition.

    The updated setup can also provide a visual map of the Google destinations receiving measurement data. Optimized containers may send data directly to those destinations instead of loading additional gtag.js code, which Google says can reduce measurement latency and potentially improve site performance. Treat the destination map as part of release review: every expected destination should be present, and every unexpected destination should be investigated before publication.

    If you already run a sophisticated Tag Manager container, don’t publish an optimization proposal on the assumption that a simpler configuration is identical. Optimization is optional, and authorized users can preview proposed changes before publishing. Existing event tags are intended to remain unchanged, but initialization and account-linking behavior still deserve review.

    Pay particular attention to deployment code. Google’s announced direction moves new snippets toward a shared format without the gtag config command and recommends the gtm init trigger for initialization behavior. A legacy setup that still depends on the config command can be configured to wait for it. Document that dependency before migration so a cleanup doesn’t silently change consent initialization, configuration order or event availability.

    Before publishing any capture change, run the actual customer path and verify the business result, not just the debug console. Confirm that the event fires once, carries the expected transaction and identity keys, excludes unapproved properties, reaches only approved destinations and remains consistent after navigation or refresh. Save the reviewed container version so the release can be traced and reversed if validation fails.

    Connect interactions to a governed customer identity

    Retail and digital interaction objects pass through a protected matching hub and connect to one customer silhouette.

    Measure identity coverage, not enrollment

    Ecommerce accounts and subscription relationships often provide authentication by design. Physical retail, grocery and quick-service transactions are harder because a purchase can happen without identification. Loyalty can bridge that gap when a member identifies at the register, in an app or during a drive-through transaction.

    A large loyalty membership total doesn’t show whether purchase history is connected. The operational metric is the share of transactions that arrive with a customer attached.

    Identity coverage = identified eligible transactions divided by all eligible transactions.

    Define eligible for your business before using the ratio. It should represent transactions in which your measurement design provided a legitimate opportunity to identify the customer. Then segment coverage by channel, device, store, checkout path or other operational handoff. The aggregate rate can look stable while one important path fails to collect or transmit an identifier.

    Coverage alone isn’t enough. A transaction can contain an identifier and still connect to the wrong profile. Track at least three separate outcomes: identified and resolved, identified but unresolved, and anonymous. That separation tells you whether the problem sits in collection, transport or identity matching.

    Make identity joins explainable and correctable

    Keep raw identifiers and the connected profile identifier as separate fields. The raw values show what each system observed; the profile identifier shows the result of resolution. If you overwrite the former with the latter, it becomes difficult to explain a bad merge or repair customer history later.

    • Prefer authenticated or directly captured relationships when linking activity to a known profile.
    • Record which identifier and originating system caused each link.
    • Define what evidence permits two records to merge and what evidence requires them to split.
    • Preserve the time of the link so historical calculations can be reproduced.
    • Do not label an unresolved identifier as a new customer merely because no history was returned.
    • Provide a correction path for shared accounts, recycled identifiers, entry errors and other bad joins.

    Consent must travel with this process. A profile join can turn previously disconnected activity into a more revealing customer history, so it can expand the consequences of a permission error. Store the relevant permission and permitted-use context with identifiers and events, enforce it before audience activation and have the appropriate privacy or legal owner validate retention and use rules for your business. A separate consent database that isn’t consulted during the join or audience sync does not protect the downstream decision.

    The final test is continuity. A register transaction, app session and loyalty account create connected history only if they resolve to the intended profile, appear soon enough for the marketing decision and retain the same governance rules wherever they are used.

    Turn connected history into fresh, usable marketing signals

    A sequence of customer interactions passes through a glowing prism and emerges as three illuminated marketing signals beside a customer silhouette.

    Once events are connected, keep three data layers distinct. They have different owners, update patterns and failure modes.

    Data layerWhat belongs in itQuestion it must answer
    Identity and governanceIdentifiers, consent, permitted uses and relationships among profilesMay this activity be joined and used for this purpose?
    Loyalty program stateTier, points balance, reward eligibility, redemption history and tenureWhat program status or benefit currently applies?
    Derived attributesPurchase cadence, time between orders, category affinity, time and location patterns, channel mix and offer responseWhat does connected behavior imply for the next marketing decision?

    The third layer makes history actionable, but only when freshness matches the behavior. Purchase cadence can produce a signal when nothing happens. If a customer usually buys on a recurring pattern and then misses expected purchases, no new transaction arrives to trigger an update. A scheduled calculation must detect the absence. Category affinity changes differently: repeated purchases can establish or shift a preference, while an isolated purchase should not automatically redefine the profile.

    Don’t assign one universal refresh schedule to every attribute. Work backward from the decision. An exclusion used by an active acquisition campaign may need recent purchase status. A category preference built across a longer history can change more gradually. The right interval depends on your observed buying cycle and how quickly a stale value can cause the wrong action.

    Give every derived attribute its own contract:

    • A plain-language definition that marketing, analytics and engineering interpret the same way.
    • The qualifying events and event properties used in the calculation.
    • The identity coverage required before the result is considered usable.
    • The update mode: event-driven, scheduled or both.
    • The condition that makes the value stale or unknown.
    • The allowed marketing destinations and permitted purposes.
    • The fallback when history is incomplete, delayed or contradictory.
    • The owner responsible for validating changes to the logic.

    Activation should preserve those definitions. If repeat-buyer status means one thing in analytics and another in the ad audience, the profile is not truly connected at the decision layer. Use a shared, versioned rule or prove that each destination implements an equivalent rule.

    • Acquisition suppression: use confirmed, sufficiently current customer history; never assume unresolved means new.
    • Reactivation: use a cadence or inactivity signal that is recalculated even when no new event arrives.
    • Category messaging: require enough connected history to distinguish a repeated preference from an isolated purchase.
    • Loyalty treatment: use current program state rather than recreating tier or reward rules inside each advertising destination.
    • Conversion-value optimization: document which profile signal changes the value and how stale, missing or disallowed data is handled.

    Audit one customer journey from capture to activation

    A dashboard can show healthy event volumes while a profile, audience or consent handoff is broken. Use a governed test profile and trace one complete journey through the system:

    1. Complete the intended interaction through the real web, app, loyalty or point-of-sale path.
    2. Confirm that the canonical event appears once with the expected occurrence time, transaction key, properties and consent context.
    3. Verify that the captured identifier resolves to the intended profile and that the resolution method is recorded.
    4. Inspect the connected history to make sure the event appears once and in the correct order.
    5. Run or wait for the relevant derived calculation, including any scheduled logic required to detect inactivity.
    6. Evaluate the audience or decision rule and confirm that unknown, stale and disallowed states follow their documented fallback.
    7. Verify that only approved destinations receive the event, attribute or audience membership.
    8. Change or withdraw the test permission where your system supports it, then confirm that downstream activation respects the new state.

    Run that trace after changes to tags, identity rules, profile calculations, consent handling or audience logic. Volume monitoring should remain in place, but an end-to-end trace reveals whether all the individually healthy components still produce the intended customer decision.

    Your next move is deliberately narrow. Choose one campaign in which a first-time customer and an established customer should be treated differently. Write the decision contract, instrument the minimum required event and trace one test profile from capture to destination. Expand to another signal only after you can explain every identity join, freshness rule, permission check and fallback on that path.

    References