Tag: AI Tools

  • AI Coding Assistant Market Share: Who Leads in 2026?

    AI Coding Assistant Market Share: Who Leads in 2026?

    If you are choosing an AI coding assistant for yourself or your development team, the headline answer is clear: Claude Code leads the October 2026 primary-tool market at 29.4%, ahead of GitHub Copilot at 22.7%. That does not automatically make Claude Code the right purchase. The aggregate ranking hides large differences between startups and enterprises, terminal users and IDE users, and the assistant you open versus the model that actually generates the code.

    The useful question is not simply which product is biggest. It is which market signal applies to your environment, what the rapid move toward coding agents changes, and how much weight market share should carry in your evaluation. Here is how to read the numbers without turning popularity into a substitute for testing.

    Read primary-tool share as a competitive signal, not total adoption

    The October estimate measures the percentage of professional developers who name a product as their primary AI coding assistant: the one they use most often to write, edit, or review production code. It does not count every tool a developer has tried, every installed extension, total seats, vendor revenue, or the volume of code generated.

    That distinction matters because many developers use two or three assistants. A developer might rely on Claude Code for repository-wide implementation, keep GitHub Copilot enabled for inline completion, and occasionally send a background task to Codex. Only the tool used most often receives that developer’s primary-tool share.

    The estimate combines an August 4 to September 26, 2026 survey of 2,350 professional developers in North America and Europe with publicly disclosed seat and usage figures. The responses were normalized into a market model. That makes the results useful for understanding competition among leading products, but they are not a worldwide census or a direct measure of software quality.

    Use the rankings to build a shortlist, understand where workflows are moving, and challenge an outdated default. Do not use them alone to approve a company-wide rollout.

    Key takeaways

    • Claude Code leads with 29.4% of primary-tool share in October 2026; GitHub Copilot follows at 22.7%, Cursor at 13.1%, and OpenAI Codex at 11.8%.
    • The four largest assistants hold 77.0% combined, up from 71.2% in January 2026.
    • Terminal and CLI agents are now the largest interface category, rising from 21.3% in January to 38.6% in October.
    • Company size changes the ranking: Claude Code leads among startups, while GitHub Copilot leads at companies with more than 5,000 employees.
    • Product share and model share are different. Claude models account for 47.3% of model-family coding usage because they are available through products beyond Claude Code.
    • Market share can tell you which tools deserve evaluation. Only a controlled test against your repositories, policies, and workflows can tell you which one deserves deployment.

    The October leaderboard shows both concentration and disruption
    Large central technology nodes and smaller fast-moving nodes compete inside a glowing circular digital arena.

    The October 2026 primary-tool snapshot puts two terminal-oriented agents in the top four and shows substantial movement since January. The change column uses percentage points, not percent growth.

    RankAI coding assistantDeveloperPrimary interfaceOctober 2026 shareChange since January
    1Claude CodeAnthropicTerminal agent29.4%+10.9 points
    2GitHub CopilotMicrosoft / GitHubIDE extension22.7%-7.8 points
    3CursorAnysphereAI-native IDE13.1%-4.9 points
    4OpenAI CodexOpenAITerminal and cloud agent11.8%+7.6 points
    5Google Antigravity and Gemini Code AssistGoogleAI-native IDE5.6%+1.1 points
    6JetBrains AI and JunieJetBrainsIDE extension4.3%-0.6 points
    7WindsurfCognitionAI-native IDE2.9%-1.9 points
    8Amazon Q Developer and KiroAmazonIDE extension2.6%-0.8 points
    9OpenCodeOpen sourceTerminal agent2.4%+1.6 points
    10ClineOpen sourceIDE extension1.7%-0.5 points
    –All other toolsVariousVarious3.5%-4.7 points

    Claude Code’s lead is meaningful because it is paired with the largest gain in the table. OpenAI Codex has the second-largest increase and has nearly tripled its primary-tool share since January. Copilot and Cursor remain substantial products, but both have lost share while agent-oriented tools have gained it.

    The top four products now account for 77.0% of primary-tool usage, compared with 71.2% in January. That is evidence of concentration within this definition of the market. It is not evidence that the category has settled: the order inside that concentrated group has changed quickly.

    The five-quarter trajectory is more useful than a single rank

    Quarterly averages smooth out the monthly movement and show that the change in leadership was not a one-month fluctuation. They also explain why the Q3 values below differ slightly from the October snapshot.

    AssistantQ3 2025Q4 2025Q1 2026Q2 2026Q3 2026
    GitHub Copilot36.2%33.4%30.1%26.0%23.1%
    Claude Code7.9%12.6%19.2%24.8%28.7%
    Cursor19.4%19.9%17.6%15.2%13.5%
    OpenAI Codex1.8%3.1%4.6%8.3%11.2%
    Google3.6%4.1%4.0%4.9%5.4%

    Claude Code passed GitHub Copilot between Q2 and Q3 2026. Copilot declined in every quarter shown, while Claude Code rose in every quarter. Cursor peaked at 19.9% in Q4 2025 and then declined for three consecutive quarters. Codex accelerated most sharply after Q1 2026, moving from 4.6% to 8.3% in Q2 and 11.2% in Q3. Google’s movement was steadier, ending Q3 at 5.4%.

    For a buyer, sustained direction deserves more weight than a narrow difference in one snapshot. A rising product is more likely to receive integrations, community attention, training material, and internal advocacy. A falling product can still be the best operational fit, especially when its decline reflects a changing interface preference rather than a failure of the product itself.

    The decisive change is from suggestions to delegated tasks
    A developer moves from receiving one code suggestion to supervising AI agents that coordinate coding, testing, and deployment tasks.

    The market is not merely swapping one vendor for another. Developers are changing how they interact with coding AI. Inline completion asks an assistant to help with the next fragment of code. An agent can receive a broader goal, inspect multiple files, make coordinated edits, run commands or tests, and return a larger unit of work for review.

    The interface numbers capture that shift. Tools that support several interfaces are assigned to the one each respondent uses most often, so the categories describe dominant behavior rather than permanent product boundaries.

    Interface typeJanuary 2026 shareOctober 2026 shareChange
    Terminal / CLI agent21.3%38.6%+17.3 points
    IDE extension41.2%29.4%-11.8 points
    AI-native IDE24.8%17.9%-6.9 points
    Cloud / background agent5.1%9.2%+4.1 points
    Browser-based app builder7.6%4.9%-2.7 points

    Terminal and CLI agents gained 17.3 points between January and October, becoming the largest interface category at 38.6%. Cloud and background agents also gained share. IDE extensions fell from 41.2% to 29.4%, while AI-native IDEs fell from 24.8% to 17.9%.

    This does not mean the IDE is disappearing. IDE extensions still represent nearly three in ten primary workflows, and many agent users review the resulting code in an editor. It means that an evaluation built entirely around autocomplete quality is now incomplete.

    Your test set should include the work agents are being asked to own: a change that touches several files, a bug whose cause is not identified in the prompt, a refactor that must preserve behavior, and a review task that requires following repository conventions. Record whether the assistant finds the right context, makes coherent changes, validates them, and leaves an understandable diff. A fast completion is not useful if the developer spends longer discovering and correcting hidden mistakes.

    Agent capability also changes the risk boundary. If a tool can execute commands, modify many files, access external systems, or open pull requests, test it first in a protected branch or isolated environment. Apply the least permissions it needs, keep credentials out of its context, require review before merge, and let your normal test and security controls judge the output. The specific downside is larger than a poor inline suggestion: an agent can propagate a wrong assumption across a repository or act on an unintended resource.

    Your company size and model layer change the apparent winner

    The overall ranking is least reliable when it is treated as though every buyer faces the same constraints. The split by employer size shows four materially different markets.

    Company sizeClaude CodeGitHub CopilotCursorOpenAI CodexAll other tools
    Startup, 1-50 employees36.8%9.7%21.4%15.2%16.9%
    Small business, 51-50033.1%17.5%16.2%13.4%19.8%
    Mid-market, 501-5,00027.9%25.8%11.7%10.9%23.7%
    Enterprise, more than 5,00022.4%35.6%8.3%9.1%24.6%

    Claude Code is strongest among startups at 36.8% and declines steadily to 22.4% at enterprises. Cursor has an even sharper segment gap, moving from 21.4% among startups to 8.3% at companies with more than 5,000 employees. Codex follows the same broad pattern, though less dramatically.

    GitHub Copilot moves in the opposite direction. It holds 9.7% among startups but leads the enterprise segment at 35.6%. Existing Microsoft licensing agreements help explain why Copilot remains the default procurement route inside many large organizations. At mid-market companies, Claude Code and Copilot are much closer, at 27.9% and 25.8% respectively.

    If you work at a startup, the aggregate table understates the prevalence of Claude Code, Cursor, and Codex among your peers. If you manage enterprise tooling, it understates Copilot’s position and the influence of procurement, identity, administration, and existing contracts. Use the segment closest to your organization as the starting point, then check whether your technical and governance requirements resemble that peer group.

    Do not confuse the assistant with the underlying model

    A product is the working environment: its interface, context handling, repository tools, permissions, integrations, and review flow. A model is the code-generating engine available inside that environment. Several assistants allow developers to choose among model families, so the product leaderboard cannot tell you which models generate the most coding output.

    Model familyDeveloperJanuary 2026 shareOctober 2026 share
    ClaudeAnthropic49.2%47.3%
    GPTOpenAI22.4%28.6%
    GeminiGoogle11.8%10.2%
    Open-weight models, including Qwen, DeepSeek, Kimi, and GLMVarious10.3%9.4%
    GrokxAI3.4%2.1%
    All other modelsVarious2.9%2.4%

    Claude models account for 47.3% of model-family coding usage, substantially more than Claude Code’s 29.4% product share. The difference exists because Claude models are also used within Cursor, GitHub Copilot, and open-source agents. GPT models gained 6.2 points between January and October, reaching 28.6% as Codex expanded. Open-weight models retained 9.4%, with their use concentrated among cost-sensitive teams and self-hosted deployments.

    This separation gives you a better evaluation design. First judge whether the product fits your workflow and controls. Then compare the models available inside it on the same tasks. Keep the model name and version in your evaluation record; otherwise, a model change can be mistaken for a product improvement or regression.

    Turn the market-share numbers into a defensible tool decision

    Market share is useful evidence of momentum, ecosystem depth, and peer adoption. It does not directly measure correctness, security, developer satisfaction, review burden, total cost, or performance on your codebase. A defensible decision uses the market data to narrow the field and repository-level evidence to choose among the finalists.

    1. Define the job before naming a vendor. Decide whether you mainly need inline completion, repository exploration, multi-file implementation, code review, background execution, or a combination. The interface trend shows that these are no longer interchangeable versions of the same task.
    2. Apply your non-negotiable constraints. Check supported editors and terminals, operating environments, authentication, administrative controls, data handling, model availability, network access, auditability, and contract requirements. Remove any product that cannot meet a genuine constraint before comparing output quality.
    3. Build a segment-aware shortlist. Include the overall leader, the leader for your company-size segment, and a credible alternative with a different interface or model strategy. An enterprise shortlist that ignores Copilot would miss the segment leader; a startup shortlist containing only Copilot would ignore how differently that segment behaves.
    4. Use the same representative task set. Give every finalist an existing bug, a multi-file feature, a behavior-preserving refactor, and a code-review assignment drawn from the kinds of repositories it would actually encounter. Keep the prompt, starting commit, permissions, and acceptance criteria consistent.
    5. Score the cost of reaching an acceptable result. Record whether the final change passes the relevant tests, how much developer intervention it requires, how long review and correction take, whether it follows repository conventions, and what the successful result costs. Do not reward a tool merely for producing more code or producing it faster.
    6. Test assistant and model choices separately. When a product offers several models, rerun the important tasks with each viable model. This reveals whether the value comes from the interface and agent harness, the underlying model, or their combination.
    7. Control the rollout and set a reassessment trigger. Begin with repositories and permissions where mistakes are detectable and reversible. Expand only after the review burden and failure modes are understood. Reassess when a major model, agent mode, pricing structure, policy requirement, or contract renewal changes the decision.

    The practical choice is rarely the product with the largest number beside its name. It is the assistant that completes your representative work with the lowest combined burden of prompting, correction, review, administration, and risk. Use the 2026 leaderboard to decide what deserves a serious test, then let reproducible work in your own environment decide what your team adopts.

    References


  • Goodie vs. Profound: Which AEO Platform Fits Your Team?

    Goodie vs. Profound: Which AEO Platform Fits Your Team?

    You are not choosing between two AI visibility dashboards. You are choosing where your team will do the hardest part of answer engine optimization: finding worthwhile prompts, deciding what to change, shipping the work, or proving that the work affected the business.

    If you are stuck between Goodie and Profound, start with that bottleneck. Goodie is the clearer fit when you want prompt research, prioritized actions, execution, and revenue attribution in one operating loop. Profound is the stronger candidate when deep prompt intelligence, crawler analysis, and configurable enterprise workflows matter more than receiving a tightly prescribed action queue.

    The practical answer: choose the workflow your team can run

    Both platforms can help you monitor how a brand appears in AI-generated answers. That overlap is real, but it is not where the buying decision lives. The meaningful difference is what happens before monitoring and after a visibility problem appears.

    Decision areaGoodieProfoundWhat it means for you
    Primary orientationClosed-loop AEO operationsEnterprise AI-search intelligence and automationChoose between a more prescribed operating loop and a deeper intelligence layer your team can configure.
    Prompt researchTurns prompt opportunities into monitored topics and optimization workConversation Explorer emphasizes prompt demand and audience-question intelligenceDecide whether you need an actionable queue or a larger research environment.
    OptimizationPrioritized actions tied to visibility gapsWorkflows and agents that can support automated content operationsGoodie reduces interpretation work; Profound can reward teams able to design their own processes.
    Technical intelligenceConnects monitoring with recommended content and technical changesAgent Analytics examines how AI crawlers interact with a siteProfound deserves close attention when crawler behavior is a central diagnostic requirement.
    Business measurementRevenue attribution is presented as part of the native AEO loopStrong visibility, crawler, and referral analysis; revenue-level measurement needs closer validationIf finance expects pipeline or revenue evidence, test the attribution chain rather than accepting an integration logo.
    Operating fitTeams that want fewer handoffs between analysis and executionEnterprises with analysts, marketing engineers, or established content operationsThe more capable your internal operating team is, the more value it can extract from a flexible intelligence platform.

    Goodie positions its product around a research-to-revenue loop, while Profound emphasizes Conversation Explorer, Agent Analytics, and agentic workflows. Those capability claims originate with Goodie, one of the vendors being evaluated, so treat them as hypotheses for your proof-of-fit rather than as an independent benchmark.

    The short recommendation is straightforward. Choose Goodie when the missing link is turning visibility data into owned work and connecting that work to commercial outcomes. Put Profound first when you already have people who can interpret data and execute, but they need richer prompt intelligence, crawler evidence, and automation infrastructure.

    Prompt research: decide whether you need a map or a queue

    Two strategists compare a broad constellation of connected prompt signals with a focused queue of prompt cards in a digital studio.

    Your prompt set is not a minor configuration detail. It defines the market the platform measures. If you track only brand-name questions, your score can look healthy while you remain absent from the unbranded questions buyers ask before they know you. If you fill the set with broad informational prompts, you can generate a large dashboard with little connection to a purchase decision.

    A useful prompt library should cover distinct stages of the decision, including:

    • Problem recognition: questions asked before the buyer knows which category could help.
    • Category discovery: requests for approaches, products, providers, or methods.
    • Comparison: questions that place alternatives, features, constraints, or use cases side by side.
    • Validation: questions about proof, reliability, security, implementation, or compatibility.
    • Purchase friction: questions about price, migration, onboarding, contracts, and switching risk.
    • Post-purchase use: questions that can influence retention, adoption, and recommendation.

    Profound’s Conversation Explorer is built around discovering and evaluating what people ask answer engines. That makes Profound compelling when your first problem is demand intelligence: you do not yet know which conversations matter, how questions cluster, or where the relevant opportunity sits.

    Goodie’s Prompt Research is designed to feed discovered opportunities into monitoring and optimization actions. That orientation is useful when your team already understands the market reasonably well but struggles to convert research into an ordered backlog.

    Make both vendors work from the same prompt brief

    Do not let either demo begin with a polished sample category. Give both vendors the same brief containing your products, markets, buyer roles, competitors, and exclusions. Include questions where you expect to appear, questions where a competitor usually appears, and questions for which you do not yet know the answer.

    1. Ask the platform to expand your seed questions without adding irrelevant informational demand.
    2. Require an explanation for why each suggested prompt belongs in the monitored set.
    3. Inspect the raw answer-engine responses behind every aggregate score.
    4. Check whether prompts can be segmented by intent, audience, market, product, and stage of the buying journey.
    5. Change the prompt set and confirm that historical reporting remains interpretable.
    6. Ask how a discovered opportunity becomes assigned work, not merely another saved chart.

    The winner is not the platform that returns the largest list. It is the one that helps you defend why a prompt matters and shows what your team should do with it. A vast prompt database can still produce a weak AEO program if no one can distinguish buyer demand from topical noise.

    Optimization and attribution reveal the real split

    Visibility monitoring tells you that an answer engine mentioned a competitor, cited another domain, or described your brand inaccurately. That is diagnosis. The operational value begins when someone can identify the underlying cause, choose an intervention, assign an owner, publish or deploy the change, and watch the relevant answers afterward.

    Goodie puts prioritized optimization actions and revenue attribution inside the same product scope as prompt research and monitoring. For a lean team, that can remove the recurring handoff from analyst to strategist to writer or developer. It also gives leadership a more direct narrative: this was the visibility gap, this was the action, and this was the observed business outcome.

    Profound should not be dismissed as a monitoring-only product. Its Workflows support automated content operations, while Agent Analytics examines crawler activity and answer-engine referrals. The distinction is that Profound’s value leans more heavily on the sophistication of the operator. A marketing engineering team may prefer that flexibility. A small SEO team may discover that it has bought a powerful system without enough capacity to design and maintain the workflows around it.

    Test whether an optimization is evidence, advice, or execution

    Vendors often place all three under the word optimization, but they are different deliverables:

    • Evidence identifies the prompt, response, cited sources, competitor, and affected page.
    • Advice explains the likely cause and recommends a specific change.
    • Execution creates, exports, assigns, publishes, or deploys the work.

    During the evaluation, select a genuine visibility gap and follow it all the way through the product. Ask which page should change, what should change on it, why that intervention matches the evidence, who receives the task, and how the system detects a later answer change. If the workflow ends with generic advice such as improve authority or create better content, you are still buying diagnosis.

    Do not confuse an AI referral report with revenue attribution

    A referral dashboard can show visits from an answer engine. Revenue attribution has to explain how those visits, leads, opportunities, or purchases are associated with the channel. A visibility trend is further removed: a brand can gain mentions without receiving a click, and a later conversion may have several earlier influences.

    Goodie’s native attribution proposition gives it the clearer advantage when proving commercial impact is a purchase requirement. You should still make the team expose the method. Ask these questions on screen:

    • Which outcomes are observed directly, and which are modeled?
    • How are direct referrals distinguished from zero-click exposure?
    • Can reporting separate first-touch, last-touch, and assisted influence?
    • Can you trace a prompt, visibility gap, optimization action, changed response, visit, and conversion without manually joining exports?
    • Which analytics and CRM fields are required?
    • Can your analysts export the underlying events and reproduce the reported total?
    • How does the system avoid claiming causation from a visibility increase that merely occurred before a revenue increase?

    If the platform cannot answer those questions, call the feature directional measurement rather than revenue attribution. That does not make it useless. It makes the claim precise enough for your finance and analytics teams to use responsibly.

    Enterprise pricing: model the total cost of operation

    The headline prices create an easy trap. Goodie lists Core at $399 per month and Pro at $999 per month, while Profound lists Starter at $99 per month and Growth at $399 per month; broader enterprise packages use custom pricing. Those figures do not represent equivalent scopes.

    A lower subscription can become the more expensive operating model if you must add analyst time, workflow tooling, content production, technical implementation, and a separate attribution layer. An integrated platform can also become expensive if the features you need sit above the entry plan or if usage expands with prompts, answer engines, brands, markets, and response volume.

    Calculate total operating cost as the subscription plus usage expansion, onboarding, integrations, internal analysis, content and technical execution, data engineering, security review, and ongoing administration. Use the same scope for both quotes.

    Quote lineWhat to requireWhy it changes the real price
    Prompt economicsTracked prompts, research queries, generated responses, refresh frequency, and overage rulesVendors can meter different units even when their plan labels look similar.
    Engine coverageExact answer engines available on the quoted tierA long platform list is irrelevant if the engines you need require an upgrade.
    Organizational scopeBrands, products, markets, countries, languages, seats, roles, and workspacesEnterprise cost often grows through organizational complexity rather than a single feature.
    Data accessHistory, retention, raw responses, exports, API access, and business-intelligence connectionsA dashboard can become a data silo if usable evidence cannot leave it.
    ExecutionAction allowances, workflow or agent credits, publishing paths, approvals, and task-system integrationsAn action layer may be available but metered separately from monitoring.
    AttributionAnalytics connections, CRM support, identity handling, models, and raw event accessAttribution may require implementation work outside the license.
    GovernanceSSO, permissions, audit records, data handling, and procurement documentationRequired controls can move an otherwise affordable deployment into an enterprise contract.
    ServiceOnboarding, strategist access, support channel, response commitments, and trainingA platform that requires specialist operation should be priced with that labor included.
    Commercial termsBilling period, minimum commitment, renewal mechanics, overages, implementation fees, and exit accessThe monthly figure alone does not reveal contractual risk.

    Key takeaways

    • Choose Goodie when your main gap is turning prompt and visibility data into prioritized work and connecting the result to revenue.
    • Choose Profound when deep prompt intelligence, crawler analysis, and configurable enterprise automation are the priority, and you have specialists who can operate them.
    • Do not treat visibility, referral traffic, and revenue attribution as interchangeable measurements.
    • Compare quotes using the same engines, prompts, brands, markets, seats, integrations, data access, service, and execution workload.
    • Treat every vendor-supplied capability claim as something to reproduce with your own prompts, pages, and analytics path.

    Run a proof-of-fit that produces work, not screenshots

    A cross-functional team moves prompt artifacts through testing stations for discovery, content improvement, release, verification, and outcome validation.

    A polished dashboard demo tells you very little about whether the platform will survive contact with your organization. A useful proof-of-fit starts with your evidence and ends with a decision or deliverable your team would genuinely use.

    1. Write the operating problem in one sentence. For example: the content team cannot tell which unbranded buyer questions deserve work, or leadership cannot connect AEO activity to pipeline.
    2. Provide an identical prompt set, competitor set, market scope, and group of existing pages to both vendors.
    3. Require access to the raw responses, citations, timestamps, segmentation, and calculation behind every score shown.
    4. Select a real visibility gap and make each platform diagnose it, recommend a change, and route the work to the person who would own it.
    5. Run the proposed change through your approval and publishing process. Note every manual export, copy-and-paste step, missing integration, and specialist handoff.
    6. Connect the relevant analytics environment and trace what the platform can observe after the change. Separate answer visibility, referrals, conversions, and modeled influence.
    7. Request a production quote for the exact tested scope, including expansion rules and the controls procurement will require.

    Score the result on prompt relevance, diagnostic transparency, action quality, workflow fit, measurement credibility, governance, and total operating cost. Do not create a broad feature checklist in which every row has equal value. A missing capability that blocks your operating loop matters more than several interesting features your team will not use.

    Goodie should win your evaluation if it consistently turns relevant prompt gaps into work your existing team can ship, then gives your analysts a defensible path to business outcomes. Profound should win if its prompt and crawler intelligence changes your decisions materially, and your team can exploit its workflows without adding an unplanned operating layer.

    If neither vendor can reproduce its claims using your prompts and data, do not force a selection. Tighten the use case, establish a manual baseline, and return when you know which part of the AEO loop deserves software. Before the next demo, complete this sentence: We are buying this platform so that a named owner can make a named decision and ship a named change without a named bottleneck. The product that proves that workflow is the better choice for you.

    References

  • Profound’s Gartner 2026 Recognition: What It Signals

    Profound’s Gartner 2026 Recognition: What It Signals

    If Profound’s Gartner recognition has put the platform on your shortlist, treat that as a reason to investigate, not a reason to buy. The useful question isn’t whether the recognition sounds impressive. It’s whether Profound can help your team turn an AI visibility problem into a specific intervention and then show what changed.

    That distinction matters because AI search programs often become reporting programs. Teams collect mentions, citations, prompts, and competitor comparisons, but the findings never become owned work with measurable consequences. The strongest interpretation of this recognition is that the market is beginning to demand a complete operating loop rather than another dashboard.

    What the Gartner mention does and does not prove

    Profound reports that it was named in Gartner’s 2026 Coolest Vendor Innovations in CRM alongside Canva, Decagon, dx0, and Twenty. That makes the company relevant to a serious evaluation of emerging AI marketing infrastructure.

    It does not, by itself, establish that Profound is the best platform for your organization. A recognition is not a product benchmark, an implementation plan, or proof of business impact in your environment. It doesn’t answer questions about data coverage, workflow fit, measurement quality, integrations, governance, or the effort required to turn a recommendation into a deployed change.

    The claim also comes from Profound’s own account of the recognition. That doesn’t make it unimportant, but it does set the correct evidence standard: use the mention to justify deeper due diligence, then make the product earn its place through your own workflow and data.

    Don’t turn the recognition into an improvised ranking. The named companies address different parts of customer and marketing work, so their appearance together doesn’t mean they are interchangeable competitors. For your decision, the relevant comparison is between Profound and the other ways you could operate your AI visibility program, including internal analysis, specialist tools, agencies, and connected systems.

    Why the insight-to-outcome loop matters in AI visibility

    An isometric circular workflow carries search inputs through analysis, assigned work, production, and measured feedback while team members collaborate at each stage.

    Profound interprets the recognition as evidence that marketers increasingly expect a closed loop from insight to action to measured outcome. That is a vendor-held interpretation, but it gives buyers a much better evaluation standard than feature counting.

    AI visibility work starts with an observation: perhaps a brand is missing from an important answer, a competitor is cited more often, or a product is described inaccurately. None of those observations creates value on its own. Value appears only when the team can diagnose a plausible cause, assign a suitable intervention, publish or distribute the change, and measure the result against a defined baseline.

    StageQuestion your workflow must answerEvidence to request
    InsightWhat exactly is happening, for which queries, audiences, markets, and AI experiences?Saved answer-level observations, timestamps, query definitions, cited domains, and a clear distinction between collected data and inferred explanations.
    ActionWhat should change, where should it change, and who owns the work?A recommendation tied to the original observation, a destination such as a page or entity record, an owner, status, and change history.
    OutcomeDid visibility, representation, referral activity, or a downstream business measure improve after the intervention?A preserved baseline, comparable follow-up observations, deployment dates, and an outcome definition agreed before the work began.

    This framework also prevents a common category error. A suggested content revision, outreach task, or JSON-LD update is an action, not an outcome. Schema markup can make eligible facts easier for machines to interpret when it accurately represents visible content, but merely deploying markup doesn’t prove that an AI system used it or that customer behavior changed.

    The CRM context is useful here. Customer and revenue consequences usually live downstream from visibility data. A credible closed loop therefore needs either native connections or documented handoffs between AI answer monitoring, content operations, technical implementation, analytics, and customer systems. It doesn’t all have to happen inside one platform, but the path between systems must be traceable.

    Run this six-part evaluation before you choose a platform

    A cross-functional team tests six connected evaluation stations in a modern workshop while an out-of-focus trophy sits to the side.

    A polished demonstration can hide the hardest operational gaps. Use one real topic from your business and ask the vendor to follow it from observation through measurement. The following test works whether you are assessing Profound or another AI visibility system.

    1. Define your evaluation set before the demonstration. Include branded questions, category questions, comparison questions, and problem-led questions that matter to actual buyers. Specify the markets, languages, products, and AI experiences in scope. This prevents a vendor from selecting only the examples that make its interface look strong.
    2. Inspect the underlying observation. Ask to see the answer captured, when it was captured, the query used, and any citations or brand mentions detected. You need to know which elements are direct observations and which are scores, classifications, or interpretations produced by the platform.
    3. Challenge the diagnosis. Ask why the system believes a particular content, technical, entity, or authority gap caused the observed result. A useful platform should let your team examine the evidence behind a recommendation. Treat unexplained scores and confident causal claims cautiously.
    4. Follow the recommendation into an owned task. Identify who receives it, where the work happens, what approval is required, and how completion is recorded. If staff must copy findings manually into another system, count that labor and the risk of lost context when you compare options.
    5. Agree on the outcome before making the change. Decide whether success means more relevant mentions, more accurate representation, stronger citation presence, qualified referral activity, or a business result recorded downstream. Don’t substitute a platform’s convenient metric for the decision your organization actually cares about.
    6. Repeat the measurement with a change log. Preserve the initial query set and observation dates, record exactly what was deployed, and compare like with like. AI-generated answers can vary, so a single favorable response is weak evidence. Look for a pattern that is meaningful enough to justify the next round of work.

    This evaluation does not require the vendor to promise perfect attribution. In fact, causal humility is a positive sign. Content changes, model behavior, competitor activity, retrieval choices, and outside coverage can all affect an answer. What you need is a system that preserves enough evidence to distinguish a plausible result from a convenient story.

    Watch for the gaps that turn a closed loop into a slogan

    The phrase “closed loop” sounds complete, but several missing links can make it operationally empty. Look for these gaps during procurement and pilot design:

    • Undefined coverage: The platform reports a visibility score without showing which prompts, markets, models, or observation periods produced it.
    • Diagnosis without evidence: It recommends creating or changing content but cannot connect the recommendation to a captured answer, citation pattern, or identifiable information gap.
    • Action without ownership: Findings remain in the dashboard because no person, destination, approval state, or deadline is attached to them.
    • Publishing without verification: A page or schema change is marked complete, but nobody checks whether the intended fact is visible, accurate, indexable, and consistent across relevant brand properties.
    • Measurement without comparability: The follow-up uses different questions, filters, markets, or definitions, making apparent improvement difficult to interpret.
    • Visibility without business context: The team celebrates more mentions without asking whether the brand is represented accurately, appears in relevant buying situations, or influences a meaningful downstream behavior.

    You should also separate platform capability from implementation maturity. A product may support the required workflow while your organization lacks owners, publishing access, analytics connections, or an agreed measurement model. Buying more software will not repair those operating gaps. Document them before procurement so that platform limitations and internal limitations don’t get confused.

    Key takeaways

    • Profound’s Gartner 2026 recognition is a credible reason to include the company in an evaluation, not proof that it fits your stack or will improve your results.
    • The most useful signal is the emphasis on connecting insight, action, and outcome. Test that complete path rather than comparing dashboard features in isolation.
    • Use a real business topic during the demonstration and require answer-level evidence, an owned action, a deployment record, and a comparable follow-up measurement.
    • Define success before the pilot. Mentions, citations, representation accuracy, referral activity, and business outcomes answer different questions.
    • A closed loop can span several systems. What matters is preserved context, clear ownership, and a traceable line from observation to consequence.

    Make the next step a workflow test, not a prestige vote

    Choose one commercially important topic cluster and map its complete path: the questions people ask, the answers you can observe, the evidence behind any diagnosis, the person who can make a change, and the outcome you will examine afterward. Then ask Profound to demonstrate that path using your definitions rather than a prepared success case.

    If the workflow remains traceable from observation to consequence, the recognition has helped you discover a platform worth piloting. If the trail disappears between dashboard insight and business action, the Gartner mention should not carry the decision. Your next move is to test the loop.

    References


  • Build, Buy, or Outsource Marketing AI: A Decision Framework

    Build, Buy, or Outsource Marketing AI: A Decision Framework

    Your team has found a marketing workflow worth improving with AI. A vendor can sell you a platform, a specialist can configure a solution, and someone internally is probably confident they can build a prototype. The dangerous question is which option looks cheapest at the start.

    The useful question is where repeatable software should end, where your workflow needs specialist implementation, and where qualified human judgment must remain. A focused 30-minute sorting exercise can answer that before an interesting prototype becomes an unsupported internal product.

    Key takeaways

    • Buy software when the capability is common across companies and the vendor can absorb maintenance, updates, and support.
    • Outsource implementation knowledge when your workflow is custom but the expertise needed to build it is temporary.
    • Build internally when the logic is genuinely differentiating, your team will improve it regularly, and you can support it after launch.
    • Do not deploy an AI workflow unless a named person can verify its output using evidence and subject knowledge.
    • Make the decision for each workflow step, not for an entire department, role, or AI initiative.
    • Compare lifecycle cost, including review and maintenance, and validate the choice with a controlled pilot before allowing autonomous action.

    Treat the workflow as layers, not one build-or-buy choice

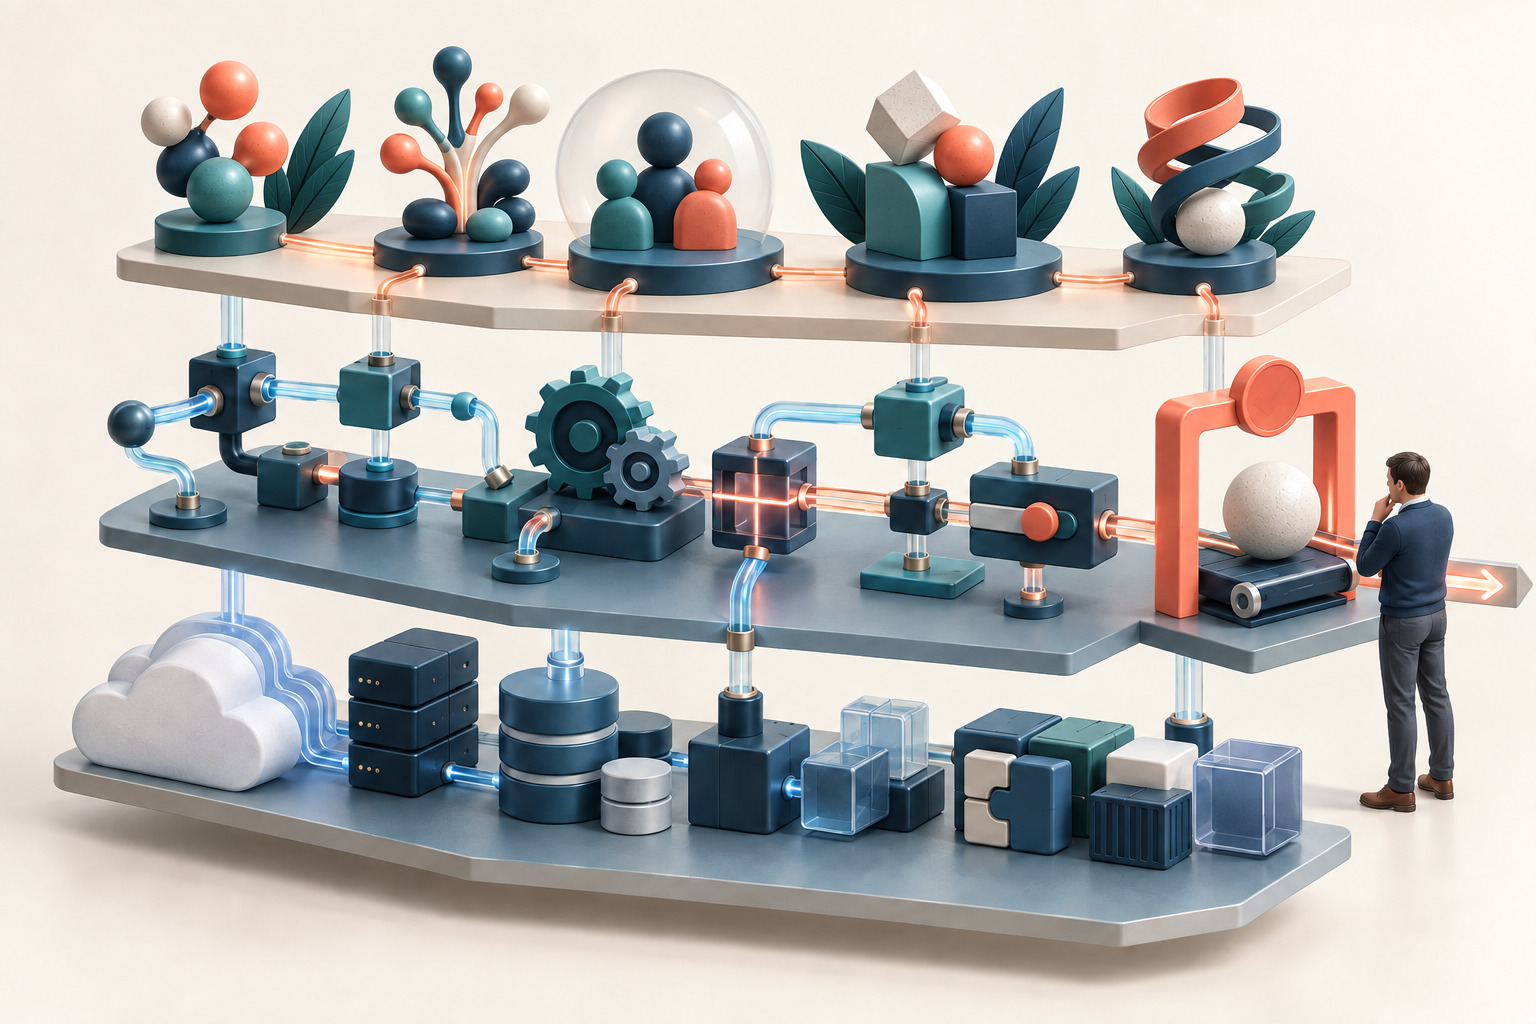
    An exploded three-layer workflow combines standard software modules, configurable connections, and a human approval checkpoint.

    A marketing automation is rarely one indivisible system. A visibility report, for example, may collect data, normalize names, identify changes, interpret those changes, route exceptions, obtain approval, and distribute a finished report. Those steps do not have to come from the same place.

    Break the workflow into boxes before comparing solutions. For every box, record its input, transformation, output, owner, reviewer, and downstream decision. You can then route each layer according to what makes it difficult.

    Workflow layerMarketing examplesSensible defaultYour continuing responsibility
    Common software capabilityRank tracking, citation monitoring, brand-mention tracking, crawl diagnostics, and content scoringBuyConfiguration, data access, quality checks, and vendor oversight
    Company-specific implementationApproval routing, data mapping, reporting cadence, subject-matter-expert intake, and approved CTA insertionOutsource the initial design or implementation, then own itRequirements, acceptance tests, documentation, and an internal process owner
    Differentiating logicYour prioritization rules, proprietary data relationships, brand judgment, and decision criteriaBuild or retain internallyRoadmap, maintenance, testing, and knowledge continuity
    Human controlAccuracy review, exception handling, interpretation, and final approvalKeep qualified ownership inside the teamEvidence standards, escalation rules, and accountability for the resulting decision

    This is a deliberate hybrid, not a compromise. You might buy the monitoring engine, hire a specialist to connect it to your reporting process, build a narrow layer containing your prioritization rules, and keep final interpretation with an analyst. Recreating the monitoring platform would add little advantage; handing your judgment to an opaque system would surrender too much.

    An MIT review of enterprise generative AI projects reported zero return among 95% of the organizations it examined, while external partnerships represented a higher share of successful deployments than internal development. That should not be converted into a universal failure probability: the initiative volumes were uneven, and there was too little hybrid build-buy evidence to quantify that route. The practical warning is narrower. A working prototype is not a successful deployment, especially when the system does not fit the way people already work.

    Do not automate work that nobody can verify

    Two people inspect assets at a checkpoint in an automated production line before approved items continue.

    Before discussing price or architecture, ask one gating question: can a named person on your team perform the task manually or reliably check the result? If the answer is no, pause the automation. You would be installing a system whose failures your team cannot recognize.

    Fluent output makes this risk easy to underestimate. A model can turn a spike in a group of Google Search Console queries into a confident claim that AI visibility is rising, even though the data does not establish that conclusion. The error can look polished enough to enter a leadership meeting unless someone understands both the data and the inference being made.

    Only 13% of marketers fully trust AI output without a human reading it. That is not merely an adoption problem. It is a staffing and workflow requirement: the review still needs time from someone qualified to judge the work.

    The State of CRM Data Report 2026 found that nearly 78% of C-suite respondents and 92% of SVP or VP respondents had acted on an AI recommendation they later suspected was wrong because of poor underlying data. The corresponding figure among individual contributors was 41%. These are self-reported suspicions, not measured model error rates, but they expose an important control problem: the person with authority to act may be farther from the evidence needed to challenge the recommendation.

    Create a verification contract before you automate. It should answer:

    • What decision can this output influence? A draft that stays in an editor is different from a report that changes budget or reaches an executive.
    • What evidence should support the answer? Require links, source records, query data, calculation inputs, or another trace that the reviewer can inspect.
    • Who is qualified to review it? Assign a person or role, not an unspecified human in the loop.
    • What counts as an unacceptable error? Define concrete failure classes such as fabricated facts, incorrect data mapping, unsupported attribution, missing exceptions, or off-brand recommendations.
    • What happens when confidence is low or evidence is missing? Route the case to a person rather than letting the system improvise.
    • Which outputs always require approval? Keep review on every output that can publish content, contact a customer, alter spending, or materially influence a leadership decision.

    If no one can fill in that contract, your next investment is expertise, not automation. Narrow the task, train an owner, or obtain specialist help before deploying the tool.

    Buy common capability, outsource the learning curve, build your edge

    Buy when the underlying problem is common

    Buying is usually the sound route when thousands of other teams need substantially the same capability. Tracking, monitoring, crawling, diagnostics, and scoring all require unglamorous infrastructure work: connectors change, interfaces break, usage grows, and edge cases accumulate. A mature vendor spreads that work across its customers and provides someone to fix the product when it fails.

    Do not evaluate only the demo. Ask the vendor to show how the product handles your real inputs and exceptions. Confirm:

    • whether it supports the data systems you actually use;
    • how it logs inputs, changes, failures, and human approvals;
    • whether reviewers can inspect the evidence behind an output;
    • how data, configurations, and results can be exported;
    • which maintenance and support work is included;
    • how usage, seats, or additional integrations affect cost;
    • what happens to your workflow when the vendor changes a model or feature; and
    • what access controls apply before customer, employee, or proprietary data enters the system.

    The product does not need to mirror your process perfectly out of the box. It does need to cover the commodity layer without forcing your team to become its unpaid engineering and support department.

    Outsource when the workflow is yours but the learning is temporary

    Your approval chain, internal taxonomy, reporting schedule, subject-matter-expert process, and pre-approved copy may be unique. The implementation problems hiding underneath them often are not. Someone who has configured similar workflows already knows where handoffs fail, which exceptions need human input, and which apparently simple steps become brittle when automated.

    Use a practical test: will your team apply the knowledge gained from building this every week? If not, paying employees to discover each failure mode for the first time is an expensive way to acquire one-use expertise. Buy the learning curve through a validated template, a focused consultation, a short implementation engagement, or a specialist resource library.

    Outsourcing should leave you with an operable system, not a permanent mystery. Put these deliverables into the engagement:

    • a map of the workflow, inputs, outputs, owners, and exceptions;
    • documented configuration and administrator access;
    • acceptance tests covering normal, messy, and missing inputs;
    • a failure log describing known limits and escalation paths;
    • training for the internal owner and reviewers;
    • a handover plan, maintenance estimate, and change process; and
    • clear ownership and export rights for data, prompts, rules, documentation, and other deliverables.

    Keep an internal owner involved throughout. A handoff at the end cannot recover reasoning and decisions that were never documented.

    Build when the capability creates durable advantage

    Building internally makes sense when the system encodes something meaningfully different about how you market, not merely because your workflow has custom field names. Your team should be able to answer yes to all of these questions:

    • Does the logic create a real advantage rather than duplicate a standard product feature?
    • Will your team use and improve the resulting technical or operational knowledge regularly?
    • Are your requirements unlikely to be met through configuration, integration, or a narrow extension of existing software?
    • Can you assign an enduring product owner and the people needed to test, monitor, document, and repair it?
    • Will ownership survive if the original builder changes roles or leaves?
    • Can a qualified person verify the system’s output and stop it when it behaves incorrectly?

    An internal prototype may appear inexpensive because its future obligations are invisible. Once colleagues depend on it, the team owns permissions, changing integrations, model behavior, tests, documentation, support, incident response, and every request for a small improvement. If those duties do not have owners, the organization has created software without creating a software function.

    Build the narrowest layer that contains your advantage. Purchasing a stable platform and adding your own orchestration or decision rules is often more defensible than rebuilding data collection, authentication, dashboards, and administrative features around it.

    Use a hybrid route deliberately

    A strong marketing AI workflow may use all three routes. A vendor collects visibility data. A specialist maps the data to your taxonomy and approval path. Your team encodes its prioritization rules and approved CTA library. An analyst reviews anomalies and interpretation before the report reaches leadership.

    Write the boundary between those layers down. Specify who owns the data, configuration, custom logic, review, maintenance, and recovery process. Hybrid systems become fragile when every participant assumes somebody else owns the seam.

    Make the decision in 30 minutes, then test one handoff

    You do not need a long procurement exercise to choose an initial route. You do need a disciplined comparison that counts work beyond the visible fee.

    Use this 30-minute decision agenda

    1. Minutes 0-5: define the outcome. Name the marketing result, the user, and the decision the workflow should improve. Reject objectives such as use AI or automate content; they do not define value.
    2. Minutes 5-10: map the steps. Draw each input, transformation, review, exception, and output. Do not route the workflow until you can see its parts.
    3. Minutes 10-15: classify the layers. Mark each step as common capability, company-specific implementation, differentiating logic, or human control.
    4. Minutes 15-20: apply the verification gate. Name the reviewer, required evidence, unacceptable errors, and escalation path.
    5. Minutes 20-25: compare lifecycle cost. Add internal labor, implementation, review, maintenance, support, and displaced marketing work to the visible price.
    6. Minutes 25-30: choose a route and pilot boundary. Decide what to buy, outsource, build, or leave manual. Assign an owner and state what evidence would justify expansion.

    Compare total cost on the same basis

    A subscription price cannot be compared directly with a development estimate. Use the same operating horizon and the same labor assumptions for every option.

    • Buy: subscription or usage charges, implementation, integrations, internal administration, review, training, migration, and eventual exit work.
    • Outsource: specialist fees, required software, internal subject-matter-expert time, review, training, handover, and ongoing maintenance.
    • Build: discovery, meetings, design, development, testing, infrastructure, documentation, monitoring, support, review, repairs, and the marketing work displaced by those hours.

    Calculate internal labor using the time of every contributor, not just the person writing prompts or code. Include the people clarifying requirements, attending meetings, preparing data, testing outputs, correcting errors, approving work, and responding when the workflow breaks.

    Then name the opportunity cost in operational terms. Which campaign, analysis, customer interview, content update, or technical fix will wait while the team builds and maintains this? If no displaced work appears in the comparison, the internal option has been priced as though staff time were unlimited.

    Keep consequence separate from speculative arithmetic. If a bad output could publish an unsupported claim, misclassify performance, expose sensitive data, or redirect budget, record that failure and the control that prevents it. Do not invent a precise dollar value merely to make the spreadsheet look complete.

    Pilot a bounded step before replacing a job

    Test one handoff whose output can be compared with the existing process. A narrow pilot reveals whether the proposed route reduces work or merely moves it into checking, correction, and maintenance.

    1. Capture the baseline. Record the current input, output, turnaround, human effort, recurring errors, and approval path.
    2. Prepare test cases. Include normal inputs, incomplete data, unusual cases, and situations that should be escalated rather than answered.
    3. Define acceptance before testing. State the required evidence, allowed error classes, review time, and conditions that would stop the pilot.
    4. Run in shadow mode. Compare results without letting the system publish, send, spend, or change a production record on its own.
    5. Log every intervention. Separate factual corrections, data-mapping problems, brand edits, integration failures, and exceptions. That log shows whether the problem is the model, the implementation, the input, or the process itself.
    6. Calculate net value. Subtract review, repair, administration, and maintenance effort from gross time saved. Include improvements in consistency or turnaround only when the pilot demonstrates them.
    7. Decide explicitly. Expand, revise, change the sourcing route, keep the step manual, or stop. Name the production owner and rollback method before expansion.

    Stop or narrow the automation when failures are hard to detect, review consumes most of the apparent saving, changing inputs repeatedly break the workflow, or nobody accepts maintenance ownership. That is useful pilot evidence, not a reason to keep investing until the original idea appears justified.

    Take the next proposed marketing automation and draw its steps on one page. Mark each box buy, outsource, build, or human control. Do not approve procurement or development until every box has a verification owner and the resulting system has a lifecycle owner. The goal is not to own more AI software. It is to improve a marketing outcome with the smallest reliable system that your team can understand and sustain.

    References


  • Profound Sheets Templates: Build an AI Visibility Workflow

    Profound Sheets Templates: Build an AI Visibility Workflow

    Someone has asked you to explain why your brand appears in some AI answers and disappears from others. You do not need another dashboard screenshot. You need a working sheet that turns observations into a prioritized, defensible next step.

    Profound Sheets Templates can reduce setup work because they provide a starting point for common ways teams put Sheets to work. Treat that starting structure as an analysis contract: define what each row means, keep comparisons stable, and decide what action a result is allowed to trigger before you start interpreting it.

    Start with the decision the sheet must support

    The easiest mistake is choosing a template because its output looks useful. A table of brand mentions, citations, prompts, or competitors can be interesting without resolving the decision in front of you. Start with the decision, then select the template whose row structure can support it.

    Most AI visibility work begins with one of these questions:

    • Content prioritization: Which audience questions need a new page, a clearer answer, or stronger supporting evidence?
    • Brand accuracy: Which recurring claims about your company, products, or category require verification or correction?
    • Competitive analysis: On which relevant themes do competitors appear while your brand does not?
    • Source analysis: Which pages or domains are being cited, and what makes those resources useful for the question being answered?
    • Monitoring: How does a fixed set of observations change across models, markets, languages, or reporting periods?

    Write the purpose of your sheet as a single sentence: “This sheet will help [owner] decide [action] for [scope] during [decision cycle].” If you cannot complete that sentence precisely, the analysis is not ready to run.

    DecisionUseful row unitOutput to produce
    Prioritize contentOne topic or intent clusterAn ordered backlog with a reason for each recommendation
    Investigate brand accuracyOne claim observed in one answer environmentA verification queue linked to evidence
    Compare competitorsOne brand-by-theme observationSpecific gaps that require inspection
    Monitor changeOne repeatable observation for a named model, interface, and periodA like-for-like change log

    Do not force several incompatible decisions into one table. A content backlog, a competitor matrix, and a time-series log often require different row units. Combining them produces duplicate records, unclear denominators, and summaries that nobody can reproduce.

    Define what each row represents before trusting the output

    A floating blank grid contains consistent sequences of abstract objects in each row, with one fragmented row shown out of alignment.

    A row is not merely a place where a result lands. It is the smallest observation your analysis treats as distinct. The same prompt run in a different model, interface, market, language, or period may be a different observation. If those contexts are collapsed, a change in conditions can look like a change in brand performance.

    Create a short data dictionary before you customize a Profound Sheets Template. Your process should preserve these details, whether they live in the template itself or in an accompanying methodology record:

    • Scope: The brand, product, website, market, and language included in the analysis.
    • Prompt definition: The exact prompt or a stable cluster name, plus the rule used to place prompts in that cluster.
    • Answer environment: The named model or answer engine and the interface through which the answer was observed.
    • Observation time: When the answer was collected, so later changes are not mistaken for inconsistent analysis.
    • Entity rule: Which company, product, abbreviation, and accepted aliases count as the same entity.
    • Evidence: The answer text, cited URL, captured result, or another durable reference that lets a reviewer inspect the observation.
    • Review state: Whether the row is unreviewed, checked, disputed, or ready to support a decision.
    • Ownership: The person or function responsible for verifying the result and taking the next action.

    Keep visibility concepts separate. A brand mention is not necessarily a citation. A citation is not necessarily an endorsement. Prominent placement is not proof of factual accuracy. Positive language is not proof that the correct product or entity was identified. Give each concept its own field instead of hiding them inside one broad “visibility” label.

    Rates need visible denominators. Store the underlying count and the eligible observation set alongside any percentage or share. Otherwise, a filtered view can change the meaning of the metric without changing its label. Define how blank, unavailable, duplicate, and ambiguous results are handled as well; none of those states should silently become zero.

    Customize the template without breaking comparability

    A template is a scaffold, not a universal measurement standard. You will usually need to adapt it to your market, taxonomy, content inventory, and reporting workflow. The safe approach is to change it in controlled layers so you can still trace every conclusion back to an observation.

    1. Preserve a baseline. Keep an untouched copy or a clear record of the original structure. Overwriting the only version can make previous calculations and field meanings impossible to recover.
    2. Test the unmodified workflow on a representative subset. Include an expected positive result, an expected absence, and an ambiguous case. This reveals how the template handles edge cases before you commit to a full analysis.
    3. Add only fields tied to the decision. A column should help you segment observations, validate evidence, assign work, or choose an action. If it does none of those things, leave it out.
    4. Document derived measures. Record the numerator, denominator, filters, exclusions, and grouping logic behind every calculated metric. A label such as “share” or “score” is not a definition.
    5. Check outliers against the underlying answer. An unusually strong or weak result may be real, but it may also reflect an alias mismatch, prompt classification error, missing result, or changed answer environment.
    6. Freeze the method for the reporting cycle. When you change the prompt set, entity rules, model scope, or calculation logic, create a new version and record the change. Do not silently rewrite historical results to match a new method.

    Run a quality check before distributing any summary. Look specifically for duplicate aliases, inconsistent topic labels, missing market or language values, citations counted as mentions, mentions counted as citations, blank cells treated as negative observations, and manual notes mixed into raw fields. These errors are mundane, but they can reverse the apparent direction of a result.

    Keep exploratory prompts separate from monitoring prompts. Exploration is allowed to change as you discover new questions. Monitoring needs a stable comparison set. Mixing the two makes growth in prompt coverage look like a movement in visibility, even when the underlying comparable observations did not improve.

    Turn observations into SEO, AEO, and GEO actions

    Evidence tokens pass through a blank decision grid and branch toward search, direct-answer, and networked-globe action streams.

    An observed result tells you what appeared under defined conditions. It does not, by itself, tell you why it appeared. A competitor citation does not prove that a particular page element caused inclusion. Your brand’s absence does not prove that your content is poor. Treat the sheet as a diagnostic queue, then investigate the relevant answer, prompt intent, cited resources, and owned content before prescribing a change.

    ObservationWhat to verifyPossible action
    An important brand fact is wrongThe exact claim, entity identity, cited resources, and corresponding information on owned pagesCorrect the authoritative owned page and make the factual statement consistent across relevant properties
    The brand is absent for a relevant topicWhether the prompt represents real audience intent and whether an existing page answers it directlyCreate or improve a focused resource if a genuine information gap exists
    A competitor appears repeatedlyThe cited URLs, answer format, evidence, scope, and task those pages satisfyClose the specific information or evidence gap rather than copying the competitor’s page
    The result changes frequentlyThe model, interface, prompt wording, market, language, and collection periodContinue controlled monitoring before making an expensive content change
    The brand appears accurately and is supported by a relevant pageThe cited asset, its freshness, and neighboring audience questionsMaintain the resource and extend coverage only where a related intent is demonstrably useful

    Prioritize a finding through four gates:

    • Business relevance: Does the topic affect a product, audience, reputation concern, or decision your organization actually serves?
    • Recurrence: Does the pattern persist across comparable observations, or is it a single volatile answer?
    • Evidence quality: Can a reviewer inspect the answer, prompt, context, and cited material?
    • Controllability: Is there a specific owned asset, factual inconsistency, or content gap your team can address?

    A finding that fails one of these gates belongs in investigation or monitoring, not an implementation backlog. This prevents your team from spending time on visible but low-value anomalies.

    For findings that do become content work, connect the sheet to your content inventory. Assign a canonical URL or planned asset, an owner, the audience question, the factual evidence required, and a review state. The finished page should answer the task plainly, support important claims, identify the relevant entity consistently, and expose useful information in visible content.

    Structured data should describe that visible content accurately. JSON-LD is not a patch for a weak answer, an unsupported claim, or an ambiguous entity. Use the most specific applicable schema only when the page genuinely contains the corresponding information, and keep the markup aligned when the page changes.

    Maintain three distinct layers as the workflow grows: raw observations, reviewed findings, and approved actions. Raw evidence should remain stable. Review can add interpretation and confidence. The action register can then track the canonical URL, owner, status, rationale, and expected user outcome. Separating these layers stops an editorial opinion from being mistaken for collected data.

    Key takeaways

    • Choose a Profound Sheets Template from the decision you need to make, not from the most appealing output.
    • Define the row unit, prompt rules, entity rules, answer environment, and evidence requirements before interpreting results.
    • Keep mentions, citations, placement, sentiment, and factual accuracy as separate observations.
    • Preserve raw results and version every methodological change so reporting periods remain comparable.
    • Require business relevance, recurrence, inspectable evidence, and a controllable next step before turning a finding into SEO, AEO, or GEO work.

    Start with one decision from your current reporting cycle. Write its row definition, select the closest template, and test the workflow on a representative subset. Once another person can reproduce the conclusion from the stored evidence, you have a process worth scaling.

    References


  • Beyond SEO Dogma: The Business Value of Human Judgment

    Beyond SEO Dogma: The Business Value of Human Judgment

    Your crawler has returned 10,000 warnings. An AI platform can group them, draft tickets, recommend pages, and generate enough activity to fill the next planning cycle. The dashboard looks decisive. You still have not answered the question that matters: which work deserves to happen?

    That question is where an SEO practitioner earns their place. The valuable work is not reciting rules or producing more deliverables. It is separating a material threat from a harmless convention, connecting the recommendation to a business outcome, and accepting responsibility for what the team does next.

    SEO dogma begins when the reason disappears

    Most best practices began as useful shorthand. Use one H1. Keep title tags within a familiar length. Place the target phrase in prominent locations. Improve Core Web Vitals until the report is green. Add schema. Publish fresh content. These recommendations can be sensible, but their usefulness depends on the conditions that made them sensible.

    Repetition strips those conditions away. A tactic that worked for a particular site, template, query set, or search environment becomes a universal checklist item. The recommendation survives; the mechanism does not. A crawler then gives the item a severity label, and the label begins to stand in for analysis.

    The correction is not to reject every established practice. Treat each one as a starting hypothesis. Rewrite it in this form: When an observable condition exists, make a specific change because a named mechanism is causing harm, then evaluate a relevant signal.

    For example, delayed JavaScript rendering on an important page template can interfere with discoverability, so the team should investigate how meaningful content becomes available. A few CMS-generated H1 elements on otherwise understandable pages present a different situation. Both appear in an audit, but only evidence can tell you whether either condition warrants engineering time.

    Key takeaways

    • A best practice should begin an investigation, not end one.
    • An issue count measures inventory, not impact.
    • Automation can scale observation and production; a person must still choose the outcome worth pursuing.
    • A useful practitioner makes reasoning, uncertainty, and tradeoffs visible.
    • Leaving a condition unchanged can be a responsible decision when the evidence, accepted risk, and review trigger are documented.

    Run every recommendation through a consequence test

    A hand considers several levers connected by mechanical linkages to different miniature business outcomes.

    A priority score supplied by a tool is an input. It is not a business case. Before a recommendation reaches the backlog, require clear answers to the following questions.

    1. What condition did we actually observe? Identify the affected URL, template, content type, or journey. Do not substitute a rule violation for an observation.
    2. What problem could the condition cause? Name the mechanism: failed discovery, incorrect canonical selection, muddled intent, poor usability, lost qualified demand, or another concrete consequence.
    3. What evidence connects the condition to that problem? Look for changes in access, indexing, visibility, user behavior, qualified traffic, or business performance. If the connection remains hypothetical, say so.
    4. How much valuable surface area is affected? Count pages only after identifying whether those pages matter. One template controlling important URLs may deserve more attention than thousands of isolated warnings on obsolete assets.
    5. What happens if we leave it alone? Describe the likely downside, its confidence level, and the point at which waiting would become unacceptable.
    6. What are we giving up to fix it? Compare the recommendation with the best alternative use of content, engineering, design, and review capacity.

    This test changes how familiar audit findings are handled. It also exposes why blanket priorities fail:

    Audit findingQuestion that determines priorityDefensible disposition
    Misconfigured canonical directivesAre important duplicate or competing URLs causing search engines to ignore the intended canonical signal?Act when the condition affects valuable pages or creates a material cannibalization risk.
    Delayed JavaScript renderingIs meaningful content on an important template difficult for search engines to access or discover?Investigate the template and prioritize the root cause over individual URL tickets.
    Core Web Vitals outside a recommended thresholdIs an important product, service, or conversion page slow enough to affect user behavior, or did a low-traffic resource page miss a benchmark by a small margin?Investigate demonstrated user friction. Monitor a marginal benchmark miss when no meaningful consequence is evident.
    Multiple H1 elementsIs the content hierarchy genuinely confusing, or is the warning a side effect of the CMS and design system?Fix a communication or template problem. Do not create urgent work solely to satisfy the crawler.
    Missing meta descriptions on legacy pagesDo the pages attract meaningful search demand or support the current content strategy?Improve descriptions where better search presentation could matter; defer low-value legacy inventory.

    The same logic applies beyond SEO. Alt text, semantic structure, and performance can matter for users even when their immediate ranking effect is limited. Do not dismiss a wider accessibility or usability responsibility merely because an item loses an SEO prioritization contest. Route it to the right owner and evaluate it on the right grounds.

    Give AI the inventory, but keep a person on the decision

    Robotic arms organize trays in a large archive while a person selects one object at an illuminated workbench.

    AI is well suited to reducing the cost of seeing and producing things. It can accelerate keyword research, organize large datasets, prepare first-draft briefs, group repeated technical findings, monitor changes, and generate implementation options. Those are valuable capabilities, especially when they remove repetitive work from a skilled team.

    The boundary appears when an observation must become a commitment. Keyword volume does not establish that the query attracts the right customer. A distinct-looking phrase does not prove the site needs another URL. A technically valid page idea can still conflict with product positioning, legal review, sales priorities, brand standards, or existing content competing for the same intent.

    Consider an automated audit that returns 100 flags. A responsible practitioner may advance five, defer 90, and reject five after tracing each one to the pages, users, and systems involved. The valuable output is the explanation for that distribution, not the speed at which the original list appeared.

    Use automation for work such as:

    • Crawling, collecting, classifying, and deduplicating observations.
    • Preparing keyword, page, competitor, and performance inventories for review.
    • Drafting briefs, acceptance criteria, test cases, and implementation alternatives.
    • Repeating defined checks and surfacing changes that deserve investigation.
    • Producing content or code drafts within constraints set by accountable reviewers.

    Keep a named person accountable for:

    • Defining which customer and business outcomes the search work should support.
    • Choosing among a new page, a consolidation, a revision, a technical fix, a test, or no action.
    • Distinguishing a systemic failure from a cosmetic warning.
    • Weighing product, engineering, legal, sales, brand, and customer-service constraints.
    • Explaining the tradeoff to the people whose time or risk the recommendation consumes.
    • Changing course when the original recommendation does not produce the expected result.

    This is not an argument for preserving manual work. An internal team may reasonably automate production or replace some external execution. The mistake is removing the decision owner along with the repetitive task. Software can create activity, but it does not own the downside when the activity was pointed in the wrong direction.

    Volume makes this distinction more important. Expanding five thoughtful articles into 50 mediocre ones does not become a sound strategy because generation is inexpensive. If the pages do not earn attention, trust, qualified visits, or business value, automation has only scaled the original error.

    Make human judgment visible, testable, and accountable

    Human expertise should not be defended as intuition that others must accept on faith. An unexplained opinion is no better than an unexplained tool score. Judgment becomes valuable to a team when someone can inspect the reasoning, challenge the assumptions, and evaluate what happened afterward.

    This also changes how practitioners present their work. If SEO is sold as a bundle of audits, spreadsheets, briefs, reports, and pages per month, software will usually look cheaper and faster. The practitioner has framed the engagement around the part that is easiest to automate. The differentiating deliverable should be a decision with evidence and ownership.

    Use a compact decision record

    Attach the following record to any recommendation that will consume meaningful time or introduce risk:

    • Observed condition: What exists now, stated without the audit tool’s judgmental language.
    • Evidence: The data or inspection that supports the diagnosis, plus any important gaps.
    • Affected surface: The pages, templates, queries, audiences, or journeys exposed to the condition.
    • Consequence: The search, user, or business outcome that may be harmed.
    • Options: Fix, test, monitor, accept, consolidate, remove, or choose another relevant response.
    • Recommendation: The selected option and the reason it outranks the alternatives.
    • Risk: What could go wrong if the team acts, and what could go wrong if it does not.
    • Success signal: The observable change that would support the recommendation.
    • Owner and review trigger: The person responsible and the evidence or event that will cause the decision to be reconsidered.

    Apply that format to a familiar H1 warning. Suppose a CMS produces three H1 elements on a small service site. Inspect whether the visible hierarchy is confusing, whether the main subject is unclear, and whether the affected pages show a related access or discoverability problem. If those checks reveal no meaningful consequence, record the decision to accept the condition for now and revisit it when the template changes or new evidence appears. If the hierarchy is genuinely broken, fix the shared template instead of opening repetitive page-level tickets.

    No action is not the absence of a decision when the evidence, risk, and review trigger are explicit. It is often the clearest sign that someone is prioritizing outcomes instead of performing compliance.

    Report decisions instead of completed activity

    Closing 2,000 crawler warnings may sound productive, but the number of issues closed is not an outcome. A useful reporting cycle should show:

    • The highest-consequence conditions found and the evidence behind them.
    • Which items were assigned to action, testing, monitoring, or acceptance.
    • Why the selected work outranked competing opportunities.
    • What changed after implementation and what remains uncertain.
    • Which risks the team knowingly accepted and what would trigger another review.
    • Which low-value projects were avoided, preserving capacity for more consequential work.
    • Which decision or dependency now requires leadership, engineering, product, or legal input.

    This format makes expert value inspectable. It also gives AI a better operating environment because the system can work from explicit objectives, classifications, constraints, and review conditions instead of an unexamined collection of SEO maxims.

    Change the next SEO planning conversation

    You do not need to redesign the whole operating model before improving the next decision. Start with the loudest warning in the current audit and force it through a disciplined sequence.

    1. Group repeated instances by root cause, template, or content type so the team is discussing conditions rather than raw counts.
    2. Inspect representative affected pages, including the ones most important to discovery, customers, or revenue.
    3. Rewrite the recommendation as a conditional claim with a mechanism and an expected signal.
    4. Choose an explicit disposition: act, test, monitor, accept, consolidate, remove, or investigate further.
    5. Name the person who owns the choice and the evidence that would cause it to change.

    If you are deciding whether software can replace a practitioner, ask questions that expose the missing layer:

    • Who decides whether a keyword represents valuable demand rather than available demand?
    • Who checks whether a proposed page should instead become a consolidation?
    • Who can explain why one template problem outranks thousands of isolated warnings?
    • Who carries the recommendation into engineering, product, legal, or leadership discussions?
    • Who owns the downside and changes the plan when the expected result does not appear?

    If no named person owns those decisions, you have bought throughput rather than strategy. The problem is not that the system lacks enough rules. It is that nobody is accountable for deciding when those rules apply.

    Use AI aggressively to reduce repetitive work and widen the field of evidence. Then require a human to connect that evidence to consequences, opportunity cost, and a defensible next action. On your next planning call, do not approve a ticket until its owner can name the harmed page or journey, explain the mechanism, and state what improvement would justify the work. That is the practical difference between SEO compliance and SEO judgment.

    References


  • Google AI Tools for Search Marketers: A Practical Workflow

    Google AI Tools for Search Marketers: A Practical Workflow

    Google now puts AI on both sides of a search marketer’s desk. On the organic side, AI-generated search experiences decide how information is assembled and cited. On the paid side, AI interprets campaign data and proposes explanations for performance changes.

    Your job is not to collect every new feature. It is to separate two workflows: earning visibility in AI-generated answers and using AI to investigate paid-search performance. That distinction tells you what to measure, what to prompt, and which conclusions still need human verification.

    Match each Google AI tool to the question it can answer

    Start by deciding whether you are examining the market or examining your account. AI Mode, AI Overviews, and Gemini can help you observe how Google interprets a topic. Google Ads AI Dashboards, homepage insights, and Ask Advisor work with advertising performance.

    Google AI surfaceUseful marketing questionOutput to captureConclusion to avoid
    AI ModeHow is this query answered, and which pages support the answer?Answer structure, cited URLs, entities, claims, and missing subtopicsA citation is a permanent ranking position
    AI OverviewsWhat synthesized answer appears alongside conventional search results?Answer framing, cited domains, and the relationship between the generated answer and the surrounding resultsOne result represents every user, query variation, or future search
    GeminiHow might an AI assistant interpret the topic or decompose the user’s request?Terminology, follow-up questions, ambiguities, and information needsA Gemini response is a direct proxy for Google Search rankings
    Google Ads AI DashboardsWhat changed in campaign performance, where did it change, and what may have contributed?A scoped visualization, account segments, and an explanation to verifyAn AI-generated explanation proves causation
    Ask Advisor and homepage insightsWhich account questions or anomalies deserve investigation?Questions, hypotheses, and paths into the underlying account dataA recommendation should be applied without checking its scope and commercial risk

    This separation matters because AI Mode is an external discovery environment, while an Ads dashboard is an internal analysis environment. AI Mode can show how Google retrieves, orders, and cites information. It cannot tell you why an advertising campaign’s cost changed. An Ads dashboard can analyze account data, but it cannot establish whether your organic content is eligible to support an AI-generated answer.

    Do not combine all of these observations into a single “AI visibility” score. Keep at least two records: an organic answer-and-citation log and a paid-performance investigation log. Otherwise, a change in advertising efficiency can be mistaken for a change in search demand, or a volatile AI citation can be mistaken for durable organic growth.

    Use AI Mode as a citation audit, not a rank tracker

    A magnifying glass inspects links between an abstract AI answer panel and several source documents, with one unsupported connection highlighted.

    A conventional rank check asks where a URL appears for a query. An AI citation audit asks a different set of questions: What answer did Google construct? Which claims needed support? Which sources were selected? What did the cited pages make especially clear?

    That makes AI Mode useful for diagnosing content, but weak as a one-observation scoreboard. Generated answers can change with wording, context, and the shape of the request. Record what you see, but do not turn a single appearance or absence into a general claim about visibility.

    1. Build the query set from real decisions. Include the problem a person is solving, the comparison they need to make, the constraint that changes the answer, and the follow-up question likely to come next. A broad head term rarely reveals the whole information journey.
    2. Run a controlled observation. Keep the wording of each query in your log. Check the conventional results page, note whether an AI Overview appears, and inspect AI Mode separately. Do not silently change the prompt and then compare the outputs as though the query stayed constant.
    3. Record the answer anatomy. Capture the main answer, the subquestions it addresses, named entities, cited URLs, and the specific claim each citation appears to support. A domain count alone tells you almost nothing about why a page was useful.
    4. Inspect the cited pages. Look for the passage that answers the question, the definitions surrounding it, supporting evidence, descriptive headings, and any comparison structure. The useful unit is often a clearly supported claim inside a page, not the page as an indivisible object.
    5. Compare your page with the information need. Mark missing answers, buried definitions, unexplained terminology, unsupported assertions, and comparisons that use inconsistent dimensions. Those are concrete editing targets.
    6. Recheck after a meaningful revision. Keep the original query and observation beside the new one. Treat a changed answer as an observation to investigate, not proof that one edit caused it.

    The resulting worksheet should have one row per query and columns for intent, answer framing, cited pages, supported claims, gaps, planned edits, and the next observation. This gives your team evidence it can discuss. A screenshot folder without query wording or claim-level notes does not.

    Make a page easier to retrieve without writing for a robot

    Retrievability starts with clarity. Put the direct answer near the question it resolves. Name the entity before switching to pronouns. Define specialist terms. Keep qualifications attached to the claim they limit. If you compare options, use the same criteria for each option so the relationship is visible rather than implied.

    • Give each important question a descriptive heading and an immediate answer.
    • Use the full name of a product, organization, method, or standard when ambiguity is possible.
    • Support factual claims on the page instead of expecting a search system to infer evidence from a distant internal link.
    • Place limitations beside recommendations. Moving them to a generic disclaimer weakens the answer and can mislead the reader.
    • Use structured data only when it accurately describes visible content. Schema can clarify meaning; it cannot rescue an unsupported or missing answer.
    • Link related pages according to the reader’s next question, not merely because they share a keyword.

    This is not a replacement for technical SEO. A page still needs to be accessible, indexable, canonicalized correctly, and connected to the rest of the site. AEO and GEO work build on that foundation by making answers, entities, relationships, and evidence easier to identify.

    Prompt Google Ads AI Dashboards like an analyst

    Google Ads AI Dashboards are appearing in some advertiser accounts, so you may not have access yet. Where the feature is available, a natural-language request can generate a visual report instead of requiring you to select every metric, dimension, and chart manually.

    The dashboard can also attach a real-time AI summary of what changed and what may be driving it. That saves report-construction time. It does not remove the need to frame the question or verify the explanation.

    A useful dashboard prompt contains six parts: the decision, account scope, metric, comparison, segmentation, and requested output. If one is missing, Gemini has to infer it, and the chart may be technically correct while answering the wrong business question.

    • Decision: State what you are trying to understand, such as whether an efficiency change is concentrated or account-wide.
    • Scope: Name the campaigns, campaign type, product group, geography, device, or other relevant boundary.
    • Metric: Specify the outcome and its related inputs. Asking only about conversions can hide a simultaneous change in spend or traffic.
    • Comparison: Name the periods or segments being compared and make sure they are commercially comparable.
    • Segmentation: Ask for the dimension that could expose the change instead of accepting an account-wide average.
    • Output: Request the visualization, largest contributors, and a clear separation between observed data and possible explanations.

    A reusable prompt pattern is:

    Compare [metric set] for [campaign scope] between [period or segment A] and [period or segment B]. Break the result down by [dimension]. Visualize absolute and relative changes, identify the largest contributors to the account-level movement, and separate observations from possible causes.

    Reusable Google Ads analysis prompt

    You can adapt that pattern to practical questions:

    • Compare cost, conversions, and cost per conversion across campaigns for two comparable periods. Show which campaigns contributed most to the account-level change.
    • Break out cost, conversions, and conversion value by device for brand and non-brand campaign groups. Flag cases where volume and efficiency moved in different directions.
    • Chart daily spend and conversions for a selected campaign group. Identify the dates and campaigns responsible for the largest deviations, without assigning a cause.
    • Compare performance by geography for the selected campaigns. Separate changes caused by traffic volume from changes in conversion efficiency.

    These prompts do more than request a prettier report. They force you to define the denominator, the comparison, and the decision. If the generated chart cannot accommodate a requested metric or dimension, revise the scope rather than accepting a substitute without noting it.

    Verify the AI explanation before changing content or spend

    An analyst cross-checks an AI-generated performance explanation against a calendar, change history, source document, and calculator before approving an action.

    The most convincing AI mistake is a plausible explanation attached to accurate numbers. A dashboard may correctly show that cost per conversion rose while offering a cause that the chart cannot prove. The phrase “may be driving” marks a hypothesis, not a causal finding.

    Run every material insight through the same verification loop:

    1. Confirm the scope. Check the date range, campaign selection, filters, excluded segments, and comparison period. A summary can be accurate for its slice and still misrepresent the account.
    2. Confirm the metric definition. Make sure the chart is using the conversion, value, cost, or efficiency measure your decision actually depends on. Similar labels are not interchangeable.
    3. Locate the contributors. Move from the account total to campaigns and then to the dimension behind the movement. An average can conceal opposite changes in separate segments.
    4. Separate observation from cause. “Mobile efficiency declined” is an observation. “The landing page caused the decline” requires evidence beyond two events occurring near each other.
    5. Check the underlying rows. Review the data behind the visualization before presenting the summary or applying a recommendation. The chart is an interface to the account, not an independent record.
    6. Choose a reversible next step. Investigate, annotate, or run a controlled change before making a broad account adjustment.

    Paid-search decisions can spend real money. Do not increase budgets, change bids, pause broad campaign groups, or alter conversion settings solely because an AI summary sounds certain. Use the same approval process you would apply to a human analyst’s recommendation, and preserve a record of the original settings and the reason for the change.

    Apply the same discipline to organic content. Do not rewrite an accurate, useful page merely because it was absent from one AI Mode response. First determine whether the page answers the same intent, whether another page on your site is the better candidate, and whether the proposed edit improves the reader’s answer. Citation visibility is an outcome to observe, not permission to weaken the page.

    Key takeaways and your next working session

    • Use AI Mode and AI Overviews to inspect answer construction and citations; do not treat them as conventional rank trackers.
    • Use Gemini for exploratory interpretation, not as proof of how Google Search will rank a page.
    • Use Ads AI Dashboards to reduce report-building work, but define the scope, metric, comparison, and segment in the prompt.
    • Treat every generated explanation as a hypothesis until the underlying account data supports it.
    • Keep organic citation observations separate from paid-performance investigations.
    • Improve content by clarifying answers, entities, evidence, and relationships while preserving technical SEO and reader value.

    For your next working session, choose one valuable query cluster and one unresolved Google Ads performance question. Build a citation log for the first and a tightly scoped dashboard prompt for the second. If every conclusion can be traced back to a cited page or a defined slice of account data, the AI is helping you investigate. If it cannot, keep it in the hypothesis column.

    References


  • Google Ads AI Transparency: A Practical Audit Framework

    Google Ads AI Transparency: A Practical Audit Framework

    When Google Ads can rewrite the product title a shopper sees, knowing what you entered in Merchant Center is no longer enough. And when an AI coding assistant can generate integrations, troubleshoot failures, and query a live advertising account, working code is no longer sufficient proof that the work is correct.

    You need an evidence chain: what the AI changed, what rules or schema supported the change, what actually ran or served, and what happened afterward. Two Google Ads developments make that easier: reporting for AI-generated Shopping titles and a schema-aware Google Ads API assistant. Used carefully, they let you audit automation without giving up its speed.

    Treat Google Ads AI as two separate control problems

    Google Ads AI acts at more than one point in the advertising workflow. The control you need depends on where the automation operates.

    AI layerWhat can changeEvidence availableYour control decision
    Ad deliveryThe product title presented in a Shopping adOriginal and customized titles plus impressions, product clicks, CTR, cost, and average CPCDetermine whether the generated wording preserves product identity and attracts useful traffic
    API developmentIntegration code, GAQL queries, diagnostics, and reporting workflowsGoogle Ads-specific rules, GAQL validation, Protobuf schema inspection, and live query resultsDetermine whether the implementation is valid for the intended API version, account, and business question

    The first layer is a message-governance problem. The second is a software-governance problem. Combining them under a vague instruction to “monitor the AI” produces weak reviews because the artifacts, risks, and owners are different.

    Use the same principle for both: never approve an AI output without identifying the input, the transformation, and the observed result. A generated title is an output. So is a valid GAQL query. Neither tells you by itself whether the outcome serves your commercial intent.

    Audit the product title shoppers actually see

    A magnifying glass compares a source product record with an AI-processed shopping listing shown on a smartphone.

    Google AI can create a customized product title and serve it when it considers that version more relevant than the advertiser-provided title. The original remains eligible to appear when Google considers it more relevant. The practical consequence is simple: your feed title is an input to ad delivery, not a guarantee of the final wording.

    The Product titles report is beginning to appear in Google Ads, so availability may not be uniform across every account. Where it is available, it can place the original and AI-customized titles beside delivery and traffic metrics. That gives you something much more useful than a general notice that automation may alter copy: it gives you inspectable examples.

    Review meaning before performance

    Start by checking whether the generated title still identifies the product accurately. A higher CTR cannot repair a title that creates the wrong expectation.

    1. Compare the identifying details. Check whether the generated wording preserves the brand, model, product type, variant, size, material, compatibility, or other detail a buyer needs to distinguish the item.
    2. Look for a change in promise. Flag wording that implies a feature, bundle, use case, audience, or level of compatibility that the product page does not support.
    3. Check brand and legal sensitivity. Route regulated claims, trademarks, guarantees, and tightly controlled brand language to the appropriate reviewer before treating the title as acceptable.
    4. Inspect the landing-page match. A title may be technically accurate but still emphasize something the landing page does not make easy to find. That mismatch can attract a click while weakening the visit.
    5. Classify the change. Record whether the generated title clarifies the product, rearranges existing details, introduces a new interpretation, or removes a distinguishing detail. This turns isolated examples into patterns you can act on.

    When generated titles repeatedly clarify information that was buried or absent in your originals, treat that as a feed-quality hypothesis. Do not merely admire the AI version. Ask whether the original titles should communicate the same useful distinction more directly.

    Read the metrics as observation, not a controlled test

    The report can include impressions, product clicks, CTR, cost, and average CPC. Those measures answer different questions:

    • Impressions show how much exposure a title received. A dramatic-looking CTR difference attached to limited exposure deserves caution.
    • Product clicks show traffic volume, but not whether those visitors produced valuable outcomes.
    • CTR describes the rate at which impressions produced clicks. It can help you spot wording that attracts attention, but it does not establish why the difference occurred.
    • Cost and average CPC show the price of the traffic. They do not, by themselves, establish revenue, margin, lead quality, or profitability.

    Do not label this comparison an A/B test unless you have a genuinely controlled experimental design. Google may select an original or customized title because it considers one more relevant in a particular serving context. Different contexts can therefore influence both which title appears and how it performs. The report reveals an association between a served title and its results; it does not automatically isolate the title as the cause.

    Your decision should combine three checks: semantic accuracy, sufficient exposure, and downstream business value from your existing measurement setup. A title that earns more clicks but brings poorly matched visitors is not an improvement.

    Make the API assistant prove technical validity

    Google Ads API Developer Assistant v4.0.0 moves from the earlier standalone local-workspace structure to a globally available plugin architecture. It can supply Google Ads-specific rules, skills, and diagnostic commands across projects. The architecture is not compatible with previous releases, so adopting version 4 should be treated as a migration rather than a routine in-place update.

    The assistant supports AI coding workflows in Antigravity and Claude Code. It can generate integration code for Python, Java, PHP, .NET, and Ruby. More importantly for reliability, it can inspect local Protobuf schemas and client-library code instead of depending entirely on what the underlying model remembers about Google Ads.

    That grounding is most useful when you require it as part of the workflow. Use this review sequence:

    1. Identify the intended API version. Record it with the task so a reviewer can distinguish current fields and enums from suggestions that belong to another version.
    2. Inspect the relevant schema before accepting generated code. Confirm resource names, available fields, data types, and enum values against the active version.
    3. Validate every GAQL query before execution. The local validator can check syntax, field compatibility, date segmentation, resources, metrics, date clauses, and zero-impression rules in one pass.
    4. Review account and time context. Before a natural-language request runs against live data, verify the customer ID, manager-account relationship where relevant, date range, segments, metrics, and expected level of aggregation.
    5. Read the generated code as code. Schema validity does not replace review of authentication, account selection, data handling, error paths, and whether the integration performs only the operations you intended.
    6. Save a reproducible result. The assistant can return live results as a formatted table and can save ad hoc reporting output as CSV. Preserve the validated query with the output so another person can reproduce what was retrieved.

    This approach is faster than asking a general-purpose model to guess at a broken query over multiple attempts. It is also safer because the query is checked against Google Ads-specific constraints before it reaches the account.

    Use conversational troubleshooting as triage

    The assistant can investigate offline conversion upload failures, manager-account hierarchy problems, and Performance Max listing filters. It can also help answer broader questions, such as which ads have problems and how those problems might be addressed.

    Treat the response as structured triage. Ask it to identify the failing object, inspect the applicable schema, show the relevant error or rule, and separate confirmed findings from proposed fixes. Then review the recommendation before changing production code or campaign configuration. A conversational explanation is easier to consume than a raw error, but readability is not evidence.

    Know what grounding does not prove

    Schema inspection and local validation reduce a specific class of AI failure: invented fields, incompatible combinations, and version-mismatched configurations. They do not prove that the request reflects the business question you meant to ask.

    • Syntactic validity: Can the query be parsed? The validator can address this.
    • Schema validity: Do the resources, fields, metrics, types, and enums exist and work together for the active version? Schema inspection and Google Ads-specific rules can address much of this.
    • Account validity: Is the query running for the correct customer, through the intended manager hierarchy, over the correct dates? The assistant can help retrieve customer IDs and diagnose hierarchy issues, but you still need to confirm the intended account context.
    • Business validity: Does the output answer the decision you need to make? A perfectly valid cost query is still wrong if the decision depends on profitable conversions or qualified leads.

    The same distinction applies to Shopping titles. Transparency shows you the generated wording and associated performance. It does not prove the wording is accurate, brand-safe, incrementally better, or responsible for the observed result.

    Google says the plugin architecture improves speed and reduces resource and token consumption by loading only the rules and schemas needed for a task, with caching to avoid repeated lookups. Those efficiency claims are useful for adoption planning, but they are separate from auditability. Faster generation changes how quickly work arrives; it does not lower the review standard.

    Build one evidence trail across marketing and development

    Marketing and engineering specialists inspect a connected evidence trail linking product data, validated code, live advertising outputs, and archived outcomes.

    You do not need a large governance program to make these tools accountable. You need a compact record that joins the AI output to the decision made about it.

    For AI-generated product titles, record the product or internal SKU, original title, generated title, review classification, impressions, product clicks, CTR, cost, average CPC, relevant downstream outcome from your measurement system, reviewer, and decision. This is your internal audit log; it should not be confused with a claim that every field appears in the Product titles report.

    For API work, record the customer context, intended API version, client language, user request, generated GAQL or code, validation result, schema fields inspected, date clauses, output location, reviewer, and deployment decision. If the work concerns an offline conversion upload, account hierarchy, or Performance Max listing filter, preserve the original failure details with the diagnosis.

    Assign ownership by artifact:

    • The feed owner is accountable for the original product data and for recurring weaknesses exposed by generated titles.
    • The performance marketer assesses title accuracy, delivery metrics, traffic quality, and the business relevance of the comparison.
    • The developer owns API-version selection, schema verification, query validation, code review, and reproducibility.
    • The appropriate brand, compliance, or business owner approves wording or implementation decisions that exceed the marketer’s or developer’s authority.

    Use event-based reviews instead of checking everything indiscriminately. Review when customized titles first appear, after meaningful feed changes, when a high-impression title changes the product’s meaning, before adopting the incompatible version 4 plugin architecture, before deploying generated integration code, and when a known troubleshooting case affects reporting or conversion data.

    Key takeaways

    • Google may serve an AI-customized Shopping title instead of the title you supplied, so audit the message that appeared rather than assuming feed copy reached the shopper unchanged.
    • Use the Product titles report to inspect original and generated titles with impressions, product clicks, CTR, cost, and average CPC, but do not mistake an observational comparison for a controlled experiment.
    • Check semantic accuracy before celebrating performance. More clicks are not useful when the title attracts the wrong buyer or changes the product promise.
    • Require the Google Ads API Developer Assistant to inspect the active schema and validate GAQL before execution. A fluent answer without those checks is weaker evidence.
    • Separate syntax, schema, account context, and business intent. An implementation can pass the first two tests while still answering the wrong question.
    • Keep an internal record connecting each AI output to its input, validation evidence, reviewer, observed result, and final decision.

    Start with the Shopping products receiving the most impressions and one API workflow where validation failures currently consume time. Establish the evidence record there, assign an owner, and make approval depend on inspectable proof. The aim is not to block automation. It is to shorten the distance between an AI-made change and your ability to understand, verify, and correct it.

    References


  • How to Verify AI-Assisted Development for Technical SEO

    How to Verify AI-Assisted Development for Technical SEO

    The ticket says resolved. The AI says the tests pass. Staging looks right. Yet the production page still sends the wrong canonical, omits a locale mapping, or calculates a score that no customer can see. This is where fast AI-assisted development becomes expensive: a working result can still be different from the result you requested.

    You do not need to slow every project down with a heavyweight approval process. You need a definition of done that can survive contact with production. The workflow below turns an SEO concern into a testable requirement, checks the result at the layer where search engines and users encounter it, and leaves evidence another person can reproduce.

    Key takeaways

    • Write the acceptance test before asking an AI or developer to implement the fix.
    • Translate audit labels into mechanisms, affected scope, required behavior, and an observable pass condition.
    • Verify the deployed response, rendered output, crawl behavior, and user-facing result when those layers are relevant.
    • Treat AI explanations, screenshots, successful builds, and closed tickets as supporting evidence, not proof by themselves.
    • Record the build, URLs, inputs, procedure, expected result, actual result, and exceptions so someone else can reproduce the decision.
    • Separate technical verification from business impact: proving that a fix shipped does not prove that rankings, traffic, AI citations, or revenue improved.

    A green status can conceal four different failures

    A green status beacon sits above four transparent pipeline chambers containing different hidden software and website configuration failures.

    Most weak verification starts with one overloaded question: “Is it done?” That question allows several different claims to collapse into one answer. Code can exist without being deployed. A function can run without its output reaching the interface. A page can look correct in a browser while its raw HTML or response headers remain wrong. A crawler can stop reporting an issue because its configuration or crawl path changed.

    Use four checkpoints instead:

    1. Specified: Does the requirement describe the intended behavior precisely enough that two implementers would build the same thing?
    2. Implemented: Is the required logic present in the code, template, configuration, edge rule, or data pipeline that is supposed to provide it?
    3. Deployed and executing: Is that implementation included in the production build, active under the relevant conditions, and operating on the intended URLs or inputs?
    4. Observable: Does the intended recipient actually receive the result through the raw response, rendered page, crawlable link graph, report, interface, API, or other promised delivery surface?

    These checkpoints catch different defects. A unit test may prove that a function behaves correctly while saying nothing about whether the function was wired into the production path. A deployment log may prove that a build reached the server while saying nothing about which markup a crawler received. A backend record may prove that a value was calculated while saying nothing about whether the client ever received or saw that value.

    The risk is not merely theoretical. In one production platform, a core trust-scoring capability was described in documentation and client-facing materials but was absent from the live system. The gap survived eight months of status updates because the updates reported completion without testing the promised capability from end to end.

    That distinction matters even more when AI writes the code. An AI can satisfy the visible shape of a request while missing an unstated business rule, an edge case, a template family, or the connection between backend logic and frontend delivery. Its confident explanation is a description of its attempt. Your acceptance test decides whether the attempt succeeded.

    Write the acceptance test before AI writes the code

    A prompt is not automatically a specification. “Fix the canonicals,” “add schema,” or “improve page speed” names a desired direction, but none defines a finished state. The ambiguity is especially costly when AI can produce a plausible patch before anyone has decided what the site should actually do.

    For each requirement, create a compact acceptance contract with these fields:

    • Problem: State the current mechanism, not a generic tool label. Identify what is absent, duplicated, incorrect, unreachable, delayed, or delivered to the wrong surface.
    • Scope: Name the templates, URL patterns, locales, environments, user states, bot states, or data inputs covered by the change. State important exclusions as well.
    • Required behavior: Describe the exact output and the conditions under which it should appear.
    • Observation point: Say where the behavior must be visible: response headers, server-delivered HTML, rendered DOM, internal link graph, structured data, API response, interface, export, or report.
    • Test procedure: Record the URLs or inputs, the actions to perform, the tool or retrieval method, and the comparison to make.
    • Pass condition: Define an observable result that produces an unambiguous pass or fail.
    • Negative and edge cases: Include conditions where the feature must not run, as well as representative boundary cases.
    • Required evidence: Decide what must be attached to the ticket, such as a response capture, rendered output, crawl extract, test result, or screen recording.

    Consider a canonical issue on product variants. “Fix the canonical tags” leaves the consolidation policy, affected templates, output location, target format, and test method open to interpretation. A workable acceptance contract could instead say:

    • Problem: Variant URLs on the named product template emit self-referencing canonical elements, although the approved policy consolidates those variants to the parent product URL.
    • Scope: The named template and URL pattern only; category pages and independently indexable variants are excluded.
    • Required behavior: Each in-scope variant emits one canonical element whose resolved absolute URL exactly matches its approved parent URL.
    • Observation point: The server-delivered HTML, plus the rendered DOM if client-side code can alter the element.
    • Test procedure: Fetch representative standard, parameterized, and edge-case URLs; compare the emitted target with the approved mapping; then crawl the in-scope pattern to look for recurrence.
    • Pass condition: Every tested URL emits the expected target, no tested page emits a second conflicting canonical, and the scoped crawl finds no instance of the original mechanism.

    This contract does more than test the final patch. It forces the team to decide which variants should consolidate before code is generated. That is the right time to find an unclear policy. If you wait until review, the implementation itself starts dictating the requirement.

    You can ask AI to draft test cases, identify ambiguities, propose edge cases, and explain which files it changed. Do not ask it to define success after it has already selected an implementation. A human owner should approve the expected behavior first, particularly when the change can alter crawling, indexing signals, redirects, rendering, or customer-visible reporting.

    Translate technical SEO findings into build specifications

    An audit tool reports what it detected under its own rules. It does not know your indexation policy, locale model, preferred URL mapping, rendering architecture, business priority, or acceptable exception. That is why forwarding a scanner flag is not the same as writing a specification.

    Before opening a build ticket, identify the underlying mechanism and convert it into a result the implementer can observe. The following patterns show the level of precision to aim for.

    Audit labelMechanism to identifyExample of a verifiable pass condition
    Broken canonicalOn named URLs or templates, determine whether the canonical is absent, duplicated, malformed, non-resolving, or pointed at a target that conflicts with the approved mapping.Each representative URL emits one expected absolute canonical at the required observation point, with no conflicting duplicate; a scoped recrawl finds no recurrence of that mechanism.
    Missing hreflangIdentify the affected locale cluster and whether the failure is a missing entry, an incorrect locale value, a broken target, or an incomplete reciprocal mapping.Every tested member of the approved cluster emits the complete intended mapping, each mapped target resolves as expected, and reciprocal entries are present where the site policy requires them.
    Orphaned pageConfirm that the page is intended to be discoverable through internal links and that the orphan finding is not caused by the crawl seed, exclusions, blocked resources, or a deliberately isolated workflow.The page receives the specified crawlable internal link from the approved source or template and becomes reachable when the agreed crawl is rerun from its defined seed.
    Page speed issueName the affected metric or event, URL or template, test environment, and likely mechanism, such as server delay, a render-blocking resource, or an oversized page component.The specified server, template, asset, or delivery change is present, and the same measurement procedure is rerun on the same scope with the before-and-after evidence attached. Any numerical threshold must come from the project’s approved performance target.
    Structured data issueIdentify the exact entity, property, value, page type, and generation layer involved. Separate invalid syntax from markup that is valid but inconsistent with visible page content or the site’s entity model.The production page emits parseable JSON-LD matching the approved schema contract and visible content on all representative templates, with absent or inapplicable properties omitted according to that contract.

    The last column is deliberately narrower than “SEO improved.” A developer can control whether the required markup, link, header, or response ships. The team cannot turn a ranking, citation, or traffic change into a guaranteed acceptance criterion for one technical ticket. Keep the engineering test causal and observable; measure search outcomes separately over an appropriate period.

    Triage the finding before specifying the fix

    Not every crawler warning deserves development time. Run four checks before converting one into a ticket:

    1. Confirm the mechanism. Inspect representative affected URLs rather than relying only on the tool’s label.
    2. Confirm the intended policy. Decide what the site should do and whether the flagged behavior is genuinely wrong for this template, locale, or page state.
    3. Confirm the scope. Determine whether the issue affects one page, one template, one release path, or a broader class of URLs. Include a known-good comparison where possible.
    4. Confirm the owner and layer. Route the change to the place that produces the defect: server configuration, CDN or edge rule, application logic, template, content entry, client-side rendering, or reporting interface.

    This prevents two familiar mistakes. The first is repairing a symptom at the page level when a template or delivery rule keeps regenerating it. The second is applying a broad template fix to a finding that was actually caused by one malformed record. AI will happily automate either mistake if the requested scope is wrong.

    Verify the production response and leave reproducible proof

    A developer checks a live website response on a laptop while organizing server, crawler, source, and screenshot evidence in an adjacent tray.

    Reviewing code is useful, but technical SEO behavior is often shaped by several layers after the code is written: build configuration, environment variables, content data, feature flags, routing, caches, edge rules, rendering, and deployment state. Verification therefore has to follow the result to the surface where a crawler, user, customer, or reporting recipient encounters it.

    Run a layered release check

    1. Freeze the requirement and baseline. Save the acceptance contract and capture the failing response, page, crawl result, or user-facing behavior before implementation. Without a baseline, a changed result can be mistaken for a correct one.
    2. Inspect the implementation layer. Confirm that the relevant code, template, rule, mapping, or configuration exists and covers the stated conditions. This catches omitted logic and accidental changes outside scope.
    3. Run focused automated tests. Test the core rule and the edge cases identified in advance. A passing build is not enough when the build contains no assertion for the requirement you care about.
    4. Confirm the deployed artifact. Tie the test to a build or release identifier. Verifying a local branch or staging build does not prove that the same change reached production.
    5. Observe the receiving surface. Inspect the raw status, headers, and HTML when the requirement lives there. Render the page when scripts can create or modify the output. Crawl from the agreed seed when discovery or internal linking is the concern. Open the interface or export when a customer-visible result was promised.
    6. Test representative failures and exclusions. Check a normal case, an edge case, and a case where the behavior must not apply. A feature that works everywhere can be just as wrong as one that works nowhere.
    7. Repeat the check in production. Re-run the defined procedure against the live URLs or inputs after deployment. If caching or delayed processing is part of the system, verify the result after the relevant layer has updated rather than assuming a purge or job completed.
    8. Run a scoped regression check. Confirm that adjacent templates, locales, page states, or outputs named in the risk assessment still behave as intended.

    Choose only the layers that can affect the requirement, but do not stop one layer early. If the promise is “the customer can see the score,” a correct database value is intermediate evidence. If the promise is “a crawler receives this canonical,” a correct component in the source repository is intermediate evidence. In both cases, the final check belongs at the receiving surface.

    Build a proof packet another person can reproduce

    A screenshot can help, but it rarely captures request conditions, raw markup, build identity, or scope. Close the ticket with a small proof packet containing:

    • The requirement or acceptance-test identifier.
    • The production build, release, or configuration version tested.
    • The exact URLs, inputs, locale, login state, user agent, or feature state needed to reproduce the check.
    • The test date and environment.
    • The retrieval, rendering, crawl, validation, or interface procedure used.
    • The expected result beside the actual result.
    • Raw evidence where relevant, such as response headers, HTML, JSON-LD, API output, a crawl extract, an automated test result, or a user-facing capture.
    • Any exceptions, unresolved cases, and the person responsible for the next decision.

    This changes reporting from activity to evidence. “The canonical fix was deployed” reports an action. “The named production build emitted the approved canonical for the standard, parameterized, and edge-case samples; the scoped crawl found no recurrence; one excluded template was unchanged” reports a verified result and its boundary.

    Keep technical proof separate from search impact

    Verification should also limit what you claim. A passing structured-data test proves that the tested markup conforms to your approved contract. It does not prove that a search engine will display a feature or that an AI system will cite the page. A correct canonical implementation proves that the declared signal shipped. It does not prove which URL a search engine will ultimately select or how rankings will move.

    Report those as separate layers:

    • Delivery: What code, configuration, template, or content change entered production?
    • Technical behavior: What did the live system return or display under the defined test conditions?
    • Coverage: How much of the intended URL, template, locale, or user-state scope passed?
    • Search or business outcome: What later changed in discovery, indexing, visibility, citations, traffic, leads, or revenue, and what other factors prevent a simple causal claim?

    This separation protects decision quality. A failed search outcome does not retroactively mean the implementation test was invalid, and a successful implementation does not justify claiming an outcome that has not been measured.

    Make evidence part of the definition of done

    The workflow becomes durable when the ticket cannot close without its proof packet. Let AI generate code, suggest cases, draft automated checks, and compare outputs. Keep human ownership over the intended policy, acceptable scope, production evidence, exceptions, and business claim.

    Start with one open technical SEO ticket. Replace its audit label with the exact mechanism, affected scope, required production behavior, observation point, and pass condition. If you cannot describe the evidence that would make you close it, the work is not ready to be built. If you can, both the AI and the reviewer have a standard they can actually meet.

    References


  • How to Choose AI Search Optimization and Query Analytics Tools

    How to Choose AI Search Optimization and Query Analytics Tools

    You’re looking at an AI visibility dashboard that says your brand is being cited more often. The line is moving in the right direction, but it still doesn’t tell you whether new buyers discovered you, existing demand simply used your name, or any cited page contributed to a useful business outcome.

    That is the real tool-selection problem. You don’t need another score with an upward arrow. You need a system that preserves the chain from query to citation to page to outcome, then shows you what to change.

    Start with the decision your tool must support

    AI search optimization tools often combine monitoring, query analysis, content recommendations, competitive tracking, and attribution. Those functions may appear in one interface, but they answer different questions. Treating them as one category makes it easy to buy broad coverage without gaining a usable workflow.

    Write down the decisions you expect the tool to improve before you review its features:

    1. Where are we absent? Identify the topics, questions, platforms, markets, and answer types where your brand or pages are missing.
    2. Why are we absent? Determine whether the likely gap concerns content relevance, factual clarity, source eligibility, entity representation, authority, technical accessibility, or a weak match between the query and the page.
    3. What should we change? Turn the observation into a specific action on a specific URL, entity record, content brief, internal link, or structured-data implementation.
    4. Did the change matter? Compare the same query set and conditions after the change, then connect improved visibility to visits, leads, transactions, or another outcome that matters to your organization.

    The underlying measurement chain contains several distinct objects:

    • Audience intent: the problem or decision a person is trying to resolve.
    • User prompt: the words the person enters into an AI interface, when that information is actually available.
    • Grounding query: a lookup an AI system uses to find supporting information for its response. This is not necessarily the user’s verbatim prompt. Microsoft Clarity’s AI reporting, for example, surfaces grounding queries used to retrieve supporting information.
    • Citation: the page or domain selected as support.
    • Answer inclusion: whether the answer mentions, describes, compares, or recommends the brand.
    • Outcome: what happens after exposure, such as a visit, signup, qualified lead, assisted conversion, or transaction.

    A tool that observes only one layer cannot explain the whole chain. Citation tracking doesn’t automatically reveal the original prompt. A brand mention doesn’t prove that your page was cited. Referral traffic doesn’t show every answer that influenced a person without producing a click. Revenue attribution doesn’t become trustworthy merely because a dashboard attaches currency to an AI channel.

    Define each metric before accepting it. Record its numerator, denominator, platforms, markets, languages, query set, brand rules, reporting window, and treatment of missing observations. A citation rate calculated from a monitored query set describes that set; it is not a census of your visibility across every possible AI answer.

    Separate branded demand from non-branded discovery

    Two separate streams of abstract search signals represent existing brand demand and broader discovery before entering an analytics system.

    An aggregate visibility score can rise while your ability to reach unfamiliar buyers remains flat. That happens when branded questions and generic category questions are blended into one total.

    A branded query contains your company, product, domain, or another deliberate brand identifier. A non-branded query expresses a problem, category, use case, comparison criterion, or desired outcome without naming you. The first group usually tells you about retrieval around existing awareness. The second gives you a clearer view of discovery and consideration beyond that awareness.

    Microsoft Clarity can now label individual AI queries as branded, filter by branded or non-branded status, and break Share of Authority out by query type. The important lesson is broader than one product: any query analytics workflow should preserve this distinction rather than bury it inside a blended score.

    Observed patternWorking interpretationWhat to inspect next
    Branded visibility improves while non-branded visibility is flatExisting brand retrieval may be strengthening without broader category discoveryReview missing generic intents, competitor citations, and whether you have a suitable page for each important problem or category query
    Non-branded citations improve but brand inclusion does notYour pages may be useful as evidence without creating a strong connection to the brandInspect how clearly the cited page identifies the organization, product, expertise, and relationship between the evidence and the brand
    Citations improve but downstream outcomes remain flatThe new exposure may be informational, poorly matched to the intended audience, or disconnected from a useful next stepCheck the cited URLs, query intent, landing-page path, calls to action, and whether the outcome is measurable at all
    Branded visibility declines while non-branded visibility is stableGeneral topical relevance may be intact while brand-specific retrieval or representation has weakenedCheck name variants, product facts, changed URLs, outdated pages, inconsistent entity details, and competing pages that may have replaced the intended citation

    These are diagnostic hypotheses, not proof of causation. Use them to choose the next inspection, not to declare why an AI system behaved as it did.

    Your brand classification rules also need to be explicit. Build a controlled dictionary containing the company name, product names, domains, accepted abbreviations, former names that still matter, and common variants. Keep competitor-only queries out of your branded segment. Put queries that contain both your brand and a competitor into a separate brand-plus-competitor segment if comparisons matter to you.

    Preserve the raw query beside the assigned label. When the dictionary changes, record the change and reprocess historical data consistently where possible. Otherwise, a reporting shift caused by classification can look like a visibility shift caused by the market.

    Turn query analytics into an optimization queue

    Abstract query signals are sorted into groups and condensed into a short stack of prioritized optimization cards.

    A query report becomes useful when every important observation has an owner, a target page, a proposed change, and a validation method. Without those fields, the dashboard produces interesting meetings rather than better search assets.

    Use this operating loop:

    1. Capture the evidence. Keep the raw query, platform, observation time, market and language where available, branded status, cited URL, brand inclusion, answer evidence, and any connected outcome identifier. A screenshot can help with review, but retain exportable text or structured records as well.
    2. Cluster by intent. Group wording variants around the same underlying job, such as learning, evaluating, comparing, troubleshooting, or buying. Do not force ambiguous queries into a convenient category; an unknown bucket is more honest than false precision.
    3. Map each cluster to the page that should win. Record the preferred URL even when it is not currently cited. If several internal pages compete for the same intent, decide which one should be canonical for the task before producing more content.
    4. Write a testable diagnosis. Replace vague notes such as improve authority with statements such as the preferred page does not answer the comparison criterion present in the query, or the cited page contains an outdated product description.
    5. Make the smallest defensible change. Clarify the direct answer, add missing evidence, update obsolete facts, improve the heading and page structure, strengthen relevant internal links, or repair structured data that inaccurately expresses visible page content.
    6. Recheck under comparable conditions. Use the same defined query set, platforms, markets, and classification rules. Preserve before-and-after evidence and treat a single changed answer as an observation, not conclusive proof.
    7. Connect the result to an outcome. Determine whether the change affected only citation presence or also brand inclusion, qualified visits, assisted conversions, leads, transactions, or another declared objective.

    The diagnosis step prevents a common failure: applying the same content tactic to every visibility gap. Different observations call for different checks.

    • The relevant query appears, but your domain is not cited: inspect the pages that are cited, the kind of evidence they provide, and whether you have an eligible page that directly satisfies the intent.
    • Your domain is cited through the wrong page: inspect internal competition, redirects, canonical signals, page purpose, and whether the preferred page is actually the better answer.
    • Your page is cited, but the brand is not meaningfully included: examine whether the page supplies a fact without establishing a clear relationship between that fact, your entity, and the reader’s decision.
    • The brand appears, but a material fact is wrong: prioritize factual correction over visibility growth. Audit the current page, structured data, consistent entity details, and any outdated content that could support the error.
    • Visibility and traffic improve, but conversions do not: inspect intent fit and the path after arrival. The cited content may answer an early-stage question while the page asks for a late-stage commitment.

    Structured data belongs inside this workflow, but it isn’t a substitute for the page. JSON-LD should express accurate, visible, supported facts and relationships. Adding markup for information the reader cannot verify on the page creates a data-quality problem rather than an optimization advantage.

    Keep the queue prioritized by consequence as well as visibility. An inaccurate product claim deserves attention even if it appears in a small query cluster. A high-volume-looking theme may deserve less attention if it has no suitable audience, page, or business path. The tool should help you retain those distinctions instead of sorting every task by a single proprietary score.

    Choose the tool by the evidence it can preserve

    AI platform coverage, optimization actions, agentic commerce, and revenue attribution form a useful buying frame. They are not interchangeable, and a long feature list in one area does not compensate for missing evidence in another.

    Buying criterionEvidence to requestWarning sign
    Platform coverageA precise list of answer experiences, markets, languages, collection methods, refresh behavior, and historical availability, plus raw evidence behind each observationA platform logo is shown without explaining which surface, geography, or data-collection method it represents
    Query analyticsRaw query export, a clear distinction between user prompts and grounding queries, editable brand rules, intent grouping, page mapping, and traceable metric definitionsAll observations are collapsed into a visibility score whose denominator and monitored universe are unclear
    Optimization actionsA recommendation that identifies the query, diagnosis, target URL, proposed change, supporting evidence, owner, status, and validation signalGeneric instructions to add authority, improve quality, or write more content without showing the affected query and page
    Agentic commerceA concrete explanation of the agent action being observed or enabled, the product data required, the supported transaction path, and the event record available for verificationThe term agentic is used for ordinary content generation, chatbot interaction, or product monitoring without an observable commerce action
    Revenue attributionThe identifiers and rules that connect exposure, citation, visit, conversion, and revenue; documented attribution logic; accessible underlying records; and a path for unresolved or unattributed casesRevenue appears beside an AI channel without a reproducible connection between the visibility event and the business event
    Data portabilityExports for raw observations, labels, evidence, URLs, recommendations, status history, and outcome joins in a format your team can use elsewhereYour history, classifications, and evidence disappear when the subscription ends or cannot be independently audited

    Agentic commerce should carry substantial weight only when it matches your business model. If you sell structured products and expect agents to participate in discovery or transactions, ask exactly which part of that path the tool measures. If you publish advice, generate leads, or sell a service through a considered sales process, query coverage, citation evidence, content actionability, and attribution may deserve more weight.

    Do not evaluate attribution from the dashboard label. Ask the vendor to walk through one record from the observed AI event to the business outcome. You should be able to see what was directly measured, what was joined, what was modeled, which window and rules were applied, and where uncertainty remains. If that chain cannot be reproduced, treat the revenue figure as directional.

    Run a bounded pilot with your own query set before making a long-term commitment. Include branded, non-branded, comparison, factual, and action-oriented intents that matter to your audience. Define the preferred page and expected outcome for each cluster in advance. Then inspect whether the tool:

    • captures the platforms and markets you actually care about;
    • shows raw evidence behind its classifications and scores;
    • distinguishes prompts, grounding queries, citations, mentions, and outcomes;
    • lets you correct brand labels and query clusters without losing the original record;
    • turns a visibility gap into a page-level action your team can assign;
    • preserves before-and-after evidence after a change;
    • exports the data required for independent analysis; and
    • explains attribution without hiding the join logic.

    Treat missing raw evidence, unclear denominators, or unusable exports as gating failures when auditability matters. A polished interface can save reporting time, but it cannot repair an unverifiable measurement model.

    Key takeaways

    • Choose an AI search tool for the decisions it improves, not the number of charts it contains.
    • Keep audience intent, user prompts, grounding queries, citations, answer inclusion, visits, and outcomes as separate measurement layers.
    • Split branded retrieval from non-branded discovery before interpreting any aggregate visibility trend.
    • Require every optimization recommendation to name the affected query, target page, diagnosis, proposed change, and validation signal.
    • Judge platform coverage by precise surfaces, markets, collection methods, and raw evidence rather than platform logos.
    • Accept revenue attribution only when you can inspect the chain connecting an AI observation to the business event.

    Your next move can be small. Take one important non-branded query cluster, identify the page that should answer it, and trace the available evidence from grounding query to citation to brand inclusion to outcome. Make one defensible change and preserve the before-and-after record.

    If your current tool cannot support that chain, you now know the capability to look for. If it can, stop watching the aggregate score and start using the evidence to run an optimization queue.

    References