Tag: AI Tools

  • Human-Led AI for SEO: A Workflow That Protects Quality

    Human-Led AI for SEO: A Workflow That Protects Quality

    AI can shorten research and analysis, but your real bottleneck is no longer producing text. It is producing a page with a defensible point of view, traceable facts, and a reason to exist beside every page already competing for attention.

    You do not need an AI-free SEO process. You need a clear line of accountability: machines compress inputs and expose patterns; people choose the search problem, supply the evidence, make the judgment, write the consequential passages, and approve what goes live.

    Put AI upstream of authorship

    AI can compress SEO tasks that took hours into minutes. That makes it useful for clustering keywords, mapping themes to URLs, finding patterns in exports, organizing supplied material, and generating options for a strategist to evaluate.

    The boundary is simple. AI may reduce the amount of information you have to inspect, but it should not decide what is true, what your audience needs, what your evidence means, or what your brand is prepared to claim. When the model moves from organizing the work to supplying the substance, efficiency starts consuming the quality it was supposed to create.

    Workflow stageUseful AI roleHuman responsibilityRequired output
    Opportunity analysisCluster exports, connect related queries, and flag changesDecide which problems matter to the audience and the businessA prioritized page list with a reason for each choice
    Content briefingOrganize questions, entities, subtopics, and supplied factsChoose the intent, answer, evidence, angle, and exclusionsA human-owned brief rather than an unverified generated outline
    DraftingOffer structures, counterarguments, examples to investigate, and constrained rewritesWrite the answer, interpretation, firsthand material, and tradeoffsA draft whose consequential claims have identifiable provenance
    Quality controlFlag repetition, inconsistency, ambiguity, and possible unsupported claimsVerify every claim and decide whether the page deserves publicationA factual, useful page with a named human approver
    MeasurementGroup page and query data so changes are easier to inspectInterpret the movement and choose the next actionA documented decision to keep, repair, reframe, consolidate, or retire the page

    Do not confuse human-edited content with human-led content. Changing headings, fixing grammar, and removing awkward transitions may improve presentation, but it does not add experience, evidence, or an original conclusion. If a model chose the premise, assembled the claims, and wrote the argument, a cosmetic edit leaves the model in charge of authorship.

    A small first-party comparison illustrates the risk without proving a universal rule. In that set, three purely AI-written pages launched in April 2025 had nearly disappeared from search results by January 2026. After five AI-drafted, human-edited pages were rewritten by hand, they subsequently recorded 12% more clicks and 27% more impressions year over year during the reported three-month window. Those figures come from a limited set of pages, so they are a warning signal rather than a performance promise. The useful conclusion is narrower: surface editing is not a substitute for original authorship.

    The strategic risk is not the mere presence of AI. It is scaled production that adds little beyond what is already available. Search visibility becomes harder to defend when every page repeats the same consensus in the same vocabulary. Your workflow therefore needs to optimize for information gain and usefulness before it optimizes for publishing volume.

    Build an evidence packet before you ask for content
    Hands assemble documents, reference cards, an audio recorder, and fact markers into an organized evidence packet on a table.

    A keyword export is an opportunity map, not an evidence base. It can tell you which language people use and which URLs are changing, but it cannot supply the expertise that makes your answer worth trusting. Before an LLM sees a writing task, create a compact evidence packet that a human owns.

    1. Define the reader’s decision. Finish this sentence: “After reading, the reader should be able to…” If you cannot name the decision or action, the page is not ready for a brief.
    2. Write the answer in rough human language. State the recommendation, the important qualification, and what common advice misses. This can be messy. Its purpose is to establish the point of view before generated language begins influencing it.
    3. Collect admissible evidence. Include relevant internal notes, documented procedures, approved customer material, product records, first-party data, and external references you are permitted to use. Label firsthand material as such and identify who can verify it.
    4. Create a claim ledger. For each consequential claim, record the supporting artifact or URL, any limitation, the person responsible for verification, and whether the claim is safe to publish. A blank evidence field is a research task, not an invitation for the model to complete the sentence.
    5. Name the page’s original contribution. It might be a firsthand process, an analysis of your own data, a decision framework grounded in expertise, a documented failure mode, or a clearer answer to a question others leave unresolved. If you cannot point to the contribution, do more work before drafting.

    Only then should you hand the organizational work to AI. One practical workflow used Gemini to group more than 2,000 declining Page 1 keywords from Ahrefs into topical clusters. After Google Search Console data was added, the themes were mapped to the URLs losing visibility. That is a good division of labor: the machine narrows a large field; the strategist inspects the affected pages, determines why they matter, and decides what deserves to change.

    Give the model a task contract instead of a vague request to “create an SEO brief.” A useful contract contains these boundaries:

    • Input boundary: use only the attached exports, notes, and approved references.
    • Analytical task: cluster related items, identify duplicates, map clusters to existing URLs, or surface conflicts.
    • Non-authority rule: do not decide which interpretation is correct and do not convert an unsupported idea into a fact.
    • Traceability rule: preserve the row, URL, note, or artifact behind every finding.
    • Uncertainty rule: place missing, ambiguous, or contradictory information in a separate review queue.
    • Output rule: return a structured table or list that a strategist can inspect; do not write publication-ready copy unless a later, bounded task requires it.

    This contract changes the model’s job from “sound knowledgeable” to “make the human’s review faster.” That is the kind of leverage an SEO team can safely repeat.

    Draft from human judgment, then use AI as a critic

    The most consequential writing should begin with a person, even when the starting material is a rough collection of notes. The direct answer, interpretation of evidence, firsthand example, meaningful qualification, and final recommendation carry the page’s real value. Those are precisely the passages you should not outsource to a probability engine.

    1. Lock the thesis before generating prose. Record what you believe the reader should do, why, when that advice does not apply, and what evidence supports it.
    2. Turn each section into a promise. A section should help the reader make a decision, complete a task, or detect a problem. “Benefits of AI” is a topic; “Choose which SEO tasks AI may own” is a useful promise.
    3. Assign evidence before paragraphs. Put the relevant claim-ledger entries beneath the section that will use them. If a section has no evidence or expertise attached, remove it or return to research.
    4. Draft the high-judgment passages in human language. Preserve concrete terms, uncertainty, exceptions, and the reasoning that connects evidence to action.
    5. Give AI bounded revision jobs. Ask it to identify repetition, list unanswered objections, find contradictions, propose clearer ordering, check whether a conclusion follows from the supplied evidence, or create alternate wording for one difficult sentence.
    6. Perform the final edit against the evidence packet, not against the model’s fluency. A sentence that sounds polished but cannot be verified is still a defect.

    During that final edit, interrogate every paragraph:

    • What does this paragraph let the reader do, decide, or notice?
    • Which approved artifact supports its factual claims?
    • Could the paragraph appear unchanged on a competitor’s site? If so, what specific knowledge is missing?
    • Does it state a condition, mechanism, or consequence, or merely announce that something is important?
    • Has polished language hidden uncertainty that was present in the underlying evidence?
    • Would a subject-matter expert sign their name to the wording?

    Do not use a so-called humanizer as a substitute for this review. Passing generated copy through another machine may replace one recognizable writing pattern with another awkward pattern, but it does not create evidence, experience, or a better decision for the reader.

    A vocabulary check can still help. Habitual terms such as delve, tapestry, paramount, synergy, cutting-edge, and game-changing often accompany generic generated prose. Add unwanted terms to your prompt when they conflict with your house voice, then search for them during editing. Treat them as symptoms, not proof. A technically correct term should remain when it is the most precise language available.

    The stronger style instruction is behavioral: use concrete nouns and active verbs; name the actor, action, object, and condition; do not claim importance without showing the consequence; flag a missing example instead of inventing one. That improves usefulness without turning your editorial standard into a blacklist.

    Gate publication with evidence and extraction audits
    An editor inspects a floating web page against source documents and structural page elements before allowing it through a publication checkpoint.

    Human-led does not mean one person glances at the draft before publication. It means a human can explain why the page exists, where its claims came from, what AI did, and why the final answer is defensible. Use two separate gates so factual quality and search presentation do not blur into one subjective approval.

    Gate 1: evidence, accuracy, and originality

    • Every number, date, named event, comparison, and consequential factual claim resolves to an approved reference or internal artifact.
    • Firsthand language points to genuine firsthand material. The page does not imply a test, customer result, interview, or experience that never occurred.
    • Qualifications from the evidence survive into the copy. A limited observation has not become a universal rule.
    • The original contribution is visible in the draft, not merely recorded in the brief.
    • The conclusion follows from the evidence rather than from a confident generated transition.
    • A subject-matter owner has approved the technical meaning, while an editor has approved the communication.

    Classify the result as pass, repair, or block. Block publication when a material claim lacks provenance, the page implies experience you do not have, or no original contribution is present. Repair unclear structure and weak examples only after those blocking problems are resolved.

    Gate 2: search intent and answer extraction

    • The opening resolves the main question without making the reader cross several generic paragraphs first.
    • Each heading describes a decision, task, distinction, or failure mode rather than a broad topic label.
    • The core answer appears in a self-contained paragraph that remains accurate when read apart from the surrounding copy.
    • Names for products, organizations, concepts, and processes stay consistent throughout the page.
    • Citations sit beside the claims they support, allowing readers and retrieval systems to connect evidence with the statement.
    • Lists contain real steps or criteria rather than chopped-up prose.
    • Any JSON-LD or other structured data represents what the visible page actually says. Schema can clarify the content’s structure; it cannot supply expertise or originality missing from the page.

    This second gate supports SEO, AEO, and GEO without distorting the writing for machines. A clear answer, stable terminology, nearby evidence, and faithful structured data also reduce the reader’s effort. If an optimization makes the page harder for a person to understand, it has failed the more important test.

    Measure the page, not the amount of AI

    Record the page’s publication or revision date, target query cluster, intended reader action, original contribution, human owner, and the tasks assigned to AI. Without that record, a future reviewer cannot tell whether a result came from the strategy, the evidence, the execution, or an unrelated change.

    Use first-party Google Search Console and Google Analytics 4 data to inspect performance, but do not treat a before-and-after movement as automatic proof of causation. Review the relevant URL and query cluster, note changes in impressions and clicks, and connect those signals to the reader outcome that matters on your site. Sitewide totals can conceal a page-level gain or loss.

    When a page weakens, do not respond by generating more copy. Return to the evidence packet. Check whether the intended query changed, the answer became stale, a competing page now resolves the task more directly, or your original contribution was never clear. Then choose a specific action: repair the evidence, sharpen the answer, reframe the intent, consolidate overlap, or leave the page alone while more data accumulates.

    Key takeaways for a human-led SEO workflow

    • Use AI to compress, classify, map, challenge, and proofread. Keep truth, intent, interpretation, original contribution, and publication approval with people.
    • Require a human artifact before prompting: a rough answer, evidence packet, claim ledger, and explicit reason the page deserves to exist.
    • Make AI preserve provenance and expose uncertainty. Fluent output without traceable support should never enter a publishable draft as fact.
    • Judge human involvement by decision ownership, not by how many words an editor changed after generation.
    • Optimize answer structure and schema only after the page passes its evidence and originality gate.
    • Measure URL and query outcomes, document the workflow used, and diagnose weak pages before creating more content.

    Take one brief already in production and label every handoff as AI-owned, human-owned, or human-approved. If AI currently owns the thesis, factual support, interpretation, or final judgment, move that responsibility back to a named person before the page goes live. That single change gives you the speed of AI without allowing speed to become your editorial standard.

    References


  • How to Control Accessibility Risk in AI-Generated Websites

    How to Control Accessibility Risk in AI-Generated Websites

    Your AI-built page renders cleanly, the form submits, and the structured data validates. None of that tells you whether a customer can navigate it with a keyboard, understand it through a screen reader, or recover from an error without sight.

    The practical decision isn’t whether to use AI. It is whether your team treats AI output as an untrusted draft or as proof that a page is ready. A reliable process keeps the speed while putting human usability, measurable acceptance criteria, and release authority around it.

    AI scales familiar accessibility failures

    AI-generated experiences do not need exotic defects to exclude people. The persistent failures are ordinary: low-contrast text, images without useful alternative text, form fields without labels, links and buttons without accessible names, and pages that do not declare their language.

    The 2026 WebAIM Million report found detectable accessibility failures on 95.9% of the top one million homepages, averaging 56.1 errors per page. The number of detected errors increased 10.1% after six consecutive years of improvement. At the same time, the average homepage grew to 1,437 elements, 22.5% more than a year earlier and nearly twice the 2019 count.

    Those numbers do not prove that AI alone caused the increase. They do show the environment in which AI tools now operate: complex pages, rapid production, and recurring defects embedded in the examples that code generators can reproduce. When one flawed component is reused across a navigation system, form builder, landing-page template, or personalization layer, the problem scales with it.

    The hardest failures are often invisible in a visual review. An empty button can still have a polished icon. A field can appear to have a label even when the label is not programmatically connected to it. A modal can look correct while trapping keyboard focus. A validation message can be bright red yet never be announced by assistive technology.

    This is where SEO and AI-optimization teams need a precise distinction. Machine-readable is not the same as human-operable. Valid JSON-LD, descriptive metadata, crawlable text, and clean schema relationships cannot make an inaccessible checkout, lead form, menu, or account flow usable. Treat accessibility as a property of the rendered experience, including every interactive state, rather than another item on a technical SEO validation report.

    Make accessibility a release gate, not a prompt adjective

    Three reviewers test an unlabeled website interface with a keyboard, headphones, braille display, and mobile device before a closed release gate.

    Adding the word accessible to an AI prompt can improve the direction of an output. It cannot certify the result. The prompt is an instruction; the release gate is the evidence that the instruction was followed.

    Define what ready means before generation starts

    Your acceptance criteria should describe observable behavior. They should apply to the initial page and to the states created after a person opens a menu, submits incomplete information, changes a filter, launches a modal, or receives a success message.

    Release layerWhat to verifyReason to stop publication
    Page structureDocument language, meaningful headings, semantic regions, and native controls where availableStructure or reading order does not convey the same meaning as the visual layout
    Content and perceptionRequired contrast, useful image alternatives, understandable instructions, and information that is not conveyed by color aloneA person cannot perceive essential content or distinguish a required state
    Forms and controlsConnected labels, descriptive control names, instructions, validation, and error recoveryA field or action is unnamed, ambiguous, or impossible to correct
    Keyboard behaviorLogical focus order, visible focus, activation, backward navigation, and a way to leave overlaysA task traps focus, hides focus, or requires a pointer
    Dynamic behaviorChanges in state, expanded or collapsed controls, loading, errors, and completion feedbackImportant changes are visible but not exposed to assistive technology

    Set the applicable accessibility requirement with a qualified specialist before you turn this table into a formal conformance gate. Legal obligations, contractual commitments, and technical standards can differ by market and product. The table is an operational starting point, not a legal opinion or a substitute for a conformance assessment.

    Give the generator constraints it can act on

    An effective generation brief names the behavior you expect and asks the model to expose uncertainty. Include requirements such as these:

    • Use semantic HTML and native links, buttons, inputs, and headings before creating custom interactive elements.
    • Give every interactive control a clear accessible name that describes its action or destination.
    • Connect each form field to its label, instructions, required state, and error message.
    • Make the complete task operable by keyboard, with a logical order and visible focus.
    • Provide meaningful alternative text for informative images and handle decorative images so they do not create noise.
    • Declare the document language and preserve a meaningful heading hierarchy.
    • Do not use color, position, shape, or animation as the only way to communicate information.
    • List any requirement the generated output cannot verify without browser testing or human review.

    That final instruction matters. It separates code generation from verification and makes unsupported assumptions visible before they become release assumptions.

    Put the same constraints into your component specifications, CMS templates, design-system documentation, and definition of done. A good one-off prompt cannot compensate for a shared component that keeps producing empty buttons or disconnected labels.

    Test the journeys an automated scan cannot complete

    Two usability participants test abstract web forms using a braille display, keyboard, headphones, and an adaptive switch while a researcher observes.

    Automated inspection is valuable because it can cover many pages quickly and catch repeatable markup problems. It is not an end-to-end usability test. AudioEye estimates that automated tools can detect about two-thirds of accessibility issues and automatically fix about half of the issues they detect. Because that is a vendor-supplied estimate rather than a universal benchmark for every tool and website, use it as a warning about coverage limits, not as a guaranteed detection rate.

    Use four complementary checks:

    1. Run automated inspection across templates and states. Scan more than the public URL. Include opened menus, validation errors, filtered results, modals, account states, and any page variation inserted by your CMS or personalization system.
    2. Complete the task with a keyboard. Start before the first control, move forward and backward, activate every required action, and confirm that focus remains visible and predictable. Verify that overlays can be closed and that focus returns somewhere sensible.
    3. Complete the task with assistive technology. Check whether headings describe the page, controls have useful names, expanded and selected states are communicated, fields have connected instructions, and errors are announced at the point where the user needs them.
    4. Review meaning with a person. Automation can detect a missing text alternative more easily than it can judge whether the supplied text communicates the image’s purpose. The same distinction applies to generic link text, unclear instructions, confusing heading order, and technically present but unhelpful labels.

    Do not begin with a random sample of low-impact pages. Start with the journeys whose failure blocks a result: purchase, lead submission, registration, authentication, search, account management, and support. Then test the shared header, navigation, cookie controls, forms, and modal components that appear across many URLs. Fixing the reusable component reduces recurrence; patching individual generated pages leaves the underlying production fault in place.

    For each journey, write the task in plain language before testing. For example: find a product, choose an option, add it to the cart, correct an invalid field, and finish checkout. A pass means the person can complete the entire task and understand the result. A clean scan on the opening screen is not a substitute.

    When a failure appears, prioritize it by consequence and reach:

    1. A blocker that prevents a person from completing a critical task.
    2. A defect in a shared component that affects many pages or states.
    3. A serious information or error-recovery failure that can produce a wrong action.
    4. An isolated content defect on a high-traffic or high-intent page.
    5. A lower-impact issue that does not block the task but still needs a named owner and deadline.

    Do not suppress a scanner warning merely to improve a dashboard score. Resolve it, document why it does not apply, or have someone qualified review the ambiguity. The goal is a usable journey, not a smaller count.

    Make ownership and evidence visible

    Accessibility fails operationally when everybody can influence the experience but nobody can stop its release. Assign responsibility at the point where each type of defect enters the system:

    • The requester or marketer owns the brief, content clarity, image intent, link purpose, and acceptance criteria.
    • The designer owns contrast choices, focus treatment, interaction states, responsive behavior, and the visual presentation of errors.
    • The developer or platform owner owns semantic implementation, keyboard behavior, programmatic relationships, dynamic state, and regression fixes.
    • A qualified accessibility reviewer performs the manual and assistive-technology checks that automation cannot settle.
    • The release owner has explicit authority to block publication or record a time-bound exception with its risk, owner, and remediation date.

    One person may hold several of these roles in a small team. The important part is that none of them remain implied.

    A purchased tool is not evidence that a journey works

    AudioEye’s 2026 litigation analysis reports that U.S. digital accessibility lawsuits doubled from 2020, with 26,253 combined federal and state claims filed in 2025. Ecommerce accounted for 78% of the cases in its dataset. More revealingly, 38.5% of companies facing claims already had an accessibility tool in place.

    That does not show that accessibility tools increase litigation risk. It shows why buying a tool, installing a badge, or reporting a partial score should not be confused with verifying a working experience.

    Partial coverage can also be a weak legal position. On June 4, 2026, a French court ordered Carrefour to bring its website and app to full accessibility conformance within six months, rejecting claimed conformance levels of 50% to 70% as a defense in that case. The ruling is jurisdiction-specific; it is not a universal interpretation of every accessibility law. If you need to determine your legal obligations or exposure, involve qualified accessibility professionals and legal counsel familiar with each market in which you operate.

    Report outcomes, not just defect totals

    An issue count is useful for triage, but it can hide severity. One unnamed checkout button can matter more than many low-impact warnings on an informational page. Put these measures beside the marketing and product metrics your team already reviews:

    • Critical journeys tested and the states covered in each test.
    • Blocking defects, affected templates, and affected business actions.
    • Repeated defects traced to shared components or generation instructions.
    • Open issue age, named owner, target date, and retest status.
    • Regressions found after CMS, component, campaign, or personalization changes.
    • Conversion, completion, abandonment, and bounce metrics for remediated high-traffic pages.

    Record the page or component version, test date, automated tool, manual scenarios, reviewer, results, and fixes. That history helps you distinguish an isolated content mistake from a systemic production problem. It also gives the next release team a known test set instead of forcing them to rediscover the journey.

    If you compare conversion before and after remediation, avoid claiming that accessibility alone caused the change when traffic mix, campaign creative, pricing, or other page elements also changed. Use a controlled test where practical, or annotate the competing changes. Accessibility should not need an immediate conversion lift to justify removing a barrier, but weak attribution will not help you secure lasting operational support.

    Key takeaways

    • Treat AI-generated code and content as drafts until the rendered journey passes defined accessibility checks.
    • Test interactive states and task completion, not only the opening screen or public URL.
    • Combine automated coverage with keyboard, assistive-technology, and human meaning reviews.
    • Fix shared components and generation constraints before patching the same defect page by page.
    • Assign a release owner who can block publication and require evidence of retesting.
    • Do not treat a tool, badge, issue score, or partial conformance percentage as proof that customers can use the experience.

    Start with the next high-consequence page in your production queue. Write down the three tasks a visitor must complete, name the person who will test them without relying on a mouse, and reserve time to fix the shared component if one fails. Do that before publication, then carry the same gate into every AI-assisted template. That is how accessibility becomes part of production rather than an emergency after launch.

    References


  • How a £50 Meta Campaign Became a £1,000 PPC Lesson

    How a £50 Meta Campaign Became a £1,000 PPC Lesson

    A small budget error can become an expensive account-management problem when it is paired with weak monitoring. Google Ads specialist Heather Robinson’s account of a Meta campaign overspend illustrates how routine work, rather than unfamiliar technology, can create the greatest operational risk.

    As reported by Search Engine Land, the campaign was supposed to spend £50 over one weekend but ultimately exceeded £1,000. The episode offers practical lessons about launch controls, conversion tracking, client communication and the proper role of AI in paid media.

    How one budget setting changed the campaign

    Robinson said the £50 budget was configured as a daily amount rather than a lifetime limit. The campaign was then left running for three weeks and was not reviewed until she prepared for a client meeting.

    The distinction between the two budget types was decisive. A lifetime budget is intended to govern spending across a campaign’s scheduled duration, while a daily budget communicates an ongoing daily spending target. Selecting the wrong option therefore changed both the amount the platform could spend and the length of time during which it could continue doing so.

    According to Robinson, the underlying problem was complacency rather than a lack of platform knowledge. Repetition had made the setup feel automatic, while a heavy workload and the absence of another reviewer allowed the incorrect setting to pass unchecked.

    Key takeaways for paid media teams

    • Familiar campaign types still require a complete pre-launch review.
    • Budget type, amount, dates and post-launch delivery should be checked separately.
    • Tracking must represent genuine business outcomes, not merely convenient website actions.
    • AI can accelerate analysis, but an experienced person should remain accountable for approval.
    • When an error affects a client, direct disclosure and a prevention plan can help preserve trust.

    A checklist must extend beyond the launch button

    The incident led Robinson to introduce a structured checklist for every Google Ads and Meta launch, regardless of how familiar the work appears. That response matters because experience and process solve different problems: experience helps a marketer make informed decisions, while a checklist protects against skipped steps, interruptions and misplaced confidence.

    A useful control should cover campaign settings before publication and confirm actual behavior afterward. Budget amount and type, start and end dates, targeting, creative, conversion actions and account ownership all deserve explicit review. An early delivery check then tests whether the live campaign matches the approved plan. For higher-risk launches, a second reviewer can provide additional protection, but even an individual practitioner can create separation by reviewing the setup after a pause rather than approving it immediately.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    Correct spending is not enough if measurement is wrong

    Robinson identified inaccurate conversion tracking as the most common problem she encounters when auditing new client accounts. She linked many of those problems to mistakes made during migrations from Universal Analytics to GA4, leaving some advertisers optimizing toward actions that do not produce revenue.

    In one example she discussed, an ecommerce account had spent a year treating use of the site’s search bar as the optimization goal instead of completed purchases. Once that configuration was corrected, the account effectively had to begin rebuilding its machine-learning signals around the right outcome.

    This broadens the lesson beyond budget control. A campaign can obey its spending limit and still make poor decisions if the conversion signal is misconfigured. Before evaluating automated bidding or creative performance, advertisers should verify what each primary conversion represents, whether it fires at the correct moment and whether it corresponds to a meaningful business result.

    Accountability and human review remain essential

    Robinson chose to disclose the overspend during a scheduled face-to-face meeting, accept responsibility and explain how she would prevent a recurrence. Search Engine Land reported that the client was unhappy but valued her transparency; nearly a decade later, the company remains a client. The outcome does not make the error harmless, but it shows why a candid explanation is more constructive than blaming the advertising platform or minimizing the impact.

    The same accountability principle applies to AI. Robinson uses AI for tasks such as reviewing search-term reports and identifying possible optimization opportunities, but she does not treat it as a substitute for manual checks. She also warned that unreviewed AI-generated ads can produce repetitive, low-quality messaging.

    Paid media platforms will continue adding automation and new features. The durable response is to test them within clear controls, keep a person responsible for final decisions and turn each failure into a stronger operating process.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • OpenAI’s Desktop Consolidation: What Atlas Users Face

    OpenAI’s Desktop Consolidation: What Atlas Users Face

    OpenAI’s reported plan to retire ChatGPT Atlas is more than a product cancellation. It points to a desktop strategy built around one primary ChatGPT application that combines browsing, agent-led work, and Codex capabilities.

    For users and organizations, the immediate questions are practical: how firm the retirement date is, whether adopting an OpenAI browser remains necessary, and what the consolidation could mean for research and digital discovery.

    The desktop app is becoming the center of the product

    CrushPress.AI reported that OpenAI intends to discontinue Atlas as a standalone desktop browser and move its browser-based AI features into a new ChatGPT desktop app. The same report describes that app as bringing together ChatGPT Work, OpenAI’s work-focused agent, and ChatGPT Codex.

    This is a consolidation of entry points as much as a consolidation of features. Instead of asking users to choose among a dedicated AI browser, a separate Codex application, and the broader ChatGPT experience, the reported direction places those functions inside a common desktop environment.

    The sequence reported by CrushPress.AI helps explain the shift. Atlas launched on Mac in October, a dedicated Codex app followed, and an in-app browser was added in April. The planned unified app appears to gather capabilities that had been introduced through separate products, although the source does not provide a detailed migration map.

    Key takeaways

    • ChatGPT Atlas is reportedly scheduled to be retired as a standalone browser.
    • The stated Aug. 9 date is a target, so it should not be treated as an unconditional deadline without further notice.
    • Browser functions, ChatGPT Work, and Codex are being positioned within a unified ChatGPT desktop app.
    • Chrome users are expected to retain access to ChatGPT and Codex through OpenAI’s Chrome extension.
    • The change could concentrate more research and task completion inside ChatGPT, increasing its role in digital discovery.

    The Aug. 9 date carries an important qualification

    CrushPress.AI cited OpenAI’s James Sun as saying on X that Aug. 9 was the current targeted date for deprecation. According to the report, Sun also said that more information would be shared in the application and by email.

    That wording establishes a planned direction but preserves uncertainty around execution. A target date can change, and the supplied report does not specify when access will stop, whether data or settings will transfer automatically, or whether every Atlas feature will have an equivalent in the new app.

    Atlas users should therefore treat official in-app and email notices as the operative migration guidance. Before the target date, organizations can identify which workflows depend on Atlas and document any browser-specific behavior they would need to reproduce. That is prudent continuity planning, not evidence that any particular feature will be lost.

    Users still have two reported browser paths

    A computer user views two visual pathways from a desktop application to separate generic browser experiences.

    The consolidation does not necessarily require every user to replace an existing browser. CrushPress.AI reported that the new desktop app will include browser capabilities, while people who prefer Chrome can use OpenAI’s Chrome extension to access ChatGPT and Codex.

    Those paths serve different working preferences. A unified desktop app can keep browsing and agent tools in one OpenAI-controlled environment. An extension can place the same broad services closer to an established Chrome workflow. The source does not compare feature parity, security controls, performance, or account requirements, so it would be premature to declare either route universally better.

    For teams, the decision should follow the work being performed. Relevant considerations include whether tasks depend on existing Chrome profiles and extensions, whether the unified app offers necessary workflow controls, and how each option fits internal software and security policies. These are evaluation criteria rather than reported product guarantees.

    Consolidation could expand ChatGPT’s role in discovery

    A person uses a central desktop assistant connected to floating research pages, documents, code panels, and media tiles.

    The strategic consequence extends beyond desktop software. When browsing, questions, research, coding, and task execution occupy the same interface, the distance between finding information and acting on it becomes shorter. CrushPress.AI argues that this gives ChatGPT another opportunity to influence how people research brands and discover information outside traditional search-result pages.

    For marketers and publishers, the relevant change is not merely the disappearance of an Atlas icon. It is the possibility that more discovery activity will occur within the main ChatGPT experience, where answers and actions may be combined. That makes accurate, accessible, and clearly attributable information increasingly important, while the supplied source does not establish how the new app will select or present particular brands.

    The next signals to watch are OpenAI’s promised notices, the final treatment of Atlas accounts and workflows, and the practical feature differences between the desktop app and Chrome extension. Those details will determine whether this is mostly a packaging change or a meaningful shift in how desktop users browse and complete work.

    References

  • How to Evaluate AI Marketing Tools Before You Commit

    How to Evaluate AI Marketing Tools Before You Commit

    An AI marketing tool can look persuasive in a demonstration and still fail in day-to-day use. A sound evaluation therefore has to connect the product to a defined business problem, credible evidence, acceptable data practices and the team’s actual capacity to adopt it.

    The most useful approach is a staged decision process. Each stage should eliminate a different kind of risk before price or novelty turns an interesting product into an expensive commitment.

    Turn the business need into a testable decision

    Evaluation should begin with the marketing problem rather than the product’s feature list. The source article recommends asking vendors to explain the challenge their tool addresses and how solving it affects a business outcome. If that connection remains vague, a sophisticated set of AI capabilities does not establish that the product is useful.

    Before meeting a vendor, the buying team can create a short decision brief describing the current workflow, its most important constraint, the people affected and the result that should improve. That result might concern output, troubleshooting or another outcome already important to the organization. The purpose is not to manufacture a justification for buying software; it is to establish a baseline against which the tool can be judged.

    Claims about saving time require an additional question: what will the organization do with the recovered capacity? The source cautions that time savings are not automatically valuable. They become meaningful when the team can redirect that time toward work that advances an existing objective.

    This framing also exposes unnecessary purchases. If the problem can be resolved through a process change, better use of an existing platform or clearer ownership, adding another tool may increase complexity without addressing the underlying constraint.

    Match the evidence standard to the vendor’s maturity

    A glowing software module passes through a sequence of visual testing gates in a modern evaluation lab.

    A relevant case study is more informative than a broad success claim. According to the source, buyers should look for evidence involving organizations with a comparable size, market, vertical or use case, along with concrete results. The closer the operating conditions are to the buyer’s own environment, the easier it is to determine whether the evidence transfers.

    Evidence should also extend beyond customer logos. A credible vendor needs sufficient domain understanding to explain how marketers perform the work, where the recurring friction occurs and why the product was designed in its present form. The source notes that deep subject expertise does not have to reside with every salesperson, but a serious prospective customer should be able to reach someone who has it.

    Vendor maturity changes the appropriate test. An established provider can reasonably be expected to show repeatable results from relevant customers. An early-stage provider may not have that record, so transparency becomes part of the evidence: the vendor should identify where the product is unproven, explain what has been observed in other settings and define what the early partnership would require.

    Being an early adopter can offer an advantage, but the source also identifies added exposure to bugs, feedback demands and uncertain performance. Contract flexibility should reflect that imbalance. A newer vendor that expects the customer to absorb experimentation risk while offering no corresponding flexibility presents a weak partnership proposition.

    Treat data terms as part of the product

    Data governance is not a secondary legal review to perform after a product has been selected. It is part of the product evaluation because access to marketing, campaign or customer information can determine the consequences of a poor choice.

    The source recommends obtaining clear answers about who owns the customer’s data, where it is stored, how long it is retained, whether it is used for model training and what happens when the relationship ends. Any training of shared or third-party models should require explicit consent. If training is permitted only for a customer’s own instance, that limitation should be stated precisely.

    Verbal assurances are not enough. The source treats inconsistencies between a sales explanation and the terms of service as a warning sign and argues that material commitments belong in the contract. The practical evaluation standard is therefore documentary: can the vendor’s claims be located in binding terms, and do those terms cover the complete data lifecycle?

    This review also tests vendor quality. Clear, consistent answers suggest that the provider understands its own systems and customer obligations. Deflection or ambiguity leaves the buyer unable to assess exposure, regardless of how compelling the product appears.

    Calculate adoption cost, not just subscription cost

    A marketing team handles system setup, data preparation, training and workflow changes beside a simple subscription token.

    The commercial price is only one component of an AI tool’s cost. The source highlights implementation time, internal effort, integrations, training, quality assurance and possible disruption to the existing marketing technology stack. A product can be affordable on paper yet uneconomic if it consumes resources the organization cannot reliably provide.

    A useful implementation review follows the proposed tool through the real workflow. It identifies who will configure it, which systems must connect to it, who will review its outputs, how exceptions will be handled and what ongoing maintenance the vendor expects from the customer. This makes hidden dependencies visible before a contract creates pressure to proceed.

    Adoption is also a trust problem. As the source observes, a product that people cannot understand, trust or fit into their routines will not produce its promised value. The evaluation should therefore include the intended users, not only procurement leaders or executives. Their experience can reveal whether the tool removes friction or merely relocates it.

    A limited pilot can combine these questions into one decision. It should start with the predefined problem, use agreed evidence of success, operate under acceptable data terms and expose the actual workload imposed on the team. The decision at the end should account for both the result and the effort required to produce it.

    Key takeaways

    • Define the business problem and intended outcome before reviewing product features.
    • Demand evidence relevant to the organization’s size, market, vertical or use case.
    • Adjust expectations for vendor maturity, but require transparency and risk-sharing from early-stage providers.
    • Verify ownership, storage, retention, training and deletion terms in binding documents.
    • Evaluate implementation effort, workflow fit and user trust alongside the subscription price.

    As AI products continue to multiply, disciplined evaluation will matter more than rapid purchasing. Teams that document the problem, evidence threshold, governance requirements and adoption burden in advance will be better positioned to recognize tools that deserve a durable place in the marketing stack.

    References

  • Conductor MCP Server: Trusted AEO and SEO Data for AI

    Conductor MCP Server: Trusted AEO and SEO Data for AI

    I use Conductor’s MCP Server to ground the AI tools my team already relies on in verified AEO and SEO intelligence, instead of depending on a stale snapshot of the web.

    Graphic announcing a new product release for an AEO and SEO Intelligence Layer, with white text on a dark green abstract gradient design.
    A bold launch visual introduces an AEO and SEO Intelligence Layer, framing verified search and AI visibility data as a modern layer for marketing teams.

    Inspired by this post on Conductor Blog.


    crushpress.ai community screenshot
  • Modern SEO Workflows: From Dashboards to Small Tools

    Modern SEO Workflows: From Dashboards to Small Tools

    A modern SEO workflow has to do more than collect rankings and audit errors. It must distinguish visibility from traffic opportunity, focus limited time on pages that matter to the business, and turn recurring analysis into reliable automation.

    The most useful operating model is therefore not a wholesale replacement of traditional SEO software. It is a layered system in which established data sources reveal the problem, people choose the intervention, and AI-assisted tools reduce the cost of repeating proven work.

    The operating model matters more than the size of the stack

    Rank trackers, keyword platforms and site crawlers remain useful because search engines still need to discover, interpret and evaluate pages. However, the reported case for a new SEO stack is that those tools describe only part of a more fragmented search environment. AI Overviews, local packs, shopping features and other result formats can change how much value a nominal ranking produces. Historical search volume can likewise remain stable while an answer displayed in the results reduces the traffic available to publishers.

    That changes the role of measurement. A ranking is an observation, not an outcome. The workflow must connect traditional visibility, AI-search presence, landing-page behavior and conversion evidence before deciding what deserves attention. The same source reported that LLM referral traffic in its cited dataset grew by 80% between the first and second halves of 2025 and converted at 18%, while accounting for 2% or less of total traffic. Those figures were presented as evidence of a small but potentially meaningful channel, not as proof that conventional search had ceased to matter.

    Workflow layerQuestion it answersTypical inputsRequired output
    ObserveWhere is visibility, demand or performance changing?Search Console, analytics, rank tracking, crawls and AI-visibility observationsA short list of material signals
    DecideWhich signal is worth acting on now?Business value, intent, conversion proximity and implementation effortOne prioritized intervention
    ShipWhat can improve the page or remove the constraint?Content edits, internal links, technical fixes and clearer conversion supportA completed change or actionable brief
    SystematizeWhich repeated work should become faster and more consistent?APIs, scripts, notebooks and carefully supervised LLMsA documented, testable process

    This sequence prevents a common tooling mistake: automating a report before establishing which decision the report should support. It also preserves a place for human judgment between data collection and implementation.

    A 120-minute loop can connect monitoring with delivery

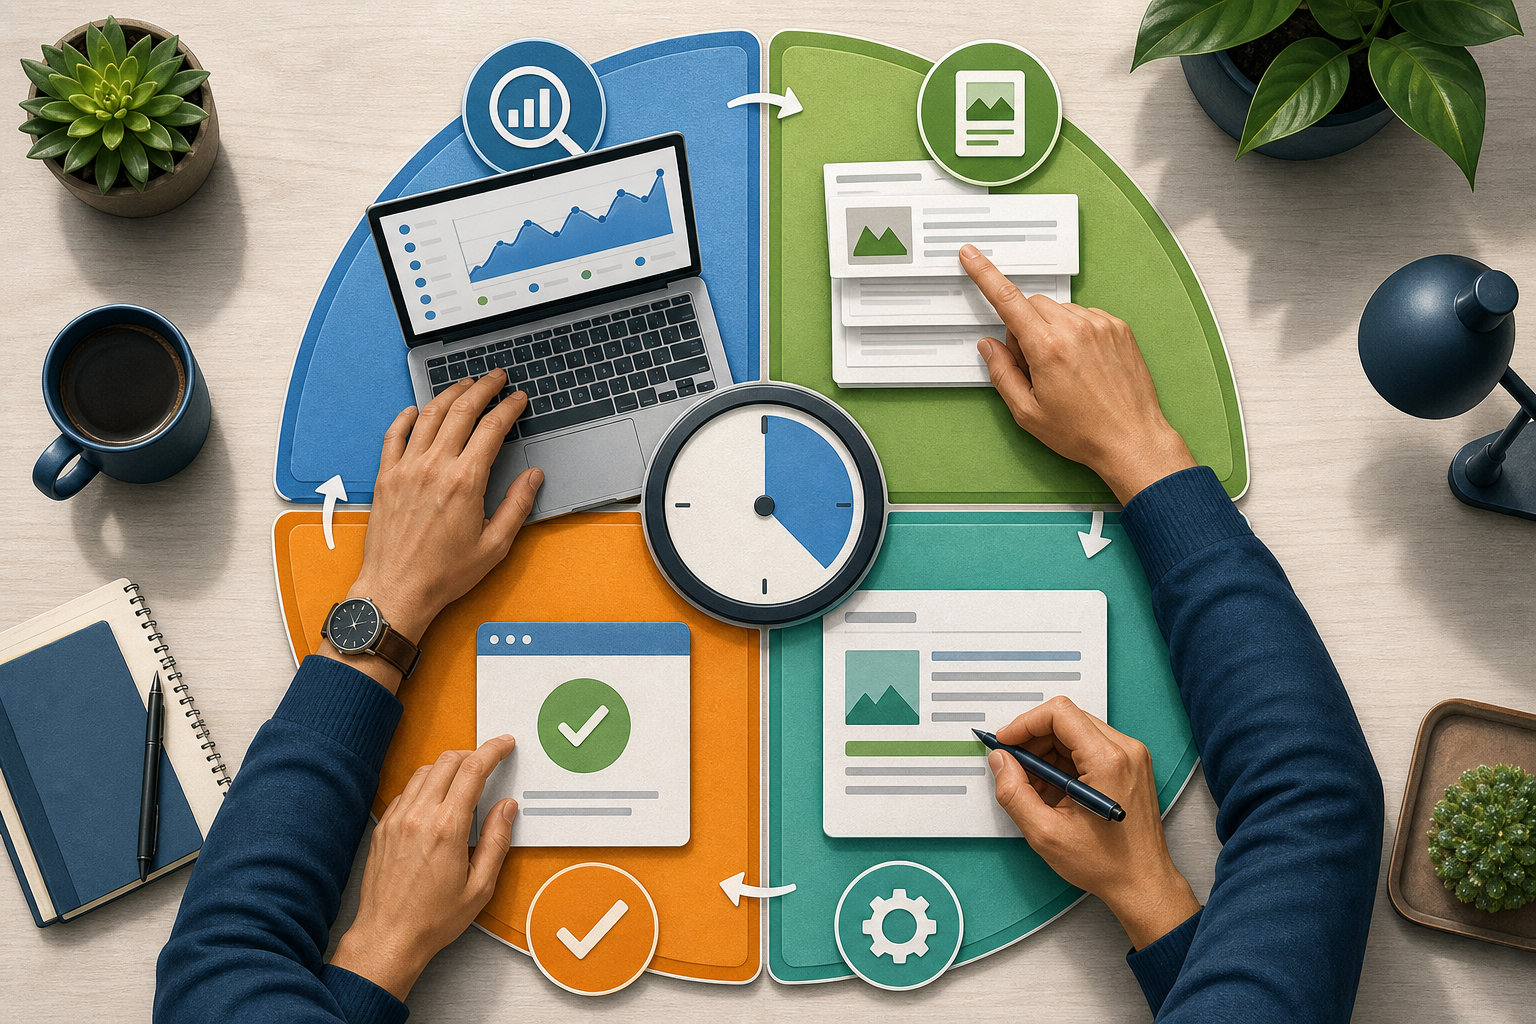
    A top-down desk scene shows four connected stages of an SEO workflow arranged in a circle around a strategist's hands.

    The reported 120-minute workflow addresses a practical constraint: on a lean marketing team, SEO competes with campaigns, reporting, email, social publishing and website requests. Its strongest principle is that a weekly session should finish with work shipped, not merely with more metrics reviewed.

    The first five time boxes below follow the source’s reported schedule. The final 20-minute block is a synthesis of the other sources’ automation guidance, turning the weekly session into a tool-development feedback loop.

    1. Minutes 0-15: inspect Search Console and analytics for meaningful movement, including clicks, impressions, click-through rate, landing-page performance, conversions and critical indexing warnings. Record the largest win, concern and investigation target rather than building a presentation.
    2. Minutes 15-35: identify a small number of query opportunities. The source recommends examining queries in positions 4-15 with meaningful impressions, pages with weak click-through rates and results where the ranking page only partly satisfies intent.
    3. Minutes 35-60: improve one page close to revenue, such as a product, service, category, pricing, comparison or consultation page. The change might address an objection, clarify the audience, add proof, answer a relevant question or make the next action easier to understand.
    4. Minutes 60-80: resolve one consequential technical or indexing problem. If a direct fix is not possible, produce an assigned issue or a developer brief with affected URLs and the expected behavior.
    5. Minutes 80-100: strengthen internal links between useful informational pages and relevant commercial destinations, while also connecting supporting guides and newer strategic content.
    6. Minutes 100-120: verify what changed, document the result and mark one repetitive task as a possible automation candidate. That candidate should enter a backlog rather than becoming an improvised build during the same session.

    The value of this cadence is not the clock alone. It creates a recurring path from signal to decision to change. It also generates concrete automation ideas: a comparison performed every week, a recurring CSV cleanup, a repeated title check or a manual alert that depends on the same thresholds each time.

    Small tools should begin with a bounded decision

    The source on vibe coding describes a low-barrier pattern: specify a program in natural language, run the generated code in an environment such as Google Colab, inspect the output and return errors to the AI for another iteration. It distinguishes this from AI-assisted coding, where a developer remains more directly responsible for the system, and from no-code platforms, which expose automation through visual interfaces.

    The distinction helps set an appropriate ceiling. Vibe coding is presented as suitable for prototypes, internal utilities, demonstrations and tasks where a useful result does not have to be perfect. Commercial software, sensitive systems and products requiring dependable maintenance call for stronger engineering, security and testing practices.

    A reported SEO example makes the right project shape clear. After a site crawl produced vector embeddings, the author prompted an AI to create a Colab tool that would compare vectors with cosine similarity and suggest related pages within each locale. The program had an explicit input, a defined matching rule and a CSV output. It did not attempt to automate an entire SEO strategy.

    Before generating code, a useful tool brief should define:

    • The decision or bottleneck the tool is meant to improve.
    • The exact input source, required columns and accepted file format.
    • The transformation or rule applied to the data.
    • The expected output format and who will use it.
    • A small set of known examples for checking correctness.
    • The behavior when data is absent, duplicated, malformed or unexpectedly large.
    • The APIs, credentials, usage charges and execution environment involved.

    Tool choice can then follow complexity. An LLM may be enough to explore a one-off dataset or review copy. An API becomes useful when manual exports are the bottleneck. A lightweight script suits a stable transformation such as flagging performance changes or checking metadata. A notebook is appropriate when code, commentary and outputs need to remain together. A maintained application is warranted only when the process has durable users, permissions, interfaces and support requirements.

    Validation is part of the workflow, not a final polish

    A compact modular tool moves a web page tile through several visual validation checkpoints while rejected variants remain separated.

    All three sources point toward speed, but they also expose different reasons to retain human control. The new-stack article recommends using LLMs for analysis, content review, competitor comparison, metadata and structured data while keeping editorial and strategic oversight. The weekly workflow keeps prioritization tied to commercial importance. The vibe-coding account shows why plausible-looking output cannot be accepted on appearance alone.

    In one example from the vibe-coding source, an underspecified prompt failed to explain that the input would be a CSV. The generated tool responded with invented URLs, traffic figures and charts. The same source reports that generated code can depend on packages that are not installed, and that paid APIs may introduce authentication steps and usage costs. These are not edge concerns: they demonstrate that execution, factual grounding and operating cost must all be tested separately.

    • Ground the run: identify the authoritative input and reject synthetic substitutes unless test data is explicitly requested.
    • Test a sample: compare several outputs with results that can be checked manually, including an ordinary case and an edge case.
    • Inspect failure behavior: confirm that missing columns, empty files, invalid credentials and API errors produce understandable messages.
    • Protect access: keep credentials out of prompts, shared notebooks, exported files and source code intended for distribution.
    • Track cost: estimate which calls consume paid API units or usage-based platform resources before scheduling repeated runs.
    • Preserve review: require a person to approve consequential content changes, redirects, canonical decisions, schema deployment or other site-wide actions.
    • Document ownership: record the tool’s purpose, dependencies, expected inputs, validation method and person responsible for maintenance.

    A prototype should be promoted into a recurring workflow only after it produces repeatable results on known data. If the logic affects many pages or a revenue-critical system, code review and stronger testing become proportionally more important.

    Key takeaways

    • Keep traditional SEO data, but interpret rankings and search volume alongside result features, traffic opportunity and business outcomes.
    • Time-box reporting so that every weekly SEO session produces a shipped improvement, an assigned fix or a precise implementation brief.
    • Use recurring manual work to discover automation opportunities; do not begin with a tool and search for a problem afterward.
    • Give every small SEO utility explicit inputs, transformation rules, outputs, test cases and failure behavior.
    • Treat LLMs, APIs and scripts as accelerators within a reviewed process, not as substitutes for strategy, factual checks or technical ownership.

    As search interfaces continue to diversify, the durable advantage will come from shortening the distance between a trustworthy signal and a verified improvement. Teams can build that capability incrementally, one weekly decision and one well-scoped tool at a time.

    References

  • Reddit AI Advertising Tools: What Marketers Need to Evaluate

    Reddit AI Advertising Tools: What Marketers Need to Evaluate

    Reddit’s emerging AI advertising stack is designed to turn community conversations into campaign inputs, creative elements and shopping experiences. The important shift is not simply faster ad production: it is the attempt to make advertising reflect the language, interests and product discussions already present on the platform.

    For marketers, the practical question is whether that conversational context can improve relevance without sacrificing accuracy, brand control or measurement discipline. The supplied report outlines a promising toolset, but it also makes clear that several features and their performance evidence remain preliminary.

    Key takeaways

    • Reddit is applying AI to several stages of advertising, including concept generation, community-specific creative, social-proof elements and product discovery.
    • The reported tools draw on a corpus of more than 25 billion posts and comments, giving Reddit a distinctive source of conversational context.
    • The free-form ad generator and tailored creative assets were described as beta products, while Redditor Highlights was reported as generally available and the carousel-style shopping format as a test.
    • Early tests reportedly produced a 130% increase in view-through rates and a 71% increase in video completion rates, but the supplied report does not provide enough methodological detail to treat those figures as universal benchmarks.
    • Advertisers should evaluate relevance, brand safety, authenticity and incremental business results separately rather than assuming that community-informed creative will improve every metric.

    Four advertising jobs within one AI strategy

    The reported releases are best understood as a connected workflow rather than a single AI product. Reddit is using community data at four different points: drafting an ad, adapting it to an audience, adding evidence from users and connecting product discovery to relevant discussions.

    Generating a platform-native starting point

    The free-form ad generator, described as being in beta, combines information from an advertiser’s website with Reddit conversations. Its strategic role is to create a first draft informed by both the brand’s source material and the way related subjects are discussed on Reddit.

    That can reduce the distance between conventional campaign copy and a community’s vocabulary, but generated output still requires human review. A brand remains responsible for verifying product claims, preserving its voice and ensuring that conversational language is not mistaken for permission to imitate users.

    Adapting creative to particular communities

    A second beta capability reportedly identifies relevant communities and produces tailored headlines and visuals. This moves personalization beyond basic audience selection: the creative itself can change according to the context in which it appears.

    The potential benefit is greater message-to-community alignment. The corresponding risk is fragmentation. If each variation uses a different promise or tone, campaign managers may struggle to determine whether performance came from the audience, the creative treatment or another delivery variable.

    Placing community sentiment inside the ad

    Redditor Highlights, reported as generally available, allows advertisers to incorporate Reddit discussions into ads. Unlike AI-generated copy, this feature uses community expression as an explicit credibility layer.

    Its value depends on context. A relevant discussion can help a prospective buyer understand why a product matters, while an isolated or unrepresentative comment could create a distorted impression. Advertisers therefore need to assess whether a highlighted conversation supports the ad’s claim and fairly reflects the surrounding sentiment.

    Connecting product discovery with active discussion

    The report also describes a shopping format being tested in which products appear in a carousel and are matched with ongoing conversations. This treats commerce as an extension of research behavior: a person discussing a need or comparing options can encounter relevant products without leaving the conversational setting.

    That proximity may shorten the path from consideration to product discovery, but relevance is crucial. A technically related product can still feel intrusive if the discussion is informational, sensitive or resistant to commercial participation.

    The strategic opportunity is context, not automation alone

    A marketer selects an advertising concept connected to clusters of community discussions and product interests.

    Many advertising platforms can automate copy or image variations. Reddit’s claimed differentiation is the use of what the report calls Community Intelligence: patterns and sentiment derived from the platform’s conversations. The supplied article says that the underlying corpus exceeds 25 billion posts and comments.

    Scale alone does not guarantee insight. The useful part is the relationship among questions, recommendations, objections and purchase considerations within communities. When interpreted carefully, those signals can help an advertiser identify the language people use, the trade-offs they care about and the information missing from conventional product messaging.

    This makes the tools potentially useful beyond production speed. They can support a feedback loop in which audience research informs creative, campaign responses expose new questions, and those questions shape later messaging. That is a broader application than using generative AI merely to produce more versions of the same advertisement.

    How to read the early performance claims

    The source reports that early machine-learning tests delivered a 130% lift in view-through rates and a 71% increase in video completion rates. These figures are signals worth investigating, not settled expectations for every advertiser.

    The supplied material does not specify the campaign mix, comparison baseline, test duration, sample size or statistical uncertainty behind the results. It also does not establish which tool or model change produced each lift. Because only one source report was supplied, the claims are not independently corroborated within this synthesis.

    View-through and video completion metrics reveal whether people stayed with an ad, but they do not by themselves establish incremental sales, qualified leads or long-term brand effects. A sound test would keep the business objective visible while separating creative engagement from downstream outcomes. Advertisers should compare community-informed creative with an appropriate control, use consistent conversion definitions and examine whether any improvement persists across communities and campaign periods.

    A practical framework for advertiser evaluation

    Three marketers assess campaign prototypes using visual symbols for accuracy, brand safety, relevance and measurement.

    The maturity labels in the report should shape adoption. Generally available functionality can enter normal campaign testing with established controls, while beta and experimental formats warrant narrower pilots, closer review and documented assumptions.

    Creative quality should be judged on more than fluency. Reviewers need to check whether a generated concept is supported by the advertiser’s website, whether it accurately reflects the targeted community and whether its language respects the difference between participating in a conversation and exploiting it. Claims, visuals and cited discussions should also be examined individually; a suitable headline does not make every associated asset suitable.

    Measurement should distinguish three questions. First, did the AI-assisted version improve attention or engagement? Second, did that attention produce a meaningful business result? Third, did the effect come from better creative, a better audience match or the novelty of the format? Treating those as separate questions makes the results more transferable to later campaigns.

    Reddit’s direction suggests that community conversations may increasingly influence both what an ad says and where a product appears. The advertisers most likely to learn from that shift will use the tools as structured hypotheses about audience relevance, then let controlled results determine where automation deserves a larger role.

    References

  • Profound for Slack: What the Integration Could Change

    Profound for Slack: What the Integration Could Change

    Profound’s Slack integration is intended to move parts of the platform’s workflow into the communication environment where teams already coordinate. According to Profound’s announcement, users can ask questions and launch projects from Slack rather than switching platforms.

    The practical value is not simply that Slack gains another application. It is that questions, project initiation, and team discussion could become parts of one continuous workflow. However, the supplied announcement is brief and does not document setup requirements, supported commands, permissions, or administrative controls, so its claims should be treated as Profound’s description of the integration rather than independently verified capabilities.

    What Profound says teams can do from Slack

    Profound describes the integration around two central actions: asking questions and launching projects without leaving Slack. The company also says users can create and manage projects directly from the messaging platform. Taken together, those statements position Slack as an operational entry point to Profound, not merely a destination for automated notifications.

    That distinction matters. A notification-only connection reports activity after it happens elsewhere. An action-oriented integration lets a user begin or influence work from within a conversation. Based on the announcement, Profound is presenting its Slack connection as the latter, although the source does not specify how much project management is available inside Slack or which actions still require Profound’s primary interface.

    The workflow opportunity is shared context

    Three colleagues view connected message, document, task, and AI elements arranged in one shared workflow.

    The clearest potential benefit is a shorter path between discussion and action. Teams frequently use workplace messaging to surface a question, gather input, identify an owner, and decide what should happen next. If a Profound question or project can be initiated at that point, the team may not need to transfer the request manually into a separate workflow before work begins.

    This could also make collaboration more visible. An action initiated from a relevant Slack conversation can remain connected to the language and decisions that prompted it, provided the integration preserves that context. Profound’s post emphasizes smoother collaboration and simpler daily work, but it does not explain whether threads, channel history, attachments, or participant information are carried into a project. Those details will determine whether the integration genuinely preserves context or merely relocates the launch button.

    The integration may be most useful where requests already originate in Slack. In such a workflow, the benefit is not replacing Profound’s full interface. It is reducing the friction between recognizing a need and starting the appropriate work. Teams that conduct little project coordination in Slack may see less value from the same design.

    Key takeaways

    • Profound reports that users can ask questions and launch projects from Slack.
    • The announcement also describes creating and managing projects directly from the messaging platform.
    • The main potential advantage is a more direct transition from team conversation to project action.
    • The source does not provide enough detail to assess setup, permissions, supported actions, data handling, or the depth of project management available in Slack.

    Important questions before a team-wide rollout

    Two administrators review abstract permissions and workflow controls before opening access to a larger team.

    A useful evaluation should begin with workflow fit. Teams should identify which Profound tasks routinely start as Slack conversations and determine whether the integration removes a real handoff. A feature can be convenient without improving the overall process if users must immediately leave Slack to supply missing information or complete the project setup.

    Access and governance also require attention. The supplied source does not say who can install the integration, where its actions are available, how project permissions are applied, or what information passes between the two services. Workspace administrators therefore need product documentation or direct confirmation from the provider before deciding whether the connection meets their organization’s requirements.

    Teams should also clarify the boundary between Slack and Profound. Useful questions include whether project status can be reviewed from Slack, whether existing projects can be managed as well as new ones created, and whether actions work in channels, threads, and direct messages. These are evaluation questions, not capabilities established by the supplied announcement.

    A limited pilot would provide the clearest operational signal. The relevant outcome is whether participants can move from a question or decision to a properly configured Profound project with fewer handoffs, while maintaining ownership and visibility. Adoption alone would not demonstrate that the integration improved the workflow.

    What remains to be demonstrated

    Profound’s announcement establishes the intended direction: bringing questions and project activity closer to team conversation. It does not establish the integration’s technical depth, its administrative model, or measurable productivity gains. With only one short, first-party source supplied, there is no independent account against which to compare the company’s description.

    The integration’s lasting value will depend on whether it connects conversation to accountable work without sacrificing necessary context or controls. Clearer documentation and practical team use should make that boundary easier to judge.

    References

  • Exciting Support for Claude Fable Now in Profound

    Exciting Support for Claude Fable Now in Profound

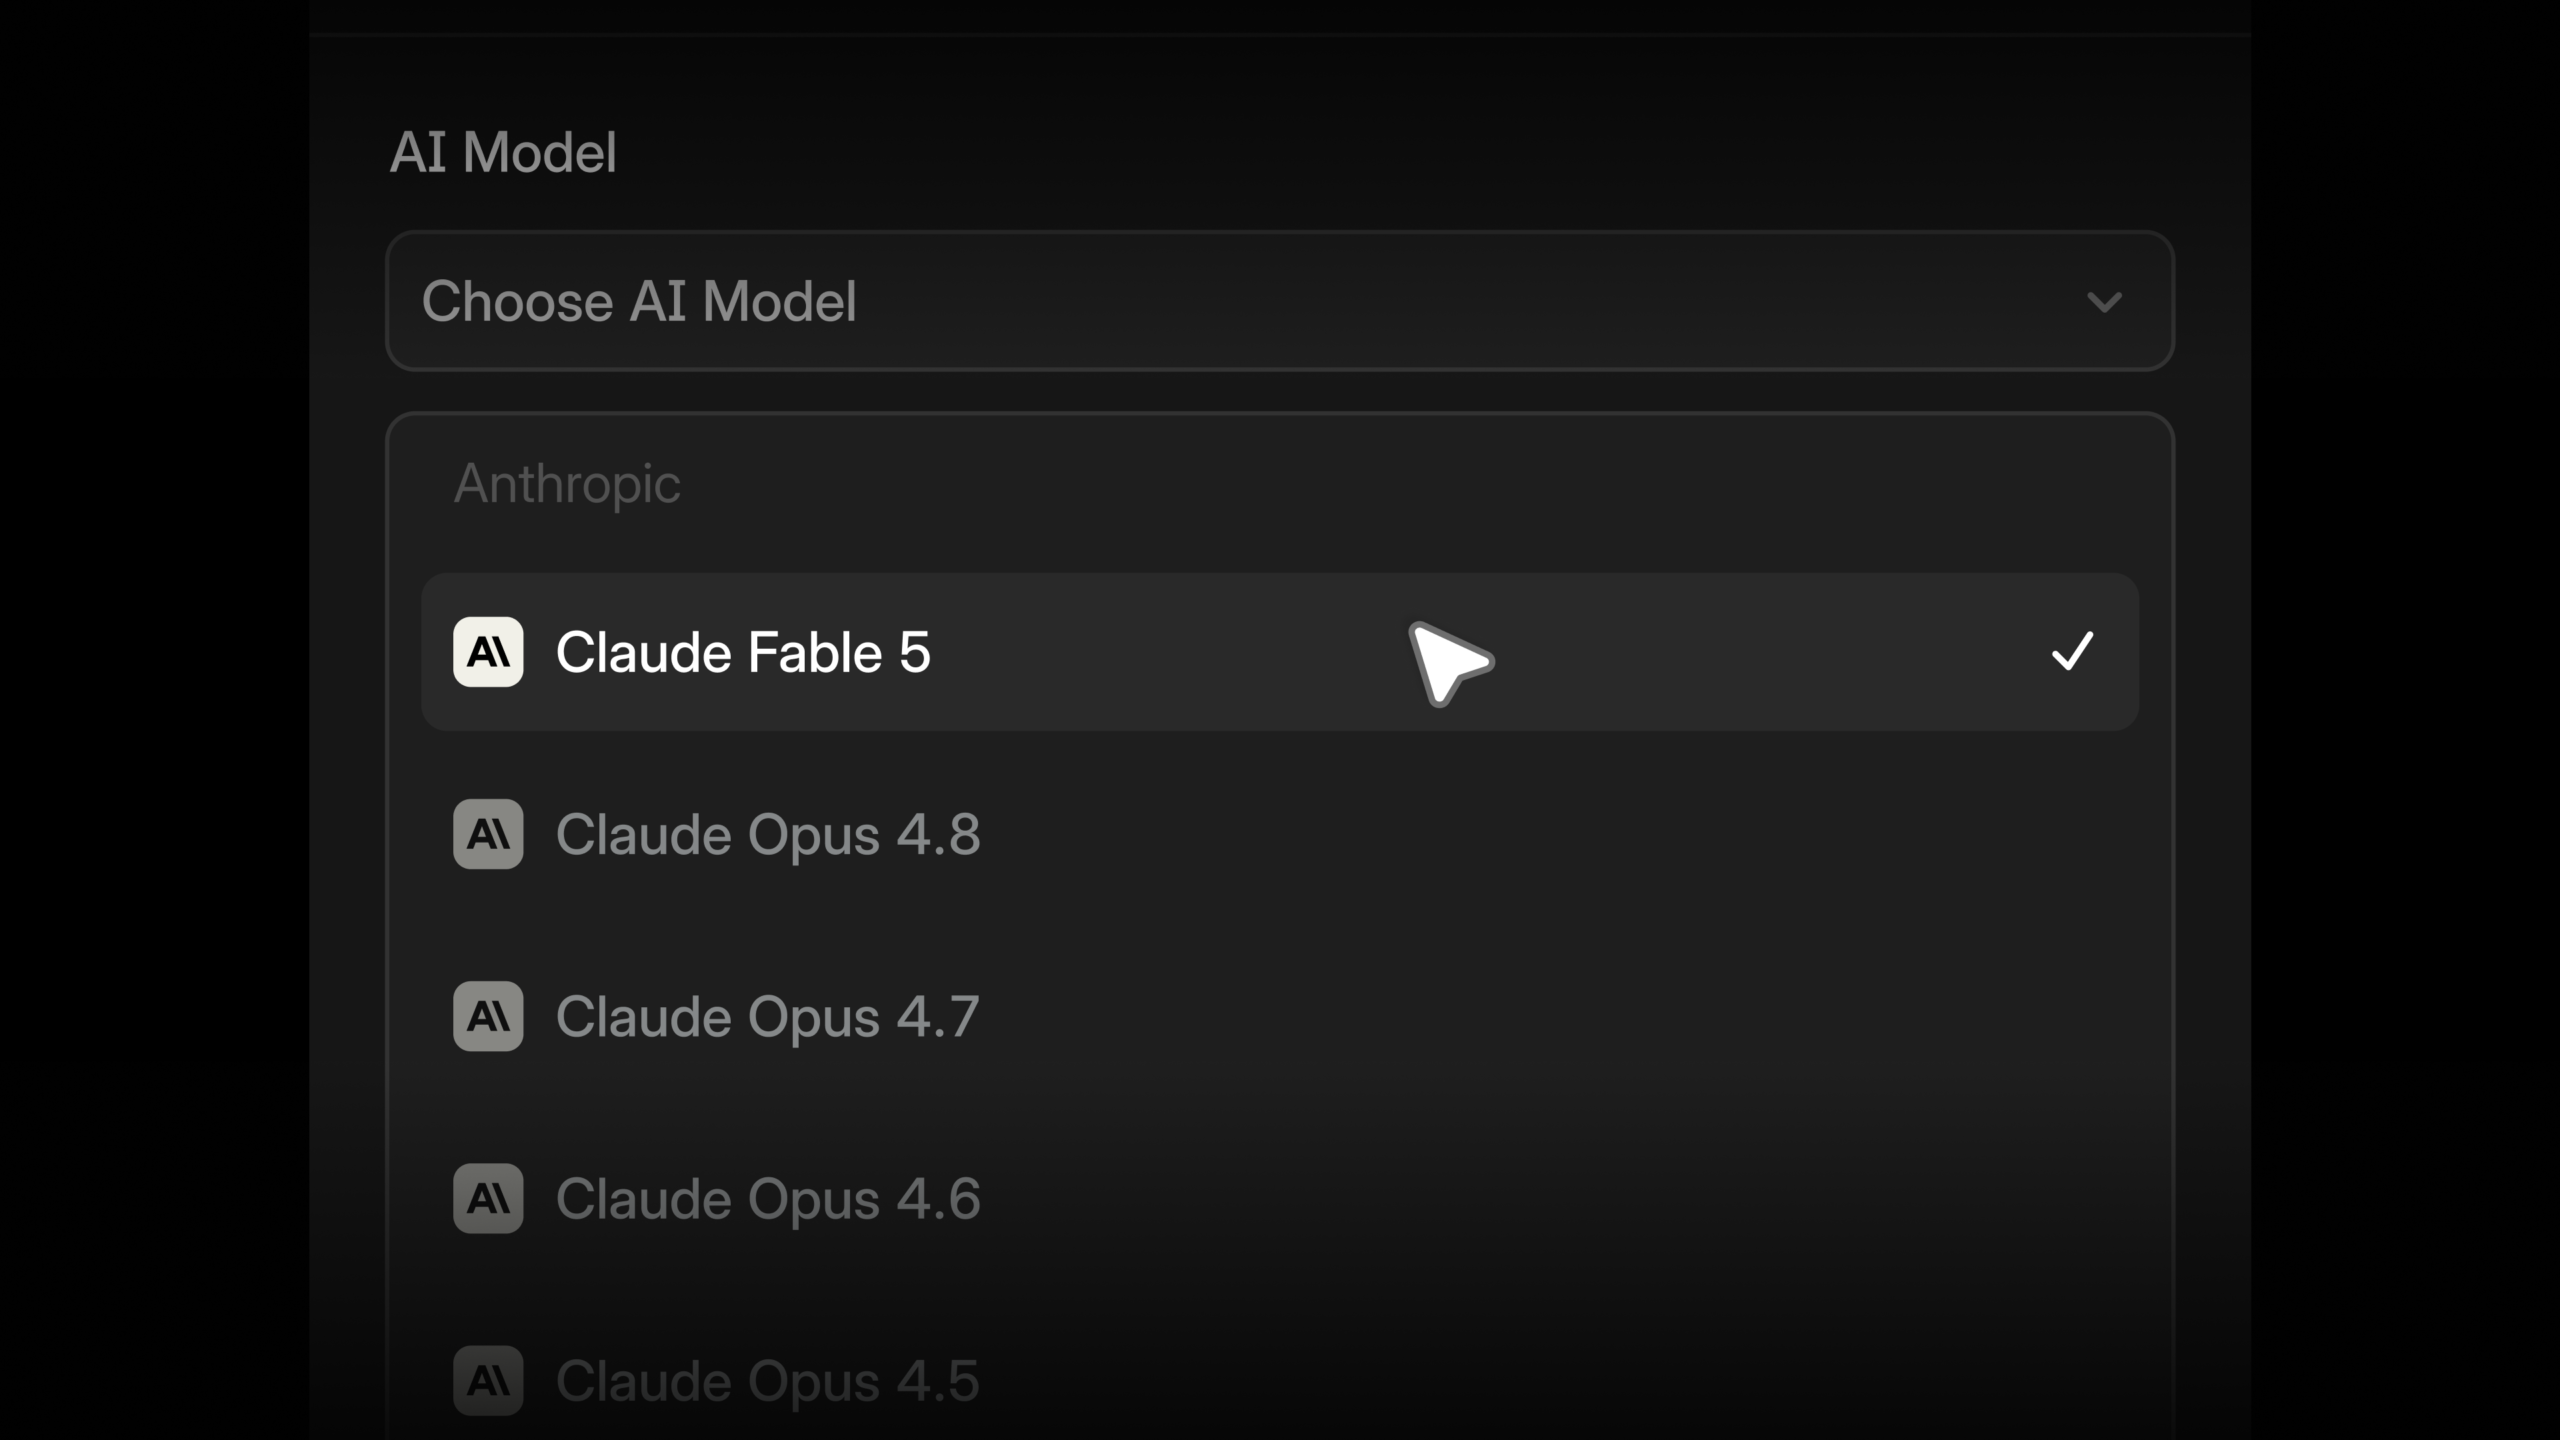
    I’m thrilled to share some fantastic news with you. We’ve just launched support for Claude Fable within Profound, and it’s an upgrade that I’m genuinely excited about.

    Incorporating Claude Fable into our system not only enhances user experience but also brings a new level of efficiency to our platform. This integration is designed to provide seamless functionality and improve overall productivity.

    I’m confident that this addition will greatly benefit all users by offering enhanced capabilities and features that are both intuitive and powerful. Stay tuned for more updates as we continue to innovate and evolve.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot