Tag: AI Marketing

  • AI Marketer Image Generation: A Practical Publishing Workflow

    AI Marketer Image Generation: A Practical Publishing Workflow

    You need a campaign image, but a blank prompt box is not a creative brief. If you ask an AI marketer for something that looks professional without defining the image’s job, you can get a polished asset that is unusable, off-brand, or disconnected from the page it is supposed to support.

    The useful shift is that image generation can now sit inside an AI marketer workflow. That can shorten the distance between an idea and a draft. It does not remove the need for direction, review, accessibility, or measurement. The workflow below turns that faster first draft into an image you can publish with confidence.

    Define the image’s job before describing its appearance

    Start with the placement, not the visual style. A blog hero, a paid social creative, a product illustration, and a supporting diagram may cover the same subject, but they solve different communication problems. The placement determines how much detail the image can carry, where the focal point belongs, whether text will be added later, and what the viewer should understand at a glance.

    Write a short image brief with six decisions:

    1. Placement: Name the exact destination, such as the hero area of a landing page, the opening image for an article, or a paid social placement.
    2. Communication goal: Complete the sentence: After seeing this image, the viewer should understand that…
    3. Audience: Identify who should recognize themselves, their work, or their problem in the scene.
    4. Focal subject: Choose the one element that must remain clear when the image is viewed at its final size.
    5. Brand constraints: Specify the visual characteristics that must stay consistent, including approved colors, level of realism, composition, mood, and any recurring visual motifs.
    6. Exclusions: List what must not appear, especially unsupported product details, invented interfaces, competitor marks, illegible text, visual cliches, or sensitive representations.

    A workable brief is concrete enough to reject the wrong image. For example: Create a wide editorial hero for an article aimed at B2B content leaders. Show one marketer directing an AI-assisted image workflow, with the review step visually prominent. Use a restrained, credible visual language with generous negative space on the left for a headline. Do not include logos, embedded words, dashboards, or futuristic humanoid robots.

    If your brief only contains adjectives such as modern, bold, premium, or innovative, it is not finished. Replace each adjective with a visible choice. Premium might mean restrained color, deliberate lighting, a limited number of objects, and generous negative space. Modern might mean a clean editorial composition rather than neon circuitry. The model can act on visible instructions; it cannot infer your internal definition of taste.

    Generate controlled variations instead of unrelated options
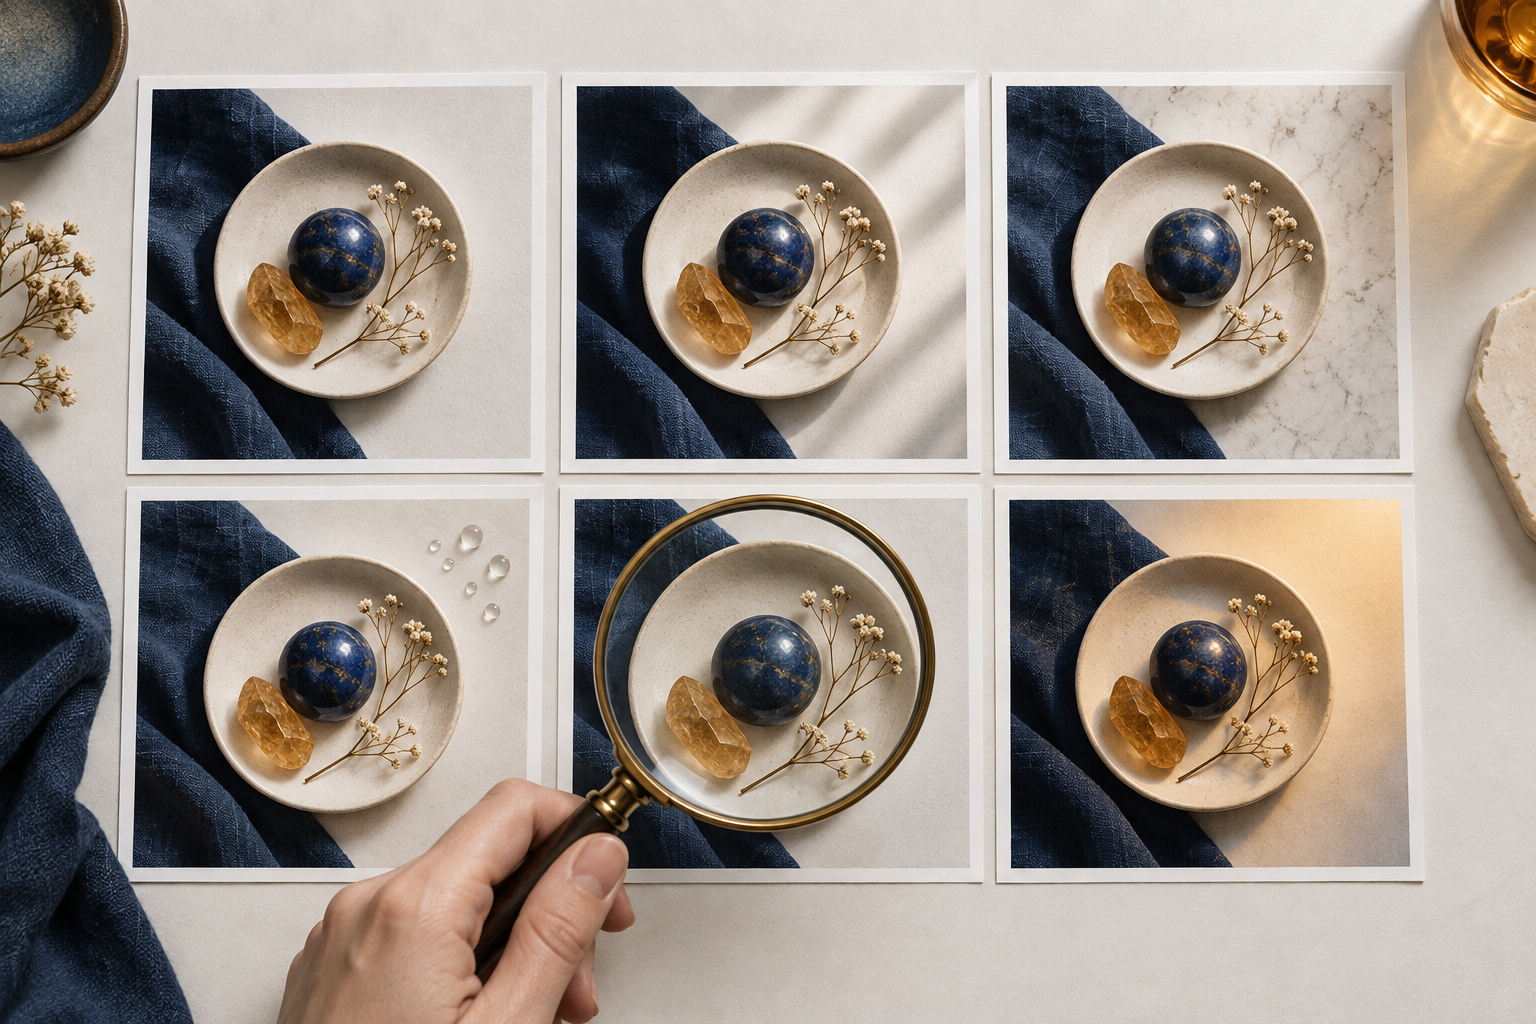
    A hand compares six closely related campaign image variations arranged on a studio table.

    The fastest route to a usable result is not asking for many unrelated concepts. Generate around one approved direction, then vary one decision at a time. This makes feedback precise and prevents the team from restarting the creative conversation with every draft.

    Build the prompt in this order: deliverable, purpose, subject, action, environment, composition, visual treatment, brand constraints, and exclusions. Put the non-negotiable information near the beginning. If the focal subject or empty space matters more than the color palette, say so first.

    • Composition variation: Keep the subject and visual treatment fixed, but test centered, off-center, close, and wide framing.
    • Concept variation: Keep the intended message fixed, but test a literal scene against a simple visual metaphor.
    • Tone variation: Keep the composition fixed, but adjust the level of warmth, energy, realism, or formality.
    • Channel variation: Preserve the concept while adapting the crop and visual density for each destination.

    Evaluate every candidate at the size and crop in which people will encounter it. A detailed scene can look impressive when enlarged and turn into visual noise in a card or mobile feed. The reverse also happens: a simple image may look sparse in isolation but work well once the headline, navigation, and call to action surround it.

    Do not rely on generated pixels for exact copy, product labels, interface text, pricing, or legal language. If wording must be correct, reserve clean space and add the approved text during layout. The same rule applies to a real product interface: use an approved screenshot or a clearly conceptual treatment instead of letting the generator invent controls that customers might mistake for actual functionality.

    Keep a small decision record for the selected asset: the brief, prompt, chosen output, intended placements, edits, reviewer, and approval status. That record gives you a reusable starting point when another channel needs a related image. It also separates approved creative direction from the accidental details of one generation.

    Run a four-part review before the image reaches WordPress
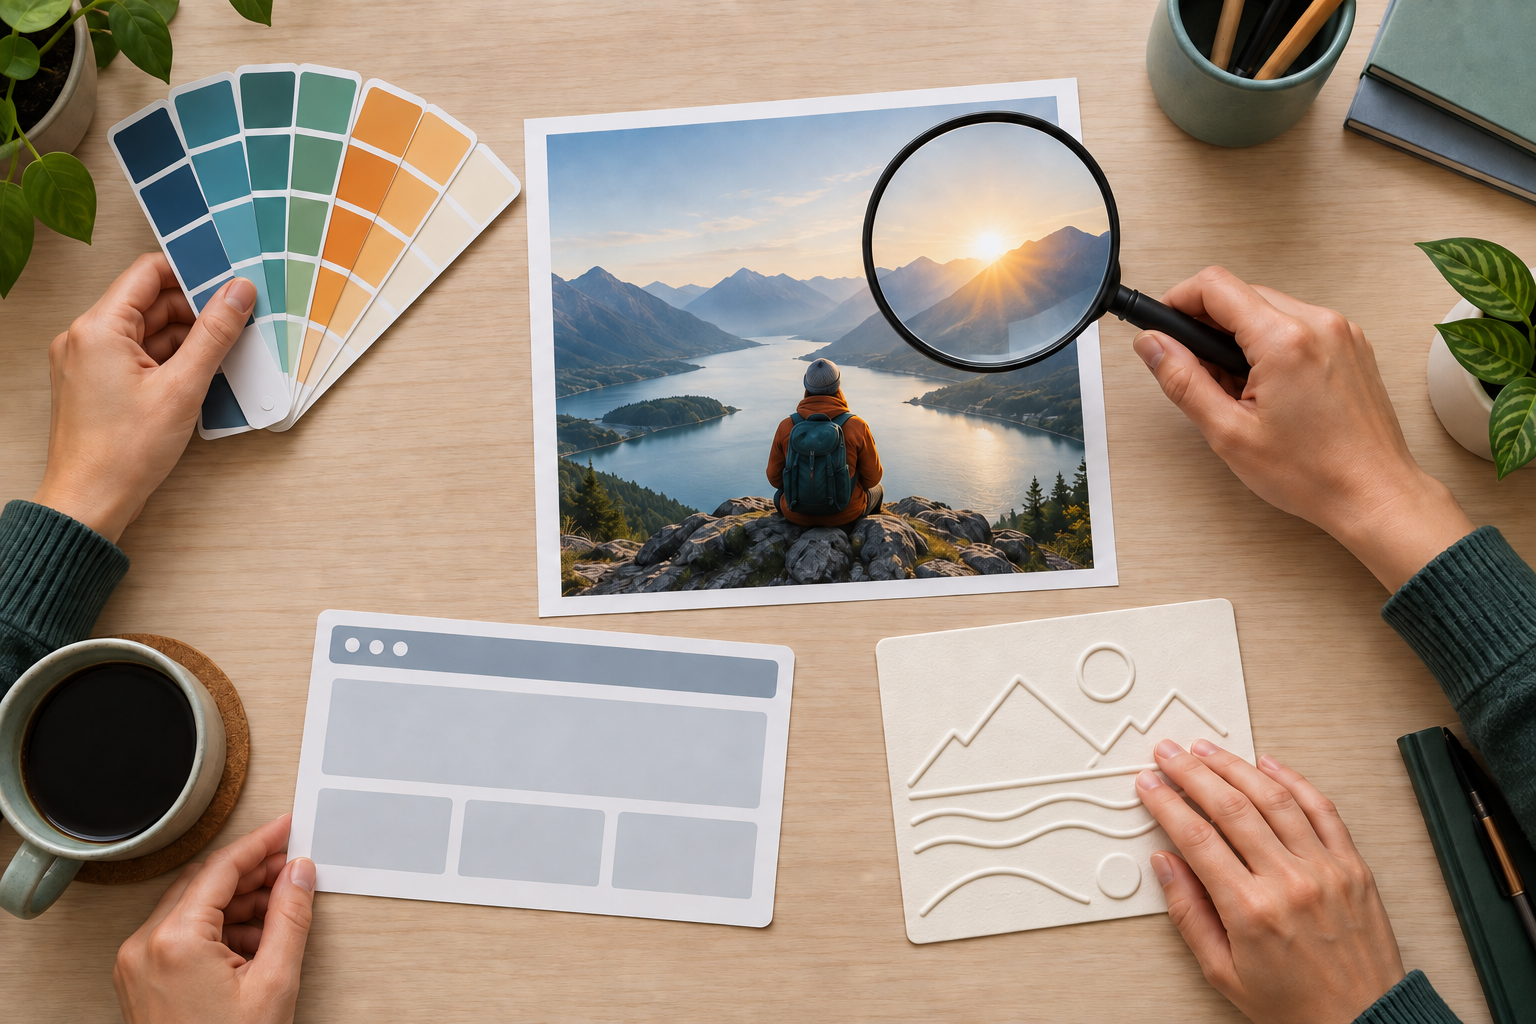
    A campaign image sits at the center of a desk surrounded by tools for checking color, defects, page context, and accessibility.

    Visual appeal is only one approval criterion. Review the candidate through four separate gates so that a striking image does not distract you from a factual, production, or governance problem.

    1. Truth and context

    • Does the image imply a capability, result, customer, partnership, location, event, or product detail that you cannot substantiate?
    • Could a conceptual interface be mistaken for the real product?
    • Are charts, maps, signs, screens, packages, or technical equipment plausible enough to mislead a viewer?
    • Does the representation of people fit the actual audience and context without leaning on a stereotype?

    Treat an unsupported visual claim the same way you would treat unsupported copy. Remove it, replace it with an approved asset, or make the conceptual nature unmistakable.

    2. Brand fit

    • Would the image still feel connected to your brand if the logo were absent?
    • Does its level of polish match the surrounding page rather than overpowering it?
    • Are lighting, color, subject treatment, and visual density consistent with the rest of the campaign?
    • Does it avoid the generic motifs your brand has decided not to use?

    Brand consistency is easier to review when you describe it as repeatable visual constraints. A request to make an image feel more on-brand gives the next operator little guidance. A direction to reduce the palette, remove glowing interface elements, retain natural lighting, and preserve negative space can be repeated.

    3. Production quality

    • Inspect faces, hands, reflections, repeated objects, edges, shadows, and background details at full size.
    • Check every required crop instead of assuming one master image will survive them all.
    • Confirm that overlays remain readable against the image in the final layout.
    • Remove embedded gibberish, accidental marks, and elements that resemble logos.
    • Export an appropriately sized web asset rather than uploading a needlessly heavy working file.

    4. Rights and accountability

    • Verify the image tool’s current usage terms for your intended commercial or editorial context.
    • Do not prompt for a living artist’s signature style or use a real person’s likeness without the permissions your use requires.
    • Retain the generation and approval record where your content team can retrieve it.
    • Follow any disclosure, labeling, or provenance policy that applies to your organization, market, or publishing platform.

    If the image depicts a real person, regulated product, medical situation, financial outcome, or news event, move it out of the routine approval queue. The downside is not merely an awkward visual. A synthetic depiction can create a false factual impression, so use approved documentary material or obtain the appropriate specialist review.

    Publish the image as part of the page’s meaning

    An attractive image does not make a thin page authoritative, and image generation by itself does not create SEO or AI-search visibility. The asset should clarify the same entity, problem, process, or product that the surrounding text explains. If the image and page target different ideas, no metadata can repair the mismatch.

    • Use a descriptive filename: Name the actual subject and function of the image. Avoid camera-roll names, prompt fragments, and keyword strings.
    • Write alt text for purpose: Describe the useful information the image contributes in its page context. Do not begin with image of, repeat the caption, or pack in search terms. If the image is purely decorative, handle it as decorative rather than forcing a redundant description.
    • Keep nearby copy explicit: Introduce the concept in the heading, caption, or paragraph around the image. Do not make readers infer a critical claim from pixels alone.
    • Use a real caption when context is needed: A caption can explain that a visual is conceptual, identify what a diagram shows, or connect an illustration to the point being made.
    • Preserve consistency in structured data: If the page’s JSON-LD identifies an image, use the public URL of the image actually associated with the visible page. Do not invent creator, license, or ownership information merely to fill properties.
    • Check the delivered page: Confirm that the image loads, remains legible on small screens, has not been cropped around the wrong focal point, and does not push the page’s main answer below an oversized hero.

    The practical objective is alignment. The page title, main answer, visible image, alt text, caption, and structured representation should describe the same thing without duplicating one another mechanically. That gives human readers a coherent page and reduces ambiguity for systems trying to interpret it.

    Measure whether the image improved the marketing outcome

    Generation volume is not a performance metric. Neither is the number of minutes removed from the drafting stage if review and rework simply move downstream. Choose the image’s success measure from its job: engagement with an ad, progression from a landing-page hero, comprehension of an explained process, or completion of the action the surrounding content requests.

    When you test an image, hold the headline, offer, audience, placement, and call to action steady. Change one meaningful visual variable, such as human subject versus product detail, literal scene versus diagram, or close crop versus environmental context. If multiple elements change together, the result cannot tell you which decision mattered.

    Pair quantitative performance with a review of failure reasons. Track why generated candidates were rejected: weak message fit, brand mismatch, factual risk, poor crop, unusable text, or production artifacts. A repeated rejection reason is a briefing problem you can fix upstream. It is more actionable than simply asking the model for better images.

    Key takeaways

    • Start with the image’s placement and communication job, not a list of visual adjectives.
    • Generate controlled variations around one approved direction so feedback produces a decision.
    • Add exact wording, product interfaces, and other factual details through an approved production process.
    • Review truth, brand fit, production quality, and rights as separate approval gates.
    • Connect the image to the page with useful alt text, nearby context, consistent metadata, and a working public URL.
    • Judge the asset by the marketing outcome it supports, then use rejection patterns to improve the next brief.

    For your next asset, do not begin by polishing a longer prompt. Write the six-part brief, generate one controlled set of variations, and send only the strongest candidate through the four review gates. That small operating discipline is what turns AI image generation from a novelty into a dependable part of content production.

    References


  • Profound’s Gartner 2026 Recognition: What It Signals

    Profound’s Gartner 2026 Recognition: What It Signals

    If Profound’s Gartner recognition has put the platform on your shortlist, treat that as a reason to investigate, not a reason to buy. The useful question isn’t whether the recognition sounds impressive. It’s whether Profound can help your team turn an AI visibility problem into a specific intervention and then show what changed.

    That distinction matters because AI search programs often become reporting programs. Teams collect mentions, citations, prompts, and competitor comparisons, but the findings never become owned work with measurable consequences. The strongest interpretation of this recognition is that the market is beginning to demand a complete operating loop rather than another dashboard.

    What the Gartner mention does and does not prove

    Profound reports that it was named in Gartner’s 2026 Coolest Vendor Innovations in CRM alongside Canva, Decagon, dx0, and Twenty. That makes the company relevant to a serious evaluation of emerging AI marketing infrastructure.

    It does not, by itself, establish that Profound is the best platform for your organization. A recognition is not a product benchmark, an implementation plan, or proof of business impact in your environment. It doesn’t answer questions about data coverage, workflow fit, measurement quality, integrations, governance, or the effort required to turn a recommendation into a deployed change.

    The claim also comes from Profound’s own account of the recognition. That doesn’t make it unimportant, but it does set the correct evidence standard: use the mention to justify deeper due diligence, then make the product earn its place through your own workflow and data.

    Don’t turn the recognition into an improvised ranking. The named companies address different parts of customer and marketing work, so their appearance together doesn’t mean they are interchangeable competitors. For your decision, the relevant comparison is between Profound and the other ways you could operate your AI visibility program, including internal analysis, specialist tools, agencies, and connected systems.

    Why the insight-to-outcome loop matters in AI visibility

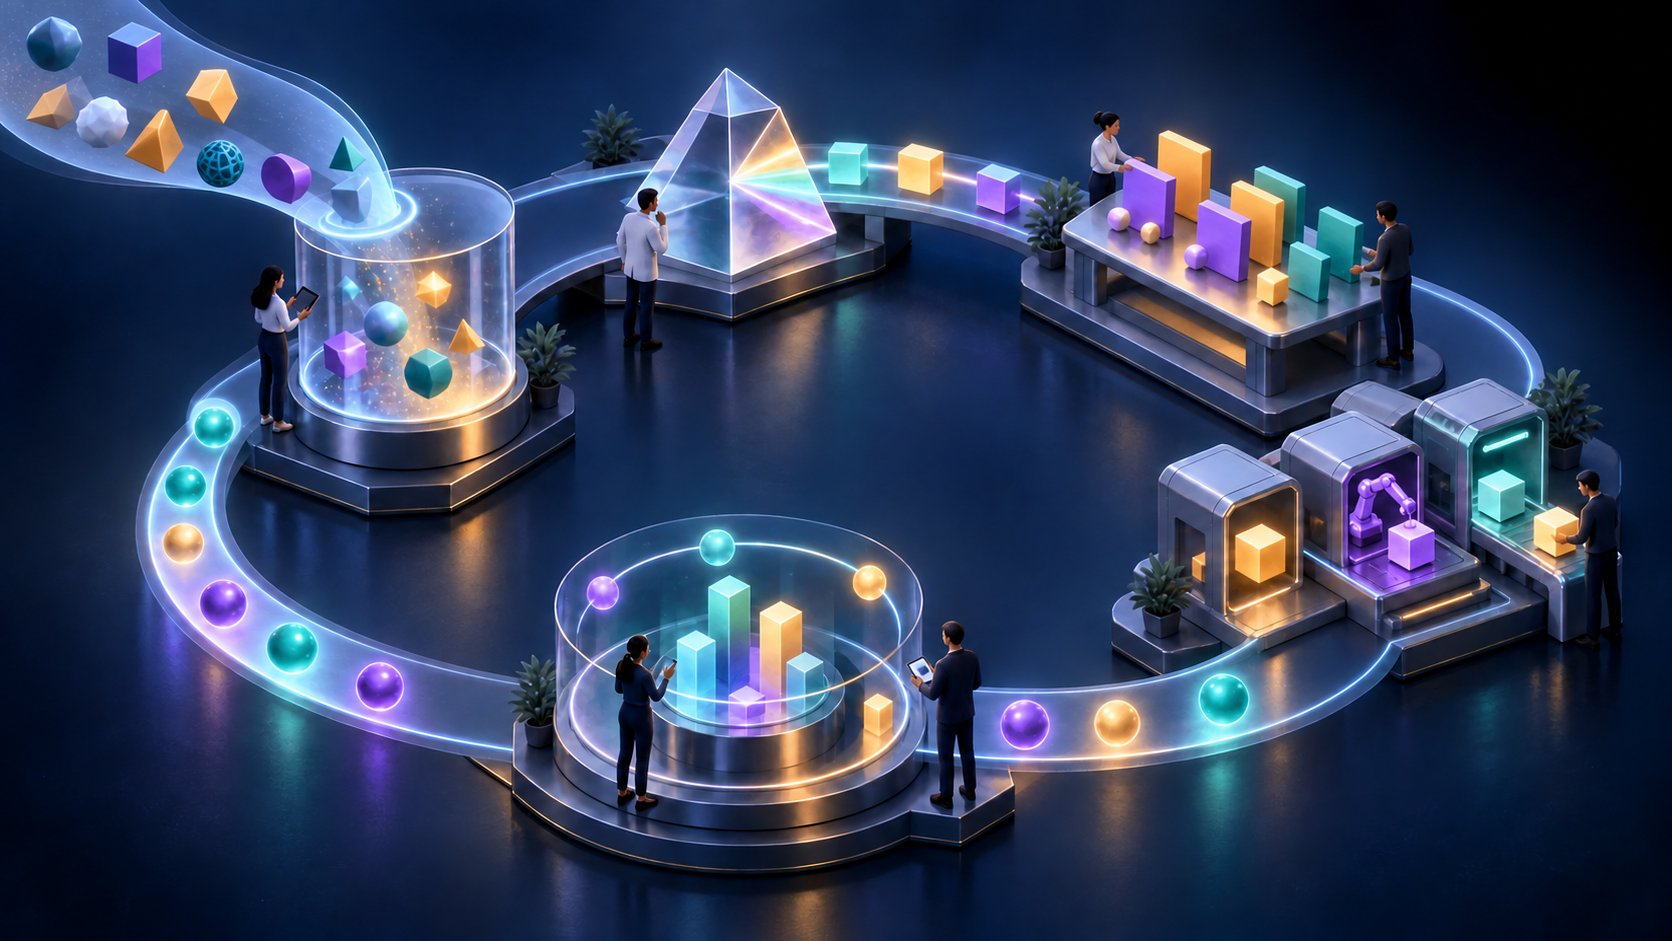
    An isometric circular workflow carries search inputs through analysis, assigned work, production, and measured feedback while team members collaborate at each stage.

    Profound interprets the recognition as evidence that marketers increasingly expect a closed loop from insight to action to measured outcome. That is a vendor-held interpretation, but it gives buyers a much better evaluation standard than feature counting.

    AI visibility work starts with an observation: perhaps a brand is missing from an important answer, a competitor is cited more often, or a product is described inaccurately. None of those observations creates value on its own. Value appears only when the team can diagnose a plausible cause, assign a suitable intervention, publish or distribute the change, and measure the result against a defined baseline.

    StageQuestion your workflow must answerEvidence to request
    InsightWhat exactly is happening, for which queries, audiences, markets, and AI experiences?Saved answer-level observations, timestamps, query definitions, cited domains, and a clear distinction between collected data and inferred explanations.
    ActionWhat should change, where should it change, and who owns the work?A recommendation tied to the original observation, a destination such as a page or entity record, an owner, status, and change history.
    OutcomeDid visibility, representation, referral activity, or a downstream business measure improve after the intervention?A preserved baseline, comparable follow-up observations, deployment dates, and an outcome definition agreed before the work began.

    This framework also prevents a common category error. A suggested content revision, outreach task, or JSON-LD update is an action, not an outcome. Schema markup can make eligible facts easier for machines to interpret when it accurately represents visible content, but merely deploying markup doesn’t prove that an AI system used it or that customer behavior changed.

    The CRM context is useful here. Customer and revenue consequences usually live downstream from visibility data. A credible closed loop therefore needs either native connections or documented handoffs between AI answer monitoring, content operations, technical implementation, analytics, and customer systems. It doesn’t all have to happen inside one platform, but the path between systems must be traceable.

    Run this six-part evaluation before you choose a platform

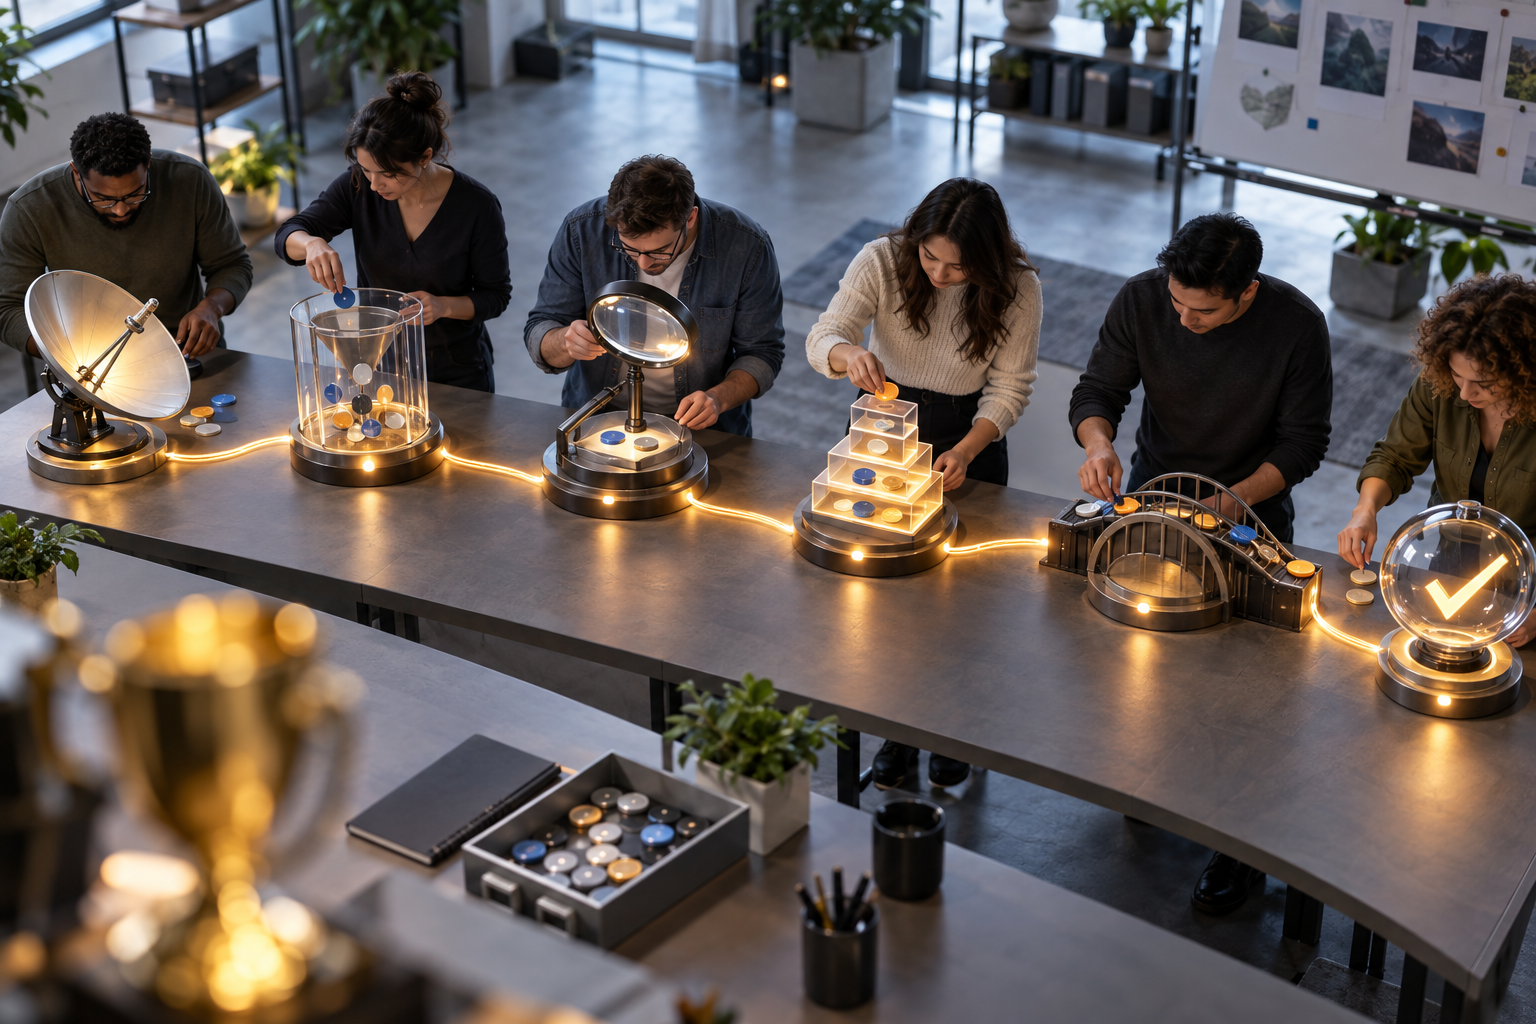
    A cross-functional team tests six connected evaluation stations in a modern workshop while an out-of-focus trophy sits to the side.

    A polished demonstration can hide the hardest operational gaps. Use one real topic from your business and ask the vendor to follow it from observation through measurement. The following test works whether you are assessing Profound or another AI visibility system.

    1. Define your evaluation set before the demonstration. Include branded questions, category questions, comparison questions, and problem-led questions that matter to actual buyers. Specify the markets, languages, products, and AI experiences in scope. This prevents a vendor from selecting only the examples that make its interface look strong.
    2. Inspect the underlying observation. Ask to see the answer captured, when it was captured, the query used, and any citations or brand mentions detected. You need to know which elements are direct observations and which are scores, classifications, or interpretations produced by the platform.
    3. Challenge the diagnosis. Ask why the system believes a particular content, technical, entity, or authority gap caused the observed result. A useful platform should let your team examine the evidence behind a recommendation. Treat unexplained scores and confident causal claims cautiously.
    4. Follow the recommendation into an owned task. Identify who receives it, where the work happens, what approval is required, and how completion is recorded. If staff must copy findings manually into another system, count that labor and the risk of lost context when you compare options.
    5. Agree on the outcome before making the change. Decide whether success means more relevant mentions, more accurate representation, stronger citation presence, qualified referral activity, or a business result recorded downstream. Don’t substitute a platform’s convenient metric for the decision your organization actually cares about.
    6. Repeat the measurement with a change log. Preserve the initial query set and observation dates, record exactly what was deployed, and compare like with like. AI-generated answers can vary, so a single favorable response is weak evidence. Look for a pattern that is meaningful enough to justify the next round of work.

    This evaluation does not require the vendor to promise perfect attribution. In fact, causal humility is a positive sign. Content changes, model behavior, competitor activity, retrieval choices, and outside coverage can all affect an answer. What you need is a system that preserves enough evidence to distinguish a plausible result from a convenient story.

    Watch for the gaps that turn a closed loop into a slogan

    The phrase “closed loop” sounds complete, but several missing links can make it operationally empty. Look for these gaps during procurement and pilot design:

    • Undefined coverage: The platform reports a visibility score without showing which prompts, markets, models, or observation periods produced it.
    • Diagnosis without evidence: It recommends creating or changing content but cannot connect the recommendation to a captured answer, citation pattern, or identifiable information gap.
    • Action without ownership: Findings remain in the dashboard because no person, destination, approval state, or deadline is attached to them.
    • Publishing without verification: A page or schema change is marked complete, but nobody checks whether the intended fact is visible, accurate, indexable, and consistent across relevant brand properties.
    • Measurement without comparability: The follow-up uses different questions, filters, markets, or definitions, making apparent improvement difficult to interpret.
    • Visibility without business context: The team celebrates more mentions without asking whether the brand is represented accurately, appears in relevant buying situations, or influences a meaningful downstream behavior.

    You should also separate platform capability from implementation maturity. A product may support the required workflow while your organization lacks owners, publishing access, analytics connections, or an agreed measurement model. Buying more software will not repair those operating gaps. Document them before procurement so that platform limitations and internal limitations don’t get confused.

    Key takeaways

    • Profound’s Gartner 2026 recognition is a credible reason to include the company in an evaluation, not proof that it fits your stack or will improve your results.
    • The most useful signal is the emphasis on connecting insight, action, and outcome. Test that complete path rather than comparing dashboard features in isolation.
    • Use a real business topic during the demonstration and require answer-level evidence, an owned action, a deployment record, and a comparable follow-up measurement.
    • Define success before the pilot. Mentions, citations, representation accuracy, referral activity, and business outcomes answer different questions.
    • A closed loop can span several systems. What matters is preserved context, clear ownership, and a traceable line from observation to consequence.

    Make the next step a workflow test, not a prestige vote

    Choose one commercially important topic cluster and map its complete path: the questions people ask, the answers you can observe, the evidence behind any diagnosis, the person who can make a change, and the outcome you will examine afterward. Then ask Profound to demonstrate that path using your definitions rather than a prepared success case.

    If the workflow remains traceable from observation to consequence, the recognition has helped you discover a platform worth piloting. If the trail disappears between dashboard insight and business action, the Gartner mention should not carry the decision. Your next move is to test the loop.

    References

  • Profound’s $180M Funding: What Marketing Teams Should Test

    Profound’s $180M Funding: What Marketing Teams Should Test

    If you are deciding whether Profound’s funding makes its platform a safer strategic bet, separate two questions immediately: Does the company have more capacity to pursue its vision, and can the product remove work from your marketing operation? The first is supported by the raise. The second still requires proof inside a workflow that matters to you.

    That distinction will keep a large funding number from becoming a substitute for product, governance, and commercial due diligence. It also gives you a practical way to evaluate AI Marketer without either dismissing the platform or buying the story before testing the system.

    What Profound has actually committed to

    Profound has raised $180 million to build an AI platform for marketing. Its stated premise is that AI is generating additional work for marketers, not simply automating existing tasks. AI Marketer is positioned as the response: a system that brings company context and agents together so marketing teams can get that work done.

    Those points establish capital, direction, and a product thesis. They do not establish the return a customer will receive. A funding total cannot tell you whether the platform fits your data, integrates with your operating stack, produces reliable outputs, shortens approval cycles, or reduces the total cost of a workflow.

    The stated goal also indicates a broad platform ambition rather than a single-purpose feature. That can be valuable when your work crosses research, analysis, content, brand governance, and execution. It can also increase implementation scope. The more jobs a platform is expected to coordinate, the more important permissions, source quality, handoffs, and ownership become.

    Use the announcement as a reason to ask better questions, not as the answer to them. Do not add unconfirmed details about valuation, investors, product allocation, delivery dates, or business performance to your internal brief. If one of those details affects your decision, request it directly and distinguish a written commitment from a forward-looking plan.

    Why more AI can create more marketing work

    A marketing team sorts and reviews a growing flow of campaign materials produced by several automated machines.

    AI reduces the cost of producing an output, but output generation is only one part of marketing. Every new model, answer surface, automated campaign, and content variant can create additional monitoring, interpretation, validation, approval, and measurement work. Faster production can therefore move the constraint downstream rather than remove it.

    You can see that effect by mapping the full chain around an AI-assisted task:

    • Inputs: Someone must select the relevant brand rules, product facts, audience assumptions, performance data, and prior decisions.
    • Generation: A model or agent produces an analysis, recommendation, brief, campaign asset, or other deliverable.
    • Verification: A person checks factual accuracy, source quality, brand fit, compliance, and whether the output answers the original question.
    • Execution: The approved output must reach the correct channel, owner, or system without losing its context.
    • Learning: Results must return to the process so that the next action reflects what changed.

    A platform can make generation faster while leaving every other stage intact. It can even increase review work if it produces more material than your team can verify. That is why prompts completed, agents deployed, and assets generated are weak measures of operating value on their own.

    Before watching a demonstration, draw one real workflow from request to approved outcome. Mark every system, human handoff, approval, wait state, and rework loop. Record the elapsed time, active working time, and recurring errors using evidence you already have. You now have a baseline against which automation can be judged.

    If your remit includes AI search visibility or generative engine optimization, a suitable workflow might begin with a visibility finding and end with an approved content or entity-data change. The test should include the analysis, supporting evidence, assignment, revision, publication approval, and follow-up measurement. Automating only the first step does not automate the workflow.

    What company context and agents must prove

    The combination of company context and agents is the central idea behind AI Marketer’s positioning. Those terms can sound complete while hiding the hardest implementation questions. Treat them as two systems to test separately.

    Test context as a governed source of truth

    Company context should do more than place files near a model. It should help the system select current, authorized information and show you what influenced an output. Ask for a live demonstration that answers these questions:

    • Which repositories, pages, records, and instructions can the system use for this task?
    • How does it decide which source is authoritative when two sources conflict?
    • How quickly does a changed product fact, policy, or brand rule become available?
    • Can access be limited by team, role, market, client, or workspace?
    • Can a reviewer trace an output back to the facts and instructions that shaped it?
    • What happens when the required evidence is missing, stale, or ambiguous?

    Do not test this with a polished sample library. Bring a controlled set of realistic material that includes one outdated item, one conflict, and one fact the system should not expose to every user. Designate the correct source in advance. A useful context layer should handle the conflict predictably, respect access boundaries, and make its reasoning inspectable enough for a reviewer to catch a mistake.

    Test agents as bounded operators

    An agent is valuable when it can advance work without gaining more authority than the task requires. Evaluate its operating boundaries, not only the quality of its final output:

    • What triggers the agent, and who can change that trigger?
    • Which data can it read, and which systems can it alter?
    • Which steps require human approval before the agent proceeds?
    • Can you stop a run immediately and prevent it from retrying?
    • Does the audit history preserve inputs, actions, outputs, approvals, and failures?
    • How does the agent behave when a dependency is unavailable or the evidence is inconclusive?
    • Can its work be exported, reassigned, or completed manually?

    Run the same task after changing a canonical input, revoking a permission, and withholding a required fact. You are looking for controlled behavior: the output should update when the approved context changes, access should disappear when permission is removed, and the agent should stop or escalate when it cannot support an answer.

    Do not grant autonomous publishing or campaign-changing permissions merely to make a pilot look complete. An opaque error can create public misinformation, brand damage, or avoidable spend. Start with read access, draft outputs, explicit approval gates, and a visible audit trail. Expand authority only after the failure behavior is understood.

    Turn the funding story into a procurement test

    A cross-functional team evaluates an AI agent in a transparent test chamber using visual checkpoints for quality, security, time savings, and commercial value.

    New capital can support product development, infrastructure, implementation, hiring, or market expansion, but the amount alone does not tell you which customer outcomes will improve. Ask Profound to connect its funded platform direction to the operating requirements in your evaluation.

    Use a short, evidence-based process:

    1. Separate product from roadmap. Mark every required capability as available, configurable, dependent on services, planned, or unsupported. Ask for written confirmation of anything that affects the purchase.
    2. Select one costly workflow. Choose a process with a clear owner, recurring inputs, an observable outcome, and enough friction to justify change. Do not begin with a broad goal such as improving marketing productivity.
    3. Run your material through the system. Use representative company context, normal approval requirements, and the systems the production workflow would need. A vendor-curated example cannot expose your integration or governance problems.
    4. Measure total work. Compare active effort, waiting, handoffs, corrections, and review demand with the baseline. Count work displaced to administrators, analysts, agencies, or implementation teams.
    5. Test failure and exit paths. Introduce stale context, a conflicting instruction, a denied permission, and an unavailable dependency. Then verify how you export outputs, retrieve records, remove data, and continue the workflow if the platform is unavailable.

    A pass-or-fail scorecard keeps the evaluation focused when a demonstration is visually impressive:

    DimensionEvidence to requestReason to pause
    Workflow valueA proof run showing less total effort, delay, or reworkThe claimed value depends mainly on future features
    Context integritySource traceability, conflict handling, freshness controls, and scoped accessThe system cannot explain which facts governed an output
    Agent controlLeast-privilege permissions, approvals, stop controls, and audit historyAgents require broad access or take opaque actions
    Operational fitWorking integrations, clear ownership, administration, and support pathsManual bridges recreate the work you intended to remove
    Commercial durabilityWritten terms for current capabilities, service levels, support, and pricingThe funding total is used in place of contractual commitments
    Exit safetyDocumented export, deletion, access removal, and offboarding proceduresYour data or workflow history cannot leave cleanly

    Funding matters most where it changes the risk of relying on the platform. Ask which capabilities exist now, which dependencies require professional services or third-party systems, what support is included, and how roadmap changes are communicated. For every answer, identify the proof: a live control, a technical document, a contractual term, or merely an intention.

    Data handling deserves the same precision. Confirm what information the system stores, where it is processed, who can access it, how long it is retained, whether it is used to improve models, and how deletion is verified. If your marketing context contains customer, partner, employee, or confidential product information, involve the people responsible for security, privacy, and legal review before production access is granted.

    Key takeaways

    • Profound’s $180 million raise supports its ability to pursue an AI platform for marketing, but it does not prove customer outcomes.
    • AI can create work after generation, especially in verification, approval, execution, governance, and measurement. Evaluate the whole workflow.
    • Company context must demonstrate source authority, freshness, traceability, conflict handling, and permission boundaries.
    • Agents must demonstrate limited authority, approval controls, predictable failure behavior, auditability, and a safe manual path.
    • Your decision should depend on production-like evidence and written commitments, not funding momentum or a curated demonstration.

    For your next step, take one workflow into the evaluation meeting and bring its real inputs, permissions, exceptions, and approval rules. Ask Profound to show what AI Marketer does at each stage, what remains human work, and which capabilities are available now.

    A platform is worth adopting when it reduces the total burden of producing a trustworthy marketing outcome while preserving control. The funding gives Profound room to pursue that standard. Your proof run should determine whether the product meets it for you.

    References

  • AI Marketing Agent Safety: A Practical Oversight Framework

    AI Marketing Agent Safety: A Practical Oversight Framework

    Your marketing agent can draft a campaign, diagnose performance, or prepare a site update. The risk changes the moment it can spend money, suppress traffic, publish claims, email customers, or overwrite a working configuration.

    You don’t need a binary verdict on whether the model is trustworthy. You need an operating system around it: complete enough context, narrowly scoped permissions, enforceable policies, approval before consequential actions, and a record that lets you reconstruct what happened.

    Replace abstract trust with three control questions

    The safer question is not whether you trust an AI model in the abstract. Ask what the agent can see, what it is structurally allowed to do, and who must approve its work before production. Those questions turn trust into controls you can inspect and test.

    1. What can it see? List every account, dataset, field, date range, customer-data class, and external tool available to the agent. Record important gaps as carefully as available data.
    2. What can it do? Separate reading, analysis, drafting, recommendation, and execution. A prompt describing what the agent should do is not a permission boundary.
    3. Who signs off? Name the role that must approve each protected action. Reviewing a change log afterward is auditing, not approval.

    Use those answers to assign every workflow an operating mode. Do not give an entire agent one blanket risk label; the same agent may be safe to query campaign data and unsafe to change a budget.

    Operating modeWhat the agent may doMinimum control
    ObserveRead approved data and explain findingsNo production write credential; disclose data scope and gaps
    ProposePrepare copy, settings, or recommended changesPolicy validation; no direct route from proposal to production
    Limited executionCreate drafts, apply labels, or act inside a designated sandboxNamed resources, hard action limits, result verification, and a tested recovery path
    Protected executionChange spend, bids, targeting, negative keywords, live content, customer communications, access, or destructive settingsExplicit approval for the exact change before execution

    Reversible does not necessarily mean low risk. You can unpause a campaign, but you cannot recover traffic and opportunities lost while it was paused. You can restore a previous page version, but not necessarily retract a claim already seen by customers or answer engines. Classify risk by consequence and exposure, not merely by whether the interface has an Undo button.

    Scope each permission across several dimensions:

    • Environment: sandbox, draft workspace, or production.
    • Identity: the brands, business units, clients, and accounts included.
    • Resource: campaigns, pages, audiences, feeds, schemas, or customer records.
    • Action: read, create, edit, publish, pause, archive, or delete.
    • Magnitude: the amount of spend, number of entities, or audience size the action can affect under your existing internal limits.
    • Time: when permission begins, when it expires, and whether approval can be reused.

    The resulting permission register should be readable by marketing, security, and the workflow owner. If nobody can state an agent’s maximum possible action without opening its prompt, the boundary is not yet clear enough.

    Ground the agent before you evaluate its reasoning

    A fluent answer can still be built on an incomplete account view. The model may not know that a missing dataset contains the decisive explanation, so its tone will not reliably reveal the gap. Treat grounding as a safety control that reduces confidently wrong diagnoses, not as an optional convenience.

    Write a grounding contract

    A grounding contract defines the context a workflow requires before the agent may answer or act. It should record:

    • The systems, accounts, entities, fields, and historical periods the agent can access.
    • Excluded or inaccessible systems that could materially change the conclusion.
    • Data freshness, timezone, attribution settings, and the time of the last successful refresh.
    • The identifiers used to join advertising, analytics, CRM, commerce, and content data.
    • Which connectors are read-only and which can write.
    • What the workflow must do when a query fails, a join is ambiguous, or required context is stale.

    For a Google Ads agent, a strong PPC grounding baseline extends well beyond a packaged performance summary:

    • Full Google Ads query access through GAQL for the resources, fields, segments, and metrics needed by the question.
    • GA4 data alongside ad data when the diagnosis depends on what happened after the click.
    • Complete change history across interface edits, scripts, agents, and other connected tools.
    • Negative keywords assembled across account-level negatives, shared lists, campaigns, and ad groups, including a deterministic check of whether a query is already blocked.
    • Auction Insights and an inspectable view of the keywords shared with a competitor when making competitive claims.
    • Relevant vertical benchmarks whose cohort and calculation are visible, rather than an unexplained generic average.

    The same principle applies outside paid search. A content agent diagnosing lost visibility needs the relevant page versions, publication history, analytics context, and technical state. A schema agent needs the live markup and the page content it describes. A lead-nurture agent needs the current consent and suppression state available to the workflow. The exact systems differ; the requirement to expose material gaps does not.

    Make missing context part of every answer

    Require an input manifest with each recommendation. It should list the datasets queried, account and entity IDs, date ranges, filters, refresh times, failed queries, and inaccessible dependencies. When required context is absent, the agent should return an incomplete-data state instead of filling the gap with a causal story.

    This also improves review. The approver can challenge the evidence itself instead of judging polished prose with no way to see what sits underneath it.

    Enforce policy outside the model

    An abstract AI core is surrounded by separate layers of permissions, rule gates, rate controls, and a locked execution chamber that block risky actions.

    A system prompt can explain policy, but it should not be the component that enforces policy. Instructions can be misunderstood, displaced by conflicting context, or applied inconsistently. A control implemented in credentials, an action gateway, or workflow code can refuse an operation regardless of the text the model produces.

    A practical enforcement path has four parts:

    1. Separate agent identity. Give the agent its own credentials so its activity is distinguishable from a person’s work.
    2. Least-privilege access. Where the platform supports granular scopes, issue only the read and write capabilities required for the approved workflow.
    3. Action gateway. Route every proposed write through one controlled service rather than allowing the model to call production tools directly.
    4. Workflow states. Move work through proposed, validated, approved, executed, and verified states. Do not let the model skip a state.

    The policy layer should inspect the actual operation, not merely the agent’s description of it. Evaluate the destination account, object IDs, current values, proposed values, batch size, credential, policy version, and approval record before the write is sent.

    Start with rules you can test

    • Deny production writes by default and allow only named actions on named resources.
    • Treat drafting and publishing as different permissions.
    • Protect changes to budgets, bidding, targeting, conversion definitions, negative keywords, customer-facing messages, user access, and billing behind the appropriate internal approver.
    • Set an internal maximum for entities affected in one execution. A request above that limit must be split or separately approved.
    • Block execution when required data is unavailable, stale under your policy, or inconsistent across systems.
    • Prefer drafts and archives to deletion. If deletion is required, identify what cannot be restored before approval.
    • Fail closed when the policy service or approval store is unavailable. An outage in the safety layer must not silently become permission to proceed.
    • Log blocked attempts and policy exceptions as well as successful actions.

    Use your organization’s existing budget authority and publishing ownership to set thresholds. A generic dollar limit copied from another company cannot express your margins, account size, customer commitments, or tolerance for interruption.

    Test the boundary, not just the happy path

    Before granting production access, deliberately submit requests that should fail:

    • A valid action aimed at the wrong client or brand.
    • A batch larger than the configured action limit.
    • A protected change with no approval.
    • A request based on missing or stale required data.
    • A connected document containing instructions that conflict with the workflow policy.
    • A proposal altered after approval.
    • An execution in which the platform accepts some changes and rejects others.

    For every test, verify the operation was blocked or contained, the event was recorded, and the right owner was notified. If success depends on the model deciding to behave, the test has exposed a prompt preference rather than a hard control.

    Make human approval an exact, usable decision

    A campaign operator reviews a website publication package, audience envelope, spending token, and rollback component before choosing between separate approval and rejection controls.

    Human approval is valuable only when it happens before the consequential action and gives the reviewer enough evidence to make a decision. Grounding makes proposals more useful to review, while policy filtering removes obvious non-starters before they reach the queue. That combination keeps human attention focused on judgment rather than basic cleanup.

    Build a proposal packet, not a chat transcript

    Every approval request should contain:

    • The exact account, campaign, page, audience, feed, schema, or record affected.
    • A before-and-after representation of every proposed value.
    • The business reason for the change and the evidence used, with its date range and refresh time.
    • The expected effect, known uncertainty, and any plausible downside.
    • The policies evaluated, including passes, blocks, warnings, and requested exceptions.
    • The total number of entities and the maximum spend, reach, or publication surface exposed under the proposal.
    • The recovery procedure, including anything that cannot be reversed.
    • The person or role responsible for approval and the time at which that approval expires.

    Show this information in the marketing system reviewers already understand when possible. A technically complete payload is not enough if the person accountable for the campaign cannot see the practical effect.

    Bind approval to the exact proposal version, destination IDs, and values. If the agent edits the proposal, the underlying account state changes, or the approval expires, require validation and approval again. Never treat approval of an idea as standing permission for whatever implementation the agent later chooses.

    Verify the write and prepare for partial failure

    1. Recheck the destination, current state, data freshness, policy version, and approval immediately before execution.
    2. Apply only the approved delta. Do not let execution broaden into related cleanup that was absent from the proposal.
    3. Read the affected resources back from the platform and compare them with the approved values.
    4. Record the request, approval, actor, platform response, successful entities, failed entities, and verification result.
    5. If only part of a batch succeeds, stop the remaining work and send the exact partial state to the owner. Do not improvise a rollback whose consequences have not been reviewed.

    A rollback plan should be tested against the real platform before you rely on it. Some operations can be restored from a known previous value; others create exposure that restoration cannot undo. Keep a kill switch that can revoke the agent’s write path independently of the model and document who is authorized to use it.

    Monitor adoption, safety, and outcomes separately

    A central view is useful because unregistered agents become invisible operational dependencies. At minimum, maintain an agent registry with the owner, purpose, connected systems, permissions, policy set, approver, current status, and kill-switch owner for each workflow.

    Management dashboards can help expose usage patterns. For example, one vendor describes a command center that shows how teams use marketing agents, the hours their work returns, and adoption relative to peers. Those are adoption and capacity signals. They do not, by themselves, prove that the work was safe, accurate, or commercially valuable.

    Organize oversight metrics into three lenses:

    • Adoption and capacity: active agents, active users, workflow frequency, proposals created, actions executed, and estimated hours returned. Document how any time-return estimate is calculated.
    • Safety and control: missing-context responses, policy blocks, exception requests, rejected proposals, stale approvals, out-of-scope attempts, partial executions, failed verification, rollbacks, incidents, and near misses.
    • Business outcomes: the marketing measures the workflow was intended to influence, alongside cost, error, complaint, and rework signals. Do not attribute an outcome to the agent merely because the two appeared in the same reporting period.

    Configure immediate alerts for attempted protected actions, unavailable policy enforcement, writes to an unregistered destination, changes to agent credentials, partial execution, and failed post-write verification. A weekly dashboard cannot contain an agent that is actively writing to the wrong account.

    During rollout, inspect every attempted production write and every policy block. Once the controls have behaved correctly under real workload, choose a recurring review cadence based on action frequency and consequence, while keeping event-driven alerts for protected operations.

    Read metrics in context. Zero policy blocks can mean that workflows are well designed, that nobody is using them, or that enforcement is not recording failures. High approval rates can indicate good proposals or automatic rubber-stamping. Pair each number with sample-level review and an accountable owner.

    Key takeaways

    • Trust is the result of inspectable controls, not a personality judgment about the model.
    • Give agents enough context to reason well, and force them to expose material gaps.
    • Enforce permissions and policies outside prompts.
    • Require approval before actions that can affect money, traffic, customers, access, or live content.
    • Bind approval to an exact, time-limited proposal and verify the resulting platform state.
    • Measure adoption, safety, and business outcomes as separate questions.

    Start with the highest-consequence agent workflow you already use. Write its grounding contract, remove every unnecessary permission, and force its next production change through proposal, policy validation, exact approval, execution, and verification. Expand only one permission or action class at a time after that path works as designed.

    References

  • How to Audit AI Marketing Recommendations Across Audiences

    How to Audit AI Marketing Recommendations Across Audiences

    You give an AI marketing tool a clear goal, and it returns a confident audience, channel, or brand recommendation. The answer looks ready to use. But before you build a campaign around it, you need to know two things: what evidence produced the recommendation, and whether the recommendation changes when the audience changes.

    If neither is visible, you do not have decision support yet. You have a plausible output whose scope, assumptions, and failure modes are hidden. The practical fix is to audit recommendation evidence and audience variation as one workflow, then require human approval wherever a change could affect reach, spend, eligibility, or brand strategy.

    One AI answer is not a complete market view

    A single answer-engine response can be useful without being representative. The engine may interpret the question through details about the user, the wording of the prompt, prior conversational context, or other signals available to the system. Change that context and the shortlist, ranking, citations, or explanation may also change.

    A vendor analysis of 71,147 answer-engine responses found differences in brand mentions, citations, and search behavior associated with income, age, gender, and occupation. That finding does not establish that every answer engine personalizes every request, nor does it explain the cause of every observed difference. It does show why a persona-neutral prompt should not be treated as a universal picture of AI visibility.

    Some variation is appropriate. A buyer prioritizing affordability and a buyer prioritizing enterprise governance may reasonably receive different recommendations. The issue is not whether answers ever change. It is whether the change follows a relevant criterion, rests on supportable evidence, and remains consistent with the underlying facts.

    Separate the stable layer from the audience-sensitive layer:

    • Stable facts include product identity, documented capabilities, known requirements, and the meaning of cited evidence. A persona change should not silently reverse them.
    • Audience-sensitive judgments include which criterion receives more weight, which use case is emphasized, which options appear first, and which tradeoff is considered acceptable.
    • Presentation choices include tone, examples, terminology, and depth. These may change while the substantive recommendation remains the same.

    This distinction helps you spot three common measurement failures:

    • False universality: one prompt produces one answer, and the result is reported as what the platform recommends to everyone.
    • Hidden exclusion: a brand appears for one persona but disappears for another, with no visible criterion explaining the difference.
    • Averaged-away variation: a dashboard combines responses across audiences and makes unstable visibility look consistent.

    Treat an AI visibility observation as a combination of platform, prompt, audience context, and observation time. If any part changes, you may be measuring a different answer environment.

    A transparent recommendation shows decision evidence

    Hands inspect the visible source, assumption, recommendation, and approval components inside a transparent decision-making assembly.

    Transparency does not mean exposing every internal model operation or demanding a private reasoning transcript. Neither gives a marketer a reliable basis for approval. You need the evidence, uncertainty, and tradeoffs that could materially change the decision.

    This matters because marketing data is rarely as tidy as the campaign brief. A marketer searching for a completed-purchase signal may encounter several similarly named events, such as purchase, checkout success, and checkout completion. The labels alone do not reveal which event represents a confirmed order, which fires earlier in the funnel, or which remains reliable after implementation changes.

    Volume does not settle the question. A frequently firing purchase event could occur before payment confirmation, while a lower-volume checkout-success event could align more closely with the business definition of a completed order. Selecting the biggest signal without checking its meaning can create a large but conceptually wrong audience.

    Require each consequential recommendation to carry an evidence card. It can appear in a conversational response, side panel, review screen, or exported log, but it should answer the following questions:

    Evidence fieldWhat the system should exposeWhat you can decide
    Business objectiveThe outcome the recommendation is intended to support, in business languageWhether the proposed action answers the request you actually made
    Selected signal or criterionThe event, attribute, source, or decision criterion carrying the recommendationWhether the system used the right representation of the goal
    Meaning and funnel stageWhat the signal appears to represent and where it occurs in the customer journeyWhether purchase, checkout, intent, and engagement are being confused
    Provenance and observed behaviorWhere the signal comes from, how it behaves, how often it fires, and when it was last observedWhether the evidence is current and dependable enough for this decision
    Audience boundariesWho is included, who is excluded, and the resulting potential reachWhether the audience matches campaign eligibility and strategy
    Alternatives consideredThe plausible competing signals or approaches that could change the outcomeWhether an apparently obvious recommendation ignored a better-defined option
    TradeoffsHow changing a threshold or criterion affects reach, expected performance, precision, or riskWhich compromise fits the business rather than merely optimizing a model score
    Uncertainty and missing contextAmbiguous definitions, unavailable metadata, sparse observations, or assumptions supplied by the systemWhether to accept, refine, investigate, or reject the recommendation
    Decision stateWhether the output is exploratory, proposed, saved, connected, or activatedWhether any real-world action has occurred and what still requires approval

    Do not accept vague evidence labels such as recent, strong, or large when the interface can expose the underlying context. Recent relative to what observation? Strong against which alternative? Large compared with which eligible population? The system does not need to manufacture precision, but it should distinguish known values from inferred meanings and unavailable information.

    The approval flow matters as much as the evidence. For recommendations that can change spending or customer eligibility, keep proposal, saving, connection, and activation as distinct states. An exploratory conversation should not silently become an active audience. Explicit confirmation creates a point where a marketer can apply business judgment, document an override, or request better evidence.

    Conversation and direct controls also serve different jobs. A conversational agent is well suited to exploring unfamiliar data and explaining why signals differ. A visual interface is better for making precise threshold adjustments after the reach-versus-performance tradeoff is understood. A trustworthy workflow lets you move between them without losing the evidence or approval state.

    Run a controlled audience-variation audit

    Four controlled test lanes hold the same campaign brief while different audience groups lead to visibly varied recommendation objects.

    An audience audit should isolate whether persona context changes the recommendation, not merely collect a folder of unrelated prompts. Keep the decision question and test conditions stable, change one relevant audience dimension at a time, and record substantive differences separately from stylistic ones.

    Build the test grid

    1. Define the decision. Write the exact question the answer must resolve, such as which solution fits a use case or which audience should receive a campaign. State the criteria that should matter before looking at the output.
    2. Create a neutral baseline. Ask the decision question without demographic or occupational context that is not necessary to answer it. This becomes the comparison point, not the presumed correct answer.
    3. Select relevant audience dimensions. Test occupation, age, income, gender, or another persona attribute only where it could plausibly affect needs, constraints, terminology, access, or evaluation criteria.
    4. Change one dimension at a time. Keep the platform, wording, product category, requested format, and other context constant. Composite personas may reflect real buyers, but they make it harder to identify which attribute drove a change.
    5. Capture the complete response. Record the prompt, audience variation, platform and model label exposed by the interface, observation time, recommended brands or actions, ordering, rationale, citations, caveats, and omitted options.
    6. Compare decisions before wording. A different example or tone is less important than a changed shortlist, reversed ranking, new exclusion, altered factual claim, or different call to action.
    7. Inspect the support. Check whether each changed recommendation is tied to an explicit audience need and whether its cited material actually supports the criterion being applied.
    8. Assign a disposition. Mark the variation as presentation-only, relevant and supported, unexplained and substantive, or factually contradictory. Each label should lead to a different next action.

    Interpret changes by materiality

    Presentation-only variation changes the vocabulary, explanation depth, or examples without altering the decision. You may still care about tone and accessibility, but it is not evidence that brand visibility changed.

    Relevant, supported variation changes the recommendation because the persona introduces a genuine decision criterion. An occupational context may change workflow requirements. An affordability constraint may alter which options qualify. The output should make that connection visible rather than relying on an unexplained proxy.

    Unexplained substantive variation changes inclusion, exclusion, order, or recommended action without identifying a relevant criterion or supporting evidence. Do not immediately label it bias or personalization; the system may be responding to ordinary output variation, hidden context, or a retrieval difference. Rerun the unchanged baseline alongside the persona variant, preserve the outputs, and investigate before drawing a causal conclusion.

    Factual contradiction occurs when stable product facts or evidence claims change solely with the persona. That is a blocking issue. Do not use the output for activation or publish the claim until you can resolve which statement is supported.

    Pay special attention to citations. A persona may receive different cited pages even when the recommendation stays similar. Record whether a citation is present, whether it supports the nearby claim, and whether it represents the same kind of evidence across variants. Citation count alone cannot tell you whether the recommendation is sound.

    Age, gender, and income can be useful diagnostic variables because audience-linked variation has been observed, but they can also be sensitive attributes. Using them to determine real customer eligibility can create privacy, fairness, or legal exposure depending on the context and jurisdiction. Use them in testing only when necessary, minimize personal data, and route any activation rule based on sensitive traits through your legal and privacy review process.

    Turn the audit into content, measurement, and controls

    An audit is only valuable if it changes how you publish, measure, or approve marketing decisions. The goal is not to force every audience to receive identical recommendations. It is to make legitimate differences explainable and unsupported differences visible.

    Make audience criteria explicit in your content

    If an answer engine changes its recommendation because of a criterion your content barely addresses, close that evidence gap on the relevant page. Add clear passages that identify:

    • who the product, service, or method is designed for;
    • which use cases it supports and which it does not;
    • what prerequisites, limitations, or eligibility conditions apply;
    • which tradeoffs a buyer must make;
    • how important terms and outcomes are defined; and
    • which verifiable facts support each suitability claim.

    Write around decision contexts, not demographic labels. A page explaining the needs of a regulated procurement workflow is more useful than a thin page targeting an occupational persona by name. A clear affordability limitation is more informative than assuming what someone can spend from a demographic category.

    Structured data can reinforce supported facts about the page, organization, product, service, author, or other entities where the relevant schema applies. It cannot make an unsupported claim trustworthy, encode every possible persona preference, or guarantee that an answer engine will recommend a brand. Use schema to clarify machine-readable facts, then make the audience-specific reasoning legible in the visible content.

    Measure visibility at the audience level

    Do not reduce answer-engine performance to a platform-wide mention rate if your buyers approach the category with materially different contexts. Track AI visibility by audience as well as by platform, while retaining the neutral baseline so you can see where variation begins.

    For each monitored decision question, record:

    • the exact prompt and persona context;
    • the engine, interface, and model information exposed at the time;
    • whether your brand was mentioned;
    • where it appeared in an ordered recommendation, if the answer provided an order;
    • the use case or criterion attached to the mention;
    • the pages or sources cited;
    • the caveats attached to the recommendation; and
    • whether the result was stable, relevantly different, unexplained, or contradictory.

    Keep the prompt set and audience definitions fixed when comparing observations over time. If you rewrite the question, change the persona, and switch platforms at once, you cannot tell whether a visibility movement came from your content, the engine, or the test design.

    Define approval boundaries before activation

    Set review rules before an agent proposes an audience or campaign. Require human approval when:

    • the selected data signal has an ambiguous business meaning;
    • the origin, observed behavior, or recency of the evidence is unavailable;
    • a threshold creates a material reach-versus-performance tradeoff;
    • a sensitive audience attribute changes inclusion or exclusion;
    • persona variants produce contradictory facts or unexplained recommendations;
    • the action can change budget, customer eligibility, messaging, or external activation; or
    • the system cannot show which assumption would most affect the recommendation.

    Preserve the human decision in a log. Record the proposal, evidence shown, audience context, chosen action, override, approver, and activation state. This is not paperwork for its own sake. It lets you distinguish a model recommendation from the business decision that followed it and prevents later reporting from treating the two as interchangeable.

    Key takeaways

    • A single AI response represents one platform, prompt, audience context, and observation time. It is not a universal market answer.
    • Useful transparency exposes the selected signals, their meaning and recency, audience boundaries, alternatives, uncertainty, and tradeoffs. A private reasoning transcript is not required.
    • Test audience variation by holding the decision question constant and changing one relevant persona dimension at a time.
    • Separate presentation changes from substantive recommendation changes, and block activation when stable facts become contradictory.
    • Measure brand mentions, ordering, use cases, citations, and caveats by audience rather than averaging every response into one platform score.
    • Keep exploration, saving, connection, and activation distinct so a marketer can refine or override the recommendation before it affects customers or spend.

    Start with the next recommendation your team is already preparing to use. Attach an evidence card, run the neutral prompt beside one relevant audience variant, and classify every substantive difference. If the system cannot explain a changed recommendation with current evidence and a relevant criterion, do not report it as universal and do not activate it. Fix the evidence, the content, or the decision rule first.

    References

  • Business Context for AI Marketing: A Practical Operating System

    Business Context for AI Marketing: A Practical Operating System

    Your AI can sound polished and still make the wrong marketing decision. It may address the wrong buyer, lead with a secondary benefit, treat an internal ambition as an approved claim, or pursue search demand that has little connection to your offer.

    If better prompting has not fixed that pattern, the missing input is probably business context. You need an approved, current layer of knowledge that tells AI what your business means, which facts it may use, and where its judgment must stop. Build that layer before you scale content generation or marketing automation.

    Why prompt polishing cannot supply missing business truth

    A prompt describes a task. It might specify the format, channel, topic, length, or desired action. It cannot reliably stand in for everything your organization knows about its customers, products, priorities, proof, and restrictions.

    When that knowledge is absent, the model has to complete the task using broad patterns. The result can be grammatically strong and strategically interchangeable. The problem is not necessarily weak writing. It is that the model has no basis for choosing your priority audience over a plausible adjacent audience, an approved product benefit over a popular category claim, or a defensible answer over a more confident one.

    A dedicated context layer is designed to hold, structure, and apply business knowledge so an AI marketer can tailor recommendations and outputs. That is a useful design principle, but reduced manual intervention should be treated as an outcome to validate in your own workflows, not as an automatic result of buying a tool.

    Separate four things that are often mixed into one oversized prompt:

    • Instructions: what the AI should do in this task.
    • Business context: what it needs to know to make choices consistent with your organization.
    • Evidence: what supports the claims it may publish.
    • Guardrails: what it must not infer, disclose, promise, or change.

    This separation makes defects diagnosable. If the format is wrong, fix the instruction. If the audience is wrong, fix the context. If a claim is unsupported, fix the evidence policy. If confidential information appears, fix access and publication controls.

    Key takeaways

    • Business context should change marketing decisions, not merely make prose sound more branded.
    • Store approved facts, priorities, boundaries, and evidence separately from task instructions.
    • Give each context item an owner, scope, status, and rule for resolving conflicts.
    • Retrieve only the context relevant to the current audience, market, offer, and channel.
    • Test context with real marketing tasks and evaluate factual fit, strategic fit, and claim discipline.

    Build context around the decisions AI must make

    Organized groups of customer, product, proof, priority, and constraint objects connect to a central processing device on a strategy table.

    Do not begin by uploading every document your company has produced. A document archive can contain useful knowledge, but it can also contain expired offers, unsupported claims, conflicting terminology, abandoned strategies, and information that should never reach a public workflow.

    Begin with a recurring marketing decision. For example: which angle should lead a landing page, which audience should receive a campaign, which questions deserve answer pages, or whether a query belongs in your organic search plan. Record the business knowledge required to make that decision correctly.

    Business layerContext to recordDecision it should change
    Strategic directionCurrent objective, priority market, priority offering, planning horizon, and explicit non-goalsWhat the AI recommends and what it deprioritizes
    AudienceTarget roles, situations, knowledge level, pains, desired outcomes, objections, and excluded segmentsWho the work addresses and which problem leads
    OfferApproved name, included capabilities, exclusions, prerequisites, availability, and customer responsibilityWhat the AI may promise or compare
    PositioningCategory, differentiation, alternatives, message hierarchy, and claims that require qualificationHow the offer is framed
    EvidenceApproved proof, claim-to-evidence relationships, citation locations, and unsupported assertionsWhich statements can be published confidently
    Brand languagePreferred terminology, prohibited wording, tone rules, definitions, and representative examplesHow the decision is expressed
    Search and discoveryCanonical entity names, topics, audience intent, query groups, answer boundaries, and relevant pagesWhat the organization should be discoverable for
    Operating constraintsGeographic scope, channel restrictions, required reviews, access limits, and escalation ownersWhat can be generated, published, or routed automatically

    For each layer, keep only information that changes a choice or constrains an output. A corporate history may be valuable background, but it does not belong in every content task. An approved definition of your product category may affect almost every page. Context earns its place through decision value, not document length.

    Separate durable knowledge from current work

    Context becomes unreliable when stable business facts and temporary campaign choices occupy the same undifferentiated file. Divide it by scope:

    • Durable business context covers identity, approved terminology, product boundaries, standing evidence rules, and persistent audience definitions.
    • Initiative context covers a launch, campaign, market, offer, or strategic priority that applies only within a named scope.
    • Task context covers the query, page, channel, format, deadline, and action required for the current output.

    Consider a hypothetical software company that generally serves finance teams but is running a campaign for controllers. Durable context defines the product and its approved capabilities. Initiative context makes controllers the priority audience for that campaign. Task context asks for an answer page addressing a controller’s specific question. The campaign should not silently redefine the company’s entire market, and the task should not rewrite product truth.

    Resolve contradictions before generation

    AI should not have to arbitrate between a sales deck, an old web page, and a current product record. If those materials disagree, more retrieval can make the result less reliable.

    Assign a canonical owner for each context type. Mark every item as approved, draft, disputed, or retired. Record which rule wins when scopes overlap. If the business has not resolved a conflict, label it as unresolved and prevent the system from converting either position into a public claim.

    A useful context layer does not pretend the organization is more certain than it is. It gives the AI a safe way to say that information is unavailable, request review, or leave a claim out.

    Make every context item usable and governable

    Long prose is easy to collect but hard to govern. One paragraph can mix an approved fact, a preference, a prediction, and an exception. When one part changes, nobody knows whether the whole paragraph remains valid.

    Store important knowledge as small records that can be approved, retrieved, superseded, or retired independently. Each record should contain:

    • Identifier: a stable name that workflows and reviewers can reference.
    • Statement: one clear fact, rule, priority, definition, or boundary.
    • Type: audience, offer, evidence, positioning, terminology, restriction, or another controlled class.
    • Scope: the brands, products, markets, audiences, channels, and initiatives to which it applies.
    • Status: approved, draft, disputed, or retired.
    • Authority: the internal system or person responsible for confirming it.
    • Evidence: the supporting material, where substantiation is required.
    • Effective condition: when the record applies and which event should trigger review.
    • Precedence: what should happen if another applicable record conflicts with it.
    • Publication permission: whether it is public, internal, restricted, or prohibited from generated output.

    This structure is useful even if you begin in a spreadsheet or content management system. The technology matters less than whether your team can tell what is true, where it applies, who approved it, and what happens when it changes.

    Translate adjectives into decision rules

    Context such as “sound professional” or “focus on quality” gives the model almost no business-specific direction. Replace abstract preferences with observable rules.
    • Replace “sound authoritative” with rules such as: lead with the decision, define specialist terms on first use, distinguish approved facts from recommendations, and omit claims that lack named support.
    • Replace “target enterprise buyers” with the roles involved, the problem each role owns, the objections that matter, the expected knowledge level, and the situations outside the campaign.
    • Replace “highlight our flexibility” with the exact configurable elements, fixed constraints, prerequisites, and wording that must not imply unlimited customization.
    • Replace “optimize for AI search” with the questions the page should answer, the entity names it must use consistently, the evidence available for each material claim, and the pages that establish supporting detail.

    The test is simple: could a reviewer look at the output and determine whether the rule was followed? If not, the context is still a mood rather than an operating instruction.

    Set an explicit order of authority

    Context records will eventually overlap. Establish an order before they do. A practical starting point is to let mandatory legal, security, privacy, and compliance restrictions override approved product facts; let approved facts override campaign language; and let campaign instructions override stylistic preferences. Your actual order should reflect your governance, but it must be visible to the workflow.

    Do not let recency win automatically. A newer brainstorm is not more authoritative than an approved product record merely because its timestamp is later. Status, ownership, and scope are stronger signals than freshness alone.

    Limit what each workflow can see

    Business context may contain unreleased plans, contractual restrictions, customer information, pricing logic, or competitive intelligence. Do not assume every model, integration, user, or publishing workflow should receive every field.

    Create separate public, internal, and restricted views. A public content workflow should receive only facts approved for publication. An internal planning workflow may receive confidential priorities but should be blocked from publishing them. Customer-level or personally identifiable information should not enter an AI workflow unless the organization has explicitly approved the tool, purpose, access controls, and handling process.

    Apply context to SEO, AEO, GEO, and campaign workflows

    A central repository is not enough. Context creates value only when the right records reach the right task. Passing the entire repository into every prompt can introduce irrelevant instructions and hidden conflicts. Retrieve the smallest approved bundle that can support the decision.

    Use this execution flow for a recurring marketing task:

    1. Name the decision, audience, market, offer, channel, and intended action.
    2. Retrieve context whose scope matches those fields.
    3. Resolve precedence and remove draft, retired, restricted, or irrelevant records.
    4. Ask the AI to produce the strategic decision or brief before it produces the finished asset.
    5. Check proposed claims against the approved evidence records.
    6. Generate the asset using only the approved decision, facts, and boundaries.
    7. Route missing evidence, conflicting context, and policy exceptions to the named owner.

    Generating the decision first matters. If you ask for the finished page immediately, a polished draft can hide an incorrect audience or message choice. A short brief exposes those errors while they are still cheap to correct.

    For SEO briefs

    Give the system more than a keyword. Supply the target audience, market, search intent, relevant offering, approved entity names, business objective, available evidence, existing page relationships, and topics that fall outside the offer.

    Require the brief to explain why the query belongs in your strategy. It should connect the query to a real audience problem, an answer your organization can support, and a useful next step. If the connection is weak, the correct output may be to deprioritize the query rather than manufacture relevance.

    For AEO and answer content

    Record the answer boundary as well as the answer. The system needs to know which conditions change the response, which terms require definition, which claims need evidence, and when a general answer would overstate what your business can support.

    Ask for a direct response that can stand on its own, followed by qualifications and supporting detail. Then verify that the visible page actually contains the facts used in summaries, metadata, and structured representations. A concise answer is useful only if compression has not removed a material condition.

    For GEO and AI discovery

    Use context to keep entity identity, product names, audience definitions, category language, and material claims consistent across related pages. Create a claim ledger for each important page with the claim, its supporting evidence, its visible location, its approval status, and any structured-data property that represents it.

    This discipline can make your published information clearer and more internally consistent. It cannot guarantee that a frontier model, answer engine, or AI search feature will retrieve, cite, summarize, or rank the page. Treat visibility as an external outcome to measure, not a promise encoded in the context layer.

    Schema markup should consume approved public facts; it should not become a back door for unverified or confidential context. The visible page, structured data, and canonical business record should agree. Schema is a publication format, not a truth engine.

    For campaigns and content operations

    Keep the strategic decision stable while adapting execution to the channel. The audience, offer boundaries, evidence policy, and intended action can remain consistent, while format, length, sequencing, and creative treatment change for email, paid media, social, landing pages, or sales enablement.

    Route human review to consequential points: new claims, unsupported comparisons, policy exceptions, sensitive audience targeting, and conflicts between records. When approved context already covers a routine choice, reviewers should not have to reconstruct the same business logic for every asset.

    Test the context system, not just the prose

    An analyst observes two parallel AI marketing test pipelines, one producing scattered results and the other producing consistent outputs through organized context modules.

    Do not judge the system by whether one draft sounds impressive. A fluent output can still be wrong, and a stylistic preference can distract reviewers from a serious context failure.

    Build a test set from real, recurring work: a search brief, an answer page, a campaign angle, a product comparison decision, a content refresh, or another task your team already reviews. Include ordinary cases, boundary cases, missing-information cases, and cases in which the correct response is to escalate or refuse a claim.

    For each task, compare a context-enabled run with a baseline using the same task and model settings. Evaluate the decision and evidence use before evaluating style. Your review should answer:

    • Did it select the intended audience, market, offer, and objective?
    • Did it use the approved terminology and canonical entity names?
    • Did it distinguish a verified fact from a recommendation, hypothesis, or unknown?
    • Did every material claim stay within the available evidence?
    • Did it obey exclusions, publication permissions, and review requirements?
    • Did it explain why the recommendation fits the current business priority?
    • Did it avoid dragging irrelevant context into the output?
    • Did the same approved facts remain consistent across channels and formats?

    Record failures against the context system rather than patching each draft in isolation.

    Observed failureLikely context defectCorrective action
    The output is polished but aimed at the wrong buyerAudience scope is vague, overlapping, or not retrievedAdd inclusion and exclusion rules, then test retrieval against the task scope
    The output contains a plausible but unsupported benefitClaims are not linked to evidence or unsupported claims are not prohibitedCreate a claim-to-evidence record and require escalation when support is absent
    The recommendation follows an outdated priorityInitiative status or precedence is unclearRetire the old record and specify which current initiative overrides durable defaults
    The answer is correct but interchangeable with competitorsPositioning is expressed as adjectives rather than decision rulesRecord the actual category, differentiators, alternatives, and message hierarchy
    Different workflows describe the same offer differentlyCanonical names and offer boundaries are duplicated across systemsReference one approved record and distribute channel-specific views from it
    The AI exposes internal plans in public copyPublication permissions or access scopes are missingSeparate public and restricted views, then block restricted fields from publishing workflows
    The system asks for manual review on every taskApproval status, boundaries, or exception rules are incompleteApprove routine cases explicitly and reserve escalation for named exceptions

    Define what ready means

    Your context layer is ready for a workflow when the AI can make the intended decision, identify the applicable evidence, respect the stated boundaries, and surface uncertainty without a reviewer rebuilding the brief from scratch. It is not ready merely because the repository is large or the generated copy sounds on-brand.

    Start with one recurring decision before attempting an organization-wide knowledge project. Capture only the context needed for that decision, assign authority and publication status, compare it with the baseline, and repair the defects you observe. Expand to another workflow only when the first context bundle consistently changes decisions in the intended way.

    The goal is not maximum context. It is the minimum approved context required for AI to do useful marketing work without inventing the business around your prompt.

    References

  • How to Build Trustworthy AI Agents for Marketing Operations

    How to Build Trustworthy AI Agents for Marketing Operations

    You have an agent that can inspect ad accounts overnight, draft a content brief before stand-up, or flag a broken funnel. The uncomfortable question arrives just after the demo: what, exactly, are you willing to let it do without asking?

    If your answer is “we’ll review it,” you don’t yet have a control system. You have an intention. A trustworthy marketing agent needs a bounded job, owned data, explicit permissions, evidence attached to its conclusions, a release gate, and a way to stop or reverse its actions. Here is how to put that operating model in place.

    A trustworthy agent is a controlled workflow, not a clever model

    A model generates an answer. An agent combines a model with data, instructions, tools, scheduled triggers, and permission to take or prepare actions. That surrounding system determines whether a plausible mistake becomes a harmless draft, a misleading alert, or a customer-facing incident.

    Trustworthiness therefore isn’t the promise that an agent will never be wrong. It is your ability to see what the agent observed, understand why it reached a conclusion, constrain what it can do, route uncertain cases to the right person, and recover when something fails. In production, reliability is decided by governance, realistic testing, and named review paths at least as much as by model capability.

    The most useful mental model is a new employee with unusual speed. You wouldn’t give a new marketing analyst unrestricted CRM access, authority to change pricing, and permission to email customers on the first morning. You would define the role, grant only the access it needs, review early work, and expand responsibility after the work proves dependable. An AI agent needs the same management discipline, encoded in the workflow rather than left in a manager’s head.

    Before deployment, make sure every agent has clear answers to these questions:

    • What specific decision or task does the agent own?
    • Which systems, records, fields, and time periods may it inspect?
    • Which facts and business rules must it know before making a judgment?
    • What evidence must accompany each conclusion or recommendation?
    • When must it abstain, escalate, or ask for missing information?
    • Who reviews consequential work, and what counts as approval?
    • Which actions can it take, and how can those actions be stopped or reversed?
    • Which version of the model, instructions, tools, and data definitions produced the result?

    If any answer is “it depends,” write down what it depends on. That conditional logic is part of the product. It cannot remain tribal knowledge if the agent is expected to make repeatable decisions.

    Begin with one bounded decision, not a general marketing assistant

    “Monitor our marketing” sounds like a useful assignment, but it contains dozens of hidden jobs. Does monitoring mean detecting a tracking outage, explaining a CPA change, checking whether campaigns are serving, judging lead quality, finding off-brand copy, or recommending budget shifts? Each job needs different data, context, freshness rules, and escalation paths.

    Start with a task whose input and acceptable output can be described precisely. Read-only analysis is usually the safest entry point because the agent can create value without changing the underlying system. Examples include investigating an ad-delivery alert, identifying content briefs with missing source material, finding inconsistent campaign naming, or preparing a proposed JSON-LD correction for validation and human review.

    Write a short job card for the workflow:

    • Trigger: State what starts the run, such as a scheduled account check or an anomaly from an existing monitoring rule.
    • Question: Express the decision in one sentence. For example: “Has campaign delivery stopped during comparable business hours?”
    • Inputs: Name the approved systems, fields, reporting windows, business rules, and account notes.
    • Output: Define the required finding, supporting evidence, uncertainty, and proposed next step.
    • Prohibited behavior: State what the agent must not infer, retrieve, publish, send, or change.
    • Escalation: List the conditions that require abstention or human judgment.
    • Reviewer: Assign a role or person responsible for accepting consequential recommendations.
    • Success and failure: Describe both a useful result and an unsafe result. A fluent explanation without adequate evidence belongs in the failure column.

    Pay special attention to time. Marketing data often arrives on different schedules, so “recent” does not necessarily mean “complete.” A production ad-management agent once interpreted conversions that had not arrived yet as a severe performance decline. Making its analysis dependable required safe comparison windows, conversion-maturity rules, uncertainty ranges, and refusal when the lag could not be modeled reliably.

    Apply that lesson beyond paid media. A CRM agent should not label a campaign unproductive before the normal sales cycle has elapsed. A content agent should not declare a page unsuccessful before the chosen reporting period is complete. An SEO agent should not turn a partial crawl or delayed analytics import into a confident diagnosis. Freshness and maturity are different properties, and the agent needs rules for both.

    Refusal is not a defect when the evidence is immature, contradictory, or missing. A trustworthy response may be: “I cannot distinguish a real decline from reporting delay with the approved data.” That is more useful than an elaborate guess because it tells the operator what information is needed next.

    Give the agent a data contract and a business context pack

    Connecting an agent to more systems does not automatically make it better informed. It can instead create several conflicting versions of revenue, conversion, customer status, or campaign ownership. The agent will still produce coherent prose even when the underlying records disagree.

    A data contract tells the agent what it may use and how each input should be interpreted. Create one before refining the prompt. For every permitted input, record:

    • The system and field that hold the data.
    • The business owner responsible for its meaning and quality.
    • Whether it is the authoritative value or a convenience copy.
    • How frequently it updates and when it becomes mature enough for judgment.
    • The unit, attribution rule, time zone, status definition, and other interpretation rules.
    • Known gaps, exclusions, and failure signals.
    • What the agent must do when the input is absent, stale, or inconsistent.
    • Whether the field contains personal, confidential, regulated, or otherwise restricted information.

    Then create a separate context pack for facts that do not live cleanly in reporting tables. Include the products the business actually sells, excluded services, target locations, budget constraints, active promotions, sales-cycle expectations, conversion-lag patterns, campaign goals, approved claims, brand restrictions, and known tracking limitations. Without this context, an agent can correctly calculate the numbers and still reach the wrong business conclusion. A paid-media agent, for example, cannot identify an irrelevant pet-insurance keyword for a business-insurance advertiser unless it knows what the business sells and can access the operational context used by human analysts.

    Keep the context pack owned and maintainable. Each rule should have an owner, a status, and a replacement path when the business changes. Otherwise an old promotion, discontinued service, or superseded approval rule can remain active inside the agent long after people have moved on.

    Use least-privilege access. If the task requires campaign totals, do not expose raw customer records. If the agent only prepares a content update, give it draft access rather than publishing rights. If it reads a CRM status, restrict it to the approved fields rather than the full contact object. Governed implementations can limit access to approved data, mask immature conversion information, and require evidence for recommendations.

    Trace where the data goes as well as what the agent can retrieve. Before customer, prospect, health, or financial information reaches a third-party AI service, determine where it is processed, what the provider may retain or reuse, and which internal policy governs that transfer. Marketing data deserves the same boundary-setting applied to other sensitive operational systems; convenient access is not the same as necessary access.

    If the team cannot identify the owner or meaning of an important field, stop at read-only experimentation. A better prompt cannot resolve a disputed definition of revenue, repair missing conversion data, or decide which system is authoritative.

    Set autonomy by consequence and reversibility

    An AI device faces three increasingly restricted action zones, from reversible draft tasks to guarded campaign controls and a locked high-consequence mechanism.

    Teams often treat autonomy as a switch: either the agent acts or a person does. A safer design separates observation, recommendation, preparation, and execution. The agent can then earn broader permissions without receiving blanket authority.

    Operating levelMarketing exampleDefault permissionRelease condition
    ObserveCheck reporting data and surface a possible anomalyRead approved fields; create an internal recordFreshness checks pass and evidence is attached
    RecommendExplain a performance change or propose a content correctionNo external changeAssumptions, uncertainty, affected assets, and reviewer are explicit
    PrepareBuild a draft ad, email, brief, metadata edit, or schema patchWrite only to a draft or sandboxValidation passes and a named person approves publication
    ActPause a campaign, move budget, publish content, change pricing, or send a messageOff by defaultThe action is narrowly pre-approved, policy-compliant, observable, and safely reversible; otherwise human approval remains mandatory

    Two variables should control the level: consequence and reversibility. A duplicate internal alert is annoying but recoverable. An incorrect customer email, pricing change, destructive CRM update, or large budget movement can create brand, financial, privacy, or legal exposure. Work carrying that weight needs a human checkpoint; letting an unreviewed agent send customer communications or make consequential commercial decisions is not an acceptable starting posture.

    For high-impact recommendations, add an independent check before the decision reaches the approver. That check should evaluate the evidence and policy conditions, not merely ask another model whether the prose sounds convincing. It can verify that the reporting window is mature, the cited records exist, the requested action is permitted, and contradictory data has been surfaced. Higher-stakes analysis benefits from a separate review path before a person is asked to act.

    Require an evidence packet for every recommendation. It should contain:

    • The conclusion in plain language.
    • The period, comparison, account, page, campaign, or record under review.
    • The approved inputs actually used.
    • Missing, stale, masked, or contradictory inputs.
    • Assumptions and relevant business rules.
    • The agent’s uncertainty or reason for abstaining.
    • The proposed action and assets it would affect.
    • The required approval and available rollback path.

    Do not allow the agent to hide uncertainty inside polished prose. Evidence must be inspectable by the person making the decision. If a recommendation cannot be traced back to permitted inputs, it should fail the release gate regardless of how reasonable it sounds.

    Release, monitor, and stop the agent like production software

    Human operators monitor an AI agent moving from testing through a gated deployment lane, with health sensors, an evidence trail, an emergency stop, and a rollback track.

    Test safe behavior, not just good answers

    A handful of impressive demo prompts proves very little. Build an evaluation set from the situations the agent will face after release: routine work, different ways users phrase the same request, incomplete data, delayed conversions, stale account notes, conflicting systems, out-of-scope requests, and cases where the correct response is escalation.

    For each case, define the expected behavior rather than one perfect paragraph. Should the agent answer, flag uncertainty, request information, refuse, or escalate? Which evidence must appear? Which tools may it call? Which actions must remain blocked? This makes the evaluation durable even when wording varies.

    Add simple pass-or-fail checks around important invariants:

    • A read-only agent cannot invoke a write operation.
    • A draft-only content agent cannot publish.
    • Restricted fields never appear in retrieved context or output.
    • A performance judgment cannot use a reporting window marked immature.
    • A recommendation cannot pass without evidence identifiers and required assumptions.
    • A missing authoritative input triggers the prescribed abstention or escalation.
    • An action outside the job card is rejected even when a user asks persuasively.

    Run the agent in shadow mode before granting action rights. Let it inspect real work and produce results without changing external systems. Compare its findings with the decisions made through the existing process, examine both disagreements and omissions, and update the job card, data contract, context pack, and evaluation set. Only then consider expanding its operating level.

    Version every component that can change behavior

    The prompt is not the whole agent. Store the system instructions, policy rules, model identifier, provider settings, tool definitions, data-field mappings, business definitions, context-pack version, evaluation results, approval decision, and release date as one traceable configuration.

    This matters because behavior can drift even when your team changes nothing visible. A provider can update the model underneath a workflow, while a data field, tool response, or business rule can change independently. Unversioned models and prompts make it difficult to explain why customer-facing behavior changed or recreate how the system acted earlier. Marketing teams need release discipline and behavior monitoring around model and prompt changes, just as they do around application changes.

    Rerun the relevant evaluations whenever any behavioral component changes. If the provider does not expose a fixed model version, record the identifier it does provide and use recurring evaluation results to detect observed changes. Do not assume unchanged prompts guarantee unchanged behavior.

    Monitor usefulness, silence, and operator burden

    Accuracy on answered cases is not enough. Monitor unsupported conclusions, inappropriate certainty, policy violations, reviewer overrides, action reversals, duplicate alerts, unnecessary escalations, and cases where a reviewer had to retrieve evidence the agent should have supplied.

    Review non-alerts as well as alerts. An agent can look quiet because nothing is wrong, because its thresholds are sensible, or because it missed the problem. Sample runs where it concluded that no action was needed and verify that the underlying data supports that silence.

    Noise is an operational failure. If people repeatedly dismiss duplicate, untimely, or low-value alerts, they will stop treating the agent as a useful colleague. A working ad-management agent had to remove duplicate notifications and messages that could wait because convincing the team to pay attention depended on reducing noise as well as improving analysis.

    Give operators a visible stop path. When the agent behaves unexpectedly, they should be able to pause scheduled runs, revoke write credentials, preserve the decision trace, identify the changed component, rerun evaluations, and restore a known configuration. Re-enable a smaller scope before returning full permissions.

    Rollback has limits. You can restore a campaign setting or draft, but you cannot make a sent email unread or erase a public impression of an incorrect claim. Keep human approval in front of actions whose consequences cannot be meaningfully reversed.

    Key takeaways

    • Trust is a property of the whole workflow: data, context, permissions, evidence, review, monitoring, and recovery.
    • Start with a bounded, read-only decision whose correct inputs and safe output can be described precisely.
    • Treat data freshness, data maturity, and business meaning as separate requirements.
    • Grant the minimum fields and tools needed for the job; broad access is not a substitute for context.
    • Increase autonomy according to consequence and reversibility, not model fluency.
    • Make abstention, escalation, and evidence-bearing recommendations part of the success criteria.
    • Version every component that can change behavior, then retest and monitor real-world use.

    Pick the smallest marketing decision that currently consumes repeated human attention. Write its job card and data contract before connecting an agent. If you cannot define the evidence, permissions, reviewer, and stop path, the workflow is not ready for autonomy. If you can, you have a foundation that can earn broader responsibility instead of merely requesting trust.

    References

  • How to Evaluate AI Marketing Tools Before You Commit

    How to Evaluate AI Marketing Tools Before You Commit

    An AI marketing tool can look persuasive in a demonstration and still fail in day-to-day use. A sound evaluation therefore has to connect the product to a defined business problem, credible evidence, acceptable data practices and the team’s actual capacity to adopt it.

    The most useful approach is a staged decision process. Each stage should eliminate a different kind of risk before price or novelty turns an interesting product into an expensive commitment.

    Turn the business need into a testable decision

    Evaluation should begin with the marketing problem rather than the product’s feature list. The source article recommends asking vendors to explain the challenge their tool addresses and how solving it affects a business outcome. If that connection remains vague, a sophisticated set of AI capabilities does not establish that the product is useful.

    Before meeting a vendor, the buying team can create a short decision brief describing the current workflow, its most important constraint, the people affected and the result that should improve. That result might concern output, troubleshooting or another outcome already important to the organization. The purpose is not to manufacture a justification for buying software; it is to establish a baseline against which the tool can be judged.

    Claims about saving time require an additional question: what will the organization do with the recovered capacity? The source cautions that time savings are not automatically valuable. They become meaningful when the team can redirect that time toward work that advances an existing objective.

    This framing also exposes unnecessary purchases. If the problem can be resolved through a process change, better use of an existing platform or clearer ownership, adding another tool may increase complexity without addressing the underlying constraint.

    Match the evidence standard to the vendor’s maturity

    A glowing software module passes through a sequence of visual testing gates in a modern evaluation lab.

    A relevant case study is more informative than a broad success claim. According to the source, buyers should look for evidence involving organizations with a comparable size, market, vertical or use case, along with concrete results. The closer the operating conditions are to the buyer’s own environment, the easier it is to determine whether the evidence transfers.

    Evidence should also extend beyond customer logos. A credible vendor needs sufficient domain understanding to explain how marketers perform the work, where the recurring friction occurs and why the product was designed in its present form. The source notes that deep subject expertise does not have to reside with every salesperson, but a serious prospective customer should be able to reach someone who has it.

    Vendor maturity changes the appropriate test. An established provider can reasonably be expected to show repeatable results from relevant customers. An early-stage provider may not have that record, so transparency becomes part of the evidence: the vendor should identify where the product is unproven, explain what has been observed in other settings and define what the early partnership would require.

    Being an early adopter can offer an advantage, but the source also identifies added exposure to bugs, feedback demands and uncertain performance. Contract flexibility should reflect that imbalance. A newer vendor that expects the customer to absorb experimentation risk while offering no corresponding flexibility presents a weak partnership proposition.

    Treat data terms as part of the product

    Data governance is not a secondary legal review to perform after a product has been selected. It is part of the product evaluation because access to marketing, campaign or customer information can determine the consequences of a poor choice.
    The source recommends obtaining clear answers about who owns the customer’s data, where it is stored, how long it is retained, whether it is used for model training and what happens when the relationship ends. Any training of shared or third-party models should require explicit consent. If training is permitted only for a customer’s own instance, that limitation should be stated precisely.

    Verbal assurances are not enough. The source treats inconsistencies between a sales explanation and the terms of service as a warning sign and argues that material commitments belong in the contract. The practical evaluation standard is therefore documentary: can the vendor’s claims be located in binding terms, and do those terms cover the complete data lifecycle?
    This review also tests vendor quality. Clear, consistent answers suggest that the provider understands its own systems and customer obligations. Deflection or ambiguity leaves the buyer unable to assess exposure, regardless of how compelling the product appears.

    Calculate adoption cost, not just subscription cost

    A marketing team handles system setup, data preparation, training and workflow changes beside a simple subscription token.

    The commercial price is only one component of an AI tool’s cost. The source highlights implementation time, internal effort, integrations, training, quality assurance and possible disruption to the existing marketing technology stack. A product can be affordable on paper yet uneconomic if it consumes resources the organization cannot reliably provide.

    A useful implementation review follows the proposed tool through the real workflow. It identifies who will configure it, which systems must connect to it, who will review its outputs, how exceptions will be handled and what ongoing maintenance the vendor expects from the customer. This makes hidden dependencies visible before a contract creates pressure to proceed.

    Adoption is also a trust problem. As the source observes, a product that people cannot understand, trust or fit into their routines will not produce its promised value. The evaluation should therefore include the intended users, not only procurement leaders or executives. Their experience can reveal whether the tool removes friction or merely relocates it.

    A limited pilot can combine these questions into one decision. It should start with the predefined problem, use agreed evidence of success, operate under acceptable data terms and expose the actual workload imposed on the team. The decision at the end should account for both the result and the effort required to produce it.

    Key takeaways

    • Define the business problem and intended outcome before reviewing product features.
    • Demand evidence relevant to the organization’s size, market, vertical or use case.
    • Adjust expectations for vendor maturity, but require transparency and risk-sharing from early-stage providers.
    • Verify ownership, storage, retention, training and deletion terms in binding documents.
    • Evaluate implementation effort, workflow fit and user trust alongside the subscription price.

    As AI products continue to multiply, disciplined evaluation will matter more than rapid purchasing. Teams that document the problem, evidence threshold, governance requirements and adoption burden in advance will be better positioned to recognize tools that deserve a durable place in the marketing stack.

    References

  • AI Marketing Data Activation: From Signals to Outcomes

    AI Marketing Data Activation: From Signals to Outcomes

    AI-powered marketing data activation is not simply the use of a model to analyze a database. It is the operating discipline of turning available signals into decisions, actions, and measurable feedback while the information is still useful.

    The two source articles examine that challenge at different levels. One presents a focused SEO workflow that joins competitive, search, and engagement data to prioritize content. The other argues for an enterprise performance model in which a unified data foundation and activation layer help marketers pursue business outcomes without continually expanding the technology stack. Together, they show what separates an isolated AI task from a repeatable activation system.

    Data activation is a decision system, not another data store

    Marketing teams can possess substantial amounts of data and still struggle to act on it. The performance-marketing article identifies fragmented customer profiles, disconnected activation systems, and stale audience definitions as barriers that AI cannot overcome by itself. Its central argument is that many apparent model failures are actually failures in the underlying data and operating architecture.

    The content-gap workflow demonstrates the same issue in a narrower setting. Competitive rankings can expose thousands of missing keywords, but the list alone does not establish what the business should publish. The workflow adds Google Search Console signals and Google Analytics engagement data so that AI can interpret competitive opportunity alongside existing authority and business value.

    This distinction is fundamental: data collection produces records, analysis identifies patterns, and activation connects those patterns to an approved action. AI can accelerate interpretation and propose a course of action, but it does not eliminate the need for relevant inputs, decision criteria, or an execution path.

    Key takeaways

    • AI activation begins with connected, usable data rather than a model or agent selected in isolation.
    • First-party performance signals help distinguish attractive-looking opportunities from opportunities that support business goals.
    • A useful system converts a stated outcome into proposed logic, a reviewable action, and measurable feedback.
    • Human oversight remains important for competitor selection, exclusions, strategic context, and final approval.

    The right foundation combines relevance, quality, and access

    Three interlocking data layers support a glowing activation hub while incoming signals pass through quality filters and access gateways.

    A strong activation foundation does not require every available data point. It requires the information needed to make a particular decision, joined at a level that preserves its meaning. More inputs can create more noise when they represent irrelevant markets, incompatible intent, outdated definitions, or entities that should not be compared.

    The SEO source illustrates relevance through competitor selection. Its workflow narrows the comparison to three to five sites serving a similar business and audience, while generally filtering out marketplaces, community sites, reference properties, directories, and unrelated publishers that could distort the opportunity set. It also recommends a stakeholder check because product or sales teams may know about strategic competitors that are not yet obvious in organic-search data.

    Quality then depends on cleaning the inputs. The workflow removes duplicates and excludes such noise as competitor-branded terms, careers, login and support queries, out-of-scope locations, mismatched intent, and overly broad commercial terms. This is not clerical work around the edges of AI. It defines the boundaries within which the model can form useful clusters and recommendations.

    Access is the third requirement. The SEO article describes both manual exports and direct retrieval through Model Context Protocol connections. Either route can support the analysis; the important point is that competitive rankings, first-party search signals, and landing-page outcomes become available within one reasoning workflow. Direct connectivity may reduce transfer work, but it does not replace validation, exclusions, or governance.

    At enterprise scale, the performance-marketing source extends this principle to customer profiles and activation destinations. It argues that the data foundation and activation layer should operate as a connected performance engine. That is a broader architectural claim than the SEO example, but both approaches depend on the same underlying capability: AI must be able to interpret trusted context and pass an approved decision toward execution.

    A practical loop turns signals into marketing action

    The sources suggest an operating loop that can be applied beyond SEO or audience management. The specific datasets and delivery channels will vary, but the decision sequence remains useful:

    1. Define the outcome. Begin with the result the team wants to influence, such as improving a content opportunity, increasing customer value, or reducing churn. A clear outcome gives the model a basis for prioritization.
    2. Select decision-relevant signals. Combine external opportunity data with first-party evidence and business performance. In the content-gap example, those roles are filled by Semrush, Google Search Console, and Google Analytics respectively.
    3. Normalize and filter the inputs. Remove duplicate, stale, irrelevant, or mismatched records before asking AI to detect patterns. Retain the exclusions and assumptions so that another reviewer can understand the analytical boundary.
    4. Ask AI for structured proposals. The output should be reviewable logic rather than an opaque verdict: topic clusters, priority tiers, audience conditions, supporting evidence, and uncertainties are more useful than a bare recommendation.
    5. Apply business review. Marketers and relevant stakeholders should confirm that the proposed logic reflects strategy, customer meaning, brand constraints, and operational reality.
    6. Activate through a defined destination. An approved decision must connect to a content roadmap, audience system, campaign platform, or another execution process. Without this step, the workflow remains analysis rather than activation.
    7. Measure and feed back the result. Performance data should return to the decision process so the team can refine its definitions and priorities instead of repeatedly starting from a static segment or report.

    The SEO workflow makes the prioritization stage concrete. It looks for missing competitor topics, areas where competitors rank higher, and subjects where the site already leads. Search Console impressions and positions between 8 and 20 can indicate existing topical association, while Analytics engagement and conversion signals add evidence of business relevance. The resulting roadmap is therefore based on the relationship among opportunity, attainability, and value rather than search volume alone.

    The enterprise source applies outcome-led reasoning to audience creation. It describes an mParticle capability that lets a marketer express an objective in plain language, after which an agent proposes audience logic for review and approval. It also presents Audience Expansion and Household Reach as examples of using first-party data to seek additional prospects or address a wider decision-making unit. These are vendor-reported product examples, not independent proof of performance, but they illustrate how an AI proposal can be connected to an activation path.

    Governance and measurement keep automation useful

    A circular workflow connects signal collection, AI decision-making, channel actions, measurement, and a guarded oversight checkpoint.

    The sources do not support a hands-off model of marketing. The performance article explicitly frames the marketer as the leader and the agent as a collaborator. The SEO workflow likewise preserves human judgment when selecting competitors, defining exclusions, checking stakeholder knowledge, and deciding which opportunities belong on the roadmap.

    That division of labor offers a practical governance model. AI can reduce the effort required to reconcile large datasets, group related signals, draft audience logic, and surface patterns. People remain accountable for the objective, data scope, acceptable trade-offs, approval, and interpretation of results. A proposed segment or content cluster should therefore be traceable to its inputs and understandable before it reaches production.

    Measurement should also match the original outcome. The content-gap source uses organic sessions, engagement rate, average engagement time, key events or conversions, and landing-page performance to add business context. The performance source emphasizes outcomes such as customer lifetime value and churn rather than the operational completion of an audience-building task. In both cases, task completion is not the same as marketing success.

    A sensible maturity path is to begin with one bounded decision where data sources, reviewers, activation destinations, and success signals are identifiable. Once that loop is reliable, the organization can reuse its controls and feedback process for additional use cases. The durable advantage will come from shortening the distance between evidence and action while preserving the context and accountability that make the action worth taking.

    References

  • Why I Stop Positioning AI as a People Replacement

    Why I Stop Positioning AI as a People Replacement

    I think one of the biggest mistakes in AI marketing is positioning a product as a replacement for people. That message can win attention in the short term, but I believe it quietly drains trust over time.

    This is a little different from what I usually write about, but it matters. The way we talk about AI shapes how customers, employees, executives, and markets respond to it.

    In this memo, I want to focus on three things: why “substitution positioning” feels powerful at first but weakens a brand later, what the data says about whether AI is actually replacing people, and how I think companies should position AI instead.

    Image

    The cardinal sin of positioning in the AI era is replacement. I call it substitution positioning. It is tempting because it sounds bold, efficient, and disruptive. But over time, it creates anxiety, skepticism, and credibility problems.

    We have seen this pattern already. Anthropic CEO Dario Amodei predicted that software engineering jobs could disappear within 6 to 12 months as models began doing most or all of what software engineers do end to end. Yet demand for software engineers has continued to look strong.

    Image

    OpenAI CEO Sam Altman also predicted that many customer support jobs would go away because AI could handle that work better. Soon after, customer service hiring began outpacing the broader job market.

    I understand why fear works as a marketing tool. The fear of being replaced gets attention fast. It got me, too. When powerful AI models gained traction, I worried about my own future. But when I still see AI companies hiring copywriters, SEOs, engineers, and support teams, I sleep better.

    Image

    Fear sells because it taps into fight-or-flight. Layoffs make that story even louder. They let companies frame cost-cutting as innovation and make the replacement narrative feel more real than it may actually be.

    But I do not think the facts support the clean replacement story. In New York, companies can indicate when mass layoffs are caused by technological innovation or automation. In one reported period, more than 160 companies filed mass layoffs affecting roughly 28,300 workers, and not one chose AI as the reason. That list included companies such as Amazon and Goldman Sachs.

    Image

    Researchers at Yale also studied employment data from the Current Population Survey over 33 months and found no evidence of job displacement from AI. To me, the pattern looks less like instant replacement and more like the earlier waves of computers and the internet changing how work gets done.

    That is why I keep coming back to this point: stop trying to make replacement happen. It is not happening in the simple, dramatic way many AI narratives suggest.

    Image

    AI is powerful, but it is also inconsistent. In its current form, it can do some tasks better than humans and fail badly at others. That paradox is often called the Jagged Frontier.

    The Jagged Frontier idea matters because it explains why some people see AI as transformative while others remain lukewarm. A BCG and Harvard study of 758 knowledge workers found that people get the most value from AI when they understand what it is good at and where it breaks down.

    Image

    Microsoft reached a similar conclusion in its 2026 Work Trend Index Annual Report. The company found that a small group of advanced AI users, described as Frontier Professionals, were not simply using AI more often. They also knew which mode of AI use fit each task.

    That distinction is important. The best AI users are not handing everything over blindly. They are applying judgment. They know when to use AI as a helper, when to use it as a collaborator, when to use agents for multi-step workflows, and when to keep a human firmly in control.

    Image

    I still do not trust most AI workflows enough to leave them running with no maintenance, review, or quality assurance. The question I ask is simple: would I bet my brand, customer experience, or revenue on a fully automated workflow with no human oversight?

    Klarna is a useful warning here. The company publicly promoted the idea that AI was doing the work of hundreds of agents and helping reduce headcount. Later, it reversed course and rehired humans after leadership acknowledged that aggressive cost-cutting had lowered quality and that customers still wanted a human option.

    Image

    That is the tradeoff I see with substitution positioning. It creates immediate attention, but it can damage long-term credibility. The words often do not match the operational reality.

    Replacement positioning could work if customers truly wanted full replacement and if the technology were consistently ready for it. I do not think either condition is true.

    Image

    Cost reduction is a strong AI argument because it shows up quickly on the P&L. Productivity gains usually take longer. They build inside companies over time and often take even longer to appear across the broader economy.

    But when replacement positioning goes beyond cost-cutting and becomes people-cutting, I believe it starts to antagonize the very people companies need to win over.

    Image

    We have already seen backlash. Duolingo’s AI-first memo drew heavy criticism before the company reframed AI as a tool to accelerate work rather than replace contractors. Surveys have found that some workers refuse to use AI tools because they fear job loss. Pew has reported that many U.S. adults are more concerned than excited about AI in daily life. Reuters/Ipsos polling has shown widespread fear that AI will permanently displace workers.

    There is also a quality problem. When employees believe the purpose of AI is to replace them, they may disengage or produce lower-quality work. In my view, that is not just an adoption issue. It is a positioning failure.

    Image

    Executives often feel more excited about AI than the employees asked to use it every day. That gap matters. If leadership talks about AI as a replacement engine, employees hear a threat. If leadership talks about AI as leverage, employees have a reason to learn.

    Token economics also complicate the replacement story. Some companies have bragged about massive AI usage, but token costs are still a real business variable. As those costs normalize, the math may make junior employees look interesting again, especially when human judgment, context, and accountability are part of the output.

    So what should replace replacement? I think the answer is enhancement. Instead of positioning AI as a way to remove people, I would position it as a way to make capable people more effective.

    AI can be used in two broad ways. A company can try to reduce the number of people, or it can grow output with the same number of people. The data I have seen suggests that productivity gains often create the stronger return.

    A National Bureau of Economic Research paper surveyed 750 executives about AI’s impact on productivity and labor markets. Larger firms showed more interest in replacing labor costs, but the highest ROI came from productivity growth.

    That is the lesson I take from the research: doing more with the talent you already have is often stronger than trying to remove the talent that knows what good work looks like.

    Building products has become easier, but distribution has not. When supply explodes, the scarce thing is not output. The scarce thing is being the product, brand, or service that actually gets chosen.

    That is why positioning matters more than ever. Product quality still matters, but the way I frame AI use can determine whether people see it as empowering or threatening.

    My takeaway is simple: I would stop selling AI as a people replacement. I would sell it as judgment leverage, workflow acceleration, and creative expansion. Fear can get attention, but empowerment is a better long-term strategy.

    This post first appeared on the author’s website and is republished here with permission.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot