You have an AI visibility dashboard, an optimization assistant, automated reports, and perhaps a system that can change campaigns or content. The uncomfortable question is no longer whether the tools can produce more data or recommendations. It is whether anyone will notice when they are wrong, incomplete, disconnected, or silently doing nothing.
The answer is not another dashboard. You need a control system around the tools: named owners, visible baselines, actionable alerts, approval boundaries, independent checks, and a record of what changed. Build that first, and AI can remove repetitive work without removing judgment.
The control problem starts where the dashboard ends
Marketing failures are often obvious in retrospect and almost invisible while they are happening. In one paid-search account, all Bing campaigns across North America remained paused for three months. The advertiser was spending millions each month, three agency employees worked on the account alongside an internal team, and the client still discovered the problem first.
The important detail is not the mistaken click. Human errors are inevitable. The deeper failure was that the operating system had no effective way to detect a large, unexpected change. People were processing enormous CSV files and completing campaign work, but execution activity was mistaken for oversight.
The same weakness can hide inside an AI search program. A report can arrive on schedule while its prompt runs are incomplete. A visibility score can move because the monitored query set changed. An optimization assistant can recommend content that is plausible but irrelevant to the buyer. An automated workflow can publish technically valid schema that misrepresents what the page actually offers.
Tool coverage is not operational ownership. Before adding another platform, make sure every important system can answer five questions:
- What exactly is being observed or changed?
- How will we know if the system stops working or produces an abnormal result?
- Who receives that signal and owns the investigation?
- Which actions may happen automatically, and which require approval?
- How do we verify the result and reverse a harmful change?
Those questions reveal four distinct roles that vendors often blur together:
| Tool role | What it should do | Required human control |
|---|---|---|
| Observer | Collect AI mentions, citations, query data, traffic, spend, conversions, or technical status | Confirm coverage, freshness, and whether a movement is real |
| Advisor | Recommend content, targeting, schema, or campaign changes | Test the reasoning against business context and supporting evidence |
| Operator | Apply an approved change to a live system | Limit permissions, define scope, log the action, and preserve rollback |
| Auditor | Check whether the observer, advisor, and operator behaved as expected | Escalate exceptions to an accountable owner |
A single product may perform more than one role, but your governance should keep the roles conceptually separate. The system that proposes a change should not be treated as sufficient proof that the change worked. The automation that edits a campaign or page should not be its own only auditor.
Build a minimum viable oversight loop
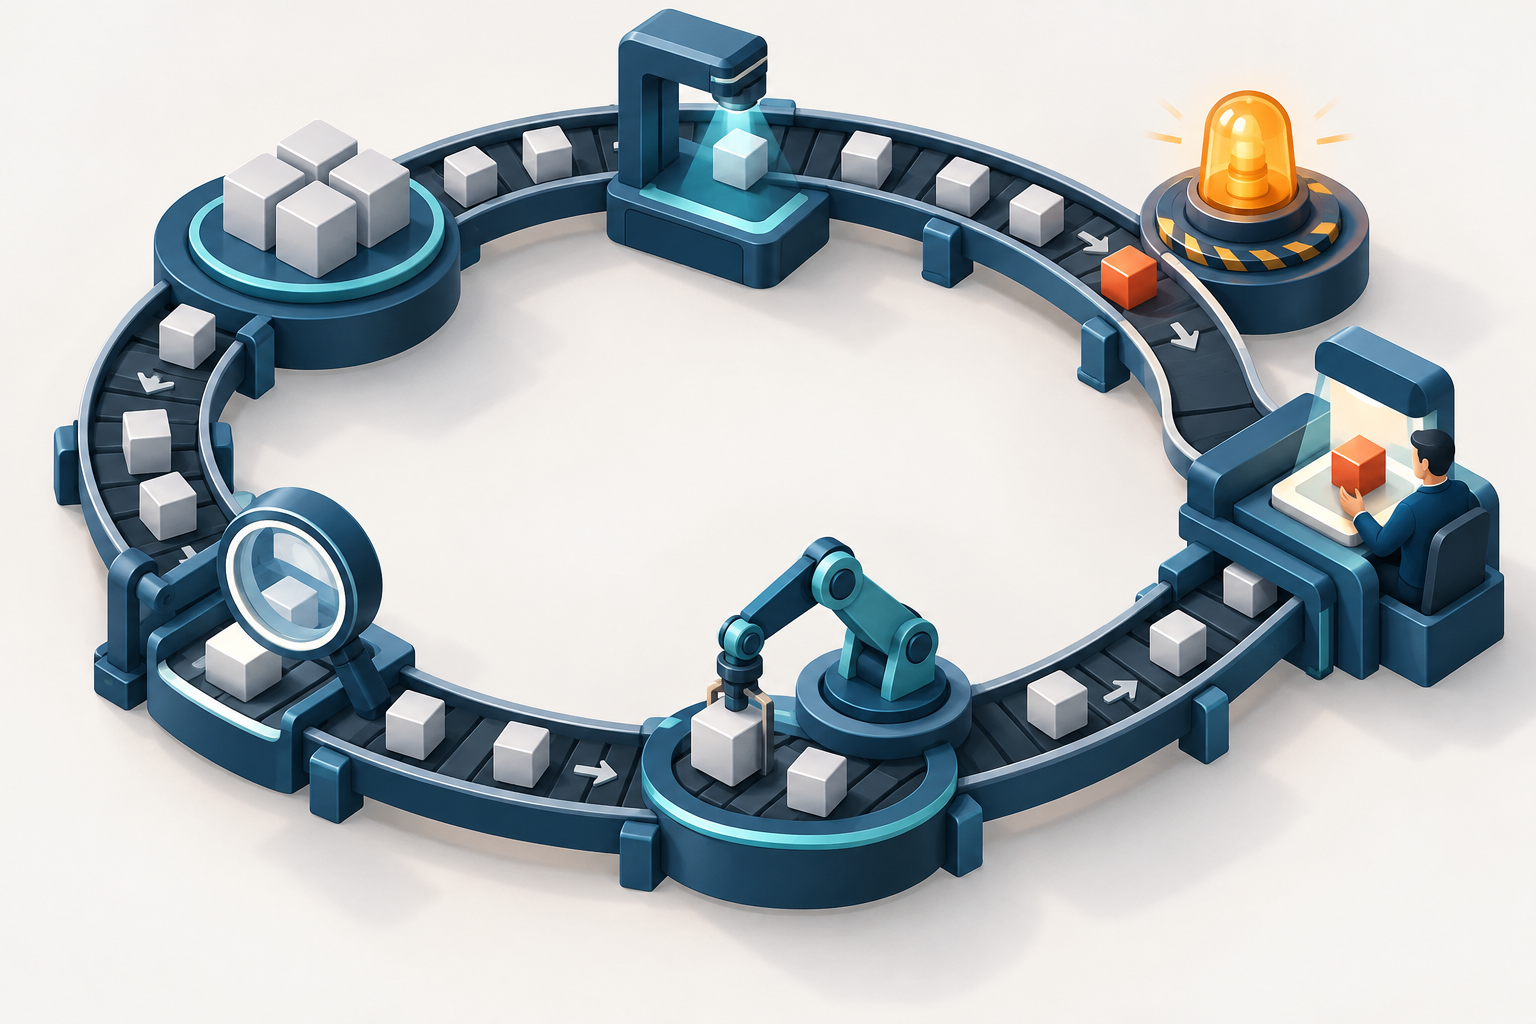
You do not need an elaborate governance department to control AI search marketing. You need a loop that turns abnormal conditions into owned decisions. Build it in this order.
- Separate the business outcome from the tool signal. Revenue, qualified leads, retained customers, and profitable acquisition are outcomes. AI mentions, citations, visibility scores, organic rankings, search terms, traffic, spend, and conversions are signals at different points in the chain. Record which outcome each signal is meant to inform.
- Define the monitored surface. Name the search engine, AI assistant, market, language, device or interface when relevant, query or prompt set, page group, campaign, and data source. A metric without scope cannot be interpreted consistently.
- Record a baseline before automating a response. Use your own recent operating pattern and business tolerance. Do not accept a vendor default merely because it is available. A retailer with volatile promotions and a B2B company with a narrow query set should not share the same trigger logic.
- Create alerts for silent failures first. Prioritize conditions that could remain unnoticed: zero or near-zero activity, missing prompt runs, stale data, failed tracking, an unexpected coverage gap, a sudden drop in spend or conversions, or an automation that did not complete. Simple email or Slack alerts can be more valuable than sophisticated recommendations if they surface the right exception.
- Give every alert an owner and response rule. Specify who investigates, where the investigation is recorded, what evidence is required, and who can authorize remediation. An alert sent to a crowded group channel without an owner is only another report.
- Verify through an independent view. Check a campaign state in the advertising platform, a deployed page in the browser, schema in the rendered output, referral activity in analytics, or stored AI responses behind a visibility score. Verification should come from something other than the workflow that made the change.
- Close the loop. Record the cause, correction, impact, and preventive control. If a mistake exposes a missing alert, permission boundary, or review step, change the operating system rather than relying on people to remember the incident.
Use three review rhythms for three different jobs
Automation should watch continuously or on the shortest practical schedule for broken tracking, missing data, stopped campaigns, failed jobs, and abrupt departures from normal activity. This is machine work: repetitive, narrow, and time-sensitive.
A regular human exception review should examine alerts, unresolved anomalies, automated changes, and failed validations. The reviewer is not there to admire a report. The reviewer decides whether the signal requires action, deeper investigation, or dismissal with a documented reason.
A slower strategy review should challenge the assumptions underneath the system. Are the monitored prompts still connected to customer demand? Do the pages being optimized serve a commercial or informational purpose? Are visibility movements associated with useful visits, leads, or sales? Has the business changed while the monitoring configuration stayed still?
This separation prevents a common failure: asking a fast operational dashboard to answer a slow strategic question. An alert can tell you that a metric moved. It cannot decide whether the metric still deserves attention.
Choose AI search tools by the decision they improve
The selection problem is getting harder because the category is crowded. There are already at least 13 tools positioned around ChatGPT optimization and brand visibility, with differences in engine coverage, tracking, and pricing. A longer feature list will not tell you which one belongs in your workflow.
Start with a decision, not a demo. Examples include deciding which pages need factual improvements, which customer questions lack a credible answer, where competitors are cited instead of your brand, or whether a technical deployment reduced discoverability. Then evaluate whether the tool produces evidence that makes that decision better.
- Surface coverage: Which assistants, search experiences, markets, and languages are actually measured? Does the vendor distinguish between products and interfaces, or combine them into an ambiguous visibility number?
- Measurement design: Can you see the monitored prompts or queries, how they were selected, when they run, and whether they changed? A score is difficult to trust when its denominator and sampling method are hidden.
- Evidence access: Can you inspect the underlying response, citation, mention, timestamp, and relevant page? You should be able to move from a chart to the observation behind it.
- Freshness and failure reporting: Does the platform disclose delayed, skipped, or failed checks? Ask what happens when an engine cannot be queried or an integration stops sending data.
- History and comparability: Can you distinguish a real visibility change from a change in prompts, engine coverage, tracking configuration, or scoring logic?
- Workflow fit: Can an anomaly reach the person responsible for acting on it? Look for useful exports, integrations, ownership fields, annotations, and change history rather than a report that must be manually reinterpreted elsewhere.
- Business connection: Can the data be compared with search demand, analytics, conversions, customer questions, and content performance? AI visibility alone is an intermediate signal, not proof of commercial value.
- Commercial and access controls: Identify what determines cost, who can see sensitive data, who can change configurations, and whether essential evidence or exports sit behind a higher plan.
Pilot the failure modes, not just the happy path
A good pilot does more than produce an attractive baseline report. Keep the monitored scope stable, document the configuration, and test whether your team can trace a metric back to evidence. Then deliberately inspect how the tool handles incomplete runs, stale integrations, absent data, large movements, and configuration changes.
Ask the team using the pilot to produce one decision record. It should identify the observation, explain the likely cause, show the supporting evidence, propose an action, name the approver, define validation, and state how the change could be reversed. If the platform cannot support that modest workflow, adding more tracked prompts will not solve the problem.
Be especially careful with composite visibility scores. Treat them as navigation aids, not ground truth. A score can help you find where to investigate, but it should not trigger a high-impact content, technical, or budget change unless you can inspect the components that moved.
Keep business judgment outside the automation loop
AI is well suited to bounded tasks: generating a monitoring script, checking for missing data, classifying anomalies, drafting a content brief, or assembling evidence for review. It is much less reliable as the sole author of strategy because strategy depends on constraints that may never appear in the platform.
Your tool may not know that a service has low margins, a product is unavailable in one market, a lead type rarely closes, a legal review is required, a sales team uses different terminology, or a highly visible topic attracts the wrong customer. Someone who understands the business must supply and challenge that context.
Require a short decision record before any material automated change:
- Objective: What business result is this intended to improve?
- Evidence: Which raw observations support the change, and what evidence points against it?
- Scope: Which pages, queries, campaigns, markets, or systems will be affected?
- Assumptions: What must be true for the recommendation to work?
- Risk: What could be lost through an incorrect change, including traffic, spend, data integrity, conversions, or trust?
- Approval: Who has enough business and channel knowledge to authorize it?
- Validation: Which signal will show whether the change worked, and which guardrail will reveal harm?
- Rollback: How will you restore the previous state without reconstructing it from memory?
This record is deliberately small. Its purpose is to stop plausible AI output from sliding directly into production without a falsifiable reason.
You should apply the same skepticism to broad claims about changing search behavior. A preliminary analysis covering two years of Google Ads search terms across hundreds of accounts in France, the UK, and the US found that average query length remained relatively flat. That does not prove AI is having no effect on search behavior. It shows that one popular assumption, that paid-search queries must already be getting longer and more conversational, was not demonstrated by that measure in those datasets.
The operational lesson is simple: do not let an AI-era narrative substitute for your own evidence. Examine your search terms, customer questions, analytics, conversion paths, and recorded AI responses. If the data contradicts a platform recommendation, investigate the contradiction before changing your strategy.
Give automation a smaller permission boundary than its capability
A system may be capable of editing every campaign or publishing across the site. That does not mean it should have permission to do so. Start with read-only access. Move to drafted recommendations, then to approved changes, and only then consider bounded automatic execution for repetitive, reversible actions.
Define boundaries by impact, not convenience. An automated annotation or internal alert has a different risk profile from changing bids, pausing campaigns, rewriting a product claim, modifying canonical tags, or publishing structured data. The more difficult a change is to detect or reverse, the stronger the approval and independent verification should be.
Archive the previous state before a live change. Record who or what initiated it, the approved scope, the execution time, and the validation result. A change log is not administrative clutter; it is how you separate cause from coincidence when metrics move later.
Key takeaways for a controlled AI search stack
- Buy tools for a defined decision, not for the size of their feature list.
- Treat AI visibility as an intermediate, sampled signal that must be connected to business outcomes.
- Monitor missing and stale data as aggressively as falling performance.
- Attach every important alert to an owner, an investigation path, and an escalation rule.
- Keep observation, recommendation, execution, and audit separate, even when one platform performs all four.
- Require evidence, approval, validation, and rollback before material automated changes.
- Use your own search, customer, analytics, and conversion data to test assumptions about AI-driven behavior.
- Reduce permissions until an automation has proved reliable within a clearly bounded scope.
Your next move is not to replace your stack. Choose its most expensive silent failure, define the signal that would expose it, name the person who owns the response, and test the full path from alert to verified correction. Once that loop works, expand it one risk at a time.
References
- Search Engine Land — Rémi Kerhoas’ shares how a PPC mistake went unnoticed for three months
- HiGoodie Blog — 13 Best ChatGPT Optimization Tools for Brand Visibility 2026

Leave a Reply