Tag: Auditing

  • A Practical Quality-Control System for AI-Driven SEO

    A Practical Quality-Control System for AI-Driven SEO

    You have a polished AI-generated SEO audit open in front of you. The findings sound technical, the recommendations are neatly prioritized, and the implementation plan looks ready to hand to a developer. The difficult question is whether any of it is safe to ship.

    An AI system doesn’t need to invent an entire audit to cause damage. One unsupported crawl diagnosis can trigger an unnecessary rebuild. One incorrect indexing assumption can send a team into Google Search Console looking for a problem that isn’t there. One generic content plan can consume a quarter’s budget without giving searchers anything new. The answer is not to remove AI from SEO. It is to make evidence, approval, and accountability part of the production system.

    Key takeaways

    • Classify every material AI claim as observed, inferred, or unverified before it enters an audit or roadmap.
    • Treat missing access as an unknown, not as evidence that a setting, submission, profile, or configuration is missing.
    • Set the review burden according to the change’s blast radius. Template rules, indexing controls, redirects, structured data, and programmatic pages need stronger gates than draft copy.
    • Judge AI-assisted content by accuracy, originality, usefulness, and intent alignment rather than by whether a model helped write it.
    • Give every recommendation a named verifier, approver, implementation owner, success measure, and rollback condition.

    Make every AI finding prove what it claims
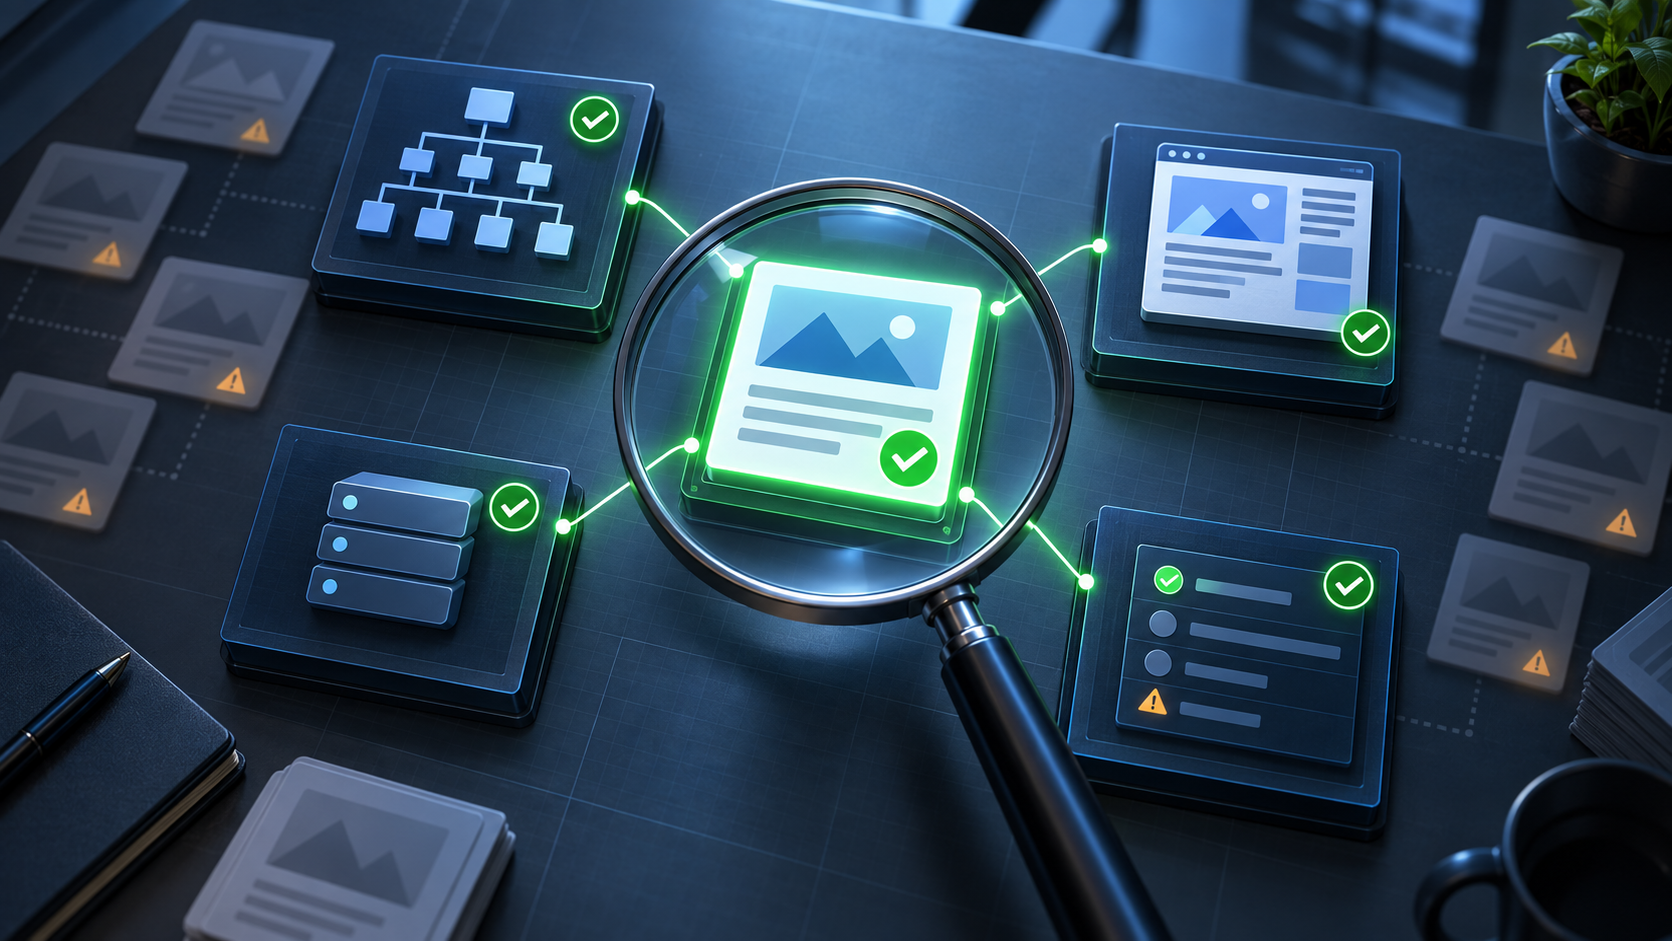
    A magnifying lens examines a digital recommendation connected to several sources of website evidence.

    The most important distinction in AI-assisted SEO is not human versus machine. It is evidence versus assumption.

    Require the model to label each finding before it recommends a fix:

    • Observed: The condition is directly visible in an identified crawl row, response, rendered page, account report, or CMS setting. The finding should point to that evidence.
    • Inferred: The available evidence supports an explanation, but other explanations remain possible. The finding should state those alternatives and describe the check that would distinguish them.
    • Unverified: The required system, account, page state, or business fact was not available. This belongs in a request-for-access list, not a defect list.

    This prevents a common failure: converting unavailable information into a negative finding. A model working from crawl exports cannot know whether a sitemap has been submitted in Google Search Console. In one 41-site venue audit, that unsupported claim still appeared on every owner-facing sheet. The same work produced a recommendation to claim an already-claimed Google Business Profile and a JavaScript crawlability diagnosis for a one-page HTML site.

    Each statement sounded plausible. None was established by the data the model had. Use a claim-to-evidence gate like this:

    Proposed findingEvidence neededRelease condition
    JavaScript is blocking crawlabilityRepresentative URLs, server responses, raw HTML, rendered HTML, and the specific content or links that disappear without renderingReproduce the failure and rule out a simple HTML page, an isolated script error, or a crawler configuration problem
    The Google Business Profile is unclaimedThe current claim state from the live listing or an authorized business accountVerify ownership status before assigning an ownership task
    No sitemap has been submittedThe Sitemaps report in the relevant Google Search Console propertyIf account access is absent, label submission status unverified; finding an XML file does not prove submission
    Duplicate URLs are harmless parameter variationsURL samples, response codes, rendered content, canonical signals, internal links, and the rule producing the variantsMap the pattern before choosing canonicalization, redirection, consolidation, or no action
    A title tag needs optimizationPage purpose, target query, current title, competing intent, brand constraints, and available performance dataConfirm that the proposed title is accurate, distinctive, useful, and aligned with the page rather than merely containing a keyword

    An inference is not automatically bad. Technical SEO requires inference because crawls, indexes, analytics, and live pages expose different parts of the system. The failure occurs when an inference is presented as an observation and the uncertainty disappears before the recommendation reaches the decision-maker.

    Put consequential SEO changes behind release gates
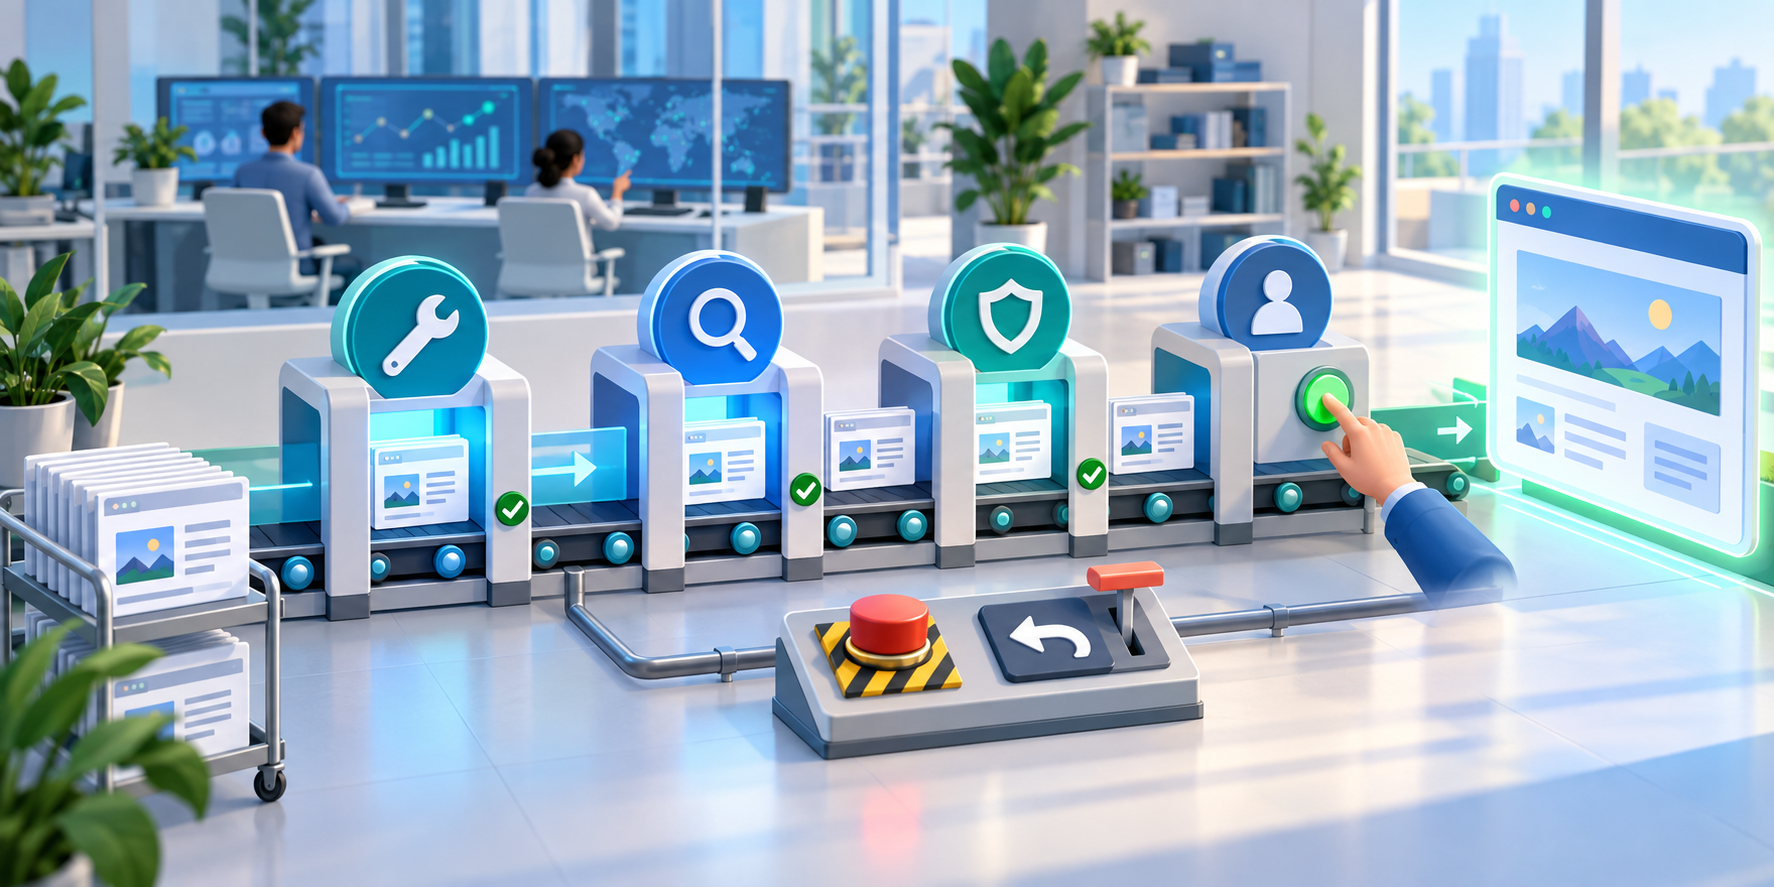
    A webpage component passes through several review stations before reaching a live website.

    AI is well suited to extracting repeated patterns, grouping crawl data, drafting hypotheses, comparing fields, and assembling first-pass documentation. It should not silently become the person who decides what is true, which risk is acceptable, or whether a production change goes live.

    Use this workflow for audits, content programs, schema deployments, local optimization, and AI-search initiatives:

    1. Define the decision. Ask a bounded question such as whether a URL pattern should be consolidated, whether a template exposes sufficient entity information, or why a page group is not being indexed. A request to find SEO problems invites a long list without a business hierarchy.
    2. Inventory the available evidence. Record which crawls, analytics properties, Google Search Console properties, CMS templates, log files, local listings, keyword data, and business facts are actually available. Make access gaps explicit in the prompt and the deliverable.
    3. Require structured claims. Have the model return the affected scope, evidence, claim type, alternative explanation, confidence, proposed action, and validation method. Reject conclusions that cannot point back to an input.
    4. Verify patterns, not just isolated rows. Inspect examples that match the proposed rule and counterexamples that do not. A valid example proves that a condition can occur; it does not prove the model has correctly described the entire URL class.
    5. Prioritize by impact, confidence, and reversibility. A dramatic recommendation with weak evidence should not outrank a well-supported issue tied to discovery, conversion, or operational cost. Separate confidence in the diagnosis from confidence in the proposed remedy.
    6. Stage the implementation. Preserve the current configuration, test on representative pages or a controlled environment, and define the check that must pass before wider release. For template changes, inspect more than the page used during development.
    7. Approve and monitor. Name the person who accepted the evidence and the person who released the change. Compare the result with the stated success measure, and revert or investigate when the agreed failure condition appears.

    Escalate review according to blast radius

    A copy suggestion held in a draft has limited downside. A rule that changes every canonical tag or generates thousands of pages does not. High-blast-radius work includes robots directives, noindex rules, redirects, canonical logic, automated internal links, sitewide structured data, reusable title templates, programmatic landing pages, and changes to business identity information. Require direct evidence, human approval, staged deployment, and a rollback path for these changes.

    Pattern detection also deserves human review even when the model has the right dataset. One crawl contained 111 duplicate title tags caused by show names appended to default.aspx as path segments, with the variants rendering the same page. The model did not identify the underlying duplicate-URL problem until a person called attention to it. A fluent crawl summary is therefore not proof that the important pattern was found.

    Test the finished page for value, not for AI fingerprints

    An invisible watermark or other detectable authorship signal can indicate that a model contributed to text. It cannot tell you whether the page is accurate, original, useful, or appropriate for a query. Trying to disguise the production method solves the wrong quality problem.

    Google’s stated position is that appropriate use of AI or automation is not inherently against its guidelines. The relevant spam risk is scaled content created primarily to manipulate rankings while adding little or no value, regardless of whether people, software, or both produced it. That makes the release question straightforward: what does this page contribute that deserves to exist?

    Before an AI-assisted page is published, an editor should be able to answer yes to each of these questions:

    • Does the page have a specific job? It should resolve a recognizable question, comparison, task, or decision for a defined audience. A keyword variation alone is not a separate job.
    • Does it add something defensible? Useful additions can include verified facts, first-party expertise supplied by the organization, a clearer procedure, a meaningful comparison, a worked example, original data, or a synthesis that changes what the reader can do.
    • Can every concrete claim be traced? Names, dates, measurements, product behavior, quotations, and policy claims need an identifiable basis. A citation must support the exact sentence it is attached to.
    • Is the page distinct from existing URLs? Compare its purpose and substance with current pages, not only its title. If two URLs answer the same need, expanding or consolidating an existing page may be better than publishing another one.
    • Does the language fit the organization and the reader? Generic wording that could be moved unchanged to a competitor’s site is a warning that the model had too little real context.
    • Is the title both accurate and compelling? Keyword inclusion does not excuse a dull, repetitive, or misleading title. Preserve meaningful brand language when it already communicates the page’s value.
    • Does structured data describe visible reality? Validate the syntax, but also verify that names, types, relationships, offers, ratings, authorship, and other marked-up facts agree with the page and the business.
    • Would the page still be worth publishing without an expected ranking gain? If the answer is no, the content may exist for the search system rather than the person using it.

    Early traffic does not override these tests. A widely publicized scale experiment mirrored a competitor’s sitemap into roughly 1,800 generated articles and reached a reported 490,000 monthly visits, but the gains largely disappeared within months. The warning is not that AI-assisted pages cannot rank. It is that temporary acquisition does not prove durable value, sound strategy, or acceptable risk.

    Make accountability visible to clients and internal teams

    AI has made professional-looking SEO work easier to produce without making the underlying judgment easier. A clean roadmap, technical vocabulary, and a long issue list are weak signals of competence when software can generate all three.

    SEO still has no mandatory experience requirement or universal competency test. That leaves buyers and marketing leaders responsible for distinguishing genuine diagnosis from plausible output. A course badge can show that someone completed a course; it does not establish that the person can investigate an unfamiliar site, prioritize commercial consequences, or recognize when the available data cannot support an answer.

    Keep a decision record, not just a final deliverable

    For every recommendation that reaches a roadmap, retain:

    • A concise issue statement and the affected URL, template, entity, or account scope.
    • The raw evidence or a stable pointer to it.
    • The claim classification: observed, inferred, or unverified.
    • Alternative explanations considered and the checks used to exclude them.
    • The expected user or business consequence.
    • The proposed change and the reason it was selected over other remedies.
    • The person who verified the finding and the person who approved the action.
    • The release date, success measure, monitoring location, and rollback condition.
    • The actual result, including neutral or negative outcomes.

    This record creates a chain from evidence to outcome. It also makes corrections useful. When a recommendation fails, the team can see whether the diagnosis was wrong, the implementation changed, an assumption was untested, or the expected effect simply did not occur.

    Evaluate an SEO provider by how they reason

    If you are hiring an agency, consultant, employee, or AI-search specialist, ask them to work backward from a recommendation:

    • Show the raw evidence behind one important finding and explain what it does and does not establish.
    • Describe a recommendation they rejected after investigation and what changed their assessment.
    • Identify the unavailable data that could materially change the current diagnosis.
    • Explain which proposed change has the largest blast radius and how they would test and reverse it.
    • Separate the business outcome from the activity they will report. Published pages, completed audits, and fixed tickets are outputs, not proof of organic growth or improved visibility.
    • State what result would cause them to revise the strategy rather than defend it.

    Be cautious when every finding carries the same confidence, recommendations have no inspectable evidence, a provider guarantees a ranking position, or the report measures work volume without connecting it to discovery, qualified traffic, leads, revenue, or another agreed objective. Competence is visible in diagnosis, prioritization, restraint, and explanation, not in the number of defects a tool can list.

    Start with one AI-assisted audit already in your pipeline. Select the recommendation with the largest potential effect, trace it back to the raw evidence, and name what would disprove it. If the necessary access is missing, relabel the finding as unverified. If the evidence holds, stage the change, assign an owner, and record the outcome. That single release gate turns AI from an unaccountable answer generator into a supervised SEO instrument.

    References


  • Long-Term SEO Lessons for Durable AI Search Visibility

    Long-Term SEO Lessons for Durable AI Search Visibility

    If you are deciding whether AI search means rebuilding your SEO program, do not begin by renaming every task GEO. First separate what has changed from what has not. Interfaces now accept longer prompts, follow-up questions, images, and richer context. Your underlying job is still to understand what someone needs, make the answer accessible, support it with credible evidence, and connect that answer to a useful next step.

    The durable advantage is not predicting the next interface. It is building an SEO system that can absorb interface changes without abandoning sound diagnosis, technical access, content quality, or business judgment.

    Search interfaces change; the user’s job survives

    A person in a circular workspace follows one illuminated path past a keyboard, conversation form, camera, and context panels toward a practical solution.

    A keyword is not the need itself. It is the amount of that need a particular search box allows someone to express. Short search fields encouraged compressed phrases. Conversational systems let people add requirements, objections, examples, and follow-up questions. Multimodal systems can accept a screenshot instead of forcing the user to describe what is on it.

    This matters because a keyword list can capture familiar language while missing much of the context people now supply. A 17-month Semrush clickstream analysis credited to Luke Harsel found that 65% to 85% of ChatGPT prompts matched no term in a database of 27 billion keywords. That finding does not make keyword research obsolete. It shows why keyword volume cannot be treated as a complete map of demand.

    Use keywords as clues, then build around intent. For every important page or topic, create an intent brief with five fields:

    <!– wp:list {
  • How to Run an AI Brand Visibility Audit That Drives Action

    How to Run an AI Brand Visibility Audit That Drives Action

    Your search rankings can look healthy while an AI answer ignores your brand, describes it incorrectly, or recommends a competitor. That does not mean SEO stopped mattering. It means the outcome you need to measure has changed.

    A useful AI brand visibility audit shows where your brand appears, what the system claims about it, which evidence supports the answer, and why another brand may be selected instead. Traditional search visibility and AI visibility can diverge, so you cannot use rankings or local-pack presence as a substitute for this work.

    Key takeaways

    • Measure mentions, recommendations, citations, and factual accuracy separately. They are different outcomes with different fixes.
    • Test the questions customers ask while choosing, comparing, and validating options. A branded lookup alone cannot reveal whether AI systems discover your brand.
    • Check crawler access, entity consistency, factual specificity, claim support, unique information, and JSON-LD before treating missing visibility as a content-volume problem.
    • Treat one generated answer as an observation. Prioritize patterns that recur across relevant prompts, sessions, or AI surfaces.
    • Fix access barriers and incorrect facts before chasing more mentions. Being visible with the wrong information is not a win.

    Build a prompt set around customer decisions

    Blank prompt tiles branch between objects symbolizing product discovery, comparison, selection, purchase, and customer support.

    Start with the decision your customer is trying to make. A prompt such as What is [brand]? tests recognition and basic factual recall. It does not show whether your brand would be found when the customer has not named it.

    Create prompts for each commercially important audience, need, location, and constraint. Keep the wording neutral. If you tell the system that your brand is the leading option or ask why it was excluded, you have already biased the test.

    1. Discovery: Which [category] providers serve [audience or location] and meet [specific need]?
    2. Fit: Which option is suitable for someone who needs [feature, policy, use case, or constraint]?
    3. Comparison: How do [brand] and [competitor] differ for [specific decision]?
    4. Fact retrieval: What does [brand] offer, where is it available, and what policies apply?
    5. Validation: Is [brand] a credible option for [use case], and what evidence supports that assessment?

    Reuse the same wording when you want comparable observations. Begin a fresh conversation where possible, preserve the complete response, and record any visible citations. Do not reduce the result to a yes-or-no mention check.

    DimensionWhat to recordWhat it reveals
    PresenceAbsent, named, or described without a clear nameWhether the system associates your entity with the prompt
    ProminencePrimary recommendation, alternative, comparison subject, or passing mentionWhether visibility is commercially meaningful
    CitationYour site, another site, or no visible citationWhich evidence is available for inspection
    AccuracyCorrect, outdated, contradictory, unsupported, or unclearWhether visibility helps or harms the customer decision
    Competitive displacementWhich alternative appears and the stated reasonWhere another brand supplies stronger relevance or evidence

    Paid monitoring platforms can automate structured prompts across multiple AI surfaces and track mentions, citations, competitors, and inconsistencies over time. That automation is difficult to reproduce at scale, but the initial diagnostic can still be performed manually if you preserve the evidence and apply consistent labels.

    Inspect the signals behind each answer

    A glowing answer orb connected to layered source signals, including a webpage, document, storefront, reviews, and citation nodes, with strong, weak, and broken links.

    Prompt results show the symptom. Your next job is to find the upstream reason. More content is not the default answer: an access restriction, contradictory business fact, vague claim, or missing entity relationship can undermine an otherwise substantial site.

    Confirm that AI crawlers can reach meaningful content

    Open yourdomain.com/robots.txt and inspect any rules for GPTBot, ClaudeBot, PerplexityBot, and Google-Extended. A disallow rule may be an intentional policy choice, so document it before changing it. The audit question is whether access matches the organization’s actual policy, not whether every crawler should automatically be allowed.

    Then visit the site as a new user. Check whether the homepage or important landing pages hide their substantive content behind a cookie wall, language selector, location picker, or another interstitial. These gates can leave less-established crawlers unable to reach the facts even when conventional search crawling appears healthy.

    Map the entities the brand needs AI to understand

    List each distinct thing an answer may need to describe: the business, products or service lines, relevant staff, policies, locations, and location context. For each entity, record its canonical name, defining attributes, public URL, supporting evidence, and the person responsible for keeping it current.

    Do not treat a passing marketing mention as documentation. A location page that says conveniently located but gives no nearby landmarks, distances, transport details, or service area leaves the location entity underdefined. A service page that promises flexible options but never names those options creates the same problem.

    Compare important facts across the website, Google Business Profile, and other public representations. Different names, addresses, policies, descriptions, or availability statements create entity drift. Consistency is a foundational trust signal; decide which location is canonical, correct it first, and then align the rest.

    Test whether the facts are extractable and defensible

    AI systems can reuse a direct factual statement more cleanly than a sentence built from vague adjectives and unclear pronouns. Paste a priority page into an AI assistant and ask it to identify every pronoun, adjective, or phrase whose referent or meaning is ambiguous. Require a fact-specific rewrite for each flagged sentence, then verify the rewrite yourself before publishing it.

    Audit claims separately. Search your pages for best, most, only, award-winning, leading, and similar language. Record the evidence behind each claim, the entity that granted any award, and the page where a reader can verify it. If the evidence does not exist, narrow the statement to a supportable fact or remove it. An uncheckable superlative gives an AI system little reason to repeat the claim.

    Look for information gain and meaningful structured data

    Take several sentences from a priority page and search for them in quotation marks. If competitors could publish the same wording without changing a detail, the page contributes little unique evidence. Replace generic language with information your organization can substantiate: named processes, exact policy conditions, original measurements, specific product attributes, or first-party findings.

    View the page source and search for application/ld+json. No match means that page has no JSON-LD block. A match is only the beginning of the check: inspect whether the markup represents the actual entities and relationships on the page or merely supplies a thin, flat label.

    Verify that names, URLs, locations, and relationships agree with visible content. Inspect sameAs values carefully and use them only for records that genuinely identify the same entity, including applicable Wikidata or Knowledge Graph identifiers. Structured data can clarify identity and relationships, but its presence does not guarantee a recommendation.

    Turn response patterns into a prioritized diagnosis

    A single visibility percentage conceals the difference between absence, weak prominence, missing evidence, and factual error. Diagnose each repeated pattern before assigning work.

    Observed patternInvestigate firstAction to take
    Brand is absent from non-branded discovery promptsCrawler access, category association, location facts, and incomplete entitiesResolve access barriers and add explicit, supportable facts connecting the brand to the relevant need
    Brand appears only when namedWeak association with the use case, audience, category, or locationStrengthen the relevant entity pages with decision-ready facts rather than repeating the brand name
    Brand is mentioned with incorrect factsContradictory or outdated public representationsCorrect the canonical page, align external profiles, and document the changed fact for retesting
    A competitor is recommended and citedThe cited page’s specificity, proof, entity coverage, and fit to the promptIdentify the evidence your page lacks; do not copy the competitor’s wording
    Your site is cited but the brand is not recommendedEvidence for customer fit, limitations, policies, and differentiatorsMake the decision criteria explicit and support each material claim
    A recommendation appears without a visible citationAccuracy and reproducibility of the stated reasoningRecord the answer without guessing its origin, verify every claim, and look for the pattern in other tests

    Prioritize by consequence and dependency, not by whichever gap is easiest to edit.

    1. Remove access barriers that prevent important pages from being reached.
    2. Correct wrong or contradictory business facts, especially facts that could change a customer’s decision.
    3. Complete the commercially important entities and their location, product, service, staff, and policy attributes.
    4. Replace generic claims with verifiable evidence and information the brand uniquely possesses.
    5. Refine JSON-LD so it faithfully represents the corrected visible content and entity relationships.
    6. Rerun the unchanged prompts and compare the complete answers, not just the mention count.

    Each resulting ticket should contain the prompt, the complete observed answer, the affected customer decision, the suspected cause, the page or profile to change, the evidence required, and the retest condition. This keeps an AI visibility problem from becoming a vague request to improve the content.

    Make the audit repeatable without turning it into dashboard theater

    Keep a durable audit log. At minimum, capture the prompt, audience, need, location or constraint, AI surface, conversation state, observation date, full answer, prominence label, cited URLs, factual errors, named competitors, suspected cause, owner, and fix status. Preserve raw outputs even if you later calculate summary metrics.

    Repeat the audit with the same core prompt set after material changes to the website, business facts, policies, products, services, or locations. Add prompts when a genuinely new customer decision appears, but do not silently rewrite old prompts and compare the results as if the test stayed constant.

    Automation becomes useful when the number of prompts, AI surfaces, locations, or competitors makes manual tracking unreliable. Some platforms let teams ask natural-language questions and receive answers grounded in their own visibility data. That can speed up investigation, but the interface should still lead you back to inspectable evidence.

    Before adopting a paid visibility platform, verify that it can retain raw responses, expose citations, preserve prompt wording, distinguish mentions from recommendations, compare competitors, flag entity inconsistencies, and show change history. A polished composite score is not enough if you cannot trace it to the answer that created it.

    Begin with the customer decision that matters most. Capture the current answers, label what happened, and fix the first upstream failure: access, identity, specificity, evidence, or structure. Then rerun the same prompt. The practical goal is fewer missing, unsupported, and incorrect brand answers when a customer is ready to choose.

    References


  • Google Analytics Hostname Allowlists: A Safe Setup Plan

    Google Analytics Hostname Allowlists: A Safe Setup Plan

    Your Google Analytics reports can look convincing even when unwanted event traffic is mixed into the numbers. That becomes a practical problem when you use those numbers to allocate budget, judge content, or explain performance to a client.

    A hostname allowlist gives you a cleaner default: define where legitimate browser events may originate, then filter events associated with other hostnames. The important work is not creating the filter. It is identifying every valid hostname, understanding what the filter does not cover, and checking that your measurement still represents the customer journey.

    Why an Include filter is stronger than a growing blocklist

    Hostname filtering used to be built around Exclude filters. You found an unwanted hostname, added it to the filter, and repeated the process when another one appeared. Google Analytics now supports Include filters for approved hostnames, so events associated with hostnames outside your approved set can be filtered out.

    The difference is operational, not cosmetic. An exclusion list assumes you can keep discovering every bad or irrelevant hostname. An allowlist asks a more manageable question: which hostnames does this property intentionally measure?

    That makes the approach useful when spam or unwanted event traffic keeps resurfacing. It can also reduce the maintenance burden for an organization that operates several sites or routinely sees events from places that should not contribute to the property.

    The tradeoff is precision. A denylist fails open: something new remains until you exclude it. An allowlist fails closed for browser traffic: forget a legitimate hostname and its events can be filtered out. Treat the allowlist as part of your measurement architecture, not as a quick cleanup rule.

    Key takeaways

    • Use a hostname Include filter when you can define the trusted domains that should contribute browser events to the property.
    • Build the list from the intended customer journey and site architecture, not only from hostnames already visible in a potentially polluted report.
    • Do not confuse a hostname with a traffic source. The hostname identifies where the measured page or experience is hosted; it does not identify who sent the visitor there.
    • Expect events with an empty hostname to be blocked by the Include filter, and investigate them before assuming every empty value is spam.
    • Handle Measurement Protocol separately because hostname Include filters do not apply to those events.
    • Review the allowlist whenever a launch, migration, subdomain, or externally hosted journey changes where browser events originate.

    Build an allowlist that matches the real measurement journey

    A visitor journey connects a main website, regional site, store, hosted checkout, and support portal to one analytics hub.

    Start with what the property is supposed to measure

    Do not begin by copying every hostname you see in a report. That risks turning existing contamination into an approved list. Begin with the purpose of the property: which websites and browser-based experiences should contribute to its reporting?

    Map each stage of a journey that matters. Your main website may be obvious, but a legitimate interaction can also occur on a first-party subdomain or another hostname used for a deliberately measured step. Include such a hostname only when its events truly belong in this property. Ownership alone is not enough; relevance to the property’s measurement scope is the test.

    Record hostnames, not complete URLs. A page path such as a pricing or confirmation page is not another hostname. Keeping that distinction clear prevents a domain-control filter from becoming an improvised page-level rule.

    Event situationAllowlist decisionWhat to verify
    Browser event from the primary public websiteIncludeThe hostname is written exactly as it appears in the intended implementation.
    Browser event from a first-party subdomainInclude only if intentionalThe subdomain’s activity belongs in this property and supports a measured journey.
    Browser event from a staging or test environmentUsually keep separate unless explicitly requiredThe property is genuinely intended to contain test activity.
    Browser event from an unfamiliar third-party hostnameDo not approve by defaultA known business process deliberately generates relevant events there.
    Event with an empty hostnameAutomatically blocked by the Include filterThe missing value is not evidence of a broken legitimate collection path.
    Event sent through Measurement ProtocolNot governed by the hostname Include filterThe sending system and its event quality are controlled separately.

    Investigate empty hostname events before activation

    An Include filter automatically blocks events whose hostname is empty. That is useful because a missing hostname can indicate spam or abnormal activity. It is not proof that every affected event is malicious, however. Some traffic sent through gtag.js can also arrive without a hostname.

    Use that behavior as a diagnostic checkpoint. Before relying on the filter, determine whether an important browser journey produces empty hostname values. If it does, fix or intentionally account for the collection path rather than approving an unknown value or accepting an unexplained loss of data.

    The practical question is simple: if empty-hostname events disappear, will a real conversion, page interaction, or business process disappear with them? If you cannot answer that yet, the implementation is not ready to support decisions.

    Separate Measurement Protocol governance from browser filtering

    Hostname Include filters do not apply to Measurement Protocol events. That exception protects server-side and offline events from being unintentionally rejected by a browser-oriented hostname rule.

    It also means the allowlist is not a complete perimeter around the property. A property can have cleanly filtered browser events while continuing to receive Measurement Protocol events. Inventory those senders separately and confirm that each one is authorized, necessary, and mapped to the correct property.

    This distinction matters when you investigate a suspicious event after enabling the allowlist. Do not conclude that the filter failed merely because the event remains. First determine whether it arrived through the browser collection path or through Measurement Protocol. The two routes are subject to different controls.

    Roll out the filter without creating a reporting blind spot

    An analyst monitors parallel original and filtered event streams in a dark control room during a staged rollout.

    A useful rollout has three parts: scope, validation, and ownership. Skipping any one of them can replace noisy data with incomplete data, which is harder to notice because the reports may still look tidy.

    1. Write down the property’s purpose. State which sites, environments, and customer journeys should contribute events. This gives every hostname an explicit reason to be included or omitted.
    2. Inventory trusted browser hostnames. Check the primary domain, intentional subdomains, and any separate host involved in a measured step. Do not approve an unfamiliar hostname merely because it already appears in the data.
    3. Identify non-browser senders. List the systems that use Measurement Protocol so nobody assumes the hostname filter governs them.
    4. Create the hostname Include filter. Use the approved inventory as the filter’s specification. Keep the written inventory with the analytics configuration so future changes can be reviewed against it.
    5. Exercise critical journeys. Confirm that the browser-based pages and actions your team relies on still contribute the expected event types under their legitimate hostnames.
    6. Check the negative cases. Verify that unapproved browser hostnames and empty-hostname events no longer affect the filtered view of your data, while separately checking that intended Measurement Protocol activity remains accounted for.
    7. Assign an owner. Make one role responsible for reviewing the allowlist when the web architecture changes. Without ownership, a correct filter gradually becomes incomplete.

    Document why each hostname is trusted, not just its spelling. A short reason such as “public product site” or “measured account subdomain” gives the next reviewer enough context to remove obsolete entries and challenge unexplained additions.

    Know what cleaner analytics can and cannot improve

    A hostname allowlist is a data-quality control. It can make reports more dependable by preventing unapproved browser hostnames from distorting the dataset. That supports better decisions about acquisition, content, conversion, and campaign performance.

    It is not an SEO, AEO, or generative-engine ranking signal. Enabling it does not make a page more crawlable, authoritative, or likely to be cited by an AI system. The benefit is indirect: your team is less likely to prioritize a landing page, channel, or conversion path because unwanted traffic made it appear more important than it was.

    Be especially careful with trend comparisons around the change. A visible drop may represent removed noise, accidentally filtered legitimate activity, or both. Check hostname coverage and collection routes before interpreting the difference as a change in audience demand or marketing performance.

    Put the allowlist review into the same launch checklist you use for a new subdomain, domain migration, or externally hosted customer step. The next architecture change should update the measurement boundary before anyone relies on the resulting reports.

    References


  • Crawl Budget and Pagination: A Technical SEO Playbook

    Crawl Budget and Pagination: A Technical SEO Playbook

    If your products or archive posts disappear after page 1, reducing the number of crawlable URLs can feel like the obvious fix. It often is not. Pagination may be the only internal route that exposes deeper items, so removing it can turn crawl waste into orphaned content.

    The better objective is controlled discovery: give crawlers a finite, stable sequence through valuable content while preventing filters, sort orders, tracking parameters, and duplicate URL formats from multiplying that sequence. You protect crawl capacity by removing useless paths, not by hiding useful ones.

    First decide whether you have a crawl-budget problem

    Crawl budget is the time and computing resources a crawler is prepared to spend on your site. For Googlebot, it reflects both crawl capacity and crawl demand. Capacity concerns what your server can handle without becoming unstable. Demand concerns which URLs appear valuable or in need of another visit.

    Those two forces create different problems. Slow responses and server errors can cause a crawler to reduce its pace. Duplicate, low-value, or spam-like URL patterns can reduce the apparent value of fetching more URLs. A pagination fix cannot compensate for an unreliable server, and faster hosting cannot make an unlimited set of filter combinations worth crawling.

    Google’s criteria for active crawl-budget management are narrower than many teams assume. The clearest candidates are sites with more than 1 million unique pages, medium or large sites whose content changes frequently, and sites with many URLs marked “Discovered – currently not indexed” in Google Search Console.

    That does not mean a smaller site can skip the audit. Your catalog, article count, or CMS dashboard does not reveal the number of URLs a crawler can encounter. Facets, pagination, alternate parameter orders, languages, locations, search pages, and session values can turn one content set into many crawlable representations.

    • Inventory the exposed URLs. Crawl from the same public entry points available to search engines. Do not begin with a spreadsheet of products or posts.
    • Group URLs by pattern. Separate canonical content, pagination, filters, sort orders, internal search, tracking parameters, and malformed combinations.
    • Distinguish discovery from indexing. A URL that has never been fetched points to a different constraint than a fetched page that was judged unworthy of indexing.
    • Check server behavior. Look for timeouts, error responses, and URL patterns that require disproportionately expensive rendering or database work.

    There is no universal healthy number of crawls per day. A useful baseline is whether important new or changed URLs are discovered and revisited while requests to low-value patterns remain controlled. Measure that outcome on your own site instead of copying another domain’s crawl rate.

    Build pagination as discovery infrastructure

    A finite chain of page modules connects a category platform to multiple groups of content cards.

    Pagination divides one ordered content set into addressable pages. It adds URLs, but those URLs provide paths to products, posts, discussions, and other deeply nested content. That is productive crawl activity when each page exposes items that would otherwise be difficult to reach.

    A crawler should be able to begin at the first category or archive page, follow ordinary HTML links through the sequence, and reach every intended item. It should not need to click a JavaScript-only button, submit a form, maintain a session, or scroll until client-side code decides to load another batch.

    1. Choose one stable URL format. Formats such as ?page=2 or /page/2/ can work. Do not expose multiple formats for the same sequence.
    2. Use links with href destinations. Previous and next controls should be crawlable links. A short set of numbered links can provide additional routes into a long sequence.
    3. Link every listed item directly. Products and posts should have canonical destination URLs in the rendered listing, not destinations assembled only after an interaction.
    4. Give each page a distinct slice. Page 2 should not reproduce page 1 under a different URL. Stable ordering also reduces unnecessary repetition when crawlers revisit the sequence.
    5. Use a self-referencing canonical by default. If page 2 contains a distinct set of items, pointing its canonical to page 1 misrepresents that relationship. Consolidate only URLs that are genuinely equivalent.
    6. Keep page 1 canonicalized consistently. Link to one preferred first-page URL instead of alternating between the clean category URL and a duplicate such as ?page=1.
    7. Give infinite scroll a paginated fallback. Each batch should be available at a stable URL through crawlable links, even if human visitors receive a continuous visual experience.
    8. Stop at the real end of the sequence. Do not generate an endless run of empty page numbers. Remove internal links to pages beyond the last valid result and return an appropriate not-found response when an invalid page is requested.

    Do not automatically canonicalize every paginated URL to the first page or apply a blanket noindex directive. Overly aggressive canonicalization can prevent useful paginated URLs from appearing in search results, while removing their crawl value can make deeper items harder to find. A canonical signal expresses a preferred equivalent; it is not a general crawl-control switch.

    An XML sitemap helps crawlers discover canonical products, posts, and other destination pages, but it does not replace internal linking. Pagination remains an additional discovery route even when sitemaps are present. That route also shows how the content belongs within your site architecture.

    Do not spend engineering time adding rel=prev/next solely for Google. Google disclosed in March 2019 that it had stopped using that markup. There is little evidence that the tags now improve Google crawling. Stable URLs and ordinary internal links do the essential work.

    Control the URL multipliers surrounding pagination

    A central route carries unique page tiles forward while barriers stop surrounding branches from producing duplicates.

    Pagination is often blamed for an explosion created elsewhere. A page parameter moves through an ordered set. A facet creates a subset. A sort parameter rearranges a set. A tracking parameter records attribution. Treating all four as interchangeable leads to the wrong controls.

    Consider a category with filters for material, color, size, availability, and price. If every combination can be reordered, paginated, and expressed in several parameter orders, each useful category sequence gains a large number of low-value variants. Faceted navigation and uncontrolled URL creation can make a site far larger than its owners expect.

    URL classIts roleRecommended default
    Primary category or archiveMain landing page for a content setIndexable, internally prominent, and self-canonical
    Page 2 and deeperContinuation and item discoveryCrawlable, linked in sequence, and normally self-canonical
    Curated facet with standalone valueStable subset that serves a distinct needExpose deliberately, give it a consistent URL, and support it with useful content and links
    Sort or filter variant with no standalone valueAlternate presentation of an existing setKeep it out of routine crawl paths; consolidate only when it is truly equivalent
    Tracking or session URLMeasurement or temporary stateRemove it from internal links and point users and bots toward the clean destination
    Empty or out-of-range pageNo useful contentRemove links to it, omit it from sitemaps, and return an accurate response

    Turn that classification into generation rules in the CMS or commerce platform. Cleanup at the crawler level is less effective if templates continue manufacturing new variations.

    • Whitelist intentional facets. Link only to combinations that have a defined user and search purpose. A usable filter does not automatically need an indexable landing page.
    • Normalize parameter order and naming. The same state should not be reachable as several URLs merely because parameters were added in a different sequence or aliases were used.
    • Keep tracking values out of internal links. Campaign parameters belong at acquisition boundaries, not in persistent navigation, breadcrumbs, related-item modules, or pagination controls.
    • Prevent impossible combinations. Do not render links to empty intersections or filters that cannot change the result.
    • Limit pagination to valid result pages. Calculate the actual last page and avoid links to arbitrary higher values.
    • Consolidate exact duplicates. Redirect duplicate URL formats when the equivalence is permanent. Use canonical signals when an alternate representation must remain available, but do not label materially different subsets as duplicates.

    Be careful with robots.txt. Blocking a pattern may reduce requests, but it also prevents the crawler from seeing page-level canonical or noindex signals on those URLs. More importantly, a broad rule can remove the only route to products buried in a filtered or paginated set. First confirm that every valuable destination has another crawlable path. Then remove unwanted internal links and duplicate generation at the source. Use crawling restrictions only after you know what they will cut off.

    The same caution applies to noindex. Indexing eligibility and crawl access solve different problems. A noindex directive can keep a low-value result page out of the index, but the page still has to be crawled for that directive to be read. If the real problem is an unlimited URL generator, noindex alone leaves the generator running.

    Audit the path from category page to destination URL

    A useful audit must show both what your site exposes and what crawlers actually request. A crawler simulation, server logs, and Google Search Console answer different parts of that question. None is sufficient alone.

    1. Crawl from public entry points. Use Googlebot or Bingbot settings and begin at the homepage, major category pages, and XML sitemaps. Crawling as the search bot sees the site reveals a more realistic exposed URL count.
    2. Export every discovered URL with its pattern. Record status code, canonical target, indexability, referring page, crawl depth, and whether the URL appeared in a sitemap.
    3. Map representative page sequences. For each important template, follow page 1 to page 2, a middle page, the last page, and several item destinations. Verify that links exist in the rendered HTML and that each page returns the expected slice.
    4. Find canonical destinations with no internal links. A product listed in a sitemap but absent from navigation is still weakly connected. Determine which category or archive should provide its durable route.
    5. Analyze server logs by crawler and URL pattern. Separate requests for canonical destinations, pagination, facets, sorting, tracking parameters, errors, and redirects. This shows whether crawl activity supports discovery or loops through variants.
    6. Inspect “Discovered – currently not indexed” samples. Identify whether affected URLs are valuable destinations, duplicate parameters, or deep items whose only route is fragile pagination. The remedy depends on that classification.
    7. Check capacity signals. Compare bot requests with slow responses, timeouts, and server errors. Because poor server response can cause a crawler to reduce fetching speed and connections, reliability fixes may precede URL-policy changes.
    8. Repeat the crawl after deployment. Confirm that intended destinations remain reachable and that removed patterns are no longer linked. Do not judge success only by a smaller URL total.

    Prioritize by consequence. Server failures and unbounded URL generation can affect the entire site. Broken page-to-page links can isolate whole sections. Duplicate first-page formats are usually narrower. Metadata refinements on page 27 matter less than restoring the link that allows a crawler to reach page 27 at all.

    Track a compact set of outcome measures rather than one headline crawl count:

    • The share of intended canonical products or posts reached during a full crawl.
    • The number of valuable destination URLs with no crawlable internal link.
    • The share of verified bot requests spent on noncanonical parameter patterns, redirects, errors, and empty pages.
    • The recurrence of server errors or slow responses during crawler activity.
    • The time between a meaningful content change and the next verified bot request, using CMS timestamps and logs.
    • The trend and URL composition of “Discovered – currently not indexed” in Google Search Console.

    Segment AI crawler traffic separately from Googlebot and Bingbot. AI agents and bots add their own access and resource considerations, so their requests should not be folded into one generic bot total. The broadly compatible foundation is still the same: stable URLs, accessible HTML links, accurate responses, deliberate crawler rules, and a server that remains healthy under load.

    Key takeaways

    • Optimize crawl paths, not the smallest possible URL count. Useful pagination can increase URL volume while improving discovery.
    • Keep each valid paginated page stable and crawlable. Use direct HTML links, distinct result slices, one URL format, and self-referencing canonicals by default.
    • Treat facets as the main multiplier. Whitelist intentional combinations and stop templates from linking arbitrary filter, sort, tracking, and pagination permutations.
    • Do not use canonical, noindex, and robots.txt interchangeably. They address consolidation, indexing, and crawling respectively, and a careless rule can hide the only path to valuable content.
    • Prove the result with three views. A site crawl shows what can be reached, logs show what bots request, and Search Console shows how Google processes discovered URLs.

    Start with one high-value category rather than changing the whole site at once. Export its complete page chain, list every parameter variation the templates expose, and trace several deep items back to crawlable category links. If you cannot reach every intended item without entering arbitrary parameter states, fix that path first. Once the model works, apply the same URL rules to the remaining templates.

    References


  • AI Marketing Agent Safety: A Practical Oversight Framework

    AI Marketing Agent Safety: A Practical Oversight Framework

    Your marketing agent can draft a campaign, diagnose performance, or prepare a site update. The risk changes the moment it can spend money, suppress traffic, publish claims, email customers, or overwrite a working configuration.

    You don’t need a binary verdict on whether the model is trustworthy. You need an operating system around it: complete enough context, narrowly scoped permissions, enforceable policies, approval before consequential actions, and a record that lets you reconstruct what happened.

    Replace abstract trust with three control questions

    The safer question is not whether you trust an AI model in the abstract. Ask what the agent can see, what it is structurally allowed to do, and who must approve its work before production. Those questions turn trust into controls you can inspect and test.

    1. What can it see? List every account, dataset, field, date range, customer-data class, and external tool available to the agent. Record important gaps as carefully as available data.
    2. What can it do? Separate reading, analysis, drafting, recommendation, and execution. A prompt describing what the agent should do is not a permission boundary.
    3. Who signs off? Name the role that must approve each protected action. Reviewing a change log afterward is auditing, not approval.

    Use those answers to assign every workflow an operating mode. Do not give an entire agent one blanket risk label; the same agent may be safe to query campaign data and unsafe to change a budget.

    Operating modeWhat the agent may doMinimum control
    ObserveRead approved data and explain findingsNo production write credential; disclose data scope and gaps
    ProposePrepare copy, settings, or recommended changesPolicy validation; no direct route from proposal to production
    Limited executionCreate drafts, apply labels, or act inside a designated sandboxNamed resources, hard action limits, result verification, and a tested recovery path
    Protected executionChange spend, bids, targeting, negative keywords, live content, customer communications, access, or destructive settingsExplicit approval for the exact change before execution

    Reversible does not necessarily mean low risk. You can unpause a campaign, but you cannot recover traffic and opportunities lost while it was paused. You can restore a previous page version, but not necessarily retract a claim already seen by customers or answer engines. Classify risk by consequence and exposure, not merely by whether the interface has an Undo button.

    Scope each permission across several dimensions:

    • Environment: sandbox, draft workspace, or production.
    • Identity: the brands, business units, clients, and accounts included.
    • Resource: campaigns, pages, audiences, feeds, schemas, or customer records.
    • Action: read, create, edit, publish, pause, archive, or delete.
    • Magnitude: the amount of spend, number of entities, or audience size the action can affect under your existing internal limits.
    • Time: when permission begins, when it expires, and whether approval can be reused.

    The resulting permission register should be readable by marketing, security, and the workflow owner. If nobody can state an agent’s maximum possible action without opening its prompt, the boundary is not yet clear enough.

    Ground the agent before you evaluate its reasoning

    A fluent answer can still be built on an incomplete account view. The model may not know that a missing dataset contains the decisive explanation, so its tone will not reliably reveal the gap. Treat grounding as a safety control that reduces confidently wrong diagnoses, not as an optional convenience.

    Write a grounding contract

    A grounding contract defines the context a workflow requires before the agent may answer or act. It should record:

    • The systems, accounts, entities, fields, and historical periods the agent can access.
    • Excluded or inaccessible systems that could materially change the conclusion.
    • Data freshness, timezone, attribution settings, and the time of the last successful refresh.
    • The identifiers used to join advertising, analytics, CRM, commerce, and content data.
    • Which connectors are read-only and which can write.
    • What the workflow must do when a query fails, a join is ambiguous, or required context is stale.

    For a Google Ads agent, a strong PPC grounding baseline extends well beyond a packaged performance summary:

    • Full Google Ads query access through GAQL for the resources, fields, segments, and metrics needed by the question.
    • GA4 data alongside ad data when the diagnosis depends on what happened after the click.
    • Complete change history across interface edits, scripts, agents, and other connected tools.
    • Negative keywords assembled across account-level negatives, shared lists, campaigns, and ad groups, including a deterministic check of whether a query is already blocked.
    • Auction Insights and an inspectable view of the keywords shared with a competitor when making competitive claims.
    • Relevant vertical benchmarks whose cohort and calculation are visible, rather than an unexplained generic average.

    The same principle applies outside paid search. A content agent diagnosing lost visibility needs the relevant page versions, publication history, analytics context, and technical state. A schema agent needs the live markup and the page content it describes. A lead-nurture agent needs the current consent and suppression state available to the workflow. The exact systems differ; the requirement to expose material gaps does not.

    Make missing context part of every answer

    Require an input manifest with each recommendation. It should list the datasets queried, account and entity IDs, date ranges, filters, refresh times, failed queries, and inaccessible dependencies. When required context is absent, the agent should return an incomplete-data state instead of filling the gap with a causal story.

    This also improves review. The approver can challenge the evidence itself instead of judging polished prose with no way to see what sits underneath it.

    Enforce policy outside the model

    An abstract AI core is surrounded by separate layers of permissions, rule gates, rate controls, and a locked execution chamber that block risky actions.

    A system prompt can explain policy, but it should not be the component that enforces policy. Instructions can be misunderstood, displaced by conflicting context, or applied inconsistently. A control implemented in credentials, an action gateway, or workflow code can refuse an operation regardless of the text the model produces.

    A practical enforcement path has four parts:

    1. Separate agent identity. Give the agent its own credentials so its activity is distinguishable from a person’s work.
    2. Least-privilege access. Where the platform supports granular scopes, issue only the read and write capabilities required for the approved workflow.
    3. Action gateway. Route every proposed write through one controlled service rather than allowing the model to call production tools directly.
    4. Workflow states. Move work through proposed, validated, approved, executed, and verified states. Do not let the model skip a state.

    The policy layer should inspect the actual operation, not merely the agent’s description of it. Evaluate the destination account, object IDs, current values, proposed values, batch size, credential, policy version, and approval record before the write is sent.

    Start with rules you can test

    • Deny production writes by default and allow only named actions on named resources.
    • Treat drafting and publishing as different permissions.
    • Protect changes to budgets, bidding, targeting, conversion definitions, negative keywords, customer-facing messages, user access, and billing behind the appropriate internal approver.
    • Set an internal maximum for entities affected in one execution. A request above that limit must be split or separately approved.
    • Block execution when required data is unavailable, stale under your policy, or inconsistent across systems.
    • Prefer drafts and archives to deletion. If deletion is required, identify what cannot be restored before approval.
    • Fail closed when the policy service or approval store is unavailable. An outage in the safety layer must not silently become permission to proceed.
    • Log blocked attempts and policy exceptions as well as successful actions.

    Use your organization’s existing budget authority and publishing ownership to set thresholds. A generic dollar limit copied from another company cannot express your margins, account size, customer commitments, or tolerance for interruption.

    Test the boundary, not just the happy path

    Before granting production access, deliberately submit requests that should fail:

    • A valid action aimed at the wrong client or brand.
    • A batch larger than the configured action limit.
    • A protected change with no approval.
    • A request based on missing or stale required data.
    • A connected document containing instructions that conflict with the workflow policy.
    • A proposal altered after approval.
    • An execution in which the platform accepts some changes and rejects others.

    For every test, verify the operation was blocked or contained, the event was recorded, and the right owner was notified. If success depends on the model deciding to behave, the test has exposed a prompt preference rather than a hard control.

    Make human approval an exact, usable decision

    A campaign operator reviews a website publication package, audience envelope, spending token, and rollback component before choosing between separate approval and rejection controls.

    Human approval is valuable only when it happens before the consequential action and gives the reviewer enough evidence to make a decision. Grounding makes proposals more useful to review, while policy filtering removes obvious non-starters before they reach the queue. That combination keeps human attention focused on judgment rather than basic cleanup.

    Build a proposal packet, not a chat transcript

    Every approval request should contain:

    • The exact account, campaign, page, audience, feed, schema, or record affected.
    • A before-and-after representation of every proposed value.
    • The business reason for the change and the evidence used, with its date range and refresh time.
    • The expected effect, known uncertainty, and any plausible downside.
    • The policies evaluated, including passes, blocks, warnings, and requested exceptions.
    • The total number of entities and the maximum spend, reach, or publication surface exposed under the proposal.
    • The recovery procedure, including anything that cannot be reversed.
    • The person or role responsible for approval and the time at which that approval expires.

    Show this information in the marketing system reviewers already understand when possible. A technically complete payload is not enough if the person accountable for the campaign cannot see the practical effect.

    Bind approval to the exact proposal version, destination IDs, and values. If the agent edits the proposal, the underlying account state changes, or the approval expires, require validation and approval again. Never treat approval of an idea as standing permission for whatever implementation the agent later chooses.

    Verify the write and prepare for partial failure

    1. Recheck the destination, current state, data freshness, policy version, and approval immediately before execution.
    2. Apply only the approved delta. Do not let execution broaden into related cleanup that was absent from the proposal.
    3. Read the affected resources back from the platform and compare them with the approved values.
    4. Record the request, approval, actor, platform response, successful entities, failed entities, and verification result.
    5. If only part of a batch succeeds, stop the remaining work and send the exact partial state to the owner. Do not improvise a rollback whose consequences have not been reviewed.

    A rollback plan should be tested against the real platform before you rely on it. Some operations can be restored from a known previous value; others create exposure that restoration cannot undo. Keep a kill switch that can revoke the agent’s write path independently of the model and document who is authorized to use it.

    Monitor adoption, safety, and outcomes separately

    A central view is useful because unregistered agents become invisible operational dependencies. At minimum, maintain an agent registry with the owner, purpose, connected systems, permissions, policy set, approver, current status, and kill-switch owner for each workflow.

    Management dashboards can help expose usage patterns. For example, one vendor describes a command center that shows how teams use marketing agents, the hours their work returns, and adoption relative to peers. Those are adoption and capacity signals. They do not, by themselves, prove that the work was safe, accurate, or commercially valuable.

    Organize oversight metrics into three lenses:

    • Adoption and capacity: active agents, active users, workflow frequency, proposals created, actions executed, and estimated hours returned. Document how any time-return estimate is calculated.
    • Safety and control: missing-context responses, policy blocks, exception requests, rejected proposals, stale approvals, out-of-scope attempts, partial executions, failed verification, rollbacks, incidents, and near misses.
    • Business outcomes: the marketing measures the workflow was intended to influence, alongside cost, error, complaint, and rework signals. Do not attribute an outcome to the agent merely because the two appeared in the same reporting period.

    Configure immediate alerts for attempted protected actions, unavailable policy enforcement, writes to an unregistered destination, changes to agent credentials, partial execution, and failed post-write verification. A weekly dashboard cannot contain an agent that is actively writing to the wrong account.

    During rollout, inspect every attempted production write and every policy block. Once the controls have behaved correctly under real workload, choose a recurring review cadence based on action frequency and consequence, while keeping event-driven alerts for protected operations.

    Read metrics in context. Zero policy blocks can mean that workflows are well designed, that nobody is using them, or that enforcement is not recording failures. High approval rates can indicate good proposals or automatic rubber-stamping. Pair each number with sample-level review and an accountable owner.

    Key takeaways

    • Trust is the result of inspectable controls, not a personality judgment about the model.
    • Give agents enough context to reason well, and force them to expose material gaps.
    • Enforce permissions and policies outside prompts.
    • Require approval before actions that can affect money, traffic, customers, access, or live content.
    • Bind approval to an exact, time-limited proposal and verify the resulting platform state.
    • Measure adoption, safety, and business outcomes as separate questions.

    Start with the highest-consequence agent workflow you already use. Write its grounding contract, remove every unnecessary permission, and force its next production change through proposal, policy validation, exact approval, execution, and verification. Expand only one permission or action class at a time after that path works as designed.

    References


  • How to Audit Google Business Profile Collected Info

    How to Audit Google Business Profile Collected Info

    When Google calls, texts, or messages your business to confirm a detail, the answer may not disappear when the conversation ends. Google can retain that information and use it to match your business with people looking for relevant services.

    You can now inspect some of this automated data in the Collected info area of your Google Business Profile. The important part is knowing what to verify, what to delete, and what must be corrected elsewhere. Deleting a collected item and editing your public profile are two separate actions.

    Key takeaways

    • Collected info can contain details gathered through automated calls, texts, WhatsApp messages, or chat conversations with your business.
    • Open your Business Profile and select Edit profile, then Collected info, to review available entries.
    • Check the content, collection date, source, and original language before deciding whether an item is accurate.
    • Delete information that is wrong, outdated, misleading, or no longer representative of the business.
    • Deleting an item removes it from Google’s collected records but does not change a detail already displayed on your Business Profile.
    • The feature is limited to certain regions, languages, and business categories, so an absent tab does not necessarily indicate an account problem.

    What Collected info contains and why it matters

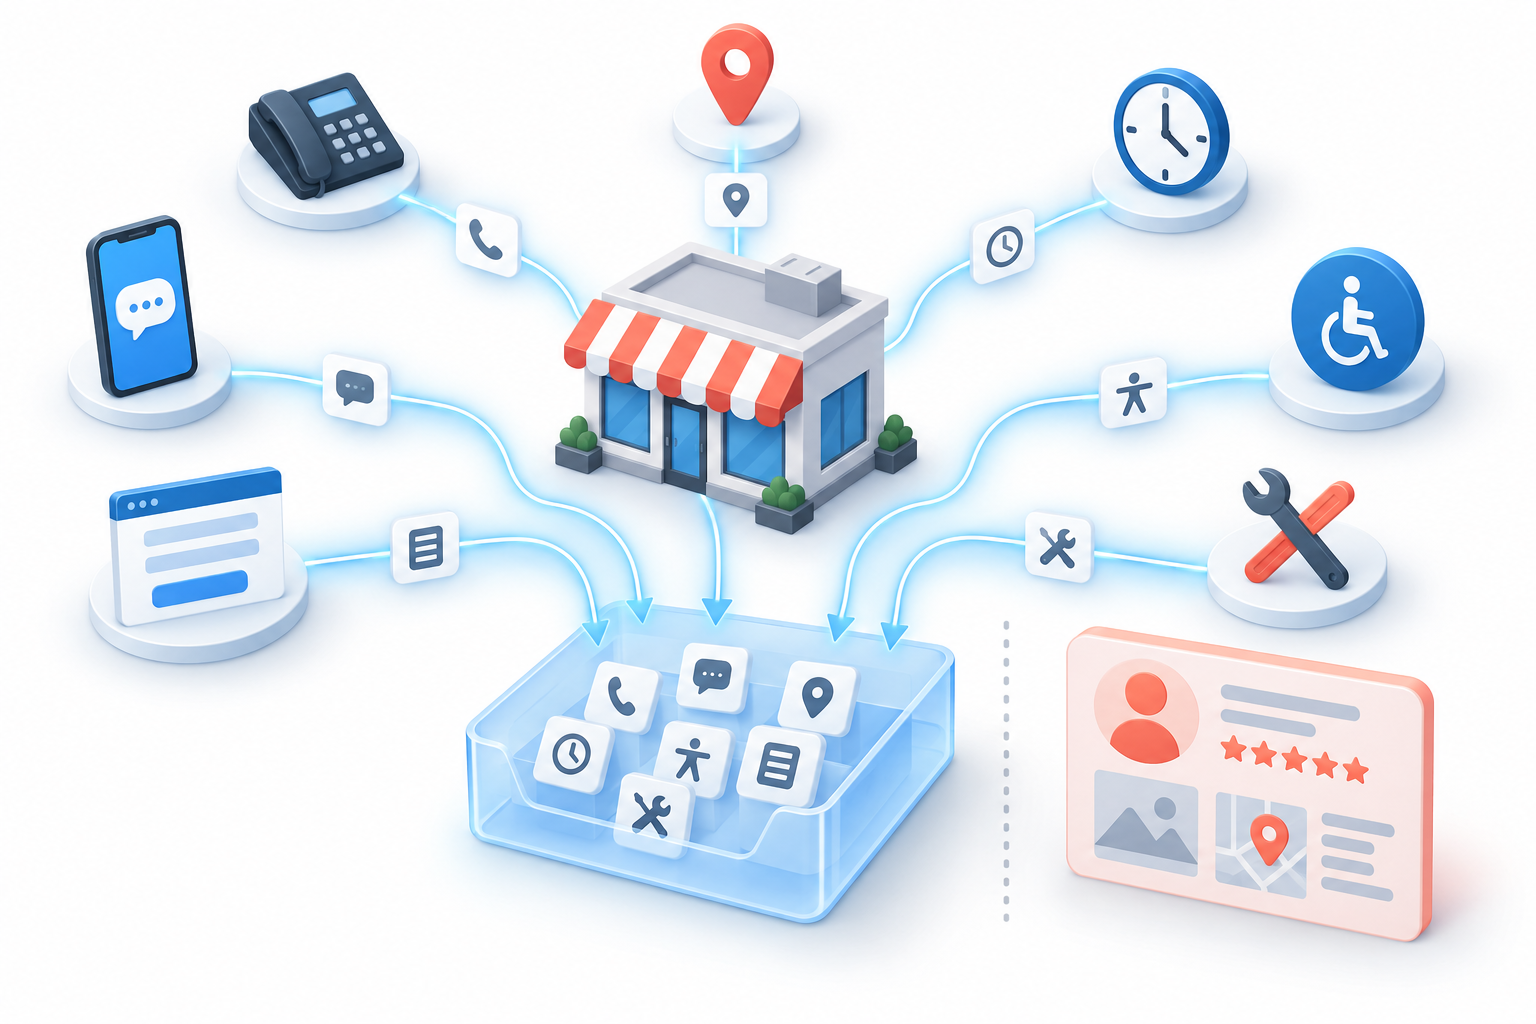
    Phone, message, location, hours and service symbols feed data into a collected-information tray beside a separate public profile panel.

    Collected info is a record of business details obtained through conversations involving Google’s automated assistant. Google may occasionally contact the verified phone number on a profile through a call, text, or WhatsApp message to confirm information. The dashboard can also identify information gathered through phone or chat conversations.

    The stated purpose is practical: the information may be used to update the profile and help match the business with customers looking for relevant services. Treat each entry as a claim about what a customer can expect from your business, not as harmless background data.

    For example, a staff member might give an accurate answer about an exceptional request, a temporary service, or an option available only at one location. The answer can still become misleading if it is interpreted as a general promise. Your audit therefore needs to check scope and conditions, not just whether the words are technically true.

    This is an accuracy control, not a new local ranking switch. Nothing about the feature establishes that retaining more collected entries will improve rankings. The useful goal is to keep Google from relying on a fact that is stale, incomplete, or broader than the service you actually provide.

    Collected info is also not a complete edit history for your listing. It covers information gathered through the relevant automated interactions. Changes made through other profile fields or systems still need their own checks.

    Audit each entry against the business customers can use

    Start from the Google account that manages the verified profile. Open the Business Profile, choose Edit profile, and then select Collected info. If the option is available, work through the entries in a fixed order:

    1. Read the entire entry before acting. Do not delete something merely because its wording differs from your website.
    2. Check where it came from. The interface can show the source of the information, which helps you identify the conversation or operating process behind it.
    3. Check when it was collected. A once-correct answer can become inaccurate after a service, policy, staffing, or location change.
    4. Account for the language. Collected information is displayed in the language in which it was originally provided. Ask a qualified colleague to review it if nobody responsible for the profile can confidently interpret that language.
    5. Compare it with current operations. Confirm that employees at the location would give the same answer now and that customers can actually receive what the entry implies.
    6. Compare it with your public facts. Check the relevant Business Profile field, location page, service page, and structured data where applicable. Note every conflict before deciding which system needs correction.

    Use four questions to test the meaning of an entry:

    • Is this true for this specific location?
    • Is it a normal offering, or was it an exception made for one customer?
    • Does the answer depend on an appointment, schedule, service area, qualification, or other condition?
    • Would a customer reading the statement without the original conversation understand it correctly?

    The fourth question catches the most subtle problem. A short answer can be true inside a conversation while becoming overbroad when separated from the question that prompted it. If essential context is missing, do not preserve the item merely because one interpretation is accurate.

    If you do not see Collected info, do not assume the profile is broken or that Google has gathered nothing. The feature is available only for select regions, languages, and business categories. Continue auditing the visible profile and keep your operational facts consistent while availability expands or changes.

    Delete the collected record, then correct the public layer

    One hand removes an incorrect collected data card while another updates the matching field in a separate public business profile.

    When an entry is inaccurate or outdated, select Delete and confirm Delete. Before doing so, record the value, collection date, and displayed source in your internal audit log if your team needs an explanation of what was removed.

    The deletion has a narrow effect. It removes the item from Google’s collected records but does not alter other details already present on the Business Profile. This distinction prevents a common cleanup mistake: deleting the collected evidence while leaving the customer-facing error untouched.

    After deleting an incorrect item, inspect the live profile separately. If the same claim appears in a public field, correct that field through the appropriate Business Profile editor. Then check your website and LocalBusiness structured data. A profile action does not rewrite page copy or JSON-LD, and a website correction does not automatically remove a collected record.

    Use this decision rule for every entry:

    • Accurate and properly scoped: leave the collected item in place and confirm that your other customer-facing information agrees.
    • Accurate but easy to misread: check whether the public profile or website needs clearer conditions. If the collected wording itself creates a false impression, delete it.
    • Outdated: delete the collected item and update every public location where the old fact still appears.
    • Incorrect: delete it, correct any affected profile fields, and find out why the business supplied the wrong answer.
    • Unverifiable: ask the person who owns that service or location to confirm it. Do not guess based on old marketing copy.

    Do not delete an entry simply because it was gathered automatically. Automation explains how the information arrived; it does not determine whether the information is useful. Accuracy, scope, and currency should decide the action.

    Prevent the next automated answer from creating a conflict

    A profile manager can clean up the dashboard, but the underlying problem often begins elsewhere. The person answering a call or message may be working from memory, accommodating an unusual request, or using terminology that differs from the website. If that operating gap remains, another interaction can produce another questionable answer.

    Create a compact fact sheet for employees and vendors who handle customer conversations. For each important business attribute, record:

    • the approved customer-facing statement;
    • the location or service area to which it applies;
    • any conditions that materially change the answer;
    • the employee or team authorized to verify it;
    • the primary system or document that owns the fact; and
    • the last time the fact was confirmed.

    This does not need to become a large governance project. A shared sheet or controlled internal page is enough if someone owns it and frontline staff can find it while responding to a call or message.

    Review Collected info when a material business fact changes, when a new entry appears, or when you discover a mismatch in a broader local listing audit. Useful triggers include changes to services, operating hours, appointment requirements, contact routes, location-specific availability, and the team or vendor answering customer inquiries. Event-based checks are more defensible than inventing a universal daily or weekly schedule.

    For AEO and generative engine optimization work, keep the scope clear. Collected info belongs to Google Business Profile; it is not JSON-LD, and its presence does not prove that unrelated AI systems know the same fact. Use the audit to identify your canonical answer, then align the Business Profile, website copy, structured data, and staff responses where each applies.

    Your next move is simple: open Edit profile, look for Collected info, and validate the first entry against current operations before deleting anything. If you find an error, fix both layers involved: the collected record and every public field that still repeats the claim.

    References


  • How to Validate a Programmatic SEO Pilot Before Scaling

    How to Validate a Programmatic SEO Pilot Before Scaling

    You have a spreadsheet full of potential URLs, a working template, and a credible path to publishing at scale. The decision in front of you is not whether the pages can be generated. It is whether the underlying page pattern deserves to be multiplied.

    That distinction matters because one page model can unlock hundreds or thousands of search opportunities, but it can multiply weak differentiation just as efficiently. A proper pilot should reveal where the model earns discovery, distinct search demand, and useful visitor behavior. It should also expose the conditions under which the model breaks.

    Key takeaways

    • Compare 10 candidate pages before development. If their substance barely changes, the template is not ready for search.
    • Build the pilot from strong, average, and difficult cases. A collection of obvious winners cannot validate the larger opportunity.
    • Record each page’s intended query family, possible competing URL, unique information, and desired visitor action before launch.
    • Evaluate four separate gates: discovery and indexing, query fit, performance drivers, and business behavior.
    • Scale only the segments supported by the evidence. A successful subset does not justify publishing every possible permutation.

    Define the page pattern as a testable hypothesis

    A programmatic template is not a strategy by itself. It is a production mechanism. Your strategy begins with a hypothesis about why each generated page will deserve its own URL and satisfy a distinct need.

    Write that hypothesis in a form your pilot can disprove:

    For [audience or context], a page differentiated by [variable] will satisfy [query family] because it provides [unique information], leading the visitor toward [useful action].

    For an integration library, the variable might be the connected product. The unique information might include supported workflows, setup instructions, screenshots, and limitations. For location pages, meaningful differences could come from local inventory, provider availability, pricing, or market-specific data. A changed city name or software logo is not meaningful differentiation if the underlying problem, evidence, and answer stay the same.

    Before anyone builds the generator, sketch 10 candidate pages and compare them side by side. For each candidate, answer:

    • What information changes in a way that helps this visitor?
    • What problem, constraint, or decision is specific to this variation?
    • What data, proof, examples, or screenshots change?
    • What capability, inventory, workflow, or limitation changes?
    • What should the visitor do next, and why is that action appropriate here?

    If most answers reduce to swapped nouns, do not move into pilot production. You have found a keyword permutation, not a durable page pattern. Either add a data source that creates substantive variation, narrow the eligible page set, or abandon the pattern.

    This is also where structured data belongs in the plan. Keep markup and other template-wide elements consistent unless you are deliberately testing them. Valid JSON-LD can describe a page accurately, but it cannot supply the missing local facts, workflows, inventory, or proof that should distinguish one generated URL from another.

    Create a pilot manifest before publishing. Give every candidate a row containing:

    • The proposed URL and page type.
    • The primary search intent and related query family.
    • The existing URL most likely to compete with it.
    • The unique information or assets available for that variation.
    • The intended visitor action.
    • Relevant characteristics such as demand, data depth, inventory, internal-link depth, competition, and content completeness.

    Those fields become your baseline. Without them, a team can reinterpret almost any post-launch result as success.

    Build a representative pilot, not a showcase

    A varied sample of blank web-page cards and assorted data pieces is arranged on a worktable beside a larger unused stack.

    The easiest candidates are useful for proving that the template can work under favorable conditions. They cannot tell you whether it will hold up across the full library.

    Build your sample around the dimensions that vary in the eventual rollout. A location project might include large, medium, and small markets, plus locations with rich and limited inventory. An integration project might include well-known connections with extensive workflows, ordinary integrations with moderate demand, and edge cases with less supporting material. A use-case library should likewise include both obvious audience needs and narrower combinations.

    There is no universal number of pages that makes a pilot valid. The right sample depends on how many materially different conditions the template must survive. List those conditions first, then select enough candidates to expose recurring differences without building the full library.

    A practical selection process looks like this:

    1. List every dimension that could change page quality or performance: demand, data depth, inventory, competition, link depth, and completeness.
    2. Divide each dimension into meaningful bands, such as stronger, typical, and weaker cases. Use labels appropriate to your dataset rather than arbitrary industry thresholds.
    3. Select candidates across the intersections. Do not let high-demand, data-rich pages dominate the sample.
    4. Check the manifest for missing conditions. If thin-data or low-demand cases will exist after scaling, they must appear in the pilot.
    5. Freeze the sample and success rules before results arrive. Additions made after launch should be treated as a new test, not quietly folded into the original one.

    A representative pilot is intentionally uncomfortable. It includes pages you suspect may fail because those failures help define an eligibility rule. If data-poor variations repeatedly fall out of the index or never acquire distinct queries, the lesson is not necessarily that the entire model failed. The model may work only above a particular level of data or inventory. That boundary is exactly what the pilot should uncover.

    Use four validation gates instead of one traffic total

    Web-page tiles move through four symbolic checkpoints for discovery, differentiation, quality, and visitor interaction before entering a limited expansion area.

    Do not collapse the pilot into sessions, clicks, or aggregate impressions. A few strong URLs can conceal widespread indexing problems, query overlap, or pages that attract attention without helping the business. Evaluate each gate separately, by URL and by candidate segment.

    Gate 1: Can Google discover and retain the pages?

    Start by checking whether Google can find each pilot page through your internal linking structure. Then distinguish initial indexing from sustained indexing. A URL that enters the index briefly and later disappears has not demonstrated the same stability as one that remains indexed.

    • Was the URL discovered?
    • Did it enter the index?
    • Did it remain indexed over the observation period?
    • Do indexed and excluded pages differ by data depth, inventory, completeness, or internal-link depth?

    Suppose 40 of 50 pilot location pages remain indexed, while the excluded pages consistently have limited local inventory. That is not proof that inventory alone caused the outcome. It is a useful hypothesis: the page model may require more inventory to remain viable. Test that condition in the next controlled batch before turning it into a permanent rule.

    Do not respond to weak indexing by publishing more URLs. That increases the number of pages requiring discovery, internal links, and maintenance without resolving the defect the pilot exposed.

    Gate 2: Do the URLs attract their intended query families?

    Compare the queries recorded in your manifest with the impressions each URL receives in Google Search Console. Look beyond the primary phrase. Related queries often show more clearly whether Google understands the page’s specific purpose.

    Imagine separate pages for CRM software aimed at accountants, real estate agents, and consultants. The pattern is beginning to differentiate if each page attracts searches connected to its intended industry. If all three mainly appear for the same generic CRM terms and overlap with the main product page, the audience variable has not translated into distinct search relevance.

    Some query overlap is natural. The warning sign is not a shared word; it is a shared job. Flag URLs when most of their visibility comes from a generic intent already served elsewhere, when several generated pages repeatedly compete for the same query family, or when the intended supporting queries never emerge.

    For every flagged URL, choose a deliberate response: sharpen its unique information, merge it into a stronger page, change the eligibility rule, or remove it from the scalable pattern. Do not leave overlapping URLs in place simply because each one received impressions.

    Gate 3: Which page characteristics travel with better results?

    Once individual results are visible, group pilot pages by the characteristics you recorded before launch. Compare cohorts based on search demand, unique-data depth, inventory or product availability, internal-link depth, competition, and content completeness.

    The objective is not to crown a universal ranking factor. It is to identify the operating conditions for your page model. Integration pages with detailed setup instructions and several supported workflows may consistently outperform pages with a short capability description. Data-rich locations may remain indexed more reliably than locations with sparse availability. Those associations tell you what to test next and which candidates should qualify for expansion.

    Keep the analysis at URL level before rolling it up. Report how each segment performs across indexing, intended-query visibility, and the desired visitor action. An overall average can look healthy even when every edge case fails.

    Gate 4: Does the visibility produce useful behavior?

    Organic visibility is an intermediate result. Your pilot also needs a business outcome appropriate to the intent: starting setup, viewing available inventory, requesting information, creating an account, or moving into another meaningful step.

    Define that action before launch and measure it by page and segment. Otherwise, teams tend to celebrate whatever metric moved. A page with impressions but no useful next step may have an intent mismatch, an incomplete answer, or a weak transition into the product. A lower-volume page can still justify its place if it attracts the intended audience and produces the behavior the page was designed to support.

    If AI visibility is also part of your objective, record it separately rather than treating Google indexing as a proxy. Define the prompt family you care about, note whether the brand or page appears in the relevant response, and capture any citation or link that is actually present. Keep those observations distinct from Search Console query performance so one channel does not mask failure in another.

    Turn the evidence into a bounded scale decision

    A pilot is finished when it supports a decision, not when a reporting window happens to close. Give it enough time to collect meaningful evidence, then classify the result. Do not invent a universal waiting period; demand and page conditions differ too much for one calendar threshold to fit every project.

    Observed patternLikely implicationNext action
    Weak discovery across most segmentsThe internal path to the library is not working reliably.Repair the linking structure and rerun the pilot before expanding.
    Only data-rich or inventory-rich pages remain indexedThe template may work under a narrower eligibility condition.Test and document a minimum data rule, then exclude weaker candidates.
    Pages are indexed but attract generic, overlapping queriesThe proposed variation is not creating a distinct search purpose.Rework the page model, consolidate overlapping URLs, or stop the pattern.
    Visibility appears, but the intended action does notSearch intent, page value, or the next-step path may be misaligned.Diagnose the affected segment and retest before increasing URL volume.
    Strong results occur only among obvious head casesThe opportunity is smaller than the full permutation count suggests.Scale the proven segment and keep adjacent segments in testing.
    Multiple representative segments pass all four gatesThe page pattern has earned a controlled expansion.Release the next bounded batch and apply the same validation process.

    Use four decision states rather than forcing a binary launch:

    • Scale: Multiple representative segments meet your predeclared standards across all four gates, and you can describe the characteristics associated with success.
    • Expand the pilot: Results are promising, but an important condition is underrepresented or the apparent pattern rests on too few comparable pages.
    • Rework: The URLs are discoverable, but query overlap, thin differentiation, or weak business behavior points to a repairable page-model problem.
    • Stop: Most candidates cannot support materially different information, or representative pages repeatedly fail without a credible condition you can change.

    When you do scale, scale in bounded batches. Carry the manifest, eligibility rules, internal-link approach, and four gates into every release. New segments introduce new conditions, so success among large markets, popular integrations, or rich-data pages should not grant automatic approval to smaller markets, obscure connections, or sparse records.

    Your next step is simple: put 10 proposed pages side by side and complete the manifest before approving the generator. If their differences disappear under scrutiny, you have avoided multiplying a weak idea. If the differences hold, publish a representative pilot and let observed indexing, query fit, page characteristics, and business behavior determine how far the pattern deserves to go.

    References


  • GA4 Shows Zero Traffic on September 1: What to Do

    GA4 Shows Zero Traffic on September 1: What to Do

    If GA4 shows a flat zero for September 1, 2026, don’t start changing tags. The same alarming gap has appeared across many accounts, so the chart is not reliable evidence that your audience disappeared.

    September 1 was showing no Google Analytics data across multiple properties, while no cause or official Google confirmation had been reported. A Google-side reporting or processing problem is therefore the leading explanation, but you should still verify that your own site and data collection are healthy.

    What the September 1 gap does and does not tell you

    A zero in a report can describe two very different situations: no activity occurred, or activity was not available to that report. Treating those conditions as interchangeable is how a temporary analytics incident turns into bad marketing decisions.

    The widespread pattern makes an isolated collapse in your website traffic less likely. It does not yet establish the exact failure mode. Google had not confirmed the incident, identified its cause, supplied a resolution time, or said whether the missing data would be restored. Until those questions are answered, describe September 1 as unavailable or provisional data rather than verified zero traffic.

    Key takeaways

    • Do not interpret the September 1 GA4 zero as proof that traffic, rankings, leads, or sales collapsed.
    • Check independent operational systems before deciding whether you also had a website or tracking problem.
    • Avoid republishing tags, changing consent settings, or adding a second tracker merely to make the historical gap disappear.
    • Mark September 1 as provisional in dashboards and reports so the apparent zero does not distort comparisons.
    • Investigate locally if the gap extends beyond the affected date, current events are also absent, or other business systems show a matching decline.

    Separate a GA4 reporting failure from a real outage

    An analyst inspects a working event stream that becomes obscured at a separate reporting layer.

    You don’t need to prove the internal cause before protecting the business. You need to establish whether customers could reach the site, whether meaningful activity continued, and whether the anomaly is limited to GA4.

    1. Record the exact scope. Note the GA4 property, data stream, property time zone, affected date, report, filters, comparisons, and the time you checked. Save an unedited screenshot. This gives you a clean baseline if the figures later change.
    2. Inspect a wider date range. Confirm whether only September 1 is blank or whether the gap continues into adjacent dates. Also remove report filters and comparisons temporarily. A date-specific gap across ordinary reports points in a different direction from an ongoing absence confined to one filtered view.
    3. Compare other properties you legitimately manage. The same date missing from unrelated properties supports the working theory of a shared GA4 problem. One affected property while the others behave normally deserves closer inspection of that property’s collection setup.
    4. Check independent evidence of activity. Ecommerce teams can review orders and payment records. Lead-generation teams can check form submissions, call records, and CRM entries. Publishers can use web-server or CDN requests. Paid teams can inspect platform-side clicks and conversions. SEO teams can use Search Console and server logs as directional evidence.
    5. Check the present separately from the past. Verify whether current page views and events are reaching your live-event or debugging tools. Current collection can be healthy while a historical date remains unavailable in standard reports.
    6. Review your change history last. Look for releases involving the Google tag, Google Tag Manager, measurement IDs, consent controls, redirects, domains, checkout flows, or content security settings. Investigate a coinciding change when the evidence points to your property; do not assume coincidence proves causation.

    These systems will not produce identical totals. They measure different actions, use different attribution rules, and may process data on different schedules. For this triage, you are not trying to reconcile every session. You are answering a narrower question: did meaningful activity continue while GA4 displayed zero?

    Observed patternWorking interpretationNext action
    Several unrelated GA4 properties are blank on September 1, while independent activity looks normalA shared reporting or processing incident is more likelyPreserve the implementation, document the gap, and recheck the affected reports
    One property or stream is blank while comparable properties workA property-specific configuration or collection problem is more plausibleInspect deployments, measurement IDs, filters, consent behavior, and stream coverage
    GA4, orders, leads, and server activity all fall togetherA genuine website, demand, or operational problem may have occurredUse your normal site-incident and business-diagnosis process
    The historical date is blank, but current events are arrivingThe problem may be limited to historical processing or reportingKeep current tracking unchanged and leave September 1 flagged as provisional

    Do not create a second problem while trying to fix the first

    A vendor-side reporting problem cannot be repaired by repeatedly publishing your container. Unnecessary changes can duplicate events, split data between measurement IDs, alter consent behavior, or make later diagnosis harder.

    Unless your checks reveal a separate local fault, avoid these responses:

    • Do not add another GA4 tag to compensate for the missing date.
    • Do not replace a measurement ID simply because one historical report is blank.
    • Do not loosen consent settings in an attempt to recover traffic.
    • Do not republish an unchanged tag container as a speculative fix.
    • Do not import invented session or conversion values to fill the hole.
    • Do not overwrite raw exports or source tables with estimates.

    If you find a genuine configuration error, make the smallest correction that addresses that error and document its publication time. That separation matters: otherwise you may not be able to tell whether subsequent data returned because Google resolved the broader incident or because your implementation changed.

    Keep one missing day from corrupting performance decisions

    One empty data tile is isolated within a longer sequence while a strategist evaluates the surrounding trend.

    The operational risk is not just an empty chart. September 1 can flow into weekly totals, period-over-period comparisons, blended dashboards, automated alerts, forecasts, campaign rules, and client reports. A literal zero makes every downstream calculation look more definitive than the underlying data deserves.

    • Flag the date. Add an incident annotation or companion note wherever September 1 appears. Include the affected property and state that the value is provisional.
    • Represent missingness honestly. In derived dashboards, use an unavailable or null state for the flagged date when your reporting process permits it. Do not silently substitute zero.
    • Pause final reporting for that date. You can continue preparing a report, but do not lock totals, comparisons, or conclusions that depend materially on September 1.
    • Recalculate affected windows. If data later appears, rerun every report whose range includes September 1 rather than updating only the daily chart.
    • Audit automation. Check whether the apparent zero triggered alerts, bid or budget rules, pacing decisions, anomaly detection, or stakeholder notifications. Reverse a downstream action only after verifying why it fired.
    • Preserve the original evidence. Keep the screenshot, query conditions, report export, and incident note. Do not erase the audit trail when the numbers change.

    For paid campaigns, a GA4 zero by itself is not a sound reason to pause spending; examine ad-platform activity and business outcomes first. For SEO and AEO work, it is not evidence of lost rankings or lost visibility. Check search performance and server activity, then revisit GA4 when processing is restored or clarified.

    Know when to treat it as your own tracking incident

    The widespread September 1 pattern is useful context, not a permanent explanation for every empty report. Move from watchful documentation to a property-level investigation when your evidence stops matching the shared incident.

    • The missing range extends beyond September 1 while other properties have normal data.
    • Current live-event checks show no activity despite confirmed visits.
    • Only one data stream, hostname, region, device group, or conversion path is affected.
    • A tag, consent, domain, redirect, or deployment change coincides with the beginning of the gap.
    • Independent systems also show that visits, transactions, or leads stopped.
    • The broader reporting issue clears but your property remains blank.

    Until one of those signals appears, keep the response controlled: preserve your measurement setup, mark September 1 as unavailable, assign one owner to recheck the affected reports, and rerun dependent analysis if the figures return. That protects both your data and the decisions built on it.

    References


  • Why Technical SEO Audit Recommendations Fail to Ship

    Why Technical SEO Audit Recommendations Fail to Ship

    Your technical SEO audit is finished, but nothing is moving. The findings are sitting in a shared drive, developers keep asking what to change, and the severity labels are not helping anyone decide what deserves attention.

    The problem is usually not a shortage of issues. It is the gap between observing a technical condition and producing a trusted, scoped recommendation. You close that gap by validating each finding, tracing it to the system that creates it, and defining a result that another team can implement and verify.

    Confirm the problem exists before you classify it

    A crawler finding is a lead, not a fact. It tells you where to investigate. It does not automatically tell you what users, Google, or an AI crawler received.

    Compare the initial HTML with the rendered page

    JavaScript can change the body copy, internal links, canonical element, or meta robots directive after the server sends the initial HTML. A crawl that examines only the initial response can therefore report missing elements that appear after rendering. The opposite problem matters too: a browser may display content correctly even though that content is absent from the response available to a crawler that does not run JavaScript.

    Run the crawl with JavaScript rendering enabled and store both the original and rendered HTML. Then compare the versions for the elements that affect discovery, interpretation, and indexing:

    • Primary body content and headings.
    • Links to important internal destinations.
    • The canonical URL.
    • Meta robots directives.
    • Any navigation or related-content module responsible for exposing more URLs.

    Treat a difference as material only when it changes what a crawler can discover or understand. A decorative class added after rendering is not an SEO recommendation. An internal link or index directive that exists only after a successful script execution may be one.

    Google can render most pages, but rendered-only content remains dependent on scripts, resources, and execution completing successfully. Many AI crawlers do not execute JavaScript, so a page that is usable and indexable in one system may still expose very little to another. For content intended to support AI discovery, inspect the initial HTML rather than assuming the browser’s final screen represents every crawler’s view.

    When the difference affects a page you want indexed, check the URL in Google Search Console’s URL Inspection tool. Use Google’s rendered view to confirm whether the content or directive was available during inspection. Attach that evidence to the finding; it is more useful to an engineer than a crawler screenshot without platform confirmation.

    Separate expected exclusions from indexing failures

    Open Search Console and go to Indexing > Pages. The Page indexing report distinguishes conditions such as indexed, crawled but not indexed, discovered but not indexed, soft 404, redirected, excluded by noindex, and alternate page with a canonical.

    Do not convert every item under “Not indexed” into a task. An alternate URL with the intended canonical, a deliberately noindexed page, and a redirected URL can all be correct outcomes. The audit question is not “How many URLs are excluded?” It is “Does the reported state match the intended state for this page type?”

    Investigate the mismatch. A commercial or informational page intended to rank but listed as “Crawled – currently not indexed” deserves examination. So does a growing “Discovered – currently not indexed” group containing URLs you expect Google to crawl. By contrast, an intentionally excluded filter URL may require no change at all.

    Add an intended-indexing field to your audit worksheet. Mark each sampled URL as indexable, canonicalized elsewhere, noindexed, redirected, or intentionally unavailable before you evaluate Google’s classification. That one field prevents normal exclusions from competing with genuine failures.

    Audit templates and URL-generating rules, not random pages

    A central website template machine repeats the same structural flaw across many generated page tiles while isolated pages are inspected nearby.

    Random URL sampling tends to find isolated symptoms. Technical SEO failures are often produced by a template, routing rule, filter, or CMS behavior that affects a whole class of pages.

    Build the sample around every page type the site generates. Depending on the site, that may include product detail pages, category or listing pages, blog posts, filtered views, paginated series, and parameterized URLs. Include both pages intended for indexing and pages intended for exclusion. The goal is to test the rules at their boundaries, not merely to confirm that an ordinary page works.

    For each template, record:

    • The business purpose of the page type.
    • Whether its URLs should be discovered, crawled, indexed, or consolidated into another URL.
    • How users and crawlers reach it.
    • Its expected status code, canonical behavior, and robots state.
    • Whether important content and links appear in the initial HTML.
    • Which CMS component, route, or template controls the behavior.

    This changes the unit of work. A canonical error on a product template is not a collection of unrelated URL problems. On a catalog containing 40,000 product pages, one faulty template rule can affect all 40,000. The URL export demonstrates scope, but the template is the implementation target.

    Template-based sampling also makes the recommendation easier to estimate. “Change the canonical logic on the product detail template” identifies a system boundary. “Fix these 40,000 URLs” leaves the development team to discover the shared cause themselves.

    Keep the complete URL list as supporting evidence, not as the task description. Give the implementation team representative examples covering the important states: a normal page, an affected page, an excluded variant, and any edge case that changes the expected behavior. If the same proposed fix cannot explain all those examples, the diagnosis is not finished.

    Triangulate findings before asking another team to act

    No single data source sees the whole technical system. A crawler shows what it discovered and received. Search Console shows Google’s classification. Analytics reflects tracked visits. Server logs show requests that actually reached the server. Their differences are not noise to discard; they often reveal the failure mechanism.

    Evidence sourceWhat it can confirmImportant blind spot
    SEO crawlerLinked URLs, status responses, directives, internal links, and rendered-versus-original HTML when configured for renderingIt cannot discover an orphan URL unless you supply the URL through another source
    Google Search ConsoleGoogle’s indexing classification, inspected rendering, and sampled crawl informationIt may show Google’s outcome without fully explaining the underlying site behavior
    AnalyticsVisits where the tracking code executesIt does not provide a complete record of crawler requests
    Server logsRequests made to the server, including requested URLs, response codes, and crawler activityThey require access, retention, and filtering that may not already be available

    Server logs are especially valuable when you suspect intermittent 5xx responses, rate limiting, or crawler activity concentrated on URLs that do not matter. They show what Googlebot or an AI crawler requested and what the server returned. If logs are unavailable, Search Console’s Crawl Stats report offers sampled request examples and a breakdown that can help you decide where to investigate.

    Before a finding becomes a development recommendation, confirm it in at least two places. Choose the pair based on the claim:

    • For a rendering claim, compare original and rendered HTML, then inspect the URL in Search Console.
    • For an indexing claim, compare the intended state with the Page indexing report and the page’s actual directives.
    • For a response-code claim, compare the crawler result with a direct request and, when available, server logs.
    • For a crawl-allocation claim, use logs or Crawl Stats to see which URL patterns crawlers actually request.
    • For an orphan-page claim, compare crawler discovery with URLs found in Search Console, analytics, sitemaps, or logs.

    When the evidence disagrees, pause the recommendation. A crawler may record 429 or 503 responses because its request rate triggered site protections. The same URL may load normally when opened manually. Confirm the exact URL with a direct request, review the crawl rate, and check logs before declaring a server failure. Tool classifications can reflect the conditions created by the audit itself.

    This validation step protects more than the current ticket. Sending an engineer after one phantom problem weakens confidence in every finding that follows. A shorter audit containing reproducible evidence is more useful than a long export whose labels have not been checked.

    Turn observations into implementation-ready recommendations

    Three diagnostic sources converge on a website defect that is converted into fitted replacement parts and installed by an engineer.

    “The site has duplicate URLs” describes a result. It does not identify what must change. The duplicates might come from faceted navigation, session identifiers appended to URLs, or a CMS that publishes the same content under a second path. Deleting the current URLs addresses the inventory while leaving the generator intact, so the problem can return when the behavior is triggered again.

    Trace the issue upstream. Find the link, component, route, parameter rule, or publication workflow that creates the unwanted state. Then write the recommendation against that cause.

    Use a ticket structure that supports estimation and testing

    A shippable technical SEO recommendation should contain the following fields:

    1. Intended behavior: State which URL class should be discoverable, indexable, canonicalized, redirected, or excluded.
    2. Observed behavior: Describe the mismatch without copying a crawler label as the explanation.
    3. Affected system: Name the template, route, filter, CMS component, or rendering process that produces it.
    4. Evidence: Include representative URLs and confirmation from at least two relevant sources.
    5. Root cause: Explain the rule or dependency responsible. If it is still a hypothesis, label it as one and request the diagnostic work needed to confirm it.
    6. Required change: Define the behavior to alter without prescribing unsupported implementation details.
    7. Acceptance criteria: Describe what should be true after deployment in the response, rendered DOM, crawl, and relevant platform report.
    8. Scope and risk: Identify affected templates, intentional exceptions, dependencies, and any indexing behavior that must not change.

    Compare these two versions:

    Weak: Fix 12,000 duplicate URLs. High severity.

    Shippable: Filter controls on the category template generate crawlable parameter URLs that are not intended as separate search results. Confirm which control emits each pattern, change the generating rule so the unwanted URLs are no longer exposed through that path, and preserve the clean category URLs. After deployment, the supplied clean and filtered examples must return their intended status, canonical, robots state, and internal-link behavior in both the initial and rendered HTML.

    The second version does not pretend the implementation is known before the cause is confirmed. It gives engineering a system boundary, an intended outcome, test cases, and protected behavior.

    Prioritize with impact, confidence, and effort

    A crawler’s severity setting is not your roadmap. Its classification cannot know whether an excluded URL was meant to rank, whether a template affects a commercially important page type, or whether the apparent error exists outside the crawl environment.

    Rank validated findings with four questions:

    • Impact: Does the condition prevent important pages or content from being discovered, rendered, understood, or indexed as intended?
    • Scope: Is it generated by a shared template or rule, or confined to an isolated URL?
    • Confidence: Is the finding reproduced and confirmed by independent evidence, or is the cause still hypothetical?
    • Effort and dependency: Can the responsible team estimate the change, and does another system or release have to move first?

    Do not hide uncertainty by assigning a more urgent label. A high-impact hypothesis should become a priority diagnostic task. A confirmed template defect should become an implementation task. An expected exclusion should be documented and closed. Those are three different decisions, even if a crawler places all three URLs in the same warning bucket.

    Be careful with changes to canonicals, redirects, robots directives, and URL generation. A broad template edit can alter the indexing state of every page using it. Test representative intended and excluded cases before release, then repeat the same checks after deployment. The acceptance criteria should make unintended changes visible before the ticket is considered complete.

    Key takeaways

    • Treat crawler findings as leads until you reproduce and validate them.
    • Compare initial and rendered HTML whenever JavaScript can add content, links, canonicals, or robots directives.
    • Judge Search Console exclusions against each page type’s intended indexing state.
    • Sample by template and generated URL pattern, because shared rules create scalable failures.
    • Confirm development recommendations with at least two relevant evidence sources.
    • Write the task against the root cause, with representative examples and testable acceptance criteria.
    • Prioritize by impact, scope, confidence, and implementation effort rather than tool severity.

    Take the next finding in your audit and try to write its acceptance criteria. If you cannot state what should be different after deployment, which template controls it, and how you will verify the result, keep investigating. Once those answers are explicit, the audit stops being a report and becomes work a team can safely ship.

    References