If your products or archive posts disappear after page 1, reducing the number of crawlable URLs can feel like the obvious fix. It often is not. Pagination may be the only internal route that exposes deeper items, so removing it can turn crawl waste into orphaned content.
The better objective is controlled discovery: give crawlers a finite, stable sequence through valuable content while preventing filters, sort orders, tracking parameters, and duplicate URL formats from multiplying that sequence. You protect crawl capacity by removing useless paths, not by hiding useful ones.
First decide whether you have a crawl-budget problem
Crawl budget is the time and computing resources a crawler is prepared to spend on your site. For Googlebot, it reflects both crawl capacity and crawl demand. Capacity concerns what your server can handle without becoming unstable. Demand concerns which URLs appear valuable or in need of another visit.
Those two forces create different problems. Slow responses and server errors can cause a crawler to reduce its pace. Duplicate, low-value, or spam-like URL patterns can reduce the apparent value of fetching more URLs. A pagination fix cannot compensate for an unreliable server, and faster hosting cannot make an unlimited set of filter combinations worth crawling.
Google’s criteria for active crawl-budget management are narrower than many teams assume. The clearest candidates are sites with more than 1 million unique pages, medium or large sites whose content changes frequently, and sites with many URLs marked “Discovered – currently not indexed” in Google Search Console.
That does not mean a smaller site can skip the audit. Your catalog, article count, or CMS dashboard does not reveal the number of URLs a crawler can encounter. Facets, pagination, alternate parameter orders, languages, locations, search pages, and session values can turn one content set into many crawlable representations.
- Inventory the exposed URLs. Crawl from the same public entry points available to search engines. Do not begin with a spreadsheet of products or posts.
- Group URLs by pattern. Separate canonical content, pagination, filters, sort orders, internal search, tracking parameters, and malformed combinations.
- Distinguish discovery from indexing. A URL that has never been fetched points to a different constraint than a fetched page that was judged unworthy of indexing.
- Check server behavior. Look for timeouts, error responses, and URL patterns that require disproportionately expensive rendering or database work.
There is no universal healthy number of crawls per day. A useful baseline is whether important new or changed URLs are discovered and revisited while requests to low-value patterns remain controlled. Measure that outcome on your own site instead of copying another domain’s crawl rate.
Build pagination as discovery infrastructure
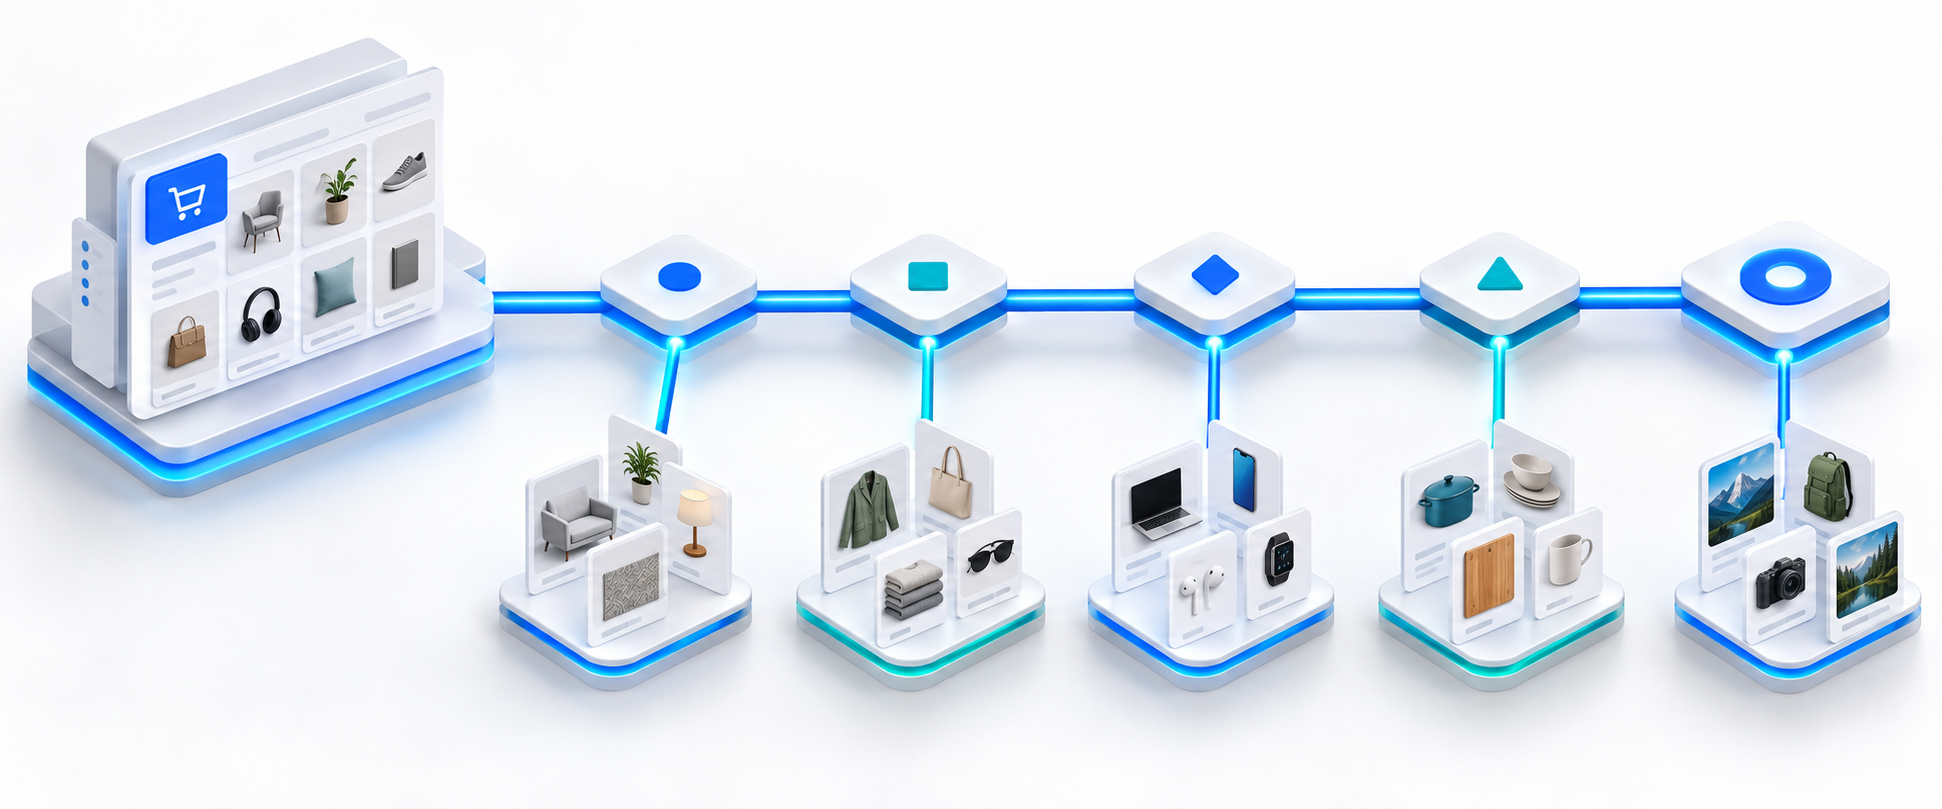
Pagination divides one ordered content set into addressable pages. It adds URLs, but those URLs provide paths to products, posts, discussions, and other deeply nested content. That is productive crawl activity when each page exposes items that would otherwise be difficult to reach.
A crawler should be able to begin at the first category or archive page, follow ordinary HTML links through the sequence, and reach every intended item. It should not need to click a JavaScript-only button, submit a form, maintain a session, or scroll until client-side code decides to load another batch.
- Choose one stable URL format. Formats such as ?page=2 or /page/2/ can work. Do not expose multiple formats for the same sequence.
- Use links with href destinations. Previous and next controls should be crawlable links. A short set of numbered links can provide additional routes into a long sequence.
- Link every listed item directly. Products and posts should have canonical destination URLs in the rendered listing, not destinations assembled only after an interaction.
- Give each page a distinct slice. Page 2 should not reproduce page 1 under a different URL. Stable ordering also reduces unnecessary repetition when crawlers revisit the sequence.
- Use a self-referencing canonical by default. If page 2 contains a distinct set of items, pointing its canonical to page 1 misrepresents that relationship. Consolidate only URLs that are genuinely equivalent.
- Keep page 1 canonicalized consistently. Link to one preferred first-page URL instead of alternating between the clean category URL and a duplicate such as ?page=1.
- Give infinite scroll a paginated fallback. Each batch should be available at a stable URL through crawlable links, even if human visitors receive a continuous visual experience.
- Stop at the real end of the sequence. Do not generate an endless run of empty page numbers. Remove internal links to pages beyond the last valid result and return an appropriate not-found response when an invalid page is requested.
Do not automatically canonicalize every paginated URL to the first page or apply a blanket noindex directive. Overly aggressive canonicalization can prevent useful paginated URLs from appearing in search results, while removing their crawl value can make deeper items harder to find. A canonical signal expresses a preferred equivalent; it is not a general crawl-control switch.
An XML sitemap helps crawlers discover canonical products, posts, and other destination pages, but it does not replace internal linking. Pagination remains an additional discovery route even when sitemaps are present. That route also shows how the content belongs within your site architecture.
Do not spend engineering time adding rel=prev/next solely for Google. Google disclosed in March 2019 that it had stopped using that markup. There is little evidence that the tags now improve Google crawling. Stable URLs and ordinary internal links do the essential work.
Control the URL multipliers surrounding pagination
Pagination is often blamed for an explosion created elsewhere. A page parameter moves through an ordered set. A facet creates a subset. A sort parameter rearranges a set. A tracking parameter records attribution. Treating all four as interchangeable leads to the wrong controls.
Consider a category with filters for material, color, size, availability, and price. If every combination can be reordered, paginated, and expressed in several parameter orders, each useful category sequence gains a large number of low-value variants. Faceted navigation and uncontrolled URL creation can make a site far larger than its owners expect.
| URL class | Its role | Recommended default |
|---|---|---|
| Primary category or archive | Main landing page for a content set | Indexable, internally prominent, and self-canonical |
| Page 2 and deeper | Continuation and item discovery | Crawlable, linked in sequence, and normally self-canonical |
| Curated facet with standalone value | Stable subset that serves a distinct need | Expose deliberately, give it a consistent URL, and support it with useful content and links |
| Sort or filter variant with no standalone value | Alternate presentation of an existing set | Keep it out of routine crawl paths; consolidate only when it is truly equivalent |
| Tracking or session URL | Measurement or temporary state | Remove it from internal links and point users and bots toward the clean destination |
| Empty or out-of-range page | No useful content | Remove links to it, omit it from sitemaps, and return an accurate response |
Turn that classification into generation rules in the CMS or commerce platform. Cleanup at the crawler level is less effective if templates continue manufacturing new variations.
- Whitelist intentional facets. Link only to combinations that have a defined user and search purpose. A usable filter does not automatically need an indexable landing page.
- Normalize parameter order and naming. The same state should not be reachable as several URLs merely because parameters were added in a different sequence or aliases were used.
- Keep tracking values out of internal links. Campaign parameters belong at acquisition boundaries, not in persistent navigation, breadcrumbs, related-item modules, or pagination controls.
- Prevent impossible combinations. Do not render links to empty intersections or filters that cannot change the result.
- Limit pagination to valid result pages. Calculate the actual last page and avoid links to arbitrary higher values.
- Consolidate exact duplicates. Redirect duplicate URL formats when the equivalence is permanent. Use canonical signals when an alternate representation must remain available, but do not label materially different subsets as duplicates.
Be careful with robots.txt. Blocking a pattern may reduce requests, but it also prevents the crawler from seeing page-level canonical or noindex signals on those URLs. More importantly, a broad rule can remove the only route to products buried in a filtered or paginated set. First confirm that every valuable destination has another crawlable path. Then remove unwanted internal links and duplicate generation at the source. Use crawling restrictions only after you know what they will cut off.
The same caution applies to noindex. Indexing eligibility and crawl access solve different problems. A noindex directive can keep a low-value result page out of the index, but the page still has to be crawled for that directive to be read. If the real problem is an unlimited URL generator, noindex alone leaves the generator running.
Audit the path from category page to destination URL
A useful audit must show both what your site exposes and what crawlers actually request. A crawler simulation, server logs, and Google Search Console answer different parts of that question. None is sufficient alone.
- Crawl from public entry points. Use Googlebot or Bingbot settings and begin at the homepage, major category pages, and XML sitemaps. Crawling as the search bot sees the site reveals a more realistic exposed URL count.
- Export every discovered URL with its pattern. Record status code, canonical target, indexability, referring page, crawl depth, and whether the URL appeared in a sitemap.
- Map representative page sequences. For each important template, follow page 1 to page 2, a middle page, the last page, and several item destinations. Verify that links exist in the rendered HTML and that each page returns the expected slice.
- Find canonical destinations with no internal links. A product listed in a sitemap but absent from navigation is still weakly connected. Determine which category or archive should provide its durable route.
- Analyze server logs by crawler and URL pattern. Separate requests for canonical destinations, pagination, facets, sorting, tracking parameters, errors, and redirects. This shows whether crawl activity supports discovery or loops through variants.
- Inspect “Discovered – currently not indexed” samples. Identify whether affected URLs are valuable destinations, duplicate parameters, or deep items whose only route is fragile pagination. The remedy depends on that classification.
- Check capacity signals. Compare bot requests with slow responses, timeouts, and server errors. Because poor server response can cause a crawler to reduce fetching speed and connections, reliability fixes may precede URL-policy changes.
- Repeat the crawl after deployment. Confirm that intended destinations remain reachable and that removed patterns are no longer linked. Do not judge success only by a smaller URL total.
Prioritize by consequence. Server failures and unbounded URL generation can affect the entire site. Broken page-to-page links can isolate whole sections. Duplicate first-page formats are usually narrower. Metadata refinements on page 27 matter less than restoring the link that allows a crawler to reach page 27 at all.
Track a compact set of outcome measures rather than one headline crawl count:
- The share of intended canonical products or posts reached during a full crawl.
- The number of valuable destination URLs with no crawlable internal link.
- The share of verified bot requests spent on noncanonical parameter patterns, redirects, errors, and empty pages.
- The recurrence of server errors or slow responses during crawler activity.
- The time between a meaningful content change and the next verified bot request, using CMS timestamps and logs.
- The trend and URL composition of “Discovered – currently not indexed” in Google Search Console.
Segment AI crawler traffic separately from Googlebot and Bingbot. AI agents and bots add their own access and resource considerations, so their requests should not be folded into one generic bot total. The broadly compatible foundation is still the same: stable URLs, accessible HTML links, accurate responses, deliberate crawler rules, and a server that remains healthy under load.
Key takeaways
- Optimize crawl paths, not the smallest possible URL count. Useful pagination can increase URL volume while improving discovery.
- Keep each valid paginated page stable and crawlable. Use direct HTML links, distinct result slices, one URL format, and self-referencing canonicals by default.
- Treat facets as the main multiplier. Whitelist intentional combinations and stop templates from linking arbitrary filter, sort, tracking, and pagination permutations.
- Do not use canonical, noindex, and robots.txt interchangeably. They address consolidation, indexing, and crawling respectively, and a careless rule can hide the only path to valuable content.
- Prove the result with three views. A site crawl shows what can be reached, logs show what bots request, and Search Console shows how Google processes discovered URLs.
Start with one high-value category rather than changing the whole site at once. Export its complete page chain, list every parameter variation the templates expose, and trace several deep items back to crawlable category links. If you cannot reach every intended item without entering arbitrary parameter states, fix that path first. Once the model works, apply the same URL rules to the remaining templates.
References
- Search Engine Land – Crawl budget: What you need to know in 2027
- Search Engine Land – Pagination and SEO: What you need to know in 2027

Leave a Reply