Tag: AI Bots

  • Crawl Budget and Pagination: A Technical SEO Playbook

    Crawl Budget and Pagination: A Technical SEO Playbook

    If your products or archive posts disappear after page 1, reducing the number of crawlable URLs can feel like the obvious fix. It often is not. Pagination may be the only internal route that exposes deeper items, so removing it can turn crawl waste into orphaned content.

    The better objective is controlled discovery: give crawlers a finite, stable sequence through valuable content while preventing filters, sort orders, tracking parameters, and duplicate URL formats from multiplying that sequence. You protect crawl capacity by removing useless paths, not by hiding useful ones.

    First decide whether you have a crawl-budget problem

    Crawl budget is the time and computing resources a crawler is prepared to spend on your site. For Googlebot, it reflects both crawl capacity and crawl demand. Capacity concerns what your server can handle without becoming unstable. Demand concerns which URLs appear valuable or in need of another visit.

    Those two forces create different problems. Slow responses and server errors can cause a crawler to reduce its pace. Duplicate, low-value, or spam-like URL patterns can reduce the apparent value of fetching more URLs. A pagination fix cannot compensate for an unreliable server, and faster hosting cannot make an unlimited set of filter combinations worth crawling.

    Google’s criteria for active crawl-budget management are narrower than many teams assume. The clearest candidates are sites with more than 1 million unique pages, medium or large sites whose content changes frequently, and sites with many URLs marked “Discovered – currently not indexed” in Google Search Console.

    That does not mean a smaller site can skip the audit. Your catalog, article count, or CMS dashboard does not reveal the number of URLs a crawler can encounter. Facets, pagination, alternate parameter orders, languages, locations, search pages, and session values can turn one content set into many crawlable representations.

    • Inventory the exposed URLs. Crawl from the same public entry points available to search engines. Do not begin with a spreadsheet of products or posts.
    • Group URLs by pattern. Separate canonical content, pagination, filters, sort orders, internal search, tracking parameters, and malformed combinations.
    • Distinguish discovery from indexing. A URL that has never been fetched points to a different constraint than a fetched page that was judged unworthy of indexing.
    • Check server behavior. Look for timeouts, error responses, and URL patterns that require disproportionately expensive rendering or database work.

    There is no universal healthy number of crawls per day. A useful baseline is whether important new or changed URLs are discovered and revisited while requests to low-value patterns remain controlled. Measure that outcome on your own site instead of copying another domain’s crawl rate.

    Build pagination as discovery infrastructure
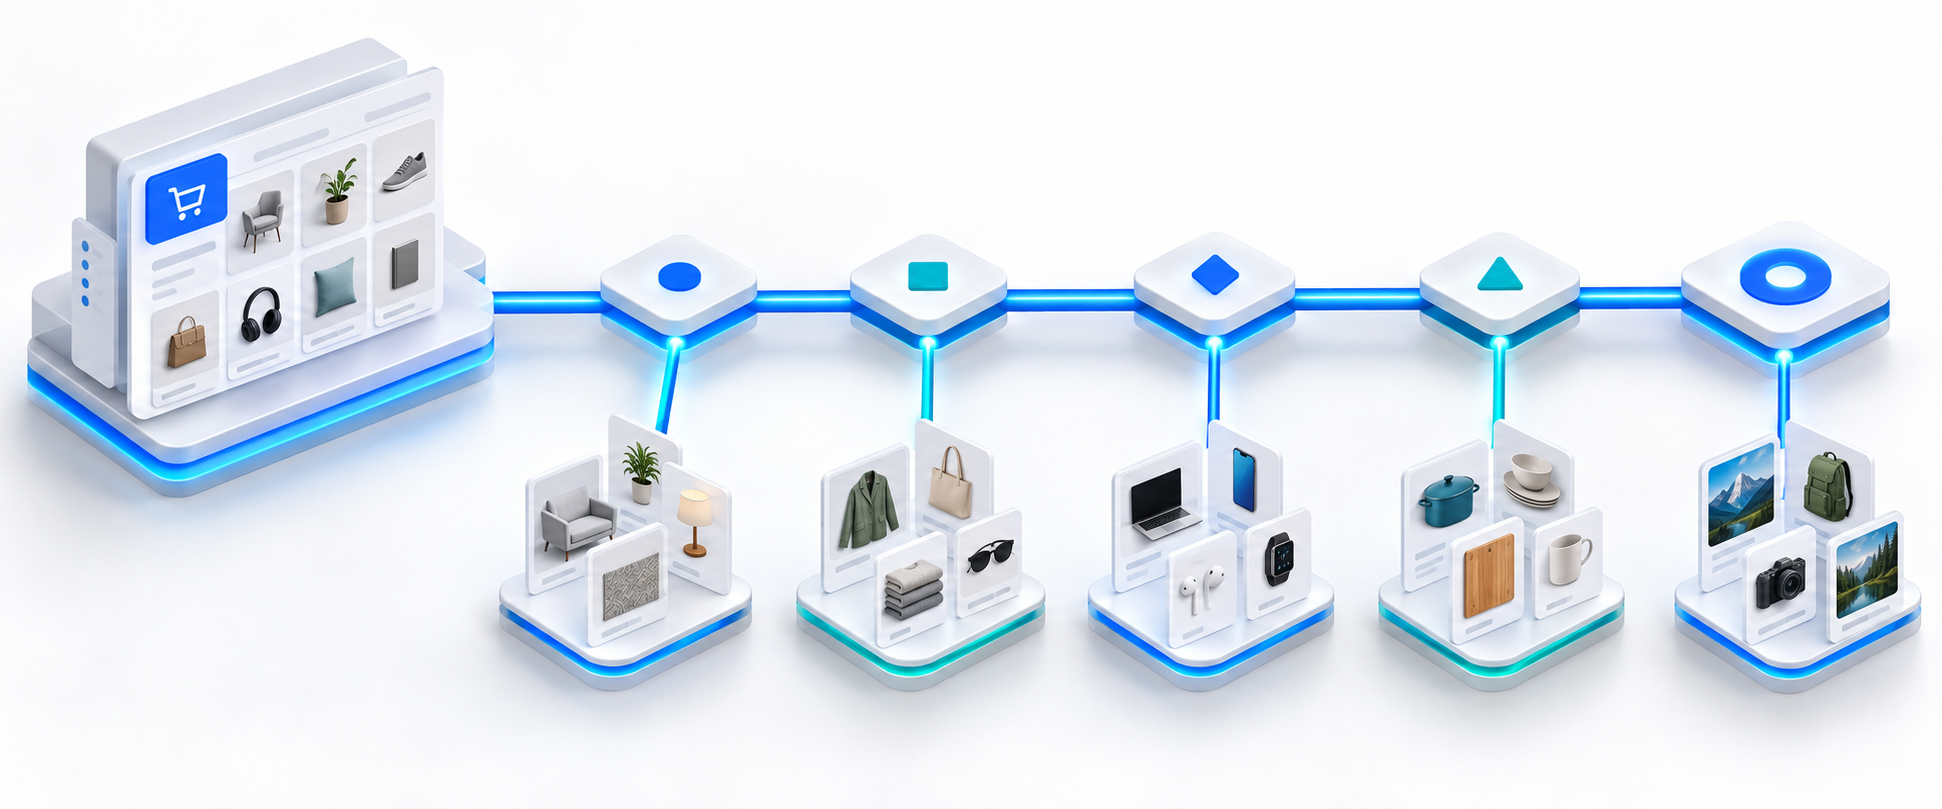
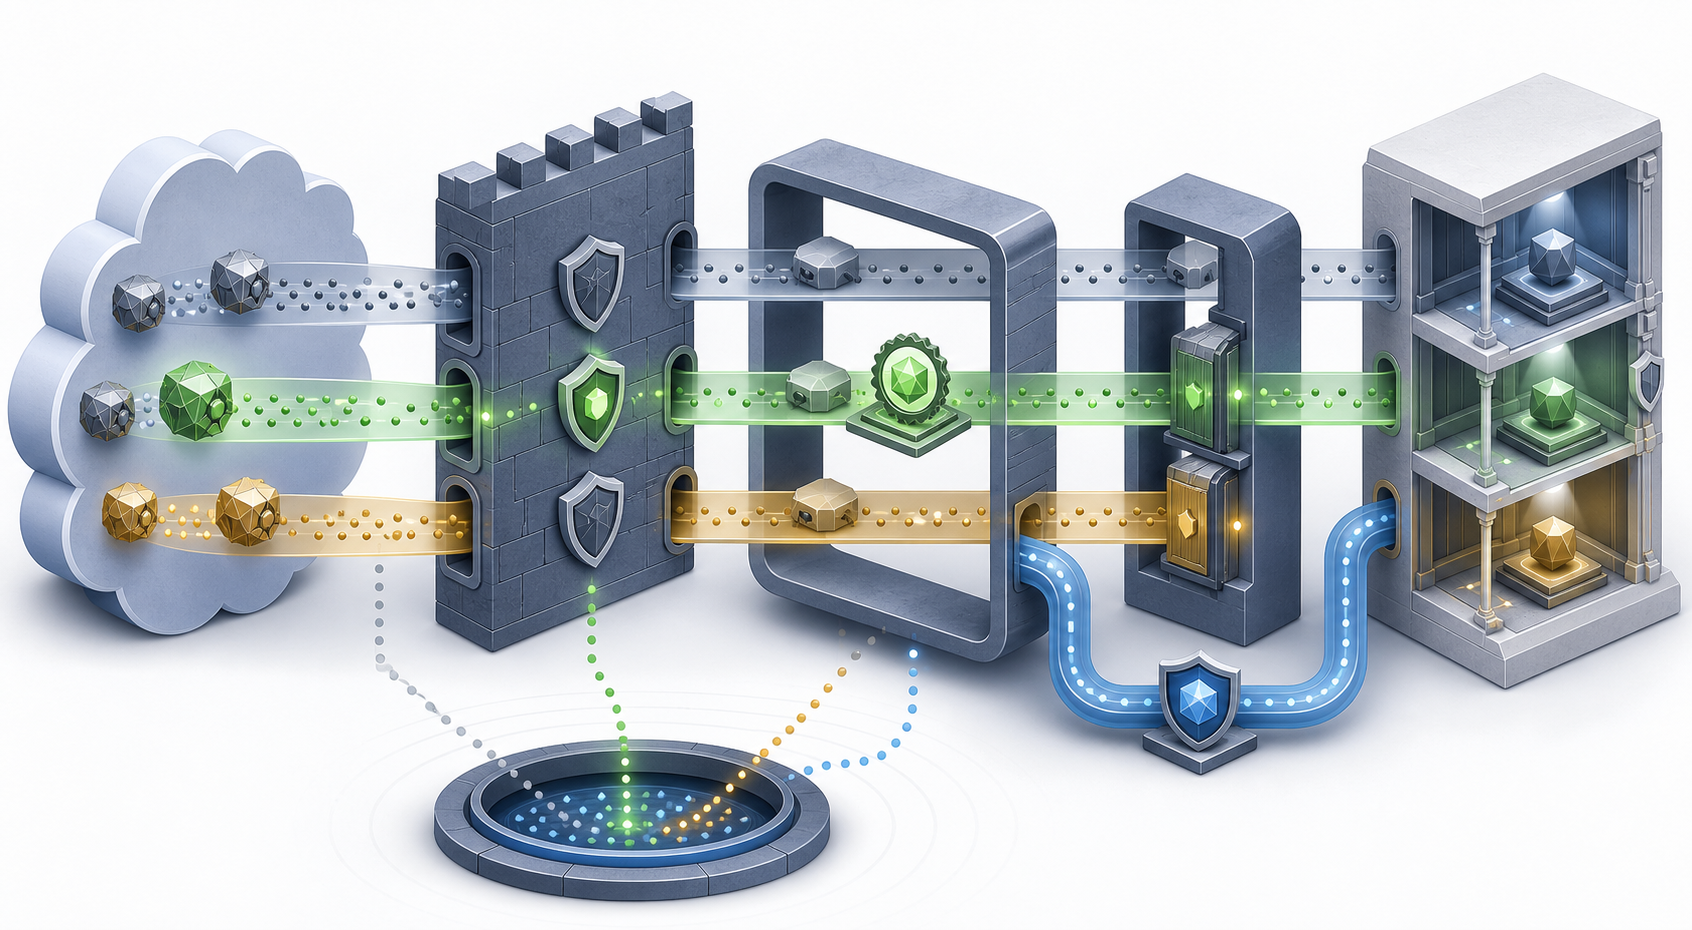
    A finite chain of page modules connects a category platform to multiple groups of content cards.

    Pagination divides one ordered content set into addressable pages. It adds URLs, but those URLs provide paths to products, posts, discussions, and other deeply nested content. That is productive crawl activity when each page exposes items that would otherwise be difficult to reach.

    A crawler should be able to begin at the first category or archive page, follow ordinary HTML links through the sequence, and reach every intended item. It should not need to click a JavaScript-only button, submit a form, maintain a session, or scroll until client-side code decides to load another batch.

    1. Choose one stable URL format. Formats such as ?page=2 or /page/2/ can work. Do not expose multiple formats for the same sequence.
    2. Use links with href destinations. Previous and next controls should be crawlable links. A short set of numbered links can provide additional routes into a long sequence.
    3. Link every listed item directly. Products and posts should have canonical destination URLs in the rendered listing, not destinations assembled only after an interaction.
    4. Give each page a distinct slice. Page 2 should not reproduce page 1 under a different URL. Stable ordering also reduces unnecessary repetition when crawlers revisit the sequence.
    5. Use a self-referencing canonical by default. If page 2 contains a distinct set of items, pointing its canonical to page 1 misrepresents that relationship. Consolidate only URLs that are genuinely equivalent.
    6. Keep page 1 canonicalized consistently. Link to one preferred first-page URL instead of alternating between the clean category URL and a duplicate such as ?page=1.
    7. Give infinite scroll a paginated fallback. Each batch should be available at a stable URL through crawlable links, even if human visitors receive a continuous visual experience.
    8. Stop at the real end of the sequence. Do not generate an endless run of empty page numbers. Remove internal links to pages beyond the last valid result and return an appropriate not-found response when an invalid page is requested.

    Do not automatically canonicalize every paginated URL to the first page or apply a blanket noindex directive. Overly aggressive canonicalization can prevent useful paginated URLs from appearing in search results, while removing their crawl value can make deeper items harder to find. A canonical signal expresses a preferred equivalent; it is not a general crawl-control switch.

    An XML sitemap helps crawlers discover canonical products, posts, and other destination pages, but it does not replace internal linking. Pagination remains an additional discovery route even when sitemaps are present. That route also shows how the content belongs within your site architecture.

    Do not spend engineering time adding rel=prev/next solely for Google. Google disclosed in March 2019 that it had stopped using that markup. There is little evidence that the tags now improve Google crawling. Stable URLs and ordinary internal links do the essential work.

    Control the URL multipliers surrounding pagination
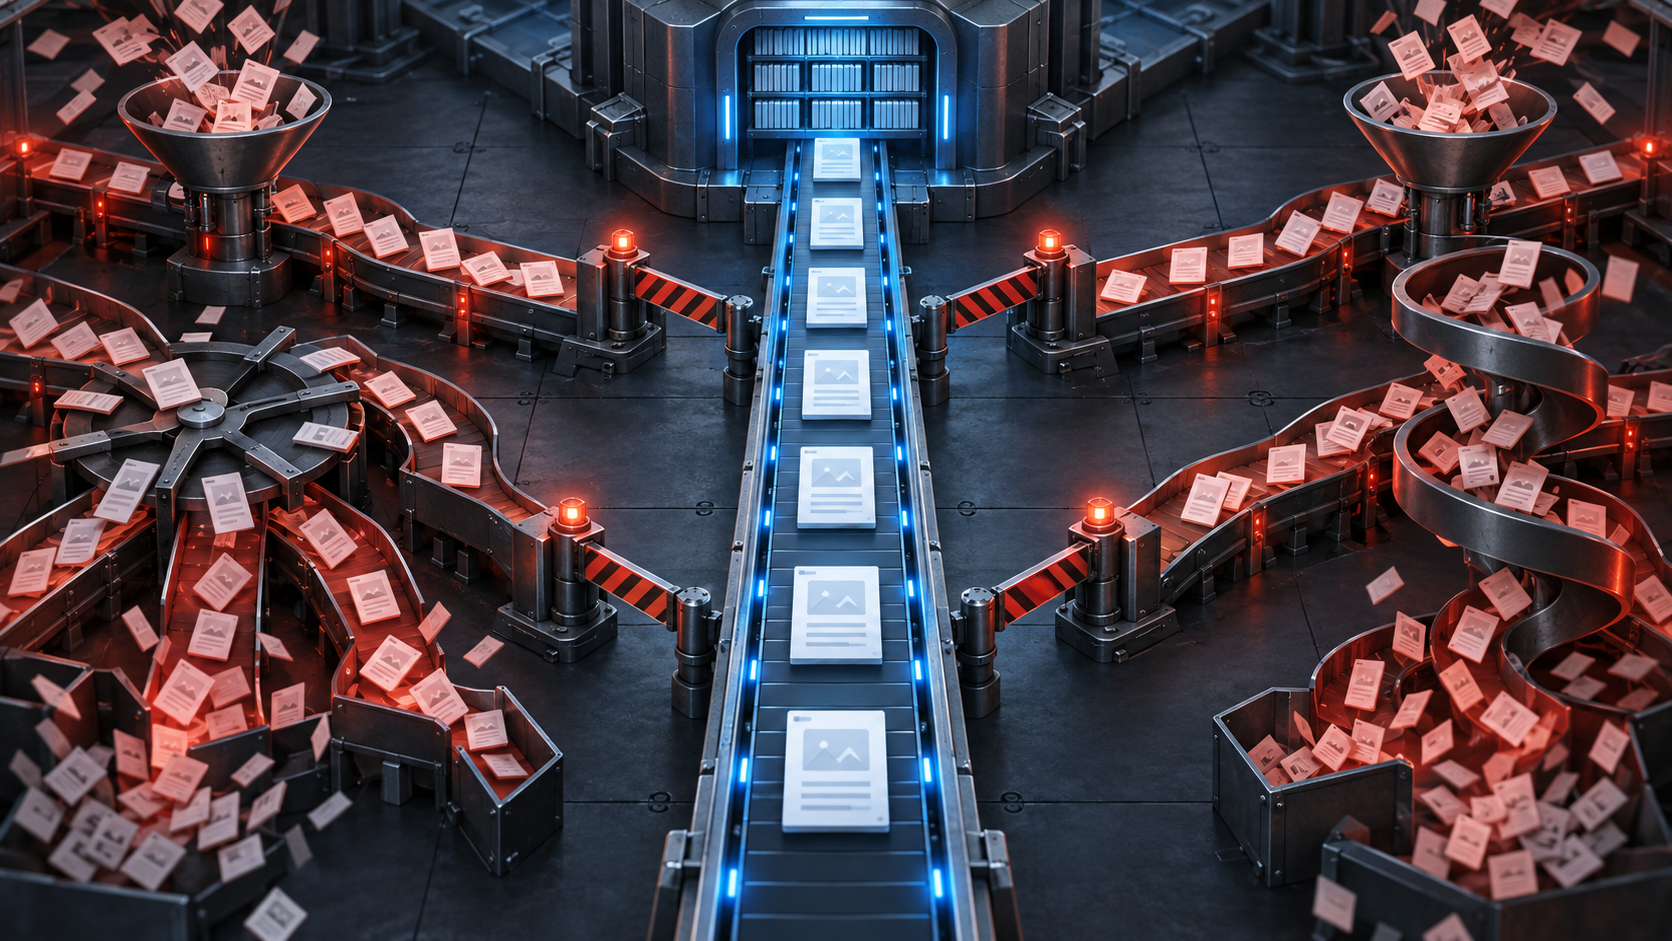
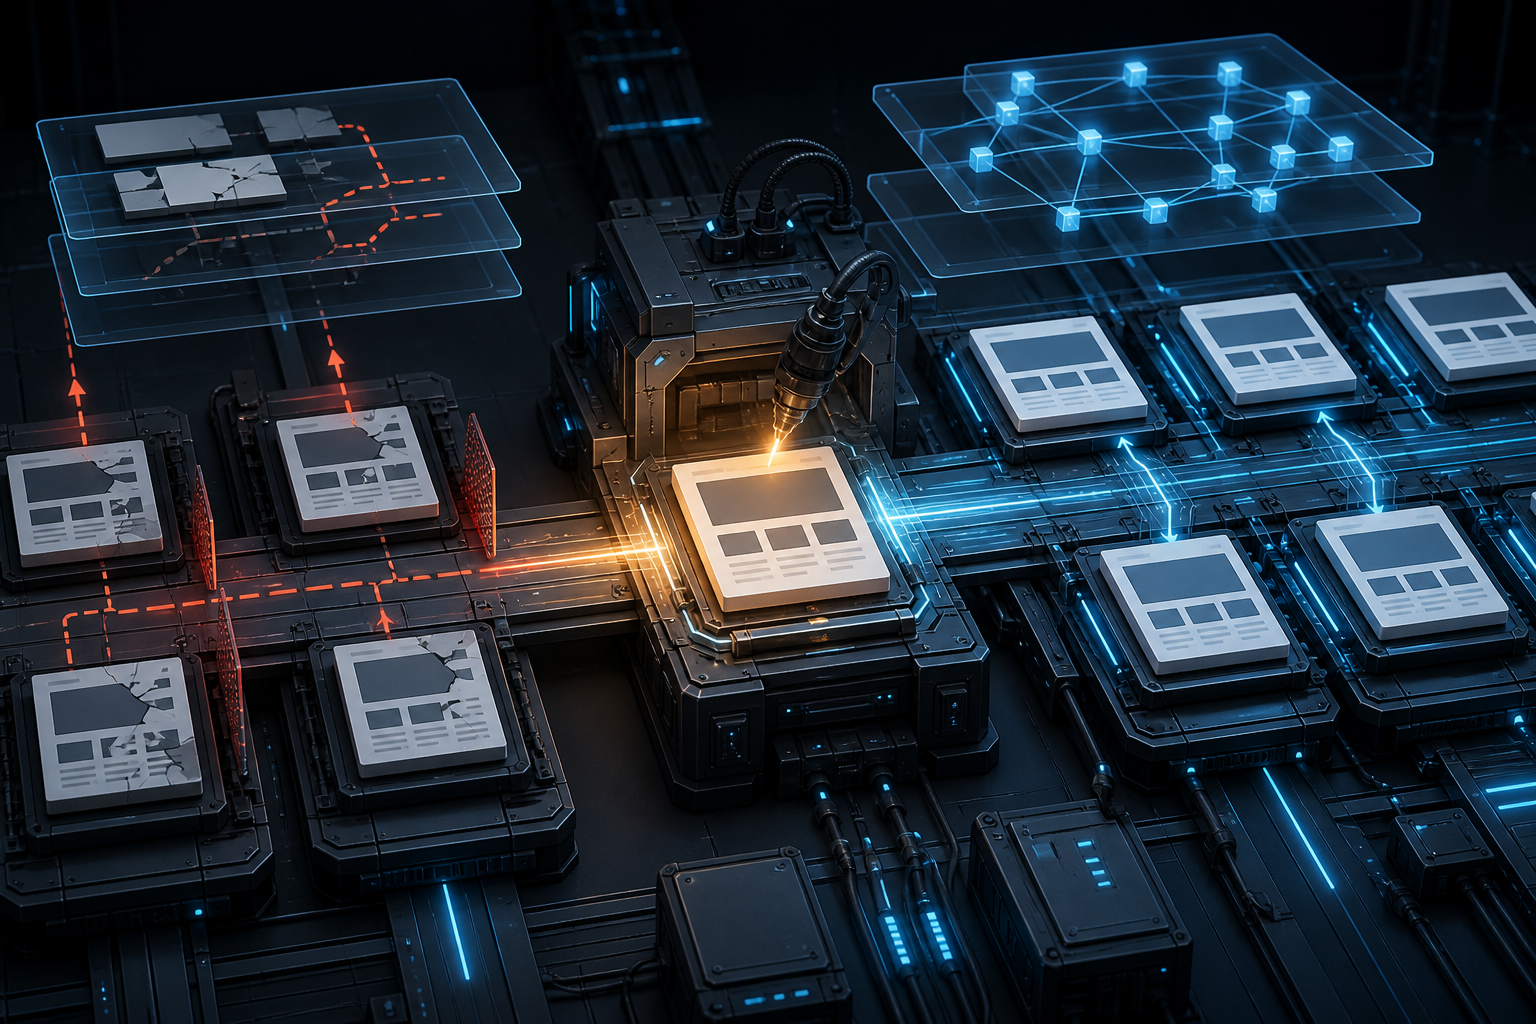
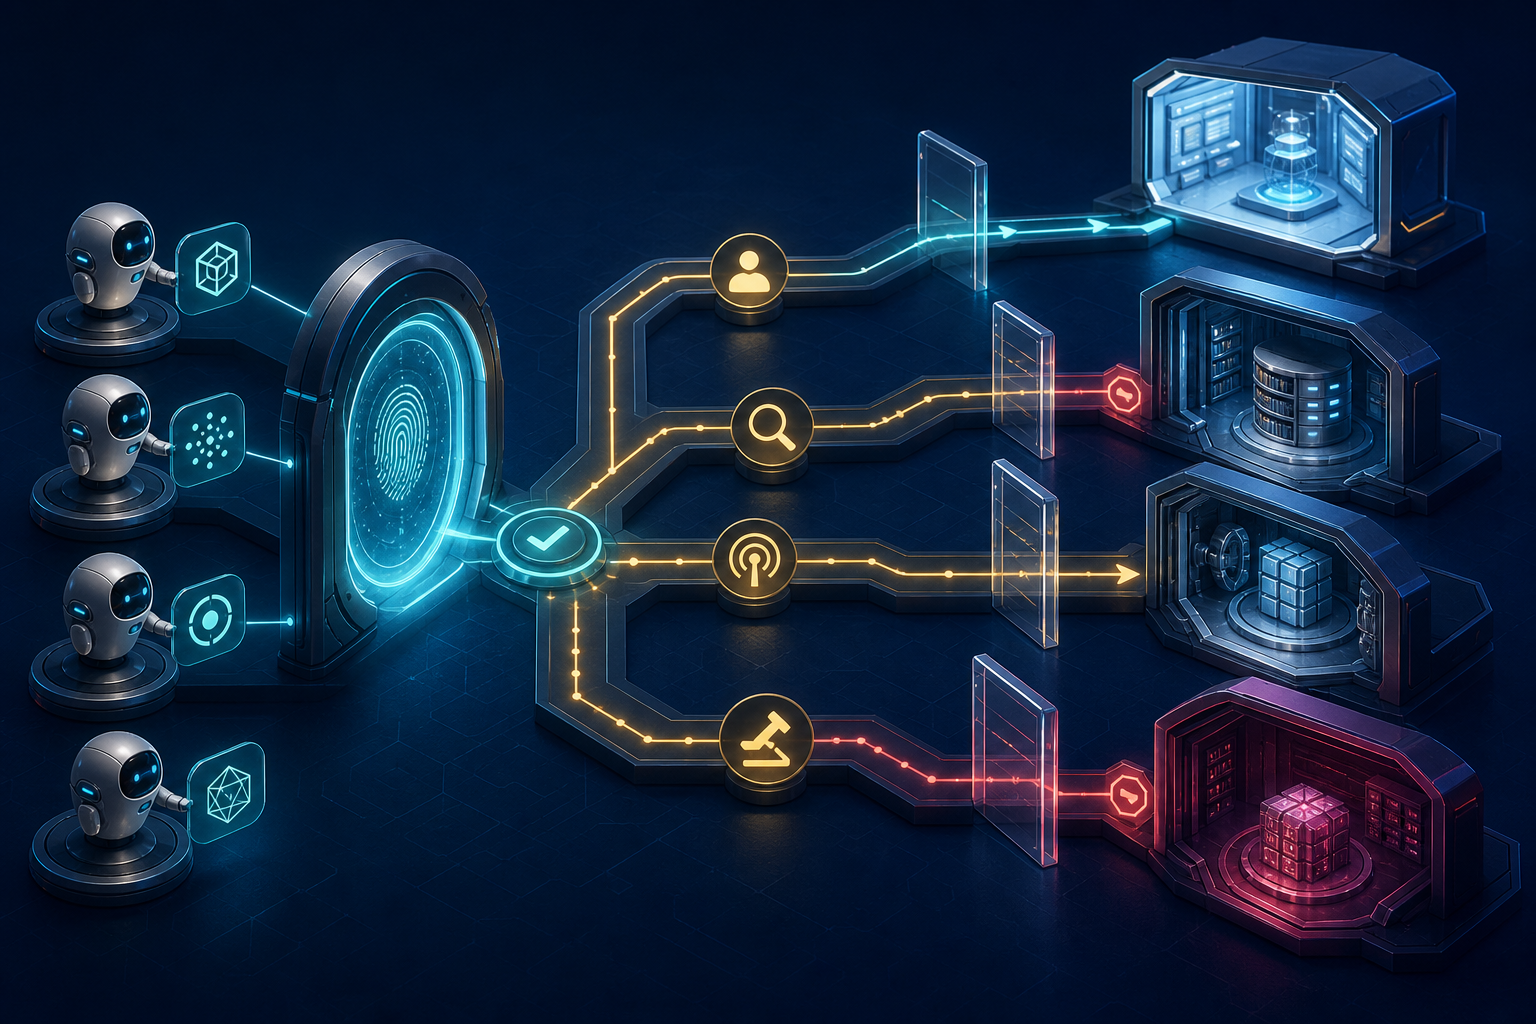
    A central route carries unique page tiles forward while barriers stop surrounding branches from producing duplicates.

    Pagination is often blamed for an explosion created elsewhere. A page parameter moves through an ordered set. A facet creates a subset. A sort parameter rearranges a set. A tracking parameter records attribution. Treating all four as interchangeable leads to the wrong controls.

    Consider a category with filters for material, color, size, availability, and price. If every combination can be reordered, paginated, and expressed in several parameter orders, each useful category sequence gains a large number of low-value variants. Faceted navigation and uncontrolled URL creation can make a site far larger than its owners expect.

    URL classIts roleRecommended default
    Primary category or archiveMain landing page for a content setIndexable, internally prominent, and self-canonical
    Page 2 and deeperContinuation and item discoveryCrawlable, linked in sequence, and normally self-canonical
    Curated facet with standalone valueStable subset that serves a distinct needExpose deliberately, give it a consistent URL, and support it with useful content and links
    Sort or filter variant with no standalone valueAlternate presentation of an existing setKeep it out of routine crawl paths; consolidate only when it is truly equivalent
    Tracking or session URLMeasurement or temporary stateRemove it from internal links and point users and bots toward the clean destination
    Empty or out-of-range pageNo useful contentRemove links to it, omit it from sitemaps, and return an accurate response

    Turn that classification into generation rules in the CMS or commerce platform. Cleanup at the crawler level is less effective if templates continue manufacturing new variations.

    • Whitelist intentional facets. Link only to combinations that have a defined user and search purpose. A usable filter does not automatically need an indexable landing page.
    • Normalize parameter order and naming. The same state should not be reachable as several URLs merely because parameters were added in a different sequence or aliases were used.
    • Keep tracking values out of internal links. Campaign parameters belong at acquisition boundaries, not in persistent navigation, breadcrumbs, related-item modules, or pagination controls.
    • Prevent impossible combinations. Do not render links to empty intersections or filters that cannot change the result.
    • Limit pagination to valid result pages. Calculate the actual last page and avoid links to arbitrary higher values.
    • Consolidate exact duplicates. Redirect duplicate URL formats when the equivalence is permanent. Use canonical signals when an alternate representation must remain available, but do not label materially different subsets as duplicates.

    Be careful with robots.txt. Blocking a pattern may reduce requests, but it also prevents the crawler from seeing page-level canonical or noindex signals on those URLs. More importantly, a broad rule can remove the only route to products buried in a filtered or paginated set. First confirm that every valuable destination has another crawlable path. Then remove unwanted internal links and duplicate generation at the source. Use crawling restrictions only after you know what they will cut off.

    The same caution applies to noindex. Indexing eligibility and crawl access solve different problems. A noindex directive can keep a low-value result page out of the index, but the page still has to be crawled for that directive to be read. If the real problem is an unlimited URL generator, noindex alone leaves the generator running.

    Audit the path from category page to destination URL

    A useful audit must show both what your site exposes and what crawlers actually request. A crawler simulation, server logs, and Google Search Console answer different parts of that question. None is sufficient alone.

    1. Crawl from public entry points. Use Googlebot or Bingbot settings and begin at the homepage, major category pages, and XML sitemaps. Crawling as the search bot sees the site reveals a more realistic exposed URL count.
    2. Export every discovered URL with its pattern. Record status code, canonical target, indexability, referring page, crawl depth, and whether the URL appeared in a sitemap.
    3. Map representative page sequences. For each important template, follow page 1 to page 2, a middle page, the last page, and several item destinations. Verify that links exist in the rendered HTML and that each page returns the expected slice.
    4. Find canonical destinations with no internal links. A product listed in a sitemap but absent from navigation is still weakly connected. Determine which category or archive should provide its durable route.
    5. Analyze server logs by crawler and URL pattern. Separate requests for canonical destinations, pagination, facets, sorting, tracking parameters, errors, and redirects. This shows whether crawl activity supports discovery or loops through variants.
    6. Inspect “Discovered – currently not indexed” samples. Identify whether affected URLs are valuable destinations, duplicate parameters, or deep items whose only route is fragile pagination. The remedy depends on that classification.
    7. Check capacity signals. Compare bot requests with slow responses, timeouts, and server errors. Because poor server response can cause a crawler to reduce fetching speed and connections, reliability fixes may precede URL-policy changes.
    8. Repeat the crawl after deployment. Confirm that intended destinations remain reachable and that removed patterns are no longer linked. Do not judge success only by a smaller URL total.

    Prioritize by consequence. Server failures and unbounded URL generation can affect the entire site. Broken page-to-page links can isolate whole sections. Duplicate first-page formats are usually narrower. Metadata refinements on page 27 matter less than restoring the link that allows a crawler to reach page 27 at all.

    Track a compact set of outcome measures rather than one headline crawl count:

    • The share of intended canonical products or posts reached during a full crawl.
    • The number of valuable destination URLs with no crawlable internal link.
    • The share of verified bot requests spent on noncanonical parameter patterns, redirects, errors, and empty pages.
    • The recurrence of server errors or slow responses during crawler activity.
    • The time between a meaningful content change and the next verified bot request, using CMS timestamps and logs.
    • The trend and URL composition of “Discovered – currently not indexed” in Google Search Console.

    Segment AI crawler traffic separately from Googlebot and Bingbot. AI agents and bots add their own access and resource considerations, so their requests should not be folded into one generic bot total. The broadly compatible foundation is still the same: stable URLs, accessible HTML links, accurate responses, deliberate crawler rules, and a server that remains healthy under load.

    Key takeaways

    • Optimize crawl paths, not the smallest possible URL count. Useful pagination can increase URL volume while improving discovery.
    • Keep each valid paginated page stable and crawlable. Use direct HTML links, distinct result slices, one URL format, and self-referencing canonicals by default.
    • Treat facets as the main multiplier. Whitelist intentional combinations and stop templates from linking arbitrary filter, sort, tracking, and pagination permutations.
    • Do not use canonical, noindex, and robots.txt interchangeably. They address consolidation, indexing, and crawling respectively, and a careless rule can hide the only path to valuable content.
    • Prove the result with three views. A site crawl shows what can be reached, logs show what bots request, and Search Console shows how Google processes discovered URLs.

    Start with one high-value category rather than changing the whole site at once. Export its complete page chain, list every parameter variation the templates expose, and trace several deep items back to crawlable category links. If you cannot reach every intended item without entering arbitrary parameter states, fix that path first. Once the model works, apply the same URL rules to the remaining templates.

    References


  • AI Search Crawlability: A Technical SEO Audit Framework

    AI Search Crawlability: A Technical SEO Audit Framework

    Your pages can perform well in Google and still be effectively missing from AI-generated answers. The problem is often not the writing. An AI crawler may be blocked, unable to discover links, or receiving an HTML shell that omits the content and structured data people see in a browser.

    You can diagnose that problem without guessing about prompts or rewriting every page. Audit the route from robots.txt to the raw server response, then fix the first point where a retrieval bot loses access, discovery, or meaning.

    Key takeaways

    • Audit the initial HTML response, not just the rendered page in your browser. Critical links, text, headings, metadata, and JSON-LD should be present before JavaScript runs.
    • Treat training crawlers, search or retrieval crawlers, and user-initiated browsing agents as separate policy decisions in robots.txt.
    • Use server-side rendering, static generation, or a hybrid approach for anything an AI system must discover, understand, or cite.
    • Use server logs to distinguish a crawlability failure from a selection failure. A page that was never requested has a different problem from a page that was fetched but not cited.

    Crawlability has three gates, and robots.txt is only the first

    A useful AI crawlability audit separates access, discovery, and extraction. Combining them into one pass-or-fail score hides the actual repair.

    GateWhat to testTypical failure
    AccessDoes your robots policy permit the intended agent, and can it receive a usable response?The agent is disallowed, challenged, rate-limited, redirected incorrectly, or served an error.
    DiscoveryCan the agent find the URL through links that exist in the initial HTML?It reaches a hub page but cannot see JavaScript-injected links to child pages.
    ExtractionDoes the response contain the main text, headings, factual details, metadata, and structured data?The URL loads, but the response is an application shell whose useful content appears only after JavaScript runs.

    Passing one gate proves nothing about the next. An Allow rule cannot make a client-rendered product description appear in the response. An XML sitemap may expose a URL, but it cannot supply missing text or JSON-LD. A browser screenshot can show a complete page even when the crawler receives almost nothing.

    Do not use Google rendering as a proxy for every other system. The crawler ecosystem includes agents with different jobs and different rendering behavior. A successful Google inspection therefore does not establish that an AI retrieval crawler can follow the same path or extract the same facts.

    Set crawler access by purpose, not by the letters AI

    AI platforms can operate more than one agent. One may crawl broadly for model training, another may retrieve information for search, and another may visit a URL in response to a user’s request. Blocking or allowing the entire family with an inherited rule can produce the opposite of your intended policy.

    • Training-oriented access: Decide whether broad reuse of your content fits your publishing, licensing, and compliance policy. ClaudeBot is an example of a crawler identified for training.
    • Search and retrieval access: If you want pages to be available for AI answers, inspect rules affecting agents such as Claude-SearchBot and OAI-SearchBot separately from training crawlers.
    • User-initiated browsing: Agents such as Claude-User and ChatGPT-User may fetch a page when a person asks an assistant to visit or use it. Treat that behavior as its own access decision.

    The names matter because a blanket policy is not a strategy. A publisher may reasonably block training while allowing retrieval. A regulated organization may choose a narrower policy. The technical requirement is that robots.txt express the decision you actually made rather than a rule inherited from an old template, security product, or previous agency.

    1. Write down the intended outcome for training, retrieval, and user-initiated access before editing robots.txt.
    2. Map every relevant user agent to one of those outcomes. Do not assume agents owned by the same company serve the same function.
    3. Review specific user-agent groups as well as broad wildcard rules. Look for inherited blocks that catch retrieval agents unintentionally.
    4. Test the resulting policy with the exact user-agent names, then fetch representative URLs to confirm that permitted agents receive normal responses.
    5. Record who owns the policy and why. Otherwise, a future security or infrastructure change can silently reverse it.

    Robots permission is necessary only when you want that agent to enter. It is not evidence that the agent can navigate the site or understand the response. Continue the audit even after the policy passes.

    Put the discovery path and critical facts in the initial HTML

    Two server-response paths show a crawler receiving a complete structured page on one side and an empty page shell on the other.

    Client-side rendering creates the largest practical gap between what a person sees and what many AI crawlers receive. If the server sends an empty container and JavaScript later inserts navigation, body copy, product details, or schema, a crawler that does not execute that script encounters an incomplete page.

    The risk is especially clear in internal navigation. During the first 27 days of a 41-day controlled crawl experiment, GPTBot and ClaudeBot each reached all 748 hierarchy pages exposed through hard-coded HTML and none of the hierarchy pages available only through JavaScript-injected links. Googlebot reached seven of 293 pages in the JavaScript group, or 2%, and 35 of 748 in the HTML group, or 5%.

    Those percentages are not universal crawl-rate benchmarks. The experiment intentionally removed sitemaps, breadcrumbs, and other alternative discovery paths so that reaching a JavaScript-only child would demonstrate script execution. What it establishes is the mechanism: when the only route to a page is a link inserted after load, major AI crawlers may stop at the parent.

    Different crawlers from the same organization are not interchangeable either. GoogleOther rendered enough JavaScript to reach 142 of the 293 JavaScript-group pages in that experiment, while Googlebot reached seven. Activity from a secondary agent does not prove that the crawler responsible for a particular search or retrieval function saw the same pages.

    For every page you want an AI system to use, place these elements in the server-delivered response:

    • Followable internal links: Category, topic, breadcrumb, related-content, pagination, and other important paths should use links with destinations present in the raw HTML. Keep XML sitemaps as an additional discovery route, not as a repair for invisible navigation.
    • The primary answer: The page’s main text, headings, definitions, specifications, and other decision-critical facts should not depend on a client-side API call.
    • Entity details: Names, authors, dates, prices, product attributes, and relationships should appear clearly where they are relevant to the page.
    • Critical metadata: Do not rely on JavaScript to add information that a crawler needs to classify or interpret the page.
    • Structured data: Put the applicable schema markup, including JSON-LD, in the initial HTML rather than injecting it after the application mounts.

    Server-delivered structured data gives a no-JavaScript crawler explicit entity and relationship signals. It can reduce ambiguity around facts such as names, dates, authors, prices, and product attributes. It should describe information that is also supported by the page, not act as a hidden substitute for missing visible content.

    You do not have to remove JavaScript from the site. Use static site generation for content that can be built in advance, server-side rendering for pages whose critical response must be assembled dynamically, or a hybrid model that renders essential content and navigation on the server while leaving filters, interactions, and enhancements to the client.

    The implementation label is less important than the response. A framework can claim SSR while a particular component still fetches its text, links, or schema in the browser. Verify the actual HTML returned for the actual template.

    Run an audit that ends in a template-level fix

    Multiple page tiles pass through a diagnostic system and become complete after a central website template component is repaired.

    Start with representative paths rather than a random list of URLs. Include a top-level hub, a child page, a deep page that depends on several internal clicks, and each commercially or editorially important template. The relationship between those pages is part of the test.

    1. Fetch the raw response without executing JavaScript. Save the response body and relevant headers. In a browser, View Source is more useful for this check than the Elements panel, which normally reflects the post-JavaScript document.
    2. Confirm basic access. Check the response status, redirect destination, robots rules, and any challenge or interstitial delivered to the chosen agent. A visually normal page in your own session does not prove that an unauthenticated crawler receives it.
    3. Search the response for the primary information. Verify that the title, main heading, answer text, defining facts, authorship, dates, product information, and other page-specific content are present as text rather than empty component placeholders.
    4. Trace the internal path. Starting at the hub, inspect the raw HTML for links to the next level. Repeat until you reach the deep sample. If the path disappears before JavaScript runs, you have found a discovery boundary.
    5. Inspect JSON-LD in the response. Confirm that the intended schema type, entity properties, and relationships are present server-side and agree with the information a reader can see.
    6. Compare raw and rendered output. Any critical element that exists only in the rendered document is a client-side dependency. Classify it as discovery, content, metadata, or structured data so the development request names the actual failure.
    7. Review server logs. Group requests by user agent, path, response status, and time. Look for agents that reach hubs but consistently stop before child pages. Do not trust a user-agent string alone when identity matters; the controlled crawler experiment verified Googlebot and Bingbot through reverse DNS to exclude spoofed traffic.
    8. Repair the shared template and retest the path. A server-rendering fix to a hub, navigation component, or JSON-LD component can restore access across many URLs. Confirm the new response before treating deployment as completion.

    Interpret the failure pattern before changing content

    • The agent never requests the URL: Check robots access and discovery first. The absence of a request is not evidence that the copy needs optimization.
    • The agent requests hubs but not their children: Inspect the parent response for missing links. A repeated stop at the same directory level is a strong JavaScript-boundary signal when the child links are absent from raw HTML.
    • The agent requests the page but receives a thin shell: Move the critical content and facts into SSR, SSG, or hybrid output. Changing schema alone will not supply the missing body content.
    • The text is present but JSON-LD appears only after rendering: change how the markup is delivered. Server-render it and verify it in the response body.
    • Training is allowed while retrieval is blocked: revisit the robots policy if AI search visibility is the goal. The configuration does not match that objective.
    • The page is fetched with complete HTML but is not cited: crawlability has probably passed for that request. Retrieval, relevance, factual clarity, and citation selection are separate stages, so do not keep treating every absence as a rendering bug.

    Begin with one high-value hub and its deepest important child. Make sure an intended retrieval agent can access both URLs and that the raw responses contain the links, main content, factual details, and JSON-LD needed to interpret them. Once that path passes, apply the repair at the template level and verify the result in your logs before commissioning another round of content rewrites.

    References


  • AI Crawler Blocking and Publisher Citations: What to Do

    AI Crawler Blocking and Publisher Citations: What to Do

    If you publish original reporting or expert content, AI access can look like a blunt choice: allow crawlers and risk uncontrolled reuse, or block them and risk disappearing from AI answers. That framing is too simple to support a sound policy.

    Your real decision is narrower: which forms of access serve your publishing goals, which ones create unacceptable risk, and what evidence would justify changing the rules? Treating every AI bot as the same crawler makes all three questions harder to answer.

    Blocking is a crawler instruction, not a citation switch

    A rule in robots.txt tells a matching, compliant crawler whether it may request specified URLs. It does not directly tell an answer engine to cite your pages, remove an existing citation, forget previously acquired material, or resolve questions about licensing and content rights.

    That distinction matters because crawler blocking does not produce one consistent citation outcome. An analysis spanning 31 million AI citations and the robots.txt files of 105 publishers found that blocking affected some models but appeared to do nothing on others. This is strong evidence against treating a sitewide block as a universal off switch. It does not establish how every individual engine will respond to your site.

    Several mechanisms can explain why a blocked domain may still appear in an answer. An engine may already hold an older representation of the page. It may encounter the information through syndication, quotation, feeds, links, or another accessible copy. A vendor may also use different access paths for training, indexing, search retrieval, and user-requested page fetching. Blocking one declared user agent controls only that user agent’s future requests to the covered URLs.

    Key takeaways

    • Blocking an AI crawler may change citations in one model and have no observable effect in another.
    • A citation is an output from an answer system; robots.txt governs one input path.
    • Do not use a sitewide block when your actual concern applies only to a particular crawler, content section, or use case.
    • Measure citation coverage, freshness, referrals, and crawl activity before and after a change.
    • Keep every policy change documented and reversible because crawler identities and model behavior can change.

    Separate training, discovery, retrieval, and citation

    A central digital library connects to four separate gated routes for bulk transfer, scanning, single-document retrieval, and a return link to a source.

    Publishers often say they want to block AI when they mean one of four different things. You may object to model training. You may want to prevent a page from entering an AI search index. You may want to stop live retrieval when a user asks a question. Or you may want an engine to stop naming your domain in generated answers.

    Those are not interchangeable objectives. A policy can restrict one access path without producing the desired result at another layer. Before editing robots.txt, write down the exact outcome you want and the evidence that would prove you achieved it.

    Decision layerThe question to answerEvidence to collect
    TrainingDo you permit this vendor to use covered content for model development?The vendor’s documented crawler purpose, your agreements, and applicable rights guidance
    DiscoveryDo you want new and updated URLs available to the engine’s search or retrieval system?Declared crawler activity, discovery of test URLs, and citation freshness
    Live retrievalMay the system fetch a page in response to a user’s request?Server requests associated with controlled prompts and the responses returned
    CitationDoes your domain receive visible attribution in answers that rely on your subject matter?A fixed query set, cited URLs, answer captures, dates, and referral traffic

    Build a crawler registry around those layers. For each user-agent token, record the vendor, declared purpose, official documentation you relied on, current directive, affected paths, date added, internal owner, and next review trigger. A label such as AI bot is not precise enough. If you cannot verify what a token controls, mark it unverified instead of guessing from its name.

    Audit every hostname that serves publishable content. A correct policy on the main domain does not tell you what is served from a separate news, mobile, archive, or syndicated host. Fetch the live /robots.txt file from each relevant hostname, then compare the returned file with the configuration you intended to deploy.

    Choose the policy that matches the value you protect

    There is no universally correct balance between AI visibility and access control. A publisher funded by subscriptions may value exclusivity differently from a specialist publication that depends on discovery and authority. The right policy starts with the business outcome, not with a generic list of bots.

    If AI citations are a discovery channel

    Preserve the access paths that appear to support discovery and retrieval while evaluating training controls separately. Do not assume that allowing every AI-labeled crawler will buy citations. Permission is only a prerequisite for a crawler to request content; it is not a promise that the engine will select, quote, or attribute your page.

    Prioritize the content where attribution has measurable value: original reporting, unique datasets, primary explanations, product documentation, and pages that answer recurring audience questions. Track whether engines cite the canonical page, an outdated URL, a syndicated copy, or another site discussing your work. That URL-level distinction tells you more than a domain-wide visibility score.

    If content control is the primary concern

    Block the verified crawler or protected path that corresponds to the concern, then define what success means. Success might be the end of requests from that declared user agent. It should not automatically be defined as disappearance from every generated answer, because blocking may not remove previously acquired material or copies available elsewhere.

    Do not treat robots.txt as a licensing agreement or a complete legal remedy. It is a technical access signal. If the decision affects contracted syndication, paid archives, copyright enforcement, or material revenue, have qualified legal counsel review the policy and the relevant agreements before you rely on the file as protection.

    If you need a balanced default

    Use selective controls rather than an undifferentiated allow-all or block-all rule. Keep public, citation-worthy pages available to verified discovery or retrieval crawlers when that supports your goals. Apply narrower restrictions to premium sections, private utilities, internal search results, duplicate archives, or other areas that have a different value and risk profile.

    Path-level rules require operational discipline. A careless pattern can cover more URLs than intended, and a later site migration can change what the pattern matches. Pair each directive with a plain-language note describing its purpose and test representative allowed and blocked URLs after every deployment that touches routing, hostnames, or robots.txt.

    Measure a block as a controlled publishing change

    Two matching content setups are observed side by side while an editor changes one removable access gate and leaves the other conditions aligned.

    A citation audit cannot tell you much if the query set, content, and crawler policy all change at once. Use a fixed protocol so that a drop or gain has a plausible connection to the rule you changed.

    1. State the hypothesis. Name the crawler or access path, the URLs affected, the expected outcome, and the downside you are willing to accept.
    2. Create a baseline. Record current directives, server requests, AI citations, cited URLs, answer captures, referral sessions, and publication dates before making the change.
    3. Use a stable query set. Include branded questions, non-branded questions where your content is eligible, and queries tied to newly published material. Keep the wording fixed during the test.
    4. Change one crawler family or content segment. Multiple simultaneous blocks may be quicker to deploy, but they make the result difficult to interpret.
    5. Verify the live rule. Fetch the public file, test representative URLs, and confirm that unrelated search crawlers and content sections retain their intended access.
    6. Observe a normal publishing cycle. Your measurement period must include enough new and updated content to reveal whether discovery and citation freshness changed. A quiet interval cannot test freshness.
    7. Repeat the same checks. Use the same engines, query wording, account state where practical, location assumptions, and capture method. Generated answers can vary, so retain the underlying observations rather than only a summary score.
    8. Compare by engine and URL class. A blended total can hide a decline in one model, an increase in another, or a problem limited to recent reporting.
    9. Keep or reverse the rule. Apply a decision threshold chosen in advance. Document the result even when no effect is visible.

    Define citation coverage as the share of eligible test queries that produce at least one citation to your domain. Record citation accuracy separately: whether the linked page actually supports the claim beside it. Also measure citation freshness as the interval between publication or material update and the first observed citation. These metrics answer different questions. A domain can maintain overall coverage while engines continue citing old pages.

    Referral sessions are useful but incomplete. A visible citation can influence recognition without receiving a click, while an uncited brand mention will not appear in citation counts. Keep citations, mentions, referral traffic, and crawler requests as separate columns so that one metric does not stand in for the whole outcome.

    Server logs provide another necessary check, but declared user-agent strings are not proof of identity on their own. Use the vendor’s current verification method where one is available, retain request details needed for analysis, and classify unverifiable traffic separately. Otherwise, spoofed or mislabeled requests can make a supposedly precise crawler report misleading.

    Watch for confounders before claiming that a directive caused the result. Major content revisions, URL migrations, canonical changes, paywall changes, syndication launches, engine updates, and shifts in publishing volume can all alter citations during the same period. Note those events in the audit log and rerun the test when the result is ambiguous.

    Make the next crawler decision reversible

    Do not deploy a sitewide AI block merely because you expect it to erase citations, and do not allow every AI crawler merely because you want more visibility. Neither expectation is supported as a universal rule.

    Open your live robots.txt file and turn its AI-related directives into a crawler registry now. Give every rule a verified target, a business purpose, an affected URL set, a success metric, and a rollback condition. If a rule has none of those, it is not yet a strategy; it is an assumption running in production.

    References


  • AI Search Visibility and the New Publisher Control Layer

    AI Search Visibility and the New Publisher Control Layer

    AI search creates a consequential choice for publishers: content must be accessible enough to be discovered, but unrestricted crawler access may weaken control over valuable archives. Visibility strategy and content governance can no longer be treated as separate concerns.

    Two reports illustrate the emerging trade-off. One describes the factors associated with citations across prominent AI platforms; the other describes publisher tools for deciding which AI crawlers may access content. Together, they suggest a practical operating model built around influence, access, measurement, and deliberate rights decisions.

    AI visibility extends beyond the published page

    CrushPress.AI’s account of Goodie’s fourth AEO Periodic Table says the research examined 1.13 million prompts across ChatGPT, Claude, Perplexity, Grok, Gemini, and Google AI Mode. The reported framework assigns explicit weights to 14 factors and adds Search & Fan-Out Rank and Originality & Information Gain as new factors.

    The most strategically important finding may be the reported weight of external validation. According to the article, off-site earned and social citations represent 22% of total citation leverage, exceeding the contribution of any single on-page content factor in the framework. This does not establish that mentions automatically cause AI citations, but it does challenge a page-only approach to AI search optimization.

    For publishers, the implication is that accessibility is only one condition of visibility. Original material, conventional search prominence, references from other sites, and social discussion may all help an AI system encounter or evaluate a publisher’s work. Opening a site to crawlers cannot compensate for weak information value or a lack of recognition elsewhere.

    Crawler access is a policy decision, not a visibility guarantee

    Digital crawler devices approach an online archive through open, restricted, and closed access gates.

    The second report addresses the access side of the equation. CrushPress.AI reported that beehiiv integrated Cloudflare’s Crawl Control technology so newsletter publishers can monitor, permit, or restrict AI bots from the beehiiv dashboard. The interface reportedly shows attempted crawler access, blocked activity, and referral traffic attributed to AI interactions.

    That distinction matters because crawling, citation, and referral traffic are different events. A bot may access a page without citing it; an AI service may mention a publisher without producing a measurable visit; and a referral may arrive without revealing how extensively content was used. Crawler logs therefore describe access behavior, not the full value exchange between a publisher and an AI platform.

    The reported integration lets publishers allow or block specific AI models through simplified permissions, while Cloudflare is expected to update coverage as new crawlers appear. The article says beta access to activity insights is available to every beehiiv user, whereas blocking is available to beehiiv Max subscribers. These are platform-reported capabilities rather than evidence that a particular permission setting will improve revenue, citations, or audience growth.

    The core trade-off is distribution versus optionality

    The two choices described in the Cloudflare and beehiiv announcement are maximum discovery and content protection. Maximum discovery permits AI search engines and agents to crawl more freely in pursuit of broader distribution. Content protection blocks scraping to preserve archives for possible monetization or licensing.

    Policy posturePrimary objectiveEvidence to monitorMain limitation
    Broader accessIncrease the opportunity for AI discoveryCrawler activity, referrals, and observed citationsAccess does not guarantee attribution or traffic
    Stricter protectionRetain control over potentially licensable archivesBlocked requests and changes in discovery or referralsProtection may reduce opportunities to be found
    Model-specific accessBalance distribution and protection by crawlerResults associated with each permission decisionRequires continuing review as crawlers and services change

    The appropriate posture may differ by publishing model. A publication that depends on reach may place more value on discoverability, while one with a differentiated paid archive may place more value on preserving licensing options. A model-specific approach can sit between those positions when the available controls support it.

    A practical framework connects permissions to outcomes

    People gather around a table where four symbolic tools connect to a protected digital content archive.

    Define the objective first. A crawler setting should serve an explicit goal, such as brand visibility, qualified referrals, subscription growth, archive protection, or future licensing. Without that goal, access decisions risk becoming symbolic rather than operational.

    Separate access metrics from visibility metrics. Crawler attempts and blocked requests indicate demand for access. Referral traffic indicates one form of audience return. Citations and brand mentions indicate representation inside AI answers. These measurements answer different questions and should not be collapsed into a single AI traffic number.

    Invest beyond crawler permissions. The AEO research summary points to originality, search and fan-out rank, and off-site earned and social citations. Publishers seeking AI visibility therefore need useful source material and external recognition as well as technically accessible pages.

    Review policies by crawler. The beehiiv integration reportedly supports permissions for specific AI models. Publishers can use that granularity to compare access activity and referrals before applying one rule to every bot, while recognizing that the supplied reports do not establish the commercial value of any individual crawler.

    Preserve uncertainty in evaluation. Neither source proves that allowing a crawler causes citations or that blocking one preserves a future licensing opportunity. Decisions should be treated as revisable policies informed by observed results, not permanent conclusions drawn from a single dashboard or ranking study.

    Key takeaways

    • AI search visibility combines content quality, conventional discoverability, external recognition, and crawler access.
    • Goodie’s reported framework gives off-site earned and social citations 22% of total citation leverage, highlighting the importance of signals beyond a publisher’s own pages.
    • Cloudflare and beehiiv reportedly give newsletter publishers visibility into crawler activity and controls for permitting or blocking specific AI models.
    • Crawling, citation, and referral traffic are distinct outcomes and should be measured separately.
    • Publisher controls work best when they are tied to a declared distribution, subscription, protection, or licensing objective.

    Visibility strategy will become a governance discipline

    As access controls become easier to operate, the difficult work will shift from implementation to judgment. Publishers will need to decide which forms of AI discovery create value, what evidence supports that conclusion, and which content rights they are unwilling to exchange for uncertain exposure. The strongest strategy will keep those decisions measurable and reversible as both crawler behavior and citation patterns evolve.

    References

  • How Bot Traffic Changes AI Search Visibility Measurement

    How Bot Traffic Changes AI Search Visibility Measurement

    AI is changing web visibility in two directions at once: answer systems can influence buyers without sending a visit, while automated agents can generate large volumes of requests without producing human attention. The result is a widening gap between what traffic logs record and what marketing teams actually need to understand.

    Bringing these developments together reveals a practical lesson: request volume, human engagement, and market influence must be measured as separate layers. A useful visibility model then reconnects those layers without treating any single signal as proof of AI-driven demand.

    More web requests do not necessarily mean a larger audience

    The clearest warning against equating traffic with attention comes from the bot data. The CrushPress.AI article on automated web requests reports, based on figures shared by Cloudflare CEO Matthew Prince, that bots accounted for 57.3% of global HTTP requests for HTML content, compared with 42.7% from humans. It also says this crossed a threshold Prince had predicted during SXSW would be reached by early 2027.

    Those percentages describe requests, not unique visitors, reading time, purchasing intent, or revenue. That distinction becomes especially important in an agentic browsing environment. As the article explains, a person shopping online might inspect a small number of pages, whereas an AI agent could request thousands while researching on the person’s behalf. The activity is real at the infrastructure level, but it does not create thousands of human opportunities to view advertising or engage with a page.

    This creates a measurement paradox. A site can receive more machine activity while seeing little corresponding improvement in human sessions or commercial outcomes. Publishers and brands therefore need to classify automated requests before using raw traffic trends to judge reach, content performance, or audience growth.

    AI can create influence while removing the observable visit

    The attribution problem is the mirror image of the bot-traffic problem. Automated systems may produce requests that overstate apparent audience activity, yet AI-generated answers may also create genuine brand influence that website analytics fail to capture.

    The CrushPress.AI article on AI search visibility describes prospects using tools such as ChatGPT or Google’s AI Overviews to discover vendors, compare alternatives, and form a shortlist before visiting any company website. A brand can appear in recommendations, comparisons, citations, or generated responses throughout that research. If the prospect later arrives through a branded query or a direct visit, conventional analytics may record only that final, deceptively simple step.

    This extends the zero-click pattern already associated with search features such as snippets, knowledge panels, and local packs. Generative answers can compress more of the research process into the search or assistant interface, making the missing click more consequential: discovery and evaluation can both occur before the measurable session begins.

    The combined implication is that low referral traffic does not necessarily mean low AI influence, just as high request volume does not necessarily mean high human interest. One metric can undercount the role of AI in a buying journey while another can overstate the audience that AI activity represents.

    A layered measurement model separates activity from impact

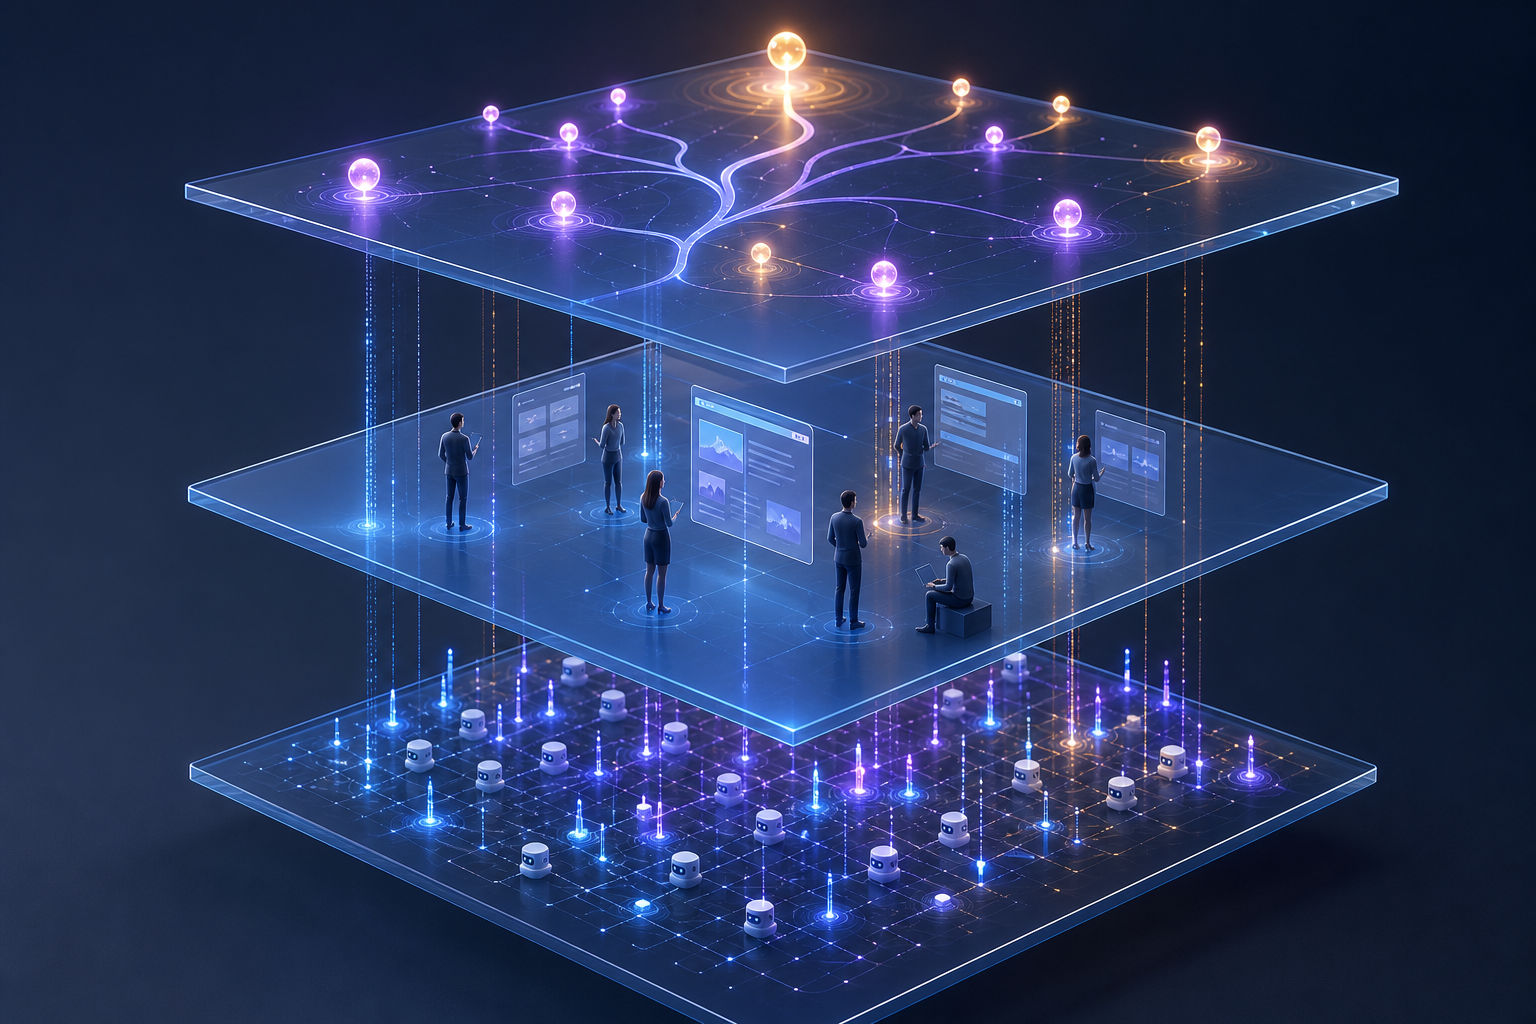
    Three connected transparent layers depict automated requests, human engagement, and broader influence as separate forms of measurement.

    A more useful model starts by distinguishing three questions. The first is whether machines are accessing the site. The second is whether people are arriving and engaging. The third is whether AI systems are shaping awareness or consideration before those visits. Keeping the questions separate prevents request logs, referral reports, and brand indicators from being collapsed into a single ambiguous traffic number.

    At the machine-activity layer, teams can examine bot identification and request patterns to determine how much recorded activity is automated. This layer helps explain infrastructure demand and content access, but it should not be presented as audience reach without supporting evidence of human engagement.

    At the human-behavior layer, traditional analytics remain useful for sessions, engagement, assisted conversions, and conversion paths. The AI search visibility article specifically identifies assisted conversions as a way to detect channels that contributed before the final interaction. These reports remain incomplete when an AI exposure sends no detectable referral, but they still show how observable touchpoints work together.

    At the influence layer, the same article proposes watching branded search growth, direct traffic trends, and brand appearances within AI prompts and recommendations. None is conclusive alone. Branded searches can have several causes, direct traffic is an imprecise category, and an AI mention does not prove that it affected a purchase. Read together over time, however, these signals can support a more credible account of how awareness and consideration are developing.

    The strongest interpretation comes from convergence. Repeated AI visibility followed by growth in branded demand, relevant human engagement, and assisted or completed conversions presents a more meaningful pattern than any isolated spike. This is an inference framework rather than person-level attribution: it indicates probable influence without claiming to reconstruct every buyer’s path.

    Key takeaways

    • Bot request share measures automated access, not the size or quality of a human audience.
    • AI-generated answers can influence discovery and vendor evaluation without producing a referral click.
    • Direct visits and branded searches may be downstream signs of earlier AI exposure, but neither proves causation by itself.
    • AI visibility measurement should combine machine-activity data, human engagement, conversion evidence, and brand-demand signals.
    • Trends that move together are more informative than a single traffic, mention, or attribution metric.

    Visibility strategy must serve machines and people differently

    An abstract AI agent and a person access the same central web content through different structured and visual pathways.

    The growth of automated access gives brands a reason to make content clear, authoritative, and interpretable by AI systems, as the bot-traffic article argues. But machine readability is not an end in itself. The commercial objective is still to help a person discover, evaluate, trust, and eventually choose the brand.

    Reporting should reflect that distinction. Bot requests belong in an access and infrastructure view; human sessions belong in an engagement view; AI mentions and branded-demand indicators belong in an influence view; conversions remain the outcome view. Connecting these views can reveal useful relationships, but labeling them separately limits false precision.

    As AI agents assume more browsing and answer engines absorb more research, the most resilient measurement programs will track both sides of the exchange: how machines consume content and how people reveal the effects later.

    References

  • AI Search Indexing and Citation Visibility: A Practical Audit

    AI Search Indexing and Citation Visibility: A Practical Audit

    You can have pages indexed in conventional search, steady organic traffic, and normal reporting, yet remain invisible in an AI answer. That mismatch is real: healthy search metrics have coexisted with zero measured presence on individual AI platforms.

    The useful question is not, “Why doesn’t AI like my site?” It is, “Where does the path from crawl request to visible citation break?” Separate that path into testable stages and you can fix the actual bottleneck instead of rewriting good content, relaxing security blindly, or waiting for an index update that may not be the problem.

    AI visibility has several distinct failure points

    A conventional search index primarily helps rank pages for a query. An AI grounding system has a harder job. It must find evidence that is relevant, but it also needs to judge whether that evidence is accurate, current, sufficiently supported, and complete enough to help construct an answer.

    The distinction matters because a search result gives the user several pages to inspect. A generated response combines information on the user’s behalf. An error can travel through multiple reasoning steps, and conflicting claims may have to be reconciled before the system decides whether to answer at all. Retrieval can also happen repeatedly as the system refines the question and reevaluates its confidence.

    Use the following chain as a diagnostic model. It is not a claim that every AI platform uses an identical architecture. It is a practical way to locate failure.

    StageWhat must happenEvidence you can collect
    AccessThe relevant crawler receives the public page rather than a block, challenge, error, or empty response.Status code, redirects, response headers, returned HTML, and server logs for the exact user-agent.
    ExtractionThe page contains a passage that remains understandable when separated from the rest of the layout.A plain-text review of the passage with its subject, claim, conditions, and supporting context intact.
    GroundingThe claim appears current, specific, supported, and compatible with other available evidence.Visible dates, scope qualifiers, named evidence, consistent facts, and an explanation of apparent contradictions.
    Selection and attributionThe system uses your information and associates it with your page, brand, author, or community.Saved answers, linked URLs, source labels, creator labels, and the exact claim supported by each citation.
    Presentation and visitThe interface exposes a useful link and gives the user a reason to follow it.Inline-link placement, previews, suggested follow-up links, referral data, and landing-page engagement.

    Do not collapse these stages into one visibility score. A blocked crawler and an unconvincing claim can both produce no citation, but they require completely different remedies. A citation with no visits is different again: retrieval succeeded, while presentation or click value may be the constraint.

    Rule out crawler blocks before rewriting content

    An abstract crawler approaches a server archive through layered security gates, with one route open and several routes blocked.

    A platform-specific zero is a reason to investigate access, especially when other AI systems already use the same site. It is not proof by itself. Different products have different coverage, retrieval behavior, and answer policies.

    One 30-day monitoring snapshot of searchinfluence.com recorded 37.8% presence in Google AI Mode, 22.2% in Copilot, 16.3% in Google Gemini, 9.6% in ChatGPT, and 7.8% in Perplexity, while Claude and Meta AI both measured 0.0%. Those percentages are not industry benchmarks. Their value was diagnostic: the uneven pattern made crawler access worth testing before anyone blamed topical authority or page quality.

    The infrastructure evidence was much stronger. Seven days of Cloudflare logs contained 29,099 bot requests, with 65.8% involving AI bots, and the response behavior varied by user-agent. Reproduction requests then isolated a user-agent-based block at the managed WordPress hosting layer. Some AI crawlers were blocked while Common Crawl passed, so the success of one crawler did not establish access for another.

    Run your own access audit in this order:

    1. Choose a representative public test set. Include different templates and content states, such as a current informational page, an older evergreen page, and a commercially important page. Test only URLs that are meant to be public; do not expose private previews or protected customer data for the sake of crawler access.
    2. Capture an ordinary response. Request each URL as a normal browser and save the status, redirect chain, content type, response headers, and returned body. This gives you a baseline for comparison.
    3. Repeat the request with the exact AI user-agent. Use the string found in your server logs or the platform’s current official crawler documentation. Keep the URL, request method, and timing as consistent as practical. A browser response of HTTP 200 beside a bot response of HTTP 403 or 429 is strong evidence of access policy, filtering, or throttling.
    4. Inspect the body, not only the status. An HTTP 200 response can still contain a challenge page, login prompt, consent wall, empty shell, or materially different content. Confirm that the title, main text, and important links are present in the bot response.
    5. Trace every enforcement layer. Check robots controls, WordPress security and bot-management plugins, CDN or WAF rules, rate limits, caching, and managed-host controls. Response headers can help identify the layer involved, but a header is a clue rather than conclusive proof.
    6. Correlate the request with logs. Group by user-agent, URL, status, and time. Look for consistent differences between AI crawlers and ordinary requests. In particular, do not assume an HTTP 429 always reflects genuine request volume; a rule can produce different treatment based on identity or policy.
    7. Apply the narrowest correction and retest. Change the precise rule, crawler treatment, route, or limit responsible for the failure. Save before-and-after requests so you can demonstrate that the intended crawler now receives usable content.

    Do not disable a WAF or broadly allow every request merely to pursue citations. That can raise abuse, security, and compute-cost risks. User-agent strings are also easy to imitate. Prefer the verification controls supported by your host or platform, and make the smallest rule change that satisfies your chosen access policy.

    Three misreadings cause unnecessary work. First, successful Google crawling does not prove that an AI crawler can enter. Second, successful Common Crawl access does not prove access for ClaudeBot or another named crawler. Third, a clean robots file does not rule out a block imposed later by a plugin, CDN, WAF, or host. Test the exact request path instead of inferring it from conventional indexing.

    Write passages that can support an answer

    Once access is confirmed, evaluate the page as evidence rather than as a collection of keywords. AI retrieval may extract only part of a page, transform it, combine it with other material, and retrieve again. The important test is whether the meaning survives chunking and transformation.

    Keep the claim and its qualifications together

    Read each important passage without the page title, navigation, previous paragraph, or accompanying graphic. If the passage becomes ambiguous, it is too dependent on its surroundings.

    • Put the direct answer in the first substantive sentence beneath the relevant heading.
    • Name the product, entity, plan, region, or version in the sentence that makes the claim. Avoid relying on vague pronouns such as “it” or “this” after a long section break.
    • Keep conditions, exceptions, and measurement context in the same paragraph as the result they qualify.
    • Place the evidentiary basis close to the factual claim. Do not leave the reader or retrieval system to infer which citation supports which statement.
    • Split unrelated claims into separate paragraphs. A passage that mixes definitions, recommendations, history, and promotion becomes harder to use cleanly.

    Weak pattern: “It works differently on the newer plan. This is the limit.” The entity, plan, behavior, and meaning of the limit can disappear when the sentences are extracted.

    Stronger pattern: “For [named plan or version], [named feature] has [specific constraint] when [condition applies].” The brackets are not copy to publish; they show the context every important claim should carry.

    This does not mean repeating the same keyword in every sentence. It means removing unresolved references. Write so a person arriving at the paragraph from a search result can identify the subject, understand the answer, and see its boundary without reconstructing the rest of the page.

    Make freshness visible in the facts

    Stale content is more dangerous in a generated answer than in a list of links because the outdated claim can be repeated as part of a single synthesized response. Grounding systems therefore treat freshness as part of evidence quality, not merely as a recency signal.

    Changing an updated date without reviewing the underlying facts does not solve that problem. Maintain a simple freshness ledger for mutable pages with these fields:

    • Page and section containing the claim.
    • The fact that can change, not merely the page topic.
    • The product, version, geography, plan, or period to which it applies.
    • The evidence used to verify it.
    • The person responsible for review.
    • The last factual review and the event that should trigger the next one.

    When a fact changes, update the claim and its qualification together. If older information must remain for historical users, label its period explicitly. The goal is not to make every page look new. It is to stop an old statement from masquerading as a current one.

    Explain contradictions instead of leaving them to the model

    A ranked results page can place disagreeing pages next to each other and let the user decide. A generated answer has to decide how, or whether, the claims fit together. Conflict recognition is therefore part of the grounding problem.

    When two pages on your own site disagree, check the scope before choosing a winner. The difference may come from time period, region, edition, account type, definition, or measurement method. Put that distinction beside each claim. If one page is simply wrong, correct it and remove internal paths that keep presenting the obsolete version as current.

    Do not hide a legitimate disagreement. Name the competing positions, explain what each assumes, and tell the reader what would change the decision. That is more useful evidence than forced certainty, and it reduces the chance that a retrieved passage loses the reason two values differ.

    Use structured data as a consistency check

    Schema and JSON-LD can clarify entities, relationships, authorship, dates, and attributes, but they cannot rescue a blocked response or turn an unsupported assertion into reliable evidence. Treat markup as a machine-readable reflection of the visible page.

    Audit the page and markup together. Names, dates, authors, products, and factual values should agree. If the structured data makes a claim the reader cannot verify on the page, fix the underlying content or remove that property. Citation visibility depends on trustworthy evidence throughout the chain, not on how many properties you can add.

    Measure citation visibility as its own funnel

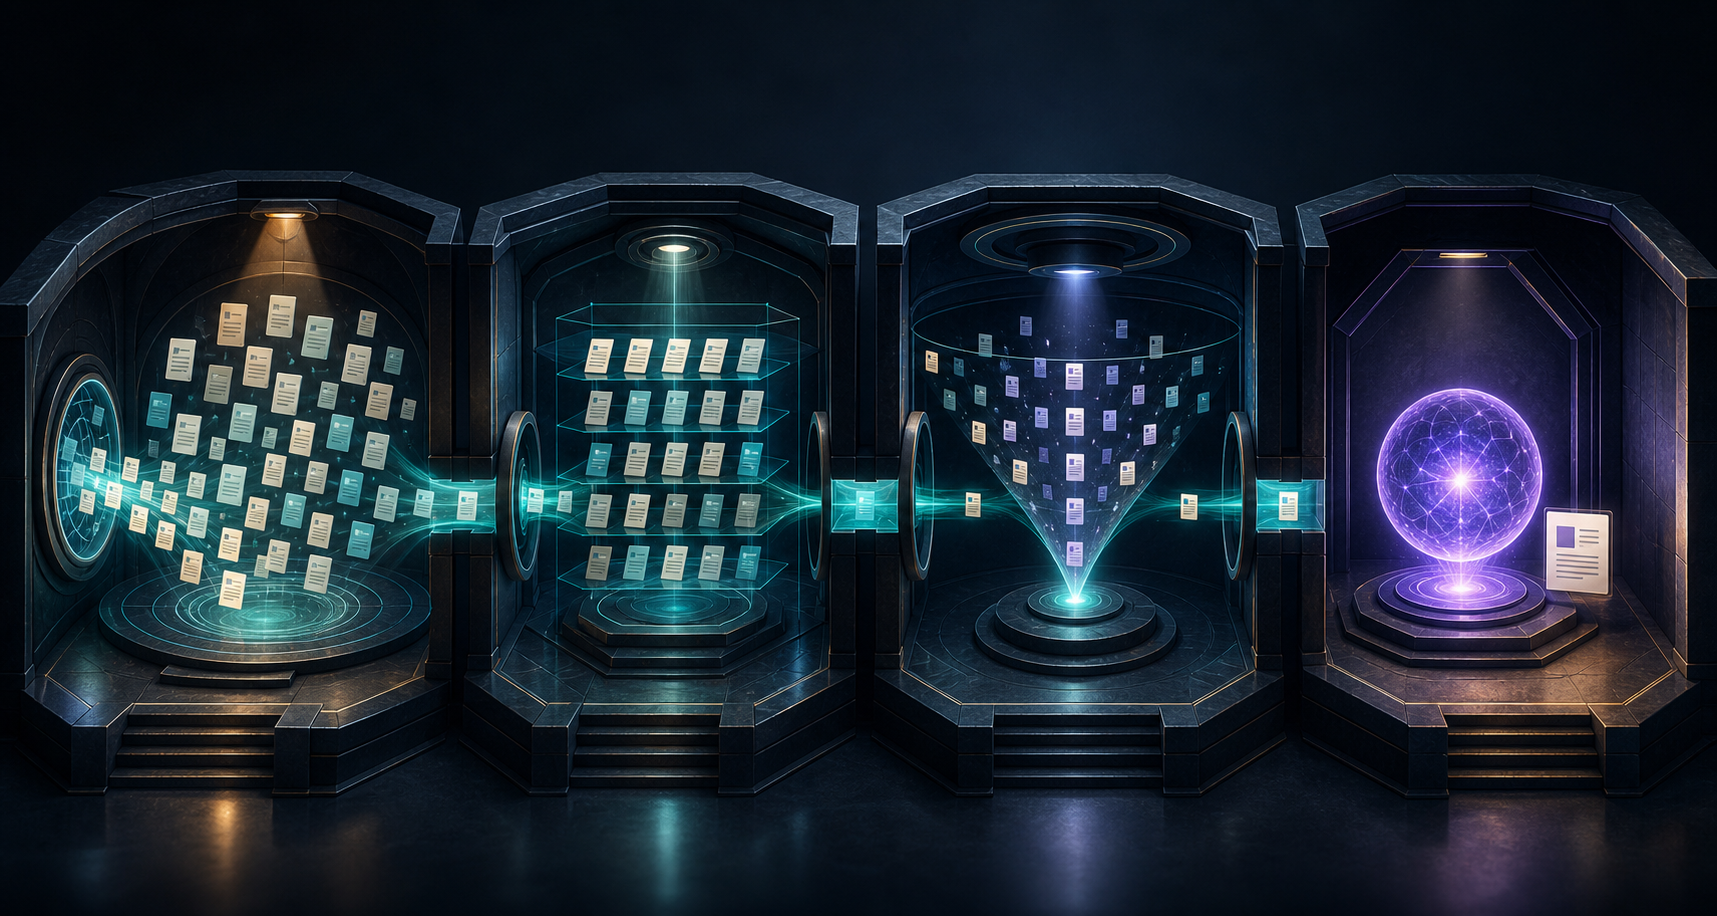
    Document tiles pass through four connected chambers, with fewer tiles reaching a source card beside a glowing answer orb.

    Search Console can tell you a great deal about conventional Google search, but it cannot diagnose every AI platform. A site may have normal traffic and indexing signals while specific AI systems show no measurable presence. Build a separate observation set for AI answers, then connect it back to crawl logs and analytics.

    1. Define a stable prompt set. Use the real questions for which your pages contain an answer. Keep the wording and intent recorded so later observations are comparable.
    2. Record the execution context. Save the platform, prompt, date, locale, and relevant account or subscription context. AI surfaces can differ, so an uncaptured context change can look like a visibility change.
    3. Preserve the response. Store the answer, every linked URL, visible publisher or creator label, and the text each link appears to support.
    4. Classify the outcome by stage. Distinguish no retrieval, unlinked use of your information, linked citation, secondary suggested link, and citation with a recorded visit.
    5. Join observations to crawl evidence. Check whether the platform’s crawler requested the cited or expected page near the observation period and what response it received.
    6. Compare like with like. Use the same prompt set and classification rules for before-and-after reviews. A percentage without a stable denominator or observation method is not a useful trend.

    Track separate rates for separate questions:

    • Crawl pass rate: the share of tested URL and crawler combinations that return the intended, usable content.
    • Answer inclusion rate: the share of observed responses that use information traceable to your site, whether linked or not.
    • Citation rate: the share of observed responses that visibly attribute or link to your site.
    • Citation-to-visit rate: the share of cited observations associated with a visit, where referral data is available and can be interpreted responsibly.

    These are operational measurements, not universal benchmarks. Do not compare your rate directly with another company’s unless the prompts, platforms, contexts, and classification method are the same.

    Presentation deserves its own field because a citation is not one uniform object. Google’s AI features can place links beside relevant answer text, show previews on hover, suggest follow-up angles, surface subscription links, and identify creators or communities for discussion-based material. A monitoring system that records only whether your domain appeared will miss the difference between a prominent inline citation and a secondary link a user may never see.

    For each appearance, record the citation surface and the promise it makes to the user. Then inspect the destination page through that promise. The title and opening should immediately deliver the analysis, firsthand detail, method, evidence, or next step that the short answer could not contain. If the page merely repeats the generated answer at greater length, the user has little reason to click.

    Your funnel should now point to a specific class of work:

    • If the crawler cannot retrieve usable content, work on infrastructure and access policy.
    • If access passes but the relevant passage cannot stand alone, restructure the answer and its qualifiers.
    • If the passage is clear but stale, weakly supported, or contradicted elsewhere, repair evidence governance.
    • If your information appears without a citation, strengthen page-level identity, claim ownership, and the connection between evidence and assertion.
    • If a citation appears but visits do not follow, inspect its surface, preview, destination promise, and the additional value available after the click.

    AI indexing and citations: practical FAQ

    Can a page rank organically and still receive no AI citations?

    Yes. Ranking and grounding overlap, but they are not the same job. Conventional search emphasizes relevance among pages. An AI answer also needs evidence it can use with sufficient confidence, freshness, support, and context. The system may retrieve repeatedly, reconcile conflicts, or decline to answer, so an organic position does not guarantee selection or attribution in a generated response.

    Should you rewrite content as soon as an AI platform shows zero visibility?

    No. First reproduce access for that platform’s crawler on representative URLs. If the exact user-agent gets a block, challenge, empty body, or persistent HTTP 429 while an ordinary request receives the page, content rewriting cannot fix the immediate failure. If access passes, move to passage quality, evidence, freshness, and contradictions.

    Should you unblock every AI bot?

    Not automatically. Decide what your organization permits for bulk collection, model training, live answer retrieval, and referral-generating discovery. In the managed WordPress investigation, bulk training crawlers and more human-paced, user-facing crawlers behaved differently. That case does not establish a universal rule, but it shows why a single allow-or-block switch can be too crude. Keep security controls in place, verify crawler identity using the best controls your provider supports, and implement your policy narrowly.

    Does earning a citation guarantee referral traffic?

    No. Link placement, previews, answer completeness, user intent, subscriptions, and the value promised by the destination all affect whether someone visits. Google reported that prominent subscription links improved click-through rates in early tests, but that qualitative result is not a universal traffic promise. Measure the appearance, citation surface, and visit separately.

    Start with one missing platform and one important page. Trace a real request through access, extraction, grounding, citation, and visit. Preserve the evidence at each stage. If the chain breaks at the server, fix the server. If it breaks at the claim, fix the claim. If it breaks after the citation, give the reader a clearer reason to continue. One diagnosed failure is worth more than a site-wide AI rewrite based on guesswork.

    References

  • Google Web Bot Auth: A Practical Adoption Plan for Websites

    Google Web Bot Auth: A Practical Adoption Plan for Websites

    If you manage bot access at a CDN, firewall, reverse proxy, or application layer, Google Web Bot Auth presents an awkward decision: prepare for stronger bot identity without blocking legitimate traffic that does not yet use it.

    The safe approach is to add Web Bot Auth as a new verification signal, not replace your existing controls. You can then learn from signed requests, distinguish authentication from permission, and tighten access only when coverage is reliable enough for the agents and routes you care about.

    What Web Bot Auth actually changes

    A user-agent string tells you what a requester claims to be. IP and reverse-DNS checks can associate a request with known infrastructure. Neither gives you the same kind of identity evidence as a cryptographically signed request.

    Web Bot Auth is an experimental cryptographic protocol that lets participating bots sign requests. A compatible verifier can use that proof to determine whether the request came from the claimed agent rather than trusting a label that another client could copy.

    SignalWhat it tells youHow to use it now
    User-agent stringThe identity a requester claimsKeep it as classification context, not proof by itself
    IP and reverse DNSWhether the request is associated with expected network infrastructureKeep using these checks during the limited rollout
    Web Bot AuthWhether a participating agent supplied valid cryptographic identity proofAdd it as a stronger signal where verification is supported

    This is an authentication improvement, not a complete bot-management policy. A valid signature can help establish who sent a request. It does not decide whether that agent may crawl a page, use an expensive endpoint, access licensed material, or bypass rate limits. Those are authorization decisions that remain yours.

    That distinction prevents the most dangerous implementation mistake: treating “authentic” as a synonym for “allowed.” A verified agent can still request a route your policy excludes. An unsigned agent may still be legitimate while adoption remains partial.

    Why Web Bot Auth must remain an additional signal

    Web Bot Auth is in a limited test involving some AI agents hosted on Google infrastructure. Not every Google user agent uses it, and Google is not signing every bot request. Requiring a valid Web Bot Auth result across your site would therefore turn incomplete deployment into an access-control failure.

    In practice, the absence of a signature has three possible meanings: the requester is not participating, a participating agent did not sign that request, or the requester is not what it claims to be. The rollout does not yet let you collapse those cases into “fraudulent.” Keep IP, reverse-DNS, and user-agent checks operating alongside the new protocol, as Google advises during gradual adoption.

    Your internal classification should represent that uncertainty. A binary “Google bot” field is no longer enough. Use separate states such as:

    • Cryptographically verified: Web Bot Auth verification succeeded and resolved to an identity you recognize.
    • Legacy verified: the request passed your established network and identity checks but did not carry usable Web Bot Auth proof.
    • Unverified: the request supplied no acceptable proof and did not pass your legacy verification path.
    • Contradictory or failed: the claimed identity conflicts with your verification results, or supplied authentication material fails verification.

    Do not silently translate “legacy verified” into “untrusted.” That would make a protocol coverage gap look like a security finding. Conversely, do not let a familiar user-agent string upgrade an unverified request into a trusted one.

    Failed proof deserves more scrutiny than absent proof. An unsigned request may simply sit outside the test. A request that presents authentication material but cannot be validated has actively failed the verification path. Your system should preserve that distinction for policy decisions and incident review.

    A safe adoption plan for your edge and application stack

    A layered website stack shows signed and unsigned automated requests moving through observation, verification, and limited enforcement paths with monitoring and rollback routes.

    You do not need to redesign every bot rule at once. Start by separating verification from enforcement, then introduce the new result in stages.

    1. Map the current decision path. Identify where user-agent checks, IP rules, reverse-DNS verification, rate limits, robots directives, and application permissions affect a request. Note whether the decisive action happens at the CDN, firewall, reverse proxy, application, or more than one layer.
    2. Define the verdicts before integrating them. Decide how your system will represent valid, absent, failed, unsupported, and indeterminate Web Bot Auth outcomes. Do not force these states into one Boolean field.
    3. Add verification without changing access. In the first phase, calculate and log the Web Bot Auth result while preserving existing allow, limit, challenge, and deny behavior. This gives you evidence about real coverage without risking accidental exclusions.
    4. Compare signals. Review requests that claim the same agent identity but produce different network and cryptographic results. Investigate disagreements before using the new signal to make blocking decisions.
    5. Introduce graded enforcement. Prefer lower-risk actions, such as applying ordinary rate limits to unverified automation, before making a signature mandatory. Reserve strict requirements for routes where you have confirmed support and where the cost of unauthorized access justifies the tighter rule.
    6. Keep a rollback path. Authentication failures should be visible, attributable to a specific policy, and reversible without redeploying unrelated application code.

    Place verification where request data can be inspected before an irreversible allow-or-deny decision. That may be at the edge in one architecture and inside a trusted gateway in another. Do not assume your CDN, security plugin, or bot-management service supports the protocol merely because it can read headers. Cryptographic verification requires a compatible implementation and a defined trust process.

    Before enabling enforcement, make the implementer answer the operational questions that matter for any signed-request system: What parts of the request are covered? How is the signing identity trusted? How are invalid, stale, or unverifiable proofs handled? How does verification behave during key or service changes? Which failure mode applies if the verifier is unavailable? If your stack cannot answer those questions, keep the integration in observation mode.

    Your logs should store conclusions that operators can use, not just a dump of unfamiliar authentication data. Useful fields include the claimed user agent, legacy-verification result, Web Bot Auth result, resolved identity, requested route, policy action, response status, and the component that made the decision. Apply your normal security, privacy, and retention rules to those records.

    Build AI-agent access rules around identity and purpose

    Verified automated agents follow different permission paths to public and restricted website resources, while policy barriers block access to sensitive areas.

    Once you can verify an agent, resist the urge to create a single global allowlist. Public articles, resource-intensive APIs, account pages, and licensed datasets do not have the same risk or purpose. The identity result should feed a route-specific policy.

    • Verified identity plus permitted route: allow the request under the limits assigned to that agent and content class.
    • Verified identity plus prohibited route: deny it. Authentication does not override the route policy.
    • No Web Bot Auth proof plus successful legacy verification: continue the established bot policy while coverage remains incomplete.
    • Claimed known identity plus failed verification: treat the request as untrusted and preserve the failed result for investigation.
    • Unknown automation: apply your general unknown-bot controls rather than granting access based on a recognizable name.

    Private or account-bound routes still need their ordinary application authentication and authorization. Bot identity proof is not a substitute for a user session, API credential, subscription entitlement, or content license.

    The same separation applies to robots instructions and other content-use rules. Web Bot Auth can help determine which agent is asking. Your published directives and internal access policy determine what that identity may receive. Keep those systems aligned, but do not merge them conceptually.

    For SEO, AEO, and GEO teams, the immediate benefit is cleaner observability rather than a promised visibility gain. Nothing in the limited rollout establishes Web Bot Auth as a ranking, citation, or inclusion mechanism. Do not change canonical tags, structured data, content architecture, or indexation rules merely because signed bot requests appear in your logs.

    Use the stronger identity signal to answer narrower operational questions: Which verified agents request your content? Which sections do they reach? What status codes do they receive? Where do rate limits or access rules interrupt them? How often does a claimed identity match a verified identity?

    Do not label a verified crawl as an AI citation, recommendation, or referral. A request proves an interaction with a URL, not what an agent later generated for a user. Keep server-side agent activity separate from user referral traffic and from any evidence that your brand appeared in an AI answer.

    Key takeaways and your next move

    • Web Bot Auth adds cryptographic identity evidence to participating bot requests.
    • The protocol remains experimental and is being tested with only some AI agents on Google infrastructure.
    • Not every Google user agent or request is signed, so missing proof is not proof of impersonation.
    • Keep user-agent, IP, and reverse-DNS verification running alongside Web Bot Auth during the rollout.
    • Authentication establishes identity; your route, content, and rate-limit policies still decide permission.
    • Use verified requests to improve bot observability, but do not treat a crawl as evidence of an AI citation or ranking benefit.

    Your next move is concrete: map the component that currently decides whether a bot request is allowed, add a multi-state Web Bot Auth verdict to that path, and run it without enforcement first. Preserve your existing controls until signed-request coverage is confirmed for the exact agents and routes you intend to govern.

    That design lets you benefit as adoption expands without making today’s legitimate unsigned traffic pay for tomorrow’s authentication model.

    References

  • SEO Under Constraints: Rendering and Restricted Keywords

    SEO Under Constraints: Rendering and Restricted Keywords

    Your page can fail search visibility in two places at once. The content a crawler needs may not exist until JavaScript runs, while the phrase customers actually search may be prohibited by legal, trademark or brand rules.

    Treat those as separate failure modes. First, make the page understandable without waiting for client-side rendering. Then build relevance around the intent you are allowed to express. That order matters: stronger copy cannot rescue content a crawler never receives.

    Separate retrieval problems from relevance problems

    A rendering constraint affects retrieval. The server returns a thin document, and JavaScript later inserts the main copy, navigation, product details or internal links. A wording constraint affects relevance. The page is available, but the language that connects it to a valuable query is weak, indirect or deliberately absent.

    When both occur on the same page, teams often misread the symptoms. An editor adds more synonyms when the copy is missing from the initial response. A developer improves rendering while the approved vocabulary still fails to describe the searcher’s need. Neither change closes both gaps.

    QuestionWhat to inspectWhat the result means
    Can a crawler understand the page before JavaScript runs?The raw HTML response, including the title, main heading, essential copy and linksIf the page’s purpose is missing, you have a retrieval problem.
    Can a visitor understand the offer without the restricted phrase?Headings, body copy, definitions, attributes, use cases and related terminologyIf the offer remains vague, you have a relevance problem.
    Is the phrase legally prohibited or merely discouraged?The written rule for body copy, metadata, links, comparisons, questions and definitionsThe permitted tactics depend on the actual boundary, not an informal preference.
    Does the approved vocabulary match how people express the need?Query data grouped by intent rather than one isolated keywordA large demand gap may justify revisiting the policy or creating a stronger semantic route.

    Run these checks before changing templates or copy. They tell you whether the next ticket belongs with engineering, content, legal or all three. They also give each team a testable acceptance criterion instead of the vague instruction to improve SEO.

    Put the essential answer in the initial HTML

    Solid core page panels emerge first from a server while translucent secondary modules assemble behind them.

    Google can execute JavaScript, but execution is not the same as immediate, complete discovery. Pages can be queued until rendering resources are available, after which a headless browser processes the client-side code. That extra stage creates another opportunity for delayed or incomplete discovery.

    The dependency is even riskier outside Google. Many AI crawlers and other non-Google bots do not consistently execute JavaScript. If the useful answer exists only inside a client-rendered component, those systems may receive a shell rather than a document they can quote, classify or follow.

    You do not need to rebuild every interaction as a no-JavaScript application. You do need an HTML-first discovery path for anything that establishes what the page is, what it offers and where its important links lead.

    • Return a unique, meaningful page title and a clear main heading in the server response.
    • Include the primary explanation, answer, product description or service description before client-side code runs.
    • Expose essential facts that determine whether the result satisfies the visitor’s need. Do not hide the only useful details behind tabs, filters or event handlers.
    • Render primary navigation, breadcrumbs and contextual internal links as ordinary anchors with real destinations.
    • Deliver structured information needed to identify the page and its subject in the initial document where practical.
    • Add JavaScript for filtering, personalization, live calculations and other interactions after the discoverable foundation is present.

    Server-side rendering, static generation and pre-rendering can all provide that foundation. The right choice depends on how often the content changes and how much of the interface is truly dynamic. A stable service page may suit static generation. A frequently updated catalogue may need server-side rendering. A client-rendered application can selectively pre-render its public discovery pages while keeping authenticated workflows dynamic.

    A <noscript> block can be a safety net, but it should not become a second, neglected version of the page. If you use one, keep it concise and aligned with the visible experience. The safer architectural target is meaningful server-delivered HTML that JavaScript enhances rather than replaces.

    Test the response, not just the finished screen

    A browser screenshot with JavaScript enabled proves that a visitor can see the interface. It does not prove that a crawler received the content or that the links are discoverable. Use this sequence on every important template:

    1. Open the raw server response or page source. Find the title, main heading, first useful answer and primary links.
    2. Load the page with JavaScript disabled. Confirm that its subject and next step remain understandable.
    3. Inspect critical links. They should have crawlable destinations rather than relying only on click handlers.
    4. Compare the initial and enhanced versions. They can differ in presentation, but they should not contradict each other or describe different offers.
    5. Repeat the check while logged out and without stored browser state. Public discovery must not depend on a previous session.
    6. Test a sample from every shared template. Passing one editorial page says little about a product, location or category template built through a different rendering path.

    Prioritize pages by consequence. Start with the homepage, high-demand landing pages, major categories, locations and pages that supply internal links to deeper content. A missing decorative widget is inconvenient. A missing product description or category link changes what the crawler can understand and reach.

    Map the search intent before working around a restricted term

    Hands arrange groups of pictorial tokens along illuminated paths around a locked central tile.

    Do not treat every keyword restriction as the same instruction. A trademark concern, an absolute legal prohibition, a brand preference and a rule against making one phrase the primary focus create different boundaries. Get the rule in writing before anyone places the term in a heading, title, image description or link.

    The first question is not, “How can we hide this keyword?” It is, “What is the searcher trying to identify, compare or accomplish?” That change of frame gives you legitimate language to work with even when the familiar label is unavailable.

    Demand data can also reveal whether an internal naming preference carries a substantial visibility cost. In one senior-living comparison, “skilled nursing near me” showed 4,400 monthly searches while “nursing home near me” showed 27,100. Those figures do not create permission to use a prohibited phrase. They do show why legal, brand and search teams should make the decision with the same evidence in front of them.

    Build an intent map around the restricted query. Include:

    • The approved category: the clearest accurate name you are allowed to use.
    • The underlying job: what the person wants to buy, arrange, learn, compare or solve.
    • Defining attributes: materials, features, level of support, location, compatibility or other characteristics that make the offering identifiable.
    • Use contexts: the occasions, environments and situations in which the need appears.
    • Audience language: natural questions, synonyms, spelling variants and adjacent terms that people use for the same intent.
    • Necessary distinctions: what the offering is, what it is not and how nearby categories differ.

    For a beverage-insulation product, for example, the semantic field might include can cooler, insulated drink sleeve, beer, cold drinks, party favors and occasions such as a bachelorette party. No single substitute has to impersonate the restricted name. Together, accurate category, attribute and context language can make the page’s subject clear.

    Use the exact term only where permission is explicit

    Some policies allow a term in a factual definition, comparison, question or combined product label but prohibit presenting it as the brand’s preferred category. If legal or brand reviewers approve that boundary, a limited contextual mention can clarify the relationship between the common query and the approved offering.

    If the phrase is prohibited everywhere, do not smuggle it into metadata, alternative text or anchor text. Those fields are still published content. Search engines can process them, users may encounter them, and moving a term out of the visible body does not remove a trademark or compliance concern.

    Apply the same rule to each element:

    • Title and main heading: lead with the approved category and the page’s actual promise.
    • Introduction: answer the underlying need immediately. Do not force awkward synonyms into a sentence that becomes harder to understand.
    • Definitions: explain unfamiliar approved terminology and its boundaries. Use the restricted label only if that explanatory use has been cleared.
    • Internal links: choose descriptive anchor text that truthfully identifies the destination. An approved common term can be useful; an unapproved one remains unapproved.
    • Alternative text: describe the image and its purpose. It is not a storage area for keywords that copy reviewers rejected.
    • External links: do not build an artificial exact-match pattern. Use language that is accurate, natural and permitted in that context.

    You may still earn visibility without the exact phrase because relevance can be established through related concepts and intent. It is not a guarantee, especially when competitors can use the dominant wording directly. Set expectations accordingly: the goal is the strongest truthful signal set available under the constraint, not a loophole that makes the constraint disappear.

    Use one launch gate for code, copy and compliance

    A constrained page should not move through engineering, editorial and legal as three disconnected deliverables. Give it one acceptance checklist. That prevents a technically crawlable page from shipping with vague language, or approved copy from disappearing behind client-side rendering.

    1. Define the page’s job. Write one sentence stating who the page helps, what they need and what action the page should enable.
    2. Name the query family. Group the restricted term, approved synonyms, questions, category language, attributes and use cases by shared intent.
    3. Record the wording boundary. Specify whether the term is banned everywhere, allowed only in named contexts or merely excluded as the primary label. Cover headings, body copy, metadata, links and image descriptions separately.
    4. Draft the minimum complete answer. Before designing interactive elements, write the heading, concise explanation, essential facts and next-step links that must exist in the initial HTML.
    5. Place approved relevance signals. Use the approved category prominently, then add useful attributes, applications, distinctions and definitions. Each addition should improve understanding, not just keyword coverage.
    6. Render the foundation on the server. Choose static generation, server-side rendering or pre-rendering for the public content. Hydrate interactive features on top of it.
    7. Run two reviews. Technical QA verifies the raw response and crawlable links. Editorial and legal review verify that every published field follows the wording policy.
    8. Measure by query group and template. Watch whether the intended family of searches reaches the page and whether affected templates are discoverable. Do not judge the work from one exact keyword or one successfully rendered URL.

    Write the acceptance criteria so failure is obvious. “Improve crawlability” is not testable. “The service description and links to all primary locations appear in the initial HTML” is. “Use related keywords” is equally weak. “The title names the approved category, and the body explains its use, defining attributes and difference from adjacent categories” gives an editor something concrete to deliver.

    When a page still underperforms, return to the two failure modes. If the content is absent from the response, fix retrieval. If it is present but does not clearly resolve the intent, fix relevance. If the exact phrase would materially change the opportunity but remains prohibited, take the demand evidence back to the decision-maker rather than quietly violating the rule.

    Key takeaways

    • Rendering and keyword restrictions are independent constraints: one limits retrieval, while the other limits relevance signals.
    • Put the page’s heading, essential answer, core facts and important links in server-delivered HTML.
    • Use JavaScript to enhance the experience, not as the only delivery mechanism for content that must be discovered.
    • Clarify whether a restricted term is legally banned, contextually permitted or simply discouraged before placing it anywhere.
    • Build relevance through approved category language, intent, attributes, use cases, definitions and natural internal links.
    • Make raw-HTML validation and wording compliance part of the same launch gate.

    Start with one high-value template this week. Capture its raw HTML, mark the essential content that is missing, document the exact wording boundary and rebuild the smallest complete answer that satisfies both. Once that page passes, turn the checks into requirements for every template that follows.

    References


  • How to Make Content Visible in Search and AI Answers

    Your page is indexed, technically sound, and even earns search impressions. Yet it rarely appears in AI answers, recommendations, or citation-style results. That usually isn’t a signal to add more keywords. It is a signal to find the exact point where discovery breaks.

    Content visibility is a chain: access, extraction, intent matching, evidence, selection, and measurement. If you diagnose those stages in order, you can make a targeted change instead of rewriting a useful page on instinct.

    Visibility is a chain, not a single ranking setting

    A search engine or AI system must first reach the URL. It then has to extract the main content, determine what the page is about, match it to a user’s need, and decide whether the material is suitable to surface or reuse. A failure at any stage can look like the same outcome: no visibility.

    This is why crawlability and AI visibility should be treated as related but separate requirements. Allowing a crawler through the door does not make an ambiguous page understandable. Clear writing and schema cannot compensate for a blocked, redirected, or non-indexable URL.

    Distribution is also more fragmented than a conventional rankings report implies. A dataset covering 42 million Google Discover cards from December 2025 through February 2026 identified 20 selecting pipelines organized into six broad layers: core editorial, news urgency, trends, local or geographic content, social or video content, and commercial content. The sample came from hundreds of devices, so it is a substantial snapshot, but it is not a permanent map of every Google or AI system.

    The practical lesson is narrower and more useful: different surfaces can select the same URL for different reasons. A traditional ranking, a Discover recommendation, and an AI citation should not be treated as three readings from one universal visibility score.

    Key takeaways

    • If a system cannot fetch the final page, content changes will not solve the problem.
    • If the title, description, opening, headings, and structured data imply different purposes, the page’s intent is unclear.
    • If important claims lack context, dates, ownership, or supporting links, the material is harder to evaluate and safely reuse.
    • Google Search Console queries show the demand already reaching each page, making them a better starting point than a speculative keyword list.
    • Search, Discover, referral traffic, brand mentions, and AI answer citations need separate measurements.

    Diagnose the earliest broken stage before rewriting

    Start with the URL, not the copy. Work through the following checks in order and stop when you find a material failure. There is little value in polishing an answer that the relevant systems cannot reliably retrieve.

    1. Confirm access. Open the public URL without an authenticated session. Check the response, redirects, canonical target, robots rules, and page-level indexing directives. Review any firewall, bot-management, or consent layer that could return a challenge instead of the article. If your organization blocks categories of crawlers, make that an explicit policy decision rather than an accidental side effect of a security preset.
    2. Inspect the extractable page. Make sure the main answer, headings, lists, links, and evidence exist in the delivered document. Do not assume every retrieval system will execute a client-side application exactly as a human browser does. Remove overlays and template elements that obscure the opening or make navigation look like the main content.
    3. Verify page identity. The title, meta description, visible heading, introduction, canonical URL, breadcrumbs, and structured data should describe the same resource. A page presented as a tutorial in one field and a product category in another creates unnecessary ambiguity.
    4. Compare the promise with real demand. In Google Search Console, inspect the queries associated with this specific URL. Group them by the job the searcher is trying to complete, such as learning, comparing, troubleshooting, evaluating, or buying. Then compare the dominant job with what the page promises near the top.
    5. Audit evidence and ownership. Mark claims that depend on a date, platform, version, dataset, or named organization. Add that context where it changes the answer. Identify the author or responsible publisher and link important factual claims to the material that supports them.
    6. Check each outcome separately. Review organic search performance, Discover exposure where applicable, observable AI referrals, brand mentions, and citations in a controlled set of answer prompts. One healthy channel does not prove that the others are healthy.

    The first failed stage determines the next action. Fix access before content. Fix a query-to-page mismatch before adding schema. Strengthen evidence and entity clarity when the page is reachable and relevant but difficult to quote or attribute. If all of those checks pass, improve distribution and measurement instead of forcing another rewrite.

    Use Search Console to measure the intent gap

    Most content briefs begin with the audience a business hopes to attract. Search Console shows the audience Google is already connecting to the page. The difference between those two groups is your intent gap.

    That gap is about meaning, not merely shared words. Vector embeddings can place queries and page descriptions in the same semantic space, allowing their distance to be scored. A documented implementation compares page-level Search Console queries with the page’s meta description and uses the distance to identify weak alignment.

    Treat such a score as a diagnostic proxy. It is not an official Google metric, it does not prove why a page ranks, and a high similarity score does not guarantee inclusion in an AI answer. Its value is prioritization: it helps you locate pages whose positioning is far from the demand already reaching them.

    A query-to-page workflow that does not require a special tool

    1. Export queries by page. Preserve impressions, clicks, position, page, and query so that demand remains attached to the URL receiving it.
    2. Separate different kinds of demand. Keep branded or navigational searches distinct from problem, comparison, and transaction-oriented searches. They represent different reasons for reaching the page.
    3. Cluster by user task. Group queries that ask for the same outcome even when they use different vocabulary. Do not create a separate intent simply because a synonym appears.
    4. Write the demand in one plain sentence. Complete the statement: People reaching this URL mainly want to… If several unrelated endings carry meaningful demand, the page may be trying to do too many jobs.
    5. Write the page promise. Read only the title, meta description, main heading, opening paragraphs, and section headings. Complete the statement: This page helps you… Use what is actually on the page, not what the content brief intended.
    6. Choose a structural response. Keep the positioning when promise and demand agree. Refocus the opening and headings when the right answer is buried. Expand the page when it omits a necessary subproblem. Split the page when distinct audiences or tasks require incompatible answers.

    Look for five common forms of mismatch:

    • Scope gap: searchers want an implementation answer, but the page stays at the strategy level.
    • Audience gap: the page addresses specialists while the queries come from beginners, or the reverse.
    • Stage gap: the page tries to sell while the dominant demand is educational, or teaches basics to people already comparing options.
    • Format gap: the query calls for steps, criteria, or troubleshooting, but the page provides a continuous essay.
    • Outcome gap: the copy describes a topic without resolving the decision or problem behind the query.

    Do not rewrite the meta description in isolation just to improve semantic similarity. It is useful because it expresses the page’s promise compactly. If that promise changes, make the same intent visible in the heading, introduction, body, internal links, and structured data. Otherwise, you have improved the label while leaving the resource unchanged.

    Build an answer asset without weakening the full page

    An AI-visible page still needs to work as a page. Compressing everything into short definitions may make individual sentences easy to extract, but it can remove the qualifications and evidence that make the answer trustworthy. Build a clear answer core, then support it with the depth the decision requires.

    Put the answer core near the top

    Answer the main question in direct language before moving into background. State who the answer applies to, what conditions change it, and what the reader should do next. If the subject requires a sequence, expose that sequence in an ordered list. If it requires choosing among options, name the decision criteria before describing every option.

    Use headings that identify an actual subproblem. A heading such as Diagnose the earliest broken stage tells a reader and a machine what the section resolves. Generic labels such as Overview or More information do not.

    Use structured data as clarification, not decoration

    Select the most accurate schema type for the visible resource. Mark up only information a visitor can verify on the page. Keep names, authorship, publisher identity, dates, breadcrumbs, and canonical references consistent across HTML and JSON-LD. When an organization or product appears across multiple pages, use stable identifiers and naming rather than creating slightly different versions of the same entity.

    Schema cannot repair a blocked URL, substitute for a missing answer, or make unsupported claims trustworthy. Its useful role is disambiguation: it helps a system interpret the type of resource and the relationships already expressed in the visible content.

    Make provenance part of the answer

    Durable visibility in generative systems depends partly on consistent metadata, provenance, and trust signals. Give time-sensitive claims a date or version. Name the organization responsible for the content. Link to the originating evidence when a factual claim depends on it. Distinguish observed facts from your recommendation.

    This is not a request to add a long author biography to every page. It is a request to remove uncertainty that matters. A reader should be able to tell who is making the claim, when it applies, what supports it, and whether it is a fact, interpretation, or recommendation.

    Package the content for its genuine distribution context

    The measured Discover environment separated selection into layers for editorial content, urgent news, trends, local material, social or video content, and commercial content. It also evaluated pipelines by reach, speed, exclusivity, and feed volume. Those dimensions explain why a URL can have broad reach, fast pickup, or exclusive distribution without performing identically across every surface.

    Use only the attributes your content genuinely has. Preserve geographic specificity when the answer is local. Make publication and update context clear when timing changes the value. Treat an original video as a first-class resource when video is integral to the answer. Do not imitate urgency, locality, or trend relevance that the page cannot substantiate.

    Measure search and AI visibility as a portfolio

    A single visibility percentage collapses different systems, intents, and outputs into a number that is hard to act on. Use a small scorecard that keeps the stages separate:

    LayerWhat to recordWhat a weakness meansFirst response
    AccessPublic response, redirects, canonical, robots rules, indexing directives, and extractable main contentThe resource may not be consistently retrievable or eligibleFix the technical path before editing copy
    Search demandPage-level queries, impressions, clicks, and position from Search ConsoleDemand may be weak, changing, or attached to a different intentInspect query clusters and competing pages
    Intent fitAlignment between dominant query tasks and the title, description, opening, and headingsThe page promise does not match the audience reaching itDefend, refocus, expand, or split the page
    Answer readinessDirect answer, qualifications, evidence links, author or publisher, dates, and consistent structured dataThe material may be relevant but difficult to interpret, attribute, or reuseClarify the answer and its provenance
    AI presenceMentions and citations from a versioned set of prompts, plus identifiable referral traffic where availableThe page is not being selected consistently in the observed answer environmentCheck intent, evidence, entity clarity, and competing answer formats
    Discovery distributionDiscover or recommendation exposure reported separately from standard searchA distribution surface may value different timing, format, or contextual signalsImprove truthful packaging for that surface

    For AI answer checks, record the full prompt, engine, date, locale, and any account state that could affect the output. Reuse the same prompt set when evaluating a change. A single answer is an observation, not a trend, and it should not trigger a site-wide rewrite.

    Keep a change log for the URL. Record whether you altered access rules, positioning, the answer core, evidence, structured data, or distribution packaging. Then compare equivalent periods and inspect the metrics closest to the stage you changed. If you modify every layer at once, any improvement will be difficult to explain or repeat.

    Choose one page with meaningful Search Console impressions and uncertain AI visibility. Run the diagnostic from access through measurement, fix the earliest material failure, and document that change. That gives you a defensible optimization process you can apply to the next page instead of another collection of AI SEO guesses.

    References


  • AI Search Visibility When Referrals and Rankings Diverge

    AI Search Visibility When Referrals and Rankings Diverge

    If your organic sessions are falling while your brand still appears in AI answers, you do not have one visibility problem. You have at least three: whether machines can access your content, whether answer systems select it, and whether people visit after seeing it.

    Those stages need different measurements and different fixes. Separate them, and you can tell whether to improve a page, investigate a ranking change, strengthen attribution, or restrict a crawler before it consumes more value than it returns.

    Key takeaways

    • Measure content access, AI mentions and citations, referral sessions, and business outcomes separately. A lost click is not automatically lost visibility.
    • Diagnose impressions, rankings, click-through rate, and AI referrals before editing content. Ranking loss and referral loss can happen together, but they are not the same failure.
    • Give answer systems a clear, supportable answer while giving people a practical reason to visit, such as a workflow, template, decision tool, original data, or implementation detail.
    • Classify bots by identity and business role. Allow, rate-limit, license, challenge, or block them according to their value, cost, and contractual status.

    Build a visibility ledger that follows the whole journey

    An isometric table shows a document moving through connected access, selection, citation, and visitor stages.

    Sessions used to serve as a rough proxy for search visibility because discovery commonly led to a results page and then a click. An AI interface can now retrieve a page, use its information, mention its brand, cite its URL, and still satisfy the user without sending a visit. One traffic graph cannot show which of those events occurred.

    Use a ledger with three distinct stages:

    • Access: a search crawler, training crawler, or real-time fetcher can retrieve the page.
    • Selection: an answer system uses the information, mentions the brand, or links to the page.
    • Referral and value: the user visits, engages, subscribes, generates a lead, or completes another meaningful action.

    The distinction matters because the gap can be severe. Akamai measured application-layer traffic across websites, apps, and APIs from July through December 2025 and found AI bot activity up 300% during 2025. Within that analysis, AI-chatbot referrals delivered about 96% less traffic than traditional search, while only about 1% of users clicked sources cited in AI answers. Treat those figures as directional evidence, not universal benchmarks: your result will depend on your audience, query mix, business model, and the interfaces that expose your content.

    LayerRecordWhat a change can indicateFirst response
    Traditional search exposureImpressions, query, landing page, market, and average positionChanges in demand, ranking, eligibility, or query mixSegment the loss before changing pages
    Traditional search referralClicks, click-through rate, sessions, and landing-page outcomesA difference between being shown and being chosenInspect result presentation, search features, intent, and page promise
    AI selectionAccurate brand mentions, linked citations, cited URLs, and factual errors across a fixed prompt setWhether the brand is represented and whether an owned page receives attributionCheck entity clarity, answer structure, evidence, and page accessibility
    AI referralRaw referrer, channel, landing page, engagement, conversion, and revenue where availableWhether observed visibility produces visits and business valueImprove the post-answer reason to visit and the landing experience
    Machine-access costVerified agent identity, requests, pages fetched, bandwidth, cache use, and origin loadWhether retrieval consumes infrastructure without a corresponding benefitAllow, rate-limit, license, challenge, or block by bot class

    For AI selection, build a repeatable prompt panel rather than collecting convenient screenshots. Include the questions that matter at each stage of your customer’s decision, then preserve the exact prompt, interface, language, market, date, response, mention, citation, and cited URL. If you operate across languages or countries, maintain separate panels; visibility in one market does not establish visibility in another.

    1. Choose prompts from real search queries, support questions, sales objections, and tasks associated with your important pages.
    2. Run the same prompts under comparable conditions. Changing the wording and the interface at the same time makes the result difficult to interpret.
    3. Record an accurate mention separately from a linked citation. A brand can be visible without receiving an owned link.
    4. Check whether the answer represents the brand, product, author, and claim correctly. An inaccurate mention is not a visibility win.
    5. Annotate content releases, schema changes, crawler-policy changes, major deployments, and confirmed search updates beside the results.

    Create simple rates from this ledger: prompts with an accurate mention divided by prompts checked; prompts with an owned citation divided by prompts checked; and AI-referred conversions divided by identifiable AI-referred sessions. Keep the underlying counts beside every rate. A perfect percentage from a tiny or changing prompt set can create more confidence than the measurement deserves.

    Normalize recognizable AI referrers into a reporting channel, but preserve the raw referrer and landing page. Do not depend on campaign parameters for links you do not control. Some interfaces expose little or no useful referral information, so analytics should be treated as the observable portion of AI traffic, not a complete census of AI influence.

    Separate ranking loss from click loss before editing content

    A traffic decline near an algorithm update invites a quick rewrite. That can destroy useful evidence and change the page before you know what failed. Start by marking the rollout window. The March 2026 Google core update ran from March 27 through April 8, finishing after 12 days and 4 hours. A comparison that mixes rollout days with stable periods cannot cleanly separate the before and after states.

    1. Annotate the confirmed update window and every important site change, including migrations, template releases, internal-link changes, rendering changes, and crawler rules.
    2. Compare matched periods outside the rollout. Account for normal seasonality, promotions, and demand changes that affect the same queries.
    3. Segment by query group, page type, directory, market, and device. Sitewide averages can conceal a concentrated loss in one template or topic.
    4. Inspect impressions, position, clicks, and click-through rate together. Then compare those patterns with your sampled AI visibility and AI-referral data.
    5. Review the affected page group only after the failure mode is visible. Preserve an export or snapshot before making material changes so you can evaluate and reverse them.

    Use the pattern, not one metric, to choose the next action:

    • If impressions and positions decline for the same queries and pages, investigate a ranking, relevance, eligibility, or demand problem. Do not assume that a lower sitewide average tells you which one.
    • If impressions remain broadly stable while clicks and click-through rate decline, the result is still being shown but fewer searchers are choosing it. Inspect the result-page features, title and snippet promise, intent fit, and competing ways the query is answered.
    • If traditional search remains stable while sampled AI citations or identifiable AI referrals decline, check machine access, citation selection, brand ambiguity, and measurement coverage before rewriting the page.
    • If sessions decline but qualified leads, subscriptions, or revenue do not, quantify the commercial effect before setting a traffic-restoration target. Not every lost informational click has the same value.
    • If several layers decline at once, keep separate workstreams. A content review cannot repair broken bot access, and a crawler rule cannot make an unsatisfying page more useful.

    Google’s standing position is that a core-update decline does not necessarily mean something is wrong with the site, and meaningful recovery may depend on a later update. That is a reason to avoid panicked reversals, not a reason to wait passively. Review whether affected pages deliver helpful, reliable, people-first information, especially where the page promise and the actual answer have drifted apart.

    Create pages that can be cited and still deserve a visit

    Trying to withhold the basic answer is a poor response to zero-click search. It frustrates readers and leaves answer systems with weaker material to interpret. State the answer clearly, support it, and make the rest of the page valuable after the answer is known.

    A citation-ready, visit-worthy page usually needs these layers:

    • A decisive answer: address the page’s main question directly instead of making the reader extract it from a long preamble.
    • Scope and qualifiers: state the country, language, platform, version, date, audience, or conditions that change the answer. A technically correct statement can still mislead when its scope is hidden.
    • Evidence: connect important claims to their originating authority, underlying data, or documented method. Distinguish a fact from an inference or editorial recommendation.
    • Entity clarity: use consistent names for the organization, product, author, location, and service. Explain relationships that a reader should not have to infer from branding alone.
    • A decision layer: show trade-offs, applicability, exclusions, and common misreadings so the reader can decide whether the answer fits their situation.
    • An action layer: provide the procedure, checklist, template, calculator, original data, implementation detail, or troubleshooting path that helps the reader complete the task.

    This structure makes the central claim easy to identify without turning the page into a disposable definition. The answer earns selection; the decision and action layers earn the visit.

    JSON-LD can clarify what a page represents, but it is not a referral strategy and it does not guarantee selection in an AI answer. Use the schema type that matches the visible content, connect related entities consistently, and validate the markup after publishing. Do not place claims, reviews, authorship, dates, or relationships in structured data that the page itself does not support.

    Apply the same discipline to freshness. Show a meaningful update date when the substance changed, identify version-dependent instructions, and remove contradictions between the page, its metadata, and its structured data. Changing a date without revising stale information creates a freshness signal for the editor, not new value for the reader.

    Before consolidating or unpublishing a weak page, check its inbound links, internal links, ranking queries, citations, conversions, and role in a topic cluster. Preserve a copy and plan the appropriate destination before removing a URL. A careless cleanup can erase authority or break an existing citation even when raw sessions look unimportant.

    Turn AI crawler access into an explicit business policy

    A person controls open, metered, and closed gates between geometric crawler machines and a secure digital archive.

    More machine access does not automatically produce more discovery, attribution, or revenue. It can also increase server and CDN costs. The 300% rise in AI bot activity observed during 2025 makes bot classification an operating issue, not merely a security log to review after something breaks.

    Start by separating training crawlers, which collect material for model development, from real-time fetchers, which retrieve current content to answer a live request. Their timing, potential value, and commercial relationship differ. A single allow-or-block rule ignores those differences.

    Bot classPossible business rolePolicy optionsMain risk to check
    Search or discovery crawlerMakes pages eligible for a discovery surfaceVerify and allow under controlled limitsBlocking can remove a path to visibility
    Authenticated licensed agentAccesses content under agreed commercial termsAllow only within authenticated scope and limitsUnverified requests may exceed the agreement
    Real-time answer fetcherRetrieves current information for an immediate answerAllow, rate-limit, or license according to measured value and costFresh content may be consumed without useful attribution or referral
    Training crawlerCollects content for model developmentAllow, block, or license according to rights and commercial policyDirect referral value may be weak or unobservable
    Unknown or abusive scraperNo verified legitimate roleChallenge, rate-limit, block, or cautiously tarpitSpoofed identities and false positives can misclassify traffic

    A user-agent string is a claim, not proof. Where an operator publishes a verification method, use it. Keep agent identity, request behavior, targeted URLs, bandwidth, origin load, and any referral or licensing value in the same review. That turns a vague bot debate into a policy decision supported by observable costs and benefits.

    1. Observe before enforcing. Establish which agents request which page groups and how much infrastructure they consume.
    2. Verify identity. Do not grant privileged access or apply a punitive rule solely from a self-declared bot name.
    3. Assign a role. Record whether the agent supports discovery, live answering, training, a licensed relationship, or no recognized purpose.
    4. Choose the least disruptive effective control. Options include scoped access, caching, rate limits, authentication, challenges, blocking, and carefully tested tarpitting.
    5. Stage material changes with a rollback path. Watch crawl activity, indexation, sampled AI citations, referrals, server load, and user errors after enforcement.
    6. Review licensing and content-rights terms with appropriate legal counsel before charging for access or signing an agreement. A crawler configuration cannot determine ownership or contractual rights.

    Robots directives can communicate preferences to compliant agents, but they are not authentication or an access-control wall. Enforce sensitive or paid access with controls that can identify and authorize the requesting agent. If you use tarpitting, apply it only after careful classification: deliberately slowing the wrong traffic can harm legitimate discovery or user-facing performance.

    Emerging approaches such as Know Your Agent identity verification and TollBit pay-per-crawl access are intended to turn retrieval into an authenticated, manageable transaction. Treat that model as an option to evaluate, not guaranteed replacement revenue. The commercial case still depends on enforceable identity, demand for your content, contract terms, delivery cost, and the value of any visibility you give up by restricting access.

    Your next move should come from the first broken link in the chain. Build the ledger, mark known update and deployment dates, test the questions that matter, and classify the agents consuming your pages. Then change one layer at a time and keep a rollback path. That is how you protect visibility without mistaking every lost click for a lost audience.

    References