Tag: AI Bots

  • How to Build Search Visibility for AI Agents and Answers

    How to Build Search Visibility for AI Agents and Answers

    You can rank in conventional search and still be absent when an AI system assembles an answer. The missing piece is often not another keyword. An agent has to reach your content, isolate the relevant passage, connect it to the right entity and decide that the claim is clear enough to reuse.

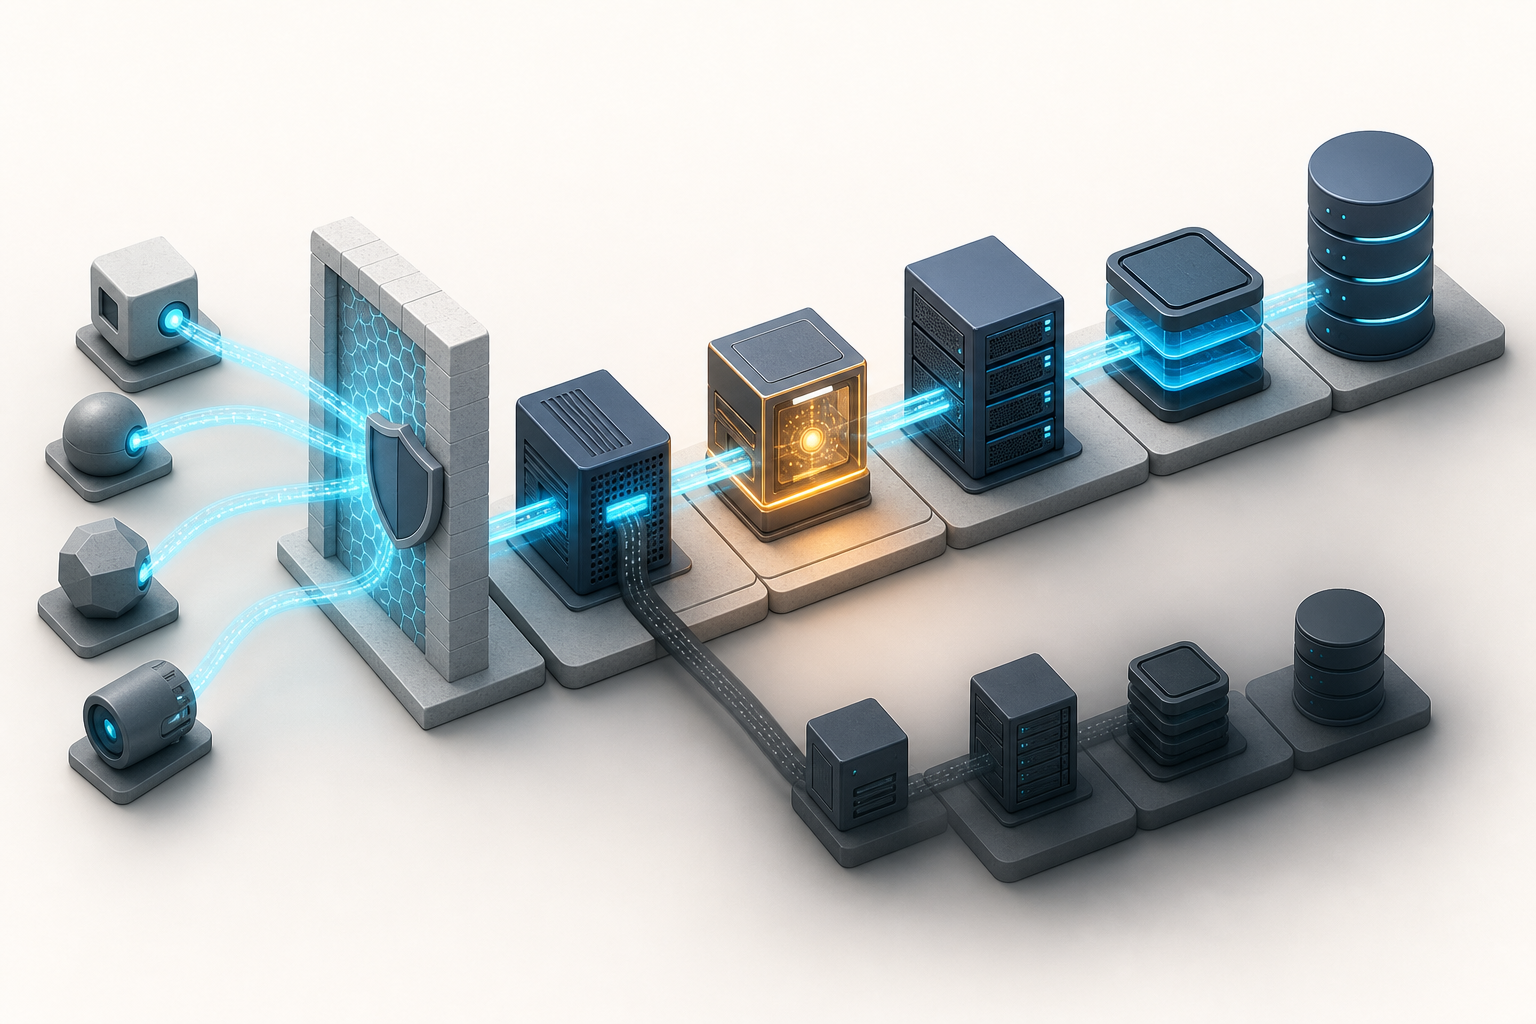
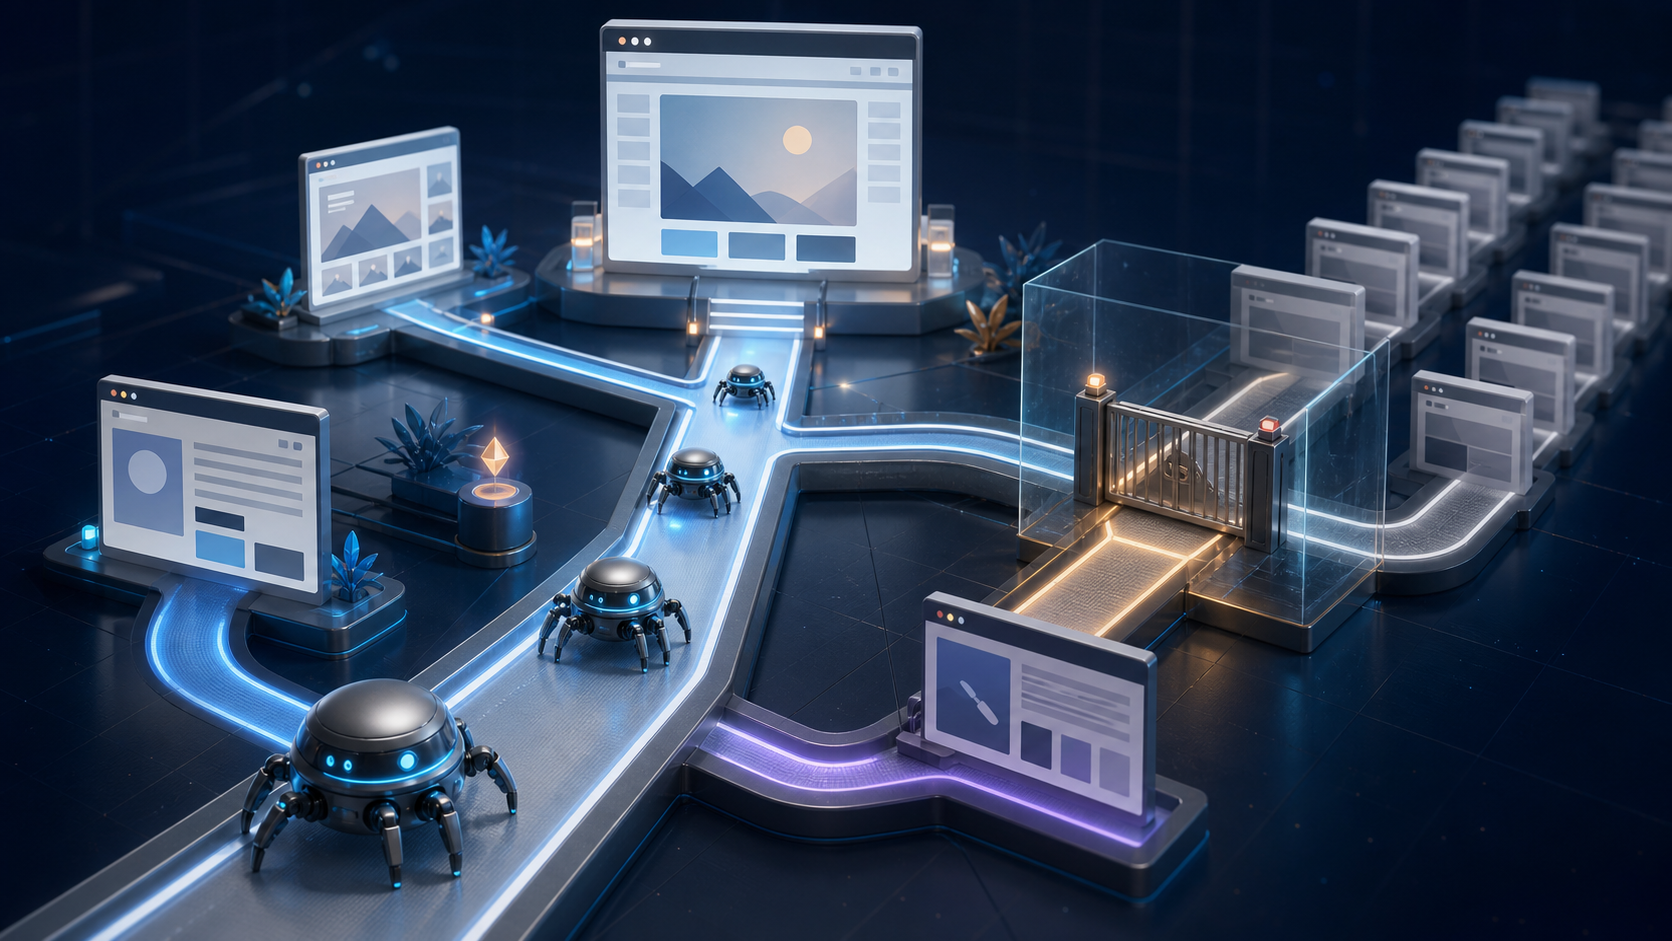
    Treat that sequence as a visibility pipeline. When you control access, extraction, delivery and measurement separately, you can diagnose why a page is missing instead of making broad content changes and hoping one of them works.

    Key takeaways

    • Set separate policies for model-training crawlers and agents that retrieve information for live answers. Blocking a vendor name broadly can block the function you actually want.
    • Make the core answer understandable in raw HTML, then use semantic sections and accurate structured data to reduce extraction ambiguity.
    • Keep titles, canonicals, essential metadata and critical structured data early in the HTML response. A page that renders correctly in your browser can still present an incomplete document to a crawler.
    • Use pull crawling for durable pages, push discovery for important updates, machine-readable delivery for structured facts and MCP access when an agent genuinely needs current data.
    • Measure bot access, extracted content, citation share and business outcomes as separate signals. Referral traffic alone cannot tell you whether generative visibility improved.

    Build a five-entry visibility pipeline

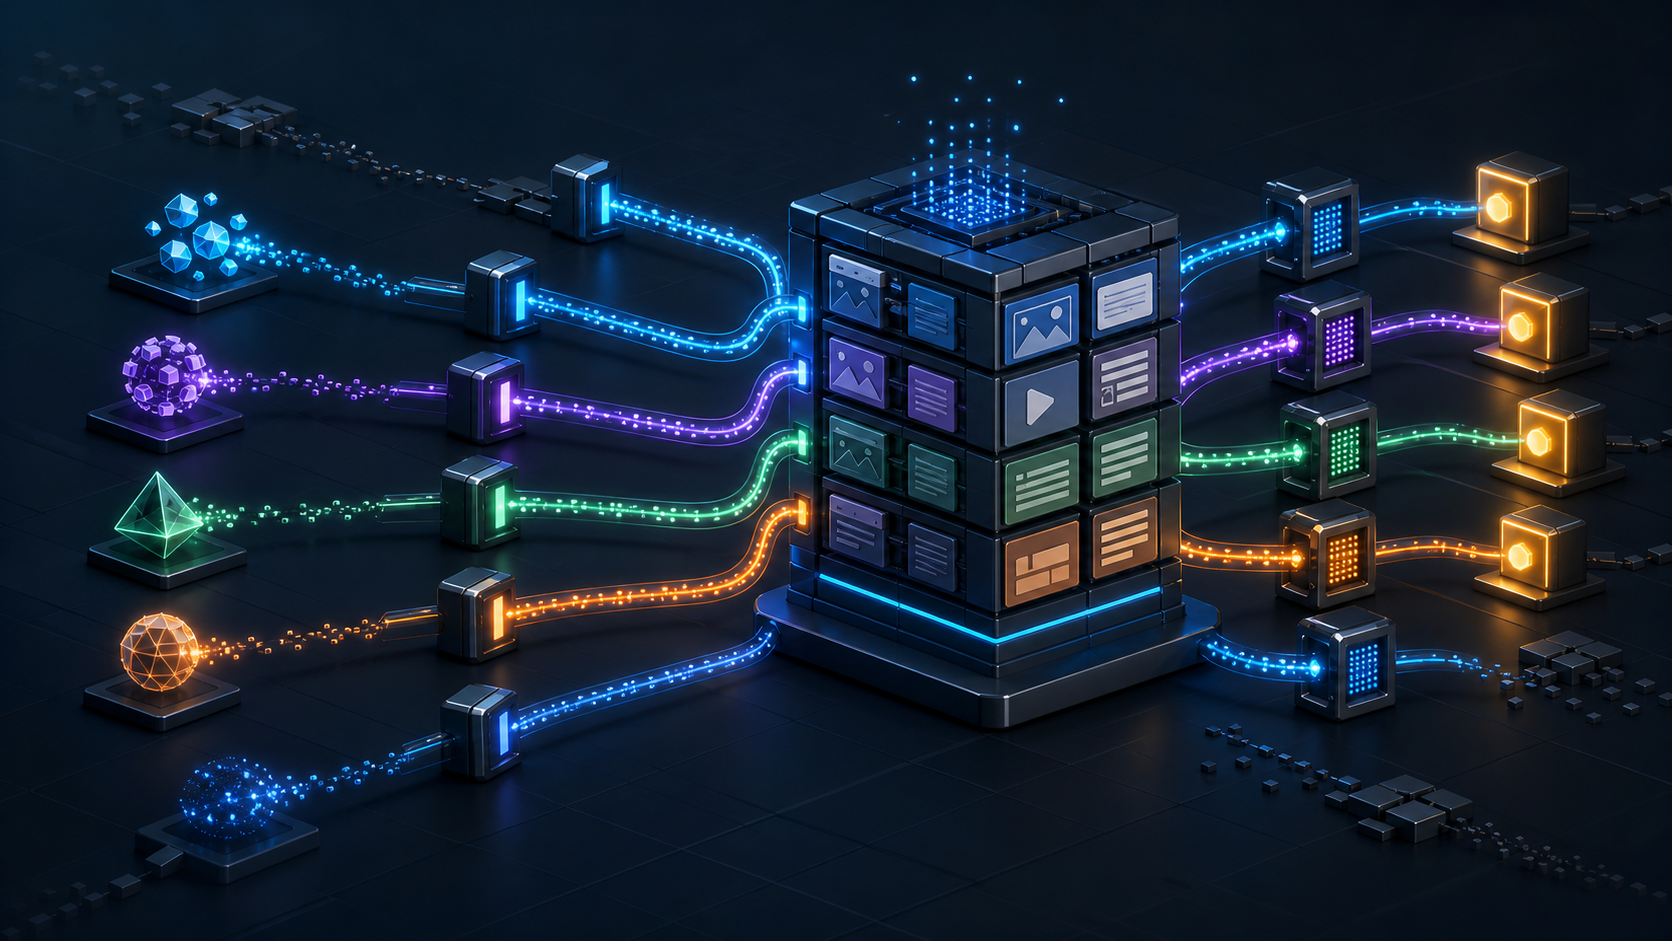
    Traditional search workflows often compress discovery, indexing and ranking into one mental model. Generative systems add retrieval, passage extraction, entity annotation and answer assembly. Your content can enter that process through five distinct routes.

    Entry routeWhat it doesWhere it fits
    Pull crawlingA crawler discovers and fetches a public URL on its own schedule.Evergreen pages, documentation, category hubs and other durable web content.
    Push discoveryYou notify a participating system that a URL is new or has changed.Pages whose value depends on being discovered soon after publication or revision.
    Push dataMachine-readable facts are delivered directly instead of relying only on page extraction.Structured catalogs, feeds and other data with a defined receiving system.
    MCP accessAn agent requests current information through a Model Context Protocol connection.Data that changes too quickly to be represented reliably by an occasional crawl.
    Ambient entryA system recommends or introduces information without a conventional explicit search query.Brand and entity discovery influenced by consistent, well-annotated information.

    These routes are complementary, not maturity levels. An evergreen explainer usually needs a clean crawl path more than an MCP server. A changing first-party dataset may need a direct machine interface because a cached page can become stale between fetches. Map each important content type to the least complicated route that preserves its accuracy.

    All five routes eventually depend on annotation: the system has to associate a fact with the correct organization, product, person, place or topic. That is why delivery alone is insufficient. Conflicting names, unclear ownership, inconsistent dates or schema that disagrees with visible copy can weaken the content after it has been successfully fetched.

    Separate training permission from live-answer retrieval

    The label AI bot hides several different jobs. The same provider may use one user agent for model training and another for retrieval or search. Current crawler distinctions include separate training, crawling and live-search identities:

    • OpenAI: GPTBot is associated with training, while OAI-SearchBot is associated with search and retrieval.
    • Anthropic: ClaudeBot is associated with training; Claude-User and Claude-SearchBot serve retrieval or search functions.
    • Perplexity: PerplexityBot is the crawler identity, while Perplexity-User is associated with user-driven searching.

    Decide what you want before editing robots.txt. For each user agent, record whether public editorial pages, product information, support documentation and downloadable resources should be accessible. Make the training decision independently from the retrieval decision. A company can decline training access while still choosing to make public pages available to a search-oriented agent.

    A narrowly scoped rule can look like this:

    User-agent: GPTBot
    Allow: /public/
    Disallow: /private/

    Do not use robots.txt to protect confidential information. It is a crawler directive, not an authentication system. Private, customer-specific and administrative content needs server-side access control whether a path is disallowed or not.

    After deployment, inspect server logs by user agent. Confirm that the intended crawler reaches the intended URLs, receives a successful response and can fetch resources needed to interpret the page. A syntactically tidy policy is not evidence that the access path works.

    Use llms.txt as a map, not a dependency

    The emerging llms.txt convention can give agents a concise map of important links, while llms-full.txt can aggregate larger amounts of text into one machine-oriented resource. Adoption is not universal, so neither file should be the only way to discover or understand your content.

    If you publish llms.txt, generate it from the same canonical content inventory used by your sitemap and navigation. Include public, authoritative URLs rather than every filtered, duplicated or campaign-specific variation. Keep the file synchronized when pages move or claims change. It does not override robots.txt, authentication, canonical signals or the content of the page itself.

    Make each page fragment-ready
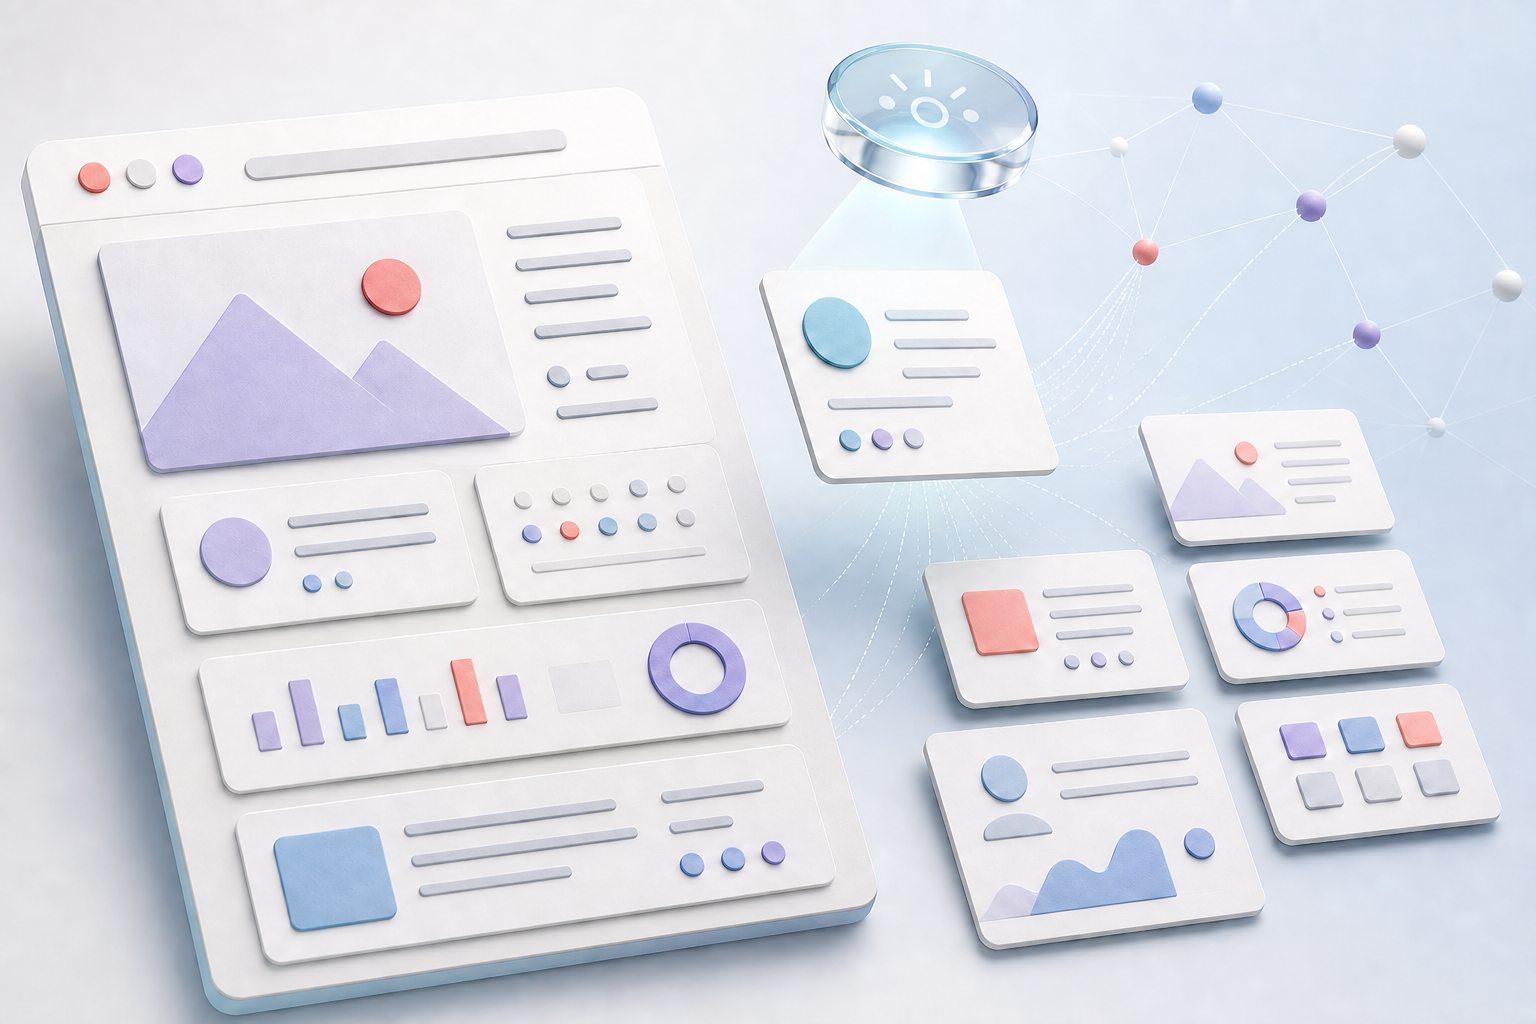
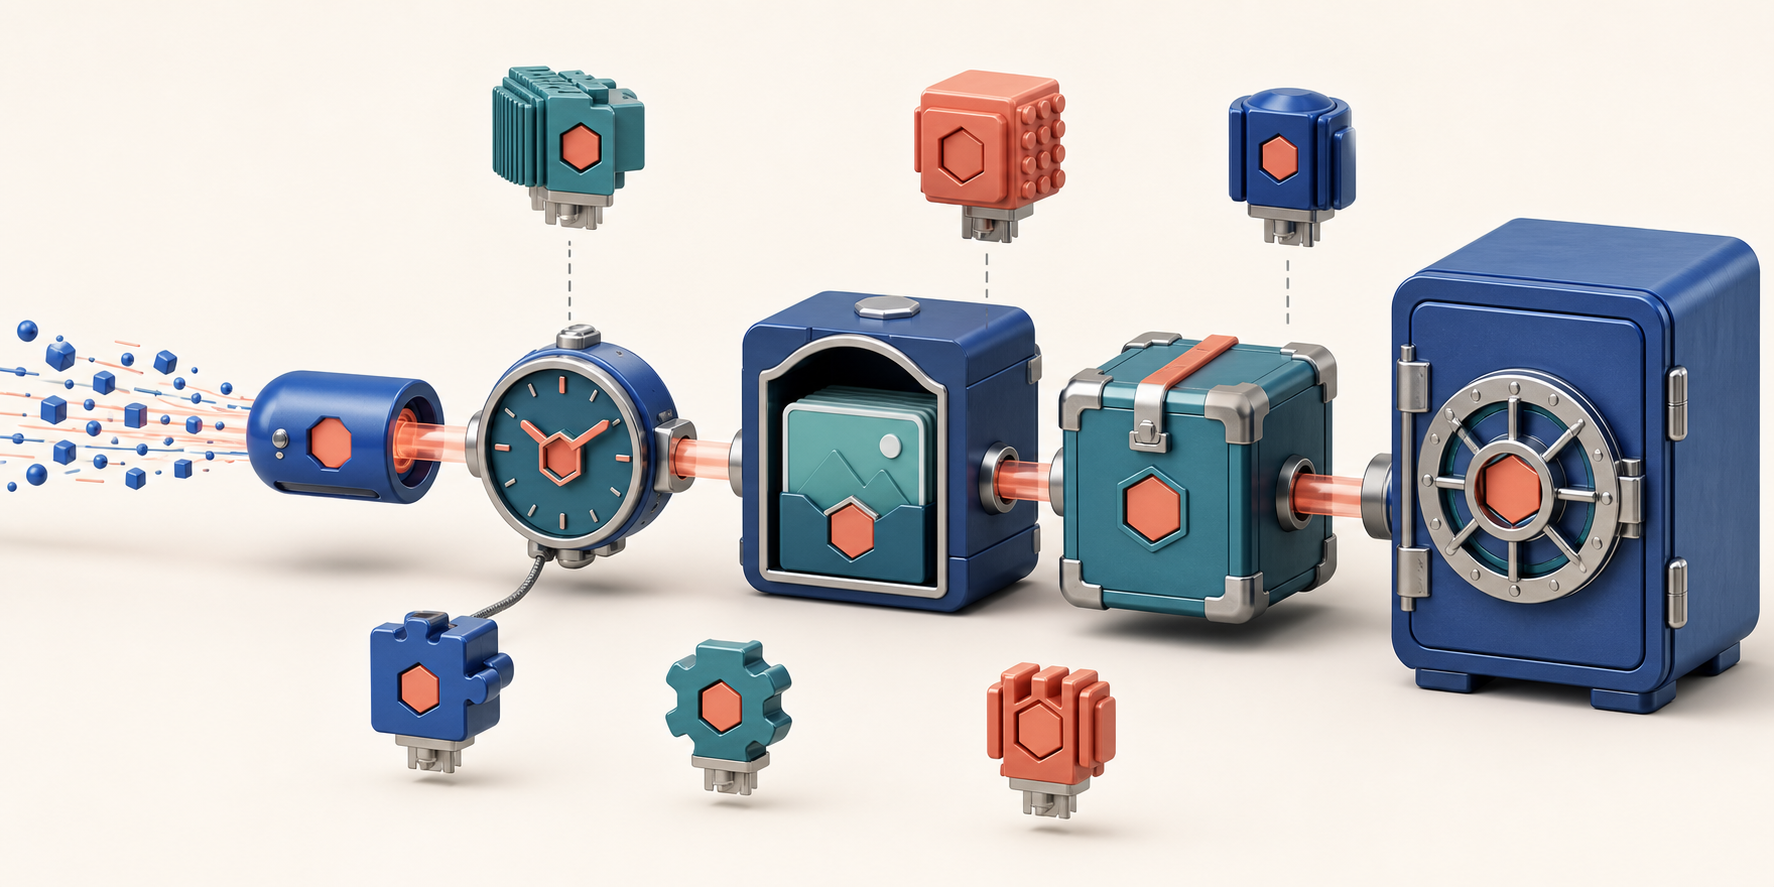
    A digital page separates into modular content cards while an AI lens selects one card and links it to a network of entities.

    An agent rarely needs every sentence on a long page. It needs a passage that answers the current question without losing essential qualifications. Your job is to make that passage easy to locate and safe to reuse.

    Build each important section in this order: state the answer, name the entity it applies to, add the condition or limitation, then provide the supporting explanation. Put exceptions beside the claim they qualify. If a warning appears several sections later, extraction can separate it from the advice it was meant to constrain.

    • Use a descriptive heading that reflects the question or decision addressed by the section.
    • Answer immediately beneath that heading instead of opening with scene-setting copy.
    • Name the product, organization, method or audience inside the passage. Avoid relying on vague references such as it, they or this solution when the fragment could be retrieved alone.
    • Keep definitions stable. Do not alternate between near-synonyms if they could make one entity look like several unrelated entities.
    • Use lists for steps and criteria, and tables only when rows and columns express a real comparison.
    • Link supporting detail close to the claim it supports rather than collecting all evidence in an unrelated footer.

    Semantic HTML helps establish those boundaries. Use <article> for the primary work, <section> for coherent subtopics and <aside> for genuinely supplementary material. This does not guarantee selection, but it gives crawlers a clearer representation than a page composed entirely of generic containers.

    Structured data should agree with the visible page. Use the schema type that matches the content, identify the same entities named in the copy and omit properties you cannot support on the page. JSON-LD can reduce ambiguity; it cannot repair an unclear claim or turn unsupported markup into trustworthy information.

    Put critical information within the fetched bytes

    Payload order matters when a crawler stops before the document ends. Googlebot fetches up to 2MB for an individual non-PDF URL, with the HTTP response headers included in that limit. When an HTML response exceeds the threshold, the downloaded portion is passed to indexing and the Web Rendering Service as though it were the complete file. Bytes after the cutoff are not fetched, rendered or indexed. PDFs have a higher 64MB limit.

    The Web Rendering Service can fetch referenced resources separately and execute JavaScript like a modern browser, so external scripts and styles do not consume the parent HTML document’s byte allowance. That is a reason to remove oversized inline payloads, not a reason to hide the central answer behind unnecessary client-side execution.

    Do not generalize Google’s exact limits to every AI crawler. Use them as a concrete reminder that a page visible in your browser is not necessarily the same document a bot received or completed.

    • Inspect the raw server response as well as the rendered page.
    • Place the title, canonical link, essential meta tags and critical structured data early in the HTML.
    • Move large CSS and JavaScript payloads into external resources where appropriate.
    • Remove duplicated navigation, serialized application state and other bulky inline material that delays the primary content.
    • Verify that the central answer appears without requiring a click, expansion control or user-specific session.
    • Compare raw and rendered text so you know what depends on JavaScript.

    Response performance belongs in the same audit. When a server cannot deliver resources efficiently, fetchers may slow their activity to avoid adding load, which can reduce crawl frequency. Review latency alongside status and crawl counts instead of interpreting fewer requests as a content-quality judgment.

    Add push paths where freshness changes the answer

    Publishing and waiting remains reasonable for stable content, but it is incomplete when discovery speed or data freshness affects whether an answer is useful. Add proactive delivery in layers, after the public URL and its canonical content are sound.

    1. Preserve the pull foundation. Give every durable page a crawlable canonical URL, sensible internal links and an accurate sitemap entry. Push mechanisms should supplement this foundation.
    2. Notify systems about meaningful URL changes. Bing’s IndexNow can accelerate discovery by telling participating systems that content is new or updated. Treat the notification as an entry signal, not a substitute for a fetchable and interpretable page.
    3. Provide machine-readable data when a receiver supports it. Use a structured feed or direct data connection for facts that should not depend on extracting prose. Define one authoritative source so the feed and public page do not contradict each other.
    4. Use MCP for genuinely current interactions. An MCP connection is justified when an agent needs information that could become stale between crawls. Specify what each tool exposes, which fields are authoritative, how errors are represented and who may call it. Do not create an MCP layer merely to duplicate static editorial pages.
    5. Strengthen the inputs to ambient discovery. Keep names, descriptions and relationships consistent across your first-party content and machine-readable outputs. Ambient recommendations are not a submission box you can force; they depend on whether systems can confidently recognize and contextualize the entity.

    Use a freshness test when choosing the route: if an older value would make the answer materially wrong, evaluate direct data or MCP access. If the information remains accurate until the next normal crawl, keep the architecture simple and focus on extraction quality.

    Centralize the underlying data before adding several delivery methods. Otherwise a page, feed and agent tool can expose three different versions of the same fact. Faster delivery only makes that inconsistency spread sooner.

    Measure access, citations and outcomes separately
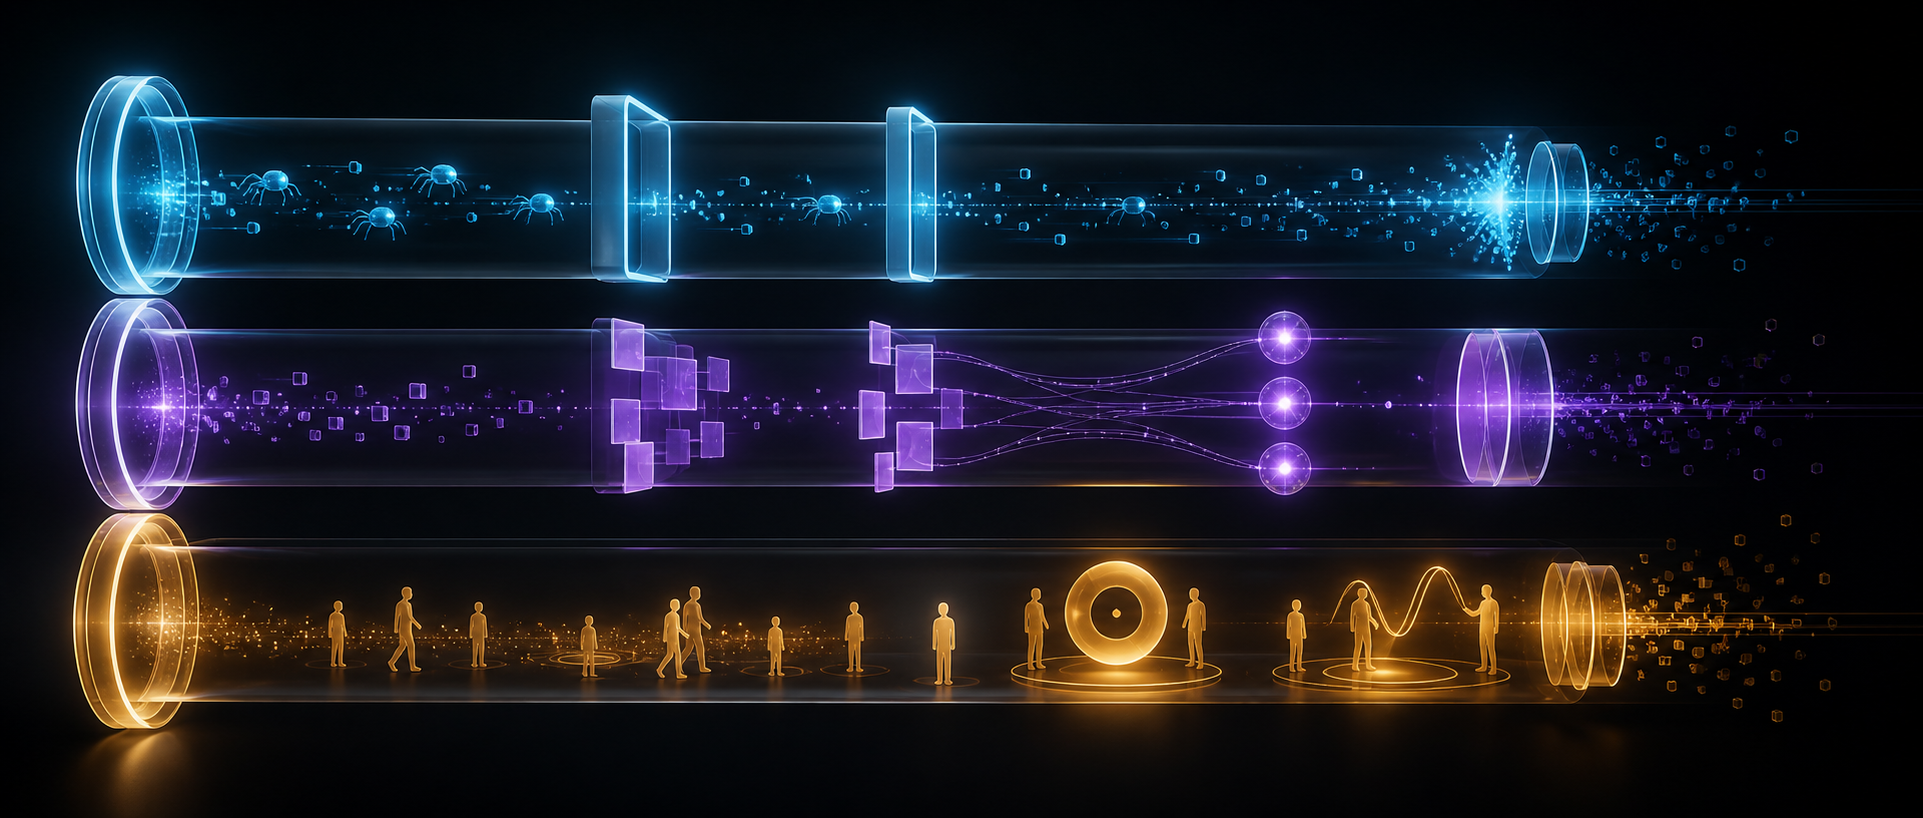
    Three parallel visual channels depict content access, citation connections, and human outcomes using abstract gateways, fragments, and symbols.

    A click-only dashboard cannot explain generative visibility. An answer may cite you without sending a visit, retrieve your page without using it or mention your brand while linking elsewhere. A practical GEO technical audit combines citation share, log analysis and zero-click behavior rather than collapsing them into one traffic number.

    • Access: Group server requests by user agent. Record which important URLs were requested, whether they were allowed, how the server responded and whether latency changed.
    • Extraction: Compare the raw response with the rendered page. Confirm that the answer, entity name, qualifications, canonical and structured data are present and mutually consistent.
    • Interpretation: Check whether headings, visible copy, schema and linked canonical resources describe the same entity and claim. Flag conflicting names, dates, ownership or status.
    • Visibility: Maintain a fixed set of representative questions. Citation share is the portion of checked answers that cite your domain or a tracked URL. Record the engine, model, query, cited page and claim so later checks remain interpretable.
    • Outcome: Track identifiable AI referrals and their business actions, but keep citations as a separate measure. No referral does not prove that the system ignored you; the generated answer may have satisfied the user without a click.
    • SEO context: Compare changes in AI visibility with domain metrics, backlink profiles, keyword research and organic-search data. This helps distinguish an agent-access problem from a broader authority, demand or search-performance problem.

    The combination of signals points to the next action. No crawler requests usually directs you toward discovery or access controls. Successful fetching with no usable passage points toward rendering or extraction. Clear extraction with weak citation presence points toward annotation, relevance or authority. More citations without more referrals may reflect zero-click use rather than failure.

    Keep the prompt set and measurement method stable while evaluating a change. If you replace the questions, engines and success definition at the same time, the before-and-after comparison cannot tell you which intervention mattered.

    Start with one content cluster tied to a real business or reputation goal. Verify crawler policy, raw HTML, semantic sections and structured data; then add IndexNow, a structured feed or MCP only where the content’s freshness requires it. Record access and citations before and after the change. Once that evidence chain works, make it part of the publishing workflow for every similar page.

    References


  • How to Build an AI-Era SEO and Content Strategy That Holds Up

    How to Build an AI-Era SEO and Content Strategy That Holds Up

    If your traffic plan still starts with a keyword list and ends when a page is published, AI search exposes the missing middle. You need content that answers a real decision clearly enough for search engines and language models to retrieve, while giving a person enough evidence to trust the answer and take the next step.

    You don’t need a separate content library for every search or AI interface. You need one evidence-led system: learn how your audience describes the problem, organize that demand into distinct decisions, publish answerable pages, keep them technically accessible, and measure what happens after a machine fetches them.

    Key takeaways

    • Start with customer evidence, not an AI-generated keyword universe. Reviews, calls, audience data and search behavior reveal the language and stakes behind a query.
    • Use a persona GPT as a critic grounded in your approved evidence. It can expose omissions quickly, but it cannot replace customers or validate its own assumptions.
    • Build long-tail clusters around distinct decisions, constraints and stages. Don’t create a new URL for every wording variation.
    • Make each important section an answer module: a descriptive heading, a direct answer, its conditions, supporting evidence and a useful next step.
    • Keep canonical HTML as your default. Treat Markdown delivery as a controlled experiment, not as a presumed AI-ranking advantage.
    • Measure demand, crawling, retrieval, visits and business outcomes separately. More bot requests alone do not prove more AI visibility or value.

    Start with audience evidence, not AI guesses

    AI can organize what you know about an audience. It cannot know that audience merely because you assigned it a name, job title and personality. A fictional persona built from a prompt usually reflects your assumptions with more polished wording.

    Begin with observable inputs. Useful audience research can combine SparkToro exploration, review mining and sales-call listening. Each channel reveals something different: where people spend attention, how they describe satisfactory and disappointing outcomes, and which question finally moves them to contact a company.

    Put those inputs into an evidence bank before asking AI to interpret them. Each record should preserve:

    • The trigger: what changed or happened before the person started looking.
    • The job: what progress the person is trying to make, expressed as an action rather than a broad topic.
    • The original wording: the customer’s own phrase, kept separate from your preferred terminology.
    • The constraint: budget, compatibility, risk, experience, time, approval or another condition shaping the answer.
    • The objection: what could stop the decision or make the person distrust a claim.
    • The decision criteria: what the person compares and which proof they need.
    • The journey moment: whether they are identifying the problem, evaluating approaches, choosing an option or trying to implement it.
    • The evidence location: the call note, review, survey response, analytics view or other record from which the observation came.

    This structure prevents a common content mistake. Two people can type similar words while facing different decisions, and one person can use several different queries while making the same decision. The decision should determine your content architecture; the wording should help you shape headings, examples and internal links.

    Now turn the evidence into an operational persona. Skip invented hobbies and decorative biographies unless they affect the purchase or task. Capture the person’s context, trigger, desired progress, current alternative, objections, proof threshold and appropriate next action. Attach the supporting records so an editor can inspect where each conclusion came from.

    A custom GPT becomes useful at this point because it acts as an interface to the evidence. Give it only approved persona material, explain which fields are facts and which are interpretations, and require it to expose uncertainty. Persona GPTs can provide fast feedback on alignment and omissions, but their claims still need to be checked against the supplied data.

    Use this persona test prompt: Review this page only against the supplied persona evidence. For every criticism, identify the supporting evidence field. Mark any unsupported inference as unknown. Separate missing information, unclear wording and genuine objections. Do not rewrite the page until you have explained why each proposed change matters to this persona.

    That last instruction matters. If you ask for a rewrite first, fluent copy can conceal weak reasoning. Ask for the evidence trail first, decide which criticism is valid, and then request a constrained revision. Update the persona when new calls, reviews or campaign findings change what you know; remove stale assumptions rather than allowing the profile to grow indefinitely.

    Map long-tail demand to decisions, not keyword variations

    Hands sort blank audience research cards into clusters that branch toward several different decision outcomes.

    A useful long-tail query is not simply a longer phrase. It usually narrows the decision by adding a situation, goal, constraint, comparison or stage. That specificity is valuable because it tells you what must be present for an answer to feel complete.

    Use customer language as the seed, then let AI expand the dimensions around it. AI-assisted long-tail work is most useful when the model is asked to expose meaningful variations rather than generate a large list of loosely related phrases.

    For each observed problem, explore these dimensions:

    • Situation: what is already true when the search begins.
    • Goal: the result the person is trying to achieve.
    • Constraint: the condition that rules out a generic answer.
    • Alternative: the option, workaround or competitor category being considered.
    • Risk: what the person fears losing, breaking or choosing incorrectly.
    • Stage: whether the person needs orientation, evaluation, selection or implementation help.

    Require every generated query or question to carry one of two labels: supported by an evidence-bank record or an unvalidated hypothesis. Hypotheses can become research prompts. They should not quietly become editorial facts just because the wording sounds plausible.

    Use this expansion prompt: From the supplied customer evidence, generate question variants by situation, goal, constraint, alternative, risk and journey stage. Preserve the customer’s terminology. Cite the evidence record behind each question. Put anything not directly supported into a separate hypothesis list, and do not invent demand, product capabilities or customer concerns.

    Next, group the questions by the decision they serve. You are looking for answer overlap, not merely shared words. If several queries lead to the same recommendation, evidence and next step, they probably belong on the same canonical page. Give the page a clear primary decision and use subsections for the meaningful variants.

    Create a separate URL only when the reader has a materially different job, needs a different answer, requires different proof, or should take a different next action. Otherwise, more pages create maintenance work and compete to explain the same thing. A larger content inventory is not broader coverage when the underlying answers are interchangeable.

    For every planned page, write a short content contract before drafting:

    • The decision this page helps the reader make.
    • The audience situation and constraints it covers.
    • The direct answer the page must deliver.
    • The evidence available to support that answer.
    • The adjacent questions that belong as subsections.
    • The questions that belong on other pages.
    • The next useful action after the reader understands the answer.

    This contract gives editors, subject-matter experts and AI tools the same boundary. It also makes content consolidation easier: when two pages claim the same decision, you can compare their evidence and choose which one should own it. Check existing traffic, links and business dependencies before merging or redirecting a live URL.

    Publish answer modules, then test the delivery format

    Editors rearrange the same visual answer modules into desktop, mobile, and conversational interface layouts.

    Build sections that can stand on their own

    Search results and AI answers often retrieve a passage, not the argument as you pictured it on the editorial calendar. Important sections therefore need enough local context to remain accurate when encountered on their own. That does not mean repeating the entire page under every heading. It means resolving ambiguous subjects and carrying necessary conditions into the answer.

    A durable answer module has a simple shape:

    • A descriptive heading: name the exact question, task or distinction addressed by the section.
    • A direct opening answer: give the conclusion before background, including any condition that changes it.
    • An explanation: show the mechanism, reasoning or distinction that makes the conclusion credible.
    • Supporting evidence: provide the relevant data, specification, example, expert input or first-party observation you actually possess.
    • An action boundary: tell the reader what to do, what not to infer and when a different answer applies.
    • A next step: point to the next decision, tool, page or workflow rather than ending with a vague invitation.

    Answer-first writing is not the same as oversimplification. A direct answer can be conditional. In fact, stating the condition early is more useful than offering a universal claim and burying the exceptions later. The reader should be able to tell quickly whether the answer applies to their situation.

    Keep entity references explicit at section boundaries. Name the product, organization, method or concept instead of opening a retrieved passage with an unclear it, they or this. Define an acronym before relying on it. Use the same name consistently unless a real distinction requires different terminology.

    Separate three kinds of statement during editing: observed fact, interpretation and recommendation. Facts need a traceable basis. Interpretations need reasoning. Recommendations need a condition and intended outcome. If you lack proof, do not ask AI to manufacture an example, quotation, benchmark or customer story to make the section feel authoritative.

    Use semantic HTML to preserve the hierarchy: headings for sections, lists for criteria or steps, and tables only for real comparisons. If you add JSON-LD, it should describe the visible page accurately. Structured data can clarify entities and content properties, but it cannot repair a vague answer, unsupported claim or page that search systems cannot fetch.

    Treat Markdown as a testable delivery hypothesis

    Markdown can represent clean, easy-to-parse text. That does not establish that AI crawlers prefer it, that additional crawling produces citations, or that citations produce customers. Formatting, access, retrieval and business value are separate questions.

    Your canonical public page should usually remain HTML because it serves browsers and ordinary search discovery directly. Do not replace working canonical pages or publish uncontrolled duplicate URLs merely to attract AI bots. If you want to offer a Markdown representation, decide how canonicalization, internal linking, metadata and updates will remain consistent before exposing it.

    Run a controlled test if format preference matters to your site:

    1. Select a representative cohort and a comparable control group.
    2. Change only the delivery format. Keep the underlying content, page purpose, internal discovery, canonical signals and server availability stable.
    3. Record which crawler labels request each version, whether the full response is delivered, and whether requests repeat.
    4. Measure crawl behavior separately from appearance in relevant AI answers.
    5. Measure AI visibility separately from human visits and qualified actions.
    6. Document the hypothesis and stopping condition before inspecting the result, so an interesting traffic spike does not become the success definition after the fact.

    One controlled setup observed 381 pages over three weeks. That scale is useful as a reminder that a formatting claim needs a cohort and an observation window, not a single-page before-and-after anecdote. It does not establish the correct sample or duration for your site, which depends on how often your pages are normally fetched.

    Request logs are diagnostic evidence, not the final KPI. A bot label does not tell you whether a model retrieved the page for an important question, represented the answer accurately, sent a visitor or influenced a business result. Keep those outcomes separate in your reporting.

    Measure the full chain from demand to business outcome

    AI-era SEO becomes manageable when you stop treating visibility as one metric. A page can answer a valuable question but remain inaccessible. It can be fetched without being retrieved. It can appear in an answer without earning a visit. It can earn visits that never reach the right next step.

    StageQuestion to answerSignals to inspectLikely response
    DemandDoes this question reflect a real audience decision?Customer calls, reviews, audience findings, search behavior and on-site questionsRevise the query cluster or collect more evidence before producing more content
    AccessCan the relevant systems discover and fetch the intended content?Server requests, successful delivery, canonical handling, internal links and rendered page contentFix discovery, blocking, rendering or delivery issues before rewriting the answer
    RetrievalDoes the page appear for the relevant question and context?A documented query set, answer citations, brand mentions and passage selectionImprove answer fit, entity clarity, supporting evidence and alignment with the decision
    VisitDo exposed users reach the site and continue?Landing sessions, available referral data and engagement with the intended next stepStrengthen the transition from the answer to a useful on-site action
    OutcomeDoes the interaction produce a qualified result?Relevant signups, inquiries, purchases or other business actionsCorrect the audience, offer, page intent or conversion path

    The stage where performance breaks tells you what to change. If crawlers do not fetch the page, investigate access and discovery. If the page is fetched but absent from relevant answers, inspect intent fit, extractability, evidence and entity consistency. If the answer mentions you but few people visit, the interface may already satisfy the query; give the reader a concrete reason to continue rather than withholding the basic answer. If qualified visitors arrive but do not act, the problem is more likely the offer, proof or next step than crawl format.

    Use a stable set of audience questions for retrieval checks. Record the wording, audience context, system tested and observed answer so later comparisons mean something. AI output can vary, so do not treat a single response as a durable ranking. Look for repeated patterns under documented conditions.

    Connect each content change to a hypothesis. A useful change log states which audience evidence triggered the edit, which answer module changed, what technical behavior should improve, and which downstream outcome will determine whether the change stays. Avoid changing the persona, page structure, delivery format and call to action at the same time; you will not know which layer caused the movement.

    A practical first implementation

    1. Choose a commercially meaningful query cluster already supported by customer evidence.
    2. Build the evidence bank and operational persona for that decision.
    3. Give the canonical page a content contract, then remove sections that do not help the decision.
    4. Rewrite the core sections as answer modules with explicit conditions, evidence and next steps.
    5. Check semantic structure, visible content, JSON-LD accuracy, internal discovery and server delivery.
    6. Use the persona GPT to identify unsupported assumptions and missing objections, requiring an evidence reference for every criticism.
    7. Establish the demand, access, retrieval, visit and outcome baselines before testing a delivery or content change.
    8. Expand the system to another cluster only after you can explain what worked, where it worked and which evidence supports that conclusion.

    Start with the page closest to a real customer decision, not the topic with the easiest AI-generated outline. By your next editorial review, you should be able to show which audience evidence shaped that page, which decision it owns, how machines can access and interpret it, and which outcome will decide its next revision.

    References

  • Should You Create Separate Markdown Pages for LLM Crawlers?

    Should You Create Separate Markdown Pages for LLM Crawlers?

    You are considering a markdown version of every page because cleaner text seems easier for an LLM to consume. The idea sounds tidy: keep the normal HTML for people, give crawlers a stripped-down .md page, and hope the machine-readable copy earns more visibility in AI answers.

    Do not make that your default. A separate, bot-oriented markdown mirror adds another crawlable URL and another copy of your content without solving a demonstrated parsing problem. If its content differs from the page people see, the tactic can also cross into cloaking. Your safer and more durable approach is to make one public page clear, complete, structured, and consistent for every visitor.

    Use one public page as the authoritative answer

    Normal HTML is already machine-readable. Language models have long been able to read and parse ordinary web pages, so an HTML-to-markdown conversion does not automatically remove a barrier between your content and an AI system. That is why Google and Bing representatives advise against separate pages created specifically for LLMs.

    The important distinction is not HTML versus markdown. It is a public resource with an independent purpose versus a shadow copy made only for crawlers.

    • A normal public HTML page: This should remain your primary page. It serves users, search crawlers, and AI systems from the same maintained content.
    • A downloadable markdown document people intentionally use: This can have a legitimate purpose. Its value comes from being a real user-facing resource, not from its file extension.
    • A complete public documentation set authored in markdown: The format itself is not the problem. If the documents are the actual product people read, they are not merely crawler mirrors.
    • A second URL containing the same copy for bots: This creates duplication and maintenance work without a clear need.
    • A markdown response shown only when a crawler user agent requests the page: This is the highest-risk pattern because the server is deliberately changing what it provides according to visitor identity.

    Use a simple test before creating another representation: would a person, customer, developer, or partner deliberately visit or download it? If the only answer is that an LLM might prefer it, keep working on the public page instead.

    Why a bot-only markdown mirror creates avoidable risk

    Two parallel web pages drift out of alignment as tangled paths and mismatched content blocks surround a crawler at a fork.

    Both versions may still be crawled and compared

    A second format does not necessarily replace crawling of the first. Bing has indicated that it may crawl the normal page anyway to check similarity. You can therefore create more crawl activity, not less, while giving the search engine two versions whose relationship it must interpret.

    This matters even when your first markdown export is perfectly accurate. Every additional URL becomes another artifact that your publishing workflow must generate, link, update, test, and retire. The benefit is speculative; the operational burden is immediate.

    The copies will eventually drift

    Duplicate representations rarely fail dramatically on launch day. They fail quietly after the main template changes. A price, product name, eligibility condition, author detail, internal link, or correction is updated in HTML but not in the markdown exporter. The machine-oriented page then becomes the less reliable version of the same answer.

    Human readers also provide an informal quality-control layer. They encounter broken layouts, stale claims, missing links, and confusing passages on the page your team regularly reviews. A bot-only output can remain broken because nobody uses it as a person would. Search guidance specifically warns that non-user versions are often neglected for this reason.

    Material differences can become cloaking

    You do not need to send byte-for-byte identical files to every client. A browser may receive styling, navigation, scripts, and interactive controls that do not belong in a plain-text representation. The problem begins when crawler detection changes the substantive page: its main claims, named entities, product details, links, availability, or overall meaning.

    Serving one message to people and a different one to crawlers can be treated as cloaking and violate Google policy. Calling the alternate response markdown, JSON, an AI feed, or an optimization layer does not change that underlying relationship. If a machine is being given content a user cannot reach and verify, stop and examine why.

    Make the HTML page easier to understand instead

    The useful work is not converting syntax. It is reducing ambiguity in the page everyone receives. That improves the same resource for readers, conventional search systems, and AI-driven discovery without creating a parallel publishing system.

    1. Answer the primary question in visible page content. Do not reserve the concise explanation, definition, comparison, or conclusion for a crawler payload. A reader should be able to find the answer on the public URL.
    2. Give each section a descriptive heading. Headings such as Benefits or Details provide little context. State the decision, condition, or question the section resolves.
    3. Use lists only when the information is actually a sequence or set. Lists clarify steps, requirements, and criteria. Connected reasoning still belongs in paragraphs.
    4. Name entities consistently. Use the same product, organization, person, location, and feature names throughout the page. Explain abbreviations when they first appear instead of making a system infer whether two labels mean the same thing.
    5. Keep important qualifications beside the claim. If a condition changes an answer, do not bury it in a distant note. Clear scope is more valuable than an artificially short sentence.
    6. Put structured data on the public page. Bing has explicitly expressed a preference for schema embedded in pages. The markup should describe the content users can actually see rather than introduce separate claims for crawlers.
    7. Keep useful images. The ability of language models to process images undermines the assumption that every visual page must be converted into plain text. Use meaningful captions, labels, and alternative text where appropriate, while keeping essential facts available in the page content.
    8. Maintain stable internal paths to the page. Navigation and contextual links help people and crawlers reach the same authoritative resource. A hidden markdown mirror does not repair a page that is difficult to discover within your own site.

    None of these changes guarantees inclusion or citation in an AI answer. They do remove self-created ambiguity. That is the right optimization target: make your meaning easier to extract without inventing a different meaning for machines.

    Audit markdown and JSON endpoints already on your site

    An analyst inspects a network of web pages, document files, and data endpoints with a magnifying lens highlighting forgotten branches.

    If a plugin, agency, developer, or edge rule has already produced machine-oriented versions, do not delete them blindly. First identify which URLs exist, whether anyone uses them, and whether other systems depend on them. Then consolidate the endpoints that have no independent purpose.

    1. Inventory every alternate route. Look for paths ending in .md or .json, format query parameters, alternate-link declarations, sitemap entries, CMS export features, and CDN or server rules that inspect user-agent strings.
    2. Request the same URL in more than one way. Compare the ordinary browser response with the response produced for the crawlers your configuration recognizes. Record the status code, final URL, main text, links, headings, structured data, and robots directives.
    3. Identify the owner and purpose of each endpoint. A public API response, developer download, or genuinely used raw document may deserve to remain. A page created solely because someone expected LLMs to require markdown does not have the same justification.
    4. Compare meaning, not just word count. Check names, facts, conditions, product information, calls to action, and destination links. A shorter representation may still be equivalent; a version that changes the answer is not.
    5. Choose one maintained public page. Move any uniquely useful explanation into that page. Do not leave the best answer trapped inside the machine-only copy.
    6. Retire unjustified mirrors carefully. Remove bot-specific routing, discovery links, and generator rules. If an alternate URL has acquired legitimate links or usage, map it to the corresponding public page rather than sending every retired route to an unrelated destination.
    7. Clear every layer that can preserve the old behavior. Application caches, page caches, and edge caches can make a removed user-agent rule appear active after the code has changed.
    8. Repeat the comparison after deployment. Confirm that the normal URL now delivers the same substantive answer regardless of crawler identity. Check more than the homepage because these rules are often limited to particular templates or directories.

    Create a small audit record with four fields for each alternate URL: its public purpose, its owner, the authoritative equivalent, and the action you took. That turns a vague AI-optimization experiment into a maintenance decision your content and engineering teams can revisit.

    Key takeaways

    • Do not create a second markdown page merely because an LLM might find it easier to read; normal HTML is already readable by language systems.
    • The extension is not the issue. The issue is a duplicate or crawler-only representation with no genuine user purpose.
    • Expect separate versions to increase crawling and maintenance because a search engine may still fetch the HTML page to compare them.
    • If crawler detection changes substantive content, the implementation can become cloaking rather than optimization.
    • Put the complete answer, clear structure, consistent entities, useful media, and accurate schema on the public page everyone can access.
    • If alternate endpoints already exist, inventory and compare them before consolidating so you do not break a legitimate API, download, or linked resource.

    Start with one representative page, inspect every machine-oriented variant it can produce, and remove the variant whose only purpose is supposed LLM preference. Then spend the saved maintenance effort improving the public answer. One well-structured page that people can read and correct is a stronger foundation than two versions whose differences you must continually police.

    References

  • AI Search Visibility Optimization: An Actionable Framework

    AI Search Visibility Optimization: An Actionable Framework

    If your pages rank in Google but disappear when a buyer asks ChatGPT, Gemini, or Perplexity what to choose, you do not have a conventional ranking problem. You have a chain-of-trust problem. The assistant must be able to reach your information, understand what it means, reconcile it with information elsewhere, and decide that it is relevant and credible enough to use.

    That changes where you should start. Publishing more content or adding AI-related keywords will not repair a blocked crawler, a confused business identity, or conflicting location data. Audit the full path to an AI answer, then fix the earliest point at which your visibility breaks.

    AI visibility is a connected system, not a single ranking

    Traditional rank tracking asks where a page appears for a query. AI search visibility covers several different outcomes: whether an assistant mentions your brand, uses your content, links to your site, states your facts accurately, or recommends you as a suitable choice. A brand can succeed at one outcome and fail at another.

    A practical audit separates the system into these stages:

    • Access: Can retrieval systems and permitted bots reach the important public pages without being blocked by robots rules, authentication, a firewall, or a challenge page?
    • Interpretation: Does each page make the subject, claim, location, product, and relationship between entities explicit?
    • Corroboration: Do your website, business profiles, reviews, and other public records agree on the facts that matter?
    • Selection: Does your information answer the user’s actual task well enough to be cited or recommended?

    The order matters. Better copy cannot compensate for a page that cannot be retrieved. Perfect crawl access cannot resolve two different addresses for the same location. Consistent facts do not guarantee selection when the page never answers the question behind the prompt.

    What you observeLikely bottleneckFirst check
    Important public pages are absent from retrieval or crawler logsAccessRobots rules, authentication, CDN controls, and firewall challenges
    Assistants state an old address, name, or service detailInterpretation or corroborationThe canonical page and every prominent public profile carrying that fact
    Your pages are cited for facts, but your brand is not recommendedConfidence or task fitReputation signals, comparative evidence, and whether the offer fits the prompt
    Google visibility is strong while assistant visibility is weakSelectionA separate prompt-level baseline for each assistant

    Do not label every absence a crawl problem. If an assistant accurately summarizes a page but does not mention your brand, it obtained the information through some path. Your next work belongs farther down the chain, usually in attribution, corroboration, or selection.

    Prove access before you rewrite the content

    A glowing crawler-like orb follows an open route through a cutaway website structure while other routes are blocked by barriers.

    Start with the pages closest to discovery, evaluation, and conversion. These are usually your main service or product pages, location pages, comparison resources, original research, documentation, pricing explanations, and pages that answer recurring pre-sale questions. The goal is not to make every URL equally prominent. It is to ensure that your most useful public information is technically reachable.

    1. Fetch each priority URL without a login. Confirm that the response contains the intended page, not a consent wall, security challenge, empty shell, or error message.
    2. Read robots.txt as a set of instructions. Look for broad disallow rules, overlapping bot-specific directives, and stale rules left by a migration or staging environment.
    3. Inspect controls outside robots.txt. A CDN, web application firewall, rate limit, or bot-management product can reject a request even when the robots file allows it.
    4. Follow redirects to the final page. The destination should remain public, load the substantive content, and identify the stable canonical version of the URL.
    5. Review server and security logs. Look for successful requests, repeated rejections, redirects, and challenge responses associated with the crawlers you intend to permit.
    6. Retest after changing a rule. A configuration edit is not proof that the final URL is reachable through the full delivery stack.

    Refining robots.txt and maintaining a useful llms.txt file can improve the conditions under which AI bots discover your content. The files serve different jobs. Robots.txt communicates crawl permissions. An llms.txt file can act as a concise map to important, canonical resources.

    If you publish llms.txt, keep it selective. Point to pages that explain who you are, what you offer, and where your strongest reference material lives. Remove redirected, duplicated, expired, and thin URLs. Update the file when important destinations change. A stale directory creates another version of your site for machines to reconcile.

    Treat llms.txt as a signpost, not an access-control system or a visibility guarantee. It does not override robots.txt, authentication, firewall rules, or a broken page. It also does not replace ordinary internal links and crawlable site architecture. Do not expose private, administrative, customer, or staging URLs merely to make a crawler test pass.

    Your access audit passes when a priority public URL can be retrieved without credentials, returns the intended substantive content, survives the redirect path, identifies a stable canonical destination, and is not rejected by a rule or security control you meant to allow.

    Make your identity, evidence, and suitability easy to resolve

    Build pages around complete, extractable answers

    An extractable page does not need robotic prose. It needs explicit relationships. A reader and a retrieval system should both be able to identify what the page answers, which entity the answer concerns, where the claim applies, and what supports it.

    • Use a descriptive heading that matches a real question or decision rather than a vague slogan.
    • Name the company, product, service, or location before relying on pronouns such as it, this, or we.
    • Give the direct answer first, then add conditions, exceptions, evidence, and next steps.
    • Keep supporting evidence close to the claim it supports. Do not make a reader hunt through unrelated pages to understand the basis of an important statement.
    • Distinguish facts from positioning. Availability, location, compatibility, and eligibility should not be buried inside promotional language.
    • Use internal links with descriptive anchor text so the relationship between an overview, supporting evidence, and a detailed resource is apparent.
    • Keep structured data, including JSON-LD, aligned with the visible page. Markup should clarify information that users can verify on the page, not introduce a separate set of claims.

    Page structure is especially important when a fact has a limited scope. If a service is available only in a particular region, a feature applies only to one plan, or a result depends on stated conditions, carry that qualifier into the answer itself. A technically accurate sentence can still create a wrong AI answer when its limiting context is several paragraphs away.

    Give every team one record of core business facts

    Create an internal fact sheet for the details that assistants and customers must not get wrong. Include the official brand and location names, canonical URLs, contact details, addresses, operating hours, service areas, categories, and current descriptions of the main products or services. Assign an owner to each field so an operational change has somewhere to go before conflicting versions spread.

    Audit those facts across your own site and the external platforms likely to carry them, including Google Maps, Yelp, and Facebook. Check each location separately. A correct corporate address does not repair an incorrect branch profile, and a correct branch page does not erase stale hours elsewhere.

    Consistency does not require identical marketing copy on every platform. It requires agreement on verifiable facts. Preserve platform-appropriate descriptions, but remove conflicts in identity, location, availability, and contact information. When you find a discrepancy, correct the system that owns the bad record rather than merely publishing another page with the right answer.

    Treat reputation as a confidence signal, not decoration

    AI recommendations are markedly selective in the local context measured by SOCi’s 2026 Local Visibility Index. Across nearly 350,000 locations belonging to 2,751 multi-location brands, ChatGPT recommended 1.2% of locations, Gemini recommended 11%, and Perplexity recommended 7.4%. Brands appeared in Google’s local three-pack 35.9% of the time. The resulting gap ranged from about three to 30 times within that dataset.

    Those percentages describe a particular multi-location sample, not a universal multiplier for every query, industry, or business. They still expose a costly assumption: strong local Google performance is not a dependable proxy for AI recommendations.

    Profile accuracy also differed by assistant in the same dataset. Gemini returned accurate business information in 100% of the measured cases, while ChatGPT and Perplexity reached 68%. That variation is a reason to inspect individual answers and platforms, not to calculate one blended visibility score that hides factual errors.

    Ratings appeared to work more like a confidence filter than a simple ranking boost. Locations recommended by ChatGPT averaged 4.3 stars, with slightly lower averages for Gemini and Perplexity. Do not turn 4.3 into a supposed eligibility threshold; it is an observed average, not a published cutoff. Use it as a prompt to examine the underlying customer experience, recurring complaints, unresolved listing errors, and whether your public reputation supports the recommendation you want an assistant to make.

    Measure mentions, citations, accuracy, and recommendations separately

    A central AI prism connects to four abstract outcomes represented by a presence orb, source link, matching objects, and a selected object passing through a gateway.

    A conventional position report cannot show whether an assistant named your brand, recommended it, cited it, or repeated an incorrect fact. Build a prompt-level measurement set around the tasks your audience actually performs.

    • Discovery prompts: The user is identifying possible approaches, providers, products, or locations.
    • Comparison prompts: The user is weighing alternatives against explicit requirements.
    • Suitability prompts: The user wants to know what fits a particular situation, industry, location, or constraint.
    • Factual prompts: The user needs an address, capability, policy, compatibility detail, operating hour, or other verifiable fact.
    • Branded prompts: The user already knows your name and expects an accurate explanation.
    • Non-branded prompts: The user describes the need without giving the assistant your brand as a hint.

    For every test, record the exact prompt, platform, model or product surface when identifiable, location context, account state, test date, complete answer, cited URLs, brand mentions, recommendation status, and factual errors. Preserve the response itself. AI answers can vary, and a result you did not save cannot be audited later.

    Keep the core metrics separate:

    • Visibility rate: the share of eligible responses that mention your brand.
    • Recommendation rate: the share that present your brand as a suitable option, not merely as background.
    • Citation rate: the share that link to or explicitly identify your owned content.
    • Factual accuracy: whether the material facts stated about your brand are correct and current.
    • Cross-platform consistency: whether different assistants produce materially compatible descriptions of the same entity.

    A single answer is an observation, not a trend. Retest the same prompt set under documented conditions and look for direction across repeated runs. Change a small, named group of inputs, log the change, and then use the same prompts again. Otherwise, you will not know whether an apparent improvement came from your work, answer variability, or a different testing context.

    Keep Google and AI results side by side, but never substitute one for the other. Fewer than half of the brands leading local Google visibility also led their sectors in AI outcomes. In retail, only 45% of the top 20 local-search brands also reached the leading group for AI recommendations. That is dataset-specific evidence for maintaining separate dashboards and separate diagnoses.

    Use the following sequence to turn the audit into work:

    1. Baseline the prompts connected to your highest-value customer decisions.
    2. Resolve access failures on the pages that should answer those prompts.
    3. Correct conflicting identity, location, product, and availability facts.
    4. Rewrite weak pages so the direct answer, scope, evidence, and entity relationships are explicit.
    5. Repair inaccurate external profiles and address the operational causes of recurring negative sentiment.
    6. Retest the same prompt set and classify each remaining failure as an access, interpretation, corroboration, or selection problem.

    Key takeaways

    • Google rankings are useful context, but they do not predict whether an AI assistant will cite or recommend you.
    • Fix the earliest broken stage: access, interpretation, corroboration, or selection.
    • Robots.txt and llms.txt can support discovery, but neither repairs firewall blocks, private pages, weak answers, or conflicting facts.
    • Your site, Google Maps, Yelp, Facebook, and other prominent profiles should agree on verifiable business details.
    • Structured data should reinforce visible content, not create claims that users cannot verify on the page.
    • Measure mentions, recommendations, citations, and factual accuracy separately for each assistant.
    • Review averages from a multi-location dataset are diagnostic context, not universal eligibility thresholds.

    Start with one high-value query cluster rather than a site-wide rewrite. Confirm that its best pages are reachable, align the facts across your public presence, strengthen the direct answers and supporting evidence, and capture a baseline in the assistants your audience uses. That gives you a controlled unit of work and a result you can actually diagnose.

    References

  • How to Diagnose Google Crawling and Indexing Visibility

    How to Diagnose Google Crawling and Indexing Visibility

    An important URL is missing from Google, but Search Console isn’t giving you a clean explanation. Before you resubmit the page, rewrite it, or change sitewide settings, identify exactly where its visibility chain broke.

    The useful question isn’t simply, “Is this page indexed?” You need to know whether Google discovered the URL, whether Googlebot could fetch it, whether the page was eligible for indexing, whether Google selected it for the index, and whether the data you’re reading is current. Those are different conditions with different fixes.

    Google crawling and indexing: key takeaways

    • Crawling, indexing, and ranking are separate stages. Evidence from one stage doesn’t prove that the next stage succeeded.
    • Check the Page Indexing report’s last update before interpreting a change. The report normally trails activity by a few days and can experience longer reporting delays.
    • Diagnose one exact URL from the server response upward: access, robots rules, indexing directives, canonical signals, discovery paths, and Search Console status.
    • Use server logs and Search Console together. Logs tell you whether a request reached your server; Search Console tells you how Google classified the URL.
    • More bot requests do not automatically produce more indexed pages, rankings, referral traffic, or AI visibility.

    Find the broken stage in the visibility chain

    A page doesn’t move directly from publication to search results. It passes through a sequence, and a failure early in that sequence makes later optimization irrelevant. Work through these stages in order.

    • Discovery: Google needs a route to the URL. Internal links and XML sitemaps can provide that route. A URL that exists only in your CMS, an orphaned landing page, or a malformed link may never enter the normal discovery path.
    • Crawl permission: Googlebot must be allowed to request the URL and the resources needed to understand it. Check the applicable robots.txt user-agent group, authentication, firewall rules, CDN controls, and bot-protection settings.
    • Fetch success: Your server must return the intended content reliably. Inspect the response that a crawler receives, not merely what an administrator sees while logged into the CMS. Redirect loops, error responses, empty output, and challenge pages can all interrupt this stage.
    • Index eligibility: The fetched response must not contain an unintended noindex directive. Check both the HTML meta robots tag and the X-Robots-Tag HTTP header. Also verify that the page isn’t presenting a canonical URL that points somewhere else.
    • Index selection: An eligible page is a candidate, not a guaranteed index entry. Google may select another canonical, treat several URLs as duplicates, or decide not to retain the page. Repeated submission doesn’t resolve contradictory page-level signals.
    • Search visibility: Indexing makes a URL eligible to appear; it doesn’t guarantee impressions or rankings. If the URL is indexed, move the investigation to query relevance, content usefulness, internal prominence, competitive strength, and search-result presentation.

    This sequence prevents a common diagnostic mistake: trying to improve content when Googlebot is blocked, or changing crawl settings when the page is already indexed and simply isn’t ranking. Label the failed stage before choosing the intervention.

    Keep robots.txt and noindex conceptually separate. Robots.txt controls crawling. A meta robots or X-Robots-Tag noindex directive controls index eligibility after the directive is fetched. If you block a URL in robots.txt while also relying on a page-level noindex directive, Google may be unable to revisit the page and read that directive. Choose the control that matches the outcome you actually want.

    Audit one URL in an order that preserves the evidence

    An abstract webpage is examined on a digital workbench beside link, server, rendering, selection, and archive components arranged in sequence.

    Start with a specific URL, not a sitewide theory. Record the result of each check before changing anything. If you alter robots rules, canonicals, internal links, and content simultaneously, you lose the ability to tell which condition mattered.

    1. Define the URL that should be visible. Write down its exact protocol, hostname, path, parameters, and expected canonical. Test the final destination rather than a shortened URL, tracking link, or redirecting variant.
    2. Inspect the delivered HTTP response. Confirm that an anonymous request can reach the intended page and receives the expected successful response. Follow redirects and make sure they terminate on the correct URL. Check whether a CDN, consent layer, security product, or login requirement serves different content to automated requests.
    3. Match the URL against robots.txt. Evaluate the rules for Googlebot, including the most specific applicable path. Don’t assume that a rule written for another crawler applies to Googlebot, or that a global rule is harmless because the page loads in your browser.
    4. Read every indexing directive. Inspect the HTML and HTTP headers for noindex or conflicting robots instructions. CMS dashboards can describe an intended setting while plugins, templates, caching layers, or edge rules deliver something different.
    5. Trace the canonical signals. Compare the declared canonical with the final URL, redirects, sitemap entry, internal links, and alternate versions. If those signals nominate different URLs, decide which one should win and align them. A canonical tag isn’t a substitute for a coherent URL policy.
    6. Verify discovery paths. Link the page from an indexable, relevant page using a normal crawlable link. Include the preferred URL in the appropriate XML sitemap. Sitemap inclusion helps discovery and monitoring, but it doesn’t override noindex directives, access failures, or canonical conflicts.
    7. Compare Google’s view with your server evidence. Review the URL-level information available in Search Console, the Page Indexing category, and your server logs. Note whether Googlebot requested the URL, which response it received, and whether Search Console is describing a crawl problem, an indexing directive, a canonical decision, or a reporting state.
    8. Fix the narrowest confirmed cause. Correct the response, rule, directive, canonical, or discovery path that failed. Then use Search Console’s validation or submission workflow where appropriate and wait for new evidence instead of repeatedly changing unrelated parts of the page.

    Run the same checks on a healthy sibling URL that uses the same template. If both URLs fail in the same way, investigate the shared template, plugin, CDN rule, or server configuration. If only one fails, stay focused on its directives, links, canonical target, and content relationship to other URLs.

    The Page Indexing report is designed to show which pages Google can find and index, identify exclusion or error patterns, and let you monitor whether submitted fixes were accepted. That makes it valuable for pattern detection, but it doesn’t replace inspection of the actual response or the logs generated when Googlebot visits.

    Separate stale Search Console data from a real SEO failure

    Search Console reporting is not a live event stream. Before treating a count increase, count decrease, or unchanged category as a new technical problem, read the report’s last-updated date. A fresh deployment and an older report can both be accurate within their own time frames.

    A documented service incident left Page Indexing data delayed for roughly a month. Once it was resolved, report freshness returned to the usual delay of a few days and indexing-issue emails resumed. That history matters because a stale reporting layer can make a successful fix look unprocessed or a new problem look invisible.

    Use this check when the numbers appear frozen:

    • Read the timestamp first. Compare the report’s last update with the publication date, deployment time, and date of your fix. Don’t expect a snapshot that predates the change to confirm it.
    • Check the scope of the lag. Look at unrelated URLs and other Search Console views. If many sections stop advancing at the same date, reporting freshness is a stronger explanation than a simultaneous sitewide indexing failure.
    • Inspect the URL directly. A URL-level inspection can provide evidence that differs from an older aggregate report. Record both results with their dates rather than forcing them into a single conclusion.
    • Read server logs. A recent Googlebot request proves that the request reached your infrastructure, even if an aggregate report hasn’t incorporated it. The status code, redirect destination, response size, and requested resources provide clues about what happened next.
    • Preserve the before-and-after state. Record the directive, canonical, response, report category, and report date at the time of the fix. When the report updates, you can evaluate the change against evidence instead of memory.

    Email alerts are useful prompts, but silence isn’t proof that indexing is healthy. Alerts can be interrupted, and not every URL-level issue becomes an email. Your monitoring process should still include report freshness, representative URL checks, and server-side crawl evidence.

    If the report date is current and Google has recrawled the corrected URL, an unchanged exclusion deserves investigation. If the report predates the fix, wait for a newer snapshot while checking live evidence. That distinction can save you from reverting a correct implementation because the dashboard hadn’t caught up.

    Read bot activity without mistaking it for visibility

    Robotic crawlers send signals into a website structure while a separate gate allows only a few page tiles into an illuminated library.

    Googlebot deserves priority when your immediate goal is Google Search visibility, but raw crawl volume is not a success metric. In Cloudflare’s 2025 traffic measurements, Googlebot generated more than 25% of Verified Bot traffic and 4.5% of all HTML requests, compared with 4.2% for all other AI bots combined. Google also delivered almost 90% of search-engine referral traffic in that data.

    Those figures explain why a Google-specific crawl problem can have a disproportionate visibility cost. They do not mean that every Googlebot request creates an index entry, or that a higher request count improves rankings. A crawler can revisit redirects, error pages, duplicate URLs, resources, or pages that remain excluded.

    Separate Google Search access from access granted to other AI crawlers. AI crawlers were among the user agents most frequently disallowed in robots.txt, while AI user-action crawling grew sharply. Your policy may reasonably differ by crawler and business objective. What matters diagnostically is that an increase from an AI bot doesn’t prove Googlebot access, Google indexing, AI citation, or referral traffic.

    What you observeWhat the evidence supportsWhat to check next
    No Googlebot request appears within your retained log windowYou don’t yet have server-side evidence of a Googlebot visitCheck internal discovery, sitemap inclusion, robots.txt, DNS and CDN access, security rules, and whether log coverage includes the correct host
    Googlebot requests receive redirects, blocked responses, or server errorsGoogle reached the infrastructure, but fetching the intended page failed or took a different pathFollow the complete response chain and correct the redirect, origin, firewall, authentication, or availability problem
    Googlebot receives the intended successful response, but the URL isn’t indexedAt least one fetch succeeded; crawl access alone isn’t the remaining questionInspect noindex directives, X-Robots-Tag headers, canonical selection, duplicate variants, and the Page Indexing reason
    The Page Indexing date is old across unrelated URL groupsThe dashboard may not yet represent recent crawling or fixesUse URL-level inspection and logs while waiting for a newer aggregate snapshot
    The URL is indexed but receives no meaningful impressionsThe investigation has moved beyond basic crawl and index eligibilityEvaluate query alignment, search intent, internal prominence, content usefulness, competing results, and result presentation
    Requests from other AI bots rise while Googlebot activity does notNon-Google crawl activity increasedReview user-agent-specific access rules and measure each visibility surface separately

    Maintain a simple incident ledger for important URL groups. Record the preferred URL, page purpose, HTTP response, robots.txt result, page-level directive, canonical target, discovery path, latest Googlebot request in your retained logs, current Search Console category, report date, and next action. This turns an ambiguous visibility complaint into a set of testable conditions.

    Start with your highest-value missing URL and one healthy peer that uses the same template. Complete the ledger before changing the site. Once a repeatable cause appears, fix it at the narrowest shared layer, validate the delivered output, and then watch for new crawl and indexing evidence.

    References

  • Should You Block AI Crawlers? A Publisher Access Plan

    You’re deciding whether to shut out AI crawlers, but the cost of a mistake is lopsided. Allow too much and you may give away valuable access while absorbing the infrastructure cost. Block too broadly and you may cut off search discovery that still brings readers, customers, and subscribers.

    The workable approach is to stop treating “AI” as one access category. Decide which systems may retrieve which content, for which purpose, under which conditions. Then enforce that policy in layers and measure the result.

    Separate discovery, retrieval, training, and licensing

    A crawler request is a technical event, not a complete explanation of intent. The same public page can have several distinct uses, and your business may benefit from some while rejecting others.

    • Conventional search discovery: A search crawler retrieves a page so the page can be considered for a search index. Access makes discovery possible; it does not guarantee indexing or rankings.
    • Live AI retrieval: A system fetches current information to help answer a user’s request. You may value the resulting visibility, but allowing retrieval does not guarantee a citation or referral visit.
    • Model development: An operator collects content for training or related model-improvement work. This can involve a different value exchange from answering a current query.
    • Licensed access: A publisher deliberately supplies content under agreed technical and commercial terms, potentially through authentication, metering, or a dedicated feed.

    These purposes are strategically separate even when a platform does not give you separate crawler controls. That limitation matters: you can only implement distinctions that the operator exposes and your infrastructure can verify. Where an operator combines purposes, record the exception and make the resulting trade deliberately.

    Key takeaways

    • Preserve conventional search access unless you have consciously decided that its discovery value no longer justifies it.
    • Set policy by crawler identity, declared purpose, and content class rather than using one domain-wide rule for every automated request.
    • Use robots.txt to communicate crawl preferences, but use server-side controls or authentication when access must actually be prevented.
    • Roll out narrow, reversible rules and compare infrastructure savings with changes in discovery, revenue, and AI visibility.

    A blanket block creates an asymmetric business risk

    The volume is large enough to justify active management. Cloudflare reported that, following the July 1 launch of its pay-per-crawl initiative, customers had blocked 416 billion AI-bot requests. That figure demonstrates the scale of crawler demand on participating sites. It does not establish that every blocked request would have harmed a publisher or that blocking is the right default for every site.

    Access is also uneven. Cloudflare argues that publishers cannot cleanly separate Google Search access from Google AI access, and puts Google’s page visibility at 3.2 times OpenAI’s, 4.6 times Microsoft’s, and 4.8 times Anthropic’s or Meta’s. Those are vendor-supplied measurements, so treat the ratios as a directional view of the access imbalance rather than universal traffic benchmarks.

    This is why “block all AI” can be a misleading objective. If the platform connects conventional search crawling with AI use, the technical setting may force a wider business decision than you intended. Before deploying a rule, write down which benefit you are prepared to lose. If the answer is “none of our organic search discovery,” a domain-wide crawler block is too blunt.

    The reverse is also true. “Allow everything for visibility” is not a strategy. An allowed request may generate no referral, citation, subscription, or licensing opportunity. Access should remain open because it serves a defined outcome, not because the crawler includes “AI” in its name.

    Build an access matrix your engineers can enforce

    Turn the policy into a small matrix before touching robots.txt or a firewall rule. Start with four access tiers and assign each content class to one of them.

    Access tierUse it forTechnical defaultBusiness condition
    Open discoveryPublic pages intended for broad distributionAllow verified search crawlers and selected AI access; monitor usageReach and discoverability outweigh reuse concerns
    Search-preservedPublic pages that should remain searchable but are not offered for wider AI collectionAllow conventional search where the operator exposes a separate identity; deny or throttle named AI crawlersThe technical identities can be separated reliably
    Metered or licensedOriginal archives, structured collections, or other material with concentrated reuse valueRequire authentication, rate limits, or a controlled delivery channelAccess is granted under recorded operational and commercial terms
    ClosedSubscriber-only, internal, personal, or otherwise non-public materialRequire authentication and enforce denial at the server or application layerPublic crawler access is unnecessary or inappropriate

    Do not classify the whole site by its most valuable page. A public news story, an evergreen guide, a subscriber archive, an image library, and an internal search endpoint can justify different rules. URL groups make the policy more precise and make mistakes easier to reverse.

    For every crawler-policy combination, record the operator, declared purpose, method used to verify identity, allowed URL groups, rate limit if any, enforcement layer, policy owner, and review date. If you cannot verify the operator or purpose, classify the traffic according to your risk tolerance rather than guessing from a friendly-looking user-agent string.

    Keep the technical policy separate from the legal permission. A crawler being able to retrieve a page does not by itself define the terms under which the content may be reused. If you intend to sell or contractually license access, have appropriate legal counsel establish the rights, attribution, payment, update, termination, and enforcement terms.

    Enforce the policy in layers, not with one bot rule

    Robots.txt is useful for expressing crawl instructions to compliant operators. It is not authentication, and it does not prevent an unidentified or non-compliant client from requesting a public URL. Use the control that matches the consequence of failure.

    1. Capture a baseline. Before changing access, record crawler requests, transferred bytes, cache misses, origin load, requested URL groups, response codes, search crawl health, search traffic, observable AI referrals, and conversions. Note campaigns or publishing spikes that could distort the comparison.
    2. Inventory and verify identities. Group requests by claimed user agent, network identity, paths requested, rate, and behavior. A user-agent string can be copied, so do not approve or block high-impact access solely because a request claims a recognizable name. Use verification information supplied by the relevant operator where it is available.
    3. Publish the intended crawl rules. Add crawler-specific robots.txt instructions only after confirming that the rule preserves the search access you want. Test the deployed file, including rules inherited from broader user-agent groups.
    4. Enforce consequential restrictions upstream. Use your CDN, web application firewall, origin, or application to throttle or deny matching requests. Keep each rule narrow, log its matches, return a consistent response, name an owner, and document the rollback procedure.
    5. Put valuable non-public material behind authentication. Do not rely on robots.txt to protect subscriber content, private files, customer information, unpublished drafts, or licensed datasets. If anonymous visitors can retrieve a URL, an automated client may be able to retrieve it too.
    6. Stage the rollout. Begin with one verified crawler identity or one low-risk URL group. Review false positives and business metrics before extending the rule. This limits the damage if a shared identity, proxy, or overly broad path pattern catches traffic you meant to preserve.

    Blocking only affects requests that reach your controls and match your rules. It does not prove that a model lacks the content, and allowing a crawler does not prove that the content will appear in an answer. Describe the operational outcome accurately: you allowed, throttled, or denied a particular access path.

    Measure whether blocking improved your position

    A successful block is not merely a rising denial count. The useful question is whether the policy improved the exchange between access granted and value received. Review the same scorecard before and after each staged change.

    • Infrastructure: Requests, bandwidth, cache misses, origin work, and load associated with each verified crawler and content class.
    • Search discovery: Crawl errors, accessible pages, index coverage, organic impressions, clicks, and landing-page conversions. Investigate changes that coincide with a rule deployment before expanding it.
    • AI visibility: Observable AI referrals, cited pages found through a consistent sample of relevant prompts, brand mentions, and resulting conversions. Referral logs measure visits, not every unseen citation or model use, so do not treat zero referrals as proof of zero exposure.
    • Content value: Subscriptions, leads, revenue, partnership requests, and licensing discussions associated with the affected material.
    • Policy quality: False positives, unidentified automation, repeated requests against denied paths, operator verification failures, and rules that no longer match your content structure.

    Set the decision rule before examining the result. Retain a restriction when it materially reduces unwanted access or resource use without damaging the outcomes you chose to preserve. Roll it back when search discovery or legitimate partner access declines because the match was too broad. Move valuable, persistent demand toward authenticated or licensed access when the opportunity justifies the operational and legal work.

    Your first action can be small: write one policy sentence for conventional search, one for live AI retrieval, one for model-development access, and one for premium content. Compare those sentences with the controls your platforms actually expose. Where policy and tooling do not line up, start with the narrowest reversible restriction and preserve the baseline you will need to judge it.

    References

  • AI Observability for WordPress: A Practical Setup Guide

    AI Observability for WordPress: A Practical Setup Guide

    You know AI systems are reaching websites, but your WordPress reports may not show which agents requested which pages, what the site returned, or where the collection gaps are. Without that evidence, AI optimization turns into a series of content changes with no reliable feedback loop.

    The useful goal is not a bigger bot-traffic chart. It is an auditable path from an observed request to the corresponding WordPress content item and delivery result. Build that path first, label what it cannot prove, and the data becomes useful for technical fixes and editorial decisions.

    Define what AI observability can actually prove

    An AI agent request is evidence of access. It is not evidence that a model understood the page, retained its information, cited it in an answer, or sent a visitor. That distinction should shape your dashboard before you collect any data.

    Observed signalQuestion it can answerWhat it does not prove
    Agent-labelled requestWas this URL requested by a client presenting this identity?That the identity is authentic or the content entered a model
    Successful deliveryDid the site return the requested resource without a visible delivery error?That the agent parsed, trusted, or retained the content
    Repeated requestsDid the same declared agent family return to the page?That the page gained AI visibility
    Identifiable AI referralDid a human visit arrive with a recognizable referral signal?Which model answer, citation, or passage caused the visit

    Think of observability as four connected layers: access, delivery, content mapping, and outcome measurement. WordPress-side agent analytics is strongest at the first three. Outcome evidence usually comes from a separate visibility, citation, or referral measurement process.

    Keep those layers separate in reports. A page can receive frequent agent requests without appearing in an answer, while a page can influence an answer without producing an identifiable referral. Calling every request an impression or every request increase a visibility gain creates certainty the data does not support.

    Put the collector where your hosting stack can see requests

    Isometric website hosting stack with request paths crossing a glowing collection sensor before reaching server, cache, application, and database layers, while one path bypasses it.

    Raw edge or server logs are a natural place to observe automated requests, but WordPress teams do not always have access to them. Managed hosting can place the relevant delivery layer outside your control, and an external log drain may not be available on the account.

    A WordPress-specific integration gives you another collection point. Profound Agent Analytics, for example, supports WordPress through a custom plugin intended to track crawler and agent interaction even when traditional CDN log drains are unavailable. The same collection model can be relevant to both managed and self-hosted WordPress, although the visible portion of the request path depends on the hosting architecture.

    The important caveat is caching. If an edge cache answers a request before WordPress runs, a collector operating only inside WordPress may never see it. A plugin can therefore be working correctly while still producing an incomplete view. You need to identify that boundary rather than assume every public request passes through the application.

    Trace the request path before installation

    Draw the actual path from an agent to the requested page. Include the edge network, host-level cache, security layer, web server, WordPress runtime, and analytics collector where each applies. Then answer these questions:

    • Which layer receives every public request first?
    • Which layer can serve a cached page without invoking WordPress?
    • Can your team export logs from that upstream layer?
    • Does the collector receive the original request identity, or a rewritten value from a proxy?
    • Which page types bypass the cache and which are normally served from it?
    • Will multiple collectors create duplicate events for the same request?

    This map tells you whether a plugin is your primary collector, a gap-filler, or one part of a combined dataset. It also gives you a precise limitation to disclose in reports: for example, WordPress-executed requests are visible while edge-served requests are not.

    Use an acceptance test, not a successful activation screen

    Plugin activation only proves that WordPress accepted the plugin. Validate the data path with controlled requests before relying on the dashboard:

    1. Request a public page using a clearly marked test user-agent value. Confirm that the event appears with the expected path and observation time.
    2. Request a URL that redirects. Check whether the collector records the requested address, the destination, and the delivery result without merging away useful evidence.
    3. Compare a route known to reach WordPress with one normally served from an upstream cache. If only the first appears, document the cache blind spot.
    4. Check that query parameters do not fragment a single article into misleadingly separate pages. Preserve the raw request for diagnosis, but report against a normalized content identity.
    5. Verify that private, administrative, preview, login, and account routes are excluded or handled under your data policy.
    6. Export a sample. Confirm that the fields required for analysis are available outside the dashboard and that observation times use an understood time zone.

    A synthetic user-agent request tests capture, not bot authenticity. Keep that distinction in the test record so a validation event is never mistaken for genuine agent activity.

    Build an event model that survives WordPress changes

    A connected sequence links an abstract automated request, timing and origin components, a modular content item, a response package, and a stored event while surrounding website modules change position.

    Raw URLs are fragile analytical keys. Slugs change, tracking parameters multiply, redirects accumulate, and the same content may be reachable through several address variants. Map each observed request to a stable WordPress content identity whenever possible.

    A useful event record contains the following fields, subject to what your stack can expose:

    • Observation time and time zone: needed to align requests with publishing, deployments, and access-rule changes.
    • Raw requested path: preserves the evidence required to diagnose malformed URLs, obsolete links, and parameter noise.
    • Normalized or canonical URL: allows equivalent requests to be grouped for reporting.
    • WordPress content identity: connects the request to the post, page, product, archive, attachment, or other content object that produced the response.
    • Content state: distinguishes a current public item from a redirect, missing resource, preview, or restricted route.
    • Declared agent identity: retains both the raw user-agent value and the normalized family assigned by your detection rules.
    • Request method and delivery result: separates ordinary page retrieval from other request types and highlights redirects, missing pages, blocked requests, and server failures.
    • Collection point: identifies whether the event came from WordPress, the server, an edge layer, or another integration.
    • Cache state, when visible: helps explain why similar requests appear in one collector but not another.

    Do not discard the raw path or raw user-agent value after classification. Detection rules evolve, and retaining the original value lets you reclassify historical events without pretending the earlier label was definitive.

    User-agent text is a claim made by the requester, not proof of identity. If your system performs additional verification, store the verification state separately. Useful labels include declared, verified, unverified, and unknown, but only use verified when an actual verification method ran successfully. A polished agent name in a dashboard should not erase that uncertainty.

    Collect only what the analysis needs. Full query strings can contain identifiers or sensitive values, and administrative routes can expose operational details. Normalize or remove unnecessary parameters, restrict access to raw telemetry, and apply the same retention and privacy review you use for other request logs.

    Turn agent requests into technical and editorial decisions

    Agent request volume is an input to investigation, not a content score. A high count may reflect repeated fetching, a loop, URL duplication, or ordinary rediscovery. A low count may reflect an access problem, an upstream visibility gap, or simply limited observed activity. Start with patterns that lead to a decision.

    • Coverage: Compare requested content with the set of public pages you intended to expose. Investigate important sections that never appear, but first rule out cache blind spots and collection failures.
    • Concentration: Group requests by content type, topic cluster, template, and normalized page. This shows where observed attention is concentrated without treating that attention as endorsement.
    • Delivery quality: Find agent requests ending in redirects, missing resources, access denials, or server failures. Fix broken delivery before rewriting the destination page.
    • Duplicate paths: Look for several URLs mapping to the same WordPress item. Consolidate reporting around the canonical identity and inspect why the variants remain discoverable.
    • Recurrence: Separate isolated retrieval from repeated requests over time. Recurrence can justify closer inspection, but it still does not prove citation or model use.
    • Change alignment: Annotate publishing, schema, template, internal-link, and access-rule changes. Compare the same request signals afterward, while treating movement as correlation unless outcome evidence supports a stronger conclusion.

    The operating loop should move from data quality to site quality and only then to content optimization:

    1. Validate that the relevant delivery layers are represented and that agent classifications have not changed unexpectedly.
    2. Resolve delivery failures, redirect chains, duplicate routes, and unintended access restrictions.
    3. Map the remaining requests to WordPress content objects and group them by meaningful editorial dimensions.
    4. Select a content hypothesis tied to a visible pattern. Examples include answering the page’s central question earlier, clarifying entity relationships, improving descriptive headings, updating stale claims, or adding internal links that expose related material.
    5. Make the smallest change that can test the hypothesis, record it as an annotation, and preserve the prior state when practical.
    6. Revisit the same access and delivery signals, then check separate citation, visibility, and referral evidence before claiming an outcome.

    Structured data belongs in this workflow when it accurately describes the visible page. Agent analytics may help you choose which content to inspect, but request counts cannot establish that a schema change caused a model to cite the page. Keep implementation quality and outcome attribution as separate questions.

    Evaluate an AI observability tool against your blind spots

    Choose the tool that fits your request path and decision process, not the one with the longest list of bot names. Ask each provider or internal implementation owner these questions before rollout:

    • Where does collection occur, and which cache or CDN paths bypass it?
    • Will it work on the current WordPress hosting plan if external log drains are unavailable?
    • Does it retain raw request evidence as well as normalized agent labels?
    • How does it distinguish declared identity from verified identity?
    • Can it map URL variants to canonical URLs and stable WordPress content objects?
    • Can you filter by content type, topic, template, delivery result, and collection point?
    • Can raw and aggregated data be exported in a usable format?
    • How are duplicate events handled when several layers observe the same request?
    • What data is stored, who can access it, and how can sensitive parameters or private routes be excluded?
    • What happens to page delivery if the analytics service or plugin integration fails?
    • Does the reporting distinguish requests from citations, visibility, and human referrals?

    A credible tool should make its coverage boundary understandable. If you cannot determine where an event was observed, how an identity was assigned, or which requests are invisible, the resulting precision is mostly cosmetic.

    Key takeaways

    • AI observability starts with a traceable request, not a visibility claim.
    • A WordPress plugin can restore useful request data when CDN log drains are unavailable, but upstream caching may still create gaps.
    • Normalize URLs to stable WordPress content identities while retaining raw evidence for diagnosis and reclassification.
    • Treat user-agent identity as declared unless a separate verification method confirms it.
    • Fix collection and delivery problems before using request patterns to prioritize content work.
    • Measure citations, AI visibility, and referrals separately from crawler or agent access.

    Before changing another page for AI search, trace a controlled request from its entry point to its normalized WordPress record. If the chain breaks, repair the instrumentation first. Once it holds, use the pattern across genuine requests to choose the next technical or editorial change, and reserve outcome claims for outcome evidence.

    References

  • Robots.txt SEO Configuration: A Safe, Testable Setup

    Robots.txt SEO Configuration: A Safe, Testable Setup

    You are looking at robots.txt because crawlers are spending time on the wrong URLs, a migration introduced unfamiliar rules, or someone wants to block a page from search. The risky part is that all three problems can look similar while requiring different controls.

    A good configuration is usually short. It limits crawl waste without hiding pages, resources, or signals that search engines need. Here is how to decide what belongs in the file, write the narrowest workable rules, and test them before they affect valuable content.

    Give each SEO objective the right control

    Three distinct mechanisms regulate a crawler tunnel, protect a private vault, and adjust the visibility of a public page-shaped object.

    The Robots Exclusion Protocol has coordinated crawler access since 1994, but robots.txt still has one primary job: requesting that compliant crawlers avoid particular URL paths. It does not protect content, guarantee deindexing, consolidate duplicates, or redirect visitors.

    That distinction prevents the most damaging configuration error. A crawler can discover a blocked URL through links even though it cannot fetch the page. The URL may therefore remain known to the search engine without its current content being crawled. If you need a crawler to process a noindex directive, canonical tag, redirect, or rendered page, robots.txt must not prevent that fetch.

    What you need to accomplishAppropriate controlWhy
    Reduce requests to a verified crawl trap or low-value URL spaceA narrow robots.txt ruleThe crawler does not need to fetch those matching paths.
    Keep a crawlable page out of search resultsA robots meta noindex directive or equivalent response headerThe crawler must fetch the URL to see and process the indexing instruction.
    Consolidate duplicate pagesConsistent internal links, an appropriate redirect, or a canonical signalBlocking a duplicate can prevent the crawler from seeing the signal intended to consolidate it.
    Protect private, preview, administrative, or staging contentAuthentication and access controlsRobots.txt is public and voluntary; it is not a security boundary.
    Retire a page or move it elsewhereAn appropriate redirect or not-found responseThe response communicates the URL’s actual state instead of merely suppressing crawling.

    Anyone can open /robots.txt. Do not put confidential paths, credentials, internal hostnames, or explanations of sensitive systems in it. A bot that does not honor the protocol can ignore every line. If unauthorized access would create a problem, secure the resource at the server or application layer.

    Build rules from URL evidence, not page labels

    Robots rules match URLs. They do not understand concepts such as “thin content,” “member area,” or “filter page.” Before writing a directive, translate the business label into an exact, observable path pattern.

    1. Inspect actual crawler requests. Use server logs, crawl reports, and your site architecture to identify paths that bots are requesting repeatedly. A large theoretical URL space is not automatically a crawl problem; confirm that crawlers are entering it.
    2. Classify the URLs by desired behavior. Decide whether each group should be crawled and indexed, crawled but not indexed, redirected, removed, or protected. Only the first decision is directly managed through robots.txt.
    3. Find a stable URL boundary. Prefer a dedicated directory or unmistakable prefix over fragments that can also occur in valuable URLs. If the unwanted set cannot be isolated safely, fix URL generation or navigation instead of forcing a broad exclusion.
    4. Collect boundary examples. Include known URLs that should match, known URLs that must remain crawlable, paths with and without trailing slashes, mixed-case variants that actually exist, and representative query strings.
    5. Assign a reason and owner to every rule. Record why it exists, what evidence justified it, and who should review it after migrations or routing changes. Keep confidential operational detail outside the public file.

    Internal search results, sorting paths, faceted navigation, tracking variants, generated calendars, and duplicate utility views can be candidates for crawl restrictions. None should be blocked merely because it belongs to that class. First check whether the URLs receive organic traffic, serve as landing pages, carry useful links, or need to expose indexing and canonical signals.

    Keep the scope of each robots file in view. The file belongs at the root of the origin it governs. A rule on the main host does not automatically control a shop, help center, asset host, or other subdomain. Protocol and port differences can create separate origins as well. Audit the exact locations from which search engines request content rather than assuming one file covers the entire brand.

    Write the smallest configuration that expresses the intent

    A group begins with User-agent and is followed by directives for that crawler or crawler family. Disallow identifies paths you do not want fetched. Allow can preserve a narrower path inside a broader exclusion when the target crawler supports that logic.

    This illustrative configuration asks compatible crawlers to avoid an internal search directory while preserving a useful help path inside it:

    User-agent: *
    Disallow: /search/
    Allow: /search/help/
    Sitemap: https://www.example.com/sitemap.xml

    Do not paste that example into production unchanged. It is safe only if your site’s valuable URLs and routing behavior match the stated intent. In particular, test both /search and /search/. The trailing slash changes what the pattern can match.

    Use separate user-agent groups only when you have a deliberate crawler-specific policy. That may matter when search crawlers, archive crawlers, commercial bots, and AI bots serve different purposes. Keep each group complete and unambiguous, because directive support and group handling are not identical across every crawler.

    Wildcards such as * and end-of-URL matching with $ can express patterns that plain prefixes cannot. They also increase the chance of an unintended match, and support can vary. If a rule depends on either character, verify the syntax for every crawler that matters and test representative URLs through that crawler’s parser or testing facility.

    Keep comments brief and operational. A # comment can document a rule’s purpose, but the public file is the wrong place for sensitive notes. In most configurations, readable path-based rules are easier to audit than dense wildcard expressions.

    Reject these common configurations during review:

    • Disallow: / in a production-wide group. It requests that the affected crawler avoid the whole site. Treat it as a release-blocking change unless complete exclusion is the explicit objective.
    • A noindex instruction placed in robots.txt. Use a supported page-level meta directive or response header and leave the URL crawlable long enough for the crawler to process it.
    • Rules that expose private locations. Remove the path from the public file if secrecy matters, then protect it with authentication or authorization.
    • Broad blocks on scripts, styles, images, or API responses needed for rendering. Search engines may need those resources to understand the visible page. Test rendered output before excluding asset paths.
    • Parameter rules copied from a different URL structure. A generic pattern for filters or sorting can also catch category pages, pagination, campaign landing pages, or other valuable combinations.
    • A robots file copied from staging. Staging should be protected by access controls, while production should have an independently reviewed configuration. Deployment automation must not transfer an environment-wide block accidentally.
    • Crawl-delay treated as a universal throttle. Support is not consistent across crawlers. Verify crawler-specific controls and address server capacity directly instead of assuming one directive will regulate every bot.
    • Rules added solely to “improve crawl budget.” A directive cannot save meaningful requests if crawlers were not visiting the affected space. Establish a log-based baseline and confirm that the change alters the intended behavior.

    Test matching, deployment, and crawler response separately

    A crawler rule is checked in three separate laboratory chambers for path matching, deployment, and crawler response.

    A syntax check is necessary, but it is not enough. A technically valid rule can still block the wrong URLs. Treat the change as a routing change with an explicit test set and a rollback path.

    1. Save the current file. Put the proposed version under version control or otherwise preserve an immediately deployable rollback copy.
    2. Fetch the real endpoint. Confirm that /robots.txt is reachable without authentication from the exact production origin and returns the intended plain-text content. Check each relevant subdomain separately.
    3. Run positive and negative URL tests. Test known blocked URLs, known allowed URLs, boundary cases, trailing-slash variants, letter-case variants that your server recognizes, and URLs containing representative parameters.
    4. Test each important crawler identity. Do not assume a wildcard group behaves identically to a crawler-specific group or that every bot supports the same pattern extensions.
    5. Crawl the site as a user would navigate it. Check that indexable pages, canonical destinations, structured-data resources, images, scripts, and styles remain accessible where search engines need them.
    6. Deploy the narrowest change first. Avoid combining a robots rewrite with unrelated routing, canonical, sitemap, or template changes. Isolation makes an unexpected result easier to diagnose and reverse.
    7. Watch requests and search diagnostics. Compare server logs and crawl reports with the pre-change baseline. Look for reduced requests in the targeted space and any new blocks affecting valuable URLs.

    Do not judge the result from an immediate manual fetch alone. Compliant crawlers can cache robots.txt and revisit known URL spaces on their own schedules. Keep monitoring through subsequent crawl activity, and retain the rollback until the logs show the intended request pattern without losses elsewhere.

    Recheck the file after a redesign, domain migration, subdomain launch, routing change, faceted-navigation update, or content-management migration. Those events can change URL boundaries even when robots.txt itself remains untouched.

    Key takeaways

    • Use robots.txt to manage crawler access, not as a security, removal, redirect, canonicalization, or guaranteed indexing control.
    • Keep pages crawlable when search engines need to process noindex, canonical, redirect, rendering, or structured-data signals.
    • Base exclusions on observed crawler requests and stable URL patterns, then use the narrowest rule that isolates the unwanted space.
    • Treat each origin separately and verify every relevant host, subdomain, protocol, and crawler group.
    • Assume wildcard, end-anchor, exception, and crawl-rate behavior can vary until you confirm support for the target crawler.
    • Test URLs that should match and URLs that must not match, then verify the result in server logs after deployment.

    Start with your current file and a compact set of real URLs. For every directive, write down the crawler, the matching URL space, the desired behavior, and the evidence that the rule is needed. If you cannot do that cleanly, narrow the rule or leave it out until the underlying URL problem is understood.

    References

  • AI Observability Integrations: From Bot Logs to Decisions

    AI Observability Integrations: From Bot Logs to Decisions

    You can have a dashboard full of AI crawler requests and another full of citation results, yet still be unable to answer the question that matters: what should your team change?

    The answer is not another chart. You need an evidence chain that connects agent access, content delivery, AI visibility, and an owned decision. This guide shows you how to design that chain across CDN data, citation analytics, MCP tools, and software development kits without treating correlation as proof.

    Key takeaways

    • Start with a recurring decision, then choose the integrations needed to support it. A connector without a decision is only data movement.
    • CDN and server evidence can show that an identified AI agent requested a URL and received a response. It cannot, by itself, show that the content was indexed, understood, cited, or used to form an answer.
    • Give request data and citation data the same stable content identifier. Raw URLs are too inconsistent to serve as your primary join key.
    • Use MCP for bounded, interactive questions and SDKs for scheduled, repeatable workflows. Both should return the same definitions, filters, freshness information, and failure states.
    • Treat missing telemetry as unknown, not as zero activity. Every dashboard and alert should expose its observation window, coverage, and last successful ingestion time.
    • Keep analytics tools read-only by default. Publishing, crawler-control, and configuration changes need separate permissions and explicit human approval.

    Build an evidence chain before choosing connectors

    Four modular devices representing access, delivery, visibility, and action are connected in sequence on a dark investigation table.

    AI observability becomes useful when it separates four different questions. Combining them into a single visibility score hides the exact failure your team needs to fix.

    Evidence layerQuestion it can answerUseful recordsWhat it cannot prove
    AccessDid an identified or suspected AI agent request the content?Request time, observed URL, agent classification, hostThat the agent retained or understood the content
    DeliveryWhat did your infrastructure return?Response status, redirect target, cache or edge result when availableThat the returned content was eligible for an AI answer
    VisibilityDid your monitored prompts produce a mention or citation?Prompt set, model or surface, market, answer, cited URL, observation timeThat a particular crawler request caused the citation
    ActionWho will respond, and what decision will the evidence change?Owner, trigger condition, runbook, change recordThat the intervention will improve performance

    Write the operational question before you configure any integration. Good questions contain a defined content set, an observation window, a comparison, and a possible action. For example: which priority product pages received identified agent requests but remained absent from our monitored citation set during the same reporting window?

    That question tells you what must be joined. You need a priority-page inventory, normalized request events, citation observations, a shared time convention, and a stable content key. It also tells you what not to collect. If a field cannot filter the question, explain the result, or trigger an action, it does not belong in the first implementation.

    A practical integration map should also name the system of record for every concept. Your CDN can own request evidence. Your visibility platform can own prompt and citation observations. Your content inventory can own canonical identity. Your workflow system can own the resulting task. Do not allow several connectors to redefine the same metric independently.

    Use CDN data as access evidence, not citation evidence

    For websites delivered through Akamai, an Agent Analytics integration can bring AI crawler and bot interactions at the CDN into the observability layer. That moves analysis closer to the point where requests are actually served, which is valuable when application analytics do not provide a dependable view of non-human traffic.

    The important word is access. A request event can establish that your infrastructure observed traffic matching a classification rule. The corresponding response can establish what the infrastructure returned. Neither event tells you whether an AI system indexed the page, incorporated its claims, or cited it later.

    Preserve the raw event and add a reporting identity

    Do not overwrite source fields while cleaning the data. Keep the observed URL and bot identifier, then create normalized reporting fields beside them. This lets you change a classification or canonicalization rule without losing the evidence that produced the original result.

    • Event time: Store a consistent timezone and retain enough precision to diagnose ingestion delays.
    • Observed host and URL: Preserve what was requested before redirects or canonical mapping.
    • Content ID: Map URL variants to a stable identifier owned by your content inventory.
    • Response result: Retain the status and relevant edge outcome supplied by the integration.
    • Agent family: Use a normalized label for reporting while preserving the raw identifier.
    • Classification basis: Record whether identity is verified, claimed, inferred, or unknown.
    • Ingestion metadata: Include the connector, processing time, and schema version so data gaps can be distinguished from traffic gaps.

    A user-agent string is a claim, not conclusive identity. Where a bot operator publishes a verification mechanism and your data supports it, keep verified traffic separate from traffic classified only by its declared name. Do not silently discard ambiguous requests. Put them in an unknown or suspected group so a classifier update does not rewrite history invisibly.

    Define metrics that answer delivery questions

    Keep edge metrics narrow enough that their names remain true. Useful definitions include:

    • Priority-content request coverage: Distinct priority content IDs with at least one qualifying agent request divided by all content IDs in the declared priority set.
    • Accepted-response rate: Qualifying requests that received a response your team has explicitly classified as usable, divided by all qualifying requests. Publish the accepted status rules beside the metric.
    • Request distribution: Qualifying requests grouped by content type, directory, locale, or template.
    • Delivery friction: Qualifying requests returning an error, an unintended redirect, or another response state that your runbook treats as a problem.
    • Telemetry freshness: Time of the latest successfully ingested event compared with the end of the displayed reporting window.

    Keep query parameters only when they change the content you need to analyze. Strip known tracking parameters from the reporting URL, but retain the untouched observed URL under restricted access. This prevents campaign variants from fragmenting page-level coverage while preserving the evidence needed to investigate a mismatch.

    Most importantly, distinguish no observed request from no request. A connector outage, an unsupported property, an excluded hostname, a parsing failure, or a delayed export can all produce an empty chart. Add an ingestion heartbeat and coverage status to the dashboard. If the pipeline is incomplete, display unknown rather than a reassuring zero.

    Choose MCP or an SDK according to the decision path

    Collection is only half the integration problem. The data must reach the person or system making the decision. An MCP server can make visibility reports, bot analytics, and citation data queryable from Claude Desktop and other AI workflows. TypeScript and Python SDKs provide another route for software that needs repeatable access without requiring every user to construct raw API calls.

    These interfaces serve different operating patterns:

    • Use MCP for investigation: An analyst asks a bounded question, examines the result, changes a filter, and decides what to inspect next.
    • Use an SDK for repetition: A scheduled job applies a stable query, validates the response, stores normalized output, and triggers a defined downstream workflow.
    • Use your analytics store for history: Retain the governed data needed for trends and reproducibility rather than expecting a conversational session to become the long-term record.

    MCP should expose small, well-described tools rather than a vague tool that can fetch everything. A tool named for a business question is easier to govern than a generic query endpoint. Its contract should state required inputs, permitted filters, output fields, timezone, freshness behavior, pagination, and known gaps.

    Every response should carry enough context to survive outside the chat where it was requested. Return the observation window, timezone, applied filters, dimensions, last successful ingestion time, classification version, and completeness status with the result. An answer such as “twelve pages were not observed” is unsafe if the recipient cannot tell which property, bot class, page set, or window produced it.

    Apply read-only and least-privilege defaults

    Analytics access can expose private URLs, query values, unpublished content paths, customer identifiers, or internal prompt sets. Minimize that exposure before an AI assistant receives the data.

    • Give each integration only the properties, reports, and fields required for its named use case.
    • Use read-only credentials for investigation tools and keep secrets outside prompts, tool descriptions, and returned records.
    • Redact or aggregate sensitive URL parameters and payload fields before they enter the conversational layer.
    • Log tool name, caller, filters, execution time, result status, and returned record count for later review.
    • Treat text retrieved from pages, answers, and metadata as data, not as instructions that can redefine the assistant’s task.
    • Return explicit permission, timeout, partial-data, and rate-limit errors. Do not convert them into empty results.

    Do not give the same assistant silent permission to change robots controls, publish content, purge caches, or alter production configuration. A mistaken interpretation could affect site availability or discoverability. Put mutating actions behind separate tools, narrower credentials, a preview of the proposed change, and human approval.

    Join access and citations without inventing causality

    Separate cyan request tokens and violet citation nodes meet at a transparent matching surface while an analyst compares the joined evidence.

    The edge event and the AI answer usually do not share a request ID. Join them for analysis through governed dimensions: stable content ID, canonical URL, agent or surface family, locale when available, and aligned observation windows. That produces a useful relationship, but not proof that one particular request caused one particular answer.

    Your content ID is the critical bridge. The same page may appear as an HTTP and HTTPS URL, with tracking parameters, behind redirects, or under several cited URL forms. Keep observed_url, canonical_url, and content_id as separate fields. The first preserves evidence, the second supports URL reporting, and the third gives you a stable entity for longitudinal analysis.

    Observed agent accessObserved citationWhat you can concludeNext investigation
    NoNoYou do not yet know whether the issue is delivery, observation coverage, prompt coverage, or content selection.Validate both pipelines, then inspect delivery rules and whether the page belongs in the monitored prompt set.
    YesNoAccess was observed, but citation was not observed in the declared prompt set and window.Compare the page with cited alternatives, confirm the returned content, and inspect relevance, clarity, and entity alignment.
    NoYesCitation was observed without matching access evidence in the current dataset.Check timing, alternate URLs, cached access, agent classification, hostname coverage, and ingestion gaps.
    YesYesBoth signals were observed. The data still does not establish request-level causation.Inspect consistency, citation context, answer accuracy, and changes across comparable windows.

    Keep referral traffic as a separate downstream signal. A bot request is not a citation, and a citation is not a visit. Combining the three can help you see a pathway from technical access to visibility to site activity, but each transition has its own coverage limits. Label the stages rather than collapsing them into a single number.

    Put the integration into production with a decision-first runbook

    1. Select one recurring decision. Name the person who makes it and the action they may take.
    2. Declare the analysis scope. Record the properties, hostnames, priority content set, agent classes, prompt set, surfaces, locale, timezone, and observation window.
    3. Write the data contract. Define every field, accepted response state, normalization rule, null behavior, freshness expectation, and source of record.
    4. Connect data with read-only access. Start with the smallest permissions and fields that can answer the chosen question.
    5. Reconcile samples. Trace selected records from the originating system through normalization and into the final query. Confirm that redirects, parameter variants, unknown bots, duplicates, and missing fields behave as documented.
    6. Create the shared content key. Map observed and cited URL variants to a stable content ID without deleting their original forms.
    7. Expose one bounded query. Return the result together with scope, freshness, filters, and completeness metadata through MCP or an SDK workflow.
    8. Test failure states. Disable or restrict a test credential, supply an invalid filter, simulate delayed input, and confirm that each problem produces an explicit error or unknown state rather than an empty success.
    9. Attach an action. Give every alert an owner, diagnostic query, safe response, escalation path, and change record.
    10. Review the decision, not just the pipeline. If the output does not change what the owner does, narrow the question or retire the integration.

    A strong first production query is deliberately narrow: show priority content that received qualifying agent activity but had no citation in a specified prompt set, and include the reporting window, data freshness, classification basis, and coverage state. That result gives an SEO or content owner a finite investigation queue without pretending to explain the cause.

    Start there. Once your team can trace a decision from raw event to normalized evidence to an owned action, add another question. That sequence turns integrations into an observability system your team can challenge, maintain, and actually use.

    References