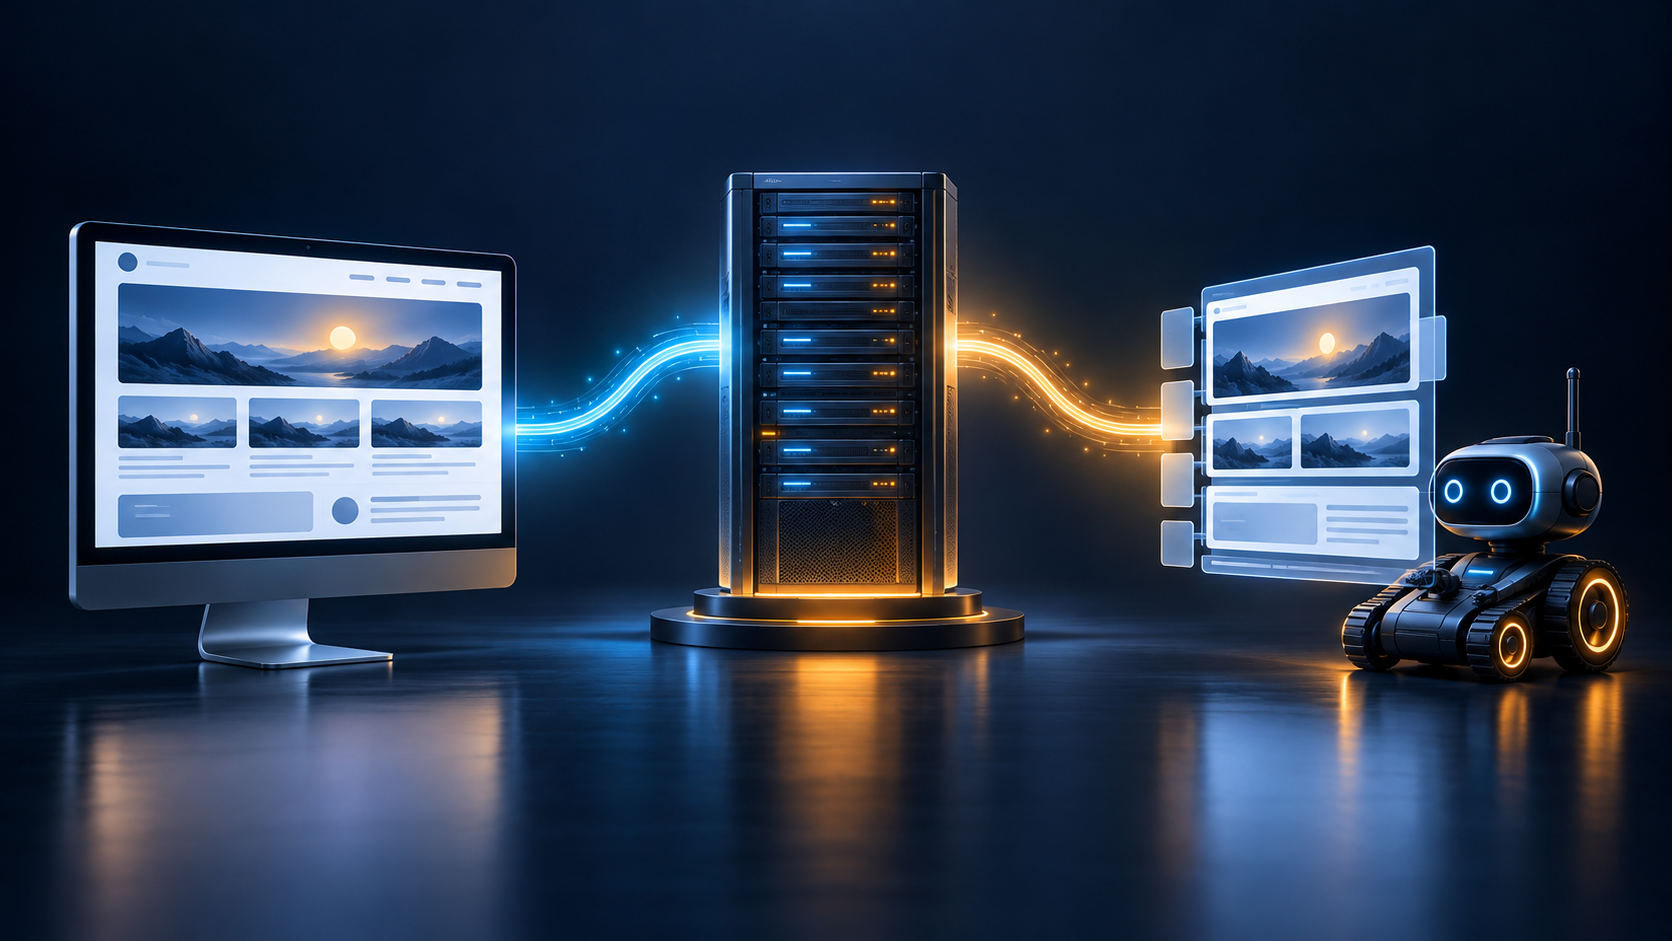
Your page looks complete in a browser, but an AI crawler may receive little more than navigation, placeholders, and script tags. If the information that answers a visitor’s question appears only after JavaScript runs, your content can be published, indexable in theory, and still difficult for a bot to retrieve.
Dynamic rendering can close that delivery gap. It is useful when rendering is the actual problem, however – not as a general cure for weak content, blocked crawling, or poor site architecture. Here is how to decide whether you need it, deploy it without creating two conflicting versions of a page, and verify the response a bot really gets.
Dynamic rendering fixes delivery, not content quality
A JavaScript-heavy page can exist in two materially different states. The initial server response may contain an application shell, while the browser’s final document contains the article, product information, links, and structured data added after scripts run. Human visitors generally judge the final state. A crawler must first be able and willing to perform enough of that client-side work to reach it.
Dynamic bot rendering inserts a delivery layer between the request and the page. It recognizes an AI-bot request and returns a fully rendered version while leaving the normal human experience unchanged. In a typical implementation, the renderer loads the page, allows its required content to resolve, and returns useful HTML rather than requiring the crawler to assemble the page itself.
Think of this as a compatibility layer. It can make existing information easier for a crawler to retrieve, but it cannot make that information accurate, distinctive, or worthy of citation. It also cannot compensate for a request that never reaches the renderer.
- If a crawler is denied by access controls, fix the access decision first.
- If the page is hidden behind authentication, rendering must not be used to expose it publicly.
- If the answer is thin, ambiguous, outdated, or contradicted elsewhere on the site, improve the answer itself.
- If important pages have no crawlable internal links, repair discovery and navigation.
- If the raw response already contains the complete page, another rendering layer may add complexity without solving a real problem.
Dynamic rendering is therefore a technical optimization for a specific failure mode: the public page contains useful information, but the response available to a bot does not reliably carry that information.
Confirm the rendering gap before you deploy anything
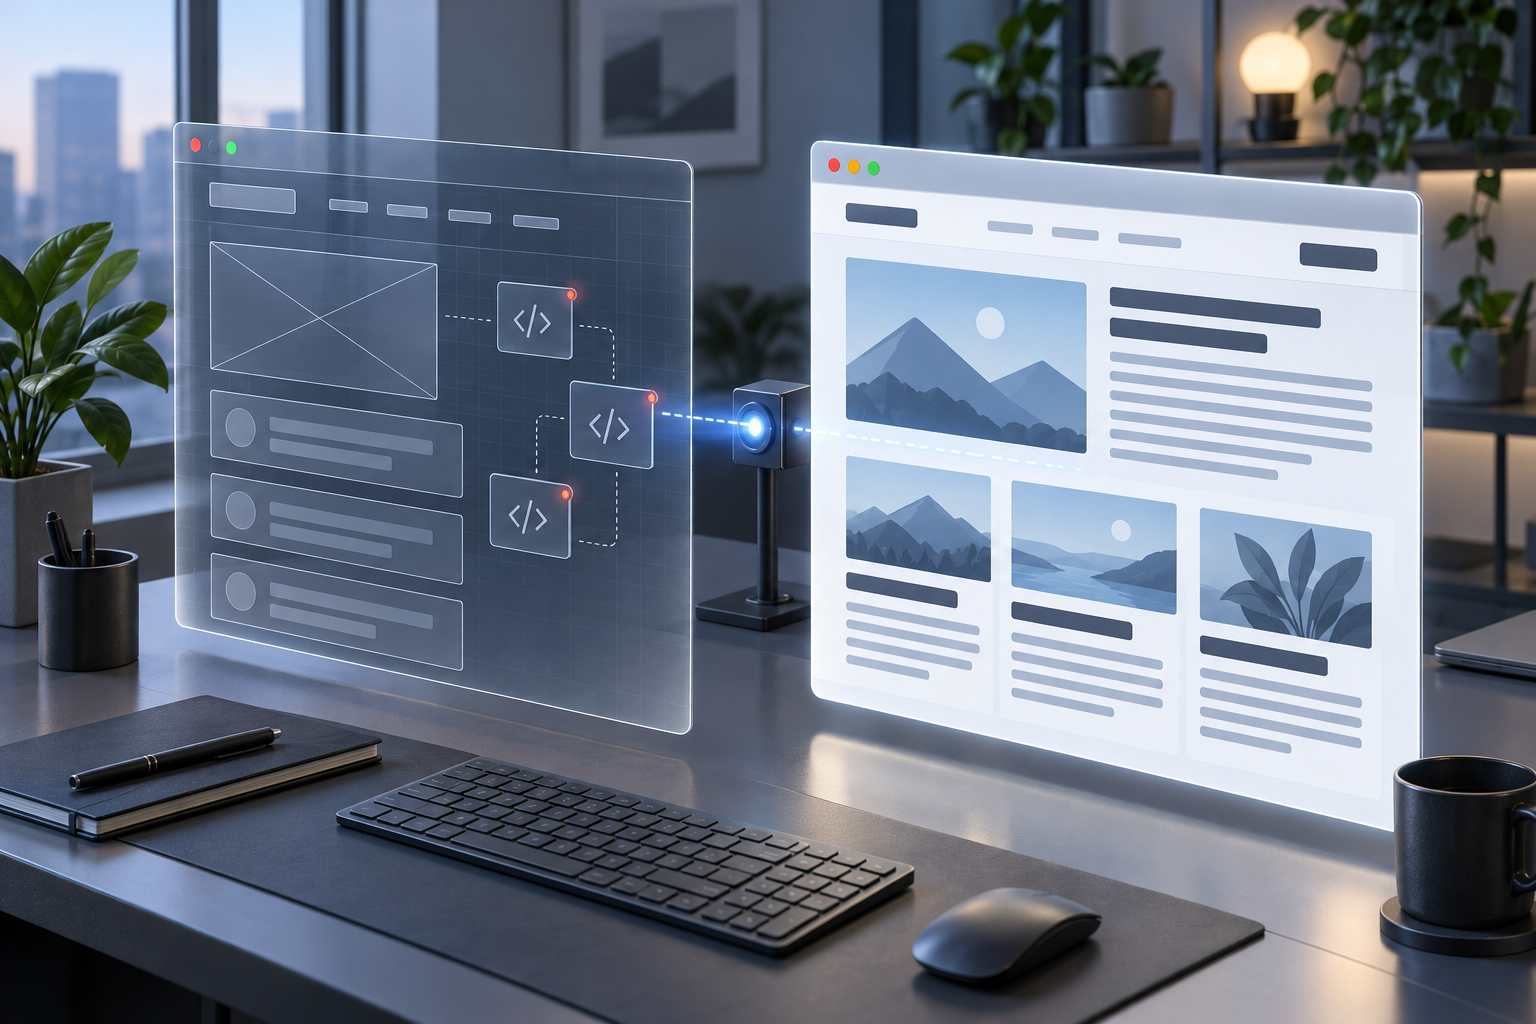
Do not diagnose the page by looking only at it in a normal browser. The browser’s developer tools usually show the document after scripts have modified it. You also need to inspect the original response body – the HTML returned before client-side rendering – because that is the safer baseline for crawler accessibility.
Run the diagnosis across representative templates, not just the homepage. An article, category page, product page, comparison page, and documentation page can use different rendering paths even when they share the same design system.
- Choose a small set of public URLs that represent your highest-value templates and common edge cases.
- Open each page normally and record the primary answer, headings, factual details, internal links, title, canonical URL, robots directives, and structured data present after the page finishes loading.
- Inspect the original response or fetch the URL with a simple HTTP client that does not execute JavaScript.
- Compare meaning, not appearance. The raw HTML does not need the browser’s styling or interactive behavior, but it should contain the substantive information a crawler needs.
- Check whether the request is redirected, challenged, denied, rate-limited, or served an error. Those are access and reliability problems, not rendering problems.
- Repeat the check on pages with different publication states, content lengths, and data dependencies so that one unusually simple URL does not produce a false sense of coverage.
| What you observe | Likely diagnosis | Best next move |
|---|---|---|
| The original HTML contains the main answer, links, metadata, and relevant structured data. | No material rendering gap on that template. | Do not add bot rendering solely because the site uses JavaScript. Investigate content, discovery, or access issues instead. |
| The complete content appears in the browser but is absent from the original HTML. | Client-side rendering is carrying essential information. | Evaluate server rendering, build-time generation, or dynamic bot rendering. |
| The request receives a denial, challenge, redirect loop, or error. | The crawler cannot reliably reach the page. | Correct the firewall, routing, crawl-control, or reliability problem before changing rendering. |
| The HTML is complete, but important pages are difficult to reach through ordinary links. | Discovery and site architecture are the constraint. | Add crawlable internal links and clarify the relationship among pages. |
| The public page changes by login, session, or customer account. | There is a privacy and response-segmentation risk. | Define a safe public representation. Never render authenticated or customer-specific data into a bot response. |
If the raw HTML is incomplete, consider whether the site can provide the same complete server-rendered response to everyone. A universal server-rendered or statically generated baseline is usually easier to reason about because it removes bot classification and response variance. Dynamic rendering is most defensible when replacing the front-end rendering model is impractical, the human experience must remain unchanged, and the missing-content problem is concentrated in requests from known crawlers.
Build one semantic page, even when you serve two response forms
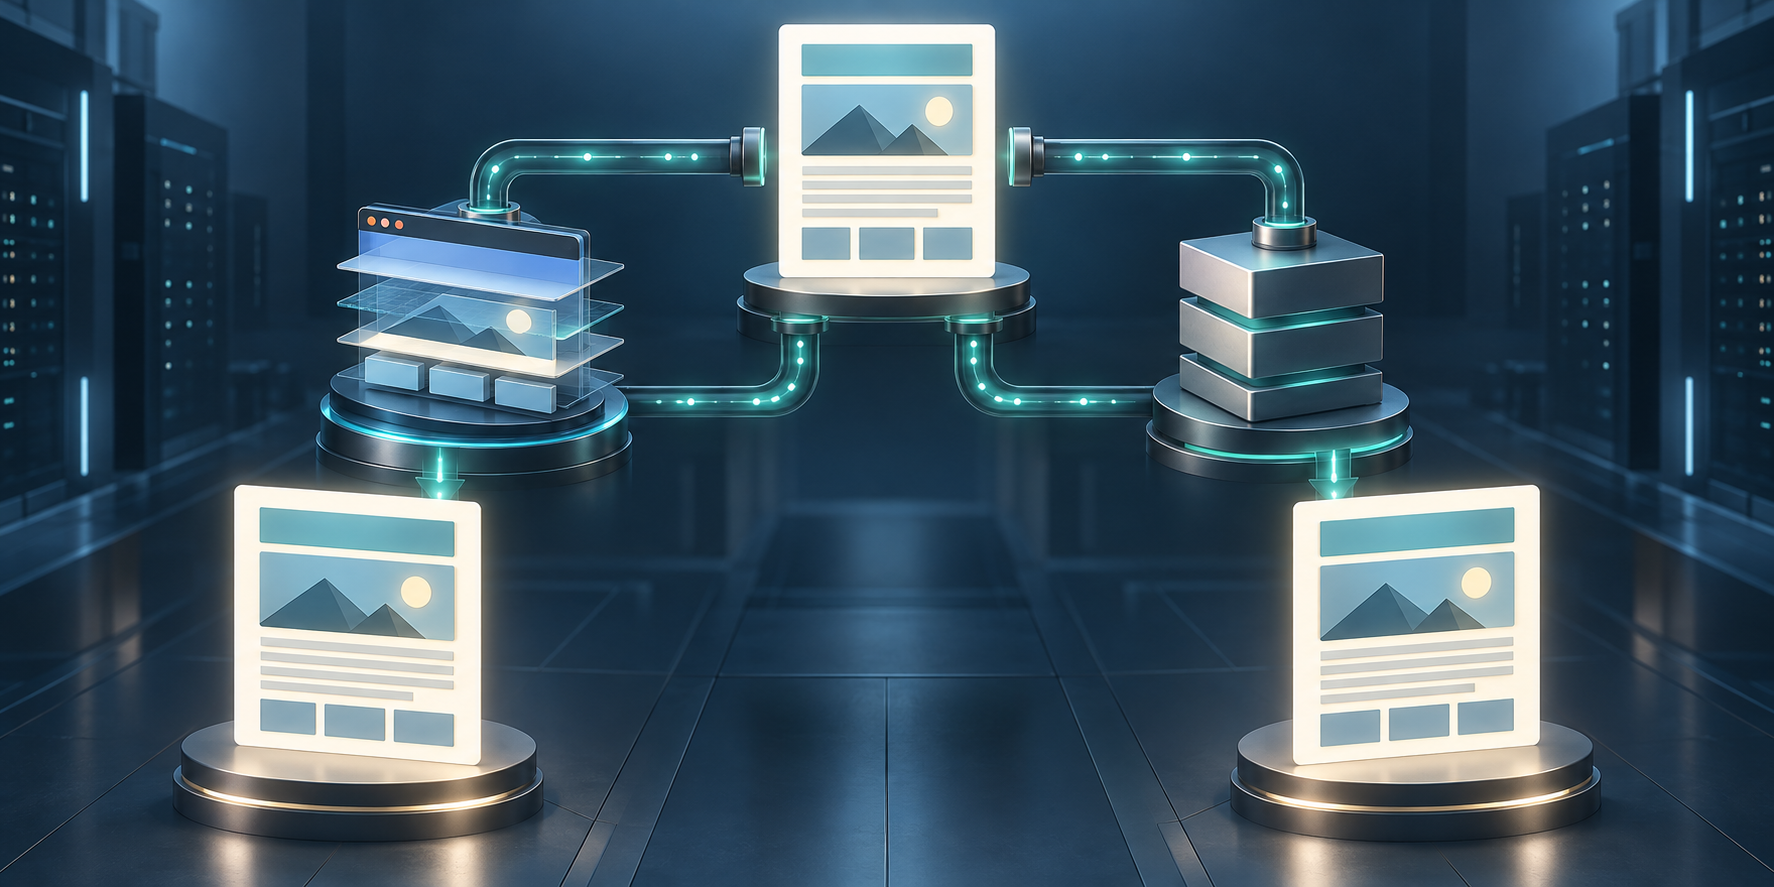
The human and bot responses do not need identical markup. They do need to make the same substantive claims. Dynamic rendering becomes fragile when it evolves into a separate editorial surface with its own copy, offers, facts, or navigation.
Set a parity contract before implementation. For any canonical URL, the two response paths should agree on:
- The primary topic, answer, factual claims, qualifications, and visible supporting information.
- The page title, canonical URL, language, and crawl directives.
- The destination and meaning of important internal links.
- The availability state of products, services, downloads, or other resources.
- The structured data entities and properties, which should describe information a visitor can also find on the page.
- The publication or update state of the content.
- The intended HTTP outcome, including equivalent redirects and not-found behavior.
Do not require byte-for-byte equality. A bot response may omit decorative animation, interactive controls, personalization, analytics code, or browser-only application state. The useful test is semantic parity: would a person reading either version reach the same factual understanding of the page?
Keep bot detection narrow and auditable
An AI bot is not a single technical client. Different crawlers can identify themselves differently and can change their request behavior. Treat detection rules as maintained configuration, not as a one-time switch.
- Start with crawler identities you deliberately intend to support.
- Document what sends a request down the rendered path and who owns updates to that logic.
- Log the classification decision so that you can explain why a particular response was served.
- Do not classify every unfamiliar client as an AI bot. Overbroad matching can create unexpected cache, security, and debugging behavior.
- Keep access policy separate from rendering policy. Permission to crawl and the format of the response are related decisions, but they are not the same decision.
Design the cache around response variants
Caching is where a sound rendering design can fail operationally. If an edge cache does not distinguish the applicable response paths, a human may receive the bot snapshot or a crawler may receive the JavaScript shell. The renderer can also serve stale facts if its cache remains valid after the underlying page changes.
- Make the response variant part of the cache decision wherever the rendered and normal outputs differ.
- Use the same canonical URL rather than creating a separate public bot URL.
- Connect cache invalidation to the events that publish, update, unpublish, or materially change a page.
- Never cache authenticated, session-specific, or customer-specific output as a public bot response.
- Define a safe fallback for rendering failures and record when it is used. A silent fallback to an empty application shell can make the system appear healthy while the original problem returns.
Roll out by template, not across the entire domain at once
A staged release makes content differences and infrastructure mistakes easier to isolate. Choose one valuable template with a confirmed rendering gap, then expand only after its ordinary and rendered responses remain aligned through real content updates.
- Save baseline responses for both the normal route and the proposed bot route.
- Enable rendering for a controlled group of URLs from one template.
- Verify content parity, status behavior, metadata, structured data, internal links, freshness, and the absence of private data.
- Publish and edit pages in that group to confirm that rendered responses update with the source content.
- Inspect logs for misclassification, rendering failures, redirect problems, and unexpected fallback use.
- Expand to the next template only after the first one remains stable under normal editorial changes.
This sequence also tells you whether dynamic rendering is becoming an unmanageable second publishing system. If every template needs separate copy rules and manual exceptions, the site may be better served by changing its underlying rendering architecture.
Test the bot response and measure the problem you meant to solve
A successful render is not merely a request that returns a page. It is a request that returns the correct public page, with the required information, at the expected URL, while remaining current and operationally reliable.
Use your rendering system’s preview or a controlled request that matches a configured crawler identity. Then inspect the returned body without allowing another round of client-side rendering to hide omissions. For each representative URL, verify:
- The main answer and its necessary context are present in the returned HTML.
- Headings, lists, tables, definitions, product facts, and other meaningful page elements are represented as text rather than empty placeholders.
- Important internal links use ordinary destinations that can be extracted from the response.
- The title, canonical URL, robots directives, and structured data correspond to the human page.
- Redirected, removed, and unavailable pages retain their intended status behavior.
- Newly published or edited information appears after the expected cache update.
- No account data, session information, unpublished material, or administrative content is present.
- The response remains understandable without executing additional JavaScript.
Automate the stable parts of this check. A regression test can request both variants and assert that required content fields, canonical values, directives, links, and structured data entities exist in each. Do not reduce parity to a complete HTML diff; implementation markup can legitimately differ and generate noise. Test the content and signals that must remain equivalent.
Measure delivery before visibility. Rendering logs should tell you which eligible requests used the rendered route, whether the render completed, whether a cached or fallback response was served, and which URLs repeatedly failed. Content checks should tell you whether required information was present and fresh. These are direct indicators that the implementation is doing its job.
AI visibility is a downstream outcome with more variables. Monitor crawl activity, discoverability, attributable referrals where available, and inclusion in the AI experiences important to your audience, but do not treat every later citation or ranking change as proof that rendering caused it. Content quality, authority, relevance, internal discovery, access rules, and the external system’s own behavior remain part of the result.
Key takeaways
- Use dynamic rendering only after confirming that essential public content is present in the browser but missing from the original HTML response.
- Fix denials, authentication barriers, broken routing, weak internal links, and poor content at their own layer; rendering does not solve them.
- Keep human and bot responses semantically equivalent, including factual claims, metadata, canonical signals, links, structured data, and content freshness.
- Separate cache variants carefully and never expose authenticated or personalized information through the bot-rendered path.
- Release one template at a time, automate parity checks, and judge the implementation first by complete, current, reliable delivery.
Start with one representative URL today. Compare its original response with the completed browser page and name the missing information precisely. If the gap is real, you now have a testable requirement for dynamic rendering. If it is not, you have avoided adding infrastructure that would have addressed the wrong problem.
References

Leave a Reply