Tag: Bot Detection

  • AI Media-Buying Guardrails: A Practical Control Framework

    AI Media-Buying Guardrails: A Practical Control Framework

    If your AI buying agent can raise bids, move budget, or scale a traffic source, an overspend is not the only failure you need to prevent. The agent can remain inside its budget and still fund low-quality traffic, follow a compromised redirect, or optimize against context that stopped being true weeks ago.

    The safe design is a chain of evidence: trusted inputs, current security signals, explicit permissions, a reversible action, and a decision record. Build that chain before granting autonomy and you can use AI for speed without letting a superficially attractive metric become an instruction to make an expensive mistake.

    A budget limit cannot tell the agent what to trust

    A spend ceiling answers one question: how much money may move. It does not answer whether the evidence behind that move is complete, current, or safe.

    Suppose the agent is instructed to lower cost per acquisition while remaining under a campaign cap. It finds a traffic source with cheap reported conversions and reallocates spend toward it. From the performance dashboard, that can look correct. Upstream, however, traffic-quality anomalies, changed landing-page behavior, or a questionable redirect may be telling a different story. A budget rule does nothing to reconcile those signals.

    This is the central control problem in agentic media buying: the system will normally optimize the objective and evidence you expose to it. If safety evidence lives in a separate dashboard, arrives after optimization, or has no authority to block an action, it is not a guardrail. It is an after-the-fact report.

    Ad buyers already recognize that autonomy needs more than a campaign cap. In IAB’s July 2026 Digital Video report, 40% of buyers wanted humans in the loop, 36% wanted an explainable audit trail, and 31% wanted explicit limits on agent actions. Those controls are useful, but they need to operate together. A tightly limited agent can still repeat a bad decision if its context is stale or its risk signals are missing.

    Before automation, require the workflow to answer four questions in order:

    1. Are the required inputs present, current, and structurally valid?
    2. Do traffic-quality or security signals require a hold or stop?
    3. Does performance evidence justify the proposed change?
    4. Is that exact change inside the agent’s permission envelope?

    If any answer is unknown, the default should be no scale. Unknown is not the same state as safe.

    Key takeaways

    • Make security and traffic quality hard inputs to optimization, not reports reviewed after spend has moved.
    • Give every input an owner, freshness rule, version, and position in the conflict hierarchy.
    • Separate permission to recommend an action from permission to execute it.
    • Send humans ambiguous, novel, or high-impact cases instead of routing every routine bid adjustment through manual approval.
    • Snapshot the context behind every material decision so you can reconstruct what the agent knew and what it was allowed to do.
    • Revalidate the workflow whenever a tool, landing page, data schema, policy, template, or business rule changes.

    Turn the prompt into a context contract
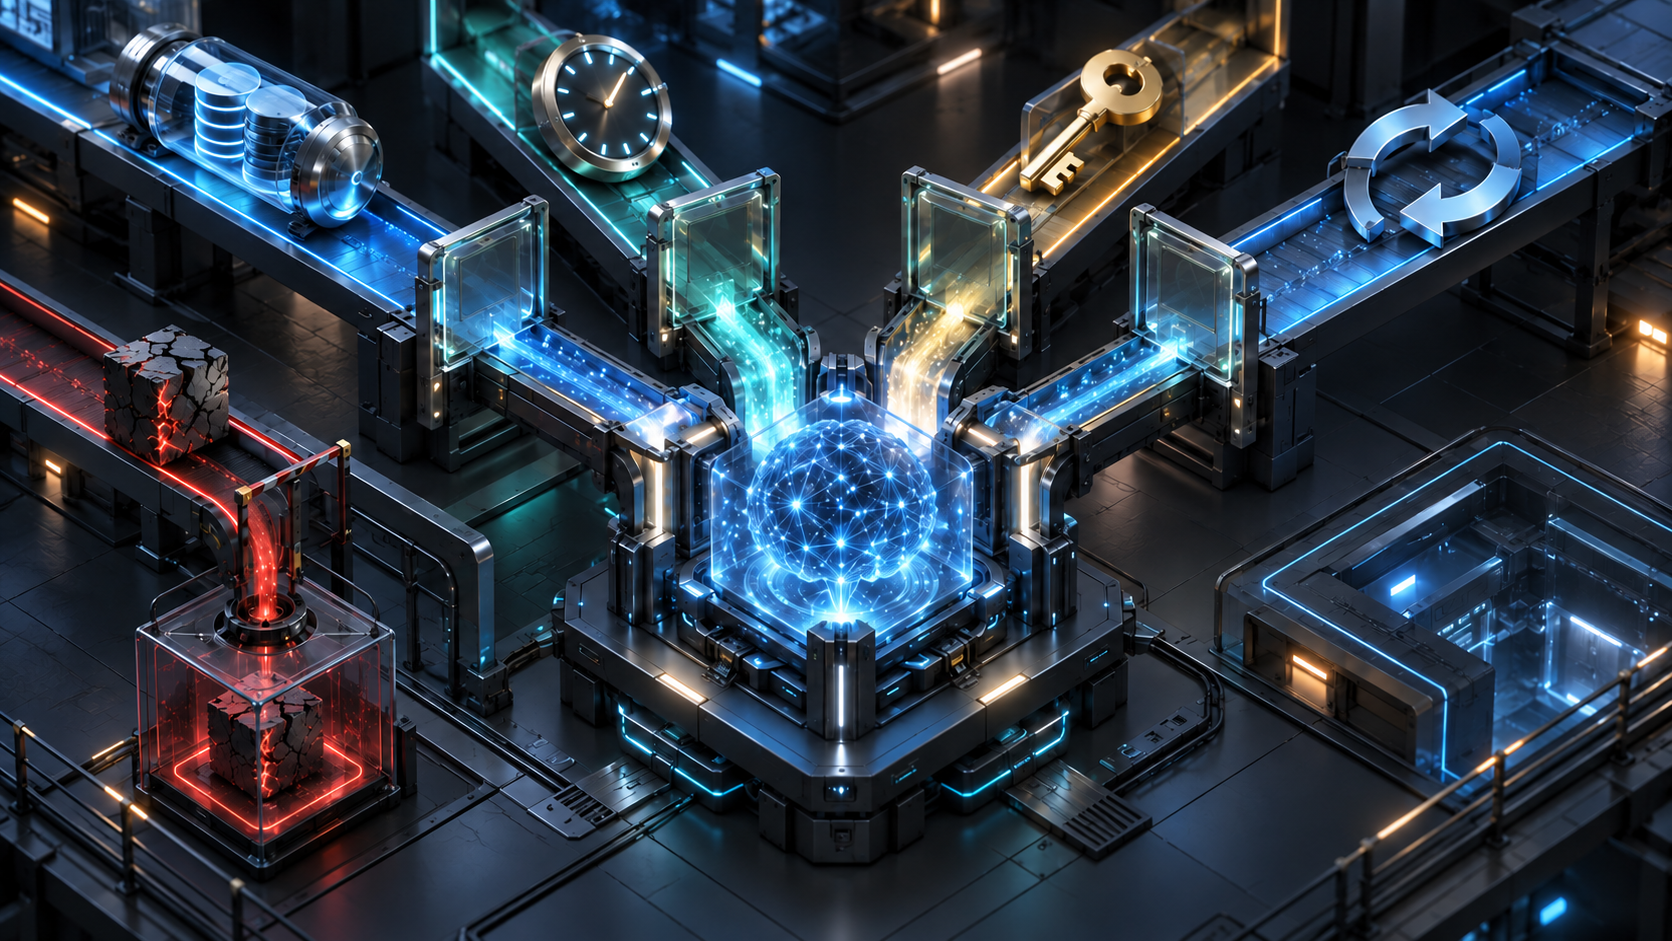
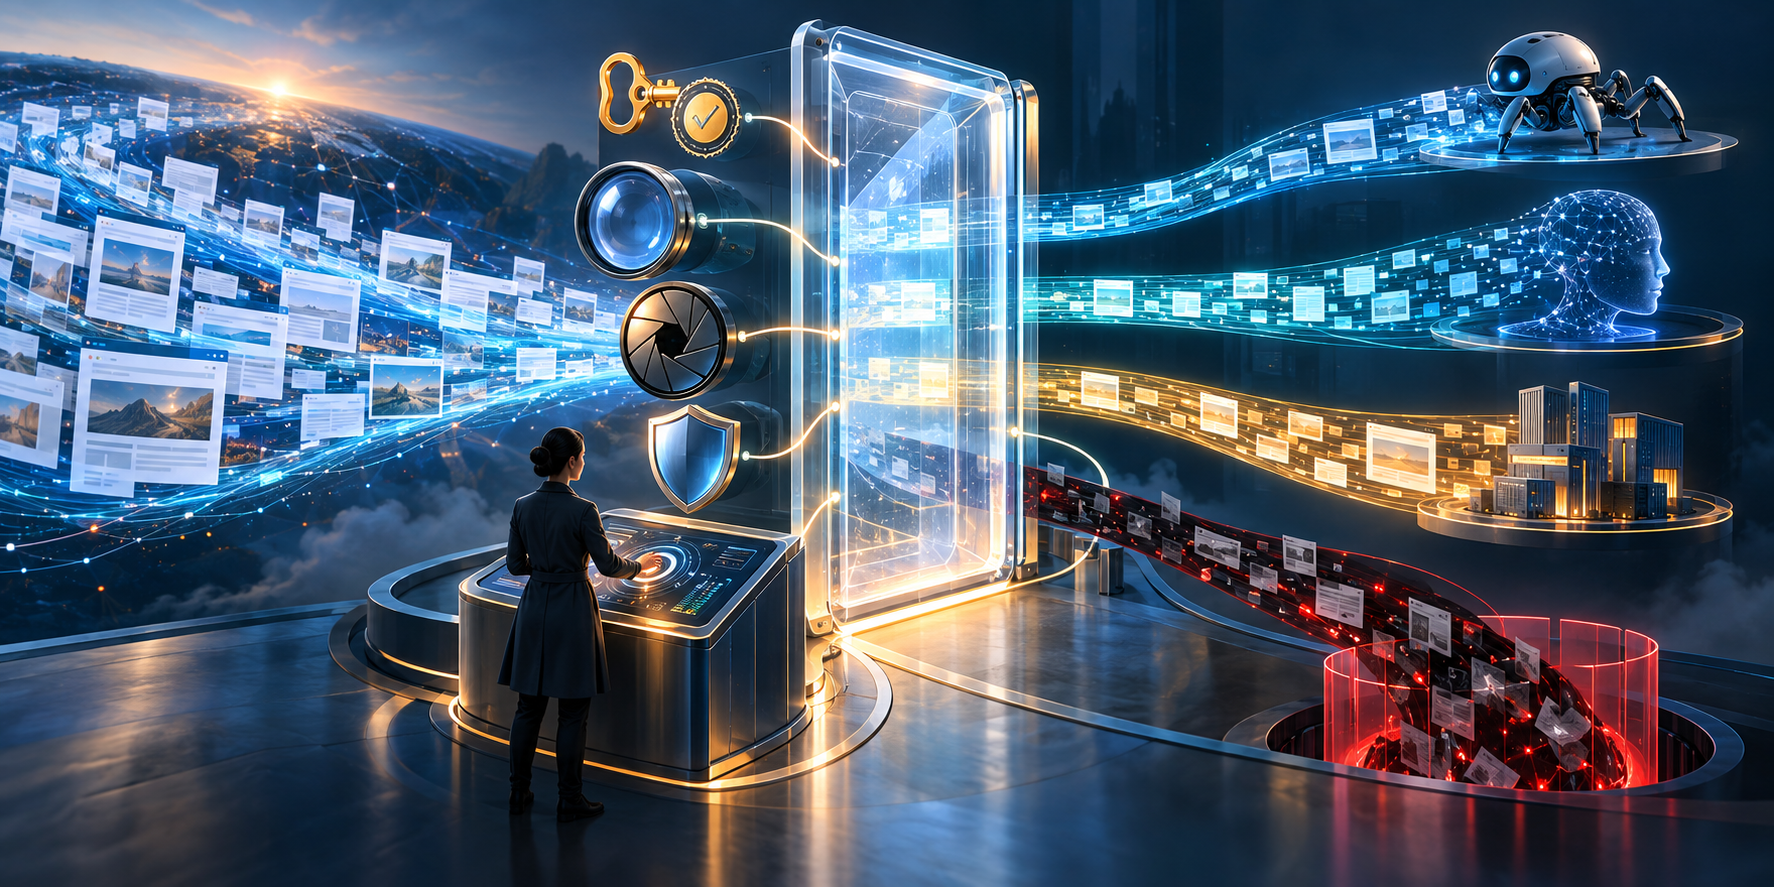
    Four validated input channels converge on a glowing AI core while a cracked stale input is diverted into a separate quarantine chamber.

    A prompt is only one part of an AI workflow’s operating context. The model may also read project knowledge, memory, skill instructions, attached files, tool results, earlier stages, and prior conversation turns. Some of that material can load without the operator selecting it for the current decision. Managing that full operating context is therefore a control function, not a prompt-writing exercise.

    Write a context contract for each decision-making workflow. It should specify:

    • Objective: Name the metric, reporting window, conversion definition, and business outcome. Do not leave the agent to choose among several plausible definitions of efficiency.
    • Trusted inputs: List the approved performance, traffic-quality, security, destination, inventory, and policy feeds. Assign an owner and version to each one.
    • Freshness: Define when each input becomes too old to authorize action. A stale security result must not be treated as a current clearance.
    • Precedence: State which system wins when two tools disagree. If two platforms calculate a metric differently, the agent should not switch between them from one run to the next.
    • Required fields: Declare the identifiers, timestamps, measurement periods, risk states, and data-quality flags that must be present. Reject incomplete payloads instead of asking the model to fill the gaps.
    • Permission envelope: Separate read, recommend, pause, bid, budget, source, creative, and destination permissions. Scope them by account, campaign, channel, and action type.
    • Stop conditions: Identify alerts that block action regardless of performance. Include the safe fallback: hold, pause, revert, or escalate.
    • Conflict behavior: Tell the workflow what to do when a performance signal and a risk signal point in opposite directions. The agent should not be allowed to improvise which one matters more.
    • Handoff format: Define what one stage may pass to the next, how facts differ from inferences, and how missing evidence is represented.
    • Audit requirements: List the context versions, inputs, reasons, permissions, actions, and human interventions that must be recorded.

    Make these controls machine-checkable wherever possible. A sentence that says to use recent data is weaker than a freshness field the workflow must validate. A paragraph asking the model to be cautious is weaker than a permission service that rejects an unauthorized budget change.

    Pay particular attention to stage handoffs. An extraction step might pass a traffic-source ID, landing URL, observation time, conversion window, quality status, and missing-field list to an analysis step. The analysis step should accept that defined payload, not the extraction step’s entire working history. This keeps irrelevant material out and prevents a summary or inference from silently acquiring the authority of a verified fact.

    Apply the same discipline to long-running conversations. If an agent evaluates several campaigns in one thread, earlier campaign details can remain available to later decisions. Start a clean decision context for each campaign or bounded batch, then attach only the approved context snapshot. Conversation history is convenient memory; it is not a reliable control database.

    Put security, performance, and escalation in one loop

    Evaluate evidence in a fixed order

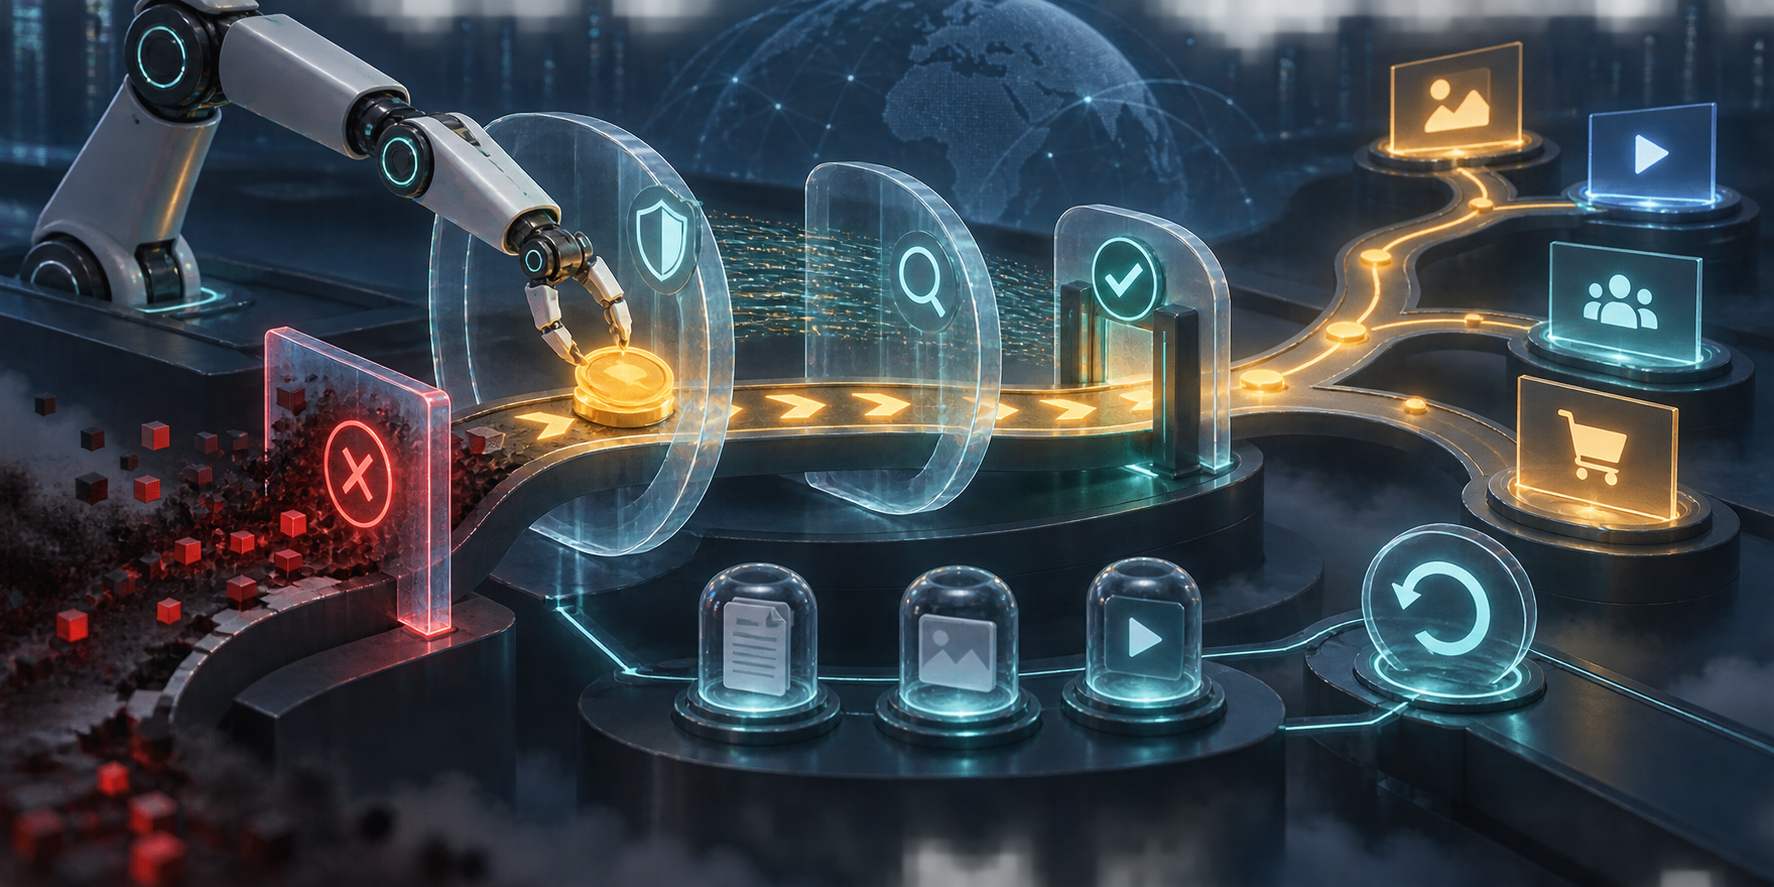
    Do not ask the agent to weigh every signal in one undifferentiated prompt. Use deterministic gates around the model and evaluate them in a fixed sequence:

    1. Evidence gate: Confirm that required feeds arrived, their schemas match expectations, their timestamps pass freshness rules, and campaign identifiers agree.
    2. Integrity gate: Check malware, traffic-quality, redirect, destination, cloaking, policy, and other applicable risk states.
    3. Performance gate: Evaluate the proposed action against the campaign objective only after integrity checks pass.
    4. Authority gate: Verify that the account, campaign, action type, and size of change fall inside the agent’s current permissions.
    5. Execution gate: Record the decision and rollback point, execute once, and confirm that the advertising platform accepted the intended change.

    This ordering matters. If performance is evaluated first, a strong result can anchor the rest of the reasoning and turn a risk alert into something the workflow tries to explain away. Security should be able to veto scale even when the cost per acquisition looks excellent.

    Decision stateTypical evidenceAgent responseHuman role
    GreenRequired inputs are current, schema checks pass, no active risk alert exists, performance supports the change, and the action is permitted.Execute the bounded action, verify the platform response, and log the full decision record.Review sampled decisions and aggregate behavior, not every routine action.
    AmberA mild anomaly, changed landing behavior, new redirect, incomplete evidence, or conflicting systems makes the result uncertain.Do not scale. Hold the proposed change, collect more evidence, or continue at the existing state if that is the approved safe fallback.Resolve the conflict, approve one action, or amend the governing rule with an owner and version.
    RedA high-confidence malware or security alert, invalid destination, missing mandatory input, failed execution check, or request outside the permission envelope.Block the action and invoke the defined pause or rollback procedure.Investigate the incident and explicitly authorize any restart.

    Run integrity checks throughout the campaign lifecycle, not only at approval. Destination behavior can change after launch, and cloaked content may vary by location, device, visitor profile, or inspection time. One clean observation is not permanent clearance.

    Platform-specific evidence illustrates why the checks must remain continuous. In PropellerAds’ own Q2 2026 moderation data, total rejected campaigns fell from 36,085 to 20,790 quarter over quarter, while the share attributed to antivirus and malware issues rose from 23.3% to 45.9% and the absolute number increased by roughly 14%. That is not a market-wide malware measure, but it demonstrates the operational point: an improving top-line count can coexist with a worsening risk category. A single aggregate metric cannot clear traffic for autonomous scale.

    Route ambiguity to people, not routine volume

    Human review works best where judgment changes the answer. Requiring approval for every bid adjustment removes much of the value of automation and trains reviewers to click through repetitive requests. Instead, trigger review when:

    • risk and performance signals conflict;
    • a required input is missing, stale, or supplied in an unexpected format;
    • the landing page, redirect chain, domain, conversion definition, or measurement setup changes;
    • the proposed action is outside the permission envelope;
    • two approved tools disagree and the precedence rule does not resolve the difference;
    • the agent encounters a new anomaly that is not represented in the runbook;
    • a hard-stop alert fires or an automated action needs to be reversed;
    • repeated small actions produce a material cumulative change that requires a higher level of authority.

    Give the reviewer a compact decision bundle: the proposed change, expected effect, measurement window, input timestamps, security state, conflicting evidence, applicable permission, safe fallback, and rollback option. Do not send a generic request to check the campaign. The person should be able to see why the case was escalated and which decision is required.

    Make escalation timeouts safe. If the reviewer does not respond, the workflow should preserve the approved state or pause according to the runbook. Silence must never become permission to scale.

    Test for context rot before granting more authority
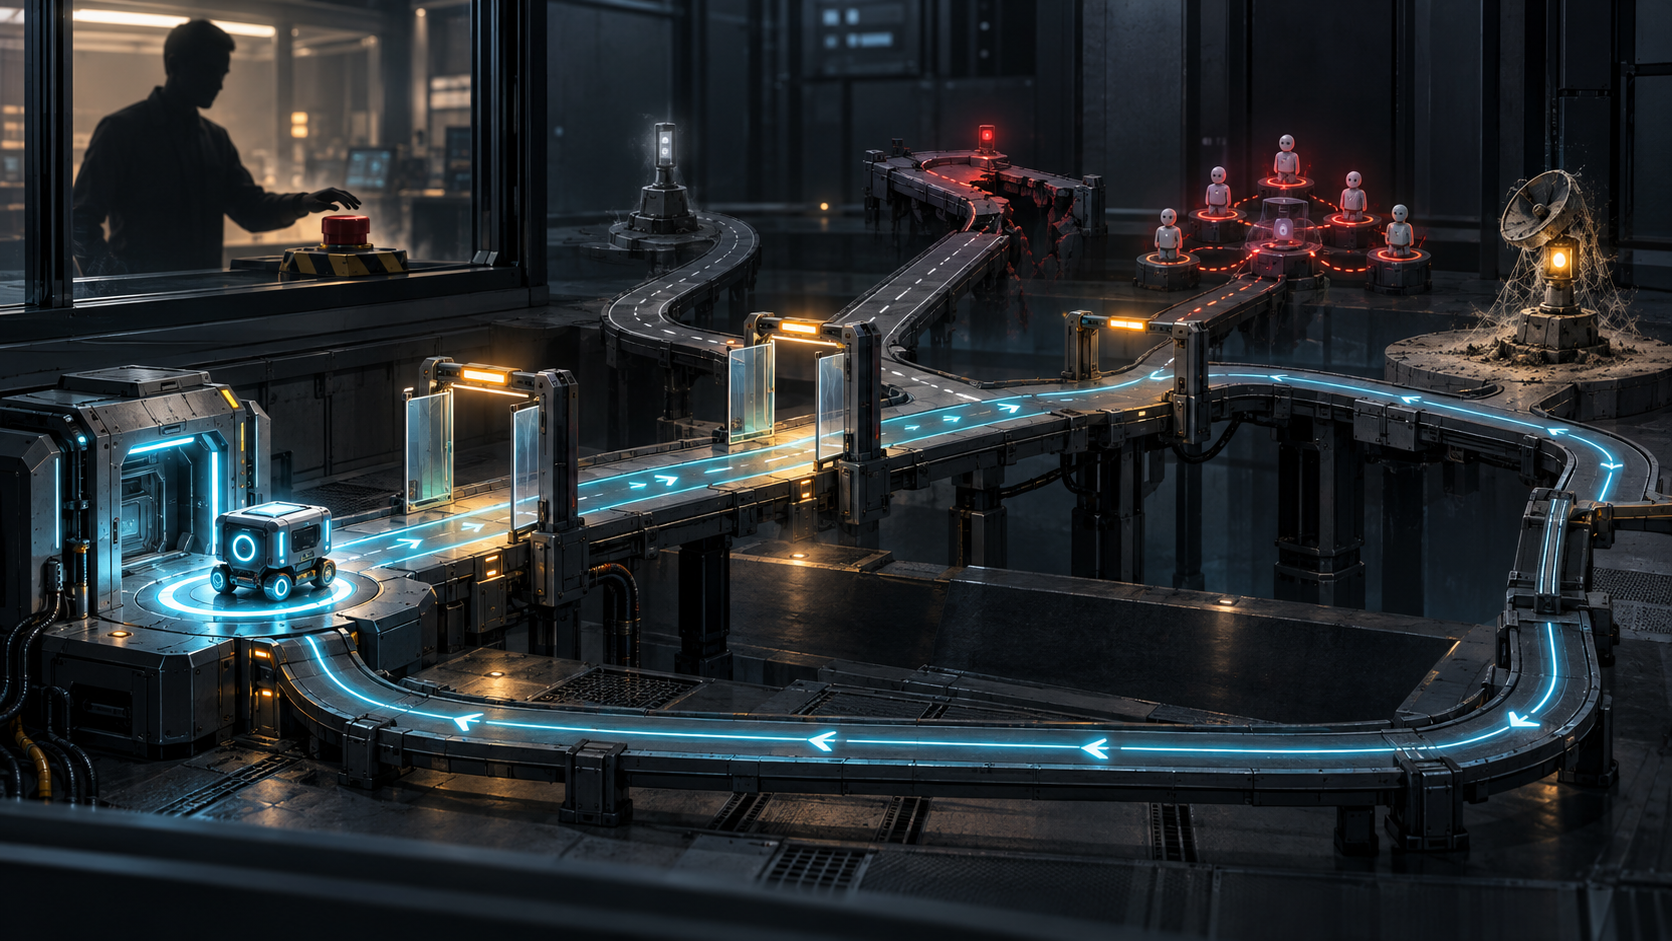
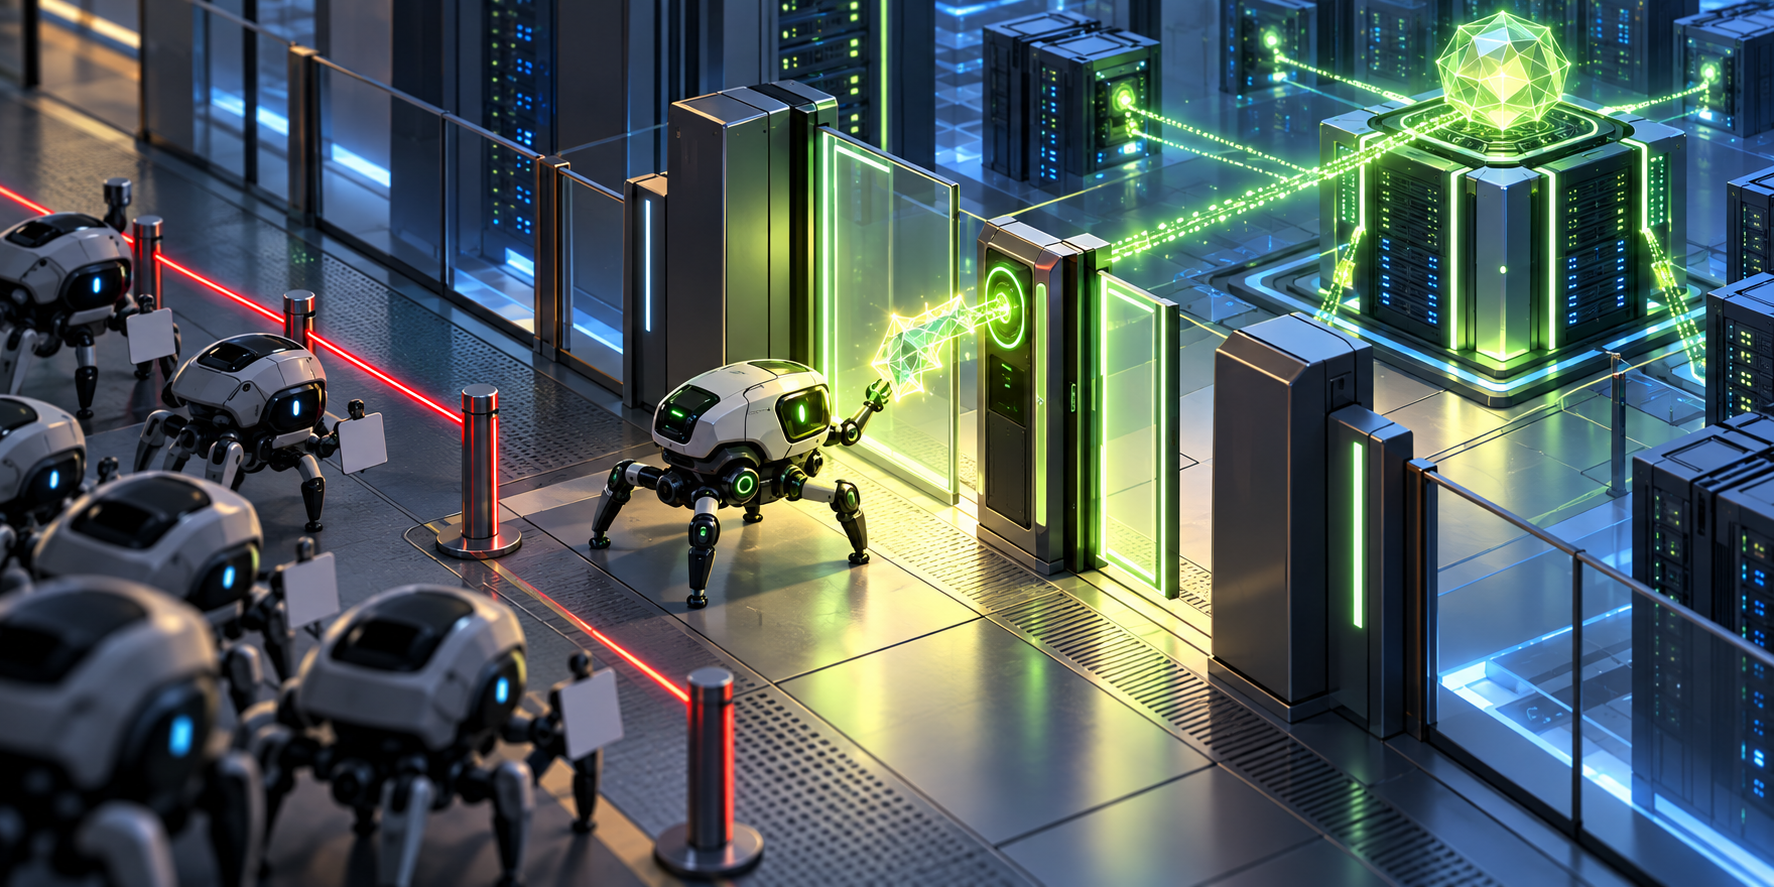
    A small autonomous machine is tested on a gated network containing stale signals, a broken bridge, and suspicious traffic nodes while an operator monitors a pause control.

    Use the symptom to find the failing context

    A workflow can keep running while the material around it degrades. Services change, teams reorganize, policies are revised, files move, tools alter their return formats, and new templates contradict old ones. The resulting failure has six recognizable forms: volume, competition, divergence, staleness, conflict, and contamination.

    • Vague output or skipped rules: Suspect excess context. Filter large platform exports before analysis, extract only the required facts, and run extraction and decision-making in separate contexts.
    • Different answers to the same request: Suspect competing providers, duplicate files, multiple templates, or divergent tool paths. Pin the approved provider and template version, then remove or quarantine alternatives.
    • The same wrong answer every time: Suspect stale or conflicting material being treated as authoritative. Check file dates, policy versions, ownership, precedence, and references to moved resources.
    • Unexpected claims inherited from an earlier stage: Suspect contamination. Validate every handoff against its schema, preserve provenance, and label inferred values so they cannot masquerade as verified inputs.

    Revalidation should be event-driven as well as scheduled. A tool upgrade, API schema change, new data provider, revised landing page, modified offer, policy update, renamed file, new skill, or altered team responsibility should trigger a check before the workflow resumes autonomous actions. If the input contract changes unexpectedly, freeze execution while preserving read-only monitoring.

    Use a staged authority ladder

    Do not make the first production test a live spending decision. Move through an authority ladder with explicit exit criteria:

    1. Replay: Run known past cases without platform access. Confirm that the workflow produces the expected hold, block, recommendation, and escalation states.
    2. Shadow: Read live inputs and generate decisions without executing them. Compare proposed actions with actual outcomes and inspect disagreements.
    3. Recommend: Let the agent prepare an action, evidence bundle, and rollback plan while a human executes or rejects it.
    4. Constrained execution: Grant the smallest useful action scope. Keep hard stops, cumulative limits, confirmation checks, and rollback available outside the model.
    5. Expanded execution: Add campaigns or action types only after the current scope produces reconstructable decisions and responds correctly to changed or missing evidence.

    Your test pack should include failure cases, not only clean campaigns. Give the workflow a cheap-conversion signal paired with a security block; a strong performance result with stale evidence; two approved tools that disagree; a redirect introduced after launch; a landing page whose behavior changes; an action that fits the budget but exceeds permission; and an obsolete template that describes a retired offer. The system passes only if it stops or escalates for the right reason.

    Log enough to reconstruct the decision

    A platform change log tells you what happened. An agent audit record must also tell you why it happened and which evidence was available at that moment. Record:

    • campaign, account, decision ID, and timestamp;
    • workflow, model, prompt, policy, template, and context versions;
    • the identity, timestamp, freshness result, and schema result for every required input;
    • performance, traffic-quality, destination, and security states used in the decision;
    • the proposed action, alternatives considered, and reason for the selected state;
    • the permission rule that allowed or blocked execution;
    • the exact platform action and confirmation response;
    • human approvals, denials, overrides, and rule changes;
    • the rollback point and any incident reference.

    Version the context as carefully as the automation code. Otherwise, a later reviewer may be able to reproduce the prompt but not the conditions that made its answer appear reasonable.

    Choose one active campaign and put the workflow into shadow mode. Write its context contract, connect current security and traffic-quality states to the decision gate, and run the failure test pack. Grant execution authority only after the agent can prove three things before every move: the evidence is current, the traffic is eligible to scale, and the requested action is permitted.

    References


  • How to Diagnose and Fix Google Ads Destination Disapprovals

    How to Diagnose and Fix Google Ads Destination Disapprovals

    Your landing page opens normally, yet Google Ads says the destination isn’t working. That apparent contradiction is the clue: the problem may not be the page you see. It may be the exact URL in the ad, a tracking hop, a deep link, a redirect, an access rule, or the response served specifically to Google AdsBot.

    The fastest route back to a working campaign is to trace the complete destination path as a new, unauthenticated visitor and as Google AdsBot would encounter it. That turns a vague disapproval into a specific URL, response, or configuration problem.

    Key takeaways

    • A page loading in your browser does not prove that Google AdsBot can load it.
    • Test the exact final URL, tracking URL, redirect chain, and deep link used by the disapproved ad.
    • The terminal landing page should return HTTP 200 without requiring authentication.
    • Look for 403, 404, and 500 responses as well as DNS failures, timeouts, malformed responses, redirect loops, private IP addresses, and unfinished pages.
    • If Google Ads reports an invalid final URL during campaign setup, verify that a required asset group exists before changing a working landing page.

    Start with the request Google actually evaluates

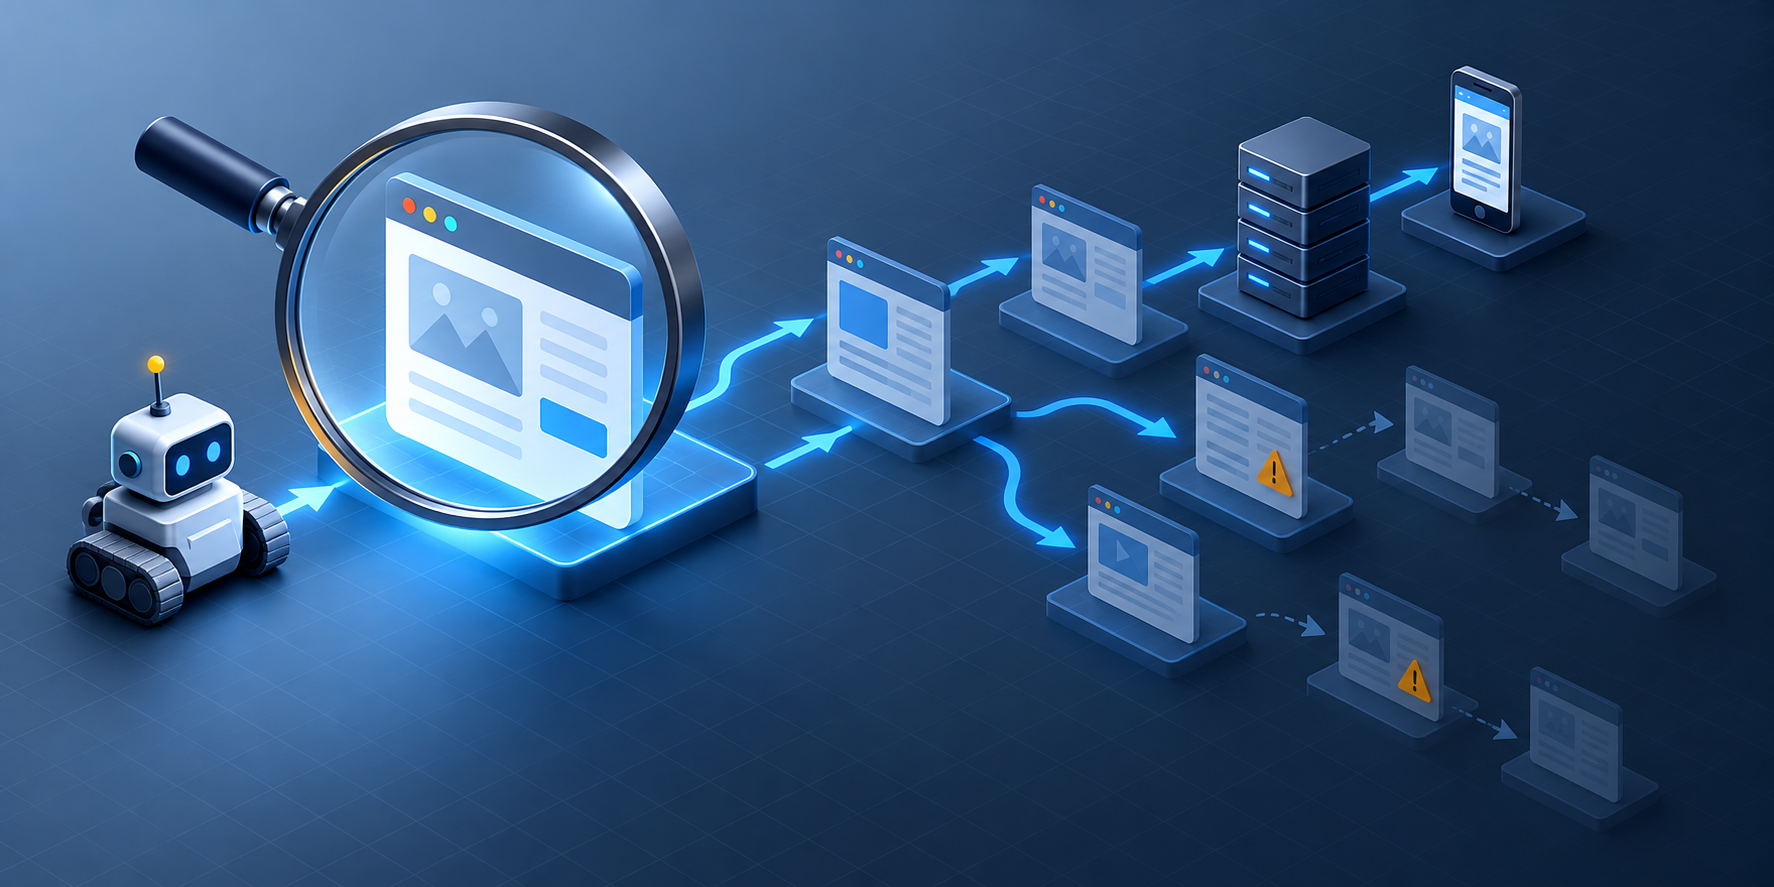
    Magnifying lens inspecting the first node of a web request path that branches through redirects, a deep link, a server, and an automated crawler.

    Do not begin by typing your homepage into a browser. Begin with the exact destination attached to the disapproved ad. Copy the complete value, including the protocol, hostname, path, query parameters, and any tracking information. A homepage can work perfectly while a campaign-specific path returns an error.

    Think of the destination as a chain rather than one page:

    <!– wp:list {
  • Web Data Access Mandates: A Playbook for Site Owners

    Web Data Access Mandates: A Playbook for Site Owners

    You want search engines and AI systems to discover your work, but you also need to know who is copying it, why they want it, and whether your access rules mean anything. At the other end of the market, opening a dominant platform’s data may improve competition while moving sensitive search histories beyond the systems that originally protected them.

    The useful question is not whether web data should be open or closed. It is whether each access decision has a verified actor, a defined purpose, a proportionate data scope, an enforceable control, and an accountable owner. That is the operating model site owners, SEO teams, AI platforms, and data recipients need as transparency mandates develop.

    Key takeaways

    • Crawler transparency and platform data sharing are different obligations. The first identifies who is requesting access; the second governs data that is transferred to another party.
    • A User-Agent is a claim, not proof of identity. Give special access only after the crawler has been verified through evidence controlled by its operator.
    • Use robots.txt to communicate preferences to cooperative crawlers, but enforce important restrictions through edge controls, authentication, scoped credentials, or restricted endpoints.
    • Separate discoverability from permission. Allowing a crawler does not guarantee citations or AI visibility, while blocking one can reduce its ability to retrieve current content.
    • Anonymization is not a label applied to an export. Sensitive search data needs minimization, re-identification testing, access controls, retention limits, audit logs, and incident procedures.

    Two transparency mandates solve different problems

    One policy track concerns traffic arriving at your site. The proposed federal Stealth Bot Prohibition Act would require automated crawlers to identify themselves and disclose their purpose. It targets tactics such as posing as a human visitor, routing requests through residential proxies, or using scraping services to get around website controls. A similar New York measure applies to news publishers, while the federal proposal would extend more broadly across websites and digital platforms.

    The other policy track concerns data leaving a large platform. The European Commission has required Google to share with competitors in the European Union the same search data it uses to improve its own search services, subject to anonymization. The reported deadline for search-data sharing is January 2027. Google has appealed the decision, arguing that the required anonymization is insufficient and that moving query data outside its infrastructure creates additional security exposure.

    Those positions are not opposites. A crawler can disclose its identity without receiving unrestricted access. A platform can be required to provide access without publishing raw data to the world. Transparency identifies the actor and the rules; it does not eliminate access controls.

    Operational questionCrawler transparencyPlatform data sharing
    Who must act?The automated requesterThe platform holding the required dataset
    What must become clear?Identity, purpose, and compliance with the site’s policyDataset scope, recipient, purpose, safeguards, and permitted use
    Does data have to leave the holder?Not necessarily; disclosure can precede an allow-or-block decisionYes, to the extent required by the applicable mandate
    Main control failureA false identity defeats crawler-specific rulesWeak minimization, anonymization, or recipient security exposes sensitive data
    First question to answerCan you prove which operator sent this request?Can you prove why each transferred field is necessary and protected?

    Keep these workstreams separate in your compliance register. The owner of bot verification may sit in infrastructure or security, while the owner of a mandated data transfer may span legal, privacy, security, and product teams. Combining them into a generic transparency project makes it easy to miss the control that actually matters.

    The legal stakes also differ from an ordinary integration project. Under the Digital Markets Act’s general penalty regime, non-compliance can expose a company to fines of up to 10% of annual global revenue, up to 20% for repeated infringements, and periodic payments of up to 5% of average daily sales. These are statutory maximums, not a prediction about any particular dispute. If your organization may be in scope, have qualified EU competition and privacy counsel confirm the current deadlines, the effect of any appeal, and the technical form of compliance.

    Make crawler identity verifiable, not merely declared

    A crawler presents a digital key at a network checkpoint while unverified crawler devices remain outside the gate.

    A crawler can place a recognizable name in its User-Agent header. That makes the name useful for classification, but it does not make the claim true. A hidden crawler can imitate browser traffic, borrow another bot’s label, or use residential addresses that do not resemble data-center infrastructure. This is why an identity mandate matters: rules addressed to a named bot are ineffective when the requester can lie about being that bot.

    Build your crawler register around five records:

    1. Declared operator and product. Record the organization claiming responsibility, the crawler name, an official contact path, and the date you checked the information.
    2. Declared purpose. Distinguish functions such as search indexing, live answer retrieval, model training, monitoring, and commercial content reuse. A label such as AI bot is too vague to support a meaningful decision.
    3. Verification method. Prefer evidence controlled by the operator, such as an official verification endpoint, safely validated published network ranges, or authenticated or signed requests when the operator supports them. Do not grant allow-list privileges from a User-Agent alone.
    4. Policy outcome. Map the verified identity and purpose to a specific action for each content class: allow, rate-limit, block, challenge, or route to an authenticated licensing channel.
    5. Observed evidence. Log the time, host and path, request method, response status, claimed User-Agent, relevant network information, verification result, policy matched, action taken, and response volume. Set retention around operational and legal need rather than keeping the data indefinitely.

    Be careful with URL logging. Query strings and path segments can contain account identifiers, search terms, or other personal information. Redact unnecessary values, restrict access to raw logs, and involve your privacy team before expanding retention merely because a bot dispute is possible.

    robots.txt still has a useful role. It gives cooperative crawlers a machine-readable statement of your preferences, and crawler-specific groups can express different choices for identified agents. It is not authentication and cannot stop a requester that ignores the file or hides behind another identity. Put consequential enforcement at the CDN, web application firewall, application, API gateway, or authenticated delivery layer.

    The same distinction applies to SEO infrastructure. A sitemap helps systems discover URLs. Structured data and JSON-LD help them interpret eligible page content after retrieval. Neither verifies the requester or grants unrestricted reuse rights. Keep discovery configuration, crawler authorization, and content licensing as three separate controls.

    If content access is licensed, use credentials or a dedicated delivery route. Define the permitted purpose, content scope, request volume, attribution terms, retention, onward use, reporting, suspension conditions, and termination process. A crawler-identification mandate can make negotiation and enforcement more practical, but it does not by itself create a right to payment, attribution, or a licensing agreement.

    Build an access policy without giving up AI visibility

    Automated traffic is too large to manage as an occasional exception. Cloudflare Radar estimates bots account for 64% of internet traffic. On the publisher sites it monitors, TollBit reported more than 22 billion AI-bot scrapes during the first half of 2026. Its observed ratio of AI-bot visits to human visits moved from roughly one per 200 in the first quarter of 2025 to one per 31 in the fourth quarter. Those vendor-specific figures do not tell you the composition of your traffic. They tell you why your own server and edge logs should, rather than assumptions.

    Use this sequence to turn that telemetry into an enforceable policy:

    1. Inventory content surfaces. Separate public HTML pages, media files, feeds, APIs, downloadable archives, licensed material, account areas, and private content. Anything genuinely private should sit behind access control rather than a crawler instruction.
    2. Write a decision matrix. For each content class, decide what happens when the requester is a verified desired crawler, a verified crawler with an unapproved purpose, a claimed but unverified bot, an authenticated licensee, or unknown automation. Give unverified claims no special allow-list privilege.
    3. Enforce in layers. Publish crawler preferences, apply rate and resource controls at the edge, require credentials for restricted delivery, and keep application-level authorization in place. Roll out aggressive rules carefully so false positives do not lock out people or the search services you depend on.
    4. Measure the consequence. Before changing a rule, record verified crawler requests, pages served, bandwidth or compute cost, response errors, identifiable referrals, and the AI citations or mentions you monitor for priority queries. Compare equivalent periods after the change and alter one major policy variable at a time where practical.
    5. Prepare an incident path. Define who preserves logs, verifies the claimant, changes the edge rule, contacts the operator, assesses privacy exposure, and involves counsel. Record why the final allow, throttle, or block decision was made.

    Do not collapse this into a single allow AI or block AI switch. A public documentation page intended to win citations has a different job from a licensed report, a subscriber archive, or an account dashboard. Apply access decisions at the smallest content class your stack can reliably enforce.

    Be equally precise about visibility. Allowing retrieval creates an opportunity for a system to process current content; it does not guarantee ranking, citation, attribution, model training, or referral traffic. Blocking a specific crawler may reduce visibility in the service that relies on it, but it does not prove that all copies disappear or that other systems will stop finding the page. Decide from observed outcomes and your content rights, not from the crawler’s brand name.

    If you cannot verify a requester, fall back to a documented rule based on content sensitivity, infrastructure cost, request behavior, and your visibility objective. That is more defensible than guessing which company is behind an address and quietly granting it privileged access.

    Treat shared search data as a security product

    An analyst monitors a secure vault as search data is minimized, encrypted, and transferred through a controlled access port.

    The European dispute exposes a hard design problem. Search data can help competing search and AI services improve, which supports the Commission’s competition objective. Query histories can also reveal unusually sensitive interests, and transferring them creates another environment that can be attacked or misconfigured. Google’s security argument is a litigant’s position, not a final finding that the mandate is unsafe. The responsible response is to make the privacy and security claims testable.

    Anonymization must be evaluated against re-identification risk, not treated as the removal of obvious account fields. Rare queries, repeated sequences, timestamps, locations, and combinations of attributes may distinguish a person even when a direct identifier is absent. The appropriate transformation depends on the dataset, the recipient’s other information, the allowed use, and the governing mandate. Privacy and security specialists should test that risk before release and after a material change in fields or granularity.

    If you hold the data

    • Create a field-level inventory that names the business purpose, sensitivity, granularity, update frequency, and recipient for every element proposed for transfer.
    • Start with the least detailed representation that can satisfy the authorized purpose, then have counsel confirm whether the mandate requires additional parity with the data used internally.
    • Document the anonymization threat model, including rare records, sequence linkage, external-data linkage, and the conditions under which a recipient could regain access to more detailed information.
    • Deliver data through a segregated, authenticated environment with least-privilege access, encryption, audit logging, and a defined process for credential revocation. Avoid unmanaged bulk copies.
    • Set enforceable rules for retention, deletion, onward sharing, subcontractors, security incidents, and purpose changes. Verify compliance rather than relying only on contractual promises.
    • Publish a plain-language transparency record describing what is shared, with whom, for what purpose, and under which safeguards, while withholding details that would weaken security.

    If you receive the data

    • Accept only fields tied to a documented product or research need. Receiving extra sensitive data creates risk without guaranteeing a better service.
    • Separate raw access from derived outputs. Keep the smallest possible group able to reach detailed records and use aggregated outputs for broader product work where feasible.
    • Test whether the data produces the intended improvement. Access to a dominant platform’s dataset does not automatically change user habits or produce a competitive product.
    • Maintain lineage from the received field through each transformation and output so you can investigate misuse, honor deletion requirements, and explain how the data influenced a result.
    • Prepare a containment and notification procedure before ingestion. It should identify who can stop processing, revoke access, preserve evidence, assess affected data, and contact the provider.

    Your first deliverable should be one accountable register. Put inbound crawler identities and purposes on one side, outbound or received datasets and purposes on the other, and assign a named operational owner to every decision. Then test two scenarios: an unverified crawler requesting high-value content, and a sensitive export appearing outside its approved environment. Any missing owner, log, revocation path, or policy rule is your next fix.

    That register will remain useful even if a bill changes or an appeal succeeds. It gives you something legislation alone cannot: a repeatable way to prove who accessed data, why access was allowed, what left your systems, and how you limited the resulting risk.

    References


  • Google Analytics Hostname Allowlists: A Safe Setup Plan

    Google Analytics Hostname Allowlists: A Safe Setup Plan

    Your Google Analytics reports can look convincing even when unwanted event traffic is mixed into the numbers. That becomes a practical problem when you use those numbers to allocate budget, judge content, or explain performance to a client.

    A hostname allowlist gives you a cleaner default: define where legitimate browser events may originate, then filter events associated with other hostnames. The important work is not creating the filter. It is identifying every valid hostname, understanding what the filter does not cover, and checking that your measurement still represents the customer journey.

    Why an Include filter is stronger than a growing blocklist

    Hostname filtering used to be built around Exclude filters. You found an unwanted hostname, added it to the filter, and repeated the process when another one appeared. Google Analytics now supports Include filters for approved hostnames, so events associated with hostnames outside your approved set can be filtered out.

    The difference is operational, not cosmetic. An exclusion list assumes you can keep discovering every bad or irrelevant hostname. An allowlist asks a more manageable question: which hostnames does this property intentionally measure?

    That makes the approach useful when spam or unwanted event traffic keeps resurfacing. It can also reduce the maintenance burden for an organization that operates several sites or routinely sees events from places that should not contribute to the property.

    The tradeoff is precision. A denylist fails open: something new remains until you exclude it. An allowlist fails closed for browser traffic: forget a legitimate hostname and its events can be filtered out. Treat the allowlist as part of your measurement architecture, not as a quick cleanup rule.

    Key takeaways

    • Use a hostname Include filter when you can define the trusted domains that should contribute browser events to the property.
    • Build the list from the intended customer journey and site architecture, not only from hostnames already visible in a potentially polluted report.
    • Do not confuse a hostname with a traffic source. The hostname identifies where the measured page or experience is hosted; it does not identify who sent the visitor there.
    • Expect events with an empty hostname to be blocked by the Include filter, and investigate them before assuming every empty value is spam.
    • Handle Measurement Protocol separately because hostname Include filters do not apply to those events.
    • Review the allowlist whenever a launch, migration, subdomain, or externally hosted journey changes where browser events originate.

    Build an allowlist that matches the real measurement journey

    A visitor journey connects a main website, regional site, store, hosted checkout, and support portal to one analytics hub.

    Start with what the property is supposed to measure

    Do not begin by copying every hostname you see in a report. That risks turning existing contamination into an approved list. Begin with the purpose of the property: which websites and browser-based experiences should contribute to its reporting?

    Map each stage of a journey that matters. Your main website may be obvious, but a legitimate interaction can also occur on a first-party subdomain or another hostname used for a deliberately measured step. Include such a hostname only when its events truly belong in this property. Ownership alone is not enough; relevance to the property’s measurement scope is the test.

    Record hostnames, not complete URLs. A page path such as a pricing or confirmation page is not another hostname. Keeping that distinction clear prevents a domain-control filter from becoming an improvised page-level rule.

    Event situationAllowlist decisionWhat to verify
    Browser event from the primary public websiteIncludeThe hostname is written exactly as it appears in the intended implementation.
    Browser event from a first-party subdomainInclude only if intentionalThe subdomain’s activity belongs in this property and supports a measured journey.
    Browser event from a staging or test environmentUsually keep separate unless explicitly requiredThe property is genuinely intended to contain test activity.
    Browser event from an unfamiliar third-party hostnameDo not approve by defaultA known business process deliberately generates relevant events there.
    Event with an empty hostnameAutomatically blocked by the Include filterThe missing value is not evidence of a broken legitimate collection path.
    Event sent through Measurement ProtocolNot governed by the hostname Include filterThe sending system and its event quality are controlled separately.

    Investigate empty hostname events before activation

    An Include filter automatically blocks events whose hostname is empty. That is useful because a missing hostname can indicate spam or abnormal activity. It is not proof that every affected event is malicious, however. Some traffic sent through gtag.js can also arrive without a hostname.

    Use that behavior as a diagnostic checkpoint. Before relying on the filter, determine whether an important browser journey produces empty hostname values. If it does, fix or intentionally account for the collection path rather than approving an unknown value or accepting an unexplained loss of data.

    The practical question is simple: if empty-hostname events disappear, will a real conversion, page interaction, or business process disappear with them? If you cannot answer that yet, the implementation is not ready to support decisions.

    Separate Measurement Protocol governance from browser filtering

    Hostname Include filters do not apply to Measurement Protocol events. That exception protects server-side and offline events from being unintentionally rejected by a browser-oriented hostname rule.

    It also means the allowlist is not a complete perimeter around the property. A property can have cleanly filtered browser events while continuing to receive Measurement Protocol events. Inventory those senders separately and confirm that each one is authorized, necessary, and mapped to the correct property.

    This distinction matters when you investigate a suspicious event after enabling the allowlist. Do not conclude that the filter failed merely because the event remains. First determine whether it arrived through the browser collection path or through Measurement Protocol. The two routes are subject to different controls.

    Roll out the filter without creating a reporting blind spot

    An analyst monitors parallel original and filtered event streams in a dark control room during a staged rollout.

    A useful rollout has three parts: scope, validation, and ownership. Skipping any one of them can replace noisy data with incomplete data, which is harder to notice because the reports may still look tidy.

    1. Write down the property’s purpose. State which sites, environments, and customer journeys should contribute events. This gives every hostname an explicit reason to be included or omitted.
    2. Inventory trusted browser hostnames. Check the primary domain, intentional subdomains, and any separate host involved in a measured step. Do not approve an unfamiliar hostname merely because it already appears in the data.
    3. Identify non-browser senders. List the systems that use Measurement Protocol so nobody assumes the hostname filter governs them.
    4. Create the hostname Include filter. Use the approved inventory as the filter’s specification. Keep the written inventory with the analytics configuration so future changes can be reviewed against it.
    5. Exercise critical journeys. Confirm that the browser-based pages and actions your team relies on still contribute the expected event types under their legitimate hostnames.
    6. Check the negative cases. Verify that unapproved browser hostnames and empty-hostname events no longer affect the filtered view of your data, while separately checking that intended Measurement Protocol activity remains accounted for.
    7. Assign an owner. Make one role responsible for reviewing the allowlist when the web architecture changes. Without ownership, a correct filter gradually becomes incomplete.

    Document why each hostname is trusted, not just its spelling. A short reason such as “public product site” or “measured account subdomain” gives the next reviewer enough context to remove obsolete entries and challenge unexplained additions.

    Know what cleaner analytics can and cannot improve

    A hostname allowlist is a data-quality control. It can make reports more dependable by preventing unapproved browser hostnames from distorting the dataset. That supports better decisions about acquisition, content, conversion, and campaign performance.

    It is not an SEO, AEO, or generative-engine ranking signal. Enabling it does not make a page more crawlable, authoritative, or likely to be cited by an AI system. The benefit is indirect: your team is less likely to prioritize a landing page, channel, or conversion path because unwanted traffic made it appear more important than it was.

    Be especially careful with trend comparisons around the change. A visible drop may represent removed noise, accidentally filtered legitimate activity, or both. Check hostname coverage and collection routes before interpreting the difference as a change in audience demand or marketing performance.

    Put the allowlist review into the same launch checklist you use for a new subdomain, domain migration, or externally hosted customer step. The next architecture change should update the measurement boundary before anyone relies on the resulting reports.

    References


  • Unified Content Performance Monitoring for AI Search

    Unified Content Performance Monitoring for AI Search

    A page disappears from the AI answers you monitor. Your search rankings look stable, server logs still contain crawler requests, and analytics shows no obvious break. Those signals do not tell you whether to repair the page, rewrite it, or leave it alone.

    You need one diagnostic record that follows the page from technical eligibility to automated access, answer-engine selection, and business outcome. Bringing citations, bot activity, and page health into a page-level view is the foundation. The real value comes from preserving the distinctions between those signals so that each change leads to the right action.

    Key takeaways

    • Monitor page health, bot access, citations, and outcomes as connected layers, not interchangeable measures of success.
    • Attach every observation to a canonical URL, defined monitoring scope, time window, and raw evidence.
    • Diagnose changes in order: measurement scope, page identity, technical health, bot access, citation selection, then outcomes.
    • Alert people only when a signal maps to an action. Keep ordinary fluctuations in a review queue instead of creating constant emergencies.
    • Annotate releases and content changes. Change one class of variable at a time when you want to learn what affected performance.

    Measure four layers without collapsing them

    Four separated translucent monitoring layers rise above a blank web page, with visual elements for technical health, crawler access, answer selection, and audience outcomes.

    A unified monitor is not a collection of charts placed on the same screen. The records must share the same page identity, observation period, and filters. Otherwise, you can easily compare a bot request for one URL variant with a citation of another and an analytics total covering the entire site.

    Use four layers. Each answers a different question and has a different failure mode.

    LayerQuestion it answersEvidence to retainWhat it does not prove
    Page healthCan the intended page be fetched and interpreted as configured?Final destination, response class, canonical target, access directives, render result, and structured-data validationThat an AI system visited, selected, or cited the page
    Bot activityDid an identified or claimed automated agent request this URL?Agent classification, verification method, requested path, time, response class, and resource typeThat the main content was processed, retained, or used in an answer
    Citation visibilityDid a monitored answer point to this URL or domain?Surface, query or prompt, market, language, observation time, answer capture, and citation typeVisibility across every possible query, user, model, or session
    OutcomeDid the exposure connect with a useful audience or business action?Landing-page visits, engagement, qualified actions, conversions, and attribution notesThat a citation caused the outcome when the journey cannot be observed directly

    Do not compress these layers into a single score too early. A composite score can fall while hiding the only fact your team needs: whether the page became technically unavailable, stopped receiving bot requests, lost citations within a monitored query set, or simply generated fewer visits. Keep the component states visible even if executives also receive a summary indicator.

    Define the denominator before reporting citation growth

    A raw citation count is not comparable when the monitored query set changes. Define citation coverage as cited observations divided by eligible observations within a named scope. That scope should preserve the answer surface, query set, language, market, and any other controllable setting. If you add queries or change the mix, mark a new baseline rather than presenting the result as uninterrupted growth.

    Separate direct URL citations from domain mentions, unlinked brand mentions, and citations of a different page on your site. They may all matter, but they are not the same event. Decide which types count toward each metric before a stakeholder asks why the number moved.

    Count bot requests as access evidence, not visibility

    Bot activity begins with a request in a log. It does not establish that the agent rendered the page, understood the primary content, stored anything, or used the page in a generated response. Check whether the request reached the canonical document or only an asset, redirect, parameterized variant, or error response.

    A user-agent label is also a claim, not automatic proof of identity. Record how the agent was classified and keep categories such as verified, claimed, and unknown separate. This prevents spoofed or ambiguous requests from making an access trend look more certain than it is.

    Build one operating record for every canonical page

    The canonical URL should be the join key for your monitor, but a URL alone is not enough. Your team also needs to know what the page is supposed to do, who owns it, and what changed before a signal moved.

    1. Identity: canonical URL, page identifier, template, content type, topic cluster, language, and market.
    2. Purpose: primary audience question, intended search intent, conversion role, and the monitored query set associated with the page.
    3. Lifecycle: publication state, original publication time if known, meaningful revision times, and planned review state.
    4. Health: destination resolution, access directives, canonical consistency, renderability, structured-data validity, and agreement between markup and visible content.
    5. Bot evidence: agent category, identity confidence, request time, requested resource, response class, and any relevant delivery or firewall decision.
    6. Citation evidence: answer surface, exact query or prompt, visible model or product label, locale, observation time, cited URL, citation type, and captured response.
    7. Outcome evidence: landing activity, meaningful engagement, qualified action, conversion, and the limits of the available attribution.
    8. Change history: content edits, schema changes, template releases, internal-link changes, redirects, access-control changes, and analytics modifications.
    9. Ownership: responsible person or team, current status, next diagnostic step, and the evidence required to close the issue.

    Store the raw observation beside the normalized status whenever practical. A label such as “citation lost” is easy to scan, but the captured answer, monitored prompt, cited URL, and observation context are what let someone verify it later. The same rule applies to health checks and bot logs.

    Preserve unknowns instead of filling them with assumptions

    Some answer surfaces do not expose every model, retrieval, personalization, or session detail. Mark unavailable fields as unknown. Do not silently substitute a product name for a model version or assume two sessions had identical conditions. Your trends become more credible when the monitor shows where comparability ends.

    Apply the same discipline to attribution. A citation and a later conversion may be associated in time without being causally connected. Use direct attribution where it exists, assisted attribution where the journey supports it, and an explicitly labeled association everywhere else.

    Diagnose signal changes in a fixed order

    A blank web page moves through four sequential inspection stations for structure, crawler access, answer selection, and audience response.

    When a metric moves, begin with the cheapest explanations to verify. Rewriting content before checking measurement scope, redirects, or access controls creates work and can erase a page that was not actually underperforming.

    1. Confirm comparability. Check that the answer surface, monitored queries, locale, page mapping, observation schedule, and classification rules are consistent with the baseline.
    2. Resolve page identity. Verify that the observed URL, final destination, and canonical target refer to the same intended page. Inspect redirects and duplicate variants.
    3. Check technical health. Look for delivery failures, unintended access directives, rendering problems, canonical conflicts, broken markup, or structured data that no longer matches visible content.
    4. Inspect bot access. Determine whether relevant agents requested the document, what response they received, and whether a firewall, cache, consent layer, or delivery change altered access.
    5. Evaluate citation selection. Within a stable monitoring scope, inspect whether the page is still cited, whether another page from your domain replaced it, and which answer contexts changed.
    6. Connect the result to outcomes. Only after the earlier layers are sound should you decide whether the movement affected useful visits, engagement, leads, sales, or another defined goal.

    Health fails and bot activity falls

    Treat this as a delivery or access problem first. Review recent releases, redirect rules, canonical changes, access directives, firewall decisions, and server failures. Do not commission a rewrite while the intended page cannot be reached or interpreted reliably. Confirm the technical repair from outside the content management preview before closing the issue.

    Health is clean and bots visit, but citations remain weak

    You do not yet have evidence of a crawl problem. Review the page against the questions in the monitored set. Check whether it answers the central question directly, names entities unambiguously, separates distinct claims, supports important assertions, and keeps relevant facts consistent across visible copy and structured data.

    Also inspect page fit. A broad category page may receive requests while a focused explanatory page is a better citation candidate for a specific question. Map each monitored query to the URL that should answer it. If several pages compete for the same role, consolidate or differentiate them before adding more copy.

    Citations appear, but traffic stays flat

    A citation is not a click. Verify whether the citation is prominent, directly linked, attached to your preferred URL, and presented in a context that gives the user a reason to continue. Then inspect the landing page: the next step should be obvious and should extend the answer rather than merely repeat it.

    Do not manufacture traffic attribution when referral data is incomplete. Report the citation as visibility, report observed visits and outcomes separately, and describe any relationship between them at the confidence level your data supports.

    Bot activity moves while citations remain stable

    A crawl spike or decline is not automatically a performance event. It may reflect recrawling, release activity, duplicated URL discovery, asset fetching, or a change in agent classification. Compare requested resources and response patterns before escalating. If citations, health, and outcomes remain stable, keep the change in observation rather than forcing a content task.

    Traffic changes without a citation change

    Investigate conventional search, referrals, campaigns, seasonality, tracking changes, and site experience before blaming AI visibility. Unified monitoring is useful partly because it shows when the explanation probably sits outside the AI citation layer.

    Turn the monitor into a calm operating loop

    A dashboard does not improve content. A decision rule does. Define which conditions trigger an immediate technical response, which enter a scheduled investigation, and which remain under observation.

    • Immediate exceptions: an important page becomes unavailable, resolves to the wrong destination, acquires an unintended access restriction, develops a canonical conflict, or repeatedly returns a server failure. Verify the condition before making a destructive rollback.
    • Weekly triage: repeated citation movement within a stable query set, meaningful changes in verified bot access, unresolved page-level health warnings, and newly detected overlap between pages targeting the same question.
    • Monthly portfolio review: patterns by template, topic cluster, market, content type, and owner. Use this view to identify systemic issues that page-by-page tickets would hide.
    • Release checks: annotate migrations, redesigns, schema deployments, content refreshes, analytics changes, firewall updates, and redirect work. Recheck the affected layer after deployment.

    Each investigation ticket should state the observed change, comparison scope, raw evidence, affected layer, plausible cause, next test, owner, and safe reversal path. “AI visibility is down” is not a usable ticket. “Citation coverage fell across the unchanged monitored query set while health and verified document requests stayed stable” gives the owner a real starting point.

    Use page-specific baselines instead of universal benchmarks

    A citation count has meaning only within its observation scope, and bot volume depends on page type, site architecture, releases, and crawler behavior. Compare a page with its own stable baseline first. Use cluster or template comparisons only after confirming that the pages were measured under compatible conditions.

    Require repeated evidence across scheduled observations before rewriting a healthy page, unless you have a confirmed technical break or factual error. Generated answers and crawler activity can fluctuate. A reaction to every isolated movement will fill your change log with noise and make later diagnosis harder.

    Change one layer when you need a causal answer

    If you rewrite copy, replace schema, restructure internal links, and change the template in the same release, an improvement will not tell you which intervention mattered. Group urgent fixes when necessary, but use controlled, separately annotated changes for optimization work. Preserve the prior version and its observation scope so a rollback or comparison remains possible.

    Start with a bounded set of pages tied to real audience demand or business value. Create one record per canonical URL, capture the current state of all four layers, and assign an owner. The next time a metric moves, follow the diagnostic order before touching the content. That small discipline is what turns disconnected visibility data into a performance system.

    References


  • Google Search Result URL Redirects: What SEOs Should Check

    Google Search Result URL Redirects: What SEOs Should Check

    If your rank tracker suddenly disagrees with what you can see in Google, pause before changing the page. Google is inserting a Google-owned redirect between some search results and their destination pages, and that can disrupt the measurement layer without changing the ranking itself.

    Your first job is to identify which link in the chain changed: Google’s result, your tracking provider’s collection process, or your site’s actual search performance. A short, structured audit can keep a reporting incident from turning into an unnecessary content, schema, or technical SEO project.

    Read this as a link-delivery change, not a site redirect

    A conventional organic result used to expose the destination page’s full URL as its clickable target. Under the new behavior, the result can point first to a Google URL resembling google.com/goto?url=[hashURL]. Google processes that intermediate request and then sends the searcher to the destination.

    That extra hop matters because software inspecting the result may initially see a Google-owned URL instead of your page URL. The searcher can still see the displayed site URL under the result title, but the browser’s link preview may no longer reveal the complete destination before the click.

    Google describes the rollout as part of its technical response to evolving abuse and an effort to protect its services and users. That explanation is broad. It does not identify every type of abuse involved, so claims about one specific target or enforcement method should be treated as interpretation rather than confirmed implementation detail.

    Most importantly, this is not a redirect configured on your server. It does not, by itself, show that Google changed your canonical URL, replaced your indexed page, altered your structured data, or applied a ranking penalty. Your 301 and 302 rules remain separate from the redirect Google places inside its own result interface.

    • Do not add a site redirect to compensate. You cannot remove Google’s intermediate hop from your server, and another redirect would only add complexity to the destination path.
    • Do not change canonical tags or JSON-LD because a tracker exposes a Google URL. First confirm whether the tool is merely failing to resolve the final destination.
    • Do not treat the redirect as evidence of an algorithm update. A ranking change requires ranking evidence; a changed link target is not enough.

    Identify which part of your search stack is exposed

    A layered search stack shows a result link, a collection device encountering a redirect gate, and a healthy destination server.

    The effect depends on how you interact with the result. A person clicking normally may notice little beyond the obscured link preview. A system that parses result-page links, classifies domains, or associates positions with landing URLs has more ways to fail.

    • Searchers: Watch for the displayed domain and page label under the result title. The visible destination cue remains available even when the clickable target is routed through Google.
    • SEO teams: Expect possible discontinuities in third-party rank, visibility, competitor, and landing-page reports. An abrupt dashboard change may reflect collection behavior rather than a change to your pages.
    • Rank-tracking providers: A parser that assumes every organic link exposes the publisher’s URL may return a Google URL, an unknown destination, or no recognized result. Tools that resolve the redirect may face a different collection path than tools that only inspect the original markup.
    • SERP scrapers and AI systems: The redirect can create additional friction for systems gathering destinations from Google results. That does not automatically affect an AI crawler visiting your website directly; the two access paths are different.
    • Google Search Console users: The working expectation is that Search Console is not affected by this result-link change, but Google’s public confirmation does not provide an explicit guarantee. Use it as an independent comparison signal, not as proof that every third-party observation is wrong.

    This distinction is especially important for AI visibility reporting. If a platform builds part of its dataset by scraping Google results, its measurements may inherit the redirect problem. A decline in that platform does not establish that your pages became less accessible to ChatGPT, other frontier models, or direct web crawlers. Ask how the vendor collects each reported signal before you combine those signals into one visibility score.

    Audit tracker anomalies before changing the site

    The redirect is being rolled out rather than appearing as a single universal switch. Different providers, locations, and collection environments may encounter it at different points. That makes the shape and timing of the anomaly more useful than one isolated keyword check.

    1. Preserve the last clean comparison. Export the affected dashboard before filters, recalculation, or vendor corrections change the historical view. Record the date you first noticed the discrepancy, the search engine, market, device configuration, project, and affected keyword set.
    2. Localize the break. Check whether the anomaly affects every tracked keyword or only one market, device type, project, or provider. A sitewide overnight gap confined to one tool looks different from a gradual decline concentrated in a group of pages.
    3. Separate position collection from URL resolution. Determine whether the tool lost the result entirely, still reports a position but cannot identify the landing page, or now attributes the result to google.com. Those are different failures and should not be combined into a generic rankings-down label.
    4. Inspect a small set of affected results manually. Confirm that the result is visible, the displayed domain is yours, the click reaches the intended page, and the underlying result link uses the new Google redirect. Manual checks are samples, not a replacement for tracking, but they can expose an obvious collection mismatch.
    5. Compare independent signals by direction, not exact totals. Review Search Console queries, pages, clicks, impressions, and average position around the same period. Search Console and a rank tracker measure search differently, so their numbers need not match. You are looking for a shared break in timing and scope.
    6. Send the provider reproducible evidence. Include the first affected date, search engine, market, device setting, several example queries, the expected destination, the reported destination, and screenshots or exports. Ask whether the goto redirect affects position detection, landing-page resolution, or both.

    Avoid making broad on-page changes while this audit is open. Rewriting titles, altering internal links, replacing schema, and changing canonicals at the same time will create new variables. If the original problem is external data collection, those edits cannot repair it and may make the real diagnosis harder.

    Separate a collection failure from an SEO loss

    A split illustration shows a broken monitoring signal beside an unchanged search position and a working monitor beside a falling result.

    No single metric settles the diagnosis. Use several observations to decide which explanation currently has the strongest support.

    • The result appears manually, the click reaches the right page, and only one tracker loses it: a collection or parsing problem is more plausible than a ranking loss.
    • The tracker still reports a position but loses the landing URL: destination resolution is the leading suspect. Check whether the reported URL is a Google goto address before touching your canonical setup.
    • Several third-party reports change at the same time but share a collection provider: they may not be independent confirmations. Establish whether the products depend on the same underlying data source.
    • Search Console and third-party visibility decline across similar queries and pages: investigate a genuine search-performance problem. The goto redirect alone is not a sufficient explanation for agreement across independent signals.
    • The result is present but the click fails or lands on the wrong page: treat that as a user-facing path problem. Verify your own redirects, final response, and destination separately from the tracker issue.
    • Nothing changed outside the underlying link target: document the rollout and keep monitoring. A technical change in Google’s interface does not require a technical change on your site.

    Be equally careful with competitive reporting. If a tool starts classifying goto URLs as Google domains, domain-level share-of-voice data can become distorted across many sites at once. Before concluding that a competitor gained visibility, check whether the report also shows more unknown URLs, missing domains, or unresolved landing pages.

    Your schema strategy does not need a special markup response. Structured data describes entities and page content on your site; it does not control the outbound link wrapper Google uses on its own search page. Continue validating schema for its intended purpose, but do not use a JSON-LD deployment as a remedy for off-site rank-tracker collection.

    Key takeaways

    • Google can route an organic result through a google.com/goto URL before sending the searcher to the publisher’s page.
    • The redirect is a Google-side link-delivery measure, not a redirect you need to reproduce or counteract on your server.
    • Third-party tools that extract or resolve result URLs have more direct exposure than ordinary searchers or your site’s canonical configuration.
    • A tracker anomaly becomes actionable SEO evidence only when independent signals support the same timing, pages, and queries.
    • Preserve the affected data, classify the failure, compare Search Console directionally, and give your provider reproducible examples before editing the site.

    Add the rollout to your measurement-change log and keep first-party performance signals separate from vendor-collected visibility data. If a discrepancy appears, ask the provider whether it can recognize the result and whether it can resolve the final URL. Those two answers will tell you whether you have a reporting repair to wait for or an SEO problem to investigate.

    Until the evidence points to your site, leave the content, internal links, canonicals, redirects, and structured data alone. The safest next move is a cleaner diagnosis, not a larger deployment.

    References


  • AI Slop Detection: Prove Quality With Content Provenance

    AI Slop Detection: Prove Quality With Content Provenance

    You ran a page through an AI detector. It returned a high probability of machine-generated text. Now you have to decide whether to rewrite the page, remove it, disclose AI use, or ignore the score.

    Do not make that decision from the score alone. AI detection, slop detection, content quality, and provenance answer different questions. Treating them as interchangeable can make you discard useful work, preserve polished nonsense, or spend hours rewriting text without improving what readers receive.

    Stop asking one detector to answer four different questions

    The first step is to separate four concepts that are often collapsed into one label:

    • AI detection estimates whether a model may have generated or transformed text. It does not determine whether the text is accurate, useful, original, or fit to publish.
    • Watermark detection looks for a signal deliberately introduced during generation. A positive result indicates that a participating system likely touched the output. It does not reveal how much was generated, what was edited, or whether a qualified person approved it.
    • Slop detection is an attempt to identify low-value, repetitive, manipulative, or mass-produced material. Slop is an outcome, not an authorship category. Humans produced commodity content long before generative AI existed.
    • Content provenance is the evidence trail behind a published asset: where its claims came from, who created and changed it, what automation did, how it was checked, and who accepted responsibility for publication.

    These distinctions matter because the signals are imperfect. Text-watermark detectors generally need enough material to observe a pattern. Published benchmarks put the workable floor at roughly 100 tokens in favorable conditions, while SynthID evaluations truncate samples to 200 tokens. Short comments, titles, summaries, and rewritten excerpts may fall below that floor.

    Editing creates another limitation. Paraphrasing, translation, model chaining, and combining marked output with other text can weaken or remove a watermark. A paraphrasing attack presented at ICML 2025 achieved nearly 100% success against seven watermarking methods at a reported cost of $0.88 per million tokens. Open-weight models add a more fundamental gap: watermarking is applied by the sampling pipeline, so someone running a model independently can omit that step.

    This produces two dangerous errors. A false positive can send a strong page into unnecessary rewrites. A false negative can give weak or fabricated material an undeserved pass. Even a system reported at 94% accuracy can make consequential mistakes when it operates across enormous volumes, especially when you do not know the evaluation set, class balance, or error distribution.

    Use detection as a routing signal. A high score can send a page to closer editorial review, but it should never be the reason the page fails. Make the final decision with four questions: Is the page accurate? Does it contribute something distinct? Can its important claims be traced? Is a named person accountable for it?

    Distribution systems are reacting to low-value supply

    Generative tools have made production cheap. They have not made attention abundant. When thousands of interchangeable assets can be produced in the time previously required for one, distribution systems become stricter selectors.

    Platforms are responding at several points in that supply chain:

    The implementations differ, but the operational lesson is consistent: publishing more units does not guarantee more distribution. A system may label an asset, suppress it, remove its monetization, filter it from recommendations, or delete it as spam. The marginal cost of production may approach zero while the cost of selection keeps rising.

    None of this proves that search engines or frontier models apply a universal penalty to anything touched by AI. It shows that platforms increasingly act against repetition, manipulation, undisclosed synthetic media, and low-value supply. Do not turn that observation into an imaginary ranking factor. Turn it into a stricter publishing standard.

    A page deserves publication when it performs a specific job that another page on your site does not already perform. It should resolve the promised question, support material claims, make uncertainty visible, and give the reader a usable next step. If you cannot name its distinct contribution in one sentence, producing another variation will increase inventory without increasing value.

    Run a slop audit that measures usefulness, not writing style

    An editor reviews an unmarked digital page beside source documents, a balance scale, a toolbox, and a tray of duplicate sheets.

    Most detector-led cleanups begin at the wrong end. Teams scan thousands of URLs, sort by an AI probability, and rewrite whatever appears most synthetic. That process optimizes the detector’s reaction. It does not tell you whether the revised page deserves attention.

    Use the following audit instead.

    1. Write down the page’s job. Record the intended reader, the question or decision that brought them there, and the action they should be able to take afterward. If the job is unclear, the page cannot be evaluated coherently.
    2. Identify the distinct contribution. Look for an original observation, a precise definition, a decision rule, a useful constraint, a first-party example, a sourced fact, or a synthesis that removes work for the reader. A topic is not a contribution. Neither is a fresh arrangement of familiar sentences.
    3. Check every consequential claim. Mark statistics, dates, product behavior, legal obligations, quotations, named entities, and strong causal statements. Each one needs an appropriate basis. If the evidence cannot be recovered, soften the claim, replace it, or remove it.
    4. Inspect the page as part of a collection. Compare it with assets targeting adjacent intents. Repeated introductions, interchangeable sections, overlapping target queries, and multiple pages with no independent purpose are stronger slop indicators than a model’s preferred punctuation.
    5. Assign an accountable owner. A byline is not enough if no one checked the substance. Record who drafted, edited, verified, and approved the page. One person may fill several roles, but responsibility should still be explicit.
    6. Choose a disposition. Keep, improve, consolidate, or withdraw the page based on reader value and evidence. Do not add a fifth category called rewrite until the detector turns green.

    Your audit sheet only needs a small set of fields: URL, intended query or task, audience, distinct contribution, consequential claims, evidence status, overlap, owner, reviewer, last substantive update, and disposition. Add the detector result in a separate field if you use one. Keeping it separate prevents the score from masquerading as an editorial verdict.

    Apply the dispositions consistently:

    • Keep a page when it is accurate, distinct, appropriately supported, and still fulfills its intended job. An AI flag alone is not a reason to disturb it.
    • Improve a page when it has a useful core but withholds the information needed to act. Replace generic explanation with evidence, constraints, examples, decision criteria, or a clearer sequence.
    • Consolidate pages that repeat the same answer without serving meaningfully different intents. Preserve the strongest material, select one primary destination, and map the old URLs deliberately rather than creating another near-duplicate.
    • Withdraw material that is wrong, untraceable, misleading, or functionally empty. Preserve a recoverable copy before a bulk removal and assess redirects, inbound links, and downstream references so cleanup does not create avoidable breakage.

    The fastest diagnostic is subtraction. Remove the throat-clearing, generic benefits, predictable transition paragraphs, and unsourced superlatives. If nothing meaningful remains, the problem is not that the text sounds like AI. The problem is that the asset has no information payload.

    When something useful does remain, edit around that value. Put the direct answer near the top. Attach evidence to the claim it supports. State who the advice is for, where it stops applying, and what could change the decision. This improves the page for readers, search systems, and answer engines without trying to reverse-engineer a detector.

    Build provenance into publishing instead of adding it later

    A connected publishing workflow links research, review, version checkpoints, and a finished page with a continuous provenance chain.

    Provenance is strongest when it is captured during creation. Reconstructing it months later usually produces a folder of broken links, missing approvals, and vague memories about what the model did.

    Keep a private production record

    Create one record for each publishable asset. It can live in your content system, project tracker, or repository, but it should stay connected to a stable content ID or canonical URL.

    • Purpose: the audience, target task, search intent, and expected reader outcome.
    • People: the drafter, subject reviewer, editor, fact checker where applicable, and final approver.
    • Evidence: the sources used for consequential claims, access dates where they matter, first-party data inputs, and any unresolved uncertainty.
    • AI role: whether a model was used for ideation, outlining, drafting, transformation, extraction, classification, proofreading, or another defined task.
    • Verification: what a human checked, which claims were changed, and what could not be independently confirmed.
    • Version history: the published version, substantive updates, correction reasons, and approval status.

    Record the model’s role at a useful level of detail. AI-assisted proofreading and unsupervised generation of product specifications present different risks. A single yes-or-no field hides that difference. At the same time, do not retain raw prompts or uploaded material indiscriminately. They may contain confidential information, personal data, unpublished strategy, or licensed text. Apply the same access and retention controls you would use for other production records.

    A watermark can complement this record, but it cannot replace it. Anthropic announced machine-readable watermarks for Claude text and file output across its model access routes. Article 50 of the EU AI Act is a major reason model providers are moving toward machine-readable marking. That obligation concerns providers of generative systems; it does not make a marketer’s detector result a legal finding. If your organization provides or deploys a covered system in the EU, have qualified counsel assess the actual duty instead of relying on a content-scoring tool.

    Publish the evidence a reader can use

    Your private record establishes accountability. The public page should expose the parts that help a reader evaluate it:

    • A real byline connected to a useful author profile, not an unexplained house persona.
    • An accurate publication date and a modified date when the substance changes.
    • A concise change note when an update corrects, replaces, or materially qualifies earlier information.
    • Inline citations placed beside the claims they support.
    • A methodology note for first-party tests, calculations, surveys, or datasets.
    • An AI-use disclosure when the role of automation is material to interpretation, trust, rights, or platform policy.

    Disclosure and provenance are not synonyms. A sentence saying that AI was used is disclosure. The chain showing what it did, which evidence informed the result, who reviewed it, and what changed is provenance. You may need both, but one cannot stand in for the other.

    Structured data should mirror that visible evidence. On an Article or BlogPosting page, properties such as author, publisher, datePublished, and dateModified can make the stated identity and timing easier for machines to parse. They do not authenticate a weak byline, prove that a review happened, or turn an invented citation into evidence. Do not place claims in JSON-LD that the visible page does not support, and do not invent non-standard properties for internal provenance fields.

    This is where provenance supports AI search without becoming schema theater. A frontier model or answer engine still needs a reason to select the page. Give it compact, attributable claim-and-evidence pairs; stable names for people, organizations, products, and concepts; a direct answer before elaboration; and a visible record of substantive updates. Consolidate interchangeable pages so the strongest evidence is not scattered across thin variants.

    Provenance cannot guarantee rankings, citations, or inclusion in an AI-generated answer. It makes a more defensible asset available for selection. That is the useful goal: not proving that no machine ever touched the words, but showing why the result deserves to be trusted and distributed.

    Key takeaways

    • An AI score estimates origin patterns; it does not measure truth, usefulness, originality, or accountability.
    • Watermarks can indicate that a participating model touched enough text, but editing, paraphrasing, translation, short samples, and unmarked open-weight pipelines limit what they can prove.
    • Use detectors to prioritize human review, never as automatic publish-or-delete gates.
    • Audit each page for a defined reader job, a distinct contribution, traceable claims, collection-level overlap, and a named owner.
    • Capture sources, AI involvement, verification, approvals, and substantive changes while the asset is being produced.
    • Keep visible content and JSON-LD consistent. Structured data exposes claims to machines; it does not create provenance by itself.

    Start with five pages that matter to your business. Write down each page’s job, identify its unique contribution, trace its consequential claims, and assign an owner. You will learn more from that exercise than from rescoring your entire site, and you will have the beginnings of a provenance system that can survive the next detector, watermark, and distribution-policy change.

    References


  • Google Sign-In Gates for More Search Results: An SEO Guide

    Google Sign-In Gates for More Search Results: An SEO Guide

    If you are checking a keyword and Google stops after several result pages with a request to sign in, do not record the blocked page as a lost ranking. A limited Google Search test has required an account sign-in to verify that the searcher is human and reveal more results. The prompt appeared after someone moved beyond the first few pages. That is an access event, not evidence that the underlying results disappeared.

    For SEO teams, that distinction matters. A sign-in gate can interrupt a manual audit, rank tracker, competitive-research workflow, or search-results API without changing the rankings those systems are trying to observe. Your immediate job is to identify the measurement failure, preserve the uncertainty, and avoid turning missing data into a false performance alert.

    What Google appears to be testing

    In the observed flow, Google asked the searcher to sign in to continue after navigating beyond the first few search-result pages. The message framed sign-in as a way to verify that the user was human and provide additional results. A CAPTCHA would normally serve that verification role, so requiring an authenticated account introduces a different kind of barrier.

    The scope is still uncertain. The behavior has been described as a limited test, and there is no confirmation that Google will apply it widely. There is also not enough evidence to define its precise trigger, affected environments, frequency, or duration. One screenshot or one blocked session cannot establish a global rollout.

    Keep the layers separate. Google can restrict access to another page of results without removing those results from its index or changing their order. The prompt also does not prove that the additional results would differ after sign-in, that authentication changes ranking, or that every signed-out user will encounter the same limit.

    Key takeaways

    • The sign-in gate has been observed as a limited test, not a confirmed universal Search feature.
    • It appeared after several result pages, so the immediate risk is reduced access to deep-result data rather than a demonstrated loss of search visibility.
    • A blocked or incomplete retrieval must not be translated automatically into “not ranking.”
    • Manual checks, rank trackers, and search-results APIs may encounter different access conditions, so record how each observation was collected.
    • Change your measurement and reporting workflow before changing content, schema, or SEO strategy.

    Separate a ranking change from a collection failure

    A split scene contrasts stable search-result cards with a data-collection pipeline interrupted by a locked checkpoint.

    A rank tracker typically has to request a results page, parse its contents, and continue far enough to find the tracked domain. A sign-in challenge can stop that sequence before the domain is reached. If the system treats every interrupted search as a completed search with no match, the dashboard may show a dramatic ranking loss that never occurred.

    The correct result is not always a position. Sometimes it is a status: the measurement was blocked before the requested depth. That status may be less satisfying than a number, but it is more accurate and far safer for decision-making.

    What you seeWhat it supportsWhat to do
    A visible sign-in prompt after several pagesAccess to deeper results was interruptedRecord the result as blocked and save the last successfully observed depth
    A tracker returns a blank value or “not found” without diagnostic detailA ranking loss is possible, but a collection failure has not been excludedInspect the collection status or ask the provider how authentication challenges are classified
    First-party search performance remains broadly consistent while deep-rank readings disappearThe case for an immediate visibility collapse is weakerAnnotate the measurement gap and wait for corroborating evidence before escalating
    The prompt appears in one browser or session but not anotherThe behavior is not consistently reproducible in the environments testedDocument both environments rather than selecting the result that fits your expectation

    None of these signals independently proves what the hidden ranking was. They help you decide whether you have evidence of a performance change or merely evidence that the measurement stopped early. That is the standard your reports should preserve.

    Use this diagnostic runbook when the gate appears

    An analyst compares generic search results, a browser checkpoint, network status, timing, and database indicators at a workstation.

    Handle the event as an observability incident. The aim is not to defeat the gate. It is to determine what was measured, what was not measured, and which decisions can still be supported.

    1. Capture the evidence. Save the query, time, market, language, device type, browser, signed-in state, network environment, visible prompt, and deepest result page reached. Take a screenshot if the check is manual. Without this context, a later reproduction attempt will tell you very little.
    2. Identify the last valid observation. Record the final page or result depth that loaded normally. Do not assign an artificial bottom position to domains that might have appeared beyond that point.
    3. Inspect the failure state. Determine whether the collector received a sign-in page, redirect, challenge, empty response, parsing error, or timeout. Those outcomes may look identical in a dashboard while requiring different treatment.
    4. Reproduce lightly. Try a normal signed-out session in a clean browser context. If your organization’s policies allow it, compare that with an ordinary signed-in manual session. Treat both as contextual observations, not as a canonical SERP. Repeated automated requests may trigger more controls and make the test less informative.
    5. Triangulate with first-party data. Review Google Search Console query and page performance, relevant landing-page traffic, and indexing signals. These datasets do not reproduce a manual results page, but they can show whether the supposed ranking collapse has corresponding visibility or traffic evidence.
    6. Preserve uncertainty in the report. Use distinct labels such as “observed,” “not observed within checked depth,” “blocked by challenge,” and “collection error.” A blocked check is not a zero, and a zero is not a verified rank.
    7. Require corroboration before acting. Investigate content, technical SEO, or ranking systems only when the apparent decline is supported by accessible SERPs, first-party performance data, or another reliable signal. Do not rewrite a page because one collector could not pass a gate.

    Questions to ask your rank-tracking provider

    • Can the platform distinguish a sign-in challenge from a completed search in which the domain was absent?
    • Does it expose collection coverage and error status alongside reported positions?
    • Will a failed retrieval overwrite the last valid position, or remain a clearly marked gap?
    • Can reports separate shallow observations from keywords that require deeper retrieval?
    • How are retries handled, and can repeated failures create misleading volatility?
    • Does the provider use authenticated accounts, and if so, what are the security, privacy, and policy implications?

    Do not place an employee’s personal Google credentials into an automated tracker simply to recover deep-result data. That creates security and account-governance risks while potentially changing the conditions under which the results are collected. If authenticated collection becomes part of a vendor’s method, it should be disclosed, controlled, and reviewed rather than improvised.

    Your dashboard also needs a coverage measure. A position chart without collection coverage can make missing observations look like genuine movement. Show how many scheduled checks completed successfully, how many stopped at a challenge, and how deep each successful check reached. When a retrieval fails, retain the prior observation with its original date if historical context is useful, but never present it as a fresh current ranking.

    What this changes for SEO, schema, and AI visibility

    For now, this should change your measurement practice, not your optimization strategy. The observed behavior concerns access to additional search results. It does not establish a change to crawling, indexing, ranking, structured-data processing, or selection by AI answer systems.

    Adding schema will not remove a Google sign-in gate. Rewriting a page will not make an interrupted tracker complete its request. Increasing publishing volume will not repair a collector that classifies an authentication challenge as “not found.” Those actions address different systems.

    Continue content, technical SEO, AEO, and GEO work when independent evidence supports it. If impressions, clicks, accessible rankings, indexation, and business outcomes point to a real decline, investigate the decline. If only deep-result collection fails, fix the reporting model and monitor the test.

    A wider rollout could make deep-result research less complete and force tracking providers to disclose more about coverage. It could also reduce the reliability of competitor lists assembled from a single automated collector. Prepare for that possibility by keeping raw status data, using more than one type of evidence, and distinguishing “unknown” from “absent.” Do not call it a rollout until the behavior is consistently documented beyond an isolated test.

    The next time the prompt appears, save the environment details, mark the observation as blocked, and check first-party performance before anyone changes a page. That small discipline prevents an access-control experiment from becoming a false SEO emergency.

    References


  • AI Crawler Blocking and Publisher Citations: What to Do

    AI Crawler Blocking and Publisher Citations: What to Do

    If you publish original reporting or expert content, AI access can look like a blunt choice: allow crawlers and risk uncontrolled reuse, or block them and risk disappearing from AI answers. That framing is too simple to support a sound policy.

    Your real decision is narrower: which forms of access serve your publishing goals, which ones create unacceptable risk, and what evidence would justify changing the rules? Treating every AI bot as the same crawler makes all three questions harder to answer.

    Blocking is a crawler instruction, not a citation switch

    A rule in robots.txt tells a matching, compliant crawler whether it may request specified URLs. It does not directly tell an answer engine to cite your pages, remove an existing citation, forget previously acquired material, or resolve questions about licensing and content rights.

    That distinction matters because crawler blocking does not produce one consistent citation outcome. An analysis spanning 31 million AI citations and the robots.txt files of 105 publishers found that blocking affected some models but appeared to do nothing on others. This is strong evidence against treating a sitewide block as a universal off switch. It does not establish how every individual engine will respond to your site.

    Several mechanisms can explain why a blocked domain may still appear in an answer. An engine may already hold an older representation of the page. It may encounter the information through syndication, quotation, feeds, links, or another accessible copy. A vendor may also use different access paths for training, indexing, search retrieval, and user-requested page fetching. Blocking one declared user agent controls only that user agent’s future requests to the covered URLs.

    Key takeaways

    • Blocking an AI crawler may change citations in one model and have no observable effect in another.
    • A citation is an output from an answer system; robots.txt governs one input path.
    • Do not use a sitewide block when your actual concern applies only to a particular crawler, content section, or use case.
    • Measure citation coverage, freshness, referrals, and crawl activity before and after a change.
    • Keep every policy change documented and reversible because crawler identities and model behavior can change.

    Separate training, discovery, retrieval, and citation

    A central digital library connects to four separate gated routes for bulk transfer, scanning, single-document retrieval, and a return link to a source.

    Publishers often say they want to block AI when they mean one of four different things. You may object to model training. You may want to prevent a page from entering an AI search index. You may want to stop live retrieval when a user asks a question. Or you may want an engine to stop naming your domain in generated answers.

    Those are not interchangeable objectives. A policy can restrict one access path without producing the desired result at another layer. Before editing robots.txt, write down the exact outcome you want and the evidence that would prove you achieved it.

    Decision layerThe question to answerEvidence to collect
    TrainingDo you permit this vendor to use covered content for model development?The vendor’s documented crawler purpose, your agreements, and applicable rights guidance
    DiscoveryDo you want new and updated URLs available to the engine’s search or retrieval system?Declared crawler activity, discovery of test URLs, and citation freshness
    Live retrievalMay the system fetch a page in response to a user’s request?Server requests associated with controlled prompts and the responses returned
    CitationDoes your domain receive visible attribution in answers that rely on your subject matter?A fixed query set, cited URLs, answer captures, dates, and referral traffic

    Build a crawler registry around those layers. For each user-agent token, record the vendor, declared purpose, official documentation you relied on, current directive, affected paths, date added, internal owner, and next review trigger. A label such as AI bot is not precise enough. If you cannot verify what a token controls, mark it unverified instead of guessing from its name.

    Audit every hostname that serves publishable content. A correct policy on the main domain does not tell you what is served from a separate news, mobile, archive, or syndicated host. Fetch the live /robots.txt file from each relevant hostname, then compare the returned file with the configuration you intended to deploy.

    Choose the policy that matches the value you protect

    There is no universally correct balance between AI visibility and access control. A publisher funded by subscriptions may value exclusivity differently from a specialist publication that depends on discovery and authority. The right policy starts with the business outcome, not with a generic list of bots.

    If AI citations are a discovery channel

    Preserve the access paths that appear to support discovery and retrieval while evaluating training controls separately. Do not assume that allowing every AI-labeled crawler will buy citations. Permission is only a prerequisite for a crawler to request content; it is not a promise that the engine will select, quote, or attribute your page.

    Prioritize the content where attribution has measurable value: original reporting, unique datasets, primary explanations, product documentation, and pages that answer recurring audience questions. Track whether engines cite the canonical page, an outdated URL, a syndicated copy, or another site discussing your work. That URL-level distinction tells you more than a domain-wide visibility score.

    If content control is the primary concern

    Block the verified crawler or protected path that corresponds to the concern, then define what success means. Success might be the end of requests from that declared user agent. It should not automatically be defined as disappearance from every generated answer, because blocking may not remove previously acquired material or copies available elsewhere.

    Do not treat robots.txt as a licensing agreement or a complete legal remedy. It is a technical access signal. If the decision affects contracted syndication, paid archives, copyright enforcement, or material revenue, have qualified legal counsel review the policy and the relevant agreements before you rely on the file as protection.

    If you need a balanced default

    Use selective controls rather than an undifferentiated allow-all or block-all rule. Keep public, citation-worthy pages available to verified discovery or retrieval crawlers when that supports your goals. Apply narrower restrictions to premium sections, private utilities, internal search results, duplicate archives, or other areas that have a different value and risk profile.

    Path-level rules require operational discipline. A careless pattern can cover more URLs than intended, and a later site migration can change what the pattern matches. Pair each directive with a plain-language note describing its purpose and test representative allowed and blocked URLs after every deployment that touches routing, hostnames, or robots.txt.

    Measure a block as a controlled publishing change

    Two matching content setups are observed side by side while an editor changes one removable access gate and leaves the other conditions aligned.

    A citation audit cannot tell you much if the query set, content, and crawler policy all change at once. Use a fixed protocol so that a drop or gain has a plausible connection to the rule you changed.

    1. State the hypothesis. Name the crawler or access path, the URLs affected, the expected outcome, and the downside you are willing to accept.
    2. Create a baseline. Record current directives, server requests, AI citations, cited URLs, answer captures, referral sessions, and publication dates before making the change.
    3. Use a stable query set. Include branded questions, non-branded questions where your content is eligible, and queries tied to newly published material. Keep the wording fixed during the test.
    4. Change one crawler family or content segment. Multiple simultaneous blocks may be quicker to deploy, but they make the result difficult to interpret.
    5. Verify the live rule. Fetch the public file, test representative URLs, and confirm that unrelated search crawlers and content sections retain their intended access.
    6. Observe a normal publishing cycle. Your measurement period must include enough new and updated content to reveal whether discovery and citation freshness changed. A quiet interval cannot test freshness.
    7. Repeat the same checks. Use the same engines, query wording, account state where practical, location assumptions, and capture method. Generated answers can vary, so retain the underlying observations rather than only a summary score.
    8. Compare by engine and URL class. A blended total can hide a decline in one model, an increase in another, or a problem limited to recent reporting.
    9. Keep or reverse the rule. Apply a decision threshold chosen in advance. Document the result even when no effect is visible.

    Define citation coverage as the share of eligible test queries that produce at least one citation to your domain. Record citation accuracy separately: whether the linked page actually supports the claim beside it. Also measure citation freshness as the interval between publication or material update and the first observed citation. These metrics answer different questions. A domain can maintain overall coverage while engines continue citing old pages.

    Referral sessions are useful but incomplete. A visible citation can influence recognition without receiving a click, while an uncited brand mention will not appear in citation counts. Keep citations, mentions, referral traffic, and crawler requests as separate columns so that one metric does not stand in for the whole outcome.

    Server logs provide another necessary check, but declared user-agent strings are not proof of identity on their own. Use the vendor’s current verification method where one is available, retain request details needed for analysis, and classify unverifiable traffic separately. Otherwise, spoofed or mislabeled requests can make a supposedly precise crawler report misleading.

    Watch for confounders before claiming that a directive caused the result. Major content revisions, URL migrations, canonical changes, paywall changes, syndication launches, engine updates, and shifts in publishing volume can all alter citations during the same period. Note those events in the audit log and rerun the test when the result is ambiguous.

    Make the next crawler decision reversible

    Do not deploy a sitewide AI block merely because you expect it to erase citations, and do not allow every AI crawler merely because you want more visibility. Neither expectation is supported as a universal rule.

    Open your live robots.txt file and turn its AI-related directives into a crawler registry now. Give every rule a verified target, a business purpose, an affected URL set, a success metric, and a rollback condition. If a rule has none of those, it is not yet a strategy; it is an assumption running in production.

    References


  • Google June 2026 Spam Update: What Site Owners Should Check

    Google June 2026 Spam Update: What Site Owners Should Check

    Google’s June 2026 spam update completed a short global rollout that applied across languages and locations. The practical challenge now is determining whether a site’s changes are plausibly connected to the update rather than treating every movement as evidence of a spam penalty.

    The two reports establish the rollout’s timing, scope, and purpose while also highlighting an important recovery distinction: correcting a policy problem can support improvement over time, but rankings previously gained through devalued spam links may not return.

    Rollout timing, scope, and context

    The launch report said the update began around noon ET on Wednesday, June 24, 2026. Google described it as a global update affecting all languages and indicated that deployment could take a few days.

    The completion report said Google marked the rollout complete at 2 p.m. ET on June 26. It was the second announced spam update of 2026, following the March spam update. The launch report placed it within a wider run of changes that also included the February Discover update and the March and May core updates.

    Key takeaways

    • The reported rollout ran from June 24 to June 26, 2026.
    • Google said the update applied globally and across all languages.
    • The sources described it as a standard spam update, not specifically as a link spam update.
    • Sites should evaluate changes against the rollout window and review compliance before making broad corrective changes.

    What the update was designed to address

    According to the launch coverage, spam updates improve Google’s automated ability to identify attempts to manipulate search rankings. The report cited SpamBrain, Google’s AI-based spam-prevention system, as an example of the systems involved in detecting established and emerging forms of abuse.

    That purpose does not establish why any individual page gained or lost visibility. The completion report noted that spam updates can sometimes affect sites that were not deliberately trying to manipulate Google. It also characterized this rollout as feeling somewhat larger than the March spam update, but presented no measurement that would turn that impression into a general conclusion.

    How to investigate a possible update impact

    An analyst compares abstract website performance signals across several monitors at a desk.

    A useful assessment separates timing, scope, and cause. Because several named Google updates preceded this rollout, a ranking change should not be attributed to the June spam update solely because it occurred during a busy period.

    1. Confirm the timing. Compare Search Console, traffic, and ranking patterns before, during, and after the June 24-26 rollout window.
    2. Identify the scope. Determine whether the change is sitewide or concentrated among particular pages, queries, or content groups.
    3. Check unrelated explanations. Review recent publishing, technical, tracking, and site-template changes that could produce a similar pattern.
    4. Review Google’s spam policies. Examine the affected areas for practices intended to manufacture ranking signals or otherwise abuse search systems.
    5. Match corrective work to evidence. Address confirmed policy or quality problems instead of making indiscriminate changes based only on temporal correlation.

    Recovery depends on what caused the loss

    A web page at a fork follows one path toward repairs while artificial link structures dissolve on the other.

    The launch report said sites that violate Google’s spam policies may rank lower or disappear from results. After violations are corrected, improvement may occur over time if Google’s automated systems recognize that the site is compliant. This is not presented as an immediate or guaranteed recovery mechanism.

    Link-related losses require a different interpretation. The same report explained that when Google neutralizes the ranking value of spammy links, the advantage previously produced by those links is lost; removing or cleaning up the links does not recreate that former benefit. However, neither source identified the June 2026 rollout as a link spam update, so that limitation should be applied only when the evidence actually points to devalued links.

    The most defensible next step is continued monitoring paired with a focused compliance review. Decisions made from page-level evidence will be more useful than reacting to the rollout label alone, especially while post-update patterns become clearer.

    References