Category: Technical optimization

  • Google UGC Fresh Data Program: A Platform Readiness Guide

    Google UGC Fresh Data Program: A Platform Readiness Guide

    If you operate a forum or social platform, the Google UGC Fresh Data Program could shorten the gap between a useful new discussion appearing on your site and Google processing it for Search. But you need more than popular content or valid schema to qualify.

    Approved platforms can use a dedicated ingestion pipeline to send fresh content and interaction signals. That makes this a platform engineering and content-governance project, not an instant-indexing shortcut. Before you apply, use the following checks to find the gaps that could make your platform ineligible or leave your team unable to operate the pipeline reliably.

    Treat the program as a freshness pipeline, not a ranking switch

    The program gives Google a proactive feed of timely UGC and engagement information. Its purpose is to help fresh, authentic, first-hand perspectives get processed and updated quickly across Search features.

    Search mechanismWhat it doesWhat you should not assume
    UGC Fresh Data ProgramAccepts timely content and interaction data from approved UGC platforms through a specialized pipeline.Submission does not guarantee that a page will appear in Search.
    Traditional crawlingLets Google discover and process publicly accessible web content through its normal systems.The UGC pipeline does not replace crawlable pages, stable URLs, or on-page markup.
    Google Indexing APIOperates independently from this program.The UGC program is not an extension of the Indexing API for general web content.
    Search selectionDetermines whether processed content is shown for a particular search experience.Access to the ingestion pipeline does not create a ranking or inclusion guarantee.

    This distinction should shape your internal business case. You are applying for a faster and more direct way to transmit eligible UGC data. You are not buying a place in the results, bypassing Google’s selection systems, or replacing technical SEO.

    It also matters for AI-search planning. Google has described the destination broadly as Search features; it has not identified a specific AI surface or promised visibility in AI-generated answers. Do not forecast AI citations, AI Overview placements, traffic gains, or ranking improvements as outcomes of acceptance. The defensible goal is narrower: make high-quality, public UGC available to Google with less freshness lag.

    Run this eligibility gate before you apply

    Mark each requirement as Ready, Gap, or Unknown. A Gap means you have implementation work to complete. An Unknown means you need evidence, not a more optimistic interpretation of the requirement.

    1. Your platform is primarily built around UGC. The intended candidates are platforms focused on user-generated content, social posts, or forum discussions. A conventional publisher, ecommerce site, or company blog with a comment section is unlikely to satisfy a requirement that the platform primarily host UGC.
    2. Each submission represents content on its own stable page. Eligible UGC should live on dedicated pages with stable URLs, rather than existing only inside a profile or continuously changing feed. Open several older content URLs and confirm that they still identify the same discussion or post.
    3. You can demonstrate meaningful scale. Google expects a high volume of UGC and a significant user base, but no numeric eligibility threshold has been specified. Prepare accurate internal measurements of publishing volume, active participation, public content inventory, and growth without inventing a cutoff Google has not published.
    4. The content is public and attributable. Users and Googlebot must be able to reach the content without a login or paywall. Every UGC item must also be attributable to a creator who has a public profile. Test this while signed out; an employee’s authenticated browser is not evidence of public access.
    5. Your team can support the technical contract. You need the capacity to implement secure OAuth 2.0 authentication, construct JSON-LD payloads that pass strict validation, and maintain valid schema.org markup on the corresponding web pages.
    6. Moderation is an operating function, not a policy page. The platform must not publish illegal content and must actively moderate its UGC. Users also need a reporting mechanism. Confirm that reports enter a monitored workflow with clear ownership; an unmonitored form does not demonstrate active moderation.
    7. You can move at UGC speed. Content should be submitted as fresh as possible, ideally within minutes. Your systems must also be able to provide regular engagement-counter updates within 72 hours of creation.

    Some of these are hard eligibility conditions, not items to place on a post-acceptance roadmap. Public access, creator attribution, stable content pages, moderation, and reporting need to be properties of the live platform. If they apply only to a small pilot area while most of the platform works differently, document that limitation before deciding whether to apply.

    Align the public page, schema, and submitted payload
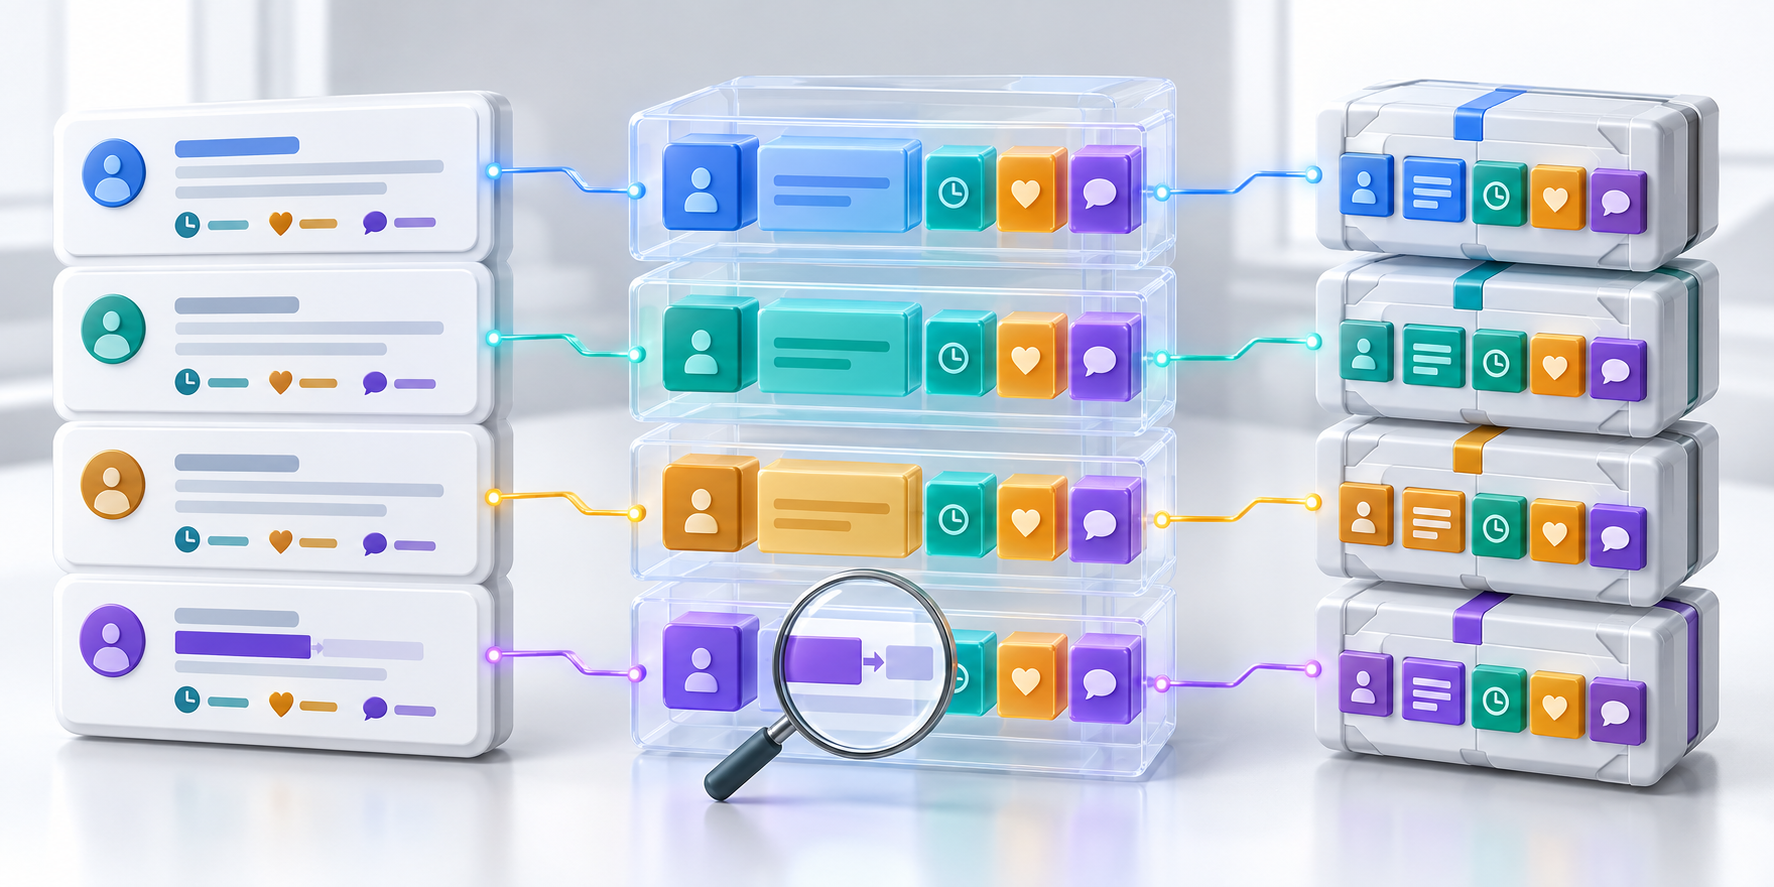
    Matching colored data tokens connect a public discussion page, nested data blocks, and submission payload modules.

    The program creates two structured-data surfaces that your team must keep conceptually separate. One is the schema.org markup embedded on the public URL. The other is the JSON-LD payload transmitted through the dedicated pipeline. Having one does not remove the requirement for the other.

    Google names SocialMediaPosting and DiscussionForumPosting, including interactionStatistic sub-fields, as examples of suitable on-page structured data. Choose a type that describes the content people actually see. Do not label an editorial page as a forum post merely to make it resemble an eligibility example.

    Your safest design uses one internal content entity to generate the public page, the on-page markup, and the pipeline payload. That reduces the chance that the three surfaces disagree about the URL, creator, content state, or engagement totals.

    • Stable content identity: Define which internal record owns the permanent public URL and what happens when a title, category, or moderation state changes.
    • Public creator identity: Map every eligible item to a creator profile that an unauthenticated visitor can open.
    • Schema selection: Record which UGC formats map to SocialMediaPosting, DiscussionForumPosting, or another appropriate schema.org type.
    • Interaction mapping: Identify the counters your product maintains, where their authoritative values live, and how the page and payload will receive consistent updates.
    • Validation ownership: Make one engineering or data team responsible for rejecting malformed payloads before transmission and for detecting broken on-page markup after releases.
    • Eligibility state: Prevent private, gated, removed, unmoderated, or otherwise ineligible records from entering the submission queue.

    Do not guess at undisclosed endpoint behavior or build a production integration around an assumed payload contract. Detailed developer documentation is provided after acceptance. Before then, build the internal mappings, validation boundaries, queue interfaces, and operational ownership that will let you implement the actual contract without redesigning your content system.

    Design for minutes, then keep the counters current
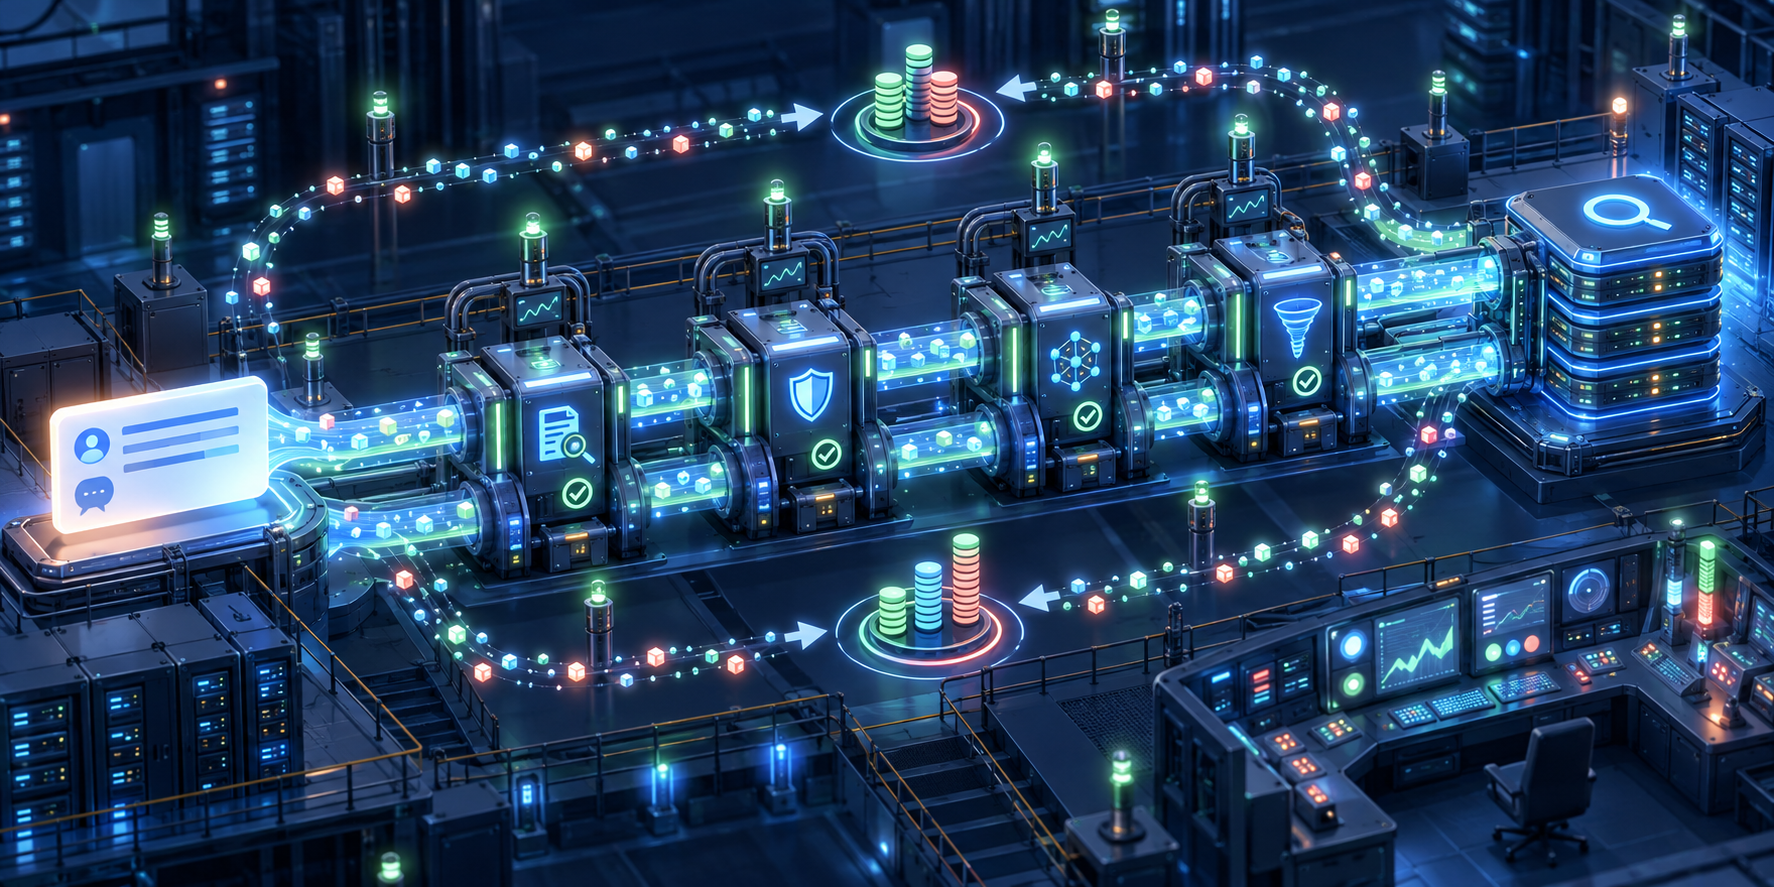
    A glowing discussion card moves through validation checkpoints while interaction particles loop back to update token stacks.

    A nightly export is poorly matched to a program that asks for content within minutes. The publish event should start an observable workflow as soon as the public page, creator attribution, and moderation state are ready.

    1. Commit the public page first. The submitted item should resolve to the dedicated, publicly accessible URL represented by the payload.
    2. Check eligibility at queue entry. Confirm that the item is public, attributed, supported by the correct on-page markup, and allowed by the platform’s moderation state.
    3. Create the submission job immediately. Record the content identifier, public URL, publication time, schema mapping, and payload version so the team can measure delay and reproduce failures.
    4. Authenticate through OAuth 2.0. Keep credentials and token handling within the service responsible for transmission, with access limited to the systems that need it.
    5. Validate before sending. A fast malformed submission is still a failed submission. Block payloads that do not satisfy the accepted contract and route them to a visible error queue.
    6. Record every outcome. Preserve enough information to distinguish validation failures, authentication failures, delivery failures, and records that never entered the queue.
    7. Schedule engagement updates. Send the required counter updates within the 72-hour window instead of treating the initial content submission as the end of the job.
    8. Plan correction controls. Once the developer documentation defines update and deletion behavior, add explicit handling for edited, removed, restricted, or re-moderated content rather than improvising those cases in production.

    Use operational measurements that expose where freshness is being lost. Track publication-to-queue delay, queue-to-delivery delay, validation failure rate, authentication failure rate, the age of the latest engagement update, and the share of eligible records that never produced a job. These measurements do not prove Search inclusion, but they do show whether your side of the pipeline is working.

    Assign alerts to people who can act on them. A dashboard that nobody owns will not protect a minutes-level workflow. The runbook should identify who handles expiring credentials, schema regressions, queue backlogs, counter discrepancies, and moderation-state changes.

    Apply with evidence your platform is ready to operate

    The application should make it easy to verify that your platform fits the program and can support the integration. Assemble a readiness packet before completing the form, even if the form does not request every artifact directly.

    • A concise description of the platform’s UGC model and the people who create the content.
    • Accurate measurements showing UGC publishing volume, public content inventory, and user participation.
    • Representative content URLs that work in a signed-out browser and remain tied to one discussion or post.
    • Representative public creator profiles connected to those content pages.
    • A URL-lifecycle explanation covering edits, moves, removals, and privacy changes.
    • Examples of valid on-page SocialMediaPosting or DiscussionForumPosting markup, where those types fit.
    • A data-flow diagram showing how a publish event can reach the submission queue within minutes and how engagement counters are refreshed within 72 hours.
    • The team responsible for OAuth 2.0, payload validation, monitoring, and incident response.
    • Your moderation process, user-reporting path, and operational ownership for reports.

    Apply when you can support those claims with live examples and named owners. Google provides an application form and indicates a six-to-eight-week wait for a status response. Treat that as a response window, not a promise of acceptance, implementation, or Search visibility.

    Use the waiting period to keep improving normal crawl access, on-page structured data, moderation coverage, and pipeline observability. The specialized feed is independent of traditional organic crawling, and participation does not guarantee inclusion, so pausing ordinary SEO work would create the wrong dependency.

    Key takeaways

    • Apply now if UGC is your platform’s primary content, individual posts have stable public URLs, creators have public profiles, moderation and reporting are active, and your team can meet the technical and freshness requirements.
    • Delay the application if public access, creator attribution, on-page schema, OAuth 2.0 ownership, payload validation, or engagement updates still depend on unplanned work.
    • Assume the program is a poor fit if the platform is not primarily UGC, the meaningful content exists only in feeds or profile pages, or users must log in or pay to view it.
    • Measure delivery, not rankings when evaluating the integration. Acceptance can improve the path by which fresh UGC reaches Google, but it does not guarantee indexing, rankings, Search traffic, or AI visibility.
    • Keep normal SEO running because the dedicated pipeline remains separate from traditional crawling and Search selection.

    Your next move is a concrete audit. Take the 20 newest UGC URLs on your platform and open each one while signed out. Check the stable URL, visible content, public creator profile, schema type, interaction markup, and reporting route. Then trace each publication event through your proposed submission and counter-update workflow. If the same failure appears across the sample, fix the underlying platform rule before applying. If the sample passes, compile the evidence, submit the application, and use the response window to harden the pipeline.

    References


  • Google Crawl-to-Serving Timelines: How to Diagnose Delays

    Google Crawl-to-Serving Timelines: How to Diagnose Delays

    You changed a page, but Google still shows the old title, selects another canonical, omits the URL, or leaves its rankings unchanged. It is tempting to call every one of those outcomes a crawling delay. That label is too broad to tell you whether to wait or intervene.

    Treat search visibility as a sequence of handoffs. First identify the last handoff that completed. Then investigate the next one. This gives you a defensible timeline and keeps you from changing a page repeatedly while Google is still processing an earlier version.

    A crawl is only the first handoff

    An updated webpage moves from a retrieval machine through scanning, archive, comparison, and display stages in a digital facility.

    There is no universal timer that starts when you press Publish and ends when the page appears exactly as intended in search. Several distinct events have to occur:

    1. Discovery: Google learns that the URL exists or has changed.
    2. Crawling: Google requests the URL and receives a response.
    3. Rendering and processing: Google evaluates the returned document, including content that depends on rendering.
    4. Indexing and canonicalization: Google determines what the page represents, whether it belongs in the index, and which URL should represent substantially similar content.
    5. Serving: Google decides whether and how to show the indexed result for a particular query.

    Passing one stage does not prove that the next stage has finished. A Googlebot request in your server logs proves a fetch occurred; it does not prove indexing. An indexed URL is eligible to appear, but it is not guaranteed to rank for the query you care about. A result appearing in search does not guarantee that Google will use your preferred title, snippet, canonical, or structured-data presentation.

    Discovery, refreshes, sitemap processing, robots.txt controls, rendering, indexing, link annotations, removals, canonicalization, structured data, titles, snippets, core updates, and spam updates all have their own typical and slowest processing bands. Your deployment time therefore is not a reliable prediction of when every downstream search signal will change.

    Set your expectation from the change you made

    The right clock depends on what changed. Before diagnosing a delay, name the exact search outcome you expect.

    • A new URL must be discovered, crawled, processed, considered for indexing, and then served. Finding it in a sitemap is only an early step.
    • Updated body copy requires another crawl and another round of processing. The live page can be correct while Google’s stored understanding still reflects an earlier version.
    • A title or description change is not complete merely because Google has fetched the page. Serving systems still decide what representation is useful for a query, so your supplied text may not be shown verbatim.
    • A canonical change asks Google to reconsider a cluster of related URLs. The canonical element matters, but internal links, redirects, sitemap entries, and duplicate-page signals should point in the same direction.
    • A robots, noindex, or removal change depends on Google being able to encounter and process the relevant control. Do not block a URL in robots.txt and assume Google can then fetch a page-level noindex directive from it.
    • Structured-data changes require valid markup to be found and processed. Validity can establish eligibility for a search feature; it does not guarantee that the feature will be served.
    • Internal-link changes can affect discovery and link annotations, but they do not create an immediate ranking promise.
    • A sitewide ranking change may belong to a broader ranking or spam-system rollout rather than the crawl status of one page.

    Use a typical range as a planning expectation and a slowest range as a prompt to investigate. Neither is a service-level guarantee. One spam-update benchmark put a typical change at one to two days, while the September 2026 spam update was expected to roll out over two weeks. Resubmitting one URL cannot shorten a system-level rollout. Rollout duration and URL-processing time answer different questions.

    Diagnose the symptom before deciding to wait

    Do not begin with the age of the change. Begin with the observable mismatch between the live page and Google’s current state.

    What you observeHandoff to inspectWhat to do next
    No crawl or discovery signal for the URLDiscovery and accessConfirm the URL returns the intended response, is not accidentally blocked, appears in an appropriate sitemap, and is linked from a crawlable page that Google already knows.
    Google fetched the URL, but important content is absent from the processed pageRenderingCompare the initial HTML with the rendered output. Make essential content and links available reliably, and fix failed or blocked resources rather than waiting for another identical render.
    The page is crawled, but another URL is selected as canonicalCanonicalizationCheck for conflicting canonical elements, redirects, internal links, sitemap URLs, and near-duplicate pages. Align those signals before requesting another crawl.
    The correct URL is indexed, but its title, snippet, or rich-result treatment is stale or differentServing and presentationVerify that the current HTML contains the intended information and that structured data is valid. Then allow time for reprocessing, while remembering that Google can generate a query-specific presentation.
    The indexed page is current, but impressions or rankings have not improvedRanking and query fitStop treating the issue as crawl latency. Examine whether the page satisfies the target intent, offers distinctive information, and has enough internal prominence and authority to compete.
    Many pages shift during a named search updateSystem rolloutSeparate rollout monitoring from page-level debugging. Avoid drawing a final conclusion from an incomplete rollout or making several unrelated sitewide changes at once.

    Google Search Console can help you locate the handoff. For an affected URL, compare the indexing status, last crawl information, Google-selected canonical, and inspected page with the live version. Server logs can confirm whether Googlebot requested the URL. A rendered-page check can reveal whether essential content was available during processing.

    Interpret each signal narrowly. A successful live test shows that Google can access the page now; it does not establish what happened during an earlier fetch. A crawl in the logs establishes retrieval, not indexing. An indexing status establishes index state, not rankings. Keeping those distinctions intact prevents false diagnoses.

    Build a release log that preserves the evidence

    Three preserved webpage versions are arranged beside a server model, clock, camera, archive sleeves, and magnifying glass.

    A useful crawl-to-serving timeline begins with your own deployment record. Without one, teams tend to compare today’s search result with an uncertain memory of what changed and when.

    1. Record the deployment. Save the timestamp, affected URL or template, old state, new state, and the specific result you expect Google to change.
    2. Classify the expected handoff. Decide whether success means discovery, a fresh crawl, corrected rendering, indexing, canonical selection, a new search presentation, or a ranking response.
    3. Verify production immediately. Check the response status, final URL after redirects, canonical element, robots directives, robots.txt access, rendered main content, internal links, and sitemap entry where relevant.
    4. Capture a baseline. Save the current Search Console state and relevant server-log evidence. If you later see a different crawl date or canonical, you will know which stage moved.
    5. Request reprocessing only when it helps. An indexing request can encourage another look at a limited set of important URLs, but it does not remove the later indexing, canonicalization, ranking, or serving decisions.
    6. Change one cause at a time. Rewriting content, changing canonicals, altering internal links, and resubmitting the URL together may produce movement, but you will not know which intervention mattered.
    7. Escalate by pattern. One delayed URL points toward page-level access, content, duplication, or canonical signals. A delayed template group points toward rendering, directives, linking, or sitemap generation. A sitewide movement may require update-level analysis.

    Repeatedly requesting indexing without correcting a contradictory signal is not a diagnosis. Neither is changing the page every day. Both actions muddy the sequence you need to observe. Once production is technically sound, preserve the version long enough to see whether the next handoff completes.

    Key takeaways

    • Crawl-to-serving is a chain of separate processes, not one countdown from publication.
    • A crawl proves retrieval. It does not, by itself, prove rendering, indexing, canonical selection, ranking, or the final search presentation.
    • Set your expectation from the changed element: a new URL, canonical, title, structured-data block, internal link, or ranking signal can follow a different path.
    • Use typical timing as a planning band and slowest timing as an investigation trigger, not as a guaranteed deadline.
    • Diagnose the first incomplete handoff and correct its inputs before requesting another crawl.

    For your next release, write down the first Google-visible signal that should change and where you will verify it. If that signal appears but the next one does not, move your investigation forward one stage. If nothing has reached the first stage, fix discovery or access before spending time on rankings.

    References

  • Crawl Budget and Pagination: A Technical SEO Playbook

    Crawl Budget and Pagination: A Technical SEO Playbook

    If your products or archive posts disappear after page 1, reducing the number of crawlable URLs can feel like the obvious fix. It often is not. Pagination may be the only internal route that exposes deeper items, so removing it can turn crawl waste into orphaned content.

    The better objective is controlled discovery: give crawlers a finite, stable sequence through valuable content while preventing filters, sort orders, tracking parameters, and duplicate URL formats from multiplying that sequence. You protect crawl capacity by removing useless paths, not by hiding useful ones.

    First decide whether you have a crawl-budget problem

    Crawl budget is the time and computing resources a crawler is prepared to spend on your site. For Googlebot, it reflects both crawl capacity and crawl demand. Capacity concerns what your server can handle without becoming unstable. Demand concerns which URLs appear valuable or in need of another visit.

    Those two forces create different problems. Slow responses and server errors can cause a crawler to reduce its pace. Duplicate, low-value, or spam-like URL patterns can reduce the apparent value of fetching more URLs. A pagination fix cannot compensate for an unreliable server, and faster hosting cannot make an unlimited set of filter combinations worth crawling.

    Google’s criteria for active crawl-budget management are narrower than many teams assume. The clearest candidates are sites with more than 1 million unique pages, medium or large sites whose content changes frequently, and sites with many URLs marked “Discovered – currently not indexed” in Google Search Console.

    That does not mean a smaller site can skip the audit. Your catalog, article count, or CMS dashboard does not reveal the number of URLs a crawler can encounter. Facets, pagination, alternate parameter orders, languages, locations, search pages, and session values can turn one content set into many crawlable representations.

    • Inventory the exposed URLs. Crawl from the same public entry points available to search engines. Do not begin with a spreadsheet of products or posts.
    • Group URLs by pattern. Separate canonical content, pagination, filters, sort orders, internal search, tracking parameters, and malformed combinations.
    • Distinguish discovery from indexing. A URL that has never been fetched points to a different constraint than a fetched page that was judged unworthy of indexing.
    • Check server behavior. Look for timeouts, error responses, and URL patterns that require disproportionately expensive rendering or database work.

    There is no universal healthy number of crawls per day. A useful baseline is whether important new or changed URLs are discovered and revisited while requests to low-value patterns remain controlled. Measure that outcome on your own site instead of copying another domain’s crawl rate.

    Build pagination as discovery infrastructure

    A finite chain of page modules connects a category platform to multiple groups of content cards.

    Pagination divides one ordered content set into addressable pages. It adds URLs, but those URLs provide paths to products, posts, discussions, and other deeply nested content. That is productive crawl activity when each page exposes items that would otherwise be difficult to reach.

    A crawler should be able to begin at the first category or archive page, follow ordinary HTML links through the sequence, and reach every intended item. It should not need to click a JavaScript-only button, submit a form, maintain a session, or scroll until client-side code decides to load another batch.

    1. Choose one stable URL format. Formats such as ?page=2 or /page/2/ can work. Do not expose multiple formats for the same sequence.
    2. Use links with href destinations. Previous and next controls should be crawlable links. A short set of numbered links can provide additional routes into a long sequence.
    3. Link every listed item directly. Products and posts should have canonical destination URLs in the rendered listing, not destinations assembled only after an interaction.
    4. Give each page a distinct slice. Page 2 should not reproduce page 1 under a different URL. Stable ordering also reduces unnecessary repetition when crawlers revisit the sequence.
    5. Use a self-referencing canonical by default. If page 2 contains a distinct set of items, pointing its canonical to page 1 misrepresents that relationship. Consolidate only URLs that are genuinely equivalent.
    6. Keep page 1 canonicalized consistently. Link to one preferred first-page URL instead of alternating between the clean category URL and a duplicate such as ?page=1.
    7. Give infinite scroll a paginated fallback. Each batch should be available at a stable URL through crawlable links, even if human visitors receive a continuous visual experience.
    8. Stop at the real end of the sequence. Do not generate an endless run of empty page numbers. Remove internal links to pages beyond the last valid result and return an appropriate not-found response when an invalid page is requested.

    Do not automatically canonicalize every paginated URL to the first page or apply a blanket noindex directive. Overly aggressive canonicalization can prevent useful paginated URLs from appearing in search results, while removing their crawl value can make deeper items harder to find. A canonical signal expresses a preferred equivalent; it is not a general crawl-control switch.

    An XML sitemap helps crawlers discover canonical products, posts, and other destination pages, but it does not replace internal linking. Pagination remains an additional discovery route even when sitemaps are present. That route also shows how the content belongs within your site architecture.

    Do not spend engineering time adding rel=prev/next solely for Google. Google disclosed in March 2019 that it had stopped using that markup. There is little evidence that the tags now improve Google crawling. Stable URLs and ordinary internal links do the essential work.

    Control the URL multipliers surrounding pagination

    A central route carries unique page tiles forward while barriers stop surrounding branches from producing duplicates.

    Pagination is often blamed for an explosion created elsewhere. A page parameter moves through an ordered set. A facet creates a subset. A sort parameter rearranges a set. A tracking parameter records attribution. Treating all four as interchangeable leads to the wrong controls.

    Consider a category with filters for material, color, size, availability, and price. If every combination can be reordered, paginated, and expressed in several parameter orders, each useful category sequence gains a large number of low-value variants. Faceted navigation and uncontrolled URL creation can make a site far larger than its owners expect.

    URL classIts roleRecommended default
    Primary category or archiveMain landing page for a content setIndexable, internally prominent, and self-canonical
    Page 2 and deeperContinuation and item discoveryCrawlable, linked in sequence, and normally self-canonical
    Curated facet with standalone valueStable subset that serves a distinct needExpose deliberately, give it a consistent URL, and support it with useful content and links
    Sort or filter variant with no standalone valueAlternate presentation of an existing setKeep it out of routine crawl paths; consolidate only when it is truly equivalent
    Tracking or session URLMeasurement or temporary stateRemove it from internal links and point users and bots toward the clean destination
    Empty or out-of-range pageNo useful contentRemove links to it, omit it from sitemaps, and return an accurate response

    Turn that classification into generation rules in the CMS or commerce platform. Cleanup at the crawler level is less effective if templates continue manufacturing new variations.

    • Whitelist intentional facets. Link only to combinations that have a defined user and search purpose. A usable filter does not automatically need an indexable landing page.
    • Normalize parameter order and naming. The same state should not be reachable as several URLs merely because parameters were added in a different sequence or aliases were used.
    • Keep tracking values out of internal links. Campaign parameters belong at acquisition boundaries, not in persistent navigation, breadcrumbs, related-item modules, or pagination controls.
    • Prevent impossible combinations. Do not render links to empty intersections or filters that cannot change the result.
    • Limit pagination to valid result pages. Calculate the actual last page and avoid links to arbitrary higher values.
    • Consolidate exact duplicates. Redirect duplicate URL formats when the equivalence is permanent. Use canonical signals when an alternate representation must remain available, but do not label materially different subsets as duplicates.

    Be careful with robots.txt. Blocking a pattern may reduce requests, but it also prevents the crawler from seeing page-level canonical or noindex signals on those URLs. More importantly, a broad rule can remove the only route to products buried in a filtered or paginated set. First confirm that every valuable destination has another crawlable path. Then remove unwanted internal links and duplicate generation at the source. Use crawling restrictions only after you know what they will cut off.

    The same caution applies to noindex. Indexing eligibility and crawl access solve different problems. A noindex directive can keep a low-value result page out of the index, but the page still has to be crawled for that directive to be read. If the real problem is an unlimited URL generator, noindex alone leaves the generator running.

    Audit the path from category page to destination URL

    A useful audit must show both what your site exposes and what crawlers actually request. A crawler simulation, server logs, and Google Search Console answer different parts of that question. None is sufficient alone.

    1. Crawl from public entry points. Use Googlebot or Bingbot settings and begin at the homepage, major category pages, and XML sitemaps. Crawling as the search bot sees the site reveals a more realistic exposed URL count.
    2. Export every discovered URL with its pattern. Record status code, canonical target, indexability, referring page, crawl depth, and whether the URL appeared in a sitemap.
    3. Map representative page sequences. For each important template, follow page 1 to page 2, a middle page, the last page, and several item destinations. Verify that links exist in the rendered HTML and that each page returns the expected slice.
    4. Find canonical destinations with no internal links. A product listed in a sitemap but absent from navigation is still weakly connected. Determine which category or archive should provide its durable route.
    5. Analyze server logs by crawler and URL pattern. Separate requests for canonical destinations, pagination, facets, sorting, tracking parameters, errors, and redirects. This shows whether crawl activity supports discovery or loops through variants.
    6. Inspect “Discovered – currently not indexed” samples. Identify whether affected URLs are valuable destinations, duplicate parameters, or deep items whose only route is fragile pagination. The remedy depends on that classification.
    7. Check capacity signals. Compare bot requests with slow responses, timeouts, and server errors. Because poor server response can cause a crawler to reduce fetching speed and connections, reliability fixes may precede URL-policy changes.
    8. Repeat the crawl after deployment. Confirm that intended destinations remain reachable and that removed patterns are no longer linked. Do not judge success only by a smaller URL total.

    Prioritize by consequence. Server failures and unbounded URL generation can affect the entire site. Broken page-to-page links can isolate whole sections. Duplicate first-page formats are usually narrower. Metadata refinements on page 27 matter less than restoring the link that allows a crawler to reach page 27 at all.

    Track a compact set of outcome measures rather than one headline crawl count:

    • The share of intended canonical products or posts reached during a full crawl.
    • The number of valuable destination URLs with no crawlable internal link.
    • The share of verified bot requests spent on noncanonical parameter patterns, redirects, errors, and empty pages.
    • The recurrence of server errors or slow responses during crawler activity.
    • The time between a meaningful content change and the next verified bot request, using CMS timestamps and logs.
    • The trend and URL composition of “Discovered – currently not indexed” in Google Search Console.

    Segment AI crawler traffic separately from Googlebot and Bingbot. AI agents and bots add their own access and resource considerations, so their requests should not be folded into one generic bot total. The broadly compatible foundation is still the same: stable URLs, accessible HTML links, accurate responses, deliberate crawler rules, and a server that remains healthy under load.

    Key takeaways

    • Optimize crawl paths, not the smallest possible URL count. Useful pagination can increase URL volume while improving discovery.
    • Keep each valid paginated page stable and crawlable. Use direct HTML links, distinct result slices, one URL format, and self-referencing canonicals by default.
    • Treat facets as the main multiplier. Whitelist intentional combinations and stop templates from linking arbitrary filter, sort, tracking, and pagination permutations.
    • Do not use canonical, noindex, and robots.txt interchangeably. They address consolidation, indexing, and crawling respectively, and a careless rule can hide the only path to valuable content.
    • Prove the result with three views. A site crawl shows what can be reached, logs show what bots request, and Search Console shows how Google processes discovered URLs.

    Start with one high-value category rather than changing the whole site at once. Export its complete page chain, list every parameter variation the templates expose, and trace several deep items back to crawlable category links. If you cannot reach every intended item without entering arbitrary parameter states, fix that path first. Once the model works, apply the same URL rules to the remaining templates.

    References


  • How to Tell Whether an SEO Audit Is Worth the Money

    How to Tell Whether an SEO Audit Is Worth the Money

    You have an SEO audit proposal in front of you, but the deliverables sound suspiciously like a list of errors from a crawling tool. The price may buy expert investigation, or it may buy an export you could generate yourself.

    The difference is judgment. A valuable audit identifies which findings are real, explains why they matter to your business, accounts for intentional choices and technical constraints, and gives your team a safe order of operations. Use the framework below before signing a proposal or implementing recommendations from an audit you have already received.

    Start with the decision the audit must unlock

    An audit cannot be valuable in the abstract. It has to help you make a decision: what to repair, what to improve, what to leave alone, and where to invest next.

    Write the audit’s job as one sentence before discussing tools or deliverables. For example:

    • Find out why commercially important pages are not being crawled, indexed, or discovered.
    • Determine whether a site migration introduced technical problems that are suppressing organic visibility.
    • Identify which content gaps prevent the site from satisfying the audience’s most important questions.
    • Separate genuine technical defects from warnings that do not affect search performance.
    • Assess whether search and AI visibility lead visitors toward a meaningful conversion.

    That sentence becomes your first acceptance criterion. If a recommendation does not help answer the stated question, it should not outrank work that does.

    The auditor also needs context that a crawler cannot collect on its own. At minimum, provide your business goals, priority audiences, important products or services, conversion paths, recent site changes, platform constraints, known technical debt, and any SEO decisions your team made intentionally. Without that context, an automated warning can easily be mistaken for a defect. Implementing the resulting recommendation may waste development time or reduce visibility instead of improving it.

    AI search does not make this discovery work optional. Many large language model experiences use retrieval and existing search results to find information with which to construct or check an answer. Your pages still need to be accessible, indexable, relevant, credible enough to surface, and useful once someone arrives. That makes an effective SEO audit part technical review, part content evaluation, and part business analysis. Calling the same crawler export a GEO audit does not add value.

    A valuable audit adds judgment to crawler data

    A specialist inspects a layered website structure with a magnifying lens while automated devices flag both harmless details and one broken connection.

    Crawlers are useful. They can expose URLs, response behavior, directives, internal linking patterns, metadata, and other machine-readable signals at a scale that manual browsing cannot match. The mistake is treating those observations as conclusions.

    This distinction matters because professional audits can cost from $2,500 to more than $20,000, depending in part on the size of the site and the engagement. Screaming Frog and Sitebulb cost a fraction of that amount, and trial access may be available. Run one of them against your site before buying an audit. You do not need to become a technical SEO; you only need enough familiarity to recognize when the final deliverable reproduces automated output without adding analysis.

    Part of the workLow-value outputUseful audit work
    DiscoveryRepeats crawler warnings and severity labelsCombines automated findings with manual investigation
    ContextAssumes every unusual configuration is wrongChecks business intent, technical debt, templates, and platform constraints
    EvidenceNames an issue without showing its scopeProvides affected URLs, patterns, or examples when they are needed
    ExplanationUses generic wording that could describe any siteExplains what is happening on your site, why it matters, and what may have caused it
    RecommendationIssues a universal command such as fix all or remove allTailors the action to your goals and identifies exceptions, dependencies, and risks
    PriorityCopies a tool’s high, medium, or low labelOrders work by likely business impact, effort, confidence, and potential downside
    HandoffEnds with a list of tasksClarifies ownership, implementation needs, and how the result will be checked

    Ask the auditor to walk you through one finding using that table. A convincing answer should distinguish what the tool detected from what manual review established. It should connect the issue to your audit objective, explain the proposed change, identify what could be affected, and state how your team will know whether the change worked.

    Generic explanations are another warning sign. Crawler documentation often explains why a category of warning may matter. Paying an expert makes sense when the expert can determine whether it matters here. A useful explanation names the relevant part of your site and shows the path from observation to consequence. If the same paragraph could be pasted into an audit for an unrelated company, it is probably documentation rather than analysis.

    Test every recommendation before it enters the backlog

    A technical team tests a website component in a transparent staging chamber before moving it toward a balanced production structure.

    A long audit can feel substantial while still being difficult to use. Do not judge it by page count, warning count, or the number of charts. Judge each recommendation by whether your team can verify, understand, execute, and measure it.

    Is the finding valid?

    Start with the evidence. Which URLs, page types, templates, queries, or journeys are affected? Is the pattern consistent? Did manual review confirm the crawler’s interpretation? Could the behavior be intentional?

    A tool can tell you that two pages look similar or that a directive blocks crawling. It cannot reliably decide whether the pages serve different audiences or whether the directive protects low-value areas from unnecessary crawling. The audit should resolve that ambiguity, not hide it beneath a severity label.

    Is the finding material?

    Connect the issue to a meaningful outcome. Does it prevent discovery or indexing? Does it weaken the page’s relevance for an important audience? Does it make a valuable page harder to navigate? Does it obstruct the conversion path?

    Not every technically imperfect detail deserves engineering time. An audit should make that trade-off visible. The useful question is not whether a warning exists; it is whether resolving that warning is a better use of resources than the competing work in your backlog.

    Is the recommendation executable and safe?

    Your implementation team should be able to identify the target, desired behavior, dependencies, owner, and exceptions. The auditor should provide examples where that falls within their expertise. Where it does not, they should still explain what needs to change and why, then identify the type of specialist required.

    Be especially careful with recommendations that affect server configuration, templates, directives, canonicals, redirects, or large groups of URLs. A blanket change can alter access to far more pages than the audit intended. Do not send ambiguous instructions straight into production. Have a qualified developer define the implementation, use your normal review and testing process, and preserve a rollback path.

    Can you verify the result?

    Define completion before implementation. A technical change may be complete when the intended URLs return the expected behavior and the crawler confirms no unintended pattern. A content change may require checking discovery, relevant search visibility, qualified visits, and the next step in the conversion journey.

    Separate implementation validation from performance evaluation. The first asks whether the change was deployed correctly. The second asks whether it improved the outcome that justified the work. Without both, your team can close tickets without learning whether the audit created value.

    For a fast review, label every recommendation Keep, Clarify, or Reject. Keep it when the evidence, consequence, action, risk, and validation plan are clear. Mark it Clarify when one of those elements is missing. Reject it when manual review disproves the finding, the action conflicts with an intentional decision, or the likely value does not justify the risk and effort. This turns an intimidating report into a governed backlog.

    Protect the engagement in the scope and contract

    You should know what will be delivered before the crawl begins. A strong scope does not merely promise an SEO audit. It describes the investigative work, the form of the evidence, the method of prioritization, and the handoff.

    • Manual review: Require investigation beyond crawler, analytics, or LLM output.
    • Site-specific reasoning: Require each material finding to explain its relevance to your site, audience, and business objective.
    • Evidence: Specify that affected URLs, templates, examples, or patterns will be included where needed.
    • Prioritization: Ask for impact, confidence, effort, dependencies, and implementation risk rather than tool-generated severity alone.
    • Handoff: Define whether the fee includes a walkthrough, questions from developers, implementation examples, or post-change validation.
    • Exclusions: Record what the auditor will diagnose but cannot implement, and who is expected to own that work.
    • Early notification: Require the auditor to tell you if manual investigation finds nothing material beyond automated output.

    A refund or scope-change provision can make the final point enforceable. One practical starting point is: The deliverable must include material findings from manual review and site-specific reasoning beyond automated crawler or LLM output. If the auditor determines that no such findings exist, the parties will agree to a revised scope or an appropriate partial refund before final delivery. A deliverable consisting solely of automated output triggers a full refund.

    That language carries commercial and legal consequences, so have your procurement team or counsel adapt it to the engagement and local requirements. The purpose is not to prohibit crawlers or AI assistance. Those tools can support the work. The provision makes clear that your fee purchases human discovery, interpretation, and prioritization rather than undisclosed automation.

    If the investigation finds that a full audit is unnecessary, do not force production of a padded report. Agree on the useful alternative before the work continues. Depending on the professional’s actual skills and your original goal, the remaining effort might be redirected toward content, development planning, conversion analysis, analytics, or another defined need. Document the revised deliverable and price so goodwill does not replace accountability.

    You can also evaluate the auditor’s fit before signing. The relevant expertise depends on the question you need answered. A crawl and indexation problem calls for strong technical and development literacy. A visibility problem may require content and audience analysis. An engagement expected to connect traffic with revenue needs analytics and conversion competence. No individual has to implement every discipline, but the proposal should state where the auditor’s expertise ends and how gaps will be handled.

    Key takeaways

    • An audit fee should buy judgment, prioritization, and a safer decision path, not merely crawler data.
    • Define the business question first; recommendations that do not help answer it should not dominate the backlog.
    • Run a crawler yourself before hiring so you can distinguish automated output from expert investigation.
    • Require manual review that accounts for your audience, goals, intentional decisions, technical debt, and conversion path.
    • Accept a recommendation only when its evidence, consequence, action, risk, ownership, and validation method are clear.
    • Put site-specific deliverables, early notification, scope revision, and refund terms in the agreement before work begins.
    • Evaluate AI-search readiness through the same fundamentals: accessible and indexable pages, relevant content, sufficient visibility, and a useful destination for the visitor.

    Open the proposal or completed audit now and highlight where it promises manual discovery, site-specific reasoning, prioritized action, implementation safeguards, and validation. Ask for a revision wherever one of those elements is absent. If recommendations have already reached your backlog, place the ambiguous ones on hold until someone can supply the missing evidence or context.

    The right audit leaves you with fewer uncertainties, not simply more tasks. Buy it when you need informed decisions that your tools and internal context cannot produce separately.

    References


  • Search Console Indexing Data Gap: What to Check First

    Search Console Indexing Data Gap: What to Check First

    Your Page indexing chart runs normally, goes blank for several June dates, and then resumes. That pattern can look like mass deindexing at first glance. It is not. A missing observation is not a zero, and it does not show that Google removed your URLs.

    The June 2026 pattern was broadly observed across Search Console profiles. Google’s John Mueller said the Page indexing report was not updated during the affected period and the missing indexing data would not be backfilled. Your immediate job is therefore to confirm that your graph has the same fingerprint, verify the site’s present condition with independent evidence, and preserve the gap honestly in your reporting.

    Key takeaways

    • A blank interval in the Page indexing chart means data is unavailable. It does not mean that zero pages were indexed.
    • Matching June dates across unrelated Search Console properties strongly supports a platform reporting gap, especially when data resumes afterward.
    • The missing history cannot tell you what happened inside the gap. Current URL checks, server logs, technical controls, and search activity can tell you whether a problem exists now.
    • Do not change canonicals, robots directives, noindex rules, or sitemaps just to repair the chart. Those actions cannot recreate missing report data.
    • Record the affected dates as unavailable, not zero. Do not interpolate the gap and present the result as observed Search Console data.

    Confirm that you are looking at the June reporting gap

    Start with the shape of the graph. A decline and a data gap are different events. A decline gives you plotted values that move downward. A data gap removes observations from the time series altogether. Neither pattern proves its cause, but confusing one for the other sends the investigation in the wrong direction.

    1. Capture the visible boundaries. Record the first and last missing dates shown in each affected property. Use the dates in your own interface rather than copying a range from somebody else’s screenshot.
    2. Distinguish an empty interval from a zero value. If the chart has no point or line for a date, treat the value as unavailable. Do not enter zero indexed pages in a spreadsheet or dashboard.
    3. Compare properties. If you manage unrelated sites, check whether their Page indexing charts lose the same June dates. A synchronized hole across separate hosts is much more consistent with a reporting problem than with simultaneous technical failures on every site.
    4. Inspect the values on both sides. Data resuming near its earlier range supports the reporting-gap explanation. A substantially different level after the gap deserves attention, but it still does not reveal when or why the change occurred.
    5. Write down any contradictory evidence. Unexpected URL Inspection results, changed server responses, new robots rules, organic landing-page losses, or a recent deployment should be investigated on their own merits.

    This check identifies what the chart can and cannot prove. It cannot prove that every URL remained indexed during the missing period. It also cannot support a claim that URLs were dropped. The observations needed to answer that historical question are absent.

    Validate present indexing with independent evidence

    Three diagnostic signals converge on an intact website structure to represent independent indexing checks.

    Once you have identified the reporting gap, switch from trying to recover the graph to checking the site’s current condition. Use evidence that comes from the URLs, your infrastructure, and search outcomes. No single check replaces the missing history, but agreement across these layers gives you a defensible operational decision.

    Inspect representative URLs

    Choose a small but deliberate sample in URL Inspection. Include the homepage, a recently published URL, an important commercial or conversion page, a typical editorial page, and a template that has had indexing trouble before. Selecting only the homepage can hide a template-level failure.

    Review the current indexing information, crawl access, and canonical information shown for each sample. The goal is not to reconstruct June. It is to find out whether Google currently sees the pages in the state you intended. If several URLs from the same template show the same unexpected condition, stop treating the matter as a chart-only anomaly and investigate that template.

    Check the controls that can actually affect indexing

    • Confirm that important URLs return the intended HTTP response instead of an error, redirect loop, or soft failure.
    • Check page-level noindex directives and robots controls for unintended restrictions.
    • Verify that canonical destinations still point where you expect, particularly on templated and parameterized pages.
    • Review whether important URLs remain represented correctly in the relevant sitemap.
    • Check deployments, CMS changes, migrations, security rules, and template releases around the period for changes that could affect crawling or indexing.
    • If retained server logs are available, examine Googlebot requests and the responses returned by the server. Logs can show crawler access even when the Search Console chart cannot show historical totals.

    A configuration change is evidence only when it affects the URLs and behavior in question. A deployment happening near the gap is not automatically the cause. Connect the change to a response, directive, canonical, rendering problem, or other observable mechanism before you roll it back.

    Compare search and analytics outcomes

    Review Search Console Performance data, analytics landing-page activity, and available server logs over the same broad period. Stable organic activity does not prove that every URL stayed indexed, but it makes a sitewide indexing collapse less plausible. A decline in traffic does not prove deindexing either; rankings, demand, tracking, site availability, and page changes can produce similar symptoms.

    Use these signals as corroboration. When current URL states, technical controls, crawl evidence, and organic landing activity all look normal, the blank Page indexing interval is reasonably handled as a reporting limitation. When several independent signals move together, you have grounds for a technical investigation even though the June graph itself remains unusable.

    Protect your site and your historical reporting

    Missing telemetry creates pressure to do something visible. Resist changes that target the chart instead of a confirmed site fault. Repeatedly submitting the same sitemap, requesting indexing for every URL, or altering indexation controls will not recreate historical observations that Search Console did not retain.

    • Do not bulk-change canonicals. You could create a genuine consolidation problem while trying to solve a reporting problem.
    • Do not remove robots or noindex controls without checking their purpose. Some exclusions are intentional and protect search quality, private areas, or duplicate URL spaces.
    • Do not treat mass indexing requests as a repair. A request concerns a URL’s current handling; it cannot repopulate an aggregate historical chart.
    • Do not rewrite missing values as zero. Zero means an observed count of none. The June gap means no report observation is available.
    • Do not smooth the line without disclosure. An estimate may be useful for an internal model, but it must remain visibly labeled as estimated rather than reported Search Console data.

    In a data warehouse or spreadsheet, store the affected values as null or unavailable. In a chart, leave a break in the line. If your reporting system cannot accept null values, exclude the affected dates from calculations and add a visible annotation instead of coercing them to zero.

    For trend analysis, use complete periods before and after the gap. You can describe the difference between those periods, but you cannot assign the change to a particular missing date or calculate a reliable daily rate across the break. If data resumes at a different level, call it a post-gap difference until other evidence establishes the timing and cause.

    Ready-to-use status note: Search Console Page indexing data is unavailable for [affected June 2026 dates]. The Page indexing report was not updated during that interval, and Google does not backfill the missing values. Current URL, crawl-control, log, and traffic checks show [stable or changed conditions]. We are treating this as [a reporting-only limitation or an open technical investigation].

    Know when to open a real indexing investigation

    An overhead diagnostic pathway separates a harmless reporting gap from warning signs that merit an indexing investigation.

    The known reporting gap should lower the urgency of the blank chart, not become an excuse to ignore other evidence. Escalate when the anomaly extends beyond the shared June interval or when URL-level and operational signals indicate a separate problem.

    • Missing Page indexing observations continue beyond the affected June dates shown across your other properties.
    • Representative URLs now show an unexpected indexing condition or canonical destination.
    • Important templates return errors, carry unintended noindex directives, block crawling, or produce inconsistent canonical signals.
    • Server logs show a meaningful crawl-access or response change that aligns with a site release or infrastructure event.
    • Organic landing-page activity and Search Console Performance data decline outside the missing Page indexing interval.
    • The Page indexing series resumes at a materially different level and stays there rather than returning to its previous range.

    If one of those conditions appears, define the affected cohort before making changes. Segment URLs by template, response, canonical target, publication period, and intended indexability. Find the earliest independent sign of the problem, map it to deployments or configuration changes, and fix only the mechanism you can confirm. That sequence prevents a broad, risky response to what may be a narrow fault.

    For the June 2026 gap itself, the practical next move is simple: annotate the unavailable dates, inspect representative URLs, and preserve null values in every downstream report. If the independent checks remain stable, continue your planned SEO work. If they do not, begin the investigation from the earliest reliable signal rather than from the blank graph.

    References


  • How to Validate a Programmatic SEO Pilot Before Scaling

    How to Validate a Programmatic SEO Pilot Before Scaling

    You have a spreadsheet full of potential URLs, a working template, and a credible path to publishing at scale. The decision in front of you is not whether the pages can be generated. It is whether the underlying page pattern deserves to be multiplied.

    That distinction matters because one page model can unlock hundreds or thousands of search opportunities, but it can multiply weak differentiation just as efficiently. A proper pilot should reveal where the model earns discovery, distinct search demand, and useful visitor behavior. It should also expose the conditions under which the model breaks.

    Key takeaways

    • Compare 10 candidate pages before development. If their substance barely changes, the template is not ready for search.
    • Build the pilot from strong, average, and difficult cases. A collection of obvious winners cannot validate the larger opportunity.
    • Record each page’s intended query family, possible competing URL, unique information, and desired visitor action before launch.
    • Evaluate four separate gates: discovery and indexing, query fit, performance drivers, and business behavior.
    • Scale only the segments supported by the evidence. A successful subset does not justify publishing every possible permutation.

    Define the page pattern as a testable hypothesis

    A programmatic template is not a strategy by itself. It is a production mechanism. Your strategy begins with a hypothesis about why each generated page will deserve its own URL and satisfy a distinct need.

    Write that hypothesis in a form your pilot can disprove:

    For [audience or context], a page differentiated by [variable] will satisfy [query family] because it provides [unique information], leading the visitor toward [useful action].

    For an integration library, the variable might be the connected product. The unique information might include supported workflows, setup instructions, screenshots, and limitations. For location pages, meaningful differences could come from local inventory, provider availability, pricing, or market-specific data. A changed city name or software logo is not meaningful differentiation if the underlying problem, evidence, and answer stay the same.

    Before anyone builds the generator, sketch 10 candidate pages and compare them side by side. For each candidate, answer:

    • What information changes in a way that helps this visitor?
    • What problem, constraint, or decision is specific to this variation?
    • What data, proof, examples, or screenshots change?
    • What capability, inventory, workflow, or limitation changes?
    • What should the visitor do next, and why is that action appropriate here?

    If most answers reduce to swapped nouns, do not move into pilot production. You have found a keyword permutation, not a durable page pattern. Either add a data source that creates substantive variation, narrow the eligible page set, or abandon the pattern.

    This is also where structured data belongs in the plan. Keep markup and other template-wide elements consistent unless you are deliberately testing them. Valid JSON-LD can describe a page accurately, but it cannot supply the missing local facts, workflows, inventory, or proof that should distinguish one generated URL from another.

    Create a pilot manifest before publishing. Give every candidate a row containing:

    • The proposed URL and page type.
    • The primary search intent and related query family.
    • The existing URL most likely to compete with it.
    • The unique information or assets available for that variation.
    • The intended visitor action.
    • Relevant characteristics such as demand, data depth, inventory, internal-link depth, competition, and content completeness.

    Those fields become your baseline. Without them, a team can reinterpret almost any post-launch result as success.

    Build a representative pilot, not a showcase

    A varied sample of blank web-page cards and assorted data pieces is arranged on a worktable beside a larger unused stack.

    The easiest candidates are useful for proving that the template can work under favorable conditions. They cannot tell you whether it will hold up across the full library.

    Build your sample around the dimensions that vary in the eventual rollout. A location project might include large, medium, and small markets, plus locations with rich and limited inventory. An integration project might include well-known connections with extensive workflows, ordinary integrations with moderate demand, and edge cases with less supporting material. A use-case library should likewise include both obvious audience needs and narrower combinations.

    There is no universal number of pages that makes a pilot valid. The right sample depends on how many materially different conditions the template must survive. List those conditions first, then select enough candidates to expose recurring differences without building the full library.

    A practical selection process looks like this:

    1. List every dimension that could change page quality or performance: demand, data depth, inventory, competition, link depth, and completeness.
    2. Divide each dimension into meaningful bands, such as stronger, typical, and weaker cases. Use labels appropriate to your dataset rather than arbitrary industry thresholds.
    3. Select candidates across the intersections. Do not let high-demand, data-rich pages dominate the sample.
    4. Check the manifest for missing conditions. If thin-data or low-demand cases will exist after scaling, they must appear in the pilot.
    5. Freeze the sample and success rules before results arrive. Additions made after launch should be treated as a new test, not quietly folded into the original one.

    A representative pilot is intentionally uncomfortable. It includes pages you suspect may fail because those failures help define an eligibility rule. If data-poor variations repeatedly fall out of the index or never acquire distinct queries, the lesson is not necessarily that the entire model failed. The model may work only above a particular level of data or inventory. That boundary is exactly what the pilot should uncover.

    Use four validation gates instead of one traffic total

    Web-page tiles move through four symbolic checkpoints for discovery, differentiation, quality, and visitor interaction before entering a limited expansion area.

    Do not collapse the pilot into sessions, clicks, or aggregate impressions. A few strong URLs can conceal widespread indexing problems, query overlap, or pages that attract attention without helping the business. Evaluate each gate separately, by URL and by candidate segment.

    Gate 1: Can Google discover and retain the pages?

    Start by checking whether Google can find each pilot page through your internal linking structure. Then distinguish initial indexing from sustained indexing. A URL that enters the index briefly and later disappears has not demonstrated the same stability as one that remains indexed.

    • Was the URL discovered?
    • Did it enter the index?
    • Did it remain indexed over the observation period?
    • Do indexed and excluded pages differ by data depth, inventory, completeness, or internal-link depth?

    Suppose 40 of 50 pilot location pages remain indexed, while the excluded pages consistently have limited local inventory. That is not proof that inventory alone caused the outcome. It is a useful hypothesis: the page model may require more inventory to remain viable. Test that condition in the next controlled batch before turning it into a permanent rule.

    Do not respond to weak indexing by publishing more URLs. That increases the number of pages requiring discovery, internal links, and maintenance without resolving the defect the pilot exposed.

    Gate 2: Do the URLs attract their intended query families?

    Compare the queries recorded in your manifest with the impressions each URL receives in Google Search Console. Look beyond the primary phrase. Related queries often show more clearly whether Google understands the page’s specific purpose.

    Imagine separate pages for CRM software aimed at accountants, real estate agents, and consultants. The pattern is beginning to differentiate if each page attracts searches connected to its intended industry. If all three mainly appear for the same generic CRM terms and overlap with the main product page, the audience variable has not translated into distinct search relevance.

    Some query overlap is natural. The warning sign is not a shared word; it is a shared job. Flag URLs when most of their visibility comes from a generic intent already served elsewhere, when several generated pages repeatedly compete for the same query family, or when the intended supporting queries never emerge.

    For every flagged URL, choose a deliberate response: sharpen its unique information, merge it into a stronger page, change the eligibility rule, or remove it from the scalable pattern. Do not leave overlapping URLs in place simply because each one received impressions.

    Gate 3: Which page characteristics travel with better results?

    Once individual results are visible, group pilot pages by the characteristics you recorded before launch. Compare cohorts based on search demand, unique-data depth, inventory or product availability, internal-link depth, competition, and content completeness.

    The objective is not to crown a universal ranking factor. It is to identify the operating conditions for your page model. Integration pages with detailed setup instructions and several supported workflows may consistently outperform pages with a short capability description. Data-rich locations may remain indexed more reliably than locations with sparse availability. Those associations tell you what to test next and which candidates should qualify for expansion.

    Keep the analysis at URL level before rolling it up. Report how each segment performs across indexing, intended-query visibility, and the desired visitor action. An overall average can look healthy even when every edge case fails.

    Gate 4: Does the visibility produce useful behavior?

    Organic visibility is an intermediate result. Your pilot also needs a business outcome appropriate to the intent: starting setup, viewing available inventory, requesting information, creating an account, or moving into another meaningful step.

    Define that action before launch and measure it by page and segment. Otherwise, teams tend to celebrate whatever metric moved. A page with impressions but no useful next step may have an intent mismatch, an incomplete answer, or a weak transition into the product. A lower-volume page can still justify its place if it attracts the intended audience and produces the behavior the page was designed to support.

    If AI visibility is also part of your objective, record it separately rather than treating Google indexing as a proxy. Define the prompt family you care about, note whether the brand or page appears in the relevant response, and capture any citation or link that is actually present. Keep those observations distinct from Search Console query performance so one channel does not mask failure in another.

    Turn the evidence into a bounded scale decision

    A pilot is finished when it supports a decision, not when a reporting window happens to close. Give it enough time to collect meaningful evidence, then classify the result. Do not invent a universal waiting period; demand and page conditions differ too much for one calendar threshold to fit every project.

    Observed patternLikely implicationNext action
    Weak discovery across most segmentsThe internal path to the library is not working reliably.Repair the linking structure and rerun the pilot before expanding.
    Only data-rich or inventory-rich pages remain indexedThe template may work under a narrower eligibility condition.Test and document a minimum data rule, then exclude weaker candidates.
    Pages are indexed but attract generic, overlapping queriesThe proposed variation is not creating a distinct search purpose.Rework the page model, consolidate overlapping URLs, or stop the pattern.
    Visibility appears, but the intended action does notSearch intent, page value, or the next-step path may be misaligned.Diagnose the affected segment and retest before increasing URL volume.
    Strong results occur only among obvious head casesThe opportunity is smaller than the full permutation count suggests.Scale the proven segment and keep adjacent segments in testing.
    Multiple representative segments pass all four gatesThe page pattern has earned a controlled expansion.Release the next bounded batch and apply the same validation process.

    Use four decision states rather than forcing a binary launch:

    • Scale: Multiple representative segments meet your predeclared standards across all four gates, and you can describe the characteristics associated with success.
    • Expand the pilot: Results are promising, but an important condition is underrepresented or the apparent pattern rests on too few comparable pages.
    • Rework: The URLs are discoverable, but query overlap, thin differentiation, or weak business behavior points to a repairable page-model problem.
    • Stop: Most candidates cannot support materially different information, or representative pages repeatedly fail without a credible condition you can change.

    When you do scale, scale in bounded batches. Carry the manifest, eligibility rules, internal-link approach, and four gates into every release. New segments introduce new conditions, so success among large markets, popular integrations, or rich-data pages should not grant automatic approval to smaller markets, obscure connections, or sparse records.

    Your next step is simple: put 10 proposed pages side by side and complete the manifest before approving the generator. If their differences disappear under scrutiny, you have avoided multiplying a weak idea. If the differences hold, publish a representative pilot and let observed indexing, query fit, page characteristics, and business behavior determine how far the pattern deserves to go.

    References


  • Why Technical SEO Audit Recommendations Fail to Ship

    Why Technical SEO Audit Recommendations Fail to Ship

    Your technical SEO audit is finished, but nothing is moving. The findings are sitting in a shared drive, developers keep asking what to change, and the severity labels are not helping anyone decide what deserves attention.

    The problem is usually not a shortage of issues. It is the gap between observing a technical condition and producing a trusted, scoped recommendation. You close that gap by validating each finding, tracing it to the system that creates it, and defining a result that another team can implement and verify.

    Confirm the problem exists before you classify it

    A crawler finding is a lead, not a fact. It tells you where to investigate. It does not automatically tell you what users, Google, or an AI crawler received.

    Compare the initial HTML with the rendered page

    JavaScript can change the body copy, internal links, canonical element, or meta robots directive after the server sends the initial HTML. A crawl that examines only the initial response can therefore report missing elements that appear after rendering. The opposite problem matters too: a browser may display content correctly even though that content is absent from the response available to a crawler that does not run JavaScript.

    Run the crawl with JavaScript rendering enabled and store both the original and rendered HTML. Then compare the versions for the elements that affect discovery, interpretation, and indexing:

    • Primary body content and headings.
    • Links to important internal destinations.
    • The canonical URL.
    • Meta robots directives.
    • Any navigation or related-content module responsible for exposing more URLs.

    Treat a difference as material only when it changes what a crawler can discover or understand. A decorative class added after rendering is not an SEO recommendation. An internal link or index directive that exists only after a successful script execution may be one.

    Google can render most pages, but rendered-only content remains dependent on scripts, resources, and execution completing successfully. Many AI crawlers do not execute JavaScript, so a page that is usable and indexable in one system may still expose very little to another. For content intended to support AI discovery, inspect the initial HTML rather than assuming the browser’s final screen represents every crawler’s view.

    When the difference affects a page you want indexed, check the URL in Google Search Console’s URL Inspection tool. Use Google’s rendered view to confirm whether the content or directive was available during inspection. Attach that evidence to the finding; it is more useful to an engineer than a crawler screenshot without platform confirmation.

    Separate expected exclusions from indexing failures

    Open Search Console and go to Indexing > Pages. The Page indexing report distinguishes conditions such as indexed, crawled but not indexed, discovered but not indexed, soft 404, redirected, excluded by noindex, and alternate page with a canonical.

    Do not convert every item under “Not indexed” into a task. An alternate URL with the intended canonical, a deliberately noindexed page, and a redirected URL can all be correct outcomes. The audit question is not “How many URLs are excluded?” It is “Does the reported state match the intended state for this page type?”

    Investigate the mismatch. A commercial or informational page intended to rank but listed as “Crawled – currently not indexed” deserves examination. So does a growing “Discovered – currently not indexed” group containing URLs you expect Google to crawl. By contrast, an intentionally excluded filter URL may require no change at all.

    Add an intended-indexing field to your audit worksheet. Mark each sampled URL as indexable, canonicalized elsewhere, noindexed, redirected, or intentionally unavailable before you evaluate Google’s classification. That one field prevents normal exclusions from competing with genuine failures.

    Audit templates and URL-generating rules, not random pages

    A central website template machine repeats the same structural flaw across many generated page tiles while isolated pages are inspected nearby.

    Random URL sampling tends to find isolated symptoms. Technical SEO failures are often produced by a template, routing rule, filter, or CMS behavior that affects a whole class of pages.

    Build the sample around every page type the site generates. Depending on the site, that may include product detail pages, category or listing pages, blog posts, filtered views, paginated series, and parameterized URLs. Include both pages intended for indexing and pages intended for exclusion. The goal is to test the rules at their boundaries, not merely to confirm that an ordinary page works.

    For each template, record:

    • The business purpose of the page type.
    • Whether its URLs should be discovered, crawled, indexed, or consolidated into another URL.
    • How users and crawlers reach it.
    • Its expected status code, canonical behavior, and robots state.
    • Whether important content and links appear in the initial HTML.
    • Which CMS component, route, or template controls the behavior.

    This changes the unit of work. A canonical error on a product template is not a collection of unrelated URL problems. On a catalog containing 40,000 product pages, one faulty template rule can affect all 40,000. The URL export demonstrates scope, but the template is the implementation target.

    Template-based sampling also makes the recommendation easier to estimate. “Change the canonical logic on the product detail template” identifies a system boundary. “Fix these 40,000 URLs” leaves the development team to discover the shared cause themselves.

    Keep the complete URL list as supporting evidence, not as the task description. Give the implementation team representative examples covering the important states: a normal page, an affected page, an excluded variant, and any edge case that changes the expected behavior. If the same proposed fix cannot explain all those examples, the diagnosis is not finished.

    Triangulate findings before asking another team to act

    No single data source sees the whole technical system. A crawler shows what it discovered and received. Search Console shows Google’s classification. Analytics reflects tracked visits. Server logs show requests that actually reached the server. Their differences are not noise to discard; they often reveal the failure mechanism.

    Evidence sourceWhat it can confirmImportant blind spot
    SEO crawlerLinked URLs, status responses, directives, internal links, and rendered-versus-original HTML when configured for renderingIt cannot discover an orphan URL unless you supply the URL through another source
    Google Search ConsoleGoogle’s indexing classification, inspected rendering, and sampled crawl informationIt may show Google’s outcome without fully explaining the underlying site behavior
    AnalyticsVisits where the tracking code executesIt does not provide a complete record of crawler requests
    Server logsRequests made to the server, including requested URLs, response codes, and crawler activityThey require access, retention, and filtering that may not already be available

    Server logs are especially valuable when you suspect intermittent 5xx responses, rate limiting, or crawler activity concentrated on URLs that do not matter. They show what Googlebot or an AI crawler requested and what the server returned. If logs are unavailable, Search Console’s Crawl Stats report offers sampled request examples and a breakdown that can help you decide where to investigate.

    Before a finding becomes a development recommendation, confirm it in at least two places. Choose the pair based on the claim:

    • For a rendering claim, compare original and rendered HTML, then inspect the URL in Search Console.
    • For an indexing claim, compare the intended state with the Page indexing report and the page’s actual directives.
    • For a response-code claim, compare the crawler result with a direct request and, when available, server logs.
    • For a crawl-allocation claim, use logs or Crawl Stats to see which URL patterns crawlers actually request.
    • For an orphan-page claim, compare crawler discovery with URLs found in Search Console, analytics, sitemaps, or logs.

    When the evidence disagrees, pause the recommendation. A crawler may record 429 or 503 responses because its request rate triggered site protections. The same URL may load normally when opened manually. Confirm the exact URL with a direct request, review the crawl rate, and check logs before declaring a server failure. Tool classifications can reflect the conditions created by the audit itself.

    This validation step protects more than the current ticket. Sending an engineer after one phantom problem weakens confidence in every finding that follows. A shorter audit containing reproducible evidence is more useful than a long export whose labels have not been checked.

    Turn observations into implementation-ready recommendations

    Three diagnostic sources converge on a website defect that is converted into fitted replacement parts and installed by an engineer.

    “The site has duplicate URLs” describes a result. It does not identify what must change. The duplicates might come from faceted navigation, session identifiers appended to URLs, or a CMS that publishes the same content under a second path. Deleting the current URLs addresses the inventory while leaving the generator intact, so the problem can return when the behavior is triggered again.

    Trace the issue upstream. Find the link, component, route, parameter rule, or publication workflow that creates the unwanted state. Then write the recommendation against that cause.

    Use a ticket structure that supports estimation and testing

    A shippable technical SEO recommendation should contain the following fields:

    1. Intended behavior: State which URL class should be discoverable, indexable, canonicalized, redirected, or excluded.
    2. Observed behavior: Describe the mismatch without copying a crawler label as the explanation.
    3. Affected system: Name the template, route, filter, CMS component, or rendering process that produces it.
    4. Evidence: Include representative URLs and confirmation from at least two relevant sources.
    5. Root cause: Explain the rule or dependency responsible. If it is still a hypothesis, label it as one and request the diagnostic work needed to confirm it.
    6. Required change: Define the behavior to alter without prescribing unsupported implementation details.
    7. Acceptance criteria: Describe what should be true after deployment in the response, rendered DOM, crawl, and relevant platform report.
    8. Scope and risk: Identify affected templates, intentional exceptions, dependencies, and any indexing behavior that must not change.

    Compare these two versions:

    Weak: Fix 12,000 duplicate URLs. High severity.

    Shippable: Filter controls on the category template generate crawlable parameter URLs that are not intended as separate search results. Confirm which control emits each pattern, change the generating rule so the unwanted URLs are no longer exposed through that path, and preserve the clean category URLs. After deployment, the supplied clean and filtered examples must return their intended status, canonical, robots state, and internal-link behavior in both the initial and rendered HTML.

    The second version does not pretend the implementation is known before the cause is confirmed. It gives engineering a system boundary, an intended outcome, test cases, and protected behavior.

    Prioritize with impact, confidence, and effort

    A crawler’s severity setting is not your roadmap. Its classification cannot know whether an excluded URL was meant to rank, whether a template affects a commercially important page type, or whether the apparent error exists outside the crawl environment.

    Rank validated findings with four questions:

    • Impact: Does the condition prevent important pages or content from being discovered, rendered, understood, or indexed as intended?
    • Scope: Is it generated by a shared template or rule, or confined to an isolated URL?
    • Confidence: Is the finding reproduced and confirmed by independent evidence, or is the cause still hypothetical?
    • Effort and dependency: Can the responsible team estimate the change, and does another system or release have to move first?

    Do not hide uncertainty by assigning a more urgent label. A high-impact hypothesis should become a priority diagnostic task. A confirmed template defect should become an implementation task. An expected exclusion should be documented and closed. Those are three different decisions, even if a crawler places all three URLs in the same warning bucket.

    Be careful with changes to canonicals, redirects, robots directives, and URL generation. A broad template edit can alter the indexing state of every page using it. Test representative intended and excluded cases before release, then repeat the same checks after deployment. The acceptance criteria should make unintended changes visible before the ticket is considered complete.

    Key takeaways

    • Treat crawler findings as leads until you reproduce and validate them.
    • Compare initial and rendered HTML whenever JavaScript can add content, links, canonicals, or robots directives.
    • Judge Search Console exclusions against each page type’s intended indexing state.
    • Sample by template and generated URL pattern, because shared rules create scalable failures.
    • Confirm development recommendations with at least two relevant evidence sources.
    • Write the task against the root cause, with representative examples and testable acceptance criteria.
    • Prioritize by impact, scope, confidence, and implementation effort rather than tool severity.

    Take the next finding in your audit and try to write its acceptance criteria. If you cannot state what should be different after deployment, which template controls it, and how you will verify the result, keep investigating. Once those answers are explicit, the audit stops being a report and becomes work a team can safely ship.

    References


  • Google Search Result URL Redirects: What SEOs Should Check

    Google Search Result URL Redirects: What SEOs Should Check

    If your rank tracker suddenly disagrees with what you can see in Google, pause before changing the page. Google is inserting a Google-owned redirect between some search results and their destination pages, and that can disrupt the measurement layer without changing the ranking itself.

    Your first job is to identify which link in the chain changed: Google’s result, your tracking provider’s collection process, or your site’s actual search performance. A short, structured audit can keep a reporting incident from turning into an unnecessary content, schema, or technical SEO project.

    Read this as a link-delivery change, not a site redirect

    A conventional organic result used to expose the destination page’s full URL as its clickable target. Under the new behavior, the result can point first to a Google URL resembling google.com/goto?url=[hashURL]. Google processes that intermediate request and then sends the searcher to the destination.

    That extra hop matters because software inspecting the result may initially see a Google-owned URL instead of your page URL. The searcher can still see the displayed site URL under the result title, but the browser’s link preview may no longer reveal the complete destination before the click.

    Google describes the rollout as part of its technical response to evolving abuse and an effort to protect its services and users. That explanation is broad. It does not identify every type of abuse involved, so claims about one specific target or enforcement method should be treated as interpretation rather than confirmed implementation detail.

    Most importantly, this is not a redirect configured on your server. It does not, by itself, show that Google changed your canonical URL, replaced your indexed page, altered your structured data, or applied a ranking penalty. Your 301 and 302 rules remain separate from the redirect Google places inside its own result interface.

    • Do not add a site redirect to compensate. You cannot remove Google’s intermediate hop from your server, and another redirect would only add complexity to the destination path.
    • Do not change canonical tags or JSON-LD because a tracker exposes a Google URL. First confirm whether the tool is merely failing to resolve the final destination.
    • Do not treat the redirect as evidence of an algorithm update. A ranking change requires ranking evidence; a changed link target is not enough.

    Identify which part of your search stack is exposed

    A layered search stack shows a result link, a collection device encountering a redirect gate, and a healthy destination server.

    The effect depends on how you interact with the result. A person clicking normally may notice little beyond the obscured link preview. A system that parses result-page links, classifies domains, or associates positions with landing URLs has more ways to fail.

    • Searchers: Watch for the displayed domain and page label under the result title. The visible destination cue remains available even when the clickable target is routed through Google.
    • SEO teams: Expect possible discontinuities in third-party rank, visibility, competitor, and landing-page reports. An abrupt dashboard change may reflect collection behavior rather than a change to your pages.
    • Rank-tracking providers: A parser that assumes every organic link exposes the publisher’s URL may return a Google URL, an unknown destination, or no recognized result. Tools that resolve the redirect may face a different collection path than tools that only inspect the original markup.
    • SERP scrapers and AI systems: The redirect can create additional friction for systems gathering destinations from Google results. That does not automatically affect an AI crawler visiting your website directly; the two access paths are different.
    • Google Search Console users: The working expectation is that Search Console is not affected by this result-link change, but Google’s public confirmation does not provide an explicit guarantee. Use it as an independent comparison signal, not as proof that every third-party observation is wrong.

    This distinction is especially important for AI visibility reporting. If a platform builds part of its dataset by scraping Google results, its measurements may inherit the redirect problem. A decline in that platform does not establish that your pages became less accessible to ChatGPT, other frontier models, or direct web crawlers. Ask how the vendor collects each reported signal before you combine those signals into one visibility score.

    Audit tracker anomalies before changing the site

    The redirect is being rolled out rather than appearing as a single universal switch. Different providers, locations, and collection environments may encounter it at different points. That makes the shape and timing of the anomaly more useful than one isolated keyword check.

    1. Preserve the last clean comparison. Export the affected dashboard before filters, recalculation, or vendor corrections change the historical view. Record the date you first noticed the discrepancy, the search engine, market, device configuration, project, and affected keyword set.
    2. Localize the break. Check whether the anomaly affects every tracked keyword or only one market, device type, project, or provider. A sitewide overnight gap confined to one tool looks different from a gradual decline concentrated in a group of pages.
    3. Separate position collection from URL resolution. Determine whether the tool lost the result entirely, still reports a position but cannot identify the landing page, or now attributes the result to google.com. Those are different failures and should not be combined into a generic rankings-down label.
    4. Inspect a small set of affected results manually. Confirm that the result is visible, the displayed domain is yours, the click reaches the intended page, and the underlying result link uses the new Google redirect. Manual checks are samples, not a replacement for tracking, but they can expose an obvious collection mismatch.
    5. Compare independent signals by direction, not exact totals. Review Search Console queries, pages, clicks, impressions, and average position around the same period. Search Console and a rank tracker measure search differently, so their numbers need not match. You are looking for a shared break in timing and scope.
    6. Send the provider reproducible evidence. Include the first affected date, search engine, market, device setting, several example queries, the expected destination, the reported destination, and screenshots or exports. Ask whether the goto redirect affects position detection, landing-page resolution, or both.

    Avoid making broad on-page changes while this audit is open. Rewriting titles, altering internal links, replacing schema, and changing canonicals at the same time will create new variables. If the original problem is external data collection, those edits cannot repair it and may make the real diagnosis harder.

    Separate a collection failure from an SEO loss

    A split illustration shows a broken monitoring signal beside an unchanged search position and a working monitor beside a falling result.

    No single metric settles the diagnosis. Use several observations to decide which explanation currently has the strongest support.

    • The result appears manually, the click reaches the right page, and only one tracker loses it: a collection or parsing problem is more plausible than a ranking loss.
    • The tracker still reports a position but loses the landing URL: destination resolution is the leading suspect. Check whether the reported URL is a Google goto address before touching your canonical setup.
    • Several third-party reports change at the same time but share a collection provider: they may not be independent confirmations. Establish whether the products depend on the same underlying data source.
    • Search Console and third-party visibility decline across similar queries and pages: investigate a genuine search-performance problem. The goto redirect alone is not a sufficient explanation for agreement across independent signals.
    • The result is present but the click fails or lands on the wrong page: treat that as a user-facing path problem. Verify your own redirects, final response, and destination separately from the tracker issue.
    • Nothing changed outside the underlying link target: document the rollout and keep monitoring. A technical change in Google’s interface does not require a technical change on your site.

    Be equally careful with competitive reporting. If a tool starts classifying goto URLs as Google domains, domain-level share-of-voice data can become distorted across many sites at once. Before concluding that a competitor gained visibility, check whether the report also shows more unknown URLs, missing domains, or unresolved landing pages.

    Your schema strategy does not need a special markup response. Structured data describes entities and page content on your site; it does not control the outbound link wrapper Google uses on its own search page. Continue validating schema for its intended purpose, but do not use a JSON-LD deployment as a remedy for off-site rank-tracker collection.

    Key takeaways

    • Google can route an organic result through a google.com/goto URL before sending the searcher to the publisher’s page.
    • The redirect is a Google-side link-delivery measure, not a redirect you need to reproduce or counteract on your server.
    • Third-party tools that extract or resolve result URLs have more direct exposure than ordinary searchers or your site’s canonical configuration.
    • A tracker anomaly becomes actionable SEO evidence only when independent signals support the same timing, pages, and queries.
    • Preserve the affected data, classify the failure, compare Search Console directionally, and give your provider reproducible examples before editing the site.

    Add the rollout to your measurement-change log and keep first-party performance signals separate from vendor-collected visibility data. If a discrepancy appears, ask the provider whether it can recognize the result and whether it can resolve the final URL. Those two answers will tell you whether you have a reporting repair to wait for or an SEO problem to investigate.

    Until the evidence points to your site, leave the content, internal links, canonicals, redirects, and structured data alone. The safest next move is a cleaner diagnosis, not a larger deployment.

    References


  • AI Search Crawlability: A Technical SEO Audit Framework

    AI Search Crawlability: A Technical SEO Audit Framework

    Your pages can perform well in Google and still be effectively missing from AI-generated answers. The problem is often not the writing. An AI crawler may be blocked, unable to discover links, or receiving an HTML shell that omits the content and structured data people see in a browser.

    You can diagnose that problem without guessing about prompts or rewriting every page. Audit the route from robots.txt to the raw server response, then fix the first point where a retrieval bot loses access, discovery, or meaning.

    Key takeaways

    • Audit the initial HTML response, not just the rendered page in your browser. Critical links, text, headings, metadata, and JSON-LD should be present before JavaScript runs.
    • Treat training crawlers, search or retrieval crawlers, and user-initiated browsing agents as separate policy decisions in robots.txt.
    • Use server-side rendering, static generation, or a hybrid approach for anything an AI system must discover, understand, or cite.
    • Use server logs to distinguish a crawlability failure from a selection failure. A page that was never requested has a different problem from a page that was fetched but not cited.

    Crawlability has three gates, and robots.txt is only the first

    A useful AI crawlability audit separates access, discovery, and extraction. Combining them into one pass-or-fail score hides the actual repair.

    GateWhat to testTypical failure
    AccessDoes your robots policy permit the intended agent, and can it receive a usable response?The agent is disallowed, challenged, rate-limited, redirected incorrectly, or served an error.
    DiscoveryCan the agent find the URL through links that exist in the initial HTML?It reaches a hub page but cannot see JavaScript-injected links to child pages.
    ExtractionDoes the response contain the main text, headings, factual details, metadata, and structured data?The URL loads, but the response is an application shell whose useful content appears only after JavaScript runs.

    Passing one gate proves nothing about the next. An Allow rule cannot make a client-rendered product description appear in the response. An XML sitemap may expose a URL, but it cannot supply missing text or JSON-LD. A browser screenshot can show a complete page even when the crawler receives almost nothing.

    Do not use Google rendering as a proxy for every other system. The crawler ecosystem includes agents with different jobs and different rendering behavior. A successful Google inspection therefore does not establish that an AI retrieval crawler can follow the same path or extract the same facts.

    Set crawler access by purpose, not by the letters AI

    AI platforms can operate more than one agent. One may crawl broadly for model training, another may retrieve information for search, and another may visit a URL in response to a user’s request. Blocking or allowing the entire family with an inherited rule can produce the opposite of your intended policy.

    • Training-oriented access: Decide whether broad reuse of your content fits your publishing, licensing, and compliance policy. ClaudeBot is an example of a crawler identified for training.
    • Search and retrieval access: If you want pages to be available for AI answers, inspect rules affecting agents such as Claude-SearchBot and OAI-SearchBot separately from training crawlers.
    • User-initiated browsing: Agents such as Claude-User and ChatGPT-User may fetch a page when a person asks an assistant to visit or use it. Treat that behavior as its own access decision.

    The names matter because a blanket policy is not a strategy. A publisher may reasonably block training while allowing retrieval. A regulated organization may choose a narrower policy. The technical requirement is that robots.txt express the decision you actually made rather than a rule inherited from an old template, security product, or previous agency.

    1. Write down the intended outcome for training, retrieval, and user-initiated access before editing robots.txt.
    2. Map every relevant user agent to one of those outcomes. Do not assume agents owned by the same company serve the same function.
    3. Review specific user-agent groups as well as broad wildcard rules. Look for inherited blocks that catch retrieval agents unintentionally.
    4. Test the resulting policy with the exact user-agent names, then fetch representative URLs to confirm that permitted agents receive normal responses.
    5. Record who owns the policy and why. Otherwise, a future security or infrastructure change can silently reverse it.

    Robots permission is necessary only when you want that agent to enter. It is not evidence that the agent can navigate the site or understand the response. Continue the audit even after the policy passes.

    Put the discovery path and critical facts in the initial HTML

    Two server-response paths show a crawler receiving a complete structured page on one side and an empty page shell on the other.

    Client-side rendering creates the largest practical gap between what a person sees and what many AI crawlers receive. If the server sends an empty container and JavaScript later inserts navigation, body copy, product details, or schema, a crawler that does not execute that script encounters an incomplete page.

    The risk is especially clear in internal navigation. During the first 27 days of a 41-day controlled crawl experiment, GPTBot and ClaudeBot each reached all 748 hierarchy pages exposed through hard-coded HTML and none of the hierarchy pages available only through JavaScript-injected links. Googlebot reached seven of 293 pages in the JavaScript group, or 2%, and 35 of 748 in the HTML group, or 5%.

    Those percentages are not universal crawl-rate benchmarks. The experiment intentionally removed sitemaps, breadcrumbs, and other alternative discovery paths so that reaching a JavaScript-only child would demonstrate script execution. What it establishes is the mechanism: when the only route to a page is a link inserted after load, major AI crawlers may stop at the parent.

    Different crawlers from the same organization are not interchangeable either. GoogleOther rendered enough JavaScript to reach 142 of the 293 JavaScript-group pages in that experiment, while Googlebot reached seven. Activity from a secondary agent does not prove that the crawler responsible for a particular search or retrieval function saw the same pages.

    For every page you want an AI system to use, place these elements in the server-delivered response:

    • Followable internal links: Category, topic, breadcrumb, related-content, pagination, and other important paths should use links with destinations present in the raw HTML. Keep XML sitemaps as an additional discovery route, not as a repair for invisible navigation.
    • The primary answer: The page’s main text, headings, definitions, specifications, and other decision-critical facts should not depend on a client-side API call.
    • Entity details: Names, authors, dates, prices, product attributes, and relationships should appear clearly where they are relevant to the page.
    • Critical metadata: Do not rely on JavaScript to add information that a crawler needs to classify or interpret the page.
    • Structured data: Put the applicable schema markup, including JSON-LD, in the initial HTML rather than injecting it after the application mounts.

    Server-delivered structured data gives a no-JavaScript crawler explicit entity and relationship signals. It can reduce ambiguity around facts such as names, dates, authors, prices, and product attributes. It should describe information that is also supported by the page, not act as a hidden substitute for missing visible content.

    You do not have to remove JavaScript from the site. Use static site generation for content that can be built in advance, server-side rendering for pages whose critical response must be assembled dynamically, or a hybrid model that renders essential content and navigation on the server while leaving filters, interactions, and enhancements to the client.

    The implementation label is less important than the response. A framework can claim SSR while a particular component still fetches its text, links, or schema in the browser. Verify the actual HTML returned for the actual template.

    Run an audit that ends in a template-level fix

    Multiple page tiles pass through a diagnostic system and become complete after a central website template component is repaired.

    Start with representative paths rather than a random list of URLs. Include a top-level hub, a child page, a deep page that depends on several internal clicks, and each commercially or editorially important template. The relationship between those pages is part of the test.

    1. Fetch the raw response without executing JavaScript. Save the response body and relevant headers. In a browser, View Source is more useful for this check than the Elements panel, which normally reflects the post-JavaScript document.
    2. Confirm basic access. Check the response status, redirect destination, robots rules, and any challenge or interstitial delivered to the chosen agent. A visually normal page in your own session does not prove that an unauthenticated crawler receives it.
    3. Search the response for the primary information. Verify that the title, main heading, answer text, defining facts, authorship, dates, product information, and other page-specific content are present as text rather than empty component placeholders.
    4. Trace the internal path. Starting at the hub, inspect the raw HTML for links to the next level. Repeat until you reach the deep sample. If the path disappears before JavaScript runs, you have found a discovery boundary.
    5. Inspect JSON-LD in the response. Confirm that the intended schema type, entity properties, and relationships are present server-side and agree with the information a reader can see.
    6. Compare raw and rendered output. Any critical element that exists only in the rendered document is a client-side dependency. Classify it as discovery, content, metadata, or structured data so the development request names the actual failure.
    7. Review server logs. Group requests by user agent, path, response status, and time. Look for agents that reach hubs but consistently stop before child pages. Do not trust a user-agent string alone when identity matters; the controlled crawler experiment verified Googlebot and Bingbot through reverse DNS to exclude spoofed traffic.
    8. Repair the shared template and retest the path. A server-rendering fix to a hub, navigation component, or JSON-LD component can restore access across many URLs. Confirm the new response before treating deployment as completion.

    Interpret the failure pattern before changing content

    • The agent never requests the URL: Check robots access and discovery first. The absence of a request is not evidence that the copy needs optimization.
    • The agent requests hubs but not their children: Inspect the parent response for missing links. A repeated stop at the same directory level is a strong JavaScript-boundary signal when the child links are absent from raw HTML.
    • The agent requests the page but receives a thin shell: Move the critical content and facts into SSR, SSG, or hybrid output. Changing schema alone will not supply the missing body content.
    • The text is present but JSON-LD appears only after rendering: change how the markup is delivered. Server-render it and verify it in the response body.
    • Training is allowed while retrieval is blocked: revisit the robots policy if AI search visibility is the goal. The configuration does not match that objective.
    • The page is fetched with complete HTML but is not cited: crawlability has probably passed for that request. Retrieval, relevance, factual clarity, and citation selection are separate stages, so do not keep treating every absence as a rendering bug.

    Begin with one high-value hub and its deepest important child. Make sure an intended retrieval agent can access both URLs and that the raw responses contain the links, main content, factual details, and JSON-LD needed to interpret them. Once that path passes, apply the repair at the template level and verify the result in your logs before commissioning another round of content rewrites.

    References


  • How to Verify AI-Assisted Development for Technical SEO

    How to Verify AI-Assisted Development for Technical SEO

    The ticket says resolved. The AI says the tests pass. Staging looks right. Yet the production page still sends the wrong canonical, omits a locale mapping, or calculates a score that no customer can see. This is where fast AI-assisted development becomes expensive: a working result can still be different from the result you requested.

    You do not need to slow every project down with a heavyweight approval process. You need a definition of done that can survive contact with production. The workflow below turns an SEO concern into a testable requirement, checks the result at the layer where search engines and users encounter it, and leaves evidence another person can reproduce.

    Key takeaways

    • Write the acceptance test before asking an AI or developer to implement the fix.
    • Translate audit labels into mechanisms, affected scope, required behavior, and an observable pass condition.
    • Verify the deployed response, rendered output, crawl behavior, and user-facing result when those layers are relevant.
    • Treat AI explanations, screenshots, successful builds, and closed tickets as supporting evidence, not proof by themselves.
    • Record the build, URLs, inputs, procedure, expected result, actual result, and exceptions so someone else can reproduce the decision.
    • Separate technical verification from business impact: proving that a fix shipped does not prove that rankings, traffic, AI citations, or revenue improved.

    A green status can conceal four different failures

    A green status beacon sits above four transparent pipeline chambers containing different hidden software and website configuration failures.

    Most weak verification starts with one overloaded question: “Is it done?” That question allows several different claims to collapse into one answer. Code can exist without being deployed. A function can run without its output reaching the interface. A page can look correct in a browser while its raw HTML or response headers remain wrong. A crawler can stop reporting an issue because its configuration or crawl path changed.

    Use four checkpoints instead:

    1. Specified: Does the requirement describe the intended behavior precisely enough that two implementers would build the same thing?
    2. Implemented: Is the required logic present in the code, template, configuration, edge rule, or data pipeline that is supposed to provide it?
    3. Deployed and executing: Is that implementation included in the production build, active under the relevant conditions, and operating on the intended URLs or inputs?
    4. Observable: Does the intended recipient actually receive the result through the raw response, rendered page, crawlable link graph, report, interface, API, or other promised delivery surface?

    These checkpoints catch different defects. A unit test may prove that a function behaves correctly while saying nothing about whether the function was wired into the production path. A deployment log may prove that a build reached the server while saying nothing about which markup a crawler received. A backend record may prove that a value was calculated while saying nothing about whether the client ever received or saw that value.

    The risk is not merely theoretical. In one production platform, a core trust-scoring capability was described in documentation and client-facing materials but was absent from the live system. The gap survived eight months of status updates because the updates reported completion without testing the promised capability from end to end.

    That distinction matters even more when AI writes the code. An AI can satisfy the visible shape of a request while missing an unstated business rule, an edge case, a template family, or the connection between backend logic and frontend delivery. Its confident explanation is a description of its attempt. Your acceptance test decides whether the attempt succeeded.

    Write the acceptance test before AI writes the code

    A prompt is not automatically a specification. “Fix the canonicals,” “add schema,” or “improve page speed” names a desired direction, but none defines a finished state. The ambiguity is especially costly when AI can produce a plausible patch before anyone has decided what the site should actually do.

    For each requirement, create a compact acceptance contract with these fields:

    • Problem: State the current mechanism, not a generic tool label. Identify what is absent, duplicated, incorrect, unreachable, delayed, or delivered to the wrong surface.
    • Scope: Name the templates, URL patterns, locales, environments, user states, bot states, or data inputs covered by the change. State important exclusions as well.
    • Required behavior: Describe the exact output and the conditions under which it should appear.
    • Observation point: Say where the behavior must be visible: response headers, server-delivered HTML, rendered DOM, internal link graph, structured data, API response, interface, export, or report.
    • Test procedure: Record the URLs or inputs, the actions to perform, the tool or retrieval method, and the comparison to make.
    • Pass condition: Define an observable result that produces an unambiguous pass or fail.
    • Negative and edge cases: Include conditions where the feature must not run, as well as representative boundary cases.
    • Required evidence: Decide what must be attached to the ticket, such as a response capture, rendered output, crawl extract, test result, or screen recording.

    Consider a canonical issue on product variants. “Fix the canonical tags” leaves the consolidation policy, affected templates, output location, target format, and test method open to interpretation. A workable acceptance contract could instead say:

    • Problem: Variant URLs on the named product template emit self-referencing canonical elements, although the approved policy consolidates those variants to the parent product URL.
    • Scope: The named template and URL pattern only; category pages and independently indexable variants are excluded.
    • Required behavior: Each in-scope variant emits one canonical element whose resolved absolute URL exactly matches its approved parent URL.
    • Observation point: The server-delivered HTML, plus the rendered DOM if client-side code can alter the element.
    • Test procedure: Fetch representative standard, parameterized, and edge-case URLs; compare the emitted target with the approved mapping; then crawl the in-scope pattern to look for recurrence.
    • Pass condition: Every tested URL emits the expected target, no tested page emits a second conflicting canonical, and the scoped crawl finds no instance of the original mechanism.

    This contract does more than test the final patch. It forces the team to decide which variants should consolidate before code is generated. That is the right time to find an unclear policy. If you wait until review, the implementation itself starts dictating the requirement.

    You can ask AI to draft test cases, identify ambiguities, propose edge cases, and explain which files it changed. Do not ask it to define success after it has already selected an implementation. A human owner should approve the expected behavior first, particularly when the change can alter crawling, indexing signals, redirects, rendering, or customer-visible reporting.

    Translate technical SEO findings into build specifications

    An audit tool reports what it detected under its own rules. It does not know your indexation policy, locale model, preferred URL mapping, rendering architecture, business priority, or acceptable exception. That is why forwarding a scanner flag is not the same as writing a specification.

    Before opening a build ticket, identify the underlying mechanism and convert it into a result the implementer can observe. The following patterns show the level of precision to aim for.

    Audit labelMechanism to identifyExample of a verifiable pass condition
    Broken canonicalOn named URLs or templates, determine whether the canonical is absent, duplicated, malformed, non-resolving, or pointed at a target that conflicts with the approved mapping.Each representative URL emits one expected absolute canonical at the required observation point, with no conflicting duplicate; a scoped recrawl finds no recurrence of that mechanism.
    Missing hreflangIdentify the affected locale cluster and whether the failure is a missing entry, an incorrect locale value, a broken target, or an incomplete reciprocal mapping.Every tested member of the approved cluster emits the complete intended mapping, each mapped target resolves as expected, and reciprocal entries are present where the site policy requires them.
    Orphaned pageConfirm that the page is intended to be discoverable through internal links and that the orphan finding is not caused by the crawl seed, exclusions, blocked resources, or a deliberately isolated workflow.The page receives the specified crawlable internal link from the approved source or template and becomes reachable when the agreed crawl is rerun from its defined seed.
    Page speed issueName the affected metric or event, URL or template, test environment, and likely mechanism, such as server delay, a render-blocking resource, or an oversized page component.The specified server, template, asset, or delivery change is present, and the same measurement procedure is rerun on the same scope with the before-and-after evidence attached. Any numerical threshold must come from the project’s approved performance target.
    Structured data issueIdentify the exact entity, property, value, page type, and generation layer involved. Separate invalid syntax from markup that is valid but inconsistent with visible page content or the site’s entity model.The production page emits parseable JSON-LD matching the approved schema contract and visible content on all representative templates, with absent or inapplicable properties omitted according to that contract.

    The last column is deliberately narrower than “SEO improved.” A developer can control whether the required markup, link, header, or response ships. The team cannot turn a ranking, citation, or traffic change into a guaranteed acceptance criterion for one technical ticket. Keep the engineering test causal and observable; measure search outcomes separately over an appropriate period.

    Triage the finding before specifying the fix

    Not every crawler warning deserves development time. Run four checks before converting one into a ticket:

    1. Confirm the mechanism. Inspect representative affected URLs rather than relying only on the tool’s label.
    2. Confirm the intended policy. Decide what the site should do and whether the flagged behavior is genuinely wrong for this template, locale, or page state.
    3. Confirm the scope. Determine whether the issue affects one page, one template, one release path, or a broader class of URLs. Include a known-good comparison where possible.
    4. Confirm the owner and layer. Route the change to the place that produces the defect: server configuration, CDN or edge rule, application logic, template, content entry, client-side rendering, or reporting interface.

    This prevents two familiar mistakes. The first is repairing a symptom at the page level when a template or delivery rule keeps regenerating it. The second is applying a broad template fix to a finding that was actually caused by one malformed record. AI will happily automate either mistake if the requested scope is wrong.

    Verify the production response and leave reproducible proof

    A developer checks a live website response on a laptop while organizing server, crawler, source, and screenshot evidence in an adjacent tray.

    Reviewing code is useful, but technical SEO behavior is often shaped by several layers after the code is written: build configuration, environment variables, content data, feature flags, routing, caches, edge rules, rendering, and deployment state. Verification therefore has to follow the result to the surface where a crawler, user, customer, or reporting recipient encounters it.

    Run a layered release check

    1. Freeze the requirement and baseline. Save the acceptance contract and capture the failing response, page, crawl result, or user-facing behavior before implementation. Without a baseline, a changed result can be mistaken for a correct one.
    2. Inspect the implementation layer. Confirm that the relevant code, template, rule, mapping, or configuration exists and covers the stated conditions. This catches omitted logic and accidental changes outside scope.
    3. Run focused automated tests. Test the core rule and the edge cases identified in advance. A passing build is not enough when the build contains no assertion for the requirement you care about.
    4. Confirm the deployed artifact. Tie the test to a build or release identifier. Verifying a local branch or staging build does not prove that the same change reached production.
    5. Observe the receiving surface. Inspect the raw status, headers, and HTML when the requirement lives there. Render the page when scripts can create or modify the output. Crawl from the agreed seed when discovery or internal linking is the concern. Open the interface or export when a customer-visible result was promised.
    6. Test representative failures and exclusions. Check a normal case, an edge case, and a case where the behavior must not apply. A feature that works everywhere can be just as wrong as one that works nowhere.
    7. Repeat the check in production. Re-run the defined procedure against the live URLs or inputs after deployment. If caching or delayed processing is part of the system, verify the result after the relevant layer has updated rather than assuming a purge or job completed.
    8. Run a scoped regression check. Confirm that adjacent templates, locales, page states, or outputs named in the risk assessment still behave as intended.

    Choose only the layers that can affect the requirement, but do not stop one layer early. If the promise is “the customer can see the score,” a correct database value is intermediate evidence. If the promise is “a crawler receives this canonical,” a correct component in the source repository is intermediate evidence. In both cases, the final check belongs at the receiving surface.

    Build a proof packet another person can reproduce

    A screenshot can help, but it rarely captures request conditions, raw markup, build identity, or scope. Close the ticket with a small proof packet containing:

    • The requirement or acceptance-test identifier.
    • The production build, release, or configuration version tested.
    • The exact URLs, inputs, locale, login state, user agent, or feature state needed to reproduce the check.
    • The test date and environment.
    • The retrieval, rendering, crawl, validation, or interface procedure used.
    • The expected result beside the actual result.
    • Raw evidence where relevant, such as response headers, HTML, JSON-LD, API output, a crawl extract, an automated test result, or a user-facing capture.
    • Any exceptions, unresolved cases, and the person responsible for the next decision.

    This changes reporting from activity to evidence. “The canonical fix was deployed” reports an action. “The named production build emitted the approved canonical for the standard, parameterized, and edge-case samples; the scoped crawl found no recurrence; one excluded template was unchanged” reports a verified result and its boundary.

    Keep technical proof separate from search impact

    Verification should also limit what you claim. A passing structured-data test proves that the tested markup conforms to your approved contract. It does not prove that a search engine will display a feature or that an AI system will cite the page. A correct canonical implementation proves that the declared signal shipped. It does not prove which URL a search engine will ultimately select or how rankings will move.

    Report those as separate layers:

    • Delivery: What code, configuration, template, or content change entered production?
    • Technical behavior: What did the live system return or display under the defined test conditions?
    • Coverage: How much of the intended URL, template, locale, or user-state scope passed?
    • Search or business outcome: What later changed in discovery, indexing, visibility, citations, traffic, leads, or revenue, and what other factors prevent a simple causal claim?

    This separation protects decision quality. A failed search outcome does not retroactively mean the implementation test was invalid, and a successful implementation does not justify claiming an outcome that has not been measured.

    Make evidence part of the definition of done

    The workflow becomes durable when the ticket cannot close without its proof packet. Let AI generate code, suggest cases, draft automated checks, and compare outputs. Keep human ownership over the intended policy, acceptable scope, production evidence, exceptions, and business claim.

    Start with one open technical SEO ticket. Replace its audit label with the exact mechanism, affected scope, required production behavior, observation point, and pass condition. If you cannot describe the evidence that would make you close it, the work is not ready to be built. If you can, both the AI and the reviewer have a standard they can actually meet.

    References