Category: Technical optimization

  • Technical SEO Experiment Design: A Practical Framework

    Technical SEO Experiment Design: A Practical Framework

    You shipped a technical SEO change, watched the graph move, and now someone wants to know whether the change caused it. A before-and-after screenshot cannot answer that question. Demand, competitors, algorithm updates and overlapping site changes keep moving, whether your deployment works or not.

    A useful experiment gives you a defensible rollout decision. It identifies the pages that actually received the treatment, compares them with pages facing the same outside conditions, waits for search engines to encounter the change, and defines what success means before anyone sees the result.

    Start with the rollout decision, not the dashboard

    Do not begin with a broad question such as, "Do internal links help SEO?" You cannot turn the answer into a clean implementation decision. Begin with the exact change under consideration and the scope of the possible rollout.

    Suppose you manage a multi-location site. Location pages are reachable mainly through a central locator and state pages, and you want to add contextual links. A testable intervention would be: add one consistently placed module to selected location pages, with links to three nearby locations and two relevant service pages. The design, placement, link count and selection logic stay fixed throughout the treatment group.

    That definition is narrow enough to reproduce. It also prevents the test from quietly becoming a bundle of internal links, rewritten copy, new navigation and a redesigned template. If all four change together, you may learn that the bundle performed differently, but you will not know which part deserves the rollout.

    Write a one-page test charter

    Your test charter should settle the following points before implementation:

    1. Decision: State what you will roll out, reject or revise after the test.
    2. Eligible population: List the templates, directories or page types to which the decision could apply. Record exclusions such as newly launched pages, unstable markets or pages scheduled for another change.
    3. Treatment: Describe the implementation precisely enough that another developer could reproduce it without filling in missing choices.
    4. Unit of assignment: Decide whether you are assigning individual pages, page clusters, markets, categories or templates.
    5. Expected mechanism: Explain the step between the implementation and the desired outcome.
    6. Primary outcome: Choose the metric that will determine the decision. Treat other metrics as diagnostic or protective guardrails.
    7. Decision rules: Define success, failure and inconclusive results before the data arrives.

    A useful hypothesis connects the treatment, mechanism, affected pages and comparison. For the location-page example, it could be: "Adding contextual links from selected location pages to related location and service pages will strengthen crawl paths and internal signals, improving the organic visibility of those destinations relative to comparable pages that retain the existing structure."

    Notice that the receiving pages are central to the hypothesis. The pages displaying the module are not necessarily where the benefit will appear. If your implementation changes how authority and crawlers reach other URLs, those destination URLs belong in the measurement plan.

    Replace vague decision language with operational definitions. "Meaningful improvement" should refer to a minimum effect worth the engineering effort and rollout risk. "Enough data" should require verified implementation, adequate crawl exposure and a stable comparison. Set those standards now. Choosing them after seeing the graph invites the team to move the goalposts.

    Choose the strongest counterfactual your site can support
    Two matched rows of abstract web-page modules travel through the same environment, while a precision device changes one component in only one row.

    The central design question is not what happened after launch. It is what would probably have happened to the treated pages during the same period without the change. Your control or comparison group is an attempt to estimate that missing outcome.

    No SEO control is perfect. Pages differ in age, authority, search intent, link history, demand, competition and seasonality. They also interact through shared templates and internal links. Your job is to build the strongest comparison the site genuinely supports, then state where it remains weak.

    DesignUse it whenWhat it improvesMain limitation
    Concurrent split testYou have a large, stable set of sufficiently similar pages and can safely withhold the change from part of it.Treatment and control experience the same calendar period, helping account for demand shifts, seasonality and broad search changes.A nominally random split can still be imbalanced when markets, categories or page histories differ sharply.
    Matched page groupsA clean split is impractical, but you can identify pages or sections with similar historical behavior.Matching can account for baseline trajectory, demand, crawl frequency, indexing, page age or market characteristics.Unmeasured differences can still explain part of the result.
    Phased rolloutThe change is intended for the whole site, but it can be introduced across markets, categories or templates in stages.Untreated phases provide temporary concurrent controls while delivery continues.The control disappears as rollout advances, and later phases may face different conditions.
    Before-and-after observationNo credible concurrent control is available.It can reveal direction and surface implementation problems.It cannot reliably separate the change from external events, so conclusions must remain limited.

    Do not assume a 50/50 split creates comparable groups. A location-page template can cover major cities, small markets, mature pages and recent launches. If the stronger markets land disproportionately in one group, random assignment has not rescued the design.

    Build the groups in this order:

    1. Create the eligible page pool using the exclusions in your test charter.
    2. Collect pre-test behavior for the metrics connected to the hypothesis, including clicks, impressions, rankings, crawl activity or indexing where relevant.
    3. Describe structural differences such as page age, market size, branded demand, template subtype and known seasonal behavior.
    4. Pair, stratify or match pages using characteristics that could plausibly affect the outcome.
    5. Inspect the historical trajectories of the proposed groups. Similar current totals are less useful when one group has been rising and the other declining.
    6. Lock the assigned URLs before launch and preserve that list. Do not move inconvenient pages between groups after results begin to appear.

    Historical co-movement often matters more than equal starting values. A higher-traffic treatment group can still be informative when it has moved like the comparison group over time. Conversely, two groups with matching traffic on launch day may be poor controls if their preceding trends point in opposite directions.

    When the page pool is small or highly varied, honest matching may produce a stronger test than a ceremonial random split. The method should reflect the control you possess, not the certainty you want to present.

    Protect the treatment from contamination and spillover

    A strong comparison will not save a test whose implementation keeps changing. Freeze the feature being tested, record unrelated releases and make ownership explicit. If a critical production fix must alter the affected template, document the date, affected URLs and expected influence instead of pretending the test remained untouched.

    Use an implementation checklist before examining outcomes:

    • Confirm that every assigned treatment page received the intended feature and every control page remained untreated.
    • Check the production output a crawler can encounter, not only a component preview or staging screenshot.
    • Validate the destination URLs, link selection logic, canonical targets and status behavior relevant to the change.
    • Record partial deployments, rollbacks, rendering failures and pages added or removed during the test.
    • Keep a dated change log for migrations, template releases, navigation changes, content programs and other work that could affect either group.
    • Preserve the original page assignments even if some URLs later need to be excluded from the final analysis. Record exclusions and their reasons separately.

    Internal-link experiments need an additional check: treatment can spill beyond the page carrying the new module. If treatment page A links to control page B, page B may receive part of the intervention. Comparing A with B as though only A were exposed would misstate what the test changed.

    Map the link graph created by the feature before assigning groups. When pages are tightly connected, assign coherent clusters, markets or sections rather than individual URLs. If cross-group links cannot be avoided, label the affected destinations and interpret the comparison as partially contaminated.

    Contamination also works in the opposite direction. A shared template update, global navigation change or sitewide indexing problem can reach both groups. A concurrent control may help absorb the common movement, but only if you know the event occurred and can verify that it affected the groups similarly.

    Measure exposure before judging the SEO outcome
    A glowing probe scans a network of web-page tiles, illuminating encountered treated pages while other pages and blocked routes remain dim.

    A deployment timestamp is not proof that the search system has encountered your treatment. Search engines have to revisit the relevant pages, process what they find and propagate any downstream effects. Calling a test early because a fixed number of calendar weeks has passed can turn an exposure failure into an apparent SEO failure.

    Think in three clocks. The development clock starts when the release reaches production. The exposure clock advances as the affected source and destination pages are crawled and processed. The outcome clock covers the period in which the hypothesized search effects have a reasonable opportunity to appear. These clocks rarely start together.

    Build the measurement stack in layers:

    • Deployment: How many assigned pages contain the correct treatment? How many controls were accidentally changed?
    • Exposure: Which treated source pages and affected destination pages have been recrawled since deployment? Is crawl coverage broad enough to evaluate the group?
    • Mechanism: Did the signals closest to the intervention move, such as crawl activity, discovery or indexing where those are part of the hypothesis?
    • Primary outcome: Did the predefined visibility, ranking, impression, click or traffic measure improve relative to the comparison?
    • Guardrails: Did the change create declines, crawl waste, indexing problems or regressions elsewhere in the eligible population?

    Report coverage, not just elapsed time. If only a limited portion of affected pages has been revisited, the result is not yet a fair test of the implementation. Insufficient recrawling can make an otherwise valid change look ineffective.

    Match every metric to a place in the causal chain. For an internal-linking test, crawl behavior is closer to the implementation than organic clicks. That makes crawl data useful diagnostic evidence, but it does not automatically make it the business outcome. If crawl activity improves while visibility does not, you have evidence for one step of the mechanism, not proof that the full hypothesis succeeded.

    Measure both sides of a transfer. Track the pages carrying the new links to verify implementation and the pages receiving them to test the expected benefit. Aggregating the whole site can hide the effect by mixing exposed destinations with thousands of unaffected URLs.

    Use the launch date as an annotation, not as an automatic verdict date. The stopping rule should depend on verified exposure, usable outcome data and the continued validity of the comparison. If those conditions are not met, classify the result as inconclusive rather than extending or ending the test until the graph tells the preferred story.

    Turn the result into a rollout, rejection or retest decision

    Start with the comparison, not the treatment group’s raw chart. At minimum, calculate how the treatment changed from its baseline and how the control changed over the same period. The difference between those changes is the incremental estimate you care about. Use the metric transformation and aggregation method you selected before launch; switching between totals, averages and percentages after seeing the data is another way to manufacture a favorable reading.

    Then classify the result against the prewritten rules:

    • Success: The implementation and exposure checks pass, the primary outcome improves relative to the comparison by a practically worthwhile amount, and guardrails remain acceptable. Roll out to the population represented by the test, not automatically to unrelated templates or markets.
    • Failure: Exposure and comparison quality are adequate, but the primary outcome shows no meaningful incremental benefit or declines. Do not rescue the test by promoting a secondary metric that happened to move.
    • Inconclusive: Crawl exposure is insufficient, treatment integrity failed, the groups stopped being comparable, contamination was material or the available signal cannot support a decision. Fix the design and retest if the decision remains valuable.

    Mixed results need a causal reading. If crawl activity improves but rankings do not, the change may have influenced the early mechanism without producing the intended visibility outcome. That can justify further investigation, but it is not a ranking win. If both treatment and control rise together by similar amounts, the movement is evidence of a shared condition, not an incremental treatment effect. If only a narrow page subtype benefits, consider a targeted rollout rather than averaging the subtype away or extending the feature everywhere.

    Write the final decision with its boundary conditions. Name the tested page population, intervention, exposure status, comparison method, primary result, important guardrails and known weaknesses. A result from established location pages does not automatically establish the same effect for editorial articles, product pages or newly launched markets.

    Key takeaways

    • Define the rollout decision, treatment, mechanism, affected pages and primary outcome before implementation.
    • Use a concurrent split when page volume and comparability permit it; otherwise use matched groups, a phased rollout or a carefully qualified before-and-after observation.
    • Compare historical trajectories, not just launch-day traffic, when building treatment and control groups.
    • Prevent overlapping releases and cross-group links from contaminating the intervention.
    • Verify deployment and crawl exposure before interpreting rankings, clicks or traffic.
    • Predefine success, failure and inconclusive states, then keep secondary metrics in their diagnostic roles.

    Your next step is small: choose one pending technical change and write its test charter before the implementation ticket is finalized. If you cannot name the decision, comparison, affected URLs, exposure check and stopping rule on one page, the experiment is not ready to launch.

    References


  • How to Control Accessibility Risk in AI-Generated Websites

    How to Control Accessibility Risk in AI-Generated Websites

    Your AI-built page renders cleanly, the form submits, and the structured data validates. None of that tells you whether a customer can navigate it with a keyboard, understand it through a screen reader, or recover from an error without sight.

    The practical decision isn’t whether to use AI. It is whether your team treats AI output as an untrusted draft or as proof that a page is ready. A reliable process keeps the speed while putting human usability, measurable acceptance criteria, and release authority around it.

    AI scales familiar accessibility failures

    AI-generated experiences do not need exotic defects to exclude people. The persistent failures are ordinary: low-contrast text, images without useful alternative text, form fields without labels, links and buttons without accessible names, and pages that do not declare their language.

    The 2026 WebAIM Million report found detectable accessibility failures on 95.9% of the top one million homepages, averaging 56.1 errors per page. The number of detected errors increased 10.1% after six consecutive years of improvement. At the same time, the average homepage grew to 1,437 elements, 22.5% more than a year earlier and nearly twice the 2019 count.

    Those numbers do not prove that AI alone caused the increase. They do show the environment in which AI tools now operate: complex pages, rapid production, and recurring defects embedded in the examples that code generators can reproduce. When one flawed component is reused across a navigation system, form builder, landing-page template, or personalization layer, the problem scales with it.

    The hardest failures are often invisible in a visual review. An empty button can still have a polished icon. A field can appear to have a label even when the label is not programmatically connected to it. A modal can look correct while trapping keyboard focus. A validation message can be bright red yet never be announced by assistive technology.

    This is where SEO and AI-optimization teams need a precise distinction. Machine-readable is not the same as human-operable. Valid JSON-LD, descriptive metadata, crawlable text, and clean schema relationships cannot make an inaccessible checkout, lead form, menu, or account flow usable. Treat accessibility as a property of the rendered experience, including every interactive state, rather than another item on a technical SEO validation report.

    Make accessibility a release gate, not a prompt adjective

    Three reviewers test an unlabeled website interface with a keyboard, headphones, braille display, and mobile device before a closed release gate.

    Adding the word accessible to an AI prompt can improve the direction of an output. It cannot certify the result. The prompt is an instruction; the release gate is the evidence that the instruction was followed.

    Define what ready means before generation starts

    Your acceptance criteria should describe observable behavior. They should apply to the initial page and to the states created after a person opens a menu, submits incomplete information, changes a filter, launches a modal, or receives a success message.

    Release layerWhat to verifyReason to stop publication
    Page structureDocument language, meaningful headings, semantic regions, and native controls where availableStructure or reading order does not convey the same meaning as the visual layout
    Content and perceptionRequired contrast, useful image alternatives, understandable instructions, and information that is not conveyed by color aloneA person cannot perceive essential content or distinguish a required state
    Forms and controlsConnected labels, descriptive control names, instructions, validation, and error recoveryA field or action is unnamed, ambiguous, or impossible to correct
    Keyboard behaviorLogical focus order, visible focus, activation, backward navigation, and a way to leave overlaysA task traps focus, hides focus, or requires a pointer
    Dynamic behaviorChanges in state, expanded or collapsed controls, loading, errors, and completion feedbackImportant changes are visible but not exposed to assistive technology

    Set the applicable accessibility requirement with a qualified specialist before you turn this table into a formal conformance gate. Legal obligations, contractual commitments, and technical standards can differ by market and product. The table is an operational starting point, not a legal opinion or a substitute for a conformance assessment.

    Give the generator constraints it can act on

    An effective generation brief names the behavior you expect and asks the model to expose uncertainty. Include requirements such as these:

    • Use semantic HTML and native links, buttons, inputs, and headings before creating custom interactive elements.
    • Give every interactive control a clear accessible name that describes its action or destination.
    • Connect each form field to its label, instructions, required state, and error message.
    • Make the complete task operable by keyboard, with a logical order and visible focus.
    • Provide meaningful alternative text for informative images and handle decorative images so they do not create noise.
    • Declare the document language and preserve a meaningful heading hierarchy.
    • Do not use color, position, shape, or animation as the only way to communicate information.
    • List any requirement the generated output cannot verify without browser testing or human review.

    That final instruction matters. It separates code generation from verification and makes unsupported assumptions visible before they become release assumptions.

    Put the same constraints into your component specifications, CMS templates, design-system documentation, and definition of done. A good one-off prompt cannot compensate for a shared component that keeps producing empty buttons or disconnected labels.

    Test the journeys an automated scan cannot complete

    Two usability participants test abstract web forms using a braille display, keyboard, headphones, and an adaptive switch while a researcher observes.

    Automated inspection is valuable because it can cover many pages quickly and catch repeatable markup problems. It is not an end-to-end usability test. AudioEye estimates that automated tools can detect about two-thirds of accessibility issues and automatically fix about half of the issues they detect. Because that is a vendor-supplied estimate rather than a universal benchmark for every tool and website, use it as a warning about coverage limits, not as a guaranteed detection rate.

    Use four complementary checks:

    1. Run automated inspection across templates and states. Scan more than the public URL. Include opened menus, validation errors, filtered results, modals, account states, and any page variation inserted by your CMS or personalization system.
    2. Complete the task with a keyboard. Start before the first control, move forward and backward, activate every required action, and confirm that focus remains visible and predictable. Verify that overlays can be closed and that focus returns somewhere sensible.
    3. Complete the task with assistive technology. Check whether headings describe the page, controls have useful names, expanded and selected states are communicated, fields have connected instructions, and errors are announced at the point where the user needs them.
    4. Review meaning with a person. Automation can detect a missing text alternative more easily than it can judge whether the supplied text communicates the image’s purpose. The same distinction applies to generic link text, unclear instructions, confusing heading order, and technically present but unhelpful labels.

    Do not begin with a random sample of low-impact pages. Start with the journeys whose failure blocks a result: purchase, lead submission, registration, authentication, search, account management, and support. Then test the shared header, navigation, cookie controls, forms, and modal components that appear across many URLs. Fixing the reusable component reduces recurrence; patching individual generated pages leaves the underlying production fault in place.

    For each journey, write the task in plain language before testing. For example: find a product, choose an option, add it to the cart, correct an invalid field, and finish checkout. A pass means the person can complete the entire task and understand the result. A clean scan on the opening screen is not a substitute.

    When a failure appears, prioritize it by consequence and reach:

    1. A blocker that prevents a person from completing a critical task.
    2. A defect in a shared component that affects many pages or states.
    3. A serious information or error-recovery failure that can produce a wrong action.
    4. An isolated content defect on a high-traffic or high-intent page.
    5. A lower-impact issue that does not block the task but still needs a named owner and deadline.

    Do not suppress a scanner warning merely to improve a dashboard score. Resolve it, document why it does not apply, or have someone qualified review the ambiguity. The goal is a usable journey, not a smaller count.

    Make ownership and evidence visible

    Accessibility fails operationally when everybody can influence the experience but nobody can stop its release. Assign responsibility at the point where each type of defect enters the system:

    • The requester or marketer owns the brief, content clarity, image intent, link purpose, and acceptance criteria.
    • The designer owns contrast choices, focus treatment, interaction states, responsive behavior, and the visual presentation of errors.
    • The developer or platform owner owns semantic implementation, keyboard behavior, programmatic relationships, dynamic state, and regression fixes.
    • A qualified accessibility reviewer performs the manual and assistive-technology checks that automation cannot settle.
    • The release owner has explicit authority to block publication or record a time-bound exception with its risk, owner, and remediation date.

    One person may hold several of these roles in a small team. The important part is that none of them remain implied.

    A purchased tool is not evidence that a journey works

    AudioEye’s 2026 litigation analysis reports that U.S. digital accessibility lawsuits doubled from 2020, with 26,253 combined federal and state claims filed in 2025. Ecommerce accounted for 78% of the cases in its dataset. More revealingly, 38.5% of companies facing claims already had an accessibility tool in place.

    That does not show that accessibility tools increase litigation risk. It shows why buying a tool, installing a badge, or reporting a partial score should not be confused with verifying a working experience.

    Partial coverage can also be a weak legal position. On June 4, 2026, a French court ordered Carrefour to bring its website and app to full accessibility conformance within six months, rejecting claimed conformance levels of 50% to 70% as a defense in that case. The ruling is jurisdiction-specific; it is not a universal interpretation of every accessibility law. If you need to determine your legal obligations or exposure, involve qualified accessibility professionals and legal counsel familiar with each market in which you operate.

    Report outcomes, not just defect totals

    An issue count is useful for triage, but it can hide severity. One unnamed checkout button can matter more than many low-impact warnings on an informational page. Put these measures beside the marketing and product metrics your team already reviews:

    • Critical journeys tested and the states covered in each test.
    • Blocking defects, affected templates, and affected business actions.
    • Repeated defects traced to shared components or generation instructions.
    • Open issue age, named owner, target date, and retest status.
    • Regressions found after CMS, component, campaign, or personalization changes.
    • Conversion, completion, abandonment, and bounce metrics for remediated high-traffic pages.

    Record the page or component version, test date, automated tool, manual scenarios, reviewer, results, and fixes. That history helps you distinguish an isolated content mistake from a systemic production problem. It also gives the next release team a known test set instead of forcing them to rediscover the journey.

    If you compare conversion before and after remediation, avoid claiming that accessibility alone caused the change when traffic mix, campaign creative, pricing, or other page elements also changed. Use a controlled test where practical, or annotate the competing changes. Accessibility should not need an immediate conversion lift to justify removing a barrier, but weak attribution will not help you secure lasting operational support.

    Key takeaways

    • Treat AI-generated code and content as drafts until the rendered journey passes defined accessibility checks.
    • Test interactive states and task completion, not only the opening screen or public URL.
    • Combine automated coverage with keyboard, assistive-technology, and human meaning reviews.
    • Fix shared components and generation constraints before patching the same defect page by page.
    • Assign a release owner who can block publication and require evidence of retesting.
    • Do not treat a tool, badge, issue score, or partial conformance percentage as proof that customers can use the experience.

    Start with the next high-consequence page in your production queue. Write down the three tasks a visitor must complete, name the person who will test them without relying on a mouse, and reserve time to fix the shared component if one fails. Do that before publication, then carry the same gate into every AI-assisted template. That is how accessibility becomes part of production rather than an emergency after launch.

    References

  • AI Crawler Blocking and Publisher Citations: What to Do

    AI Crawler Blocking and Publisher Citations: What to Do

    If you publish original reporting or expert content, AI access can look like a blunt choice: allow crawlers and risk uncontrolled reuse, or block them and risk disappearing from AI answers. That framing is too simple to support a sound policy.

    Your real decision is narrower: which forms of access serve your publishing goals, which ones create unacceptable risk, and what evidence would justify changing the rules? Treating every AI bot as the same crawler makes all three questions harder to answer.

    Blocking is a crawler instruction, not a citation switch

    A rule in robots.txt tells a matching, compliant crawler whether it may request specified URLs. It does not directly tell an answer engine to cite your pages, remove an existing citation, forget previously acquired material, or resolve questions about licensing and content rights.

    That distinction matters because crawler blocking does not produce one consistent citation outcome. An analysis spanning 31 million AI citations and the robots.txt files of 105 publishers found that blocking affected some models but appeared to do nothing on others. This is strong evidence against treating a sitewide block as a universal off switch. It does not establish how every individual engine will respond to your site.

    Several mechanisms can explain why a blocked domain may still appear in an answer. An engine may already hold an older representation of the page. It may encounter the information through syndication, quotation, feeds, links, or another accessible copy. A vendor may also use different access paths for training, indexing, search retrieval, and user-requested page fetching. Blocking one declared user agent controls only that user agent’s future requests to the covered URLs.

    Key takeaways

    • Blocking an AI crawler may change citations in one model and have no observable effect in another.
    • A citation is an output from an answer system; robots.txt governs one input path.
    • Do not use a sitewide block when your actual concern applies only to a particular crawler, content section, or use case.
    • Measure citation coverage, freshness, referrals, and crawl activity before and after a change.
    • Keep every policy change documented and reversible because crawler identities and model behavior can change.

    Separate training, discovery, retrieval, and citation

    A central digital library connects to four separate gated routes for bulk transfer, scanning, single-document retrieval, and a return link to a source.

    Publishers often say they want to block AI when they mean one of four different things. You may object to model training. You may want to prevent a page from entering an AI search index. You may want to stop live retrieval when a user asks a question. Or you may want an engine to stop naming your domain in generated answers.

    Those are not interchangeable objectives. A policy can restrict one access path without producing the desired result at another layer. Before editing robots.txt, write down the exact outcome you want and the evidence that would prove you achieved it.

    Decision layerThe question to answerEvidence to collect
    TrainingDo you permit this vendor to use covered content for model development?The vendor’s documented crawler purpose, your agreements, and applicable rights guidance
    DiscoveryDo you want new and updated URLs available to the engine’s search or retrieval system?Declared crawler activity, discovery of test URLs, and citation freshness
    Live retrievalMay the system fetch a page in response to a user’s request?Server requests associated with controlled prompts and the responses returned
    CitationDoes your domain receive visible attribution in answers that rely on your subject matter?A fixed query set, cited URLs, answer captures, dates, and referral traffic

    Build a crawler registry around those layers. For each user-agent token, record the vendor, declared purpose, official documentation you relied on, current directive, affected paths, date added, internal owner, and next review trigger. A label such as AI bot is not precise enough. If you cannot verify what a token controls, mark it unverified instead of guessing from its name.

    Audit every hostname that serves publishable content. A correct policy on the main domain does not tell you what is served from a separate news, mobile, archive, or syndicated host. Fetch the live /robots.txt file from each relevant hostname, then compare the returned file with the configuration you intended to deploy.

    Choose the policy that matches the value you protect

    There is no universally correct balance between AI visibility and access control. A publisher funded by subscriptions may value exclusivity differently from a specialist publication that depends on discovery and authority. The right policy starts with the business outcome, not with a generic list of bots.

    If AI citations are a discovery channel

    Preserve the access paths that appear to support discovery and retrieval while evaluating training controls separately. Do not assume that allowing every AI-labeled crawler will buy citations. Permission is only a prerequisite for a crawler to request content; it is not a promise that the engine will select, quote, or attribute your page.

    Prioritize the content where attribution has measurable value: original reporting, unique datasets, primary explanations, product documentation, and pages that answer recurring audience questions. Track whether engines cite the canonical page, an outdated URL, a syndicated copy, or another site discussing your work. That URL-level distinction tells you more than a domain-wide visibility score.

    If content control is the primary concern

    Block the verified crawler or protected path that corresponds to the concern, then define what success means. Success might be the end of requests from that declared user agent. It should not automatically be defined as disappearance from every generated answer, because blocking may not remove previously acquired material or copies available elsewhere.

    Do not treat robots.txt as a licensing agreement or a complete legal remedy. It is a technical access signal. If the decision affects contracted syndication, paid archives, copyright enforcement, or material revenue, have qualified legal counsel review the policy and the relevant agreements before you rely on the file as protection.

    If you need a balanced default

    Use selective controls rather than an undifferentiated allow-all or block-all rule. Keep public, citation-worthy pages available to verified discovery or retrieval crawlers when that supports your goals. Apply narrower restrictions to premium sections, private utilities, internal search results, duplicate archives, or other areas that have a different value and risk profile.

    Path-level rules require operational discipline. A careless pattern can cover more URLs than intended, and a later site migration can change what the pattern matches. Pair each directive with a plain-language note describing its purpose and test representative allowed and blocked URLs after every deployment that touches routing, hostnames, or robots.txt.

    Measure a block as a controlled publishing change

    Two matching content setups are observed side by side while an editor changes one removable access gate and leaves the other conditions aligned.

    A citation audit cannot tell you much if the query set, content, and crawler policy all change at once. Use a fixed protocol so that a drop or gain has a plausible connection to the rule you changed.

    1. State the hypothesis. Name the crawler or access path, the URLs affected, the expected outcome, and the downside you are willing to accept.
    2. Create a baseline. Record current directives, server requests, AI citations, cited URLs, answer captures, referral sessions, and publication dates before making the change.
    3. Use a stable query set. Include branded questions, non-branded questions where your content is eligible, and queries tied to newly published material. Keep the wording fixed during the test.
    4. Change one crawler family or content segment. Multiple simultaneous blocks may be quicker to deploy, but they make the result difficult to interpret.
    5. Verify the live rule. Fetch the public file, test representative URLs, and confirm that unrelated search crawlers and content sections retain their intended access.
    6. Observe a normal publishing cycle. Your measurement period must include enough new and updated content to reveal whether discovery and citation freshness changed. A quiet interval cannot test freshness.
    7. Repeat the same checks. Use the same engines, query wording, account state where practical, location assumptions, and capture method. Generated answers can vary, so retain the underlying observations rather than only a summary score.
    8. Compare by engine and URL class. A blended total can hide a decline in one model, an increase in another, or a problem limited to recent reporting.
    9. Keep or reverse the rule. Apply a decision threshold chosen in advance. Document the result even when no effect is visible.

    Define citation coverage as the share of eligible test queries that produce at least one citation to your domain. Record citation accuracy separately: whether the linked page actually supports the claim beside it. Also measure citation freshness as the interval between publication or material update and the first observed citation. These metrics answer different questions. A domain can maintain overall coverage while engines continue citing old pages.

    Referral sessions are useful but incomplete. A visible citation can influence recognition without receiving a click, while an uncited brand mention will not appear in citation counts. Keep citations, mentions, referral traffic, and crawler requests as separate columns so that one metric does not stand in for the whole outcome.

    Server logs provide another necessary check, but declared user-agent strings are not proof of identity on their own. Use the vendor’s current verification method where one is available, retain request details needed for analysis, and classify unverifiable traffic separately. Otherwise, spoofed or mislabeled requests can make a supposedly precise crawler report misleading.

    Watch for confounders before claiming that a directive caused the result. Major content revisions, URL migrations, canonical changes, paywall changes, syndication launches, engine updates, and shifts in publishing volume can all alter citations during the same period. Note those events in the audit log and rerun the test when the result is ambiguous.

    Make the next crawler decision reversible

    Do not deploy a sitewide AI block merely because you expect it to erase citations, and do not allow every AI crawler merely because you want more visibility. Neither expectation is supported as a universal rule.

    Open your live robots.txt file and turn its AI-related directives into a crawler registry now. Give every rule a verified target, a business purpose, an affected URL set, a success metric, and a rollback condition. If a rule has none of those, it is not yet a strategy; it is an assumption running in production.

    References

  • How to Prioritize SEO Technical Debt Without Wasting Sprints

    How to Prioritize SEO Technical Debt Without Wasting Sprints

    Your crawler has finished, and now you have 10,001 flags competing for attention. The highest counts look urgent, the tool has assigned severity labels, and someone wants to know how quickly the team can make the report green.

    Do not turn that export into your roadmap. Your job is to find the small set of problems that obstruct valuable pages, repeat through important templates, or become more expensive if they survive the next release. Everything else should be scheduled, monitored, or deliberately left alone.

    Start with page value, not issue volume

    Technical SEO debt is the gap between the site you have and the technical foundation needed to support organic discovery, indexation, performance, and growth. It can sit in crawling, indexation, architecture, templates, performance, migrations, structured data, or reporting. That breadth is why a raw list of errors is such a poor prioritization system.

    A warning matters only in context. A canonical conflict on a revenue-generating template is a different problem from the same conflict on an old tag page with no impressions. A missing meta description on an important category page may deserve attention; the same omission across zero-impression utility URLs may have no useful upside. Issue type alone cannot tell you what to do.

    Segment the site before scoring the debt. At minimum, separate these groups:

    • Revenue and conversion pages: Product, service, category, lead-generation, signup, or other pages tied to a valuable action.
    • Organic discovery pages: Editorial, educational, comparison, glossary, location, and other pages intended to attract demand.
    • Supporting pages: Content that strengthens navigation, topical relationships, trust, or the user journey without being the final conversion destination.
    • Utility pages: Account, filter, sort, search, print, login, and operational URLs that may not belong in search results.
    • Legacy and generated URLs: Redirected paths, parameters, faceted combinations, outdated structures, and other URLs created by historical or automated behavior.

    For each segment, record its intended indexation state, business purpose, organic role, template, and owner. This prevents a common audit failure: treating every crawlable URL as though it should rank. An excluded utility URL may be working exactly as intended, while one excluded product template could represent a serious access problem.

    Then validate whether each finding is isolated or systemic. Sample representative URLs and inspect the underlying template or rule. A thousand warnings caused by one template defect are one scalable problem, not a thousand separate tasks. Conversely, one incorrect robots.txt rule can be more urgent than thousands of harmless metadata warnings.

    Put every finding into one of four action buckets

    A miniature audit station sorts small issue tokens into a repair bench, a future-work shelf, an observation chamber, and an archive compartment.

    Every finding should end with a decision, not merely a severity label. Use four buckets: fix now, fix soon, monitor, and ignore for now. The boundaries depend on affected pages and outcomes, not on how alarming the crawler makes the warning look.

    ActionUse it whenTypical examples
    Fix nowThe issue blocks or materially weakens access, discovery, ranking, conversion, or a business-critical path.Noindex directives on priority pages; robots.txt blocks on important sections; key pages canonicalized elsewhere; broken migration redirects; broken internal links to revenue pages; slow core templates; competing duplicate page sets.
    Fix soonThe issue creates meaningful drag, affects a valuable segment, or will constrain growth and maintenance if allowed to spread.Buried priority pages; outdated XML sitemap entries; faceted crawl waste; missing schema on important templates; thin indexable pages at scale; inconsistent heading templates.
    MonitorThe possible impact is limited or unclear, and current performance does not justify immediate work.Minor performance misses on low-traffic pages; a few redirect chains; duplicate titles on low-value URLs; non-critical crawl anomalies; JavaScript concerns involving non-indexable elements.
    Ignore for nowThe imperfection does not affect search access, valuable journeys, current performance, or future scalability.Missing descriptions on zero-impression pages; old 404s with no traffic or links; duplicate headings on utility pages; low-value HTML validation warnings; flags on intentionally blocked or noindexed URLs.

    The phrase for now matters. Ignoring an issue is a documented decision based on current scope and impact, not a claim that the issue can never matter. A warning on a dormant template may move into the roadmap if that template becomes part of a launch, migration, or expansion.

    Use this decision sequence when a finding is disputed:

    1. Confirm intent. Is the directive, status code, canonical, internal-link pattern, or generated URL behavior deliberate?
    2. Identify the affected segment. Does the issue touch pages that should be discovered, indexed, ranked, or used to complete a valuable action?
    3. Describe the mechanism. State how the issue could affect crawling, indexation, internal authority flow, page understanding, user experience, or conversion. If you cannot describe a credible mechanism, do not assign an urgent priority.
    4. Check observable impact. Review indexation, impressions, organic traffic, conversions, crawl behavior, and affected search journeys where those measurements are available.
    5. Find the root cause. Determine whether the defect lives in one URL, a template, navigation, platform configuration, rendering, or a migration rule.
    6. Assess delay risk. Ask whether waiting leaves performance stable or allows the problem to spread, compound, or become embedded in another release.

    This sequence also exposes false emergencies. A crawler may flag blocked pages because it cannot inspect them fully, but those warnings are irrelevant if the pages are intentionally excluded and have no organic role. The target is not a perfect crawl score or zero excluded URLs. It is a site where important pages can be accessed, understood, prioritized, and used.

    Score impact, scale, risk, and effort without fake precision

    Once the action bucket is clear, score each finding across five factors: SEO impact, business impact, scale, risk, and effort. A simple high, medium, or low assessment is often more defensible than a complicated formula. The score should make the reasoning visible, not disguise judgment as mathematics.

    FactorQuestions that raise priorityQuestions that lower priority
    SEO impactCan this prevent crawling or indexation, send contradictory canonical signals, weaken internal discovery, or impair pages already earning visibility?Is the warning limited to intentionally excluded pages, cosmetic metadata, or behavior with no plausible search mechanism?
    Business impactDoes it affect pages tied to sales, leads, demos, signups, qualified visits, or another defined business outcome?Are the affected URLs unused, obsolete, or disconnected from valuable journeys?
    ScaleDoes one rule or template affect an important page set? Will the number of affected URLs grow automatically?Is it an isolated edge case with no sign of repetition?
    RiskCould waiting cause traffic loss, migration failure, index growth, cannibalization, or a harder future repair?Is the behavior stable, contained, reversible, and unlikely to spread?
    EffortCan a contained template or configuration change solve the root cause with manageable QA?Does the repair require broad platform work, content rewrites, multiple teams, or risky URL changes for little expected benefit?

    Effort should shape sequencing, but it should not erase impact. A difficult crawl or indexation blocker does not become unimportant because it needs engineering time. Likewise, an easy metadata cleanup does not become strategic merely because the team can finish it quickly. Keep quick wins on the roadmap only when their expected benefit exceeds the opportunity cost.

    Translate the result into priority language that product and engineering teams already understand:

    • P0: Business-critical pages cannot be crawled or indexed as intended.
    • P1: A high-impact template, architecture, performance, migration, or duplication issue is limiting visibility, growth, or conversion.
    • P2: The work is useful and justified but not urgent; schedule it behind access blockers and high-value systemic fixes.
    • P3: Monitor the condition, document why it is not being fixed, or batch it with related maintenance.

    Write a one-sentence priority case for every P0 and P1 item: This issue affects [page segment and scope], interferes with [search or user mechanism], puts [business outcome] at risk, and can be corrected through [root-cause change and dependencies]. If you cannot fill in those fields, the task probably needs more investigation or a lower priority.

    Structured data needs the same discipline. Missing or invalid schema on an important template can create machine-readable clarity debt and may justify a fix. But schema cleanup should not outrank a robots block, incorrect noindex, or canonical error that prevents the underlying page from being considered at all. Search and AI visibility begin with accessible, indexable, coherent pages; markup cannot compensate for a broken foundation.

    Turn the audit into root-cause tickets and a sequenced roadmap

    A technician repairs one shared website template hub that feeds many connected page modules, with maintenance stations arranged in sequence beside the network.

    An audit finding is not ready for a sprint merely because it has a URL list. Development teams need a bounded change, an intended outcome, and a way to prove the fix worked. Create one ticket for the root cause and keep the affected URLs as evidence.

    Each implementation-ready ticket should contain:

    • Outcome: What should search engines and users be able to do after the change?
    • Affected segment: Which page group, template, directory, or navigation path is involved?
    • Observed and intended behavior: What happens now, and what should happen instead?
    • Scope evidence: Representative URLs, the known pattern, and whether the count is exact or crawl-dependent.
    • Impact case: The search mechanism, business consequence, scale, and delay risk supporting the priority.
    • Root cause: The template, rule, component, content process, or platform behavior that should change.
    • Acceptance criteria: Testable conditions covering directives, status codes, rendered output, links, canonicals, sitemap inclusion, or structured data as relevant.
    • QA and rollback: Representative test cases, expected side effects, monitoring signals, and a safe way to reverse the change.
    • Ownership and dependencies: The engineering, SEO, content, analytics, or product work required to finish the task.

    Bulk changes to canonicals, robots directives, redirects, internal links, and URL generation can remove valuable pages from search or create new crawl paths. Test template changes on representative URLs, preserve the previous configuration, and define rollback conditions before deployment. A large affected count increases the need for QA; it does not prove the expected benefit.

    Sequence the roadmap by dependency. Restore access to important pages first. Then repair high-value templates and architecture. Address scalable crawl, indexation, performance, and structured data debt after the underlying pages are stable. Batch low-impact cleanup with related platform or content work rather than demanding a separate sprint.

    Do not overlook reporting debt. If Google Search Console and analytics data cannot be mapped to useful page groups, the team cannot reliably distinguish a broad commercial problem from noise on low-value URLs. In that case, segment-level measurement may be the enabling task that makes the rest of the prioritization defensible.

    Every monitor or ignore decision needs a review trigger. Reassess when the affected template changes, the issue spreads into a priority segment, indexation or traffic shifts, a migration is planned, or the site begins generating the URLs at greater scale. This turns the backlog into a controlled risk register instead of a graveyard of unresolved warnings.

    Key takeaways

    • Prioritize technical SEO debt by page segment and business purpose, not by warning count.
    • Fix access blockers and defects on valuable, scalable templates before cosmetic cleanup on low-value URLs.
    • Assign every finding to fix now, fix soon, monitor, or ignore for now; do not leave the decision implicit.
    • Score SEO impact, business impact, scale, future risk, and implementation effort, then write the reason for the assigned priority in plain language.
    • Create root-cause tickets with acceptance criteria, QA, rollback conditions, ownership, and monitoring triggers.
    • Measure success through restored access, visibility, useful journeys, conversions, or reduced scalable risk, not a perfect crawl score.

    Take the highest-volume issue in your current audit and re-evaluate it against one valuable page segment. If you cannot connect it to a search mechanism, business outcome, scalable risk, or enabling dependency, move it down. Then give the recovered capacity to the smallest root-cause change that protects the pages your organic strategy actually depends on.

    References
  • Technical SEO Prioritization: What to Fix First and Why

    Technical SEO Prioritization: What to Fix First and Why

    You have a crawl report full of red warnings, a development queue with little room, and stakeholders asking what any of the proposed work will change. Turning every warning into a ticket will fill the backlog. It will not tell you what deserves to be fixed first.

    Technical SEO prioritization is a constrained investment decision. Very few technical activities deserve top priority on every website. Before requesting developer time, you need to establish that the problem exists on your site, affects something valuable, has a plausible path to a business outcome, and can be measured after the change.

    Key takeaways

    • An audit warning is a signal to investigate, not proof that development work is necessary.
    • Prioritize the obstacle and its consequence: which important pages, users, or search bots are affected, what they cannot do, and what that costs the business.
    • Only score an implementation after you have evidence, a causal mechanism, an affected scope, a success metric, and an estimate of effort and risk.
    • Core Web Vitals work, redirect cleanup, and crawl optimization become priorities when they address demonstrated harm. They are usually weak requests when they only improve an already acceptable score or remove harmless warnings.
    • Every development ticket should state the expected outcome, baseline, acceptance criteria, measurement plan, opportunity cost, and condition under which the work should be stopped or reconsidered.

    An audit finding is not automatically a problem

    An audit tool observes technical conditions. It may find redirected internal links, slow test results, duplicate URLs, crawlable parameters, or other departures from its preferred configuration. That is useful evidence, but the tool does not know which page groups produce revenue, which warnings affect real users, what your search performance depends on, or what your developers would have to postpone to clear the alert.

    This is the distinction that keeps a technical backlog under control: a finding describes what exists; a problem explains why that condition is harmful here. If the only justification is that an audit alert needs to be cleared or a best-practice box needs to be checked, the request is not ready for implementation.

    Turn each material finding into a short diagnostic brief before you prioritize it:

    1. Observed condition: Describe what is happening on production URLs, not just the name of the audit rule.
    2. Affected scope: Identify the page group, template, user journey, or crawl path involved. Separate valuable URLs from incidental ones.
    3. Failure mechanism: Explain what the condition prevents or makes harder. A bot may be unable to reach a destination, a user may struggle to load a page, or unwanted URLs may consume crawling activity.
    4. Likely consequence: Connect the failure to qualified organic traffic, conversion, revenue, churn, usability, or another outcome the business already recognizes.
    5. Baseline evidence: Record the current technical and business measurements. Without a baseline, a successful deployment can still leave you unable to demonstrate success.
    6. Counterevidence: Note what would weaken the case. If important content is already being crawled reliably, for example, a broad crawl-budget project may not solve a current problem.

    The causal sentence should be plain: Because this condition affects this valuable scope, users or bots cannot complete this behavior, which puts this measurable outcome at risk. If you cannot complete that sentence without relying entirely on words such as could or might, do not disguise uncertainty with a high audit severity. Create a smaller validation task and collect the missing evidence first.

    Compare two redirect requests. Internal links return 301 responses merely restates a crawler result. Links on an important template enter a redirect loop, so neither users nor bots can reach the intended destination describes an operational problem. The second statement provides a mechanism, scope, consequence, and testable result. The first does not.

    The same discipline applies to performance. Improve the page-speed score treats the score as the outcome. Bring a failing, revenue-producing page group into the acceptable range and test whether its conversion rate improves distinguishes the diagnostic metric from the business result.

    Use evidence, impact, reach, cost, and risk to rank the work

    An isometric system moves a broken webpage tile through checkpoints represented by a magnifying lens, connected network, tools, and shield before it reaches a workbench.

    Do not begin with a weighted spreadsheet. Scoring weakly defined tickets creates false precision. First pass each request through a decision gate; then use a consistent set of dimensions to compare the requests that remain. This matters because SEO time and developer capacity are both limited, and every accepted ticket displaces another piece of work.

    1. Is the condition real? Confirm it on representative production URLs. If the finding is stale, confined to a test environment, or caused by the crawler configuration, close it before estimating a fix.
    2. Does it affect valuable scope? Segment affected URLs by template, purpose, organic opportunity, and business role. A large count of unimportant URLs should not automatically outrank a smaller set of critical pages.
    3. Is the mechanism credible? State how the condition interferes with crawling, loading, navigation, or another necessary behavior. A correlation without a mechanism deserves investigation, not an expensive rollout.
    4. Can you name the outcome and measure it? Choose a primary business or user metric and a supporting technical metric. If the technical score improves while the meaningful outcome does not, report that distinction.
    5. Is the intervention proportionate? Estimate engineering, quality assurance, content, analytics, and release effort. Include regression risk and the availability of a safe rollback.
    6. What loses if this wins? Compare the request with the work it would displace. Opportunity cost belongs in the priority decision, not in a footnote added after approval.
    DimensionQuestion to answerEvidence that strengthens priority
    ImpactWhat meaningful outcome changes if the fix works?A direct path to revenue, qualified traffic, conversion, retention, usability, or access to important content
    ConfidenceHow certain are you that this condition causes the observed harm?Reproducible behavior, consistent measurements, and a mechanism that fits the evidence
    Reach and valueWhich pages, users, and journeys are affected?A clearly defined page group with material organic or business value
    EffortWhat must be designed, built, tested, deployed, and monitored?A bounded change with known dependencies and realistic acceptance criteria
    RiskWhat can regress, and how will you recover?A contained release, observable guardrails, and a practical rollback
    MeasurabilityHow will you distinguish a successful fix from a successful deployment?A recorded baseline, a technical indicator, a primary outcome, and a defined evaluation condition

    Put every request into one of three queues

    • Commit: The problem is demonstrated, the affected scope matters, the expected outcome is measurable, and the cost and risk are justified. Prepare the implementation ticket.
    • Validate: The suspected harm is plausible, but evidence, scope, or causality is incomplete. Approve a diagnostic task rather than the full fix.
    • Park: The request is based on a warning, cosmetic cleanliness, or incremental improvement with no material expected outcome. Record the reason and a condition that would reactivate it.

    This approach avoids two common distortions. First, URL count is not the same as business reach: one critical landing-page template can matter more than a much larger archive with no meaningful search demand. Second, a sitewide warning is not automatically severe. If users and bots can complete the required behavior and no outcome is being harmed, broad reach merely describes how widely a harmless condition appears.

    You also do not need to force every decision into a numerical score. A critical access failure can outrank other work even when its affected URL count is small. A low-risk housekeeping change can remain parked even when it is easy. Use the dimensions to expose the tradeoff, not to let arithmetic make the decision for you.

    Know when three familiar technical fixes are worth doing

    Almost any technical recommendation can be valuable in the right context. The mistake is treating the recommendation itself as the context. Core Web Vitals, redirects, and crawl-budget work show how the same task can be urgent on one site and unproductive on another.

    Core Web Vitals: fix failure before optimizing success

    Core Web Vitals work has a sensible stopping point. If an important page group is outside the applicable good range, users struggle to load it, or poor performance damages usability, there is a concrete problem to solve. Once those pages are in the good range, however, shaving a few more milliseconds from Largest Contentful Paint is likely to deliver diminishing returns.

    • Commit when valuable pages genuinely miss the target and the loading experience interferes with use of the page.
    • Validate when a test score looks poor but you have not yet established which production pages and users are affected.
    • Park when the page group is already in the good range and the proposed outcome is merely a greener score.
    • Measure the affected performance metric alongside the relevant user or business result. On an ecommerce page group, that may include conversion rate and revenue rather than load time alone.

    This does not make speed unimportant. It keeps the goal honest. A development team should know whether it is repairing a poor experience or pursuing a small technical improvement whose commercial effect is unknown.

    Redirects: treat broken paths as defects, not every 301

    A redirect is not inherently a defect. Its job is to send a request to a different destination. The prioritization question is whether that behavior prevents efficient access to the correct page.

    Redirect work becomes material when you find loops, irrelevant destinations, widespread paths that impair crawling, or chains extending beyond five hops. Those conditions can stop or hinder users and bots before they reach the intended content. A crawl report that merely contains ordinary 301 responses does not establish the same harm.

    • Commit when a loop blocks the destination, a long chain creates a meaningful access problem, or redirects repeatedly send requests to irrelevant pages.
    • Validate when the report contains many redirects but you do not know whether they form harmful chains or affect important crawl paths.
    • Park when links resolve reliably through a single appropriate redirect and no crawling or user problem is evident.
    • Handle opportunistically when you are already editing the relevant CMS content and can update an internal link to its final destination at negligible additional cost.

    The opportunistic edit and the priority project are different decisions. It is reasonable to remove avoidable hops while touching a page. It is harder to justify displacing higher-impact work solely to make a crawl report free of redirect notices.

    Crawl budget: require evidence that crawling is constrained

    Crawl optimization depends heavily on scale and site behavior. Large enterprise sites are more likely to need crawl-path work, while crawl budget is usually not a material issue for smaller sites. Site size alone is not the diagnosis, though. The useful evidence is whether bots are spending time in spider traps or unwanted URL spaces while important content is difficult to reach.

    • Commit when spider traps create uncontrolled crawling, unwanted pages consume substantial attention, or important content is not reliably crawlable.
    • Validate when the concern is based on site size or URL count but Google Search Console and your crawl evidence have not yet shown an access problem.
    • Park when important content is already crawlable and no unwanted crawl pattern is interfering with it.
    • Reactivate the work if a new template, parameter space, or navigation pattern creates a trap or makes valuable sections harder for bots to reach.

    Do not ask developers to optimize an abstract budget. Name the wasteful path, the valuable path it competes with, the evidence of interference, and the measurement that will show the intervention worked.

    Turn the winning priority into a measurable development ticket

    A developer repairs a selected broken component and restores an illuminated path through a modular website model.

    A technically correct request can still lose the sprint-planning conversation if it does not explain its value. Developers need enough detail to estimate and test the change. Decision-makers need to understand why the work is financially or operationally preferable to everything it would displace.

    A decision-ready ticket should contain the following:

    1. Problem statement: Describe the observed production behavior and why it is harmful. Do not paste the audit recommendation in place of a diagnosis.
    2. Affected scope: Name the templates, page groups, journeys, and audiences involved. Include unaffected scope when that boundary helps contain the implementation.
    3. Evidence: Attach reproducible examples and the relevant crawl, Google Search Console, performance, analytics, or business measurements.
    4. Expected outcome: State what should improve for users, search bots, or the business. Revenue, qualified traffic, conversion, and churn are stronger outcomes than clearing an alert.
    5. Proposed intervention: Define the intended behavior while leaving room for engineering to choose a safe implementation where appropriate.
    6. Acceptance criteria: Specify what must be true on the affected URLs after release. Include technical checks and any guardrail that must not regress.
    7. Measurement plan: Record the baseline, primary outcome, supporting technical metric, comparison method, and the condition under which you will evaluate the result.
    8. Effort, dependencies, and risk: Identify other teams, release constraints, quality-assurance needs, possible regressions, and rollback requirements.
    9. Opportunity cost: Name the competing work likely to be delayed. This forces an explicit choice instead of treating developer capacity as free.
    10. Reactivation or stop condition: State what new evidence would revive a parked request, invalidate the proposed fix, or end further optimization.

    Model the business case without turning a scenario into a promise

    Page speed illustrates the difference between a metric and a case for investment. Reducing load time is an implementation objective. The business case may be that a faster ecommerce experience could improve conversion on the affected page group. To test that case, record its current organic traffic, conversion rate, and annual revenue, then model what a plausible change in conversion would mean while making the assumptions visible.

    Keep a scenario labeled as a scenario. It is not a forecast merely because it appears in a spreadsheet. The ticket should separate what you know now, what you expect the intervention to change, and what you will measure afterward. That prevents a successful technical release from being reported as proven commercial growth before the business metric has moved.

    The same separation works for non-revenue outcomes. A crawl fix can be technically successful because important destinations become reachable, while qualified traffic remains unchanged. A redirect repair can remove a loop without affecting conversion. Record both results. The technical result tells you whether the implementation worked; the business result tells you whether the original prioritization hypothesis was valuable.

    Close the loop after release

    • Confirm that the acceptance criteria hold on the intended production scope, not only on a test URL.
    • Check guardrails for regressions before attributing any broader benefit to the change.
    • Compare the supporting technical metric with its baseline.
    • Evaluate the primary user or business outcome separately and preserve uncertainty where other changes could have contributed.
    • Record whether the hypothesis was supported, contradicted, or remains unresolved. Use that result to improve confidence estimates for similar backlog items.
    • Stop incremental work when the original harm is resolved and the next proposed improvement lacks a measurable expected return.

    Now open your technical backlog and take its highest-ranked request. Rewrite it in one sentence: We should make this change because this evidence shows that the current condition affects this valuable scope, interferes with this necessary behavior, and puts this outcome at risk; success will be measured this way. If you cannot fill every part with evidence, move the request to validation or park it with a reactivation trigger. That decision is useful technical SEO work too.

    References
  • What Google’s Indexing API Really Tells Job Boards

    What Google’s Indexing API Really Tells Job Boards

    Job listings have a timing problem: they can change or expire before ordinary crawling catches up. Google’s Indexing API appears to solve that problem by accepting notifications when eligible pages are created, updated, or removed.

    The important limitation is that an accepted request confirms delivery of a notification, not the outcome a job board ultimately needs. Understanding that distinction helps teams measure the API accurately and avoid treating clean server responses as proof of search visibility.

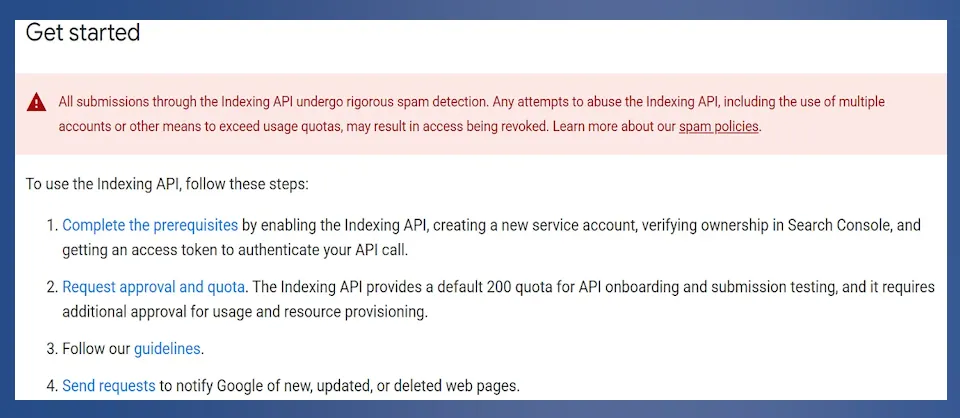
    Indexing API "Get started" page with a spam warning and four setup steps.
    A "Get started" panel warns that submissions undergo spam detection, then lists prerequisites, approval and quota requests, guidelines, and request submission.

    A notification is only the first event in the chain

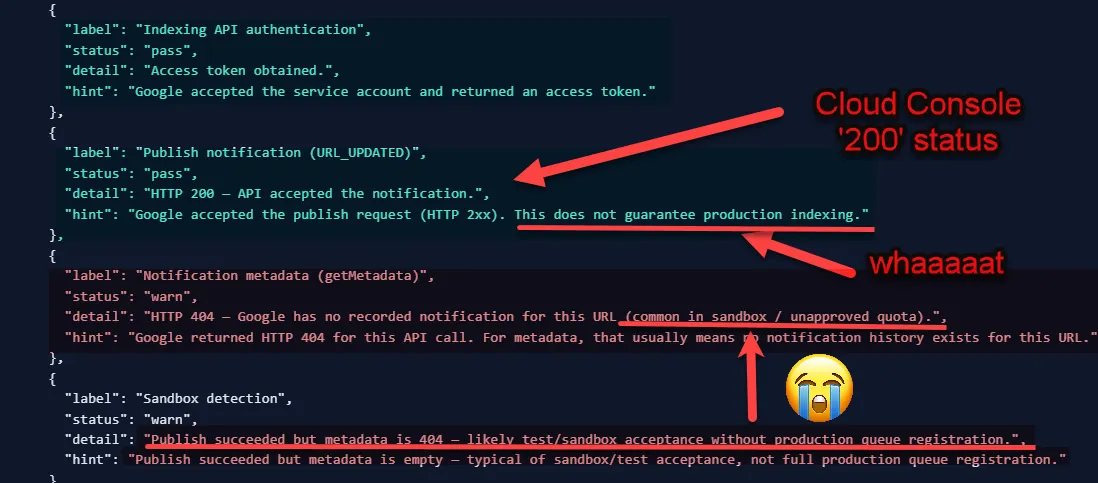
    According to Search Engine Land, a successful API request means Google received the submission. It does not establish that Google crawled the page, added it to the index, displayed it in the Google Jobs experience, or generated traffic from it.

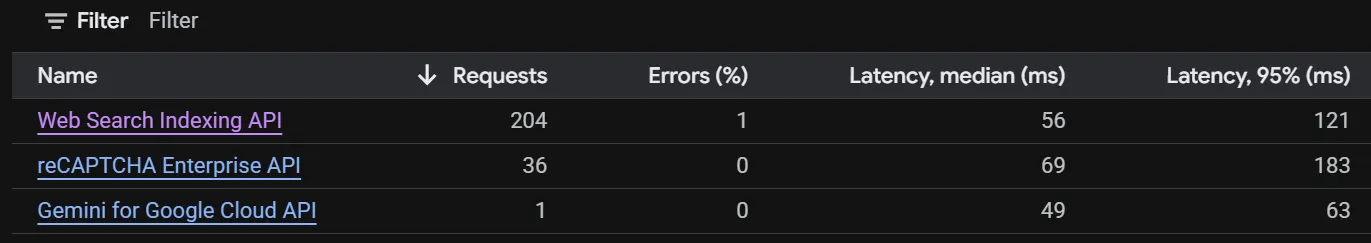
    Dark API metrics table showing requests, error rates, and median and 95th-percentile latency for three services.
    A filtered metrics table lists 204 Web Search Indexing API requests, 36 reCAPTCHA Enterprise API requests, and one Gemini for Google Cloud API request.

    Those are separate stages with separate evidence requirements:

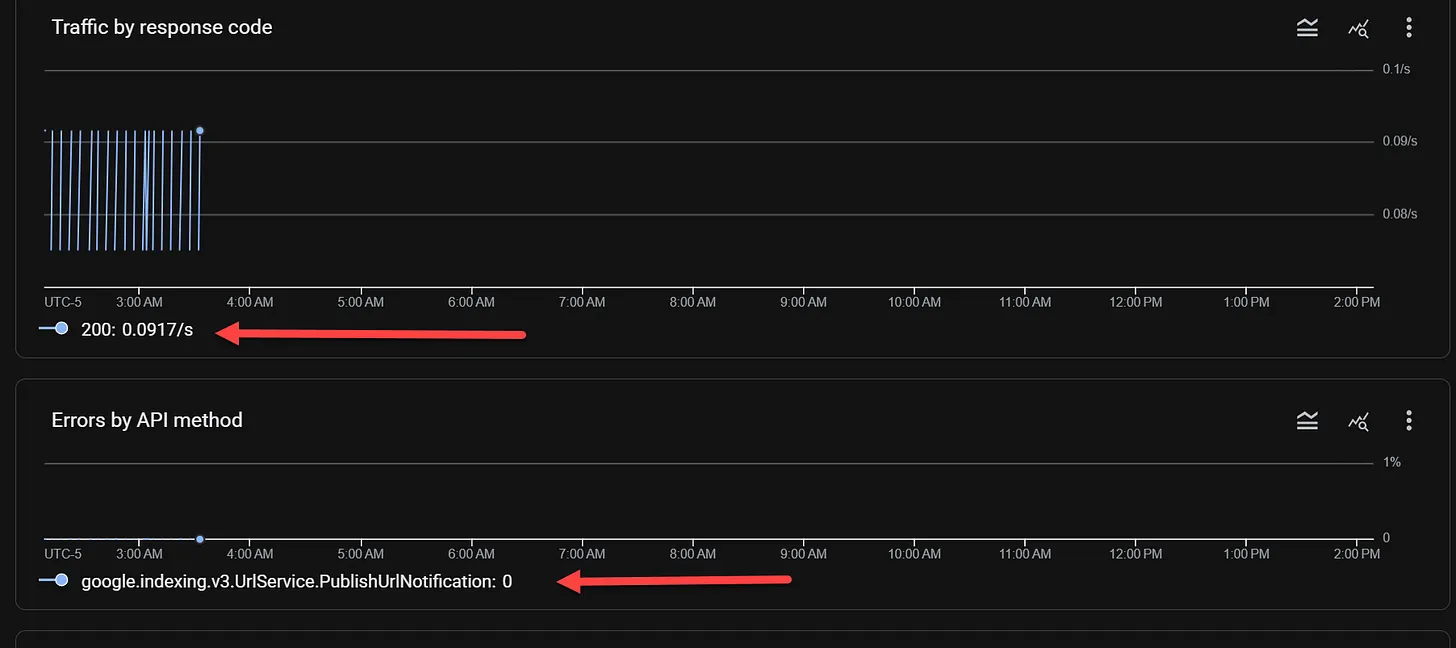
    Dark dashboard charts show HTTP 200 traffic at 0.0917/s and zero API errors, with red arrows pointing to the legends.
    Two dark monitoring charts display intermittent HTTP 200 traffic near 3:00 AM and zero errors for the listed PublishUrlNotification API method.
    • Submitted: The site’s system sent a notification.
    • Accepted: Google returned a successful response to that request.
    • Crawled: Google fetched the page.
    • Indexed: Google made the page eligible to appear in search.
    • Visible and productive: The listing earned impressions, clicks, or conversions.

    A reliable reporting setup should preserve these distinctions. Otherwise, an operational metric such as API acceptance can be mistaken for an SEO result.

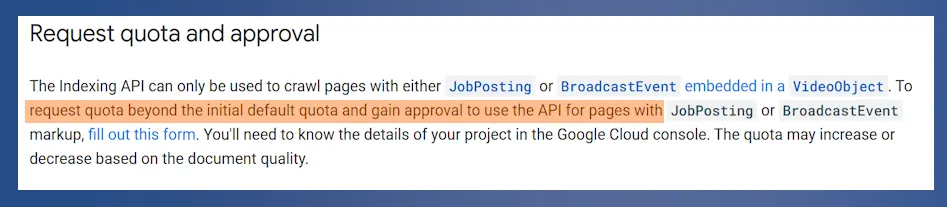
    Documentation excerpt titled "Request quota and approval" with a quota request sentence highlighted in orange.
    A documentation excerpt says the Indexing API is limited to JobPosting or BroadcastEvent pages and directs users to submit a form for more quota and approval.

    Key takeaways

    • The Indexing API is restricted to eligible job-posting and livestream pages; it is not a general acceleration tool for arbitrary URLs.
    • An HTTP 200 response confirms receipt, not crawling, indexing, removal, ranking, or traffic.
    • Notification metadata describes submissions rather than the current index status of a page.
    • Quota availability and successful test requests do not necessarily prove that an account has production access.
    • Job boards should validate structured data, API behavior, and search status as separate layers.

    The API has a narrow, defined scope

    Search Engine Land reports that Google permits the API for pages carrying JobPosting structured data and for livestream pages using BroadcastEvent within a VideoObject. Blog posts, product pages, category archives, service pages, and other ordinary URLs are outside that stated use.

    Annotated API results show HTTP 200 publish success, a 404 metadata warning, red arrows, and a crying emoji.
    A dark code-style report contrasts a passed URL_UPDATED request and HTTP 200 response with a getMetadata HTTP 404 warning, highlighted by red arrows, "whaaaaaat," and a crying emoji.

    For an eligible job page, the two relevant notification types are straightforward. URL_UPDATED can be sent when a listing is published or meaningfully changed. URL_DELETED can be sent when the listing has been removed and should no longer remain indexed.

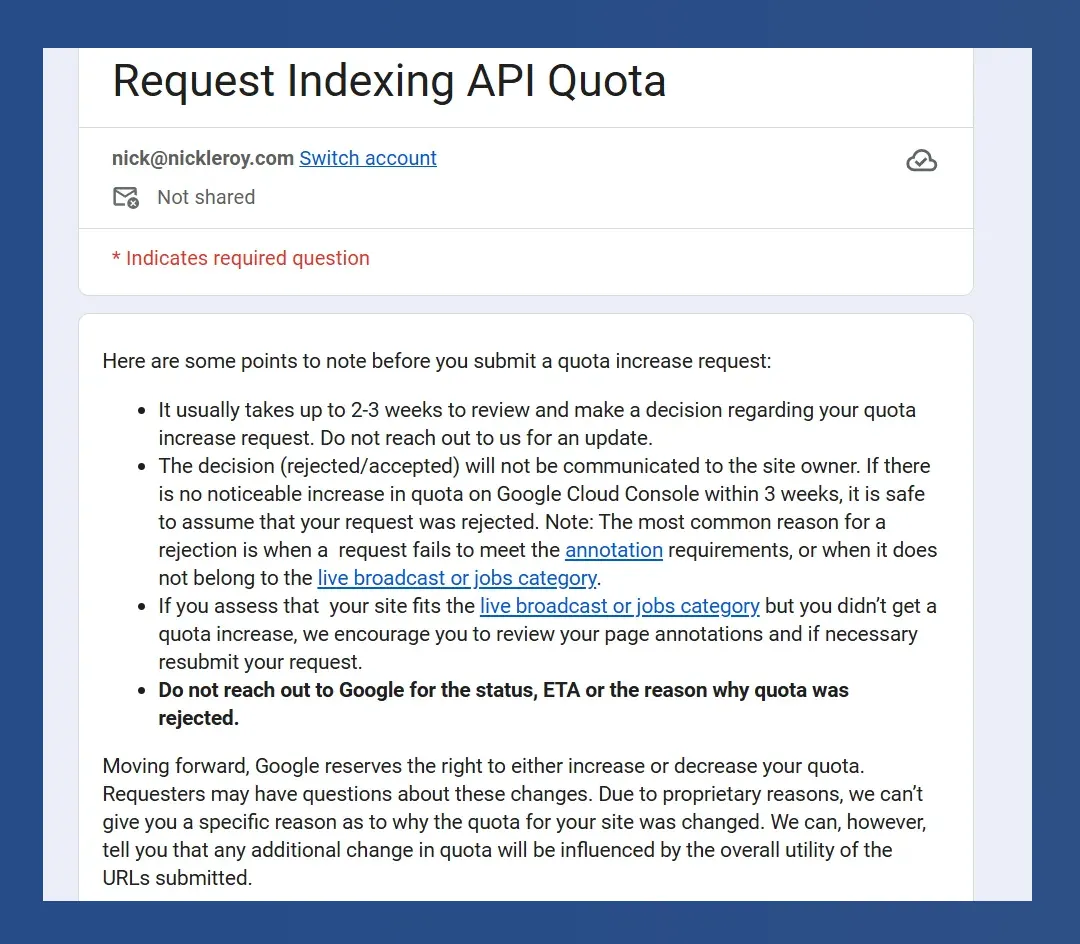
    Request Indexing API Quota form with notes on review times, eligibility, rejections, and quota changes.
    A Request Indexing API Quota form says reviews usually take two to three weeks and warns that annotation and eligible-content requirements must be met.

    Even here, the request is not a command. The source notes that Google’s documentation says the company may recrawl a URL after an accepted update request and may remove one after an accepted deletion request. That wording preserves Google’s control over what happens next.

    Job indexing health check with passing results, two warnings, and a raw JSON response.
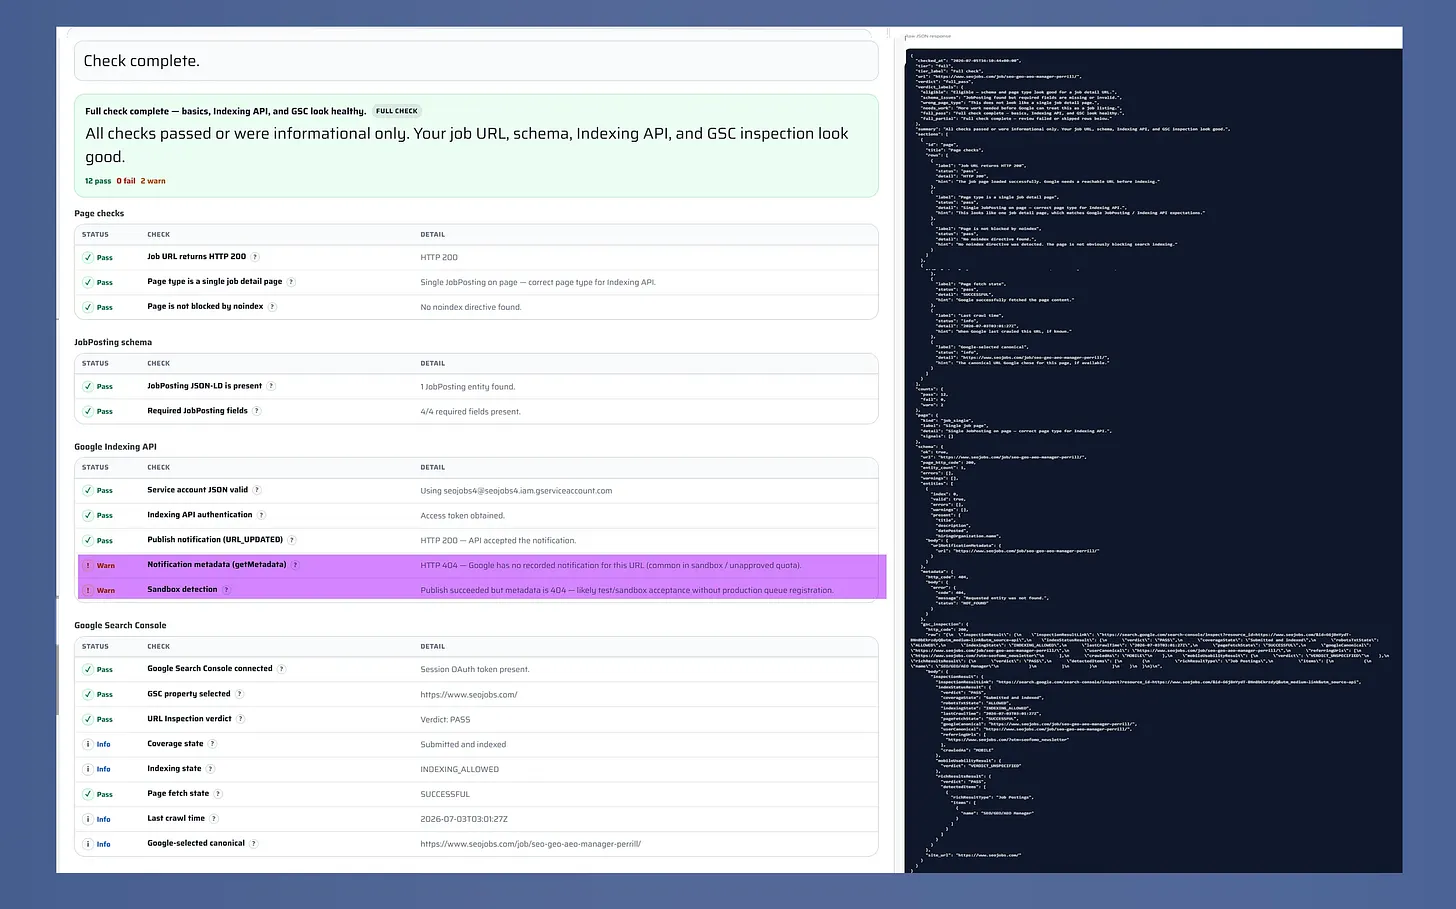
    A completed job indexing health check shows 12 passes, no failures, and two warnings beside a dark panel containing the full raw JSON response.

    Metadata, sandbox access, and quotas require careful reading

    The API’s getMetadata capability can help confirm the history of update and deletion notifications for a URL. It cannot answer the larger question of whether that URL is currently crawled, indexed, removed, or receiving exposure. Metadata is therefore useful for diagnosing the submission pipeline, but it is not an index-status report.

    ```json
{
  "alt": "SEO For Lunch newsletter promotion with Nick Leroy smiling in checkered shirt.",
  "caption": "Join Nick Leroy for a fresh take on SEO with the #SEOForLunch newsletter—bringing actionable insights straight to your inbox.",
  "description": "This image promotes the #SEOForLunch newsletter by Nick Leroy, featuring a smiling Nick in a checkered shirt against a blue graphic background. The design includes a plate graphic with 'Not Your Average Table Talk' and emphasizes SEO insights, inviting viewers to subscribe at seoforlunch.com. Keywords: SEO, Nick Leroy, newsletter, marketing, insights."
}
```

    Access also has an onboarding dimension. Search Engine Land says Google’s quickstart documentation describes a default quota of 200 requests for onboarding and submission testing, with further approval required for usage and resource provisioning. A visible quota or apparently successful test can therefore create confidence without demonstrating full production service.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    The source also reports approval delays, but the evidence should be treated as observational rather than definitive. The article’s author said two job-board requests had received no response after six months in 2026. Alexander Chukovski reportedly said none of the job boards he worked with over roughly 10 to 12 months received a response. These accounts suggest that approvals may have become harder to obtain, but they do not prove that Google has stopped processing every request.

    How job boards can validate the system responsibly

    A practical audit should test the implementation in layers rather than seeking one all-purpose success signal:

    1. Confirm that the URL represents a supported job posting and contains the required structured data.
    2. Verify that update and deletion requests use the appropriate notification type.
    3. Record response codes and notification metadata as evidence of API delivery only.
    4. Check crawling, indexing, and search performance through appropriate search diagnostics instead of inferring them from the API response.
    5. Track expired listings separately so removal can be verified rather than assumed.

    The source highlights a free Job Indexing Health Check on SEOJobs.com that can review job schema and, in its fuller mode, API and Google Search Console responses. Whether teams use that tool or their own diagnostics, the sound approach is the same: measure each stage according to what its evidence can actually prove.

    For job boards, the API can remain a useful notification channel. Its value becomes clearer, not weaker, once acceptance is treated as the beginning of verification rather than the finish line.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Agent Website Accessibility: A Practical Framework

    AI Agent Website Accessibility: A Practical Framework

    AI agent website accessibility is the ability of an automated assistant to discover a page, retrieve its contents, identify the relevant facts, and cite the business as the source. A site can work well for a human visitor yet fail this sequence when important information is hidden, dynamically rendered, ambiguous, or difficult to fetch.

    The practical goal is not to redesign every page for bots. It is to ensure that decision-critical facts survive the agent’s path from search to answer, especially when a prospective buyer asks about pricing, features, integrations, security, or compliance.

    Agent accessibility is a chain, not a page feature

    An agent typically starts with a task rather than a preferred website. It searches for relevant pages, fetches their contents, extracts an answer, and identifies sources it can cite. Failure at any stage can remove the vendor from the resulting answer even if the information appears somewhere on its site.

    This makes agent accessibility broader than visual presentation. A polished pricing grid offers little machine value if its values appear only after client-side code runs. A detailed PDF may contain the answer but make individual plan terms difficult to isolate. A contact-sales page may be accessible and accurate, but it cannot support a numeric answer that the company has chosen not to publish.

    This operational definition should not be confused with, or used as a replacement for, accessibility for people with disabilities. Human accessibility and agent accessibility address different users and failure modes, even though clear structure and understandable content can benefit both.

    Pricing exposes weaknesses that other product facts do not

    A geometric AI assistant faces layered website panels where pricing symbols are visible on one panel but obscured behind a modal and fragmented elements on others.

    A CrushPress.AI analysis conducted with Siteline founder David Kaufman examined three buyer tasks across 100 B2B products. The agent had to find each official vendor site without being given a starting URL, and each task was run five times to account for variable model behavior.

    Buyer taskFirst-party answer rateFirst-party citation share
    Pricing and features79%84%
    Integrations93%99%
    Security and compliance92%99%

    According to the analysis, pricing and feature research generated 77% of all third-party citations in the study. The contrast matters because pricing is both commercially sensitive and central to comparison. Integrations and security information can often be stated as straightforward facts; pricing may depend on plans, billing periods, usage, optional services, negotiated terms, or eligibility rules.

    Non-disclosure was only part of the problem. When a vendor did not publish a real price, 45% of pricing runs cited at least one third-party source. When a numeric public price was present, third-party sources still appeared in 18% of runs. Publishing information therefore improves the opportunity for first-party attribution, but does not guarantee that an agent can extract or trust it.

    Three failure gates determine whether the vendor remains the source

    Disclosure: is there a direct answer?

    The first gate is whether the company states the requested fact. If a price is unavailable, the page can still give an authoritative first-party answer by clearly saying that pricing is customized or requires sales contact. Vague packaging language creates a larger information gap, which third parties may fill without the vendor controlling the context.

    Extraction: can the fact be separated from the interface?

    The second gate is machine-readability. The source identified JavaScript interfaces, calculators, toggles, screenshots, PDFs, and ambiguous tables as potential obstacles. Its Zendesk example described a pricing grid that loaded for people but left the agent without usable plan data, leading to a 53-second process involving six tool calls before the agent turned to third-party blogs.

    The underlying editorial requirement is precision. A price needs an associated plan, unit, billing period, qualification rule, and any material condition. If those relationships are conveyed mainly through layout or interactive state, an agent may retrieve the values without understanding what they mean.

    Reachability: can the page be fetched consistently?

    The third gate is access. Fetch failures, blocking, rate limits, or unreachable pages appeared in 7% of all runs reported by CrushPress.AI, but their effect was disproportionate. Within pricing runs, an access error was associated with third-party fallback in 77% of cases, compared with 17% when no access error occurred.

    The study also compared high- and low-friction runs at the 90th and 10th percentiles. It reported a 4.4-fold cost difference, a 4.7-fold token difference, and a twofold time difference. Those costs are borne by the agent operator rather than the website, but they indicate how quickly retrieval friction can make an alternative source more attractive.

    A practical audit should follow the agent’s full journey

    A luminous AI agent travels through search, web document, fact extraction, and source-link stations along a pathway with three gateways and one blocked side route.

    Start with buyer questions, not page templates

    An audit can begin with the questions a buyer would delegate: What does the product cost? What is included? Which systems does it integrate with? Which security or compliance claims does the vendor make? Testing should begin from external discovery rather than a supplied page URL, mirroring the study’s method and revealing whether the intended first-party page can be found at all.

    Separate essential facts from interactive presentation

    Core plan and product facts should appear as clear page text that a fetcher can retrieve, even when the human experience also uses toggles or calculators. Labels should make relationships explicit: which plan a value belongs to, what the billing basis is, and which conditions change the amount. Complex pricing can remain complex, but its methodology should be explained in a form that can be quoted and cited without reconstructing the interface.

    Evaluate the answer and the citation separately

    A successful audit asks two different questions: did the agent produce an accurate answer, and did it support that answer with the vendor’s page? An answer sourced from a directory or editorial site may appear satisfactory while still showing that the vendor has lost control of attribution. In the reported pricing fallbacks, editorial pages accounted for 52.2% of fallback citations, directories for 45.7%, and ecosystem pages for 2.1%.

    Repeated testing is important because one successful retrieval does not establish reliable access. Results should be checked across multiple attempts, with special attention to blocked fetches, empty dynamic components, inconsistent plan labels, and facts that change when an interface control is activated.

    Key takeaways

    • Agent accessibility depends on discovery, retrieval, extraction, interpretation, and citation; a failure at any gate can push the answer to another source.
    • Pricing is a demanding test because disclosure choices and technical presentation can both prevent first-party attribution.
    • Publishing a number is insufficient when its plan, billing basis, conditions, or surrounding methodology remain ambiguous.
    • Access errors were uncommon in the reported study but sharply increased third-party fallback when they occurred.
    • Audits should test realistic buyer questions from search, repeat the attempts, and score answer accuracy separately from first-party citation.

    As agents assume more research and comparison work, the most resilient sites will treat machine access as part of publishing quality. The priority is a first-party record that remains understandable and citable after the interface itself is removed.

    References
  • Google Canonicalization Fixes: Why Results May Take Two Weeks

    Google Canonicalization Fixes: Why Results May Take Two Weeks

    A corrected canonicalization problem may not disappear from Google Search immediately. According to the supplied report, Google’s updated troubleshooting guidance says affected pages can remain in a duplicate cluster for up to two weeks after the underlying content issue has been fixed.

    That distinction matters when evaluating a repair. The visible search result can lag behind the site change, so an unchanged canonical selection during this window is not, by itself, evidence that the fix failed.

    What the two-week window does and does not mean

    The source reports that Google added the timing clarification near the beginning of its canonicalization troubleshooting guide. The stated period is an allowance of up to two weeks, not a promise that every case will take that long or resolve at the end of a fixed countdown.

    It is therefore best understood as an observation window. Once Google has processed the relevant update, teams may need to allow the full period before treating the continued clustering of a page as a persistent problem. Making another change too quickly can blur the result of the original repair and make diagnosis harder.

    Page similarity is central to duplicate clustering

    Several structurally similar web-page cards grouped inside a translucent cluster, with a different page outside it.

    The reported guidance also explains an important condition behind canonicalization: pages must be sufficiently similar for Google’s systems to place them in the same duplicate cluster. Google then selects one version from that group as the canonical page.

    This connects the timeline to the substance of the fix. If two URLs still present substantially similar material, changing a preference signal alone may not immediately alter how the system groups them. By contrast, the source says clearer differences in the content can help prompt faster reevaluation.
    That does not make content differentiation a universal remedy. Some URLs are intentionally duplicate or near-duplicate versions and should remain consolidated. The useful question is whether the observed cluster reflects the site’s intended relationship between the pages.

    A monitoring sequence that preserves diagnostic clarity

    A repaired web-page card, an hourglass, and a magnifying glass arranged as a three-stage monitoring sequence.

    The two-week guidance supports a more disciplined way to assess canonicalization work:

    1. Confirm that the underlying content issue has actually been corrected and that the intended relationship between the URLs is unambiguous.
    2. Record when the corrected version became available for Google to process.
    3. Observe the affected URLs during the reported window without repeatedly changing the same pages.
    4. If the unwanted clustering persists after sufficient time has passed, reassess whether the pages remain similar enough to justify Google’s selection.
    5. Separate a delayed response from a genuinely incorrect outcome before planning another intervention.

    This sequence avoids treating every day of unchanged results as a new failure. It also preserves a cleaner connection between a particular change and the eventual search outcome.

    Key takeaways

    • The supplied report says canonicalization fixes can take up to two weeks to appear in Google Search.
    • A page may remain in an existing duplicate cluster while Google reevaluates the corrected content.
    • Clustering depends on pages being sufficiently similar, so the actual relationship between their content remains important.
    • A continued canonical selection inside the reported window is not conclusive proof that a repair failed.
    • Teams can reduce unnecessary rework by documenting the change, allowing time for processing, and reevaluating only after the observation window.

    Going forward, canonicalization reviews should pair technical correctness with patient measurement: make the intended page relationship clear, preserve a stable test period, and judge the result only after Google has had time to reconsider the cluster.

    References
  • Hydration and SEO: What I Watch Before Rankings Slip

    Hydration and SEO: What I Watch Before Rankings Slip

    When I work on a site built with a framework like Next.js, Nuxt, SvelteKit, or a similar JavaScript framework, I pay close attention to hydration. It is the step that turns server-rendered HTML into an interactive page, but it is often explained in a way that does not connect clearly to SEO.

    I think hydration is easier to understand when I separate content from behavior. The content may already be visible, but the page may not be fully usable until the browser finishes connecting that content to the JavaScript behind it.

    What I mean by hydration

    Hydration is the process where JavaScript in the browser takes over the static HTML that was built on the server. The server sends a complete page first, and then the framework attaches the logic that makes buttons, menus, forms, filters, and other interactive pieces actually work.

    Here is how I usually explain the sequence. First, the server builds the page and sends fully formed HTML to the browser. I can see the content quickly, but the page is not interactive yet. Then the framework loads, walks through the existing HTML, attaches event listeners, and reconnects the visible markup to the application logic. Once that is done, the page behaves like a normal interactive app.

    This is why server-rendered HTML can feel fast at first. It can paint quickly and often helps with first impressions and Largest Contentful Paint (LCP). The tradeoff is that, with traditional hydration, the page may appear ready before it is actually usable.

    Hydration adds interactivity, not content

    The most important distinction I keep in mind is this: hydration does not add the main content to the page. The text, images, and layout should already be present in the server-rendered HTML. Hydration only adds behavior by wiring that HTML to the JavaScript that responds to clicks, typing, taps, and other user actions.

    Timeline diagram showing server-rendered HTML becomes visible before hydration, while buttons remain inactive until hydration completes.
    A hydration timeline shows the gap between content appearing and a page becoming usable: HTML is visible first, but buttons only work after hydration completes.

    Put simply, before hydration I can read the page. After hydration, I can use it.

    I also avoid confusing hydration with the rendering pattern itself. Server-side rendering (SSR), static site generation (SSG), and client-side rendering (CSR) describe where and when the page is built. Hydration describes what happens after server-rendered or statically generated HTML reaches the browser and needs to become interactive.

    From an SEO perspective, that distinction matters. When a page uses SSR or SSG correctly, the core content is already in the initial HTML. Google can discover and index that content from the HTML before depending on a JavaScript render step, which is generally more reliable than sending a mostly empty client-rendered shell.

    When I see hydration become an SEO problem

    Most of the time, I do not treat hydration itself as an SEO problem. It becomes a problem when hydration breaks, usually because the HTML created on the server does not match what the framework expects to create in the browser.

    That kind of mismatch can happen when content depends on browser-only APIs such as localStorage, when a value changes between server and client rendering such as new Date(), when a third-party script or browser extension changes the DOM before hydration finishes, or when invalid HTML causes the browser to rewrite the structure before the framework can attach to it.

    Diagram comparing web page before and after hydration, showing JavaScript hydration adds behavior to make a subscribe button interactive.
    Before hydration, a server-rendered page can be read but not used; after hydration, JavaScript adds behavior so elements like the Subscribe button respond.

    When the two versions do not line up, the framework may throw away the mismatched section and re-render it in the browser. The exact behavior depends on the framework, but the SEO and performance risks are similar.

    For example, if a <time> value is generated with new Date(), the server may output one value while the browser generates another. That mismatch can force a re-render, even though the page appeared to load correctly at first.

    I worry about this because it can hurt the page in several ways. A re-render can make the page feel sluggish, which can affect Interaction to Next Paint (INP). It can shift the layout, which can affect Cumulative Layout Shift (CLS). It can also break user actions if event listeners fail to attach properly, leaving buttons, menus, or forms unresponsive.

    In severe cases, Google may read the raw server HTML before JavaScript finishes rendering and then index content that visitors never actually see after the page re-renders. That is the scenario I want to avoid most: search engines and users experiencing different versions of the same page.

    The fix is usually not an SEO trick. It is a development fix. I want the underlying mismatch removed by using valid HTML, avoiding browser-only logic during server rendering, stabilizing values that change between server and client, and controlling third-party scripts that alter the DOM too early.

    Diagram showing a hydration mismatch where server HTML time differs from browser render, causing re-render, layout shift and SEO indexing issues.
    When server HTML and browser-rendered content disagree, hydration may discard and rebuild the page, creating layout shifts, broken UI and potential SEO indexing problems.

    How I spot hydration problems on a live site

    Hydration errors are usually easier to catch in development than on a live site, but I still look for a few practical signals. I start with the browser’s Developer Tools console and check for hydration warnings, JavaScript errors, or framework-specific mismatch messages.

    Then I watch the page load carefully. If content flickers, shifts, disappears, reappears, or stays unresponsive for longer than expected, I treat that as a sign worth investigating.

    I also use Google Search Console’s URL Inspection tool on important templates to see how Google renders the page. For larger sites, I prefer crawling with JavaScript rendering enabled in tools like Screaming Frog or Sitebulb so I can compare rendered output against raw HTML at scale.

    How I think about different hydration approaches

    Modern frameworks handle hydration in different ways, and I think of those differences as a balance between performance, interactivity, and how much JavaScript must run in the browser.
    Full hydration means the entire page hydrates in one pass. It is straightforward, but it usually ships the most JavaScript and asks the browser to do the most main-thread work. Next.js Pages Router is a common example of this model.

    Neon Google search bar with microphone icon over a futuristic digital data background, representing search technology and SEO updates.
    A glowing Google search bar cuts through streams of digital data, capturing the fast-moving world of search, shopping visibility, and SEO innovation.

    Partial hydration hydrates only the interactive pieces, often called islands. Static sections remain plain HTML and do not need client-side JavaScript. Astro’s islands architecture is a well-known example of this approach.

    Progressive hydration hydrates the page in pieces over time. A framework may hydrate sections as they scroll into view or as browser resources become available. Angular’s incremental hydration follows this general pattern.
    React Server Components take a different path by letting some components render entirely on the server and ship no client-side JavaScript for those server-only parts. In those cases, there is nothing for the browser to hydrate for that portion of the page. Next.js App Router uses this model.

    Resumability goes further by trying to skip hydration entirely. Instead of re-running components on load, the page resumes from the state the server already produced. Qwik is the main example here, although I still view it as newer and less battle-tested than some of the older patterns.

    When I compare these techniques, I look at what hydrates, how much JavaScript ships, and how much work the browser must do. Full hydration touches the entire page and usually ships the most JavaScript. Partial hydration touches only interactive components and ships less. Progressive hydration spreads the work over time. React Server Components reduce hydration for server-only parts. Resumability aims to avoid hydration altogether.

    What this means for my SEO work

    I do not assume hydration is bad for SEO. In most cases, it is simply part of how modern server-rendered and statically generated sites become interactive.

    What I do watch closely is whether the server HTML and the browser-rendered version agree. If they do, hydration is usually a performance and user experience consideration. If they do not, hydration can become a visibility problem, especially when Google indexes a version of the page that users never see.

    Newer frameworks reduce some of this risk by shipping less JavaScript and doing less work in the browser, but they do not remove the need for careful implementation. For me, the practical takeaway is simple: make sure the important content is present in the initial HTML, keep server and client output consistent, and test how search engines actually render the page.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How Sale Dates and Product Categories Work in Merchant Markup

    How Sale Dates and Product Categories Work in Merchant Markup

    Google’s merchant listing structured data guidance now covers two pieces of product information that often live outside the page markup: when a sale price applies and how a product is categorized. Together, the additions give merchants a clearer way to keep product pages, structured data, and Merchant Center submissions conceptually aligned.

    The practical value is not simply having more properties to publish. It is being able to represent promotional timing and product classification consistently, without treating structured data as an isolated SEO layer.

    Key takeaways

    • Google’s updated guidance explains how validFrom, validThrough, and priceValidUntil can describe the effective period of a sale price.
    • The timing properties may be placed on Offer or PriceSpecification nodes, according to the supplied CrushPress.AI report.
    • Product.category can use merchant-defined text or CategoryCode values associated with a formal category system.
    • The additions align structured data more closely with Merchant Center’s sale_price_effective_date, product_type, and google_product_category attributes.
    • Consistent values across the product page, structured data, and feed should be the implementation priority; the new markup does not by itself guarantee greater search visibility.

    Two updates address one product-data problem

    The supplied CrushPress.AI report presents sale duration and product category as additions to the same merchant listing documentation. Although they describe different aspects of a product, both address a common operational problem: important commerce data can become inconsistent when it is maintained separately in a storefront, structured data, and a Merchant Center feed.

    The sale guidance connects schema.org properties with Merchant Center’s sale_price_effective_date attribute. The category guidance similarly connects Product.category with the product_type and google_product_category feed attributes. This does not make those fields interchangeable in every system. It does, however, give implementation teams a clearer correspondence between the concepts expressed in each channel.

    That correspondence matters because promotional data is time-sensitive, while category data is usually taxonomy-sensitive. A pricing error may expose an expired or premature offer; a category mismatch may give systems conflicting descriptions of what the product is. The documentation changes provide a more explicit model for managing both risks.

    Sale markup should follow the promotion’s actual lifecycle

    A product moves through three calendar-like stages, with a discount tag attached only during the illuminated middle stage.

    According to the report, Google’s new sale-duration section discusses validFrom, validThrough, and priceValidUntil as ways to define when a sale price is effective. It also includes guidance and examples for assigning the properties to either an Offer or a PriceSpecification node.

    The choice of node should reflect how the site’s product model owns pricing information. If an Offer contains the active commercial terms, the timing data may belong with that offer. If prices are represented through a dedicated PriceSpecification, keeping the dates with that specification can make the relationship between the amount and its validity period clearer. The important point is to use a coherent model rather than distributing related values arbitrarily.

    Implementation should begin with the source of truth for the promotion. The structured data’s start and end values should be generated from the same approved schedule that controls the visible sale price and, where applicable, the Merchant Center submission. Automated removal or replacement after the promotion ends is just as important as publishing the future dates correctly.

    Teams should also distinguish a scheduled sale from a routine price update. The reported guidance concerns the effective period of sale pricing; it should not be used to manufacture a promotional window when the page does not genuinely present a time-bound offer.

    Product categories can preserve two useful vocabularies

    One product connects to two separate branching arrangements of blank category tiles and folders.

    The same report says Google’s documentation now supports Product.category using both Text and CategoryCode types. This mirrors two different classification needs represented in Merchant Center: product_type can express a merchant’s own taxonomy, while google_product_category represents Google’s classification.

    A custom text category can preserve the language used in navigation, merchandising, reporting, or inventory management. A category code can identify the product within an external classification system. These are complementary signals: one communicates the merchant’s view of the catalog, and the other connects the item to a standardized vocabulary.

    The source reports that Google’s examples allow custom text labels and Google Product Category codes in structured data. The implementation lesson is to retain the meaning of each value. A merchant label should not be presented as though it were an official code, and a code should remain associated with the category system it comes from.

    Category markup should also be generated from maintained catalog data rather than copied manually into individual templates. Central ownership reduces the chance that a product is reclassified in the feed or storefront while stale structured data remains on the page.

    A practical implementation and validation sequence

    1. Identify the systems that control visible prices, promotion schedules, merchant feeds, and catalog categories.
    2. Map sale start and end data to validFrom, validThrough, or priceValidUntil in the Offer or PriceSpecification model used by the site.
    3. Map the internal merchant taxonomy and any Google category assignment to the appropriate Text or CategoryCode representation for Product.category.
    4. Generate the markup from the same governed data used by the storefront and feed instead of maintaining a separate manual copy.
    5. Check products before a sale begins, while it is active, and after it ends to confirm that visible content and machine-readable values change together.
    6. Include category and promotional fields in routine structured-data audits so catalog migrations and template changes do not silently create conflicts.

    Validation should cover meaning as well as syntax. Markup can be technically parseable while still containing an expired sale window, an incorrect category, or a value that disagrees with the page. The more useful test is whether every representation describes the same product and offer at the same moment.

    As merchant markup moves closer to feed-level expressiveness, the durable advantage will come from shared product-data governance. Merchants that connect templates to reliable pricing and taxonomy sources will be better positioned to adopt these fields without creating another layer of catalog maintenance.

    References