Your AI advertising dashboard can be numerically correct and still lead you to the wrong decision. This happens when it collapses four different things into one performance label: what delivered, what the platform optimized for, what it attributed, and what its budget tools are allowed to use.
You need a reporting system that keeps those layers visible. The framework below will help you turn campaign data into defensible actions without letting an AI-generated summary hide attribution limits, product eligibility problems, or gaps between web and app measurement.
Key takeaways
- Show the selected optimization goal beside every supporting conversion. A reported outcome is not necessarily an outcome the campaign pursued.
- Label each conversion separately as reportable, used for optimization, and eligible for budgeting. Those are three different permissions.
- Treat attribution as a rule for assigning credit, not proof that an ad caused the outcome.
- Put product rejections, review pauses, identity changes, and measurement changes on the campaign timeline so operational interruptions are not mistaken for performance failures.
- Let AI explain a governed dataset. Keep metric definitions, joins, formulas, and eligibility rules deterministic and reviewable.
Build every report around one decision
A dashboard built to answer every possible question usually answers none of them clearly. The person deciding whether to scale a campaign needs a different view from the person diagnosing a rejected product or reconciling app purchases. Start with the decision, then select the data required to make it.
A useful report header should identify:
- Decision: Scale, hold, reduce, diagnose, or repair.
- Scope: Account, campaign, ad group, product, channel, market, and customer surface.
- Primary outcome: The conversion event selected as the optimization goal.
- Supporting outcomes: Other attributed events that help you judge lead quality, downstream value, or progression through the journey.
- Comparison: The period, segment, or campaign being used as the reference point.
- Measurement context: Attribution model, attribution window, currency, time zone, data freshness, and known coverage gaps.
- Next action: The proposed change, its owner, and the condition that would reverse or confirm it.
Do not force every conversion into a single blended total. A campaign optimized for one event can now expose other attributed events through the public ChatGPT Ads Insights API. That additional visibility is useful, but it does not change the campaign’s selected goal.
Keep the primary outcome and supporting outcomes in separate columns. If the optimization goal improves while a downstream purchase metric weakens, you have a quality question to investigate. If purchases improve while the optimization goal is unchanged, you have a useful signal, but not automatic proof that the campaign caused the improvement.
Separate delivery, eligibility, outcomes, and attribution
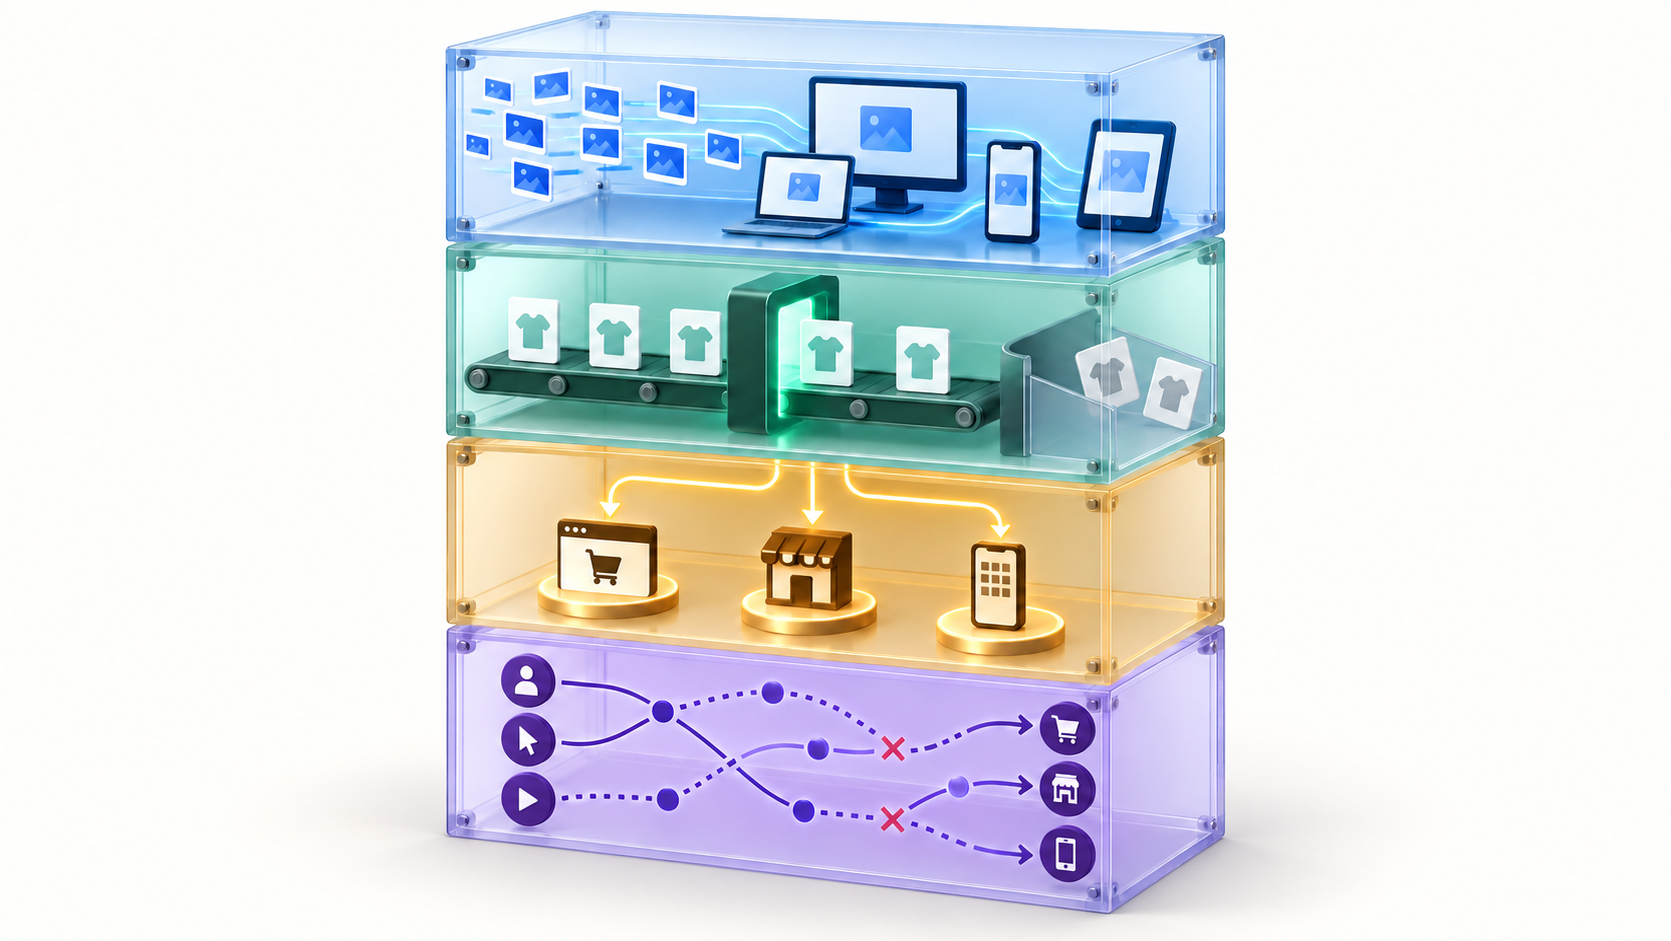
A trustworthy report lets you locate the stage at which performance changed. Use distinct reporting layers instead of dropping every metric into one scorecard.
| Reporting layer | Question it answers | What to include | Decision it supports |
|---|---|---|---|
| Delivery | Did the campaign reach and engage its available audience? | Platform delivery metrics at the campaign, ad group, and product levels | Investigate distribution, targeting, serving, or creative exposure |
| Cost | What did that delivery consume? | Spend and consistently calculated efficiency metrics | Check financial guardrails and locate changes in cost |
| Product eligibility | Could each advertised product serve? | Feed item, review state, rejection reason, and status-change time | Repair catalog or policy issues before judging demand |
| Outcomes | Which conversion events received credit? | Optimization goal and supporting attributed events, kept separate | Evaluate the chosen objective and inspect downstream quality |
| Attribution and governance | Under which rules and account conditions were results recorded? | Model, window, surface, naming changes, review pauses, and measurement changes | Compare compatible data and explain discontinuities |
ChatGPT Ads reporting can supply delivery, cost, product, and attributed conversion metrics. Preserve those metric families as separate datasets or clearly identified groups in your reporting model. That makes it possible to tell the difference between a serving problem, a cost problem, a catalog problem, and a conversion problem.
Product campaigns need an eligibility layer because a rejected item did not receive the same opportunity as an approved item. ChatGPT Ads now exposes product review status and individual rejection reasons. Bring those fields into the report before calculating product-level winners and losers. Otherwise, you may penalize an item for not converting when the actual issue was that it could not serve.
Operational changes also belong on the timeline. ChatGPT Ads separates the internal account name, public brand name, and registered legal name. A public brand-name change can pause serving during review, while a legal-name change can restart business review and may also interrupt delivery. Record those identity and review events as annotations. A delivery gap during a review is an operational interruption, not evidence that the audience rejected the campaign.
Treat reporting, optimization, and budgeting as separate controls
Every conversion in your measurement plan needs three explicit flags:
- Reportable: Can the event appear in performance or attribution reporting?
- Optimization-enabled: Is the campaign actively trying to generate this event?
- Budget-eligible: Can an automated or cross-channel budgeting system use this event when allocating money?
Never infer the second or third flag from the first. The ChatGPT Ads Insights API can return attributed events beyond the selected optimization goal. Google can include app conversions in performance reporting, attribution analysis, and attribution models while its cross-channel budgeting features remain limited to web conversions. In both cases, visibility is broader than at least one action layer.
Use supporting conversions without changing the meaning of success
Supporting conversions can reveal what happens after the event selected for optimization. They are especially useful when the selected event represents an earlier step in the customer journey. Keep them in the report, but preserve their role.
For each event, store its business definition, customer surface, reporting status, optimization status, budgeting status, and attribution configuration. If one of those fields is unknown, label it unknown. Do not allow the reporting layer or an AI assistant to silently convert an unknown into a yes.
Keep a visible boundary between web and app measurement
Google’s expanded conversion reporting can bring app activity into broader performance and attribution views. Advertisers can also configure attribution for app conversions independently from other conversion types. However, availability may still vary by Google Analytics property, and app outcomes are not yet included in cross-channel budgeting.
This can make a report look unified even when the underlying controls are not. Add a surface field to every conversion row and display web and app subtotals before showing a combined figure. Also record the attribution setting applied to each surface. A combined total is decision-safe only when you can explain what was counted, how credit was assigned, and whether the downstream tool can act on all of it.
An AI-generated recommendation should never say that a budget allocator will react to app conversions merely because those conversions appear in the same report. It can recommend a manual review of the evidence, but it must preserve the platform’s actual budgeting boundary.
Build a reporting pipeline that AI can audit
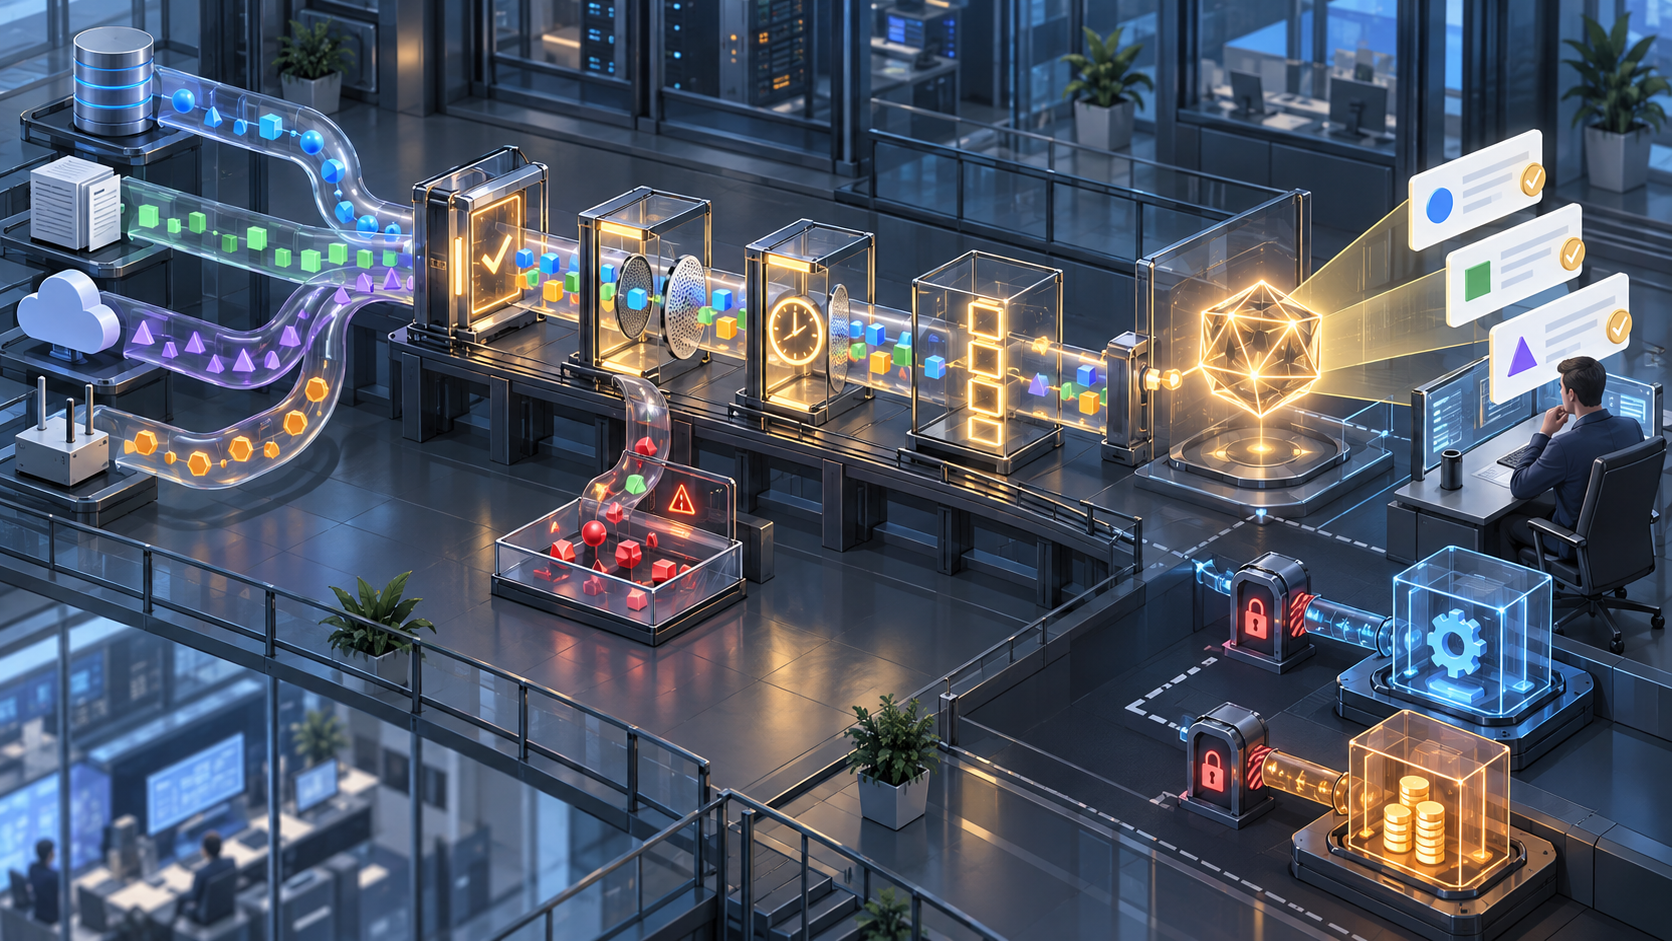
Automation makes governance more important, not less. Spreadsheet uploads can create multiple ChatGPT product campaigns and ad groups while generating ad templates automatically. Set naming rules and persistent identifiers before a bulk launch so the resulting scale does not produce an untraceable reporting structure.
- Create a conversion registry. Give every event a stable identifier, business meaning, customer surface, owner, reportable flag, optimization flag, budget-eligibility flag, and attribution configuration.
- Define a campaign taxonomy. Standardize the fields used for market, product group, objective, funnel stage, audience, and experiment. Keep platform IDs even when human-readable names change.
- Extract raw data without rewriting its meaning. Preserve native platform fields, IDs, statuses, and timestamps before creating normalized views.
- Normalize context explicitly. Apply consistent date boundaries, time zones, currencies, and metric formulas. Retain the raw values so transformations can be audited.
- Join operational status data. Add product review states, rejection reasons, account reviews, serving pauses, feed changes, and measurement-setting changes to the campaign timeline.
- Reconcile before interpreting. Compare API totals with the platform interface using the same dates, filters, attribution settings, time zone, and account scope. Investigate differences rather than hiding them in a blended total.
- Calculate metrics deterministically. Use documented formulas for rates, costs, and rollups. Do not ask a language model to perform the authoritative aggregation from loosely formatted exports.
- Generate the narrative last. Give AI the reconciled table, metric definitions, change log, and decision question. Require every recommendation to point back to visible evidence.
Give the AI a narrow reporting contract
A useful reporting assistant should distinguish observation from interpretation. Its instructions should require it to use only supplied data, preserve platform definitions, identify missing fields, avoid causal claims from attributed conversions, and state when a proposed action depends on an unverified setting.
Require each generated finding to contain:
- Observation: The measured change, including its scope and comparison.
- Evidence: The exact metrics, dimensions, statuses, and time period supporting the observation.
- Interpretation: A plausible explanation clearly labeled as an inference.
- Measurement limits: Attribution, availability, eligibility, or data-quality constraints that could change the reading.
- Action: A reversible next step tied to the original decision.
- Validation condition: What must be checked before the recommendation is implemented or expanded.
This structure prevents polished prose from outrunning the evidence. Attribution tells you how a model assigned credit; it does not establish causal lift. When causality matters, the report should identify the need for an appropriate experiment rather than dressing an attribution result up as proof.
Run these checks before automating recommendations
- API and interface totals reconcile under identical filters and settings.
- Every conversion has separate reporting, optimization, and budgeting flags.
- Web and app events retain their surface and attribution configuration.
- Rejected, pending, and approved products are distinguishable.
- Serving pauses and account, brand, feed, goal, or attribution changes are annotated.
- Missing and unavailable values remain distinct from zero.
- Every generated recommendation cites the rows and definitions it relies on.
- A person with budget authority reviews consequential changes before they are applied.
Start with one active campaign and complete the conversion registry before rebuilding the dashboard. Put the business meaning, surface, reporting status, optimization status, budget eligibility, and attribution setup beside every outcome. If you cannot complete those fields, the campaign is not ready for automated interpretation. Fix that boundary first; the reporting interface can follow.
References
- Search Engine Land — OpenAI expands ChatGPT Ads with bulk product campaigns and deeper reporting
- Search Engine Land — Google expands cross-channel conversion reporting to app campaigns

Leave a Reply