Category: Advertising

  • YouTube Masthead Access for Online Gambling Advertisers

    YouTube Masthead Access for Online Gambling Advertisers

    Your gambling licence alone does not unlock YouTube’s most prominent advertising placement. Starting October 21, 2026, Google will extend YouTube Masthead eligibility to more certified online gambling advertisers, but access will still depend on the product, jurisdiction, registration rules, certification scope, and campaign controls.

    If you’re planning a Masthead campaign, qualify the exact product-market combination before you commit the budget or build the creative. The policy change creates an opportunity, not an automatic approval.

    The change opens one premium placement, not the whole platform

    YouTube’s Masthead requirements already permit sports betting advertising. The October change expands eligibility to additional forms of online gambling advertising, provided the advertiser holds the relevant Google Ads certification and satisfies the applicable legal restrictions.

    That distinction matters. Masthead eligibility, Google Ads certification, and campaign approval are related, but they aren’t interchangeable:

    • Eligibility means your type of gambling business may be considered for the placement.
    • Certification means Google has approved you to advertise the relevant gambling category in the jurisdictions covered by that certification.
    • Campaign approval means the specific account, targeting, creative, destination, and other campaign elements satisfy Google’s applicable policies.

    Passing one stage does not guarantee the next. A certified advertiser can still submit a campaign that falls outside its approved geography, reaches an impermissible age group, or conflicts with another Google advertising policy.

    Use this four-gate test before treating your brand as eligible
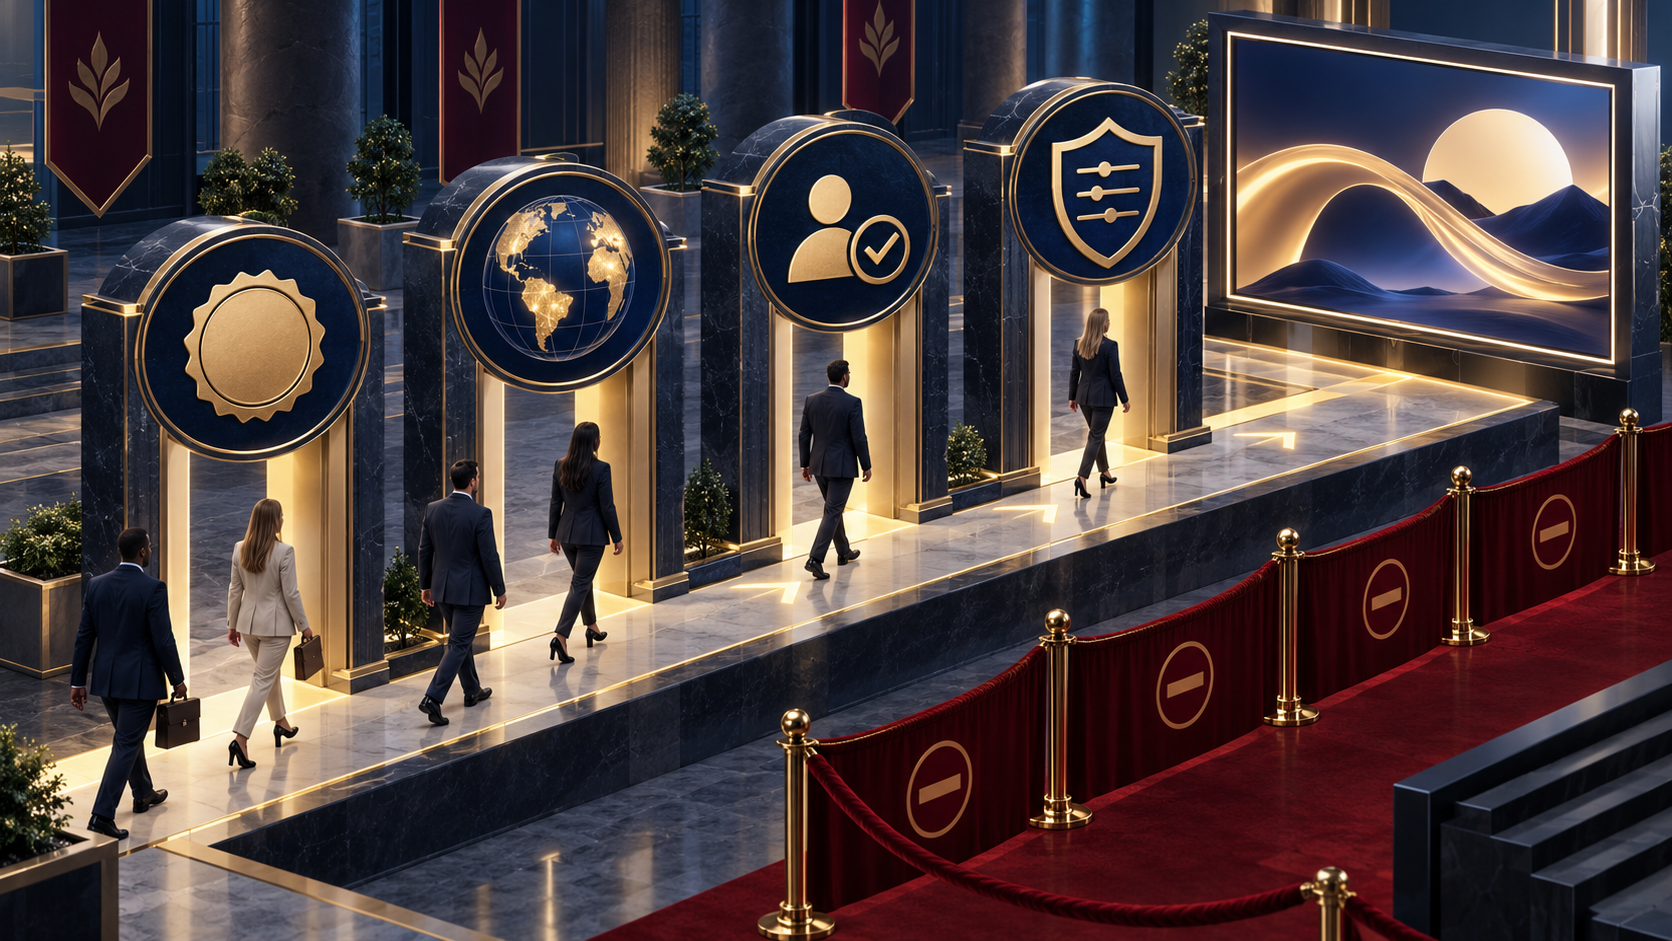
    An advertiser passes through four gates symbolizing licensing, jurisdiction, registration, and campaign controls on the way to a premium video screen.

    Run each proposed product and target market through four gates. If any answer is unknown, treat the campaign as pending rather than eligible.

    1. Does mandatory state or national registration apply? The exception is easy to misread: online gambling advertisers not subject to mandatory state or national gambling registration remain excluded from the expanded eligibility. Operating in a category without a registration requirement is not a shortcut into the Masthead.
    2. Are you legally permitted to offer the product in the target jurisdiction? Confirm the relevant registration and licensing position for the product and location. If the answer depends on an interpretation of local law, use qualified legal counsel rather than inferring eligibility from a competitor’s campaign.
    3. Do you hold the matching Google Ads certification? Certification is not a universal gambling credential. Approval depends on the gambling category, local rules, licensing requirements, and jurisdictions you intend to target.
    4. Can the campaign enforce every geographic and age restriction? The campaign must stay inside the approved markets and comply with all applicable age limits. A broad audience setup can invalidate an otherwise eligible plan.

    The third gate deserves particular attention. A government licence or registration addresses your legal status. Google Ads certification addresses your permission to advertise through Google’s systems. Keep both records in your campaign approval file; neither should be treated as a substitute for the other.

    Map eligibility by product and jurisdiction
    A compliance team reviews connections between different gambling products and selected regions on an unlabeled tabletop map.

    Don’t label the entire company “approved” because one product is certified in one market. Build a simple eligibility matrix with one row for every product-jurisdiction combination you want to advertise.

    • Product or gambling category
    • Target country, state, or other applicable jurisdiction
    • Whether mandatory gambling registration applies
    • Registration and licensing status
    • Google Ads certification status and scope
    • Required geographic exclusions
    • Applicable age restrictions
    • Overall status: eligible, pending, or blocked

    This matrix prevents a common planning error: allowing a valid approval in one market to become an assumption about another. It also gives media, legal, compliance, and creative teams the same definition of what can launch.

    Be strict about the status labels. “Pending” should mean that a required decision, certification, or legal confirmation is still outstanding. It should not be converted to “eligible” because the campaign deadline is approaching. “Blocked” should identify the failing gate so the team knows whether the constraint is the product, jurisdiction, registration rule, certification, or targeting requirement.

    Sequence the campaign so compliance is not the final dependency

    The expensive mistake is to complete the media plan and creative first, then discover that the certification doesn’t cover the proposed product or market. Use this order instead:

    1. Define the exact gambling product being promoted.
    2. List every jurisdiction the campaign would reach.
    3. Confirm whether mandatory registration applies in each product-market combination.
    4. Verify the relevant registration, licensing, and legal permissions.
    5. Obtain or confirm Google Ads certification for the applicable category and jurisdictions.
    6. Configure geographic targeting, geographic exclusions, and age controls around the narrowest permitted scope.
    7. Review the creative, destination, account, and campaign against Google’s broader advertising policies.
    8. Commit the Masthead budget and launch date only after the required approvals are confirmed.

    For the initial rollout, narrow scope is easier to govern. A campaign covering one confirmed product-market combination has fewer ways to drift beyond its permissions than a launch that combines several products and jurisdictions. Expansion can follow as additional rows in the eligibility matrix become confirmed.

    October 21 is an eligibility start date, not a guaranteed campaign launch date. Account review, certification, legal clearance, and campaign approval still determine whether your specific campaign can run. Keep an alternative media plan until those dependencies are settled, particularly when the Masthead date is tied to a fixed promotion.

    Key questions about YouTube gambling ad access

    Can every online gambling operator buy a YouTube Masthead from October 21?

    No. The expansion applies to eligible, certified advertisers that satisfy the relevant legal, registration, licensing, geographic, and age requirements. It is not blanket permission for online gambling advertising.

    Does a gambling licence replace Google Ads certification?

    No. A licence or registration establishes a legal status under the applicable jurisdiction. Google Ads certification is a separate platform requirement for advertising the covered gambling category and market.

    Does one Google certification cover every jurisdiction?

    You should not assume that it does. Certification requirements depend on the category, jurisdiction, local regulation, and applicable licensing rules. Verify the scope against every market in the campaign.

    Are sports betting advertisers newly eligible?

    No. YouTube’s existing Masthead policy already permits sports betting advertising. The change extends potential access to more certified online gambling advertisers.

    Your next move is concrete: write down the exact product and jurisdiction you want to promote, then clear all four gates before briefing the campaign. If registration, licensing, certification, geography, or age controls remain unresolved, the Masthead plan is not ready for budget approval.

    References


  • AdMob Black-Screen Outage: What App Publishers Should Do

    AdMob Black-Screen Outage: What App Publishers Should Do

    When people report that your app “freezes” immediately after a video ad, you need to answer two questions quickly: is your own release broken, and can you stop more users from entering the same dead end?

    The documented AdMob failure can replace an interstitial video with a solid black screen and leave its close button unresponsive. It affects iOS and Android, and the only reported escape for the user is to force-close the app. Here is how to confirm the pattern, contain it, measure the damage, and restore the placement without making a rushed code change.

    Know the boundary of the AdMob failure

    The confirmed failure is narrow enough to guide your response but serious enough to justify immediate action. An interstitial video fails to render, the user sees a black screen, and the close control does not work. Reports cover both iOS and Android applications.

    AdMob itself may remain accessible while publishers encounter error messages, high latency, or other unexpected behavior. At the reported stage of the incident, Google was investigating, had announced no estimated resolution time, and offered no workaround for the failed interstitial.

    That boundary matters. The known issue concerns interstitial video ads; it does not establish that every AdMob format or every placement is failing. Do not disable unrelated inventory merely because it uses the same ad platform. Equally, do not dismiss the incident as an iOS view-controller problem or an Android rendering regression when the same symptom is appearing across both operating systems.

    There is also an important distinction between a vendor workaround and publisher containment. Google may have no way for you to repair the ad after it becomes a black screen. You may still be able to prevent your app from requesting or presenting the affected placement through remote configuration, a feature flag, or an emergency release.

    Confirm the pattern before changing your SDK or app code

    Four test phones show matching black full-screen ad failures while a separate control phone displays a normal app interface.

    A black screen is a symptom, not a diagnosis. Treat the AdMob incident as a strong lead, then collect enough evidence to distinguish it from your own navigation, lifecycle, or rendering bug.

    1. Identify the exact trigger. Record the screen, user action, and interstitial placement immediately preceding the black screen. “The app went black” is not enough to isolate an ad failure.
    2. Capture the environment. Preserve the app version, build number, operating system, device model, timestamp with time zone, and network condition. Ask support teams to collect the same fields from new reports.
    3. Inspect the session sequence. Determine whether the app process remains active behind a full-screen ad surface, whether the close control appears, and whether tapping it produces any response.
    4. Review your ad events. Look for the request, load, presentation, dismissal, and failure events your integration already records. Event names vary by SDK and implementation, so use your own instrumentation rather than assuming a callback was fired.
    5. Test the path without the placement. If the next screen works when the interstitial is suppressed in a controlled environment, the evidence points toward the ad boundary rather than the destination screen.
    6. Check both mobile platforms. Matching behavior on iOS and Android strengthens the case for a shared service or creative-delivery problem. A report from only one platform does not rule out the AdMob incident, but it does justify checking platform-specific code.

    Use your existing test environment and approved ad-testing setup when reproducing the flow. An unsuccessful reproduction does not prove that production is healthy: ad delivery varies, and the affected video may not appear in every request.

    Avoid upgrading, downgrading, or replacing the mobile ads SDK solely because the visible symptom resembles an integration bug. Those changes introduce a second variable and may not affect a service-side outage. First establish whether the failure aligns with the known interstitial pattern and whether suppressing that placement restores the user journey.

    Contain the user trap at the placement level

    A smartphone app journey routes around a black ad screen that has been isolated behind a protective barrier.

    Your immediate goal is not to recover every missed impression. It is to stop a full-screen dependency from making the rest of the app unreachable.

    • Use a remote kill switch if one exists. Stop invoking the affected interstitial placement without disabling ad formats that are still working.
    • Fail open at the gate. If the interstitial sits between a completed action and the next app screen, let the user continue without the ad while the placement is suppressed.
    • Do not create an automatic retry loop. Repeatedly requesting another interstitial at the same transition can send the user back into the broken experience.
    • Remove the placement from relaunch-sensitive paths. A person who force-closes the app should not immediately encounter the same interstitial after reopening it.
    • Consider an emergency release when server-side control is unavailable. Keep the change narrow: bypass the affected placement rather than combining the response with an SDK migration or unrelated feature work.
    • Reassess paid acquisition into an unavoidable broken path. If a high-traffic onboarding or conversion flow cannot bypass the interstitial, continuing to drive users into it may waste campaign spend and amplify abandonment.

    Suppression has an obvious monetization cost, but leaving the placement active can cost the entire session. The outage can affect ad engagement and publisher revenue while also increasing user frustration and app abandonment. Make that tradeoff explicitly rather than allowing a revenue-protection default to decide it for you.

    Give support teams a precise response they can use: “A video ad may display a black screen with a close button that does not respond. Close the app completely and reopen it. We are temporarily limiting the affected ad placement while the provider investigates.”

    Do not promise that reopening permanently fixes the issue; force-closing only gives the user a way out of the current screen. Do not publish a resolution time that Google has not supplied. If you cannot suppress the placement, tell users where it occurs so they can make an informed choice about using that path.

    Measure the blocked journey, then restore cautiously

    Look beyond crash-free sessions

    A trapped interstitial may not look like a conventional application crash in your monitoring. The user can leave by force-closing the app, so a healthy crash-free metric is not proof that the experience is healthy.

    Build the incident view around the user journey: ad presentation, expected dismissal, arrival at the next screen, session termination, and subsequent reopen. Compare the affected period with your normal baseline, segmented at least by placement, operating system, and app version. Use your established timing baseline rather than inventing a new universal timeout during the incident.

    • Count interstitial presentations that are not followed by the expected dismissal or next-screen event.
    • Track exits and rapid reopens after an interstitial presentation.
    • Review support tickets and app-store feedback for black-screen, frozen-ad, and unresponsive-close descriptions.
    • Watch requests, impressions, engagement, and revenue by the affected placement; the outage may alter each metric differently.
    • Preserve a timeline of configuration changes, releases, reports, and observed recovery so that later analysis can separate the outage from your mitigation.

    Be careful with interpretation. A lower impression count after you suppress a placement is expected. A decline before suppression may reflect failed rendering or disrupted sessions, but the available incident information does not establish exactly how every AdMob reporting metric records the failure.

    Require evidence before full restoration

    Do not re-enable the placement merely because complaints slow down. Confirm that Google has marked the incident resolved, then validate the affected journey on both iOS and Android. Check that the video renders, the close control responds, the dismissal event arrives, and the user reaches the intended next screen.

    If your controls allow it, restore the placement to a limited share of traffic first. Watch the same presentation-to-dismissal and next-screen signals used during triage. Expand only when those signals return to their ordinary baseline. If limited restoration reproduces the black screen, disable the placement again and preserve the new session evidence.

    Key takeaways

    • The known AdMob failure turns an interstitial video into a black screen with an unresponsive close button on iOS and Android.
    • Force-closing the app is the only reported way for a user to escape the affected screen; it is not a permanent fix.
    • At the reported stage, Google was investigating and had provided neither a workaround nor an estimated resolution time.
    • Confirm the placement-level pattern before changing your SDK, then suppress only the affected interstitial where your controls permit.
    • Measure dismissal and journey completion rather than relying on crash metrics alone.
    • Restore the placement only after a confirmed resolution and successful validation on both mobile platforms.

    Once the incident is behind you, add one durable control: every full-screen third-party placement should have a remotely operated off switch. The next provider failure should require a configuration change, not an emergency app release, before you can give users their app back.

    References

  • AI Media-Buying Guardrails: A Practical Control Framework

    AI Media-Buying Guardrails: A Practical Control Framework

    If your AI buying agent can raise bids, move budget, or scale a traffic source, an overspend is not the only failure you need to prevent. The agent can remain inside its budget and still fund low-quality traffic, follow a compromised redirect, or optimize against context that stopped being true weeks ago.

    The safe design is a chain of evidence: trusted inputs, current security signals, explicit permissions, a reversible action, and a decision record. Build that chain before granting autonomy and you can use AI for speed without letting a superficially attractive metric become an instruction to make an expensive mistake.

    A budget limit cannot tell the agent what to trust

    A spend ceiling answers one question: how much money may move. It does not answer whether the evidence behind that move is complete, current, or safe.

    Suppose the agent is instructed to lower cost per acquisition while remaining under a campaign cap. It finds a traffic source with cheap reported conversions and reallocates spend toward it. From the performance dashboard, that can look correct. Upstream, however, traffic-quality anomalies, changed landing-page behavior, or a questionable redirect may be telling a different story. A budget rule does nothing to reconcile those signals.

    This is the central control problem in agentic media buying: the system will normally optimize the objective and evidence you expose to it. If safety evidence lives in a separate dashboard, arrives after optimization, or has no authority to block an action, it is not a guardrail. It is an after-the-fact report.

    Ad buyers already recognize that autonomy needs more than a campaign cap. In IAB’s July 2026 Digital Video report, 40% of buyers wanted humans in the loop, 36% wanted an explainable audit trail, and 31% wanted explicit limits on agent actions. Those controls are useful, but they need to operate together. A tightly limited agent can still repeat a bad decision if its context is stale or its risk signals are missing.

    Before automation, require the workflow to answer four questions in order:

    1. Are the required inputs present, current, and structurally valid?
    2. Do traffic-quality or security signals require a hold or stop?
    3. Does performance evidence justify the proposed change?
    4. Is that exact change inside the agent’s permission envelope?

    If any answer is unknown, the default should be no scale. Unknown is not the same state as safe.

    Key takeaways

    • Make security and traffic quality hard inputs to optimization, not reports reviewed after spend has moved.
    • Give every input an owner, freshness rule, version, and position in the conflict hierarchy.
    • Separate permission to recommend an action from permission to execute it.
    • Send humans ambiguous, novel, or high-impact cases instead of routing every routine bid adjustment through manual approval.
    • Snapshot the context behind every material decision so you can reconstruct what the agent knew and what it was allowed to do.
    • Revalidate the workflow whenever a tool, landing page, data schema, policy, template, or business rule changes.

    Turn the prompt into a context contract

    Four validated input channels converge on a glowing AI core while a cracked stale input is diverted into a separate quarantine chamber.

    A prompt is only one part of an AI workflow’s operating context. The model may also read project knowledge, memory, skill instructions, attached files, tool results, earlier stages, and prior conversation turns. Some of that material can load without the operator selecting it for the current decision. Managing that full operating context is therefore a control function, not a prompt-writing exercise.

    Write a context contract for each decision-making workflow. It should specify:

    • Objective: Name the metric, reporting window, conversion definition, and business outcome. Do not leave the agent to choose among several plausible definitions of efficiency.
    • Trusted inputs: List the approved performance, traffic-quality, security, destination, inventory, and policy feeds. Assign an owner and version to each one.
    • Freshness: Define when each input becomes too old to authorize action. A stale security result must not be treated as a current clearance.
    • Precedence: State which system wins when two tools disagree. If two platforms calculate a metric differently, the agent should not switch between them from one run to the next.
    • Required fields: Declare the identifiers, timestamps, measurement periods, risk states, and data-quality flags that must be present. Reject incomplete payloads instead of asking the model to fill the gaps.
    • Permission envelope: Separate read, recommend, pause, bid, budget, source, creative, and destination permissions. Scope them by account, campaign, channel, and action type.
    • Stop conditions: Identify alerts that block action regardless of performance. Include the safe fallback: hold, pause, revert, or escalate.
    • Conflict behavior: Tell the workflow what to do when a performance signal and a risk signal point in opposite directions. The agent should not be allowed to improvise which one matters more.
    • Handoff format: Define what one stage may pass to the next, how facts differ from inferences, and how missing evidence is represented.
    • Audit requirements: List the context versions, inputs, reasons, permissions, actions, and human interventions that must be recorded.

    Make these controls machine-checkable wherever possible. A sentence that says to use recent data is weaker than a freshness field the workflow must validate. A paragraph asking the model to be cautious is weaker than a permission service that rejects an unauthorized budget change.

    Pay particular attention to stage handoffs. An extraction step might pass a traffic-source ID, landing URL, observation time, conversion window, quality status, and missing-field list to an analysis step. The analysis step should accept that defined payload, not the extraction step’s entire working history. This keeps irrelevant material out and prevents a summary or inference from silently acquiring the authority of a verified fact.

    Apply the same discipline to long-running conversations. If an agent evaluates several campaigns in one thread, earlier campaign details can remain available to later decisions. Start a clean decision context for each campaign or bounded batch, then attach only the approved context snapshot. Conversation history is convenient memory; it is not a reliable control database.

    Put security, performance, and escalation in one loop

    Evaluate evidence in a fixed order

    Do not ask the agent to weigh every signal in one undifferentiated prompt. Use deterministic gates around the model and evaluate them in a fixed sequence:

    1. Evidence gate: Confirm that required feeds arrived, their schemas match expectations, their timestamps pass freshness rules, and campaign identifiers agree.
    2. Integrity gate: Check malware, traffic-quality, redirect, destination, cloaking, policy, and other applicable risk states.
    3. Performance gate: Evaluate the proposed action against the campaign objective only after integrity checks pass.
    4. Authority gate: Verify that the account, campaign, action type, and size of change fall inside the agent’s current permissions.
    5. Execution gate: Record the decision and rollback point, execute once, and confirm that the advertising platform accepted the intended change.

    This ordering matters. If performance is evaluated first, a strong result can anchor the rest of the reasoning and turn a risk alert into something the workflow tries to explain away. Security should be able to veto scale even when the cost per acquisition looks excellent.

    Decision stateTypical evidenceAgent responseHuman role
    GreenRequired inputs are current, schema checks pass, no active risk alert exists, performance supports the change, and the action is permitted.Execute the bounded action, verify the platform response, and log the full decision record.Review sampled decisions and aggregate behavior, not every routine action.
    AmberA mild anomaly, changed landing behavior, new redirect, incomplete evidence, or conflicting systems makes the result uncertain.Do not scale. Hold the proposed change, collect more evidence, or continue at the existing state if that is the approved safe fallback.Resolve the conflict, approve one action, or amend the governing rule with an owner and version.
    RedA high-confidence malware or security alert, invalid destination, missing mandatory input, failed execution check, or request outside the permission envelope.Block the action and invoke the defined pause or rollback procedure.Investigate the incident and explicitly authorize any restart.

    Run integrity checks throughout the campaign lifecycle, not only at approval. Destination behavior can change after launch, and cloaked content may vary by location, device, visitor profile, or inspection time. One clean observation is not permanent clearance.

    Platform-specific evidence illustrates why the checks must remain continuous. In PropellerAds’ own Q2 2026 moderation data, total rejected campaigns fell from 36,085 to 20,790 quarter over quarter, while the share attributed to antivirus and malware issues rose from 23.3% to 45.9% and the absolute number increased by roughly 14%. That is not a market-wide malware measure, but it demonstrates the operational point: an improving top-line count can coexist with a worsening risk category. A single aggregate metric cannot clear traffic for autonomous scale.

    Route ambiguity to people, not routine volume

    Human review works best where judgment changes the answer. Requiring approval for every bid adjustment removes much of the value of automation and trains reviewers to click through repetitive requests. Instead, trigger review when:

    • risk and performance signals conflict;
    • a required input is missing, stale, or supplied in an unexpected format;
    • the landing page, redirect chain, domain, conversion definition, or measurement setup changes;
    • the proposed action is outside the permission envelope;
    • two approved tools disagree and the precedence rule does not resolve the difference;
    • the agent encounters a new anomaly that is not represented in the runbook;
    • a hard-stop alert fires or an automated action needs to be reversed;
    • repeated small actions produce a material cumulative change that requires a higher level of authority.

    Give the reviewer a compact decision bundle: the proposed change, expected effect, measurement window, input timestamps, security state, conflicting evidence, applicable permission, safe fallback, and rollback option. Do not send a generic request to check the campaign. The person should be able to see why the case was escalated and which decision is required.

    Make escalation timeouts safe. If the reviewer does not respond, the workflow should preserve the approved state or pause according to the runbook. Silence must never become permission to scale.

    Test for context rot before granting more authority

    A small autonomous machine is tested on a gated network containing stale signals, a broken bridge, and suspicious traffic nodes while an operator monitors a pause control.

    Use the symptom to find the failing context

    A workflow can keep running while the material around it degrades. Services change, teams reorganize, policies are revised, files move, tools alter their return formats, and new templates contradict old ones. The resulting failure has six recognizable forms: volume, competition, divergence, staleness, conflict, and contamination.

    • Vague output or skipped rules: Suspect excess context. Filter large platform exports before analysis, extract only the required facts, and run extraction and decision-making in separate contexts.
    • Different answers to the same request: Suspect competing providers, duplicate files, multiple templates, or divergent tool paths. Pin the approved provider and template version, then remove or quarantine alternatives.
    • The same wrong answer every time: Suspect stale or conflicting material being treated as authoritative. Check file dates, policy versions, ownership, precedence, and references to moved resources.
    • Unexpected claims inherited from an earlier stage: Suspect contamination. Validate every handoff against its schema, preserve provenance, and label inferred values so they cannot masquerade as verified inputs.

    Revalidation should be event-driven as well as scheduled. A tool upgrade, API schema change, new data provider, revised landing page, modified offer, policy update, renamed file, new skill, or altered team responsibility should trigger a check before the workflow resumes autonomous actions. If the input contract changes unexpectedly, freeze execution while preserving read-only monitoring.

    Use a staged authority ladder

    Do not make the first production test a live spending decision. Move through an authority ladder with explicit exit criteria:

    1. Replay: Run known past cases without platform access. Confirm that the workflow produces the expected hold, block, recommendation, and escalation states.
    2. Shadow: Read live inputs and generate decisions without executing them. Compare proposed actions with actual outcomes and inspect disagreements.
    3. Recommend: Let the agent prepare an action, evidence bundle, and rollback plan while a human executes or rejects it.
    4. Constrained execution: Grant the smallest useful action scope. Keep hard stops, cumulative limits, confirmation checks, and rollback available outside the model.
    5. Expanded execution: Add campaigns or action types only after the current scope produces reconstructable decisions and responds correctly to changed or missing evidence.

    Your test pack should include failure cases, not only clean campaigns. Give the workflow a cheap-conversion signal paired with a security block; a strong performance result with stale evidence; two approved tools that disagree; a redirect introduced after launch; a landing page whose behavior changes; an action that fits the budget but exceeds permission; and an obsolete template that describes a retired offer. The system passes only if it stops or escalates for the right reason.

    Log enough to reconstruct the decision

    A platform change log tells you what happened. An agent audit record must also tell you why it happened and which evidence was available at that moment. Record:

    • campaign, account, decision ID, and timestamp;
    • workflow, model, prompt, policy, template, and context versions;
    • the identity, timestamp, freshness result, and schema result for every required input;
    • performance, traffic-quality, destination, and security states used in the decision;
    • the proposed action, alternatives considered, and reason for the selected state;
    • the permission rule that allowed or blocked execution;
    • the exact platform action and confirmation response;
    • human approvals, denials, overrides, and rule changes;
    • the rollback point and any incident reference.

    Version the context as carefully as the automation code. Otherwise, a later reviewer may be able to reproduce the prompt but not the conditions that made its answer appear reasonable.

    Choose one active campaign and put the workflow into shadow mode. Write its context contract, connect current security and traffic-quality states to the decision gate, and run the failure test pack. Grant execution authority only after the agent can prove three things before every move: the evidence is current, the traffic is eligible to scale, and the requested action is permitted.

    References


  • Retail Media Audience Sharing in Google Ads: A Practical Guide

    Retail Media Audience Sharing in Google Ads: A Practical Guide

    If you sell through a retailer, some of the most useful shopper signals may sit in the retailer’s account while your campaign sits in yours. Google Ads commerce audience sharing creates a bridge between those two positions. That bridge is useful, but narrow: it is limited to eligible commerce media network campaigns.

    Before you build a media plan around it, you need to know what can be shared, where the resulting audiences can be used, what each partner can see and how you will judge the outcome. Getting those decisions in writing before activation prevents an audience opportunity from turning into an account, measurement or expectations problem.

    The feature is useful, but its lane is narrow

    Commerce audience sharing lets a retailer or marketplace make selected first-party audience segments available to a brand or seller through Google Ads. That gives an advertising partner access to audiences grounded in the commerce partner’s own customer relationships and shopping activity, rather than requiring the advertiser to build the same relationship independently.

    The roles are straightforward:

    • The commerce partner is the retailer or marketplace that owns and shares the eligible first-party segments.
    • The advertising partner is the brand or seller that can use those shared segments in an eligible retail media campaign.
    • Google Ads supplies the campaign infrastructure through which the collaboration operates.

    The most important limitation is also the easiest to miss. Shared commerce audiences are available for commerce media network campaigns, not for automatic use across regular Search, Shopping or Performance Max campaigns. Operationally, you should treat this as audience access for a qualifying retail media program, not as a portable audience asset that can be reused throughout your Google Ads account.

    That boundary should shape your go-or-no-go decision. The feature is a plausible fit when your immediate goal is to reach a retailer’s existing customers, high-intent shoppers or another retailer-defined customer group inside an eligible commerce media network campaign. It is not the answer when your plan depends on carrying the same segment into ordinary Search, Shopping or Performance Max activity.

    It is also a paid media capability, not an organic visibility tactic. Activating a retailer audience does not change how your pages are indexed, cited in AI answers or surfaced through SEO, AEO or GEO. Keep retail media activation and organic search optimization as separate workstreams, even when they support the same commercial objective.

    Prove the account and campaign path before planning creative

    An isometric account-to-campaign pathway connects retailer and advertiser workspaces through eligibility and access checkpoints, while incompatible routes are blocked.

    A promising audience idea has no value if the required accounts, eligibility and campaign type are not in place. Validate the operating path before you assign budget or ask a creative team to produce segment-specific ads.

    1. Identify the commerce partner. Name the retailer or marketplace that will make the segment available. Do not leave ownership implied between a brand, agency, seller and retailer.
    2. Confirm eligibility on both sides. The commerce partner and advertising partner must each satisfy Google’s eligibility requirements. One eligible account does not make the other eligible.
    3. Confirm the campaign type. Write down that the intended activation is an eligible commerce media network campaign. If the media plan only contains regular Search, Shopping or Performance Max campaigns, stop and redesign the audience plan.
    4. Map the required account relationships. The retailer’s sharing setup involves linking its Google Ads account with the relevant Google Merchant Center and data-sharing accounts. Assign an owner for each account and identify who can approve each link.
    5. Inventory the segments that will actually be shared. Availability is a commerce-partner decision. Build the campaign around confirmed segments, not around audience names that you hope the retailer can provide.
    6. Agree on the handoff. Record who publishes the segment, who confirms that it is available, who attaches it to the campaign and who resolves access problems.

    This sequence matters because audience strategy and account setup are different jobs. The advertiser may know which shoppers it wants, while the retailer controls which first-party segments are made available. A short activation brief should join those responsibilities instead of allowing each side to assume the other has handled them.

    Your brief should name the commerce partner, advertising partner, Google Ads account, relevant Merchant Center and data-sharing relationships, eligible campaign type, approved audience segments, primary conversion and approval owners. If any one of those fields is unresolved, the campaign is not ready for an audience-dependent launch date.

    Build the audience plan around a decision, not a label

    A segment called high intent sounds useful, but the label alone does not tell you what action to take. Ask what business decision becomes different because that audience is available.

    • Existing customers: Use this type of retailer-defined segment when the campaign has a clear relationship objective, such as presenting a relevant next purchase or a distinct customer message. Decide in advance whether existing customers are the target, a separate reporting group or outside the acquisition objective.
    • High-intent shoppers: Use this type only after the retailer explains what makes a shopper high intent. The campaign message should reflect the next action you want that shopper to take, not merely repeat a broad awareness message.
    • Specific customer segments: Request a segment when a meaningful difference in customer type changes the offer, product emphasis, creative or measurement plan. If every segment will receive the same treatment, extra segmentation may add operational complexity without improving the decision.

    For every requested segment, document the following questions:

    • What customer type does the segment represent?
    • Which behavior or relationship qualifies a person for it?
    • How recent must that qualifying behavior be?
    • How is the segment refreshed?
    • Can customers belong to more than one shared segment?
    • Which eligible campaigns may use it?
    • Which conversion will determine whether using it was worthwhile?

    Those operational definitions may require a direct agreement with the retailer. The information visible to an advertising partner includes segment names, customer types and conversion data, but a usable campaign brief often needs more context than a segment name can carry.

    Naming deserves care as well. A segment name should be clear enough for the advertiser to select and report on correctly. It should not contain customer-level information or encode details that are inappropriate to expose to a partner. Use a stable naming pattern that distinguishes the customer type, intended use and any version the partners need to recognize.

    The governing principle is simple: request the smallest meaningful set of audiences that can change a campaign decision. A long list of vaguely differentiated segments makes implementation and interpretation harder. A clearly defined segment tied to a specific message and conversion creates something both partners can evaluate.

    Measure value without calling every conversion incremental

    An analyst separates a mixed stream of conversion symbols into distinct groups to distinguish observed results from possible incremental effects.

    Audience sharing gives both sides visibility, but not identical visibility. Advertising partners can see shared audience information and conversion data. Commerce partners can access performance metrics showing how their audiences are being used and how the campaigns perform. Agree on a shared scorecard before launch so that each side does not reach a different conclusion from its own view.

    Separate four measurement questions:

    1. Was the intended audience available and used? Confirm that the correct shared segment was attached to the correct eligible campaign.
    2. Did the campaign produce the selected conversion? Define the conversion before launch and use the conversion data available to the advertising partner consistently.
    3. Was performance better than a relevant comparison? Where practical, compare the audience strategy with a campaign or audience treatment that is similar enough to inform the decision. Avoid changing the audience, creative, offer and optimization objective simultaneously if you want to understand which choice mattered.
    4. What can you honestly claim? Strong performance within a high-intent audience shows that the campaign reached and converted valuable shoppers. It does not, by itself, prove that every conversion was caused by audience sharing or that those purchases would not otherwise have happened.

    The distinction between efficiency and incrementality is important. A retailer’s high-intent audience may naturally contain people who are already close to buying. That can make the segment commercially useful, but a strong conversion result is still a performance observation unless the measurement design supports a causal lift claim. Label the result accurately: performance, comparative performance or incremental lift should not be treated as interchangeable terms.

    Set the decision rule before the campaign runs. State which conversion matters, which comparison you will use, which campaign variables must remain consistent and what result would lead you to expand, revise or stop the activation. The rule does not need an invented universal benchmark. It needs to match your economics and be agreed by the people who will act on it.

    Audience collaboration also needs a governance check. Document the approved campaign purpose, the people who can access the relevant accounts, the audience naming convention and the performance information each partner expects to review. Platform eligibility answers whether the feature can be used; it does not replace the commercial, privacy or contractual review appropriate to the partners’ relationship. Involve the responsible internal teams before sharing or activating customer-based segments.

    Key takeaways

    • Commerce audience sharing lets eligible retailers and marketplaces make first-party segments available to eligible brands and sellers through Google Ads.
    • The shared segments are limited to commerce media network campaigns; they do not automatically extend to regular Search, Shopping or Performance Max campaigns.
    • The retailer’s setup depends on the relevant Google Ads, Google Merchant Center and data-sharing account relationships.
    • Advertisers can see segment names, customer types and conversion data, while commerce partners can review performance information about audience use and campaign results.
    • A useful segment needs an operational definition, a distinct campaign decision and a named conversion. A persuasive label is not enough.
    • Campaign performance and incremental impact are different claims. Use comparison-based or causal language only when the measurement design supports it.

    If the campaign qualifies, begin with one documented audience, one campaign objective, one primary conversion and one agreed comparison plan. Resolve account ownership and eligibility before creative production begins. If your strategy requires the audience in standard Search, Shopping or Performance Max campaigns, choose another audience path instead of building a plan around access this feature does not provide.

    References


  • How to Test ChatGPT Visual Ads and Measure Incremental Lift

    How to Test ChatGPT Visual Ads and Measure Incremental Lift

    You have a budget decision to make: treat ChatGPT visual ads as a testable acquisition channel, or wait until the reporting ecosystem matures. The answer doesn’t depend on how novel the placement looks. It depends on whether you can connect the ad to a business outcome and then show that the spend caused more of that outcome.

    That distinction matters because a strong attributed return can still reflect demand that already existed. Before you fund a pilot, build a measurement plan that separates delivery, attribution and incremental lift. Otherwise, you may get an encouraging dashboard without learning whether the channel deserves more money.

    Visual ads create a paid surface, not organic AI visibility

    ChatGPT’s visual ads are intended to present products, services and experiences through imagery. The initial test is planned for image-generation experiences with a group of U.S. advertisers. The ads will be labeled and kept separate from images generated by ChatGPT.

    That separation gives you the first rule for reporting: paid exposure is not an organic recommendation, citation or answer-engine visibility win. Keep ChatGPT Ads in your paid-media scorecard. Track organic ChatGPT mentions, citations and referral traffic separately. If the same landing page receives both, use distinct campaign identifiers wherever the available implementation permits it.

    The image-generation setting also changes the creative question. A conventional display asset may be designed to interrupt passive browsing. Here, the surrounding activity involves making or refining visual material. That doesn’t prove a particular user intent, but it gives you a sensible creative hypothesis: the image should make the product, service or experience immediately understandable without pretending to be part of the generated output.

    • Show the offer clearly. A viewer should be able to identify what is being advertised before reading supporting copy.
    • Choose one proposition per variant. If an image tries to communicate price, quality, use case, social proof and product range at once, you won’t know which idea affected performance.
    • Preserve message continuity. The landing page should repeat the product, promise and visual cues used in the ad. A visual click followed by an unrelated page weakens both conversion rate and your ability to diagnose the creative.
    • Keep paid and generated media distinct internally. Asset names, reports and presentations should call the unit an ad. Don’t describe impressions as appearances in ChatGPT-generated images.
    • Request the actual creative specification. Confirm supported dimensions, copy fields, file limits, review rules and destination behavior before resizing an existing campaign library.

    OpenAI says ChatGPT reaches 1.2 billion people each week. That is a platform-supplied reach figure, not an estimate of addressable buyers or commercial intent. Use scale as a reason to investigate the channel, not as the input for a revenue forecast.

    Build the measurement chain before you launch creative

    A visual ad card passes through four connected transparent measurement modules on a dark tabletop.

    The announced measurement ecosystem has four distinct layers. They are related, but they do not answer the same question. Treating every integration as “tracking” is how teams end up with several dashboards and no agreed result.

    Measurement layerNamed partnersQuestion it should answer
    Conversion-data connectionsHightouch, Tealium and LiveRampCan confirmed business outcomes be sent back into the advertising platform?
    AttributionAppsFlyer, Triple Whale, Adjust, DV Rockerbox, Northbeam, Branch, Singular, Kochava, Airbridge and TenjinWhich tracked conversions receive credit for a ChatGPT Ads touchpoint?
    Full-funnel measurementFospha, Measured and INCRMNTALHow does the channel appear to contribute across the customer journey?
    Geo-based incrementalityHaus, Measured and WorkMagicDid exposure create additional conversions that would not otherwise have occurred?

    These announced partner relationships give you a map of the emerging stack. They do not establish that every connection has identical capabilities, availability or eligibility. Ask each vendor what data moves, in which direction, how often it updates, how conversions are matched, and what reporting is actually available for your account.

    Your internal data contract should come first. A partner cannot repair an event that fires inconsistently, counts duplicate orders or changes meaning midway through the test.

    1. Name one primary outcome. Use the event that represents business value, such as a completed purchase or a lead that has passed your qualification rule. Page views and button clicks can help diagnose the path, but they should not replace the outcome.
    2. Write the counting rule. State when the event becomes valid, how cancellations or invalid leads are handled, and whether repeat transactions count. Apply the same definition to every channel in the comparison.
    3. Deduplicate at the transaction level. Pass a stable order or conversion identifier through the systems that are permitted to receive it. One purchase reported by a browser, server and partner must remain one purchase.
    4. Preserve the fields needed for analysis. Record timestamp, conversion value, currency, campaign identifier and new-versus-returning customer status when those fields are available and allowed by your consent and data-governance rules.
    5. Choose the source of truth. Decide whether final revenue comes from your commerce platform, CRM or another controlled system. Ad and attribution dashboards can explain credit; they should not silently redefine booked revenue.
    6. Test the path end to end. Complete a controlled conversion, confirm that it appears once in the source of truth, and verify that each connected system receives the expected event and value.
    7. Freeze the measurement definitions. Document attribution windows, identity rules, exclusions and late-arriving conversion treatment before launch. If a definition changes, annotate the date and avoid blending the two periods as though they were comparable.

    This setup gives you traceability. When two dashboards disagree, you can inspect event definitions, matching and attribution settings instead of debating which total looks more favorable.

    Attribution tells you who received credit; incrementality tests causation

    A split illustration shows converging customer paths beside two matched groups, one exposed to an ad and producing extra outcome tokens.

    An attributed conversion occurred after a measurable advertising touchpoint and was assigned to that touchpoint under a defined rule. An incremental conversion is an estimated additional outcome caused by the advertising. Those are different claims.

    Suppose someone was already likely to buy, saw a ChatGPT ad and then converted. An attribution model may award the ad some or all of the credit. An incrementality design asks what would probably have happened without the ad. The first result can be useful for journey analysis; the second is the stronger basis for increasing budget.

    The early results illustrate why you must read each metric literally rather than combine them into a single success narrative.

    Early partner-reported resultWhat it supportsWhat it does not establish
    DV Rockerbox measured WeightWatchers’ attributed CPA from ChatGPT Ads at 15.3% below its blended paid-search benchmark.Attributed acquisition cost compared favorably with that advertiser’s chosen benchmark in that measurement.It does not by itself prove incremental lift or provide a benchmark for another advertiser.
    WorkMagic found that 67% of Dose’s incremental purchases came from new customers.The reported incremental purchases included a substantial new-customer component in that case.It does not reveal how another brand’s customer mix, total lift or economics will behave.
    Triple Whale reported that 93% of Portland Leather visitors from ChatGPT Ads were new.The tracked visitor mix was heavily weighted toward new visitors for that advertiser.New visitors are not automatically new customers, incremental purchases or profitable orders.

    These are preliminary, partner-reported results from individual advertisers, not broad platform benchmarks. They can justify forming testable hypotheses. They cannot justify inserting the same CPA improvement or new-customer share into your forecast.

    A useful reporting hierarchy has three levels:

    • Delivery validation: Did the campaign spend and produce measurable visits or other intended responses? This tells you whether the setup functioned.
    • Attributed efficiency: What cost per attributed outcome and attributed return did your chosen model report? This helps compare credit under consistent rules.
    • Incremental business impact: How many additional outcomes did the experiment estimate, and at what incremental cost? This is the scale-or-stop question.

    For a geo-based incrementality test, work with the measurement partner to choose comparable exposed and control regions, account for their pre-test differences, and set the primary outcome before delivery begins. Keep major promotions, pricing changes and channel shifts consistent where possible. When they cannot be kept consistent, log them so the analysis can account for a contaminated period rather than treating it as clean.

    Define the budget decision in advance as well. Your acceptable incremental acquisition cost should come from unit economics, not from the platform’s attributed CPA. If the estimated lift is too uncertain to distinguish from normal variation, call the result inconclusive. Do not relabel uncertainty as zero impact, and do not scale it as proof of success.

    Use a test charter that forces a scale, iterate or stop decision

    A pilot becomes useful when it resolves a decision. Before the campaign starts, put the following items on one page and require the channel owner, analyst and business owner to agree on them.

    1. Decision: State what will happen after the readout. Examples include expanding the test, revising the offer or creative, or stopping spend. Avoid goals such as “learn about the channel” that permit any result to look acceptable.
    2. Hypothesis: Describe the mechanism you expect. A useful form is: a clearly visual presentation of this offer will generate additional qualified demand from this type of need, producing an incremental outcome within our acceptable economics.
    3. Primary metric: Select one business outcome and define its numerator and denominator. Keep diagnostic measures such as click-through rate, landing-page engagement and attributed conversions secondary.
    4. Incrementality method: Name the geo design or other approved causal method, the measurement partner, the exposed and control units, and the planned analysis. Do not add incrementality after seeing an attributed result you like.
    5. Creative variables: List the element each variant changes. Change one major proposition at a time when the available delivery controls make that practical; otherwise, a winning asset will not tell you what to reuse.
    6. Landing-page path: Record the destination, conversion steps and analytics events. Confirm that the page supports the exact claim shown in the visual.
    7. Data owners: Assign one person to conversion integrity, one to paid-platform operations and one to final analysis. Shared accountability without named owners usually means unresolved discrepancies at readout.
    8. Decision thresholds: Write the minimum acceptable business result and the treatment of statistical uncertainty before launch. Use your own margin, retention and capacity constraints rather than copying a partner-reported case.
    9. Confounder log: Track promotions, inventory shortages, site outages, price changes, major organic coverage and material changes in other paid channels.

    At the readout, separate creative diagnosis from channel diagnosis. Weak delivery or a broken conversion path means you did not get a valid channel test. Strong attribution with no measurable lift means the ads may be capturing existing demand. Incremental conversions with unacceptable economics mean the channel caused an effect, but not one you should scale in its current form.

    Use three possible decisions. Scale only when the data chain is sound and incremental economics meet the prewritten requirement. Iterate when the test is valid but points to a specific repairable constraint, such as the offer, creative clarity or landing-page path. Stop when a valid test misses the business threshold and there is no evidence-backed change likely to alter the result.

    Treat brand suitability as an operating control

    Brand safety and brand suitability are related but not identical. Safety addresses broadly harmful or unacceptable environments. Suitability applies your brand’s own tolerance to contexts that may be acceptable for one advertiser and wrong for another.

    OpenAI is developing brand-suitability evaluation pilots with DoubleVerify and Integral Ad Science. The evaluations are planned for controlled environments and do not give those partners access to private user conversations. Qualifying advertisers can also use Negative Phrases for more specific placement requirements.

    Those controls are meaningful, but they do not replace your own policy. A negative-phrase list is only as useful as its coverage, maintenance and enforcement. Build the internal process before launch:

    • Create three context tiers. Mark categories as prohibited, review-required or generally acceptable. This gives campaign operators a decision rule instead of an unstructured list of concerns.
    • Translate prohibited contexts into phrases. Use language that represents the actual context you need to avoid. Confirm the supported matching behavior before assuming that variants, synonyms or related concepts are covered.
    • Record the reason for every restriction. Tie it to legal requirements, product policy, audience sensitivity or brand standards. This makes the list maintainable and prevents unexplained phrases from accumulating.
    • Ask what evidence is available. Determine what placement, suitability or verification reporting your account can receive and at what level of detail. Do not promise internal stakeholders a conversation-level log when the suitability pilots explicitly avoid private conversations.
    • Define escalation and pause authority. Name who reviews questionable placements, who can stop spend and how findings change the phrase list or creative policy.
    • Review controls alongside creative. An accurate placement policy cannot rescue an image that exaggerates the product, obscures material conditions or implies that the ad is ChatGPT-generated content.

    Key takeaways

    • Report ChatGPT visual ads as paid media, separately from organic ChatGPT recommendations, citations and AI-search visibility.
    • Connect a clean, deduplicated business outcome before evaluating creative performance.
    • Use attribution to understand assigned credit, but use incrementality to decide whether the channel created additional conversions.
    • Treat the early advertiser results as hypotheses for your own test, not as planning benchmarks.
    • Set scale, iterate and stop rules before launch so the readout produces a budget decision.
    • Turn brand suitability into a documented policy with phrase controls, evidence requirements and named escalation owners.

    Your next move should be a measurement charter, not a large rollout. Choose one business outcome, verify its data path, define the incrementality design and write the decision threshold. Once those pieces are agreed, creative testing can teach you something durable instead of merely generating another attributed-performance report.

    References


  • Political Campaign AI Spending: Where the 2026 Money Goes

    Political Campaign AI Spending: Where the 2026 Money Goes

    If you are building, buying, or measuring AI for a 2026 political campaign, the biggest budgeting mistake is treating AI as a single technology line. The headline total combines tools, AI-assisted work, automated outreach, and the media used to distribute AI-influenced advertising. A campaign can therefore spend little on software while creating a large AI-related footprint.

    You need to separate cost, operational use, and public exposure before deciding whether your campaign is underinvesting, overspending, or simply counting differently. That distinction turns an eye-catching market estimate into a budget you can actually manage.

    The $899 million headline is not a software market size

    Political campaigns, party committees, and outside groups are projected to spend $899 million on AI during the 2026 cycle. That would be 2.8 times the 2024 total and about 22 times the 2022 total. It is also equivalent to roughly 8.5% of the projected $10.6 billion in overall political advertising for the cycle.

    But $899 million does not mean campaigns are buying $899 million of AI software. The estimate includes three materially different forms of spending:

    • Direct payments for AI vendors, platforms, and general-purpose subscriptions.
    • The portion of production, targeting, fundraising, and outreach costs attributed to AI.
    • Media dollars placed behind advertisements generated or enhanced with AI.

    Those categories answer different questions. Direct vendor spending helps you assess the technology market. AI-attributable workflow spending tells you how deeply campaigns are using the technology. Media placement measures how much paid distribution sits behind AI-influenced assets. Combining them is useful for estimating AI’s overall campaign footprint, but it cannot tell you what AI products earned or how much a campaign saved.

    The total is also a projection, not a final audited tally. Its methodology covers more than 41,000 federal and state disbursement records, platform advertising libraries, and 57 consultant and vendor interviews, with activity tracked through September 24 and modeled through Election Day on November 3. Treat it as a structured market estimate. Do not use it as proof that every campaign classifies AI spending the same way.

    Before comparing your own budget with the market, decide which question you are asking. If you want to know what your technology stack costs, exclude media. If you want to understand operational adoption, include the AI-assisted share of labor and services. If you are assessing voter exposure, include distribution but keep it separate from production. One blended figure cannot answer all three questions.

    Distribution and outreach absorb more money than AI tools

    A small AI workstation connects through branching light trails to many phones, screens, mail pieces, and canvassing devices.

    The projected category mix shows where AI is entering campaign operations. Media placement behind AI-generated or AI-enhanced advertising is the largest category. General-purpose subscriptions are the smallest. That gap matters: the visible scale of political AI is being driven more by amplification and workflow adoption than by the price of access to a model.

    Spending categoryProjected 2026 spendingShare of totalGrowth versus 2024Question your budget should answer
    Media placement behind AI-generated or AI-enhanced ads$237 million26.4%3.3xCan you connect each placement to a specific asset, audience, and outcome?
    AI voter outreach$173 million19.2%3.0xWhen does an automated interaction move to a trained person?
    AI fundraising optimization$147 million16.4%2.4xAre you measuring net fundraising performance rather than message volume?
    AI audience modeling and targeting$131 million14.6%1.8xDoes the model improve decisions against a defined non-AI baseline?
    AI creative production$98 million10.9%4.7xWho verifies facts, voices, likenesses, and required disclosures before release?
    AI-assisted media buying fees$65 million7.2%2.8xCan you separate the service or algorithmic fee from the underlying media spend?
    General-purpose AI tools and subscriptions$48 million5.3%4.0xWho controls accounts, data access, retention, and offboarding?

    Creative production is growing fastest at 4.7 times its 2024 level, but it still accounts for only 10.9% of projected 2026 AI spending. Audience modeling is growing slowest at 1.8 times because it already had a meaningful base before the recent expansion of generative tools. Fast growth, large spending, and operational maturity are therefore three different signals.

    Do not judge an AI program by the number of assets it produces. A campaign can generate hundreds of variants without improving persuasion, fundraising, or contact quality. Measure the result associated with each workflow: approved production time for creative, net revenue for fundraising, successful contacts and escalations for outreach, incremental performance for targeting, and cost per desired action for media. Keep output volume as a diagnostic metric, not the primary success metric.

    Adoption also cuts across party lines. Republican candidates, parties, and aligned outside groups account for a projected $415 million, compared with $374 million on the Democratic side. Outside groups allocate a larger portion of their budgets to AI than candidates and parties, with Republican-aligned groups reaching 10.2%. Party affiliation is a poor proxy for AI maturity; spender type and workflow are more useful.

    Race size, geography, and timing change the right strategy

    Absolute spending concentrates in federal contests. House races account for a projected $305 million and Senate races for $286 million, together representing 65.7% of campaign AI spending. Yet smaller races use AI more intensively relative to their available media.

    Local and judicial races have AI-generated or AI-enhanced elements in 16.2% of ads, and AI represents 13.8% of their media budgets. State legislative races follow at 14.7% of ads and 12.4% of media budgets. House races are lower on both measures, at 9.2% and 8.9%, despite carrying the largest dollar total. Ballot measures sit at the other end, with AI elements in 6.3% of ads and 5.2% of media budgets.

    This is a denominator problem that can distort competitive analysis. A small campaign may look more AI-intensive because automation replaces work it could not otherwise afford. A large federal campaign can spend far more dollars while AI remains a smaller percentage of a much larger operation. Compare campaigns on both absolute spending and share of budget. Using only one will misclassify the smaller operation or obscure the larger one’s reach.

    Geography produces another concentration effect. The ten highest-spending states account for $460.1 million, or 51.2% of the projected total. Maine reaches $25.09 per registered voter, almost three times the next-highest figure in that group, as a competitive Senate race concentrates spending across a relatively small electorate. A national average will not tell you what competitive pressure looks like in an individual state.

    Disclosure practices vary just as sharply. Among the ten highest-spending states, the recorded share of AI ads carrying a disclosure ranges from 29% in Georgia to 78% in California. Across states with AI disclosure laws, 64% of AI ads carried a disclosure, versus 27% in states without one. That relationship indicates that legal requirements affect behavior, but it is not a substitute for a state-by-state compliance review.

    Build a jurisdiction field into the asset record before production begins. Record where the asset will run, what was generated or materially altered, which disclosure decision was made, who approved it, and which final version entered distribution. When the applicable rule is unclear, hold the asset and ask qualified election counsel. Retrofitting a disclosure after placement creates avoidable legal, financial, and reputational exposure.

    Timing is equally important. At the aligned one-month point, cumulative 2026 AI spending reaches $612 million, with a projected $899 million by Election Day. Spending within each cycle has roughly doubled every three months as Election Day approaches. The final month is projected to contain 32% of 2026 spending, below the 37% final-month share in 2024 because outreach and fundraising automation moved earlier to reach early voters.

    Do not postpone governance until the spending ramp. The final weeks are when review time contracts, asset volume rises, and media decisions become harder to reverse. Approve vendors, data permissions, escalation paths, disclosure rules, and evidence requirements before the high-volume period. The late-cycle budget should scale a controlled workflow, not finance the first real test of one.

    Build an AI budget that can survive scrutiny

    Transparent budget containers, coins, a magnifying glass, a locked data box, and a balance scale are arranged on an orderly campaign planning desk.

    A defensible AI budget starts with a ledger, not a list of tools. The cost of an AI program can include software, implementation, data work, human review, compliance, vendor services, and media. If you record only subscription invoices, you will understate the program. If you label every placement behind an AI-assisted asset as technology spend, you will lose sight of what the technology itself costs.

    1. Choose the unit of analysis. State whether you are tracking direct vendor cost, AI-enabled workflow cost, or media exposure. Maintain all three if leadership needs a complete view, but never merge them without labels.
    2. Classify spending at the invoice or line-item level. Assign every item to creative production, outreach, fundraising, targeting, media-buying services, general tools, or media placement. Prevent one invoice from disappearing into a broad digital-services account.
    3. Attach each cost to an accountable workflow. Record the race, jurisdiction, vendor, campaign owner, data used, synthetic or altered elements, human reviewer, approval status, and distribution channel.
    4. Set the baseline before the pilot. Compare the AI-enabled workflow with the existing process on the outcome that matters. Time saved is meaningful for production; it is not evidence of better persuasion. Message volume is meaningful for operations; it is not evidence of better fundraising.
    5. Create a release gate. Require factual verification, permission checks for voice and likeness, disclosure review, accessibility review where relevant, security review, and named human approval before an asset or automated interaction goes live.
    6. Scale only the validated component. If a creative workflow saves time but targeting does not improve performance, scale production rather than buying a larger bundled program. A vendor relationship does not have to expand as one indivisible unit.

    Your ledger should let a reviewer move in both directions: from an invoice to the assets and outcomes it funded, and from a public asset back to its production record, approval, disclosure decision, and media spend. That traceability is more useful than a generic AI policy because it shows how the policy operated in a specific case.

    If you publish or optimize political content

    More campaign investment means more creative variants, automated contacts, and paid distribution. It does not create independent corroboration. Treat campaign-generated material as a claim that requires verification, even when the asset looks polished or appears repeatedly across channels.

    • Put the publication or revision date, jurisdiction, race, candidate or issue, and sponsor context where a reader can see them.
    • Separate campaign assertions from independently verified facts, and link to the strongest available primary evidence for factual claims.
    • Keep the original approved asset and a correction history so changes do not erase provenance.
    • Use structured data only for information visible on the page. Markup can clarify entities and dates, but it cannot turn an unsupported claim into reliable evidence.
    • Do not present repeated synthetic content as multiple independent confirmations. Distribution volume and source diversity are not the same thing.

    These practices help human readers, search systems, and AI answer engines distinguish what happened, who is making a claim, when it applies, and which evidence supports it. They do not guarantee visibility or favorable treatment, but they reduce ambiguity at the point where political information is most likely to be compressed into a short answer.

    Key takeaways

    • The projected $899 million total measures a broad AI-related campaign footprint, not just software purchases or vendor revenue.
    • Media placement is the largest category at $237 million, while general-purpose tools and subscriptions account for $48 million.
    • Creative production is growing fastest, but output volume alone does not establish campaign impact.
    • Federal races lead in total dollars, while local, judicial, and state legislative races use AI more intensively relative to their media.
    • Disclosure practices differ substantially by state, so every asset needs a jurisdiction-specific review and an auditable approval record.
    • Budgeting should separate direct technology cost, AI-enabled workflow cost, and paid exposure, then connect each to a defined outcome.

    Start by exporting every AI-related expense and reclassifying it into technology, workflow, or distribution. Then choose one high-exposure workflow, give it a measurable baseline and a named approval owner, and resolve its disclosure path before shifting more money into it. That is how you turn a market trend into a campaign decision you can explain, test, and defend.

    References


  • Google Ad-Tech Antitrust Litigation: A Publisher’s Playbook

    Google Ad-Tech Antitrust Litigation: A Publisher’s Playbook

    If you depend on programmatic advertising revenue, the Google ad-tech litigation creates a planning problem before it creates a financial opportunity. The wrong response is to put a recovery into your forecast or make a rushed platform change. The useful response is to determine whether your business touches the surviving claims and whether you can still explain, with records, how money moved through your ad stack.

    Major claims remain alive, but that is not the same as a finding that every publisher was harmed. Your immediate job is to separate what the court has established, what the publishers still must prove, and what evidence your own legal and finance teams would need to evaluate any potential exposure or recovery.

    The ruling preserved a path, not a payout

    On Sept. 30, U.S. District Judge P. Kevin Castel issued an 88-page opinion denying Google’s requests for summary judgment on the publishers’ principal ad-tech claims. He also declined to exclude important expert testimony supporting their damages cases.

    Summary judgment is a pretrial mechanism for resolving claims that do not require a trial to decide. Denying it means Google did not persuade the court to dispose of the principal claims on the pretrial record. It does not mean the publishers have won a damages award, that every expert assumption has been accepted, or that every remaining dispute will necessarily reach trial.

    What the decision didWhat it did not do
    Kept the publishers’ principal ad-tech claims in the litigationDecide how much, if anything, Google owes
    Allowed key damages testimony to remain in the caseAdopt the experts’ estimates as proven losses
    Preserved claims involving the AdX publisher class and Mikula Web SolutionsPreserve every claim brought by every plaintiff
    Prevented Google from relitigating certain findings from the separate Virginia caseEstablish injury and damages for each publisher automatically

    The mixed outcome matters. Castel ruled for Google on the New York General Business Law claims brought by Gannett and Daily Mail, on claims brought by The Progressive, and on Inform’s federal antitrust claims. Claims involving the AdX publisher class and Mikula Web Solutions were allowed to continue. A headline saying publishers cleared a major hurdle is accurate, but it is too broad to answer whether a particular company, legal theory, or alleged loss remains in play.

    When you brief executives, use a claim matrix rather than a win-or-loss label. Give each claimant and legal theory its own row, then record whether the claim survived, which issues are already established, which issues remain disputed, and what procedural event comes next. That prevents a partial ruling from turning into an inaccurate company-wide assumption.

    The economic dispute sits between inventory and demand

    An abstract publisher page and advertiser nodes connected through a layered auction system carrying metallic tokens.

    A publisher ad server manages advertising inventory and helps decide which demand source can fill an opportunity. An exchange provides a marketplace in which demand can compete for that inventory. When one company controls important infrastructure on both sides of that handoff, the rules connecting the products can affect which demand participates, how an auction operates, what fees are charged, and what reaches the publisher.

    That connection is central here. The publishers allege that Google’s control over its publisher ad server and the AdX exchange, combined with practices governing ad auctions, reduced publisher revenue or produced excessive fees. Google contests those allegations. The disputed question is therefore not simply whether publishers used Google technology; it is whether challenged conduct caused a measurable economic injury.

    The litigation also draws on the federal government’s separate ad-tech case in Virginia. Castel had already determined that Google could not relitigate certain findings from that proceeding, including the finding that Google unlawfully tied its publisher ad server to AdX. That gives the publisher plaintiffs an important established point, but it does not calculate the consequences for a particular publisher. Injury, causation, and damages still have to be connected to the conduct at issue.

    For your business, the practical unit of analysis is an ad-monetization dependency map. It should show:

    • The legal entities, sites, applications, and business units that sold digital inventory.
    • The publisher ad server and exchanges used during each relevant period, including migrations and material configuration changes.
    • Which demand paths were direct, exchange-based, mediated, or otherwise dependent on the publisher ad server.
    • The contracts, amendments, fee schedules, invoices, and reporting accounts associated with each path.
    • The identifiers that connect domains, properties, accounts, reports, and payment records across systems.
    • The employees or vendors who understood auction configuration, yield management, billing, and reporting definitions at the time.

    This map does not establish that you belong to a class or have a claim. It gives counsel the facts needed to assess those questions without relying on institutional memory. It also reveals whether a change in revenue coincided with traffic, inventory, auction, fee, or platform changes instead of treating every decline as one undifferentiated problem.

    Do not mistake the damages estimates for recoverable amounts

    The public figures are large because they are damages estimates prepared by experts retained by the plaintiffs. They are not court-awarded compensation:

    Claimant or groupPlaintiffs’ expert estimate
    GannettRoughly $901 million
    Daily Mail$600 million
    Publisher class$1.72 billion through March 31, 2024

    The plaintiffs claim additional class damages after March 31, 2024, but no additional amount was provided. Do not extend the $1.72 billion estimate beyond that date, apply it as a percentage of industry revenue, or use it to derive a hypothetical recovery for your company. None of those calculations is supported by the disclosed figures.

    An expert’s testimony can remain admissible while its assumptions, method, causal reasoning, and conclusions remain disputed. The publishers still need to prove that the challenged conduct injured them and that the requested damages are attributable to that conduct. Google can continue contesting those points.

    Your finance team should therefore treat the amounts as allegations supported by the plaintiffs’ models, not as receivables or operating income. If you need an internal scenario, build it in layers:

    1. Use zero recovery as the operating baseline unless legal and accounting advisers determine otherwise.
    2. Ask counsel whether the relevant legal entity, products, time periods, and transactions could fall within a surviving claim or class.
    3. Identify which revenue, fee, and auction records could support or contradict economic injury.
    4. Document every assumption in any contingent scenario, including eligibility, time boundaries, allocation method, legal costs, and uncertainty.
    5. Keep the scenario outside normal performance targets so an unresolved lawsuit does not distort hiring, content, or technology decisions.

    The same restraint applies to vendor decisions. A surviving antitrust claim is not proof that your current contract is invalid, that a migration will improve yield, or that another stack will produce a particular result. Evaluate a change using your own fees, demand access, reporting quality, operational cost, and measured auction outcomes.

    Build a counsel-led evidence pack while the systems are identifiable

    An overhead view of storage drives, blank records, archive envelopes, and a magnifying glass arranged as an evidence pack.

    This is an operational preparation checklist, not a determination that your company is part of the litigation or subject to a legal-hold obligation. If the surviving claims may be relevant to your business, ask qualified antitrust or litigation counsel to assess eligibility and preservation duties. Do that before changing retention policies or launching a broad data collection.

    1. Create a system inventory. Record each ad server, exchange, reporting interface, billing system, data warehouse, and archive, along with its owner and available date range.
    2. Preserve the commercial record. Locate contracts, order forms, amendments, invoices, payment statements, fee disclosures, account notices, and documents explaining platform migrations or material configuration changes.
    3. Preserve the operational record. Identify ordinary-course auction reports, revenue reports, configuration histories, demand-partner lists, account identifiers, and metric definitions. Record where a field was renamed or calculated differently over time.
    4. Build a dated chronology. Align platform changes with shifts in impressions, fill, auction participation, reported fees, and net publisher revenue. A chronology makes alternative explanations visible instead of assuming every movement came from the challenged conduct.
    5. Reconcile money to activity. Where the data permits, connect inventory and auction records to invoices and net payments. Record unexplained gaps rather than backfilling them with estimates.
    6. Document limitations. Note missing periods, expired logs, acquired properties, changed account IDs, inconsistent currencies, and reports that cannot be reproduced. A known limitation is more useful than false precision.
    7. Control access. Keep the working set limited to the people who need it, and follow counsel’s directions for preservation, privilege, privacy, security, and collection scope.

    Do not delete, rewrite, or normalize potentially relevant originals after counsel identifies a preservation obligation. At the same time, do not collect extra user-level information merely because it might be available. An indiscriminate collection can create privacy and security exposure without helping establish publisher-level fees or revenue. Preserve what is relevant, document what each field means, and let counsel define the defensible scope.

    SEO, content, and audience teams also have a role. Keep acquisition performance separate from monetization performance in your reporting:

    • Acquisition: visits or sessions from organic search, AI-search referrals, direct traffic, social platforms, and other channels.
    • Inventory: ad opportunities, eligible impressions, ad load, and fill-related measures available in your systems.
    • Monetization: auction outcomes, disclosed fees, and net publisher revenue, with the governing metric definitions attached.

    Traffic can improve while monetization weakens, or monetization can improve while traffic falls. A single blended revenue-per-session figure hides that distinction. Separating the layers helps you evaluate content performance accurately now and gives legal and financial reviewers a cleaner record if they later need to isolate alleged ad-tech harm.

    Key takeaways for publisher teams

    • The Sept. 30 decision kept principal Google ad-tech claims alive and preserved key expert testimony; it did not award damages.
    • Google cannot relitigate certain findings from the separate Virginia case, including unlawful tying of its publisher ad server to AdX, but publisher-specific injury and damages still require proof.
    • The estimates of roughly $901 million for Gannett, $600 million for Daily Mail, and $1.72 billion for the publisher class are plaintiffs’ expert estimates, not payouts.
    • The result varies by claimant and legal theory. Several claims were resolved for Google, while claims involving the AdX publisher class and Mikula Web Solutions continue.
    • Your defensible next step is a counsel-led review of eligibility, systems, contracts, fees, and retained data—not an assumed recovery or an emergency platform migration.

    Within your next reporting cycle, produce a one-page ad-stack dependency map and assign owners for the supporting contracts, reports, and payment records. Have counsel decide whether a deeper eligibility or preservation review is warranted. That gives you a decision-ready file without pretending the litigation has already produced money for publishers.

    References


  • A Practical Framework for AI Advertising Campaign Reporting

    A Practical Framework for AI Advertising Campaign Reporting

    Your AI advertising dashboard can be numerically correct and still lead you to the wrong decision. This happens when it collapses four different things into one performance label: what delivered, what the platform optimized for, what it attributed, and what its budget tools are allowed to use.

    You need a reporting system that keeps those layers visible. The framework below will help you turn campaign data into defensible actions without letting an AI-generated summary hide attribution limits, product eligibility problems, or gaps between web and app measurement.

    Key takeaways

    • Show the selected optimization goal beside every supporting conversion. A reported outcome is not necessarily an outcome the campaign pursued.
    • Label each conversion separately as reportable, used for optimization, and eligible for budgeting. Those are three different permissions.
    • Treat attribution as a rule for assigning credit, not proof that an ad caused the outcome.
    • Put product rejections, review pauses, identity changes, and measurement changes on the campaign timeline so operational interruptions are not mistaken for performance failures.
    • Let AI explain a governed dataset. Keep metric definitions, joins, formulas, and eligibility rules deterministic and reviewable.

    Build every report around one decision

    A dashboard built to answer every possible question usually answers none of them clearly. The person deciding whether to scale a campaign needs a different view from the person diagnosing a rejected product or reconciling app purchases. Start with the decision, then select the data required to make it.

    A useful report header should identify:

    • Decision: Scale, hold, reduce, diagnose, or repair.
    • Scope: Account, campaign, ad group, product, channel, market, and customer surface.
    • Primary outcome: The conversion event selected as the optimization goal.
    • Supporting outcomes: Other attributed events that help you judge lead quality, downstream value, or progression through the journey.
    • Comparison: The period, segment, or campaign being used as the reference point.
    • Measurement context: Attribution model, attribution window, currency, time zone, data freshness, and known coverage gaps.
    • Next action: The proposed change, its owner, and the condition that would reverse or confirm it.

    Do not force every conversion into a single blended total. A campaign optimized for one event can now expose other attributed events through the public ChatGPT Ads Insights API. That additional visibility is useful, but it does not change the campaign’s selected goal.

    Keep the primary outcome and supporting outcomes in separate columns. If the optimization goal improves while a downstream purchase metric weakens, you have a quality question to investigate. If purchases improve while the optimization goal is unchanged, you have a useful signal, but not automatic proof that the campaign caused the improvement.

    Separate delivery, eligibility, outcomes, and attribution

    Four transparent stacked chambers separately depict ad delivery, product eligibility, customer outcomes, and attribution paths.

    A trustworthy report lets you locate the stage at which performance changed. Use distinct reporting layers instead of dropping every metric into one scorecard.

    Reporting layerQuestion it answersWhat to includeDecision it supports
    DeliveryDid the campaign reach and engage its available audience?Platform delivery metrics at the campaign, ad group, and product levelsInvestigate distribution, targeting, serving, or creative exposure
    CostWhat did that delivery consume?Spend and consistently calculated efficiency metricsCheck financial guardrails and locate changes in cost
    Product eligibilityCould each advertised product serve?Feed item, review state, rejection reason, and status-change timeRepair catalog or policy issues before judging demand
    OutcomesWhich conversion events received credit?Optimization goal and supporting attributed events, kept separateEvaluate the chosen objective and inspect downstream quality
    Attribution and governanceUnder which rules and account conditions were results recorded?Model, window, surface, naming changes, review pauses, and measurement changesCompare compatible data and explain discontinuities

    ChatGPT Ads reporting can supply delivery, cost, product, and attributed conversion metrics. Preserve those metric families as separate datasets or clearly identified groups in your reporting model. That makes it possible to tell the difference between a serving problem, a cost problem, a catalog problem, and a conversion problem.

    Product campaigns need an eligibility layer because a rejected item did not receive the same opportunity as an approved item. ChatGPT Ads now exposes product review status and individual rejection reasons. Bring those fields into the report before calculating product-level winners and losers. Otherwise, you may penalize an item for not converting when the actual issue was that it could not serve.

    Operational changes also belong on the timeline. ChatGPT Ads separates the internal account name, public brand name, and registered legal name. A public brand-name change can pause serving during review, while a legal-name change can restart business review and may also interrupt delivery. Record those identity and review events as annotations. A delivery gap during a review is an operational interruption, not evidence that the audience rejected the campaign.

    Treat reporting, optimization, and budgeting as separate controls

    Every conversion in your measurement plan needs three explicit flags:

    • Reportable: Can the event appear in performance or attribution reporting?
    • Optimization-enabled: Is the campaign actively trying to generate this event?
    • Budget-eligible: Can an automated or cross-channel budgeting system use this event when allocating money?

    Never infer the second or third flag from the first. The ChatGPT Ads Insights API can return attributed events beyond the selected optimization goal. Google can include app conversions in performance reporting, attribution analysis, and attribution models while its cross-channel budgeting features remain limited to web conversions. In both cases, visibility is broader than at least one action layer.

    Use supporting conversions without changing the meaning of success

    Supporting conversions can reveal what happens after the event selected for optimization. They are especially useful when the selected event represents an earlier step in the customer journey. Keep them in the report, but preserve their role.

    For each event, store its business definition, customer surface, reporting status, optimization status, budgeting status, and attribution configuration. If one of those fields is unknown, label it unknown. Do not allow the reporting layer or an AI assistant to silently convert an unknown into a yes.

    Keep a visible boundary between web and app measurement

    Google’s expanded conversion reporting can bring app activity into broader performance and attribution views. Advertisers can also configure attribution for app conversions independently from other conversion types. However, availability may still vary by Google Analytics property, and app outcomes are not yet included in cross-channel budgeting.

    This can make a report look unified even when the underlying controls are not. Add a surface field to every conversion row and display web and app subtotals before showing a combined figure. Also record the attribution setting applied to each surface. A combined total is decision-safe only when you can explain what was counted, how credit was assigned, and whether the downstream tool can act on all of it.

    An AI-generated recommendation should never say that a budget allocator will react to app conversions merely because those conversions appear in the same report. It can recommend a manual review of the evidence, but it must preserve the platform’s actual budgeting boundary.

    Build a reporting pipeline that AI can audit

    Transparent data channels pass advertising events through validation and lineage checks before an AI system presents evidence to a human reviewer.

    Automation makes governance more important, not less. Spreadsheet uploads can create multiple ChatGPT product campaigns and ad groups while generating ad templates automatically. Set naming rules and persistent identifiers before a bulk launch so the resulting scale does not produce an untraceable reporting structure.

    1. Create a conversion registry. Give every event a stable identifier, business meaning, customer surface, owner, reportable flag, optimization flag, budget-eligibility flag, and attribution configuration.
    2. Define a campaign taxonomy. Standardize the fields used for market, product group, objective, funnel stage, audience, and experiment. Keep platform IDs even when human-readable names change.
    3. Extract raw data without rewriting its meaning. Preserve native platform fields, IDs, statuses, and timestamps before creating normalized views.
    4. Normalize context explicitly. Apply consistent date boundaries, time zones, currencies, and metric formulas. Retain the raw values so transformations can be audited.
    5. Join operational status data. Add product review states, rejection reasons, account reviews, serving pauses, feed changes, and measurement-setting changes to the campaign timeline.
    6. Reconcile before interpreting. Compare API totals with the platform interface using the same dates, filters, attribution settings, time zone, and account scope. Investigate differences rather than hiding them in a blended total.
    7. Calculate metrics deterministically. Use documented formulas for rates, costs, and rollups. Do not ask a language model to perform the authoritative aggregation from loosely formatted exports.
    8. Generate the narrative last. Give AI the reconciled table, metric definitions, change log, and decision question. Require every recommendation to point back to visible evidence.

    Give the AI a narrow reporting contract

    A useful reporting assistant should distinguish observation from interpretation. Its instructions should require it to use only supplied data, preserve platform definitions, identify missing fields, avoid causal claims from attributed conversions, and state when a proposed action depends on an unverified setting.

    Require each generated finding to contain:

    • Observation: The measured change, including its scope and comparison.
    • Evidence: The exact metrics, dimensions, statuses, and time period supporting the observation.
    • Interpretation: A plausible explanation clearly labeled as an inference.
    • Measurement limits: Attribution, availability, eligibility, or data-quality constraints that could change the reading.
    • Action: A reversible next step tied to the original decision.
    • Validation condition: What must be checked before the recommendation is implemented or expanded.

    This structure prevents polished prose from outrunning the evidence. Attribution tells you how a model assigned credit; it does not establish causal lift. When causality matters, the report should identify the need for an appropriate experiment rather than dressing an attribution result up as proof.

    Run these checks before automating recommendations

    • API and interface totals reconcile under identical filters and settings.
    • Every conversion has separate reporting, optimization, and budgeting flags.
    • Web and app events retain their surface and attribution configuration.
    • Rejected, pending, and approved products are distinguishable.
    • Serving pauses and account, brand, feed, goal, or attribution changes are annotated.
    • Missing and unavailable values remain distinct from zero.
    • Every generated recommendation cites the rows and definitions it relies on.
    • A person with budget authority reviews consequential changes before they are applied.

    Start with one active campaign and complete the conversion registry before rebuilding the dashboard. Put the business meaning, surface, reporting status, optimization status, budget eligibility, and attribution setup beside every outcome. If you cannot complete those fields, the campaign is not ready for automated interpretation. Fix that boundary first; the reporting interface can follow.

    References


  • ChatGPT Ads Strategy: A Practical Framework for Adoption

    ChatGPT Ads Strategy: A Practical Framework for Adoption

    You are probably not deciding whether ChatGPT Ads are interesting. You are deciding whether they deserve budget, which campaigns should fund the test, and how you will know whether the channel is producing customers rather than curiosity clicks.

    The sensible answer is neither a full commitment nor a wait-and-see posture. ChatGPT advertising has enough reach to justify a controlled test, but not enough established practice to justify treating it like a mature replacement for paid search. Your advantage comes from learning the channel without putting proven acquisition at risk.

    Give ChatGPT Ads a specific job in your channel mix

    ChatGPT Ads moved beyond novelty quickly. Six months after launch, 43% of ad-eligible ChatGPT users in the United States had seen an ad. The channel had also reached a $1 billion annualized revenue run rate and attracted tens of thousands of advertisers.

    Those numbers establish adoption, not effectiveness for your business. The underlying data included more than 98,000 ads and 8,000 landing pages, with a U.S. collection of more than 95,000 ads from over 500 advertisers between April 1 and August 16. That is a substantial early view of advertiser behavior, but it remains observational evidence from a channel whose auction, formats, and user habits are still developing.

    Start by assigning the channel one clear role. The best initial role is usually incremental acquisition: reaching a user whose active conversation reveals a relevant need, while leaving your validated search and social programs intact. Google still carries significantly more advertising volume, so moving core search budget before ChatGPT proves comparable business value would exchange known performance for an uncertain learning curve.

    You are ready for a pilot when all of the following are true:

    • You have a product, service, or offer that already converts through a measurable digital path.
    • You can ring-fence an experimental budget without interrupting campaigns that reliably produce revenue or qualified leads.
    • You can create copy specifically for conversational use cases instead of importing a complete Google or Meta campaign unchanged.
    • You have feature, product, or pricing pages that can receive high-intent traffic without a redesign.
    • You can track the business outcome after the click, not just impressions and click-through rate.

    Delay the pilot if you need a new channel to rescue weak unit economics, cannot distinguish qualified conversions from raw form submissions, or have no capacity to produce and evaluate creative variants. A developing platform magnifies those weaknesses; it does not solve them.

    Keep paid placement separate from your AEO and GEO reporting as well. ChatGPT ads remain separate from ChatGPT’s answers. Buying an ad is therefore not evidence that your brand is being cited, recommended, or represented accurately in an organic answer. Paid acquisition and AI-search visibility can support the same business goal, but they are different surfaces with different measurement.

    Build campaigns around conversational intent, not keyword lists

    Three shoppers explore, compare, and select generic products along a pathway connected by blank speech-bubble shapes.

    A search ad usually responds to a compact query. A ChatGPT ad can appear beside a conversation containing a problem, constraints, comparisons, objections, and signs of purchase intent. That richer context changes the creative brief.

    Ad selection can use the context and intent of the conversation, the landing page, the creative, and context hints supplied by the advertiser. Treat those elements as one system. If the use case implied by your creative conflicts with the destination page, adding more variants will only distribute the mismatch more widely.

    Write a campaign brief in this order:

    1. Conversation use case: describe what the person is trying to accomplish, such as comparing plans, checking whether a feature fits a requirement, or understanding the cost of an option.
    2. Decision stage: state whether the person is exploring the problem, validating a shortlist, or preparing to act.
    3. Immediate question: write the question your ad must answer or help resolve at that moment.
    4. Promise: identify the useful next step you can honestly offer, without pretending the ad is part of the assistant’s answer.
    5. Proof: choose the product detail, capability, price information, or other evidence that supports the promise.
    6. Destination: send the click to the page that completes that exact thought.

    This process prevents a common failure: targeting a relevant conversation with generic brand copy. Relevance is not simply being in the right category. Your message must connect the user’s current task to a concrete next action.

    Native creative is already a distinguishing behavior among active advertisers. Leading advertisers created 98% new copy for ChatGPT instead of recycling copy from other platforms. Advertisers with more creative variations also tended to capture more impression share, although no fixed number of ads emerged as the correct target. Half of the top 10 advertisers were running more ads on ChatGPT than on Meta.

    Do not read that as an instruction to maximize asset count. It is a reason to build a controlled variation system. Create a matrix with conversation use case on one axis and message angle on the other. An angle might emphasize a feature, pricing clarity, suitability, or the next action. Every variant should have a named hypothesis, so you know what you learned when performance changes.

    For the cleanest initial test, compare ChatGPT-native copy with your best imported baseline while keeping the offer and landing page constant. If the native version wins on meaningful downstream outcomes, test the next variable. Changing the audience logic, message, offer, and destination simultaneously may produce a winner, but it will not tell you why it won.

    Keep the landing-page plan deliberately narrow

    You do not need a new microsite before you can learn anything. Feature, pricing, and product pages are the most common destinations, and most advertisers use five or fewer landing pages. Existing high-intent pages are the practical place to begin.

    Choose the destination by message match, not by internal importance. A pricing promise belongs on a page where the visitor can understand pricing. A feature claim belongs on a page that explains the feature and its relevant constraints. A product comparison message needs a destination that helps the visitor evaluate the choice. The homepage should not be the automatic fallback simply because it represents the whole brand.

    Audit each candidate page against the ad before launch:

    • The opening screen continues the promise made in the ad instead of forcing the visitor to rediscover the topic.
    • The relevant product, feature, or pricing information is easy to find without navigating through unrelated sections.
    • The primary action matches the visitor’s likely stage, whether that is viewing plans, starting a purchase, requesting a demonstration, or contacting the business.
    • The page provides enough evidence to evaluate the claim made in the creative.
    • Campaign parameters distinguish ChatGPT traffic, creative, use case, and destination in your analytics.
    • The conversion event passes through to the system where revenue or lead quality can be evaluated.

    Five landing pages is an observed pattern, not a recommended quota. Use fewer if one page serves several tightly related messages without becoming vague. Build a dedicated page only when an existing destination cannot continue the ad’s promise cleanly or when isolating a distinct offer is necessary for measurement.

    This restraint matters because an oversized page plan creates two problems at once. It consumes production time before you know which conversation use cases deserve investment, and it spreads early conversion data across too many destinations. Start concentrated, identify where the signal is real, and then build around demonstrated gaps.

    Measure the pilot as a decision system, not a traffic report

    An analyst observes light particles moving through a transparent series of checkpoints toward a final outcome block in a tabletop testing apparatus.

    Click-through rates have doubled since the channel launched. That indicates improving interaction as the platform and advertisers learn, but a relative increase is not an account-level forecast. It does not tell you what acquisition cost, conversion rate, lead quality, or revenue your campaign will produce.

    Before spending, write down the decision the test is meant to support. Define the primary business outcome, your existing acquisition ceiling for that outcome, the attribution window you will use, and the minimum tracking quality required to trust the result. Use the same conversion definition as the adjacent channel you intend to compare against. Otherwise, a cheap ChatGPT lead and a qualified paid-search lead may look equivalent when they are not.

    Read the funnel in sequence

    Do not optimize every metric in isolation. Read each signal as evidence about a different part of the system:

    Observed patternLikely issue to investigateNext action
    Eligible delivery but weak click-throughThe use case, opening message, or value proposition may not fit the conversational moment.Revise the intent-to-message pairing before changing the landing page.
    Clicks but weak on-page engagementThe page may not continue the ad’s promise clearly.Align the opening content and primary action with the creative while holding the audience logic steady.
    Conversions but poor lead quality or revenueThe promise may attract the wrong buyer, or the conversion event may be too shallow.Tighten the claim and context hints, then evaluate a deeper business outcome.
    Acceptable economics across distinct creative and use-case combinationsThe result may be durable enough for controlled expansion.Add an adjacent use case or creative angle while preserving the winning combination as a control.

    Treat conversational timing as a variable

    Ads appearing in the first few turns of a conversation produce the strongest click-through rates and impression share. Conversations can continue well beyond those exchanges, so later placements still represent a longer tail of opportunity.

    The important distinction is between an observed performance pattern and a placement control. Do not promise an early-turn strategy until you have confirmed which timing controls and reporting fields are actually available in your account. If conversation-stage reporting is available, segment it. If it is not, avoid attributing a result to timing that you cannot observe.

    Early-turn creative should make the value of the next step immediately legible because the user’s requirements may still be broad. A later-stage message can be more specific when the surrounding context indicates comparison or validation. Keep those hypotheses separate in your campaign naming so a blended average does not conceal the difference.

    Set promotion and stop rules before the launch

    Promote the pilot toward a recurring budget only when conversion quality and acquisition economics meet your existing standard across distinct creative and use-case combinations. Rising CTR alone is not enough. Neither is one unusually valuable conversion that distorts a small sample.

    Pause and diagnose when tracking is incomplete, downstream quality cannot be verified, or additional creative produces reach without improving business outcomes. This protects you from scaling activity simply because the platform is growing. The adoption question is not whether other advertisers are arriving. It is whether your account has found a repeatable path from conversational intent to profitable action.

    FAQ: what the early adoption numbers do not prove

    Does broad ad exposure mean ChatGPT users are ready to buy?

    No. Exposure proves that the platform can distribute ads to a meaningful share of eligible users. Purchase intent still depends on the conversation, offer, creative, product, and destination. Use reach to justify testing, not to forecast sales.

    Should you move budget out of Google or Meta to fund the test?

    Not by default. Fund ChatGPT Ads as an incremental experiment until it meets the same business standard as the channel whose budget it would replace. If you must reduce another campaign, understand that you are giving up measured acquisition to buy learning in a less mature environment.

    Does buying ChatGPT Ads improve organic visibility in answers?

    Ads and answers are separate. Do not present paid impressions as answer citations, brand recommendations, or proof of GEO performance. Maintain separate dashboards for paid ChatGPT acquisition and organic AI visibility, even when both contribute to the same customer journey.

    Your next move is straightforward: choose one measurable business outcome, map the conversations that can lead to it, create native messages, and send them to the smallest useful set of high-intent pages. Keep the campaign experimental until the downstream economics earn a larger role.

    References


  • Holiday Display Ad Costs: A Practical 2026 Budget Plan

    Holiday Display Ad Costs: A Practical 2026 Budget Plan

    You are deciding whether to spend before Black Friday or preserve your display budget for the peak shopping period. The 2026 cost signal supports an early move, but for a specific purpose: buy less expensive prospecting reach, learn which value proposition works, and build audiences you can approach again when purchase intent strengthens.

    That is not a reason to spend simply because impressions are cheaper. CPM is only the price of access to an audience. If cautious shoppers ignore the offer, inexpensive exposure can still produce expensive customers. Your budget plan therefore needs two controls: one for media cost and another for commercial results.

    Read the 2026 cost drop as an opportunity, not a forecast

    AdRoll activity from July 1 through September 8 showed a pronounced decline in display pricing. Prospecting CPMs were 45% lower year over year and 25.5% below the comparable Q2 period. Retargeting CPMs were 29.1% lower year over year and 40.2% below the comparable Q2 period.

    Display activityYear-over-year CPM changeChange from comparable Q2 periodWhat it means for your plan
    Prospecting45% lower25.5% lowerTest new audiences and messages before peak competition intensifies.
    Retargeting29.1% lower40.2% lowerReconnect with known visitors, but let the size and quality of your audience limit spending.
    Account-based marketing4.4% higher15.1% lowerBudget against the value of named accounts rather than broad-market CPM trends.

    These figures describe relative changes, not a universal dollar price for holiday inventory. They do not tell you the CPM your account, audience, placement, geography, or buying platform will receive. Treat them as a directional benchmark for the AdRoll activity captured during that period, then compare the signal with your own live auction prices.

    The timing matters too. A decline measured before the holiday rush does not guarantee that inventory will remain inexpensive around Black Friday or Cyber Monday. Competition can intensify as more advertisers enter the auction. The useful conclusion is that an early testing window may exist, not that peak-period media has become permanently cheaper.

    Demand conditions also point in two directions. U.S. inflation held at 3.4% in August, while the University of Michigan consumer sentiment index fell to 47.8 in September, 13.2% below its year-earlier level. At the same time, Bank of America card activity showed August spending per household increasing 4.5% year over year, with shoppers favoring value-oriented and big-box retailers.

    That combination does not prove that every category will enjoy strong holiday demand. It does tell you why cheap reach and difficult conversion can coexist. People may continue spending while becoming more selective about the merchant, product, price, and promotion that earns the purchase.

    Key takeaways

    • The clearest 2026 cost opportunity is pre-peak prospecting: use it to learn and build qualified audiences, not merely to accumulate impressions.
    • Lower CPM does not automatically lower customer acquisition cost. Conversion rate and contribution per order still determine whether the campaign is economically sound.
    • Keep prospecting, retargeting, and account-based marketing separate in both reporting and budget decisions because they reach different audiences and perform different jobs.
    • Make value visible in the ad and on the landing page. A vague brand message asks a cautious shopper to do too much interpretive work.
    • Do not treat pre-holiday CPM declines as a Black Friday price guarantee. Preserve budget for peak demand and release it only when current results meet your commercial rule.

    Protect conversion economics before buying more reach

    An analyst adjusts a funnel as many tokens enter near generic ad tiles and only a few emerge beside shopping parcels.

    CPM answers one narrow question: how much did you pay for 1,000 impressions? The basic relationship is straightforward: impressions purchased equal media spend divided by CPM, multiplied by 1,000. When CPM falls, a fixed budget can buy more impressions.

    That calculation says nothing about how many viewers were suitable prospects, visited the site, understood the offer, or purchased. Customer acquisition cost answers a different question: how much media spend was required for each attributable new customer? If your CPM declines while the purchase rate declines by more, acquisition cost can rise. Scaling on CPM alone can therefore turn cheaper inventory into a larger unprofitable campaign.

    Set the commercial limit before you increase the budget. For an ecommerce campaign, that normally means defining the maximum acquisition cost the order can support after the discount and variable costs are considered. For a longer B2B sale, define the lead or opportunity outcome you are willing to fund. Do not substitute impressions, clicks, or an unqualified form submission for that outcome merely because those numbers arrive faster.

    Your holiday display scorecard should separate four layers:

    • Delivery: spend, CPM, impressions, unique reach, and frequency.
    • Response: landing-page visits and the qualified action that indicates genuine interest.
    • Commercial outcome: purchases or qualified leads, conversion rate, acquisition cost, revenue, and contribution after the promotion.
    • Audience status: new prospects, previous visitors, existing customers, and purchasers who should be excluded from acquisition messaging.

    Use the same attribution window and outcome definition whenever you compare tests. Also compare like with like. A warm retargeting audience should usually behave differently from people encountering the brand for the first time, so a blended account average can hide weak prospecting behind strong retargeting results.

    Build the holiday budget in stages

    A staged budget lets you use the inexpensive window without assuming that the same economics will survive at greater scale or during peak competition.

    1. Establish your own baseline. Pull the most comparable recent campaigns and separate prospecting, retargeting, and ABM. Record their CPM, frequency, conversion rate, acquisition cost, offer, creative, landing page, and attribution settings. This is the benchmark that matters when a broad market trend does not match your account.
    2. Fund an early prospecting test. Use the lower observed prospecting cost to compare audiences and value messages before the holiday auction becomes more crowded. Change one major promise at a time so you can identify why one version performed differently.
    3. Build a usable retargeting audience. Send qualified prospects to a page that continues the ad’s promise. Segment visitors by meaningful behavior where your platform and consent setup permit it, and exclude purchasers from acquisition ads. Cheap retargeting CPM is not useful if the underlying audience is tiny, poorly matched, or already converted.
    4. Release more budget only after a commercial signal. Scale an audience-message pair when it remains within your acceptable acquisition cost or lead economics. If CPM is attractive but the downstream outcome misses the rule, revise the audience, offer, creative, or landing page before increasing spend.
    5. Keep a peak-period reserve. Do not commit the entire seasonal budget at pre-peak prices. Hold enough flexibility to support proven combinations when shopper intent strengthens, while recognizing that the auction price may also rise.

    This approach avoids two common errors. Waiting until peak week forces you to pay for learning when competition may be stronger. Spending the full budget early assumes that cheap awareness is as valuable as high-intent demand. The staged plan buys learning first and scale second.

    Match each buying method to the job it can do

    A media planner directs budget tokens toward three different ad-buying stations connected to blank display placements.

    Use prospecting to discover demand

    Prospecting is the clearest place to use the early cost decline. Its job is to reach people who have not yet demonstrated interest, identify promising audience-message combinations, and supply qualified visitors for later campaigns. Evaluate it on both audience quality and the downstream customers it creates. Do not demand the same immediate conversion rate as retargeting, but do not excuse it from commercial accountability either.

    Let retargeting audience quality control the budget

    Retargeting reaches people who have already visited or interacted, which is why it should be reported separately. The 40.2% decline from the comparable Q2 period creates an appealing cost environment, but the available spend is constrained by the number of qualified people in the audience. Raising the budget against a small pool can increase repetition instead of finding more buyers. Watch reach and frequency together, and stop serving acquisition messages to people who have already purchased.

    Judge ABM by account value, not the broad display trend

    Account-based marketing moved differently, with CPMs rising 4.4% year over year even though they were 15.1% below the comparable Q2 period. ABM targets narrower groups of named accounts, so its pricing is not a reliable proxy for the wider display market. Use it when the potential account value and sales process justify concentrated exposure. A cheap broad-reach CPM is not a reason to replace that account strategy, and a higher ABM CPM is not evidence that it has failed.

    Whatever buying method you choose, make the value proposition easy to verify. State what is being offered, who it is for, what the price or promotion requires, and why the product deserves consideration. Carry the same terms onto the landing page. If a discount requires a code, minimum purchase, or limited eligibility, reveal that condition before the visitor reaches checkout. Hidden conditions may improve the apparent click response while weakening trust and conversion.

    Test meaningful differences rather than cosmetic variations alone. Compare a price-led message with a benefit-led message, or a general promise with a category-specific one, while keeping the audience and measurement settings stable. The goal is to learn which reason to buy survives beyond the impression and produces the outcome your budget needs.

    Before adding another dollar, separate your recent results by buying method and write the acceptable acquisition cost or lead outcome beside each one. Then fund the smallest pre-peak test that can produce a clear decision. Increase the combinations that satisfy that rule; change or stop the ones that merely deliver inexpensive impressions.

    References