Category: Advertising

  • Google Ad Tech Antitrust Oversight: A Publisher Action Plan

    Google Ad Tech Antitrust Oversight: A Publisher Action Plan

    If you publish content and depend on programmatic advertising, the practical question is whether you can reach AdX demand without centering Google’s publisher ad server in your stack. A federal court has ordered that path to be opened. Whether it improves your revenue, control, or costs still has to be proved in your own environment.

    Google’s ad tech business is not being broken apart. The remedy instead combines interoperability requirements, data sharing, restrictions on lock-in, and six years of court supervision. That gives you a reason to test alternatives, but not a reason to migrate blindly.

    What the court changed in Google’s ad tech stack
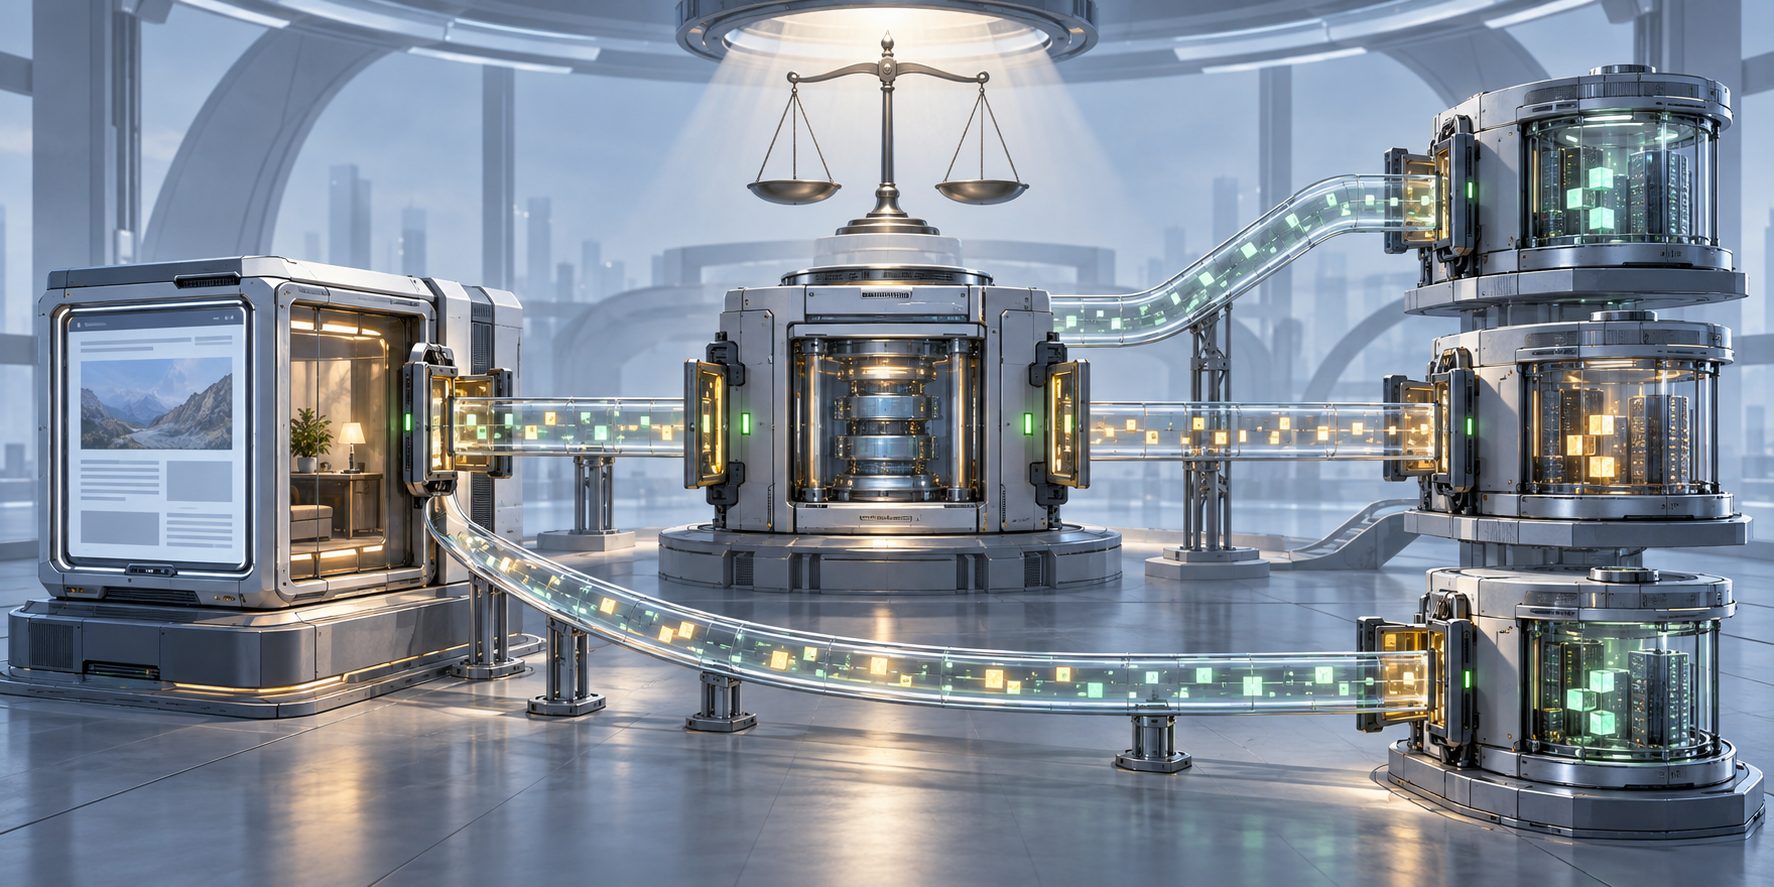
    Separate ad server and advertising exchange modules are connected by multiple open pathways beneath a balance scale.

    U.S. District Judge Leonie Brinkema found that Google had monopolized the publisher ad-server and ad-exchange markets. The remedy focuses on loosening the connections between those two parts of the advertising supply chain.

    Court-ordered changeDecision it may enableWhat you need to verify
    Rival publisher ad servers must be able to access AdX real-time bidsKeep or adopt a non-Google ad server while considering AdX demandSupported inventory, bid timing, implementation requirements, reporting, and fees
    Publishers using Google’s ad server cannot be required to use AdXEvaluate the ad server and exchange as separate purchasesWhether contracts, defaults, incentives, or workflows still make separation costly
    Practices that locked publishers into Google’s tools must endMove components of the stack without replacing everything at onceMigration support, termination terms, data portability, and operational dependencies
    Google must meet new data-sharing requirementsCompare auction behavior and performance with better informationFields supplied, granularity, delivery cadence, retention, and export rights

    The court declined to force a sale of AdX or another ad tech component because it considered structural remedies unnecessary and impractical. It concluded that behavioral restrictions could restore competition and stop a return to the conduct at issue. That is a meaningful distinction: the remedy changes how Google must operate, not who owns the infrastructure.

    Google must also appoint an antitrust compliance monitor. The remedies remain in force for six years, rather than the 15 years sought by federal and state enforcers, and the monitor has less authority than the Justice Department requested. You should therefore treat this as a supervised window for competition, not a permanent guarantee that every market friction will disappear.

    Key takeaways for publishers and advertising teams

    • Interoperability is the remedy, not the business outcome. Access to AdX bids can make another ad server more viable, but it does not guarantee higher yield, lower fees, or easier operations.
    • The most immediate opportunity is procurement leverage. You can ask vendors to price and document the ad server, exchange access, data access, and migration support separately.
    • A full-stack replacement should not be your first test. Start with a reversible inventory segment so that an integration problem cannot put all advertising revenue at risk.
    • Net performance matters more than the headline bid. Measure revenue after fees alongside fill, latency, reporting discrepancies, and staff time.
    • This is an ad tech remedy, not a search update. It does not by itself change organic rankings, indexing, structured data, AI citations, or eligibility for AI-generated search features.

    Turn the remedy into a controlled testing plan
    A publishing team compares two isolated ad delivery setups on a controlled testing bench.

    The order creates optionality. Your job is to determine whether that optionality produces a better result for your inventory. Build the evaluation before a contract renewal or migration deadline leaves you with only one practical choice.

    1. Record a baseline with stable definitions. Capture eligible impressions, bid participation, fill, gross revenue, net revenue after identifiable fees, page latency, reporting discrepancies, and operational hours. Keep the calculation method fixed so a vendor cannot appear better merely because it defines an impression or fee differently.
    2. Map the dependencies around the publisher ad server. List exchange connections, direct campaigns, identity tools, consent signals, creative review, forecasting, billing, analytics exports, and any custom automation. A component can be contractually separable while remaining expensive to replace because several workflows depend on it.
    3. Define success and failure before seeing results. Decide which metrics cannot deteriorate, which improvements would justify migration work, and which implementation costs count against the result. Include rollback triggers for material revenue loss, latency increases, missing consent signals, or inconsistent reporting.
    4. Request the new access path in writing. Ask each vendor to describe exactly how AdX real-time bids are passed to a rival publisher ad server, what inventory is supported, which data accompanies the bid, and which limitations remain. A statement that access is available is not an implementation specification.
    5. Run a reversible pilot. Use a defined inventory cohort that is large enough to evaluate but small enough to protect the wider business. Compare similar traffic and account for known changes in geography, device mix, content, and demand conditions. Do not move the entire stack on the strength of a sales demonstration.
    6. Evaluate the operating cost as well as auction results. Count troubleshooting, reconciliation, manual trafficking, vendor coordination, and delayed reporting. A small revenue gain can disappear when the alternative requires substantially more staff time.
    7. Carry verified findings into renewal negotiations. Separate requests for ad serving, exchange demand, data, support, and migration. Preserve export and termination rights so that a successful pilot can become a real choice rather than a temporary experiment.

    If a proposed change affects termination rights, exclusivity, data ownership, or material revenue commitments, have qualified counsel review the relevant contract language. The operational goal is to preserve a safe test and a workable exit, not to interpret the antitrust judgment as modifying your individual agreement automatically.

    Questions that expose whether access is genuinely usable

    The useful question is not simply whether a rival ad server can receive AdX bids. You need to know whether it can do so on terms that support a reliable auction, accurate measurement, and a commercially sensible workflow.

    Connectivity and auction behavior

    • How does the AdX real-time bid reach the rival publisher ad server, and which system makes the final auction decision?
    • Which inventory formats, account types, devices, and markets are supported?
    • What technical prerequisites, certifications, minimums, or configuration changes apply?
    • Which timestamps and identifiers are available for diagnosing bid timing, timeouts, and discrepancies?
    • What happens during an outage or degraded connection, and can the publisher configure a fallback?
    • Can the setup be piloted on selected inventory without changing the rest of the stack?

    Data, fees, and contractual control

    • Which auction and reporting fields will be shared, at what level of detail, and how quickly?
    • Can the publisher export the data in a reusable format, and what retention limits apply?
    • Which fees are charged by the exchange, ad server, integration provider, or reseller?
    • Are support, migration, reconciliation, or data access billed separately?
    • Does any discount, default, or bundle make independent selection economically difficult even when it is technically permitted?
    • What notice, termination, data-return, and transition-assistance terms apply if the test fails?

    Put the answers into the test plan and contract rather than leaving them in a presentation. The compliance monitor will oversee Google’s adherence to the final judgment, but that role does not replace your technical acceptance criteria, revenue controls, or vendor accountability.

    Keep ad tech oversight separate from search and AI visibility

    For SEO, AEO, and GEO teams, the central mistake would be to turn this antitrust remedy into a forecast about organic discovery. The requirements concern Google’s publisher ad server and ad exchange. They do not establish a change to crawling, indexing, ranking systems, AI answers, structured data processing, or citation selection.

    Keep two roadmaps. The monetization roadmap should track vendor access, auction data, fees, pilots, and contract flexibility. The search visibility roadmap should continue to track technical accessibility, content quality, entity clarity, structured data, citations, and measurable search or AI referral behavior. A development can matter to the economics of publishing without changing how a page is discovered.

    Advertisers on the demand side should be equally precise. Because the remedy targets publisher-side markets, do not assume that a campaign interface, targeting option, or buying workflow has changed. Ask agencies and technology providers to identify the exact supply-path, reporting, or fee change they are relying on before revising a media plan.

    Your best next move is deliberately practical: create a one-page performance baseline, map every dependency on the current ad server, and send the implementation questions above to vendors before the next renewal discussion. Six years of oversight creates time to build alternatives, but only measured, contractually usable alternatives give you leverage.

    References


  • Pinterest Visual Search Ads: A Practical Campaign Guide

    Pinterest Visual Search Ads: A Practical Campaign Guide

    You do not need another Pinterest campaign type simply because it exists. You need to know whether someone who has not named your product yet can recognize it visually, click it, and reach a page that confirms the same choice.

    That is the practical case for Pinterest Visual Search Ads. The query is partly an image, the ad competes during product exploration, and the landing page has to continue the comparison without introducing doubt. Here is how to decide whether the format fits your catalog, design a useful test, and connect the resulting insights to your wider search and AI visibility strategy.

    Visual Search Ads change what counts as a query

    A conventional search ad responds to words. A visual search placement can respond to the object, style, color, setting, or product relationship visible on the screen, while still considering keywords.

    Pinterest Visual Search Ads can appear in Pinterest Search Results and Pin closeups, combining keyword relevance with Pinterest’s visual understanding of images, products, and intent. Advertisers can bid for a prominent response and send the shopper directly to their website.

    This does not make keywords obsolete. It makes them one part of a richer signal. Someone may type a broad phrase, open an image that reflects the desired look, and then compare visually similar options. Your ad has to make sense in that sequence even when the shopper has not supplied an exact product name.

    For the marketer, the job changes in three ways:

    • The product’s appearance must communicate the quality that makes it relevant. A hidden benefit cannot do all the work at the impression stage.
    • The promoted product must fit the visual idea being explored, not merely share a broad category or keyword.
    • The destination page must preserve the image, variant, context, and offer that earned the click.

    Pinterest reports more than 80 billion searches per month, with the vast majority described as visual and more than half as commercially oriented. Those are platform-supplied scale figures, not a forecast for your account. Commercial intent can mean researching, comparing, saving, or buying. Your test still has to determine which of those behaviors produces economic value for you.

    The format is designed for lower-funnel objectives and can work with Pinterest Performance+, but “lower funnel” should not be read as “ready to purchase immediately.” The useful opportunity is to enter the decision while the shopper is narrowing the look, product, or category they want.

    Decide whether the format deserves a test

    The first qualification is not whether your brand has attractive images. It is whether a visible characteristic carries meaningful buying intent.

    A quick fit test

    Visual Search Ads are worth evaluating when most of the following are true:

    • People can distinguish relevant choices through visible attributes such as form, finish, pattern, silhouette, layout, color, or use context.
    • Your catalog contains products that are close enough to a shopper’s inspiration to satisfy the same need, rather than merely belonging to the same department.
    • Your product pages can open on the exact item or variant represented in the ad.
    • You can measure activity beyond impressions and saves, including qualified site visits and business outcomes.
    • Your team can isolate a product group, creative question, or targeting question instead of changing the entire account at once.
    • Your commercial model can support paid traffic while shoppers are still comparing options.

    Delay the test if the catalog is frequently out of stock, the advertised visual leads to a generic category page, or the decisive benefit is almost entirely invisible and difficult to establish on the landing page. Visual reach will not repair a broken handoff.

    Access is another qualification. Pinterest announced the format for beta rollout to eligible advertisers across its advertising markets. That wording does not guarantee that every account has the feature. Confirm availability in your account or with your Pinterest contact before building a launch schedule around it.

    Key takeaways

    • A visual query adds image-based intent; it does not eliminate keyword relevance.
    • The strongest test candidates are products whose visible attributes affect the purchase decision.
    • Creative, product selection, and landing-page continuity should be planned as one system.
    • Beta access is a reason to run a controlled experiment, not a reason to assume a new source of profitable scale.
    • Platform engagement is useful diagnostic evidence, but conversion and incremental business value should determine whether you expand the campaign.

    Build the campaign around visual continuity

    The same sage-green lounge chair appears in a styled room, a visual discovery result, and a tablet product page with consistent imagery.

    A good first campaign answers one commercial question. It should not attempt to prove that visual search works for every product, audience, creative style, and objective at the same time.

    1. Write the test claim before configuring the campaign. For example, you might test whether product-focused imagery or contextual imagery attracts visitors who are more likely to reach a product decision. Phrase the claim so the result can change what you do next.
    2. Select a coherent product group. Organize it around the visual decision the shopper is making, not merely your internal merchandising hierarchy. Products grouped together should solve a similar need and present a recognizable visual relationship.
    3. Audit product readiness. Confirm that the selected items have usable inventory, commercially acceptable economics, accurate offer information, and destination pages that represent the promoted variants.
    4. Prepare creative that reveals the decision-relevant attribute. A styled scene can establish context, while a clear product view can establish detail. Use variations to answer a defined question rather than producing arbitrary volume.
    5. Match each ad to the closest useful destination. The image, product name, variant, price, availability, and primary promise should not appear to change after the click.
    6. Record the baseline and decision rule. Identify the existing campaign, product group, or traffic source that will serve as the comparison. Decide which primary outcome would justify expansion and which guardrails would stop it.

    The fourth and fifth steps are where many otherwise promising tests fail. An image can earn attention because of one finish, arrangement, or style, only for the destination to foreground a different variation. The visitor then has to reconstruct the connection that the ad should have preserved. That friction will often appear as weak post-click performance rather than an obvious creative error.

    Use Priority Products as a business constraint

    Performance+ is also gaining a feature called Priority Products, which lets advertisers emphasize selected products for seasonal launches, promotions, or category pushes while retaining automated optimization.

    If the option is available in your account, use it to communicate a genuine merchandising priority. A new launch, a promotion, or a strategically important category can justify preference. Do not use it to force weak products into delivery merely because an internal team wants exposure. Product priority directs automation; it does not turn an unsuitable item into a strong response to visual intent.

    Keep a written record of why each item was prioritized. That lets you separate a platform-learning problem from a business constraint later. If performance is weak, you will know whether the system chose the product freely or whether your instruction narrowed its choices.

    Measure the test without mistaking activity for impact

    An overhead desk scene compares two visual shopping paths, one ending with interaction tokens and the other continuing to a basket and packed parcel.

    Visual discovery naturally produces intermediate behavior. People inspect, compare, and save. Those actions can explain what is happening, but they are not interchangeable with revenue.

    Pinterest is introducing self-serve A/B testing for creative and targeting, including within Performance+. When that capability is available, use it to isolate one decision at a time. Compare creative in one test and targeting in another. Changing both at once may produce a winner without revealing why it won.

    A practical scorecard should move from delivery to business value:

    QuestionSignals to inspectWhat the result should change
    Did the campaign reach the intended product opportunity?Delivery by planned product group and creative variationIf delivery concentrates on the wrong items, revise the product scope or priority instructions before judging the format.
    Did the visual match create qualified interest?Outbound clicks, landing-page arrival, product engagement, and progression toward a purchase actionIf the ad earns attention but the visit ends quickly, inspect visual and offer continuity before increasing spend.
    Did the interest produce commercial value?Conversions, acquisition cost, revenue, and return on ad spend using consistently defined attributionIf engagement rises without acceptable business outcomes, treat the campaign as a learning result rather than a scaling result.
    Did the campaign add value beyond activity you would have received anyway?Incrementality evidence from a suitable holdout, geographic comparison, or other controlled method where feasibleIf only platform-attributed results are available, label that limitation instead of presenting attribution as proven lift.

    Choose the primary metric before reviewing the outcome. Otherwise, a disappointing conversion test can quietly become a successful engagement test after the fact. Supporting metrics should explain the primary result, not replace it.

    Keep the product scope, landing experience, and measurement definitions stable during a comparison. If a promotion, inventory change, tracking update, or site redesign occurs during the test, record it. Those events can alter the result without saying anything meaningful about visual search.

    Do not borrow performance claims from adjacent Pinterest products. A result associated with an app-install objective, for example, is not evidence that Visual Search Ads will produce the same improvement for an ecommerce purchase campaign. Each format, objective, and business model needs its own baseline.

    Use paid-search learning to improve broader discoverability

    Visual Search Ads are not a shortcut to SEO, answer engine optimization, or generative engine optimization. They can, however, expose the visual language people use before they know the precise words for a product.

    Pinterest Intelligence is designed to interpret images, products, tastes, and intent. Do not jump from that fact to the assumption that adding more keywords to image fields or Product JSON-LD will improve an ad auction. No direct relationship of that kind has been established. Keyword stuffing also makes product information less useful to people and other systems.

    Instead, turn campaign learning into a disciplined content workflow:

    1. Record the visible attribute, use context, or product relationship represented by each meaningful creative variation.
    2. Compare attention with downstream behavior. A visual theme deserves broader use only when it attracts the right visitor and supports the intended business outcome.
    3. Reflect validated language in the appropriate page elements: clear product names, visible variant descriptions, useful category copy, concise accessibility-focused alternative text, and customer-facing answers about fit or use.
    4. Keep Product structured data accurate and consistent with the visible page where it applies. Mark up the real product and offer; do not treat schema as a hidden advertising copy field.
    5. Separate channel-specific findings from durable customer language. A concept that performs inside Pinterest may inspire a content test elsewhere, but it does not automatically predict Google rankings or inclusion in an AI-generated answer.

    This is where paid visual discovery can contribute to an SEO and GEO program without overclaiming. It gives you evidence about how people recognize and compare products. Your site can then explain those products more clearly in text, imagery, page structure, and structured data. Clarity helps users and gives search and AI systems cleaner information to interpret, but it is not a guarantee of visibility.

    Your first move should be small and concrete. Choose a coherent product set, identify the visible characteristic that carries buying intent, audit the Pin-to-page handoff, and write one testable commercial question. If you cannot define the comparison or measure the outcome, wait. If you can, the beta becomes a way to learn whether visual intent is profitable for your catalog rather than another placement competing for unexamined budget.

    References


  • Agentic Ecommerce: A Playbook for Discovery and Advertising

    Agentic Ecommerce: A Playbook for Discovery and Advertising

    If your product pages rank and your ads are live, but your products still disappear from AI-guided shopping conversations, the missing layer is usually not more promotional copy. It is decision-ready product data: facts an agent can retrieve, compare, explain, and carry into checkout.

    Your goal is no longer just to win a click. You need to help an AI determine whether a specific product fits a specific buyer’s constraints, answer the next question accurately, and make the handoff to your store without changing the facts along the way.

    The shopping funnel now contains a conversation

    A conventional product ad asks the shopper to click before learning much. A conversational ad can answer questions about fit, compatibility, features, availability, or policies inside the discovery surface. ChatGPT is testing clearly labeled Sponsored Agents that open a separate brand conversation, while Google’s Business Agent is being tested inside YouTube ads for eligible U.S. retailers.

    That changes the intermediate step, not the buyer’s underlying job. People still need to eliminate unsuitable choices, understand tradeoffs, and trust the terms of the purchase. The difference is that an agent may now perform part of that evaluation before the shopper reaches your product page.

    Do not collapse every appearance in AI into one visibility metric. There are three distinct outcomes:

    • Citation: your content supplies an explanation or fact used in an answer.
    • Recommendation: your brand enters the suggested set for a category or use case.
    • Selection: a particular product is matched to the shopper’s stated requirements and advanced toward purchase.

    Each outcome requires different work. Clear, retrievable content helps with citation. Consistent brand context supports recommendation. Complete product attributes, current commercial data, and a usable transaction path support selection. This is why LLM readability, brand context, and agentic commerce are separate optimization disciplines, even when one team owns all three.

    Do not fund this shift by abandoning traditional search. An Ahrefs-based measurement found AI Overviews on 24% of shopping queries on Sept. 3, 2026, but a Datos panel of more than 10 million desktop users measured dedicated AI Mode at only about 0.13% of web traffic. A separate panel of 75 ecommerce stores, mostly producing $1 million to $20 million in annual revenue, still placed non-branded organic search second only to paid search for revenue. The practical response is a parallel search and AI strategy, not a wholesale channel migration.

    Build a product record an agent can safely choose

    An unbranded hiking shoe is surrounded by organized visual layers representing its materials, size, fit, availability, shipping, and return details.

    An agent cannot reliably recommend what it cannot distinguish. A polished category description will not compensate for missing variant measurements, ambiguous compatibility, stale availability, or different prices in the feed and on the page.

    For every product and variant you want an agent to select, create one canonical record with five layers:

    • Identity: product name, brand, category, model, SKU or other applicable identifiers, plus the exact relationship between parent products and variants.
    • Transaction truth: price, currency, condition, availability, fulfillment choices, shipping terms, returns, warranty, and any eligibility rules for discounts or member pricing.
    • Decision attributes: dimensions, materials, fit, capacity, supported devices or systems, care requirements, included components, and other facts buyers use to rule products in or out.
    • Evidence and instructions: manuals, size charts, compatibility tables, policy pages, certifications when applicable, and factual answers to recurring pre-purchase questions.
    • Destinations: the correct product page, variant URL, cart action, policy page, or support handoff for each answer.

    Publish the same facts through the channels machines use: visible page content, merchant feeds, platform catalog integrations, and Product and Offer structured data where applicable. JSON-LD should be generated from the same commerce data as the page and feed. Treating schema as a separate copywriting exercise creates exactly the contradictions an agent should not have to resolve.

    Run a variant-level consistency check before activating an agent or campaign. Compare title, identifier, price, currency, availability, shipping, return terms, and the primary decision attributes across the page, feed, structured data, and commerce API. If a field is genuinely unknown, leave it unknown and define a safe fallback. Do not let the agent infer compatibility, delivery, or warranty coverage from adjacent products.

    Product copy still matters, but it should answer rather than decorate. Put the direct answer first, then the explanation, supporting evidence, and relevant conditions. Keep each FAQ block focused on one buyer question so it can be retrieved without unrelated text changing its meaning.

    The commercial case for this cleanup is promising but should not be overstated. Google reports that merchants following its core Merchant Center feed practices see an average 5% conversion increase in the following month. In a Lululemon test, retailer-supplied conversational attributes were incorporated in 50% of relevant AI Mode product recommendations. These are platform-reported results, not guaranteed lifts. Their useful lesson is narrower: attributes that exist as maintained data can participate in recommendations; facts trapped in campaign copy cannot be depended on in the same way.

    Design conversational ads around the next unanswered question

    A shopper and an abstract AI guide exchange symbol-filled bubbles while narrowing several coffee machines to one suitable choice.

    A conversational ad should not be a chat-shaped version of a display ad. Its job is to resolve the next material uncertainty and route the shopper to the correct action. Build an answer map before you generate creative.

    Buyer questionRequired dataSafe handoff
    Will this fit?Variant measurements, sizing method, and size-chart rulesThe selected variant and relevant size guide
    Will it work with what I own?Supported models, exclusions, required accessories, and version limitsThe compatible variant or compatibility table
    What will I actually pay?Current price, currency, shipping terms, and applicable member benefitsA cart with the same disclosed terms
    Can I get it when and where I need it?Live inventory and available fulfillment methodsThe available purchase or pickup path
    What if it is unsuitable?Return window, condition requirements, exclusions, and warranty termsThe relevant policy section or support route

    For each row, define an answer contract: the approved system of record, the claims the agent may make, the data that must be checked live, the fallback when data is unavailable, and the destination that preserves context. A useful fallback is specific: state which fact cannot be confirmed and direct the shopper to the place or person that can confirm it. A confident guess is not customer service.

    AI can also compress campaign production. ChatGPT Work’s Ads Manager plugin can create, update, and analyze campaigns from natural-language instructions; its assistance can propose copy and imagery from a landing page and campaign objective. Optional text customization can adapt headlines and descriptions to the conversation or translate them into the user’s preferred language. U.S. Shopify merchants can also use a ChatGPT Ads app to manage campaigns, while Shopify Catalog data supports more accurate product appearances in shopping conversations. These workflow and catalog integrations reduce interface work, but they do not remove the need for review.

    • Review generated copy against the canonical product record, not just the landing page’s marketing language.
    • Validate translated claims, units, policies, and variant names before enabling localized customization.
    • Require a live lookup for price, stock, delivery, and personalized benefits when those values can change.
    • Send every answer to a landing state that preserves the chosen product or variant. Do not make the shopper repeat the conversation.
    • Log unsupported questions and corrected answers as product-data defects, then fix the underlying record.

    Keep paid and independent answers conceptually separate. OpenAI says Sponsored Agent conversations are labeled and separated from the original ChatGPT conversation, advertising does not influence ChatGPT’s independent answers, and advertisers do not receive users’ private conversations. Plan your measurement around the signals the platform legitimately exposes; do not design a campaign that assumes access to private prompt history.

    Measure the path from question to profitable order

    Click-through rate cannot describe the whole experience when a conversation performs part of the product-page job. It may produce fewer but better-qualified visits, expose missing information, or assist a purchase completed through another surface. Build a measurement chain that distinguishes those outcomes.

    • Visibility: eligible ad exposure, AI share of voice, recommendation coverage across a fixed set of target shopping prompts, and the products most often surfaced.
    • Conversation: conversation starts, qualified question rate, common question categories, answer failure rate, and the share of conversations that reach a site handoff.
    • Selection: variant views, product comparisons, cart additions, and checkout starts originating from the agent experience.
    • Transaction: completed orders, revenue, margin where available, assisted conversions, and member-benefit usage.
    • Outcome quality: cancellations, returns, exchanges, and support contacts attached to agent-assisted orders.

    Define the denominators before launch. Conversation start rate is starts divided by eligible ad exposures when the platform supplies both values. Qualified question rate is conversations containing a decision question divided by starts. Answer failure rate is unsupported, corrected, or escalated answers divided by starts. If a platform withholds a denominator, mark the rate unavailable instead of combining unrelated proxies.

    Use distinct campaign identifiers and landing URLs for each agent surface, preserve product and variant context in the handoff, and record launch dates in your analytics annotations. Compare performance with a suitable unactivated product, market, or campaign group where possible. Keep budget, promotion, inventory, and seasonal differences visible so a lift is not automatically credited to the agent.

    Google’s AI performance insights in Merchant Center are generally available in Australia, Canada, India, New Zealand, and the U.S., including comparisons of brand share of voice across AI Mode and AI Overviews. Its Universal Commerce Protocol integration can also support cart transfers to merchant sites and expanded checkout testing. Loyalty data can surface member-specific pricing and benefits. These discovery, checkout, and personalization capabilities make segmentation essential: report new and returning customers, members and non-members, and agent-assisted and conventional journeys separately.

    Key takeaways: use this launch sequence

    • Choose one decision-heavy category. Start where buyers repeatedly ask about fit, compatibility, delivery, or policy terms, because those questions reveal whether the agent adds real value.
    • Separate your goals. Decide whether each activity is intended to earn a citation, a brand recommendation, a product selection, or a paid conversation.
    • Repair the product record first. Align variant identity, decision attributes, price, inventory, policies, page content, feed data, and JSON-LD before generating campaigns.
    • Create the answer map. Pair each common buyer question with an approved data field, a safe fallback, and a destination that preserves the selected product.
    • Apply campaign guardrails. Human-review generated claims and translations, require live checks for changing commercial facts, and prohibit unsupported inference.
    • Instrument the whole path. Track visibility, dialogue, selection, checkout, and post-purchase quality rather than using clicks as the sole success signal.
    • Feed failures back into operations. Repeated unanswered questions belong in the catalog backlog; frequent returns after an agent interaction may indicate that an answer or attribute is misleading.

    Start with the category where a wrong answer would most often block or spoil a purchase. Make that category reliably answerable across organic discovery, conversational ads, and checkout. Scale only after the same facts survive every handoff.

    References


  • Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    Chrome Ad Metrics: How to Audit an Ad-Heavy Website

    If increasing ad revenue has made your pages feel crowded or slow, you no longer have to settle the argument with screenshots and opinions. Chrome can now expose four separate dimensions of ad load through real-user data: how many ads people see, how much space those ads occupy, how many bytes they consume, and how much processing time they require.

    The useful move is not to chase the lowest possible number. It is to find the page patterns where advertising consumes more attention or resources than the commercial return justifies, then reduce the specific cost without weakening the rest of the business.

    The four metrics reveal different kinds of ad load

    Chrome has added four experimental advertising metrics to the Chrome User Experience Report, commonly called CrUX. Treat them as four diagnostic signals, not as interchangeable measures of whether a page has too much advertising.

    MetricWhat Chrome measuresWhat it helps you notice
    Ad CountThe average number of ads visible in the viewportHow many detected ads compete for the user’s visible attention at the same time
    Ad DensityThe average percentage of the viewport occupied by adsHow much of the visible screen advertising takes over, regardless of the number of placements
    Ad Weight – NetworkThe bytes consumed by advertisingThe data cost of the detected ad experience
    Ad Weight – CPUThe processing time consumed by ads, measured in millisecondsThe execution cost imposed by ad-related resources and scripts

    The distinction matters because a single large placement can create high density without a high count. A collection of small placements can raise count while occupying less space. A visually restrained layout can still transfer substantial data or consume considerable processing time.

    Read the metrics in combination:

    • Count and density rise together: Start with the layout. Too many placements may be visible concurrently, and they collectively occupy more of the screen.
    • Density rises while count stays near your cleaner-page baseline: Investigate placement size and persistence before removing every slot. One dominant unit may be the main difference.
    • Network weight rises while count and density remain stable: The visible layout is not telling the whole story. Inspect the advertising payload and repeated resource requests.
    • CPU weight rises by itself: Concentrate on execution. Reducing visible ad space will not necessarily address script-related processing cost.
    • The four signals stay near your baseline but commercial results remain weak: Do not assume ad load is the cause. Creative relevance, audience fit, placement quality, or another factor may deserve attention first.

    This gives you a better decision model than a blanket instruction to run fewer ads. You can identify whether the problem is competition for space, data transfer, processing, or a combination of them.

    Understand what Chrome is actually observing

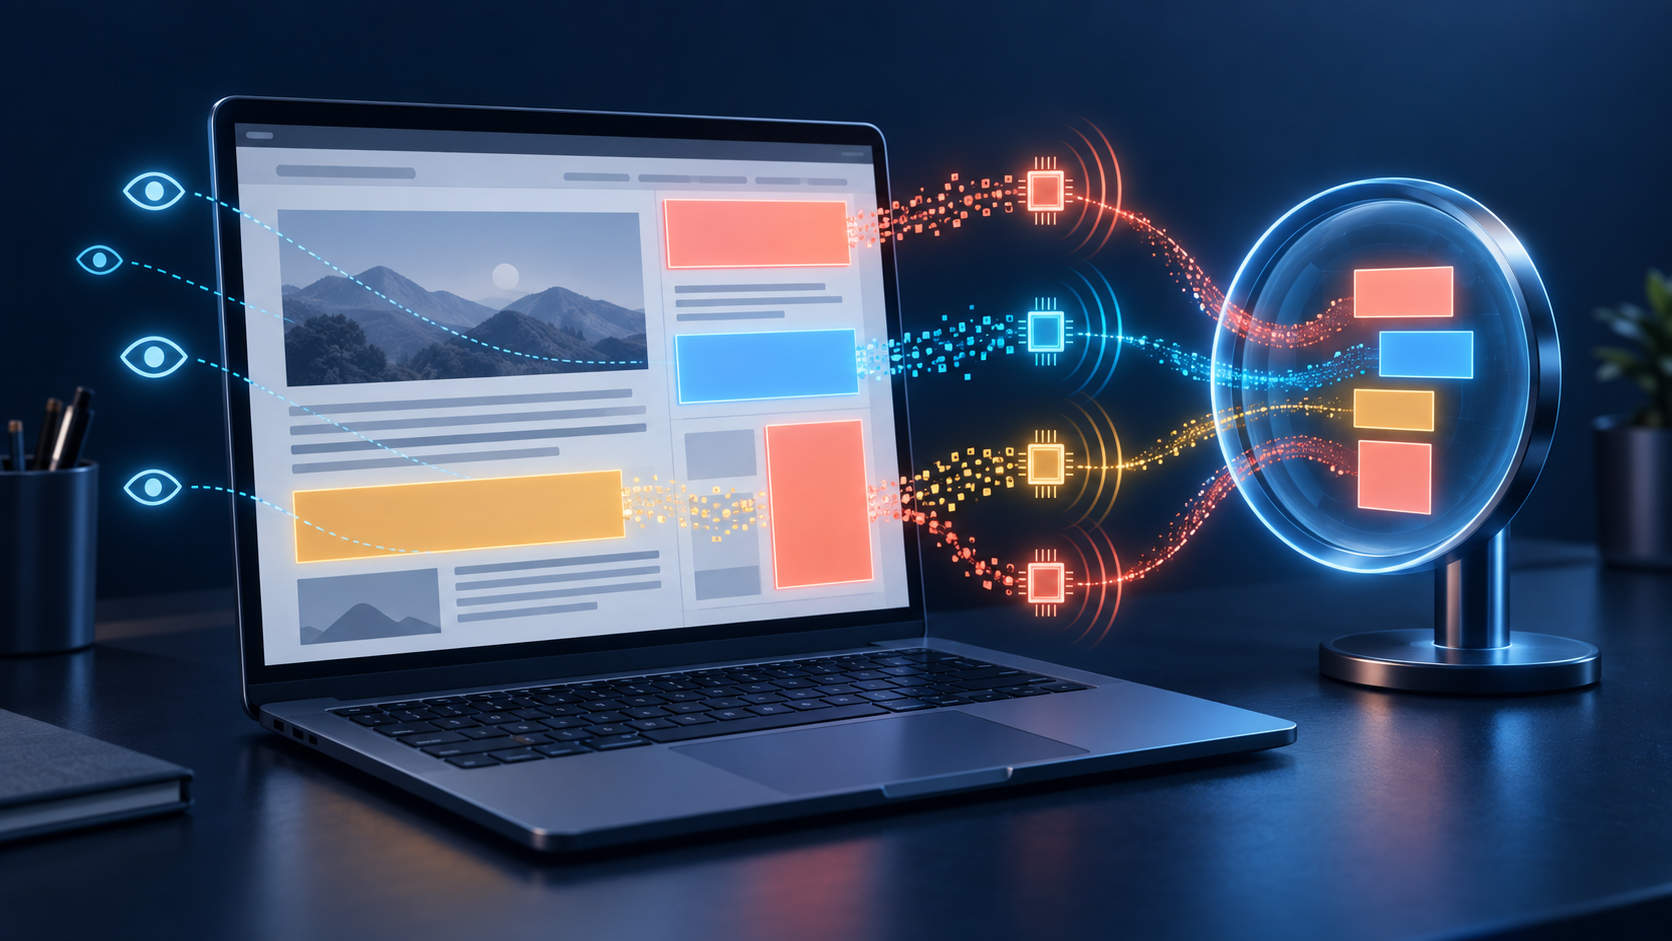
    Four floating webpage layers depict visible ad placements, their occupied area, incoming data, and processor activity above a computer monitor.

    Your ad server, content management system, and Chrome do not necessarily count the same thing. Your systems know which slots, campaigns, or line items you configured. Chrome detects advertising from the browser side.

    Chrome uses network-level filtering and script-execution analysis to identify ads. It can classify a URL as advertising when that URL matches its ad filter list. It can also recognize resources or frames created by scripts that have already been identified as ad-related.

    Ad Count should therefore be read as a count of ads Chrome detected in the visible viewport, not as a count of the placements declared in your page template. When an internal slot report and the Chrome metric differ, first check whether the two systems are measuring the same object. Do not label either figure incorrect merely because it does not match the other.

    Timing changes the interpretation too. Chrome samples the visible viewport once per second for Ad Count and Ad Density. Network and CPU usage accumulate through the user’s session. CrUX then reports the results at the 75th percentile.

    • A screenshot is not a session. A page may begin with a restrained layout and become denser as advertising appears or remains visible during use. Inspect the experience over time.
    • An initial transfer is not total network weight. Resources loaded later in a session still contribute to the accumulated advertising cost.
    • A quick lab run is not field data. CrUX reflects real Chrome usage, so device capability, network conditions, page behavior, and actual user journeys can produce a different result from a controlled check.
    • The 75th percentile is not the arithmetic mean. It marks a value at or below which three-quarters of measured experiences fall. The remaining quarter is heavier, so do not describe the number as the experience of an average user.

    That measurement model should shape your quality assurance. Reproduce an ordinary journey rather than loading the page, taking one screenshot, and declaring the layout acceptable. Let advertising appear, scroll through the content, and continue long enough to expose resources that arrive after the first view.

    Build an audit around contrasts, not invented thresholds

    Three similar webpage layouts with different ad patterns are compared on a light table using a magnifying lens and abstract resource signals.

    Chrome has not established a recommended pass or fail threshold for any of the four metrics. They are experimental, and they are not Core Web Vitals. A universal scorecard that labels a page good or bad would therefore create precision that the current program does not provide.

    You can still run a disciplined audit. Use your own comparable page patterns to establish context:

    1. Define comparable groups. Separate page patterns that have materially different jobs or layouts. An article template, a gallery, and a short reference page should not automatically share one baseline.
    2. Record all four ad metrics together. Do not report density without network and CPU weight, or combine the four into an unsupported composite score. Keeping the raw dimensions visible prevents one improvement from hiding a regression elsewhere.
    3. Keep Core Web Vitals in a separate column. The advertising metrics can sit beside established performance reporting, but they should not be relabeled as Core Web Vitals or folded into a made-up Google score.
    4. Find useful contrasts. Compare cleaner and more heavily monetized experiences within a relevant group. Look for the metric that changes most clearly rather than assuming every ad-heavy page has the same defect.
    5. Reproduce the suspected behavior. Review the page across a realistic session, paying attention to what is visible and what continues loading or executing. The goal is to connect a field signal to an observable mechanism.
    6. Change one cost dimension first. Reduce concurrent visible placements for count, occupied screen area for density, advertising payload for network weight, or unnecessary execution for CPU weight. A focused change makes the result easier to interpret.
    7. Judge the tradeoff with business outcomes. Put the ad metrics beside the revenue and campaign measures your team already trusts. Keep changes that improve the experience at an acceptable commercial cost; investigate further when a lower ad metric merely moves the problem elsewhere.
    8. Create internal guardrails only after you have a baseline. Express them as limits for comparable page patterns and document why they exist. Do not present them as official Chrome thresholds.

    A practical internal rule might require a redesigned template not to materially worsen density or CPU weight against the template it replaces while maintaining an acceptable monetization result. Your team still has to define what materially and acceptable mean, but the rule identifies the comparison, the protected outcomes, and the owner of the decision.

    When possible, test changes in isolation. Removing a placement while simultaneously changing the ad vendor, page layout, and loading behavior may improve the numbers, but it will not tell you which intervention mattered. That leaves you unable to repeat the result elsewhere.

    Avoid five costly interpretation errors

    The new metrics are useful precisely because they separate layout pressure from resource pressure. That value disappears when a team compresses them into a simplistic verdict.

    • Do not optimize only for fewer ads. A lower count can coexist with high density, network weight, or CPU weight. Verify which cost actually fell.
    • Do not treat density as a performance metric. Density describes visible space. Network and CPU weight describe resource consumption. One cannot stand in for the others.
    • Do not claim an SEO ranking effect. Nothing in the current rollout establishes these experimental measurements as ranking signals. Track them beside SEO and performance data when useful, but keep the labels honest.
    • Do not promise a media-value or bidding uplift. Better transparency could affect how buyers assess inventory, but Google has not said whether Display & Video 360 is testing these signals for bidding, valuation, or reporting.
    • Do not wait for an official cutoff before measuring. The absence of a universal threshold prevents a pass or fail verdict; it does not prevent you from detecting regressions, comparing relevant experiences, or correcting an obvious outlier.

    Publishers with cleaner experiences may eventually use the metrics to distinguish their inventory. Advertisers and agencies may use them to identify placements where clutter or resource consumption threatens attention and campaign performance. Independent advertising platforms are expected to receive the CrUX data at the same time as Google’s advertising businesses, which makes it sensible to preserve the raw metrics now rather than build a process around a proprietary composite score.

    For buyers, the right first use is comparison and investigation, not automatic exclusion. A high reading identifies a question to ask about the experience. Without an established threshold or evidence connecting that reading to your own campaign outcome, it is not yet a sufficient reason to reject inventory by itself.

    Key takeaways

    • Ad Count measures how many detected ads are visible; Ad Density measures how much of the viewport they occupy.
    • Ad Weight – Network measures advertising bytes, while Ad Weight – CPU measures advertising processing time in milliseconds.
    • Chrome samples the viewport once per second, accumulates network and CPU use through the session, and reports CrUX results at the 75th percentile.
    • The four measurements are experimental, are not Core Web Vitals, and do not have official recommended thresholds.
    • Use the metrics as separate diagnostic signals, compare relevant page patterns, and evaluate every change against both user-experience and commercial outcomes.

    Choose one commercially important page pattern this week and capture all four dimensions before changing it. That baseline will give your ad, performance, analytics, and editorial teams something concrete to improve – and it will keep future decisions grounded if buyers begin using the same signals to value inventory.

    References


  • A Practical 2027 Media Plan for Testing ChatGPT Ads

    A Practical 2027 Media Plan for Testing ChatGPT Ads

    If ChatGPT Ads has appeared in your 2027 planning deck, the difficult question isn’t whether the channel matters. It’s how much money you can risk before you know whether it adds customers or merely takes credit for demand you already created elsewhere.

    The defensible approach is to treat ChatGPT Ads as a controlled acquisition and learning bet. Give it one job, fund it with a reversible test budget, compare it with the next-best use of that money, and require evidence of incremental business value before you scale.

    Assign ChatGPT Ads one job in the channel plan

    ChatGPT is a substantial media environment, but reach alone doesn’t make it a primary channel. Its monthly audience flattened from September 2025 while Gemini continued growing, and Gemini benefits from distribution across Google Search, Android, Workspace, and YouTube. ChatGPT has to earn its usage through direct adoption and retention rather than inheriting comparable distribution.

    The overlap matters even more than the headline audience number. Only 5% of ChatGPT’s audience was reported as non-overlapping with Google. You therefore shouldn’t put ChatGPT Ads in a plan under a vague label such as incremental reach. That is a hypothesis to test, not a benefit to assume.

    Choose one primary job for the first campaign:

    • Incremental acquisition: Generate sales, subscriptions, or qualified opportunities that wouldn’t otherwise have arrived through search, direct, or another paid channel.
    • High-intent message testing: Learn which problem, constraint, or outcome moves a well-defined audience toward action.
    • Audience learning: Identify which use cases produce qualified engagement, then apply that learning to search, content, and landing pages.
    • Strategic readiness: Establish tracking, approval, creative, and reporting processes before the inventory becomes material to your category.

    Strategic readiness is a legitimate reason to spend, but it isn’t a performance result. Label it as a learning investment and cap it accordingly. If the campaign’s job is acquisition, it must eventually clear the same commercial standard as the budget it could replace.

    Write the campaign decision before writing the media plan. A useful one-page brief answers five questions:

    1. Which customer problem or buying situation are you trying to reach?
    2. What business event will count as success?
    3. Which existing campaign or budget tranche is the fair comparison?
    4. What evidence would justify the next release of spend?
    5. What result would make you stop?

    A brief that says both build awareness and drive efficient conversions leaves you no clean decision. Pick the result that controls the budget. Treat the other metrics as diagnostics.

    OpenAI’s wider strategy is another reason to keep the channel’s role proportionate. A reported 2030 revenue forecast assigned $100 billion of an expected $280 billion to ChatGPT Ads. That would make advertising significant, but still a minority of the forecast. Enterprise and API products remain central to the business. Plan for a viable ad channel without assuming it will immediately receive the controls, inventory, or organizational attention of a mature search platform.

    Size a reversible test budget, not a belief about the platform

    A small tray of budget tokens is isolated in a transparent test compartment beside a separate control lane and a larger protected reserve.

    No defensible universal percentage exists for ChatGPT Ads. Your allocation should come from opportunity cost: what is the next dollar doing now, and what evidence would persuade you to move it?

    A useful scale check is TikTok. Its roughly 2 billion monthly users represented about twice ChatGPT’s reach in the available comparison. That doesn’t mean ChatGPT deserves half your TikTok allocation; the platforms serve different behavior and intent. It does mean a plan that gives an unproven ChatGPT campaign more strategic weight than your established secondary channels needs a strong, explicit reason.

    Build the allocation from these lines rather than starting with a percentage of total media:

    Plan lineWhat to specifyWhat it prevents
    Funding sourceThe named campaign, experiment reserve, or marginal spend being displacedTreating the test as free money
    Primary outcomeA completed sale, retained subscriber, qualified opportunity, or another business eventOptimizing to cheap activity that doesn’t create value
    Comparison baselineThe marginal CPA, contribution, pipeline efficiency, or other unit economics of the next-best channelComparing a new channel with an irrelevant blended average
    All-in test capMedia, creative, landing-page, measurement, and operational costsHiding the real cost of learning
    Release gatesThe tracking, volume, quality, and incrementality evidence required for more spendScaling on early enthusiasm
    Exit ruleThe condition that pauses or ends the testLetting sunk cost become strategy

    Use marginal performance, not the account average. A mature paid-search program may have excellent blended efficiency because branded demand is cheap to capture. Its next unit of prospecting spend can be much less productive. That next unit is the relevant comparison for an experimental channel.

    Release the budget in three decision stages:

    1. Instrumentation: Spend only enough to verify campaign naming, analytics, conversion events, CRM capture, landing-page behavior, and reporting reconciliation. Don’t judge commercial performance while the measurement is still changing.
    2. Validation: Hold the core audience, offer, conversion definition, and landing experience steady long enough to evaluate qualified outcomes. A test that changes every weak variable at once can improve without teaching you why.
    3. Expansion: Release additional money only after the channel clears its predefined cost, quality, and incrementality gates. Treat each increase as another decision, not as an automatic graduation.

    Let outcome volume govern the stages. A fixed two-week test may be needlessly long for a high-volume retailer and meaningless for a low-volume enterprise funnel. Before launch, estimate how many primary outcomes you need to make the decision and whether the available budget can plausibly produce them. If it can’t, change the question. Test a qualified intermediate event, a narrower audience, or measurement readiness instead of pretending you can prove revenue impact.

    Prove incremental value instead of accepting attributed value

    Two matched groups of anonymous customer figures move through parallel test and control pathways, with one group encountering a glowing speech-bubble ad surface.

    Platform-attributed conversions answer a limited question: which outcomes can the platform associate with an ad interaction under its attribution rules? Your media plan has to answer the harder question: how many valuable outcomes did the spend cause?

    Measure the entire path to value

    Create a measurement chain before the first impression. Use consistent campaign parameters and preserve the ChatGPT campaign identifier through analytics, forms, checkout, CRM records, and revenue reporting. The platform dashboard can be one record, but it shouldn’t be the only record.

    • Primary business metric: Contribution from purchases, retained revenue, sales-accepted pipeline, or another outcome tied to the campaign’s stated job.
    • Quality metric: New-customer rate, refund or cancellation behavior, lead acceptance, progression to a meaningful sales stage, or another signal that distinguishes value from volume.
    • Efficiency metric: Marginal acquisition cost, contribution after media, or qualified-pipeline efficiency. Choose the measure your finance and channel teams already use to allocate the next dollar.
    • Diagnostic metrics: Clicks, engaged visits, form starts, and assisted conversions. Use these to find friction, not to declare victory.

    For ecommerce, revenue alone can flatter campaigns that attract discounts, returns, or existing customers. Bring contribution, new-customer status, and downstream behavior into the view. For B2B, a form completion is rarely the final value event. Reconcile it with qualification, sales acceptance, pipeline creation, and eventual progression.

    Handle Google overlap as an experiment-design problem

    With 95% implied audience overlap between ChatGPT and Google, a converted user may have seen or used both environments. Last-click reporting can move credit between channels without reflecting any change in total demand.

    Use the strongest comparison your scale and available controls allow:

    • Randomized holdout: Use a platform or audience holdout if one is available and suitable. Keep other treatment differences to a minimum.
    • Geographic split: Compare genuinely similar regions while holding major promotions and other media changes steady. Check baseline differences before launch.
    • Time-based switchback: Alternate defined on and off periods when geographic separation isn’t practical. Avoid windows distorted by holidays, launches, outages, or major budget changes elsewhere.
    • Matched-cohort analysis: Compare exposed and non-exposed customers with similar observable characteristics when a controlled design isn’t available. Treat the result as directional because unobserved differences can remain.

    Track branded search, direct visits, organic conversions, and total outcomes during the test. If ChatGPT-reported conversions rise while total qualified outcomes remain flat and another channel falls by a similar amount, you may be seeing attribution movement rather than growth. That pattern doesn’t prove cannibalization on its own, but it tells you not to scale until you investigate.

    Separate the calibration period from the decision period. Use calibration to fix broken events, rejected creative, inconsistent parameters, and landing-page defects. Once measurement is stable, lock the important variables for the validation window. Otherwise, every repair becomes part of the result and you won’t know whether the underlying media worked.

    Before releasing more budget, make the team answer four questions in writing: Did total valuable outcomes increase? Did the customers meet the same quality bar as other channels? Did the result persist after initial calibration? Does the next dollar outperform its next-best use? A no or an unknown isn’t always a reason to kill the channel, but it is a reason to withhold automatic scaling.

    Prepare an answer-ready ad and destination

    An ad inside an AI experience carries a trust problem that ordinary display planning can miss. Sam Altman described ads-plus-AI as ‘uniquely unsettling’ in October 2024, before OpenAI later launched advertising. Your creative should never depend on a user mistaking paid placement for the assistant’s neutral recommendation.

    Make the brand and commercial action clear. Don’t imitate an assistant response, imply independent endorsement, or conceal the reason for the click. Clarity may reduce low-intent traffic, which is useful when the actual objective is efficient acquisition.

    A strong creative brief has four parts:

    • The situation: Name the concrete task, constraint, or decision the customer is dealing with.
    • The useful claim: State what the product, service, or resource helps the customer do.
    • The boundary: Include the qualifier that prevents the wrong person from clicking, such as audience, region, use case, required integration, or commercial model.
    • The next action: Match the call to action to the buyer’s readiness. Don’t send an early-stage question directly to a high-friction sales form unless that is genuinely the next useful step.

    The destination should continue the exact problem framed by the ad. A generic homepage forces the visitor to reconstruct the path and makes message-level analysis impossible. Use a dedicated page or a tightly matched existing page with the promised answer, the relevant proof, material constraints, and one primary action visible without hunting.

    For teams working on AEO, GEO, and structured data, keep paid distribution and organic AI visibility distinct. An ad placement is bought. An organic mention, answer, or citation is selected through a different process. The same page can support both programs, but an improvement in one doesn’t prove an improvement in the other.

    Make the destination machine-readable and human-verifiable:

    • Name the company, product, service, intended user, and relevant availability consistently.
    • Answer the primary question near the top, then provide proof, conditions, alternatives, and the next step.
    • Use descriptive headings that expose the page’s information structure.
    • Add only schema types and properties that match visible, accurate content. Structured data should clarify the entity and offer, not manufacture claims the visitor can’t verify.
    • Keep pricing, eligibility, product names, and material limitations consistent across the ad, page, structured data, and conversion flow.
    • Decide indexability intentionally. If the page is meant to build organic visibility as well as convert paid traffic, it needs a durable URL, useful standalone content, and an indexing strategy that doesn’t conflict with duplicate variants.

    Until the platform documents a connection, don’t treat JSON-LD as an ad-targeting control or a way to improve paid placement. Its job here is to reduce ambiguity, support accurate interpretation, and keep your paid and organic destination from contradicting itself.

    Give every meaningful creative-message combination its own campaign identifier and landing-page mapping. If one message wins, you should be able to trace whether the advantage came from cheaper traffic, stronger engagement, better qualification, or higher downstream conversion. A single undifferentiated landing page hides that answer.

    Key takeaways for the scale-or-stop decision

    • Place ChatGPT Ads in the exploratory part of the 2027 plan until it proves incremental value; audience size alone doesn’t justify core-channel status.
    • Give the first campaign one primary job and one business outcome. Awareness, learning, and acquisition require different budgets and success rules.
    • Fund the test from a named marginal use of money, include production and measurement costs, and set the maximum loss before launch.
    • Build incrementality into the design because most of ChatGPT’s audience overlaps with Google. Platform-attributed conversions aren’t enough.
    • Scale on qualified downstream outcomes and marginal economics, not clicks, early novelty, or a favorable blended average.
    • Use answer-ready pages and accurate structured data, but measure paid performance separately from organic AEO and GEO visibility.

    Your next move is a one-page test charter containing the channel’s job, displaced budget, primary outcome, comparison design, release gates, and exit rule. Bring that page into the budget meeting. If nobody can name the result that earns the next tranche, ChatGPT Ads isn’t ready to scale yet.

    References


  • Amazon DSP Access to ChatGPT Ads: What Buyers Need to Know

    Amazon DSP Access to ChatGPT Ads: What Buyers Need to Know

    You already buy through Amazon DSP, and someone has asked whether ChatGPT Ads belongs in the next media plan. The hard part is not the novelty. It is knowing what Amazon can control, what OpenAI still controls, and whether the pilot can produce evidence strong enough to justify more spend.

    At launch, access is a limited U.S. managed-service pilot for select advertisers. Amazon helps with buying, campaign setup and optimization, while OpenAI decides how and where the ads are served inside ChatGPT. That division is the center of your go/no-go decision, not a footnote.

    Amazon DSP gives you a buying route, not control of ChatGPT

    A split illustration shows a campaign operator managing ad inputs on one side while a separate AI system chooses the final placement on the other.

    There are two operating layers. Amazon provides the advertiser relationship, DSP buying workflow and managed campaign support. OpenAI retains control over ad delivery and placement within ChatGPT.

    The distinction matters because familiar DSP words such as audience, inventory and placement can make the setup sound more controllable than it is. Buying the inventory through Amazon does not mean Amazon chooses where your ad appears in the ChatGPT experience.

    Key takeaways

    • The pilot is limited to the United States at launch and is available to a select group of advertisers, including Delta Vacations.
    • Access is offered as a managed service, with Amazon helping advertisers set up and optimize campaigns.
    • Advertisers can buy ChatGPT inventory on a cost-per-click or CPM basis.
    • Available options include text and image units as well as product feed ads created from advertiser catalogs.
    • Amazon manages the buying relationship, but OpenAI controls final delivery and placement inside ChatGPT.

    Turn that split into a practical rule for every campaign question. Do not ask only, “Can we target this audience in ChatGPT?” Ask what Amazon lets you configure, what information passes to OpenAI, and which system makes the final delivery decision. A setting in the buying interface is not automatically a promise about the exact prompt, conversation or organic answer that will precede your ad.

    Decide whether the pilot can answer a business question

    A pilot is worthwhile only if its result can change a later decision. “See how ChatGPT Ads perform” is too vague. A usable question is narrower: can a specific offer earn qualified visits at an acceptable cost, or can the placement deliver useful exposure to an audience you already reach through Amazon DSP?

    Check these conditions before you pursue access:

    • Your planned activation is in the United States, because broader geographic access has not been established for the launch pilot.
    • You are prepared to work through Amazon’s managed-service process rather than expecting a self-service inventory switch.
    • You have one offer that a person can understand without needing the rest of a long campaign story.
    • Your landing destination can continue the decision that the ad starts, with matching claims, imagery and next steps.
    • Aggregated reporting is sufficient for your initial decision, or you can supplement it with your own properly configured site analytics.
    • You can protect the budget as a learning allocation instead of taking money from a proven campaign before the pilot has answered anything.

    Do not disqualify your company merely because it does not sell products on Amazon. The route could also matter to nonendemic advertisers that already use Amazon DSP to reach audiences elsewhere, and Delta Vacations is among the participating U.S. advertisers. That does not guarantee eligibility, but it shows why service, travel and other non-retail advertisers should ask rather than assume the pilot is restricted to marketplace sellers.

    Send your Amazon representative a written access brief with these questions:

    1. Is our account, campaign category and intended U.S. audience eligible for the pilot?
    2. What does the managed service include, and are there minimum spend, service fee or campaign-duration requirements?
    3. Which Amazon shopping or streaming signals, if any, can actually be used for this campaign?
    4. Which delivery, exclusion, brand-suitability and placement controls does OpenAI expose through the pilot?
    5. What asset specifications, catalog fields, review steps and refresh rules apply to each format?
    6. What event is counted as a “result” in cost-per-result reporting?
    7. What reporting dimensions, cadence and latency will be available, and can destination URLs carry unique campaign parameters?

    Several of those details are not established by the announced pilot terms. That is precisely why you should ask before allocating money. If the team cannot define the result event or explain the available delivery controls, waiting is a defensible decision. An unanswered implementation question is not a learning objective.

    Choose the buying model and format around one test

    The pilot supports both CPC and CPM buying. Neither is inherently better. Each answers a different question, so choose the model after you define what the campaign must teach you.

    Use CPC when the question is about response

    CPC is the cleaner starting point when you want to learn whether the sponsored unit can earn visits. Define what makes a visit useful before launch. A click alone may be the billable action, but your own measurement should distinguish an immediate exit from a visitor who reaches the intended page, engages with the offer or completes the action your business values.

    Do not make CPC the primary metric for a campaign whose actual objective is recognition or exposure. You would be evaluating a reach question with a response metric.

    Use CPM when the question is about exposure

    CPM is more appropriate when you intend to budget around delivered impressions. Impressions can establish that delivery occurred, but they do not establish attention, persuasion or business lift. Ask whether reach, frequency or other exposure detail will accompany the aggregated metrics; those dimensions are not part of the stated reporting set.

    If you test both CPC and CPM, keep them in separately reported campaign cells if the pilot permits it. Combining them into one result makes it harder to tell whether performance came from the creative, audience, placement or buying model.

    Treat the product feed as creative infrastructure

    Product feed ads can automatically create ad assets from an advertiser’s catalog. That can reduce manual asset work, but it also makes feed quality part of creative quality. Automation will not repair an ambiguous product name, a mismatched image or a landing page that contradicts the feed.

    Before the catalog is connected, verify the following with the managed-service team:

    • Product names and variants remain understandable when seen outside your normal storefront.
    • Images are suitable for the available ChatGPT ad unit rather than merely acceptable in a product grid.
    • Price, availability and offer details match the destination page.
    • Products you do not want advertised are excluded before assets are generated.
    • Your team can preview or approve generated assets and knows how catalog changes reach the live campaign.

    Write for a sponsored next step

    Text and image ads appear beneath an organic ChatGPT response and carry a sponsored label. The creative should therefore present a clear next step, not imitate the voice of the organic answer or imply that the advertiser produced it.

    • Name the product, service or offer plainly enough that the user knows what the click leads to.
    • Use a claim that is visible and supportable on the destination page.
    • Match the call to action to the landing experience. Do not promise a comparison, quote or availability check that the next page does not provide.

    Do not invent creative around assumed character limits or placements. Obtain the pilot’s actual specifications first, then write within them.

    Measure what the pilot reports and label what it does not

    A creative tile passes through a transparent test chamber toward visible response tokens and a second output area hidden by frosted glass.

    Participating advertisers are expected to receive aggregated impressions, clicks, cost per result, CPM and CPC. Those numbers can support a useful media scorecard, but only if you separate reported facts from calculated diagnostics and site-side outcomes.

    Measurement layerMetricDecision it can support
    DeliveryImpressions and CPMWhether the campaign delivered exposure at an acceptable media cost
    ResponseClicks, CPC and calculated CTRWhether the sponsored unit earned traffic
    Defined resultCost per resultWhether the agreed result event occurred at an acceptable cost
    Business qualityYour site-side signals, if destination tagging is supportedWhether the resulting visits were valuable after the click

    You can calculate click-through rate as clicks divided by impressions, multiplied by 100. Treat it as a creative and traffic diagnostic, not proof of business value. A unit can attract clicks while sending people to a page that does not meet their intent.

    “Cost per result” is also unusable until the result has a precise definition. Ask which event triggers it, where that event is observed and whether the definition is consistent across your comparison campaigns. Two campaigns cannot be compared on cost per result if one counts a click and the other counts a deeper action.

    Prompt-level reporting, individual conversation paths and query-level placement data are not included in the stated metric list. Their absence from that list does not prove they can never be available, but you should treat them as unconfirmed until the managed-service team documents otherwise.

    Complete this measurement brief before launch:

    1. Choose one primary metric tied to the test question.
    2. Write the exact definition of a result and identify which system records it.
    3. Select the closest reasonable baseline, while acknowledging differences in format, audience and context.
    4. Specify which outcomes come from Amazon’s aggregated report and which come from your own analytics.
    5. Set a decision rule for stopping, revising or expanding the test before results create pressure to move the goalposts.

    Avoid treating a standard display, paid search or social benchmark as directly interchangeable with conversational ad inventory. A benchmark can provide context, but differences in placement and user state mean it should not become an automatic pass-fail threshold.

    Keep paid ChatGPT exposure separate from organic AI visibility

    The ads are placed beneath organic ChatGPT responses and marked as sponsored. There is no documented basis for treating an Amazon DSP purchase as a way to influence inclusion in the organic answer. Paid delivery and generative engine optimization should remain separate programs with separate evidence.

    Maintain two scorecards

    • Your paid scorecard should contain delivery, clicks, media costs, the defined result and any supported site-side quality signals.
    • Your organic scorecard should track how accurately your brand is represented in relevant answers, whether it appears for a stable set of prompts, and whether useful citations or links appear when the interface provides them.

    Do not combine those scorecards into a single “AI visibility” number. Doing so would make a paid impression look like organic discoverability and could hide an organic answer that misrepresents the brand.

    Your GEO and AEO work should continue independently:

    • Use a stable, documented set of relevant prompts so changes can be observed without changing the test every time.
    • Make the destination page answer the next questions a user is likely to have after seeing the offer.
    • Keep catalog fields, ad claims and visible landing-page facts consistent.
    • When structured data is appropriate, make sure it describes the current, visible page rather than unsupported or stale claims.
    • Record the paid campaign period so a concurrent change in organic visibility is not casually attributed to media spend.

    Your immediate next step is a one-page pilot request. Pick one offer, one U.S. activation, one buying model and one primary result. Get the delivery controls, feed workflow and result definition in writing. Launch only if the aggregated reporting can answer the decision you have set. That is how you learn from a new channel without mistaking access for visibility.

    References


  • ChatGPT Ad Restrictions: A Playbook for Rival AI Brands

    ChatGPT Ad Restrictions: A Playbook for Rival AI Brands

    If your acquisition plan assumes you can advertise a competing AI generator inside ChatGPT, treat that inventory as unconfirmed. OpenAI has reportedly stopped approving campaigns for standalone image- and audio-generation products, while video-generation tools remain eligible under the reported distinction.

    Your job now is to separate confirmed eligibility from assumptions, remove uncertain inventory from committed forecasts, and keep paid access distinct from organic visibility in ChatGPT. The restriction is narrower than an industry-wide AI advertising ban, but it exposes a channel risk every AI marketer should plan for.

    Start with the narrow scope of the reported restriction

    The clearest boundary is based on what the advertised product does. Campaigns promoting standalone image generation and standalone voice or audio generation are reportedly no longer being approved. Video-generation products can still advertise. The status of broader AI suites, adjacent tools, and products that combine several modalities has not been publicly established.

    Public details remain thin because OpenAI reportedly communicated the change directly to advertising partners instead of publishing a comprehensive announcement. That leaves you with a meaningful category signal, but not a complete eligibility rulebook for every product configuration.

    Promoted productCurrent reported signalSafe planning assumption
    Standalone image generatorCampaigns reportedly no longer approvedExclude ChatGPT spend from the committed plan unless you receive written clearance for the exact product and destination
    Standalone voice or audio generatorCampaigns reportedly no longer approvedAssume the inventory is unavailable until product-specific eligibility is confirmed
    Video generatorReportedly still permittedValidate eligibility before reserving budget and maintain a fallback channel
    Multimodal suite or adjacent AI productNo clear public boundaryRequest a ruling on the specific campaign, landing page, and promoted capability

    Adobe shows why you should evaluate products rather than make a brand-wide assumption. Adobe participated in ChatGPT’s initial advertising pilot with promotions that included Acrobat Studio and the Firefly image generator. It was then reportedly informed that standalone image and voice generation campaigns would no longer be approved. That does not establish that every Adobe product or every campaign from an AI company is prohibited.

    The commercial tension is straightforward. ChatGPT is becoming an advertising destination while OpenAI also offers image and voice capabilities that compete with products seeking access to its audience. Blocking direct competitors is not unusual for a large platform, but it means category eligibility can become a material acquisition dependency rather than a routine campaign setting.

    Treat product classification as a campaign dependency

    Unbranded modules containing image, audio, video, and mixed-media tools are sorted into separate geometric docking bays on a strategy desk.

    Do not wait for creative approval to discover that the underlying offer is ineligible. Resolve the product classification before you commit spend, forecast leads, or promise ChatGPT reach to internal stakeholders or clients.

    1. Identify the exact promoted offer. Record the product name, landing-page URL, primary capability, conversion action, and whether the tool is standalone or part of a larger suite. A parent company name is not specific enough.
    2. Request a campaign-level eligibility decision. Ask whether that exact product and destination can advertise. Also ask whether the decision is based on the product’s functionality, the landing page, the ad message, or a broader advertiser category.
    3. Get the answer in writing. Save the decision date, submitted URL, product description, approval or rejection, stated reason, and any policy language provided. A verbal indication should not support a committed revenue forecast.
    4. Recheck after a material change. A new image, voice, or video capability can change how a product is classified. Revalidate when the promoted product, destination, or central offer changes.
    5. Do not disguise the category. Rewording a generator as a generic productivity tool while sending users to the same restricted product creates a mismatch between the ad and destination. Seek a clear ruling instead of trying to route around the restriction.

    Because the reported boundary is capability-specific, use product-level approval as your operating model. Do not interpret acceptance of one tool as approval for everything sold by the same company. Likewise, one rejected generator should not automatically remove an unrelated product from consideration.

    Your forecast should reflect that distinction. Keep ChatGPT ad revenue at zero in the committed base case until the relevant campaign has been cleared. You can retain an upside scenario for approval, but labeling uncertain inventory as expected performance hides the real risk from whoever controls the budget.

    Keep paid access separate from organic ChatGPT visibility

    An advertising eligibility decision is not evidence of an organic ranking, citation, or answer-selection penalty. Nothing in the reported restriction establishes that affected products cannot appear in unsponsored ChatGPT responses, receive citations, earn brand mentions, or attract referral traffic. Measure those outcomes independently.

    This distinction matters for AI SEO, AEO, and GEO strategy. Paid placement buys distribution when the inventory is available. Organic visibility depends on whether machines and users can find, understand, verify, and use your product information. Losing access to one does not make the other automatic, but it also does not erase it.

    • Publish pages around specific user decisions. Explain what the product generates, who it is for, the workflow it supports, its important limitations, and how it differs from adjacent categories. Generic AI platform language gives an answer engine little usable material.
    • Maintain one consistent entity record. Use the same official product name, publisher, canonical URL, category, and supported capabilities across product pages, documentation, profiles, and structured data. Resolve legacy names and conflicting descriptions.
    • Use JSON-LD as factual reinforcement. Apply Organization and SoftwareApplication or Product types only where they accurately describe the visible page. Mark up verifiable properties such as name, URL, publisher, description, and applicable offers. Structured data should match the page; it is not a way to claim unsupported features or bypass an advertising restriction.
    • Create evidence-rich comparison content. Help a buyer assess output type, inputs, integrations, workflow requirements, usage terms, and limitations. State the comparison method and keep changing product facts current.
    • Protect basic discoverability. Important product and documentation pages need crawlable text, descriptive internal links, stable canonical URLs, and accessible evidence. Do not hide the facts required for evaluation inside an image, demo, or sign-in wall alone.
    • Track answer visibility separately. Use a fixed set of representative prompts and record the date, wording, product mention, linked or cited domains, destination page, and any visible model or account context. Keep this dataset separate from sponsored impressions and clicks.

    Schema does not guarantee a ChatGPT mention, and a prompt-tracking sample is not a complete view of all users. The purpose is to create a repeatable signal. You should be able to tell whether paid access disappeared, organic visibility changed, or both events happened independently.

    Build a channel plan that can survive a policy expansion

    A central AI product connects to several marketing channels while one route to a conversational AI advertising gateway is partially blocked.

    The current distinction may not be the final one. OpenAI is expanding its own AI capabilities, and video generation remains a category to watch as the advertising business develops. Treat wider restrictions as a scenario to prepare for, not as a change that has already occurred.

    1. Current-boundary scenario: standalone image and audio products remain restricted while video stays eligible. Affected brands keep ChatGPT out of the committed media plan; eligible video brands still verify each campaign.
    2. Expansion scenario: another competing AI category becomes ineligible. Preselect where the budget will move, which channel-neutral assets are ready, and which measurement owner will preserve continuity.
    3. Ambiguous-suite scenario: a product combines restricted and permitted capabilities. Pause the ChatGPT forecast until the exact offer and landing page receive a product-specific decision.
    4. Reopening scenario: eligibility broadens later. Keep a compliant campaign brief, destination-page checklist, and tracking plan ready so approval can create an opportunity without forcing a rushed launch.

    Give each scenario five fields: trigger, decision owner, affected budget, fallback destination, and measurement change. A vague note to diversify channels will not help when a campaign is rejected. A named fallback allocation and a ready landing page will.

    Revalidate eligibility at decision points rather than relying on an old approval: before submission, after a material product or landing-page change, after a rejection or partner notice, and before approved reach enters a committed forecast. This keeps policy risk attached to the campaign it can actually disrupt.

    Separate availability risk from performance risk in reporting. Availability fields should capture eligibility, approval status, decision date, affected product, destination, and reason. Performance fields such as spend, clicks, conversions, and acquisition cost only become meaningful once a campaign can run. A rejection is an inventory-access constraint, not evidence that the product or creative performed poorly.

    Key takeaways

    • OpenAI is reportedly restricting ChatGPT ads for standalone image- and audio-generation products, while video-generation advertising remains permitted under the current reported boundary.
    • The restriction was communicated to advertising partners rather than through a comprehensive public announcement, leaving important edge cases unresolved.
    • Verify the exact product, capability, campaign, and destination before committing ChatGPT advertising spend.
    • Treat product-level approval as the dependency; do not infer a company-wide ban or approval from one campaign decision.
    • Keep advertising eligibility separate from organic ChatGPT mentions, citations, referrals, and answer visibility.
    • Maintain current-boundary, expansion, ambiguous-suite, and reopening scenarios so a policy change does not force an improvised budget decision.

    Make one immediate change to your media plan: add fields for eligibility evidence, the approved product and URL, and the fallback allocation. If any field is blank, keep the spend out of the committed forecast. Then audit the product pages and structured data that support organic AI discovery. That gives you a workable acquisition plan whether the restriction holds, expands, or is later relaxed.

    References


  • ChatGPT Ads Expansion: A Measurement-First Playbook

    ChatGPT Ads Expansion: A Measurement-First Playbook

    If ChatGPT Ads has been sitting in your watch column, you now have a more concrete decision to make: can the channel pass the same audience, attribution and reporting checks as the rest of your media plan? The rollout is reaching select countries across Europe, India, the Middle East and North Africa while gaining stronger campaign infrastructure.

    That is not a reason to move budget blindly. It is a reason to design a controlled test around a measurable business outcome. The useful change is not one flashy ad format. It is the combination of more workable audiences, richer conversion matching, product-level reporting, planned conversion optimization and a natural-language campaign workflow.

    Key takeaways for your media plan

    • Availability is expanding, but it is not universal. Treat Europe, India, the Middle East and North Africa as regions containing select launch markets, not as a promise that every country or account is eligible.
    • Audience operations are becoming practical at scale. Advertisers can modify existing custom audiences, combine identifier types and create audiences containing more than 5 million members.
    • Better matching improves attribution coverage, not proof of causality. More matched conversions can make a campaign easier to evaluate, but they do not by themselves show that an ad caused the outcome.
    • Carousel reporting now supports product diagnosis. Card-level impressions and clicks can reveal which products attract attention, but card impressions are separate from billable ad impressions.
    • Goal-based conversion optimization is still a planned capability. Build a clean conversion taxonomy now, but do not forecast a future optimization model as though it were already available in your account.

    Build the measurement spine before creating ads

    An abstract measurement framework connects a website event, secure server, identity match, and verified conversion while unused ad tiles sit nearby.

    A measurable campaign starts with the decision you expect its data to support. “See how ChatGPT Ads performs” is not a decision. “Decide whether this channel can produce qualified demo requests at an acceptable cost” is. The second formulation tells you which conversion matters, which downstream data you need and what would justify more investment.

    Write a one-page measurement brief before opening the campaign builder:

    1. Name one primary conversion. Choose the event that will govern the campaign decision. Keep visits, product views and other useful signals as secondary diagnostics unless one of them is genuinely the business outcome.
    2. Define the event precisely. Record where it fires, which action qualifies, whether repeat actions count and which internal system provides the comparison total.
    3. Map the available identifiers. If you use the Measurement Pixel, it can now use additional hashed customer information, including phone numbers, names, regions and postal codes. The Conversions API is also gaining more identifiers and Android Google Advertising ID support for matching.
    4. Validate data before interpreting performance. Check that required fields are populated consistently and reconcile campaign-attributed conversions with your analytics, commerce or CRM source of truth. Resolve unexplained gaps before using cost-per-conversion figures to make a budget decision.
    5. Separate attribution from incrementality. Attribution asks which conversions can be connected to campaign interactions. Incrementality asks how many would not have happened without the campaign. Better matching strengthens the first answer; it does not automatically answer the second.
    6. Set decision rules in advance. Document the business-quality checks, budget boundary and evidence needed to stop, revise or expand the test. This prevents a promising click-through rate from overruling weak downstream results.

    The Measurement Pixel and Conversions API can use more information for conversion matching. That may connect more outcomes to campaigns, which is valuable when legitimate identifiers have been missing. It can also make attributed results look different from an earlier setup. Annotate the implementation date so you do not mistake a measurement change for a sudden change in customer behavior.

    Do not treat hashing as permission to use customer data. Have the appropriate privacy or legal owner approve the identifiers, collection basis, retention rules and transfer process before activation. Send only the data your approved setup allows.

    Use the audience tools to run cleaner tests

    Two separated audience groups move through matching ad modules toward conversion markers while a privacy shield and measurement node oversee the test.

    The audience update removes a costly source of campaign friction. Advertisers can add, remove or replace custom-audience members without rebuilding the audience, mix identifier types in one request and create audiences exceeding 5 million members. OpenAI is also easing restrictions around exclusion audiences, providing more granular size estimates and supporting GAID.

    Those capabilities matter only if you preserve the logic behind each audience. Use a simple operating record with an audience name, purpose, owner, inclusion rule, exclusion rule, identifiers used, refresh method and last-change date. When membership changes, log what changed and why. Otherwise, a performance shift can be caused by new creative, different membership or both, and you will not know which lesson to carry forward.

    For the first test, keep the audience hypothesis narrow enough to explain in one sentence. Examples of useful structures include existing prospects who have not converted, eligible previous site visitors, or a product-interest group with current customers excluded. The right construction depends on your approved data and objective; the point is to make membership correspond to a real campaign hypothesis.

    Do not confuse capacity with relevance. Support for an audience containing more than 5 million members means the system can accept a large audience; it does not mean a larger audience is inherently better. A broad file can hide major differences in intent, product fit and customer status. Split groups when those differences should change the message, bid logic or landing experience.

    Use exclusions to protect the test from obvious contamination. If the campaign is meant to acquire new customers, for example, an approved current-customer exclusion can keep known buyers from being counted as acquisition results. Check the exclusion after every audience update, especially when identifiers are mixed or replaced.

    Geography needs the same precision. The expansion covers select countries within several regions, so confirm country and account availability before copying a campaign structure across markets. Europe is not one eligibility setting, and neither is the Middle East and North Africa. Localize the offer, conversion path and audience permissions only after you know the intended market can actually run the campaign.

    Read product reporting without mixing incompatible impressions

    Product-feed campaigns now provide a more useful diagnostic layer. Ads Manager can report impressions and clicks for individual carousel cards, while the Insights API exposes product-level fields. This lets you investigate whether one item is carrying the carousel, whether heavily exposed products receive little response, or whether product selection needs to change.

    The crucial distinction is that carousel-card impressions are separate from billable ad impressions. Keep the two concepts in separate reporting fields:

    MeasureWhat it helps you answerCommon mistake
    Billable ad impressionsHow much billable campaign delivery occurredReplacing this figure with the sum of card impressions
    Carousel-card impressionsWhich products received exposure inside the carouselTreating each card exposure as another billable ad impression
    Carousel-card clicksWhich product cards attracted an interactionAssuming a click proves a sale, lead or profitable outcome
    Product-level Insights API fieldsHow to carry product detail into your reporting workflowLosing the product identifier needed to join ad data with downstream results

    Build the product report from the decision backward. If the question is which products deserve more exposure, compare card impressions and clicks alongside downstream product outcomes where your systems allow it. If the question is media cost, use the billable impression field. Do not sum card impressions into the denominator of a spend-based CPM calculation.

    Preserve stable product identifiers from the feed through the Insights API export and into analytics or commerce data. Product names, prices and creative labels can change; a stable key is what lets you compare the same item across systems and reporting periods.

    A separate optimization change is on the roadmap. OpenAI plans to introduce a conversion model that considers click-through and view-through conversions, bills by impression and optimizes delivery toward a selected conversion goal. That would move campaign buying closer to automated performance advertising, but it should remain outside your current baseline until it is available and configured.

    When the model reaches your account, verify its attribution settings before comparing it with older campaigns. In particular, establish how your team will treat view-through credit, conversion delays and overlapping attribution from other channels. Paying by impression while optimizing toward conversions means click-through rate alone will be an incomplete scorecard; cost, conversion quality and business value still have to govern the decision.

    Use natural-language campaign management with explicit controls

    A ChatGPT Ads Manager plugin can now create, manage and analyze campaigns from ChatGPT or Codex using natural-language instructions. It can generate ads from a website or brief, produce variants, troubleshoot campaigns and recommend changes. Advertisers are asked to confirm recommended updates before they are applied.

    The confirmation step is important, but approval is only as good as the brief behind it. Give the tool a structured operating specification rather than an open-ended request to improve performance:

    • Objective: the business decision and the single primary conversion.
    • Market: the eligible country, language and any offer restrictions.
    • Audience: inclusion logic, exclusions, identifiers and audience version.
    • Creative boundaries: approved claims, prohibited claims, brand requirements and available assets.
    • Landing destination: the page associated with each offer or product group.
    • Reporting cuts: campaign, audience, creative and product dimensions required for analysis.
    • Change control: return assumptions and proposed edits for review; do not apply a recommendation until the named owner confirms it.

    Review generated variants for factual accuracy, offer consistency and landing-page alignment. Review troubleshooting recommendations against the measurement brief rather than accepting them because they sound plausible. A tool can shorten drafting and analysis; your team still owns the conversion definition, data permissions, budget exposure and final approval.

    Keep paid ChatGPT performance separate from organic AI visibility. An ad click, an unpaid referral, a brand mention and a citation inside an AI-generated answer represent different mechanisms. Give paid campaigns their own campaign identifiers and cost reporting, then assess organic discovery through a separate SEO, AEO or GEO measurement view. Combining them into one ChatGPT traffic total makes both strategies harder to improve.

    Your next move is a preflight, not an automatic budget shift. Confirm market and account availability, select one primary conversion, validate the approved identifiers, document the difference between billable and card impressions, and create a controlled campaign draft. Approve spend only when those choices fit on one page and every metric has an owner.

    References


  • Human Judgment Is the Control Layer for Automated Ads

    Human Judgment Is the Control Layer for Automated Ads

    You have an hour-of-day row with spend and no conversions, an automated campaign that feels opaque, and someone asking you to "fix the waste." Excluding the hour looks decisive. It is also exactly where human judgment matters: not because a person can outbid a system one auction at a time, but because only a person can decide whether that row is mature, meaningful, and worth turning into an eligibility rule.

    Your job in automated advertising is no longer to touch every lever. It is to define the right outcome, protect the quality of the inputs, challenge weak evidence, and own changes that remove opportunities. The practical goal is not more manual control. It is better control over what the automation is allowed to decide.

    Put human judgment at the decision boundary

    Automated systems are strongest when they make frequent decisions inside a clearly defined objective. A bidding system can evaluate an auction, combine contextual signals, and adjust its bid faster than a campaign manager could. It cannot decide whether the objective itself represents a profitable customer, whether an overnight lead will receive an acceptable response, or whether the business should trade margin for growth.

    That distinction gives you a usable division of responsibility:

    DecisionWhat automation should doWhat a person must own
    Auction executionEvaluate eligible auctions and adjust bids within the chosen strategy.Choose the business objective, budget, constraints, and acceptable tradeoffs.
    Data preparationGroup records, calculate fields, identify anomalies, and assemble recurring reports.Verify definitions, attribution, data maturity, and whether the records represent real business outcomes.
    Campaign eligibilityRespect targeting, schedules, exclusions, and other account settings.Decide which opportunities the campaign should never be allowed to enter.
    Performance diagnosisSurface patterns and produce candidate explanations.Determine which explanation is credible and what evidence would disprove it.
    Final approvalPrepare a recommendation or execute an approved, bounded workflow.Accept accountability for the consequences and authorize the change.

    A simple boundary works well: let automation make high-frequency, reversible choices within an approved objective. Require human review when a decision changes the objective, conversion definition, customer promise, account eligibility, or exposure to wasted spend.

    Before approving an automated recommendation, ask four questions:

    • What outcome is the system actually optimizing?
    • Which business facts cannot be seen in the platform data?
    • Does this recommendation tune execution, or does it remove an audience, location, device, query, or time period from consideration?
    • Who will decide whether the result was acceptable after conversion lag and downstream sales are visible?

    If nobody can answer those questions, the problem is not insufficient automation. It is an undefined decision boundary.

    An ad schedule is an eligibility rule, not a cleanup tool

    Hour-of-day reports invite a common mistake. You see a weak average, label the period inefficient, and remove it. That reasoning treats every auction in an hour as if it had the same probability and value.

    Google Ads Smart Bidding works at a different level. Target CPA, Target ROAS, Maximize Conversions, and Maximize Conversion Value use auction-time bidding, with time of day and day of week among the contextual signals that can inform an individual bid. Device, location, and audience characteristics can also change the assessment. The system is not deciding that an entire hour is universally good or bad. It is evaluating the eligible auctions that occur during that hour.

    This makes the effect of scheduling easy to misread. Manual ad-schedule bid adjustments are not used by Smart Bidding, but the schedule itself is respected. Removing Tuesday morning does not tell the bidding system to be more selective on Tuesday morning. It makes every Tuesday-morning auction ineligible, including any valuable ones the hourly average concealed.

    A row with four clicks and no conversions proves only that those four recorded clicks did not yet show a conversion. It does not establish that the hour is intrinsically unprofitable. Nor does it estimate what would have happened in future auctions if the campaign had remained eligible.

    Scheduling can still be the correct decision when the restriction represents a real business constraint:

    • Home services and call-driven lead generation: Restricting delivery may be justified if an overnight inquiry cannot be answered promptly and the delayed response materially reduces its value. If those leads perform well when contacted later, the schedule would remove opportunity without fixing a business problem.
    • Appointment-based businesses: Capacity can be the binding constraint. Acquiring more demand may stop being useful once the available appointments are full.
    • Ecommerce: Customers can buy outside office hours. Operating hours alone therefore provide little basis for an exclusion; look for persistent differences in conversion value and profitability.
    • Restaurants: Opening hours, ordering hours, and reservation-search hours are not the same. Someone can make a valuable reservation before the doors open or after service ends.
    • B2B: Research does not stop at the office door. A nighttime search can produce a qualified inquiry that the sales team handles the following day.
    • News and publishing: Breaking events, elections, sports, and entertainment can move demand into hours that looked weak historically. A rigid schedule cannot anticipate every shift in attention.

    The rule is straightforward: use a schedule when you intend to prohibit participation, not merely because you want the bidding system to be cautious. If you would still want the right customer during that period, an absolute exclusion is a blunt response.

    Use a five-part evidence gate before restricting automation

    An analyst examines five visual checkpoints leading to a gated automation system.

    An automated account can generate more segmented data than a person can sensibly act on. There are 168 hours in a week before you add device, location, audience, campaign, or conversion type. Some rows will look unusually strong or weak by chance. Human judgment begins with refusing to confuse a visible pattern with a reliable decision.

    1. Wait for enough observations. Expand the date range until the pattern has had a reasonable chance to repeat. In many accounts, 60 to 90 days is a more useful starting window than a few recent days, but it is not a universal threshold. A high-volume account may mature sooner; a low-volume account or long sales cycle may need more time. The test is repeated evidence, not compliance with an arbitrary number of days.
    2. Let conversions mature. A click can convert hours or days later. Google Ads generally assigns the conversion to the date of the ad interaction, so a recent period may temporarily show its spend before all associated conversions have arrived. Check the account’s typical conversion delay before declaring yesterday evening inefficient. If the outcome data is still arriving, the conclusion is still changing.
    3. Inspect value below the average. Conversion count and average CPA may omit the result that matters. Review conversion value, lead quality, downstream sales, and customer value where those signals are available. A period with fewer conversions may still acquire better customers. Conversely, a superficially efficient period may be producing low-quality actions that never become revenue.
    4. Identify the business mechanism. Ask why the time period would be less valuable. A credible explanation might involve response time, fulfillment, inventory, staffing, or appointment capacity. If you cannot name a mechanism, treat the pattern as a question to investigate rather than a rule to implement. If the mechanism is operational, consider fixing the operation before suppressing demand.
    5. Test the restriction against broader eligibility. When traffic volume supports a meaningful comparison, test the scheduled version against a version that remains eligible for more hours. Use the business KPI that motivated the decision, allow for conversion lag, and change one major eligibility dimension at a time. One documented restaurant test found that unrestricted delivery produced 12% more conversions while reducing CPA by 3%. That is a single account result, not a universal benchmark; its value is showing why the counterfactual must be measured rather than assumed.

    This gate separates two different questions. The report asks, "What performance was recorded during the auctions that occurred?" The decision asks, "Will prohibiting future auctions improve the business result?" You cannot answer the second merely by sorting the first from worst to best.

    Document the decision before launch. Record the proposed restriction, the evidence window, known conversion delay, primary KPI, downstream quality check, operational rationale, test design, owner, and review point. That short record prevents a temporary anomaly from becoming permanent account folklore.

    Build an operating loop that removes labor, not accountability

    Two advertising professionals oversee a circular automated workflow while mechanical arms handle routine tasks.

    There are usually two kinds of automation in the same advertising workflow. The ad platform automates delivery and bidding. Analyst-facing AI can summarize meetings, organize exports, flag anomalies, draft formulas, generate basic scripts, and turn findings into review-ready formats. Both can save time, but neither should silently expand its own authority.

    Use this operating loop for consequential campaign changes:

    1. Frame the decision. Write one sentence naming the action under consideration and the business result it is meant to improve. "Reduce wasted spend" is too vague. "Determine whether overnight eligibility lowers qualified-lead profitability after leads have matured" can be tested.
    2. Assemble the evidence. Let approved tools merge exports, label time periods, calculate recurring fields, and flag unusual movement. AI is well suited to categorizing large datasets and surfacing changes that require investigation. Keep sensitive data inside approved systems and verify calculated fields before relying on them.
    3. Expose what the platform cannot see. Add sales acceptance, revenue, lead disposition, staffing constraints, inventory conditions, and other business context that is absent from the advertising interface. If the optimization signal rewards form submissions while the business needs completed sales, fix or supplement the signal before asking the algorithm to optimize harder.
    4. Generate challenges, not verdicts. Ask AI to find missing information, contradictory evidence, immature periods, unusually small samples, and alternative explanations. Do not ask it to make a final pause-or-expand decision from a summary table. AI can identify where something changed; the causal explanation still needs validation.
    5. Approve a bounded test. A person chooses the hypothesis, success measure, duration appropriate to the conversion cycle, and rollback condition. The system can then execute within those limits. Eligibility changes deserve particular care because the excluded auctions stop producing evidence once they disappear.
    6. Review and record the outcome. Wait for the agreed data to mature, compare the result with the predeclared KPI, check downstream quality, and record what changed. Meeting transcription and task extraction can remove administrative work by capturing decisions, owners, deadlines, and unresolved debates, but the meeting owner should review the output before it becomes the record.

    Prompt design should reinforce that boundary. Instead of asking, "Which hours should we turn off?" ask:

    • List time periods with persistent performance differences and show the observation count, date range, and conversion maturity for each.
    • Separate facts in the export from possible explanations that require validation.
    • Flag periods where conversion count, conversion value, and downstream lead quality point in different directions.
    • Identify which proposed actions tune execution and which actions remove campaign eligibility.
    • Draft a test plan and a list of missing inputs, without making the final approval decision.

    The same principle applies to technical work. AI can draft spreadsheet formulas, SQL, regex, account scripts, or reporting logic. Those outputs are useful because you can test whether they work. Review generated code, run it in a safe and limited context, and verify its output before it can change a production account. Fluent text is not proof of correct logic.

    Measure automation by the labor it removes and the errors it helps catch: rows reviewed, analysis time saved, anomalies surfaced, manual steps eliminated, revision cycles, and error rate. Measure the human control layer by decision quality: valid conversion signals, explicit ownership, mature evidence, reversible tests, and fewer unexplained account restrictions. Faster execution is valuable only when it carries a sound decision forward.

    Key takeaways

    • Let automated bidding make auction-level choices within a business objective that a person has defined and can defend.
    • Treat schedules, exclusions, and targeting limits as eligibility decisions. They remove opportunities rather than instructing Smart Bidding to bid more carefully.
    • Do not act on a weak hourly row until you have enough observations, mature conversions, business-value data, and a plausible mechanism.
    • Test restrictions against broader eligibility when volume permits. Historical averages do not reveal the outcome of auctions you choose not to enter.
    • Use AI to prepare evidence, find gaps, document decisions, and produce testable technical work. Keep strategy, prioritization, approval, and accountability with people.

    At your next account review, take one proposed automation change and label it either an execution aid or an eligibility decision. Automate the labor around the first. Put the second through the evidence gate before approving it. That small distinction is where responsible automated advertising starts.

    References