Category: Advertising

  • Audience Identity Match Rates: Find the Reach You Are Losing

    Audience Identity Match Rates: Find the Reach You Are Losing

    Your customer-list campaign can show a healthy click-through rate, conversion rate, and return on ad spend while missing a large share of the people you intended to reach. The reporting is not necessarily wrong. It is reporting on the customers the platform recognized, not everyone in the file you uploaded.

    Before you change bids, audiences, or creative again, measure that recognition gap. Audience identity match rate tells you whether the platform can use the audience you already paid to acquire.

    What audience identity match rate actually measures

    When you upload a first-party audience to Google Ads, Meta, or another paid platform, the destination attempts to connect identifiers such as hashed email addresses and phone numbers with its logged-in accounts. Records it cannot resolve fall out of the targetable audience.

    For an internal audit, use this operational formula:

    Audience identity match rate = matched audience / eligible records submitted x 100

    Keep the denominator consistent. Record the original export count, the number of eligible records you submitted, and any accepted-record count the platform provides. If one team calculates against raw CRM rows while another uses a cleaned and deduplicated upload, their percentages will not be comparable.

    Suppose you submit 100,000 eligible customers and the destination matches 55%. The platform recognizes 55,000 of them. The remaining 45,000 are not targetable through that uploaded list, regardless of your bid or creative quality. That does not mean all 55,000 matched customers will receive an impression; it means they have crossed the identity-resolution step and can become eligible for delivery.

    This distinction gives you three separate quantities:

    • Built audience: the customers who meet your CRM or customer-data-platform rules.
    • Matched audience: the portion the advertising destination can recognize.
    • Delivered reach: the matched people who actually receive an impression.

    Do not use reach or impressions as the numerator in your match-rate calculation. Those are delivery outcomes downstream of identity matching.

    Key takeaways

    • Match rate measures identity coverage, not campaign performance.
    • Calculate it separately for every destination, audience, and use case.
    • Inspect suppression lists as carefully as retargeting lists because an unmatched customer cannot be excluded.
    • Treat 70% as a useful triage heuristic, not a universal standard; identifier mix and platform behavior affect the result.

    Where a weak match rate quietly spends your budget

    Low match rates are often treated as a retargeting limitation. In practice, the same identity gap affects four different paid-media jobs:

    • Acquisition: Partially matched seed and exclusion lists give the platform less of the first-party signal you intended to provide. Rising customer acquisition cost can have many causes, but identity coverage belongs on the diagnostic list before you assume the bid strategy or creative is at fault.
    • Retargeting: At a 45% match rate, more than half of the intended list cannot enter that list-based retargeting audience. Campaign reporting can still look efficient because it describes the matched 45%, not the full customer group you selected.
    • Suppression: An exclusion only works for customers the platform recognizes. Unmatched existing customers can remain eligible for acquisition advertising, causing you to pay to reacquire people you already have. They may also see a new-customer offer that erodes margin or creates an avoidable customer-service problem.
    • Lookalike modeling: The platform expands from the matched part of your seed, not the complete file. If matched and unmatched customers differ systematically, the model learns from a narrower or skewed sample of the customers you considered valuable.

    Suppression and lookalike seeds inherit the same recognition problem as retargeting. That is why one account-wide match-rate average is not enough. A 70% retargeting rate does not compensate for a 42% suppression rate on a much larger customer list.

    Match rate also changes how you should read downstream metrics. A strong return on ad spend tells you the matched audience performed well. It does not tell you whether the destination recognized a representative share of the audience, whether exclusions worked, or whether your seed supplied the model with the customers you meant to supply.

    Run a 30-minute match-rate audit
    An analyst sorts anonymous audience records into matched and unresolved groups beside a laptop and timer.

    You do not need a new attribution model to establish a baseline. Start with the destinations already receiving the most money and make the calculation visible alongside the performance metrics your team reviews.

    1. Select your top three paid destinations by spend. Do not begin with every channel. The purpose of the first pass is to find whether the gap is material where it can cost the most.
    2. Choose two audiences per destination. Use one large targeting or retargeting audience and the largest suppression list. The suppression result often exposes waste that campaign-level efficiency reports cannot show.
    3. Capture the submitted count. Save the audience definition, extraction date, eligible row count, identifier fields included, and accepted-record count if the destination supplies one.
    4. Capture the recognized count. Google Ads provides a bucketed match-rate indication for Customer Match uploads. For Meta, compare the resulting audience size with the list sent. The two reporting methods are not equally precise, so label estimates and ranges rather than presenting them as exact counts.
    5. Calculate and classify the gap. If the platform provides a range, preserve the low and high estimate. Do not convert an imprecise platform value into a falsely precise percentage.
    6. Repeat after any pipeline change. Use the same audience definition and denominator so the new rate can be compared with the baseline.

    A small audit sheet is enough. Record these fields for every audience:

    Audit fieldWhat to recordWhy it matters
    DestinationGoogle Ads, Meta, or another paid platformMatch behavior differs by destination.
    Audience and purposeName plus acquisition, retargeting, suppression, or lookalikePrevents a blended rate from hiding a weak high-value list.
    Eligible inputRecords actually submitted for matchingProvides the denominator.
    Matched count or rangePlatform-reported rate or resulting audience estimateProvides the numerator or the closest available proxy.
    Identifier setEmail, phone, or bothShows whether limited identity inputs correlate with the gap.
    Extraction dateDate the file or sync snapshot was producedKeeps comparisons tied to a known audience version.

    Email-only lists commonly fall in a 40% to 60% range. A result above 70% is a reasonable signal to return your attention to creative, bids, and delivery, but it is not a guarantee that every relevant customer is covered. Use the threshold to prioritize work, not as a cross-platform leaderboard.

    Fix identity gaps in the right order

    A low rate does not automatically justify buying an enrichment product. First determine whether your own export, formatting, and identifier coverage are creating an avoidable loss.

    1. Verify the audience definition and counts. Confirm that the destination received the intended list, not an older export or a filtered subset. Reconcile the CRM count with the number actually submitted before diagnosing identity resolution.
    2. Check destination-specific preparation. Validate every field against that platform’s current formatting and hashing requirements. A phone number represented differently on each side may not resolve. Hashing protects the submitted representation; it does not turn inconsistent values into the same identifier.
    3. Use approved first-party identifiers together. If you legitimately collect both email and phone data, test a permitted multi-identifier upload against an email-only baseline. A customer may use a work address with you and a personal address on a social account, so one field can leave the platform without a usable bridge.
    4. Test record age. Compare recent customers with older cohorts using the same identifier set. If the recent cohort matches materially better, stale contact information is a more plausible problem than campaign configuration. Refresh data through legitimate customer interactions instead of guessing or silently appending questionable records.
    5. Evaluate connection-level enrichment only after the baseline. Require a clear description of what data is used, where it is processed, whether it is stored or written back, and how existing exclusions are preserved. A well-governed setup should not reintroduce identifiers deliberately withheld for privacy or compliance.

    Do not improve match rate by bypassing consent, purpose limitations, or fields your organization has excluded. The specific downside is larger than a weak campaign: you can create privacy, contractual, and compliance exposure while breaking the governance rules your customer-data system is supposed to enforce. The safe path is to improve recognition only with data your organization is entitled to use for that destination and purpose.

    Prioritize the fixes by economic consequence. Start with the largest suppression list on the highest-spend destination, then high-value retargeting audiences, acquisition exclusions, and lookalike seeds. This ordering addresses the place where a missed identity can make you pay for a customer twice before moving to less direct modeling effects.

    Prove the lift before you scale the change
    Two parallel audience test streams produce different numbers of identity connections before a closed gate to a larger audience.

    A higher match rate proves that the destination recognized more of the submitted audience. It does not, by itself, prove incremental revenue or better return on ad spend. The newly matched group may behave differently from the original matched group, so separate the identity result from the media result.

    1. Freeze the audience definition. Keep eligibility rules and the extraction window constant between baseline and treatment.
    2. Change one identity layer. Test corrected formatting, an additional approved identifier, a fresher data path, or enrichment separately when possible.
    3. Compare counts first. Verify that the input population stayed stable, then compare matched count and match rate. A larger upload is not a match-rate improvement.
    4. Hold media variables as steady as practical. Stable budgets, campaign structure, and creative make it easier to determine whether expanded recognition changed reach, conversions, customer acquisition cost, or return on ad spend.
    5. Measure suppression leakage separately. Flag acquisition conversions from people who already existed in your customer system before the campaign interaction. A falling leakage rate shows that exclusions are becoming more complete.

    Rokt mParticle reports that an identity-enrichment implementation for CKE Restaurants produced match-rate improvements of up to 117% on Google Ads and 29% on Meta, alongside improved return on the same spend. Those are vendor-reported, company-specific results, not a benchmark you should forecast into your own plan. They demonstrate what to test: whether better recognition expands usable audience coverage while the rest of the campaign remains substantially unchanged.

    Put one new line into your next paid-media review: the match rate of your largest suppression audience on your highest-spend platform. Establish the baseline, fix one failure point, and rerun the same calculation. Until that number is visible, you cannot tell whether you are optimizing the audience you built or only the fraction the platform happened to find.
    References

  • Curiosity-Driven Social Ads: A Practical Creative System

    Curiosity-Driven Social Ads: A Practical Creative System

    Your ad stops the thumb, but viewers leave as soon as the opening gives way to a familiar product pitch. The hook worked. The rest of the ad did not give them a reason to stay.

    The fix is not a louder opening or more frantic editing. You need a controlled sequence of questions, partial answers, proof, and payoff. That sequence turns a moment of attention into enough interest for someone to understand the offer and decide whether it is relevant.

    Key takeaways

    • A hook earns a pause. Curiosity earns the next few seconds by creating a question the viewer genuinely wants answered.
    • Build one primary information gap, then close it through a sequence of useful revelations rather than withholding the answer until the final frame.
    • Give creators a planned beat sheet but room to choose their own words. Natural delivery and deliberate structure can coexist.
    • Judge creative with retention, completion, replay, save, share, click, and conversion signals. No single metric tells you whether the ad is commercially effective.
    • Test the opening, revelation sequence, demonstration, and product transition separately so you can identify the part that changed performance.
    • Curiosity must repay attention. If the resolution is vague, irrelevant, or weaker than the promise, the ad becomes clickbait and trust falls with it.

    Build a curiosity chain, not a single hook

    Four connected tabletop scenes progressively reveal, demonstrate, and show the use of an unbranded product.

    Attention is an event: someone notices an unusual visual, a sharp line, or an unexpected result. Curiosity is a continuing state: the viewer notices that something remains unresolved and chooses to follow it.

    That distinction matters because Meta and TikTok increasingly use AI-powered delivery systems that respond to engagement, watch time, and downstream conversion behavior. An opening that produces a brief pause but immediate abandonment gives those systems less evidence of sustained interest than an ad people actively choose to finish, replay, save, share, or click.

    A curiosity gap is the distance between what the viewer knows and what they now want to know. It might be the cause of an unexpected result, the missing step in a demonstration, or whether a solution worked under a condition that resembles their own. It should not be a random mystery pasted onto an unrelated offer.

    Write the curiosity brief before the script

    Before anyone records, answer the following in plain language:

    1. What should the viewer understand by the end? Write the commercial conclusion without slogans. If you cannot state it clearly, the creative will wander.
    2. What question will carry the ad? Choose one primary question, such as why a familiar approach failed, what caused a surprising outcome, or whether a particular method can solve the viewer’s problem.
    3. Why does that question matter to this audience? Connect it to a recognizable frustration, risk, desire, or decision. Curiosity without relevance produces empty viewing.
    4. What evidence will resolve it? Select the demonstration, observation, comparison, explanation, or experience that makes the answer credible.
    5. Where does the product belong? Introduce it when the viewer can understand its role, not merely because the logo is due to appear.
    6. What is the complete payoff? State the answer you owe the viewer. The ending must satisfy the question created at the beginning.
    7. What should happen next? Match the call to action to the level of intent the ad has earned.

    This brief prevents a common mistake: opening with a compelling problem and then abandoning it for a feature list. Every beat should either advance the answer, provide proof, or help the viewer decide whether the answer applies to them.

    Use a question-and-answer ladder

    Do not keep one answer locked away while padding the middle. Give the viewer useful progress. Each beat can close a small question while opening the next logical one:

    • Opening tension: What happened, and why is it unexpected?
    • Relevant context: Why was the outcome a problem worth solving?
    • First revelation: What obvious explanation turned out to be incomplete?
    • Mechanism or demonstration: What was actually happening?
    • Product connection: How did the product change the process or result?
    • Resolution: What should the viewer conclude from what they have seen?
    • Next step: What can an interested viewer do now?

    The sequence should feel inevitable. If you remove the product and the opening story still reaches the same conclusion, the connection is probably too weak. If the product appears before the problem has meaning, the ad will feel like a disguised sales pitch.

    Make creator ads sound natural without leaving them to chance

    Conversational creator ads work differently from compressed brand spots. Longer, less polished creator videos are sometimes called yapper ads. They may move through a personal experience, an explanation, or a demonstration before naming the product. Their apparent looseness can make them feel like content someone chose to share rather than a commercial recited at them.

    That does not mean you should ask a creator to improvise the strategy. Most people will either disclose the conclusion too early, drift away from the main question, or remember the selling points and forget the promised payoff.

    Give the creator a beat sheet rather than a word-for-word script. Specify what each beat must accomplish, the evidence that must appear, any claim boundaries, and the final action. Let the creator choose the connective language, pauses, examples, and conversational rhythm.

    A reusable creator beat sheet

    1. Start inside the problem. Open with the moment the creator noticed something was wrong, surprising, or inconsistent with what they expected.
    2. Make the consequence concrete. Explain why the situation mattered without inflating the stakes.
    3. Show the first attempt. A failed assumption or incomplete fix gives the eventual answer context.
    4. Reveal the missing mechanism. Explain what changed the creator’s understanding of the problem.
    5. Demonstrate the product’s role. Show the action, process, or result instead of substituting adjectives for evidence.
    6. Close the original question. Return to the tension from the opening and provide a definite resolution.
    7. Invite the next step. Use a call to action that follows naturally from the resolved problem.

    A useful opening pattern is: I thought the obvious fix would solve this problem, but it made this specific symptom worse. The next beat must explain what happened. It cannot jump directly to a product name and leave the contradiction unresolved.

    Another workable pattern begins with a visible result, then asks what produced it. The demonstration supplies the answer in stages. This is especially useful when the product has a behavior viewers can see, because the proof becomes part of the story rather than a claim delivered over unrelated footage.

    During recording, capture complete thoughts and natural pauses. In editing, remove repetition but preserve the cause-and-effect chain. A jump cut should move the explanation forward, not create artificial urgency. The goal is not to make a conversational ad slow; it is to give each second a clear job.

    Protect the line between curiosity and clickbait

    Every open loop creates a debt. The viewer gives you time because the ad implies that an answer is coming. Honest curiosity repays that debt with an explanation, result, or demonstration that is useful even if the viewer does not buy.

    Clickbait uses the same surface mechanics but breaks the exchange. It exaggerates the opening, delays a simple answer without adding value, or resolves the story with information that has little to do with the promise. The problem is not merely tone. A disappointed viewer can abandon the video, ignore the call to action, or carry their distrust to the brand.

    Run a promise-payoff check

    Review the finished ad without sound first, then read its transcript without the visuals. In both passes, ask:

    • Can you state the opening promise in one sentence?
    • Does the middle provide meaningful progress, or does it merely postpone the answer?
    • Is the final answer specific enough to satisfy the opening?
    • Does the proof support the conclusion the viewer is asked to draw?
    • Is the product essential to the resolution, or has it been attached to an unrelated story?
    • Would a reasonable viewer feel that the time spent watching was respected?
    • Does the call to action follow from the evidence, or does it demand more confidence than the ad earned?

    Also inspect every transition. A strong transition answers one question and introduces the next. A weak transition changes the subject. When the ad jumps from a personal problem to a generic feature montage, curiosity collapses because the viewer can already predict the rest.

    Do not manufacture uncertainty around information the audience needs to evaluate the offer. The mystery should concern the story or mechanism, not whether the ad will eventually disclose a meaningful condition. The more consequential a fact is to the buying decision, the less useful it is as a tease.

    Measure the whole attention-to-action sequence

    A smartphone projects a path of glowing steps through a lens and doorway toward a hand reaching for a product.

    The traditional focus on the first three seconds is still useful, but it answers only whether the opening earned a chance. It does not tell you whether the story sustained interest, the proof created confidence, or the offer produced action.

    Read performance as a sequence of signals:

    • Initial attention: Did viewers stay beyond the opening instead of leaving immediately?
    • Sustained interest: Did watch time and completion behavior indicate that the middle held attention?
    • Active value: Did viewers replay, save, or share the video, including sharing it through direct messages?
    • Commercial interest: Did clicks occur after viewers had enough context to understand the offer?
    • Business outcome: Did the resulting visits produce the downstream conversion the campaign was built to generate?

    Watch time, completion, replays, saves, shares, post-view clicks, and conversions provide different evidence of chosen attention. Read them together. A long watch with no commercial response may mean the story entertained but did not qualify the viewer. A strong opening followed by weak completion points toward a middle that became predictable, repetitive, or disconnected from the hook. Completed views without clicks can indicate that the payoff was satisfying but the product transition or call to action was not persuasive.

    These patterns are diagnostic prompts, not automatic verdicts. Placement, audience delivery, offer, landing experience, and campaign objective can also shape the result. Use the creative signals to identify the next question, then isolate that question in the next test.

    Test one part of the curiosity system at a time

    Begin with a control ad and create variants around a single creative decision. Keep the offer, core message, and other controllable campaign conditions stable where possible.

    1. Test the opening. Keep the body and payoff unchanged while changing the initial tension, visual, or question. This tells you which version earns the strongest entry into the same story.
    2. Test the revelation sequence. Keep the opening constant while changing how the explanation unfolds. Compare direct explanation with demonstration, personal experience, or a problem-and-discovery progression.
    3. Test the proof. Preserve the promise and product role while changing the evidence used to resolve the question.
    4. Test product timing. Introduce the product at different logical points, but do not change the ending. Look for the point at which its appearance feels informative rather than interruptive.
    5. Test the payoff and call to action. Keep the preceding story stable while changing how explicitly the conclusion connects the result to the next step.

    Do not select a winner from the opening signal alone. The variant that stops more people can still attract poorly matched attention or fail to hold it. Compare retention behavior with clicks and downstream conversions, then choose the creative that advances the campaign’s actual objective.

    Keep a simple test record containing the hypothesis, the element changed, the control, the observed retention pattern, and the business outcome. This turns individual ads into reusable knowledge. Without that record, teams often repeat the same hook test while the real weakness sits in the middle of the story.

    Start with one active ad. Print its transcript, underline the question created in the opening, and label the exact line that resolves it. Then mark what new reason to continue appears between those points. If the middle contains no useful progress, rewrite that sequence before producing another hook.

    Automated delivery can decide who receives the next impression. Your controllable advantage is making that impression worth following. Build an honest question, reward each additional second, and let the sale follow from a conclusion the viewer was given enough evidence to reach.

    References

  • Web Push Advertising in 2026: A Shift Toward Quality

    Web Push Advertising in 2026: A Shift Toward Quality

    Web push advertising is not disappearing, but the conditions that once rewarded scale are changing. Easier opt-outs and tighter platform enforcement have made subscriber quality, compliant messaging, and durable performance more important.

    A sponsored article published by Search Engine Land and supplied by RollerAds presents the channel as a maturing market rather than a declining one. Its figures and platform observations point to modest growth, alongside near-term pressure for publishers, advertisers, and ad networks.

    Platform controls changed the economics of push

    Web push lets opted-in users receive browser-based notifications outside a publisher’s active webpage. That reach can make the format useful for timely campaigns, but it also means poor messaging practices can become intrusive quickly.

    According to the Search Engine Land article, Google introduced changes in the fourth quarter of 2024 that made unsubscribing more accessible on Android and strengthened Google Safe Browsing policies. The stated direction was greater user control, fewer deceptive notification practices, and better engagement quality.

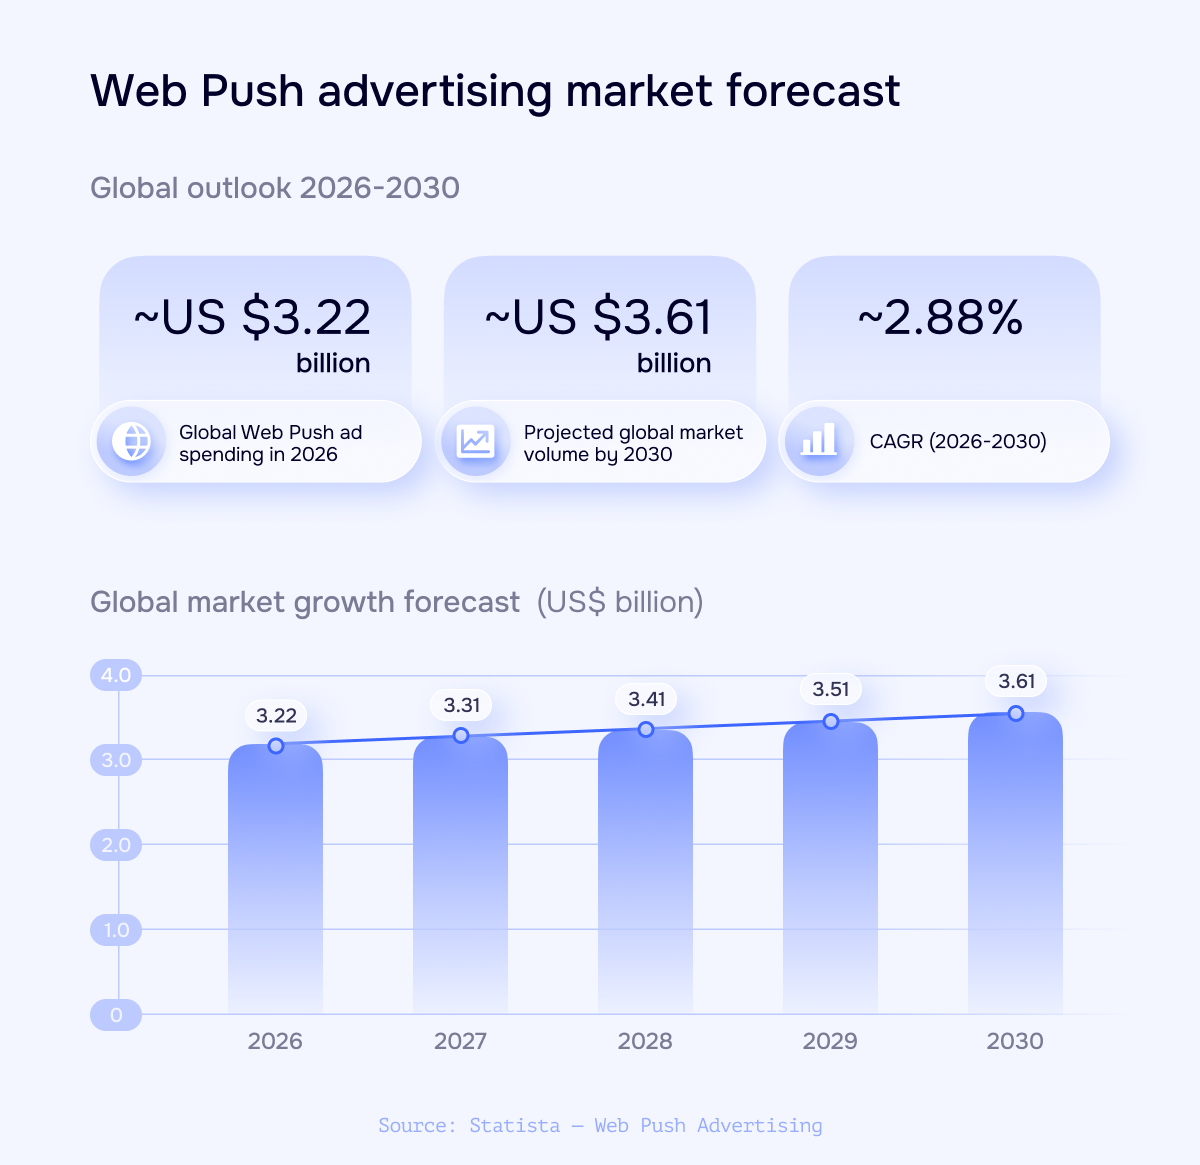
    Chart forecasting web push ad growth from US$3.22 billion in 2026 to US$3.61 billion in 2030.
    Global web push advertising is shown rising from about US$3.22 billion in 2026 to US$3.61 billion in 2030, with a stated 2026-2030 CAGR of roughly 2.88%.

    The immediate commercial effect was less comfortable. RollerAds reported that unsubscribe rates increased by 30% to 40% in some cases on its own platform. The article also says some domains were flagged, restricted, or banned over compliance problems and negative quality signals. That platform-specific result should not be treated as an industry-wide rate, but it illustrates the exposure publishers face when access to an audience depends on browser rules.

    The forecast describes maturity, not rapid expansion

    The market outlook cited in the source projects global web push ad spending of about US$3.22 billion in 2026 and approximately US$3.61 billion in 2030. The reported compound annual growth rate for 2026 through 2030 is about 2.88%.

    YearProjected global spending
    2026About US$3.22 billion
    2027About US$3.31 billion
    2028About US$3.41 billion
    2029About US$3.51 billion
    2030About US$3.61 billion

    These projections indicate continued expansion, but not a return to a volume-at-any-cost phase. Moderate growth is consistent with a channel moving toward established use cases, more selective inventory, and closer scrutiny of traffic quality. The forecast does not guarantee better returns for an individual campaign; results will still depend on targeting, creative, acquisition costs, and the quality of the underlying subscriber base.

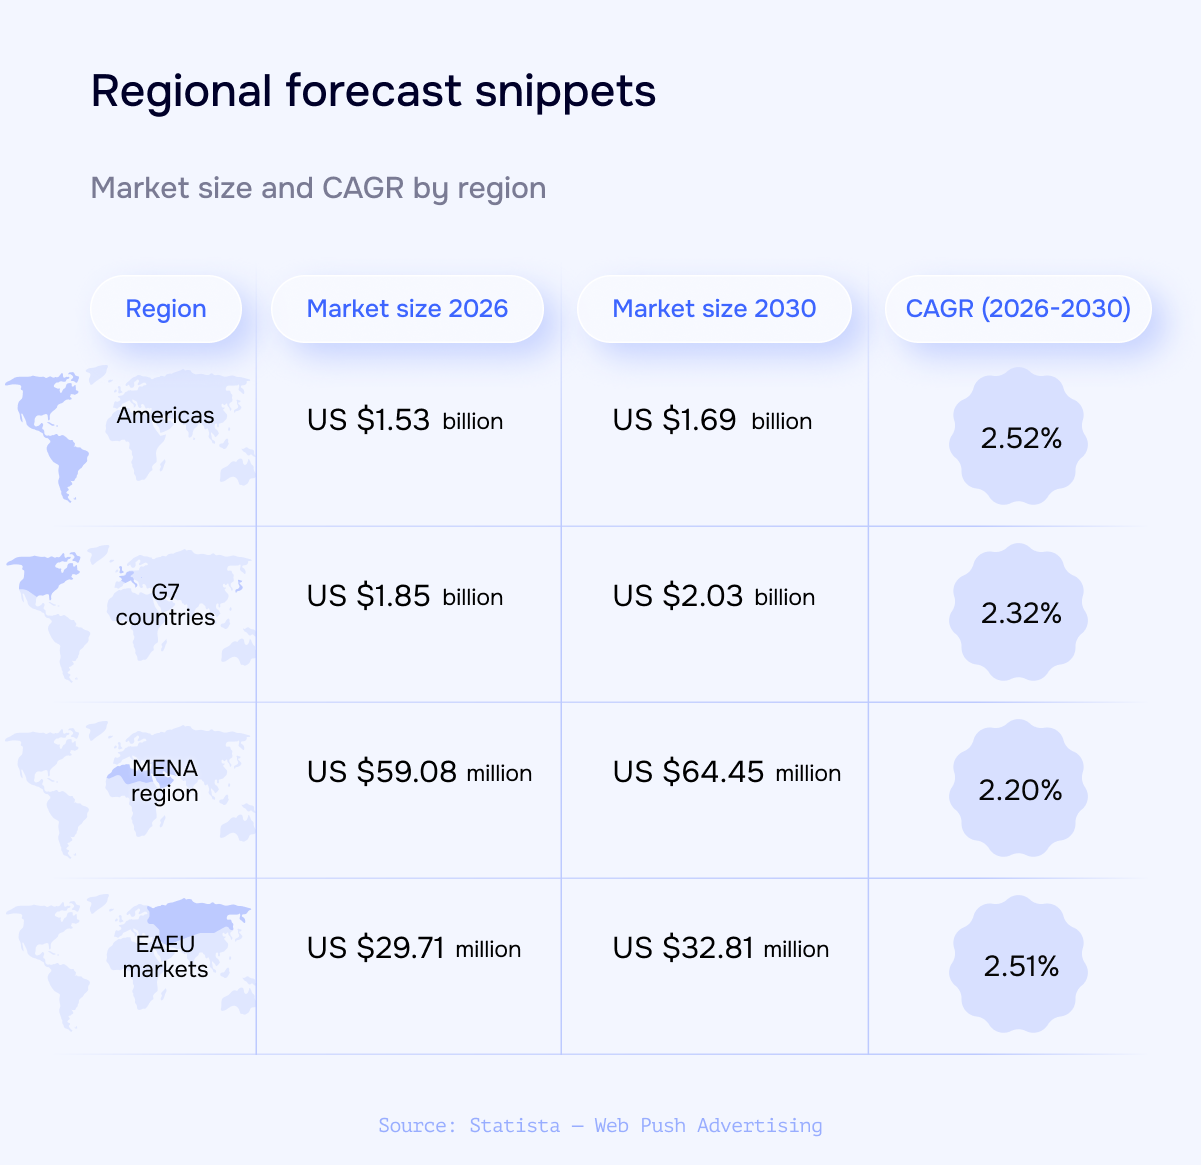
    Table comparing 2026 and 2030 market sizes and CAGR for the Americas, G7, MENA, and EAEU.
    Regional forecast table lists 2026 and 2030 market sizes for the Americas, G7 countries, MENA region, and EAEU markets, with CAGR from 2.20% to 2.52%.

    Regional projections point in the same direction

    The regional forecasts cited by the article vary in size and pace, yet all four examples show growth through 2030.

    Market20262030Reported CAGR
    AmericasAbout US$1.53 billionAbout US$1.69 billionAbout 2.52%
    G7 countriesAbout US$1.85 billionAbout US$2.03 billionAbout 2.32%
    MENAAbout US$59.08 millionAbout US$64.45 millionAbout 2.20%
    EAEU marketsAbout US$29.71 millionAbout US$32.81 millionAbout 2.51%

    The differences are relatively narrow in growth-rate terms. As the source interprets them, they reflect varying levels of market maturity and digital advertising penetration rather than opposing regional trajectories. The projections are best used as market context, not as a substitute for country-level campaign evidence.

    Key takeaways

    • Web push remains a growing advertising channel in the forecast cited by Search Engine Land, although its expected growth is moderate.
    • More accessible opt-outs can reduce the size of a subscriber list while making consent and audience relevance more visible performance factors.
    • RollerAds’ reported 30% to 40% unsubscribe increase applies to some cases on its platform, not necessarily to the whole market.
    • Stricter enforcement raises compliance risk for publishers and networks using misleading language or low-quality traffic.
    • Advertisers should judge the channel by qualified engagement, acquisition economics, and customer value rather than notification volume alone.

    What advertisers and publishers should change

    For publishers, the central issue is no longer simply how quickly a subscriber list can grow. They need clear opt-in expectations, messaging that matches what users agreed to receive, and monitoring that reveals whether campaigns are driving engagement or accelerating opt-outs.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    Advertisers should examine the source and quality of push inventory, segment audiences by relevant behavior, and test the complete funnel rather than optimizing only for clicks. A high click-through rate can still be unhelpful if the post-click experience fails to produce worthwhile outcomes. Networks, meanwhile, have an incentive to improve screening and technical controls because weak supply can expose every participant to policy and performance problems.

    The source argues that lower message pressure may eventually support stronger engagement and click-through rates, but that remains an expectation rather than a guaranteed timeline. The safer conclusion is narrower: web push still has a market, while its next phase will favor operators that can demonstrate relevance, compliance, and sustainable economics.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • The Economics Behind ChatGPT’s $100 Billion Ad Target

    The Economics Behind ChatGPT’s $100 Billion Ad Target

    ChatGPT advertising is being framed as a potential bridge between conversational AI and the large budgets already committed to digital media. The central economic question, however, is not whether ads can appear in a chatbot. It is whether the format can attract enough demand, usage and measurable commercial activity to support OpenAI’s reported revenue ambitions.

    A comparison reported by CrushPress.AI illustrates the uncertainty: OpenAI’s projection for its own advertising business is dramatically larger than Emarketer’s forecast for the entire U.S. standalone-chatbot advertising market. Understanding that discrepancy requires separating the headline numbers from their scope and underlying assumptions.

    Key takeaways

    • CrushPress.AI reported that OpenAI projected $2.5 billion in advertising revenue for the year discussed in the source and $100 billion by 2030.
    • The same article cited Emarketer’s forecast of less than $1 billion for the U.S. standalone-chatbot advertising market in that year and $5.41 billion by 2030.
    • The figures signal a major expectations gap, but they are not necessarily like-for-like because Emarketer’s estimate is limited to the United States and a defined set of standalone chatbot experiences.
    • Reaching OpenAI’s target would likely require more than inserting conventional ads into conversations; it would depend on substantial advertiser demand, commercial user activity and credible measurement.

    The forecasts describe radically different economic outcomes

    According to CrushPress.AI, OpenAI began testing ChatGPT ads in February and, by April, was projecting that advertising revenue would reach $100 billion within five years. The article also reported a $2.5 billion advertising-revenue projection for the year covered by the forecast.

    Emarketer’s outlook, as presented in the article, is much smaller. It estimated that U.S. advertising across standalone chatbots would generate less than $1 billion in the same year and rise to $5.41 billion by 2030. CrushPress.AI characterized OpenAI as being on course to miss its 2030 target by roughly 90% if the market develops along Emarketer’s forecast.

    ForecastNear-term figure reported2030 figure reportedStated scope
    OpenAI advertising projection$2.5 billion$100 billionOpenAI’s advertising business; geography was not specified in the supplied report
    Emarketer market forecastLess than $1 billion$5.41 billionU.S. standalone-chatbot advertising market

    The contrast is economically significant even before attempting a direct comparison. One outlook anticipates a very large revenue stream for a single company, while the other expects the defined market category to remain comparatively modest through 2030.

    The scope mismatch matters as much as the revenue gap

    A large sphere of conversation bubbles outweighs a smaller geographically bounded cluster on a balance scale.

    Emarketer’s forecast covered standalone chatbot products in the United States. CrushPress.AI said the category included ChatGPT, Microsoft Copilot, Google AI Mode and Amazon Alexa for Shopping, formerly known as Rufus. OpenAI’s target, by contrast, was presented as a company advertising goal without an equivalent geographic or product-boundary definition in the supplied article.

    That makes the comparison useful as a stress test, but not a definitive like-for-like verdict. OpenAI could be assuming revenue from markets outside the United States, advertising products that extend beyond a narrow standalone-chatbot definition, or commercial experiences that Emarketer classifies elsewhere. The source does not establish that those possibilities are included, so they should be treated as potential explanations rather than facts.

    The reverse caution also applies. A broader addressable market does not automatically produce broader revenue. OpenAI would still need to turn that potential into inventory advertisers value, demand they are willing to fund and outcomes they can evaluate.

    What would have to be true for the target to work

    A central conversational portal connects to an audience, a storefront, a measurement gauge and a privacy shield.

    CrushPress.AI described OpenAI’s forecast as resting on several ambitious assumptions: capturing search-advertising budgets at scale, leading a mature chatbot-ad market and outperforming previous advertising formats. Each assumption represents a separate economic hurdle.

    • Budget transfer: Advertisers would need to treat conversational placements as a meaningful destination for money currently assigned to established channels, rather than merely adding small experimental budgets.
    • Commercial intent: ChatGPT usage would need to produce enough moments in which an ad is relevant to a purchase or business decision. High overall usage alone does not establish high-value advertising inventory.
    • Pricing power: Advertisers would need evidence that chatbot placements generate sufficient value to support attractive prices. That normally depends on relevance, scarcity, audience quality and demonstrated outcomes.
    • Measurement: The format would need dependable ways to distinguish exposure, influence and conversion. Conversational journeys can complicate familiar attribution models because an answer may inform a decision without producing an immediate click.
    • User acceptance: Commercial messages would have to coexist with useful answers without weakening confidence in the product. If monetization reduces engagement, additional ad load can undermine the inventory it was intended to create.

    These conditions are connected. Strong purchase intent can improve pricing, credible measurement can accelerate budget movement, and user trust can protect continued engagement. Weakness in any one of them can constrain the others.

    How advertisers should interpret the opportunity

    The reported forecasts do not support treating chatbot advertising as either a guaranteed successor to search advertising or an irrelevant niche. They support a staged approach in which advertisers evaluate the channel based on observed behavior rather than the platform owner’s long-range target.

    Early assessments should distinguish inventory volume from inventory quality. Useful indicators would include whether placements appear during commercially relevant conversations, how clearly sponsored material is identified, what controls advertisers receive and which outcomes can be measured. Comparisons with paid search or other performance channels should use consistent conversion definitions and time horizons.

    The most informative signal will be whether chatbot advertising develops incremental demand of its own or primarily redistributes existing digital-ad budgets. OpenAI’s reported goal appears to require a market much larger than Emarketer’s defined U.S. category, making the eventual boundaries of the product and the source of advertiser spending central to the economics.

    As testing develops, the debate should become less dependent on top-down forecasts and more grounded in observable pricing, advertiser retention, measurable commercial outcomes and the effect of ads on user behavior.

    References

  • AI Ad Products Are Expanding Faster Than Disclosure Rules

    AI Ad Products Are Expanding Faster Than Disclosure Rules

    AI advertising is developing along two connected tracks: platforms are adding tools that make campaigns easier to create and manage, while also deciding how much people should be told about the technology behind an ad.

    Google’s creative-origin disclosures and OpenAI’s expanding ChatGPT Ads product show why transparency cannot be reduced to a single label. Users need to recognize paid placements, understand when AI shaped the creative, and know who remains responsible for the resulting claims.

    Key takeaways

    • Google is adding a “How this ad was made” section to My Ad Center for ads across Search, YouTube, and Discover, according to CrushPress.AI’s coverage.
    • Google will automatically disclose the use of its own generative AI ad tools, but advertisers using third-party AI tools will have control over disclosure, subject to local requirements.
    • ChatGPT Ads is adding audience, reporting, draft, and format capabilities, while its suggested ad drafts reportedly reuse website metadata rather than generating new copy or images with AI.
    • Effective transparency needs to distinguish the presence of an ad, the origin of its creative assets, and responsibility for its content.

    Advertising transparency now has two separate jobs

    A digital ad card is shown between symbols for paid placement and AI-assisted creation, with a human advertiser standing behind it.

    The first job is placement transparency: making it apparent that a recommendation, card, or other interface element is advertising. CrushPress.AI reported that OpenAI’s refreshed static ChatGPT ad card uses a clearer “Ad” badge, a more readable presentation, and larger visuals. That addresses the commercial status of the content rather than how it was produced.

    The second job is production transparency: explaining whether generative AI created or modified the ad creative. According to CrushPress.AI’s Google coverage, users will be able to open the three-dot menu or information icon on an ad and find a dedicated “How this ad was made” section inside My Ad Center. The disclosure is expected to cover ads on Search, YouTube, and Discover.

    These signals answer different questions. An ad badge tells a person why content is being shown commercially. A creative-origin disclosure explains something about how that content came into existence. A platform can provide one without fully providing the other, so treating either signal as complete transparency would leave an important gap.

    Google’s disclosure model mixes automation and advertiser choice

    Google’s reported approach creates two disclosure paths. When an advertiser uses Google’s own generative AI advertising tools, Google will automatically place the relevant information in My Ad Center. Because the platform can observe the use of its own creation tools directly, disclosure can be built into the workflow.

    The process is less uniform when creative comes from elsewhere. CrushPress.AI reported that advertisers using third-party AI tools will control whether to disclose that use. Depending on local requirements, an AI label may also appear on the ad itself, either automatically or after the advertiser uses the available control.

    This split reveals a central difficulty for AI ad governance: platforms have stronger evidence about activity within their own systems than about assets imported from outside. A dependable program therefore needs both technical detection or provenance signals and accurate declarations from advertisers.

    Google already embeds imperceptible signals, including SynthID, in material created with its generative AI tools, according to the same coverage. The source also noted that Google has required election advertisers to disclose synthetic or digitally altered content in political ads under a policy introduced in 2023. Those measures offer context for the new My Ad Center information, but they do not make all disclosure scenarios identical.

    Product automation does not always mean generative creation

    OpenAI’s reported suggested-ad workflow illustrates why precise language matters. When a campaign needs broader content coverage, ChatGPT Ads Manager may offer an “Add new ad” option that prefills an image, title, and description from existing website metadata. The advertiser can then review, edit, and assign the draft to a campaign and ad group.

    CrushPress.AI emphasized OpenAI’s statement that this feature does not generate new copy or imagery with AI. It is automated assembly, according to the description, rather than generative production. Labeling every automated advertising workflow as “AI-generated” would therefore obscure meaningful differences in how assets are sourced and transformed.

    That distinction becomes more important as the product develops. The reported ChatGPT Ads updates also include an overview tab for account health, recommended tasks and performance trends; audience-list uploads containing at least 25,000 users; audience inclusion or suppression; and ad-group bid multipliers. These are campaign-management capabilities, not evidence that the visible creative was generated by AI.

    The same report said ChatGPT Ads had expanded to Japan and South Korea. As an advertising system reaches more markets and adds targeting and optimization controls, transparency must cover the entire experience without collapsing targeting, workflow automation, generative creation, and sponsored placement into one ambiguous category.

    A practical transparency standard for advertisers

    A marketing professional reviews an advertisement through transparent layers representing sponsorship, AI involvement, and human approval.

    Advertisers can prepare for this environment by maintaining an internal record of where each asset originated, which tools materially changed it, who approved it, and which platform disclosures were selected. That record is a general operational safeguard rather than a platform-specific requirement, but it can support consistent decisions when rules differ by market, format, or creation tool.

    Teams should also separate three reviews. The first confirms that a placement is visibly identified as an ad. The second determines whether the creative requires an AI-origin disclosure. The third checks the underlying claims, identity, and offer for accuracy. Google’s existing prohibition on misleading or deceptive advertising still applies regardless of whether AI was involved, according to CrushPress.AI’s report; provenance information does not validate an ad’s message.

    Clear terminology will be as important as the controls themselves. “AI-assisted,” “AI-generated,” “AI-modified,” and “assembled from existing metadata” describe different processes. Platforms that make those distinctions understandable can give users useful context without implying that automation alone determines whether an advertisement is trustworthy.

    As AI advertising products mature, the strongest transparency systems will connect visible ad identification, reliable creative provenance, and continuing advertiser accountability. The next test is whether those elements remain coherent as more creation tools, formats, and markets enter the workflow.

    References

  • Why Marketing Automation Still Needs Human Oversight

    Why Marketing Automation Still Needs Human Oversight

    Marketing automation can react to campaign signals faster than a person, while marketing mix modeling can help explain performance across channels and longer time horizons. Neither capability removes the need for human oversight; each moves that oversight to decisions about goals, data quality, constraints, validation, and interpretation.

    The useful question is therefore not whether people or machines should control marketing. It is where human judgment has the greatest leverage in a system that combines rapid execution with slower, broader measurement.

    Automation and measurement address different decision gaps

    Campaign automation primarily shortens the gap between an observable signal and an action. The account described in the groas report used an automated system to adjust bids, budgets, keywords, match types, campaign activity, ad copy, and landing pages in response to Google Ads data. Its proposed advantage was continuous attention: a weak search term or drifting target could be addressed sooner than under a periodic manual review cycle.

    Marketing mix modeling (MMM) addresses a different problem. Rather than managing an individual auction, it estimates how channels and outside factors relate to business outcomes over time. the MMM report said a credible implementation may require two to three years of weekly data, consistent channel-level spending, offline activity, and external variables such as pricing, competitor activity, product launches, and macroeconomic conditions.

    These approaches operate at different speeds and levels of aggregation, but their dependencies converge. Both need a well-defined business outcome, trustworthy inputs, knowledge of exceptional events, and a person capable of challenging an apparently successful output. Faster optimization cannot repair a poorly chosen conversion goal, just as sophisticated modeling cannot compensate for missing or inconsistent historical data.

    DimensionCampaign automationMarketing mix modeling
    Primary purposeAct on account-level performance signalsEstimate contribution across channels and business conditions
    Reported data emphasisSearch terms, bids, budgets, devices, audiences, conversion tracking, and auction behaviorHistorical spend, outcomes, offline media, seasonality, pricing, launches, and external factors
    Main human responsibilitySet objectives, structure the account, establish guardrails, and review consequential changesSpecify the model, resolve data problems, test assumptions, calibrate estimates, and interpret uncertainty
    Failure riskRapidly optimizing toward the wrong signalProducing a plausible but misleading explanation of performance

    Human judgment matters before, during, and after automation

    Marketing specialists set campaign goals, monitor automated activity, and review outcomes across a continuous workspace.

    Before: define what the system should optimize

    The first oversight point is objective design. In the groas account, a human account manager reportedly audited campaign structure, keywords, bidding logic, budget allocation, conversion tracking, quality scores, search terms, and auction insights before automated optimization began. The report also acknowledged that people must communicate changes in products, pricing, and the relative importance of conversions. Those choices determine whether the system is improving a meaningful business result or merely making a platform metric look better.

    MMM has an equivalent setup problem. A modeler must decide which outcome to explain, how channels should be separated, which external variables belong in the model, and how unusual periods should be represented. The MMM source described the preliminary work as data archaeology because relevant records can be divided among finance, brand teams, agencies, and old spreadsheets. Human oversight begins with reconciling those records, not with selecting a modeling library.

    During: constrain action and investigate anomalies

    The reported groas rollout illustrates one way to limit early execution risk. It began with two weeks of observation, moved into calibration during weeks three and four, looked for traction in weeks five and six, and approached scaling in weeks seven and eight. This staged process is significant because automation should earn a larger operating range through observable behavior rather than receive unrestricted control on its first day.

    Oversight during MMM is more diagnostic than operational. According to the modeling source, practitioners still have to judge solutions along a Pareto frontier, assess whether an optimizer has converged, configure adstock behavior, and investigate implausible channel contributions. They may need to determine whether a suspicious result comes from an incorrect prior, a data error, or a variable that should be excluded. Code generation can reduce implementation effort without resolving any of those substantive choices.

    After: interpret evidence without overstating it

    Automated outputs still require a disciplined reading. The groas source reported a before-and-after comparison for a U.S. online mobile recharge account in which spend increased 18% to $164,000, ROAS rose from 1.02x to 1.32x, average CPC fell from $2.34 to $2, daily conversions increased from 571 to 739, conversion value grew 44%, and cost per conversion declined 14%. It also reported that active search campaigns were consolidated from 17 to 10.

    Those figures describe the source’s account snapshot, not an independently verified or universally transferable effect. A before-and-after account comparison can show that performance changed after an intervention, but by itself it does not isolate every possible cause. Seasonality, competitive conditions, demand, pricing, and concurrent business changes still need consideration. Human oversight includes distinguishing a promising operational result from a causal conclusion.

    Model sophistication does not neutralize weak inputs

    The MMM source compared three open-source options: Meta’s Robyn, Google’s Meridian, and PyMC-Marketing. It characterized Robyn as the most approachable of the three, Meridian as a more rigorous Bayesian option with uncertainty quantification and geo-level priors, and PyMC-Marketing as the most flexible but most demanding in statistical fluency. The availability of these libraries lowers the software and access barrier, but it does not make their results automatically reliable.

    This distinction also applies to campaign automation. A system may be technically capable of adjusting every available control while remaining unable to know that a tracking event is misconfigured, a temporary promotion has changed customer behavior, or a low-value conversion should no longer guide bidding. Greater execution coverage magnifies the value of clean signals, but it can also magnify the consequences of a bad specification.

    The common governance principle is proportional scrutiny. The more quickly a system can move money or the more strongly a model can influence allocation, the more clearly its inputs, permissions, assumptions, and escalation conditions should be documented. Transparency should cover not only what the technology changed or estimated, but also which human decisions framed the result.

    A supervised operating model connects action to learning

    A cross-functional team supervises a circular system of campaign actions, measurement signals, constraints, and revised decisions.

    A practical oversight structure separates responsibilities without separating the evidence. A strategy owner defines the business outcome and acceptable tradeoffs. A data owner protects conversion definitions, reconciles source systems, and records structural changes. A campaign operator monitors automated actions and intervenes when changes exceed agreed boundaries. A measurement specialist tests assumptions, communicates uncertainty, and uses experiments where possible to calibrate model estimates.

    These responsibilities should form a feedback loop. Campaign automation produces actions and fresh performance data. Broader measurement examines how channel activity relates to business outcomes. Incrementality experiments can help test selected assumptions, as the MMM source recommended. People then decide whether objectives, constraints, budgets, or measurement specifications need to change before the next cycle.

    Escalation should focus on changes that machines cannot interpret from performance data alone: broken or redefined tracking, a pricing shift, a product launch, an exceptional market disruption, an implausible channel estimate, or a budget move that conflicts with a strategic commitment. This allows routine optimization to proceed while reserving human attention for context-heavy and consequential decisions.

    Key takeaways

    • Campaign automation reduces response time, while MMM addresses cross-channel explanation; neither replaces the other.
    • Human oversight has three control points: defining objectives and inputs, governing execution and anomalies, and interpreting results.
    • Reported performance improvements should be evaluated in light of study design, business changes, and alternative explanations.
    • Open-source models and AI-assisted coding reduce technical barriers, but data reconciliation, assumption testing, and business context remain expert tasks.
    • The strongest operating model links automated action, measurement, experimentation, and human decisions in a documented feedback loop.

    As marketing systems gain more authority, oversight will need to become more explicit rather than more occasional. Organizations that define decision rights, preserve context, and test what their systems claim to learn will be better positioned to benefit from automation without surrendering accountability.

    References

  • How AI Advertising Signals Are Reshaping Audience Targeting

    How AI Advertising Signals Are Reshaping Audience Targeting

    AI-powered advertising is moving beyond simple demographic segments or keyword lists. The emerging model combines advertiser-supplied audiences, platform-native attributes, exposure data, creative inputs and conversion outcomes to help automated systems decide whom to reach and how to optimize.

    Reports about ChatGPT Ads and Microsoft Advertising illuminate different parts of that model. The former points to more direct audience control through customer-list uploads, while the latter shows how many supporting signals must work together before automated targeting can produce useful results.

    Key takeaways

    • CrushPress.AI reported an apparent ChatGPT Ads feature that accepts email- or phone-based audience lists, but the report was preliminary and did not establish match rates or performance.
    • Microsoft Advertising offers a broader signal mix that reportedly includes LinkedIn profile attributes, impression-based remarketing, landing-page imagery and conversion data.
    • An audience identifier tells an ad system who may be relevant; measurement signals tell it which outcomes should guide optimization.
    • More data does not automatically improve targeting. Clean tracking, concentrated campaign structure and relevant creative help automation interpret signals correctly.
    • Advertisers need governance for consent, list handling, exclusions and platform-specific policies alongside performance controls.

    Three signal layers now shape audience decisions

    Three layers of abstract customer, contextual, and outcome signals converge through a targeting lens toward a diverse audience.

    Advertiser-supplied identity signals

    CrushPress.AI reported that an Audiences area was appearing under Tools in ChatGPT Ads Manager. According to the report, advertisers could upload raw or hashed email addresses and phone numbers in CSV or TXT files, then use the resulting audiences as campaign filters. The account was based partly on screenshots attributed to Craig Graham and Joss Froggatt on LinkedIn, so it should be treated as an apparent rollout rather than a complete product specification.

    This type of first-party identity signal can connect an advertiser’s known customers or prospects with accounts recognized by an advertising platform. Its practical value depends on factors the report did not resolve, including audience matching, minimum usable size, availability across accounts, exclusions and measured lift. The important development is therefore not a guaranteed performance gain, but the appearance of a more direct way for advertisers to define relevant audiences inside a conversational advertising environment.

    Platform-native profile and exposure signals

    The Microsoft Advertising account describes a different source of audience intelligence: information already available within the platform’s ecosystem. It reports that LinkedIn Profile Targeting can support observation and bid adjustments, while Company, Industry, Job Function and Seniority data can serve as Performance Max audience signals. For B2B campaigns, those attributes can express professional relevance without requiring the advertiser to possess every prospect’s contact details.

    The same source highlights impression-based remarketing, which can reportedly include, exclude or adjust bids for people who have seen an ad. It says this method does not require an existing email list or site pixel and that a person may remain eligible for up to 30 days after one impression. Unlike an uploaded list, this signal reflects prior advertising exposure rather than a known customer relationship.

    Creative and outcome signals

    Audience targeting is only one part of an automated decision system. The Microsoft Advertising source also treats creative assets as signals: the platform can reportedly retrieve images from landing pages when that capability is enabled, using the advertiser’s own site as material for ad experiences. Strong, relevant imagery may help the system represent the offer, while unsuitable page images can introduce a different kind of noise.

    Conversion and attribution data complete the loop. The source identifies Microsoft Click ID, view-through conversions and simplified conversion setup as mechanisms that help connect advertising activity with outcomes. In general terms, identity and profile data indicate possible relevance, creative communicates the proposition, and conversion data tells automation which decisions appear to be working.

    Signal quality matters more than signal volume

    The two reports together suggest that AI targeting should be understood as signal engineering, not merely audience selection. Uploading a customer file may define a valuable group, but it does not establish the campaign objective, repair incomplete conversion tracking or ensure that the creative matches that group. Conversely, sophisticated bidding cannot recover reliable meaning from duplicated attribution, irrelevant conversions or poorly maintained landing-page assets.

    Campaign structure affects this interpretation. The Microsoft Advertising source argues that ad-group-level scheduling and location settings can reduce unnecessary campaign duplication and concentrate conversion activity. It also warns that automatic synchronization from an imported campaign can overwrite platform-specific changes. Importing from another advertising system may accelerate setup, but preserving the original account’s assumptions can prevent the destination platform from learning from its own audiences and auction conditions.

    Controls should be applied at the level where the underlying decision belongs. The source says Microsoft Advertising supports account-level phrase- and exact-match negatives, while noting that neither handles close variants. A broad account exclusion can remove unwanted traffic everywhere, but a nuanced restriction may belong at campaign or ad-group level. The broader lesson applies across AI advertising: guardrails help when they remove genuinely invalid choices, but overly broad rules can suppress useful learning.

    Measurement and governance determine whether targeting is useful

    A protected AI decision core filters audience signals through privacy, balance, and verification symbols before they reach groups of people.

    A useful evaluation begins by separating audience availability from audience effectiveness. The reported ChatGPT Ads capability answers a setup question: can an advertiser provide identifiers and use the matched audience as a filter? It does not, on the evidence supplied, answer whether that audience improves incremental conversions, lowers acquisition costs or simply reaches people who would have converted anyway.

    The Microsoft Advertising account emphasizes measurement before bid changes. That ordering matters because incomplete attribution can make an audience, keyword or bidding strategy appear responsible for a problem created elsewhere. Click-based and view-through measurements can also assign value differently, so teams need consistent definitions of the outcomes used to train automation.

    Before expanding an AI-targeted campaign, advertisers should establish:

    1. The targeting purpose: whether a signal is intended for inclusion, exclusion, observation, bid adjustment or automated prospecting.
    2. The source and freshness: where the data originated, how recently it was collected and whether it still represents the intended audience.
    3. The optimization event: which conversion actions represent business value and whether they are recorded consistently.
    4. The comparison: what control group, holdout or other baseline can distinguish incremental impact from ordinary demand.
    5. The creative fit: whether supplied or automatically retrieved assets accurately represent the offer for the selected audience.
    6. The governance boundary: whether collection, uploading, hashing, retention and activation follow applicable consent requirements and platform rules. Hashing changes how an identifier is represented; it does not by itself establish permission to use it.

    These checks also make cross-platform comparisons more meaningful. An uploaded customer audience, a professional-profile signal and an impression-based remarketing pool represent different relationships with a person. Treating them as interchangeable because all three appear under an audience label would conceal their different intent, reach and measurement requirements.

    The next advantage will come from coherent signals

    As conversational and established advertising platforms add more automation, audience access alone is unlikely to be a durable advantage. The stronger capability will be coordinating permissioned audience data, platform-specific context, suitable creative and trustworthy outcomes into one understandable learning loop. Marketers that can explain what each signal means, where it belongs and how its contribution will be tested will be better positioned to use new targeting controls without surrendering accountability.

    References

  • ChatGPT Ad Generation Puts Review Ahead of Automation

    ChatGPT Ad Generation Puts Review Ahead of Automation

    A reported ad-generation feature inside ChatGPT Ads could shorten the path from campaign setup to a usable creative variation. The important distinction is that the interface appears to generate a draft for approval, not a finished ad that bypasses advertiser judgment.

    For marketers, the practical value lies in faster iteration. The corresponding risk is treating generated copy as campaign strategy rather than as a starting point that still needs brand, accuracy, and performance review.

    What the reported workflow actually automates

    A visual workflow turns campaign inputs into several advertising drafts that await human selection.

    CrushPress.AI reported that an option to generate ads appears under the ChatGPT Ads platform’s ad-creation controls. According to the report, the system produces an ad variation using the advertiser’s website and campaign settings, then presents it for review, editing, and activation.

    That sequence matters. The reported interface positions artificial intelligence as a drafting layer within a conventional approval workflow. The marketer remains responsible for deciding whether the variation accurately reflects the offer, fits the campaign, and is ready to run.

    The report also describes a quick duplication option. Used carefully, that could support faster variation building: an advertiser could copy an existing ad, adjust one meaningful element, and compare the result with the original. The screenshot evidence does not, however, establish how widely the generation feature is available or how its output performs.

    Key takeaways

    • The reported tool uses website information and campaign settings to produce an ad variation.
    • Its workflow retains a human checkpoint before an ad is activated.
    • A duplication control could make structured creative variation easier, although speed alone does not create a sound experiment.
    • Generated copy still requires checks for factual accuracy, brand fit, campaign intent, and expected business value.
    • The available report shows an interface preview, not evidence of reach, output quality, or return on investment.

    Where generation can help and where it cannot

    Ad generation is most useful when the strategic inputs are already clear. A defined audience, offer, objective, and brand position give the system boundaries within which to draft. If those inputs are weak or inconsistent, quicker copy production can simply multiply the ambiguity.

    The feature may reduce mechanical work involved in producing a first variation. It cannot determine by itself whether a claim is sufficiently supported, whether the message creates the right expectation after the click, or whether a variation addresses the campaign’s actual constraint. Those are business and editorial judgments.

    The reported reliance on a website also introduces a source-quality issue. A generated ad may inherit unclear positioning, stale language, or overly broad claims from the page it uses. The output should therefore be checked against the current offer and campaign brief rather than assumed to be reliable because it originated inside the advertising platform.

    A review standard for AI-generated ads

    A marketing team checks an AI-generated ad mockup for imagery, layout, and approval criteria.

    A useful approval process begins with fidelity: the ad should describe the offer accurately and avoid introducing promises that the destination page cannot support. Reviewers should then assess whether the message reflects the intended audience and campaign objective instead of merely sounding polished.

    Brand review should cover voice, terminology, and the impression created by the ad as a whole. A grammatically clean variation can still be wrong for a brand if it exaggerates urgency, flattens an important distinction, or uses language the organization would not otherwise publish.

    Performance review requires discipline as well. The duplication control described in the report could encourage a large volume of near-identical ads. Marketers can preserve learning value by changing a deliberate variable, recording the hypothesis behind it, and judging results against the campaign’s established success measure. Generation increases the supply of options; it does not replace experimental design.

    The larger implication for campaign operations

    Embedding generation directly in an ad manager reduces the distance between source material, campaign configuration, and creative production. That convenience could lead to more variations being drafted and submitted, a commercial benefit that CrushPress.AI identified as potentially helpful to OpenAI’s advertising revenue.

    For advertisers, the more consequential change may be operational. As drafting becomes easier, quality control becomes the scarce capability. Teams will need clear ownership for approving claims, protecting brand standards, and deciding which variations deserve budget.

    The feature should therefore be evaluated less as an autonomous creative system and more as a workflow accelerator. Its long-term usefulness will depend on whether advertisers can turn faster production into better-controlled learning rather than simply a larger inventory of ads.

    References

  • How I Find Who Is Using My Brand in Paid Search Ads

    How I Find Who Is Using My Brand in Paid Search Ads

    I know competitive brand bidding is now a common PPC tactic, but that does not mean I treat it as harmless background noise. When competitors, affiliates, coupon sites, or misleading advertisers show up on branded searches, they can inflate CPCs, divert high-intent traffic, and confuse people who were already looking for my brand.

    I have seen how much difference visibility can make. Industry examples show that brands often uncover meaningful CPC inflation once they start tracking competitor bidding, affiliate activity, and trademark misuse. In documented cases, brands reduced branded CPCs by 25% to 75% after identifying infringing advertisers and enforcing their policies.

    In this guide, I walk through how I monitor branded keywords, identify who is advertising on them, and decide what actions may be available based on the evidence I find.

    Choosing Keywords So I Do Not Miss Hidden Activity

    When I want to find out who is using my brand in search ads, I start by deciding which keywords I need to monitor.

    The biggest mistake I try to avoid is watching only my exact brand name. That is a useful starting point, but it rarely shows the full picture. Some advertisers deliberately target brand-related coupon, discount, review, or alternative queries because those searches often come from high-intent users and attract less scrutiny.

    For example, someone searching for “Brand coupon” or “Brand discount code” may be much closer to buying than someone searching for the brand alone. Those queries often attract coupon affiliates, loyalty sites, and unauthorized advertisers trying to intercept branded traffic.

    I also pay attention to searches that include terms like “reviews” or “alternatives,” because those queries can bring in competitors and comparison sites that position themselves directly against my brand.

    Image

    Misspellings matter too. Some advertisers target spelling variations because they are less likely to be monitored and may face less competition.

    For a solid monitoring setup, I include my core brand name, “official page” and “login” variations, coupon and promo-code searches, review and alternative searches, commercial terms such as “buy,” “order,” and “sign up,” common misspellings, and localized versions of my brand name.

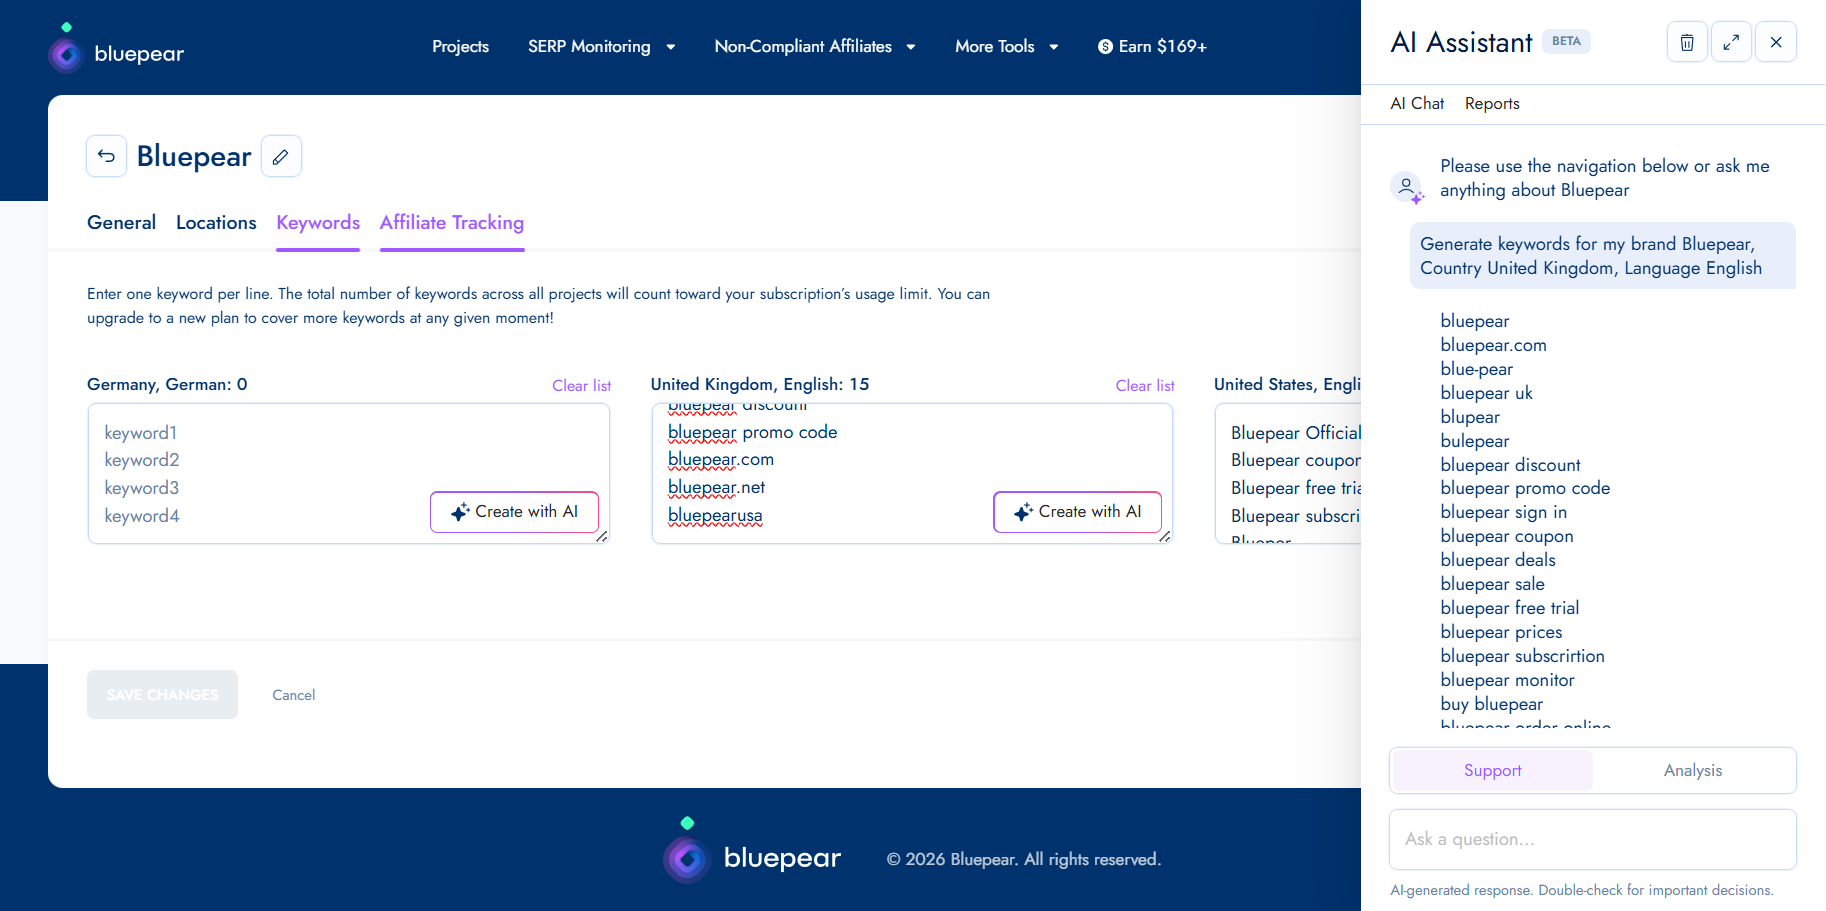
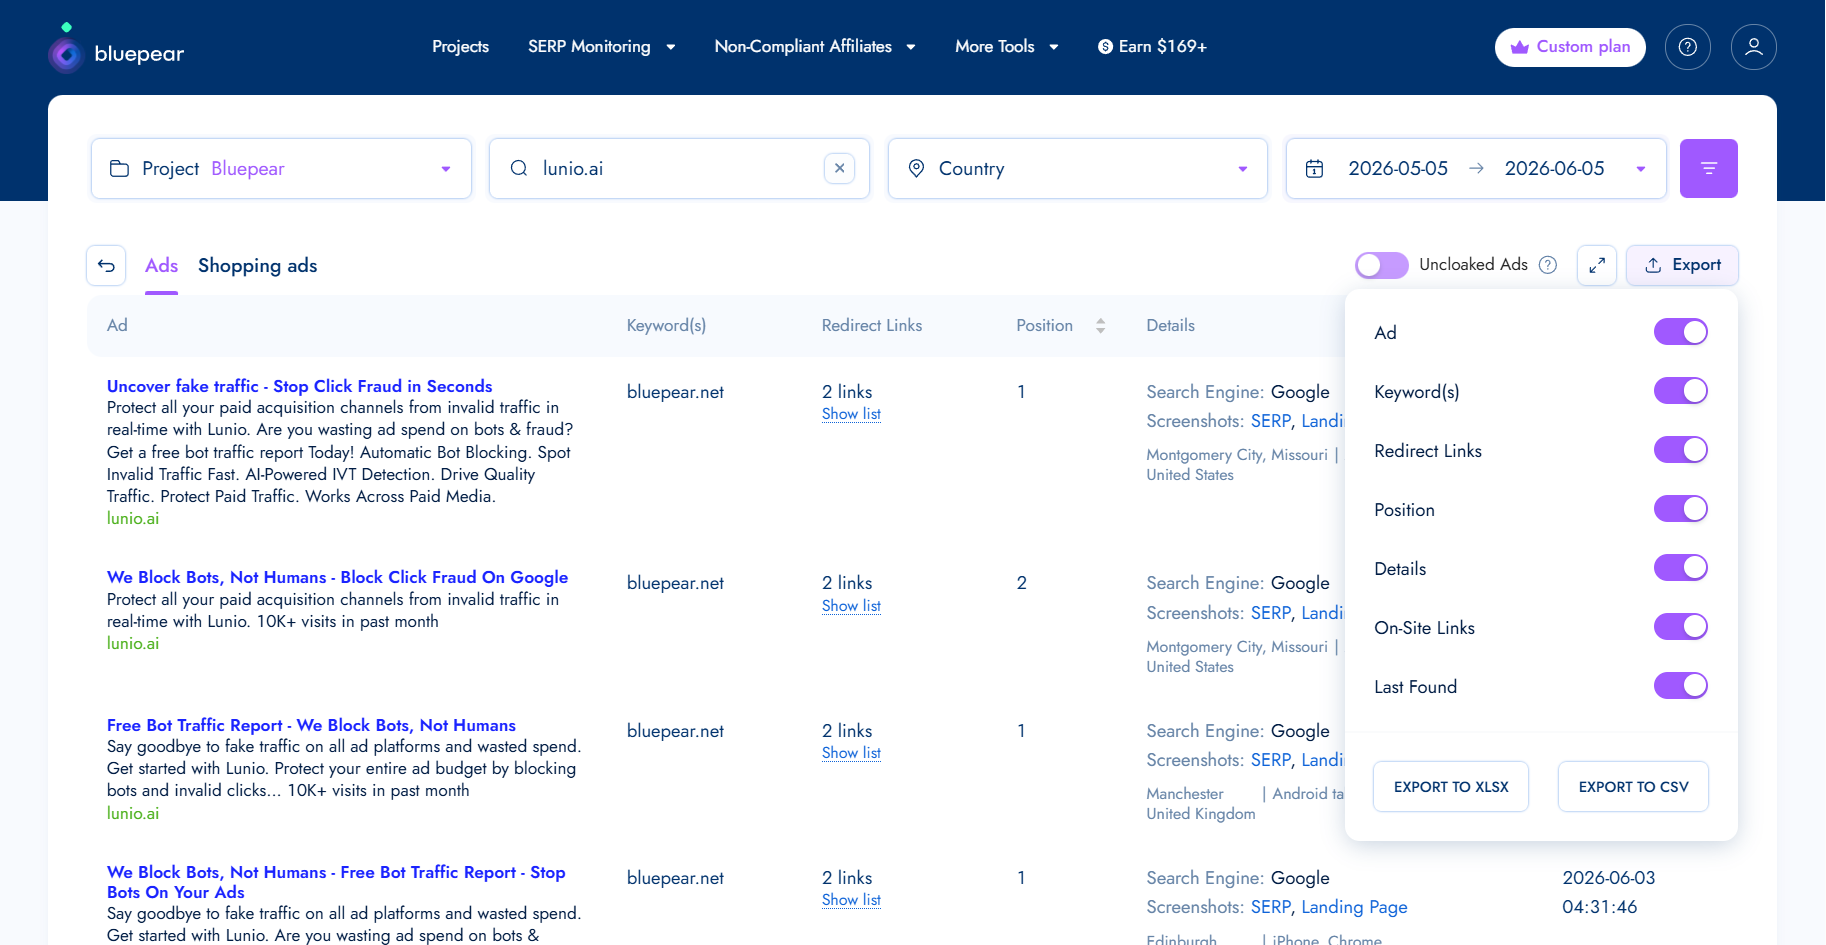
    If I am using Bluepear, its built-in AI assistant can generate keyword suggestions from this kind of list and help me expand coverage faster.

    The number of terms I monitor depends on the size of the brand portfolio, including trademarks, local branches, and product names. For many small to medium-sized brands, I would start with about 20 keywords and then expand as new risks, markets, and opportunities appear.

    Choosing Locations and Monitoring Frequency

    I do not rely on a single search from my office, on my device, at one moment in time. Search results are too dynamic for that. Two people searching the same branded keyword can see completely different ads and organic listings depending on their location, device, timing, and other variables.

    I also assume that some advertisers may be trying to hide their activity. A fraudster or an affiliate violating my PPC policy might run ads outside normal business hours to reduce the chance of being caught. If I only check manually during the workday, I may never see those ads.

    Image

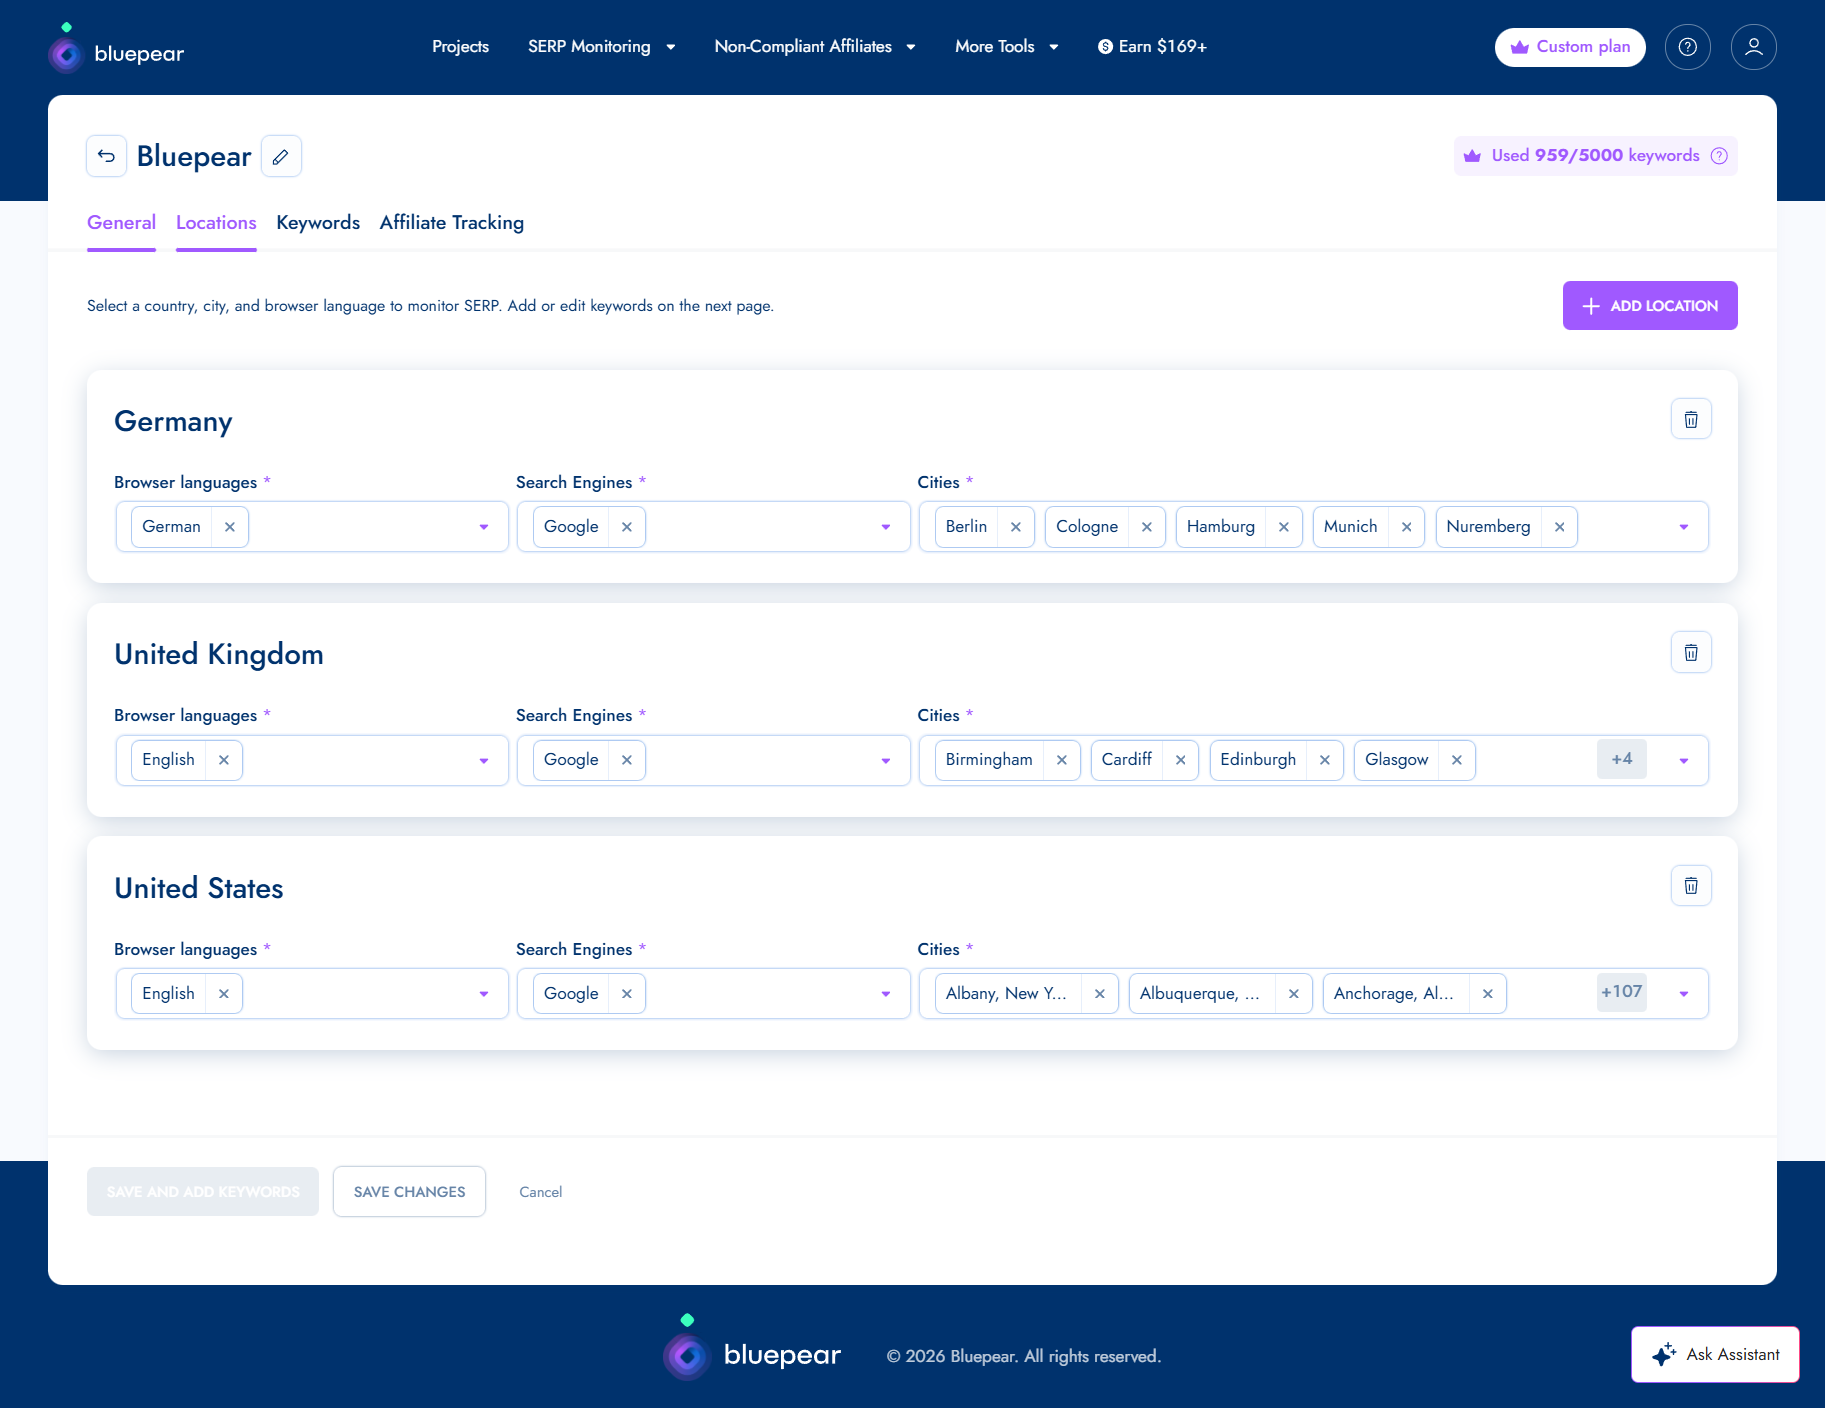
    When I monitor branded search results, I look across the countries and markets where my brand operates, regional differences within those markets, mobile and desktop results, different times of day, and weekday versus weekend activity.

    Frequency matters just as much as coverage. Some violations appear briefly and then disappear. Running checks multiple times throughout the day gives me a better chance of capturing activity that would otherwise go unnoticed.

    Tracking all of these variables manually can become tedious, especially when a brand operates across multiple markets. Bluepear accounts for locations, devices, time zones, and redirects that can obscure the true destination of traffic. I can set the parameters once and gain continuous visibility without turning monitoring into a weekly time sink.

    Reviewing Search Results and Recording Evidence

    I do not assume every advertiser bidding on my branded keywords is breaking a rule. Competitors may be allowed to bid on branded keywords if they do not use my trademark in their ad copy. Affiliates may also be authorized to promote my brand under specific program conditions.

    Still, I need to know when an advertiser’s behavior crosses the line from legitimate brand bidding into trademark misuse, policy violations, or customer deception.

    The first signal I investigate is trademark use in ad copy. If the ad mentions my brand name in the headline or description, and my trademark rules or affiliate policies restrict that use, I treat it as a possible compliance issue.

    Image

    I also look for misleading claims. Phrases that imply the advertiser is “official,” references to exclusive offers, or language that suggests authorization when none exists can confuse users and deserve review.

    Coupon and discount promotions need special attention. I verify whether the advertised discount, promo code, or offer is legitimate, because some affiliates use expired, misleading, or fabricated offers to win clicks.

    I also watch for impersonation signals. Some ads and landing pages are designed to resemble a brand’s official website. Even if the advertiser does not directly claim to be my company, that kind of presentation can still confuse users and divert branded traffic.

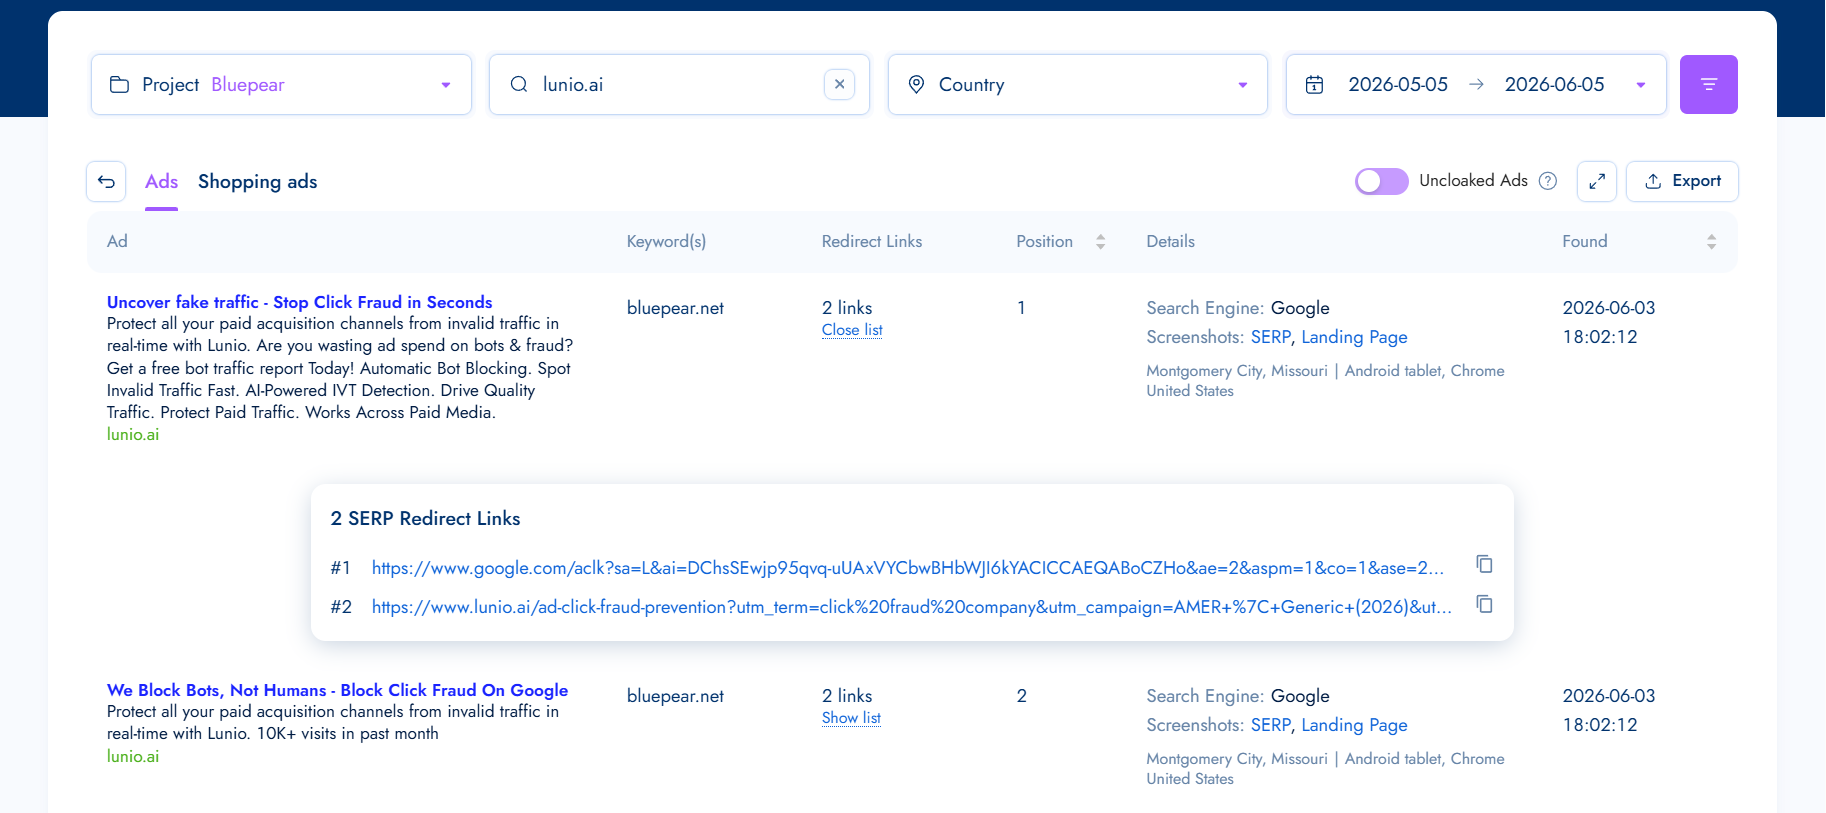
    Because advertisers can change ad copy, pause campaigns, or remove landing pages at any time, I collect evidence quickly. I record the ad copy, SERP position, triggering keyword, location, URLs, redirects, landing page content, and timestamps.

    Bluepear can handle this automatically by compiling a report with the relevant details, which makes follow-up easier when I need to contact an affiliate, review a competitor’s behavior, or escalate a trademark issue.

    Identifying Who Is Behind the Activity

    Sometimes I cannot immediately tell whether an advertiser is a competitor, an affiliate, a coupon site, or something riskier. Branded search results often include multiple participants with different motivations, so I need to understand who I am dealing with before I decide what to do next.

    Image

    I look for patterns. A direct competitor domain usually points to competitor bidding. A coupon or cashback page may indicate an affiliate, coupon site, or loyalty site. Affiliate network tracking links often suggest affiliate activity, although they can also appear in more questionable setups. Product comparison pages often point to competitors or comparison publishers.

    Other signals raise the risk level. If an ad uses my trademark, claims to be “official,” sends users through multiple redirects, promotes coupon codes I cannot verify, or lands on a page that imitates my brand’s design or messaging, I investigate more carefully.

    No single signal gives me a definitive answer. I combine multiple pieces of evidence before drawing conclusions. Once I know who is advertising on my brand terms, I can move beyond detection and decide whether their activity aligns with my policies and business goals.

    What I Do Next

    After I identify who is advertising on my brand terms and review their ads, the next step is choosing the right response.

    Competitor Brand Bidding

    Not every competitor bidding on my branded keywords requires immediate intervention. Before acting, I ask how often the competitor appears, which keywords they are targeting, whether they are using trademarked terms in ad copy, and whether they are sending users to comparison content or direct offers.

    In many cases, I monitor the activity and evaluate its business impact over time. Documenting patterns helps me establish a baseline, which can support future compliance reviews or legal conversations if escalation becomes necessary.

    Image

    Affiliate Violations

    If an affiliate is bidding on restricted branded keywords or violating program rules, I gather evidence and contact the affiliate or network. My workflow is straightforward: document the violation, verify the affiliate ID, share the evidence, request removal or corrective action, and apply program enforcement measures if needed.

    Screenshots, timestamps, and redirect data make those conversations much easier because I can show exactly what happened, where it happened, and when it was detected.

    Trademark Misuse

    Trademark-related issues require careful review. I look for unauthorized trademark use in ad copy, ads that create confusion about brand affiliation, impersonation attempts, and misleading claims that the advertiser is an official brand representative, partner, or reseller.

    The right response depends on the circumstances, internal policies, and applicable laws. In many jurisdictions, competitors are generally allowed to bid on trademarked keywords. However, ads that confuse users about the advertiser’s relationship with my brand may raise trademark or unfair competition concerns, depending on the facts and local law.

    The advertising platform’s policies matter too. Google allows advertisers to bid on trademarked keywords, but it may restrict trademark use in ad text when a valid trademark complaint is submitted. Google also prohibits ads that use trademarks in a confusing, deceptive, or misleading way.

    Before I take action, I collect as much evidence as possible, including screenshots, detection timestamps, URLs, redirects, and landing page content. Once the facts are documented, I may contact the advertiser directly, submit a trademark complaint to the advertising platform, send a cease and desist letter, or escalate through legal channels if necessary.

    Why I Keep Monitoring Brand Search

    The main lesson is that branded search protection is not a one-time audit. Affiliates can activate and pause campaigns throughout the month. Some violations appear only on weekends, outside business hours, or in specific markets. An advertiser that disappears today may return next week with new ad copy, a new domain, or a different affiliate account.

    That is why I treat brand protection as an ongoing process. Occasional searches are not enough. I need consistent monitoring and a repeatable investigation workflow that shows who is appearing on my brand terms, how they operate, and whether action is warranted.

    If I want easier visibility into my branded search landscape, Bluepear helps identify issues earlier, respond faster, and make more informed decisions about protecting traffic and advertising investments.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How AI Advertising Changes Measurement and Experimentation

    How AI Advertising Changes Measurement and Experimentation

    AI-driven advertising is making campaign delivery more adaptive while making performance harder to interpret. When platforms choose audiences, placements and combinations of creative, a conversion report can show what happened without revealing whether automation created additional demand, captured demand that already existed or simply shifted credit between channels.

    The useful response is not another all-purpose attribution metric. Advertisers need a layered measurement system that combines behavioral signals, downstream outcomes, controlled experiments and creative-quality checks. The source reports collectively show platforms moving in that direction, although each covers a different part of the problem.

    AI shifts the question from attribution to evidence

    Traditional attribution asks which interaction receives credit for a result. AI-driven campaigns create a broader question: what evidence shows that the campaign changed customer behavior? That distinction matters because an automated system may optimize successfully against its assigned conversion signal while producing little incremental value for the wider business.

    The reported expansion of YouTube measurement illustrates the shift. CrushPress.AI’s article on YouTube measurement said Google added Shorts Ad Actions to the budget optimization and reporting available for eligible Video View Campaigns. It also reported the global availability of Attributed Branded Searches, a Google Ads metric intended to identify branded Google searches following exposure to or a view of a YouTube ad.

    Those signals occupy different positions in the customer journey. A Shorts interaction describes behavior around the ad itself, while a subsequent branded search suggests that exposure may have influenced active interest. Neither is equivalent to a sale, but together they can provide a more informative path from attention to intent.

    The article relayed Google’s claim that Shorts ads associated with more than 10 seconds of watch time and a like delivered 15% higher brand consideration and 20% higher brand favourability. It also relayed Google’s statement that each additional branded search generated was associated, on average, with a $31 sales increase. These are reported platform findings and associations, not universal forecasts or proof that every additional search causes the stated sales gain.

    Signals form a measurement ladder, not a single score

    Four connected translucent platforms rise from behavioral signals to outcomes, a controlled test apparatus, and a verified decision beacon.

    AI advertising environments increasingly expose early indicators that are useful before a direct conversion occurs. The appropriate interpretation depends on how close each signal sits to the desired business outcome.

    Interaction signals diagnose relevance

    Ad dismissal is one example. CrushPress.AI’s report on ChatGPT advertising said OpenAI reported a 50% decline in dismissals after launching its advertising business and presented that change as evidence of improving relevance. A lower dismissal rate may indicate that ads feel less intrusive or more useful in a conversational setting, but it does not by itself establish incremental sales, profit or retention.

    This makes dismissal a diagnostic metric rather than a final business verdict. It can help determine whether an ad fits the user’s task and context. The same principle applies to watch time, likes and other engagement actions: they can reveal whether the experience is resonating, while stronger evidence is still required to justify budget.

    Intent and cross-channel outcomes strengthen the case

    Branded search can bridge the gap between engagement and conversion because people do not always respond through the channel that introduced them to a brand. The paid-social measurement article described a common pattern in which social advertising creates awareness and paid search later captures the visit or conversion. It recommended examining branded search activity, search click-through rate, conversion rate, lead quality, cost per acquisition and revenue-related outcomes before, during and after meaningful social changes.

    These comparisons are directional because public relations, email, influencers, product launches, seasonality and organic activity can also affect search behavior. Their value is in identifying a plausible relationship that deserves stronger testing. When branded search, search engagement and conversion efficiency move together after a campaign change, the combined pattern is more informative than any one metric viewed alone.

    Experiments are becoming the control plane for automation

    Two matched campaign environments run in parallel with one controlled variation, and their results feed back into an automation engine.

    Controlled experiments address the central weakness of observational reporting: the absence of a credible counterfactual. Instead of asking only how an AI campaign performed, an experiment asks what would likely have happened without the campaign or without the proposed change.

    Microsoft’s reported Performance Max experiment expansion separates two useful decisions. Uplift experiments compare Performance Max activity with a control group to assess incremental impact. Upgrade experiments compare an existing campaign with an upgraded Performance Max version before a broader rollout. The first tests whether the automated campaign adds value; the second tests whether changing the operating model improves results.

    Google’s Ads API v24.2 adds another level of experimental granularity. According to the source article, its COMPARE_CAMPAIGNS workflow can compare multiple campaigns or campaign types across as many as five experiment arms, including custom Performance Max experiments. A separate experiment can divide traffic within one Performance Max campaign to test text customization and final URL expansion.

    Together, these options point to three distinct testing jobs. Incrementality tests evaluate whether advertising creates additional outcomes. Upgrade tests evaluate whether a new automated campaign structure outperforms the current approach. Component tests isolate a feature or configuration inside the system. Treating these as separate questions prevents a successful feature test from being mistaken for proof that the entire campaign is incremental.

    Where platform-native experiments are unavailable, the cross-channel measurement article proposed geotargeted holdouts: paid social runs in selected test markets and is withheld from comparable control markets, with search and business outcomes compared across the groups. It also noted that this approach generally requires suitable markets, sufficient budget and enough time, while smaller advertisers may need to begin with carefully controlled pre- and post-campaign analysis.

    Creative and delivery must be measured as one system

    Automation changes what creative does. In broad-targeting systems such as Performance Max, Advantage+ and TikTok’s automated expansion, the creative does more than persuade a predefined audience. Its language, visuals, opening hook and call to action help people self-select and generate behavioral signals that influence future delivery.

    The source on creative qualification argued that specificity is therefore a performance control. A message that clearly states the relevant need, prerequisite or use case can discourage unqualified engagement while attracting people for whom the offer is appropriate. That can improve lead quality and reduce the noisy conversion data fed back into an automated system. A generic message may achieve inexpensive engagement while teaching the system to find more of the wrong response.

    Measurement should consequently connect asset-level engagement with qualified outcomes. High watch time or click-through rate is encouraging only when the same creative also contributes to appropriate leads, sales or other defined business results. Creative tests should preserve the qualifying elements that identify the intended customer, rather than optimizing hooks in isolation.

    Placement visibility is part of the same diagnosis. The Google Ads API v24.2 article reported that Performance Max placement views can be segmented by ad_network_type, providing more visibility into where performance occurs across Search, Display and partner networks. That does not remove every limitation of automated delivery, but it can help teams determine whether an apparent creative result is actually concentrated in a particular network or context.

    Build decisions around an evidence hierarchy

    A practical operating model begins by assigning each metric a job. Interaction metrics diagnose relevance, branded search and cross-channel efficiency indicate possible demand creation, and holdouts or platform experiments provide the strongest available evidence of incrementality. Business outcomes remain the decision target against which the other layers are judged.

    Key takeaways

    • Define the business outcome before choosing the platform optimization signal; the two should be connected but should not be treated as interchangeable.
    • Use dismissals, watch time, likes and clicks to diagnose relevance, not as stand-alone proof of commercial value.
    • Monitor branded search and paid-search efficiency to detect demand that an upper-funnel or social campaign may have created elsewhere.
    • Match the experiment to the decision: uplift for incrementality, upgrade tests for campaign migration and component tests for individual automation features.
    • Evaluate creative as both a persuasion mechanism and an audience qualifier, with lead quality or customer value checked alongside engagement.
    • Document delivery context, placement mix and AI-generated asset status so that experiment results remain interpretable and governable.

    The final point extends beyond performance reporting. The Google Ads API article also reported new fields for synthetic-content information and attestation. Such disclosures do not measure effectiveness, but they become important experiment metadata: teams need to know which assets were AI-generated, which controls were active and what changed between variants if they want results that can be audited and repeated.

    As automated platforms assume more control over delivery, measurement will need to become more deliberate rather than more passive. The teams best positioned for the next generation of ad products will be those that can connect useful early signals to cross-channel behavior, then challenge the apparent result with a credible control.

    References