Tag: Campaign Performance

  • Google Meridian Marketing Measurement: A Practical Guide

    Google Meridian Marketing Measurement: A Practical Guide

    Your paid-search dashboard says the campaigns are profitable. Brand demand was also rising, several other channels were active, and the customers who clicked may have intended to buy before they saw an ad. The dashboard can report the click. It cannot tell you how much of the outcome the advertising actually created.

    Google Meridian is built for that measurement gap. It uses aggregated marketing and business data to estimate incremental contribution without reconstructing individual customer journeys. Used carefully, it can give you a better basis for budget decisions. Used with weak data or overconfident assumptions, it can simply replace a misleading attribution number with a more sophisticated one.

    Choose Meridian for incrementality, not user-path attribution

    Google Meridian is an open-source, Python-based, fully Bayesian marketing mix modeling framework. It was introduced in 2024 and made available to marketers and data scientists in early 2025. Its purpose is not to produce a more detailed conversion path. It estimates how changes in marketing activity relate to changes in an outcome such as revenue, leads, or store visits.

    That distinction matters most in paid search. Under last-click attribution, a keyword can receive all the credit when someone clicks an ad and then buys. The method records what happened immediately before the conversion, but it cannot establish whether the ad generated the demand, captured demand created elsewhere, or intercepted a customer who was already looking for the brand. Meridian is designed to estimate the incremental revenue associated with search advertising rather than assigning credit to the final click.

    Use Meridian when your decision concerns channel-level or campaign-group investment over time. Suitable questions include:

    • How much of the observed revenue or lead volume was likely incremental to paid media?
    • Does branded search still look efficient after accounting for underlying search interest?
    • How should channel allocation change under a plausible budget scenario?
    • How does an experiment change the model’s estimate of a channel’s contribution?

    Do not use Meridian to answer which ad caused one person’s purchase, which exact sequence of touchpoints every customer followed, or what a single keyword will deliver tomorrow. Those are different measurement problems. Meridian works with aggregate patterns, so its useful resolution is constrained by the time, geographic, media, and outcome data you supply.

    This also explains why Meridian should complement rather than erase your operational reporting. Click and conversion data can still help with campaign pacing, landing-page diagnosis, and day-to-day execution. The mistake is treating those records as proof of incremental business impact.

    Treat search demand as a control, not proof of ad impact

    Search has an unusually difficult causality problem because demand often precedes the advertisement. A customer hears about your company, decides to visit, searches the brand name, and clicks the sponsored result. Spend, clicks, and sales all rise together, but the paid ad may not have caused the original intent.

    Meridian addresses part of this problem by allowing Google Query Volume to enter the model as a control variable. Query volume represents search interest, not paid-media performance. Including it can help the model separate underlying organic demand from paid-search effects.

    For your implementation, keep three data concepts separate:

    • Marketing input: paid-search spend, impressions, or the media variable selected for the model.
    • Demand control: query volume aligned to the same geographic and weekly structure.
    • Business outcome: the revenue, lead, or store-visit measure the model is supposed to explain.

    Do not substitute clicks for query volume and call the search-intent problem solved. Clicks are produced by the advertising system and sit inside the mechanism you are trying to measure. A demand control needs to represent the broader interest that may have existed without the paid click.

    Geographic variation provides another useful signal. Meridian’s hierarchical approach can model differences in spend and performance across regional or local markets. If one region’s media changes differently from another’s while you observe their outcomes, the model has more information with which to estimate incremental impact. If every region receives the same proportional budget change in the same week, geography adds far less identifying variation.

    Before modeling, plot spend, query volume, and the outcome by region. Look for markets that move in lockstep, regions with long missing periods, and abrupt jumps caused by reporting changes rather than customer behavior. You are not trying to find a pleasing correlation. You are checking whether the geographic panel contains real, explainable variation.

    Demand also changes without any media intervention. Meridian supports time-varying intercepts intended to account for seasonality, macroeconomic movement, and long-term organic growth in the baseline. That feature is important, but it is not permission to omit known business events. Record material pricing changes, distribution shifts, promotions, measurement changes, and other events that could move the outcome. The model cannot recognize an undocumented reporting break as a reporting break.

    Query volume and a flexible baseline reduce specific biases; they do not eliminate every confounder. Treat them as improvements to the causal design, not as automatic proof that every remaining paid-search effect is causal.

    Build a model-ready geo-by-week dataset
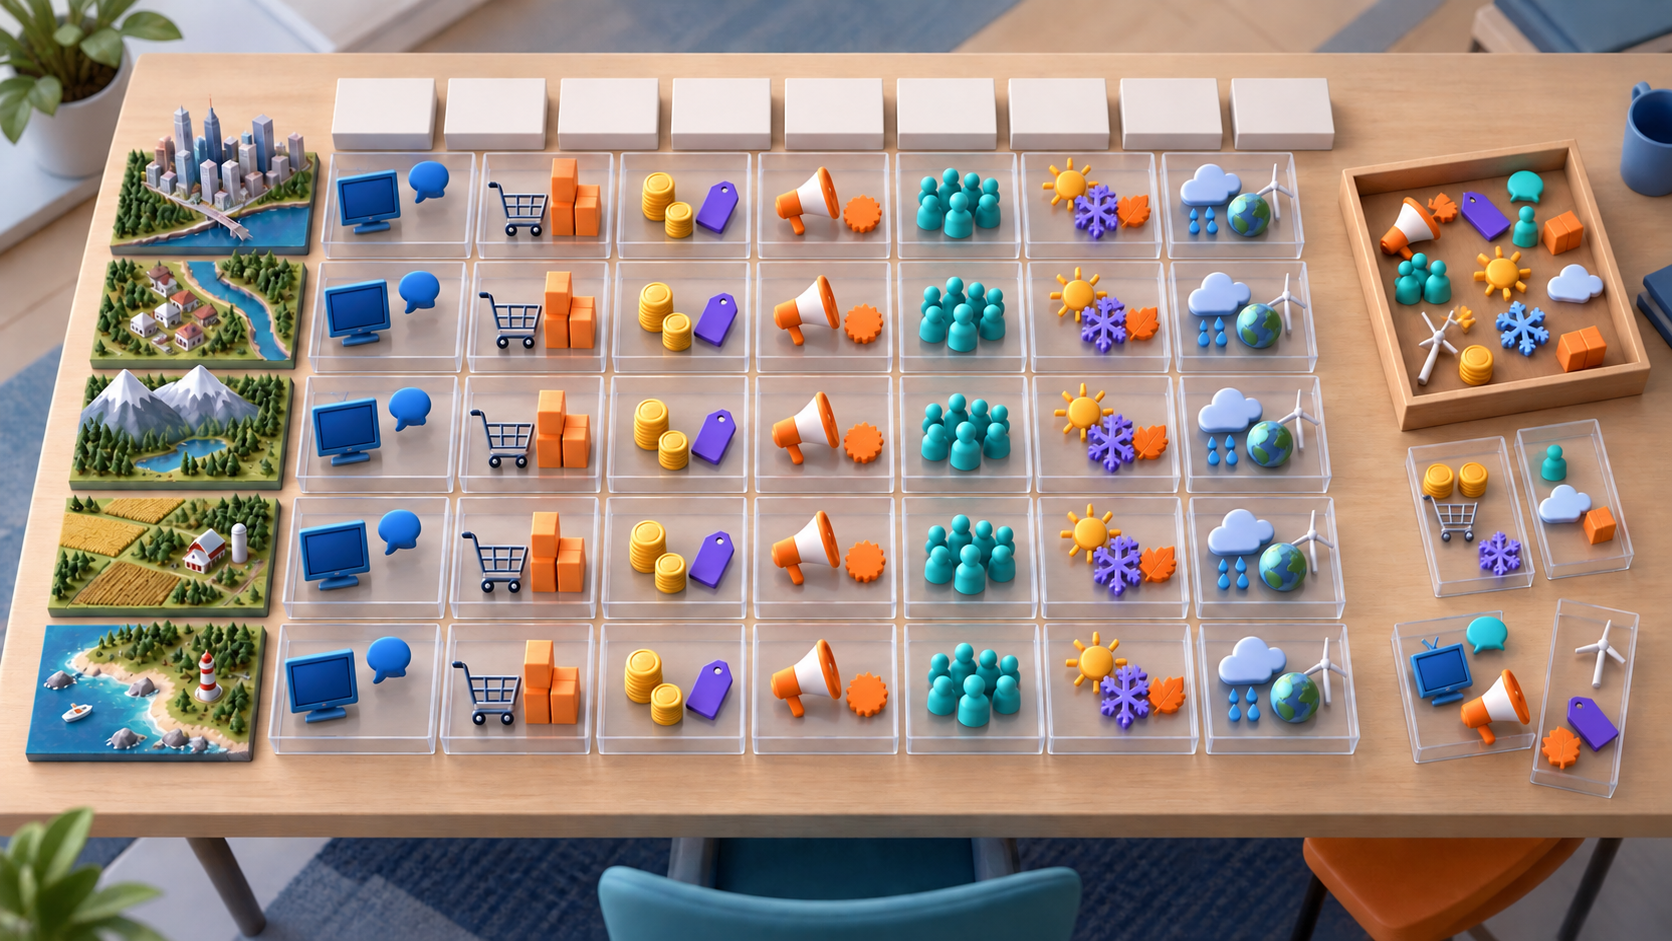
    Overhead illustration of geographic tiles and weekly blocks organized with media, sales, pricing, and seasonal data tokens.

    The practical readiness benchmark is historical weekly data, ideally broken out by geography and covering at least two years. That duration is an ideal, not a guarantee of quality and not a substitute for useful variation. Two years of inconsistent definitions can be less informative than a shorter, well-governed panel.

    Start with the decision, then choose one primary outcome. If the budget decision is about revenue, build a revenue model. If the organization manages acquisition against leads or store visits, define that measure precisely and keep the definition stable. Mixing several business outcomes into an ambiguous success metric makes the final recommendation hard to interpret.

    Data blockWhat to includeReadiness check
    Business outcomeWeekly revenue, leads, or store visits by geographyOne documented definition, stable units, and known reporting breaks
    Paid mediaSearch spend and impressions, plus relevant offline and other-channel metricsConsistent channel mapping and reconciliation with platform or finance totals
    Search demandGoogle Query Volume at a compatible geographic and time levelTreated as a demand control rather than a paid-media result
    Nonmarketing controlsKnown factors such as pricing changes and available competitor-sales signalsA credible reason each variable could affect the outcome independently of media
    Experimental evidenceRelevant incrementality or geo-lift resultsComparable channel, outcome, market, and time context, with uncertainty retained

    Audit the panel before anyone starts tuning a model:

    1. Write a data dictionary. Define every field, currency, geographic identifier, week boundary, and unit. Decide how refunds, cancellations, or revised records are handled before fitting.
    2. Reconcile totals. Aggregate the regional data and compare it with the totals used by finance and the media platforms. Explain material differences rather than silently accepting them.
    3. Distinguish zero from missing. Zero spend means the channel was inactive. A blank value may mean the feed failed. Treating both as zero can manufacture variation that never occurred.
    4. Map structural breaks. Mark changes to tracking, CRM stages, revenue recognition, pricing, territorial boundaries, and campaign naming. A clean-looking time series can still join incompatible definitions.
    5. Inspect geographic variation. Compare when and how sharply media changed across regions. Flag channels that moved almost identically everywhere, because the model may struggle to separate their effects.
    6. Preserve useful search detail. Keep enough campaign information to inspect branded search separately before deciding which paid-search activity should be grouped for modeling.

    Meridian can also use aggregated national data, but you give up some of the regional contrasts that make its geo-level approach valuable. If reliable geographic outcomes do not exist, be explicit about that limitation. Do not create false precision by assigning national sales to regions with an arbitrary allocation rule.

    A failed readiness audit is useful. It tells you to repair collection, preserve future geographic variation, or plan an incrementality experiment before asking the model for a budget answer. Forcing a run through a broken panel only postpones that work until the recommendations become harder to defend.

    Calibrate the Bayesian model before moving budget
    Balanced calibration mechanism with probability spheres, channel inputs, uncertainty rings, and budget tokens awaiting allocation.

    Meridian’s Bayesian design lets you combine historical aggregate data with prior knowledge. A prior expresses what the model knows about a parameter before it learns from the current dataset. If you have measured a channel through an incrementality test or geo-lift experiment, that result can inform the model’s priors.

    This is one of Meridian’s most useful features, but only when the evidence is genuinely comparable. A test of one campaign, market, or outcome should not be treated as universal truth for every form of search advertising. Document what was tested, where it ran, which outcome it measured, and how uncertain the estimate was. Carry that uncertainty into calibration rather than entering only the most convenient point estimate.

    Do not turn last-click return on ad spend into a strong prior merely because it is the number the team already has. That would import the original attribution bias into a model intended to move beyond it. If there is no credible experimental evidence, use appropriately cautious assumptions and let the observed aggregate data do more of the updating.

    A defensible implementation sequence looks like this:

    1. Write the measurement brief. Name the budget decision, primary KPI, planning horizon, channels in scope, and business constraints.
    2. Freeze an audited data version. Keep the model input reproducible so later changes can be traced to a data revision or a modeling decision.
    3. Specify the model. Decide the geographic structure, media variables, search-demand control, nonmarketing controls, and treatment of baseline movement.
    4. Calibrate with credible experiments. Record which prior each test informs and why that test is relevant.
    5. Examine uncertainty and sensitivity. Check whether the decision changes when reasonable priors, controls, or groupings change. A recommendation that reverses under a small specification change is not ready for a large budget shift.
    6. Run bounded scenarios. Use Meridian’s what-if planning capability for changes that remain plausible relative to the observed history. Treat extreme extrapolation cautiously.
    7. Stage the decision. Make a controlled change, define the outcome you will watch, and use a follow-up experiment where the financial consequence justifies it.

    The fitting work requires Python, commonly through a Jupyter Notebook, and usually needs an analyst or data scientist comfortable with model specification. Open source does make the code inspectable and modifiable. That helps your team review assumptions and adapt the framework, but it does not make every specification equally valid.

    When results arrive, resist reducing the posterior output to one definitive return number. Look at the range of credible outcomes, the contribution of the baseline, sensitivity to priors, and whether the result is consistent with experimental evidence. If a proposed reallocation could materially affect revenue, use the model to narrow the decision and then validate the change. Do not place a large financial bet on one run merely because its point estimate is precise.

    Google Meridian measurement FAQ

    Does Meridian replace Google Ads or analytics reporting?

    No. Advertising and analytics reports remain useful for delivery, pacing, conversion monitoring, and campaign diagnosis. Meridian addresses a different question: how much incremental business impact aggregate marketing activity appears to have produced. Keep operational reporting for execution and use the marketing mix model for strategic allocation.

    Do you need exactly two years of weekly data?

    Two years of weekly observations is an ideal data target, not proof that a model will work and not a stated universal cutoff. Coverage, consistency, geographic variation, and known business controls also matter. If you have less history, do not conceal the limitation. Assess whether a narrower model is defensible or whether data collection and experimentation should come first.

    Can a smaller company use Meridian?

    The code is openly available, so access is not restricted to companies with large television budgets. Practical suitability depends on whether you have enough stable historical data, meaningful media variation, a measurable outcome, and Python-capable analytical support. A smaller business with good data may be better positioned than a large organization with fragmented systems.

    Does open source make Meridian objective?

    No. Open source makes the underlying code available for inspection and modification, which reduces black-box risk and lets your team challenge the implementation. The answer still depends on the data, variables, priors, channel grouping, and assumptions you choose. Transparency makes scrutiny possible; it does not perform the scrutiny for you.

    Your next step should be a data inventory, not a software installation. Export weekly outcomes, paid-search spend, impressions, and available query volume by geography. Mark whether each field has two years of consistent coverage, identify definition changes, and inspect how much regional variation actually exists. If that panel survives the audit, write down the single budget decision the first model must support and assign a Python-capable analyst. If it does not, fix the collection gap or design an experiment before asking Meridian for an answer.

    References


  • Google Ads AI Creative Previews and CTR Benchmarks for 2026

    Google Ads AI Creative Previews and CTR Benchmarks for 2026

    You have a set of polished AI-generated headlines in front of you, but no reliable answer to the question that matters: will enabling them improve the campaign, or simply attract more of the wrong clicks?

    Use the AI Max preview and your clickthrough rate benchmark for different jobs. The preview is a pre-launch accuracy and positioning check. CTR is a post-launch response signal. When you keep those roles separate, you can test automation without mistaking plausible copy for proven performance.

    Key takeaways

    • AI Max can preview up to 10 generated headlines and descriptions from a final URL before you enable text customization.
    • The preview shows possible messaging, not the exact assets that will appear in live auctions.
    • A 2.1% CTR is a 2026 blended benchmark for the first search-ad position, not a universal Google Ads target.
    • Placement, ad format, industry and the presence of an AI-generated search answer can materially change the benchmark you should use.
    • Do not approve AI creative on CTR alone. Accuracy, conversion quality and the business value of those conversions remain the decision criteria.

    What the AI Max preview can actually tell you

    Google Ads is adding a preview that can produce up to 10 example headlines and descriptions in approximately 30 seconds. You enter the campaign’s final URL, and Google AI uses that landing page to create the samples. You do not have to enable text customization first.

    Where the option is available, you can find it under Asset optimization while creating a Search campaign or editing an existing one. It supports the languages already supported by text customization and most business categories, while adult content is excluded.

    The useful question is not, “Do these ads sound good?” It is, “What does Google appear to believe this page is offering, to whom, and on what terms?” That shift turns the preview into a diagnostic tool.

    A preview can help you notice:

    • Which benefits and product attributes Google treats as central.
    • Whether the landing page communicates a clear audience, use case and point of difference.
    • Whether important qualifications disappear when the offer is compressed into ad copy.
    • Whether the generated language fits your brand voice or drifts into generic advertising phrases.
    • Whether ambiguous page copy is being interpreted as a broader or stronger claim than you intended.

    It cannot tell you which headline-description combination will serve for a particular query, whether the live system will generate different wording, or what CTR the campaign will achieve. Google describes the assets as examples; the exact previewed text is not guaranteed to serve.

    That limitation changes the approval standard. You are not signing off on a fixed set of ads. You are deciding whether the page gives an automated system sufficiently accurate material from which to generate ads. A clean preview is encouraging, but it does not remove the need to inspect generated assets after activation.

    Choose a CTR benchmark that matches the auction

    CTR is clicks divided by impressions, expressed as a percentage. The arithmetic is simple; the comparison is not. A display campaign, a first-position Search ad and a local result appear in different contexts and reflect different kinds of intent. Comparing all three to one account-wide target will produce confident but misleading conclusions.

    The 2026 figures below come from a meta-analysis covering 126 agency client accounts and published CTR datasets from August 4, 2025 through August 28, 2026. The results were weighted by dataset quality and normalized to U.S. query volume. They are useful external reference points, but they are not promises for an individual campaign, another country or a different auction mix.

    CTR by ad type and placement

    Ad typePlacement2026 average CTRHow to use it
    SearchPosition 12.1%Use only for the top search-ad position and remember that it blends search pages with and without AI answers.
    SearchPosition 21.4%Compare with campaigns occupying a similar position mix.
    SearchPosition 31.1%Do not treat the gap from position 1 as a creative problem by default.
    SearchPosition 40.8%Check placement before diagnosing copy from the lower CTR.
    Local SearchLocal result4.6%Keep separate from conventional Search benchmarks.
    Local ServicesLeft2.6%Compare within the same Local Services layout.
    Local ServicesMiddle2.3%Account for the lower placement when evaluating the result.
    Local ServicesRight2.0%Use as a placement-specific reference, not an account target.
    Product Listing AdTop eight1.2%Compare with other prominent product listings.
    Product Listing AdMid-page0.55%Do not compare directly with the top-eight figure.
    DisplayAcross placements0.093%Judge in the context of a format often used for branding rather than direct click generation.
    VideoSkippable0.69%Keep separate from Search and non-skippable video.
    VideoNon-skippable0.78%Compare with the same video format and campaign objective.

    The first-position Search benchmark needs one more qualification. The top ad averaged 1.8% on results pages containing an AI-generated answer and 3.4% on pages without one. The published 2.1% figure blends those environments.

    That difference is large enough to change your diagnosis. If a campaign’s exposure shifts toward search pages with AI answers, CTR can fall even when the ad copy has not become worse. Conversely, a rise in CTR does not prove that newly generated assets caused the improvement if placement or search-page composition changed at the same time.

    CTR for the first Search ad by industry

    Industry creates another wide spread. The 2026 first-position Search averages ranged from 1.1% to 5.4% across the 19 reported industries:

    IndustryCTR for position 1
    Addiction Treatment5.4%
    Automotive2.0%
    Aviation1.3%
    CBD2.8%
    Construction1.2%
    eCommerce2.9%
    Entertainment4.0%
    Financial Services2.5%
    Higher Education & College3.7%
    Home Builders2.5%
    Home Services3.0%
    Hotels & Resorts3.6%
    HVAC Services3.1%
    Legal Services2.3%
    Medical Device1.1%
    Medical Practices2.1%
    Real Estate2.7%
    SaaS1.8%
    Solar Energy2.4%

    There is no defensible universal CTR target for AI Max-generated text in these figures. They benchmark ad formats, positions and industries, not previewed AI copy against human-written copy. If someone tells you that enabling text customization should produce a particular CTR, ask for a comparable test covering the same placement, market, query mix and conversion objective.

    Use a three-level benchmark instead:

    1. Start with your own like-for-like campaign history. Match the campaign, market, landing page, intent and approximate placement as closely as practical.
    2. Use the closest industry figure to check whether your internal baseline is broadly plausible.
    3. Use the ad-type and placement table to explain structural differences that creative changes cannot fix.

    If your industry is absent, do not force a neighboring category into service because its label sounds similar. Use the placement benchmark as a rough external anchor and let your own campaign history carry more weight.

    Audit the preview as a claims and intent test

    A marketer uses a magnifying lens to compare abstract ad-preview cards with several possible landing-page destinations.

    The preview begins with your final URL, so prepare the page before judging the output. Make the actual offer, intended customer, geographic scope, material conditions and primary distinction easy to identify. Resolve contradictory wording between the headline, body copy, pricing language and calls to action. Otherwise you are asking automation to clarify a page that has not clarified itself.

    Save every previewed asset in a simple review sheet. Give each row fields for the generated text, intended angle, supporting landing-page language, risk level and decision. Then make four passes.

    1. Check factual accuracy. Mark any invented feature, incorrect product scope, wrong location, unsupported comparison or material condition that has disappeared. One false claim is a stop signal; do not average it away because the other assets are acceptable.
    2. Check intent. Write down the search need each asset appears to answer. If you cannot identify one, the wording is probably too generic. If it implies a broader offer than the landing page delivers, it may earn curiosity clicks that will not convert.
    3. Check positioning and voice. Look for language that could belong to any competitor, inflated promises you would not publish elsewhere, or terminology your customers do not use. A grammatically clean headline can still weaken the reason to choose you.
    4. Check destination continuity. A visitor should be able to find the advertised promise, product and relevant condition immediately on the destination page. If the ad requires the reader to reinterpret the page after clicking, the message is not aligned.

    A red-yellow-green system keeps the decision concrete. Red means false, materially misleading or attached to the wrong offer. Yellow means accurate but broad, generic, ambiguous or inconsistent with your voice. Green means specific, supportable and continuous with the destination page.

    Do not enable text customization while a red issue remains. If several samples make the same mistake, inspect the landing page before blaming the model. Repeated errors may indicate that the page leaves an important distinction implicit, although the model can also introduce an error that is not present on the page. Fix the underlying ambiguity where one exists, then run the preview again.

    A single yellow asset is a monitoring item, not necessarily a rejection. Record the exact concern so that your live review has a testable condition: for example, “watch for language that presents the service as nationwide” is more useful than “keep an eye on brand fit.”

    Run the live pilot without letting CTR make the decision

    An analyst monitors two ad-testing streams using several unlabeled performance gauges, with click response shown as one signal among many.

    Once text customization is enabled, treat the saved preview as a record of likely themes, not a production manifest. Continue examining generated assets because live messaging may differ from the examples.

    Set up the pilot around one business question: can AI-generated text produce more qualified response without creating claim, positioning or destination-match problems? That question gives you a hierarchy for interpreting the data.

    1. Record the starting configuration. Save the preview, final URL, activation date, existing CTR baseline and the conversion outcomes you will use. Without that record, later changes become difficult to attribute.
    2. Limit simultaneous changes where practical. A new landing page, different targeting, altered bidding and AI-generated text introduced together will not tell you which change mattered.
    3. Compare like with like. Review placement and query mix alongside CTR, and remember that AI-answer exposure can alter the click opportunity before the user evaluates your ad.
    4. Read CTR with conversion rate and cost or value per conversion. CTR tells you that the ad attracted a click. It does not tell you that the click came from the right person or produced a worthwhile outcome.
    5. Review the actual message. If a live asset makes an inaccurate or materially misleading claim, intervene immediately. You do not need to wait for a performance threshold before correcting an accuracy problem.

    Use this interpretation grid when the numbers arrive:

    Observed resultLikely interpretationNext action
    CTR rises and conversion quality holds or improvesThe new message may be earning more useful attention.Continue the pilot and monitor the live assets for message drift.
    CTR rises but conversion rate or value declinesThe message may be too broad, curiosity-driven or mismatched with the landing page.Inspect the generated wording, search intent and destination continuity before celebrating the CTR gain.
    CTR stays flat but conversion quality improvesThe creative may be filtering for better-fit visitors rather than maximizing click volume.Judge the result against the campaign’s business objective, not the external CTR average.
    CTR falls while conversion quality improvesFewer people are clicking, but those who do may be better qualified.Compare the additional value per click with the lost volume before deciding.
    CTR and conversion outcomes both declineThe change has no evident performance benefit in the observed campaign context.Inspect placement and query changes, then disable or revise the test if the decline remains attributable to the new setup.
    Any material accuracy failurePerformance metrics are no longer the primary issue.Stop the problematic automation or asset exposure and correct the message.

    Avoid importing a universal testing duration or click threshold. A high-volume local campaign and a low-volume B2B campaign do not accumulate useful evidence at the same rate. Make the decision when your campaign has enough comparable traffic to separate a persistent pattern from daily noise, and document what “enough” means before looking at the result.

    Your next move is straightforward: preview one representative campaign, save and score every generated asset, write down the correct position-and-industry CTR reference, and define the conversion-quality guardrail before opting in. That gives AI Max a fair test without handing an attractive CTR more authority than it deserves.

    References

  • 2026 Cost Per Lead Benchmarks: 30 Industries Compared

    2026 Cost Per Lead Benchmarks: 30 Industries Compared

    If your cost per lead is $320, is that good? The number alone cannot tell you. A $320 lead would sit well above the 2026 benchmark for B2B SaaS, below the benchmark for financial services, and somewhere else entirely once lead quality and conversion are considered.

    Use industry cost-per-lead benchmarks as diagnostic ranges, not targets. First find the closest industry and channel comparison. Then calculate the CPL your own customer economics can support. That order helps you avoid cutting expensive leads that become valuable customers or scaling cheap leads that never reach the sales pipeline.

    2026 cost-per-lead benchmarks by industry

    The 2026 benchmark covers lead-generation data collected from January 2022 through August 2026. Across 30 industries, the average blended CPL was $400. Average paid CPL was $452, while average organic CPL was $350.

    A lead in this benchmark is a direct connection with a prospective customer who has expressed purchasing interest through email, phone, or an in-person introduction. CPL means gross marketing spend divided by new leads. It does not measure closed customers or include the sales costs captured by customer acquisition cost.

    The blended column is weighted by the share of leads generated by paid and organic channels in each industry. It is not simply the midpoint between the two channel figures.

    IndustryPaid CPLOrganic CPLBlended CPL2025-2026 blended change
    Addiction Treatment$384$232$304+2.4%
    Aerospace & Aviation$453$290$375+0.5%
    Automotive$319$285$302+6.7%
    B2B SaaS$318$186$249+5.1%
    Biotech$281$249$265+3.9%
    Business Insurance$440$412$427+0.7%
    Construction$282$185$235+3.5%
    Cybersecurity$434$427$429+5.7%
    eCommerce$102$90$96+5.5%
    Engineering$355$214$284-1.0%
    Entertainment$115$114$115+0.9%
    Environmental Services$343$217$283+1.8%
    Financial Services$731$591$662+1.4%
    Fintech$494$451$473+4.6%
    Healthcare$363$348$356-1.4%
    Higher Education$1,176$766$970-1.2%
    Hotels & Resorts$268$234$250-6.0%
    HVAC$118$73$96+4.3%
    Industrial IOT$573$427$501+0.8%
    IT & Managed Services$600$418$505+0.4%
    Legal Services$783$580$682+5.1%
    Manufacturing$657$440$547-1.1%
    Oil & Gas$756$526$639+0.3%
    PCB Design & Manufacturing$462$284$371-1.3%
    Pharmaceutical$126$148$140+6.9%
    Real Estate$496$450$472+5.4%
    Software Development$691$573$627+6.1%
    Solar$243$213$227+10.2%
    Staffing & Recruiting$511$543$526+5.8%
    Transportation & Logistics$671$538$604+2.7%

    Key takeaways

    • The cross-industry reference point is $400 blended CPL, but the range runs from $96 in eCommerce and HVAC to $970 in higher education. Industry context is therefore more useful than the overall average.
    • Legal services had a $682 blended CPL and financial services had a $662 CPL. Higher contract values and longer sales cycles tend to support more expensive lead acquisition than short-cycle consumer and local-service purchases.
    • Paid leads cost more than organic leads in 28 of the 30 industries. The two exceptions were pharmaceutical, at $126 paid versus $148 organic, and staffing and recruiting, at $511 paid versus $543 organic.
    • Across all industries, paid CPL carried a 29% premium over organic CPL. The widest gaps appeared in B2B SaaS, where paid leads cost 71% more, and in engineering and addiction treatment, where the premium was 66%.
    • Blended CPL increased in 24 industries. Solar recorded the largest increase at 10.2%, while hotels and resorts had the largest decline at 6.0%.

    A benchmark cannot tell you whether your CPL is profitable

    A balance scale weighs acquisition tokens against a customer journey, with a transparent funnel filtering many lead spheres into a few valuable gems.

    Your competitor’s CPL and the industry average do not pay your bills. Your acceptable CPL depends on the value of a customer, the percentage of leads that become customers, the cost of closing and serving them, and the margin your business needs to retain.

    Start with two separate calculations. Observed CPL equals gross marketing spend divided by valid new leads. Maximum CPL equals the maximum marketing acquisition cost you can support per new customer multiplied by your lead-to-customer conversion rate.

    Define that maximum marketing acquisition cost only after accounting for delivery costs, sales costs, expected retention and required margin. Use customer gross profit rather than top-line revenue when you test the ceiling. Revenue can make an unprofitable acquisition program look healthy.

    The conversion rate in the formula must come from a mature cohort of comparable leads. Do not combine a high-intent demo request with a newsletter signup, downloaded template or purchased contact. Each may have a place in your funnel, but they do not carry the same probability of becoming a customer.

    Low CPL can hide an expensive customer

    A cheap channel can produce large numbers of weak inquiries. If those leads rarely qualify, require heavy sales effort or churn quickly, the low CPL is cosmetic. A more expensive referral or high-intent search lead may create better economics because it closes more often and produces greater lifetime value.

    Read CPL beside lead-to-qualified-opportunity rate, lead-to-customer rate, sales effort, customer lifetime value, referral rate and satisfaction. If one channel costs more but wins on those downstream measures, cutting it to meet a benchmark can reduce profit while making the marketing dashboard look better.

    Make your CPL comparable before you diagnose a gap

    A benchmark comparison is useful only when its numerator, denominator and channel match yours. Most apparent CPL problems begin with one of those three elements.

    Use the same lead definition

    Decide what event creates a lead and apply that rule across every channel. Deduplicate repeat submissions, exclude spam and internal tests, and keep raw contacts separate from sales-accepted leads. If your dashboard counts every content download while the benchmark describes people showing purchasing interest, your apparently low CPL is not comparable.

    Use a complete and consistent cost policy

    Gross marketing cost should reflect the resources required to operate the channel, not whichever expenses are easiest to retrieve. For paid acquisition, that can include media, creative production, landing-page work, management and relevant tools. For organic acquisition, it can include strategy, content, technical work, optimization and distribution. The accounting choice can vary by company; the important part is to document it and apply it consistently.

    If one team reports ad spend alone while another reports fully loaded channel cost, the resulting CPLs should not be ranked against each other. Rebuild them under one cost policy first.

    Compare channel with channel

    Compare paid performance with the paid column and organic performance with the organic column. For your own blended CPL, use total paid and organic spend divided by total paid and organic leads. Do not average the two channel CPLs unless they generated identical numbers of leads.

    Keep source, campaign, offer and lead type attached to each record in your CRM. A single account-wide CPL can conceal a strong high-intent campaign, a weak prospecting campaign and an attribution problem at the same time.

    Allow conversion cohorts to mature

    CPL is available as soon as a lead enters the system, but lead quality becomes visible later. Comparing this month’s new leads with an older cohort’s closed customers creates a false relationship. Freeze channel cohorts by acquisition period, let them progress through the normal sales cycle, and then calculate qualification and customer conversion against the original lead count.

    Paid and organic CPL are moving in different directions

    The all-industry average paid CPL fell 1.3%, from $458 to $452, with declines in 15 industries. Organic CPL rose 7.3%, from $326 to $350, and increased in all 30 industries. As a result, the average paid premium over organic narrowed from 40% to 29%.

    This does not make paid acquisition cheap or organic acquisition ineffective. It means the old assumption that organic leads will remain dramatically less expensive needs to be tested against your current data.

    Lower click-through rates have been measured when search results contain AI-generated summaries. If the same content investment produces fewer site visits and leads, measured organic CPL rises even when rankings or search visibility appear stable. That mechanism is especially relevant to businesses whose buyers begin with informational research. B2B SaaS had a 13.4% organic CPL increase, while legal services and software development each rose 12.4%.

    Do not treat AI summaries as a complete explanation for every increase. Content costs, conversion performance, attribution rules, offer strength and query mix can also change your result. Look for the break in your own funnel: impressions to clicks, clicks to qualified visits, visits to leads, leads to opportunities, or opportunities to customers.

    For informational content, supplement last-click CPL with assisted pipeline evidence. Preserve original and subsequent acquisition touches, connect landing pages to CRM outcomes, and ask qualified prospects how they first encountered the business. AI visibility that influences demand may not produce an immediate click, but that possibility is not a reason to assign unverified value. Keep direct and assisted results separate so the interpretation remains auditable.

    Turn the benchmark into a channel decision

    A strategist compares a token-powered megaphone with a growing network of vines as both channels send leads toward a central sales funnel.

    Because these figures aggregate one organization’s lead-generation data across a multiyear collection period, they are planning references rather than universal market prices. Your offer, geography, brand demand, competitive environment and qualification rules can move CPL materially.

    1. Choose the closest industry row and the matching paid, organic or blended column. If your company spans categories, keep the relevant business lines separate instead of selecting the most flattering benchmark.
    2. Recalculate your observed CPL with a documented definition of gross marketing spend and a deduplicated count of valid new leads.
    3. Calculate your maximum CPL from allowable marketing acquisition cost and the conversion rate of a mature, comparable lead cohort.
    4. Compare both CPLs with downstream quality. If you are above the industry benchmark but below your profitable ceiling, investigate the gap without assuming the channel is failing. If you are below the benchmark but above your ceiling, the program still needs correction.
    5. Make the next budget decision at the channel, campaign and offer level. Shift incremental spend toward the combinations that produce customers with stronger lifetime value, referral behavior and satisfaction relative to acquisition cost.

    Your next move is not to force every campaign toward the $400 cross-industry average. Open one channel report, rebuild its numerator and denominator, and attach qualification rate, close rate and customer value. Once that view is clean, the benchmark becomes what it should be: a prompt to investigate, not a target to obey.

    References


  • AdMob Black-Screen Outage: What App Publishers Should Do

    AdMob Black-Screen Outage: What App Publishers Should Do

    When people report that your app “freezes” immediately after a video ad, you need to answer two questions quickly: is your own release broken, and can you stop more users from entering the same dead end?

    The documented AdMob failure can replace an interstitial video with a solid black screen and leave its close button unresponsive. It affects iOS and Android, and the only reported escape for the user is to force-close the app. Here is how to confirm the pattern, contain it, measure the damage, and restore the placement without making a rushed code change.

    Know the boundary of the AdMob failure

    The confirmed failure is narrow enough to guide your response but serious enough to justify immediate action. An interstitial video fails to render, the user sees a black screen, and the close control does not work. Reports cover both iOS and Android applications.

    AdMob itself may remain accessible while publishers encounter error messages, high latency, or other unexpected behavior. At the reported stage of the incident, Google was investigating, had announced no estimated resolution time, and offered no workaround for the failed interstitial.

    That boundary matters. The known issue concerns interstitial video ads; it does not establish that every AdMob format or every placement is failing. Do not disable unrelated inventory merely because it uses the same ad platform. Equally, do not dismiss the incident as an iOS view-controller problem or an Android rendering regression when the same symptom is appearing across both operating systems.

    There is also an important distinction between a vendor workaround and publisher containment. Google may have no way for you to repair the ad after it becomes a black screen. You may still be able to prevent your app from requesting or presenting the affected placement through remote configuration, a feature flag, or an emergency release.

    Confirm the pattern before changing your SDK or app code

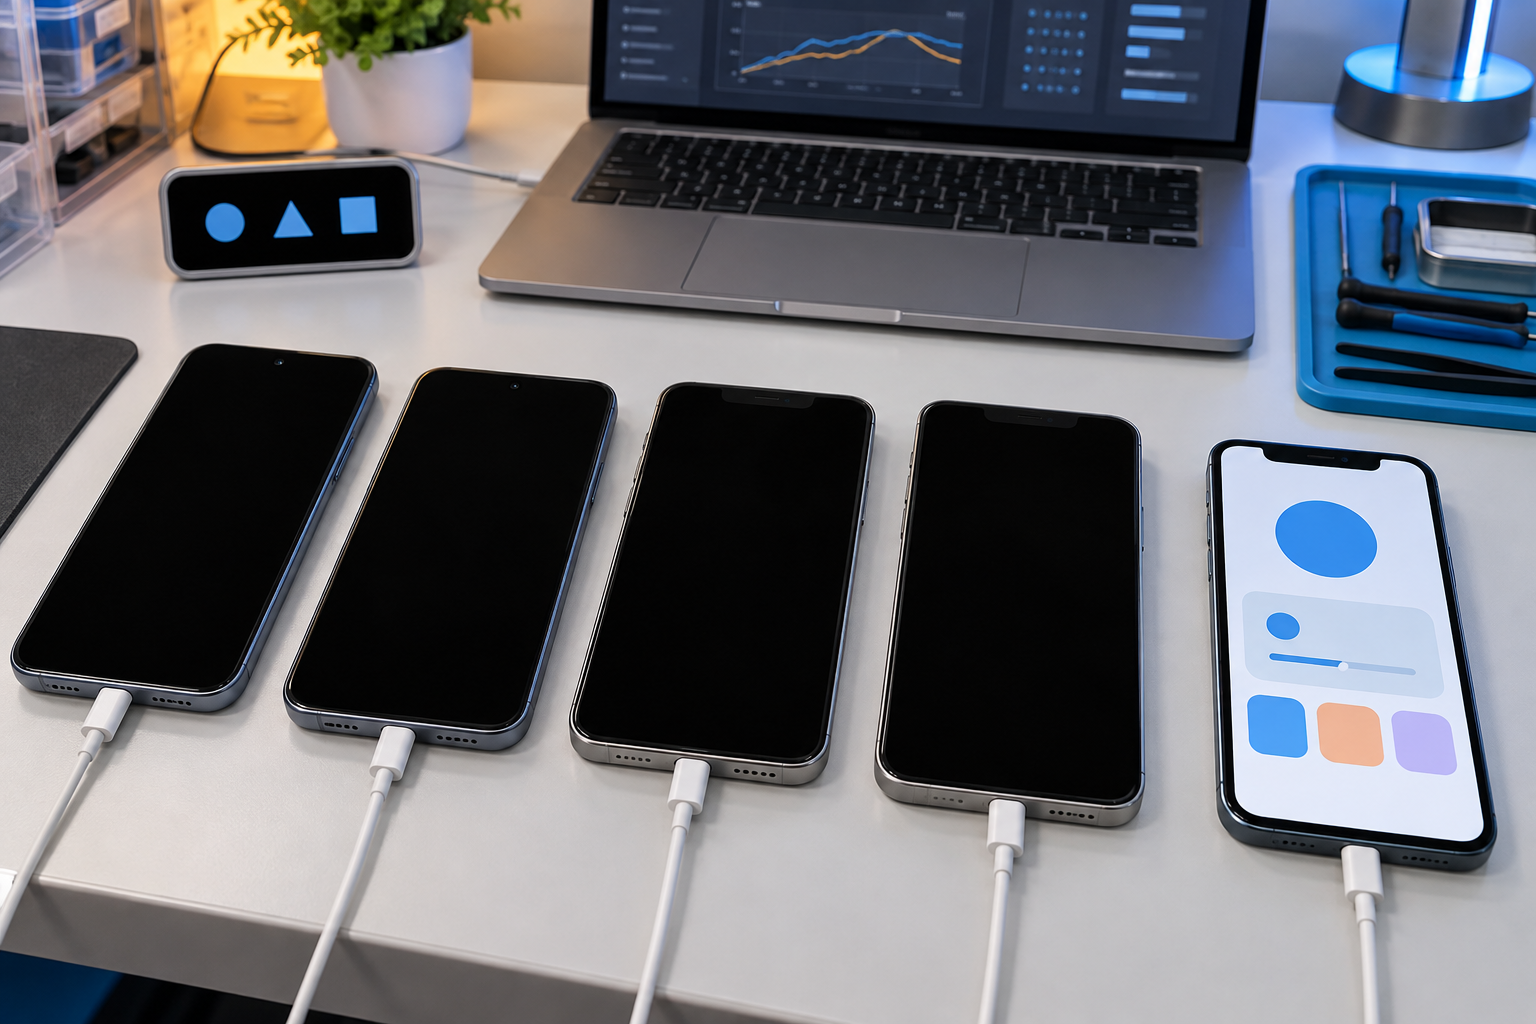
    Four test phones show matching black full-screen ad failures while a separate control phone displays a normal app interface.

    A black screen is a symptom, not a diagnosis. Treat the AdMob incident as a strong lead, then collect enough evidence to distinguish it from your own navigation, lifecycle, or rendering bug.

    1. Identify the exact trigger. Record the screen, user action, and interstitial placement immediately preceding the black screen. “The app went black” is not enough to isolate an ad failure.
    2. Capture the environment. Preserve the app version, build number, operating system, device model, timestamp with time zone, and network condition. Ask support teams to collect the same fields from new reports.
    3. Inspect the session sequence. Determine whether the app process remains active behind a full-screen ad surface, whether the close control appears, and whether tapping it produces any response.
    4. Review your ad events. Look for the request, load, presentation, dismissal, and failure events your integration already records. Event names vary by SDK and implementation, so use your own instrumentation rather than assuming a callback was fired.
    5. Test the path without the placement. If the next screen works when the interstitial is suppressed in a controlled environment, the evidence points toward the ad boundary rather than the destination screen.
    6. Check both mobile platforms. Matching behavior on iOS and Android strengthens the case for a shared service or creative-delivery problem. A report from only one platform does not rule out the AdMob incident, but it does justify checking platform-specific code.

    Use your existing test environment and approved ad-testing setup when reproducing the flow. An unsuccessful reproduction does not prove that production is healthy: ad delivery varies, and the affected video may not appear in every request.

    Avoid upgrading, downgrading, or replacing the mobile ads SDK solely because the visible symptom resembles an integration bug. Those changes introduce a second variable and may not affect a service-side outage. First establish whether the failure aligns with the known interstitial pattern and whether suppressing that placement restores the user journey.

    Contain the user trap at the placement level

    A smartphone app journey routes around a black ad screen that has been isolated behind a protective barrier.

    Your immediate goal is not to recover every missed impression. It is to stop a full-screen dependency from making the rest of the app unreachable.

    • Use a remote kill switch if one exists. Stop invoking the affected interstitial placement without disabling ad formats that are still working.
    • Fail open at the gate. If the interstitial sits between a completed action and the next app screen, let the user continue without the ad while the placement is suppressed.
    • Do not create an automatic retry loop. Repeatedly requesting another interstitial at the same transition can send the user back into the broken experience.
    • Remove the placement from relaunch-sensitive paths. A person who force-closes the app should not immediately encounter the same interstitial after reopening it.
    • Consider an emergency release when server-side control is unavailable. Keep the change narrow: bypass the affected placement rather than combining the response with an SDK migration or unrelated feature work.
    • Reassess paid acquisition into an unavoidable broken path. If a high-traffic onboarding or conversion flow cannot bypass the interstitial, continuing to drive users into it may waste campaign spend and amplify abandonment.

    Suppression has an obvious monetization cost, but leaving the placement active can cost the entire session. The outage can affect ad engagement and publisher revenue while also increasing user frustration and app abandonment. Make that tradeoff explicitly rather than allowing a revenue-protection default to decide it for you.

    Give support teams a precise response they can use: “A video ad may display a black screen with a close button that does not respond. Close the app completely and reopen it. We are temporarily limiting the affected ad placement while the provider investigates.”

    Do not promise that reopening permanently fixes the issue; force-closing only gives the user a way out of the current screen. Do not publish a resolution time that Google has not supplied. If you cannot suppress the placement, tell users where it occurs so they can make an informed choice about using that path.

    Measure the blocked journey, then restore cautiously

    Look beyond crash-free sessions

    A trapped interstitial may not look like a conventional application crash in your monitoring. The user can leave by force-closing the app, so a healthy crash-free metric is not proof that the experience is healthy.

    Build the incident view around the user journey: ad presentation, expected dismissal, arrival at the next screen, session termination, and subsequent reopen. Compare the affected period with your normal baseline, segmented at least by placement, operating system, and app version. Use your established timing baseline rather than inventing a new universal timeout during the incident.

    • Count interstitial presentations that are not followed by the expected dismissal or next-screen event.
    • Track exits and rapid reopens after an interstitial presentation.
    • Review support tickets and app-store feedback for black-screen, frozen-ad, and unresponsive-close descriptions.
    • Watch requests, impressions, engagement, and revenue by the affected placement; the outage may alter each metric differently.
    • Preserve a timeline of configuration changes, releases, reports, and observed recovery so that later analysis can separate the outage from your mitigation.

    Be careful with interpretation. A lower impression count after you suppress a placement is expected. A decline before suppression may reflect failed rendering or disrupted sessions, but the available incident information does not establish exactly how every AdMob reporting metric records the failure.

    Require evidence before full restoration

    Do not re-enable the placement merely because complaints slow down. Confirm that Google has marked the incident resolved, then validate the affected journey on both iOS and Android. Check that the video renders, the close control responds, the dismissal event arrives, and the user reaches the intended next screen.

    If your controls allow it, restore the placement to a limited share of traffic first. Watch the same presentation-to-dismissal and next-screen signals used during triage. Expand only when those signals return to their ordinary baseline. If limited restoration reproduces the black screen, disable the placement again and preserve the new session evidence.

    Key takeaways

    • The known AdMob failure turns an interstitial video into a black screen with an unresponsive close button on iOS and Android.
    • Force-closing the app is the only reported way for a user to escape the affected screen; it is not a permanent fix.
    • At the reported stage, Google was investigating and had provided neither a workaround nor an estimated resolution time.
    • Confirm the placement-level pattern before changing your SDK, then suppress only the affected interstitial where your controls permit.
    • Measure dismissal and journey completion rather than relying on crash metrics alone.
    • Restore the placement only after a confirmed resolution and successful validation on both mobile platforms.

    Once the incident is behind you, add one durable control: every full-screen third-party placement should have a remotely operated off switch. The next provider failure should require a configuration change, not an emergency app release, before you can give users their app back.

    References


  • Retail Media Audience Sharing in Google Ads: A Practical Guide

    Retail Media Audience Sharing in Google Ads: A Practical Guide

    If you sell through a retailer, some of the most useful shopper signals may sit in the retailer’s account while your campaign sits in yours. Google Ads commerce audience sharing creates a bridge between those two positions. That bridge is useful, but narrow: it is limited to eligible commerce media network campaigns.

    Before you build a media plan around it, you need to know what can be shared, where the resulting audiences can be used, what each partner can see and how you will judge the outcome. Getting those decisions in writing before activation prevents an audience opportunity from turning into an account, measurement or expectations problem.

    The feature is useful, but its lane is narrow

    Commerce audience sharing lets a retailer or marketplace make selected first-party audience segments available to a brand or seller through Google Ads. That gives an advertising partner access to audiences grounded in the commerce partner’s own customer relationships and shopping activity, rather than requiring the advertiser to build the same relationship independently.

    The roles are straightforward:

    • The commerce partner is the retailer or marketplace that owns and shares the eligible first-party segments.
    • The advertising partner is the brand or seller that can use those shared segments in an eligible retail media campaign.
    • Google Ads supplies the campaign infrastructure through which the collaboration operates.

    The most important limitation is also the easiest to miss. Shared commerce audiences are available for commerce media network campaigns, not for automatic use across regular Search, Shopping or Performance Max campaigns. Operationally, you should treat this as audience access for a qualifying retail media program, not as a portable audience asset that can be reused throughout your Google Ads account.

    That boundary should shape your go-or-no-go decision. The feature is a plausible fit when your immediate goal is to reach a retailer’s existing customers, high-intent shoppers or another retailer-defined customer group inside an eligible commerce media network campaign. It is not the answer when your plan depends on carrying the same segment into ordinary Search, Shopping or Performance Max activity.

    It is also a paid media capability, not an organic visibility tactic. Activating a retailer audience does not change how your pages are indexed, cited in AI answers or surfaced through SEO, AEO or GEO. Keep retail media activation and organic search optimization as separate workstreams, even when they support the same commercial objective.

    Prove the account and campaign path before planning creative

    An isometric account-to-campaign pathway connects retailer and advertiser workspaces through eligibility and access checkpoints, while incompatible routes are blocked.

    A promising audience idea has no value if the required accounts, eligibility and campaign type are not in place. Validate the operating path before you assign budget or ask a creative team to produce segment-specific ads.

    1. Identify the commerce partner. Name the retailer or marketplace that will make the segment available. Do not leave ownership implied between a brand, agency, seller and retailer.
    2. Confirm eligibility on both sides. The commerce partner and advertising partner must each satisfy Google’s eligibility requirements. One eligible account does not make the other eligible.
    3. Confirm the campaign type. Write down that the intended activation is an eligible commerce media network campaign. If the media plan only contains regular Search, Shopping or Performance Max campaigns, stop and redesign the audience plan.
    4. Map the required account relationships. The retailer’s sharing setup involves linking its Google Ads account with the relevant Google Merchant Center and data-sharing accounts. Assign an owner for each account and identify who can approve each link.
    5. Inventory the segments that will actually be shared. Availability is a commerce-partner decision. Build the campaign around confirmed segments, not around audience names that you hope the retailer can provide.
    6. Agree on the handoff. Record who publishes the segment, who confirms that it is available, who attaches it to the campaign and who resolves access problems.

    This sequence matters because audience strategy and account setup are different jobs. The advertiser may know which shoppers it wants, while the retailer controls which first-party segments are made available. A short activation brief should join those responsibilities instead of allowing each side to assume the other has handled them.

    Your brief should name the commerce partner, advertising partner, Google Ads account, relevant Merchant Center and data-sharing relationships, eligible campaign type, approved audience segments, primary conversion and approval owners. If any one of those fields is unresolved, the campaign is not ready for an audience-dependent launch date.

    Build the audience plan around a decision, not a label

    A segment called high intent sounds useful, but the label alone does not tell you what action to take. Ask what business decision becomes different because that audience is available.

    • Existing customers: Use this type of retailer-defined segment when the campaign has a clear relationship objective, such as presenting a relevant next purchase or a distinct customer message. Decide in advance whether existing customers are the target, a separate reporting group or outside the acquisition objective.
    • High-intent shoppers: Use this type only after the retailer explains what makes a shopper high intent. The campaign message should reflect the next action you want that shopper to take, not merely repeat a broad awareness message.
    • Specific customer segments: Request a segment when a meaningful difference in customer type changes the offer, product emphasis, creative or measurement plan. If every segment will receive the same treatment, extra segmentation may add operational complexity without improving the decision.

    For every requested segment, document the following questions:

    • What customer type does the segment represent?
    • Which behavior or relationship qualifies a person for it?
    • How recent must that qualifying behavior be?
    • How is the segment refreshed?
    • Can customers belong to more than one shared segment?
    • Which eligible campaigns may use it?
    • Which conversion will determine whether using it was worthwhile?

    Those operational definitions may require a direct agreement with the retailer. The information visible to an advertising partner includes segment names, customer types and conversion data, but a usable campaign brief often needs more context than a segment name can carry.

    Naming deserves care as well. A segment name should be clear enough for the advertiser to select and report on correctly. It should not contain customer-level information or encode details that are inappropriate to expose to a partner. Use a stable naming pattern that distinguishes the customer type, intended use and any version the partners need to recognize.

    The governing principle is simple: request the smallest meaningful set of audiences that can change a campaign decision. A long list of vaguely differentiated segments makes implementation and interpretation harder. A clearly defined segment tied to a specific message and conversion creates something both partners can evaluate.

    Measure value without calling every conversion incremental

    An analyst separates a mixed stream of conversion symbols into distinct groups to distinguish observed results from possible incremental effects.

    Audience sharing gives both sides visibility, but not identical visibility. Advertising partners can see shared audience information and conversion data. Commerce partners can access performance metrics showing how their audiences are being used and how the campaigns perform. Agree on a shared scorecard before launch so that each side does not reach a different conclusion from its own view.

    Separate four measurement questions:

    1. Was the intended audience available and used? Confirm that the correct shared segment was attached to the correct eligible campaign.
    2. Did the campaign produce the selected conversion? Define the conversion before launch and use the conversion data available to the advertising partner consistently.
    3. Was performance better than a relevant comparison? Where practical, compare the audience strategy with a campaign or audience treatment that is similar enough to inform the decision. Avoid changing the audience, creative, offer and optimization objective simultaneously if you want to understand which choice mattered.
    4. What can you honestly claim? Strong performance within a high-intent audience shows that the campaign reached and converted valuable shoppers. It does not, by itself, prove that every conversion was caused by audience sharing or that those purchases would not otherwise have happened.

    The distinction between efficiency and incrementality is important. A retailer’s high-intent audience may naturally contain people who are already close to buying. That can make the segment commercially useful, but a strong conversion result is still a performance observation unless the measurement design supports a causal lift claim. Label the result accurately: performance, comparative performance or incremental lift should not be treated as interchangeable terms.

    Set the decision rule before the campaign runs. State which conversion matters, which comparison you will use, which campaign variables must remain consistent and what result would lead you to expand, revise or stop the activation. The rule does not need an invented universal benchmark. It needs to match your economics and be agreed by the people who will act on it.

    Audience collaboration also needs a governance check. Document the approved campaign purpose, the people who can access the relevant accounts, the audience naming convention and the performance information each partner expects to review. Platform eligibility answers whether the feature can be used; it does not replace the commercial, privacy or contractual review appropriate to the partners’ relationship. Involve the responsible internal teams before sharing or activating customer-based segments.

    Key takeaways

    • Commerce audience sharing lets eligible retailers and marketplaces make first-party segments available to eligible brands and sellers through Google Ads.
    • The shared segments are limited to commerce media network campaigns; they do not automatically extend to regular Search, Shopping or Performance Max campaigns.
    • The retailer’s setup depends on the relevant Google Ads, Google Merchant Center and data-sharing account relationships.
    • Advertisers can see segment names, customer types and conversion data, while commerce partners can review performance information about audience use and campaign results.
    • A useful segment needs an operational definition, a distinct campaign decision and a named conversion. A persuasive label is not enough.
    • Campaign performance and incremental impact are different claims. Use comparison-based or causal language only when the measurement design supports it.

    If the campaign qualifies, begin with one documented audience, one campaign objective, one primary conversion and one agreed comparison plan. Resolve account ownership and eligibility before creative production begins. If your strategy requires the audience in standard Search, Shopping or Performance Max campaigns, choose another audience path instead of building a plan around access this feature does not provide.

    References


  • How to Read Google Ads Experiments and Funnel Reports

    How to Read Google Ads Experiments and Funnel Reports

    You open Google Ads and see two persuasive narratives. The funnel view shows campaigns contributing across the customer journey, while an AI-generated experiment summary points toward a recommended action. Both can help you make a decision. Neither should make that decision for you.

    The practical job is to separate three questions: Where did campaign activity appear in the journey? Did it cause an incremental result? What exactly will happen if you apply the experiment outcome? Once you keep those questions separate, the reporting becomes far more useful.

    Use funnel reporting to decide where to investigate

    The Performance by stage card on the Google Ads Overview page organizes campaign reporting around awareness, consideration, and action. It brings impressions, CPM, frequency, views, video completion rate, and conversion insights into a journey-oriented view.

    That structure is most useful when you treat each stage as a different decision question. An awareness campaign should not be judged only by the immediate conversions visible at the end of the journey. An action-focused campaign should not receive credit merely because it generated a large number of impressions. Start with the job the campaign was meant to do, then select the evidence that fits that job.

    Funnel stageDecision questionSignals to examine togetherWhat to do next
    AwarenessAre you reaching people at an acceptable exposure pattern?Impressions, CPM, frequency, and Brand Lift when configuredInvestigate reach, repetition, and whether exposure is changing brand outcomes before expanding delivery.
    ConsiderationAre people engaging deeply enough to warrant further investment?Views, video completion rate, and Search Lift when configuredIdentify which campaigns or creative approaches deserve a controlled follow-up test.
    ActionIs campaign activity connected with business outcomes?Conversion insights and Conversion Lift when configuredValidate measurement coverage, incremental impact, and economic value before changing budget or settings.

    Read these signals in pairs rather than isolation. Impressions without frequency do not tell you whether delivery is broad or repetitive. Views without completion rate do not reveal how much of the video people consumed. Conversion totals without knowing which conversion actions are eligible can produce a false comparison.

    The funnel card can also incorporate insights from Brand Lift, Search Lift, and Conversion Lift studies when they are configured. That distinction matters. Routine delivery and engagement metrics tell you what happened inside the reporting system; lift measurement is designed to address whether exposure changed an outcome.

    Do not turn a conversion path into a causal claim

    Branching customer touchpoints converge on an outcome beside two matched groups arranged for a controlled experiment.

    Video impressions can now appear in conversion paths, marked with an eye icon. This gives you visibility into exposure that was previously missing when the path showed video views but not impressions. It does not prove that the impression caused the eventual conversion.

    A conversion path is descriptive. It tells you that an eligible exposure or interaction appeared in the recorded sequence associated with a conversion. Incrementality is a different question: would the conversion have happened without that campaign exposure? A path alone cannot answer it.

    • Use the path to identify patterns worth investigating, not to declare that every recorded touchpoint deserves causal credit.
    • When the decision involves additional spend, use an incrementality method such as Conversion Lift when it is available and appropriately configured.
    • Keep observational language in your internal reporting. Say that video impressions appeared in conversion paths, not that those impressions generated every conversion in those paths.
    • Compare campaigns only after confirming that their conversion coverage is comparable.

    That last check is essential because the added video-impression visibility currently covers eligible web conversions but excludes conversions imported from Google Analytics 4. If your account relies on GA4-imported conversions, a missing video impression may reflect the reporting boundary rather than the absence of an earlier exposure.

    Before presenting a funnel report, label the conversion setup behind it. Note which actions are eligible web conversions, which are imported from GA4, and whether different campaigns are being evaluated against the same set. Without that note, an apparent gap between campaigns may be a measurement-coverage gap.

    Treat the AI experiment summary as triage, not a verdict

    The Summary tab for Google Ads experiments now includes an AI-generated panel covering the experiment goal, key findings, and recommended actions. This can reduce the time required to scan several test scorecards, particularly when you manage multiple experiments.

    Use that panel to find the decision you need to inspect. Then return to the underlying scorecard and run a consistent decision gate. The summary can condense the reported pattern, but it cannot replace the business context that determines whether the pattern is valuable.

    1. Restate the hypothesis. Write the specific change and the result it was expected to improve. If you cannot state both in one sentence, the experiment is not ready for a winner declaration.
    2. Confirm the primary outcome. Use the business outcome selected for the decision, not whichever metric happens to show the most attractive movement.
    3. Check duration and conversion volume. A promising direction based on limited observation is still limited evidence. Do not end a test merely because the automated summary sounds decisive.
    4. Inspect statistical significance. A visible difference is not automatically a reliable difference. If the evidence is inconclusive, record it as inconclusive rather than relabeling it as a tie or a failure.
    5. Test practical significance. A statistically credible change may still be too small, too costly, or too poorly aligned with the business objective to apply.
    6. Review trade-offs. Check whether improvement in the primary metric came with deterioration in a metric that protects cost, lead quality, conversion quality, or another business constraint.
    7. Evaluate the recommendation. Treat the suggested action as a candidate decision that has passed through the preceding checks, not as an instruction that bypasses them.

    This order prevents a common analytical mistake: reading the recommendation first and then searching for evidence that supports it. Decide what would count as success before you let the generated narrative frame the result.

    Statistical significance and business significance should also remain separate. Statistical significance addresses whether an observed difference is likely to be more than random variation under the test assumptions. Business significance asks whether the difference is worth the cost, risk, and operational change. You need both questions, even when the interface emphasizes only one of them.

    Check the consequence before applying a Performance Max result

    An analyst inspects a glowing recommendation at a decision gate connected to several downstream resource channels.

    The word “apply” does not have one universal effect across Performance Max experiments. The outcome depends on the experiment type, so confirm the type before accepting any recommendation.

    Performance Max experimentWhat applying the result doesDecision you must make first
    Migration experimentMoves traffic fully to Performance MaxConfirm that you intend to move all relevant traffic, not merely acknowledge the reported winner.
    Optimization experimentPermanently applies the tested settingsConfirm that every tested setting is acceptable as an ongoing campaign configuration.
    Custom experimentLets you manually select the winning versionCompare the versions against the predefined business outcome and choose deliberately.

    This is the point where a reporting interpretation becomes an account change with spending consequences. Before applying a result, record the control configuration, the tested difference, the experiment type, the selected winner, the expected platform behavior, and the person responsible for the decision. Also write down how you would respond if post-change performance no longer supports the choice.

    A compact decision record keeps the funnel view, the experiment, and the account change connected without pretending they are the same kind of evidence:

    • Business question: What decision are you trying to make?
    • Funnel stage: Is the campaign intended to influence awareness, consideration, or action?
    • Measurement coverage: Which conversion actions and exposure types are represented, and which are excluded?
    • Evidence type: Is the finding descriptive path evidence, an experiment result, or a lift result?
    • Validity check: Were duration, conversion volume, statistical significance, and business objectives considered?
    • Platform consequence: What will applying this experiment type actually change?
    • Decision: Apply, continue collecting evidence, revise the test, or stop without declaring a winner.

    The resulting workflow is straightforward. Use funnel reporting to spot the stage and signal that needs attention. Turn that observation into a specific hypothesis. Choose an experiment when you need to compare a controlled campaign change, or an appropriate lift study when the question is incrementality. Read the AI summary to orient yourself, validate it against the scorecard and business objective, then apply only after confirming the consequence.

    Key takeaways

    • The Performance by stage card is a diagnostic map across awareness, consideration, and action; it is not automatic proof of campaign impact.
    • A video impression in a conversion path shows recorded exposure, not causation.
    • Video-impression paths cover eligible web conversions and exclude GA4-imported conversions, so check coverage before comparing results.
    • AI-generated experiment summaries can speed up review, but duration, volume, statistical significance, practical value, and business objectives still determine the decision.
    • Applying a Performance Max result has different consequences for migration, optimization, and custom experiments.

    At your next review, put one sentence above the dashboard: “We are deciding whether to…” Finish that sentence before opening the AI recommendation. It will tell you which funnel evidence matters, what still needs validation, and whether pressing Apply is justified.

    References


  • Search Marketing Attribution: Measure Incremental Revenue

    Search Marketing Attribution: Measure Incremental Revenue

    Your search dashboard can look healthy while the budget decision remains unresolved. Paid search claims conversions, organic search receives assisted credit, and AI-search referrals appear in GA4 when referral data survives. Then finance asks the question the dashboard cannot answer: how much revenue would disappear if you stopped?

    Choosing another attribution model will not settle that question. You need two connected systems: an evidence chain that follows search activity into realized revenue, and a causal test that estimates what search created rather than merely touched. Here is how to build both without pretending the data is cleaner than it is.

    Attribution assigns credit; incrementality tests causation

    Attribution asks which observed touchpoints should receive credit for a conversion. Incrementality asks whether the conversion happened because of the marketing activity. Those are different questions, and they support different decisions.

    Consider a customer who already intends to buy, searches for your brand, clicks a paid result, and completes the purchase. An attribution model may give the ad full or partial credit because the click is visible. An incrementality test asks how many comparable customers would have purchased without being eligible to see that campaign.

    This distinction matters most when a channel sits close to conversion. Branded Search can collect a large amount of credited revenue without necessarily creating an equally large amount of new demand. Performance Max can span several Google properties, making channel-by-channel paths harder to interpret. For eligible Search and Performance Max campaigns, user-based Conversion Lift creates an unexposed holdout and compares its behavior with that of users who can be exposed. The difference estimates incremental conversions.

    That does not make attribution useless. Attribution helps you reconcile customer journeys, diagnose tracking, allocate observed credit, and identify where conversions are being captured. It becomes misleading only when credited revenue is presented as revenue caused.

    Key takeaways

    • Use attribution to describe observed paths and allocate credit; use incrementality to make causal budget claims.
    • Connect search activity to realized revenue before debating which attribution model deserves the final click.
    • Keep unknown and unattributed revenue visible instead of forcing every conversion into a channel.
    • Run a controlled test when the causal answer could change a meaningful spending decision.
    • Report attributed and incremental results side by side. Never substitute one for the other.

    Build the revenue trail from the business outcome backward

    A continuous illuminated path connects search touchpoints, a conversion gateway, a customer record, a contract, a payment, and gold revenue tokens.

    A reliable measurement plan begins with the outcome your organization recognizes as revenue. It does not begin with the easiest event in GA4 or the conversion a media platform happens to optimize.

    1. Define the commercial outcome. For ecommerce, decide whether the recognized value is the completed order, collected payment, or revenue after refunds and cancellations. For lead generation, distinguish a submitted form, qualified lead, opportunity, and closed-won sale. Write down the event, its valuation method, and the point at which it becomes reportable revenue.
    2. Capture acquisition evidence. Store campaign parameters for links you control, along with the landing page, referrer when available, and timestamp. Add a self-reported discovery question when the buying journey can begin in an AI answer, an untagged result, or another environment that may not pass referral data. Keep the self-reported answer separate from the machine-captured source.
    3. Preserve the first and subsequent touches. Do not overwrite the original source every time a person returns. Retain the initial discovery evidence, the most recent measurable interaction, and relevant intermediate touches so that later analysis can distinguish demand creation from conversion capture.
    4. Carry a stable record into the revenue system. Use an approved internal transaction or lead identifier to connect analytics activity with the order platform or CRM. Avoid relying on names or email addresses as analytical keys when a privacy-safe internal identifier is available.
    5. Reconcile to realized value. Join the record to the value finance recognizes. Document how you treat duplicates, reopened opportunities, cancellations, refunds, repeat purchases, and records that never match.
    6. Measure coverage. Report the share of conversions with a known acquisition source, the share of revenue successfully matched to a transaction or CRM record, and the amount left unknown. A visible unknown bucket is more trustworthy than invented precision.

    AI search makes this discipline especially important. When an AI answer does not pass a referrer or tracked link, a later direct visit cannot reveal the earlier discovery by itself. Self-reported discovery can provide supporting evidence, but it should not silently replace behavioral data. Treat agreement between the two as corroboration and disagreement as a reason to inspect the journey.

    A workable AI-search revenue program puts GA4 setup, a five-level attribution ladder, and a board-ready scorecard in the same measurement system. Traffic collection without revenue reconciliation stops too early. A revenue total without source coverage hides too much.

    Use a five-level ladder to prevent signal inflation

    Search teams often mix visibility, visits, conversions, and revenue in one report even though each represents a different level of evidence. A five-level ladder keeps those claims separate.

    1. Visibility. Rankings, impressions, mentions, citations, or other forms of search presence show that your brand or content can be discovered. They do not establish that a person visited or bought.
    2. Visits. Sessions, referral data, campaign parameters, and landing-page activity show measurable traffic. They still do not prove that the visit produced a qualified outcome.
    3. Qualified outcomes. A business-defined action such as a qualified lead or valid purchase separates meaningful demand from raw activity. The definition must be stable enough to compare across channels.
    4. Attributed revenue. Transactions or closed-won revenue matched to observed search interactions show where measurable credit appears. The attribution model determines how that credit is distributed.
    5. Incremental value. A controlled comparison estimates the additional conversions or revenue caused by the marketing activity. This is the level needed for a causal return claim.

    Apply one rule throughout the report: a metric keeps the label of the highest level its evidence actually supports. Do not multiply AI-search visibility by an average conversion rate and present the result as measured revenue. That calculation may be useful as a forecast or scenario, but it remains modeled value and should be labeled accordingly.

    The same rule applies when you change attribution models. Moving from one credit-allocation method to another can redistribute attributed revenue among touchpoints. It cannot promote the result from attributed revenue to incremental value. A different model changes the accounting view, not the counterfactual.

    For each channel, ask what prevents the evidence from moving to the next level. Missing campaign parameters block clean visit classification. An analytics-to-CRM gap blocks revenue matching. A lack of controlled variation blocks causal inference. This turns the ladder into a measurement backlog rather than a decorative maturity score.

    Run an incrementality test when the answer can change spend

    Two matched miniature markets are separated into treatment and control groups, with a search-marketing beam and additional revenue tokens appearing only in the treatment group.

    Incrementality testing has a real cost. A holdout withholds campaign exposure from some users, and those users may generate fewer conversions. Use the method when the result can change a material decision: whether to retain, reduce, expand, or restructure a campaign.

    Self-serve Google Ads Conversion Lift has explicit eligibility gates for Search and Performance Max. An advertiser needs at least 1,000 observed conversions, excluding conversions that use supplementary data; participating campaigns need a minimum budget of $5,000; and the account needs at least one compatible conversion action. Availability can still vary by account, and alpha or beta campaign types may require assistance from a Google representative.

    Meeting those gates does not guarantee a decisive result. The selected action must occur frequently enough to be statistically useful. Purchases, leads, website activity, and other eligible actions can be evaluated, but the action you choose should correspond as closely as possible to the decision you need to make.

    1. Write the decision first. State which campaign and budget choice the result will inform. A test without a decision attached tends to become an interesting chart rather than an operating tool.
    2. Choose one primary outcome before launch. Define the eligible conversion action and how it maps to revenue. If the action is a lead rather than a sale, keep the test result in incremental leads until you have a defensible lead-to-revenue mapping.
    3. Set the campaign scope. Include the campaigns needed to answer the question and avoid mixing unrelated budget decisions into the same test.
    4. Accept the holdout tradeoff explicitly. A larger holdout can improve the comparison sample, but it also withholds ads from more users. Record who accepted that opportunity cost and why it is proportionate to the decision.
    5. Keep the plan stable. Avoid changing the primary outcome, campaign scope, or interpretation rule after seeing an early result. If operations force a material change, document it rather than presenting the test as untouched.
    6. Translate the output only as far as the evidence allows. Report incremental conversions directly. Convert them to incremental revenue only through an agreed value mapping, then connect that revenue to margin if the budget decision is based on profit.

    Keep two efficiency calculations distinct:

    • Attributed ROAS = attributed revenue divided by advertising spend.
    • Incremental ROAS = incremental revenue caused by the advertising divided by advertising spend.

    Attributed ROAS can be much higher than incremental ROAS when a campaign captures conversions that were likely to happen anyway. That does not automatically mean the campaign has no value. It means its budget case should be made with incremental economics rather than the full amount of credited revenue.

    If you are not eligible for the platform test, do not turn a before-and-after chart into causal proof. A carefully designed geographic or phased-rollout test may provide a comparison when you can maintain a credible control and consistent measurement. If you cannot create that comparison, report attributed performance and state plainly that the incremental effect has not been measured.

    A board-ready scorecard shows the decision, not just the dashboard

    Executives do not need every touchpoint row. They need to see what is observed, what is inferred, what is causal, how much of the revenue trail is covered, and what decision follows.

    Scorecard lineWhat to showQuestion it answersRequired label or caveat
    Attributed revenueRealized revenue allocated to measurable search interactionsWhere did observed credit appear?Name the attribution method and reporting scope
    Incremental outcomeAdditional conversions or revenue estimated by a valid control comparisonWhat did the campaign cause?Show the tested campaigns, primary outcome, and uncertainty provided by the test
    Measurement coverageSource-known conversions, revenue-matched records, and unknown revenueHow complete is the evidence chain?Do not redistribute the unknown bucket
    EconomicsSpend, attributed ROAS, incremental ROAS when available, and the finance-approved value basisIs the activity economically useful?Keep attributed and incremental returns separate
    DecisionScale, retain, reduce, retest, or repair measurementWhat changes because of this result?Name the owner and the condition that would reverse the decision

    Read the combinations, not just the largest number:

    • High attributed revenue and credible positive lift: the channel is receiving credit and creating additional outcomes. Evaluate whether incremental economics support more investment.
    • High attributed revenue and weak or uncertain lift: the channel may be capturing existing demand. Do not use the credited total as proof that the same revenue would vanish with the spend.
    • Low attributed revenue and poor measurement coverage: the result is inconclusive. Repair source capture and revenue matching before treating the channel as ineffective.
    • Attribution changes sharply when the model changes, while experimental lift remains stable: the disagreement is primarily about credit allocation, not whether the campaign caused additional outcomes.
    • No credible control comparison: keep the causal field marked as not measured. A blank causal result is more useful than a confident answer produced by the wrong method.

    In your next reporting cycle, add two lines to every search performance review: “What revenue can we trace?” and “What revenue did we cause?” If the second answer is unavailable, do not replace it with modeled certainty. Mark it as not yet measured, identify the live budget decision it affects, and plan the smallest credible control test around that decision. This prevents credited revenue from being mistaken for created demand.

    References


  • Google Ads AI Max Reporting and Direct Offers: A Control Plan

    Google Ads AI Max Reporting and Direct Offers: A Control Plan

    When Google Ads makes automation easier to deploy, your reporting has to get stricter. AI Max can expand targeting and apply brand or location-related controls, while Direct Offers can put a context-selected incentive in front of a shopper inside AI Mode. Those capabilities can help, but they also blend media optimization with commercial policy.

    Your job is to answer two separate questions: what was the automation allowed to do, and did it create profitable demand that would not otherwise have existed? A campaign can improve on an in-platform metric while quietly reaching a different audience, relaxing a targeting boundary, or discounting orders you could have won at full price. The control plan below is designed to expose those differences before you scale them.

    Start with permission reporting, not performance reporting

    Google Ads is adding AI Max reporting columns for Locations of interest, Optimized targeting and Brand inclusions. Add them to the campaign-level view before investigating a performance change. They tell you which controls are present, which is the first layer of any useful audit.

    Think of these fields as permission reporting. They describe what a campaign is configured to use; they do not prove that a setting caused an outcome. A conversion increase beside an enabled setting is a lead for investigation, not a causal conclusion.

    Reporting columnWhat it makes visibleWhat you should check
    Locations of interestWhich campaigns use location-of-interest settingsWhether campaigns being compared use the same geographic-intent configuration
    Optimized targetingWhere automated audience expansion is enabledWhether broader reach is intentional and whether it coincides with a change in traffic quality
    Brand inclusionsWhere brand inclusion settings are appliedWhether each campaign has the brand scope your strategy requires

    The columns are still rolling out and may not be visible in every account. If you cannot find one, do not treat its absence from the interface as evidence that the underlying behavior is disabled. Confirm the campaign settings directly until the reporting fields reach your account.

    Once the columns are available, build a repeatable campaign view:

    1. Add all three AI Max columns to the same view as the outcome metrics your team actually uses.
    2. Keep campaign identity, status and commercial objective visible so campaigns with different jobs are not compared as if they were interchangeable.
    3. Save a dated export or configuration record. That gives you a snapshot of the permissions in place when results were measured.
    4. Flag unexpected combinations, such as an expansion setting enabled on one campaign but not on otherwise comparable campaigns.
    5. Resolve configuration mistakes before interpreting performance. Analysis built on unintended settings only explains the wrong experiment more precisely.

    This view should let you scan from configuration to outcome in one row. If an analyst has to open every campaign individually to discover the relevant settings, setup differences are too easy to miss and too slow to audit.

    Compare configuration cohorts before explaining a performance gap

    Three parallel campaign pathways pass through different permission controls before reaching comparable shopper groups.

    Campaign averages become misleading when they combine different automation permissions. Create configuration cohorts instead. One cohort might contain campaigns with Optimized targeting enabled; another might contain campaigns without it. You can then subdivide them by Locations of interest and Brand inclusions when those distinctions matter to the question.

    Do not automatically call one cohort a control group. A credible comparison also needs a similar commercial objective, market, offer, audience opportunity and measurement setup. A branded campaign and a prospecting campaign remain different even if their three AI Max columns match exactly.

    Use this sequence when a campaign begins outperforming or underperforming its peers:

    1. Define the business symptom. State whether the issue is lead quality, sales volume, acquisition cost, conversion value or profit. Avoid the vague diagnosis that performance changed.
    2. Map the permission state. Record the values of Locations of interest, Optimized targeting and Brand inclusions for the affected campaign and its intended comparators.
    3. Separate mismatched campaigns. Compare like configurations first. If the difference disappears, the blended average was hiding a setup distinction.
    4. Check timing. Place the first visible performance change beside the dated configuration record and other campaign changes. A setting that was already stable before the change is a weaker explanation than one altered at the same time.
    5. Change one decision at a time where practical. If targeting, bidding, creative and promotion all change together, you may improve the result but lose the ability to explain why.
    6. Write down the interpretation. Record the setting, expected mechanism, primary metric and condition that would disprove your explanation.

    The last step is important. A statement such as “Optimized targeting improved the campaign” is too broad to test. A useful interpretation is narrower: enabling expansion was followed by more qualified conversions in comparable campaigns while cost and downstream quality stayed within the team’s accepted limits. That claim can be monitored and challenged.

    Also look for configuration drift. Two campaigns that were launched from the same template can stop being comparable after later edits. The new columns make that drift easier to spot, but only if somebody owns the exception review. Assign that check to a named role and run it on the same cadence as your normal campaign review.

    Build Direct Offers as governed promotions

    Direct Offers add a second kind of automation: Google can decide not only when an offer is relevant, but also which incentive to present. The beta-labeled asset can be created at the account or campaign level, and it is limited to campaigns using AI Max or text customization.

    The setup asks for an internal offer name, final URL and short description. Google AI uses the description to judge relevance and can generate the customer-facing offer text. If you provide multiple incentives, the system can select among them using the shopper’s behavior and context. That makes the description and incentive set part of your targeting logic, not just administrative copy.

    Start with a campaign-level pilot unless you have a clear reason to expose the offer across the account. A campaign-level asset narrows the commercial blast radius and makes it easier to connect claims and redemptions to a defined test population.

    Use the following launch checklist:

    • Name the offer for analysis. Include the campaign or product scope, incentive and intended run period in the internal name. Someone reviewing an export later should not have to decode Offer 1.
    • Send traffic to the exact destination. The final URL should land where the promoted product, service or eligibility conditions can be understood and the incentive can actually be redeemed.
    • Write the description as an AI instruction. State what is being offered and the context in which it is relevant. Do not rely on clever promotional language to carry eligibility rules.
    • Begin with one incentive. Multiple incentives are supported, but allowing AI to choose among them immediately makes the first result harder to interpret. Establish a baseline before testing an incentive set.
    • Use a dedicated code batch. Single-use promotional codes can be uploaded by CSV. Keep the pilot’s codes separate so a redemption can be reconciled to the offer rather than mixed with codes from email, affiliates or customer support.
    • Set the contractual boundaries. Add the applicable terms and conditions, terms URL, start date and end date. Make sure the landing page and checkout enforce the same promise the shopper sees.
    • Cap the exposure. Direct Offers support daily limits based on total offer value or number of claims. Select the type that controls your real constraint, then set it before activation.

    A claim-count limit is useful when code inventory or fulfillment capacity is scarce. A total-value limit gives you a closer control on financial exposure, especially when incentives have different values. Neither replaces a complete promotional budget because a claim is not necessarily a redemption and a redemption is not necessarily an incremental sale.

    The shopper can see an eligible promotion beneath a sponsored result in AI Mode as a Claim one-time code option. Opening it reveals the offer details and code, along with a button to visit the advertiser’s website. Review the entire handoff from that promise to the landing page and checkout. If the displayed terms and the site experience disagree, pause the offer rather than asking support staff to repair the mismatch after purchase.

    Promotional terms can also create financial and legal exposure. If eligibility, expiry, exclusions or consumer rights require formal review in your market, put the Direct Offer through the same legal and operational approval process as any other public promotion. AI-selected delivery does not make the underlying promise less binding.

    Measure discount economics beyond claims and conversions

    A promotional tag, shopping basket, cost layers, approval gate, and branching purchase paths form a visual model of discount economics.

    A Direct Offer has at least six commercially distinct events: the offer is shown, its details are opened, a code is claimed, the shopper reaches the site, the code is redeemed and an order is completed. Do not collapse that chain into a single conversion number. Each transition answers a different question.

    DecisionMeasurementWhat a problem can mean
    Is the offer attracting attention?Claims or detail opens relative to observable offer exposureThe incentive, relevance decision or presentation is not compelling enough to prompt action
    Can shoppers use it?Redeemed codes relative to claimed codesThe site journey, eligibility rules, expiry or checkout process is creating friction
    Does it produce completed business?Completed orders and revenue tied to redeemed codesClaims are not progressing to purchases, or order tracking is incomplete
    Is the promotion affordable?Realized discount cost and contribution after the discountAdditional sales may still be eroding margin
    Is the result incremental?Difference versus a credible unoffered comparisonThe offer may be subsidizing orders that would have occurred at full price

    Use the denominator you can actually observe, and label it precisely. Claims divided by offer views is not the same metric as claims divided by sponsored-result impressions. If a required exposure event is not available in your account, report the narrower metric rather than manufacturing a rate from incompatible events.

    Reconcile the advertising record with your commerce or lead system. The promotional code is the bridge: it lets you distinguish a code that was claimed from one that was redeemed, and a redemption from an order that remained valid after returns, cancellations or lead qualification. Do not assume the Google Ads interface contains every downstream business outcome you need.

    Track the realized discount separately from media spend. A promotion can improve conversion efficiency inside an ad platform while the associated margin reduction appears only in the order system. Your decision table should therefore place ad cost, discount cost and contribution in the same review, even if the data originates in different systems.

    Redemption alone cannot establish incrementality. Some shoppers who use a code would have purchased without one. The cleanest test is a randomized unoffered group when your setup supports it. If it does not, use the closest comparable campaign or audience cohort you can maintain, keep other meaningful changes stable and document the limitations. A simple before-and-after comparison is weaker because seasonality, demand shifts and other campaign edits can move at the same time.

    Set decision rules before the pilot starts:

    • The maximum daily offer value or claim count you will permit.
    • The minimum contribution the promoted orders must retain.
    • The comparison you will use to judge incremental orders or leads.
    • The code redemption and completed-order events that must reconcile.
    • The conditions that trigger a pause, such as exhausted code inventory, a checkout failure, incorrect terms or unacceptable margin.
    • The evidence required before you add more incentives or move from campaign-level to account-level deployment.

    Read the failure pattern, not just the final total. Many claims with few redemptions points toward a broken or confusing handoff. Many redemptions without incremental growth points toward cannibalization. Few claims followed by strong purchase quality may indicate narrow relevance or limited exposure; it does not automatically justify a larger discount. Each pattern calls for a different response.

    Key takeaways

    • The new AI Max columns expose campaign permissions; they do not prove why performance changed.
    • Compare campaigns in configuration cohorts before attributing a result to Locations of interest, Optimized targeting or Brand inclusions.
    • Start a Direct Offer at campaign level with one incentive when you need a test that is easier to interpret and contain.
    • Treat the offer description as an input to AI relevance and generated copy, not as a private note.
    • Use claim limits for operational scarcity and value limits for financial exposure, then track the full promotional budget outside the asset.
    • Judge success through redemptions, completed outcomes, realized discount cost, contribution and incrementality – not claim volume alone.

    When the new columns appear in your account, export the current permission state before changing anything. Then choose one eligible campaign, document its baseline, connect a dedicated code batch to completed-order data and launch only with a hard exposure limit. That gives Google room to optimize while preserving your ability to explain what happened and decide whether it deserves to scale.

    References


  • Google Demand Gen View-Through Attribution: What Changed

    Google Demand Gen View-Through Attribution: What Changed

    If view-through conversions in a Demand Gen campaign move while spend, clicks, and downstream sales or leads look ordinary, do not assume the campaign suddenly became more or less effective. The reporting method itself may have changed underneath your benchmark.

    Google has lowered the threshold that a Display ad within Demand Gen must meet before a later conversion can receive view-through credit. That distinction matters whenever you evaluate creative, calculate performance, move budget, or report results across the transition.

    Key takeaways

    • The change is limited to Display ads within Demand Gen campaigns. It is not a blanket redefinition of every Demand Gen ad view.
    • The qualifying event is moving from an Active View-based view to a rendered ad impression.
    • Under the new definition, an impression can qualify when at least one pixel of the ad appears onscreen, even momentarily.
    • The conversion event is not being redefined. Google is changing which preceding ad views can receive credit for it.
    • A rise in view-through conversions may reflect broader attribution eligibility rather than stronger advertising performance.
    • Keep pre-change and post-change benchmarks separate, and require corroborating evidence before changing budgets or performance targets.

    The attribution gate changed, not the conversion event

    A view-through conversion, or VTC, connects a conversion to an eligible ad impression rather than to a click on that ad. Two events therefore matter: a person converts, and an earlier impression qualifies to receive view-through credit.

    Google is changing the second event for Display ads inside Demand Gen. The old method used Active View and its viewability standards to decide whether an impression was sufficiently viewable. The new method uses a rendered ad impression, which has a lower qualification threshold.

    Measurement questionActive View methodRendered-impression method
    What qualifies the preceding ad exposure?An impression that satisfies Active View viewability criteriaAn impression with at least one pixel onscreen for any amount of time
    How demanding is the qualification gate?HigherLower
    What happens to the conversion event itself?No change from this updateNo change from this update
    Which campaign inventory is covered?Display ads within Demand Gen campaigns

    Do not fill in the missing Active View criteria from memory or apply a familiar viewability threshold from another report. You do not need a percentage or duration to interpret this update correctly. The decision-relevant fact is that one onscreen pixel, however briefly displayed, can now make the impression eligible under the rendered-impression definition.

    Google’s stated reason is measurement consistency across Demand Gen inventory. That may make reporting conventions more uniform inside the campaign type, but consistency across inventory does not create continuity across time. A VTC reported under the old rule is not methodologically identical to one reported under the new rule.

    The announced transition is automatic for eligible campaigns, with no campaign-setting change required from advertisers. Your immediate job is therefore to protect reporting continuity, not to reconfigure campaign delivery.

    Why the same campaign can report more view-through conversions

    Think of VTC attribution as a gate. Under the earlier method, an impression had to pass Active View’s viewability test before it could participate in view-through attribution. Under the new method, merely rendering one pixel onscreen can open that gate.

    Lowering the gate can enlarge the pool of impressions eligible to receive credit. If people in that larger pool later convert, more conversions may be classified as view-through conversions even when the campaign did not generate additional purchases, form submissions, or other underlying conversion events.

    This does not mean every affected campaign will report an increase. Delivery, audience mix, spend, conversion lag, and actual customer behavior can all move at the same time. The update supplies a plausible measurement explanation for a change in VTCs; it does not predict the size or direction of every account’s result.

    The more important distinction is between attribution and incrementality. A VTC tells you that the platform connected an eligible impression with a later conversion under its rules. It does not, by itself, prove that the impression caused a conversion that would otherwise never have happened. A broader eligibility rule makes that distinction more important, not less.

    The definition can also change calculated KPIs. If an internal cost-per-acquisition calculation divides spend by a platform-attributed conversion count, additional VTC credit can make CPA appear lower. If a return calculation includes value assigned to those VTCs, reported return can rise. The arithmetic may be correct while the apparent improvement is methodological rather than commercial.

    Use corroborating signals before changing budget

    A balanced decision mechanism receives signals from an ad impression, a click, a conversion, and a stack of budget coins.

    Do not judge the transition from the VTC column alone. Compare that movement with signals that do not depend on the revised view definition: clicks, conversion paths involving clicks where separately available, qualified leads, completed orders, revenue, and other outcomes recorded in your own business systems.

    Pattern you observeWhat it can meanWhat to do next
    VTCs rise while clicks and independently recorded outcomes stay flatThe broader view definition is a strong candidate for at least part of the increase.Do not increase budget from the VTC movement alone. Annotate the methodology break and inspect the affected Display inventory.
    VTCs, click-associated results, and independently recorded outcomes all improveThere may be a real performance gain, although the definition change can still contribute to the VTC increase.Base the decision on the corroborating outcomes and a post-change benchmark, not on the full VTC difference.
    VTCs stay broadly stableThe practical effect may be small for this campaign or masked by other changes.Keep the reporting annotation. Stability does not make the pre-change and post-change methods identical.
    VTCs declineThe lower eligibility threshold does not explain the decline by itself.Investigate delivery, spend, audience mix, conversion lag, tracking, and business outcomes before assigning a cause.

    This check is especially important for automated spreadsheets, dashboards, scorecards, and budget rules that consume an attributed conversion total. A methodology-driven increase can silently trigger a recommendation to scale, make a target appear easier to reach, or make a post-change creative look stronger than a pre-change control.

    Pause those conclusions, not necessarily the campaign. The campaign may be performing well; the point is that this particular before-and-after comparison can no longer establish why.

    Build a clean reporting bridge across the rollout

    Two separate data platforms in muted and bright colors are connected by a two-lane illuminated bridge across a rollout boundary.

    You cannot recover comparability by pretending the definition stayed constant. You can preserve decision quality by treating the rollout as a measurement break and documenting it explicitly.

    1. Identify the affected slice. List the Demand Gen campaigns containing Display ads. Do not apply the same warning indiscriminately to unrelated campaign types or to every format inside Demand Gen.
    2. Preserve the old baseline. Save the last available pre-change reports with spend, impressions, clicks, VTCs, attributed conversion value where used, and independently observed leads or sales. Keep the raw export rather than only a chart or percentage change.
    3. Mark the methodology break. Add the change to dashboards, recurring reports, experiment logs, and client or leadership notes. If you do not have a confirmed account-level cutover date, label it as an estimated transition period instead of inventing a precise date.
    4. Separate the reporting eras. Calculate post-change VTC rates, CPA, return, and targets from post-change data. Retain the earlier benchmark for historical context, but do not blend the two periods into one continuous trend line without a visible warning.
    5. Keep the comparison conditions honest. When reviewing periods on either side of the change, account for spend, delivery, audience mix, campaign edits, conversion lag, and changes in the underlying business. The definition shift is one variable, not permission to ignore the others.
    6. Require an independent decision signal. Before increasing budget or declaring a winning creative, look for support from clicks, qualified leads, orders, revenue, or an appropriately designed experiment. The corroborating metric should not rely on the newly broadened view threshold.

    Suggested reporting note: View-through attribution eligibility for Display ads in Demand Gen changed from an Active View-based definition to a rendered-impression definition. Post-change VTC results are not directly comparable with the earlier baseline.

    Avoid creating a blanket adjustment factor to make old and new VTC totals look comparable. No universal uplift amount is provided, and the effect can vary with each campaign’s delivery and conversion behavior. Multiplying historical results by an assumed correction would replace a known methodology break with an invented one.

    The rollout was described as automatic over a period of weeks, so do not assume every account changed on the same day. For agencies or teams combining several accounts, keep the transition status at the account or campaign level until you can justify a shared post-change baseline.

    Make the next performance decision on the new baseline

    The safest immediate move is simple: add the methodology note to your recurring Demand Gen report, split the VTC trend at the transition, and check every budget recommendation against at least one outcome that does not depend on view-through eligibility.

    Once you have enough post-change data for your normal buying and conversion cycle, set fresh benchmarks under the rendered-impression definition. You can still use VTCs as an attribution signal. Just stop asking the old baseline to answer a question measured under a new rule.

    References


  • How to Test ChatGPT Visual Ads and Measure Incremental Lift

    How to Test ChatGPT Visual Ads and Measure Incremental Lift

    You have a budget decision to make: treat ChatGPT visual ads as a testable acquisition channel, or wait until the reporting ecosystem matures. The answer doesn’t depend on how novel the placement looks. It depends on whether you can connect the ad to a business outcome and then show that the spend caused more of that outcome.

    That distinction matters because a strong attributed return can still reflect demand that already existed. Before you fund a pilot, build a measurement plan that separates delivery, attribution and incremental lift. Otherwise, you may get an encouraging dashboard without learning whether the channel deserves more money.

    Visual ads create a paid surface, not organic AI visibility

    ChatGPT’s visual ads are intended to present products, services and experiences through imagery. The initial test is planned for image-generation experiences with a group of U.S. advertisers. The ads will be labeled and kept separate from images generated by ChatGPT.

    That separation gives you the first rule for reporting: paid exposure is not an organic recommendation, citation or answer-engine visibility win. Keep ChatGPT Ads in your paid-media scorecard. Track organic ChatGPT mentions, citations and referral traffic separately. If the same landing page receives both, use distinct campaign identifiers wherever the available implementation permits it.

    The image-generation setting also changes the creative question. A conventional display asset may be designed to interrupt passive browsing. Here, the surrounding activity involves making or refining visual material. That doesn’t prove a particular user intent, but it gives you a sensible creative hypothesis: the image should make the product, service or experience immediately understandable without pretending to be part of the generated output.

    • Show the offer clearly. A viewer should be able to identify what is being advertised before reading supporting copy.
    • Choose one proposition per variant. If an image tries to communicate price, quality, use case, social proof and product range at once, you won’t know which idea affected performance.
    • Preserve message continuity. The landing page should repeat the product, promise and visual cues used in the ad. A visual click followed by an unrelated page weakens both conversion rate and your ability to diagnose the creative.
    • Keep paid and generated media distinct internally. Asset names, reports and presentations should call the unit an ad. Don’t describe impressions as appearances in ChatGPT-generated images.
    • Request the actual creative specification. Confirm supported dimensions, copy fields, file limits, review rules and destination behavior before resizing an existing campaign library.

    OpenAI says ChatGPT reaches 1.2 billion people each week. That is a platform-supplied reach figure, not an estimate of addressable buyers or commercial intent. Use scale as a reason to investigate the channel, not as the input for a revenue forecast.

    Build the measurement chain before you launch creative

    A visual ad card passes through four connected transparent measurement modules on a dark tabletop.

    The announced measurement ecosystem has four distinct layers. They are related, but they do not answer the same question. Treating every integration as “tracking” is how teams end up with several dashboards and no agreed result.

    Measurement layerNamed partnersQuestion it should answer
    Conversion-data connectionsHightouch, Tealium and LiveRampCan confirmed business outcomes be sent back into the advertising platform?
    AttributionAppsFlyer, Triple Whale, Adjust, DV Rockerbox, Northbeam, Branch, Singular, Kochava, Airbridge and TenjinWhich tracked conversions receive credit for a ChatGPT Ads touchpoint?
    Full-funnel measurementFospha, Measured and INCRMNTALHow does the channel appear to contribute across the customer journey?
    Geo-based incrementalityHaus, Measured and WorkMagicDid exposure create additional conversions that would not otherwise have occurred?

    These announced partner relationships give you a map of the emerging stack. They do not establish that every connection has identical capabilities, availability or eligibility. Ask each vendor what data moves, in which direction, how often it updates, how conversions are matched, and what reporting is actually available for your account.

    Your internal data contract should come first. A partner cannot repair an event that fires inconsistently, counts duplicate orders or changes meaning midway through the test.

    1. Name one primary outcome. Use the event that represents business value, such as a completed purchase or a lead that has passed your qualification rule. Page views and button clicks can help diagnose the path, but they should not replace the outcome.
    2. Write the counting rule. State when the event becomes valid, how cancellations or invalid leads are handled, and whether repeat transactions count. Apply the same definition to every channel in the comparison.
    3. Deduplicate at the transaction level. Pass a stable order or conversion identifier through the systems that are permitted to receive it. One purchase reported by a browser, server and partner must remain one purchase.
    4. Preserve the fields needed for analysis. Record timestamp, conversion value, currency, campaign identifier and new-versus-returning customer status when those fields are available and allowed by your consent and data-governance rules.
    5. Choose the source of truth. Decide whether final revenue comes from your commerce platform, CRM or another controlled system. Ad and attribution dashboards can explain credit; they should not silently redefine booked revenue.
    6. Test the path end to end. Complete a controlled conversion, confirm that it appears once in the source of truth, and verify that each connected system receives the expected event and value.
    7. Freeze the measurement definitions. Document attribution windows, identity rules, exclusions and late-arriving conversion treatment before launch. If a definition changes, annotate the date and avoid blending the two periods as though they were comparable.

    This setup gives you traceability. When two dashboards disagree, you can inspect event definitions, matching and attribution settings instead of debating which total looks more favorable.

    Attribution tells you who received credit; incrementality tests causation

    A split illustration shows converging customer paths beside two matched groups, one exposed to an ad and producing extra outcome tokens.

    An attributed conversion occurred after a measurable advertising touchpoint and was assigned to that touchpoint under a defined rule. An incremental conversion is an estimated additional outcome caused by the advertising. Those are different claims.

    Suppose someone was already likely to buy, saw a ChatGPT ad and then converted. An attribution model may award the ad some or all of the credit. An incrementality design asks what would probably have happened without the ad. The first result can be useful for journey analysis; the second is the stronger basis for increasing budget.

    The early results illustrate why you must read each metric literally rather than combine them into a single success narrative.

    Early partner-reported resultWhat it supportsWhat it does not establish
    DV Rockerbox measured WeightWatchers’ attributed CPA from ChatGPT Ads at 15.3% below its blended paid-search benchmark.Attributed acquisition cost compared favorably with that advertiser’s chosen benchmark in that measurement.It does not by itself prove incremental lift or provide a benchmark for another advertiser.
    WorkMagic found that 67% of Dose’s incremental purchases came from new customers.The reported incremental purchases included a substantial new-customer component in that case.It does not reveal how another brand’s customer mix, total lift or economics will behave.
    Triple Whale reported that 93% of Portland Leather visitors from ChatGPT Ads were new.The tracked visitor mix was heavily weighted toward new visitors for that advertiser.New visitors are not automatically new customers, incremental purchases or profitable orders.

    These are preliminary, partner-reported results from individual advertisers, not broad platform benchmarks. They can justify forming testable hypotheses. They cannot justify inserting the same CPA improvement or new-customer share into your forecast.

    A useful reporting hierarchy has three levels:

    • Delivery validation: Did the campaign spend and produce measurable visits or other intended responses? This tells you whether the setup functioned.
    • Attributed efficiency: What cost per attributed outcome and attributed return did your chosen model report? This helps compare credit under consistent rules.
    • Incremental business impact: How many additional outcomes did the experiment estimate, and at what incremental cost? This is the scale-or-stop question.

    For a geo-based incrementality test, work with the measurement partner to choose comparable exposed and control regions, account for their pre-test differences, and set the primary outcome before delivery begins. Keep major promotions, pricing changes and channel shifts consistent where possible. When they cannot be kept consistent, log them so the analysis can account for a contaminated period rather than treating it as clean.

    Define the budget decision in advance as well. Your acceptable incremental acquisition cost should come from unit economics, not from the platform’s attributed CPA. If the estimated lift is too uncertain to distinguish from normal variation, call the result inconclusive. Do not relabel uncertainty as zero impact, and do not scale it as proof of success.

    Use a test charter that forces a scale, iterate or stop decision

    A pilot becomes useful when it resolves a decision. Before the campaign starts, put the following items on one page and require the channel owner, analyst and business owner to agree on them.

    1. Decision: State what will happen after the readout. Examples include expanding the test, revising the offer or creative, or stopping spend. Avoid goals such as “learn about the channel” that permit any result to look acceptable.
    2. Hypothesis: Describe the mechanism you expect. A useful form is: a clearly visual presentation of this offer will generate additional qualified demand from this type of need, producing an incremental outcome within our acceptable economics.
    3. Primary metric: Select one business outcome and define its numerator and denominator. Keep diagnostic measures such as click-through rate, landing-page engagement and attributed conversions secondary.
    4. Incrementality method: Name the geo design or other approved causal method, the measurement partner, the exposed and control units, and the planned analysis. Do not add incrementality after seeing an attributed result you like.
    5. Creative variables: List the element each variant changes. Change one major proposition at a time when the available delivery controls make that practical; otherwise, a winning asset will not tell you what to reuse.
    6. Landing-page path: Record the destination, conversion steps and analytics events. Confirm that the page supports the exact claim shown in the visual.
    7. Data owners: Assign one person to conversion integrity, one to paid-platform operations and one to final analysis. Shared accountability without named owners usually means unresolved discrepancies at readout.
    8. Decision thresholds: Write the minimum acceptable business result and the treatment of statistical uncertainty before launch. Use your own margin, retention and capacity constraints rather than copying a partner-reported case.
    9. Confounder log: Track promotions, inventory shortages, site outages, price changes, major organic coverage and material changes in other paid channels.

    At the readout, separate creative diagnosis from channel diagnosis. Weak delivery or a broken conversion path means you did not get a valid channel test. Strong attribution with no measurable lift means the ads may be capturing existing demand. Incremental conversions with unacceptable economics mean the channel caused an effect, but not one you should scale in its current form.

    Use three possible decisions. Scale only when the data chain is sound and incremental economics meet the prewritten requirement. Iterate when the test is valid but points to a specific repairable constraint, such as the offer, creative clarity or landing-page path. Stop when a valid test misses the business threshold and there is no evidence-backed change likely to alter the result.

    Treat brand suitability as an operating control

    Brand safety and brand suitability are related but not identical. Safety addresses broadly harmful or unacceptable environments. Suitability applies your brand’s own tolerance to contexts that may be acceptable for one advertiser and wrong for another.

    OpenAI is developing brand-suitability evaluation pilots with DoubleVerify and Integral Ad Science. The evaluations are planned for controlled environments and do not give those partners access to private user conversations. Qualifying advertisers can also use Negative Phrases for more specific placement requirements.

    Those controls are meaningful, but they do not replace your own policy. A negative-phrase list is only as useful as its coverage, maintenance and enforcement. Build the internal process before launch:

    • Create three context tiers. Mark categories as prohibited, review-required or generally acceptable. This gives campaign operators a decision rule instead of an unstructured list of concerns.
    • Translate prohibited contexts into phrases. Use language that represents the actual context you need to avoid. Confirm the supported matching behavior before assuming that variants, synonyms or related concepts are covered.
    • Record the reason for every restriction. Tie it to legal requirements, product policy, audience sensitivity or brand standards. This makes the list maintainable and prevents unexplained phrases from accumulating.
    • Ask what evidence is available. Determine what placement, suitability or verification reporting your account can receive and at what level of detail. Do not promise internal stakeholders a conversation-level log when the suitability pilots explicitly avoid private conversations.
    • Define escalation and pause authority. Name who reviews questionable placements, who can stop spend and how findings change the phrase list or creative policy.
    • Review controls alongside creative. An accurate placement policy cannot rescue an image that exaggerates the product, obscures material conditions or implies that the ad is ChatGPT-generated content.

    Key takeaways

    • Report ChatGPT visual ads as paid media, separately from organic ChatGPT recommendations, citations and AI-search visibility.
    • Connect a clean, deduplicated business outcome before evaluating creative performance.
    • Use attribution to understand assigned credit, but use incrementality to decide whether the channel created additional conversions.
    • Treat the early advertiser results as hypotheses for your own test, not as planning benchmarks.
    • Set scale, iterate and stop rules before launch so the readout produces a budget decision.
    • Turn brand suitability into a documented policy with phrase controls, evidence requirements and named escalation owners.

    Your next move should be a measurement charter, not a large rollout. Choose one business outcome, verify its data path, define the incrementality design and write the decision threshold. Once those pieces are agreed, creative testing can teach you something durable instead of merely generating another attributed-performance report.

    References