Tag: API

  • Google UGC Fresh Data Program: A Platform Readiness Guide

    Google UGC Fresh Data Program: A Platform Readiness Guide

    If you operate a forum or social platform, the Google UGC Fresh Data Program could shorten the gap between a useful new discussion appearing on your site and Google processing it for Search. But you need more than popular content or valid schema to qualify.

    Approved platforms can use a dedicated ingestion pipeline to send fresh content and interaction signals. That makes this a platform engineering and content-governance project, not an instant-indexing shortcut. Before you apply, use the following checks to find the gaps that could make your platform ineligible or leave your team unable to operate the pipeline reliably.

    Treat the program as a freshness pipeline, not a ranking switch

    The program gives Google a proactive feed of timely UGC and engagement information. Its purpose is to help fresh, authentic, first-hand perspectives get processed and updated quickly across Search features.

    Search mechanismWhat it doesWhat you should not assume
    UGC Fresh Data ProgramAccepts timely content and interaction data from approved UGC platforms through a specialized pipeline.Submission does not guarantee that a page will appear in Search.
    Traditional crawlingLets Google discover and process publicly accessible web content through its normal systems.The UGC pipeline does not replace crawlable pages, stable URLs, or on-page markup.
    Google Indexing APIOperates independently from this program.The UGC program is not an extension of the Indexing API for general web content.
    Search selectionDetermines whether processed content is shown for a particular search experience.Access to the ingestion pipeline does not create a ranking or inclusion guarantee.

    This distinction should shape your internal business case. You are applying for a faster and more direct way to transmit eligible UGC data. You are not buying a place in the results, bypassing Google’s selection systems, or replacing technical SEO.

    It also matters for AI-search planning. Google has described the destination broadly as Search features; it has not identified a specific AI surface or promised visibility in AI-generated answers. Do not forecast AI citations, AI Overview placements, traffic gains, or ranking improvements as outcomes of acceptance. The defensible goal is narrower: make high-quality, public UGC available to Google with less freshness lag.

    Run this eligibility gate before you apply

    Mark each requirement as Ready, Gap, or Unknown. A Gap means you have implementation work to complete. An Unknown means you need evidence, not a more optimistic interpretation of the requirement.

    1. Your platform is primarily built around UGC. The intended candidates are platforms focused on user-generated content, social posts, or forum discussions. A conventional publisher, ecommerce site, or company blog with a comment section is unlikely to satisfy a requirement that the platform primarily host UGC.
    2. Each submission represents content on its own stable page. Eligible UGC should live on dedicated pages with stable URLs, rather than existing only inside a profile or continuously changing feed. Open several older content URLs and confirm that they still identify the same discussion or post.
    3. You can demonstrate meaningful scale. Google expects a high volume of UGC and a significant user base, but no numeric eligibility threshold has been specified. Prepare accurate internal measurements of publishing volume, active participation, public content inventory, and growth without inventing a cutoff Google has not published.
    4. The content is public and attributable. Users and Googlebot must be able to reach the content without a login or paywall. Every UGC item must also be attributable to a creator who has a public profile. Test this while signed out; an employee’s authenticated browser is not evidence of public access.
    5. Your team can support the technical contract. You need the capacity to implement secure OAuth 2.0 authentication, construct JSON-LD payloads that pass strict validation, and maintain valid schema.org markup on the corresponding web pages.
    6. Moderation is an operating function, not a policy page. The platform must not publish illegal content and must actively moderate its UGC. Users also need a reporting mechanism. Confirm that reports enter a monitored workflow with clear ownership; an unmonitored form does not demonstrate active moderation.
    7. You can move at UGC speed. Content should be submitted as fresh as possible, ideally within minutes. Your systems must also be able to provide regular engagement-counter updates within 72 hours of creation.

    Some of these are hard eligibility conditions, not items to place on a post-acceptance roadmap. Public access, creator attribution, stable content pages, moderation, and reporting need to be properties of the live platform. If they apply only to a small pilot area while most of the platform works differently, document that limitation before deciding whether to apply.

    Align the public page, schema, and submitted payload
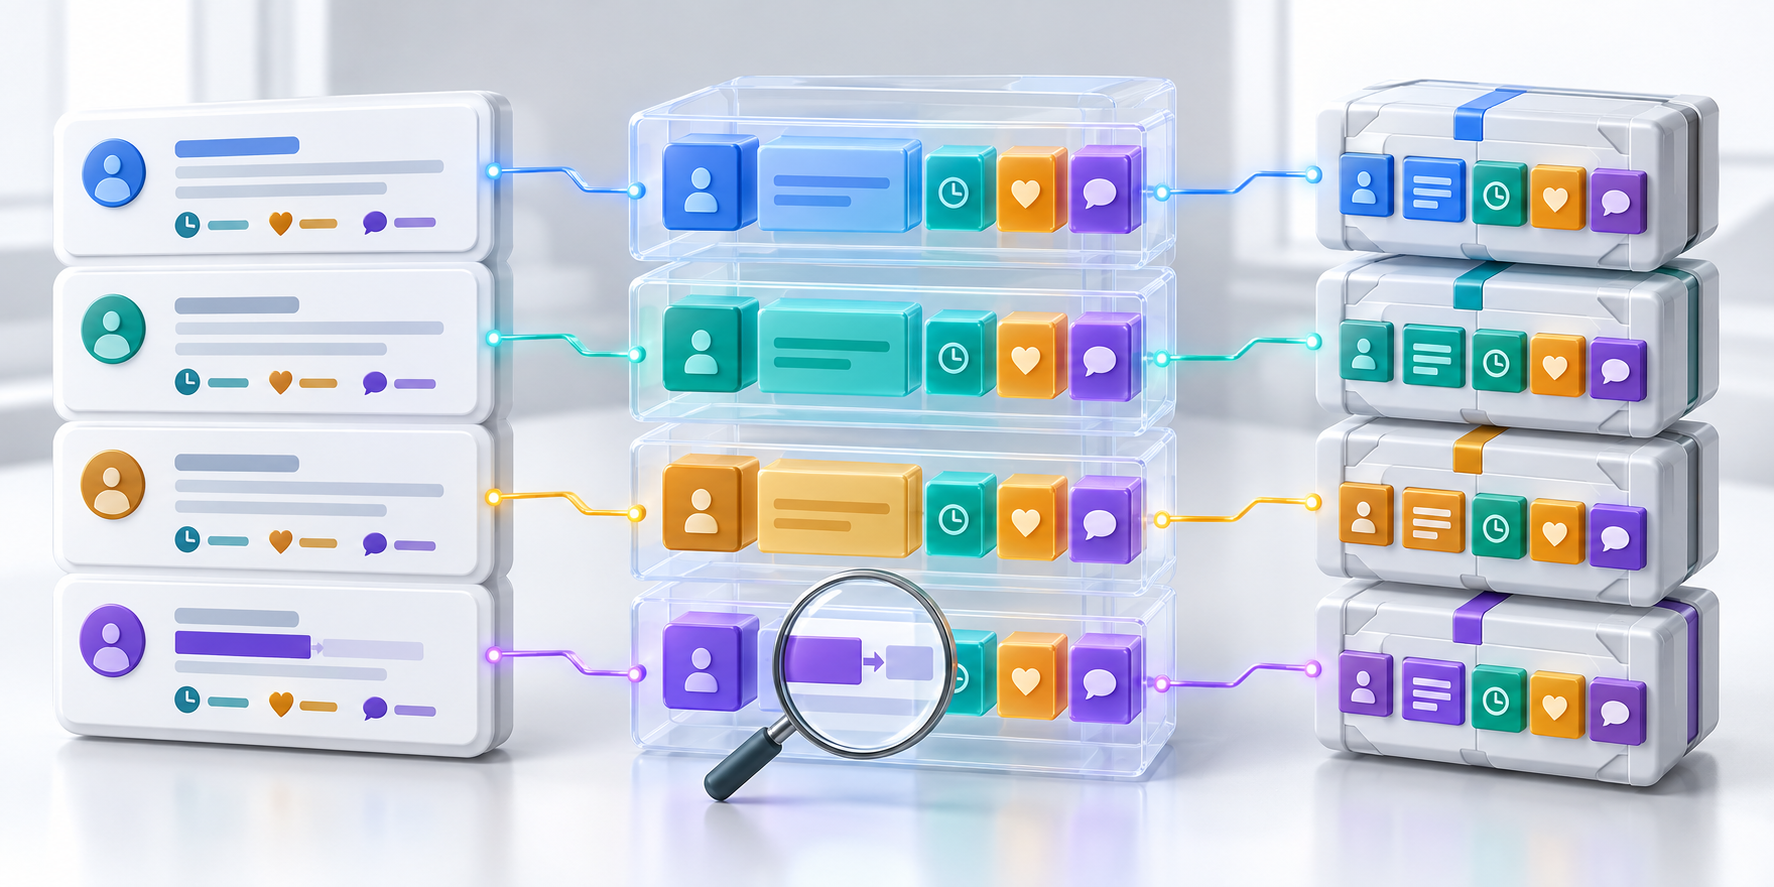
    Matching colored data tokens connect a public discussion page, nested data blocks, and submission payload modules.

    The program creates two structured-data surfaces that your team must keep conceptually separate. One is the schema.org markup embedded on the public URL. The other is the JSON-LD payload transmitted through the dedicated pipeline. Having one does not remove the requirement for the other.

    Google names SocialMediaPosting and DiscussionForumPosting, including interactionStatistic sub-fields, as examples of suitable on-page structured data. Choose a type that describes the content people actually see. Do not label an editorial page as a forum post merely to make it resemble an eligibility example.

    Your safest design uses one internal content entity to generate the public page, the on-page markup, and the pipeline payload. That reduces the chance that the three surfaces disagree about the URL, creator, content state, or engagement totals.

    • Stable content identity: Define which internal record owns the permanent public URL and what happens when a title, category, or moderation state changes.
    • Public creator identity: Map every eligible item to a creator profile that an unauthenticated visitor can open.
    • Schema selection: Record which UGC formats map to SocialMediaPosting, DiscussionForumPosting, or another appropriate schema.org type.
    • Interaction mapping: Identify the counters your product maintains, where their authoritative values live, and how the page and payload will receive consistent updates.
    • Validation ownership: Make one engineering or data team responsible for rejecting malformed payloads before transmission and for detecting broken on-page markup after releases.
    • Eligibility state: Prevent private, gated, removed, unmoderated, or otherwise ineligible records from entering the submission queue.

    Do not guess at undisclosed endpoint behavior or build a production integration around an assumed payload contract. Detailed developer documentation is provided after acceptance. Before then, build the internal mappings, validation boundaries, queue interfaces, and operational ownership that will let you implement the actual contract without redesigning your content system.

    Design for minutes, then keep the counters current
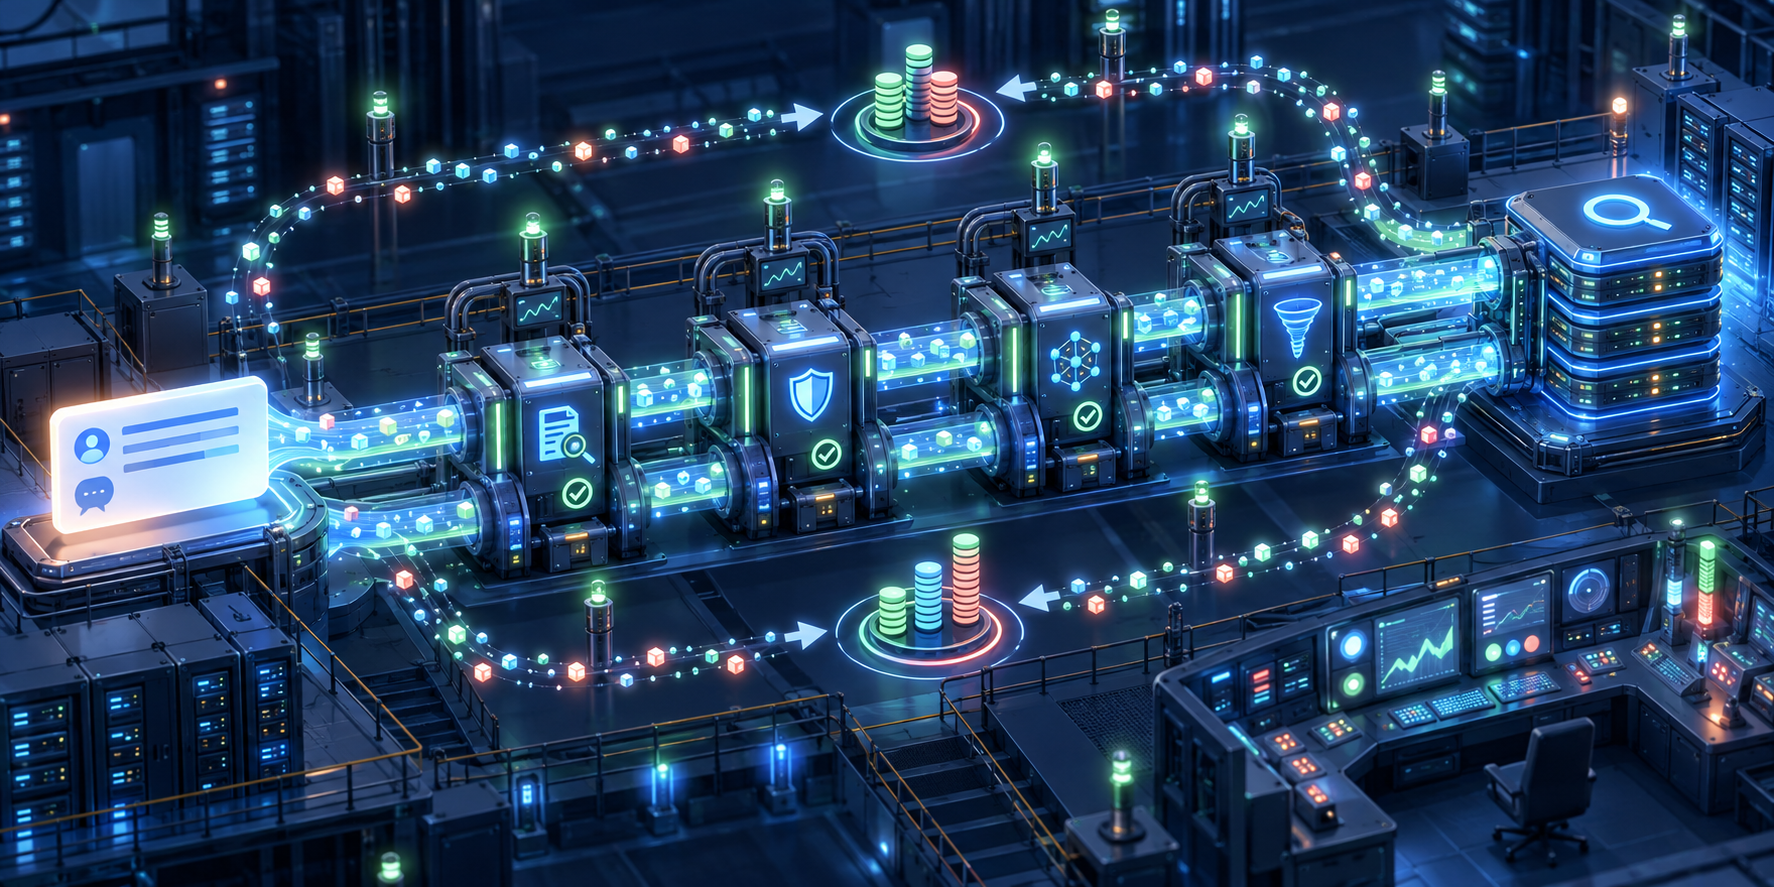
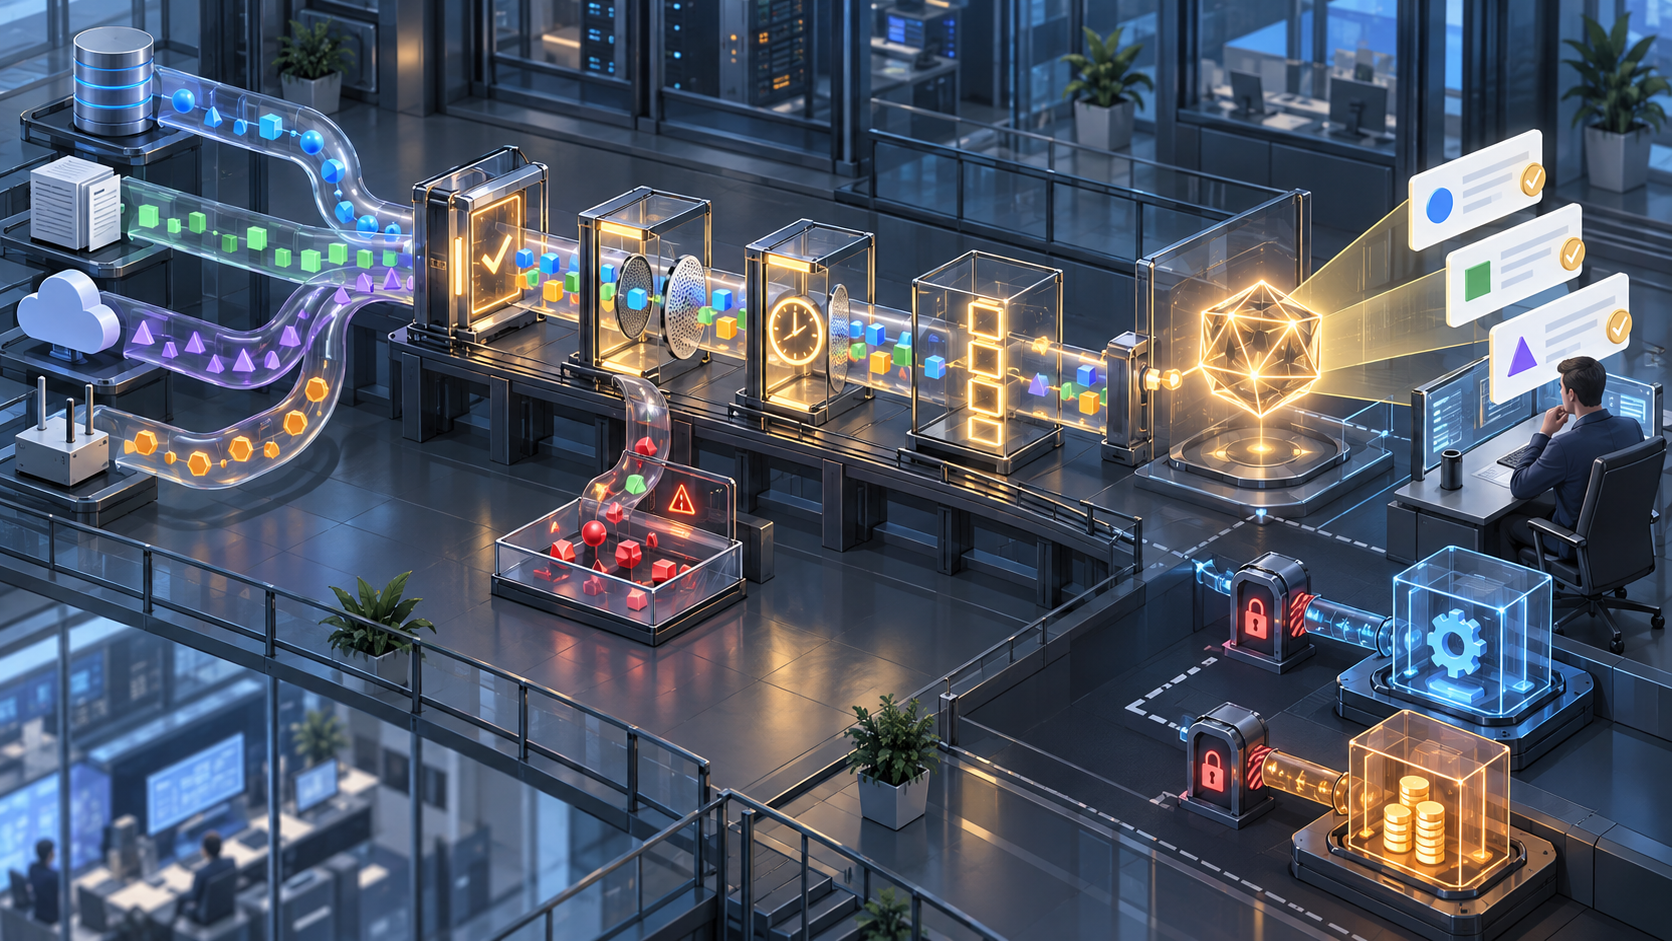
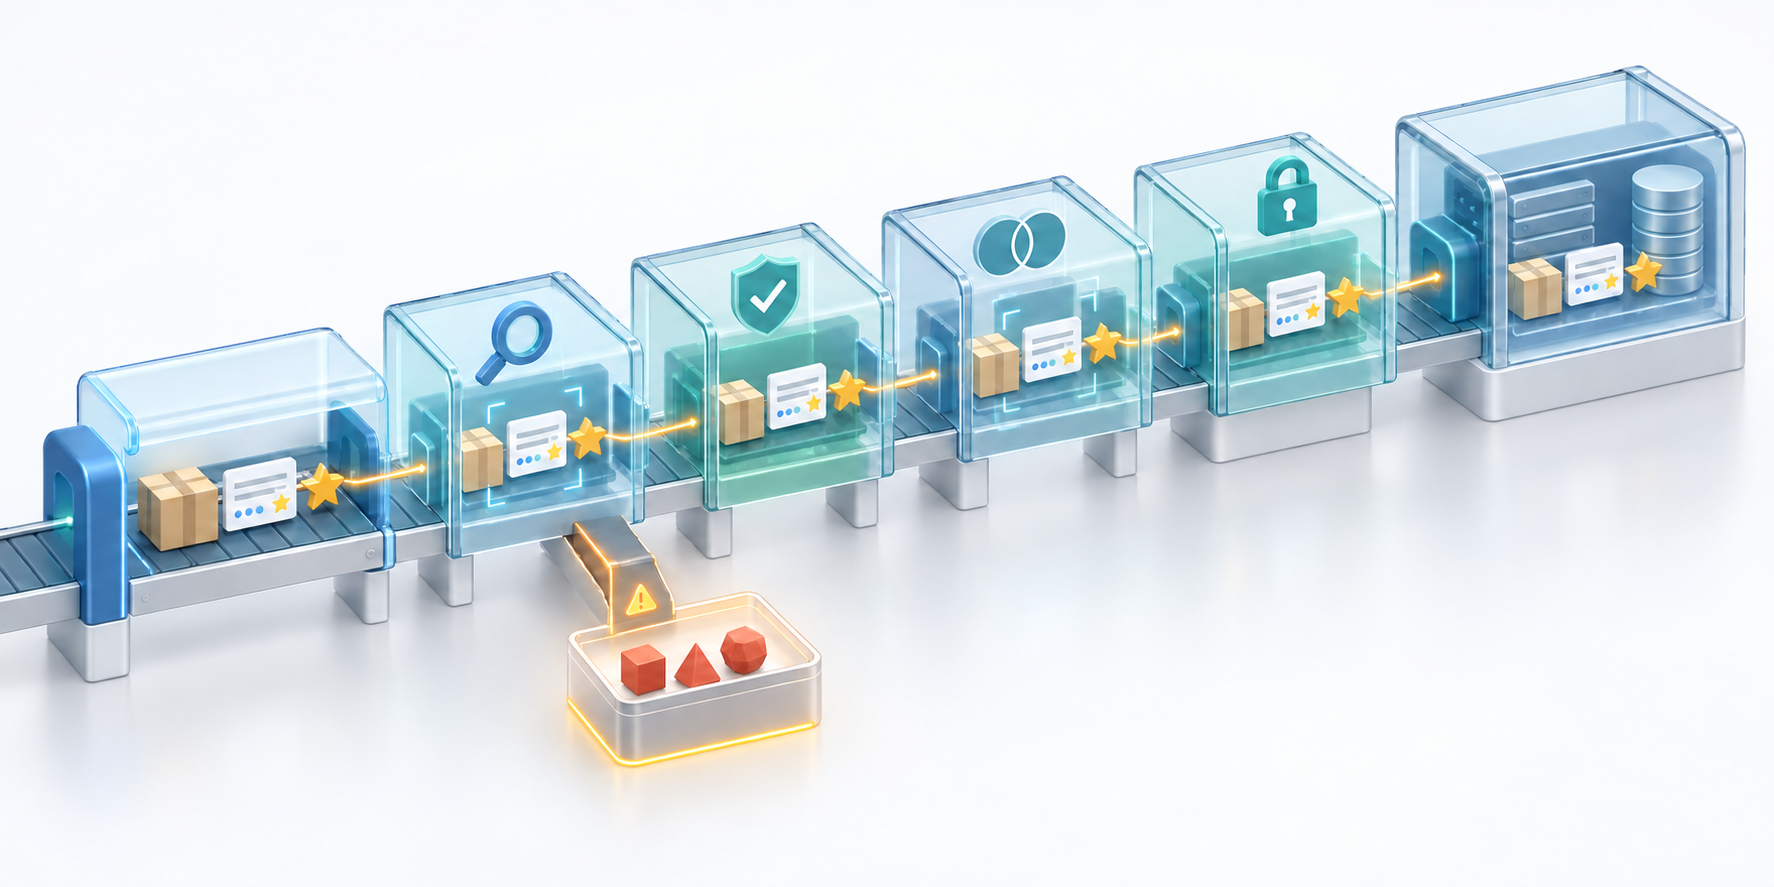
    A glowing discussion card moves through validation checkpoints while interaction particles loop back to update token stacks.

    A nightly export is poorly matched to a program that asks for content within minutes. The publish event should start an observable workflow as soon as the public page, creator attribution, and moderation state are ready.

    1. Commit the public page first. The submitted item should resolve to the dedicated, publicly accessible URL represented by the payload.
    2. Check eligibility at queue entry. Confirm that the item is public, attributed, supported by the correct on-page markup, and allowed by the platform’s moderation state.
    3. Create the submission job immediately. Record the content identifier, public URL, publication time, schema mapping, and payload version so the team can measure delay and reproduce failures.
    4. Authenticate through OAuth 2.0. Keep credentials and token handling within the service responsible for transmission, with access limited to the systems that need it.
    5. Validate before sending. A fast malformed submission is still a failed submission. Block payloads that do not satisfy the accepted contract and route them to a visible error queue.
    6. Record every outcome. Preserve enough information to distinguish validation failures, authentication failures, delivery failures, and records that never entered the queue.
    7. Schedule engagement updates. Send the required counter updates within the 72-hour window instead of treating the initial content submission as the end of the job.
    8. Plan correction controls. Once the developer documentation defines update and deletion behavior, add explicit handling for edited, removed, restricted, or re-moderated content rather than improvising those cases in production.

    Use operational measurements that expose where freshness is being lost. Track publication-to-queue delay, queue-to-delivery delay, validation failure rate, authentication failure rate, the age of the latest engagement update, and the share of eligible records that never produced a job. These measurements do not prove Search inclusion, but they do show whether your side of the pipeline is working.

    Assign alerts to people who can act on them. A dashboard that nobody owns will not protect a minutes-level workflow. The runbook should identify who handles expiring credentials, schema regressions, queue backlogs, counter discrepancies, and moderation-state changes.

    Apply with evidence your platform is ready to operate

    The application should make it easy to verify that your platform fits the program and can support the integration. Assemble a readiness packet before completing the form, even if the form does not request every artifact directly.

    • A concise description of the platform’s UGC model and the people who create the content.
    • Accurate measurements showing UGC publishing volume, public content inventory, and user participation.
    • Representative content URLs that work in a signed-out browser and remain tied to one discussion or post.
    • Representative public creator profiles connected to those content pages.
    • A URL-lifecycle explanation covering edits, moves, removals, and privacy changes.
    • Examples of valid on-page SocialMediaPosting or DiscussionForumPosting markup, where those types fit.
    • A data-flow diagram showing how a publish event can reach the submission queue within minutes and how engagement counters are refreshed within 72 hours.
    • The team responsible for OAuth 2.0, payload validation, monitoring, and incident response.
    • Your moderation process, user-reporting path, and operational ownership for reports.

    Apply when you can support those claims with live examples and named owners. Google provides an application form and indicates a six-to-eight-week wait for a status response. Treat that as a response window, not a promise of acceptance, implementation, or Search visibility.

    Use the waiting period to keep improving normal crawl access, on-page structured data, moderation coverage, and pipeline observability. The specialized feed is independent of traditional organic crawling, and participation does not guarantee inclusion, so pausing ordinary SEO work would create the wrong dependency.

    Key takeaways

    • Apply now if UGC is your platform’s primary content, individual posts have stable public URLs, creators have public profiles, moderation and reporting are active, and your team can meet the technical and freshness requirements.
    • Delay the application if public access, creator attribution, on-page schema, OAuth 2.0 ownership, payload validation, or engagement updates still depend on unplanned work.
    • Assume the program is a poor fit if the platform is not primarily UGC, the meaningful content exists only in feeds or profile pages, or users must log in or pay to view it.
    • Measure delivery, not rankings when evaluating the integration. Acceptance can improve the path by which fresh UGC reaches Google, but it does not guarantee indexing, rankings, Search traffic, or AI visibility.
    • Keep normal SEO running because the dedicated pipeline remains separate from traditional crawling and Search selection.

    Your next move is a concrete audit. Take the 20 newest UGC URLs on your platform and open each one while signed out. Check the stable URL, visible content, public creator profile, schema type, interaction markup, and reporting route. Then trace each publication event through your proposed submission and counter-update workflow. If the same failure appears across the sample, fix the underlying platform rule before applying. If the sample passes, compile the evidence, submit the application, and use the response window to harden the pipeline.

    References


  • A Practical Framework for AI Advertising Campaign Reporting

    A Practical Framework for AI Advertising Campaign Reporting

    Your AI advertising dashboard can be numerically correct and still lead you to the wrong decision. This happens when it collapses four different things into one performance label: what delivered, what the platform optimized for, what it attributed, and what its budget tools are allowed to use.

    You need a reporting system that keeps those layers visible. The framework below will help you turn campaign data into defensible actions without letting an AI-generated summary hide attribution limits, product eligibility problems, or gaps between web and app measurement.

    Key takeaways

    • Show the selected optimization goal beside every supporting conversion. A reported outcome is not necessarily an outcome the campaign pursued.
    • Label each conversion separately as reportable, used for optimization, and eligible for budgeting. Those are three different permissions.
    • Treat attribution as a rule for assigning credit, not proof that an ad caused the outcome.
    • Put product rejections, review pauses, identity changes, and measurement changes on the campaign timeline so operational interruptions are not mistaken for performance failures.
    • Let AI explain a governed dataset. Keep metric definitions, joins, formulas, and eligibility rules deterministic and reviewable.

    Build every report around one decision

    A dashboard built to answer every possible question usually answers none of them clearly. The person deciding whether to scale a campaign needs a different view from the person diagnosing a rejected product or reconciling app purchases. Start with the decision, then select the data required to make it.

    A useful report header should identify:

    • Decision: Scale, hold, reduce, diagnose, or repair.
    • Scope: Account, campaign, ad group, product, channel, market, and customer surface.
    • Primary outcome: The conversion event selected as the optimization goal.
    • Supporting outcomes: Other attributed events that help you judge lead quality, downstream value, or progression through the journey.
    • Comparison: The period, segment, or campaign being used as the reference point.
    • Measurement context: Attribution model, attribution window, currency, time zone, data freshness, and known coverage gaps.
    • Next action: The proposed change, its owner, and the condition that would reverse or confirm it.

    Do not force every conversion into a single blended total. A campaign optimized for one event can now expose other attributed events through the public ChatGPT Ads Insights API. That additional visibility is useful, but it does not change the campaign’s selected goal.

    Keep the primary outcome and supporting outcomes in separate columns. If the optimization goal improves while a downstream purchase metric weakens, you have a quality question to investigate. If purchases improve while the optimization goal is unchanged, you have a useful signal, but not automatic proof that the campaign caused the improvement.

    Separate delivery, eligibility, outcomes, and attribution

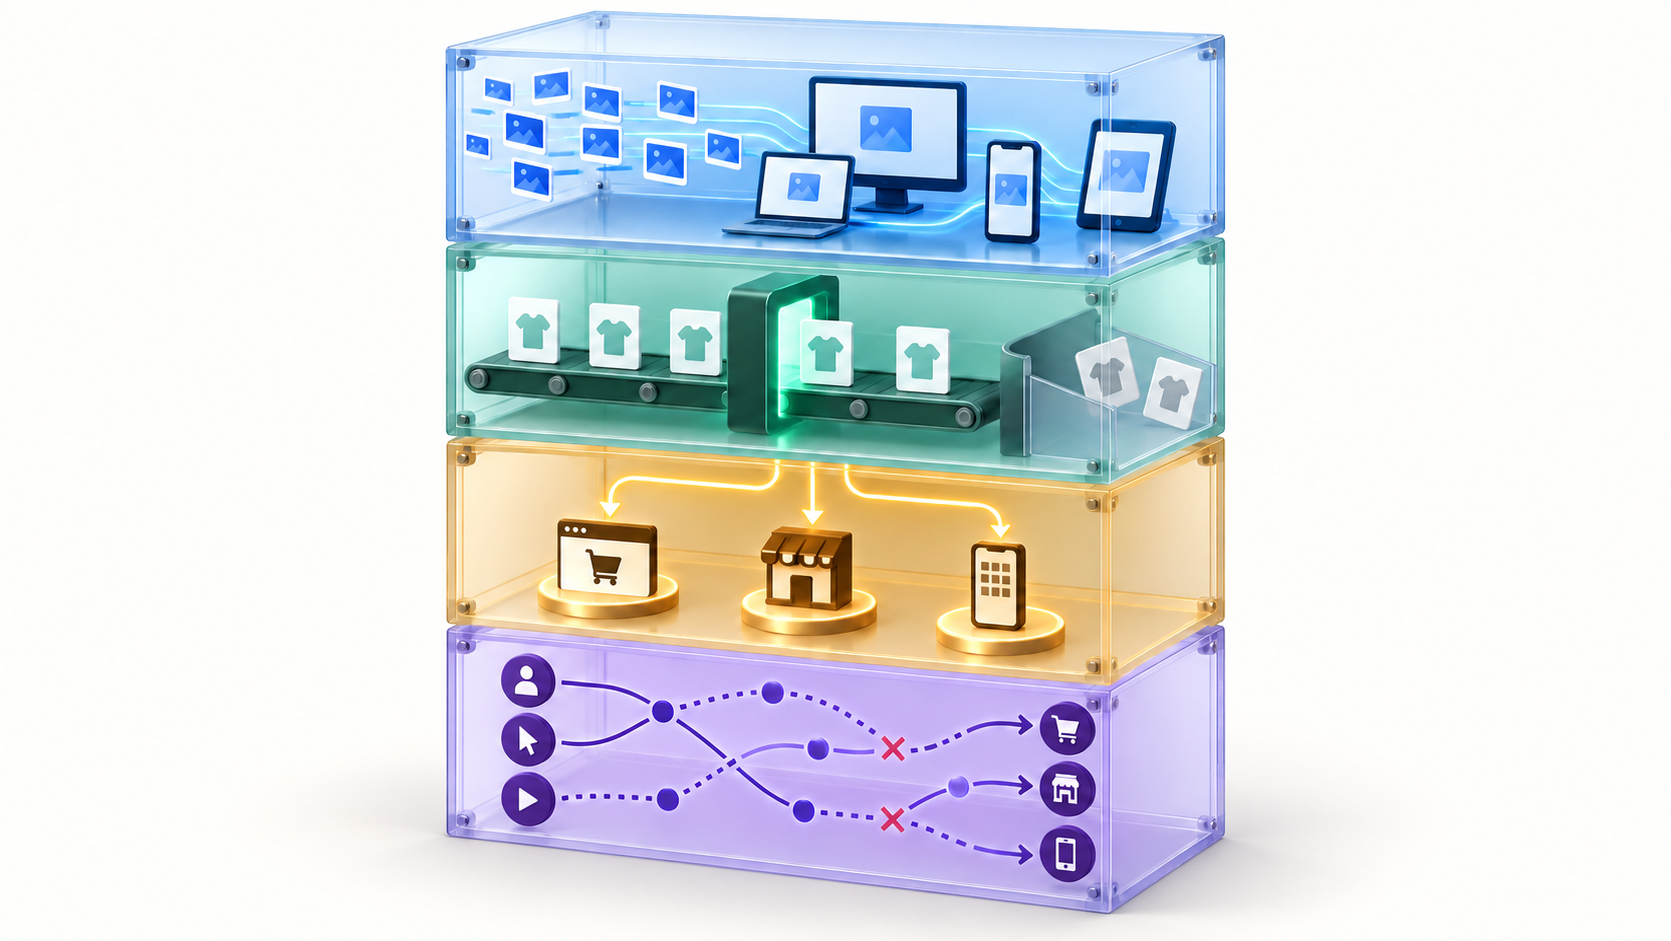
    Four transparent stacked chambers separately depict ad delivery, product eligibility, customer outcomes, and attribution paths.

    A trustworthy report lets you locate the stage at which performance changed. Use distinct reporting layers instead of dropping every metric into one scorecard.

    Reporting layerQuestion it answersWhat to includeDecision it supports
    DeliveryDid the campaign reach and engage its available audience?Platform delivery metrics at the campaign, ad group, and product levelsInvestigate distribution, targeting, serving, or creative exposure
    CostWhat did that delivery consume?Spend and consistently calculated efficiency metricsCheck financial guardrails and locate changes in cost
    Product eligibilityCould each advertised product serve?Feed item, review state, rejection reason, and status-change timeRepair catalog or policy issues before judging demand
    OutcomesWhich conversion events received credit?Optimization goal and supporting attributed events, kept separateEvaluate the chosen objective and inspect downstream quality
    Attribution and governanceUnder which rules and account conditions were results recorded?Model, window, surface, naming changes, review pauses, and measurement changesCompare compatible data and explain discontinuities

    ChatGPT Ads reporting can supply delivery, cost, product, and attributed conversion metrics. Preserve those metric families as separate datasets or clearly identified groups in your reporting model. That makes it possible to tell the difference between a serving problem, a cost problem, a catalog problem, and a conversion problem.

    Product campaigns need an eligibility layer because a rejected item did not receive the same opportunity as an approved item. ChatGPT Ads now exposes product review status and individual rejection reasons. Bring those fields into the report before calculating product-level winners and losers. Otherwise, you may penalize an item for not converting when the actual issue was that it could not serve.

    Operational changes also belong on the timeline. ChatGPT Ads separates the internal account name, public brand name, and registered legal name. A public brand-name change can pause serving during review, while a legal-name change can restart business review and may also interrupt delivery. Record those identity and review events as annotations. A delivery gap during a review is an operational interruption, not evidence that the audience rejected the campaign.

    Treat reporting, optimization, and budgeting as separate controls

    Every conversion in your measurement plan needs three explicit flags:

    • Reportable: Can the event appear in performance or attribution reporting?
    • Optimization-enabled: Is the campaign actively trying to generate this event?
    • Budget-eligible: Can an automated or cross-channel budgeting system use this event when allocating money?

    Never infer the second or third flag from the first. The ChatGPT Ads Insights API can return attributed events beyond the selected optimization goal. Google can include app conversions in performance reporting, attribution analysis, and attribution models while its cross-channel budgeting features remain limited to web conversions. In both cases, visibility is broader than at least one action layer.

    Use supporting conversions without changing the meaning of success

    Supporting conversions can reveal what happens after the event selected for optimization. They are especially useful when the selected event represents an earlier step in the customer journey. Keep them in the report, but preserve their role.

    For each event, store its business definition, customer surface, reporting status, optimization status, budgeting status, and attribution configuration. If one of those fields is unknown, label it unknown. Do not allow the reporting layer or an AI assistant to silently convert an unknown into a yes.

    Keep a visible boundary between web and app measurement

    Google’s expanded conversion reporting can bring app activity into broader performance and attribution views. Advertisers can also configure attribution for app conversions independently from other conversion types. However, availability may still vary by Google Analytics property, and app outcomes are not yet included in cross-channel budgeting.

    This can make a report look unified even when the underlying controls are not. Add a surface field to every conversion row and display web and app subtotals before showing a combined figure. Also record the attribution setting applied to each surface. A combined total is decision-safe only when you can explain what was counted, how credit was assigned, and whether the downstream tool can act on all of it.

    An AI-generated recommendation should never say that a budget allocator will react to app conversions merely because those conversions appear in the same report. It can recommend a manual review of the evidence, but it must preserve the platform’s actual budgeting boundary.

    Build a reporting pipeline that AI can audit

    Transparent data channels pass advertising events through validation and lineage checks before an AI system presents evidence to a human reviewer.

    Automation makes governance more important, not less. Spreadsheet uploads can create multiple ChatGPT product campaigns and ad groups while generating ad templates automatically. Set naming rules and persistent identifiers before a bulk launch so the resulting scale does not produce an untraceable reporting structure.

    1. Create a conversion registry. Give every event a stable identifier, business meaning, customer surface, owner, reportable flag, optimization flag, budget-eligibility flag, and attribution configuration.
    2. Define a campaign taxonomy. Standardize the fields used for market, product group, objective, funnel stage, audience, and experiment. Keep platform IDs even when human-readable names change.
    3. Extract raw data without rewriting its meaning. Preserve native platform fields, IDs, statuses, and timestamps before creating normalized views.
    4. Normalize context explicitly. Apply consistent date boundaries, time zones, currencies, and metric formulas. Retain the raw values so transformations can be audited.
    5. Join operational status data. Add product review states, rejection reasons, account reviews, serving pauses, feed changes, and measurement-setting changes to the campaign timeline.
    6. Reconcile before interpreting. Compare API totals with the platform interface using the same dates, filters, attribution settings, time zone, and account scope. Investigate differences rather than hiding them in a blended total.
    7. Calculate metrics deterministically. Use documented formulas for rates, costs, and rollups. Do not ask a language model to perform the authoritative aggregation from loosely formatted exports.
    8. Generate the narrative last. Give AI the reconciled table, metric definitions, change log, and decision question. Require every recommendation to point back to visible evidence.

    Give the AI a narrow reporting contract

    A useful reporting assistant should distinguish observation from interpretation. Its instructions should require it to use only supplied data, preserve platform definitions, identify missing fields, avoid causal claims from attributed conversions, and state when a proposed action depends on an unverified setting.

    Require each generated finding to contain:

    • Observation: The measured change, including its scope and comparison.
    • Evidence: The exact metrics, dimensions, statuses, and time period supporting the observation.
    • Interpretation: A plausible explanation clearly labeled as an inference.
    • Measurement limits: Attribution, availability, eligibility, or data-quality constraints that could change the reading.
    • Action: A reversible next step tied to the original decision.
    • Validation condition: What must be checked before the recommendation is implemented or expanded.

    This structure prevents polished prose from outrunning the evidence. Attribution tells you how a model assigned credit; it does not establish causal lift. When causality matters, the report should identify the need for an appropriate experiment rather than dressing an attribution result up as proof.

    Run these checks before automating recommendations

    • API and interface totals reconcile under identical filters and settings.
    • Every conversion has separate reporting, optimization, and budgeting flags.
    • Web and app events retain their surface and attribution configuration.
    • Rejected, pending, and approved products are distinguishable.
    • Serving pauses and account, brand, feed, goal, or attribution changes are annotated.
    • Missing and unavailable values remain distinct from zero.
    • Every generated recommendation cites the rows and definitions it relies on.
    • A person with budget authority reviews consequential changes before they are applied.

    Start with one active campaign and complete the conversion registry before rebuilding the dashboard. Put the business meaning, surface, reporting status, optimization status, budget eligibility, and attribution setup beside every outcome. If you cannot complete those fields, the campaign is not ready for automated interpretation. Fix that boundary first; the reporting interface can follow.

    References

  • Paid Search APIs: A Control Plan for PMax and Targeting

    Paid Search APIs: A Control Plan for PMax and Targeting

    Your paid search stack has more levers, but a longer settings list is not a control strategy. Your immediate job is to decide which signals belong in reporting, which controls enforce real business constraints, and which customer data should never enter an upload pipeline without an eligibility check.

    Handled carefully, the Microsoft Advertising and Google Ads APIs can help you trace intent to destinations, constrain Performance Max where the economics demand it, strengthen audience inputs, and identify bidding settings that limit auction access. The useful unit is not the endpoint. It is a closed loop: observe, diagnose, authorize, change, and verify.

    Build a control plane before you automate campaign changes

    A paid search integration should separate evidence from action. Reports, benchmarks, and recommendations tell you what may deserve attention. They do not automatically tell you which change is safe, profitable, or permitted.

    Organize the integration into four stages:

    1. Observe: retrieve delivery evidence, performance metrics, recommendations, and the current effective settings.
    2. Diagnose: classify the issue as a message mismatch, destination mismatch, targeting problem, measurement defect, auction-access constraint, or genuine business restriction.
    3. Authorize: apply an approval rule that matches the risk. A validated tracking-parameter correction is not the same decision as excluding an entire device category or changing a bidding target.
    4. Execute and verify: write the smallest eligible change, retrieve the effective setting again, and record whether the platform accepted it.

    Keep read jobs and campaign-mutation jobs separate where your architecture permits it. At minimum, every write operation should support a dry run that shows the current value, proposed value, object scope, and affected IDs before money-moving settings change.

    Your change record should capture the platform, account, campaign or asset-group ID, scope, previous value, proposed value, reason, requester, approval status, execution result, and retrieval time. Add de-duplication in your own worker so a retry cannot apply the same logical operation twice. That record becomes essential when an automated campaign behaves differently and you need to distinguish a platform decision from a change your system made.

    Turn search-term-to-page evidence into a repair queue

    An analyst traces glowing search-signal streams to model landing pages and sorts mismatches into repair trays.

    Microsoft Advertising’s Search Term Landing Page Report connects a search term, the delivered headline, the final URL, and performance metrics in the same reporting view. That closes an important diagnostic gap: you can inspect the promise a person saw and the destination that had to fulfill it.

    Do not reduce this to a list of expensive search terms. Build a mismatch workflow that preserves the full path:

    1. Store the raw evidence. Retain the search term, delivered headline, final URL, campaign identifiers, and associated metrics. Do not substitute the headline you expected to serve for the headline that was actually delivered.
    2. Create a normalized destination key. Keep the raw URL for auditing, then create a second field that removes only parameters you have confirmed do not alter page content. A parameter that controls localization, product selection, or page state is not disposable tracking noise.
    3. Score three separate relationships. Evaluate search term to headline, headline to landing page, and search term to landing page. A relevant headline can hide a poor destination, while an acceptable page can still be introduced by the wrong promise.
    4. Join relevance to outcomes. A semantic mismatch deserves inspection, but performance data determines its operational priority. A high-volume routing defect and an isolated ambiguous query should not enter the same queue with the same urgency.
    5. Assign the repair to the correct layer. Change the eligible ad messaging when the promise is wrong, adjust routing when the destination is wrong, and revise the page when it fails to answer the intent it legitimately targets.

    Suppose a term clearly asks about pricing, the delivered headline promises pricing information, and the click reaches a generic homepage that never addresses price. The weak link is the destination. Rewriting the headline may reduce the visible contradiction, but it does not satisfy the underlying intent. Your queue should make that distinction explicit.

    SEO, AEO, and GEO teams can use the same queue to prioritize clearer on-page answers. Paid query evidence can show that demand exists and reveal the language people use, but it does not prove that a page will rank organically or be cited by an AI system. Improve the visible answer first, then describe that content accurately with metadata and structured data. Schema cannot repair information the page does not contain.

    Model PMax controls by platform, object, and scope

    Performance Max is not one uniform control surface. Microsoft is adding campaign-level device exclusions, while Google Ads API v25.2 exposes URL configuration at the asset-group level and a draft-based migration path from Smart campaigns. Treating all three capabilities as a generic PMax setting will create faulty assumptions in your interface and automation.

    CapabilityScopeWhat the API permitsHow to use it safely
    Microsoft Advertising device exclusionsCampaignExclude Computers, Smartphones, or Tablets from a PMax campaignUse only after confirming that the device itself creates a durable business constraint, rather than masking a page, tracking, consent, or attribution defect
    Google Ads PMax URL configurationAsset groupConfigure tracking templates, custom URL parameters, and final URL suffixesKeep routing and measurement rules aligned with the asset group, and test the resolved URL before activation
    Google Smart-to-PMax generationCampaign draft workflowGenerate a PMax draft from an existing Smart campaignTreat the generated object as a reviewable draft, not as authorization to launch it

    Your internal model should include at least platform, control type, scope type, scope ID, requested value, effective value, and business rationale. The interface should state plainly whether a control applies to a campaign, an asset group, or a migration draft. Scope must not be inferred from a label such as PMax control.

    Device exclusion is the highest-consequence control in this set because it removes eligible reach. Before excluding a device, verify that the apparent weakness is not caused by a slow or unusable landing experience, broken conversion tracking, a consent-flow difference, or cross-device attribution. If the problem can be repaired, fix it. If the device violates a stable operating rule, document that rule and exclude it at the campaign scope the Microsoft API actually supports.

    Google’s asset-group URL controls solve a different problem. They let you attach tracking and URL information closer to the asset grouping that uses it. Validate the fully resolved destination, preserve parameters that affect content, and test that your analytics system receives the expected values. A syntactically accepted suffix can still produce a bad measurement or routing result when combined with the base URL.

    A generated PMax draft also needs a deliberate comparison with the campaign it is replacing. Review destinations and tracking, conversion goals, geography, bidding and budget assumptions, creative assets, audience inputs, and exclusions before approval. Draft generation reduces construction work; it does not transfer accountability to the API.

    Google Ads API v25.2 is a minor release without breaking changes, but integrations still need updated client libraries and code to use its additions. It is scheduled to remain supported until August 2027, so record the API version behind every capability flag and plan the next upgrade before support ends.

    Separate audience usefulness from permission to use the data

    Abstract customer-data tokens pass through separate usefulness and permission gates before entering a campaign system.

    Microsoft’s API support for LinkedIn segment targeting can add professional audience information to programmatic campaign management. That can be useful for B2B offers, but a segment name is still a targeting hypothesis, not proof of buying intent.

    For every segment, record the business question it represents, the campaign where it is eligible, and the result you expect it to influence. Your integration should also expose how the platform treats that audience object in the selected campaign context: as a reach restriction, observation layer, or automation input. Do not let a generic audience toggle hide that distinction.

    Google Customer Match introduces a more consequential data-governance decision. Advertisers can add an IP address and interaction timestamp to customer data, but both values must be uploaded unhashed. These identifiers are not available for end users in the European Economic Area, United Kingdom, or Switzerland, so geographic eligibility has to be enforced before the export reaches Google.

    Build that upload pipeline to fail closed:

    1. Check eligibility at the record level. If your collection system cannot reliably establish that the user is outside the restricted regions, omit the IP-address field for that record.
    2. Verify notice and consent before enabling the fields. The expanded matching options require appropriate collection disclosures and consent controls. Have the privacy or legal owner responsible for your markets approve the rule before activation.
    3. Use the required file format. Customer Match files can contain eight columns, and Google requires specific English-language headers, including User IP address and User Interaction timestamp. Hashing these two fields anyway does not satisfy the specified upload format.
    4. Limit exposure. Restrict access to the unhashed export, prevent raw values from appearing in debug logs, and remove temporary files according to your approved retention policy.
    5. Log decisions rather than identifiers. Record the policy version, eligible and excluded row counts, upload result, and failure reason without copying IP addresses into the operational audit trail.

    This is one place where a larger matchable audience is not automatically a better outcome. If the regional gate, collection record, or disclosure is uncertain, omit the new identifiers and use an already approved matching path. The downside of a smaller audience is preferable to transferring data you were not authorized to use.

    Use benchmarks and bidding recommendations as questions, not commands

    Google Ads API v25.2 can return competitive benchmark percentile tiers through BenchmarksService, including comparison with all advertisers and optional category filters. A percentile supplies market context. It is not a profitability target.

    Store the comparator and category filter beside the percentile. Without them, a dashboard preserves the number but loses the population that gives it meaning. Also keep the advertiser’s own absolute outcome nearby. A relative position cannot tell you whether a campaign meets its allowable acquisition cost, margin requirement, lead-quality standard, or revenue target.

    The same discipline applies to Google’s recommendations that flag Target CPA or Target ROAS settings that may be too restrictive for a campaign to enter auctions. The recommendation diagnoses possible auction-access friction. It does not establish that loosening the target will produce economically acceptable conversions.

    Before acting on that recommendation, verify the conversion definition and tracking, calculate the CPA or ROAS boundary your economics can support, decide whether the actual problem is limited auction access or weak post-click performance, and define the acceptable change before editing the target. Store whether the recommendation was accepted, modified, or declined and why. Do not make this recommendation self-executing merely because the API makes it available.

    Key takeaways

    • Separate API observation from mutation, and preserve a before-and-after record for every campaign write.
    • Evaluate search term, delivered headline, and final landing page as three connected relationships, not as independent report columns.
    • Represent PMax controls at their real scope: Microsoft device exclusions are campaign-level, while Google’s new URL controls are asset-group-level.
    • Generate a PMax draft to reduce setup work, then review it with the same standards as a manually assembled campaign.
    • Block restricted or uncertain Customer Match records before export; IP addresses and timestamps require an unhashed, region-aware pipeline.
    • Use benchmark percentiles and bidding recommendations to frame an investigation, not to replace your own economic constraints.

    For your next integration release, keep the scope small and verifiable: add one reporting path that exposes query-to-page mismatches, one write guardrail that respects the platform’s actual control scope, and one hard eligibility gate around customer-data uploads. Expand automation only after those three paths produce auditable results.

    References


  • Commercial AI Token Costs: Budgeting Beyond List Price

    Commercial AI Token Costs: Budgeting Beyond List Price

    Your spreadsheet says one model is cheaper. Your invoice says otherwise. The gap appears because the spreadsheet priced the prompt and final answer, while production also paid for reasoning, repeated instructions, failed tool calls, retries, discarded drafts, and cache behavior.

    If you are choosing a commercial AI model or defending an AI budget, compare cost per accepted outcome, not cost per million tokens. That change turns a rate card into a forecast you can actually use.

    A token price is only one layer of your production cost

    Published input and output prices tell you the rate applied to certain tokens. They do not tell you how many tokens the model will consume before your application gets an acceptable result. A useful cost model therefore has three layers:

    • Unit rates: the applicable prices for input, output, reasoning, cache reads, cache writes, and any long-context tier.
    • Consumption: the number of tokens used by the prompt, retrieved context, system instructions, tool definitions, intermediate reasoning, and response.
    • Completion efficiency: how many attempts, revisions, and tool calls you pay for before the result passes your acceptance checks.

    The third layer causes many budget misses. A cheap attempt is not a cheap task if the attempt is rejected and repeated. Nor is a successful API response necessarily a completed business task. A coding agent that returns malformed code, a content model that produces an unusable draft, or a schema generator that fails validation has consumed tokens without delivering the outcome you intended to buy.

    In measured 2026 production usage, the categories commonly omitted from simple estimates represented 52.5% of billed tokens and added 70.4% above a list-price-only estimate. These percentages are not universal overhead rates. They are a practical checklist of what your own logging needs to capture.

    Cost commonly missedShare of billed tokensAdded cost versus list-price estimateWhat to inspect
    Invisible reasoning tokens22.4%38.6%Whether reasoning usage is returned separately from visible output
    Re-sent system prompts and tool schemas11.9%9.4%How much fixed context is transmitted on every model call
    Retried and discarded generations7.8%8.1%Every failed, rejected, or superseded attempt
    Long-context pricing above 200K tokens3.1%6.2%Requests crossing a provider’s long-context pricing boundary
    Failed tool calls and malformed structured output4.6%5.3%Calls that return successfully but fail downstream validation
    Unrecovered cache-write premium2.7%2.8%Cache entries written without enough subsequent reuse

    Do not solve this by applying one generic markup to every vendor quote. Instrument each category instead. A reasoning-heavy model, a tool-using agent, and a short classification call can have radically different overhead even when their visible prompts look similar.

    Falling rate-card prices do not remove this problem. Within a constant-capability mid-tier series from Q1 2023 through Q3 2026, the list-price index fell 91.4%, but real cost per completed task fell only 62.9%. Token consumption per completed task rose 4.3 times. The completed-task cost reached its low point in Q4 2024 and then increased 80% by Q3 2026 even as published rates generally continued downward. More capable reasoning behavior can consume part of the saving advertised on the price sheet.

    Compare models by accepted task, not by token rate

    Three abstract AI processing stations turn identical inputs into rejected fragments and one finished object that fits a quality-check fixture.

    A model comparison becomes useful only after the denominator represents something your business accepts. From May 4 through August 21, 2026, a standardized set of 14 production tasks was run across 11 commercial models. The resulting cost included billed reasoning, prompt repetition, cache activity, retries, and discarded output. The September 2026 prices and measured completed-task costs show why rate-card ranking and production ranking can diverge.

    ModelInput per 1M tokensOutput per 1M tokensMeasured cost per completed task
    GPT-5.4 nano$0.20$1.25$0.0219
    Gemini 3.1 Flash-Lite$0.25$1.50$0.0288
    Claude Haiku 4.5$1.00$5.00$0.0474
    GPT-5.6 Luna$1.00$6.00$0.0607
    GPT-5.4 mini$0.75$4.50$0.0627
    Claude Sonnet 5$2.00$10.00$0.0848
    Gemini 3.6 Flash$1.50$7.50$0.1040
    GPT-5.6 Terra$2.50$15.00$0.1662
    Gemini 3.1 Pro$2.00$12.00$0.1683
    Claude Opus 5$5.00$25.00$0.2131
    GPT-5.6 Sol$5.00$30.00$0.3447

    Several reversals matter when you shortlist a model. GPT-5.4 mini had lower published input and output prices than Claude Haiku 4.5, yet its measured task cost was $0.0627 versus $0.0474. Claude Sonnet 5 had higher published rates than Gemini 3.6 Flash but completed the task set for $0.0848 instead of $0.1040. At the frontier end, GPT-5.6 Sol and Claude Opus 5 shared the same $5.00 input price, but Sol cost 62% more per completed task, with the difference driven almost entirely by output volume.

    These results do not make one model universally cheaper. Your prompts, tools, input-to-output ratio, quality threshold, and retry policy may reverse the ranking again. Use published comparisons to choose candidates, then reproduce the comparison on your own workflow.

    1. Define completion before testing. For JSON-LD, completion might require parsable output that passes your validation checks. For a content brief, it might require every mandatory field and entity. An HTTP success code is not an acceptance criterion.
    2. Freeze a representative task set. Give every candidate the same source material, system instructions, tools, output requirements, and acceptance tests.
    3. Record every billable attempt. Keep rejected generations, malformed output, repair prompts, tool-call failures, and fallback calls in the numerator.
    4. Separate visible output from total usage. Store every usage field the provider exposes, including reasoning and cache categories where available.
    5. Compare only models that meet the quality gate. A low-cost result that cannot be used is a failed attempt, not a bargain.
    6. Divide total model spend by accepted completions. That figure is your effective task cost and the basis for a credible monthly forecast.

    Content costs multiply after the first draft

    Content teams often estimate AI spend from the tokens in one draft. That calculation stops before the expensive part: revisions, replacement drafts, citation repair, structural fixes, and output that never reaches publication.

    For 1,000 words of finished, publishable copy, the measured token cost included revision rounds and discarded generations. The difference between first-draft and finished cost was substantial across every tested model.

    ModelFirst-draft costAverage revision roundsDiscarded draftsFinished cost per 1,000 wordsFinished versus first draft
    GPT-5.6 Sol$0.0861.614%$0.2072.4x
    Claude Opus 5$0.0791.29%$0.1642.1x
    GPT-5.6 Terra$0.0431.817%$0.1142.7x
    Gemini 3.1 Pro$0.0361.919%$0.1012.8x
    Gemini 3.6 Flash$0.0242.426%$0.0843.5x
    Claude Sonnet 5$0.0321.513%$0.0742.3x
    GPT-5.6 Luna$0.0172.324%$0.0583.4x
    GPT-5.4 mini$0.0132.931%$0.0544.2x
    Claude Haiku 4.5$0.0162.122%$0.0513.2x
    Gemini 3.1 Flash-Lite$0.00414.145%$0.0245.9x
    GPT-5.4 nano$0.00344.448%$0.0216.2x

    The cheapest and most expensive first drafts were separated by roughly 25 to 1. After revisions and discards, finished costs were separated by about 10 to 1. Draft rejection narrowed the apparent advantage of the cheapest models.

    Discard rate was also more useful than list price for anticipating finished cost. Claude Sonnet 5 started at $0.032 per 1,000 words, above Gemini 3.6 Flash at $0.024. Sonnet finished lower, at $0.074 versus $0.084, because its discarded-draft rate was 13% rather than 26%.

    Build that distinction into your content operations. Give every generated asset a final status such as accepted, revised, or discarded, and associate all attempts with the same job identifier. Then calculate finished token cost from all spend attached to accepted copy, divided by accepted word count and multiplied by 1,000. Counting only the last successful generation erases the waste you are trying to manage.

    Keep the quality gate explicit. For an SEO or GEO workflow, your requirements may cover factual accuracy, source support, search intent, entity coverage, structure, brand constraints, and valid structured output. The exact rubric is yours, but it must be stable across models. Otherwise, a permissive review process can make a weak model look artificially inexpensive.

    The figures above cover model-token spend. They do not represent a fully loaded content cost. Your internal budget should add editorial review, fact-checking, workflow infrastructure, monitoring, and any human repair work rather than treating a low token figure as the total cost of publication.

    Budget by workload, then route each job to the right tier

    Different task objects move through a central routing hub toward small, medium, and large processing machines, with one path passing through a cache chamber.

    A single company-wide average hides the workflows most likely to break your budget. Agentic coding, customer support, retrieval-based research, document processing, sales personalization, and content production have different volumes, context sizes, output patterns, and failure modes.

    For a modeled 50-person company, the same mix of 157,400 monthly tasks cost $6,610 at the economy tier, $19,150 at the mid tier, and $48,670 at the frontier tier. That is a 7.4-times spread before changing the workload itself.

    WorkloadMonthly tasksFrontier tierMid tierEconomy tier
    Coding agent, 20-developer team14,800$18,350$7,140$2,510
    Customer support automation62,000$9,610$3,720$1,240
    Internal RAG research tool21,500$7,290$2,940$1,020
    Document and contract processing9,700$6,410$2,580$890
    Sales outreach personalization46,000$4,830$1,910$640
    Content marketing, 8-person team3,400$2,180$860$310
    All workloads157,400$48,670$19,150$6,610

    Volume alone does not reveal the expensive workflow. The coding agent ranked fourth by task count but was the largest monthly cost. At the frontier tier, it cost $1.24 per completed task, compared with $0.16 for customer support. Agentic workflows repeatedly call models, tools, and validation steps, so a task can contain much more billable activity than one support interaction.

    Build your forecast from accepted workload volume

    Your budget sheet should have one row per distinct workflow, not one row per provider. Separate content briefs from finished drafts, retrieval answers from document ingestion, and schema generation from schema repair. They may use the same API while having different cost behavior.

    • Workload identity: team, application, task type, model, and model version.
    • Demand: expected completed tasks, not merely API requests.
    • Usage: input, output, reasoning, cache-read, and cache-write tokens where exposed.
    • Workflow overhead: attempts, tool calls, validation failures, fallback calls, and discarded results.
    • Outcome: accepted, repaired, rejected, or abandoned.
    • Unit economics: total billed spend divided by accepted completions.

    Forecast monthly model spend by multiplying expected accepted-task volume by your measured cost per accepted task. Keep the rate-card calculation beside it as a reconciliation check, not as the primary forecast. A widening gap between the two tells you to investigate prompt growth, longer retrieved context, increased reasoning, lower cache reuse, tool failures, or a rising retry rate.

    Recalculate after changes to the model version, system prompt, tool schema, context strategy, output format, or acceptance threshold. Each can alter consumption or completion efficiency even when the published token rate stays fixed.

    Use routing instead of choosing one model for everything

    Model tier should be a workload decision. Economy models are strongest candidates when the task is constrained, output can be checked automatically, and failure is cheap to retry. Mid-tier models suit broader production work where reliability and cost both matter. Frontier models deserve the jobs whose ambiguity or quality requirement produces a measurable improvement worth their higher completed-task cost.

    That does not require moving every workflow downmarket. In the modeled company, moving only the two highest-volume workloads – customer support and sales personalization – to economy models while leaving the other four at the frontier tier reduced total monthly spend by 26%. Selective routing captured savings without imposing one capability tier on every task.

    Put a quality gate after the lower-cost route and send only failed or uncertain cases to a stronger model. Count both calls when escalation occurs. Otherwise, the first model appears cheaper in your dashboard while the fallback cost disappears into another service or team.

    Key takeaways

    • Published cost per million tokens is a unit rate. Your actionable metric is total billed spend per accepted task.
    • Log reasoning, repeated system context, cache activity, retries, discarded output, tool failures, and long-context pricing instead of hiding them in a generic contingency.
    • For content, calculate cost per 1,000 accepted words from every draft and revision associated with the finished asset.
    • Benchmark candidates on the same tasks and acceptance criteria. Compare costs only among models that clear the required quality threshold.
    • Route by workload. High-volume, tightly validated tasks may justify an economy model, while ambiguous or high-impact work may justify a more capable tier.
    • Refresh the forecast whenever the model, prompt, tools, context, output contract, or quality gate changes.

    Start with one workflow that already generates meaningful volume. Attach every billable attempt to an accepted or rejected outcome, calculate its effective cost, and use that result to challenge the rate-card estimate. Once the accounting works for one workflow, extend the same measurement to the rest of your AI stack and route each task on evidence rather than model reputation.

    References


  • YouTube Ad Creative and DV360 Changes to Make by October

    YouTube Ad Creative and DV360 Changes to Make by October

    Your YouTube campaign can have a sound bid strategy and still underperform because the ad was built for another surface. At the same time, a promising creative refresh can stall before delivery if the Display & Video 360 integration behind it is not ready for October’s unversioned platform changes.

    Treat this as one operating problem with two workstreams. Improve the message people see and hear, then verify that your API and Structured Data File workflows can still create, update and protect the campaign. Here is the sequence we would use.

    Key takeaways

    • For Demand Gen in-stream skippable ads in the United States, July 2026 data associated human voice with 12% higher conversions on average, text overlays with 3% higher conversions and visible branding in the first five seconds with 4% higher conversions. These are test priorities, not guaranteed lifts.
    • Build image ads for the YouTube feed: use high-resolution, full-bleed imagery, include people when appropriate and remove black bars, excessive empty space and oversized logos.
    • Do not bake fake buttons or arrows into an image. They compete with YouTube’s functional call to action and can leave the viewer unsure about what is actually clickable.
    • On Oct. 1, DV360 API and Line Item Structured Data File workflows lose specified digital-content-label exclusions and most sensitive-category exclusion options.
    • On Oct. 12, YouTube responsive ad creation and updates require a business name and logo when those defaults are not already assigned to the parent advertiser.

    Start with voice, early branding and useful on-screen text

    A presenter speaks into a microphone while being recorded on a smartphone, surrounded by an abstract audio waveform and blank graphic overlays.

    Creative is not the decorative layer that you address after bidding and targeting. Nielsen attributed 49% of campaign ROI to creative, while Ekimetrics found that improving creative could more than double YouTube ROI. Those aggregate findings do not forecast what your account will gain, but they do justify giving creative testing the same operational attention as media settings.

    The most actionable benchmarks are narrower. They apply to Demand Gen in-stream skippable ads, use U.S. data from July 2026 and describe associations rather than proof that an isolated element caused the result. That scope matters when you decide what to test and how confidently to interpret it.

    Creative elementObserved conversion associationFirst controlled test
    Human voice12% higher on averageCompare a voiced cut with a closely matched cut that has no human voice.
    Supers or text overlay3% higher on averageAdd concise on-screen wording to the same core edit and keep the offer and call to action unchanged.
    Brand visible in the first five seconds4% higher on averageCompare immediate visual brand identification with a later brand reveal.

    Do not add those percentages together and turn the result into a forecast. The elements can interact, and campaigns that use them may differ in other important ways. Use the figures to determine test order: if you have enough traffic for only one new comparison, human voice is the most defensible place to start because it had the largest reported association.

    Give the voice a real job. It can state the viewer’s problem, establish the offer or make the next action clear. A voice that merely reads every word on screen adds sound without improving the message. Keep supers equally disciplined: reinforce the key point rather than turning the frame into a transcript.

    Early branding also needs restraint. The goal is to make the advertiser identifiable within five seconds, not to cover the opening with a logo that delays the reason to keep watching. Put the brand into the story while the viewer is still deciding whether to skip.

    For a useful test, hold the audience, offer, bid strategy, call to action and landing page as steady as your campaign setup permits. Change one creative factor at a time. If your conversion volume cannot support several cells at once, run the comparisons sequentially instead of launching a test that never produces a clear decision.

    Judge the result against the conversion action that matters to the campaign. A click-through improvement is not automatically a conversion improvement. Also, do not assume that benchmarks from U.S. Demand Gen in-stream skippable inventory transfer unchanged to Shorts, other formats or other markets. Those are separate questions for your account to answer.

    Make image assets belong in the YouTube feed

    An image can be polished in a design file and still look broken when placed in a YouTube feed. The common failure is not low production value. It is a layout that carries the visual habits of a banner, presentation slide or another ad platform into a surface where people expect immersive imagery.

    For YouTube image ads, visible people and people interacting with products tend to outperform assets without human presence in Google’s platform observations. Human presence should still make sense for the product and message; inserting an unrelated face is not a substitute for a coherent concept.

    • Fill the available frame. Start with high-resolution, full-bleed photography or lifestyle imagery rather than an image floating inside a large solid canvas.
    • Show use, not just inventory. When appropriate, let a person hold, wear, operate or otherwise interact with the product so the viewer can understand its role quickly.
    • Keep the logo proportional. The brand should be identifiable without making an oversized logo the main visual event.
    • Remove structural clutter. Black bars and large empty solid areas can make the asset feel fragmented or incorrectly formatted.
    • Delete fake interface elements. A button, play control or arrow drawn into the image is not functional. Let YouTube’s actual call-to-action control handle the interaction.

    Fake controls create two competing instruction systems. The platform presents a real action, while the picture implies another one that does nothing. That forces the viewer to determine which visual element is interactive instead of understanding the offer. If an arrow is necessary to make the call to action discoverable, the composition or message probably needs another pass.

    Review the rendered asset in its intended placement, not only at full size on a designer’s canvas. Ask whether it reads as one complete image, whether the important person or product survives the crop, whether the brand remains recognizable and whether there is exactly one obvious functional path forward. This preview is also where black bars, oversized marks and deceptive button shapes become easiest to catch.

    Native fit does not mean disguising an advertisement. It means using the visual language of the surface while keeping the advertiser and offer clear. A feed-compatible image earns attention through relevance and composition, not through an imitation of YouTube’s controls.

    Prepare DV360 automation for the October deadlines

    An abstract automation pipeline moves file cards through validation gates, version branches and safeguards beside a blank calendar.

    A better asset cannot improve results if the integration that manages it stops working. The October rollout contains three unversioned changes across the Display & Video 360 API and Structured Data Files. Do not assume an older client or a delayed API-version migration will preserve the previous behavior.

    Oct. 1: specified exclusion controls are removed

    Starting Oct. 1, advertisers will no longer be able to use API targeting to exclude specific digital content labels. The change affects available TARGETING_TYPE_DIGITAL_CONTENT_LABEL_EXCLUSION options and valid values in the Digital Content Labels - Exclude column of Line Item Structured Data Files.

    Most sensitive-category exclusions are also being removed from targeting on that date. Audit any workflow that uses TARGETING_TYPE_SENSITIVE_CATEGORY_EXCLUSION, as well as the Brand Safety Sensitivity Setting and Brand Safety Custom Settings columns in Line Item Structured Data Files.

    This is a change to available controls, not a reason to quietly weaken your brand-safety policy. Do not simply delete fields until an error disappears. First identify which business rule each field was implementing, who owns that rule and what the approved workflow should be once that targeting option is unavailable.

    Do not guess how every existing line item will display or behave after the change. Inventory the affected line items and validate the actual transition in a controlled workflow. The important distinction is between authoring a new setting, updating an existing line item and observing a previously configured value; each path deserves an explicit check.

    Oct. 12: responsive ads need business identity assets

    Starting Oct. 12, developers creating or updating YouTube responsive ads must provide a business name and logo when default values are not already assigned to the parent advertiser. The requirement also applies to ads uploaded through Ad Structured Data Files.

    That parent-advertiser condition gives you a clean preflight decision. If approved defaults exist, verify that every relevant workflow can use them. If they do not, make the business name and logo required inputs before an ad reaches the create, update or upload step. Do not wait for a production job to discover that the identity assets are missing.

    Your technical audit should cover these exact paths:

    1. Search code, configuration files and Line Item Structured Data File templates for TARGETING_TYPE_DIGITAL_CONTENT_LABEL_EXCLUSION, TARGETING_TYPE_SENSITIVE_CATEGORY_EXCLUSION and the affected column names.
    2. List every scheduled job, internal tool and third-party workflow that creates or updates YouTube responsive ads through the API.
    3. List every process that uploads Line Item or Ad Structured Data Files. Treat the two file types separately because the exclusion and identity changes affect different operations.
    4. Inspect each parent advertiser used by those workflows and record whether an approved default business name and logo are already assigned.
    5. Add a preflight check that blocks responsive-ad submission when neither advertiser defaults nor required identity inputs are available.
    6. Have the brand-safety owner approve any operational change caused by the lost exclusion options, then test create, update and file-upload paths before their respective deadlines.

    Record which test covers which deadline. A successful responsive-ad creation test does not prove that an exclusion workflow is ready, and a clean Line Item Structured Data File does not prove that an Ad Structured Data File contains the required identity. Separating those assertions will make a failure much easier to locate.

    Run one joined creative-and-delivery sprint

    Creative production and delivery engineering often sit in different queues, but the campaign depends on both. A new ad trapped behind a failed update request creates no learning. A perfectly updated integration serving weak recycled assets only automates the wrong input.

    Use this order to turn the work into a test you can trust:

    1. Clear the deadline risk. Open technical tickets for the Oct. 1 exclusion changes and the Oct. 12 identity requirement. Assign owners before asking the creative team to produce a large new batch.
    2. Freeze a useful control. Preserve the current offer, landing page, audience and conversion action so the next result can be interpreted as a creative comparison.
    3. Create focused video variants. Build a human-voice version, an early-brand version and a concise-text-overlay version. Keep the underlying proposition as consistent as possible.
    4. Rebuild image assets for the feed. Use full-bleed imagery, meaningful human presence and one clear composition. Remove fake buttons, arrows, black bars and excess empty space.
    5. Validate delivery before launch. Exercise the API create and update paths, the relevant Structured Data File uploads and the business-identity fallback. Do not mix a delivery defect into a creative performance test.
    6. Label the change in reporting. Use variant names that identify the factor being tested. When conversions move, you should be able to connect the result to voice, branding, text or image treatment without reopening the design files.

    If capacity is tight, prioritize the integration work first because its dates are fixed. Then test human voice, which had the largest reported conversion association, followed by early branding and text overlays. Feed-image cleanup can run alongside those video edits because it addresses a different asset type.

    Open your highest-spend YouTube ad and its parent advertiser record side by side. Check whether the ad uses a human voice, identifies the brand within five seconds and gives on-screen text a clear purpose. Then confirm the advertiser’s default business name and logo and search your automation for the affected exclusion identifiers. You will leave that session with one defined creative experiment and one concrete technical readiness list, both in time for October.

    References


  • Google Ads AI Transparency: A Practical Audit Framework

    Google Ads AI Transparency: A Practical Audit Framework

    When Google Ads can rewrite the product title a shopper sees, knowing what you entered in Merchant Center is no longer enough. And when an AI coding assistant can generate integrations, troubleshoot failures, and query a live advertising account, working code is no longer sufficient proof that the work is correct.

    You need an evidence chain: what the AI changed, what rules or schema supported the change, what actually ran or served, and what happened afterward. Two Google Ads developments make that easier: reporting for AI-generated Shopping titles and a schema-aware Google Ads API assistant. Used carefully, they let you audit automation without giving up its speed.

    Treat Google Ads AI as two separate control problems

    Google Ads AI acts at more than one point in the advertising workflow. The control you need depends on where the automation operates.

    AI layerWhat can changeEvidence availableYour control decision
    Ad deliveryThe product title presented in a Shopping adOriginal and customized titles plus impressions, product clicks, CTR, cost, and average CPCDetermine whether the generated wording preserves product identity and attracts useful traffic
    API developmentIntegration code, GAQL queries, diagnostics, and reporting workflowsGoogle Ads-specific rules, GAQL validation, Protobuf schema inspection, and live query resultsDetermine whether the implementation is valid for the intended API version, account, and business question

    The first layer is a message-governance problem. The second is a software-governance problem. Combining them under a vague instruction to “monitor the AI” produces weak reviews because the artifacts, risks, and owners are different.

    Use the same principle for both: never approve an AI output without identifying the input, the transformation, and the observed result. A generated title is an output. So is a valid GAQL query. Neither tells you by itself whether the outcome serves your commercial intent.

    Audit the product title shoppers actually see

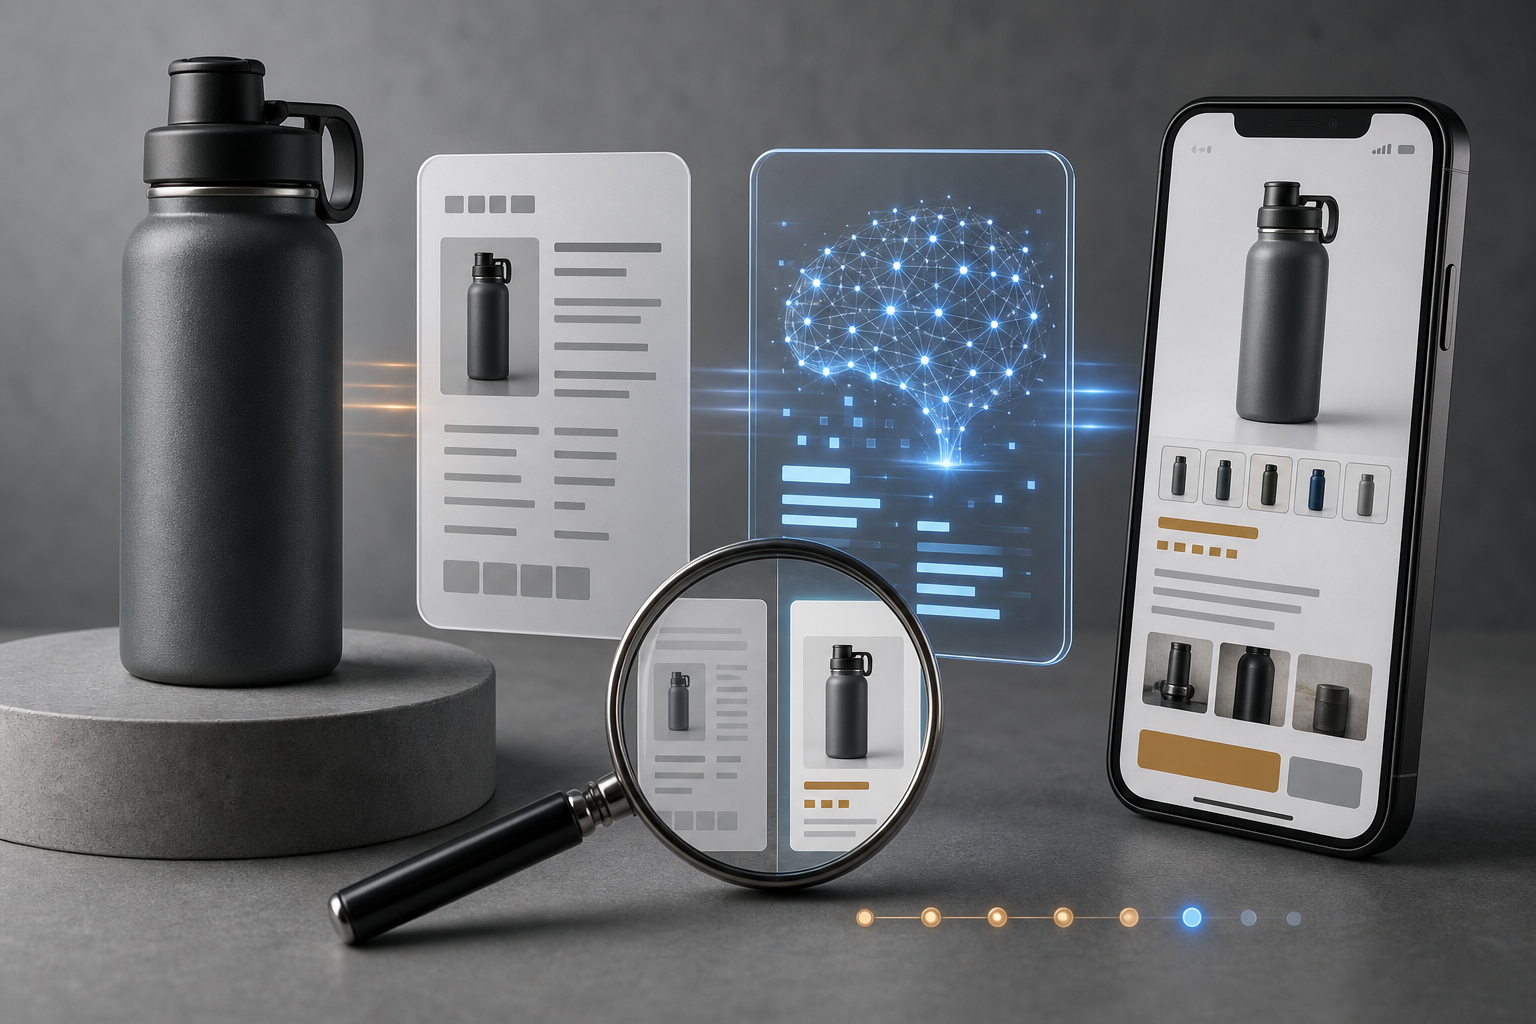
    A magnifying glass compares a source product record with an AI-processed shopping listing shown on a smartphone.

    Google AI can create a customized product title and serve it when it considers that version more relevant than the advertiser-provided title. The original remains eligible to appear when Google considers it more relevant. The practical consequence is simple: your feed title is an input to ad delivery, not a guarantee of the final wording.

    The Product titles report is beginning to appear in Google Ads, so availability may not be uniform across every account. Where it is available, it can place the original and AI-customized titles beside delivery and traffic metrics. That gives you something much more useful than a general notice that automation may alter copy: it gives you inspectable examples.

    Review meaning before performance

    Start by checking whether the generated title still identifies the product accurately. A higher CTR cannot repair a title that creates the wrong expectation.

    1. Compare the identifying details. Check whether the generated wording preserves the brand, model, product type, variant, size, material, compatibility, or other detail a buyer needs to distinguish the item.
    2. Look for a change in promise. Flag wording that implies a feature, bundle, use case, audience, or level of compatibility that the product page does not support.
    3. Check brand and legal sensitivity. Route regulated claims, trademarks, guarantees, and tightly controlled brand language to the appropriate reviewer before treating the title as acceptable.
    4. Inspect the landing-page match. A title may be technically accurate but still emphasize something the landing page does not make easy to find. That mismatch can attract a click while weakening the visit.
    5. Classify the change. Record whether the generated title clarifies the product, rearranges existing details, introduces a new interpretation, or removes a distinguishing detail. This turns isolated examples into patterns you can act on.

    When generated titles repeatedly clarify information that was buried or absent in your originals, treat that as a feed-quality hypothesis. Do not merely admire the AI version. Ask whether the original titles should communicate the same useful distinction more directly.

    Read the metrics as observation, not a controlled test

    The report can include impressions, product clicks, CTR, cost, and average CPC. Those measures answer different questions:

    • Impressions show how much exposure a title received. A dramatic-looking CTR difference attached to limited exposure deserves caution.
    • Product clicks show traffic volume, but not whether those visitors produced valuable outcomes.
    • CTR describes the rate at which impressions produced clicks. It can help you spot wording that attracts attention, but it does not establish why the difference occurred.
    • Cost and average CPC show the price of the traffic. They do not, by themselves, establish revenue, margin, lead quality, or profitability.

    Do not label this comparison an A/B test unless you have a genuinely controlled experimental design. Google may select an original or customized title because it considers one more relevant in a particular serving context. Different contexts can therefore influence both which title appears and how it performs. The report reveals an association between a served title and its results; it does not automatically isolate the title as the cause.

    Your decision should combine three checks: semantic accuracy, sufficient exposure, and downstream business value from your existing measurement setup. A title that earns more clicks but brings poorly matched visitors is not an improvement.

    Make the API assistant prove technical validity

    Google Ads API Developer Assistant v4.0.0 moves from the earlier standalone local-workspace structure to a globally available plugin architecture. It can supply Google Ads-specific rules, skills, and diagnostic commands across projects. The architecture is not compatible with previous releases, so adopting version 4 should be treated as a migration rather than a routine in-place update.

    The assistant supports AI coding workflows in Antigravity and Claude Code. It can generate integration code for Python, Java, PHP, .NET, and Ruby. More importantly for reliability, it can inspect local Protobuf schemas and client-library code instead of depending entirely on what the underlying model remembers about Google Ads.

    That grounding is most useful when you require it as part of the workflow. Use this review sequence:

    1. Identify the intended API version. Record it with the task so a reviewer can distinguish current fields and enums from suggestions that belong to another version.
    2. Inspect the relevant schema before accepting generated code. Confirm resource names, available fields, data types, and enum values against the active version.
    3. Validate every GAQL query before execution. The local validator can check syntax, field compatibility, date segmentation, resources, metrics, date clauses, and zero-impression rules in one pass.
    4. Review account and time context. Before a natural-language request runs against live data, verify the customer ID, manager-account relationship where relevant, date range, segments, metrics, and expected level of aggregation.
    5. Read the generated code as code. Schema validity does not replace review of authentication, account selection, data handling, error paths, and whether the integration performs only the operations you intended.
    6. Save a reproducible result. The assistant can return live results as a formatted table and can save ad hoc reporting output as CSV. Preserve the validated query with the output so another person can reproduce what was retrieved.

    This approach is faster than asking a general-purpose model to guess at a broken query over multiple attempts. It is also safer because the query is checked against Google Ads-specific constraints before it reaches the account.

    Use conversational troubleshooting as triage

    The assistant can investigate offline conversion upload failures, manager-account hierarchy problems, and Performance Max listing filters. It can also help answer broader questions, such as which ads have problems and how those problems might be addressed.

    Treat the response as structured triage. Ask it to identify the failing object, inspect the applicable schema, show the relevant error or rule, and separate confirmed findings from proposed fixes. Then review the recommendation before changing production code or campaign configuration. A conversational explanation is easier to consume than a raw error, but readability is not evidence.

    Know what grounding does not prove

    Schema inspection and local validation reduce a specific class of AI failure: invented fields, incompatible combinations, and version-mismatched configurations. They do not prove that the request reflects the business question you meant to ask.

    • Syntactic validity: Can the query be parsed? The validator can address this.
    • Schema validity: Do the resources, fields, metrics, types, and enums exist and work together for the active version? Schema inspection and Google Ads-specific rules can address much of this.
    • Account validity: Is the query running for the correct customer, through the intended manager hierarchy, over the correct dates? The assistant can help retrieve customer IDs and diagnose hierarchy issues, but you still need to confirm the intended account context.
    • Business validity: Does the output answer the decision you need to make? A perfectly valid cost query is still wrong if the decision depends on profitable conversions or qualified leads.

    The same distinction applies to Shopping titles. Transparency shows you the generated wording and associated performance. It does not prove the wording is accurate, brand-safe, incrementally better, or responsible for the observed result.

    Google says the plugin architecture improves speed and reduces resource and token consumption by loading only the rules and schemas needed for a task, with caching to avoid repeated lookups. Those efficiency claims are useful for adoption planning, but they are separate from auditability. Faster generation changes how quickly work arrives; it does not lower the review standard.

    Build one evidence trail across marketing and development

    Marketing and engineering specialists inspect a connected evidence trail linking product data, validated code, live advertising outputs, and archived outcomes.

    You do not need a large governance program to make these tools accountable. You need a compact record that joins the AI output to the decision made about it.

    For AI-generated product titles, record the product or internal SKU, original title, generated title, review classification, impressions, product clicks, CTR, cost, average CPC, relevant downstream outcome from your measurement system, reviewer, and decision. This is your internal audit log; it should not be confused with a claim that every field appears in the Product titles report.

    For API work, record the customer context, intended API version, client language, user request, generated GAQL or code, validation result, schema fields inspected, date clauses, output location, reviewer, and deployment decision. If the work concerns an offline conversion upload, account hierarchy, or Performance Max listing filter, preserve the original failure details with the diagnosis.

    Assign ownership by artifact:

    • The feed owner is accountable for the original product data and for recurring weaknesses exposed by generated titles.
    • The performance marketer assesses title accuracy, delivery metrics, traffic quality, and the business relevance of the comparison.
    • The developer owns API-version selection, schema verification, query validation, code review, and reproducibility.
    • The appropriate brand, compliance, or business owner approves wording or implementation decisions that exceed the marketer’s or developer’s authority.

    Use event-based reviews instead of checking everything indiscriminately. Review when customized titles first appear, after meaningful feed changes, when a high-impression title changes the product’s meaning, before adopting the incompatible version 4 plugin architecture, before deploying generated integration code, and when a known troubleshooting case affects reporting or conversion data.

    Key takeaways

    • Google may serve an AI-customized Shopping title instead of the title you supplied, so audit the message that appeared rather than assuming feed copy reached the shopper unchanged.
    • Use the Product titles report to inspect original and generated titles with impressions, product clicks, CTR, cost, and average CPC, but do not mistake an observational comparison for a controlled experiment.
    • Check semantic accuracy before celebrating performance. More clicks are not useful when the title attracts the wrong buyer or changes the product promise.
    • Require the Google Ads API Developer Assistant to inspect the active schema and validate GAQL before execution. A fluent answer without those checks is weaker evidence.
    • Separate syntax, schema, account context, and business intent. An implementation can pass the first two tests while still answering the wrong question.
    • Keep an internal record connecting each AI output to its input, validation evidence, reviewer, observed result, and final decision.

    Start with the Shopping products receiving the most impressions and one API workflow where validation failures currently consume time. Establish the evidence record there, assign an owner, and make approval depend on inspectable proof. The aim is not to block automation. It is to shorten the distance between an AI-made change and your ability to understand, verify, and correct it.

    References


  • Google Ads API v25.1: A Practical Measurement Playbook

    Google Ads API v25.1: A Practical Measurement Playbook

    If you pull Google Ads data into a warehouse, dashboard, or client-facing platform, adding fields is the easy part. The harder job is deciding which business question each field can answer without turning unlike signals into one misleading performance score.

    Google Ads API v25.1 gives you several useful separations: original versus adjusted conversion value, attributed results versus incremental lift, internal performance versus category benchmarks, and total converters versus loyalty segments. Used carefully, those distinctions can make your reporting more explainable. Used carelessly, they can produce a wider dashboard that is no more trustworthy than the old one.

    Key takeaways

    • Store original_conversion_value beside the corresponding adjusted value. The difference shows how conversion value rules and customer lifecycle goals are changing the values used downstream.
    • Treat Conversion Lift and Brand Lift as distinct measurement layers. Their API resources are read-only, and access is currently limited to allowlisted Google Ads accounts.
    • Use Product & Service Category benchmarks as context for investigation, not as automatic bidding instructions.
    • Keep brand sentiment separate from campaign outcomes. It can guide review and creator analysis, but it does not establish incremental impact.
    • Model loyalty tier, loyalty membership conditions, and conversion value as separate fields so you can explain who converted and why a value adjustment applied.
    • Although v25.1 is a drop-in upgrade for v25, you still need updated client libraries, code changes for the new capabilities, and semantic regression tests before using the data in decisions.

    Build your measurement model around six different questions

    Six separate measurement workstations examine different signals from one central data source using distinct instruments.

    The most important design choice is not which new metrics to retrieve. It is which question each capability answers. A clean measurement model keeps the following layers separate:

    Business questionv25.1 capabilityAppropriate use
    What was the conversion worth before Google applied value adjustments?original_conversion_valueAudit the effect of value rules and lifecycle goal adjustments.
    Did advertising create incremental conversions or awareness?Conversion Lift and Brand Lift resourcesInspect eligible lift studies, configurations, dimensions, and results.
    How does performance compare with a relevant market category?BenchmarksService with Product & Service CategoriesAdd competitive context to internal performance analysis.
    What sentiment is associated with a creator or brand?ContentCreatorInsightsService sentiment dataSupport creator intelligence, brand review, and reporting workflows.
    Which loyalty groups converted, and did membership affect value?Loyalty tier segmentation and loyalty membership dimensionsAnalyze converters by tier and explain membership-based value rules.
    How might parental-status targeting affect planned reach?ReachPlanService targetingUse parental status in forecasting and plannable product discovery.

    Do not collapse these capabilities into a composite campaign health score. A strong benchmark, positive sentiment, and positive lift are different observations with different scopes. Combining them can hide the exact information a decision-maker needs.

    Make original conversion value an audit layer

    The new original_conversion_value metric exposes the value of a biddable conversion before conversion value rules or customer lifecycle goal adjustments. That distinction matters whenever the value used for reporting and optimization is not identical to the underlying conversion value.

    For each compatible reporting grain, preserve at least three concepts in your own model:

    • Original value: the pre-adjustment value returned by original_conversion_value.
    • Adjusted value: the corresponding value after the applicable rules or lifecycle adjustments.
    • Adjustment delta: adjusted value minus original value, calculated in your reporting layer.

    Report the absolute delta before reaching for a percentage. A percentage becomes undefined when the original value is zero and can look extreme when the denominator is small. If you do show a percentage, define how zero and missing values are handled instead of letting a dashboard silently convert them into zeros.

    The delta is not evidence that Google changed a value incorrectly. It tells you that an adjustment occurred. Your next question is whether that adjustment matches the value rule or lifecycle policy your team intended. Where your system already stores rule metadata, expose it beside the delta so an analyst can move from detection to explanation.

    Do not replace an established revenue or return-on-ad-spend metric with original_conversion_value in one step. That can change budget conclusions simply because the definition changed. Run original and adjusted value in parallel, reconcile known value-rule cases, and label both clearly before either number reaches automated budget logic.

    Keep lift, benchmarks, and sentiment in their own lanes

    Lift data needs its study context

    Google Ads API v25.1 adds read-only resources for Conversion Lift and Brand Lift studies. You can inspect configurations, flight dates, associated campaigns, and conversion goals. The API also adds 24 Conversion Lift metrics, winner score metrics for statistical analysis, and Brand Lift dimensions covering age range, campaign, device, gender, and video.

    Read-only is an important boundary. Build your integration to retrieve and explain study data, not to promise study creation or modification through these resources. Put configuration and result data in the same analytical view: a result without its flight dates, campaign scope, and conversion goal is easy to apply to the wrong period or objective.

    Access is another boundary. Brand Lift and Conversion Lift API capabilities are currently limited to allowlisted accounts, and advertisers are directed to contact their Google representative for access. Check eligibility before committing a delivery date. In a multi-account platform, treat eligibility as an account-level capability rather than assuming that one successful request means every account is supported.

    Your internal presentation should distinguish at least four states: supported with data, supported with no returned data, unavailable because eligibility has not been established, and failed because the request encountered an error. Those are product states you define in your application, not API status labels. Keeping them separate prevents an access limitation from being reported as a zero lift result.

    Winner score metrics should retain Google’s metric names and definitions in your semantic layer. Do not relabel a winner score as probability, certainty, or incremental return unless the applicable definition supports that interpretation. The safe workflow is to display the score with its study scope, then let the measurement owner determine how it informs a campaign decision.

    Category benchmarks provide context, not a target

    BenchmarksService can now compare performance within specific Product & Service Categories and return aggregate cost and views alongside share-based measurements such as share of voice. The narrower category dimension can make a comparison more relevant than a broad benchmark group, but relevance still depends on whether the selected category represents the business being evaluated.

    Before placing a benchmark beside an account metric, document the category, measurement window, metric definition, and any other comparability controls available in your query. If those elements differ, show the benchmark as external context rather than a direct performance gap.

    A share metric and an aggregate volume metric also answer different questions. Share of voice describes relative presence, while aggregate cost and views add scale context. Show both when available. A low share in a large category may deserve a different response from the same share in a small category.

    Do not let a benchmark variance trigger bid or budget changes automatically. The comparison may identify an issue worth investigating, but it does not tell you whether the right response is more spending, different creative, narrower targeting, or no change at all. Route the variance into an analyst review that also considers the account’s own goals and economics.

    Brand sentiment is an intelligence signal

    ContentCreatorInsightsService now supports brand sentiment distributions and summaries for creators and brands. That gives advertising platforms another signal for creator research and brand reporting, but sentiment should not be presented as conversion performance or causal campaign impact.

    Use the distribution when you need to understand the mix behind a summary. A single summary can conceal whether sentiment is consistently moderate or sharply divided. The practical use is triage: identify creators or brands that warrant closer review, then examine the relevant campaign and brand context before acting.

    Connect loyalty reporting to value-rule governance

    Concentric groups of customer tokens pass through adjustable rule gates into a transparent value-measurement chamber.

    Google Ads API v25.1 allows reporting metrics to be segmented by the loyalty program tier of users who converted. It also makes loyalty membership a primary dimension for conversion value rules, allowing you to identify when a loyalty membership condition was satisfied.

    Those capabilities describe two related but different facts:

    • Loyalty tier segmentation tells you which tier is associated with a converting user.
    • Loyalty membership as a value-rule dimension tells you whether a membership condition was met when a conversion value rule was evaluated.

    Do not infer the second from the first. A converter’s tier is an audience attribute; a satisfied rule condition is part of value-processing logic. Store them separately even if your first dashboard shows them together.

    The most useful loyalty analysis combines tier segmentation with the original-versus-adjusted value audit. Start with these questions:

    • How many conversions and how much original conversion value came from each returned tier?
    • How much adjusted conversion value was reported for those same segments?
    • When a loyalty membership condition was satisfied, did the resulting delta match the intended value policy?
    • Are any apparent differences driven by a small number of conversions rather than a stable segment pattern?

    Always report conversion volume beside value when reviewing tiers. A high average value from a small segment can dominate a ranking without providing a dependable basis for budget changes. You do not need an invented universal threshold; you need enough context for the owner of the loyalty program to judge the segment responsibly.

    Parental-status targeting in ReachPlanService belongs in a different part of your model. It expands reach forecasting and plannable product discovery; it is not an observed conversion result. Keep forecast inputs and planned reach outside outcome tables so users cannot mistake a planning scenario for delivered performance.

    Roll out v25.1 without changing metric meaning by accident

    Google describes v25.1 as a drop-in upgrade for v25, but access to the new capabilities still requires the latest client libraries and corresponding code updates. Drop-in compatibility reduces migration friction; it does not replace testing of your transformations, labels, and downstream decisions.

    1. Inventory the current integration. Record the v25 services, fields, generated client types, transformation jobs, dashboards, and automated decisions that could be affected.
    2. Update the client library in an isolated change. Confirm that the existing extraction and build processes still work before requesting new resources or metrics.
    3. Regression-test existing outputs. Run representative unchanged queries through the old and upgraded paths. Compare row grain, identifiers, null handling, totals, and field mappings.
    4. Add one capability group at a time. Original conversion value, lift studies, benchmarks, sentiment, loyalty, and reach planning should enter separate staging models. This makes a semantic error easier to locate.
    5. Model access explicitly. Check allowlist eligibility for lift features and make unavailable capabilities visible to the user. Do not coerce an unavailable response into zero.
    6. Validate with known business logic. For accounts using conversion value rules or lifecycle goals, select known cases and verify that the original-to-adjusted relationship matches the configured intent.
    7. Release reporting before automation. Let analysts inspect the new fields and definitions in read-only dashboards before any benchmark, sentiment, loyalty, or value delta changes bids, budgets, or alerts.

    Give every new metric a short data contract. It should name the business question, API service or resource, reporting grain, raw and derived fields, eligibility requirement, refresh process, null policy, and downstream decision. That document is what stops an accurate field from becoming a misleading KPI six months later.

    If you need one place to start, add original_conversion_value as a parallel audit field and trace its path through your warehouse and reports. Then add category benchmarks and loyalty segmentation as separate analytical views. Treat lift integration as its own workstream because account eligibility and study context must be resolved first. Your next API pull should not merely contain more columns; it should make the path from underlying value to business decision easier to explain.

    References


  • Paid Media Conversion Measurement: What to Change Now

    Paid Media Conversion Measurement: What to Change Now

    Your paid media dashboard can keep filling up while the measurement underneath it becomes less dependable. The practical fix is not another master metric. You need to strengthen how outcome events reach Microsoft Advertising and change how your team interprets branded-search activity in Google Ads.

    Those are separate jobs. One improves event collection when browser signals are limited. The other exposes a consideration signal that sits between an ad impression and a conventional conversion. If you combine them indiscriminately, you can end up with a larger conversion total and a weaker understanding of performance.

    Separate event collection from campaign interpretation

    The most important distinction is between how an event is captured and what the event means. Microsoft Advertising’s Conversions API, or CAPI, changes the collection path. Google’s Branded Searches changes what behavior you can observe after an ad exposure.

    Measurement componentWhat it recordsHow to use itWhat not to infer
    Microsoft UETActivity captured in the browserMaintain browser-side visibility and use it with CAPIDo not assume browser collection alone covers every online or offline outcome
    Microsoft CAPIOnline or offline events sent from your systems through a server-to-server connectionImprove signal coverage and connect outcomes that do not exist solely in the browserDo not assume a second collection path automatically fixes event definitions or duplicate handling
    Google Branded SearchesA search for your brand on Google or YouTube after someone sees an eligible adAssess whether YouTube or Demand Gen activity is followed by greater brand-seeking behaviorDo not treat the signal as a sale, a bidding target, or proof of incremental lift

    This distinction should survive all the way into your dashboard. A server-recorded purchase or qualified offline outcome and a subsequent branded search may both carry a conversion label inside an ad platform, but they answer different questions. Combining them in one unlabeled total makes that total difficult to use for budgeting.

    Create separate reporting groups for business outcomes, consideration actions, and measurement diagnostics. That gives each signal a job before anyone uses it to defend a campaign.

    Add Microsoft CAPI without dismantling UET

    An isometric website and server send conversion-event packets through separate browser and server routes to one measurement destination.

    Microsoft CAPI is currently a beta capability, so your first implementation question is whether the account has access. The second is whether someone can own a server-side integration after launch. This is not a one-time tag installation; it needs an event definition, a connection to the systems where those events originate, and ongoing monitoring.

    Keep UET in place. Microsoft recommends that advertisers combine CAPI with Universal Event Tracking: UET continues to observe browser activity, while CAPI sends data directly from your systems. Treat the two paths as complementary coverage, not competing implementations.

    1. Confirm account eligibility and name a technical owner. If the beta is not available, finish the event design now so access does not become the start of the project.
    2. Build an event register before writing integration code. For every event, record the business definition, originating system, online or offline status, browser collection path, server collection path, reporting purpose, and accountable owner.
    3. Identify overlap between UET and CAPI. When the same real-world action can arrive through both paths, confirm Microsoft’s current deduplication requirements and define the identifier that ties the records together. Do not assume duplicate prevention happens automatically.
    4. Test online and offline flows separately. Use known test cases and verify that the originating system, integration logs, and advertising report describe the same action.
    5. Reconcile events at three stages: created in your system, sent by the integration, and acknowledged or reported downstream. A discrepancy then points to a specific handoff instead of becoming a general tracking mystery.
    6. Document failure handling. Your owner should know where rejected or unsent events appear, how they are retried, and how a prolonged interruption becomes visible.

    The event register matters because server-side transport cannot rescue an ambiguous conversion. If sales and marketing use different definitions of a completed outcome, CAPI can transmit that disagreement more reliably without making the resulting metric more useful.

    Server-side collection is also a transport choice, not permission to send every available customer field. Moving data out of the browser does not remove your privacy, consent, security, or data-governance obligations. Limit the payload to the approved measurement purpose and have the appropriate internal owner review it before production use.

    Reset how you report Google’s Branded Searches

    An abstract ad panel leads to a magnifying glass over products, while only one branch continues to a separate checkout package.

    Branded Searches measures a meaningful middle step: someone sees an ad and later searches for the advertiser’s brand on Google or YouTube. That can reveal demand that a click-only report misses, particularly when the ad creates memory rather than an immediate site visit.

    It is still a consideration action, not an end-of-funnel outcome. Google formally places it under the Consideration goal, and its current rules create several reporting traps that you should resolve before presenting the number.

    • The default conversion window is seven days. You can set it from one to 30 days.
    • YouTube and Demand Gen are currently listed as eligible campaign types.
    • Performance Max is not included in the current eligibility list, even though it appeared when the conversion type was originally announced.
    • Brand mapping must be configured. A missing or incomplete setup can prevent the measurement from working.
    • Branded Searches is treated as a primary conversion action, but it cannot be selected as a bidding optimization goal.
    • The metric appears in Results and All Conversions rather than the standard Conversions column.
    • You can inspect it at campaign, ad group, and asset levels, as well as through Report Editor.

    These eligibility, attribution, and reporting rules mean that a missing number is not automatically a demand problem. Check campaign type, brand mapping, conversion window, and report column before diagnosing the creative or audience.

    Choose the window for comparability, not a bigger count

    The seven-day setting is an attribution boundary. It determines how long a subsequent branded search can qualify after the relevant ad exposure; it is not a waiting period before the data becomes useful.

    Start with the seven-day default unless your measurement plan supports a different choice. If you change it, record the effective date and avoid comparing the new count directly with a period measured under the old window. Extending the eligible period can change the volume even when the campaign itself has not changed.

    Use the signal to investigate influence, not claim causation

    A search that follows an impression establishes sequence inside Google’s measurement framework. By itself, it does not prove that the search would never have happened without the ad. That distinction separates attribution from incrementality.

    Describe the metric internally as observed branded-search behavior after ad exposure. Do not rename it brand lift, incremental search, or acquired demand. If your decision requires a causal claim, an attributed sequence is not a substitute for a controlled lift design.

    The primary-conversion label deserves similar care. In this case, primary does not mean the action can steer bidding, and it does not place the metric in the usual Conversions column. Build a dedicated report from Results or All Conversions, then keep the signal separate from the outcome conversions used to judge commercial return.

    For Performance Max, treat support as unconfirmed unless the current interface or Google guidance available to your account explicitly establishes otherwise. Its absence from the current campaign list is a reason to verify, not a reason to copy the YouTube or Demand Gen setup and assume equivalent coverage.

    Put every measurement change behind a written contract

    A measurement contract is a short operating record for each signal. It prevents platform terminology from becoming your business definition and makes reporting changes auditable. Create one before you alter dashboards, goals, or stakeholder reports.

    • Signal name and plain-language definition
    • The real-world action represented
    • Originating system and collection path
    • Eligible platforms and campaign types
    • Attribution or conversion window
    • Required setup dependencies
    • The platform columns and reports where it appears
    • Whether bidding can use it
    • Whether the signal represents an outcome, consideration action, or diagnostic
    • The owner responsible for implementation and validation

    For Microsoft, the contract should distinguish UET, CAPI, and any event that can arrive through both. It should also show whether each event is online or offline and how overlap is controlled.

    For Google Branded Searches, record YouTube and Demand Gen as the currently listed campaign types, the selected one-to-30-day window, the brand-mapping dependency, the Results and All Conversions reporting locations, and the prohibition on bidding optimization. Mark Performance Max as requiring verification rather than silently treating it as eligible.

    Then use a fixed decision hierarchy. Business outcomes answer whether the investment produced value. Consideration signals help explain movement toward those outcomes. Collection diagnostics tell you whether the measurement path worked. A diagnostic should not determine budget, and a consideration action should not be presented as revenue.

    Before approving a period-over-period comparison, verify that the following conditions remained stable:

    • The eligible campaign set did not change.
    • The conversion window did not change.
    • Brand mapping remained active.
    • The same reporting column or report was used.
    • UET and CAPI coverage remained stable, or any change was annotated.
    • Duplicate handling was verified after integration changes.
    • The business definition of each outcome remained the same.

    If one of those conditions changed, annotate the break and report the affected periods separately. A clean-looking trend line is less useful than an honest discontinuity.

    Key takeaways for your next measurement review

    • Microsoft CAPI is a beta server-side measurement path, not a replacement for UET.
    • Design duplicate handling before sending the same action through browser and server paths.
    • Use CAPI to support online and offline event coverage, but keep one documented business definition for every conversion.
    • Google Branded Searches currently applies to YouTube and Demand Gen; do not assume Performance Max eligibility.
    • The Branded Searches default window is seven days and can be adjusted from one to 30 days.
    • Report Branded Searches as a consideration signal from Results or All Conversions, not as a bidding goal or proof of incremental lift.

    Your next measurement meeting should end with two named owners and two concrete outputs: a technical plan for UET plus CAPI coverage, and a reporting contract for Branded Searches. Once those are explicit, you can add signal without weakening the decisions built on it.

    References


  • Google Ads Automated Language Matching: What to Change Now

    Google Ads Automated Language Matching: What to Change Now

    If you run multilingual Google Ads campaigns, the language setting you once treated as a boundary is about to stop doing that job on Search. Leaving your campaigns untouched may not break delivery, but it can make language allocation harder to predict and language-related waste harder to diagnose.

    Your immediate task is not to find a replacement checkbox. It is to make every eligible ad and destination unmistakably suitable for the language journey you intend, preserve the controls that still matter in Performance Max, and give your reporting enough structure to expose mismatches.

    Know exactly where the language setting stops applying

    Beginning in late September, campaign-level language targeting will disappear from Search and AI Max for Search campaigns. Google will instead match Search ads largely from the language of the ads and signals indicating which languages a user understands.

    Campaign or placementWhat happens to selected languagesWhat you should control
    Standard SearchThe campaign-level setting no longer controls matchingAd language, ad-group clarity and destination language
    AI Max for SearchThe campaign-level setting no longer controls matchingAd language, eligible ad groups and destination language
    Performance Max on Google SearchThe selected campaign languages no longer apply to Search deliverySearch-facing creative and destination language
    Performance Max on YouTube, Display, Discover and GmailSelected languages continue to guide deliveryCampaign language settings as well as multilingual assets
    Shopping ads within Performance MaxLanguage settings do not affect these adsThe product and destination experience rather than the campaign language selector

    The Performance Max distinction is the easiest place to make an expensive mistake. Do not remove its language settings merely because they no longer govern Search inventory. Those settings continue to guide YouTube, Display, Discover and Gmail delivery.

    The opposite warning applies to standard Search. An existing language criterion may remain visible, but visibility does not mean enforcement. Do not use it as proof that a campaign can reach only people associated with the selected language.

    Rebuild multilingual control around the ad-to-page journey

    Three color-coded customer pathways connect abstract speech waveforms to matching search ads and landing pages while a marketer adjusts one route.

    Google can use the language of the search term, a user’s language settings and other preferences to estimate what that person understands. A user whose interface is set to one language may still receive an ad in another language if their behavior supports that match. Your campaign setting will no longer override that judgment on Search.

    That makes the ad itself a routing signal. It also makes language consistency a practical control surface: the promise in the ad, the page it opens and the next action should all work for the same reader. Audit that path in this order:

    1. Inventory every active Search ad by its actual language. Do not classify an ad from its campaign name. Read the headline, description, extensions or assets, and call to action.
    2. Record the destination language. Check the page headline, primary offer, form fields, validation messages and conversion action. A translated ad does not create a supported journey when the page or form switches languages.
    3. Identify mixed-language ad groups. If clean diagnosis matters, separate ads by intended language at the ad-group level. This gives you a clearer record of which language candidate received traffic and what happened afterward.
    4. Keep campaign separation only when it serves another business control. Separate budgets, markets, offers or conversion goals can still justify separate campaigns. Duplicating campaigns solely to select different Search languages no longer creates a reliable language boundary.
    5. Document the Performance Max exception. Mark which selected languages must remain because the campaign also serves YouTube, Display, Discover or Gmail.
    6. Add language to launch QA. Treat an ad, its destination and its conversion path as one test case. Approving only the translation of the ad leaves the costly part of the journey unchecked.

    Clear structure matters when more than one campaign or ad group is eligible. Google says AI-based ad-group prioritization will choose the candidate with the most relevant language. You cannot force that decision with the former Search language control, but you can avoid giving the system ambiguous or poorly supported candidates.

    Make landing-page language an operating requirement

    A language change in the campaign interface used to feel like a targeting task. The new model makes it a content-operations task as well. Ad creative and destination pages now carry more of the burden for Search language matching, so page ownership can no longer sit outside the campaign migration.

    For each language you actively advertise, define what a complete supported experience means. At minimum, the user should be able to understand the offer, evaluate the main terms and complete the primary action without an unexplained language switch. If the business cannot support that journey, pause or remove the corresponding ad rather than hoping the old campaign criterion will suppress it.

    Use language-specific destination paths where they already fit your site structure. They make QA and reporting easier because a landing URL can be reconciled with the language label on an ad group. The URL does not need to become a targeting theory; it needs to help your team answer a concrete question: did the intended ad open the intended experience?

    Translation alone is not enough when the offer changes by market. Check prices, availability, legal terms, fulfilment language and contact options wherever they appear in the conversion path. Those checks are not new Google Ads controls. They are safeguards against paying for a click whose promise the destination cannot fulfil.

    Monitor language matching without waiting for a perfect report

    Two analysts inspect color-coded routes between generic ad tiles and landing pages, with one mismatched connection highlighted in red.

    Automated matching can change which eligible language candidate receives traffic. Build a baseline before the rollout so a later shift is visible. The baseline does not need a new platform metric; it needs stable labels and a repeatable review.

    • Label ads and ad groups by intended language. Use one naming convention across the account so reports can be grouped without rereading every ad.
    • Record performance by that label. Compare impressions, spend, clicks, conversions and conversion value where those measures apply to your objective.
    • Review search terms against the served ad language. Read the whole query before classifying it. Brand names and borrowed words can appear inside queries written in another language.
    • Reconcile destination paths. Flag cases in which a language-labelled ad opens a page intended for a different language.
    • Use downstream evidence. Unsupported-language form submissions, calls or support requests can reveal a mismatch that click metrics alone will not explain.
    • Separate Performance Max observations by placement where your reporting allows it. A Search-delivery change should not automatically be blamed on the language settings that still guide the campaign’s other channels.

    Set alerts from your own baseline rather than borrowing a universal percentage. The available information does not establish a normal amount of language reallocation or a safe variance threshold. Your alert should identify a material change in your account, not pretend that every advertiser will experience the same shift.

    When you find a problem, change one controllable layer at a time: the eligible ad, the ad-group structure or the destination. That preserves enough evidence to tell whether the correction worked. Rebuilding campaigns, rewriting ads and changing pages simultaneously may stop the immediate symptom, but it will leave you unable to identify the cause.

    Update Google Ads API workflows by campaign type

    API users have a concrete migration requirement. Stop sending language criteria when creating or updating Search campaigns. Attempts to add or update CampaignCriterion.language for Search will return ContextError.OPERATION_NOT_PERMITTED_FOR_CONTEXT.

    Existing Search language criteria may remain but will no longer affect targeting. You may remove them, but cleanup is optional. If another internal system reads those objects, decide whether retaining inert criteria would mislead operators before choosing to leave them in place.

    Do not apply the same rule indiscriminately to Performance Max. Its language setting still influences non-Search channels, so Performance Max will not return the same context error. Branch the workflow by campaign type instead:

    1. Exclude language criteria from new Search campaign requests.
    2. Remove language mutations from Search update jobs and templates.
    3. Allow existing Search criteria to remain only if your interface clearly marks them as non-operative.
    4. Preserve supported Performance Max language operations for the channels where they still matter.
    5. Test both create and update paths so error handling does not hide unrelated failures behind the expected context error.
    6. Update internal documentation, validation rules and campaign builders that still describe Search language selection as an enforceable control.

    This is more than an API compatibility fix. If an internal campaign tool continues showing a required Search language selector, users may believe they established a boundary that Google no longer observes. Removing that false assurance is part of the migration.

    Key takeaways

    • For Search and AI Max for Search, stop treating campaign-level language selection as a targeting restriction.
    • For Performance Max, preserve selected languages because they still guide YouTube, Display, Discover and Gmail, even though they no longer govern Search placements.
    • Use deliberately separated ad languages, clearly matched destinations and consistent labels to make automated decisions easier to diagnose.
    • Keep separate multilingual campaigns when budgets, markets, offers or goals require them, not merely to recreate a language switch that no longer controls Search delivery.
    • Remove Search language mutations from API workflows, while retaining campaign-type logic for Performance Max.

    Start with the account inventory and the API branch before late September. Then run the ad-to-page language audit while the old structure is still familiar. You cannot restore the removed Search control, but you can make every language candidate intentional, measurable and supportable before automated matching decides where it belongs.

    References