Tag: API

  • Modern SEO Workflows: From Dashboards to Small Tools

    Modern SEO Workflows: From Dashboards to Small Tools

    A modern SEO workflow has to do more than collect rankings and audit errors. It must distinguish visibility from traffic opportunity, focus limited time on pages that matter to the business, and turn recurring analysis into reliable automation.

    The most useful operating model is therefore not a wholesale replacement of traditional SEO software. It is a layered system in which established data sources reveal the problem, people choose the intervention, and AI-assisted tools reduce the cost of repeating proven work.

    The operating model matters more than the size of the stack

    Rank trackers, keyword platforms and site crawlers remain useful because search engines still need to discover, interpret and evaluate pages. However, the reported case for a new SEO stack is that those tools describe only part of a more fragmented search environment. AI Overviews, local packs, shopping features and other result formats can change how much value a nominal ranking produces. Historical search volume can likewise remain stable while an answer displayed in the results reduces the traffic available to publishers.

    That changes the role of measurement. A ranking is an observation, not an outcome. The workflow must connect traditional visibility, AI-search presence, landing-page behavior and conversion evidence before deciding what deserves attention. The same source reported that LLM referral traffic in its cited dataset grew by 80% between the first and second halves of 2025 and converted at 18%, while accounting for 2% or less of total traffic. Those figures were presented as evidence of a small but potentially meaningful channel, not as proof that conventional search had ceased to matter.

    Workflow layerQuestion it answersTypical inputsRequired output
    ObserveWhere is visibility, demand or performance changing?Search Console, analytics, rank tracking, crawls and AI-visibility observationsA short list of material signals
    DecideWhich signal is worth acting on now?Business value, intent, conversion proximity and implementation effortOne prioritized intervention
    ShipWhat can improve the page or remove the constraint?Content edits, internal links, technical fixes and clearer conversion supportA completed change or actionable brief
    SystematizeWhich repeated work should become faster and more consistent?APIs, scripts, notebooks and carefully supervised LLMsA documented, testable process

    This sequence prevents a common tooling mistake: automating a report before establishing which decision the report should support. It also preserves a place for human judgment between data collection and implementation.

    A 120-minute loop can connect monitoring with delivery
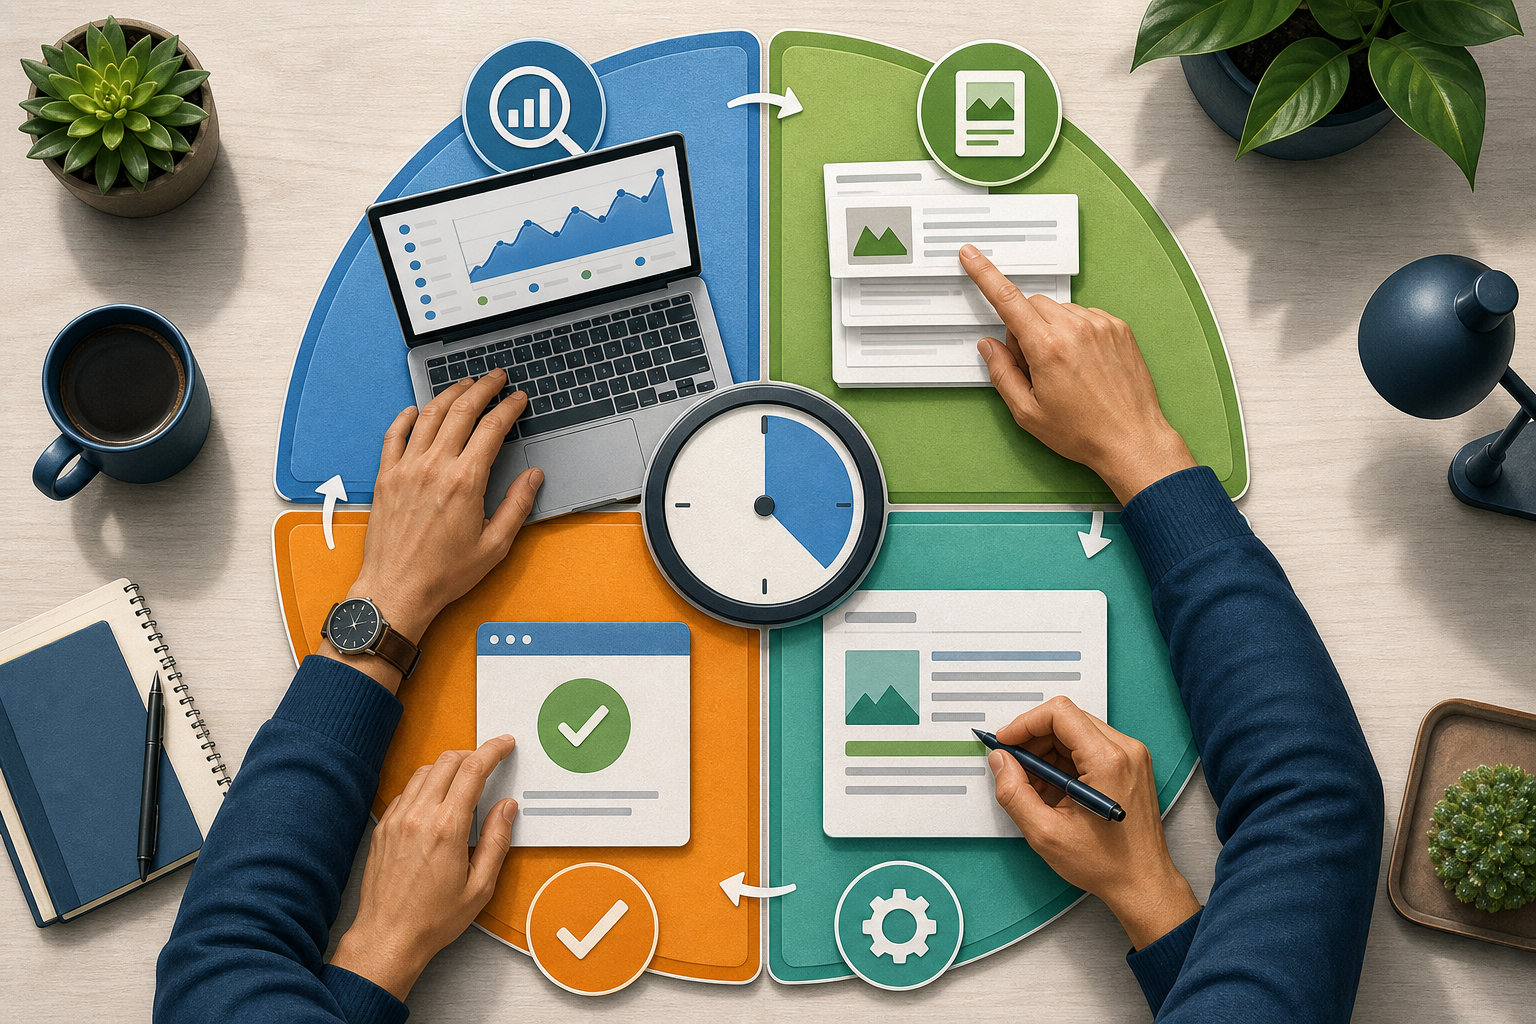
    A top-down desk scene shows four connected stages of an SEO workflow arranged in a circle around a strategist's hands.

    The reported 120-minute workflow addresses a practical constraint: on a lean marketing team, SEO competes with campaigns, reporting, email, social publishing and website requests. Its strongest principle is that a weekly session should finish with work shipped, not merely with more metrics reviewed.

    The first five time boxes below follow the source’s reported schedule. The final 20-minute block is a synthesis of the other sources’ automation guidance, turning the weekly session into a tool-development feedback loop.

    1. Minutes 0-15: inspect Search Console and analytics for meaningful movement, including clicks, impressions, click-through rate, landing-page performance, conversions and critical indexing warnings. Record the largest win, concern and investigation target rather than building a presentation.
    2. Minutes 15-35: identify a small number of query opportunities. The source recommends examining queries in positions 4-15 with meaningful impressions, pages with weak click-through rates and results where the ranking page only partly satisfies intent.
    3. Minutes 35-60: improve one page close to revenue, such as a product, service, category, pricing, comparison or consultation page. The change might address an objection, clarify the audience, add proof, answer a relevant question or make the next action easier to understand.
    4. Minutes 60-80: resolve one consequential technical or indexing problem. If a direct fix is not possible, produce an assigned issue or a developer brief with affected URLs and the expected behavior.
    5. Minutes 80-100: strengthen internal links between useful informational pages and relevant commercial destinations, while also connecting supporting guides and newer strategic content.
    6. Minutes 100-120: verify what changed, document the result and mark one repetitive task as a possible automation candidate. That candidate should enter a backlog rather than becoming an improvised build during the same session.

    The value of this cadence is not the clock alone. It creates a recurring path from signal to decision to change. It also generates concrete automation ideas: a comparison performed every week, a recurring CSV cleanup, a repeated title check or a manual alert that depends on the same thresholds each time.

    Small tools should begin with a bounded decision

    The source on vibe coding describes a low-barrier pattern: specify a program in natural language, run the generated code in an environment such as Google Colab, inspect the output and return errors to the AI for another iteration. It distinguishes this from AI-assisted coding, where a developer remains more directly responsible for the system, and from no-code platforms, which expose automation through visual interfaces.

    The distinction helps set an appropriate ceiling. Vibe coding is presented as suitable for prototypes, internal utilities, demonstrations and tasks where a useful result does not have to be perfect. Commercial software, sensitive systems and products requiring dependable maintenance call for stronger engineering, security and testing practices.

    A reported SEO example makes the right project shape clear. After a site crawl produced vector embeddings, the author prompted an AI to create a Colab tool that would compare vectors with cosine similarity and suggest related pages within each locale. The program had an explicit input, a defined matching rule and a CSV output. It did not attempt to automate an entire SEO strategy.

    Before generating code, a useful tool brief should define:

    • The decision or bottleneck the tool is meant to improve.
    • The exact input source, required columns and accepted file format.
    • The transformation or rule applied to the data.
    • The expected output format and who will use it.
    • A small set of known examples for checking correctness.
    • The behavior when data is absent, duplicated, malformed or unexpectedly large.
    • The APIs, credentials, usage charges and execution environment involved.

    Tool choice can then follow complexity. An LLM may be enough to explore a one-off dataset or review copy. An API becomes useful when manual exports are the bottleneck. A lightweight script suits a stable transformation such as flagging performance changes or checking metadata. A notebook is appropriate when code, commentary and outputs need to remain together. A maintained application is warranted only when the process has durable users, permissions, interfaces and support requirements.

    Validation is part of the workflow, not a final polish
    A compact modular tool moves a web page tile through several visual validation checkpoints while rejected variants remain separated.

    All three sources point toward speed, but they also expose different reasons to retain human control. The new-stack article recommends using LLMs for analysis, content review, competitor comparison, metadata and structured data while keeping editorial and strategic oversight. The weekly workflow keeps prioritization tied to commercial importance. The vibe-coding account shows why plausible-looking output cannot be accepted on appearance alone.

    In one example from the vibe-coding source, an underspecified prompt failed to explain that the input would be a CSV. The generated tool responded with invented URLs, traffic figures and charts. The same source reports that generated code can depend on packages that are not installed, and that paid APIs may introduce authentication steps and usage costs. These are not edge concerns: they demonstrate that execution, factual grounding and operating cost must all be tested separately.

    • Ground the run: identify the authoritative input and reject synthetic substitutes unless test data is explicitly requested.
    • Test a sample: compare several outputs with results that can be checked manually, including an ordinary case and an edge case.
    • Inspect failure behavior: confirm that missing columns, empty files, invalid credentials and API errors produce understandable messages.
    • Protect access: keep credentials out of prompts, shared notebooks, exported files and source code intended for distribution.
    • Track cost: estimate which calls consume paid API units or usage-based platform resources before scheduling repeated runs.
    • Preserve review: require a person to approve consequential content changes, redirects, canonical decisions, schema deployment or other site-wide actions.
    • Document ownership: record the tool’s purpose, dependencies, expected inputs, validation method and person responsible for maintenance.

    A prototype should be promoted into a recurring workflow only after it produces repeatable results on known data. If the logic affects many pages or a revenue-critical system, code review and stronger testing become proportionally more important.

    Key takeaways

    • Keep traditional SEO data, but interpret rankings and search volume alongside result features, traffic opportunity and business outcomes.
    • Time-box reporting so that every weekly SEO session produces a shipped improvement, an assigned fix or a precise implementation brief.
    • Use recurring manual work to discover automation opportunities; do not begin with a tool and search for a problem afterward.
    • Give every small SEO utility explicit inputs, transformation rules, outputs, test cases and failure behavior.
    • Treat LLMs, APIs and scripts as accelerators within a reviewed process, not as substitutes for strategy, factual checks or technical ownership.

    As search interfaces continue to diversify, the durable advantage will come from shortening the distance between a trustworthy signal and a verified improvement. Teams can build that capability incrementally, one weekly decision and one well-scoped tool at a time.
    References

  • Google Ads API Ending Smart Campaign Creation: My Take

    Google Ads API Ending Smart Campaign Creation: My Take

    I see Google’s latest Google Ads API change as another clear move away from legacy automation and toward newer AI-driven campaign types, especially Performance Max.

    Beginning August 3, 2026, Google says developers will no longer be able to create new Smart Campaigns through the Google Ads API. For me, the key detail is that this change is about new campaign creation only.

    Existing Smart Campaigns are not being shut down. They can keep serving ads, and advertisers and developers will still be able to update and manage those campaigns through the API.

    What changes is the ability to create brand-new Smart Campaigns through API workflows. If I depend on automated campaign setup, that is the part I would review now.

    I care about this because it signals where Google wants advertisers to go next. Smart Campaigns may continue running, but the path for new API-based campaign creation is moving toward newer products such as Performance Max, Search campaigns, and Demand Gen campaigns.

    Google is specifically pointing advertisers toward Performance Max as the primary alternative. Since Performance Max runs across Google’s advertising inventory and uses AI to automate more of the campaign process, it fits the broader direction Google has been taking for years.

    I also see this as part of a wider consolidation around automated campaign formats. Google has increasingly emphasized systems that handle bidding, targeting, and creative optimization across channels, and limiting new Smart Campaign creation reinforces that shift.

    For developers, the practical next step is to audit any application that creates Smart Campaigns before the August 3, 2026 deadline. The affected requests are campaign creation operations where advertising_channel_type is set to SMART and advertising_channel_sub_type is set to SMART_CAMPAIGN.

    After August 3, attempts to create new Smart Campaigns through the API will fail. In version 24 of the Google Ads API, developers will receive a SmartCampaignError.CREATION_FAILED error.

    In version 23 and earlier, the same type of request will return an OperationAccessDeniedError.CREATE_OPERATION_NOT_PERMITTED error.

    My main takeaway is that advertisers, agencies, and software providers should not treat this as a last-minute technical cleanup. If campaign creation is built into an internal tool, onboarding flow, or platform integration, I would start mapping the replacement path now.

    Google is not ending existing Smart Campaigns, but it is removing a key creation path for new ones. To me, that is a strong signal that future campaign planning should center on Performance Max and other AI-driven Google Ads campaign types.

    Dig deeper: Changes to Support for Smart Campaigns in the Google Ads API


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google Ads Updates Split Bidding Labels From Data Automation

    Google Ads Updates Split Bidding Labels From Data Automation

    Two Google Ads updates illustrate why the word automation needs careful interpretation. One reorganizes how established bidding strategies are named, while the other automatically begins processing eligible advertisers’ conversion data into customer lists.

    The practical distinction is consequential: the bidding update is reported as cosmetic, but the audience update changes an account default. Advertisers therefore need different responses to each development rather than treating both as changes to campaign optimization.

    Two updates, two different forms of automation

    The bidding report says Google is restoring the standalone Target CPA and Target ROAS names. It also says the underlying bidding behavior and expected campaign performance remain unchanged, with no advertiser action required.

    By contrast, the customer-list report describes an operational default: eligible accounts will have conversion-based customer lists enabled automatically, with data processing reported to begin on August 18. The sources therefore cover complementary but materially different issues. One changes the language used to describe automated decisions; the other changes how an audience-data feature is activated.

    Restored bidding names make campaign intent easier to read

    A campaign manager examines unchanged bidding mechanisms beneath rearranged blank color-coded tabs.

    According to the bidding report, “Maximize conversions with a Target CPA” will again be called Target CPA, while “Maximize conversion value with a Target ROAS” will return to Target ROAS. Maximize Conversions and Maximize Conversion Value remain available as separate strategies for advertisers prioritizing conversion volume or conversion value.

    This creates a clearer conceptual boundary between an unconstrained maximization objective and an objective governed by a stated efficiency target. It should not, however, be interpreted as a new bidding model, a performance intervention or a reason to reset campaigns. The source explicitly characterizes the change as naming-only.

    The report also connects the revised interface labels with Google Ads API terminology. Teams maintaining integrations or reporting systems are advised to watch for adjustments involving the BiddingStrategyType enum, standalone TargetCpa and TargetRoas messages, and optional targets within MaximizeConversions and MaximizeConversionValue. That makes taxonomy mapping a more relevant concern than bid-performance troubleshooting.

    Automatic customer lists require a governance decision

    A compliance team reviews anonymous data tokens passing through a privacy checkpoint into an automated audience container.

    The customer-list report says automatic enablement applies to qualifying advertisers already using both Enhanced Conversions and Customer Match but not conversion-based customer lists. Google will process existing conversion data to make the lists available without additional implementation work, according to the source.

    Availability is not the same as campaign use. The report says advertisers can subsequently decide whether to add the resulting audiences to campaigns or ad groups. The immediate decision is therefore whether the account should permit list generation at all; targeting decisions remain a separate step.

    Advertisers that do not want the feature enabled can disable conversion-based customer lists in account settings before the reported August 18 processing date. This opt-out makes the update relevant to account ownership, consent practices and internal audience-data policies even when no campaign is scheduled to use the lists.

    Key takeaways for Google Ads teams

    • Treat the Target CPA and Target ROAS update as a terminology change, not evidence that bidding logic or campaign performance has changed.
    • Keep Maximize Conversions and Maximize Conversion Value distinct from target-based strategies when documenting objectives and reporting results.
    • Review eligible accounts before the reported August 18 date and make an explicit decision about conversion-based customer-list processing.
    • Separate list creation from list activation: automatic availability does not require an advertiser to use an audience in a campaign or ad group.
    • Check API integrations and internal naming maps as Google aligns interface labels with standalone bidding-strategy types.

    What advertisers should monitor next

    Together, the updates point toward a Google Ads environment in which interfaces may become clearer while data features become more automatic. Strong account management will depend on identifying which changes merely improve labels and which alter defaults, permissions or data flows. Teams that document both bidding intent and audience-data choices will be better prepared for subsequent interface and API adjustments without mistaking automation for loss of control.

    References

  • Profound MCP Connectors: What the Integration Really Means

    Profound MCP Connectors: What the Integration Really Means

    Profound’s External MCP Connectors are presented as a way to bring outside work systems into Profound through a shared integration layer. The practical promise is less tool switching: information and actions associated with content management, project tracking, and team communication could become accessible from a more centralized workflow.

    The available source is a short, vendor-authored announcement rather than independent testing or detailed technical documentation. Its claims therefore establish Profound’s intended direction, but not the connector catalog, supported operations, security model, or measurable productivity gains.

    What Profound says its external connectors enable

    According to the Profound post, External MCP Connectors can link the platform with CMS tools, project trackers, and team communication platforms. The announcement describes these connections as a way to manage projects, streamline workflows, improve collaboration, and access important tools from a central hub.

    Those statements should be read as product positioning. The source does not identify particular supported services, distinguish between read-only access and write actions, or demonstrate a complete workflow. It also offers no comparative results showing how much time or effort the connectors save. Consequently, the meaningful takeaway is the proposed integration model, not a verified performance outcome.

    Why MCP changes the integration conversation

    Different digital systems connect through a standardized bridge to a single AI workspace.

    In general terms, the Model Context Protocol provides a standardized way for an AI-enabled application to interact with external sources and tools. Instead of treating every connection as an entirely separate product integration, an MCP-based approach can give compatible systems a common interface for exposing permitted context or actions.

    For Profound users, the architectural implication may matter more than the phrase “central hub.” A common interface can make it easier to assemble workflows spanning several systems, but it does not automatically make those systems interchangeable. Each connector can still differ in authentication, available functions, data structure, reliability, and administrative controls.

    Key takeaways

    • Profound reports that External MCP Connectors can connect CMS, project-tracking, and team-communication tools with its platform.
    • The central value proposition is workflow consolidation, although the source provides no independent evidence or quantified results.
    • MCP standardizes the connection pattern; it does not guarantee identical capabilities, permissions, or data quality across external tools.
    • Teams should evaluate each connector at the level of actual tasks, accessible data, permitted actions, and operational controls.

    The questions teams should answer before adoption

    A digital connector workflow passes through permission, identity, audit, and human approval checkpoints while a team monitors it.

    A useful evaluation starts with the workflow rather than the number of available connections. A team might examine where information currently moves between its CMS, project tracker, and communication system, then identify which transfers are repetitive, slow, or prone to inconsistency. The connector is valuable only if its available operations match those specific handoffs.

    Access boundaries also require scrutiny. Evaluators should determine which data Profound can retrieve, which actions it can initiate, how users authenticate, and whether permissions from the connected service remain enforceable. Logging, error handling, approval requirements, and procedures for revoking access are similarly important wherever a connector can change external records.

    Finally, teams should test the quality of the resulting context. Centralized access is not necessarily coherent access: duplicated records, inconsistent naming, stale project statuses, or ambiguous ownership can still undermine an integrated workflow. A limited pilot built around one repeatable task can reveal whether the connector reduces friction without obscuring accountability.

    From connectivity to dependable workflows

    Profound’s announcement points toward a platform that can sit closer to the systems where teams already plan, communicate, and manage content. Whether that direction produces meaningful efficiency will depend on the depth of individual connectors and the governance surrounding them. Future documentation and hands-on evaluation will be needed to establish which workflows are genuinely supported and how reliably they operate.

    References

  • How to Build a Google Ads Activation and Data Integration Plan

    How to Build a Google Ads Activation and Data Integration Plan

    You have retailer audiences in one system, media buying in another, and purchase data somewhere else. The problem isn’t a lack of data. It’s making that data usable across Google without losing control of identity, measurement, or ownership.

    A workable plan separates audience activation from conversion measurement, then connects them through a shared data contract. That gives your media team broader reach while preserving a credible path from ad exposure to sale.

    Key takeaways

    • Treat audience activation and conversion ingestion as separate data paths with different owners, permissions, and failure modes.
    • Use retailer first-party audiences to reach relevant shoppers through Demand Gen on YouTube, Discover, and Gmail.
    • Define one internal conversion schema before mapping events to Google destinations.
    • Do not add identifiers merely because an integration supports them. Collection rights, consent, security, and retention rules still apply.
    • Judge the integration by business outcomes and data reliability, not by audience size or event volume alone.

    Separate audience activation from conversion measurement

    Two color-coded data paths separately connect anonymous audience tokens with advertising screens and purchase events with a measurement repository.

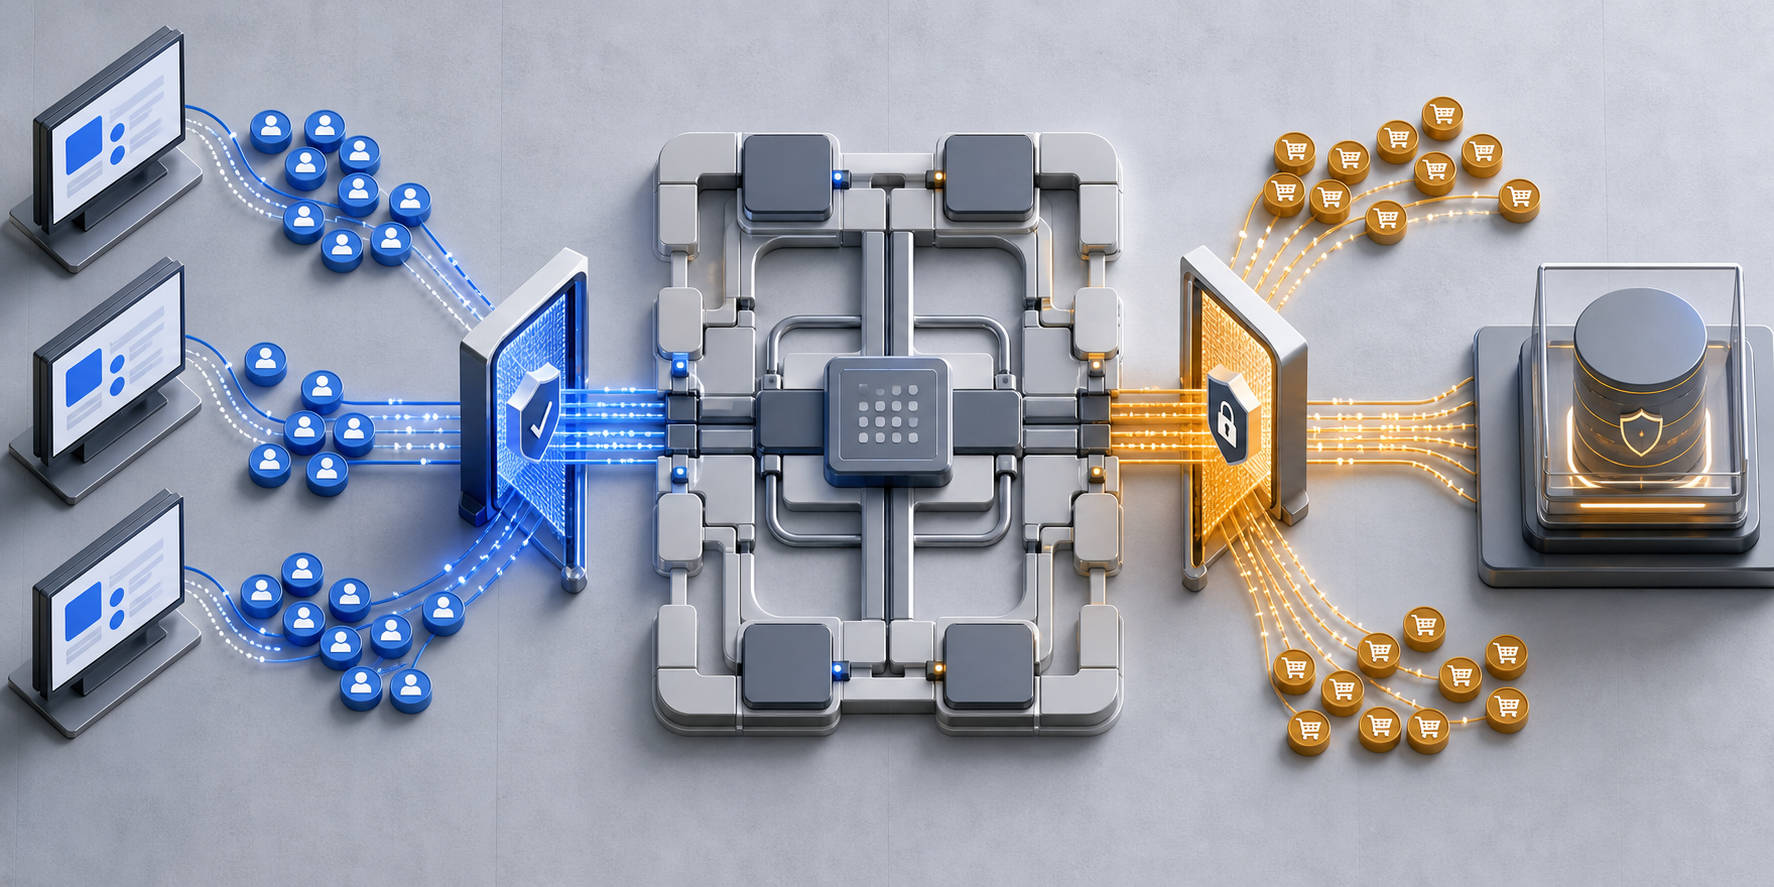
    Audience activation answers, “Who should see the campaign?” Conversion ingestion answers, “What happened after someone saw or engaged with it?” Combining those questions into one vague data project makes ownership unclear and troubleshooting difficult.

    On the activation side, the Commerce Media Suite can make retailer first-party audiences available to Demand Gen campaigns across YouTube, Discover, and Gmail. A brand can therefore use retailer audience intelligence outside the retailer’s own website while Google AI optimizes delivery toward conversions and sales.

    On the measurement side, the Data Manager API can ingest offline conversion events for Campaign Manager 360, Search Ads 360, and Display & Video 360. A common schema can route data to multiple destinations in one request instead of forcing your team to maintain a separate integration for every product.

    Data pathQuestion it answersOutput to define
    Retail audience activationWhich eligible shoppers should the brand reach?Approved retailer audience segments for Demand Gen
    Campaign deliveryWhere should those audiences encounter the campaign?Channel, creative, objective, and optimization settings
    Conversion ingestionWhich commercial outcome occurred?Validated offline event sent to the intended Google destinations
    MeasurementDid advertising contribute to a purchase?Reporting that connects exposure and engagement with sales outcomes

    Give each path its own owner. The retailer or commerce team should approve audience definitions and permitted uses. The media team should own campaign configuration. Analytics or marketing operations should own event quality, routing, and reconciliation. Privacy and security teams should approve identifier handling across all three.

    Define the data contract before building the integration

    A shared API does not automatically create shared meaning. If one team calls an order “complete” when payment is authorized and another waits until fulfillment, both can send technically valid events while producing incompatible reporting.

    Write an internal event contract before anyone maps fields. For every conversion, document the business definition, originating system, event timestamp, transaction identifier, value and currency when relevant, permitted user identifiers, consent state, destination products, correction process, and accountable owner. Treat this as your business specification, not as a substitute for the API’s required-field documentation.

    Next, create a routing matrix. Each row should be an approved event, and each destination column should state whether that event is sent, transformed, or withheld. This prevents the convenience of one-request routing from quietly turning into indiscriminate data distribution.

    Teams still using the Campaign Manager 360 API for conversion uploads should evaluate migration to the Data Manager API as the central ingestion layer. Inventory existing event definitions and destination-specific transformations first. Otherwise, a migration can preserve old inconsistencies inside a newer pipeline.

    Govern identity matching as a capability, not a shortcut

    Better matching can improve audience usefulness and attribution, but every identifier expands your governance obligations. The Data Manager API supports encrypted identifiers such as email addresses and phone numbers. Those fields should enter the pipeline only when you have a documented collection basis, approved advertising use, appropriate protection, and a defined retention policy.

    IP ingestion for Google Ads Customer Match is scheduled to begin in Q3 2026 through a CompositeData field, paired with an observation timestamp. Treat that as an additional matching option, not permission to upload every IP address available to you. Confirm product availability for your account and region, review applicable consent and policy requirements, and document where the address originated before enabling the field.

    Do not promise a specific match-rate gain. Instead, establish a controlled baseline and watch whether the additional identifier improves eligible audience reach without increasing rejected records, policy risk, unexplained reporting changes, or data-handling complexity. If your team cannot explain an identifier’s origin and permitted use, leave it out.

    Launch with evidence gates at every stage

    A glowing data pipeline passes through several security and verification checkpoints before reaching a final activation node.
    1. Name the business outcome. Choose the sale or offline conversion that the campaign is meant to influence. Avoid starting with a broad goal such as “send all customer data.”
    2. Confirm the systems of record. Identify which retailer system defines audience membership and which transaction system has authority over the final outcome.
    3. Approve audience rules. Record who qualifies, which brand may use the segment, where it may be activated, and when eligibility ends.
    4. Approve the event contract and routing matrix. Resolve differences in conversion definitions before coding field mappings.
    5. Test data quality. Verify that timestamps survive transformation, transaction identifiers remain stable, values reach only approved destinations, and duplicate events do not inflate reporting.
    6. Run a limited activation. Start with a clearly defined audience and conversion so your team can trace the path from retailer data to Demand Gen delivery and then to the reported purchase outcome.
    7. Reconcile before expanding. Compare accepted and rejected records, destination totals, retailer sales records, and unexplained gaps. Expand to more audiences or destinations only after the first path is trustworthy.

    The integration is working when your teams can answer four questions without assembling an emergency spreadsheet: which audience was eligible, where it was activated, which conversion definition was used, and how the reported outcome reconciles with the retailer’s sales record.

    Start with one audience, one commercial outcome, and an explicit owner for each data path. Once that loop is reliable, broader activation across Google’s inventory becomes an expansion of a proven system rather than another disconnected campaign.

    References

  • DV360 Demand Gen API Support: A Safe Rollout Plan

    DV360 Demand Gen API Support: A Safe Rollout Plan

    If your DV360 integration assumes every returned line item or ad group belongs to a type it already recognizes, Demand Gen support creates a practical failure point. A successful API call can still break downstream processing when an unfamiliar resource reaches a strict parser, reporting job, or campaign-management rule.

    You can prepare without rebuilding your DV360 workflow. Start by making reads tolerant of Demand Gen resources, then introduce write operations behind explicit controls.

    What Demand Gen support changes in DV360

    The Display & Video 360 API is adding support for Demand Gen line items, ad groups, and ad formats. Developers and advertisers can retrieve, create, update, and delete the supported Demand Gen resources through the API.

    The important detail is not just the new write capability. Demand Gen line items and ad groups can appear alongside standard resources in existing list responses. That means an integration may encounter them even if your team has not started creating Demand Gen campaigns through the API.

    Treat this as both a schema-compatibility change and a new automation opportunity. The first job is protecting current workflows. The second is deciding which Demand Gen actions you are ready to automate.

    Harden every workflow that reads line items or ad groups

    Different shapes of data blocks pass through a flexible gateway into organized processing lanes.

    Begin with an inventory of anything that consumes DV360 list responses. Include campaign dashboards, data pipelines, naming-rule checks, budget monitors, approval tools, and internal interfaces. A shared API client does not guarantee that every downstream consumer handles new resource types safely.

    1. Find closed type assumptions. Search for switch statements, enum validation, allowlists, and default branches that reject or misclassify an unfamiliar line-item or ad-group type.
    2. Separate parsing from business eligibility. Your integration should be able to read and retain a Demand Gen resource even when a particular workflow is not authorized to act on it.
    3. Use an explicit unsupported state. Do not silently treat an unrecognized resource as a standard line item. Record its identifier and type, skip the unsafe action, and make the event visible to operators.
    4. Test mixed responses. Exercise the full path with standard and Demand Gen resources in the same collection. Confirm that filtering, pagination, reporting, and batch processing still complete.
    5. Check output contracts. If your DV360 data feeds another system, make sure the receiving schema can preserve a new type instead of dropping the record or failing the entire batch.

    The safest behavior is forward-compatible: accept a valid object, preserve what you understand, and block only the operation that lacks a defined rule. This contains the impact of future resource additions as well.

    Add create, update, and delete operations in stages

    Three connected deployment chambers use guarded gates while background account nodes show different availability states.

    API availability does not mean every mutation should be enabled at once. Give each operation its own release control and validation path.

    1. Start with retrieval. Confirm that you can identify Demand Gen line items and ad groups, store them correctly, and display them without exposing unsupported controls.
    2. Enable creation in a constrained workflow. Validate inputs before the request, record the request and resulting resource identifier, and prevent an automatic retry from creating duplicates.
    3. Permit updates by field. Use an allowlist of fields your integration intentionally manages. Do not send a broad object copied from a read response when only one value needs to change.
    4. Protect deletion separately. Require an explicit resource-type check, a clear ownership rule, and confirmation that the target identifier belongs to the intended advertiser and campaign.

    Keep read and write permissions conceptually separate. A reporting integration may need to understand Demand Gen objects without receiving authority to modify them. A campaign-management service may need update access but no delete path.

    For each mutation, log the resource type, operation, target identifier, result, and calling workflow. That record gives your team a usable trail when an automated change needs investigation.

    Plan around partial rollout and mixed account availability

    The announced rollout begins June 10 and is expected to be fully available by June 24. During a staged release, availability should be treated as a capability to detect, not a universal assumption.

    Use a capability gate for Demand Gen writes. If a request shows that support is unavailable, return a clear status to the operator and keep the rest of the DV360 workflow running. Do not translate an availability problem into a generic campaign failure.

    Your release sequence should cover three states: no Demand Gen resources returned, Demand Gen resources returned but writes disabled, and full management enabled. Test rollback too. Turning off creation or updates should not stop the integration from reading resources that already exist.

    Operational ownership matters here. Assign one person or team to review unsupported-type logs during rollout, approve write enablement, and decide when an account is ready. Without that owner, compatibility warnings tend to sit unnoticed until a scheduled job fails.

    Key takeaways

    • Existing list queries may return Demand Gen line items and ad groups, so read compatibility comes before new campaign automation.
    • Parse valid resources independently from deciding whether a workflow may act on them.
    • Release create, update, and delete capabilities separately, with validation, logging, and operation-specific controls.
    • Expect mixed availability during the June 10 to June 24 rollout window and make write support capability-driven.
    • Keep Demand Gen reads working even when you disable mutations or roll back an automation release.

    Start with one concrete check: run a mixed-resource response through every DV360 consumer you operate. Once those paths can identify, preserve, and safely skip Demand Gen objects, you have a stable base for adding campaign management at your own pace.

    References

  • Google Ads Workflow and Data Retention: How to Adapt

    Google Ads Workflow and Data Retention: How to Adapt

    Your Google Ads team now faces two different kinds of time pressure. New ads may receive policy feedback while they are being created, while older reporting data can disappear once its retention window closes.

    The practical response is to redesign both ends of the campaign lifecycle: make compliance part of production, then make data preservation part of routine account operations. Here is a workable system you can put in place without turning every launch or export into a special project.

    Key takeaways

    • Responsive Search Ads can receive editorial feedback during drafting and a policy decision after saving, so policy checks should happen inside your creation workflow.
    • Simple, editable problems need a clear owner who can correct and resubmit them immediately. Certifications, appeals, and other complex issues need a separate escalation path.
    • Hourly, daily, and weekly reporting data is retained for 37 months, while monthly, quarterly, and annual reporting can remain available for up to 11 years.
    • Reach and frequency metrics have a three-year retention limit, so preserve them on their own schedule.
    • Expired data becomes unavailable through both the Google Ads interface and APIs. An API connection is not an archive unless it writes data to storage you control.

    Move policy review into campaign production

    The old mental model was simple: build an ad, submit it, and wait for a separate review. Real-Time Policy Reviews move feedback into the creation process. While you draft a Responsive Search Ad, Google Ads can flag editorial problems such as typos and destination-link errors. After you save it, the system can return a policy decision immediately. Ads without identified problems can move toward delivery quickly, while more complicated cases go to a post-save review screen with the issue and available next steps. The capability initially applies to Responsive Search Ads, with expansion to other campaign types planned.

    That changes what “campaign ready” should mean. Your launch checklist should no longer stop when the copy and landing page are approved internally. It should stop when the saved ad has a recorded Google Ads policy outcome.

    Separate editable issues from complex issues

    Google divides policy problems into two useful operational groups. Editable issues are problems you can correct in the ad workflow, such as formatting errors. Complex issues may require certification, an appeal, or another process that cannot be completed by rewriting a headline. Treating both groups as the same queue creates avoidable delay.

    1. Draft and preflight: Confirm the final URL, spelling, formatting, and required internal approvals before saving.
    2. Read the live feedback: Correct editorial flags while the creator still has the ad open and understands the context.
    3. Save and record the decision: Capture the policy status in your campaign tracker rather than assuming that saving means approval.
    4. Fix editable problems immediately: Keep these with the campaign builder so a minor correction does not enter a general support queue.
    5. Escalate complex problems: Assign one named owner for certifications, evidence, appeals, and communication with stakeholders.
    6. Confirm delivery: Check that an approved ad has actually begun serving before declaring the launch complete.

    For each exception, record the account, campaign, ad, exact policy message, first detection time, assigned owner, action taken, and final status. This small audit trail helps you distinguish recurring production mistakes from genuine policy disputes.

    Build your archive around the actual retention windows

    Campaign record tiles moving through layered digital storage while data outside the archive fades near abstract clock rings.

    Policy feedback can shorten the time from creation to delivery. Data retention creates the opposite constraint: waiting can permanently reduce what you are able to analyze. Beginning June 1, 2026, Google Ads applies different limits based on reporting period, and data that passes those limits is no longer available in the interface or through APIs.

    Reporting dataRetention periodPractical archive decision
    Hourly, daily, and weekly reports37 monthsBackfill granular history first and export it continuously.
    Monthly, quarterly, and annual reportsUp to 11 yearsKeep these rollups for long-range reporting, but do not treat them as a substitute for granular data.
    Unique users, average impression frequency per user, 7-day and 30-day average impression frequency, and frequency distribution metricsThree yearsGive reach and frequency data its own earlier export deadline.

    A monthly total cannot recover the daily pattern behind it. If you use historical performance for seasonality, forecasting, anomaly analysis, client benchmarking, or cross-channel planning, preserve the smallest reporting interval you genuinely need. Do not export every possible combination without a use case; that produces an expensive archive that nobody can interpret.

    Use a backfill-first export plan

    1. Inventory dependencies: List every dashboard, forecast, scheduled report, client deliverable, and internal analysis that reads Google Ads history.
    2. Classify the required grain: Mark each dependency as hourly, daily, weekly, monthly, quarterly, or annual. Identify any use of reach and frequency metrics separately.
    3. Find the oldest unpreserved period: Determine where storage you control begins. The gap between that date and the oldest data still available is your backfill target.
    4. Export the oldest granular data first: Data nearest its deletion boundary carries the greatest risk. Work forward after securing it.
    5. Automate incremental exports: Schedule recurring extraction into storage outside Google Ads. Include monitoring so a failed job cannot remain invisible for months.
    6. Retain raw and transformed data separately: Preserve an unchanged extract, then build cleaned reporting tables from it. This lets you correct transformation errors without attempting to retrieve expired records again.

    Your stored records also need enough context to remain usable. Keep stable account and campaign identifiers, reporting dates, reporting grain, relevant dimensions, metric names, account time zone, currency context, and the extraction timestamp. Document any transformation or filtering applied after export.

    Prove that the archive can replace the interface

    Specialist restoring archived campaign records into an organized reporting workspace during a recovery test.

    A successful export is not the same as a reliable archive. The real test is whether another person can reproduce a familiar report after the corresponding Google Ads data is no longer accessible.

    • Reconcile totals: Compare stored results with the Google Ads interface for several completed periods at each reporting grain you intend to keep.
    • Check completeness: Look for missing accounts, dates, campaigns, dimensions, and reach or frequency fields.
    • Test reruns: Confirm that retrying an extraction does not silently duplicate records or overwrite valid history.
    • Simulate recovery: Rebuild one recurring dashboard using only the archive and its documentation.
    • Assign ownership: Name the person responsible for failed exports, schema changes, access control, and retention decisions in your own storage.
    • Record validation evidence: Save reconciliation dates, discrepancies, fixes, and approval from the report owner.

    API users need to be especially careful. An automated query that fetches data on demand still depends on Google’s retention window. Continuity comes from writing scheduled extracts to independent storage, validating them, and keeping enough documentation to interpret them later.

    This history may also serve people outside the paid media team. If SEO, content, finance, or leadership uses advertising trends for planning, ask what granularity they depend on before choosing what to preserve. Their needs may not be visible in the Google Ads reporting setup.

    Set a 30-day operating plan

    In the first week, add the post-save policy decision to your campaign launch checklist and designate owners for editable and complex issues. During the second week, inventory reporting dependencies and retention risks. Use the third week for the oldest required backfill, prioritizing granular and reach-and-frequency data. In the fourth week, automate the next extraction, reconcile it against Google Ads, and run a report using only the stored copy.

    Then make both controls routine. Every campaign launch should end with a verified policy and delivery status. Every reporting cycle should end with a successful, validated export. That gives your team faster launches without sacrificing the history needed to understand what happened later.

    References

  • Unlock Coding Potential with the Profound API Cookbook

    Unlock Coding Potential with the Profound API Cookbook

    Hey there! I’m excited to introduce you to something that has truly changed the way I approach coding projects—the Profound API Cookbook. If you’ve ever started with the thought, ‘I want this number,’ and wished for a seamless way to transform that into runnable code, this is for you.

    Imagine having a collection of end-to-end recipes right at your fingertips, perfectly layered on top of our REST API references. This isn’t just about coding; it’s about enhancing your workflow and efficiency in a whole new way. Each recipe is designed to guide you from concept to execution with ease.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Build Google Commerce Infrastructure From Visibility to Revenue

    Build Google Commerce Infrastructure From Visibility to Revenue

    You can have thousands of products appearing on Google and still have two expensive blind spots. Shoppers may never see listings hidden behind a carousel scroll, while purchases or qualified leads completed elsewhere may never return to Google Ads.

    If you own ecommerce growth, you need two connected but distinct systems: one that measures whether products earn usable visibility, and one that returns offline outcomes to the advertising platform. Here is how to build both without confusing presence with exposure, activity with revenue, or shared reporting with attribution.

    Count the product placements shoppers can actually see

    Shopper viewing a product carousel where several items are visible and many more remain hidden beyond the screen edge.

    A product-pack appearance is not automatically an impression worth celebrating. Google can place products in horizontally scrollable carousels, so the first visible positions receive a very different opportunity from listings that require interaction before they appear.

    The scale makes this distinction material. A monitoring dataset covering more than 63,000 merchants from January 2025 through January 2026 found searches with as many as 60 individual organic product listings on one results page. A report that counts every one of those listings equally will overstate the practical reach of products buried deep in a carousel.

    Keyword coverage can be just as misleading. eBay appeared in product results for 874,621 keywords and generated about 3.2 million estimated visits, while Home Depot appeared for a slightly smaller 831,699 keywords but generated nearly 28.8 million estimated visits. The difference was associated with Home Depot securing more prominent, immediately visible positions. More appearances did not mean more useful exposure.

    Build your product-pack scorecard in layers. Keep each layer separate so an impressive top-line number cannot hide weak placement:

    • Eligible catalog: Products you expect Google to understand and consider for the category.
    • Total appearances: Every detected placement, including positions that require scrolling.
    • Visible appearances: Placements shown before a shopper scrolls the carousel.
    • Visible rate: Visible appearances divided by total appearances. Preserve the counts beside the percentage so a small sample does not look more important than it is.
    • Query quality: Segment high-demand category searches from low-volume long-tail queries. Raw keyword coverage otherwise rewards breadth whether or not that breadth produces meaningful traffic.
    • Observed visits and outcomes: Use analytics for measured sessions, transactions, leads, and revenue. Label third-party traffic estimates as estimates rather than blending them with observed data.

    Review the scorecard by category, not only by domain. A healthy total can conceal one category that wins visible positions and another that appears frequently but remains out of sight. That second category is where feed and merchandising work may create the largest gain.

    Fix commerce inputs before reaching for a blanket discount

    Discounting is easy to change and easy to report, which makes it an attractive explanation for product-pack performance. It is not a reliable standalone lever.

    Among large merchants in the monitored data, Amazon discounted 49% of its catalog and achieved a 72% visibility rate. eBay discounted only 8% and reached 81%. Walmart Seller reached the same 81% visibility rate with 24% of products discounted, while Walmart discounted 27% and recorded a lower 62% visibility rate. That irregular pattern does not establish a universal ranking formula, but it does show why discount depth should not be treated as the primary explanation for placement.

    Start with the inputs Google and shoppers need to evaluate the product: complete product data, clear category relevance, strong images, current pricing and availability, and credible reviews. Promotions can still support a commercial offer, but they cannot compensate for an unclear product identity or poor category fit.

    Turn low visibility into a product-level work queue

    1. Choose one commercially important category rather than auditing the whole catalog at once.
    2. Export products that appear for relevant queries but have a low visible rate.
    3. Compare those products with visible winners in the same category. Check data completeness, category alignment, image quality, review strength, price, and availability.
    4. Group repeated defects. Ten products with the same missing or weak input should become one system fix, not ten unrelated tickets.
    5. Correct one defect class, record the date, and remeasure the same category. Product-pack placement fluctuates, so a before-and-after comparison needs consistent queries and a sufficiently stable observation window.
    6. Escalate products that remain hidden despite clean inputs. They may face a relevance, competitiveness, or demand problem rather than a feed defect.

    This process will not prove that one field caused a ranking change. It will give you a disciplined way to improve controllable inputs without assuming that every movement came from price.

    Specialist retailers should be especially careful not to confuse smaller scale with weaker potential. Camp Chef appeared for 155,299 keywords yet generated about 2.6 million estimated visits through advantageous placements. Its footprint was much smaller than the largest marketplaces, but category focus and placement quality produced substantial estimated traffic. Depth in a category can be more commercially useful than millions of marginal appearances.

    Protect offline conversion measurement as the API route changes

    Offline checkout and sales outcomes flowing through a secure gateway into a newer cloud-based measurement connection.

    Product-pack optimization addresses organic commerce visibility. Offline conversion imports address Google Ads measurement and bidding. They belong in the same commerce operating model, but they are not the same channel and should never be presented as if one directly measures the other.

    Google is moving offline conversion imports, including enhanced conversions for leads, from the Google Ads API toward the Data Manager API. Under the communicated change, UploadClickConversions becomes nonfunctional after June 15 for affected accounts that have not used the feature during the preceding 180 days. The change applies to offline conversion imports for some developers, while other Google Ads API operations continue.

    Do not infer that your integration is safe merely because it still runs or because another Google Ads API operation succeeds. An application can keep managing campaigns while its offline conversion path quietly becomes obsolete. Missing imports can weaken reporting, attribution, and the conversion signals used by automated bidding.

    Use this migration checklist

    1. Find every dependency. Search application code, scheduled jobs, middleware, vendor integrations, and internal runbooks for UploadClickConversions. Include enhanced conversions for leads and any sales or lead events completed outside the immediate ad interaction.
    2. Map the affected accounts. Record which accounts use each workflow, when each last imported conversions, who owns the source system, and how frequently the job runs. The 180-day activity condition makes account-level evidence more useful than a platform-wide assumption.
    3. Define the event contract. Document what qualifies as a conversion, where it originates, how it is identified, which value is sent, and which system is authoritative. Migration is a poor time to preserve an event definition nobody can explain.
    4. Build the Data Manager API route. Keep unrelated Google Ads API operations in place unless they have a separate reason to move. The scope here is the conversion-ingestion workflow.
    5. Test a controlled slice. Confirm that source events are accepted, rejected events are visible to operators, and imported counts and values reconcile with the originating system.
    6. Prevent double counting. A temporary overlap can help validate a migration, but sending the same business event through two active routes without a deduplication plan can corrupt reporting. Document exactly when the old writer stops and the new writer becomes authoritative.
    7. Add failure monitoring. Alert on missing runs, unexpected volume changes, rejected events, and reconciliation gaps. A job that reports technical success but delivers no usable conversions is not healthy.

    Because the communicated cutoff applies selectively, treat the date as a prompt to verify your current environment rather than assuming every account failed at once. The decisive evidence is your dependency inventory, recent account activity, accepted-event reporting, and reconciliation with the source system.

    Join the systems without inventing cross-channel attribution

    A shared commerce data spine makes the two workstreams easier to operate. It does not make Google Ads conversion imports a measurement system for organic product packs. Preserve channel and attribution boundaries while standardizing the business entities used in both.

    At minimum, use consistent product and category identifiers across the commerce feed, landing pages, analytics, CRM or order system, and internal reporting. If you publish product structured data, align its product identity, price, and availability with the same source of truth. The immediate benefit is diagnostic: your team can trace a category from search visibility through site behavior and recorded outcomes without manually translating competing names.

    Product-pack visibilityOffline conversion pipelineWhat you can concludeNext action
    Strong and visibly placedHealthy and reconciledBoth discovery and advertising measurement are operational, but their results still require separate attribution.Compare category economics and prioritize the products with the strongest observed business outcomes.
    Strong and visibly placedBroken or uncertainOrganic discovery may be healthy, but Google Ads reporting and bidding signals are unreliable.Restore and reconcile the conversion pipeline before making bid or campaign conclusions.
    Weak or mostly hiddenHealthy and reconciledAdvertising measurement is usable; the organic product-pack problem sits upstream.Work the category-level product data, relevance, image, review, price, and availability queue.
    Weak or mostly hiddenBroken or uncertainYou have two separate failures, not one vague Google problem.Assign independent owners. Protect conversion ingestion because bidding can be affected, while product visibility remediation proceeds in parallel.

    Give each layer an operating cadence

    • Daily: Check whether offline conversion jobs ran, whether expected events arrived, and whether rejection or reconciliation thresholds were breached.
    • Weekly: Review visible versus non-visible product-pack appearances by category. Create a prioritized issue queue for products with meaningful query exposure but poor placement.
    • Monthly: Compare category-level visibility, measured site outcomes, advertising results, catalog changes, promotions, and resolved data defects. Keep estimated traffic in a separate column from observed sessions and revenue.
    • After a sudden change: Check availability, price, images, reviews, feed completeness, and category mix before concluding that discounting or a single platform update caused the movement.

    Expect movement. Nearly every merchant in the year-long monitoring dataset experienced product-pack visibility shifts, with some gaining during one period and receding later. Google can change how it weighs feed quality, availability, reviews, pricing, and images, so a previously strong visible rate is not a permanent asset.

    Key takeaways

    • Report visible product-pack appearances separately from placements hidden behind a carousel scroll.
    • Segment performance by category and query value; raw keyword coverage can conceal poor positioning and weak traffic.
    • Treat discounts as one commercial input, not a substitute for complete product data, category relevance, good images, reviews, current price, and availability.
    • Audit UploadClickConversions dependencies now and move affected offline conversion workflows to the Data Manager API with reconciliation and failure alerts.
    • Keep organic visibility and Google Ads attribution distinct, even when they share product identifiers and business reporting.

    Start with one important category and one conversion workflow. Establish the visible-placement baseline, clear the highest-frequency product-data defect, and verify that the corresponding offline conversion job reaches its destination. That gives you a working control loop you can extend across the catalog without scaling hidden measurement errors along with it.

    References

  • How to Manage Ad Targeting and API Updates Without Chaos

    How to Manage Ad Targeting and API Updates Without Chaos

    An advertising-platform release can create two very different jobs. A targeting feature asks whether you can reach a better audience. An API change asks whether your reporting, security checks, stored data, and automation will continue to work. Treat both as features to try, and you can spend budget before measurement is ready or discover a broken data dependency after the damage is done.

    That distinction matters now because Microsoft Advertising has extended LinkedIn profile targeting to connected TV campaigns, while Google Ads API v24.1 adds reporting, creative-control, experiment, authentication, and retention-related changes. You need a release process that protects existing operations first, validates measurement second, and tests growth opportunities third.

    Classify each change before scheduling the work

    The loudest feature should not automatically become the first task. Rank changes by what happens if you ignore them. A new audience may represent an opportunity, but a data-retention limit can permanently narrow the history available to your reporting system.

    Use five practical classes:

    • Continuity changes: retention limits, unsupported requests, client compatibility, and anything else that can interrupt a production workflow.
    • Measurement changes: new segments or metrics that alter how performance can be divided and interpreted.
    • Security changes: fields that help you identify account protections or authentication gaps.
    • Control changes: options that affect how an approved creative is uploaded, transformed, or displayed.
    • Growth changes: new audiences, inventory, campaign types, and experiment surfaces.

    Work through them in that order unless a documented dependency changes the sequence. Continuity comes first because lost history or a failed reporting job can affect every campaign. Measurement comes before growth because you cannot judge a new audience reliably until you know what the reporting can and cannot observe.

    For the current updates, the 37-month Google Ads data-retention boundary belongs in the continuity queue. The mobile-device platform segment belongs in measurement. The passkey field belongs in security. Demand Gen image control belongs in control. LinkedIn-based CTV targeting belongs in growth. That classification gives your team an actionable backlog rather than an undifferentiated list of announcements.

    Test professional CTV targeting as an audience hypothesis

    A media planner runs a small connected TV audience test by selecting one professional audience cluster for comparison.

    Microsoft’s CTV expansion lets advertisers use professional attributes such as industry, job function, company category, and professional identity signals. For a B2B advertiser, that can connect broad streaming exposure with a more relevant professional audience.

    It does not turn a professional attribute into buying intent. A viewer’s job function may indicate fit, but it does not prove that the viewer is researching a purchase. Treat the targeting as a testable audience hypothesis: people matching this professional profile should respond differently from a suitable comparison audience when the message and measurement remain consistent.

    Build the first test in this order:

    1. Choose one buying group. Describe it with the smallest useful combination of industry, function, and company characteristics. If you begin with a heavily stacked audience, you will not know which condition created the result or restricted delivery.
    2. Write down what the attributes mean. Record the exact audience definition, intended buying role, exclusions, eligible markets, and date of activation. Platform labels are not a substitute for an internal audience specification.
    3. Hold avoidable variables steady. Use comparable creative, offers, geography, inventory conditions, and evaluation windows across the audience cells. Otherwise, a creative or delivery difference can masquerade as a targeting effect.
    4. Select an observable outcome before launch. Do not let an easy-to-read delivery metric become the business objective by default. Use the conversion, lift, or qualified-response signal that your measurement stack can support consistently.
    5. Set a decision rule. Define what evidence would justify expanding, revising, or stopping the audience. Making that decision after seeing the result invites selective interpretation.
    6. Review privacy and compliance. Confirm that the proposed professional segmentation, creative, data handling, and market coverage fit your organization’s requirements before the audience begins receiving ads.

    Measurement deserves extra attention. CTV has traditionally operated as a brand-oriented channel with less direct attribution than search or shopping. Professional targeting can improve audience relevance, but it does not automatically resolve that measurement gap. Keep exposure quality, downstream response, and attribution confidence separate in your readout.

    Several implementation details remain uncertain, including market availability, segmentation granularity, measurement capabilities, and privacy considerations. Verify those items in the account and market you intend to use. Do not build a forecast around targeting combinations or reporting dimensions you have not confirmed are available.

    Turn Google Ads API v24.1 into an engineering checklist

    An engineer checks reporting, security, creative, experiment, automation, and data modules before an API workflow reaches production.

    API adoption is not complete when a client library installs successfully. The real work sits downstream: query builders, schemas, dashboards, experiment records, asset workflows, authentication reports, exception handling, and historical storage.

    Start by mapping each v24.1 capability to the system it can affect:

    The retention change deserves a separate migration task. Search your query code, scheduled exports, dashboards, year-over-year reports, model-training inputs, and audit workflows for requests that can reach beyond 37 months. Then verify what history is still queryable and preserve future data at the granularity your business actually needs.

    An archive is useful only if you can interpret and restore it. Store the account identifier, reporting period, timezone, currency context, field definitions, extraction timestamp, and relevant attribution or configuration metadata alongside the metrics. Test a restore into a clean table before relying on the archive. A successful export file is not proof of a recoverable reporting history.

    Update error handling as well. DateRangeError.REQUESTED_DATE_GRANULARITY_NOT_SUPPORTED identifies an unsupported date-range request. Treat a confirmed policy boundary as a query-design problem, not a transient failure to retry indefinitely. Logging the requested dates and granularity will make the remediation far faster.

    Put targeting and API work through one change-control loop

    Marketing and engineering do not need separate definitions of a successful platform update. They need one shared record that distinguishes a business hypothesis from a technical dependency.

    Change typeQuestion to answer firstEvidence requiredSafe response if it fails
    New audienceCan you isolate the audience effect?Documented audience cells, stable measurement, and a predefined decision rulePause the new segment without disturbing the existing campaign structure
    Reporting dimensionCan every downstream system accept and interpret it?Schema validation and reconciled totals against a baselineRemove the new dimension from production queries while preserving the test
    Creative-control fieldDoes the delivered asset match the approved intent?Asset-level quality review and recorded campaign mappingReturn to the previously approved asset path
    Retention boundaryCan analysis continue after platform history expires?External archive plus a successful restore testNo platform rollback exists; repair the archive and shorten unsupported queries
    Authentication-status fieldWho acts when an account lacks the expected protection?Verified field ingestion, ownership, and a remediation queueKeep the current authentication flow while correcting the reporting or rollout process

    Every change ticket should name an owner, impacted accounts, affected queries or campaigns, the validation evidence, a rollback path, and the date when someone will make a keep-or-revert decision. If no one owns that decision, the change is not ready for production.

    Keep the Microsoft audience test and Google API migration separate even if they appear in the same planning cycle. One measures whether professional targeting improves an advertising outcome. The other protects and expands the systems used to report that outcome. Combining them creates two moving parts and a result that is harder to diagnose.

    Key takeaways

    • Prioritize continuity and data-retention work before testing new reach.
    • Treat professional CTV attributes as proxies for audience fit, not proof of current purchase intent.
    • Confirm Microsoft CTV availability, measurement, segmentation, and compliance conditions in the actual account and market before forecasting results.
    • Test every new Google Ads API field through queries, schemas, storage, and dashboards before promoting it to production.
    • Maintain an external, restorable archive if your reporting requires more than 37 months of Google Ads history.
    • Give every rollout a named owner, acceptance evidence, rollback path, and decision date.

    At your next platform-change review, create two queues: one for operational deadlines and one for controlled growth tests. Clear the dependencies that can damage data or reporting, validate the measurement layer, and then give the new audience or creative capability a fair test.

    References