Tag: AI Advertising

  • How to Make AI-Assisted PPC Optimize for Real Profit

    How to Make AI-Assisted PPC Optimize for Real Profit

    Your PPC dashboard can show a healthy return while the campaign quietly consumes the margin you meant to keep. The usual problem is not that automated bidding failed. It is that the bidding system was given revenue, lead counts, or convenient proxy values and asked to treat them as business value.

    You can fix that without abandoning automation. Start by defining the economics outside the ad platform, translate them into usable conversion values and bidding limits, and then let AI control only the decisions it has enough reliable data to make.

    Start with the profit floor, not the platform target
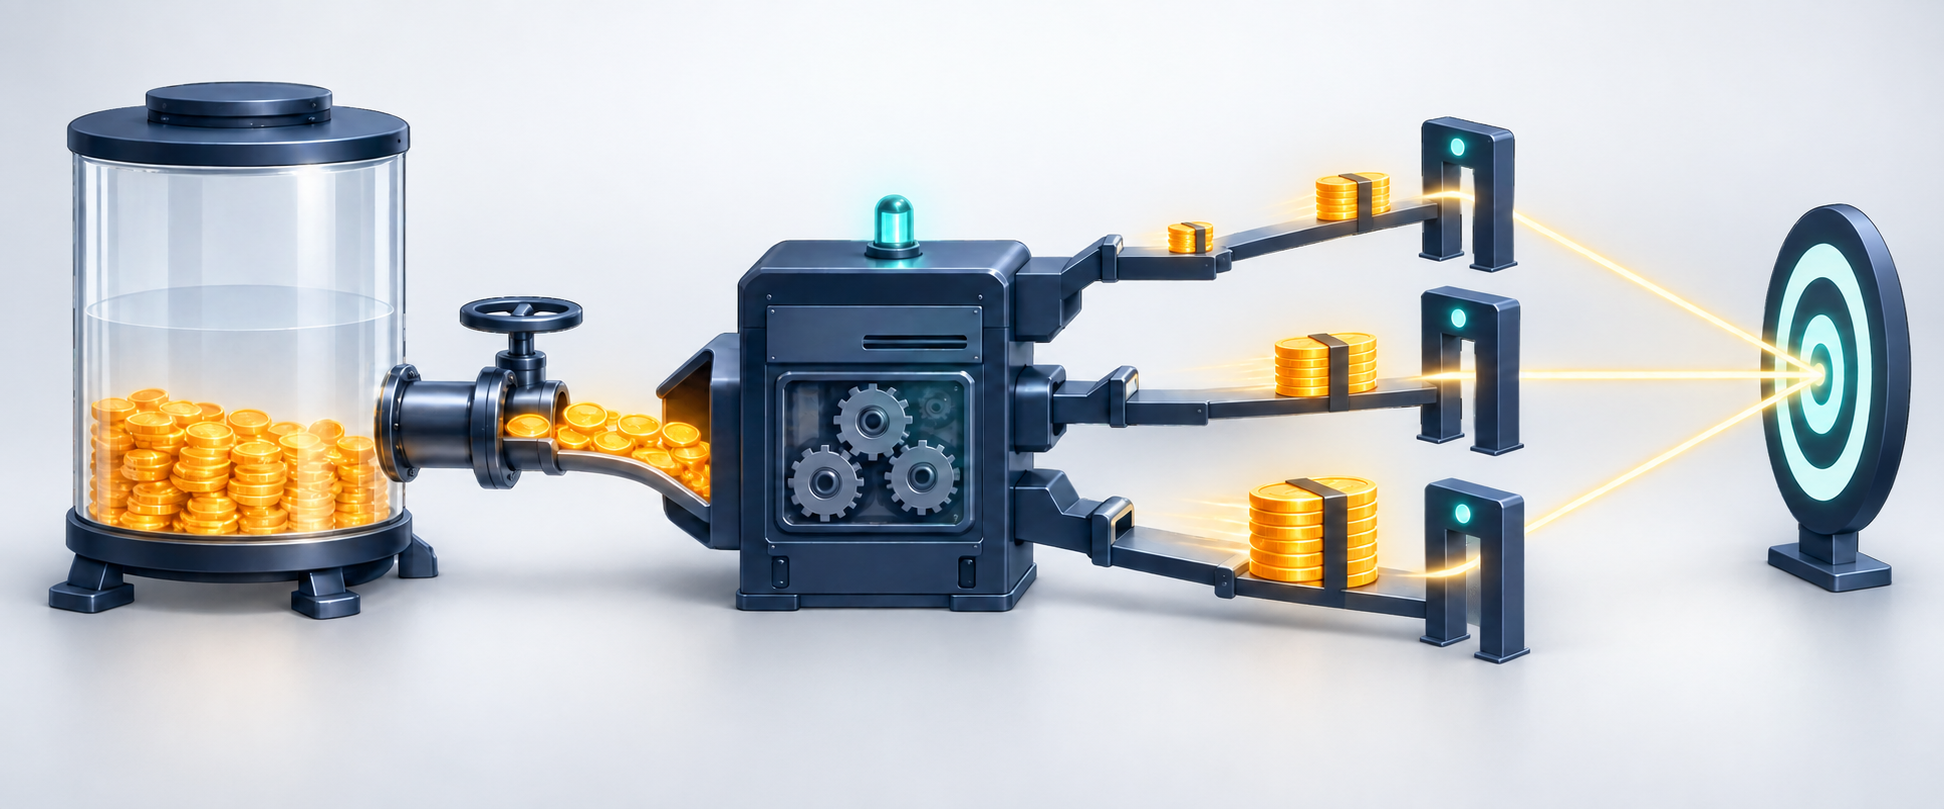
    Coins pass through trays representing product, shipping, payment, service, and return costs before the remainder reaches a protected profit platform.

    Revenue ROAS answers a narrow question: how much reported revenue did you receive for each unit of ad spend? It does not tell you how much money remained after the product, service delivery, transaction, fulfillment, return, and advertising costs attached to that revenue.

    For a campaign whose conversion value represents revenue, the basic relationship is:

    Break-even ROAS = 1 / pre-ad profit margin expressed as a decimal.

    If the relevant margin is 15%, the break-even ROAS is about 6.67, or 667%. At that point, $6.67 of revenue produces about $1 of profit before advertising for every $1 spent on ads. The campaign has covered the advertising cost under that simplified model, but it has not created additional post-ad profit.

    That distinction matters: 667% would be the economic floor in this example, not automatically a sensible operating target. A target ROAS is also a bidding instruction, not a guarantee that every order, day, or campaign will achieve that return.

    If you want a defined post-ad contribution, build it into the calculation. Let m represent the pre-ad margin as a share of revenue and p represent the share you want to retain after ad spend. Your maximum ad-spend share is m – p, so the required ROAS is 1 / (m – p). This forces the profit requirement into the target instead of adding an arbitrary cushion to the break-even number.

    Before applying that formula, settle four inputs with whoever owns the financial numbers:

    1. Confirm what conversion value means. If it is revenue, a revenue-based margin formula can work. If it is already a profit proxy or weighted lead value, applying the same margin again will distort the target.
    2. Define the pre-ad margin consistently. Record which costs are included. Shipping, returns, payment fees, and overhead can materially change true profitability, so a label such as average margin is not enough.
    3. Choose the amount that must remain after advertising. Break-even may be useful for diagnosis, but it is not the same as the return the business needs.
    4. Separate materially different economics. One average can conceal large differences among products, customers, and orders. Do not let high-margin sales make low-margin traffic look sustainable unless that blend is deliberate.

    This calculation gives AI a boundary grounded in your business. It does not make the platform profit-aware by itself.

    Give the bidding system values that survive a finance review

    An automated bidder can optimize only the value and events it receives. If every order is reported as equally valuable, it cannot infer that one product leaves ample margin while another barely covers fulfillment. If every submitted form is called a lead, it cannot know which inquiries can become revenue.

    For ecommerce campaigns

    Choose one value architecture and keep its logic intact:

    • Revenue values with margin-based targets: Report actual revenue, group products or campaign portfolios with reasonably similar economics, and calculate the target from the relevant margin. This preserves the familiar meaning of revenue ROAS.
    • Profit-proxy values: Pass a value that already reflects the economics you want the bidder to favor. Once you do that, stop interpreting the resulting return as revenue ROAS and do not reuse a target calculated on the assumption that conversion value equals revenue.

    The dangerous middle ground is to report revenue, use one blended margin across dissimilar products, and call the result profit optimization. That gives the automation a precise target built on an imprecise economic premise.

    For lead-generation campaigns

    Low-volume lead generation has a different problem: the final sale may arrive too late or too rarely to supply enough bidding signals. Accounts that cannot approach the working benchmark of about 30 conversions in 30 days can use carefully valued micro-conversions to expose progress through the funnel.

    A commercial shipping funnel provides a useful illustration of the structure:

    Those amounts are an example, not a template to copy. Your values should represent the relative economic worth of each stage. A form start is not $10 of booked revenue; it is a bidding signal. If starts are abundant and their assigned value is too generous, the system can hit its target by finding people who begin forms rather than prospects who become qualified opportunities.

    Check three things before using a value ladder:

    • Whether each stage predicts a more valuable business outcome, rather than merely being easy to track.
    • Whether one person can trigger several stages and, if so, whether the cumulative value reflects your intended bidding logic.
    • Whether the final qualified, proposed, and closed outcomes return to the ad platform so earlier assumptions can be compared with reality.

    When your sales system can provide lifecycle outcomes, send them back. Google and Microsoft support integrations with systems such as HubSpot for passing later-stage data into advertising workflows. The important part is not the connector itself. It is replacing a platform’s early proxy with the closest available version of actual customer value.

    Micro-conversions can help campaigns using conversion-based bidding, Performance Max, or AI Max obtain earlier signals. They can also make performance worse when their values are detached from qualification and revenue. More data is useful only when the data teaches the system the right preference.

    Choose how much control AI gets, one decision at a time
    A marketing analyst oversees a modular advertising console where some control units are automated and others remain under human control.

    You do not need one account-wide answer to whether you trust AI. Treat trust as permission granted for a specific job. A practical operating model separates AI-informed, AI-assisted, and AI-delegated work.

    Operating levelWhat AI doesWhat you retainGate before expanding
    AI-informedSurfaces search-term, variant, forecasting, or creative insightsYou choose and apply every campaign changeThe insight maps to a measurable business problem
    AI-assistedRuns a selected task such as bidding or asset generationYou define value, budget, scope, exclusions, and review criteriaTracking is reliable and the task has enough useful signal
    AI-delegatedOptimizes a bounded task end to endYou monitor economics, data quality, and exceptionsA controlled test beats the existing method on business outcomes

    This model prevents a common mistake: treating automated bidding, generated creative, and automated reporting as one indivisible package. They solve different problems and deserve separate permissions.

    Bidding needs signal density and economic constraints

    Bidding is often the easiest task to automate because the system can make more auction-time decisions than a person. It still needs enough useful events. Manual bidding can remain reasonable for low-volume campaigns and narrow industries where sparse conversion data gives automation little to learn from.

    Budget can become a hidden data constraint. One practical setup check uses a budget of at least 10 times the expected cost per click, based on the need to obtain roughly 10 engagements before depending on a conversion rate better than 10% for nonbranded search. Treat that as a diagnostic, not a universal spending rule. If the economics cannot support that traffic, changing the bid strategy will not repair the underlying volume problem.

    Search terms show where automation is buying growth

    Use the matched-by view in search-term reporting to inspect how often a keyword enters auctions through close variants. A high share of stable, cost-effective variants can indicate a useful auction entry point. Large swings in variant mix and bid cost can mean that the same keyword is pulling the campaign into materially different auctions.

    The action is not necessarily to bid on every variant. Choose the keyword or target that gathers enough relevant demand to produce learning, then exclude or restructure traffic that has a different economic purpose. Consolidation helps only when the combined searches deserve the same value signal and target.

    Creative and reporting still need human definitions

    AI-generated assets can increase the number of messages and placements available to a campaign. You still own brand fit, factual accuracy, offer terms, and the landing-page promise. A bidding system cannot compensate for creative that attracts the wrong intent.

    Reporting has a similar division of labor. Automation can assemble platform metrics, but you must translate them into revenue quality, margin, sales progression, and post-ad contribution. A report that ends at platform ROAS is incomplete when the decision in front of you is whether to invest more money.

    Run one test and judge it on post-ad contribution

    You do not have to delegate the whole account to learn whether automation can improve it. Compare the automated approach with the current strategy in a bounded campaign or portfolio where you can keep the economics and tracking definitions stable.

    1. Write the baseline before changing anything. Record spend, reported revenue or lead value, realized margin, qualified outcomes, and post-ad contribution. If some figures arrive later, identify that lag.
    2. State the hypothesis. Examples include finding more conversions above the profit floor, improving qualified opportunity volume within budget, or preserving contribution while increasing scale.
    3. Change one layer of control. Test bidding automation without simultaneously redefining every conversion, rebuilding all creative, and widening targeting. Otherwise, you will not know what caused the result.
    4. Freeze the value definitions during the comparison. If a tracking correction is unavoidable, mark the break and avoid treating the periods as directly comparable.
    5. Watch the traffic and outcome mix. Inspect search terms, product mix, funnel stages, and closed outcomes rather than accepting an aggregate return at face value.
    6. Expand only after the business metric improves. A platform target being met is not sufficient if margin mix, lead quality, or total contribution deteriorates.

    Read combinations of metrics, not isolated wins:

    • ROAS rises while post-ad contribution falls: inspect the product or customer mix and confirm that reported value still maps to the margin used in the target.
    • Conversion volume rises while qualified outcomes fall: reduce the influence of weak micro-conversions and return later sales stages to the platform.
    • Return per conversion rises while total contribution falls: the target may be restricting volume so severely that efficiency improved but the business result did not.
    • Volume and post-ad contribution improve together: broaden the test carefully while keeping the same value definitions and monitoring for mix changes.

    If it appears in your account, a Google Ads beta can translate an average profit margin into a suggested Target ROAS. It can also show weekly estimates for clicks, revenue, ad spend, and total profit as you change the target. Use those figures for scenario planning before applying a setting, not as evidence that the campaign will deliver the estimate.

    The calculator assumes that the reported conversion value is revenue and that the supplied average margin represents the campaign well. It does not directly make Google Ads optimize bids for profit. Your value design, segmentation, cost completeness, and later outcome imports still determine whether the target represents the business you actually have.

    Key takeaways

    • Calculate a break-even ROAS from the pre-ad margin when conversion value represents revenue, then add the post-ad contribution the business needs.
    • Do not apply a revenue-based Target ROAS formula to conversion values that already represent profit proxies or weighted lead values.
    • Use micro-conversions only when their relative values reflect progress toward qualified revenue, and replace proxies with offline outcomes when possible.
    • Grant AI control by task: insight first, selected automation second, and end-to-end delegation only after a bounded test.
    • Judge automation on post-ad contribution and outcome quality, not platform ROAS or conversion count in isolation.

    Your next step is small: take one active campaign, write down what its conversion value actually represents, calculate its economic floor, and compare that floor with the target now in the platform. Any gap you find is the first profitability problem to solve before asking AI to spend more.

    References


  • Political Campaign AI Spending: Where the 2026 Money Goes

    Political Campaign AI Spending: Where the 2026 Money Goes

    If you are building, buying, or measuring AI for a 2026 political campaign, the biggest budgeting mistake is treating AI as a single technology line. The headline total combines tools, AI-assisted work, automated outreach, and the media used to distribute AI-influenced advertising. A campaign can therefore spend little on software while creating a large AI-related footprint.

    You need to separate cost, operational use, and public exposure before deciding whether your campaign is underinvesting, overspending, or simply counting differently. That distinction turns an eye-catching market estimate into a budget you can actually manage.

    The $899 million headline is not a software market size

    Political campaigns, party committees, and outside groups are projected to spend $899 million on AI during the 2026 cycle. That would be 2.8 times the 2024 total and about 22 times the 2022 total. It is also equivalent to roughly 8.5% of the projected $10.6 billion in overall political advertising for the cycle.

    But $899 million does not mean campaigns are buying $899 million of AI software. The estimate includes three materially different forms of spending:

    • Direct payments for AI vendors, platforms, and general-purpose subscriptions.
    • The portion of production, targeting, fundraising, and outreach costs attributed to AI.
    • Media dollars placed behind advertisements generated or enhanced with AI.

    Those categories answer different questions. Direct vendor spending helps you assess the technology market. AI-attributable workflow spending tells you how deeply campaigns are using the technology. Media placement measures how much paid distribution sits behind AI-influenced assets. Combining them is useful for estimating AI’s overall campaign footprint, but it cannot tell you what AI products earned or how much a campaign saved.

    The total is also a projection, not a final audited tally. Its methodology covers more than 41,000 federal and state disbursement records, platform advertising libraries, and 57 consultant and vendor interviews, with activity tracked through September 24 and modeled through Election Day on November 3. Treat it as a structured market estimate. Do not use it as proof that every campaign classifies AI spending the same way.

    Before comparing your own budget with the market, decide which question you are asking. If you want to know what your technology stack costs, exclude media. If you want to understand operational adoption, include the AI-assisted share of labor and services. If you are assessing voter exposure, include distribution but keep it separate from production. One blended figure cannot answer all three questions.

    Distribution and outreach absorb more money than AI tools

    A small AI workstation connects through branching light trails to many phones, screens, mail pieces, and canvassing devices.

    The projected category mix shows where AI is entering campaign operations. Media placement behind AI-generated or AI-enhanced advertising is the largest category. General-purpose subscriptions are the smallest. That gap matters: the visible scale of political AI is being driven more by amplification and workflow adoption than by the price of access to a model.

    Spending categoryProjected 2026 spendingShare of totalGrowth versus 2024Question your budget should answer
    Media placement behind AI-generated or AI-enhanced ads$237 million26.4%3.3xCan you connect each placement to a specific asset, audience, and outcome?
    AI voter outreach$173 million19.2%3.0xWhen does an automated interaction move to a trained person?
    AI fundraising optimization$147 million16.4%2.4xAre you measuring net fundraising performance rather than message volume?
    AI audience modeling and targeting$131 million14.6%1.8xDoes the model improve decisions against a defined non-AI baseline?
    AI creative production$98 million10.9%4.7xWho verifies facts, voices, likenesses, and required disclosures before release?
    AI-assisted media buying fees$65 million7.2%2.8xCan you separate the service or algorithmic fee from the underlying media spend?
    General-purpose AI tools and subscriptions$48 million5.3%4.0xWho controls accounts, data access, retention, and offboarding?

    Creative production is growing fastest at 4.7 times its 2024 level, but it still accounts for only 10.9% of projected 2026 AI spending. Audience modeling is growing slowest at 1.8 times because it already had a meaningful base before the recent expansion of generative tools. Fast growth, large spending, and operational maturity are therefore three different signals.

    Do not judge an AI program by the number of assets it produces. A campaign can generate hundreds of variants without improving persuasion, fundraising, or contact quality. Measure the result associated with each workflow: approved production time for creative, net revenue for fundraising, successful contacts and escalations for outreach, incremental performance for targeting, and cost per desired action for media. Keep output volume as a diagnostic metric, not the primary success metric.

    Adoption also cuts across party lines. Republican candidates, parties, and aligned outside groups account for a projected $415 million, compared with $374 million on the Democratic side. Outside groups allocate a larger portion of their budgets to AI than candidates and parties, with Republican-aligned groups reaching 10.2%. Party affiliation is a poor proxy for AI maturity; spender type and workflow are more useful.

    Race size, geography, and timing change the right strategy

    Absolute spending concentrates in federal contests. House races account for a projected $305 million and Senate races for $286 million, together representing 65.7% of campaign AI spending. Yet smaller races use AI more intensively relative to their available media.

    Local and judicial races have AI-generated or AI-enhanced elements in 16.2% of ads, and AI represents 13.8% of their media budgets. State legislative races follow at 14.7% of ads and 12.4% of media budgets. House races are lower on both measures, at 9.2% and 8.9%, despite carrying the largest dollar total. Ballot measures sit at the other end, with AI elements in 6.3% of ads and 5.2% of media budgets.

    This is a denominator problem that can distort competitive analysis. A small campaign may look more AI-intensive because automation replaces work it could not otherwise afford. A large federal campaign can spend far more dollars while AI remains a smaller percentage of a much larger operation. Compare campaigns on both absolute spending and share of budget. Using only one will misclassify the smaller operation or obscure the larger one’s reach.

    Geography produces another concentration effect. The ten highest-spending states account for $460.1 million, or 51.2% of the projected total. Maine reaches $25.09 per registered voter, almost three times the next-highest figure in that group, as a competitive Senate race concentrates spending across a relatively small electorate. A national average will not tell you what competitive pressure looks like in an individual state.

    Disclosure practices vary just as sharply. Among the ten highest-spending states, the recorded share of AI ads carrying a disclosure ranges from 29% in Georgia to 78% in California. Across states with AI disclosure laws, 64% of AI ads carried a disclosure, versus 27% in states without one. That relationship indicates that legal requirements affect behavior, but it is not a substitute for a state-by-state compliance review.

    Build a jurisdiction field into the asset record before production begins. Record where the asset will run, what was generated or materially altered, which disclosure decision was made, who approved it, and which final version entered distribution. When the applicable rule is unclear, hold the asset and ask qualified election counsel. Retrofitting a disclosure after placement creates avoidable legal, financial, and reputational exposure.

    Timing is equally important. At the aligned one-month point, cumulative 2026 AI spending reaches $612 million, with a projected $899 million by Election Day. Spending within each cycle has roughly doubled every three months as Election Day approaches. The final month is projected to contain 32% of 2026 spending, below the 37% final-month share in 2024 because outreach and fundraising automation moved earlier to reach early voters.

    Do not postpone governance until the spending ramp. The final weeks are when review time contracts, asset volume rises, and media decisions become harder to reverse. Approve vendors, data permissions, escalation paths, disclosure rules, and evidence requirements before the high-volume period. The late-cycle budget should scale a controlled workflow, not finance the first real test of one.

    Build an AI budget that can survive scrutiny

    Transparent budget containers, coins, a magnifying glass, a locked data box, and a balance scale are arranged on an orderly campaign planning desk.

    A defensible AI budget starts with a ledger, not a list of tools. The cost of an AI program can include software, implementation, data work, human review, compliance, vendor services, and media. If you record only subscription invoices, you will understate the program. If you label every placement behind an AI-assisted asset as technology spend, you will lose sight of what the technology itself costs.

    1. Choose the unit of analysis. State whether you are tracking direct vendor cost, AI-enabled workflow cost, or media exposure. Maintain all three if leadership needs a complete view, but never merge them without labels.
    2. Classify spending at the invoice or line-item level. Assign every item to creative production, outreach, fundraising, targeting, media-buying services, general tools, or media placement. Prevent one invoice from disappearing into a broad digital-services account.
    3. Attach each cost to an accountable workflow. Record the race, jurisdiction, vendor, campaign owner, data used, synthetic or altered elements, human reviewer, approval status, and distribution channel.
    4. Set the baseline before the pilot. Compare the AI-enabled workflow with the existing process on the outcome that matters. Time saved is meaningful for production; it is not evidence of better persuasion. Message volume is meaningful for operations; it is not evidence of better fundraising.
    5. Create a release gate. Require factual verification, permission checks for voice and likeness, disclosure review, accessibility review where relevant, security review, and named human approval before an asset or automated interaction goes live.
    6. Scale only the validated component. If a creative workflow saves time but targeting does not improve performance, scale production rather than buying a larger bundled program. A vendor relationship does not have to expand as one indivisible unit.

    Your ledger should let a reviewer move in both directions: from an invoice to the assets and outcomes it funded, and from a public asset back to its production record, approval, disclosure decision, and media spend. That traceability is more useful than a generic AI policy because it shows how the policy operated in a specific case.

    If you publish or optimize political content

    More campaign investment means more creative variants, automated contacts, and paid distribution. It does not create independent corroboration. Treat campaign-generated material as a claim that requires verification, even when the asset looks polished or appears repeatedly across channels.

    • Put the publication or revision date, jurisdiction, race, candidate or issue, and sponsor context where a reader can see them.
    • Separate campaign assertions from independently verified facts, and link to the strongest available primary evidence for factual claims.
    • Keep the original approved asset and a correction history so changes do not erase provenance.
    • Use structured data only for information visible on the page. Markup can clarify entities and dates, but it cannot turn an unsupported claim into reliable evidence.
    • Do not present repeated synthetic content as multiple independent confirmations. Distribution volume and source diversity are not the same thing.

    These practices help human readers, search systems, and AI answer engines distinguish what happened, who is making a claim, when it applies, and which evidence supports it. They do not guarantee visibility or favorable treatment, but they reduce ambiguity at the point where political information is most likely to be compressed into a short answer.

    Key takeaways

    • The projected $899 million total measures a broad AI-related campaign footprint, not just software purchases or vendor revenue.
    • Media placement is the largest category at $237 million, while general-purpose tools and subscriptions account for $48 million.
    • Creative production is growing fastest, but output volume alone does not establish campaign impact.
    • Federal races lead in total dollars, while local, judicial, and state legislative races use AI more intensively relative to their media.
    • Disclosure practices differ substantially by state, so every asset needs a jurisdiction-specific review and an auditable approval record.
    • Budgeting should separate direct technology cost, AI-enabled workflow cost, and paid exposure, then connect each to a defined outcome.

    Start by exporting every AI-related expense and reclassifying it into technology, workflow, or distribution. Then choose one high-exposure workflow, give it a measurable baseline and a named approval owner, and resolve its disclosure path before shifting more money into it. That is how you turn a market trend into a campaign decision you can explain, test, and defend.

    References


  • Google Ads Automation and Localization Without Losing Control

    Google Ads Automation and Localization Without Losing Control

    If you manage Google Ads, your website is becoming part of the campaign-building system. An offer published on a page may become a promotion asset, while an existing Search campaign may become the template for a new language and market.

    That can remove hours of repetitive setup. It can also scale an expired discount, awkward translation or unsuitable budget before anyone notices. The right response is not to reject automation. It is to put a clear approval boundary between what Google can generate and what your business is prepared to promise and spend.

    Separate the two automations before setting policy

    Automated promotions and campaign localization solve different problems. They also fail differently. Treating them as one generic AI feature makes it harder to assign the right reviewer and control.

    WorkflowWhat Google createsInitial scopePrimary control
    Automated promotionsA promotion asset based on an eligible offer found on your websiteSearch and Performance Max campaigns with linked location assets and no promotion asset already attachedThe account-level Automated Promotions setting, followed by a review of assets that serve
    AI campaign localizationA new, independent campaign with localized ads, assets and keywordsEligible U.S. English Search campaigns translated into supported languages and markets during the betaLanguage, landing-page and commercial review before the localized campaign goes live

    The promotion workflow extracts a commercial claim that already exists. The localization workflow transforms an existing campaign for a different audience. The first can misstate an offer; the second can reproduce a sound campaign in a market where its language, intent or economics no longer fit.

    A useful account policy is simple: automation may identify, translate and assemble; a named owner must still authorize the promise, the audience and the spend.

    Audit your website before automated promotions serve

    A review team inspects a website page for expired dates, mismatched prices, unavailable products, and broken links before automation.

    Starting Oct. 12, eligible advertisers may be enrolled automatically. That changes the default risk. Doing nothing is no longer necessarily the same as declining the feature.

    Your first decision is whether the account should participate at all. Keep it enabled when public offers are current, clearly qualified and consistently honored online and in stores. Disable it when promotions require case-by-case approval, depend on complex eligibility rules or frequently remain visible after they expire.

    1. Open the account’s automated asset settings and find Automated Promotions. Record whether it is on or off and who approved that choice.
    2. Inventory public pages that mention discounts, coupon codes, bundles, free items or limited offers. Include store pages when location assets connect campaigns to physical locations.
    3. Make each offer understandable without surrounding marketing copy. State what qualifies, what the customer receives and, where applicable, when and where the offer is valid.
    4. Reconcile the page with the real transaction. Pricing, eligibility and brand wording should agree with the checkout flow, sales process and in-store terms.
    5. After an automated promotion begins serving, inspect it in the Assets section. An asset that has not received impressions will not appear there, so an empty view does not prove that the account is opted out.

    That last distinction matters. The setting tells you whether Google has permission to create automated promotions. The Assets view tells you what has actually accumulated impressions. Check both rather than using one as a proxy for the other.

    If you opt out, use the explicit account-level control. Do not rely on incomplete pages, ambiguous offer wording or the presence of a manually managed asset as an informal safeguard. Automated Promotions can be turned off in automated asset settings, which gives the account team an auditable decision instead of an accidental outcome.

    Launch localization as a new market, not a translation task

    The localization beta can turn one eligible Search campaign into a separate campaign for another language and location. The original campaign remains unchanged. That independence is useful, but it does not make the new campaign commercially ready.

    1. Choose a parent campaign worth reproducing. Fix known targeting, messaging or landing-page problems before translation, or the new campaign will begin with the same structural weaknesses.
    2. Select the exact target language and location. A language label is not a market strategy: Spanish for Spain and Spanish for Latin America and the Caribbean are available as distinct variants in the beta.
    3. Give the AI explicit language rules. Tell it which brand names, product names and technical terms must remain unchanged, and specify whether the voice should be formal or conversational.
    4. Review every campaign component, not just the headlines. The workflow can localize headlines, descriptions, sitelinks, callouts and keywords.
    5. Choose the landing-page method deliberately. You can install a Google-provided JavaScript snippet that dynamically translates page text for visitors from localized ads, or update the campaign URLs to point to pages you already maintain in the target language.
    6. Require a human language and market review. Use the original, localized version and English back-translation shown side by side to check meaning, then ask a fluent reviewer to assess naturalness, search intent, cultural fit and brand terminology.
    7. Reset the economics. Budgets and bids are copied from the original campaign without automatic currency conversion or exchange-rate adjustment. Do not approve launch merely because those fields are populated.

    The landing-page choice deserves particular care. Dynamic translation is a practical route when the underlying offer and customer journey are genuinely the same. A maintained local page is the stronger option when prices, availability, delivery terms, legal wording or conversion steps differ by market. In either case, review the page as the visitor will see it after clicking the localized ad.

    Images also need a separate check. When an image contains text, the workflow can remove the original wording and use the translation as supplemental text assets. Do not assume the output will simply be the same image with perfectly replaced lettering. Preview the complete creative combination and confirm that the visual still makes sense without its original embedded message.

    The beta supports U.S. English Search campaigns localized into Dutch, French, Canadian French, German, Italian, Polish, Brazilian Portuguese, European Portuguese, Spanish for Spain and Spanish for Latin America and the Caribbean. Google plans to add languages by the end of 2026 and later extend localization to Performance Max. Treat that as a roadmap, not as a capability your current launch can depend on.

    Use one release gate for assets, language and money

    Three reviewers check advertising assets, localized language elements, and budget tokens at a single campaign release gate.

    The most reliable control is a short release record shared by the website owner, campaign manager and market reviewer. It should force a yes-or-no decision on the places where automation cannot judge your business obligations.

    • Commercial truth: Is the promoted price or benefit currently available, and will every customer who meets the stated conditions receive it?
    • Qualification: Are exclusions, dates and location restrictions consistent across the ad asset, landing page, checkout or sales process, and physical store where relevant?
    • Language: Has a fluent reviewer approved the customer-facing wording rather than relying only on the English back-translation?
    • Search intent: Do the localized keywords represent how people in that market look for the offer, not merely a literal rendering of the parent keywords?
    • Landing experience: Does the visitor remain in the intended language through the meaningful conversion steps?
    • Economics: Have the copied budget and bids been reviewed for the target market instead of accepted as inherited defaults?
    • Ownership: Is one person responsible for pausing the asset or campaign when an offer, page or market condition changes?

    Use event-based reviews rather than a vague instruction to monitor regularly. Reopen the record when an offer starts or ends, a price or landing page changes, an automated asset first receives impressions, a new localized campaign is generated, or its budget and bids are changed.

    After launch, judge the localized campaign on its own market economics. It is an independent campaign, so the parent campaign’s historical success is context, not proof. For automated promotions, compare the served asset with the live offer page and the transaction customers actually receive. The purpose of monitoring is not just to catch strange wording; it is to catch a broken commercial promise.

    Key takeaways

    • Check the account-level Automated Promotions setting before Oct. 12; eligible advertisers may be enrolled without making an affirmative choice.
    • Treat every public offer page as potential campaign input, especially when Search or Performance Max campaigns use linked location assets.
    • Do not use an empty Assets view as proof that automation is disabled; unserved assets do not appear there.
    • Review localized campaigns as independent market launches, including keywords, creative, landing pages, language quality and cultural fit.
    • Replace copied budgets and bids with a deliberate market decision because the localization workflow does not perform currency or exchange-rate adjustments.

    Your next step is small and concrete: open one eligible account, document its automation setting, then choose one live offer and one possible target market to run through the release gate. That will expose missing ownership and inconsistent inputs before automation exposes them to customers.

    References


  • A Practical Framework for AI Advertising Campaign Reporting

    A Practical Framework for AI Advertising Campaign Reporting

    Your AI advertising dashboard can be numerically correct and still lead you to the wrong decision. This happens when it collapses four different things into one performance label: what delivered, what the platform optimized for, what it attributed, and what its budget tools are allowed to use.

    You need a reporting system that keeps those layers visible. The framework below will help you turn campaign data into defensible actions without letting an AI-generated summary hide attribution limits, product eligibility problems, or gaps between web and app measurement.

    Key takeaways

    • Show the selected optimization goal beside every supporting conversion. A reported outcome is not necessarily an outcome the campaign pursued.
    • Label each conversion separately as reportable, used for optimization, and eligible for budgeting. Those are three different permissions.
    • Treat attribution as a rule for assigning credit, not proof that an ad caused the outcome.
    • Put product rejections, review pauses, identity changes, and measurement changes on the campaign timeline so operational interruptions are not mistaken for performance failures.
    • Let AI explain a governed dataset. Keep metric definitions, joins, formulas, and eligibility rules deterministic and reviewable.

    Build every report around one decision

    A dashboard built to answer every possible question usually answers none of them clearly. The person deciding whether to scale a campaign needs a different view from the person diagnosing a rejected product or reconciling app purchases. Start with the decision, then select the data required to make it.

    A useful report header should identify:

    • Decision: Scale, hold, reduce, diagnose, or repair.
    • Scope: Account, campaign, ad group, product, channel, market, and customer surface.
    • Primary outcome: The conversion event selected as the optimization goal.
    • Supporting outcomes: Other attributed events that help you judge lead quality, downstream value, or progression through the journey.
    • Comparison: The period, segment, or campaign being used as the reference point.
    • Measurement context: Attribution model, attribution window, currency, time zone, data freshness, and known coverage gaps.
    • Next action: The proposed change, its owner, and the condition that would reverse or confirm it.

    Do not force every conversion into a single blended total. A campaign optimized for one event can now expose other attributed events through the public ChatGPT Ads Insights API. That additional visibility is useful, but it does not change the campaign’s selected goal.

    Keep the primary outcome and supporting outcomes in separate columns. If the optimization goal improves while a downstream purchase metric weakens, you have a quality question to investigate. If purchases improve while the optimization goal is unchanged, you have a useful signal, but not automatic proof that the campaign caused the improvement.

    Separate delivery, eligibility, outcomes, and attribution

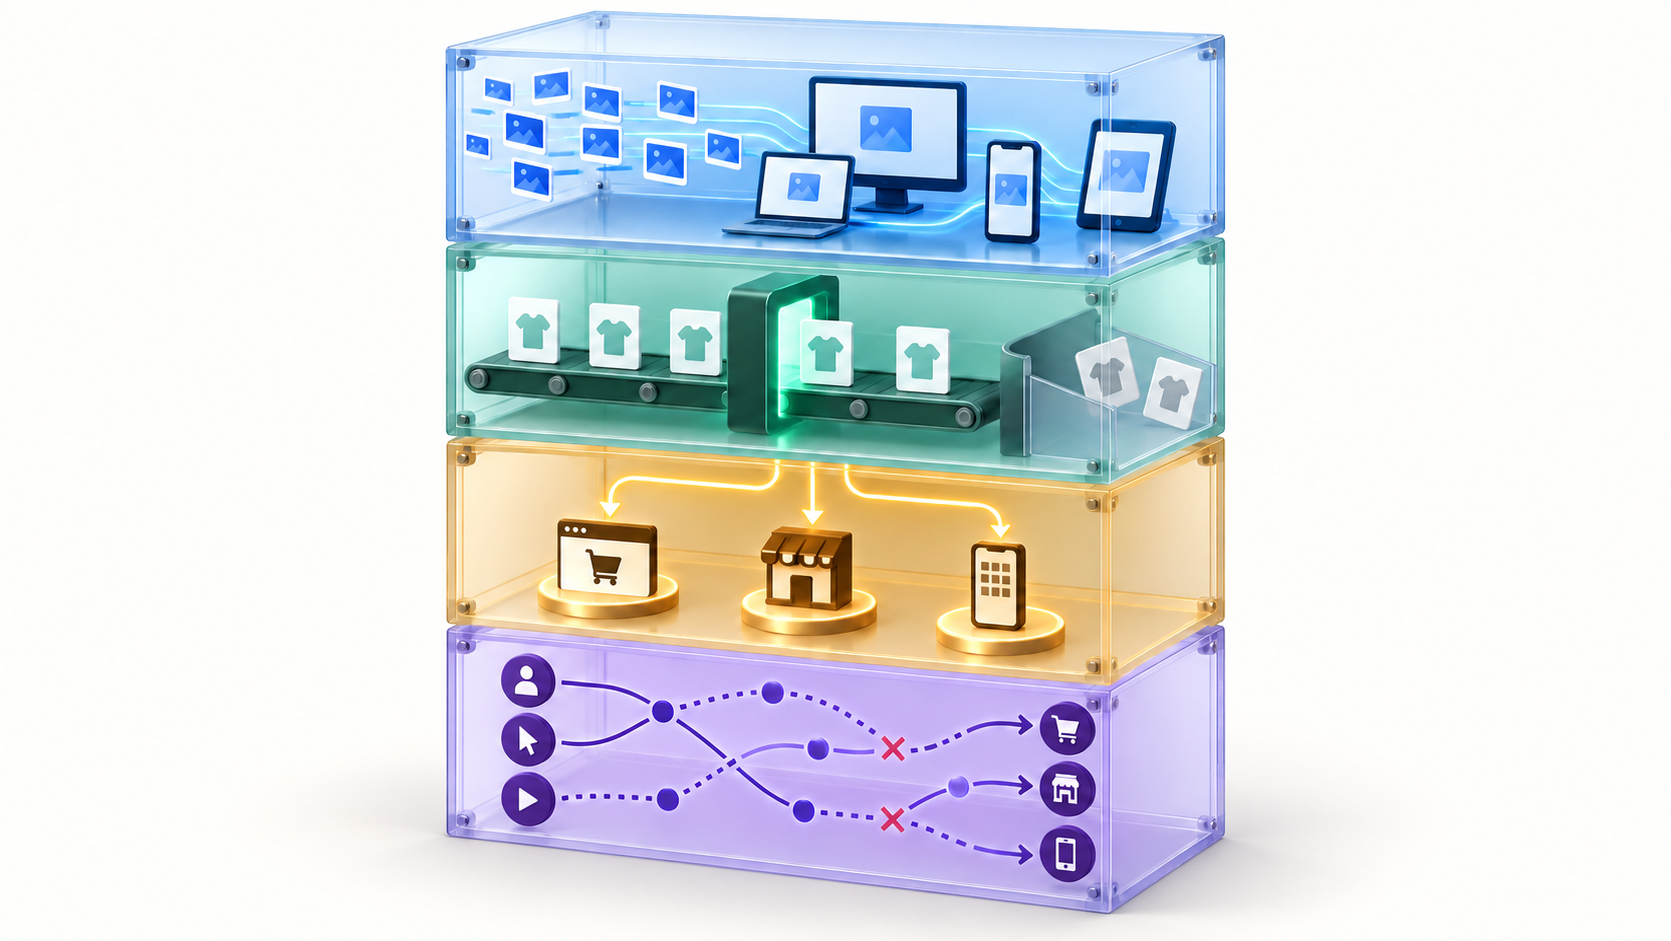
    Four transparent stacked chambers separately depict ad delivery, product eligibility, customer outcomes, and attribution paths.

    A trustworthy report lets you locate the stage at which performance changed. Use distinct reporting layers instead of dropping every metric into one scorecard.

    Reporting layerQuestion it answersWhat to includeDecision it supports
    DeliveryDid the campaign reach and engage its available audience?Platform delivery metrics at the campaign, ad group, and product levelsInvestigate distribution, targeting, serving, or creative exposure
    CostWhat did that delivery consume?Spend and consistently calculated efficiency metricsCheck financial guardrails and locate changes in cost
    Product eligibilityCould each advertised product serve?Feed item, review state, rejection reason, and status-change timeRepair catalog or policy issues before judging demand
    OutcomesWhich conversion events received credit?Optimization goal and supporting attributed events, kept separateEvaluate the chosen objective and inspect downstream quality
    Attribution and governanceUnder which rules and account conditions were results recorded?Model, window, surface, naming changes, review pauses, and measurement changesCompare compatible data and explain discontinuities

    ChatGPT Ads reporting can supply delivery, cost, product, and attributed conversion metrics. Preserve those metric families as separate datasets or clearly identified groups in your reporting model. That makes it possible to tell the difference between a serving problem, a cost problem, a catalog problem, and a conversion problem.

    Product campaigns need an eligibility layer because a rejected item did not receive the same opportunity as an approved item. ChatGPT Ads now exposes product review status and individual rejection reasons. Bring those fields into the report before calculating product-level winners and losers. Otherwise, you may penalize an item for not converting when the actual issue was that it could not serve.

    Operational changes also belong on the timeline. ChatGPT Ads separates the internal account name, public brand name, and registered legal name. A public brand-name change can pause serving during review, while a legal-name change can restart business review and may also interrupt delivery. Record those identity and review events as annotations. A delivery gap during a review is an operational interruption, not evidence that the audience rejected the campaign.

    Treat reporting, optimization, and budgeting as separate controls

    Every conversion in your measurement plan needs three explicit flags:

    • Reportable: Can the event appear in performance or attribution reporting?
    • Optimization-enabled: Is the campaign actively trying to generate this event?
    • Budget-eligible: Can an automated or cross-channel budgeting system use this event when allocating money?

    Never infer the second or third flag from the first. The ChatGPT Ads Insights API can return attributed events beyond the selected optimization goal. Google can include app conversions in performance reporting, attribution analysis, and attribution models while its cross-channel budgeting features remain limited to web conversions. In both cases, visibility is broader than at least one action layer.

    Use supporting conversions without changing the meaning of success

    Supporting conversions can reveal what happens after the event selected for optimization. They are especially useful when the selected event represents an earlier step in the customer journey. Keep them in the report, but preserve their role.

    For each event, store its business definition, customer surface, reporting status, optimization status, budgeting status, and attribution configuration. If one of those fields is unknown, label it unknown. Do not allow the reporting layer or an AI assistant to silently convert an unknown into a yes.

    Keep a visible boundary between web and app measurement

    Google’s expanded conversion reporting can bring app activity into broader performance and attribution views. Advertisers can also configure attribution for app conversions independently from other conversion types. However, availability may still vary by Google Analytics property, and app outcomes are not yet included in cross-channel budgeting.

    This can make a report look unified even when the underlying controls are not. Add a surface field to every conversion row and display web and app subtotals before showing a combined figure. Also record the attribution setting applied to each surface. A combined total is decision-safe only when you can explain what was counted, how credit was assigned, and whether the downstream tool can act on all of it.

    An AI-generated recommendation should never say that a budget allocator will react to app conversions merely because those conversions appear in the same report. It can recommend a manual review of the evidence, but it must preserve the platform’s actual budgeting boundary.

    Build a reporting pipeline that AI can audit

    Transparent data channels pass advertising events through validation and lineage checks before an AI system presents evidence to a human reviewer.

    Automation makes governance more important, not less. Spreadsheet uploads can create multiple ChatGPT product campaigns and ad groups while generating ad templates automatically. Set naming rules and persistent identifiers before a bulk launch so the resulting scale does not produce an untraceable reporting structure.

    1. Create a conversion registry. Give every event a stable identifier, business meaning, customer surface, owner, reportable flag, optimization flag, budget-eligibility flag, and attribution configuration.
    2. Define a campaign taxonomy. Standardize the fields used for market, product group, objective, funnel stage, audience, and experiment. Keep platform IDs even when human-readable names change.
    3. Extract raw data without rewriting its meaning. Preserve native platform fields, IDs, statuses, and timestamps before creating normalized views.
    4. Normalize context explicitly. Apply consistent date boundaries, time zones, currencies, and metric formulas. Retain the raw values so transformations can be audited.
    5. Join operational status data. Add product review states, rejection reasons, account reviews, serving pauses, feed changes, and measurement-setting changes to the campaign timeline.
    6. Reconcile before interpreting. Compare API totals with the platform interface using the same dates, filters, attribution settings, time zone, and account scope. Investigate differences rather than hiding them in a blended total.
    7. Calculate metrics deterministically. Use documented formulas for rates, costs, and rollups. Do not ask a language model to perform the authoritative aggregation from loosely formatted exports.
    8. Generate the narrative last. Give AI the reconciled table, metric definitions, change log, and decision question. Require every recommendation to point back to visible evidence.

    Give the AI a narrow reporting contract

    A useful reporting assistant should distinguish observation from interpretation. Its instructions should require it to use only supplied data, preserve platform definitions, identify missing fields, avoid causal claims from attributed conversions, and state when a proposed action depends on an unverified setting.

    Require each generated finding to contain:

    • Observation: The measured change, including its scope and comparison.
    • Evidence: The exact metrics, dimensions, statuses, and time period supporting the observation.
    • Interpretation: A plausible explanation clearly labeled as an inference.
    • Measurement limits: Attribution, availability, eligibility, or data-quality constraints that could change the reading.
    • Action: A reversible next step tied to the original decision.
    • Validation condition: What must be checked before the recommendation is implemented or expanded.

    This structure prevents polished prose from outrunning the evidence. Attribution tells you how a model assigned credit; it does not establish causal lift. When causality matters, the report should identify the need for an appropriate experiment rather than dressing an attribution result up as proof.

    Run these checks before automating recommendations

    • API and interface totals reconcile under identical filters and settings.
    • Every conversion has separate reporting, optimization, and budgeting flags.
    • Web and app events retain their surface and attribution configuration.
    • Rejected, pending, and approved products are distinguishable.
    • Serving pauses and account, brand, feed, goal, or attribution changes are annotated.
    • Missing and unavailable values remain distinct from zero.
    • Every generated recommendation cites the rows and definitions it relies on.
    • A person with budget authority reviews consequential changes before they are applied.

    Start with one active campaign and complete the conversion registry before rebuilding the dashboard. Put the business meaning, surface, reporting status, optimization status, budget eligibility, and attribution setup beside every outcome. If you cannot complete those fields, the campaign is not ready for automated interpretation. Fix that boundary first; the reporting interface can follow.

    References


  • How to Create Google Veo Video Ads for PMax and Demand Gen

    How to Create Google Veo Video Ads for PMax and Demand Gen

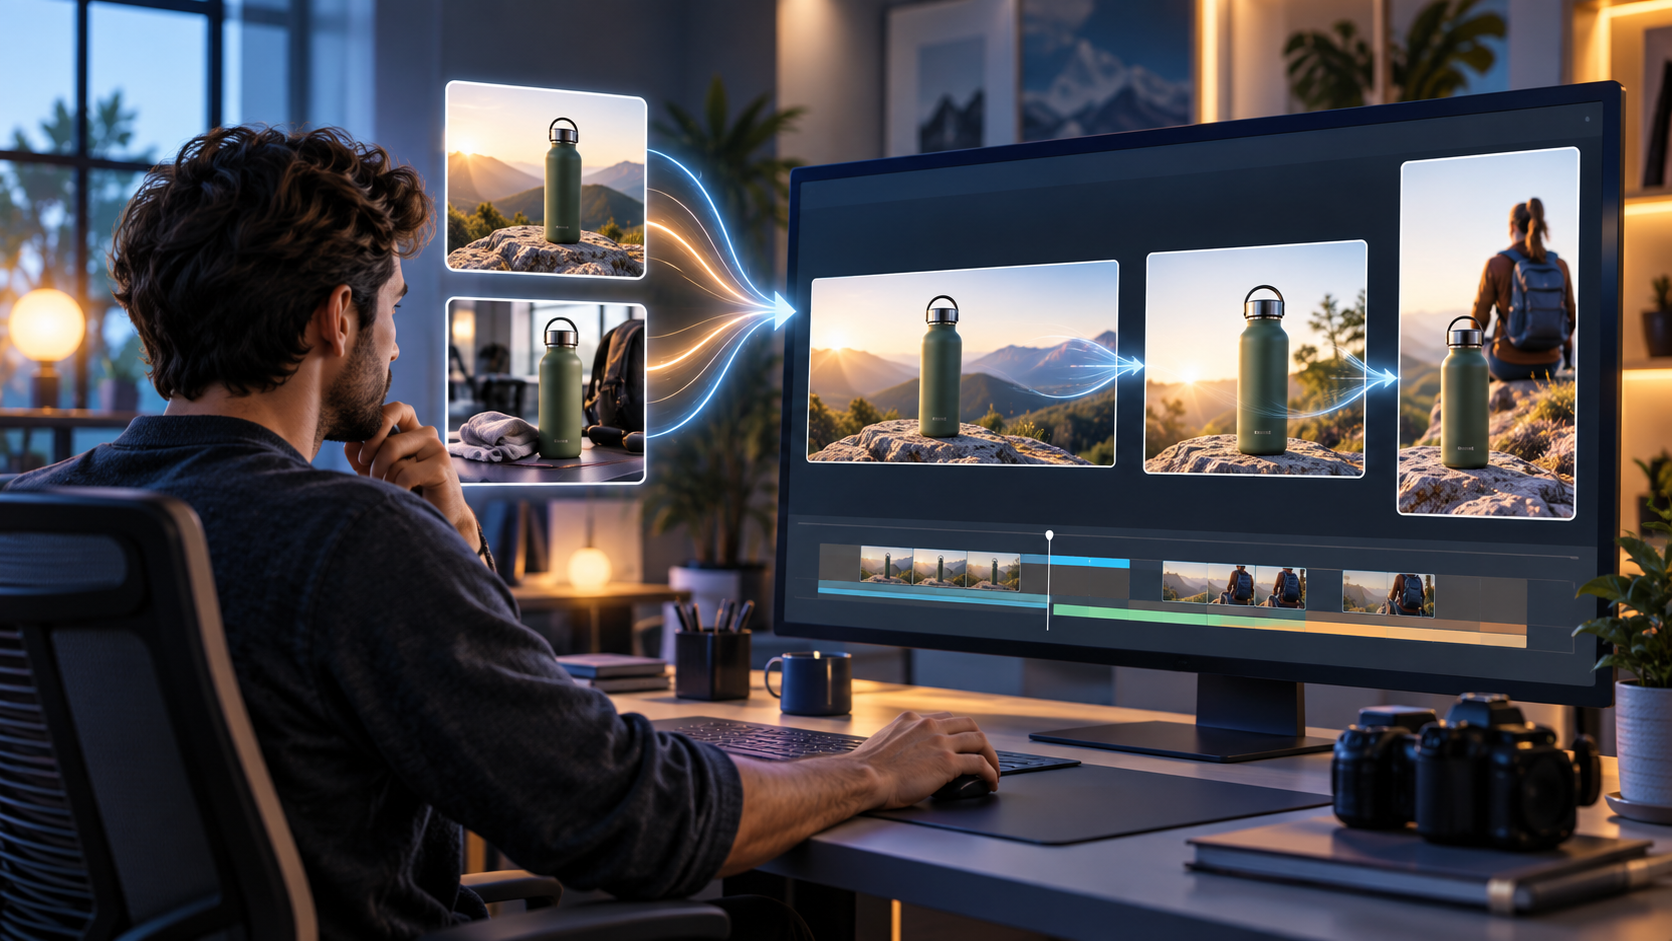
    If your PMax or Demand Gen campaign has strong still images but little usable video, you no longer need to make a full production the first step. Inside Google Ads, Veo can turn two image assets into a five- or 10-second video, giving you a faster way to add short-form creative or refresh assets that have started to wear out.

    That speed helps only when you give the tool a focused job. Veo can animate your images, assemble two scenes and apply text, but it cannot decide which benefit matters, repair a weak offer or make mismatched images tell a coherent story. Treat it as a rapid production layer: you supply the idea, evidence and brand discipline.

    Key takeaways

    • Use Veo when you have high-resolution product or service images but need a quick, short-form video asset for PMax or Demand Gen.
    • Give the video one job and organize its two scenes as a simple sequence. Ten seconds is not enough for a product tour, company introduction and offer explanation at the same time.
    • Produce the same concept in horizontal, vertical and square formats so the campaign has an appropriate asset for more available surfaces.
    • Use the two 30-character headlines for the benefit, qualification or next action. Your business name already appears first, so repeating it consumes scarce space.
    • Review results at the asset level, but do not let direct conversions become the only verdict. Delivery, engagement, clicks, website engagement and view-through conversions can reveal different parts of the asset’s contribution.

    Design one idea that fits inside ten seconds

    Veo’s time limit is a useful creative constraint. Before you open Asset Studio, complete this sentence: “After watching, the right customer should understand ______.” If you need more than one clause to fill the blank, the concept is probably too broad.

    A short Veo asset can introduce one product benefit, make a static product image more noticeable, connect a problem image to a result image or carry a familiar campaign message into a video format. It is less suitable when the sale depends on a detailed demonstration, several conditions, an extended narrative or a person speaking directly to the viewer.

    Build a two-scene bridge

    The selected images appear one after the other, so their relationship has to make sense before any animation is added. Choose one of these simple structures:

    • Context to product: Establish the setting in scene one, then make the product the clear focal point in scene two.
    • Problem to result: Show a recognizable condition first and the completed outcome second. Use this only when the result is accurate and supported by the landing page.
    • Wide view to detail: Begin with the complete product or service result, then move to the feature that explains the benefit.
    • Product to action: Use the first scene to establish what is being offered and the second to support the next step with the offer or call to action.

    The second image should resolve or deepen the first, not merely replace it. Two unrelated hero images may each look polished while producing a video with no narrative movement. Put them side by side before uploading them and ask whether the sequence is understandable as two static frames. If it is not, motion will not fix it.

    Know when the format is the wrong fit

    The image-to-video route in Google Ads does not accept images containing a face. Product images, packaging, environments, interfaces and service-result images are therefore more practical inputs than portraits or testimonial frames.

    Do not contort a people-led idea to fit that restriction. If credibility depends on a customer, creator, employee or demonstrator appearing on screen, use a production method designed for that concept. Veo is valuable because it removes production friction from suitable ideas, not because every idea should be forced through it.

    Prepare source images for all three video formats

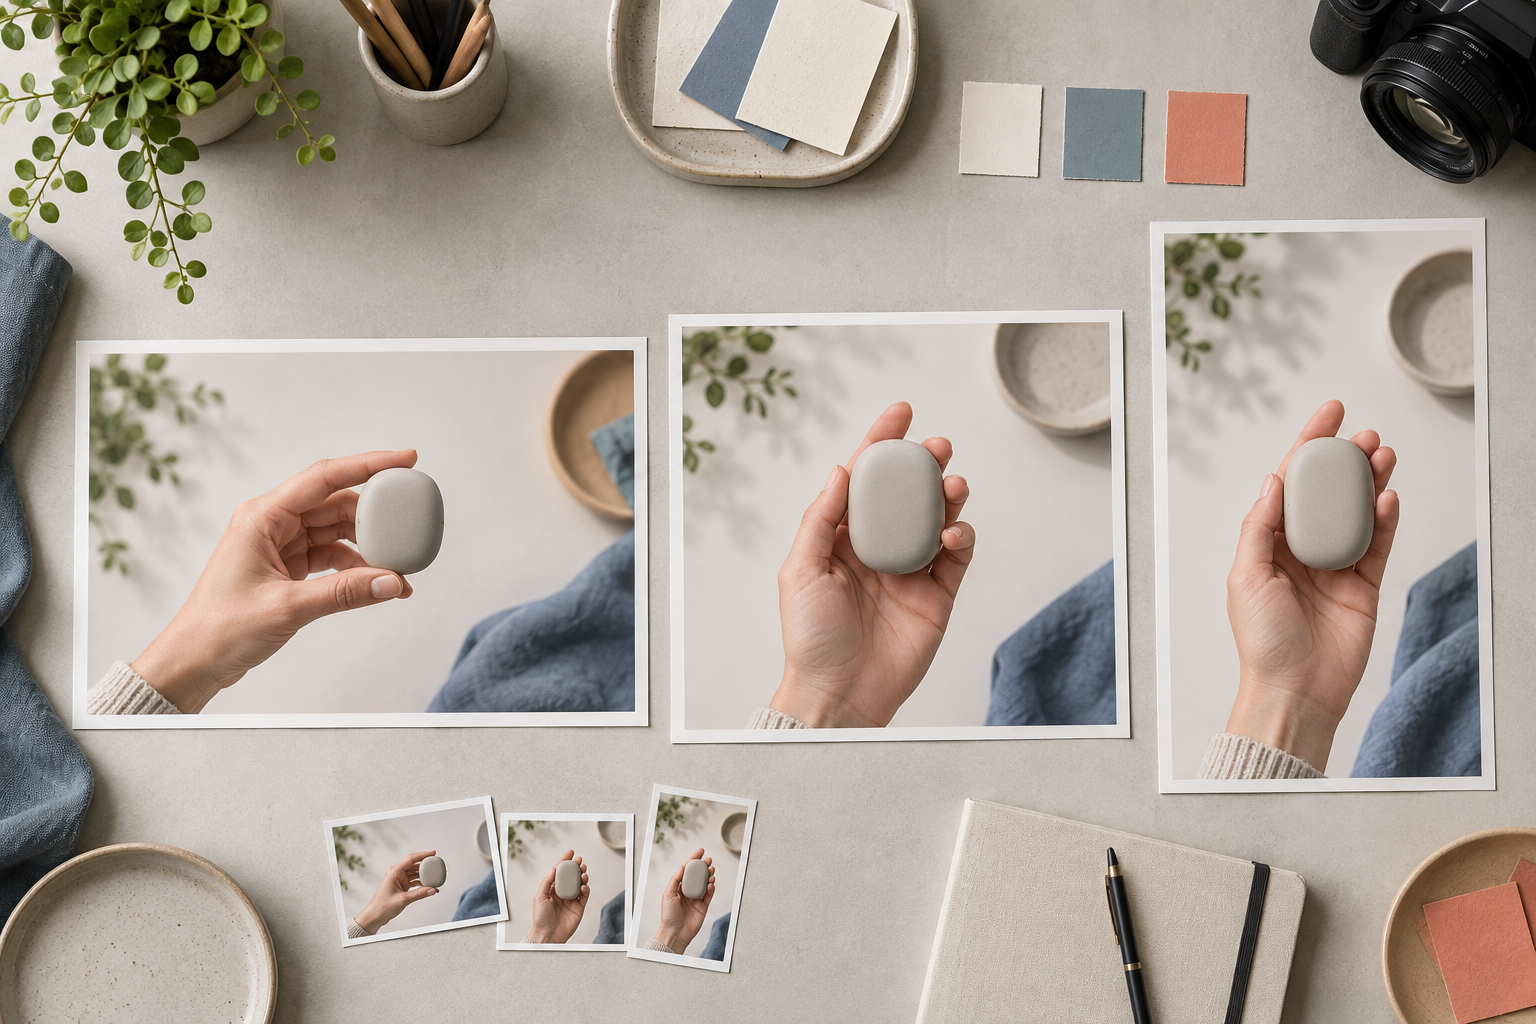
    Three source-image layouts place the same unbranded product in landscape, square, and vertical compositions.

    The quality ceiling is set before generation begins. A high-resolution image with one obvious focal point gives Veo cleaner material to animate and gives you more room to crop. A small or already-soft image may look acceptable in an account preview but become visibly grainy when shown on a larger screen.

    Google Ads supports three video shapes, and the practical goal is to create the same concept in each one:

    FormatAspect ratioRecommended HD dimensions
    Horizontal16:91920 x 1080
    Vertical9:161080 x 1920
    Square1:11080 x 1080

    Do not assume one composition will survive all three crops. A product pushed toward the left edge may work in a horizontal frame and become cramped or disappear in a vertical one. Either start with an image whose subject and important brand details sit comfortably near the center, or prepare crop-specific versions of the same scene.

    Use an image-readiness check before generation

    • Resolution: Start with the cleanest, largest approved image available. Do not enlarge a visibly soft thumbnail and expect generation to restore authentic detail.
    • Focal point: Make the product, environment or service result immediately identifiable. Competing objects make the intended subject harder to read in a brief scene.
    • Crop tolerance: Check horizontal, vertical and square crops before committing to the image. Keep essential product features, packaging and brand marks away from vulnerable edges.
    • Sequence: Match the two scenes in visual logic. Similar lighting, color and subject scale can help the transition feel intentional.
    • Copy space: Leave enough uncluttered area for overlays. Text placed over detailed packaging or a busy background may technically fit while remaining hard to read.
    • Brand accuracy: Use images that represent the product or service as it is actually sold. The generated asset should not imply a feature, finish, result or offer that the landing page cannot substantiate.
    • Face restriction: Remove any candidate that contains a face before you build around it, because that image cannot be used in this particular creation flow.

    Prepare these inputs as a small asset set rather than hunting through the library during generation. For each scene, keep an approved horizontal, vertical and square crop with consistent naming. That makes later iterations faster and reduces the chance that one format quietly uses a different concept.

    Build the asset in Google Ads, then inspect every frame

    A reviewer examines individual video frames and three aspect-ratio previews on a workstation.

    The Google Ads workflow lives in Asset Studio. Once your images and message are ready, the mechanical part is short:

    1. Open Asset Studio in your Google Ads account and go to Create videos.
    2. Select Create video from images.
    3. Choose a five- or 10-second duration. Use the shorter option only when the idea remains understandable without rushing the transition or text.
    4. Select the first image from your asset library for scene one and the second image for scene two.
    5. Review the two animation options supplied for each scene and choose the combination that keeps the focal subject clear.
    6. Select a video template and add the text overlays.
    7. Review the completed preview in the intended aspect ratio.
    8. Upload the result to a private YouTube channel or your brand’s YouTube channel, then use it as a Short in PMax or Demand Gen.

    The two available animation choices may not create radically different concepts. That is another reason to solve the story in the still images first. Choose animation based on clarity: the best option is the one that directs attention to the subject without obscuring the product or making the transition feel disconnected.

    Make the text earn its limited space

    You receive two headlines of up to 30 characters each, while the business name is the first text shown. Repeating the brand name in either headline usually wastes space that could explain why the viewer should care.

    A useful division of labor is:

    • Headline one: State the single benefit, differentiator or relevant use case.
    • Headline two: Add the most important qualifier, offer or next action.

    Write both lines before selecting a template. Count every character, then remove words that merely announce the ad. Phrases such as “introducing,” “learn more about” and a repeated business name consume room without adding a reason to continue. The image should establish the object; the copy should supply meaning the image cannot.

    Review the preview as a finished ad

    A polished transition can distract you from small errors. Pause through the preview and check the things a customer will actually see:

    • Does the product retain the correct shape, label, color and identifying details?
    • Is the focal subject visible throughout the animation rather than only in the opening frame?
    • Does the transition preserve the intended relationship between scene one and scene two?
    • Can both headlines be read comfortably without competing with the busiest part of the image?
    • Are the business name and headlines complementary rather than repetitive?
    • Does every visual and written claim match the destination page?
    • Does the crop remain clean in the specific horizontal, vertical or square version you are reviewing?

    Repeat that inspection for all three formats. Approval of the horizontal asset does not prove that the vertical crop is safe. If a version weakens the subject or message, change its source crop instead of accepting it merely to complete the set.

    Test the asset by question, not by novelty

    Launching an AI-generated video is not itself a test. A test begins with a question that can change your next decision. You might ask whether motion improves engagement over the existing still concept, whether a different first scene produces more clicks, or whether benefit-led copy brings better website engagement than feature-led copy.

    Change one creative idea at a time

    1. Add the first Veo concept without immediately removing your strongest existing assets. That preserves useful creative while the new asset begins receiving delivery.
    2. Create horizontal, vertical and square versions from the same concept so a missing format does not become the hidden reason for limited reach.
    3. Keep the offer and destination page stable for the first comparison. Otherwise, you will not know whether the video or the surrounding proposition changed the response.
    4. Name the asset so its variables remain visible. A convention such as VEO-10S-916-HOOK-A-COPY-A-V1 records the duration, ratio, hook, copy and version without requiring a separate lookup.
    5. For the next iteration, change either the opening image, the second scene or the overlay message. Changing all three produces another ad, but little usable learning.

    This will not become a perfect laboratory comparison. PMax and Demand Gen can distribute assets across different contexts, and impressions and performance vary by channel. Keep the comparison as consistent as the campaign allows, then interpret the results as directional evidence rather than pretending every variable was controlled.

    Read the full path from delivery to action

    Video performance is available at the asset level. Read the signals in sequence instead of jumping directly to the conversion column:

    • Impressions: First establish whether the asset received meaningful delivery. Low delivery is not enough evidence to call the creative a failure.
    • Engagement: Use this to judge whether the short visual and its opening moment held attention well enough to produce a response.
    • Clicks: Look for evidence that the message created enough interest for the viewer to take the next step.
    • Website engagement: Check whether the post-click behavior supports the promise made in the video. Clicks followed by weak site interaction should send you back to the message-to-page alignment, not automatically to the animation.
    • View-through conversions: Treat these as a sign that exposure may have assisted a later action. They add context, but they should not be treated as proof that the video alone caused the conversion.
    • Direct conversions: Keep them in the evaluation, but do not demand that every five- or 10-second asset behave like a direct-response unit before it can contribute value.

    The pattern between metrics tells you what to change. Delivery without engagement points toward the opening scene or visual hook. Engagement and clicks followed by weak website behavior point toward a mismatch between the ad’s promise and the landing experience. Too little delivery means you need more observation before making a creative judgment. View-through activity with few direct conversions may indicate an assisting role, but it still needs to be considered alongside the rest of the campaign.

    Start with one campaign that has approved, high-quality stills and a genuine video gap. Build one two-scene concept, render it in all three ratios and write down the variable you intend to learn from before launch. Veo’s advantage is not that one generated clip replaces every production need. It is that the next relevant creative iteration becomes easier to make, inspect and improve.

    References


  • How to Use AI Dubbing for Localized Google Ads Videos

    How to Use AI Dubbing for Localized Google Ads Videos

    You have a video ad that already works, and the next market looks promising. The tempting move is to dub the audio, duplicate the campaign, and switch it on. That is also how you end up with a polished local voice describing an offer, screen, or landing page that still feels foreign.

    Google Ads is rolling out Video Ads Dubbing in Asset Studio for 33 languages and locales. It can remove a large production barrier, but it only solves the spoken-audio layer. You still need to localize the promise around that voice, verify what the model produced, and test whether the complete journey works in the market.

    Treat AI dubbing as a production shortcut, not complete localization

    A laptop video ad is surrounded by separate layers for dubbed audio, localized visuals, a mobile page, and checkout elements.

    Dubbing changes what the audience hears. Localization changes whether the ad makes sense to that audience. Those jobs overlap, but they are not interchangeable.

    Localization layerWhat AI dubbing can handleWhat you still need to check
    Spoken messageTranslate the dialogue and generate localized speechMeaning, pronunciation, tone, pacing, emphasis, and call to action
    Visible creativeDo not assume dubbing changes itOn-screen copy, captions, product screens, prices, dates, and disclaimers
    Offer and destinationOutside the dubbing taskLanding-page language, offer availability, form fields, support information, and confirmation messages
    Market contextCannot approve commercial fit on its ownLocal expectations, brand terminology, audience relevance, and claim compliance

    This distinction should shape your budget. AI dubbing may reduce the cost of producing a usable first version, but it does not eliminate creative editing, market review, or campaign validation. If your video contains substantial on-screen copy, the audio may be the easy part.

    Access also needs to be confirmed before you plan a rollout. The feature has been free for select users, with limited availability. Check the Asset Studio options in the account that will actually run the ads. Translation, voice, and version controls may also vary as the product develops, so treat the controls visible in your account as authoritative for your workflow.

    Choose source ads and markets with a readiness scorecard

    The fastest way to waste the production savings is to dub every existing video at once. Start with an ad-market pair that can answer a useful business question.

    Score each candidate against these criteria:

    • The source ad has produced a meaningful downstream result, not merely views or clicks.
    • The spoken explanation carries an important part of the value proposition, so dubbing adds more than cosmetic polish.
    • The product, offer, and destination page are available to the intended audience.
    • The visible scenes, gestures, examples, and on-screen claims remain understandable in that market.
    • A fluent market reviewer is available to evaluate both meaning and delivery.
    • Any price, eligibility condition, guarantee, or regulated claim has an accountable owner who can approve the localized wording.

    Treat the landing page and the fluent reviewer as hard gates. If either is missing, you do not yet have a launchable localization. You have an audio file.

    Plan by market and locale, not by language alone. A shared language does not guarantee a shared offer, vocabulary, pronunciation, or destination experience. Your working sheet should identify the market, intended locale, campaign, source-video version, landing-page URL, offer owner, language reviewer, approval status, and date of the last review. That simple structure prevents a later source edit from leaving several dubbed versions silently out of date.

    Prepare a localization brief before generating anything. Include the approved source transcript, the intended meaning of each line, brand and product names that must not be translated, required pronunciations, the exact call to action, and wording that must not be introduced. If a sentence depends on a visual action, note that timing relationship explicitly.

    A clean brief does more than help the reviewer. It gives you a stable reference when the generated speech sounds plausible but changes the commercial meaning. Fluency is not proof of accuracy.

    Run every dubbed asset through a four-pass review

    Four specialists review a dubbed video for language accuracy, audio quality, cultural fit, and the final mobile experience.

    Do not approve a localized video from an English back-translation or transcript alone. The final artifact is audiovisual, so the review must be audiovisual too.

    1. Review meaning. Compare the dubbed dialogue with the approved intent line by line. Check product names, quantities, negation, conditions, calls to action, and the strength of every claim. A translation can be linguistically correct while making a promise broader or narrower than the original.
    2. Review the voice. Listen without reading the transcript. Check pronunciation, natural stress, emotional register, pace, abrupt pauses, and clipped endings. The voice should fit the scene and brand; it does not need to imitate the original speaker.
    3. Review the visual relationship. Watch the complete video with sound. Confirm that spoken references still line up with demonstrations, product screens, gestures, captions, and end cards. Flag any line that finishes too late for the scene or contradicts visible copy.
    4. Review the destination journey. Click through exactly as the audience will. The landing page should continue in the expected language, present the same offer, repeat the same qualification conditions, and use a call to action consistent with the ad. Complete the form, purchase path, or other primary action far enough to catch language reversions and conflicting details.

    Back-translation can help expose meaning drift, but it cannot tell you whether the performance sounds awkward, patronizing, overly formal, or unintentionally comic. That judgment belongs to someone who understands how the target audience actually speaks.

    Separate language approval from commercial approval. A fluent reviewer can confirm that a sentence sounds natural. The offer owner must confirm that it is accurate. If the ad makes regulated, contractual, financial, or health-related claims, send the localized wording through the appropriate compliance review before publishing. AI-generated language does not transfer responsibility for the claim to the tool.

    Record approvals against a specific source-video version. When the source script, offer, disclaimer, or destination changes, reopen every affected localization. Otherwise, a small edit to the original can create a portfolio of obsolete ads that still look approved.

    Test the localized message, not just the synthetic voice

    Your experiment should answer whether the localized ad creates better business results for that market. It should not merely ask whether the generated voice sounds convincing.

    Choose the control that matches the decision. If you want to know whether dubbing beats your current approach, compare it with the existing asset shown to a comparable audience. If you want to evaluate AI production against a locally produced version, keep the offer, landing page, audience, and campaign objective aligned as closely as the setup permits. Do not compare raw results across countries and attribute every difference to dubbing; market demand, auctions, targeting, and offers can all differ.

    Use a naming convention that exposes what changed. A practical asset label includes the market, locale, source-video identifier, localization method, and version. Keep dubbed assets separate in reporting rather than combining them under a generic localized-video label.

    Read performance as a funnel:

    • Delivery tells you whether the asset entered the intended auctions and spent enough to be evaluated.
    • Available viewing and engagement metrics tell you whether the opening and delivery retained attention.
    • Click-through rate tells you whether the ad generated a response, not whether it generated a good customer.
    • Landing-page conversion rate helps expose a mismatch between the localized promise and the destination.
    • Cost per qualified conversion, revenue, or another downstream business outcome tells you whether the localization is commercially useful.

    When click-through rate rises but conversion quality falls, inspect the translated promise, call to action, audience expectations, and landing-page continuity before declaring a win. When viewing weakens but people who click still convert, inspect the voice, opening, pacing, and first visual-audio handoff. When both creative versions change similarly, check campaign conditions before blaming or crediting the dub.

    Google promotional material has highlighted examples of an 86% increase in click-through rate and a 75% reduction in cost per click. Those are Google-provided examples, not expected results or guarantees. Do not use them as your forecast, target, or stopping rule. Your own undubbed or previously localized performance is the relevant baseline.

    Scale only after you know why a version worked. Lock the approved transcript, glossary, voice choice, destination, and source-video version. Then expand in reviewable waves, retaining separate reporting for each market. This keeps a successful test from becoming an uncontrolled batch of superficially similar assets.

    Key takeaways

    • Google Ads Video Ads Dubbing can accelerate spoken-language production across supported languages and locales, but availability remains limited.
    • A dubbed voice is only one localization layer; visible copy, offers, landing pages, and market context still need separate work.
    • Do not launch without a fluent market reviewer and a destination experience that continues the localized promise.
    • Review meaning, voice, visual timing, and the full conversion journey before approving an asset.
    • Measure downstream business outcomes against a relevant control rather than treating higher click-through rate as proof of success.
    • Keep every localized asset tied to a specific source version so later edits trigger a new review.

    Start with one proven source ad and one market where the destination and reviewer are already in place. Build the brief before opening Asset Studio, run the finished video through the complete review, and launch it as a controlled test. The real advantage is not producing dozens of voices at once. It is learning which localized message deserves to be scaled before production complexity returns.

    References


  • Google Ads Automated Bidding Changes: What to Reassess

    Google Ads Automated Bidding Changes: What to Reassess

    Your Google Ads campaign can look less efficient even when automated bidding is doing exactly what you told it to do. If a budget-limited campaign used to beat its target ROAS or CPA but now buys more expensive traffic and exhausts its budget sooner, don’t assume the bidder is broken.

    The more useful question is whether your target still expresses the result your business actually needs. Google has made target-based bidding more literal for budget-constrained campaigns, while a separate retail beta adds product-level value signals. Together, these changes put more responsibility on you to define acceptable economics rather than relying on budget pressure to produce accidental efficiency.

    Budget limits no longer create the same efficiency buffer

    A limited tank of glowing coins drains through an automated bidding machine that sends larger bundles toward several abstract auction gates.

    A target ROAS or target CPA is an instruction, not a label. If you give the bidder a target that is looser than your real business requirement, it has room to pursue additional opportunities until performance approaches that stated target.

    Before the Smart Bidding change, a constrained budget could effectively make bidding more conservative. Some campaigns captured cheaper clicks, stretched their allocations and substantially exceeded their targets. The update that started rolling out on Aug. 17 and finished globally on Aug. 27 was intended to make target-based, budget-limited campaigns perform more consistently around the goals advertisers entered, including when budgets changed.

    The practical consequence is easy to miss. A target CPA campaign set to $10 but previously delivering a $5 CPA could move closer to $10 unless the advertiser tightens the target. The equivalent can happen with target ROAS: historical overperformance is not necessarily a permanent buffer when the system is being asked to deliver only the lower stated return.

    The initial post-rollout pattern was substantial. Median CPC for budget-limited target ROAS campaigns rose 15.8%, while CPC for campaigns that were never budget-limited fell 13%. Before the change, more than half of the constrained campaigns were exceeding their ROAS targets. Only 30% of non-limited campaigns overdelivered, while 57% landed on target.

    Observed medianBefore the rolloutAfter the rolloutWhat you should notice
    CPC for budget-limited campaigns€0.38€0.44The constrained campaigns paid more for each click.
    Impression share lost to rankAbout 45%About 30%Ad rank was responsible for a smaller share of missed impressions.
    Impression share lost to budgetAbout 4%About 33%The budget became the more direct constraint.
    Overall impression share40%31%The campaigns reached a smaller portion of available impressions.

    That combination matters more than any one number. Higher CPC, lower rank loss and sharply higher budget loss indicate that the bidder may be competing more strongly when it enters an auction, then running into the spending limit sooner. It is a different mechanism from simply bidding conservatively all day.

    The findings are early rather than universal. Conversion attribution was still developing, so the long-term ROAS effect was not yet settled. Treat Aug. 17 as a meaningful diagnostic breakpoint, not as proof that every performance change in every account has the same cause.

    Audit affected campaigns without hiding the change in averages

    An account-level average can conceal exactly what you need to see. Separate target-based campaigns that were budget-limited from campaigns that had enough budget. The two groups moved differently after the rollout, so combining them can turn a clear bidding shift into an ambiguous blended trend.

    1. Identify campaigns using a target-based strategy. Separate target ROAS from target CPA so you evaluate each one against the correct efficiency measure.
    2. Flag campaigns that were budget-limited around the rollout. Keep campaigns that were never constrained as a comparison group rather than mixing their results into the same total.
    3. Use Aug. 17 as the beginning of the change and Aug. 27 as the completion point. Avoid treating the rollout interval as a clean before-or-after period.
    4. Allow conversion attribution to mature before making a final ROAS or CPA judgment. CPC and impression-share signals appear sooner than fully attributed conversion value.
    5. Compare actual performance with the target you entered. Record target ROAS versus delivered ROAS, or target CPA versus delivered CPA, rather than looking only at the change from the previous period.
    6. Review CPC, total impression share, impression share lost to rank and impression share lost to budget together where those metrics are available. This shows whether the campaign became less competitive, more budget-constrained or both.
    7. Check the business result behind the platform metric. Revenue, contribution margin, inventory priorities and acquisition value determine whether performance near the target is acceptable.

    Read the metrics as a system

    If CPC rises, rank loss falls and budget loss rises, the campaign is probably bidding more competitively and exhausting its allocation more directly. Review the target before assuming the budget is too small.

    If actual ROAS falls toward target ROAS, or actual CPA rises toward target CPA, the bidder may be using the flexibility you explicitly gave it. Decide whether the additional opportunity is economically worthwhile. Don’t call the movement a failure merely because the old campaign overdelivered, but don’t accept it merely because the platform reached its target either.

    If total impression share falls while budget loss rises, you face a real reach decision. You can accept fewer impressions, tighten the target and potentially reject more opportunities, or fund more of the available demand. The correct answer depends on the value of the next unit of spend, not on a desire to recover an old impression-share percentage.

    If those auction signals are absent, don’t force the bidding update to explain the problem. A conversion-tracking change, product mix, demand shift or landing-page issue can also alter ROAS or CPA. The update is a hypothesis to test against campaign-level evidence, not a universal diagnosis.

    Choose the lever that matches the actual constraint

    You have four defensible responses: accept less reach, tighten the target, increase the budget where the economics support it, or reconsider the bidding strategy. The dangerous response is to raise the budget automatically because the interface says a campaign is limited.

    Tighten a target that understates your real requirement

    If the business needs a higher return than the target ROAS currently entered, raise the target toward the efficiency level you genuinely require. If the business cannot tolerate the current target CPA, lower that target toward the acceptable acquisition cost. Historically delivered performance can inform the change, but it should not replace your unit economics.

    A tighter target can reduce reach because the bidder must reject opportunities that do not fit the new instruction. That is not necessarily a defect. It is the cost of refusing volume that fails your efficiency requirement.

    Increase the budget only when performance at the target is valuable

    A larger budget can make sense when the stated target is profitable and additional demand has value. Evaluate the next dollars as though they will perform near the target, not at the unusually strong ROAS or CPA the constrained campaign used to deliver. The update was designed to bring delivery closer to the entered goal, so historical overperformance is a weak basis for approving more spend.

    This decision creates direct financial exposure. Set the approved spending limit from margin, cash flow and customer value, then decide how much reach to purchase. A platform warning that a campaign is budget-limited does not establish that the missed traffic is profitable.

    Accept reduced reach when the budget is fixed

    If the spending cap cannot move and the target already reflects your economics, reduced reach may be the honest result. You cannot demand the same auction coverage, preserve the same efficiency and keep the same budget when click costs rise. Choose which constraint is real instead of asking automation to satisfy three incompatible requirements.

    Reconsider the strategy when one target cannot express the objective

    A single account-wide or campaign-wide value target can be too blunt when products have materially different commercial value. Before abandoning automation, examine whether the bidding system is receiving the wrong definition of value. For retailers, the Product Value Optimization beta is intended to address part of that problem.

    Whichever lever you select, change it deliberately. Altering the target, budget and value rules together makes the result hard to interpret. Record the reason for the first change, let attributed conversions develop, and then judge whether that lever addressed the constraint you identified.

    Product Value Optimization adds business context to retail bidding

    Generic retail products send layered margin, inventory, customer value, and priority signals into a central automated bidding engine.

    Standard conversion-value bidding can treat equal amounts of reported revenue as equally desirable even when the underlying sales have different margins or inventory consequences. Product Value Optimization is a retail beta that allows value adjustments for individual products or attributes such as brands and categories. Those adjusted signals can guide automated bidding in Performance Max and Shopping campaigns without requiring a campaign restructure.

    This gives you three different controls with three different jobs. The budget limits the spend available. The ROAS or CPA target communicates the desired efficiency. A product value rule tells the bidder which items or sales deserve more emphasis. Confusing those jobs leads to bad fixes, such as raising an entire campaign’s budget when the real need is to favor a profitable category within it.

    The beta identifies profit, seasonal sell-through and best-selling products as possible use cases. Those goals are not interchangeable. A bestseller may produce volume but weak incremental profit. Seasonal inventory may warrant temporary priority because its value falls after the selling window. A high-margin product may deserve emphasis even if it does not lead the revenue report.

    Define the rule before enabling the adjustment

    1. Choose one commercial objective for the rule: profit, seasonal sell-through or another clearly defined inventory priority.
    2. Select the narrowest appropriate level. Use a product rule when the priority is item-specific, or an attribute such as category or brand when the logic genuinely applies across that group.
    3. Write down why the selected sale is more valuable. Higher revenue alone is not enough if margin, returns or inventory costs point in the opposite direction.
    4. Map overlapping product, category and brand logic before activation. The bidder needs a coherent value hierarchy, not competing expressions of internal preferences.
    5. Keep actual revenue and profit as independent business measures. An adjusted optimization value is an instruction to the bidder; it is not proof that the resulting sales created more profit.
    6. Evaluate product mix as well as aggregate ROAS. A stable top-line return can hide a meaningful shift toward or away from the inventory the rule was designed to prioritize.

    If the beta appears in your account, start with the business distinction you can defend most clearly. A rule grounded in margin or time-sensitive inventory has a testable rationale. Prioritizing a product merely because it is already popular risks teaching the bidder to amplify volume that would have occurred anyway.

    Key takeaways

    • Budget-limited target bidding may no longer produce the same conservative bidding and accidental target overperformance it produced before the Aug. 17 rollout.
    • A CPC increase combined with lower rank loss and higher budget loss is more informative than a CPC increase viewed alone.
    • Treat target ROAS and target CPA as permissions the bidder can use, not as passive reporting benchmarks.
    • Model a budget increase at performance near the stated target rather than assuming the campaign will retain its former overperformance.
    • Use Product Value Optimization to express genuine differences in commercial value, not to promote products based on popularity alone.
    • Allow attribution to mature before declaring the long-term ROAS effect, because the available post-rollout evidence was still preliminary.

    Start with the budget-limited campaign where the gap between target and historical performance was largest. Reconstruct what changed across CPC, impression-share losses and actual efficiency, then make the smallest change that brings the bidding instruction back into line with the economics you are prepared to accept.

    References


  • Pinterest Visual Search Ads: A Practical Campaign Guide

    Pinterest Visual Search Ads: A Practical Campaign Guide

    You do not need another Pinterest campaign type simply because it exists. You need to know whether someone who has not named your product yet can recognize it visually, click it, and reach a page that confirms the same choice.

    That is the practical case for Pinterest Visual Search Ads. The query is partly an image, the ad competes during product exploration, and the landing page has to continue the comparison without introducing doubt. Here is how to decide whether the format fits your catalog, design a useful test, and connect the resulting insights to your wider search and AI visibility strategy.

    Visual Search Ads change what counts as a query

    A conventional search ad responds to words. A visual search placement can respond to the object, style, color, setting, or product relationship visible on the screen, while still considering keywords.

    Pinterest Visual Search Ads can appear in Pinterest Search Results and Pin closeups, combining keyword relevance with Pinterest’s visual understanding of images, products, and intent. Advertisers can bid for a prominent response and send the shopper directly to their website.

    This does not make keywords obsolete. It makes them one part of a richer signal. Someone may type a broad phrase, open an image that reflects the desired look, and then compare visually similar options. Your ad has to make sense in that sequence even when the shopper has not supplied an exact product name.

    For the marketer, the job changes in three ways:

    • The product’s appearance must communicate the quality that makes it relevant. A hidden benefit cannot do all the work at the impression stage.
    • The promoted product must fit the visual idea being explored, not merely share a broad category or keyword.
    • The destination page must preserve the image, variant, context, and offer that earned the click.

    Pinterest reports more than 80 billion searches per month, with the vast majority described as visual and more than half as commercially oriented. Those are platform-supplied scale figures, not a forecast for your account. Commercial intent can mean researching, comparing, saving, or buying. Your test still has to determine which of those behaviors produces economic value for you.

    The format is designed for lower-funnel objectives and can work with Pinterest Performance+, but “lower funnel” should not be read as “ready to purchase immediately.” The useful opportunity is to enter the decision while the shopper is narrowing the look, product, or category they want.

    Decide whether the format deserves a test

    The first qualification is not whether your brand has attractive images. It is whether a visible characteristic carries meaningful buying intent.

    A quick fit test

    Visual Search Ads are worth evaluating when most of the following are true:

    • People can distinguish relevant choices through visible attributes such as form, finish, pattern, silhouette, layout, color, or use context.
    • Your catalog contains products that are close enough to a shopper’s inspiration to satisfy the same need, rather than merely belonging to the same department.
    • Your product pages can open on the exact item or variant represented in the ad.
    • You can measure activity beyond impressions and saves, including qualified site visits and business outcomes.
    • Your team can isolate a product group, creative question, or targeting question instead of changing the entire account at once.
    • Your commercial model can support paid traffic while shoppers are still comparing options.

    Delay the test if the catalog is frequently out of stock, the advertised visual leads to a generic category page, or the decisive benefit is almost entirely invisible and difficult to establish on the landing page. Visual reach will not repair a broken handoff.

    Access is another qualification. Pinterest announced the format for beta rollout to eligible advertisers across its advertising markets. That wording does not guarantee that every account has the feature. Confirm availability in your account or with your Pinterest contact before building a launch schedule around it.

    Key takeaways

    • A visual query adds image-based intent; it does not eliminate keyword relevance.
    • The strongest test candidates are products whose visible attributes affect the purchase decision.
    • Creative, product selection, and landing-page continuity should be planned as one system.
    • Beta access is a reason to run a controlled experiment, not a reason to assume a new source of profitable scale.
    • Platform engagement is useful diagnostic evidence, but conversion and incremental business value should determine whether you expand the campaign.

    Build the campaign around visual continuity

    The same sage-green lounge chair appears in a styled room, a visual discovery result, and a tablet product page with consistent imagery.

    A good first campaign answers one commercial question. It should not attempt to prove that visual search works for every product, audience, creative style, and objective at the same time.

    1. Write the test claim before configuring the campaign. For example, you might test whether product-focused imagery or contextual imagery attracts visitors who are more likely to reach a product decision. Phrase the claim so the result can change what you do next.
    2. Select a coherent product group. Organize it around the visual decision the shopper is making, not merely your internal merchandising hierarchy. Products grouped together should solve a similar need and present a recognizable visual relationship.
    3. Audit product readiness. Confirm that the selected items have usable inventory, commercially acceptable economics, accurate offer information, and destination pages that represent the promoted variants.
    4. Prepare creative that reveals the decision-relevant attribute. A styled scene can establish context, while a clear product view can establish detail. Use variations to answer a defined question rather than producing arbitrary volume.
    5. Match each ad to the closest useful destination. The image, product name, variant, price, availability, and primary promise should not appear to change after the click.
    6. Record the baseline and decision rule. Identify the existing campaign, product group, or traffic source that will serve as the comparison. Decide which primary outcome would justify expansion and which guardrails would stop it.

    The fourth and fifth steps are where many otherwise promising tests fail. An image can earn attention because of one finish, arrangement, or style, only for the destination to foreground a different variation. The visitor then has to reconstruct the connection that the ad should have preserved. That friction will often appear as weak post-click performance rather than an obvious creative error.

    Use Priority Products as a business constraint

    Performance+ is also gaining a feature called Priority Products, which lets advertisers emphasize selected products for seasonal launches, promotions, or category pushes while retaining automated optimization.

    If the option is available in your account, use it to communicate a genuine merchandising priority. A new launch, a promotion, or a strategically important category can justify preference. Do not use it to force weak products into delivery merely because an internal team wants exposure. Product priority directs automation; it does not turn an unsuitable item into a strong response to visual intent.

    Keep a written record of why each item was prioritized. That lets you separate a platform-learning problem from a business constraint later. If performance is weak, you will know whether the system chose the product freely or whether your instruction narrowed its choices.

    Measure the test without mistaking activity for impact

    An overhead desk scene compares two visual shopping paths, one ending with interaction tokens and the other continuing to a basket and packed parcel.

    Visual discovery naturally produces intermediate behavior. People inspect, compare, and save. Those actions can explain what is happening, but they are not interchangeable with revenue.

    Pinterest is introducing self-serve A/B testing for creative and targeting, including within Performance+. When that capability is available, use it to isolate one decision at a time. Compare creative in one test and targeting in another. Changing both at once may produce a winner without revealing why it won.

    A practical scorecard should move from delivery to business value:

    QuestionSignals to inspectWhat the result should change
    Did the campaign reach the intended product opportunity?Delivery by planned product group and creative variationIf delivery concentrates on the wrong items, revise the product scope or priority instructions before judging the format.
    Did the visual match create qualified interest?Outbound clicks, landing-page arrival, product engagement, and progression toward a purchase actionIf the ad earns attention but the visit ends quickly, inspect visual and offer continuity before increasing spend.
    Did the interest produce commercial value?Conversions, acquisition cost, revenue, and return on ad spend using consistently defined attributionIf engagement rises without acceptable business outcomes, treat the campaign as a learning result rather than a scaling result.
    Did the campaign add value beyond activity you would have received anyway?Incrementality evidence from a suitable holdout, geographic comparison, or other controlled method where feasibleIf only platform-attributed results are available, label that limitation instead of presenting attribution as proven lift.

    Choose the primary metric before reviewing the outcome. Otherwise, a disappointing conversion test can quietly become a successful engagement test after the fact. Supporting metrics should explain the primary result, not replace it.

    Keep the product scope, landing experience, and measurement definitions stable during a comparison. If a promotion, inventory change, tracking update, or site redesign occurs during the test, record it. Those events can alter the result without saying anything meaningful about visual search.

    Do not borrow performance claims from adjacent Pinterest products. A result associated with an app-install objective, for example, is not evidence that Visual Search Ads will produce the same improvement for an ecommerce purchase campaign. Each format, objective, and business model needs its own baseline.

    Use paid-search learning to improve broader discoverability

    Visual Search Ads are not a shortcut to SEO, answer engine optimization, or generative engine optimization. They can, however, expose the visual language people use before they know the precise words for a product.

    Pinterest Intelligence is designed to interpret images, products, tastes, and intent. Do not jump from that fact to the assumption that adding more keywords to image fields or Product JSON-LD will improve an ad auction. No direct relationship of that kind has been established. Keyword stuffing also makes product information less useful to people and other systems.

    Instead, turn campaign learning into a disciplined content workflow:

    1. Record the visible attribute, use context, or product relationship represented by each meaningful creative variation.
    2. Compare attention with downstream behavior. A visual theme deserves broader use only when it attracts the right visitor and supports the intended business outcome.
    3. Reflect validated language in the appropriate page elements: clear product names, visible variant descriptions, useful category copy, concise accessibility-focused alternative text, and customer-facing answers about fit or use.
    4. Keep Product structured data accurate and consistent with the visible page where it applies. Mark up the real product and offer; do not treat schema as a hidden advertising copy field.
    5. Separate channel-specific findings from durable customer language. A concept that performs inside Pinterest may inspire a content test elsewhere, but it does not automatically predict Google rankings or inclusion in an AI-generated answer.

    This is where paid visual discovery can contribute to an SEO and GEO program without overclaiming. It gives you evidence about how people recognize and compare products. Your site can then explain those products more clearly in text, imagery, page structure, and structured data. Clarity helps users and gives search and AI systems cleaner information to interpret, but it is not a guarantee of visibility.

    Your first move should be small and concrete. Choose a coherent product set, identify the visible characteristic that carries buying intent, audit the Pin-to-page handoff, and write one testable commercial question. If you cannot define the comparison or measure the outcome, wait. If you can, the beta becomes a way to learn whether visual intent is profitable for your catalog rather than another placement competing for unexamined budget.

    References


  • Agentic Ecommerce: A Playbook for Discovery and Advertising

    Agentic Ecommerce: A Playbook for Discovery and Advertising

    If your product pages rank and your ads are live, but your products still disappear from AI-guided shopping conversations, the missing layer is usually not more promotional copy. It is decision-ready product data: facts an agent can retrieve, compare, explain, and carry into checkout.

    Your goal is no longer just to win a click. You need to help an AI determine whether a specific product fits a specific buyer’s constraints, answer the next question accurately, and make the handoff to your store without changing the facts along the way.

    The shopping funnel now contains a conversation

    A conventional product ad asks the shopper to click before learning much. A conversational ad can answer questions about fit, compatibility, features, availability, or policies inside the discovery surface. ChatGPT is testing clearly labeled Sponsored Agents that open a separate brand conversation, while Google’s Business Agent is being tested inside YouTube ads for eligible U.S. retailers.

    That changes the intermediate step, not the buyer’s underlying job. People still need to eliminate unsuitable choices, understand tradeoffs, and trust the terms of the purchase. The difference is that an agent may now perform part of that evaluation before the shopper reaches your product page.

    Do not collapse every appearance in AI into one visibility metric. There are three distinct outcomes:

    • Citation: your content supplies an explanation or fact used in an answer.
    • Recommendation: your brand enters the suggested set for a category or use case.
    • Selection: a particular product is matched to the shopper’s stated requirements and advanced toward purchase.

    Each outcome requires different work. Clear, retrievable content helps with citation. Consistent brand context supports recommendation. Complete product attributes, current commercial data, and a usable transaction path support selection. This is why LLM readability, brand context, and agentic commerce are separate optimization disciplines, even when one team owns all three.

    Do not fund this shift by abandoning traditional search. An Ahrefs-based measurement found AI Overviews on 24% of shopping queries on Sept. 3, 2026, but a Datos panel of more than 10 million desktop users measured dedicated AI Mode at only about 0.13% of web traffic. A separate panel of 75 ecommerce stores, mostly producing $1 million to $20 million in annual revenue, still placed non-branded organic search second only to paid search for revenue. The practical response is a parallel search and AI strategy, not a wholesale channel migration.

    Build a product record an agent can safely choose

    An unbranded hiking shoe is surrounded by organized visual layers representing its materials, size, fit, availability, shipping, and return details.

    An agent cannot reliably recommend what it cannot distinguish. A polished category description will not compensate for missing variant measurements, ambiguous compatibility, stale availability, or different prices in the feed and on the page.

    For every product and variant you want an agent to select, create one canonical record with five layers:

    • Identity: product name, brand, category, model, SKU or other applicable identifiers, plus the exact relationship between parent products and variants.
    • Transaction truth: price, currency, condition, availability, fulfillment choices, shipping terms, returns, warranty, and any eligibility rules for discounts or member pricing.
    • Decision attributes: dimensions, materials, fit, capacity, supported devices or systems, care requirements, included components, and other facts buyers use to rule products in or out.
    • Evidence and instructions: manuals, size charts, compatibility tables, policy pages, certifications when applicable, and factual answers to recurring pre-purchase questions.
    • Destinations: the correct product page, variant URL, cart action, policy page, or support handoff for each answer.

    Publish the same facts through the channels machines use: visible page content, merchant feeds, platform catalog integrations, and Product and Offer structured data where applicable. JSON-LD should be generated from the same commerce data as the page and feed. Treating schema as a separate copywriting exercise creates exactly the contradictions an agent should not have to resolve.

    Run a variant-level consistency check before activating an agent or campaign. Compare title, identifier, price, currency, availability, shipping, return terms, and the primary decision attributes across the page, feed, structured data, and commerce API. If a field is genuinely unknown, leave it unknown and define a safe fallback. Do not let the agent infer compatibility, delivery, or warranty coverage from adjacent products.

    Product copy still matters, but it should answer rather than decorate. Put the direct answer first, then the explanation, supporting evidence, and relevant conditions. Keep each FAQ block focused on one buyer question so it can be retrieved without unrelated text changing its meaning.

    The commercial case for this cleanup is promising but should not be overstated. Google reports that merchants following its core Merchant Center feed practices see an average 5% conversion increase in the following month. In a Lululemon test, retailer-supplied conversational attributes were incorporated in 50% of relevant AI Mode product recommendations. These are platform-reported results, not guaranteed lifts. Their useful lesson is narrower: attributes that exist as maintained data can participate in recommendations; facts trapped in campaign copy cannot be depended on in the same way.

    Design conversational ads around the next unanswered question

    A shopper and an abstract AI guide exchange symbol-filled bubbles while narrowing several coffee machines to one suitable choice.

    A conversational ad should not be a chat-shaped version of a display ad. Its job is to resolve the next material uncertainty and route the shopper to the correct action. Build an answer map before you generate creative.

    Buyer questionRequired dataSafe handoff
    Will this fit?Variant measurements, sizing method, and size-chart rulesThe selected variant and relevant size guide
    Will it work with what I own?Supported models, exclusions, required accessories, and version limitsThe compatible variant or compatibility table
    What will I actually pay?Current price, currency, shipping terms, and applicable member benefitsA cart with the same disclosed terms
    Can I get it when and where I need it?Live inventory and available fulfillment methodsThe available purchase or pickup path
    What if it is unsuitable?Return window, condition requirements, exclusions, and warranty termsThe relevant policy section or support route

    For each row, define an answer contract: the approved system of record, the claims the agent may make, the data that must be checked live, the fallback when data is unavailable, and the destination that preserves context. A useful fallback is specific: state which fact cannot be confirmed and direct the shopper to the place or person that can confirm it. A confident guess is not customer service.

    AI can also compress campaign production. ChatGPT Work’s Ads Manager plugin can create, update, and analyze campaigns from natural-language instructions; its assistance can propose copy and imagery from a landing page and campaign objective. Optional text customization can adapt headlines and descriptions to the conversation or translate them into the user’s preferred language. U.S. Shopify merchants can also use a ChatGPT Ads app to manage campaigns, while Shopify Catalog data supports more accurate product appearances in shopping conversations. These workflow and catalog integrations reduce interface work, but they do not remove the need for review.

    • Review generated copy against the canonical product record, not just the landing page’s marketing language.
    • Validate translated claims, units, policies, and variant names before enabling localized customization.
    • Require a live lookup for price, stock, delivery, and personalized benefits when those values can change.
    • Send every answer to a landing state that preserves the chosen product or variant. Do not make the shopper repeat the conversation.
    • Log unsupported questions and corrected answers as product-data defects, then fix the underlying record.

    Keep paid and independent answers conceptually separate. OpenAI says Sponsored Agent conversations are labeled and separated from the original ChatGPT conversation, advertising does not influence ChatGPT’s independent answers, and advertisers do not receive users’ private conversations. Plan your measurement around the signals the platform legitimately exposes; do not design a campaign that assumes access to private prompt history.

    Measure the path from question to profitable order

    Click-through rate cannot describe the whole experience when a conversation performs part of the product-page job. It may produce fewer but better-qualified visits, expose missing information, or assist a purchase completed through another surface. Build a measurement chain that distinguishes those outcomes.

    • Visibility: eligible ad exposure, AI share of voice, recommendation coverage across a fixed set of target shopping prompts, and the products most often surfaced.
    • Conversation: conversation starts, qualified question rate, common question categories, answer failure rate, and the share of conversations that reach a site handoff.
    • Selection: variant views, product comparisons, cart additions, and checkout starts originating from the agent experience.
    • Transaction: completed orders, revenue, margin where available, assisted conversions, and member-benefit usage.
    • Outcome quality: cancellations, returns, exchanges, and support contacts attached to agent-assisted orders.

    Define the denominators before launch. Conversation start rate is starts divided by eligible ad exposures when the platform supplies both values. Qualified question rate is conversations containing a decision question divided by starts. Answer failure rate is unsupported, corrected, or escalated answers divided by starts. If a platform withholds a denominator, mark the rate unavailable instead of combining unrelated proxies.

    Use distinct campaign identifiers and landing URLs for each agent surface, preserve product and variant context in the handoff, and record launch dates in your analytics annotations. Compare performance with a suitable unactivated product, market, or campaign group where possible. Keep budget, promotion, inventory, and seasonal differences visible so a lift is not automatically credited to the agent.

    Google’s AI performance insights in Merchant Center are generally available in Australia, Canada, India, New Zealand, and the U.S., including comparisons of brand share of voice across AI Mode and AI Overviews. Its Universal Commerce Protocol integration can also support cart transfers to merchant sites and expanded checkout testing. Loyalty data can surface member-specific pricing and benefits. These discovery, checkout, and personalization capabilities make segmentation essential: report new and returning customers, members and non-members, and agent-assisted and conventional journeys separately.

    Key takeaways: use this launch sequence

    • Choose one decision-heavy category. Start where buyers repeatedly ask about fit, compatibility, delivery, or policy terms, because those questions reveal whether the agent adds real value.
    • Separate your goals. Decide whether each activity is intended to earn a citation, a brand recommendation, a product selection, or a paid conversation.
    • Repair the product record first. Align variant identity, decision attributes, price, inventory, policies, page content, feed data, and JSON-LD before generating campaigns.
    • Create the answer map. Pair each common buyer question with an approved data field, a safe fallback, and a destination that preserves the selected product.
    • Apply campaign guardrails. Human-review generated claims and translations, require live checks for changing commercial facts, and prohibit unsupported inference.
    • Instrument the whole path. Track visibility, dialogue, selection, checkout, and post-purchase quality rather than using clicks as the sole success signal.
    • Feed failures back into operations. Repeated unanswered questions belong in the catalog backlog; frequent returns after an agent interaction may indicate that an answer or attribute is misleading.

    Start with the category where a wrong answer would most often block or spoil a purchase. Make that category reliably answerable across organic discovery, conversational ads, and checkout. Scale only after the same facts survive every handoff.

    References


  • Microsoft Synthetic Ad Disclosure Rules: A Practical Workflow

    Microsoft Synthetic Ad Disclosure Rules: A Practical Workflow

    Your designer used generative fill, your editor replaced a voice segment, or your campaign team built an image from an AI prompt. Now you need to decide whether the ad can run on Microsoft Advertising, whether it needs a disclosure, and what evidence you should keep.

    Make that decision before the final export. A disclosure added at the upload screen cannot recover missing permission, removed provenance data, or a misleading depiction. The workable approach is to review AI involvement, accuracy, authorization, disclosure, and provenance as separate controls.

    Start with AI involvement, not whether the ad looks artificial

    Microsoft Advertising places AI-generated, AI-manipulated, and other synthetic content within its policy scope. When AI helped create or materially alter an ad, the audience may need to be told.

    That does not mean every use of AI automatically receives the same label. It means every use should receive a disclosure determination. If your media buyer first learns about the AI work after receiving the finished asset, the review has started too late.

    Add these questions to the creative brief:

    • Did AI generate any copy, image, video, audio, voice, person, product, setting, or event shown in the ad?
    • Did AI materially change recorded or photographed material, even if the original was real?
    • Could the finished creative make a viewer believe that a real person said, did, endorsed, or experienced something?
    • Does it reproduce or simulate an identifiable person’s likeness or voice?
    • Which countries or regions will receive the campaign?
    • Does the working file contain watermarks, metadata, or other provenance information that must survive production?

    For an internal materiality test, ask whether the AI work could change what a reasonable viewer believes about a person, product, place, claim, or event. A background cleanup is not operationally equivalent to fabricating a product demonstration or making a person appear to deliver a statement. This is a practical escalation test, not a universal legal definition. When the answer is unclear and the campaign carries rights or regulatory exposure, have counsel qualified in the relevant market review it.

    Treat compliance as four separate approval gates

    The common mistake is to treat an “AI-generated” label as a complete compliance solution. It is only one control. Your ad should pass four gates independently.

    1. Accuracy and eligibility

    Review the people, products, places, claims, and events depicted in the creative. Microsoft expects advertisers to check that those elements are accurate before submission. A disclosure explains how content was made; it does not make a false claim, prohibited deepfake, or deceptive demonstration acceptable.

    Run the review against the finished ad, not just the prompt. Generative systems can introduce details that nobody explicitly requested, so prompt approval is not creative approval. Compare the final asset with the real product, approved claim language, authorized spokesperson material, and the event or location it purports to show.

    2. Authorization

    Confirm that you have any permission required to use a person’s likeness or voice. Advertisers remain responsible for applicable laws in every market where a campaign appears, including requirements involving consent, permissions, disclosures, likenesses, and voices.

    Do not infer authorization from access to a photograph, recording, stock asset, or previous campaign file. Document what was authorized, for which media and markets, and whether synthetic alteration or voice replication falls within that authorization. If the permission does not clearly cover the planned use, pause the ad rather than relying on a label to fill the gap.

    3. Consumer disclosure

    Determine whether a visible or audible disclosure is required for that asset, format, and market. When notice is required, it must be clear and positioned close to the content it explains. Permission from the depicted person does not eliminate a separate disclosure obligation.

    4. Machine-readable provenance

    Preserve watermarks, metadata, and other available signals identifying how synthetic content was created. These signals support provenance, but they are not necessarily visible to a consumer. Passing the provenance gate therefore does not mean you have passed the disclosure gate.

    Approve the ad only when all four gates pass. That structure prevents a reviewer from answering one narrow question – “Does it have a label?” – while missing the reason the ad should not run at all.

    Put the disclosure where the consumer encounters the synthetic content

    A person views a tablet ad with an abstract disclosure symbol placed directly beside the synthetic image.

    An AI note in a production ticket, file name, landing-page footer, or internal media plan is not a consumer-facing disclosure. When disclosure is required, Microsoft recommends embedding it directly in image and video assets. Microsoft Advertising’s disclaimer feature can also be used with formats that support it.

    Use this placement process:

    1. Add the approved disclosure to the asset master, not only to one exported placement.
    2. Keep it close to the synthetic element or claim it qualifies. Do not make the viewer search another screen for the explanation.
    3. Match the disclosure mode to the experience. Image and video disclosures need to be visible; audio-led creative may also require an audible notice.
    4. Export every required size and format, then inspect the actual output. Cropping, compression, scaling, captions, and interface overlays can make a disclosure unreadable or separate it from the relevant content.
    5. Where the Microsoft Advertising disclaimer feature is supported, decide whether it should supplement or deliver the required notice for that format. Do not assume feature availability removes the need to inspect the consumer-facing result.
    6. Record the approved wording, placement, disclosure mode, markets, formats, and approver so later adaptations do not silently change the decision.

    Do not invent a single global font size, duration, or phrase and treat it as universally sufficient. The governing requirement is that the disclosure be clear, close to the relevant content, and compliant wherever the campaign runs. If a local rule or approval imposes more specific wording or presentation, carry that requirement into the asset specification.

    Localization deserves a new review. Translated wording can become longer, a resized layout can push the label out of view, and a newly added market can change the applicable requirement. Treat each of those changes as a controlled version, not a harmless derivative.

    Protect provenance and permission records throughout production

    A creative team preserves connected provenance markers while storing permission and approval records in a secure archive.

    Images, audio, and video created with Microsoft AI tools can contain machine-readable provenance data, metadata, and imperceptible watermarks indicating AI involvement. Because those signals may not be apparent to the audience, you may still need a separate visible or audible disclosure.

    Your production workflow should preserve both the technical evidence and the human approval record:

    • Keep the original AI output before retouching, resizing, or re-encoding.
    • Retain the working file and submitted export so reviewers can trace what changed.
    • Do not deliberately remove a watermark, metadata field, or provenance signal merely to make the file look cleaner.
    • Check whether your export process retained the provenance information present in the source asset.
    • Store documented likeness and voice authorization with the creative record, including any limits relevant to synthetic alteration.
    • Keep the market-by-market disclosure decision with the exact asset version it covers.
    • Save evidence of how the consumer-facing disclosure appears in the final format.

    This record is useful only if versioning is disciplined. A later editor should be able to tell whether a new crop, translated label, revised voice track, or altered product scene reopened one of the four approval gates. “Approved” should never float free of a specific file and campaign scope.

    Interfering with machine-readable provenance information is not a harmless optimization. Along with prohibited deepfakes, impersonation, unauthorized use of a likeness or voice, and omitted required disclosures, it can contribute to an ad being rejected, restricted, or removed.

    Use a repeatable approval workflow before every submission

    Build the review into campaign operations instead of asking the media buyer to reconstruct the creative history at launch. The following workflow is specific enough to assign owners and flexible enough to use across image, video, audio, and copy-led ads.

    1. Inventory AI involvement. Record which portions of the ad were generated or materially altered and retain the original outputs.
    2. Map distribution. List the markets, languages, Microsoft Advertising formats, and derivative sizes planned for the campaign.
    3. Challenge accuracy. Verify every depicted person, product, place, claim, and event against approved factual material.
    4. Clear rights. Confirm that any likeness or voice use has the authorization required for the specific synthetic use, media, and market.
    5. Screen for stop conditions. Do not submit deceptive creative, prohibited deepfakes, impersonation, or unresolved unauthorized use merely because a disclosure can be added.
    6. Make the disclosure decision. Determine the required wording, visible or audible treatment, proximity, and market coverage. Escalate unresolved legal questions to qualified counsel.
    7. Build the notice into production. Embed it in image or video assets when required and configure the platform disclaimer feature where supported and appropriate.
    8. Run final-output quality assurance. Confirm that the disclosure remains clear and close to the relevant content and that provenance information has not been stripped.
    9. Approve a specific version. Store the decision, evidence, permissions, asset identifier, formats, markets, and approver together. Reopen review after any material creative or distribution change.

    If an ad fails because its underlying depiction is deceptive or unauthorized, rebuild or withdraw it. Relabeling is not remediation. Microsoft is allowing AI-assisted advertising, but an AI disclosure does not make deceptive creative acceptable.

    Key takeaways

    • Route every AI-generated or materially altered ad through review, even when the synthetic work is difficult to notice.
    • Assess accuracy, authorization, disclosure, and provenance separately; success in one area does not cure failure in another.
    • When disclosure is required, make it clear, close to the relevant content, and part of the asset where appropriate.
    • Preserve metadata, watermarks, and other provenance signals, but do not mistake them for consumer-facing notice.
    • Do not use a label to justify a deepfake, impersonation, deceptive claim, or unauthorized likeness or voice.
    • Repeat the determination for each market, format, language, and materially changed creative version.

    Your next move is concrete: add five required fields to the creative intake form – AI involvement, likeness or voice use, target markets, disclosure decision, and provenance status. Assign an owner to each field before the asset enters paid-media production. That small change moves compliance from a last-minute label request to a reviewable part of how the ad is made.

    References