You checked an AI answer, saw your brand missing, and now you need to know whether you have a visibility problem. One response cannot answer that. AI recommendations vary between runs, and buyers can approach the same purchase through several different questions.
A useful monitoring program treats visibility as a measured distribution, not a rank. It samples real buying decisions, repeats prompts under controlled conditions, records how each brand is presented, and turns the resulting patterns into specific content and positioning work.
Key takeaways
- Monitor buyer decisions and prompt families, not a list of exact phrases that tries to imitate traditional keyword tracking.
- Run each prompt at least 10 times for a quick directional estimate. A single answer is an observation, not a baseline.
- Measure recommendation seats, prompt coverage, citations, cited pages, and buyer-fit descriptions separately.
- Keep prompt wording, search mode, environment, and run counts consistent when comparing one period with another.
- Use monitoring to diagnose the next action. A missing recommendation, an uncited mention, and an inaccurate best for description are different problems.
Define visibility before you try to measure it
AI search visibility is not simply whether your company name appears. An answer can cite your page without recommending your product. It can recommend your brand while linking to a review site. It can also place you on a shortlist but describe you as suitable for the wrong customer.
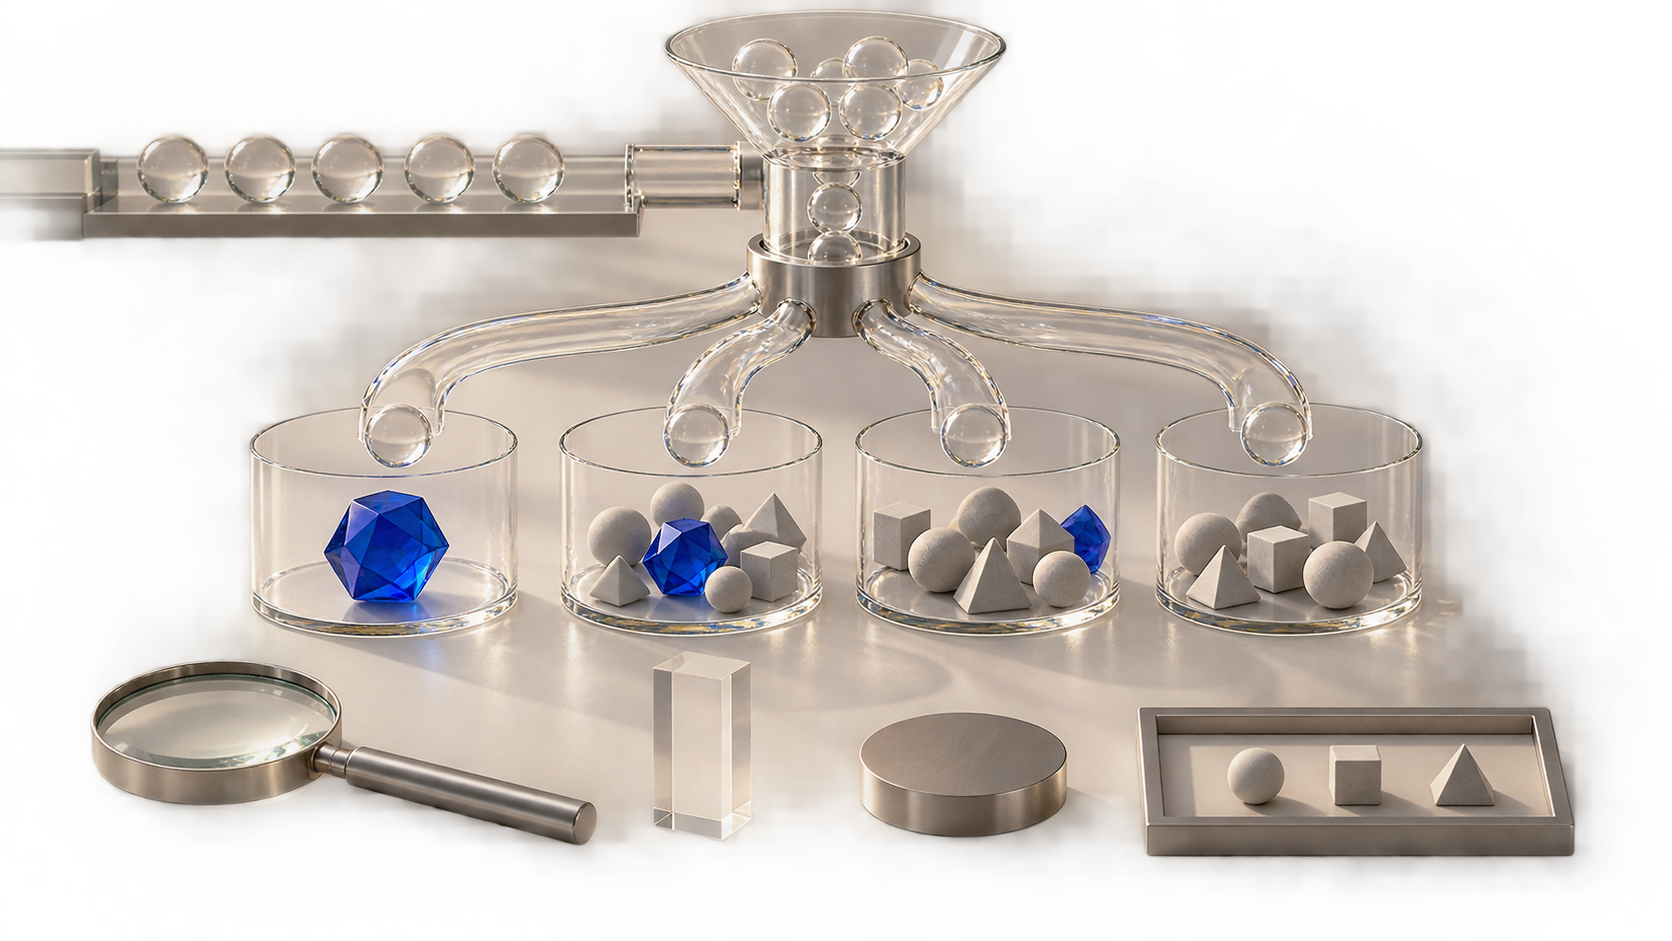
The distinction matters because AI-generated shortlists can be narrow. In one workforce-management sample, 100 responses contained an average of 5.6 recommended brands, while the referenced vendor directory contained 215 listings in the relevant category. That result belongs to one category and one test design, so it is not a universal benchmark. It does show why merely being eligible for consideration does not mean a brand will receive a seat.
Record these six layers for every completed run:
<!– wp:list {
Leave a Reply