Tag: AI Mode

  • How to Build Marketing Visibility in Google AI Mode

    How to Build Marketing Visibility in Google AI Mode

    If your search strategy still revolves around winning one short keyword with one broadly written page, Google AI Mode exposes the weakness quickly. A person can begin with a general question, add their location, budget, use case, risk tolerance, and exclusions, then keep refining the decision. Your visibility depends on whether your content remains useful as that conversation branches.

    The practical response is not to publish more generic copy or bolt AI language onto an existing SEO plan. You need distinctive, verifiable answers for organic discovery, suitable campaign inputs for paid eligibility, and reporting that does not pretend Google gives advertisers more placement-level visibility than it does.

    What visibility in AI Mode actually requires

    AI Mode is a conversational search experience. People can describe a complicated need in one prompt and narrow it through follow-up questions. Google said in October 2025 that these questions were nearly three times longer than traditional searches. That changes the unit of optimization. The keyword still matters, but so do the constraints, comparisons, exceptions, and decisions surrounding it.

    The scale warrants attention without justifying panic. By May, AI Mode had surpassed 1 billion monthly users. Paid visibility is also material, although it varies by query set and test conditions. In one July SE Ranking analysis, text ads appeared in 29.45% of responses across 50,032 selected U.S. commercial keywords, with product carousels excluded. That figure is evidence of opportunity in that sample, not a universal ad frequency you should use in a forecast.

    Key takeaways

    • Optimize for the buyer’s decision path, not just the opening query.
    • Use AI Mode’s follow-up questions to find missing answers that ordinary competitor audits overlook.
    • Build pages from verified facts, first-party expertise, and explicit boundaries instead of interchangeable claims.
    • Treat AI Mode, AI Max, and AI Overviews as different things. AI Mode is the customer experience; AI Max is an optimization layer inside eligible campaigns.
    • Keep organic visibility, paid eligibility, and business outcomes separate in reporting. Combine them only when the data supports the connection.

    That last distinction matters. A cited page, a named recommendation, and a sponsored placement are not the same outcome. They may support the same commercial journey, but they require different inputs and cannot be measured honestly as one blended AI visibility number.

    Map the questions behind the query before rewriting a page
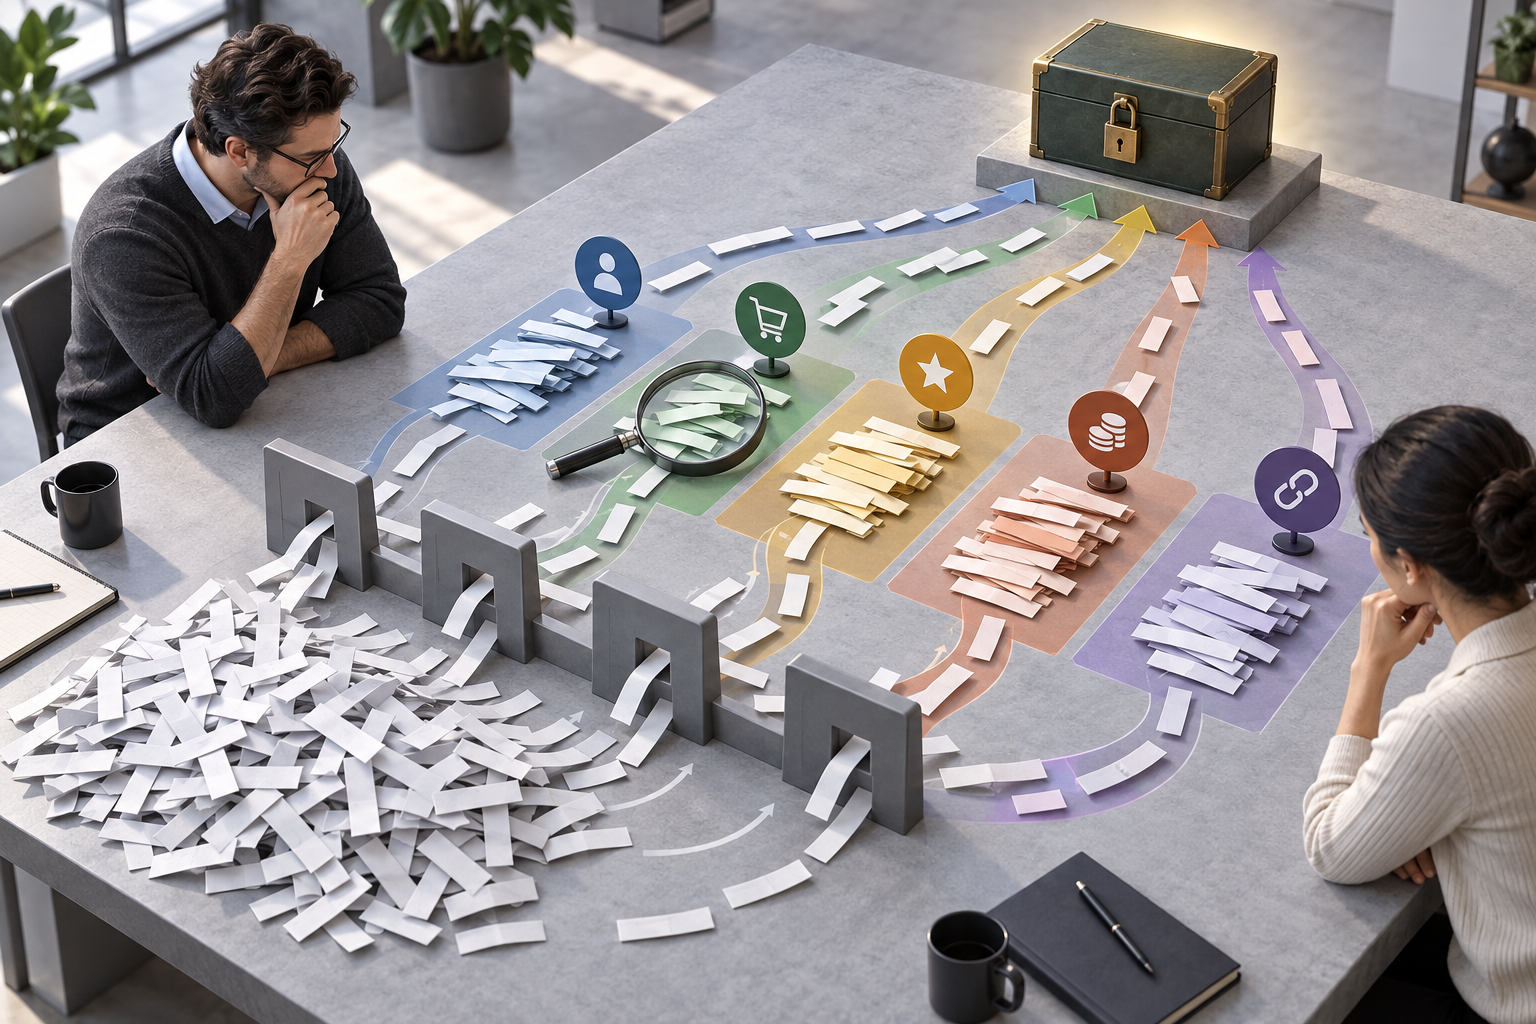
    An overhead desk scene shows a blank page connected by branching paths to objects representing location, budget, use case, timing, risk, and comparison questions.

    A conventional content audit tells you what competitors included. It rarely tells you what all of them omitted. If every service page repeats the same definition, benefits, and call to action, matching that pattern only makes your page another interchangeable input.

    AI Mode’s follow-up questions offer a more useful gap-discovery method. Begin with the natural-language question a serious buyer would ask, then watch where the conversation goes. Repeated branches reveal the details someone needs before they can decide, including conditions, thresholds, local differences, edge cases, and tradeoffs. Those branches can become your content map rather than an indiscriminate FAQ list.

    Run the query-branch audit

    1. Choose one commercially important page. Pick a service, product, or category page tied to a real decision. Do not begin with the entire site.
    2. Write the buyer’s opening question. Use a complete sentence that includes the problem and any context a genuine prospect would volunteer. A query such as “Which option fits a small team that needs approval controls but has no dedicated administrator?” is more revealing than a two-word category term.
    3. Record each follow-up question exactly. Preserve the wording. It shows you the terminology Google associates with the decision and the distinctions users may encounter next.
    4. Classify the branch. Mark whether it concerns suitability, cost, timing, location, requirements, risk, comparison, exception, proof, or next steps. This prevents ten differently phrased questions from becoming ten repetitive sections.
    5. Note what changes the answer. A useful answer often depends on company size, jurisdiction, product version, service area, eligibility, configuration, or another boundary. Capture that condition instead of writing a universal claim.
    6. Compare the branch with your page. Mark it answered, partly answered, unsupported, or absent. “Mentioned” is not the same as answered; a buyer should be able to understand the decision without decoding promotional language.
    7. Identify the evidence owner. Decide whether the answer belongs to a public reference, an internal record, a product owner, a practitioner, a customer-facing team, or another qualified subject-matter expert.
    8. Prioritize the gap. Give priority to questions that materially change the decision, align with the page’s intent, and can be answered with defensible evidence. A high-volume-sounding question with no reliable answer is not ready to publish.

    Follow-up questions are signals, not automatic editorial instructions. A suggested question may be irrelevant to your offer, impossible to verify, or better answered elsewhere. Your job is to interpret the branch, determine whether it affects the buyer’s decision, and then place the answer where it belongs.

    Decide whether the answer needs a section or its own page

    Add a section to the existing page when the question shares the same intent and can be answered without changing the page’s audience or promise. Create a separate page when the question represents a distinct task, requires substantial evidence, serves a materially different situation, or deserves a direct landing destination of its own.

    For example, an eligibility condition that determines whether someone can use a service probably belongs near the main answer. A detailed implementation workflow for people who have already chosen the service may deserve a supporting page. Link the two in the direction the buyer naturally moves.

    This method is especially valuable for local pages. Google has deep context about places, businesses, and nearby entities, so a city name inserted into a generic template is a weak differentiator. Useful local content explains the actual service area, process, venue, constraints, availability, and decision rules that change with location. Only publish those details when the business can verify them.

    Turn content gaps into evidence-backed answers

    A plausible sentence is not necessarily a publishable fact. The fastest way to contaminate an AI visibility program is to let an unverified inference move from a generated brief into customer-facing copy. Keep a claim register while researching and drafting so every material statement has a status.

    Claim labelWhat it means in your workflowPublishing action
    OBSERVEDThe detail was directly seen in the page, product, interface, record, or documented process under review.Save enough context for an editor to reproduce the observation.
    VERIFIEDThe claim was checked against an appropriate public reference or authoritative record.Cite the evidence and retain any scope, date, version, or jurisdiction qualifier.
    CLIENT-SUPPLIEDThe business or its subject-matter expert provided the claim.Name the internal owner, request support where needed, and do not present it as independently verified.
    INFERREDThe claim is a conclusion drawn from related information rather than a directly supported fact.Label it as interpretation or replace it with a supported statement before publication.
    UNKNOWNThe available material does not establish an answer.Turn the gap into a precise question for the responsible expert. Do not let a writing model fill it.

    This separation is not bureaucratic overhead. It allows public facts, internal evidence, and expert judgment to contribute without being mistaken for one another. A documented workflow built around these labels also prevents unsupported claims about experience, volume, outcomes, prices, or performance from slipping into a page because they sound reasonable.

    When a claim could affect someone’s legal rights, financial decision, safety, or regulatory exposure, route it to a qualified professional before publication. The downside is not merely a weak citation. An incorrect threshold or eligibility rule can cause a reader to make the wrong decision.

    Write the answer before the marketing copy

    Each prioritized branch should become an answer-first brief. Start with the direct response a buyer needs, then supply the conditions and evidence that make it trustworthy. A usable brief contains:

    • the buyer’s question in natural language;
    • a one- or two-sentence direct answer;
    • the conditions that would change that answer;
    • the supporting facts and their claim labels;
    • any unresolved question for a subject-matter expert;
    • the accuracy, legal, or version risk that needs review;
    • the intended location: existing section, new page, comparison page, or supporting resource;
    • the prompts you will use to retest visibility after publication.

    The resulting page should help a person distinguish between options. Include the thresholds, limitations, tradeoffs, and next step when the evidence supports them. Replace claims such as “tailored solutions” or “leading service” with information only the business is well placed to provide: how qualification works, what the process includes, where exceptions arise, which input the customer must supply, and when a different option is a better fit.

    Use structured data as a representation layer, not an evidence generator. Markup can express the entities and information present on a page, but it cannot turn a generic assertion into first-party expertise or resolve an unsupported claim. The visible answer and its evidence come first; the schema should accurately reflect them.

    Prepare paid campaigns without confusing AI Mode and AI Max

    AI Mode is the search experience a customer uses. AI Max is a collection of targeting and creative features applied to an existing Search campaign. It can expand matching through broad match and keywordless technology, use information from keywords, creative, and URLs, and adapt copy or destinations through text customization and Final URL Expansion. It is an optimization layer, not a separate campaign type.

    There is also no separate AI Mode campaign or placement switch. Turning on AI Max does not select AI Mode inventory. This distinction protects you from a common reporting error: attributing every performance change after an AI Max launch to AI Mode placements.

    Know which campaign routes are eligible

    Google’s original May 2025 announcement identified Performance Max, Shopping, and Search campaigns using broad match, including AI Max for Search, as eligible for AI Mode ad testing. At Google Marketing Live 2026, Google recommended AI Max for Search, AI Max for Shopping, and Performance Max for access to newer AI-powered formats; AI Max for Shopping was documented as a beta.

    A smaller experiment also allowed Search campaigns using exact and phrase match to serve text ads when an AI Mode user expressed clear, direct intent. Treat that as a limited test, not proof that conventional matching reaches every AI Mode format.

    FormatHow it appearsStatus in the cited announcement
    Existing text and Shopping adsEligible ads can appear within AI Mode responses.Testing
    Conversational Discovery adsGemini tailors creative to the user’s expressed need.Testing
    Highlighted AnswersSponsored businesses appear within recommendation lists with an AI-generated explanation alongside advertiser creative.Testing
    Direct OffersRelevant promotions can appear during shopping conversations.Pilot

    Testing and pilot status matters. A format described by Google may not be available in every account or country, and an eligible campaign is not guaranteed to appear. Confirm what your account actually exposes before building a media plan around a named format.

    Improve the inputs Google may use

    In conversational placements, your ad may sit inside a larger generated presentation. Google can use the user’s question, advertiser inputs, and landing-page context to decide what fits. Your work therefore extends beyond writing a compact headline.

    • Align the destination with the detailed need. A generic homepage is a poor continuation when the prompt includes a specific use case, constraint, or product requirement.
    • Keep product and offer information accurate. Do not rely on generated context to repair stale availability, unclear terms, or contradictory landing-page copy.
    • Make differentiators verifiable. The same first-party facts that strengthen organic content give the paid system clearer material to work with.
    • Review URL expansion deliberately. If the setting is active, make sure eligible destinations are current, appropriate, and able to convert the intent they may receive.
    • Document campaign changes. Record when AI Max, matching, creative, feeds, destinations, budgets, or conversion settings change. Avoid treating a period with several simultaneous changes as a clean AI Mode test.
    • Check the generated context when visible. Your approved creative may be only one part of the presentation. Watch for a mismatch between the reason Google gives, the promise in the ad, and the page a person reaches.

    Do not broaden matching solely to claim AI Mode participation. First decide whether the campaign has dependable conversion measurement, suitable landing pages, accurate business data, and enough control for the risk you are accepting. Eligibility is an input to the decision, not the business case by itself.

    Measure visibility without inventing AI Mode attribution
    Separate glass channels carry search, citation, campaign, and purchase signals toward measurement instruments without directly connecting them.

    Google currently gives advertisers limited ability to isolate and measure ads within AI Mode. That constraint should shape your dashboard and the language you use with stakeholders. If the interface does not identify the placement, label the result unknown rather than assigning it to AI Mode because a campaign was eligible.

    Build a controlled query set

    Maintain a compact set of commercially meaningful prompts for each priority topic. Include the opening buyer question, a local or operational constraint, a comparison, an exception, and a late-stage next-step query. Run the same set repeatedly so you can notice changes in answer coverage instead of collecting unrelated screenshots.

    For each observation, record:

    • the exact prompt and follow-up path;
    • the market, device context, and date of the check;
    • whether your brand or page appeared;
    • whether it appeared as a cited resource, named option, direct link, or sponsored result;
    • the claim or passage used to represent the business;
    • the destination page;
    • any inaccurate, outdated, or missing context;
    • the next content or campaign action, if the observation is reproducible and material.

    Call this an observation log, not a ranking report. Conversational answers can vary with wording and follow-up context, so a single appearance is not a permanent position. The log becomes useful when the same gaps or representations recur across your controlled query set.

    Keep three layers of reporting separate

    • Answer visibility: Are your pages and brand present for the questions that matter, and are they represented accurately?
    • Paid readiness and delivery: Are campaigns eligible, are advertiser inputs sound, and what delivery can the available Google Ads reporting actually verify?
    • Business outcomes: What qualified visits, leads, sales, revenue, or other approved conversion signals reached the business?

    Use these layers to make bounded decisions. If an important branch is repeatedly unanswered and your page lacks the information, you have a content gap. If the brand appears for the wrong use case, clarify its fit and exclusions. If an eligible campaign improves after several settings changed, report the campaign-level change but do not call it AI Mode return on ad spend without placement-level evidence. If traffic arrives but fails to progress, inspect the promise-to-page match before expanding reach.

    Start with one high-value page and one natural-language buyer question. Map its branches, resolve the most consequential unknown with the right expert, publish the direct answer, and retest the same path. Once the organic evidence is sound, evaluate paid eligibility as a separate decision. That small operating loop will teach you more than a sitewide rewrite built on assumptions.

    References


  • Google Ads AI Max Reporting and Direct Offers: A Control Plan

    Google Ads AI Max Reporting and Direct Offers: A Control Plan

    When Google Ads makes automation easier to deploy, your reporting has to get stricter. AI Max can expand targeting and apply brand or location-related controls, while Direct Offers can put a context-selected incentive in front of a shopper inside AI Mode. Those capabilities can help, but they also blend media optimization with commercial policy.

    Your job is to answer two separate questions: what was the automation allowed to do, and did it create profitable demand that would not otherwise have existed? A campaign can improve on an in-platform metric while quietly reaching a different audience, relaxing a targeting boundary, or discounting orders you could have won at full price. The control plan below is designed to expose those differences before you scale them.

    Start with permission reporting, not performance reporting

    Google Ads is adding AI Max reporting columns for Locations of interest, Optimized targeting and Brand inclusions. Add them to the campaign-level view before investigating a performance change. They tell you which controls are present, which is the first layer of any useful audit.

    Think of these fields as permission reporting. They describe what a campaign is configured to use; they do not prove that a setting caused an outcome. A conversion increase beside an enabled setting is a lead for investigation, not a causal conclusion.

    Reporting columnWhat it makes visibleWhat you should check
    Locations of interestWhich campaigns use location-of-interest settingsWhether campaigns being compared use the same geographic-intent configuration
    Optimized targetingWhere automated audience expansion is enabledWhether broader reach is intentional and whether it coincides with a change in traffic quality
    Brand inclusionsWhere brand inclusion settings are appliedWhether each campaign has the brand scope your strategy requires

    The columns are still rolling out and may not be visible in every account. If you cannot find one, do not treat its absence from the interface as evidence that the underlying behavior is disabled. Confirm the campaign settings directly until the reporting fields reach your account.

    Once the columns are available, build a repeatable campaign view:

    1. Add all three AI Max columns to the same view as the outcome metrics your team actually uses.
    2. Keep campaign identity, status and commercial objective visible so campaigns with different jobs are not compared as if they were interchangeable.
    3. Save a dated export or configuration record. That gives you a snapshot of the permissions in place when results were measured.
    4. Flag unexpected combinations, such as an expansion setting enabled on one campaign but not on otherwise comparable campaigns.
    5. Resolve configuration mistakes before interpreting performance. Analysis built on unintended settings only explains the wrong experiment more precisely.

    This view should let you scan from configuration to outcome in one row. If an analyst has to open every campaign individually to discover the relevant settings, setup differences are too easy to miss and too slow to audit.

    Compare configuration cohorts before explaining a performance gap

    Three parallel campaign pathways pass through different permission controls before reaching comparable shopper groups.

    Campaign averages become misleading when they combine different automation permissions. Create configuration cohorts instead. One cohort might contain campaigns with Optimized targeting enabled; another might contain campaigns without it. You can then subdivide them by Locations of interest and Brand inclusions when those distinctions matter to the question.

    Do not automatically call one cohort a control group. A credible comparison also needs a similar commercial objective, market, offer, audience opportunity and measurement setup. A branded campaign and a prospecting campaign remain different even if their three AI Max columns match exactly.

    Use this sequence when a campaign begins outperforming or underperforming its peers:

    1. Define the business symptom. State whether the issue is lead quality, sales volume, acquisition cost, conversion value or profit. Avoid the vague diagnosis that performance changed.
    2. Map the permission state. Record the values of Locations of interest, Optimized targeting and Brand inclusions for the affected campaign and its intended comparators.
    3. Separate mismatched campaigns. Compare like configurations first. If the difference disappears, the blended average was hiding a setup distinction.
    4. Check timing. Place the first visible performance change beside the dated configuration record and other campaign changes. A setting that was already stable before the change is a weaker explanation than one altered at the same time.
    5. Change one decision at a time where practical. If targeting, bidding, creative and promotion all change together, you may improve the result but lose the ability to explain why.
    6. Write down the interpretation. Record the setting, expected mechanism, primary metric and condition that would disprove your explanation.

    The last step is important. A statement such as “Optimized targeting improved the campaign” is too broad to test. A useful interpretation is narrower: enabling expansion was followed by more qualified conversions in comparable campaigns while cost and downstream quality stayed within the team’s accepted limits. That claim can be monitored and challenged.

    Also look for configuration drift. Two campaigns that were launched from the same template can stop being comparable after later edits. The new columns make that drift easier to spot, but only if somebody owns the exception review. Assign that check to a named role and run it on the same cadence as your normal campaign review.

    Build Direct Offers as governed promotions

    Direct Offers add a second kind of automation: Google can decide not only when an offer is relevant, but also which incentive to present. The beta-labeled asset can be created at the account or campaign level, and it is limited to campaigns using AI Max or text customization.

    The setup asks for an internal offer name, final URL and short description. Google AI uses the description to judge relevance and can generate the customer-facing offer text. If you provide multiple incentives, the system can select among them using the shopper’s behavior and context. That makes the description and incentive set part of your targeting logic, not just administrative copy.

    Start with a campaign-level pilot unless you have a clear reason to expose the offer across the account. A campaign-level asset narrows the commercial blast radius and makes it easier to connect claims and redemptions to a defined test population.

    Use the following launch checklist:

    • Name the offer for analysis. Include the campaign or product scope, incentive and intended run period in the internal name. Someone reviewing an export later should not have to decode Offer 1.
    • Send traffic to the exact destination. The final URL should land where the promoted product, service or eligibility conditions can be understood and the incentive can actually be redeemed.
    • Write the description as an AI instruction. State what is being offered and the context in which it is relevant. Do not rely on clever promotional language to carry eligibility rules.
    • Begin with one incentive. Multiple incentives are supported, but allowing AI to choose among them immediately makes the first result harder to interpret. Establish a baseline before testing an incentive set.
    • Use a dedicated code batch. Single-use promotional codes can be uploaded by CSV. Keep the pilot’s codes separate so a redemption can be reconciled to the offer rather than mixed with codes from email, affiliates or customer support.
    • Set the contractual boundaries. Add the applicable terms and conditions, terms URL, start date and end date. Make sure the landing page and checkout enforce the same promise the shopper sees.
    • Cap the exposure. Direct Offers support daily limits based on total offer value or number of claims. Select the type that controls your real constraint, then set it before activation.

    A claim-count limit is useful when code inventory or fulfillment capacity is scarce. A total-value limit gives you a closer control on financial exposure, especially when incentives have different values. Neither replaces a complete promotional budget because a claim is not necessarily a redemption and a redemption is not necessarily an incremental sale.

    The shopper can see an eligible promotion beneath a sponsored result in AI Mode as a Claim one-time code option. Opening it reveals the offer details and code, along with a button to visit the advertiser’s website. Review the entire handoff from that promise to the landing page and checkout. If the displayed terms and the site experience disagree, pause the offer rather than asking support staff to repair the mismatch after purchase.

    Promotional terms can also create financial and legal exposure. If eligibility, expiry, exclusions or consumer rights require formal review in your market, put the Direct Offer through the same legal and operational approval process as any other public promotion. AI-selected delivery does not make the underlying promise less binding.

    Measure discount economics beyond claims and conversions

    A promotional tag, shopping basket, cost layers, approval gate, and branching purchase paths form a visual model of discount economics.

    A Direct Offer has at least six commercially distinct events: the offer is shown, its details are opened, a code is claimed, the shopper reaches the site, the code is redeemed and an order is completed. Do not collapse that chain into a single conversion number. Each transition answers a different question.

    DecisionMeasurementWhat a problem can mean
    Is the offer attracting attention?Claims or detail opens relative to observable offer exposureThe incentive, relevance decision or presentation is not compelling enough to prompt action
    Can shoppers use it?Redeemed codes relative to claimed codesThe site journey, eligibility rules, expiry or checkout process is creating friction
    Does it produce completed business?Completed orders and revenue tied to redeemed codesClaims are not progressing to purchases, or order tracking is incomplete
    Is the promotion affordable?Realized discount cost and contribution after the discountAdditional sales may still be eroding margin
    Is the result incremental?Difference versus a credible unoffered comparisonThe offer may be subsidizing orders that would have occurred at full price

    Use the denominator you can actually observe, and label it precisely. Claims divided by offer views is not the same metric as claims divided by sponsored-result impressions. If a required exposure event is not available in your account, report the narrower metric rather than manufacturing a rate from incompatible events.

    Reconcile the advertising record with your commerce or lead system. The promotional code is the bridge: it lets you distinguish a code that was claimed from one that was redeemed, and a redemption from an order that remained valid after returns, cancellations or lead qualification. Do not assume the Google Ads interface contains every downstream business outcome you need.

    Track the realized discount separately from media spend. A promotion can improve conversion efficiency inside an ad platform while the associated margin reduction appears only in the order system. Your decision table should therefore place ad cost, discount cost and contribution in the same review, even if the data originates in different systems.

    Redemption alone cannot establish incrementality. Some shoppers who use a code would have purchased without one. The cleanest test is a randomized unoffered group when your setup supports it. If it does not, use the closest comparable campaign or audience cohort you can maintain, keep other meaningful changes stable and document the limitations. A simple before-and-after comparison is weaker because seasonality, demand shifts and other campaign edits can move at the same time.

    Set decision rules before the pilot starts:

    • The maximum daily offer value or claim count you will permit.
    • The minimum contribution the promoted orders must retain.
    • The comparison you will use to judge incremental orders or leads.
    • The code redemption and completed-order events that must reconcile.
    • The conditions that trigger a pause, such as exhausted code inventory, a checkout failure, incorrect terms or unacceptable margin.
    • The evidence required before you add more incentives or move from campaign-level to account-level deployment.

    Read the failure pattern, not just the final total. Many claims with few redemptions points toward a broken or confusing handoff. Many redemptions without incremental growth points toward cannibalization. Few claims followed by strong purchase quality may indicate narrow relevance or limited exposure; it does not automatically justify a larger discount. Each pattern calls for a different response.

    Key takeaways

    • The new AI Max columns expose campaign permissions; they do not prove why performance changed.
    • Compare campaigns in configuration cohorts before attributing a result to Locations of interest, Optimized targeting or Brand inclusions.
    • Start a Direct Offer at campaign level with one incentive when you need a test that is easier to interpret and contain.
    • Treat the offer description as an input to AI relevance and generated copy, not as a private note.
    • Use claim limits for operational scarcity and value limits for financial exposure, then track the full promotional budget outside the asset.
    • Judge success through redemptions, completed outcomes, realized discount cost, contribution and incrementality – not claim volume alone.

    When the new columns appear in your account, export the current permission state before changing anything. Then choose one eligible campaign, document its baseline, connect a dedicated code batch to completed-order data and launch only with a hard exposure limit. That gives Google room to optimize while preserving your ability to explain what happened and decide whether it deserves to scale.

    References


  • AI Search Visibility Monitoring: A Repeatable Framework

    AI Search Visibility Monitoring: A Repeatable Framework

    You checked an AI answer, saw your brand missing, and now you need to know whether you have a visibility problem. One response cannot answer that. AI recommendations vary between runs, and buyers can approach the same purchase through several different questions.

    A useful monitoring program treats visibility as a measured distribution, not a rank. It samples real buying decisions, repeats prompts under controlled conditions, records how each brand is presented, and turns the resulting patterns into specific content and positioning work.

    Key takeaways

    • Monitor buyer decisions and prompt families, not a list of exact phrases that tries to imitate traditional keyword tracking.
    • Run each prompt at least 10 times for a quick directional estimate. A single answer is an observation, not a baseline.
    • Measure recommendation seats, prompt coverage, citations, cited pages, and buyer-fit descriptions separately.
    • Keep prompt wording, search mode, environment, and run counts consistent when comparing one period with another.
    • Use monitoring to diagnose the next action. A missing recommendation, an uncited mention, and an inaccurate best for description are different problems.

    Define visibility before you try to measure it

    Transparent chambers show the same blue marker as prominent, peripheral, grouped with alternatives, or absent after repeated inputs.

    AI search visibility is not simply whether your company name appears. An answer can cite your page without recommending your product. It can recommend your brand while linking to a review site. It can also place you on a shortlist but describe you as suitable for the wrong customer.

    The distinction matters because AI-generated shortlists can be narrow. In one workforce-management sample, 100 responses contained an average of 5.6 recommended brands, while the referenced vendor directory contained 215 listings in the relevant category. That result belongs to one category and one test design, so it is not a universal benchmark. It does show why merely being eligible for consideration does not mean a brand will receive a seat.

    Record these six layers for every completed run:

    <!– wp:list {
  • Google Search Ranking Factors in 2026: What to Prioritize

    Google Search Ranking Factors in 2026: What to Prioritize

    If your rankings have stalled, the answer probably is not another hundred-item SEO checklist. The useful question is narrower: which improvements can still separate your page from competent competitors, and which ones merely keep you eligible to compete?

    In 2026, the strongest plan starts with satisfying content, deep subject coverage, and evidence that real searchers find the page useful. Titles, links, trust, brand recognition, freshness, and technical health still matter, but they play different roles. You need to know whether each signal creates an advantage, confirms relevance, supplies proof, or clears a minimum threshold.

    The 2026 priority map: advantage signals versus thresholds

    Use the percentages below as a directional resource-allocation model, not as Google’s official formula. These estimated 2026 weights come from a single long-running agency dataset. They can help you decide where to invest, but they cannot predict the ranking of every page for every query.

    Ranking factorEstimated 2026 weightChange from 2025Practical role
    Consistent publication of satisfying content24%Up 1 pointPrimary competitive advantage
    Niche expertise14%Up 1 pointTopical depth and retrieval coverage
    Searcher engagement13%Up 1 pointEvidence that the page resolves the visit
    Keyword in the meta title12%Down 2 pointsRelevance and click expectation
    Backlinks12%Down 1 pointExternal authority and corroboration
    Freshness6%UnchangedContinued accuracy and usefulness
    Trustworthiness5%Up 1 pointAuthorship, evidence, and accountability
    Mobile-friendly, mobile-first site4%Down 1 pointTechnical threshold
    Link distribution diversity3%UnchangedBreadth of external validation
    Page speed2%Down 1 pointTechnical threshold and usability
    Brand mentions2%New as a standalone factorEntity recognition and reputation
    Site security and SSL1%Down 1 pointTechnical threshold
    Internal links1%UnchangedDiscovery, hierarchy, and context
    Meta descriptions and 22 other factors1% combinedNot specifiedSupporting signals

    Do not turn this table into a page score. A technically perfect page does not earn a fixed number of ranking points, and publishing more often does not compensate for failing the searcher’s task. The weights are most useful at the portfolio level: they show where marginal investment is likely to produce differentiation and where compliance has become commonplace.

    Key takeaways

    • The three leading content and audience factors account for 51% of the estimated weighting: satisfying publication at 24%, niche expertise at 14%, and searcher engagement at 13%.
    • Titles and backlinks still account for 24% combined. Their declining weights mean they are no longer adequate substitutes for a weak page, not that you can ignore them.
    • Mobile friendliness, page speed, and security total 7% in the model. They behave more like eligibility thresholds because competent sites commonly meet them.
    • Schema markup, header keywords, URL keywords, meta-description keywords, and numerous smaller signals share a 1% residual group. Treat them as supporting implementation, not the center of your ranking strategy.

    Build content around complete search tasks, not publishing quotas

    A researcher at a desk brings connected source materials and visual information fragments together into one complete solution.

    Consistent publication leads the model only when the content satisfies the search. Across one agency’s client sites during the March and May 2026 core updates, sites publishing weekly gained an average of 3.8 positions on their hub keywords, while sites publishing less than monthly lost an average of 2.7 positions. That is useful directional evidence, but it does not make weekly publishing a universal rule. The meaningful variable is a sustainable flow of pages that finish a real search task.

    Volume without satisfaction can become a liability. If your team can produce one defensible page that answers the question, shows its reasoning, and helps the reader decide what to do, that page is more valuable than a cluster of near-duplicates written to occupy keyword variations.

    Design a hub for query fan-out

    Google’s AI Mode can use query fan-out to break a question into related sub-searches and retrieve different pages for the resulting needs. That favors sites with coherent depth across a subject. It does not justify making a page for every minor wording change.

    1. Name the hub’s core problem. Write it as a task the reader needs to complete, not as a broad category your company wants to own.
    2. Map meaningful dimensions. Look for genuinely different industries, use cases, customer types, specialties, constraints, and decision stages. A dimension deserves its own page only when the answer materially changes.
    3. Assign one best page to each intent. If several URLs would give essentially the same answer, consolidate them instead of forcing artificial distinctions.
    4. Give every supporting page a job. It should answer its own question, connect back to the hub, and direct the reader to the next relevant decision.
    5. Identify the missing evidence. Add the comparison, process, example, definition, limitation, original data, or decision rule that competing pages leave unresolved.

    This approach builds niche expertise through coverage and coherence. A site becomes easier to retrieve across related sub-searches because each page has a distinct purpose inside a recognizable body of work.

    Use engagement to diagnose the page, not manipulate a metric

    Searcher engagement rose to 13% for the fourth consecutive annual increase. AI Overviews and AI Mode can resolve simple informational needs before a website visit, leaving a smaller pool of people who click because they need detail, evaluation, or action. Those visitors notice generic content quickly.

    Do not reduce this to a campaign to increase time on page. Google has not handed you a public formula that converts an analytics metric into ranking points. Use behavior as diagnostic evidence instead:

    • Does the opening answer the query immediately, or make the reader cross an essay-length preamble?
    • Can a visitor find the relevant comparison, instruction, definition, or limitation without hunting through unrelated sections?
    • Does the page support the likely next action, such as checking a requirement, choosing an option, or moving to a more specific page?
    • Are visitors encountering a mismatch between the title’s promise and the page’s actual depth?

    Fix the underlying experience. Removing padded introductions, making distinctions explicit, and placing the decisive information where it is needed are more durable choices than adding interaction for its own sake.

    Make relevance, authority, trust, and brand reinforce one another

    Titles, backlinks, trust signals, and brand mentions answer different versions of the same question: why should Google select this page from this site for this search? Treating them as one coordinated proof system produces a stronger result than optimizing each in isolation.

    Write titles for clear meaning rather than exact-match repetition

    The keyword in the meta title fell from 14% to 12%, the largest decline in the 2026 weighting. Google’s May 2026 search-box redesign encouraged longer, conversational queries, making the page’s overall meaning more important than an exact string match. The title still functions as a prerequisite-level relevance signal and sets the searcher’s expectation.

    • State the main subject in language your intended reader will recognize.
    • Add the qualifier that changes the answer, such as the year, platform, audience, use case, or decision type.
    • Describe the value of the page without promising a result the content cannot deliver.
    • Remove repeated keyword variants that make the title less readable without clarifying its scope.

    A good title is not a bag of terms. It is a compact contract: this is the subject, this is the version of the problem being addressed, and this is what the reader can expect to resolve.

    Earn links with something worth citing

    Backlinks declined to 12%, continuing an eight-year downward trend, while link distribution diversity remained at 3%. Links are still meaningful evidence, but the useful links are increasingly editorial: another publisher chooses to reference your original data, resource, or explanation because it improves their own work.

    Before running outreach, ask what the recipient would actually cite. A well-defined dataset, transparent benchmark, reusable template, calculator, primary-source collection, or unusually clear decision framework gives outreach a reason to exist. A routine article with no distinctive evidence leaves you negotiating for a link rather than earning one.

    Avoid manufactured link patterns. Recent spam enforcement has focused on attempts to borrow or fabricate authority, so the downside is not limited to wasting budget. The safer strategy is to create a reference-worthy asset, identify publications whose readers genuinely need it, and explain the precise section where it contributes evidence.

    Make trust visible at the claim level

    Trustworthiness rose from 4% to 5% as low-cost AI-generated content increased the supply of plausible-looking pages. Clear authorship and credible support now help distinguish accountable information from text that merely sounds confident.

    • Identify who wrote or reviewed the page and why that person is qualified to address the subject.
    • Link factual claims to the evidence that supports them, placing the citation beside the relevant claim.
    • Separate documented facts from your interpretation, recommendation, or forecast.
    • Disclose material limitations instead of hiding the conditions under which the advice stops working.
    • Show a meaningful update date when the page has actually been reviewed or changed.
    • Make the site’s ownership, editorial responsibility, and contact path easy to verify.

    Do not assume a trusted domain can safely publish unrelated third-party material. Google’s enforcement of its site-reputation-abuse policy specifically challenges the idea that content can inherit authority merely by being hosted on a strong domain. Topical fit and editorial accountability still have to be real.

    Treat brand mentions as external corroboration

    Brand mentions entered the standalone list at an estimated 2% in 2026. Relevant mentions in authoritative publications can help establish that a company is a recognized entity with a reputation, even when every mention does not carry a link. The same public evidence can also influence whether generative systems encounter and understand the brand.

    This is not permission to flood low-quality sites with a company name. Pursue coverage where the brand contributes something verifiable: data, expert analysis, a useful tool, a documented initiative, or a defensible point of view. Track linked and unlinked coverage separately, correct naming inconsistencies, and make sure the facts on your own site agree with the facts publishers can verify elsewhere.

    Keep technical SEO above the floor and use freshness for gains

    Mobile friendliness declined to 4%, page speed to 2%, and site security to 1%. Those drops do not mean the requirements stopped mattering. Compliance is now common enough to differentiate fewer competent sites, while falling below the expected standard can still hurt disproportionately.

    Think of technical health as the floor beneath the content strategy. Before polishing a title or commissioning outreach, verify that:

    • The important page can be crawled, rendered, indexed, and assigned the intended canonical URL.
    • The mobile version contains the primary content and actions rather than a reduced or obstructed experience.
    • Core templates load without unnecessary delay or disruptive layout movement.
    • HTTPS works consistently, with no broken redirects or insecure resources undermining the page.
    • Navigation and internal links expose the hub structure to users and crawlers.

    Once those conditions are stable, another marginal technical tweak may have less value than improving the answer or adding missing topical coverage. Fix genuine failures; do not keep rebuilding an already competent foundation because technical work is easier to measure than content quality.

    Refresh substance, not timestamps

    Freshness held at 6%, and pages updated within the preceding year continued to outrank comparable untouched pages in the tracked client data. The useful interpretation is not that every page needs an annual date change. A refresh should remove decay and restore usefulness.

    • Recheck claims, dates, product behavior, screenshots, citations, and outbound links.
    • Compare the page’s scope with the current search task and add newly important distinctions.
    • Replace obsolete examples rather than placing a new paragraph above them.
    • Review internal links in both directions so newer supporting pages strengthen the hub.
    • Update the visible date only when the review produced a meaningful change.

    Keep schema in its proper role

    Schema markup, header keywords, URL keywords, meta-description keywords, and 19 other signals sit inside a combined 1% group. The tracked results did not show measurable ranking movement from structured data itself, despite broad claims that schema is the key to inclusion in AI-generated answers.

    That does not make schema useless. Keep accurate structured data that describes the visible page and its entities, but do not mistake machine-readable labels for substantive authority. Schema cannot supply missing evidence, topical depth, trustworthy authorship, editorial links, or a satisfying answer. The correct sequence is to create the real information first and mark it up faithfully second.

    Use a page-level decision order instead of a flat checklist

    An isometric web page follows an ascending path through technical, relevance, evidence, and user-engagement stages.

    A flat audit encourages teams to fix whichever issue is easiest to count. A decision order forces you to address dependencies first. Run each important page through these gates:

    1. Can the page compete at all? Resolve crawling, indexing, canonical, mobile, security, and serious performance failures before making editorial refinements.
    2. Does it resolve one identifiable search task? If the purpose is vague, choose the intended query and reader decision before rewriting individual sections.
    3. Is it the strongest page on your site for that task? Merge overlapping URLs, redirect obsolete versions where appropriate, and stop internal competition.
    4. Does it belong to a coherent hub? Connect the page to broader and narrower resources, then identify genuinely missing industry, use-case, customer-type, or specialty coverage.
    5. Does the title set the right expectation? Make the subject and decisive qualifier clear without repeating keyword variants.
    6. Can the reader verify the important claims? Add accountable authorship, direct citations, transparent reasoning, limitations, and a meaningful update record.
    7. Is there a reason for outside recognition? Develop evidence or a reusable asset that can earn editorial links, diverse references, and credible brand mentions.
    8. Does visitor behavior expose an unresolved need? Look for title-content mismatch, buried answers, missing comparisons, weak next steps, and sections that do not help the intended decision.

    The order matters. Schema refinements will not rescue an inaccessible page. A faster template will not make a generic answer distinctive. Outreach will not create durable authority when the target page offers nothing worth citing.

    Start with your most commercially important hub. Map the search tasks it must cover, choose the page that most clearly fails its reader, and repair that page from the technical floor upward. Then fill one meaningful coverage gap and create one asset that deserves external recognition. That sequence turns ranking-factor theory into work your team can assign, review, and improve.

    References


  • SEO for AI-Mediated Search: A Practical Visibility Plan

    SEO for AI-Mediated Search: A Practical Visibility Plan

    Your rankings can look healthy while your brand is missing from the answer a customer actually sees. Or an AI system can mention you, describe you incorrectly, and send no visit that your analytics can attribute. If you still judge organic performance only by positions and clicks, those failures stay hidden.

    The practical response is not to abandon SEO for a new acronym. It is to extend your existing search system so that machines can retrieve your pages, understand your entities, quote your claims, represent your brand accurately, and give an interested person a clear route to act.

    Run SEO and AI visibility as separate, connected scorecards

    Traditional rankings tell you whether a URL can compete in a search results page. They do not tell you whether ChatGPT, Gemini, Google AI Mode, or another generated-answer experience mentions your brand, cites your site, or repeats the right facts. AI visibility therefore needs its own measurements.

    This distinction matters because an answer interface can satisfy part of a search without passing the user to a website. In a March 2026 randomized field experiment involving 1,100 U.S. Chrome users, forcing nearly 95% of searches through Google AI Mode reduced the share that led to an external website by 18.8 percentage points. Participants also reported lower satisfaction, usefulness, control, personalization, and trust than people using Google normally.

    Do not turn that number into a universal traffic forecast. The treatment lasted seven days, the sample skewed younger, highly educated, and politically left-leaning, and participants were pushed into AI Mode rather than choosing it. The sound conclusion is narrower: AI-mediated discovery can materially reduce referral opportunities, and fewer clicks do not necessarily mean the answer experience served the user better.

    Build your reporting around three connected outcomes:

    • Retrieval: Can search engines and answer systems find the right page for the question? Track crawlability, indexation, rankings, relevant internal links, and whether the page appears as a cited or consulted resource.
    • Representation: Does the generated answer name the correct entity, describe it accurately, preserve important qualifications, and link to the appropriate URL? A positive-sounding mention is still a failure if it assigns the wrong feature, location, price, audience, or availability.
    • Response: What happens after exposure? Track referral visits where they are available, branded demand, assisted conversions, leads, sales, bookings, subscriptions, or the business action appropriate to the page.

    Keep these columns separate. A mention is not a citation. A citation is not a visit. A visit is not a conversion. Combining them into one visibility score hides the exact problem you need to fix.

    Turn keyword research into a prompt-and-decision map

    An overhead worktable displays blank cards, colored markers, branching threads, and comparison objects arranged from broad research to final choices.

    Keywords still reveal language, demand, and the pages competing for attention. Prompts reveal something different: the decision a person is trying to make, the conditions attached to it, and the comparison set an AI system may assemble before answering.

    A query such as “project management software” names a category. A prompt such as “Which project management platform suits a distributed agency that needs client approvals but has no dedicated administrator?” also supplies an audience, operating constraint, required capability, and evaluation criterion. A generic category page may rank for the first expression and still be unusable for the second.

    Create a prompt map for each product, service, location, person, or topic that matters commercially:

    1. Choose the entity. Start with one thing you need an answer engine to understand unambiguously: a product, service, organization, location, event, or expert.
    2. List the decisions surrounding it. Include discovery, comparison, validation, objection handling, and action. These are different information needs and may require different pages.
    3. Add real constraints. Capture the audience, use case, location, compatibility requirement, budget condition, risk, or desired outcome that changes the answer.
    4. Assign a canonical destination. Decide which page should answer each prompt family. If several URLs compete to make the same claim, consolidate the information or define a clear primary page.
    5. Record the proof required. Specifications, policies, examples, qualifications, prices, availability, authorship, and dates should sit close to the claims they support.
    6. Define the next action. A person who wants more than the generated answer should land on a page that continues the same task rather than restarting the journey.
    Decision momentPrompt patternJob of the destination pageUseful visibility signal
    DiscoverWhat approaches solve this problem for this audience?Explain the category, tradeoffs, and situations in which each approach fits.Your entity appears in the correct category and context.
    CompareWhich option fits these requirements or constraints?Make differentiators, exclusions, and supporting evidence easy to verify.The comparison includes you and states the right distinctions.
    ValidateDoes this option support a particular requirement?Provide an explicit answer, scope, conditions, and authoritative details.The answer uses the correct fact and cites its canonical page.
    ActWhere can I buy, book, apply, contact, or begin?Present current availability and a direct next step.The answer sends the user to the correct action page.

    For every tracked prompt, save the exact wording, platform, language, market or location, intended destination, expected facts, observed competitors, and business stage. This prevents a common reporting error: treating two prompts as equivalent even though one asks for information and the other asks for a recommendation.

    Your tooling should preserve this prompt-level detail. Rank Math AI, for example, tracks brand appearances in ChatGPT and Gemini separately from traditional rankings, with daily, weekly, or monthly monitoring in more than 30 languages. If you use a different platform or an internal process, require the same basic separation. The tool is instrumentation; your prompt set and evaluation criteria are the strategy.

    Make important pages easy to quote and hard to misread

    An answer engine should not have to assemble your central claim from an opening anecdote, a feature grid, a footnote, and a support page. Put the answer where a person can find it quickly, then place the evidence and limitations beside it.

    Use this structure on pages mapped to consequential prompts:

    • Direct answer: State the conclusion in plain language near the relevant heading. Answer the question before expanding it.
    • Named entity: Identify exactly which product, service, organization, location, event, version, or plan the statement concerns. Pronouns and vague category labels create avoidable ambiguity.
    • Qualifications: State who the answer applies to, where it applies, and which conditions or exclusions can change it.
    • Supporting evidence: Put specifications, policies, examples, definitions, and source links close to the claims they substantiate.
    • Freshness signal: Show a meaningful updated date when the information can change, and remove stale claims rather than leaving conflicting versions around the site.
    • Next step: Link to the comparison, documentation, product, booking, contact, or transaction page that continues the reader’s task.

    This is not permission to flatten every page into short answers. A concise answer earns comprehension; depth earns confidence. The page still needs the reasoning, evidence, alternatives, and boundaries a serious reader requires.

    Use structured data to corroborate visible facts

    JSON-LD should describe the same reality a visitor can see. It does not repair weak content, create an entity by itself, or make a stale offer current. Its useful role is to make entities, attributes, and relationships explicit without forcing a machine to infer them from presentation alone.

    Select the type that matches the actual entity. A product page may support Product markup; a property page may call for Hotel; an event page may use Event; and an important visual may be represented with ImageObject. Then verify that names, URLs, images, locations, dates, attributes, prices, and offers agree with the visible page and any current feed, inventory, booking, or location data.

    Audit these relationships as a system:

    • The entity has one preferred name and a stable canonical URL.
    • Alternate names do not accidentally create what looks like a second entity.
    • The structured description does not make claims absent from the page.
    • Offer, availability, date, location, and attribute data match operational systems.
    • Images and videos point to the entity and variant they actually depict.
    • Third-party profiles and distribution feeds do not contradict the first-party record.

    More markup is not the goal. Fewer unresolved contradictions is the goal.

    Use internal links to define the evidence path

    Internal links help a crawler discover URLs, but their strategic value goes further. They show how an overview, a detailed claim, its supporting documentation, and the action page relate to one another.

    Run a crawl and fix the basics first: broken destinations, redirect chains, and important pages with no contextual internal links. Then connect each canonical page in both directions. A category overview should point to the relevant detail page; the detail page should connect back to its parent and onward to proof or action. Use anchor text that names the relationship instead of repeating “learn more” throughout the site.

    Do not add links to every possible page. A dense but indiscriminate link graph blurs hierarchy. Link when the destination answers the next reasonable question, verifies the current claim, distinguishes a related entity, or enables the next action.

    Treat images and video as evidence, not decoration

    A tabletop studio photographs a generic mechanical component alongside close-up tools, material samples, and separated parts that reveal its construction.

    Visual optimization is no longer limited to image rankings or faster page loads. AI systems can interpret objects, attributes, surroundings, and relationships within a scene, then connect those observations to a product, place, business, or other entity. Google reports that Lens supports more than 25 billion visual searches per month, with one in five showing commercial intent.

    The important unit is therefore not the image alone. It is the relationship among the asset, the entity it depicts, the page around it, the metadata describing it, and the operational data that keeps the claim current.

    For every decision-relevant image or video:

    • Show useful attributes clearly. Original imagery should reveal the color, material, configuration, room type, amenity, dish, location, feature, or experience that affects a customer’s decision.
    • Identify the correct entity. A product image must connect to the right product and offer. A hotel image must connect to the correct property, room type, amenity, and location.
    • Write literal metadata. Use a descriptive filename, accurate alt text, and a caption when the caption adds context. Do not stuff the target phrase into descriptions of things the asset does not show.
    • Add explanatory surroundings. The heading, nearby copy, and page purpose should reinforce what the asset depicts and why it matters.
    • Make video language accessible. Supply a transcript and useful metadata so the information is available without requiring a system to infer everything from frames and audio.
    • Connect structured data. Associate the visual with the same entity, attributes, and canonical URL described on the page.
    • Keep distribution consistent. Website pages, profiles, publishers, booking platforms, product feeds, and social channels should not attach contradictory names or attributes to the same visual.

    Consider a hypothetical hotel image labeled as a rooftop pool on the property page while a booking feed assigns it to a different room category and a third-party profile calls the pool indoor. A person sees an appealing photograph; a machine sees competing entity relationships. Rewriting the alt text will not resolve that conflict. The property record, amenity data, page copy, structured data, and distribution feeds must agree.

    An asset register makes this manageable at scale. For each important visual, record its URL, depicted entity, visible attributes, canonical page, relevant structured-data type, associated feed or listing, usage rights, and last verification date. That turns visual SEO from a tagging task into a maintainable information system.

    Measure what the answer changed, then fix the weakest link

    Generated answers are observations at a point in time, not permanent rankings. Save enough context to reproduce each check: exact prompt, platform, language, location when relevant, date, answer text, cited URLs, brand description, competitors included, and the intended destination page.

    Use separate rates instead of one opaque score:

    • Mention coverage: tracked prompts in which your entity appears, divided by prompts tested.
    • First-party citation rate: answers citing your site, divided by answers in which your entity appears.
    • Representation accuracy: audited brand claims that are correct and properly qualified, divided by brand claims checked.
    • Destination accuracy: citations that lead to the canonical page for the task, divided by first-party citations observed.
    • Response value: attributable visits, engaged sessions, assisted outcomes, and completed business actions associated with AI discovery.

    Choose a monitoring cadence based on how quickly the underlying information and competitive answer set can change. A fast-moving offer or event warrants closer observation than an evergreen definition. Whatever cadence you choose, compare like with like; changing the prompt wording, language, geography, and platform at once makes the result impossible to diagnose.

    When performance changes, work through the failure in order:

    1. Not retrieved: Check indexation, crawl access, canonicalization, internal links, page relevance, and whether the necessary information exists in accessible text.
    2. Retrieved but absent from the answer: Tighten the direct answer, make the entity explicit, add the missing qualification or proof, and remove competing pages that make the canonical source unclear.
    3. Mentioned inaccurately: Locate contradictions across visible copy, JSON-LD, feeds, profiles, media metadata, and older pages. Correct the underlying record before adding more content.
    4. Mentioned but not cited: Strengthen the first-party page as the clearest source for the claim. Put evidence and the canonical fact together rather than distributing them across weak fragments.
    5. Cited but not visited: Determine whether the answer already completed the task. If a click is still useful, make the linked page promise a clear next layer: a tool, full comparison, current inventory, detailed method, documentation, or transaction.
    6. Visited but not converted: Treat this as a landing-page and journey problem. Ensure the page fulfills the prompt’s intent and makes the appropriate next action obvious.

    Do not judge an optimization by mention growth alone. A larger number of inaccurate mentions can damage understanding, while a smaller number of well-qualified citations on high-intent prompts may be more useful. Read representative answers, not just dashboard totals.

    Key takeaways

    • Keep classic rankings, AI mentions, citations, representation accuracy, visits, and conversions as distinct metrics.
    • Map prompts to customer decisions, constraints, expected facts, canonical pages, and next actions.
    • Place direct answers, qualifications, proof, and freshness signals together on the page that owns the claim.
    • Use JSON-LD, internal links, feeds, profiles, and visual metadata to reinforce one consistent entity record.
    • Diagnose the stage that failed before changing content: retrieval, inclusion, accuracy, citation, visit, or conversion.

    Start with one commercially important entity and the prompt family closest to a real decision. Record a baseline in the answer systems your audience uses, audit the canonical page and its supporting signals, correct the largest contradiction, and run the same prompts again. That small loop will teach you more than a sitewide program built around an undefined AI visibility score.

    References


  • Google AI Shopping: Prepare for Search-to-Checkout

    Google AI Shopping: Prepare for Search-to-Checkout

    If you run a Shopify store, a customer may soon discover your product and buy it without visiting your website. Eligible products can now move from recommendation to direct checkout inside Google AI Mode and the Gemini app.

    That changes more than the checkout button. You need to decide where the transaction should happen, make your product data reliable enough for an AI-assisted purchase, and measure sales that browser analytics may not fully capture. The right response is an operational audit, not an indiscriminate AI content campaign.

    Key takeaways

    • Eligible U.S. Shopify stores may have Google-native checkout activated automatically, so inspect Sales channels > Agentic before assuming you opted in or out.
    • Merchant Center data is becoming part of the transaction interface, not merely a way to qualify for product exposure.
    • Native checkout can shorten the buying path, but certain checkout blocks, bundles, custom pixels, and client-side Google Analytics tracking are not supported.
    • Measure answer presence, visible citations, product visibility, and completed transactions separately. They are related outcomes, not interchangeable versions of one ranking metric.

    Search visibility now has separate discovery and commerce layers

    AI-generated search results are no longer a fringe surface. Google AI Overviews appeared in 39.4% of U.S. desktop searches in June 2026, up from 25.8% in July 2025. That measurement describes how often the feature appeared. It does not measure clicks, visits, or sales.

    Search demand has not simply vanished into AI interfaces. U.S. desktop search volume reached 77 billion searches in the second quarter of 2026, 8% above the 71 billion recorded in the second quarter of 2024. The practical change is in what can happen between the query and your website. Google can answer the question, cite a page, present a product, and, for some shoppers and merchants, complete the transaction before a site session begins.

    Do not use the AI Overview figure as a proxy for native-checkout adoption. AI Overviews, AI Mode, and Gemini are distinct experiences, and the available checkout rollout is limited to eligible merchants and shoppers. Combining them into one AI traffic number will hide which part of the journey is actually changing.

    Track four outcomes instead of one AI visibility score

    1. Answer presence: Does the AI response discuss your brand, product, category, or information?
    2. Visible attribution: Does it name or link to your domain, product page, video, marketplace listing, or another asset you control?
    3. Product availability: Does the relevant product surface with accurate information for the shopper?
    4. Transaction availability: Can the shopper buy inside the AI experience, or are they transferred to your store?

    The first two outcomes need to remain separate. A system can use a domain while giving another domain the visible link. In lodging-related AI responses measured from December 2025 through May 2026, Tripadvisor had 61% source presence but only 21% visible citation presence. Hotels.com moved from 50% source presence to 18% citation presence, while Booking.com moved from 33% to 9%. Those numbers come from lodging, not retail, but the measurement lesson applies directly: being used, being named, and receiving a click opportunity are different results.

    Build your monitoring sheet around those distinctions. For every important query, record the date, device type, Google surface, whether your brand appeared, whether a link appeared, which URL received the link, whether a product was shown, and whether checkout was available. Use the same query set on a fixed cadence. AI responses can vary, so one screenshot should be treated as an observation rather than a permanent ranking.

    Keep traditional ranking and organic traffic beside this view, not inside it. A page can rank conventionally without appearing in an AI answer. It can inform an answer without receiving a citation. A product can also generate an order without producing the client-side visit your existing dashboard expects.

    Decide whether native checkout fits your store before leaving it enabled

    The first task is to establish your actual state. Shopify stores may be eligible when they are based in the United States, sell to U.S. customers, have a valid Merchant Center account, and make eligible products available through Merchant Center, among other requirements. Products can be synchronized through Shopify’s Google & YouTube channel or supplied through another feed method.

    For a matched store and Merchant Center account, eligible products may be included automatically. Shopify also activates purchasing by default for eligible stores. The rollout remains selective, however, so an eligible merchant should not assume that every shopper can see the same experience.

    1. Open Shopify and inspect Sales channels > Agentic.
    2. Record whether direct checkout is enabled before changing anything. Add the date to your analytics annotations or internal change log.
    3. Confirm which Merchant Center account is matched to the store and how products reach that account.
    4. Identify the products that are intended to be available through Merchant Center. Check whether their price, availability, variants, images, and descriptions match the live store.
    5. List every onsite feature involved in conversion or measurement, especially bundles, checkout blocks, custom pixels, and client-side Google Analytics tracking.
    6. Choose deliberately between native checkout and website checkout. If you disable direct checkout, products can still be discovered in AI Mode and Gemini, but shoppers will be sent to your site to purchase.

    The choice is not simply more distribution versus less distribution. It is a tradeoff between reducing steps and preserving the parts of your onsite experience that help the customer choose, configure, or understand the product.

    Decision questionLean toward native checkoutLean toward website checkout
    Can the customer understand and select the product from the information available in the AI experience?The product and its variants are straightforward.The purchase needs detailed education, configuration, or onsite assistance.
    Does the current offer depend on unsupported checkout behavior?Standard product and checkout behavior is sufficient.Bundles or specific checkout blocks are central to the offer.
    Can you evaluate performance from order and platform records?Order-level reconciliation gives you enough evidence to make a decision.Essential attribution or optimization depends on unsupported custom pixels or browser events.
    What is the primary experience goal?Removing steps between product discovery and purchase matters most.Preserving a controlled, branded onsite journey matters most.

    Native checkout does not remove the merchant from the commercial relationship. Merchants retain the underlying customer and order relationship. But that does not mean the Google-hosted experience reproduces the store’s checkout. Certain checkout blocks, product bundles, custom pixels, and client-side Google Analytics tracking are not supported.

    If one of those features affects pricing, fulfillment, compliance, or the customer’s understanding of the order, resolve that dependency before leaving native checkout enabled. If it only affects reporting, determine whether order-level reconciliation can replace the missing browser signal. Do not reject a sales channel solely because it produces fewer sessions, and do not keep it solely because it produces more orders without checking cancellations, refunds, and operational quality.

    Treat Merchant Center data as transaction infrastructure

    Structured product-data tiles for inventory, pricing, shipping, returns, and payment connect an AI interface to checkout and fulfillment.

    Merchant Center used to be easy to treat as a distribution feed sitting beside the store. That mental model is now incomplete. Eligible products supplied through Merchant Center can support discovery and direct purchase, which means a catalog error can travel farther down the buying journey before anyone notices it.

    The transaction layer is powered by the Universal Commerce Protocol, or UCP. It is an open standard developed by Google with companies including Shopify so AI agents can interact with merchants and payment systems across the shopping journey. UCP is the connection layer; it does not make incomplete, stale, or ambiguous product information reliable.

    Audit the product facts an agent must act on

    • Identity: Make titles, brand information, item identifiers, and variant identifiers stable enough to distinguish one product from another.
    • Choice: Represent differences such as size, color, quantity, and compatibility clearly. Do not bury a purchase-critical distinction in promotional copy.
    • Offer: Keep price, availability, and condition aligned with what the customer can actually buy.
    • Media: Make sure the primary image represents the selected product or variant rather than a broader collection.
    • Description: Put the facts needed to make a decision near the start. A product description should identify what the item is, who or what it is for, and the distinctions that change the choice.
    • Consistency: Align Merchant Center data, the rendered product page, and any Product structured data on the site. JSON-LD can clarify the page, but it is not a substitute for the Merchant Center feed used in this checkout rollout.

    Work from the sale backward. Ask what would cause the wrong variant, stale availability, misleading image, or incorrect price to appear at the point of purchase. Those are higher-priority defects than minor differences in promotional wording because they affect whether the transaction can be completed accurately.

    Do not add more feed detail than your team can maintain. A complete field that becomes stale is not better than a concise field tied to a reliable system of record. Assign ownership for each changing fact and document whether Shopify, another catalog system, or a feed tool controls it.

    Replace browser-only attribution with commerce reconciliation

    Client-side analytics cannot be your only conversion record when checkout may occur outside your pages. A lower session count can coexist with valid orders, while a missing browser event can look like a failed conversion even when payment completed.

    Create a compact operating view with five layers:

    1. Configuration: The Agentic setting, Merchant Center account, feed method, and dates when any of them changed.
    2. Catalog: The products intended for AI discovery, their current feed status, and material errors or exclusions.
    3. Visibility: Observations from your fixed query set, separated into answer presence, citation presence, product appearance, and checkout availability.
    4. Transactions: Orders and sales attributed to the experience when Shopify or another available record identifies them. Keep onsite orders separate.
    5. Order quality: Cancellations, refunds, fulfillment problems, and product-selection errors. These show whether a shorter checkout path is producing usable revenue.

    Annotate promotions, stockouts, price changes, feed repairs, and setting changes. A simple before-and-after comparison cannot prove that native checkout caused a sales change when inventory, demand, and rollout availability also moved. Treat it as directional evidence unless you have a controlled comparison with stable conditions.

    If direct checkout is enabled but the available records cannot distinguish its orders, document that limitation instead of filling the gap with estimated attribution. The immediate objective is to make the unknown visible. That prevents a dashboard built around website sessions from silently declaring offsite transactions nonexistent.

    Build citation opportunities around how people research products

    Shoppers compare unbranded products using visual evidence cards connected to an abstract AI search assistant.

    Your product feed supports commerce eligibility, but it is not the whole discovery strategy. In June retail searches, YouTube appeared in 23% of searches among the top listed AI Overview citations. Amazon appeared in 14%, Reddit in 12%, and Wikipedia in 11%.

    Those percentages are not traffic share, sales share, or proof that publishing on a particular platform causes an AI citation. They show that retail answers draw visible support from several kinds of destinations: video, marketplaces, communities, reference material, and merchant sites. Your visibility plan should therefore cover the questions people ask before they are ready to transact.

    1. Map real buying questions. Include category questions, comparisons, compatibility concerns, variant selection, use cases, and the policy questions that can stop a purchase.
    2. Assign one dependable destination to each answer. Use a product page for product facts, a comparison or support page for decision criteria, and a video when the customer needs to see setup, scale, movement, or results.
    3. Keep claims consistent across surfaces. Conflicting specifications, product names, availability, or positioning create ambiguity for shoppers and machines. Correct the canonical store information first, then update other profiles and listings you control.
    4. Use YouTube when demonstration adds evidence. Give the video a descriptive title and make the spoken and written explanation specific enough to stand on its own. Do not create video merely because YouTube appears frequently in citations.
    5. Treat Reddit as a listening environment, not a placement inventory. Use recurring community questions to improve your pages and documentation. Do not manufacture endorsements or disguise promotional participation as customer experience.
    6. Review marketplace information where it already matters to your business. If your products are legitimately sold on Amazon, make names, variants, and core facts consistent. The citation data alone is not a reason to open a marketplace channel.

    When reviewing a query, ask whether the AI answer contains the right fact, whether your brand is represented accurately, and whether the visible citation leads to the best page. A citation to an obsolete support page is not automatically a win. Neither is an uncited brand mention that describes the wrong product.

    Your first move should be small and observable. Check Sales channels > Agentic, capture the current state, confirm the matched Merchant Center account, and list the checkout or analytics features that would not carry into native checkout. Then choose whether to keep direct purchasing enabled and begin a recurring product-data and query review. That sequence gives you a controlled decision now while preserving room to adapt as Google expands the experience.

    References


  • Google Search Live: An SEO Playbook for Gemini Conversations

    Google Search Live: An SEO Playbook for Gemini Conversations

    If your AI-search plan still begins and ends with a typed keyword, Google Search Live creates a blind spot. A user can ask a question aloud, refine it through follow-ups, switch languages, hear an answer, and open a web result only when more detail or proof is needed.

    The practical response is not to make your copy sound robotic or to chase a new set of supposed Gemini ranking tricks. It is to build pages that can answer one part of a conversation clearly, support that answer credibly, and help the user take the next step.

    What Search Live changes, and what remains unknown

    Gemini 3.8 Live is rolling out as the model behind real-time conversations in Search Live in the Google app. The user taps the Live icon, asks a spoken question, hears an AI-generated response, and can continue with another question.

    This is not merely voice input attached to a conventional results page. The interaction can develop over several turns. Search Live can also place web links on the screen while delivering the audio response, so the spoken answer and the visible destinations perform different jobs. The answer handles the immediate exchange; a linked page can provide verification, depth, comparison, or a path to action.

    Users are not locked into the live audio session. They can open a transcript, continue by typing, and return through AI Mode history. That makes Search Live a multi-format journey rather than an isolated voice interaction.

    Selection mechanics remain unknown. The confirmed change is the interface and its underlying model, not a disclosed Search Live ranking formula. There is no sound basis for claiming that a particular word count, schema type, conversational tone, or formatting trick will secure a link in a live response.

    That distinction should shape your strategy. Preserve the technical SEO that makes a page discoverable. Improve the parts that make it usable as an answer. Then measure business outcomes without pretending that correlation reveals a private selection system.

    Map the follow-up journey before rewriting content

    A person with a phone follows a branching illuminated path through abstract clarification, comparison, verification, and action stages.

    A keyword cluster groups searches with similar meanings. A live conversation adds another dimension: each answer can produce a new constraint, objection, comparison, or request for proof. Optimizing only for the opening question leaves the rest of that journey to chance.

    Build a follow-up map for each commercially important task. Start with questions already visible in Search Console, site search, support requests, sales calls, and customer research. Do not treat every possible wording as a separate content opportunity. Group questions by the decision the user is trying to make.

    Conversation stageWhat the user needsWhat the destination page should provide
    Opening questionOrientation or a direct recommendation boundaryA concise answer, scope, and clear definitions
    ConstraintFit for a particular use case, market, budget, or requirementEligibility criteria, limitations, and relevant alternatives
    ComparisonA defensible choice between named optionsConsistent comparison dimensions and evidence for each distinction
    Trust checkProof that the answer is current and credibleNamed evidence, methodology, dates, ownership, and material caveats
    Action questionA safe next stepInstructions, prerequisites, expected outcome, and an appropriate conversion path

    For every row in your map, assign the strongest existing URL. If several near-duplicate pages compete for the same job, decide which one should be canonical and improve its internal links. If no page can answer the question without forcing the reader to assemble fragments from several URLs, you have found a genuine content gap.

    Then test the sequence aloud. Ask the opening question and write down the most natural follow-up. Repeat until the user reaches a decision or an action. This exposes missing transitions that a spreadsheet of keywords often hides. A pricing page may answer cost but fail to explain who qualifies. A comparison page may list features but omit the limitation that determines the choice. A tutorial may explain setup without telling the reader what successful completion looks like.

    The goal is not one enormous page that attempts to answer every branch. Use a focused page for each distinct intent, then connect related pages with descriptive internal links. A live conversation can move between needs; your site architecture should make the same movement possible.

    Make every destination useful as evidence and a next step

    Visitors examine source documents at a page-shaped evidence station connected by light to several next-step doorways.

    A Search Live link can appear while the audio response is still being delivered. The page therefore has to earn the click and satisfy it. A vague introduction, an unexplained claim, or a page that hides the answer below promotional copy creates friction at exactly the moment the user wants confirmation.

    Use a repeatable answer unit for important questions:

    • Descriptive heading: Name the decision or question in ordinary language.
    • Direct response: Give the useful answer immediately, including the condition that could change it.
    • Scope: State the market, product version, audience, plan, or scenario to which the answer applies.
    • Support: Provide the fact, calculation, process, or primary evidence that justifies the answer.
    • Limitation: Put material exceptions beside the claim rather than burying them in a general disclaimer.
    • Next action: Tell the reader what to check, compare, configure, or read next.

    This structure serves both people and machine-assisted retrieval without requiring awkward question stuffing. It also gives editors a useful test: if the direct response cannot stand on its own without becoming misleading, its scope or caveat is missing.

    Write for audio clarity, but do not assume Search Live reads page copy verbatim. Use explicit nouns where a pronoun could refer to several entities. Expand an acronym on first use. Keep units attached to quantities. Name both sides of a comparison. Put a decisive exception in the same paragraph as the recommendation it limits. These choices reduce ambiguity for readers and extraction systems; they do not guarantee inclusion in a generated answer.

    Use JSON-LD to confirm meaning, not manufacture it

    Structured data should describe the visible page accurately. It should not introduce claims, reviews, prices, authors, dates, or relationships that a visitor cannot verify on the page.

    • Choose the schema type that matches the actual entity or content, not the type that appears to offer the richest result.
    • Keep names, URLs, identifiers, authorship, and publisher information consistent between JSON-LD and visible content.
    • For an Article, align the headline, author, datePublished, and dateModified values with the page. Change dateModified only when the content has been materially reviewed or updated.
    • For a Product, expose offers, currency, availability, brand, and identifiers only when those properties are genuine and maintained.
    • Validate syntax after template or deployment changes, then check that dynamically generated values still agree with the rendered page.

    JSON-LD can remove ambiguity about entities and page relationships. It cannot turn weak content into reliable evidence, and no confirmed rule makes it a shortcut into Search Live. Treat it as part of semantic and technical quality, not as a visibility guarantee.

    Preserve the journey when users switch languages

    Search Live supports switching languages during the same conversation. That capability exposes a common international SEO weakness: a translated landing page exists, but its comparison, support, pricing, or conversion pages do not.

    Audit complete decision paths rather than counting translated URLs. For each priority market, check whether the user can move from the opening explanation to constraints, evidence, comparison, and action without an unexpected language change.

    • Localize meaning, examples, units, market conditions, and calls to action instead of translating words in isolation.
    • Connect genuine language or regional equivalents with accurate hreflang annotations.
    • Keep product names and stable entity identifiers consistent across localized JSON-LD while allowing the visible wording to fit the language.
    • Avoid sending every localized page to one default-language conversion page unless that is genuinely the only supported path.
    • Review spoken questions with fluent speakers. Literal translations often miss the vocabulary customers actually use when asking for help.

    Do not publish thin machine-translated pages merely to cover more languages. An incomplete local journey creates a larger gap between the answer and the action, which is the opposite of what a conversational interface needs.

    Measure the journey without inventing Search Live attribution

    Search Live can show links during the conversation, while its transcript and AI Mode history let users revisit the exchange later. A click can therefore happen during the spoken interaction, after the user reads the transcript, or after returning to history.

    Do not assume an ordinary analytics session will identify that entire path or label it cleanly as Search Live. Use three separate evidence layers:

    • Manual observations: Record the question sequence, language, visible links, and date of each check. Treat these as samples of interface behavior, not as a visibility score.
    • Discovery data: Watch relevant landing pages and query groups in Search Console. Segment by country, language, device, and page template where the available data supports it. Look for sustained changes rather than reacting to one query or one manual check.
    • Business outcomes: Measure qualified leads, purchases, sign-ups, support resolution, or another outcome appropriate to the page. A visible link has little value if the destination does not help the user complete the task.

    Annotate material content, schema, internal-link, and localization changes so you can interpret later movement. Change one coherent part of the journey at a time when practical. If you rewrite the page, alter the template, change schema, and restructure navigation together, any improvement will be difficult to diagnose.

    Be equally careful with assisted signals. Growth in branded searches, direct visits, or returning users may be consistent with exposure in an AI experience, but it does not prove that Search Live caused it. Report those signals as directional unless your measurement system provides a defensible connection.

    Model changes add another source of volatility. As Gemini models evolve, generated responses and displayed links can change even when your pages do not. Build reporting around trends, outcomes, and documented observations rather than promising permanent placement from a single appearance.

    Key takeaways

    • Search Live turns one query into a spoken, multi-turn journey, but visible web links still give publishers a role beyond the generated answer.
    • Optimize for the sequence of decisions: opening need, constraint, comparison, trust check, and next action.
    • Give each important question a focused destination with a direct answer, explicit scope, evidence, limitations, and a useful next step.
    • Keep JSON-LD accurate and consistent with visible content. Treat structured data as clarification, not a guaranteed route into Search Live.
    • For multilingual audiences, audit the whole decision path rather than translating only the first landing page.
    • Separate manual observations, discovery data, and business outcomes. Do not claim Search Live attribution that your analytics cannot establish.

    Start with your highest-value decision journey. Say the opening question aloud, follow the natural branches, and assign one strong URL to each distinct need. The first missing or unconvincing answer you uncover is the next page worth improving.

    References


  • Google AI Tools for Search Marketers: A Practical Workflow

    Google AI Tools for Search Marketers: A Practical Workflow

    Google now puts AI on both sides of a search marketer’s desk. On the organic side, AI-generated search experiences decide how information is assembled and cited. On the paid side, AI interprets campaign data and proposes explanations for performance changes.

    Your job is not to collect every new feature. It is to separate two workflows: earning visibility in AI-generated answers and using AI to investigate paid-search performance. That distinction tells you what to measure, what to prompt, and which conclusions still need human verification.

    Match each Google AI tool to the question it can answer

    Start by deciding whether you are examining the market or examining your account. AI Mode, AI Overviews, and Gemini can help you observe how Google interprets a topic. Google Ads AI Dashboards, homepage insights, and Ask Advisor work with advertising performance.

    Google AI surfaceUseful marketing questionOutput to captureConclusion to avoid
    AI ModeHow is this query answered, and which pages support the answer?Answer structure, cited URLs, entities, claims, and missing subtopicsA citation is a permanent ranking position
    AI OverviewsWhat synthesized answer appears alongside conventional search results?Answer framing, cited domains, and the relationship between the generated answer and the surrounding resultsOne result represents every user, query variation, or future search
    GeminiHow might an AI assistant interpret the topic or decompose the user’s request?Terminology, follow-up questions, ambiguities, and information needsA Gemini response is a direct proxy for Google Search rankings
    Google Ads AI DashboardsWhat changed in campaign performance, where did it change, and what may have contributed?A scoped visualization, account segments, and an explanation to verifyAn AI-generated explanation proves causation
    Ask Advisor and homepage insightsWhich account questions or anomalies deserve investigation?Questions, hypotheses, and paths into the underlying account dataA recommendation should be applied without checking its scope and commercial risk

    This separation matters because AI Mode is an external discovery environment, while an Ads dashboard is an internal analysis environment. AI Mode can show how Google retrieves, orders, and cites information. It cannot tell you why an advertising campaign’s cost changed. An Ads dashboard can analyze account data, but it cannot establish whether your organic content is eligible to support an AI-generated answer.

    Do not combine all of these observations into a single “AI visibility” score. Keep at least two records: an organic answer-and-citation log and a paid-performance investigation log. Otherwise, a change in advertising efficiency can be mistaken for a change in search demand, or a volatile AI citation can be mistaken for durable organic growth.

    Use AI Mode as a citation audit, not a rank tracker

    A magnifying glass inspects links between an abstract AI answer panel and several source documents, with one unsupported connection highlighted.

    A conventional rank check asks where a URL appears for a query. An AI citation audit asks a different set of questions: What answer did Google construct? Which claims needed support? Which sources were selected? What did the cited pages make especially clear?

    That makes AI Mode useful for diagnosing content, but weak as a one-observation scoreboard. Generated answers can change with wording, context, and the shape of the request. Record what you see, but do not turn a single appearance or absence into a general claim about visibility.

    1. Build the query set from real decisions. Include the problem a person is solving, the comparison they need to make, the constraint that changes the answer, and the follow-up question likely to come next. A broad head term rarely reveals the whole information journey.
    2. Run a controlled observation. Keep the wording of each query in your log. Check the conventional results page, note whether an AI Overview appears, and inspect AI Mode separately. Do not silently change the prompt and then compare the outputs as though the query stayed constant.
    3. Record the answer anatomy. Capture the main answer, the subquestions it addresses, named entities, cited URLs, and the specific claim each citation appears to support. A domain count alone tells you almost nothing about why a page was useful.
    4. Inspect the cited pages. Look for the passage that answers the question, the definitions surrounding it, supporting evidence, descriptive headings, and any comparison structure. The useful unit is often a clearly supported claim inside a page, not the page as an indivisible object.
    5. Compare your page with the information need. Mark missing answers, buried definitions, unexplained terminology, unsupported assertions, and comparisons that use inconsistent dimensions. Those are concrete editing targets.
    6. Recheck after a meaningful revision. Keep the original query and observation beside the new one. Treat a changed answer as an observation to investigate, not proof that one edit caused it.

    The resulting worksheet should have one row per query and columns for intent, answer framing, cited pages, supported claims, gaps, planned edits, and the next observation. This gives your team evidence it can discuss. A screenshot folder without query wording or claim-level notes does not.

    Make a page easier to retrieve without writing for a robot

    Retrievability starts with clarity. Put the direct answer near the question it resolves. Name the entity before switching to pronouns. Define specialist terms. Keep qualifications attached to the claim they limit. If you compare options, use the same criteria for each option so the relationship is visible rather than implied.

    • Give each important question a descriptive heading and an immediate answer.
    • Use the full name of a product, organization, method, or standard when ambiguity is possible.
    • Support factual claims on the page instead of expecting a search system to infer evidence from a distant internal link.
    • Place limitations beside recommendations. Moving them to a generic disclaimer weakens the answer and can mislead the reader.
    • Use structured data only when it accurately describes visible content. Schema can clarify meaning; it cannot rescue an unsupported or missing answer.
    • Link related pages according to the reader’s next question, not merely because they share a keyword.

    This is not a replacement for technical SEO. A page still needs to be accessible, indexable, canonicalized correctly, and connected to the rest of the site. AEO and GEO work build on that foundation by making answers, entities, relationships, and evidence easier to identify.

    Prompt Google Ads AI Dashboards like an analyst

    Google Ads AI Dashboards are appearing in some advertiser accounts, so you may not have access yet. Where the feature is available, a natural-language request can generate a visual report instead of requiring you to select every metric, dimension, and chart manually.

    The dashboard can also attach a real-time AI summary of what changed and what may be driving it. That saves report-construction time. It does not remove the need to frame the question or verify the explanation.

    A useful dashboard prompt contains six parts: the decision, account scope, metric, comparison, segmentation, and requested output. If one is missing, Gemini has to infer it, and the chart may be technically correct while answering the wrong business question.

    • Decision: State what you are trying to understand, such as whether an efficiency change is concentrated or account-wide.
    • Scope: Name the campaigns, campaign type, product group, geography, device, or other relevant boundary.
    • Metric: Specify the outcome and its related inputs. Asking only about conversions can hide a simultaneous change in spend or traffic.
    • Comparison: Name the periods or segments being compared and make sure they are commercially comparable.
    • Segmentation: Ask for the dimension that could expose the change instead of accepting an account-wide average.
    • Output: Request the visualization, largest contributors, and a clear separation between observed data and possible explanations.

    A reusable prompt pattern is:

    Compare [metric set] for [campaign scope] between [period or segment A] and [period or segment B]. Break the result down by [dimension]. Visualize absolute and relative changes, identify the largest contributors to the account-level movement, and separate observations from possible causes.

    Reusable Google Ads analysis prompt

    You can adapt that pattern to practical questions:

    • Compare cost, conversions, and cost per conversion across campaigns for two comparable periods. Show which campaigns contributed most to the account-level change.
    • Break out cost, conversions, and conversion value by device for brand and non-brand campaign groups. Flag cases where volume and efficiency moved in different directions.
    • Chart daily spend and conversions for a selected campaign group. Identify the dates and campaigns responsible for the largest deviations, without assigning a cause.
    • Compare performance by geography for the selected campaigns. Separate changes caused by traffic volume from changes in conversion efficiency.

    These prompts do more than request a prettier report. They force you to define the denominator, the comparison, and the decision. If the generated chart cannot accommodate a requested metric or dimension, revise the scope rather than accepting a substitute without noting it.

    Verify the AI explanation before changing content or spend

    An analyst cross-checks an AI-generated performance explanation against a calendar, change history, source document, and calculator before approving an action.

    The most convincing AI mistake is a plausible explanation attached to accurate numbers. A dashboard may correctly show that cost per conversion rose while offering a cause that the chart cannot prove. The phrase “may be driving” marks a hypothesis, not a causal finding.

    Run every material insight through the same verification loop:

    1. Confirm the scope. Check the date range, campaign selection, filters, excluded segments, and comparison period. A summary can be accurate for its slice and still misrepresent the account.
    2. Confirm the metric definition. Make sure the chart is using the conversion, value, cost, or efficiency measure your decision actually depends on. Similar labels are not interchangeable.
    3. Locate the contributors. Move from the account total to campaigns and then to the dimension behind the movement. An average can conceal opposite changes in separate segments.
    4. Separate observation from cause. “Mobile efficiency declined” is an observation. “The landing page caused the decline” requires evidence beyond two events occurring near each other.
    5. Check the underlying rows. Review the data behind the visualization before presenting the summary or applying a recommendation. The chart is an interface to the account, not an independent record.
    6. Choose a reversible next step. Investigate, annotate, or run a controlled change before making a broad account adjustment.

    Paid-search decisions can spend real money. Do not increase budgets, change bids, pause broad campaign groups, or alter conversion settings solely because an AI summary sounds certain. Use the same approval process you would apply to a human analyst’s recommendation, and preserve a record of the original settings and the reason for the change.

    Apply the same discipline to organic content. Do not rewrite an accurate, useful page merely because it was absent from one AI Mode response. First determine whether the page answers the same intent, whether another page on your site is the better candidate, and whether the proposed edit improves the reader’s answer. Citation visibility is an outcome to observe, not permission to weaken the page.

    Key takeaways and your next working session

    • Use AI Mode and AI Overviews to inspect answer construction and citations; do not treat them as conventional rank trackers.
    • Use Gemini for exploratory interpretation, not as proof of how Google Search will rank a page.
    • Use Ads AI Dashboards to reduce report-building work, but define the scope, metric, comparison, and segment in the prompt.
    • Treat every generated explanation as a hypothesis until the underlying account data supports it.
    • Keep organic citation observations separate from paid-performance investigations.
    • Improve content by clarifying answers, entities, evidence, and relationships while preserving technical SEO and reader value.

    For your next working session, choose one valuable query cluster and one unresolved Google Ads performance question. Build a citation log for the first and a tightly scoped dashboard prompt for the second. If every conclusion can be traced back to a cited page or a defined slice of account data, the AI is helping you investigate. If it cannot, keep it in the hypothesis column.

    References


  • Google AI Search Ads: How to Read the Performance Shift

    Google AI Search Ads: How to Read the Performance Shift

    If your Shopping click-through rate is climbing while clicks barely move, do not label the campaign healthier yet. That combination can appear when the impression pool contracts faster than click volume. The rate improves, but the business receives little or no additional traffic.

    At the same time, Google is testing a new route into AI Mode for tightly controlled Search campaigns. You therefore have two changes to manage: AI-generated experiences may be reshaping the inventory available to Shopping ads, while some exact and phrase match campaigns may gain access to a new search surface. The practical response is to separate reach, efficiency, intent and business outcomes before changing bids or budgets.

    Google is routing intent into different search experiences

    Google’s AI search shift is not simply another placement added to the same auction. The results experience can vary by query. A person may receive an AI Overview, conventional search results with ads, a Shopping-led result or an AI Mode response. Your campaign cannot earn an impression when Google chooses an experience that does not offer that particular ad opportunity.

    A notable pattern has appeared across thousands of Shopping and Performance Max campaigns spanning hundreds of advertiser accounts: impressions often declined more clearly than clicks, leaving clicks relatively flat or slightly lower and pushing CTR upward.

    One possible mechanism is selective routing. Google may be more likely to show an AI Overview for a query with relatively low predicted ad-click propensity, while preserving Shopping placements for searches more likely to generate a commercial click. Anecdotal observations have also found Shopping ads and AI Overviews uncommon on the same results page.

    That explanation is a hypothesis, not a demonstrated cause. The timing could be coincidental, AI Overviews could be contributing through a different mechanism, or another change could be reducing impressions. Treat the account pattern as observed and the AI Overview explanation as unconfirmed.

    Search contextWhat is supportedHow you should interpret it
    Shopping inventory alongside the growth of AI OverviewsSome large campaign datasets show impressions falling more than clicks while CTR rises. The causal role of AI Overviews remains unproven.Report the loss of reach alongside the higher rate. Do not call CTR growth an optimization win by itself.
    AI Mode with explicit, direct intentExact and phrase match keywords can trigger traditional text ads in a small experiment.Existing controlled campaigns may gain reach without an immediate switch to a more automated campaign type.
    AI Mode with complex or conversational intentAI Max and Performance Max remain Google’s products for broader conversational searches and newer formats such as Highlighted Answers.Test automated expansion separately from your controlled keyword campaigns so that you can measure what the additional reach contributes.

    The important distinction is between selection and persuasion. A higher CTR can mean that your ad persuaded a larger share of the same audience. It can also mean that Google removed lower-propensity impressions before your creative entered the picture. Those are different performance stories and demand different decisions.

    The Shopping CTR trap: a stronger rate can hide weaker reach

    A narrowing funnel reduces a field of impression particles while only a few click tokens emerge beside an unlabeled rising gauge.

    CTR is clicks divided by impressions. If impressions decline faster than clicks, CTR rises automatically. Your ad does not need to generate a single additional visit for the rate to look better.

    The size of the observed movement makes this more than a theoretical concern. One ecommerce dataset showed Shopping CTR up 17% year over year, close to a roughly 20% increase in another benchmark. Looking below the rate revealed that clicks were often flat or slightly down while impressions had fallen more substantially.

    Read CTR as one link in a metric chain

    Put these measures beside one another in every Shopping and Performance Max review:

    • Impressions show how much exposure the campaign received. A decline may indicate a smaller available opportunity, a change in eligibility, a different query mix or another delivery constraint.
    • Clicks show the traffic actually delivered. Flat clicks paired with rising CTR usually mean the rate has improved more than the outcome.
    • CTR describes click efficiency within the inventory Google served. It does not measure the size or quality of the inventory that disappeared.
    • Cost shows what you paid to participate. A selective inventory pool can change both traffic volume and auction economics.
    • Conversions, conversion value and profit show whether the campaign created a business result. Use the measure that reflects your actual commercial objective rather than treating a platform rate as the objective.

    A reach-compression pattern looks like this: impressions decline more sharply than clicks, CTR rises and total traffic remains flat or falls. That pattern should trigger an inventory and query-mix investigation, not a bid increase prompted by the CTR improvement.

    A genuine performance improvement is broader. Click volume, qualified conversions or conversion value should move in the desired direction without unacceptable cost or margin deterioration. CTR can support that conclusion, but it cannot establish it alone.

    Use comparable reporting periods and keep promotions, budget changes, product availability and campaign restructuring visible in the same view. Otherwise, an AI-search hypothesis can become a convenient explanation for a change caused inside your own account.

    Exact and phrase match are entering AI Mode with boundaries

    You do not necessarily need to move every Search campaign into AI Max or Performance Max to become eligible for AI Mode. Google has started a small experiment allowing exact and phrase match keywords to serve text ads in AI Mode.

    The restriction matters. Those keywords can participate only when Google’s systems identify explicit and direct user intent. Eligibility is therefore not guaranteed merely because a keyword uses exact or phrase match. Google still decides whether the person’s request maps directly enough to the advertiser’s keyword.

    The experiment also does not put traditional Search campaigns on equal footing with every automated option. AI Max and Performance Max are still positioned for more complex, conversational searches and provide access to newer AI Mode formats, including Highlighted Answers. Traditional campaigns are being tested specifically with text ads attached to clearer intent.

    No broad or permanent rollout has been confirmed. Do not rebuild a functioning account or move material budget solely to chase access to an experiment whose coverage Google has not disclosed. A premature migration can expand spend, change the query mix and destroy the clean baseline you need to judge incrementality.

    Keep controlled intent and automated exploration separate

    1. Preserve a control lane. Keep exact and phrase match campaigns for queries with an obvious commercial request. Think in practical intent classes such as a named product, a specific service, a price request or a purchase-ready action.
    2. Create an exploration lane. Test AI Max or Performance Max separately when you want coverage for longer, less predictable or conversational searches. Give the test its own measurement view and a bounded budget.
    3. Map the landing experience to the intent. A direct query should reach a page that answers the direct request without forcing the visitor through an unrelated explainer. A comparison or discovery query needs enough context to support a decision.
    4. Judge incremental outcomes. Measure whether the exploration lane adds useful clicks, conversions and value to the account. A higher CTR within either lane does not prove that it generated incremental demand.

    This structure lets you benefit if controlled Search inventory expands into AI Mode without surrendering the ability to test Google’s more automated route. It also prevents performance from different intent classes from being blended into one reassuring average.

    Audit the query path before changing bids or budgets

    An analyst traces an illuminated query path through abstract search, AI response, ad placement, and conversion stages while two control knobs remain untouched.

    Your next account review should identify what changed, what you can only infer and what remains unknown. Use this sequence:

    1. Capture a stable baseline. Export impressions, clicks, CTR, cost, conversions and conversion value for comparable periods before changing campaign types, match strategies or budgets.
    2. Separate campaign cohorts. Review standard Shopping, Performance Max and traditional Search independently. Within Search, separate exact and phrase match from broader automated reach. Blended account totals can hide which inventory pool contracted or expanded.
    3. Group search intent. Distinguish explicit commercial requests from exploratory or conversational needs. Google’s AI Mode test uses that distinction as an eligibility boundary, so your analysis should use it too.
    4. Diagnose the denominator. When CTR rises, check whether clicks increased or impressions merely fell faster. If the latter is true, describe the result as more selective delivery until evidence supports a stronger explanation.
    5. Label causal confidence. Mark each conclusion as observed, inferred or confirmed. Impressions down and CTR up is observed. AI Overviews caused the decline is inferred. Do not allow those statements to merge in a dashboard annotation.
    6. Change one lane at a time. Retain the original controlled campaigns while testing automated expansion. Separate budgets and document the change date so that any gain or loss remains attributable.
    7. Report the business consequence. End with traffic, conversions, value and cost. A useful report sentence is: Shopping CTR increased while impressions declined more sharply than clicks; the pattern is consistent with a more selective inventory mix, but it does not establish AI Overviews as the cause.

    Paid search and AI-search optimization should also share the intent map. If repeated results-page checks show that a query cohort receives an AI answer without a Shopping placement, the PPC team cannot bid its way into inventory that was not offered. That cohort becomes a content and AI-visibility question as well as an advertising question. Build pages that answer the exploratory need clearly, define the relevant product or entity precisely and give the user an obvious path into a commercial page.

    Keep that cross-channel conclusion proportionate to the evidence. A handful of manual searches is directional, not proof of universal delivery. Search experiences can vary, so record repeated observations and continue to distinguish your own results-page evidence from a proposed explanation of Google’s system.

    Key takeaways for your next reporting cycle

    • A rising Shopping CTR may be a denominator effect caused by impressions falling faster than clicks.
    • Cross-account data supports the impression-and-click pattern, but the claim that AI Overviews caused it remains a hypothesis.
    • Exact and phrase match Search campaigns can enter AI Mode in a small experiment when Google detects explicit, direct intent.
    • AI Max and Performance Max remain the routes positioned for more complex conversational searches and newer AI-native formats.
    • Keep controlled intent and automated exploration in separate campaign and measurement lanes.
    • Report impressions, clicks, cost and business outcomes with CTR so that shrinking reach cannot masquerade as improved performance.

    For your next report, add one line beneath every CTR change: what happened to impressions, clicks and conversion value at the same time. Then classify the explanation as observed, inferred or confirmed. That small discipline will keep your decisions sound while Google’s AI search inventory continues to change.

    References