Your AI visibility score went up. That sounds useful until someone asks what actually improved. Did more answers name your brand? Did an AI system use your website as evidence? Or did a third-party publisher do the convincing while your domain remained invisible?
Those are different outcomes, and they call for different fixes. A useful measurement system separates brand presence, evidence ownership, platform coverage, market context, and business impact. Once those layers are visible, you can stop optimizing a blended score and start correcting the specific gap in front of you.
One AI visibility score is not an authority metric
For measurement purposes, AI search authority has at least three observable layers:
- Brand salience: Does the answer name or recommend your brand?
- Owned evidence authority: Does the answer cite a page on your domain?
- Third-party corroboration: Do independent publishers, directories, news sites, or reference pages supply the evidence associated with your brand?
A mention is not a citation. A citation is not necessarily a recommendation. A brand can be prominent in generated answers while its website supplies almost none of the supporting material.
The size of that disconnect is not theoretical. In Semrush’s 2026 AI Visibility Index, fewer than half of the top 100 mentioned brands also appeared in the corresponding top 100 citation lists on average in every month measured across 22 categories and four AI platforms. That is a vendor-produced dataset rather than a universal benchmark, but it demonstrates why a combined visibility score can conceal the position you actually hold.
Ford illustrates the scale of the possible split. In the United States in July, the brand appeared in all four top-100 mention lists, while its domain ranked 1,055th for citations on ChatGPT, 1,146th on Gemini, 1,320th on AI Mode, and 748th on AI Overviews. A marketing team looking only at mentions could reasonably conclude that authority was strong. An SEO team looking at the citation positions would see that much of the evidence authority lived elsewhere.
| Brand mentioned | Owned domain cited | What the position usually means | First question to investigate |
|---|---|---|---|
| Yes | Yes | The brand is visible and the site supplies evidence. | Which prompts, pages, and claims produce both outcomes consistently? |
| Yes | No | The brand is known, but its evidence authority is largely rented from third parties. | Which external pages and claims are carrying the recommendation? |
| No | Yes | The site is useful as background evidence, but the answer does not associate that evidence strongly with the brand. | Is the page supplying general facts without making the brand-category relationship explicit? |
| No | No | The brand and domain are absent for this prompt set. | Is the problem relevance, discoverability, market language, or a genuine authority deficit? |
Treat this matrix as the starting point for diagnosis. Do not collapse it into one score before the people responsible for content, digital PR, technical SEO, and brand marketing have seen the underlying positions.
Build a dashboard that preserves the evidence
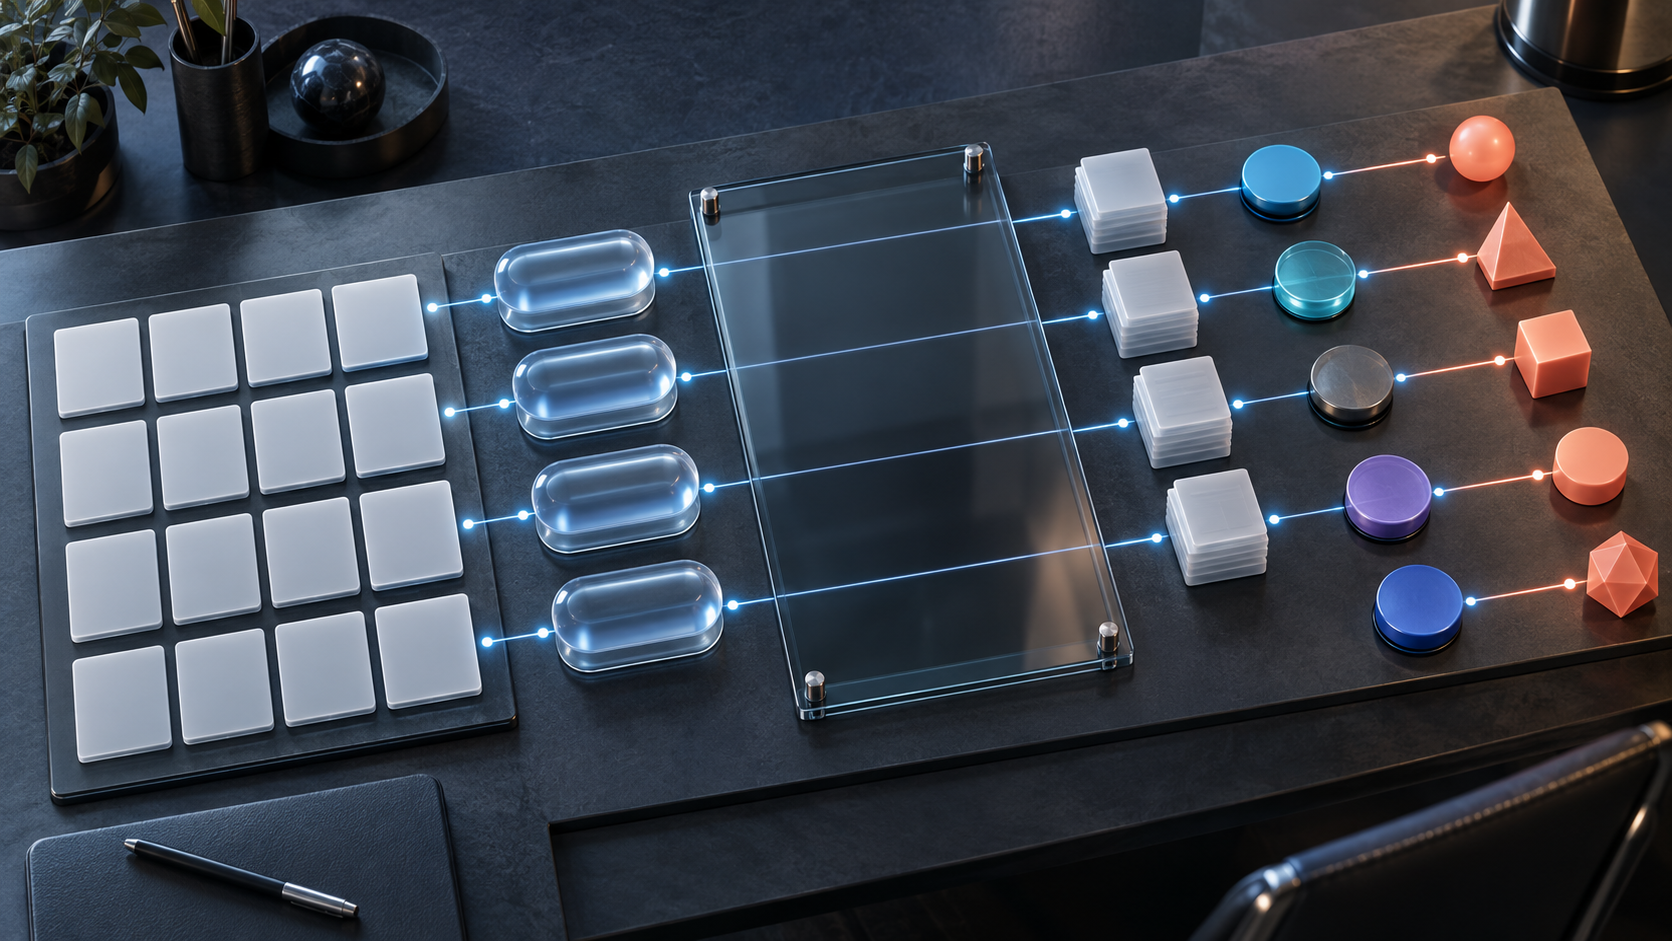
The basic unit in your dataset should be one prompt run on one platform, in one market and language, at a recorded time. That row should preserve enough context for someone else to understand the result without rerunning the prompt.
- A permanent prompt ID, the exact prompt text, and its intent category.
- The platform and product surface, such as ChatGPT, Gemini, Google AI Mode, or Google AI Overviews.
- The country, prompt language, interface language, and any location setting you controlled.
- The date, time, displayed model or product label, and account or personalization state when known.
- The complete answer or a stored snapshot, not just an extracted score.
- Whether the brand appeared, which name or product variant appeared, and whether the reference was unambiguously about the correct entity.
- Every cited URL and domain, classified as owned, competitor-owned, independent third party, or unrelated.
- The role of each citation: direct support for a brand claim, general category background, comparison evidence, contradiction, or irrelevant attachment.
- Errors, refusals, empty results, and answers with no visible citations. Keep these separate from completed eligible responses.
Automated name matching can handle the first pass, but ambiguous names need human review. A matching word is not always a brand mention, and a link appended to an answer does not always support the sentence your brand appears in.
Report rates that answer distinct questions
Use the same denominator for mention rate and owned-citation rate: completed, eligible prompt runs in the selected segment. That makes the gap between them interpretable.
- Mention rate: eligible runs that name the brand divided by all eligible runs.
- Owned-citation rate: eligible runs that cite at least one owned page divided by all eligible runs.
- Mention-to-owned-citation gap: mention rate minus owned-citation rate, expressed in percentage points. A large positive gap flags recognition without comparable evidence ownership.
- Third-party-only support rate: brand-mentioned runs with visible citations but no owned citation, divided by all brand-mentioned runs.
- Citation-to-mention conversion: owned-cited runs that also mention the brand divided by all owned-cited runs. This exposes domains that contribute evidence without receiving brand prominence.
- Owned citation share: owned citation appearances divided by all citation appearances within the same platform and prompt segment. Use this to understand the source mix, not as a substitute for run-level coverage.
Keep referral traffic and commercial outcomes in a separate layer. AI-referred sessions, qualified leads, assisted conversions, and revenue can tell you whether observable visibility creates business value where attribution is available. They cannot tell you whether a missing click came from no visibility, an uncited mention, an answer that satisfied the user without a visit, or a measurement limitation.
Normalize by platform before comparing performance
Raw citation totals are misleading because the products do not construct answers in the same way. In the measured U.S. data, Gemini mentioned more distinct brands per answer than ChatGPT, while ChatGPT showed the most source entries per answer and Gemini the fewest. Google AI Overviews also had the lowest leading-brand overlap with the other measured platforms in every month, and its source overlap with ChatGPT was the lowest.
A brand can therefore improve on ChatGPT while remaining weak in AI Overviews. It can also accumulate more raw citations on a platform that routinely displays longer source lists without gaining a stronger share of available evidence.
- Calculate mention and citation rates separately for each platform and product surface.
- Compare each platform with its own previous baseline before comparing it with another platform.
- Use per-answer rates and shares when source-list lengths differ.
- If you publish an all-platform rollup, disclose the platform weights. Base those weights on business relevance rather than whichever platform produces the most flattering score.
- Show sample size beside every rate. A percentage without its prompt-run count invites false precision.
Generated answers can vary between runs. Capture every scheduled result rather than selecting the best-looking answer, and label a single run as a snapshot rather than a trend. A trend requires the same core prompt cohort, stable segmentation, and a visible record of any methodology change.
Design a prompt panel around customer decisions
Your prompt list is the sample frame for the entire program. If it overrepresents branded questions, your brand will appear artificially strong. If it contains only broad category prompts, it may miss the comparisons and evidence checks that occur near a decision.
Build the core panel around distinct jobs a prospective customer asks an AI system to perform:
- Category discovery: finding credible providers, products, methods, or resources for a stated need.
- Problem diagnosis: understanding causes, constraints, or possible approaches before choosing a solution.
- Comparison: evaluating named or unnamed alternatives against criteria that matter to the buyer.
- Validation: checking evidence, suitability, limitations, reputation, or implementation requirements.
- Action: choosing what to buy, adopt, visit, configure, or contact in a particular market.
Keep unbranded discovery prompts genuinely unbranded. Maintain branded prompts as a separate control group for questions about reputation, capabilities, alternatives, or product fit. Otherwise, the prompt itself gives away the mention you are supposed to be measuring.
Give each prompt one main intent and enough context to produce a useful answer. Record the audience, use case, constraints, and market in structured fields instead of hiding all of them inside an inconsistent text label. Maintain a fixed core panel for trend reporting and a smaller exploratory panel for emerging language or new customer concerns. When an exploratory prompt graduates into the core panel, mark the date so the coverage change is not mistaken for performance growth.
Track the language of the market, not just a translation
For an international program, a defensible default is to track the language in which the market generates revenue and retain a constant English baseline for diagnosis and reporting. The English panel helps you see whether global topic coverage is influencing multiple markets. The local panel shows whether you are present in the vocabulary and community that customers actually use.
Do not assume those panels can be created by literal translation. A local term may represent a distinct category with its own standards, brands, and gatekeepers. In Germany, for example, Naturkosmetik is a pre-existing certified category rather than a direct translation of clean beauty. Treating the terms as interchangeable would test different concepts while pretending they were comparable.
Where local category language is uncertain, one practical routing protocol tested with French and German beauty terms compares local monthly search volume with the English term’s local-market volume:
- If English volume is at least three times local-language volume, route the main prompt to English.
- If the English-to-local ratio is 0.33 or lower, route it to the local language.
- If the ratio falls between 0.33 and 3, neither language leads by three times; track both when the budget permits.
- If either side has fewer than 50 monthly searches, treat that signal as too thin for a key prompt in this exercise and validate it with another input, such as social listening.
Those cutoffs are a selection heuristic from a particular category exercise, not a universal law. Their useful lesson is procedural: document why a prompt belongs in English, the local language, or both. Then compare equivalent customer intentions, not merely equivalent strings.
Segment the resulting data by market and language. Non-English answers may lean on English citations when local-language coverage is thin, while well-developed local categories can draw more heavily on local sources. A global average would hide both the community you are reaching and the authority deficit you need to fix.
Use the mention-citation gap to choose the right fix
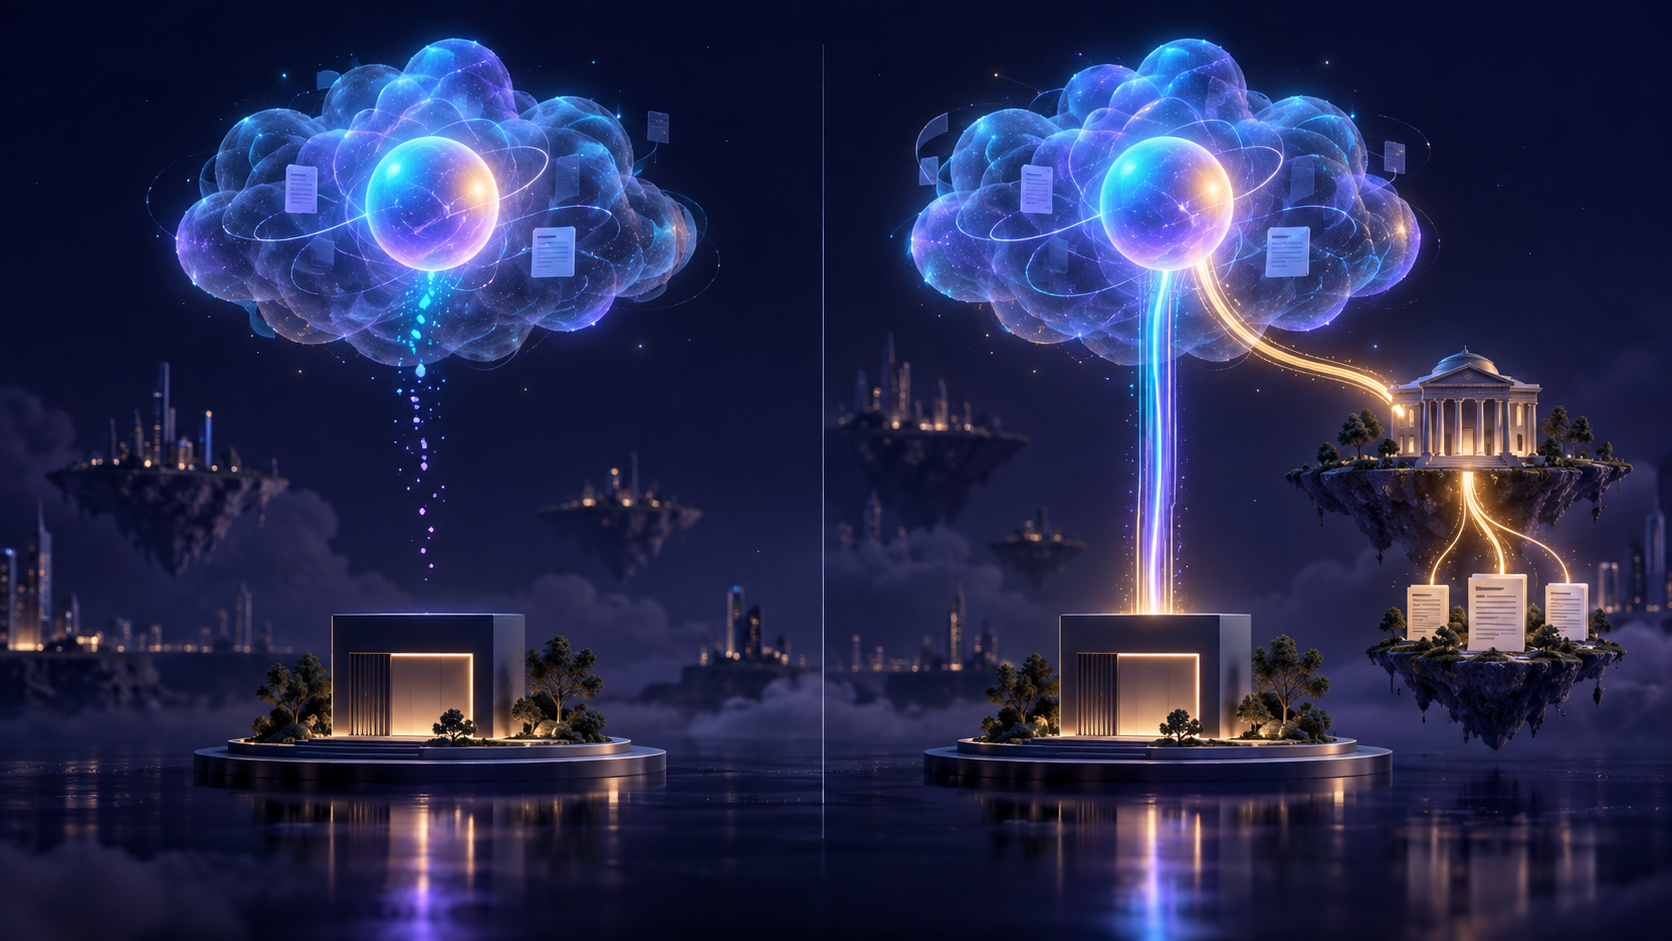
Once the dashboard exposes the four positions, resist the urge to prescribe more content for all of them. Start with the pages, claims, and platforms already visible in the answers. They show you where the system is finding evidence and where the connection breaks.
Mentioned but not cited: find who owns the evidence
Export the external URLs cited in brand-mentioned answers. Group them by the claim they support: category definition, product comparison, reputation, pricing context, technical capability, or another decision criterion. Then ask whether your site has an indexable page that answers the same legitimate question with clearer, current, directly attributable information.
- Prioritize claims that recur across multiple prompts, not a one-off citation.
- Identify whether the third-party page contains facts your site omits or expresses more plainly.
- Create or improve the appropriate owned page without copying the external treatment.
- Make the main answer easy to locate in the heading, opening explanation, and supporting details.
- Rerun the same prompt cohort and watch owned-citation rate, not just total mentions.
Third-party corroboration still has value. The objective is not to eliminate independent evidence. It is to avoid a position in which every important claim about your brand depends on a site you do not control.
Cited but not mentioned: connect the evidence to the entity
Inspect the sentence or section apparently supported by your page. If the page provides a generic statistic, definition, or tutorial while barely identifying the organization behind it, the AI system may use the evidence without making your brand part of the answer.
Clarify the relationship among the organization, its products, the category, and the supported claim. Use consistent entity names and make authorship or organizational ownership understandable on the page. Do not force the brand into every sentence; the goal is unambiguous attribution, not repetition. Track citation-to-mention conversion after the change.
Neither mentioned nor cited: test relevance before declaring failure
Absence does not prove that a page is poor. The prompt may target a category you do not serve, a language your content does not cover, or a product surface that favors a different source mix. Check prompt-market fit, indexing, crawl access, content freshness where the answer is time-sensitive, internal linking, and whether a relevant page exists at all.
Compare competitors at the claim and page level. A competitor mention tells you who appears; its cited pages tell you why the system may trust the answer. That distinction turns competitor tracking into a content and evidence diagnosis instead of a brand leaderboard.
Both visible but not producing outcomes: inspect the prompt mix
If mentions and owned citations are strong but qualified traffic or conversions remain weak, the visibility may sit in informational prompts far from a decision. Segment performance by intent before changing pages that are already doing their job. You may need better coverage of comparison, validation, or action prompts rather than more visibility for broad definitions.
Treat URL taxonomy as structural evidence, not a score
A coherent URL taxonomy can help AI engines interpret the subjects on which a site claims authority. It does not create authority by itself, but it can make topic boundaries and page relationships easier to understand.
Audit the structure from the point of view of a machine encountering one page at a time:
- Do related pages sit within a stable, recognizable topic family?
- Does each slug describe the page’s durable subject rather than an internal campaign label?
- Are the same subjects scattered across unrelated directories without a clear reason?
- Can you distinguish market and language versions consistently?
- Do internal links connect detailed pages to the appropriate topic hub?
- Are duplicate or obsolete routes competing with the page you want cited?
Do not change live URLs merely to make the taxonomy look tidy. A careless migration can break inbound links, internal links, and accumulated search signals. Map the intended structure first, preserve URLs that do not need to move, and use a planned redirect and internal-link update process for any necessary migration.
Key takeaways
- Measure brand mentions and owned-domain citations separately; they represent different kinds of visibility.
- Use a four-position matrix to distinguish owned authority, third-party dependence, unattributed evidence, and absence.
- Store the exact answer, citation URLs, platform, market, language, and run context behind every metric.
- Compare rates within a platform before rolling them up, because source-list and brand-mention behavior differ by product.
- Build prompts around customer decisions, with branded prompts separated from genuinely unbranded discovery prompts.
- Track revenue-market language alongside an English diagnostic baseline, and compare equivalent concepts rather than literal translations.
- Choose the intervention from the observed gap: content evidence, entity association, market relevance, technical discoverability, URL structure, or prompt coverage.
For your next reporting cycle, replace the headline score with the four-cell matrix, freeze a core prompt panel, and rerun it by platform and revenue-market language. Make one diagnosis-led change at a time. Then report which cell moved, which pages gained or lost evidence ownership, and whether that movement reached a customer outcome.
References
- HiGoodie Blog — The Importance of URL Taxonomy for AEO & GEO
- Search Engine Land — Your brand can win the mention and lose the citation
- Search Engine Land — What language should you track AI prompts in?

Leave a Reply