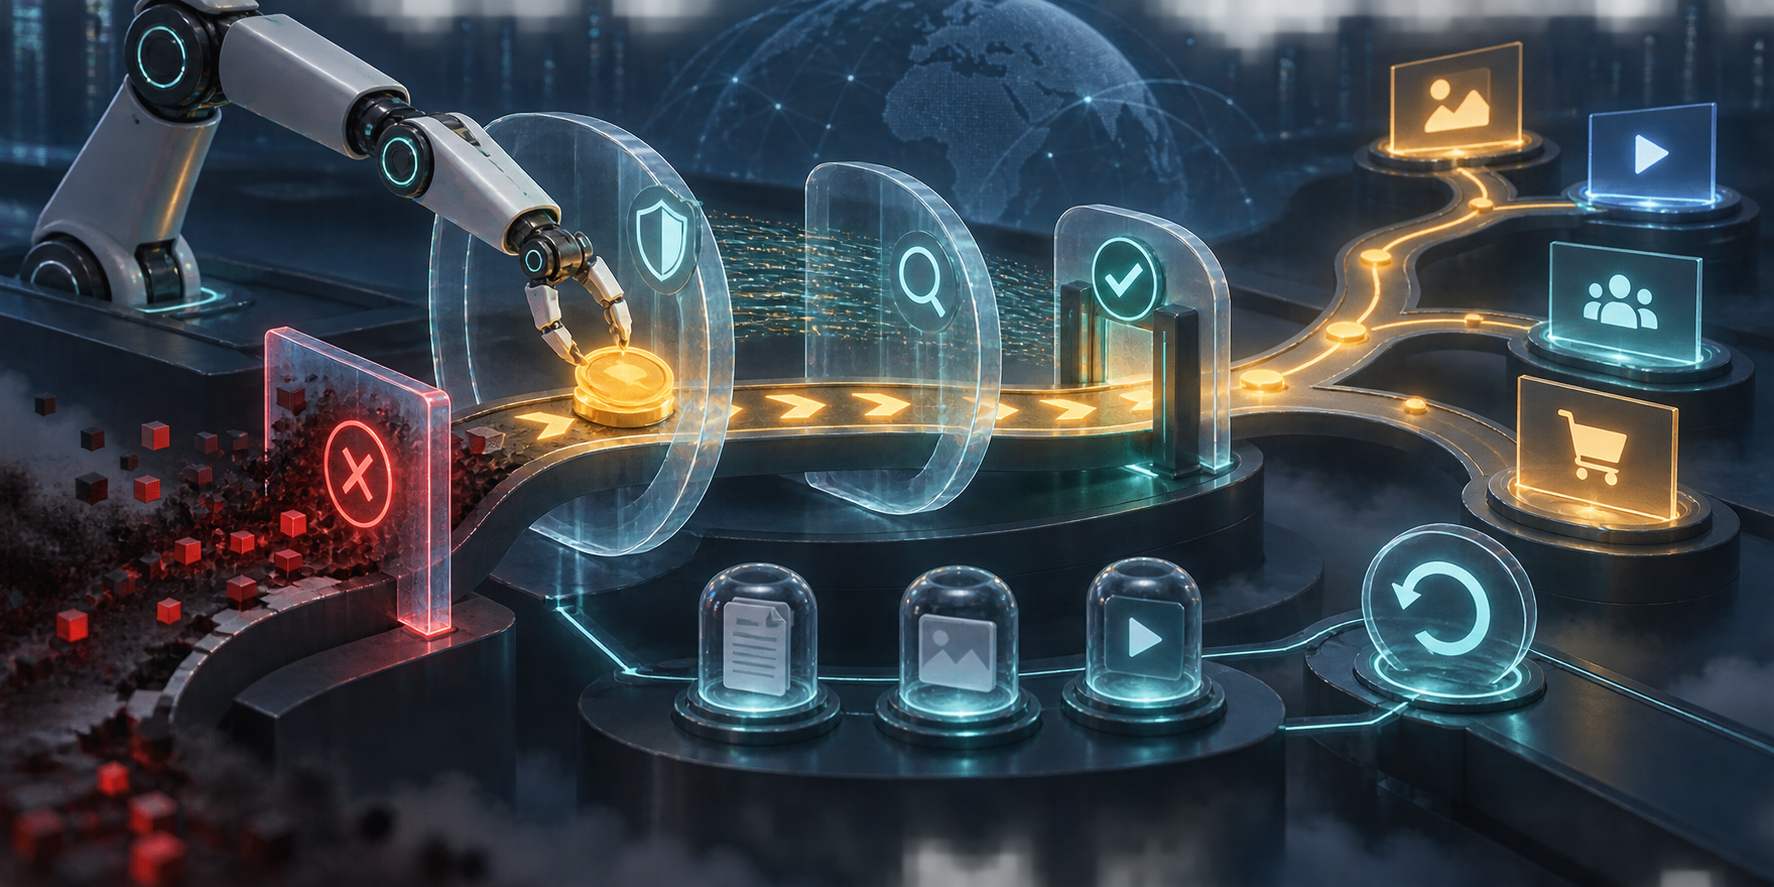
If your AI buying agent can raise bids, move budget, or scale a traffic source, an overspend is not the only failure you need to prevent. The agent can remain inside its budget and still fund low-quality traffic, follow a compromised redirect, or optimize against context that stopped being true weeks ago.
The safe design is a chain of evidence: trusted inputs, current security signals, explicit permissions, a reversible action, and a decision record. Build that chain before granting autonomy and you can use AI for speed without letting a superficially attractive metric become an instruction to make an expensive mistake.
A budget limit cannot tell the agent what to trust
A spend ceiling answers one question: how much money may move. It does not answer whether the evidence behind that move is complete, current, or safe.
Suppose the agent is instructed to lower cost per acquisition while remaining under a campaign cap. It finds a traffic source with cheap reported conversions and reallocates spend toward it. From the performance dashboard, that can look correct. Upstream, however, traffic-quality anomalies, changed landing-page behavior, or a questionable redirect may be telling a different story. A budget rule does nothing to reconcile those signals.
This is the central control problem in agentic media buying: the system will normally optimize the objective and evidence you expose to it. If safety evidence lives in a separate dashboard, arrives after optimization, or has no authority to block an action, it is not a guardrail. It is an after-the-fact report.
Ad buyers already recognize that autonomy needs more than a campaign cap. In IAB’s July 2026 Digital Video report, 40% of buyers wanted humans in the loop, 36% wanted an explainable audit trail, and 31% wanted explicit limits on agent actions. Those controls are useful, but they need to operate together. A tightly limited agent can still repeat a bad decision if its context is stale or its risk signals are missing.
Before automation, require the workflow to answer four questions in order:
- Are the required inputs present, current, and structurally valid?
- Do traffic-quality or security signals require a hold or stop?
- Does performance evidence justify the proposed change?
- Is that exact change inside the agent’s permission envelope?
If any answer is unknown, the default should be no scale. Unknown is not the same state as safe.
Key takeaways
- Make security and traffic quality hard inputs to optimization, not reports reviewed after spend has moved.
- Give every input an owner, freshness rule, version, and position in the conflict hierarchy.
- Separate permission to recommend an action from permission to execute it.
- Send humans ambiguous, novel, or high-impact cases instead of routing every routine bid adjustment through manual approval.
- Snapshot the context behind every material decision so you can reconstruct what the agent knew and what it was allowed to do.
- Revalidate the workflow whenever a tool, landing page, data schema, policy, template, or business rule changes.
Turn the prompt into a context contract
A prompt is only one part of an AI workflow’s operating context. The model may also read project knowledge, memory, skill instructions, attached files, tool results, earlier stages, and prior conversation turns. Some of that material can load without the operator selecting it for the current decision. Managing that full operating context is therefore a control function, not a prompt-writing exercise.
Write a context contract for each decision-making workflow. It should specify:
- Objective: Name the metric, reporting window, conversion definition, and business outcome. Do not leave the agent to choose among several plausible definitions of efficiency.
- Trusted inputs: List the approved performance, traffic-quality, security, destination, inventory, and policy feeds. Assign an owner and version to each one.
- Freshness: Define when each input becomes too old to authorize action. A stale security result must not be treated as a current clearance.
- Precedence: State which system wins when two tools disagree. If two platforms calculate a metric differently, the agent should not switch between them from one run to the next.
- Required fields: Declare the identifiers, timestamps, measurement periods, risk states, and data-quality flags that must be present. Reject incomplete payloads instead of asking the model to fill the gaps.
- Permission envelope: Separate read, recommend, pause, bid, budget, source, creative, and destination permissions. Scope them by account, campaign, channel, and action type.
- Stop conditions: Identify alerts that block action regardless of performance. Include the safe fallback: hold, pause, revert, or escalate.
- Conflict behavior: Tell the workflow what to do when a performance signal and a risk signal point in opposite directions. The agent should not be allowed to improvise which one matters more.
- Handoff format: Define what one stage may pass to the next, how facts differ from inferences, and how missing evidence is represented.
- Audit requirements: List the context versions, inputs, reasons, permissions, actions, and human interventions that must be recorded.
Make these controls machine-checkable wherever possible. A sentence that says to use recent data is weaker than a freshness field the workflow must validate. A paragraph asking the model to be cautious is weaker than a permission service that rejects an unauthorized budget change.
Pay particular attention to stage handoffs. An extraction step might pass a traffic-source ID, landing URL, observation time, conversion window, quality status, and missing-field list to an analysis step. The analysis step should accept that defined payload, not the extraction step’s entire working history. This keeps irrelevant material out and prevents a summary or inference from silently acquiring the authority of a verified fact.
Apply the same discipline to long-running conversations. If an agent evaluates several campaigns in one thread, earlier campaign details can remain available to later decisions. Start a clean decision context for each campaign or bounded batch, then attach only the approved context snapshot. Conversation history is convenient memory; it is not a reliable control database.
Put security, performance, and escalation in one loop
Evaluate evidence in a fixed order
Do not ask the agent to weigh every signal in one undifferentiated prompt. Use deterministic gates around the model and evaluate them in a fixed sequence:
- Evidence gate: Confirm that required feeds arrived, their schemas match expectations, their timestamps pass freshness rules, and campaign identifiers agree.
- Integrity gate: Check malware, traffic-quality, redirect, destination, cloaking, policy, and other applicable risk states.
- Performance gate: Evaluate the proposed action against the campaign objective only after integrity checks pass.
- Authority gate: Verify that the account, campaign, action type, and size of change fall inside the agent’s current permissions.
- Execution gate: Record the decision and rollback point, execute once, and confirm that the advertising platform accepted the intended change.
This ordering matters. If performance is evaluated first, a strong result can anchor the rest of the reasoning and turn a risk alert into something the workflow tries to explain away. Security should be able to veto scale even when the cost per acquisition looks excellent.
| Decision state | Typical evidence | Agent response | Human role |
|---|---|---|---|
| Green | Required inputs are current, schema checks pass, no active risk alert exists, performance supports the change, and the action is permitted. | Execute the bounded action, verify the platform response, and log the full decision record. | Review sampled decisions and aggregate behavior, not every routine action. |
| Amber | A mild anomaly, changed landing behavior, new redirect, incomplete evidence, or conflicting systems makes the result uncertain. | Do not scale. Hold the proposed change, collect more evidence, or continue at the existing state if that is the approved safe fallback. | Resolve the conflict, approve one action, or amend the governing rule with an owner and version. |
| Red | A high-confidence malware or security alert, invalid destination, missing mandatory input, failed execution check, or request outside the permission envelope. | Block the action and invoke the defined pause or rollback procedure. | Investigate the incident and explicitly authorize any restart. |
Run integrity checks throughout the campaign lifecycle, not only at approval. Destination behavior can change after launch, and cloaked content may vary by location, device, visitor profile, or inspection time. One clean observation is not permanent clearance.
Platform-specific evidence illustrates why the checks must remain continuous. In PropellerAds’ own Q2 2026 moderation data, total rejected campaigns fell from 36,085 to 20,790 quarter over quarter, while the share attributed to antivirus and malware issues rose from 23.3% to 45.9% and the absolute number increased by roughly 14%. That is not a market-wide malware measure, but it demonstrates the operational point: an improving top-line count can coexist with a worsening risk category. A single aggregate metric cannot clear traffic for autonomous scale.
Route ambiguity to people, not routine volume
Human review works best where judgment changes the answer. Requiring approval for every bid adjustment removes much of the value of automation and trains reviewers to click through repetitive requests. Instead, trigger review when:
- risk and performance signals conflict;
- a required input is missing, stale, or supplied in an unexpected format;
- the landing page, redirect chain, domain, conversion definition, or measurement setup changes;
- the proposed action is outside the permission envelope;
- two approved tools disagree and the precedence rule does not resolve the difference;
- the agent encounters a new anomaly that is not represented in the runbook;
- a hard-stop alert fires or an automated action needs to be reversed;
- repeated small actions produce a material cumulative change that requires a higher level of authority.
Give the reviewer a compact decision bundle: the proposed change, expected effect, measurement window, input timestamps, security state, conflicting evidence, applicable permission, safe fallback, and rollback option. Do not send a generic request to check the campaign. The person should be able to see why the case was escalated and which decision is required.
Make escalation timeouts safe. If the reviewer does not respond, the workflow should preserve the approved state or pause according to the runbook. Silence must never become permission to scale.
Test for context rot before granting more authority
Use the symptom to find the failing context
A workflow can keep running while the material around it degrades. Services change, teams reorganize, policies are revised, files move, tools alter their return formats, and new templates contradict old ones. The resulting failure has six recognizable forms: volume, competition, divergence, staleness, conflict, and contamination.
- Vague output or skipped rules: Suspect excess context. Filter large platform exports before analysis, extract only the required facts, and run extraction and decision-making in separate contexts.
- Different answers to the same request: Suspect competing providers, duplicate files, multiple templates, or divergent tool paths. Pin the approved provider and template version, then remove or quarantine alternatives.
- The same wrong answer every time: Suspect stale or conflicting material being treated as authoritative. Check file dates, policy versions, ownership, precedence, and references to moved resources.
- Unexpected claims inherited from an earlier stage: Suspect contamination. Validate every handoff against its schema, preserve provenance, and label inferred values so they cannot masquerade as verified inputs.
Revalidation should be event-driven as well as scheduled. A tool upgrade, API schema change, new data provider, revised landing page, modified offer, policy update, renamed file, new skill, or altered team responsibility should trigger a check before the workflow resumes autonomous actions. If the input contract changes unexpectedly, freeze execution while preserving read-only monitoring.
Use a staged authority ladder
Do not make the first production test a live spending decision. Move through an authority ladder with explicit exit criteria:
- Replay: Run known past cases without platform access. Confirm that the workflow produces the expected hold, block, recommendation, and escalation states.
- Shadow: Read live inputs and generate decisions without executing them. Compare proposed actions with actual outcomes and inspect disagreements.
- Recommend: Let the agent prepare an action, evidence bundle, and rollback plan while a human executes or rejects it.
- Constrained execution: Grant the smallest useful action scope. Keep hard stops, cumulative limits, confirmation checks, and rollback available outside the model.
- Expanded execution: Add campaigns or action types only after the current scope produces reconstructable decisions and responds correctly to changed or missing evidence.
Your test pack should include failure cases, not only clean campaigns. Give the workflow a cheap-conversion signal paired with a security block; a strong performance result with stale evidence; two approved tools that disagree; a redirect introduced after launch; a landing page whose behavior changes; an action that fits the budget but exceeds permission; and an obsolete template that describes a retired offer. The system passes only if it stops or escalates for the right reason.
Log enough to reconstruct the decision
A platform change log tells you what happened. An agent audit record must also tell you why it happened and which evidence was available at that moment. Record:
- campaign, account, decision ID, and timestamp;
- workflow, model, prompt, policy, template, and context versions;
- the identity, timestamp, freshness result, and schema result for every required input;
- performance, traffic-quality, destination, and security states used in the decision;
- the proposed action, alternatives considered, and reason for the selected state;
- the permission rule that allowed or blocked execution;
- the exact platform action and confirmation response;
- human approvals, denials, overrides, and rule changes;
- the rollback point and any incident reference.
Version the context as carefully as the automation code. Otherwise, a later reviewer may be able to reproduce the prompt but not the conditions that made its answer appear reasonable.
Choose one active campaign and put the workflow into shadow mode. Write its context contract, connect current security and traffic-quality states to the decision gate, and run the failure test pack. Grant execution authority only after the agent can prove three things before every move: the evidence is current, the traffic is eligible to scale, and the requested action is permitted.
References
- Search Engine Land – Context engineering: How to prevent AI workflows from degrading
- Search Engine Land – Agentic media buying needs malware guardrails: A PropellerAds view by PropellerAds

Leave a Reply