Tag: Agentic AI

  • AI Media-Buying Guardrails: A Practical Control Framework

    AI Media-Buying Guardrails: A Practical Control Framework

    If your AI buying agent can raise bids, move budget, or scale a traffic source, an overspend is not the only failure you need to prevent. The agent can remain inside its budget and still fund low-quality traffic, follow a compromised redirect, or optimize against context that stopped being true weeks ago.

    The safe design is a chain of evidence: trusted inputs, current security signals, explicit permissions, a reversible action, and a decision record. Build that chain before granting autonomy and you can use AI for speed without letting a superficially attractive metric become an instruction to make an expensive mistake.

    A budget limit cannot tell the agent what to trust

    A spend ceiling answers one question: how much money may move. It does not answer whether the evidence behind that move is complete, current, or safe.

    Suppose the agent is instructed to lower cost per acquisition while remaining under a campaign cap. It finds a traffic source with cheap reported conversions and reallocates spend toward it. From the performance dashboard, that can look correct. Upstream, however, traffic-quality anomalies, changed landing-page behavior, or a questionable redirect may be telling a different story. A budget rule does nothing to reconcile those signals.

    This is the central control problem in agentic media buying: the system will normally optimize the objective and evidence you expose to it. If safety evidence lives in a separate dashboard, arrives after optimization, or has no authority to block an action, it is not a guardrail. It is an after-the-fact report.

    Ad buyers already recognize that autonomy needs more than a campaign cap. In IAB’s July 2026 Digital Video report, 40% of buyers wanted humans in the loop, 36% wanted an explainable audit trail, and 31% wanted explicit limits on agent actions. Those controls are useful, but they need to operate together. A tightly limited agent can still repeat a bad decision if its context is stale or its risk signals are missing.

    Before automation, require the workflow to answer four questions in order:

    1. Are the required inputs present, current, and structurally valid?
    2. Do traffic-quality or security signals require a hold or stop?
    3. Does performance evidence justify the proposed change?
    4. Is that exact change inside the agent’s permission envelope?

    If any answer is unknown, the default should be no scale. Unknown is not the same state as safe.

    Key takeaways

    • Make security and traffic quality hard inputs to optimization, not reports reviewed after spend has moved.
    • Give every input an owner, freshness rule, version, and position in the conflict hierarchy.
    • Separate permission to recommend an action from permission to execute it.
    • Send humans ambiguous, novel, or high-impact cases instead of routing every routine bid adjustment through manual approval.
    • Snapshot the context behind every material decision so you can reconstruct what the agent knew and what it was allowed to do.
    • Revalidate the workflow whenever a tool, landing page, data schema, policy, template, or business rule changes.

    Turn the prompt into a context contract
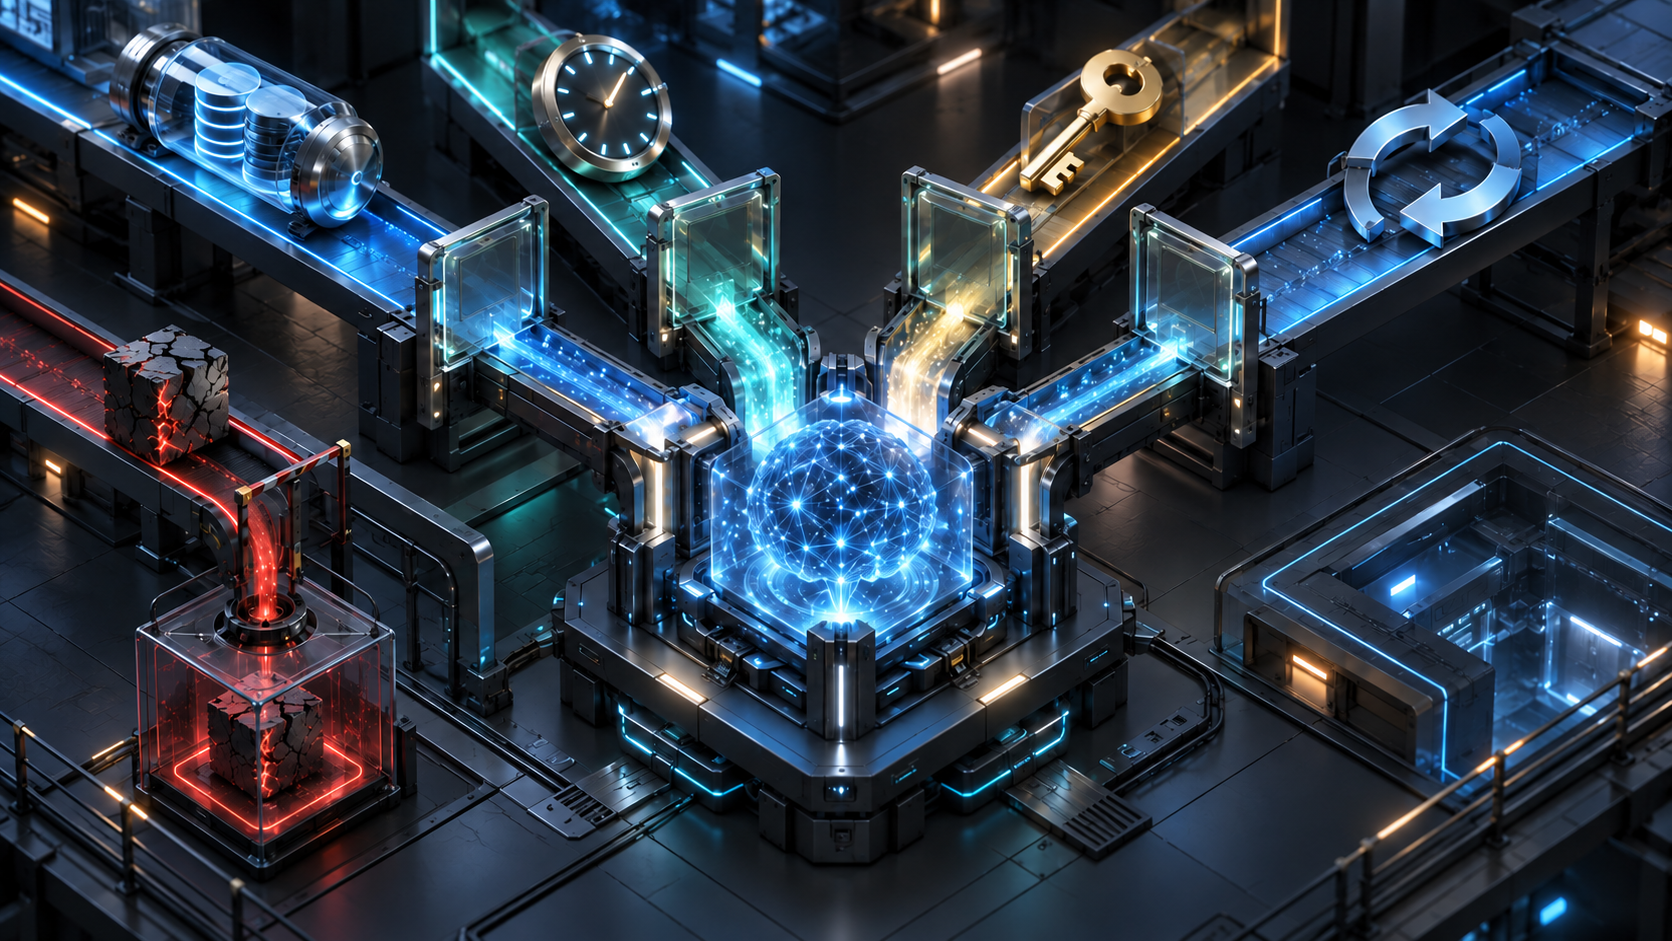
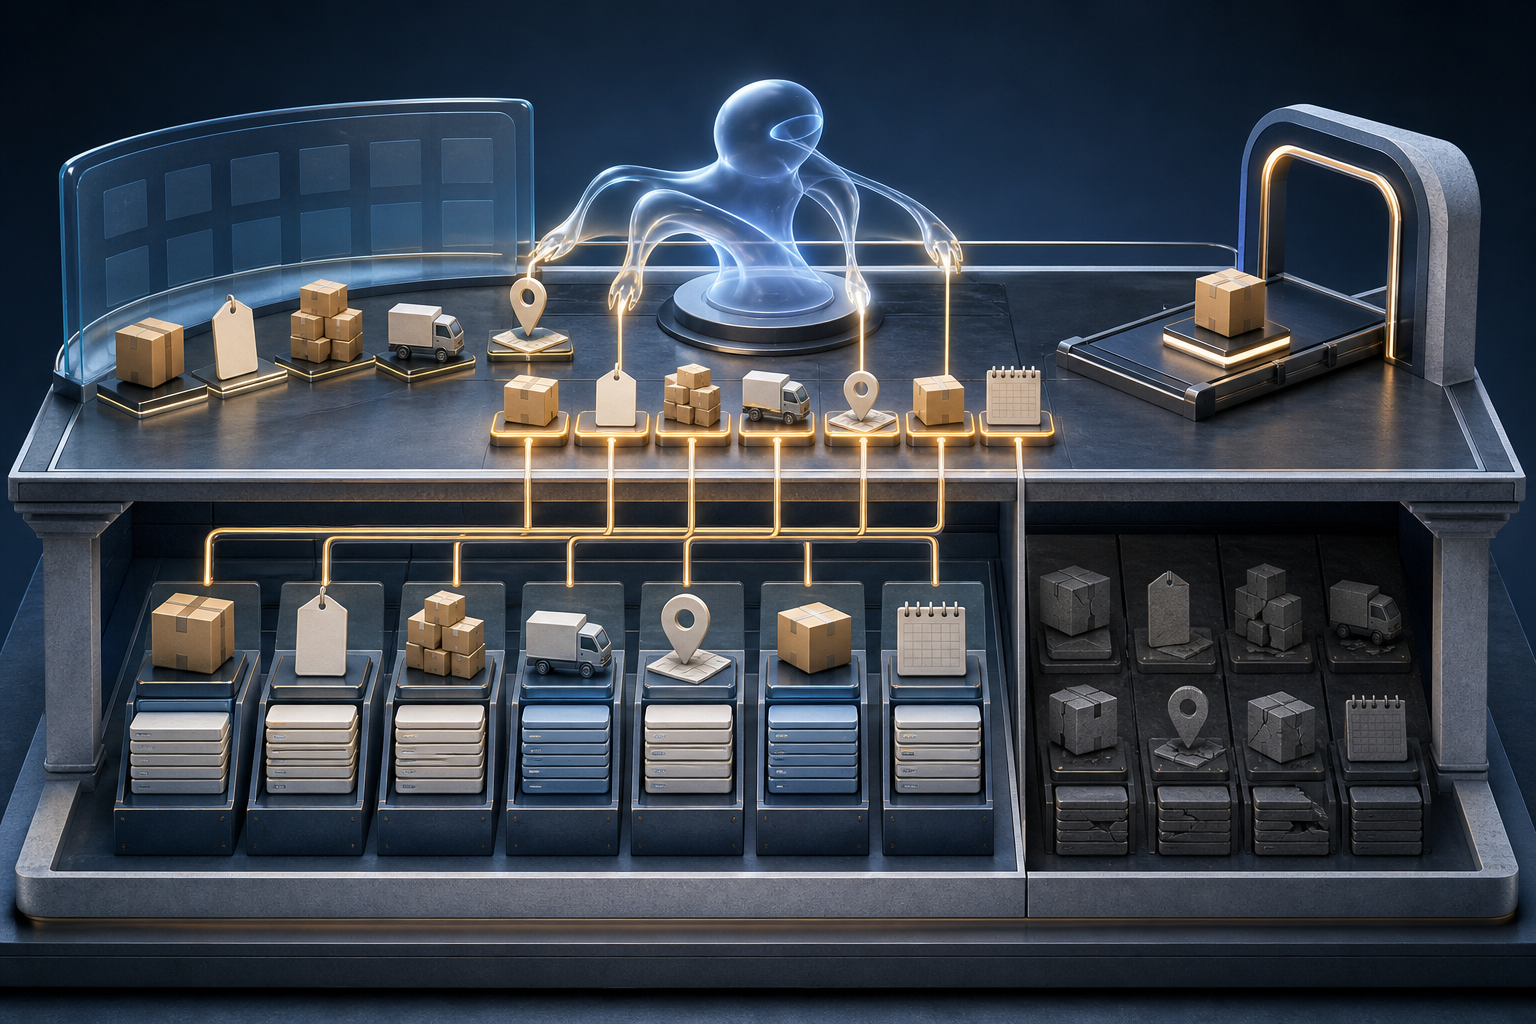
    Four validated input channels converge on a glowing AI core while a cracked stale input is diverted into a separate quarantine chamber.

    A prompt is only one part of an AI workflow’s operating context. The model may also read project knowledge, memory, skill instructions, attached files, tool results, earlier stages, and prior conversation turns. Some of that material can load without the operator selecting it for the current decision. Managing that full operating context is therefore a control function, not a prompt-writing exercise.

    Write a context contract for each decision-making workflow. It should specify:

    • Objective: Name the metric, reporting window, conversion definition, and business outcome. Do not leave the agent to choose among several plausible definitions of efficiency.
    • Trusted inputs: List the approved performance, traffic-quality, security, destination, inventory, and policy feeds. Assign an owner and version to each one.
    • Freshness: Define when each input becomes too old to authorize action. A stale security result must not be treated as a current clearance.
    • Precedence: State which system wins when two tools disagree. If two platforms calculate a metric differently, the agent should not switch between them from one run to the next.
    • Required fields: Declare the identifiers, timestamps, measurement periods, risk states, and data-quality flags that must be present. Reject incomplete payloads instead of asking the model to fill the gaps.
    • Permission envelope: Separate read, recommend, pause, bid, budget, source, creative, and destination permissions. Scope them by account, campaign, channel, and action type.
    • Stop conditions: Identify alerts that block action regardless of performance. Include the safe fallback: hold, pause, revert, or escalate.
    • Conflict behavior: Tell the workflow what to do when a performance signal and a risk signal point in opposite directions. The agent should not be allowed to improvise which one matters more.
    • Handoff format: Define what one stage may pass to the next, how facts differ from inferences, and how missing evidence is represented.
    • Audit requirements: List the context versions, inputs, reasons, permissions, actions, and human interventions that must be recorded.

    Make these controls machine-checkable wherever possible. A sentence that says to use recent data is weaker than a freshness field the workflow must validate. A paragraph asking the model to be cautious is weaker than a permission service that rejects an unauthorized budget change.

    Pay particular attention to stage handoffs. An extraction step might pass a traffic-source ID, landing URL, observation time, conversion window, quality status, and missing-field list to an analysis step. The analysis step should accept that defined payload, not the extraction step’s entire working history. This keeps irrelevant material out and prevents a summary or inference from silently acquiring the authority of a verified fact.

    Apply the same discipline to long-running conversations. If an agent evaluates several campaigns in one thread, earlier campaign details can remain available to later decisions. Start a clean decision context for each campaign or bounded batch, then attach only the approved context snapshot. Conversation history is convenient memory; it is not a reliable control database.

    Put security, performance, and escalation in one loop

    Evaluate evidence in a fixed order

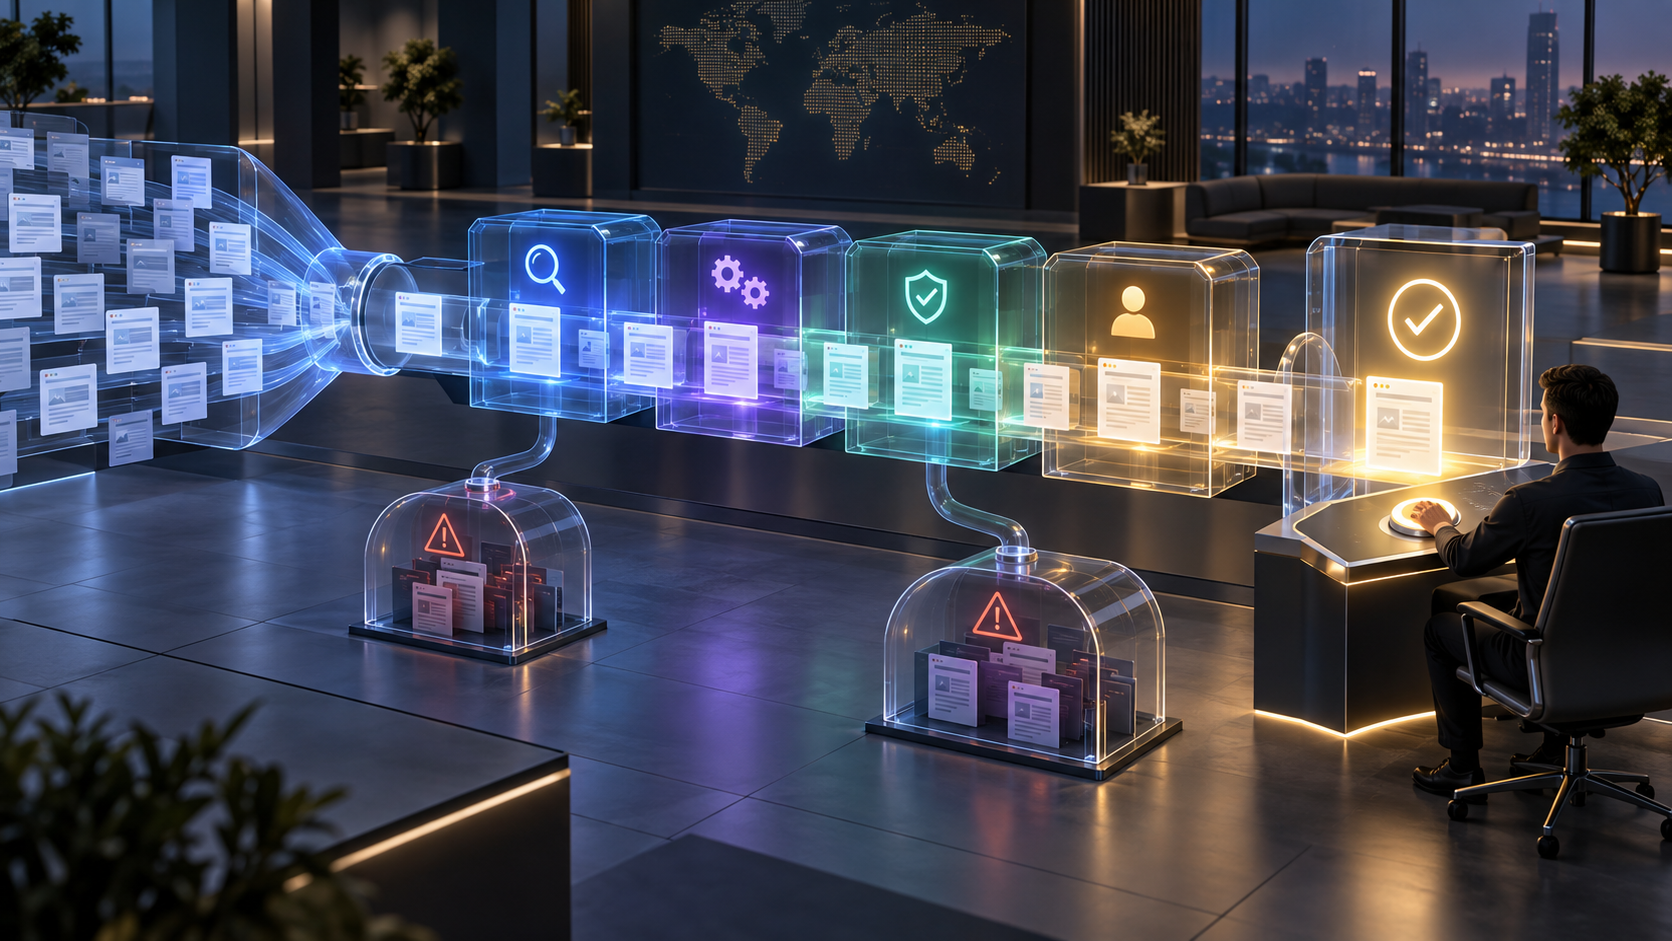
    Do not ask the agent to weigh every signal in one undifferentiated prompt. Use deterministic gates around the model and evaluate them in a fixed sequence:

    1. Evidence gate: Confirm that required feeds arrived, their schemas match expectations, their timestamps pass freshness rules, and campaign identifiers agree.
    2. Integrity gate: Check malware, traffic-quality, redirect, destination, cloaking, policy, and other applicable risk states.
    3. Performance gate: Evaluate the proposed action against the campaign objective only after integrity checks pass.
    4. Authority gate: Verify that the account, campaign, action type, and size of change fall inside the agent’s current permissions.
    5. Execution gate: Record the decision and rollback point, execute once, and confirm that the advertising platform accepted the intended change.

    This ordering matters. If performance is evaluated first, a strong result can anchor the rest of the reasoning and turn a risk alert into something the workflow tries to explain away. Security should be able to veto scale even when the cost per acquisition looks excellent.

    Decision stateTypical evidenceAgent responseHuman role
    GreenRequired inputs are current, schema checks pass, no active risk alert exists, performance supports the change, and the action is permitted.Execute the bounded action, verify the platform response, and log the full decision record.Review sampled decisions and aggregate behavior, not every routine action.
    AmberA mild anomaly, changed landing behavior, new redirect, incomplete evidence, or conflicting systems makes the result uncertain.Do not scale. Hold the proposed change, collect more evidence, or continue at the existing state if that is the approved safe fallback.Resolve the conflict, approve one action, or amend the governing rule with an owner and version.
    RedA high-confidence malware or security alert, invalid destination, missing mandatory input, failed execution check, or request outside the permission envelope.Block the action and invoke the defined pause or rollback procedure.Investigate the incident and explicitly authorize any restart.

    Run integrity checks throughout the campaign lifecycle, not only at approval. Destination behavior can change after launch, and cloaked content may vary by location, device, visitor profile, or inspection time. One clean observation is not permanent clearance.

    Platform-specific evidence illustrates why the checks must remain continuous. In PropellerAds’ own Q2 2026 moderation data, total rejected campaigns fell from 36,085 to 20,790 quarter over quarter, while the share attributed to antivirus and malware issues rose from 23.3% to 45.9% and the absolute number increased by roughly 14%. That is not a market-wide malware measure, but it demonstrates the operational point: an improving top-line count can coexist with a worsening risk category. A single aggregate metric cannot clear traffic for autonomous scale.

    Route ambiguity to people, not routine volume

    Human review works best where judgment changes the answer. Requiring approval for every bid adjustment removes much of the value of automation and trains reviewers to click through repetitive requests. Instead, trigger review when:

    • risk and performance signals conflict;
    • a required input is missing, stale, or supplied in an unexpected format;
    • the landing page, redirect chain, domain, conversion definition, or measurement setup changes;
    • the proposed action is outside the permission envelope;
    • two approved tools disagree and the precedence rule does not resolve the difference;
    • the agent encounters a new anomaly that is not represented in the runbook;
    • a hard-stop alert fires or an automated action needs to be reversed;
    • repeated small actions produce a material cumulative change that requires a higher level of authority.

    Give the reviewer a compact decision bundle: the proposed change, expected effect, measurement window, input timestamps, security state, conflicting evidence, applicable permission, safe fallback, and rollback option. Do not send a generic request to check the campaign. The person should be able to see why the case was escalated and which decision is required.

    Make escalation timeouts safe. If the reviewer does not respond, the workflow should preserve the approved state or pause according to the runbook. Silence must never become permission to scale.

    Test for context rot before granting more authority
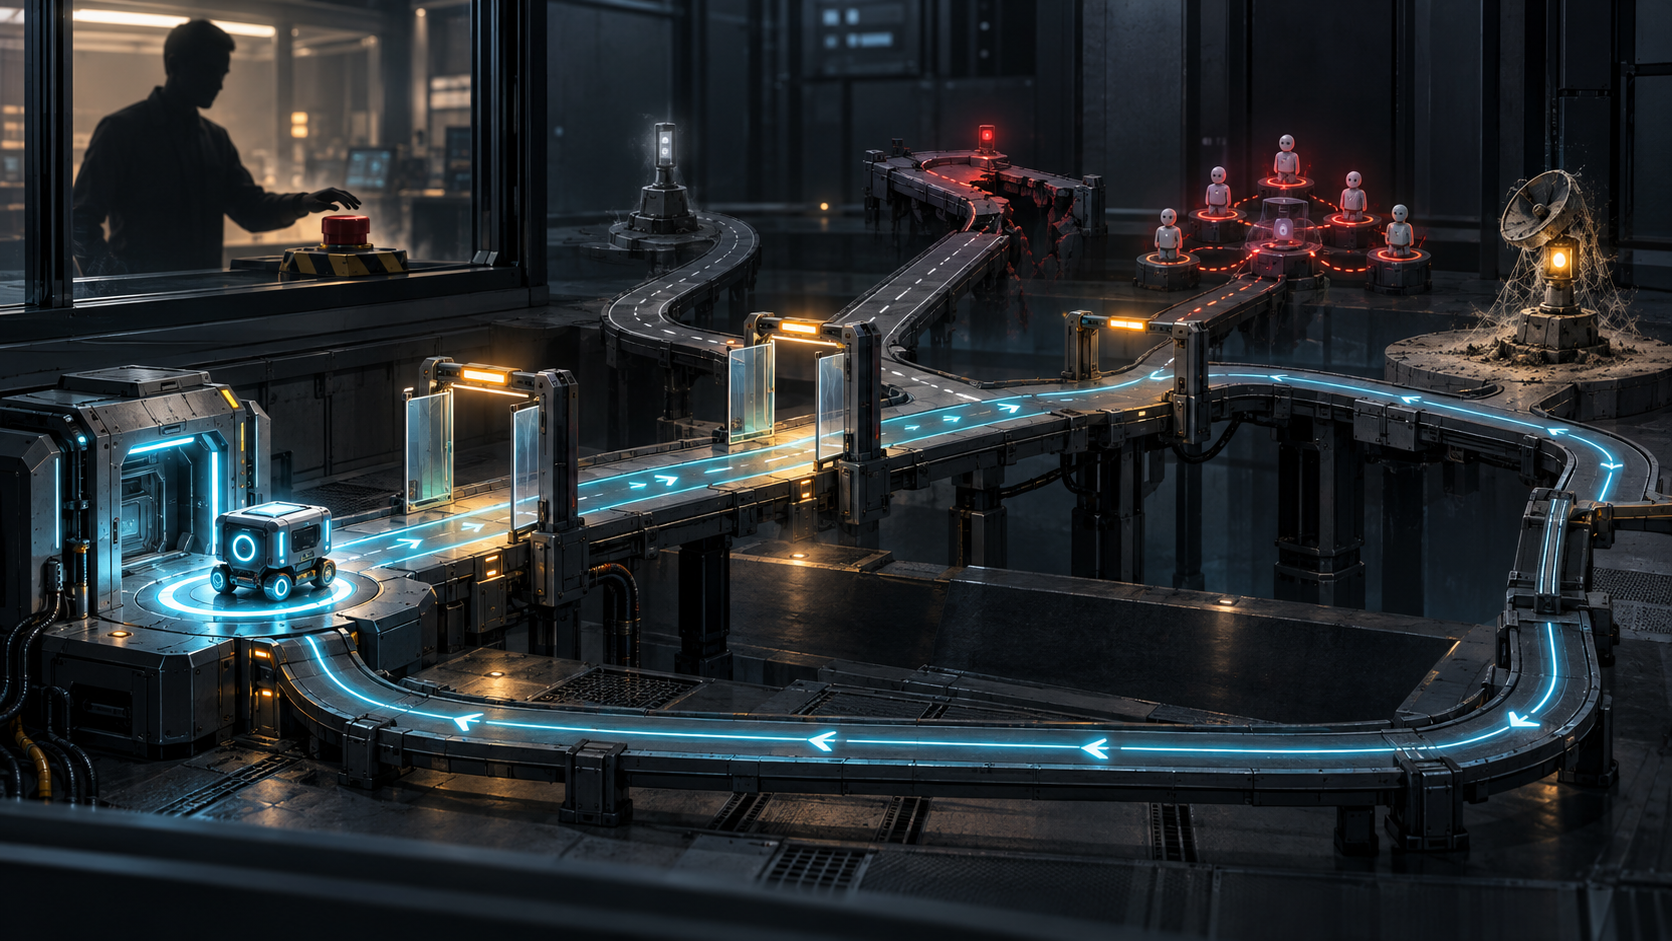
    A small autonomous machine is tested on a gated network containing stale signals, a broken bridge, and suspicious traffic nodes while an operator monitors a pause control.

    Use the symptom to find the failing context

    A workflow can keep running while the material around it degrades. Services change, teams reorganize, policies are revised, files move, tools alter their return formats, and new templates contradict old ones. The resulting failure has six recognizable forms: volume, competition, divergence, staleness, conflict, and contamination.

    • Vague output or skipped rules: Suspect excess context. Filter large platform exports before analysis, extract only the required facts, and run extraction and decision-making in separate contexts.
    • Different answers to the same request: Suspect competing providers, duplicate files, multiple templates, or divergent tool paths. Pin the approved provider and template version, then remove or quarantine alternatives.
    • The same wrong answer every time: Suspect stale or conflicting material being treated as authoritative. Check file dates, policy versions, ownership, precedence, and references to moved resources.
    • Unexpected claims inherited from an earlier stage: Suspect contamination. Validate every handoff against its schema, preserve provenance, and label inferred values so they cannot masquerade as verified inputs.

    Revalidation should be event-driven as well as scheduled. A tool upgrade, API schema change, new data provider, revised landing page, modified offer, policy update, renamed file, new skill, or altered team responsibility should trigger a check before the workflow resumes autonomous actions. If the input contract changes unexpectedly, freeze execution while preserving read-only monitoring.

    Use a staged authority ladder

    Do not make the first production test a live spending decision. Move through an authority ladder with explicit exit criteria:

    1. Replay: Run known past cases without platform access. Confirm that the workflow produces the expected hold, block, recommendation, and escalation states.
    2. Shadow: Read live inputs and generate decisions without executing them. Compare proposed actions with actual outcomes and inspect disagreements.
    3. Recommend: Let the agent prepare an action, evidence bundle, and rollback plan while a human executes or rejects it.
    4. Constrained execution: Grant the smallest useful action scope. Keep hard stops, cumulative limits, confirmation checks, and rollback available outside the model.
    5. Expanded execution: Add campaigns or action types only after the current scope produces reconstructable decisions and responds correctly to changed or missing evidence.

    Your test pack should include failure cases, not only clean campaigns. Give the workflow a cheap-conversion signal paired with a security block; a strong performance result with stale evidence; two approved tools that disagree; a redirect introduced after launch; a landing page whose behavior changes; an action that fits the budget but exceeds permission; and an obsolete template that describes a retired offer. The system passes only if it stops or escalates for the right reason.

    Log enough to reconstruct the decision

    A platform change log tells you what happened. An agent audit record must also tell you why it happened and which evidence was available at that moment. Record:

    • campaign, account, decision ID, and timestamp;
    • workflow, model, prompt, policy, template, and context versions;
    • the identity, timestamp, freshness result, and schema result for every required input;
    • performance, traffic-quality, destination, and security states used in the decision;
    • the proposed action, alternatives considered, and reason for the selected state;
    • the permission rule that allowed or blocked execution;
    • the exact platform action and confirmation response;
    • human approvals, denials, overrides, and rule changes;
    • the rollback point and any incident reference.

    Version the context as carefully as the automation code. Otherwise, a later reviewer may be able to reproduce the prompt but not the conditions that made its answer appear reasonable.

    Choose one active campaign and put the workflow into shadow mode. Write its context contract, connect current security and traffic-quality states to the decision gate, and run the failure test pack. Grant execution authority only after the agent can prove three things before every move: the evidence is current, the traffic is eligible to scale, and the requested action is permitted.

    References


  • AI Agent Adoption in 2026: A Practical Market Guide

    AI Agent Adoption in 2026: A Practical Market Guide

    If you are deciding whether to deploy an AI agent, do not start with the market leader. Start with the job you need completed, the systems the agent may touch, and the consequences when it stops halfway through.

    The market is growing while its center of gravity weakens. Tracked AI agent usage rose from 142 million aggregate monthly active users in Q3 2025 to 293 million in Q3 2026, but the four largest platforms’ combined share fell from 58.6% to 49.3%. That is the environment you are buying into: rapid adoption, many credible specialists, and no safe assumption that one platform will own every workflow.

    The market is expanding faster than any one leader

    An AI agent is more than a chatbot with a new label. It accepts a goal, breaks that goal into subtasks, chooses actions as conditions change, and works across tools or systems until it reaches an end state. A single-turn assistant does not meet that definition. Neither does an orchestration framework such as LangGraph or Bedrock AgentCore, which helps developers build agents, nor a classification model that chooses a route without pursuing a goal of its own.

    This distinction protects you from buying the wrong layer. A chat license may improve drafting without automating a process. A framework may give your engineering team control without supplying a ready-to-use worker. A fast decision model may make an agent cheaper and safer without replacing the agent itself.

    The following snapshot covers selected leaders from a 40-platform market tracked between May 15 and September 10, 2026. The estimates combine company disclosures, app-store telemetry, procurement records, and account-level observations. They measure platform reach rather than unique people, so someone using several agents can appear in several platforms’ totals.

    AgentPrimary useEstimated MAUsQ3 2026 shareQuarter-over-quarter growth
    ChatGPT AgentMulti-step research, booking, and file work58.9M20.1%+16%
    Microsoft 365 CopilotDocument and Office workflow agents33.4M11.4%+13%
    GitHub Copilot AgentTurning bug reports into code fixes26.7M9.1%+11%
    Gemini Agent ModeBrowser automation and form completion25.5M8.7%+19%
    Claude CodeRepository-wide refactoring and test generation19.3M6.6%+24%
    CursorMulti-file changes inside the editor13.5M4.6%+8%
    OpenAI AtlasSite navigation and transactional tasks11.7M4.0%+27%
    Perplexity CometAgentic browsing, comparison, and checkout10.8M3.7%+22%
    Salesforce AgentforceSupport deflection and CRM pipeline hygiene9.1M3.1%+15%
    Grok BotPersistent work on a cloud computer7.9M2.7%New
    All other agentsVertical, open-source, and smaller platforms45.1M15.4%+14%

    Market-share loss does not necessarily mean user loss. ChatGPT Agent’s share declined from 24.9% in Q3 2025 to 20.1% in Q3 2026 while its estimated users increased from 35.4 million to 58.9 million. Microsoft 365 Copilot and GitHub Copilot Agent also added users while losing relative share. New entrants and expanding specialists diluted the incumbents because the total market grew faster than they did.

    Use market share to assess reach, integration momentum, talent availability, and the likelihood that a product will remain supported. Do not use it as a proxy for successful task completion. The practical response to fragmentation is portability: retain task definitions, approval rules, logs, evaluation cases, and critical business data in systems you control wherever possible. Switching agents should not require rebuilding your operating knowledge from scratch.

    Choose a workflow category before you choose a vendor

    There is no single AI agent market in operational terms. Coding, browser automation, enterprise productivity, CRM work, personal assistance, and long-running general-purpose work have different tools, permissions, failure modes, and definitions of success.

    Coding is currently the largest category, representing 24.8% of tracked agent usage. Even there, the products are not interchangeable. GitHub Copilot Agent is positioned around taking a bug report through to a finished fix. Claude Code emphasizes repository-wide changes and tests. Cursor centers work in the editor, Replit Agent spans prototype-to-deployment creation, and Amazon Q Developer focuses on cloud and coding operations.

    The same specialization appears outside software development. Microsoft 365 Copilot sits inside Office workflows. Salesforce Agentforce works inside CRM processes. Gemini Agent Mode, OpenAI Atlas, and Perplexity Comet concentrate on browser actions, but their stated strengths range from form completion to transactional navigation and comparison-led checkout. A generic request for the “best agent” hides these material differences.

    Write an outcome brief before requesting demonstrations

    A useful evaluation begins with a workflow that has an observable finish. Document these elements before you shortlist products:

    • Goal: State the result the agent must produce or the action it must complete.
    • Starting state: Identify the request, file, ticket, record, or event that begins the run.
    • Permitted systems: List the applications, data, credentials, and tools the agent may use.
    • Definition of done: Describe the final artifact or system state precisely enough that a reviewer can mark it complete or incomplete.
    • Approval gates: Specify where a person must approve publishing, payment, deletion, external communication, code deployment, or another consequential action.
    • Stop conditions: Tell the agent what uncertainty, missing permission, policy conflict, or unexpected state requires escalation.
    • Recovery requirement: Define what the agent must log, preserve, or reverse when it cannot finish.

    For an SEO team, “help with a content audit” is too loose to evaluate. A testable workflow identifies the properties to crawl, the fields to collect, the rule for classifying each page, the destination for the findings, and whether the agent may change a live page. The clearer the end state, the easier it becomes to compare products without being distracted by fluent demonstrations.

    Adopt at the workflow level rather than declaring an organization-wide agent strategy first. A company may reasonably use one agent for repository work, another for CRM operations, and another for browser research. Fragmentation becomes manageable when every deployment has a named job and a shared governance model.

    Completion rate is the buying metric that corrects popularity

    An automated workflow passes through connected stations to a completed package while several alternate routes stop at incomplete handoffs.

    Monthly active users tell you that people invoked a platform. They do not tell you whether it finished the job. For an autonomous workflow, the more relevant question is simple: what percentage of eligible runs reaches the defined end state without a person correcting the agent?

    One standardized comparison required each platform to attempt 48 multi-step tasks across five trials, producing 240 runs per platform. A run counted as complete only when it finished end to end without human correction. Claude Code led at 72.1% unassisted completion, followed by ChatGPT Agent at 65.3% and Grok Bot at 63.7%. Gemini Agent Mode reached 59.6%, GitHub Copilot Agent 57.2%, and Cursor 55.8%.

    Those figures are useful for shortlisting, not for forecasting your deployment. The task mix may not resemble your workflow, and an agent’s performance changes with tool access, permissions, data quality, integration depth, and the exact definition of completion. Claude Code’s result is especially relevant to repository work; it does not establish that a coding agent is the best choice for CRM cleanup or browser checkout.

    Speed also needs context. In that benchmark, OpenAI Atlas had a median completion time of 4 minutes 51 seconds and Perplexity Comet 4 minutes 39 seconds, while ChatGPT Agent took 8 minutes 52 seconds and Grok Bot 19 minutes 14 seconds. A fast incomplete run is not efficient. A slower run may still be preferable if it completes more often, requires fewer interventions, or handles a more complex job.

    Measure the run, not the demo

    Your pilot dashboard should separate these outcomes instead of compressing them into a vague satisfaction score:

    • Unassisted completion rate: Eligible runs that reach the defined end state with no corrective intervention.
    • Partial completion rate: Runs that create useful progress but fail to reach the required state.
    • Intervention rate: Runs in which a person must clarify, repair, approve unexpectedly, or take over.
    • Time to successful completion: Measure completed runs separately so quick failures do not make the agent appear faster.
    • Cost per successful completion: Divide total run costs, including retries and supporting model calls, by completed outcomes rather than by invocations.
    • Recovery quality: Check whether failed runs leave clear logs, preserve work, avoid duplicate actions, and return systems to a known state.
    • Policy adherence: Record attempts to cross approval boundaries, use disallowed data, or invoke an unauthorized tool.

    Keep every started run in the denominator. If your goal is autonomous completion, a person quietly fixing the result before it reaches the dashboard is a failed autonomous run, even when the final output looks good.

    Separate the agent from the decision engines beneath it

    An exploded modular AI system shows an agent above separate reasoning, memory, control, data, and tool components as a hand replaces one module.

    An agent does not need a large generative model for every step. Planning, writing, summarizing, classifying, routing, policy checking, and executing an API call are different computational jobs. Treating them as one undifferentiated prompt raises latency and cost while making failures harder to diagnose.

    The term System One model is being used for a model that returns a typed, calibrated decision from a predefined answer set rather than free-form prose. It can choose a ticket category, route a request to a model, select a tool, or decide whether a proposed action meets a policy. It does not independently accept a goal and pursue it, so it belongs inside an agent architecture rather than in the agent column of a market-share table.

    This layer matters because structured decisions are numerous but relatively inexpensive. Across 3.1 billion production API calls observed in 1,400 applications beginning June 1, 2026, structured decision tasks represented 63.7% of calls but only 15.5% of token spend. Long-form generation showed the opposite pattern: 9.1% of calls consumed 38.4% of token spend. A specialized decision model can therefore remove a large amount of traffic from a general-purpose model without displacing a comparable share of model spending.

    The best candidates have an answer space you can enumerate before the call. Binary classification led a September 2026 survey of 421 AI engineering teams, with 60.5% already piloting or planning adoption within six months. Schema extraction ranked last at 28.7% because field values are often open-ended. That gap gives you a practical rule: use a decision model when you can list all legitimate outcomes; retain a generative model when the output itself must be created.

    Type safety is necessary, but it is not factual accuracy

    A model can return a perfectly valid category and still choose the wrong category. Constrained decoding on a small language model achieved a 0.0% type error rate in the same benchmark as Jev, so valid output syntax is not, by itself, a differentiator. You still need labeled evaluation cases that test whether the decision is correct.

    The alternatives also remain competitive. A fine-tuned encoder classifier recorded 0.09-second median latency and a $0.018 cost per million input tokens, compared with Jev at 0.14 seconds and $0.042. The tradeoff is breadth: a new classification question can require another encoder to be trained, while a broader decision endpoint can answer different predefined questions. A small language model using constrained decoding was slower at 2.1 seconds, with input priced at $0.35 per million tokens and output at $1.40.

    Early demand does not prove steady-state adoption. Jev was only seven days old when launch-week estimates put it at 31,416 developers making at least one API call, while 6.2% of new accounts reached production. Treat that as evidence of interest and low integration friction, not as evidence that the architecture has already become standard.

    A clean production design assigns each layer a narrow responsibility:

    • The agent owns the goal, task state, planning, and recovery path.
    • Decision models handle enumerable classifications, routing, ranking, policy checks, and tool selection.
    • Generative models create prose, summaries, code, and other open-ended outputs.
    • Deterministic tools read or change external systems under explicit permissions.
    • Human approval remains in front of irreversible, externally visible, or high-consequence actions.

    Log the input, output, confidence or score, selected route, tool result, and final task outcome at the relevant layer. Otherwise, a failed workflow leaves you guessing whether the planner, classifier, generator, integration, or external system caused the problem.

    Build an adoption plan that survives vendor churn

    A durable rollout does not depend on predicting which logo will lead the next market table. It depends on preserving your workflow knowledge and measuring interchangeable components against the same definition of success.

    1. Select one bounded workflow. Favor a repeatable job with an observable end state and enough current friction to justify integration work.
    2. Map the action boundary. Separate read-only work, reversible internal changes, external communications, financial actions, deployments, and destructive operations. Require human approval where an error would be difficult to reverse.
    3. Shortlist by category fit. Compare agents designed for the systems and work involved instead of beginning with overall reach.
    4. Run identical evaluation cases. Include normal requests, missing information, ambiguous instructions, permission failures, tool errors, and requests that should trigger a refusal or escalation.
    5. Score completed outcomes. Track unassisted completion, interventions, time, cost, policy adherence, and recovery behavior using the same denominator for every candidate.
    6. Decompose expensive runs. Identify classification, routing, ranking, safety, and tool-selection calls that can move to a specialized decision model or deterministic rule.
    7. Retain a migration path. Keep prompts, outcome briefs, schemas, evaluation cases, logs, and business rules outside proprietary interfaces when the platform permits it.

    If customers encounter your business through agents

    Agent adoption changes acquisition as well as operations. ChatGPT Agent is used for multi-step research and booking; Gemini Agent Mode handles browser automation and forms; OpenAI Atlas performs site navigation and transactions; Perplexity Comet supports comparison and checkout. If any of those journeys matter to your business, visibility alone is an incomplete success metric. The agent must be able to identify the right page, understand the offer, verify important facts, and complete or correctly hand off the next step.

    Apply the same outcome-based discipline to AI SEO, AEO, and GEO work:

    • Put essential product, service, eligibility, policy, and contact information in visible page text rather than only in images or interactive widgets.
    • Give each important entity, offer, and resource a stable canonical URL with a clear page purpose.
    • Keep structured data consistent with the claims a visitor can see. Schema is a machine-readable consistency layer, not permission to publish contradictory or unsupported markup.
    • Use specific labels for links, buttons, form fields, and required inputs so an agent does not have to infer what an interface element does.
    • Publish dates, units, methodology, limitations, and originating evidence beside factual claims that an agent may need to evaluate or cite.
    • Test complete journeys from discovery to the required outcome. Record where the agent selects the wrong page, loses context, cannot operate a control, encounters conflicting facts, or reaches an unexpected approval step.

    This is where agent analytics should meet search analytics. A mention in an AI answer, an agent visit, a successful product comparison, and a completed transaction are separate events. Tracking only referral traffic hides the failures between discovery and completion.

    Key takeaways

    • AI agent usage is expanding rapidly, but market share is fragmenting rather than settling around one permanent winner.
    • Choose an agent for a defined workflow category and observable end state, not for overall popularity.
    • Use unassisted completion, intervention, recovery, time, and cost per successful outcome as the core buying metrics.
    • Keep goal pursuit in the agent layer while routing enumerable decisions to specialized models or deterministic rules where appropriate.
    • Make customer journeys explicit, structured, and testable if browser and general-purpose agents are part of your discovery or conversion path.

    Your next move is deliberately small: choose one workflow whose finish you can describe in a sentence, preserve a human gate before consequential actions, and run the same cases through category-appropriate candidates. The market will keep changing. A clear outcome definition and a portable evaluation set let you benefit from that competition instead of being trapped by it.

    References


  • Agentic Ecommerce: A Playbook for Discovery and Advertising

    Agentic Ecommerce: A Playbook for Discovery and Advertising

    If your product pages rank and your ads are live, but your products still disappear from AI-guided shopping conversations, the missing layer is usually not more promotional copy. It is decision-ready product data: facts an agent can retrieve, compare, explain, and carry into checkout.

    Your goal is no longer just to win a click. You need to help an AI determine whether a specific product fits a specific buyer’s constraints, answer the next question accurately, and make the handoff to your store without changing the facts along the way.

    The shopping funnel now contains a conversation

    A conventional product ad asks the shopper to click before learning much. A conversational ad can answer questions about fit, compatibility, features, availability, or policies inside the discovery surface. ChatGPT is testing clearly labeled Sponsored Agents that open a separate brand conversation, while Google’s Business Agent is being tested inside YouTube ads for eligible U.S. retailers.

    That changes the intermediate step, not the buyer’s underlying job. People still need to eliminate unsuitable choices, understand tradeoffs, and trust the terms of the purchase. The difference is that an agent may now perform part of that evaluation before the shopper reaches your product page.

    Do not collapse every appearance in AI into one visibility metric. There are three distinct outcomes:

    • Citation: your content supplies an explanation or fact used in an answer.
    • Recommendation: your brand enters the suggested set for a category or use case.
    • Selection: a particular product is matched to the shopper’s stated requirements and advanced toward purchase.

    Each outcome requires different work. Clear, retrievable content helps with citation. Consistent brand context supports recommendation. Complete product attributes, current commercial data, and a usable transaction path support selection. This is why LLM readability, brand context, and agentic commerce are separate optimization disciplines, even when one team owns all three.

    Do not fund this shift by abandoning traditional search. An Ahrefs-based measurement found AI Overviews on 24% of shopping queries on Sept. 3, 2026, but a Datos panel of more than 10 million desktop users measured dedicated AI Mode at only about 0.13% of web traffic. A separate panel of 75 ecommerce stores, mostly producing $1 million to $20 million in annual revenue, still placed non-branded organic search second only to paid search for revenue. The practical response is a parallel search and AI strategy, not a wholesale channel migration.

    Build a product record an agent can safely choose

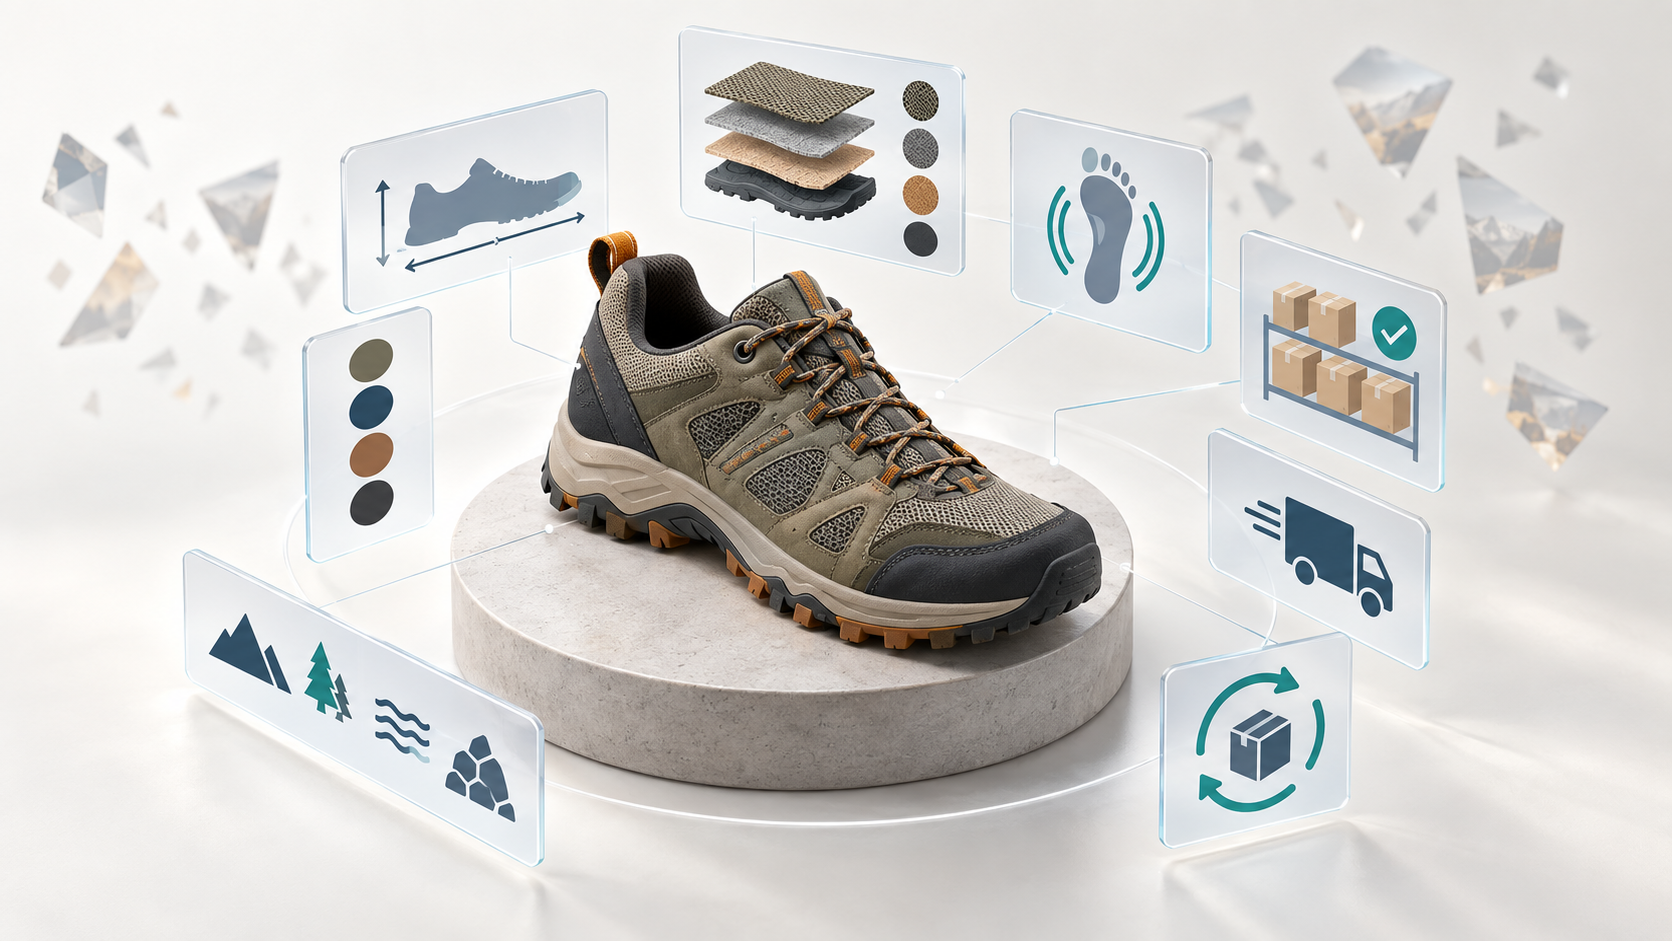
    An unbranded hiking shoe is surrounded by organized visual layers representing its materials, size, fit, availability, shipping, and return details.

    An agent cannot reliably recommend what it cannot distinguish. A polished category description will not compensate for missing variant measurements, ambiguous compatibility, stale availability, or different prices in the feed and on the page.

    For every product and variant you want an agent to select, create one canonical record with five layers:

    • Identity: product name, brand, category, model, SKU or other applicable identifiers, plus the exact relationship between parent products and variants.
    • Transaction truth: price, currency, condition, availability, fulfillment choices, shipping terms, returns, warranty, and any eligibility rules for discounts or member pricing.
    • Decision attributes: dimensions, materials, fit, capacity, supported devices or systems, care requirements, included components, and other facts buyers use to rule products in or out.
    • Evidence and instructions: manuals, size charts, compatibility tables, policy pages, certifications when applicable, and factual answers to recurring pre-purchase questions.
    • Destinations: the correct product page, variant URL, cart action, policy page, or support handoff for each answer.

    Publish the same facts through the channels machines use: visible page content, merchant feeds, platform catalog integrations, and Product and Offer structured data where applicable. JSON-LD should be generated from the same commerce data as the page and feed. Treating schema as a separate copywriting exercise creates exactly the contradictions an agent should not have to resolve.

    Run a variant-level consistency check before activating an agent or campaign. Compare title, identifier, price, currency, availability, shipping, return terms, and the primary decision attributes across the page, feed, structured data, and commerce API. If a field is genuinely unknown, leave it unknown and define a safe fallback. Do not let the agent infer compatibility, delivery, or warranty coverage from adjacent products.

    Product copy still matters, but it should answer rather than decorate. Put the direct answer first, then the explanation, supporting evidence, and relevant conditions. Keep each FAQ block focused on one buyer question so it can be retrieved without unrelated text changing its meaning.

    The commercial case for this cleanup is promising but should not be overstated. Google reports that merchants following its core Merchant Center feed practices see an average 5% conversion increase in the following month. In a Lululemon test, retailer-supplied conversational attributes were incorporated in 50% of relevant AI Mode product recommendations. These are platform-reported results, not guaranteed lifts. Their useful lesson is narrower: attributes that exist as maintained data can participate in recommendations; facts trapped in campaign copy cannot be depended on in the same way.

    Design conversational ads around the next unanswered question

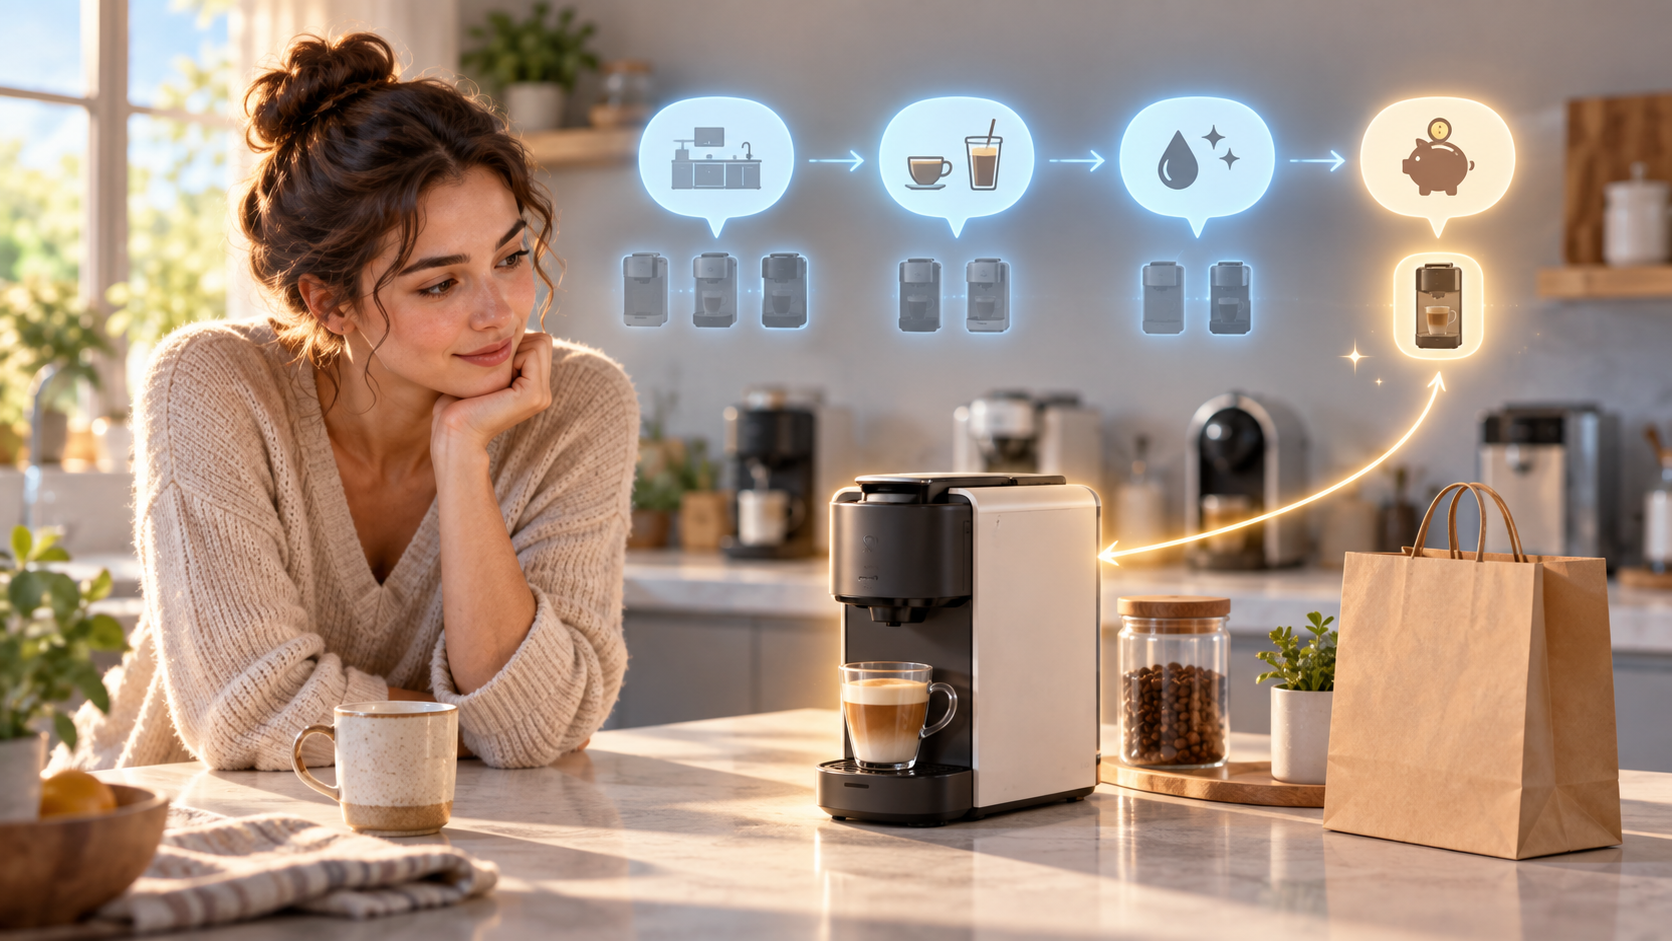
    A shopper and an abstract AI guide exchange symbol-filled bubbles while narrowing several coffee machines to one suitable choice.

    A conversational ad should not be a chat-shaped version of a display ad. Its job is to resolve the next material uncertainty and route the shopper to the correct action. Build an answer map before you generate creative.

    Buyer questionRequired dataSafe handoff
    Will this fit?Variant measurements, sizing method, and size-chart rulesThe selected variant and relevant size guide
    Will it work with what I own?Supported models, exclusions, required accessories, and version limitsThe compatible variant or compatibility table
    What will I actually pay?Current price, currency, shipping terms, and applicable member benefitsA cart with the same disclosed terms
    Can I get it when and where I need it?Live inventory and available fulfillment methodsThe available purchase or pickup path
    What if it is unsuitable?Return window, condition requirements, exclusions, and warranty termsThe relevant policy section or support route

    For each row, define an answer contract: the approved system of record, the claims the agent may make, the data that must be checked live, the fallback when data is unavailable, and the destination that preserves context. A useful fallback is specific: state which fact cannot be confirmed and direct the shopper to the place or person that can confirm it. A confident guess is not customer service.

    AI can also compress campaign production. ChatGPT Work’s Ads Manager plugin can create, update, and analyze campaigns from natural-language instructions; its assistance can propose copy and imagery from a landing page and campaign objective. Optional text customization can adapt headlines and descriptions to the conversation or translate them into the user’s preferred language. U.S. Shopify merchants can also use a ChatGPT Ads app to manage campaigns, while Shopify Catalog data supports more accurate product appearances in shopping conversations. These workflow and catalog integrations reduce interface work, but they do not remove the need for review.

    • Review generated copy against the canonical product record, not just the landing page’s marketing language.
    • Validate translated claims, units, policies, and variant names before enabling localized customization.
    • Require a live lookup for price, stock, delivery, and personalized benefits when those values can change.
    • Send every answer to a landing state that preserves the chosen product or variant. Do not make the shopper repeat the conversation.
    • Log unsupported questions and corrected answers as product-data defects, then fix the underlying record.

    Keep paid and independent answers conceptually separate. OpenAI says Sponsored Agent conversations are labeled and separated from the original ChatGPT conversation, advertising does not influence ChatGPT’s independent answers, and advertisers do not receive users’ private conversations. Plan your measurement around the signals the platform legitimately exposes; do not design a campaign that assumes access to private prompt history.

    Measure the path from question to profitable order

    Click-through rate cannot describe the whole experience when a conversation performs part of the product-page job. It may produce fewer but better-qualified visits, expose missing information, or assist a purchase completed through another surface. Build a measurement chain that distinguishes those outcomes.

    • Visibility: eligible ad exposure, AI share of voice, recommendation coverage across a fixed set of target shopping prompts, and the products most often surfaced.
    • Conversation: conversation starts, qualified question rate, common question categories, answer failure rate, and the share of conversations that reach a site handoff.
    • Selection: variant views, product comparisons, cart additions, and checkout starts originating from the agent experience.
    • Transaction: completed orders, revenue, margin where available, assisted conversions, and member-benefit usage.
    • Outcome quality: cancellations, returns, exchanges, and support contacts attached to agent-assisted orders.

    Define the denominators before launch. Conversation start rate is starts divided by eligible ad exposures when the platform supplies both values. Qualified question rate is conversations containing a decision question divided by starts. Answer failure rate is unsupported, corrected, or escalated answers divided by starts. If a platform withholds a denominator, mark the rate unavailable instead of combining unrelated proxies.

    Use distinct campaign identifiers and landing URLs for each agent surface, preserve product and variant context in the handoff, and record launch dates in your analytics annotations. Compare performance with a suitable unactivated product, market, or campaign group where possible. Keep budget, promotion, inventory, and seasonal differences visible so a lift is not automatically credited to the agent.

    Google’s AI performance insights in Merchant Center are generally available in Australia, Canada, India, New Zealand, and the U.S., including comparisons of brand share of voice across AI Mode and AI Overviews. Its Universal Commerce Protocol integration can also support cart transfers to merchant sites and expanded checkout testing. Loyalty data can surface member-specific pricing and benefits. These discovery, checkout, and personalization capabilities make segmentation essential: report new and returning customers, members and non-members, and agent-assisted and conventional journeys separately.

    Key takeaways: use this launch sequence

    • Choose one decision-heavy category. Start where buyers repeatedly ask about fit, compatibility, delivery, or policy terms, because those questions reveal whether the agent adds real value.
    • Separate your goals. Decide whether each activity is intended to earn a citation, a brand recommendation, a product selection, or a paid conversation.
    • Repair the product record first. Align variant identity, decision attributes, price, inventory, policies, page content, feed data, and JSON-LD before generating campaigns.
    • Create the answer map. Pair each common buyer question with an approved data field, a safe fallback, and a destination that preserves the selected product.
    • Apply campaign guardrails. Human-review generated claims and translations, require live checks for changing commercial facts, and prohibit unsupported inference.
    • Instrument the whole path. Track visibility, dialogue, selection, checkout, and post-purchase quality rather than using clicks as the sole success signal.
    • Feed failures back into operations. Repeated unanswered questions belong in the catalog backlog; frequent returns after an agent interaction may indicate that an answer or attribute is misleading.

    Start with the category where a wrong answer would most often block or spoil a purchase. Make that category reliably answerable across organic discovery, conversational ads, and checkout. Scale only after the same facts survive every handoff.

    References


  • Claude-Powered SEO Automation: A Safe, Scalable Playbook

    Claude-Powered SEO Automation: A Safe, Scalable Playbook

    You want Claude to remove repetitive SEO work, but you do not want an efficient mistake published across hundreds of pages. That tension is the right place to start. The question is not whether a task can be automated. It is whether you can define the task, constrain its permissions, and prove that its output is correct.

    The most useful Claude workflows combine machine-speed execution with explicit human gates. Let Claude gather, transform, compare, and prepare. Keep an SEO owner responsible for interpretation, publication, and any change that could affect traffic, regional accuracy, security, or production availability.

    Start with blast radius, not time saved

    Containment rings isolate a glowing test cluster from a much larger network of website-page tiles.

    Repetition alone does not make a task a good automation candidate. A daily news digest is repetitive and easy to discard. A plugin replacement is also repetitive, but one bad action could alter layouts or break a site. Those workflows require different permission levels even if Claude can perform both.

    Rank candidate tasks on three dimensions: how reversible the action is, how easily you can verify the result, and how widely an error would spread. Start with work that is read-only, produces a reviewable artifact, or runs entirely in staging.

    WorkflowWhat Claude receivesWhat it may produceRequired human gate
    Daily intelligence briefingNamed topics, competitors, markets, and relevance criteriaA prioritized briefing with links and follow-up questionsVerify material claims before using them in a decision
    Analytics investigationA defined property, date range, segments, and business questionTables, anomalies, and hypothesesConfirm numbers in the analytics platform and test the interpretation
    Hreflang sitemap creationCurrent sitemap URLs and regional mapping rulesDraft XML plus an exceptions reportValidate URL relationships and XML before publication
    Localization workflowApproved examples, service context, target regions, and templatesLocalized drafts and workflow tasksIn-country review and confirmation that every handoff completed
    WordPress plugin replacementA staging site, replacement requirements, and affected locationsStaging changes and an inventory of modified pagesFunctional and visual review before an approved deployment

    This ordering creates a sensible automation ladder. You first trust Claude to collect information, then to analyze controlled data, then to create artifacts, and only later to change a staging environment. Production access should never be the price of discovering whether your instructions are precise enough.

    Give Claude an operating contract, not a loose prompt

    A request such as “monitor our competitors” or “fix our hreflang” leaves too many decisions unstated. Claude has to infer what matters, which systems are authoritative, what it may change, and when it should stop. The resulting output can look polished while solving the wrong problem.

    Use the same seven-part task contract for every SEO automation:

    1. Objective: State the decision or deliverable, not just the activity. For example, produce a reviewable hreflang XML file for the specified regional sites.
    2. Inputs: Name the exact sitemap URLs, analytics property, approved content, template, site, or tracker that Claude may use.
    3. Source of truth: Identify which input wins when URLs, service names, translations, or metrics disagree.
    4. Rules: Define inclusion criteria, regional constraints, naming conventions, output format, and any fields that must never be inferred.
    5. Deliverables: Request both the main output and an exceptions report. Unmatched URLs and missing regional services should be visible, not silently omitted.
    6. Acceptance checks: Describe what must be true before the work counts as complete. Make these checks observable in the destination system.
    7. Permission boundary: Specify whether Claude may read, draft, create tasks, modify staging, or publish. Include a stop condition for missing data, failed connections, and ambiguous mappings.

    Specificity improves more than the first answer. It creates a basis for iteration. A useful intelligence briefing, for example, came from a detailed outline covering industry developments, competitor activity, and mergers and acquisitions, followed by adjustments that removed irrelevant material. The practical lesson is to treat the first output as a calibration run, not as proof that the workflow is ready.

    Store the accepted task contract alongside the workflow. When the result deteriorates, compare the failed run with that contract before adding more prose to the prompt. Most corrections belong in one of four places: the input set, the decision rules, the output structure, or the acceptance test.

    Build automation around complete SEO handoffs

    The strongest workflows do not automate an isolated sentence-generation step. They carry a defined unit of work from intake to a reviewable result. That means including the awkward handoffs where files, tasks, regional checks, or approvals usually get lost.

    1. Turn the daily briefing into a decision queue

    A generic news summary becomes another inbox. Give the briefing a fixed scope and make every item answer an operational question: What changed? Why could it matter to this business? Which site, market, competitor, or active initiative does it affect? What should a person verify next?

    Require a primary link for every item and separate confirmed developments from possible implications. Claude can prioritize the queue, but it should not turn an unverified mention into a strategy recommendation. Delete consistently irrelevant categories from the instructions and add examples of items that were genuinely useful. That feedback is how a broad digest becomes a working intelligence filter.

    2. Keep analytics access read-only and question-led

    A direct connection to Google Analytics can shorten the path from a business question to an initial analysis. Instead of manually assembling every view, you can ask Claude to examine the connected data and return a focused answer. This approach has reduced analysis time in an operational SEO workflow, but faster retrieval does not make every interpretation correct.

    Frame each request with the property, period, comparison period, segment, metric, and desired decision. Ask Claude to show the rows behind its conclusion and to label assumptions separately. Useful investigations include finding landing pages where organic traffic and conversions moved in different directions, determining whether a decline is concentrated in one country or template, and separating a sitewide change from a small set of URLs.

    Do not give an analysis workflow permission to alter campaigns, dashboards, tracking configuration, or site content. Its output is a hypothesis queue. An analyst should confirm the reported values in Google Analytics, check that the comparison is like-for-like, and decide what deserves investigation.

    3. Generate hreflang XML from controlled URL inventories

    Hreflang automation is a matching problem before it is an XML problem. Claude needs to know which pages are genuine alternates, which regions offer the same service, and which URLs do not have a valid counterpart. If those relationships are unclear, clean XML will still encode a bad international structure.

    Provide links to the current XML sitemaps, define the language and regional mapping rules, and forbid the invention of missing URLs. Ask for two outputs: the proposed XML and an exception list containing unmatched, duplicate, redirected, or ambiguous pages. In one implementation, Claude collected pages from the supplied sitemap links and built the hreflang sitemap without further input; a manual check found the first result usable. That is a promising workflow outcome, not a reason to remove validation.

    Before publication, check that every submitted URL belongs in the intended regional cluster, that alternate relationships are reciprocal, that canonical choices do not contradict those relationships, and that the XML is structurally valid. Review the exception list before the main file. It often reveals the content or information-architecture gaps that automated matching cannot responsibly resolve.

    4. Separate localization into availability, adaptation, and delivery

    Translation should not begin until you know the underlying service exists in the target region. Otherwise, automation can efficiently create a locally fluent page for an offer the regional business does not provide.

    Use three explicit stages. First, locate the authoritative page on the main site and establish the service context. Second, inspect each regional site and record whether the same service is available. Third, create a localized draft only for eligible regions, using an approved template and previous expert-vetted examples.

    The delivery stage deserves its own acceptance test. A multi-region workflow has successfully created localized drafts, opened Asana tasks, and assigned due dates from a standard formula. In that same run, the requested document was not uploaded to the task. That partial result exposes an important rule: verify every connector action independently. A task existing in Asana does not prove that its attachment, owner, date, and content all arrived.

    In-country experts found the generated translations comparable to the Google Translate output they had been receiving in that particular workflow. Do not generalize that result into unattended publishing. Product terminology, legal meaning, market eligibility, and local search language still need qualified review. Claude can prepare and route the draft; the regional owner decides whether it is accurate enough to publish.

    5. Treat WordPress changes as a staged migration

    Browser-controlled automation can remove a large amount of repetitive WordPress administration, but it also has the highest blast radius in this group. Use a current staging copy, a known replacement, a recoverable backup, and a page inventory before Claude changes anything.

    Have Claude find every place the old plugin is used, apply the replacement in staging, and return the URLs and templates it changed. Review representative pages at relevant layouts and test the function the plugin provides. If a plugin appears unused or unsupported, deactivate it first and verify that nothing depends on it before deletion. A backup and an approved rollback path are safer than assuming “unused” means consequence-free.

    One rollout across more than 20 websites reduced the operator’s hands-on requirement from an estimated hour per site to about five minutes per site. Claude found the affected locations, swapped the plugin, and performed a quick visual check, but the first attempt still contained a small visual discrepancy that required correction. Use that outcome as evidence that substantial leverage is possible, not as a universal time benchmark or proof that visual review can disappear.

    Put human approval where errors become expensive

    A human reviewer inspects a paused website update at an approval gate before it can reach a large page network.

    Human review should not be sprinkled across a workflow at random. Place it immediately before an output changes a source of truth, reaches a customer, or becomes difficult to reverse.

    • Read-only work: Claude may collect news or query analytics, but a person verifies claims and decides what deserves action.
    • Draft creation: Claude may generate XML, localized copy, reports, and task descriptions, but the artifacts remain unpublished.
    • Workflow mutation: Claude may create tracker tasks and attach files within a defined project. The operator checks each required field and handoff in the destination system.
    • Staging mutation: Claude may alter a recoverable staging site after the target, replacement, backup, and stop conditions are known.
    • Production mutation: A named owner reviews the change set, confirms the acceptance tests, and controls deployment and rollback.

    Measure the workflow on more than speed. Track hands-on time, the percentage of runs that pass without correction, the number of exceptions routed for review, and any steps that claim success without completing in the destination. A fast automation that regularly drops an attachment or misclassifies a regional service is not mature; it has merely moved the bottleneck.

    Keep a small audit record for every run: the task contract, input versions, output files, actions taken, exceptions, reviewer, and approval result. This makes failures diagnosable and prevents a corrected prompt from drifting back toward an earlier mistake.

    Key takeaways

    • Begin with reversible, read-only work and move toward staging changes only after the workflow passes defined acceptance tests.
    • Specify the objective, exact inputs, source of truth, decision rules, deliverables, checks, permissions, and stop conditions.
    • Request an exceptions report alongside every main output. Ambiguity should be surfaced for review, not hidden by a plausible answer.
    • Keep analytics interpretation, regional approval, XML publication, and production deployment under accountable human control.
    • Test every multi-system handoff in its destination. Creating a task does not prove that its attachment, owner, due date, and content arrived.
    • Evaluate automation by correction rate and verified completion as well as time saved.

    Choose one recurring SEO task and write its acceptance test before connecting Claude to anything. Run it with read-only access or in staging, record every correction, and tighten the operating contract until the result is repeatable. If you cannot describe exactly what a passing run looks like, the workflow is not ready for broader permissions.

    References


  • How to Audit AI Marketing Recommendations Across Audiences

    How to Audit AI Marketing Recommendations Across Audiences

    You give an AI marketing tool a clear goal, and it returns a confident audience, channel, or brand recommendation. The answer looks ready to use. But before you build a campaign around it, you need to know two things: what evidence produced the recommendation, and whether the recommendation changes when the audience changes.

    If neither is visible, you do not have decision support yet. You have a plausible output whose scope, assumptions, and failure modes are hidden. The practical fix is to audit recommendation evidence and audience variation as one workflow, then require human approval wherever a change could affect reach, spend, eligibility, or brand strategy.

    One AI answer is not a complete market view

    A single answer-engine response can be useful without being representative. The engine may interpret the question through details about the user, the wording of the prompt, prior conversational context, or other signals available to the system. Change that context and the shortlist, ranking, citations, or explanation may also change.

    A vendor analysis of 71,147 answer-engine responses found differences in brand mentions, citations, and search behavior associated with income, age, gender, and occupation. That finding does not establish that every answer engine personalizes every request, nor does it explain the cause of every observed difference. It does show why a persona-neutral prompt should not be treated as a universal picture of AI visibility.

    Some variation is appropriate. A buyer prioritizing affordability and a buyer prioritizing enterprise governance may reasonably receive different recommendations. The issue is not whether answers ever change. It is whether the change follows a relevant criterion, rests on supportable evidence, and remains consistent with the underlying facts.

    Separate the stable layer from the audience-sensitive layer:

    • Stable facts include product identity, documented capabilities, known requirements, and the meaning of cited evidence. A persona change should not silently reverse them.
    • Audience-sensitive judgments include which criterion receives more weight, which use case is emphasized, which options appear first, and which tradeoff is considered acceptable.
    • Presentation choices include tone, examples, terminology, and depth. These may change while the substantive recommendation remains the same.

    This distinction helps you spot three common measurement failures:

    • False universality: one prompt produces one answer, and the result is reported as what the platform recommends to everyone.
    • Hidden exclusion: a brand appears for one persona but disappears for another, with no visible criterion explaining the difference.
    • Averaged-away variation: a dashboard combines responses across audiences and makes unstable visibility look consistent.

    Treat an AI visibility observation as a combination of platform, prompt, audience context, and observation time. If any part changes, you may be measuring a different answer environment.

    A transparent recommendation shows decision evidence

    Hands inspect the visible source, assumption, recommendation, and approval components inside a transparent decision-making assembly.

    Transparency does not mean exposing every internal model operation or demanding a private reasoning transcript. Neither gives a marketer a reliable basis for approval. You need the evidence, uncertainty, and tradeoffs that could materially change the decision.

    This matters because marketing data is rarely as tidy as the campaign brief. A marketer searching for a completed-purchase signal may encounter several similarly named events, such as purchase, checkout success, and checkout completion. The labels alone do not reveal which event represents a confirmed order, which fires earlier in the funnel, or which remains reliable after implementation changes.

    Volume does not settle the question. A frequently firing purchase event could occur before payment confirmation, while a lower-volume checkout-success event could align more closely with the business definition of a completed order. Selecting the biggest signal without checking its meaning can create a large but conceptually wrong audience.

    Require each consequential recommendation to carry an evidence card. It can appear in a conversational response, side panel, review screen, or exported log, but it should answer the following questions:

    Evidence fieldWhat the system should exposeWhat you can decide
    Business objectiveThe outcome the recommendation is intended to support, in business languageWhether the proposed action answers the request you actually made
    Selected signal or criterionThe event, attribute, source, or decision criterion carrying the recommendationWhether the system used the right representation of the goal
    Meaning and funnel stageWhat the signal appears to represent and where it occurs in the customer journeyWhether purchase, checkout, intent, and engagement are being confused
    Provenance and observed behaviorWhere the signal comes from, how it behaves, how often it fires, and when it was last observedWhether the evidence is current and dependable enough for this decision
    Audience boundariesWho is included, who is excluded, and the resulting potential reachWhether the audience matches campaign eligibility and strategy
    Alternatives consideredThe plausible competing signals or approaches that could change the outcomeWhether an apparently obvious recommendation ignored a better-defined option
    TradeoffsHow changing a threshold or criterion affects reach, expected performance, precision, or riskWhich compromise fits the business rather than merely optimizing a model score
    Uncertainty and missing contextAmbiguous definitions, unavailable metadata, sparse observations, or assumptions supplied by the systemWhether to accept, refine, investigate, or reject the recommendation
    Decision stateWhether the output is exploratory, proposed, saved, connected, or activatedWhether any real-world action has occurred and what still requires approval

    Do not accept vague evidence labels such as recent, strong, or large when the interface can expose the underlying context. Recent relative to what observation? Strong against which alternative? Large compared with which eligible population? The system does not need to manufacture precision, but it should distinguish known values from inferred meanings and unavailable information.

    The approval flow matters as much as the evidence. For recommendations that can change spending or customer eligibility, keep proposal, saving, connection, and activation as distinct states. An exploratory conversation should not silently become an active audience. Explicit confirmation creates a point where a marketer can apply business judgment, document an override, or request better evidence.

    Conversation and direct controls also serve different jobs. A conversational agent is well suited to exploring unfamiliar data and explaining why signals differ. A visual interface is better for making precise threshold adjustments after the reach-versus-performance tradeoff is understood. A trustworthy workflow lets you move between them without losing the evidence or approval state.

    Run a controlled audience-variation audit

    Four controlled test lanes hold the same campaign brief while different audience groups lead to visibly varied recommendation objects.

    An audience audit should isolate whether persona context changes the recommendation, not merely collect a folder of unrelated prompts. Keep the decision question and test conditions stable, change one relevant audience dimension at a time, and record substantive differences separately from stylistic ones.

    Build the test grid

    1. Define the decision. Write the exact question the answer must resolve, such as which solution fits a use case or which audience should receive a campaign. State the criteria that should matter before looking at the output.
    2. Create a neutral baseline. Ask the decision question without demographic or occupational context that is not necessary to answer it. This becomes the comparison point, not the presumed correct answer.
    3. Select relevant audience dimensions. Test occupation, age, income, gender, or another persona attribute only where it could plausibly affect needs, constraints, terminology, access, or evaluation criteria.
    4. Change one dimension at a time. Keep the platform, wording, product category, requested format, and other context constant. Composite personas may reflect real buyers, but they make it harder to identify which attribute drove a change.
    5. Capture the complete response. Record the prompt, audience variation, platform and model label exposed by the interface, observation time, recommended brands or actions, ordering, rationale, citations, caveats, and omitted options.
    6. Compare decisions before wording. A different example or tone is less important than a changed shortlist, reversed ranking, new exclusion, altered factual claim, or different call to action.
    7. Inspect the support. Check whether each changed recommendation is tied to an explicit audience need and whether its cited material actually supports the criterion being applied.
    8. Assign a disposition. Mark the variation as presentation-only, relevant and supported, unexplained and substantive, or factually contradictory. Each label should lead to a different next action.

    Interpret changes by materiality

    Presentation-only variation changes the vocabulary, explanation depth, or examples without altering the decision. You may still care about tone and accessibility, but it is not evidence that brand visibility changed.

    Relevant, supported variation changes the recommendation because the persona introduces a genuine decision criterion. An occupational context may change workflow requirements. An affordability constraint may alter which options qualify. The output should make that connection visible rather than relying on an unexplained proxy.

    Unexplained substantive variation changes inclusion, exclusion, order, or recommended action without identifying a relevant criterion or supporting evidence. Do not immediately label it bias or personalization; the system may be responding to ordinary output variation, hidden context, or a retrieval difference. Rerun the unchanged baseline alongside the persona variant, preserve the outputs, and investigate before drawing a causal conclusion.

    Factual contradiction occurs when stable product facts or evidence claims change solely with the persona. That is a blocking issue. Do not use the output for activation or publish the claim until you can resolve which statement is supported.

    Pay special attention to citations. A persona may receive different cited pages even when the recommendation stays similar. Record whether a citation is present, whether it supports the nearby claim, and whether it represents the same kind of evidence across variants. Citation count alone cannot tell you whether the recommendation is sound.

    Age, gender, and income can be useful diagnostic variables because audience-linked variation has been observed, but they can also be sensitive attributes. Using them to determine real customer eligibility can create privacy, fairness, or legal exposure depending on the context and jurisdiction. Use them in testing only when necessary, minimize personal data, and route any activation rule based on sensitive traits through your legal and privacy review process.

    Turn the audit into content, measurement, and controls

    An audit is only valuable if it changes how you publish, measure, or approve marketing decisions. The goal is not to force every audience to receive identical recommendations. It is to make legitimate differences explainable and unsupported differences visible.

    Make audience criteria explicit in your content

    If an answer engine changes its recommendation because of a criterion your content barely addresses, close that evidence gap on the relevant page. Add clear passages that identify:

    • who the product, service, or method is designed for;
    • which use cases it supports and which it does not;
    • what prerequisites, limitations, or eligibility conditions apply;
    • which tradeoffs a buyer must make;
    • how important terms and outcomes are defined; and
    • which verifiable facts support each suitability claim.

    Write around decision contexts, not demographic labels. A page explaining the needs of a regulated procurement workflow is more useful than a thin page targeting an occupational persona by name. A clear affordability limitation is more informative than assuming what someone can spend from a demographic category.

    Structured data can reinforce supported facts about the page, organization, product, service, author, or other entities where the relevant schema applies. It cannot make an unsupported claim trustworthy, encode every possible persona preference, or guarantee that an answer engine will recommend a brand. Use schema to clarify machine-readable facts, then make the audience-specific reasoning legible in the visible content.

    Measure visibility at the audience level

    Do not reduce answer-engine performance to a platform-wide mention rate if your buyers approach the category with materially different contexts. Track AI visibility by audience as well as by platform, while retaining the neutral baseline so you can see where variation begins.

    For each monitored decision question, record:

    • the exact prompt and persona context;
    • the engine, interface, and model information exposed at the time;
    • whether your brand was mentioned;
    • where it appeared in an ordered recommendation, if the answer provided an order;
    • the use case or criterion attached to the mention;
    • the pages or sources cited;
    • the caveats attached to the recommendation; and
    • whether the result was stable, relevantly different, unexplained, or contradictory.

    Keep the prompt set and audience definitions fixed when comparing observations over time. If you rewrite the question, change the persona, and switch platforms at once, you cannot tell whether a visibility movement came from your content, the engine, or the test design.

    Define approval boundaries before activation

    Set review rules before an agent proposes an audience or campaign. Require human approval when:

    • the selected data signal has an ambiguous business meaning;
    • the origin, observed behavior, or recency of the evidence is unavailable;
    • a threshold creates a material reach-versus-performance tradeoff;
    • a sensitive audience attribute changes inclusion or exclusion;
    • persona variants produce contradictory facts or unexplained recommendations;
    • the action can change budget, customer eligibility, messaging, or external activation; or
    • the system cannot show which assumption would most affect the recommendation.

    Preserve the human decision in a log. Record the proposal, evidence shown, audience context, chosen action, override, approver, and activation state. This is not paperwork for its own sake. It lets you distinguish a model recommendation from the business decision that followed it and prevents later reporting from treating the two as interchangeable.

    Key takeaways

    • A single AI response represents one platform, prompt, audience context, and observation time. It is not a universal market answer.
    • Useful transparency exposes the selected signals, their meaning and recency, audience boundaries, alternatives, uncertainty, and tradeoffs. A private reasoning transcript is not required.
    • Test audience variation by holding the decision question constant and changing one relevant persona dimension at a time.
    • Separate presentation changes from substantive recommendation changes, and block activation when stable facts become contradictory.
    • Measure brand mentions, ordering, use cases, citations, and caveats by audience rather than averaging every response into one platform score.
    • Keep exploration, saving, connection, and activation distinct so a marketer can refine or override the recommendation before it affects customers or spend.

    Start with the next recommendation your team is already preparing to use. Attach an evidence card, run the neutral prompt beside one relevant audience variant, and classify every substantive difference. If the system cannot explain a changed recommendation with current evidence and a relevant criterion, do not report it as universal and do not activate it. Fix the evidence, the content, or the decision rule first.

    References


  • GPT-5.6 in Profound: Tiers and Workflow Implications

    GPT-5.6 in Profound: Tiers and Workflow Implications

    Profound has announced support for GPT-5.6, giving its users access to the model family through the platform’s existing AI workflows. The announcement emphasizes a choice among Sol, Terra, and Luna tiers rather than presenting GPT-5.6 as a single configuration for every task.

    The practical significance is workload matching: teams can consider different tiers for demanding reasoning and production-scale activity while evaluating whether the reported gains in capability, reliability, and efficiency hold for their own use cases.

    What GPT-5.6 support changes in Profound

    According to Profound’s announcement, GPT-5.6 is now available directly within the workflows supported by the platform. Profound characterizes it as OpenAI’s newest flagship model family and identifies advanced AI performance as the central reason for adding it.

    This is an integration announcement, not an independent benchmark. The source reports improvements in capability, reliability, and efficiency, but it does not provide test results, pricing, latency figures, context limits, or comparisons with earlier models. Those omissions matter when deciding whether the new option should replace an existing model or serve only selected workloads.

    Sol, Terra, and Luna introduce a tier-selection decision

    Profound says its GPT-5.6 support spans the Sol, Terra, and Luna tiers. It presents this range as a way to cover work extending from frontier reasoning to high-throughput production workloads, although the announcement does not assign detailed specifications or a fixed use case to each named tier.

    For teams, the important shift is therefore operational: model selection can be treated as a workload decision. A demanding research or reasoning task may call for a different balance than a repeatable, high-volume process. Without tier-level measurements in the source, however, buyers should avoid assuming which option will deliver the best quality, speed, or cost for a particular application.

    The workflows Profound expects to benefit

    Abstract task objects travel along branching illuminated paths through three differently scaled processing chambers before converging into organized outputs.

    The announcement highlights four areas: agentic workflows, coding, research, and enterprise knowledge work. These categories share a need for dependable handling of instructions and context, but they create different evaluation requirements.

    • Agentic workflows: Evaluate whether the selected tier follows multi-step instructions consistently and handles failure conditions appropriately.
    • Coding: Test against the languages, repositories, review practices, and validation tools used by the organization.
    • Research: Check source handling, factual accuracy, uncertainty, and the usefulness of generated synthesis.
    • Enterprise knowledge work: Examine performance with internal terminology, access controls, document retrieval, and required approval processes.

    These checks are general implementation practices rather than performance claims about GPT-5.6. Profound’s post identifies the target workflow categories but does not publish evidence for individual tasks within them.

    Key takeaways

    • Profound reports that GPT-5.6 is supported within its AI workflows.
    • The integration includes the Sol, Terra, and Luna tiers.
    • Profound positions the model family for uses ranging from advanced reasoning to high-throughput production.
    • Agentic systems, coding, research, and enterprise knowledge work are the principal use cases named in the announcement.
    • The post reports capability, reliability, and efficiency improvements but supplies no benchmarks or tier-level specifications.

    How teams can evaluate the integration responsibly

    A sensible evaluation begins with representative tasks rather than a broad platform-wide switch. Teams can define the required output quality, acceptable error patterns, response-time needs, and operating constraints for each workflow, then compare the available tiers under the same conditions.

    1. Select a small set of real tasks from each intended workflow.
    2. Define pass criteria before comparing model outputs.
    3. Record quality, consistency, failure modes, and human-review effort.
    4. Compare tiers without presuming that the same option will suit every workload.
    5. Expand adoption only where the results support Profound’s reported benefits.

    GPT-5.6 support broadens the choices available inside Profound, but the integration’s value will ultimately depend on how clearly organizations match those choices to their own work. More detailed tier documentation and workload-specific evidence would make that decision easier.

    References

  • Grok 4.5 Support in Profound: What It Means for Teams

    Grok 4.5 Support in Profound: What It Means for Teams

    Profound has added support for Grok 4.5, according to an announcement published on its blog. The integration gives users another model option for workflows involving research, strategy, automation, and other forms of knowledge work.

    The practical value will depend on more than model availability. Teams still need to determine where Grok 4.5 improves their work, how reliably it handles representative tasks, and whether it fits their operational requirements.

    What Profound announced

    Profound’s post says Grok 4.5 support is now available and describes the model as a new flagship designed for agentic workflows and knowledge work. It positions the integration as a way to use the model within a broader AI workflow rather than solely through isolated prompts.

    The announcement names research, strategy, automation, and everyday knowledge work as areas to explore. These are proposed applications, however, rather than reported results from comparative testing. The source does not provide benchmarks, customer outcomes, configuration details, or comparisons with other models.

    Key takeaways

    • Profound says Grok 4.5 support is available within its broader AI workflow environment.
    • The stated positioning emphasizes agentic workflows and knowledge-intensive tasks.
    • Research, strategy, automation, and routine knowledge work are the principal use cases identified in the announcement.
    • The announcement establishes integration availability, but it does not independently demonstrate performance, reliability, or superiority over alternative models.

    Where the integration could matter

    In general, an agentic workflow asks a model to help move a multi-step task toward completion. That can involve interpreting a goal, working through intermediate decisions, producing outputs, and responding to new context. Model support inside a workflow platform can therefore be more consequential than access to a standalone chat interface, provided the surrounding system can supply the context and controls the task requires.

    For research work, the relevant question is whether Grok 4.5 can consistently organize evidence, expose uncertainty, and produce outputs that remain easy to verify. For strategy work, teams should examine whether its reasoning stays connected to the supplied constraints rather than merely producing polished recommendations. Automation use cases add another requirement: predictable behavior when a task is repeated, interrupted, or handed between people and systems.

    These criteria are evaluation targets, not capabilities established by Profound’s announcement. The integration creates an opportunity to test them in context; it does not remove the need for that testing.

    How teams can evaluate Grok 4.5 in Profound

    A team evaluates an artificial intelligence system at parallel workstations using abstract result panels in a modern testing studio.
    1. Select representative tasks. Use real examples from research, planning, analysis, or automation rather than a small collection of showcase prompts.
    2. Define a baseline. Compare Grok 4.5 with the model or process already used for the same work, keeping instructions and source material as consistent as possible.
    3. Score the outputs. Assess factual accuracy, reasoning quality, adherence to constraints, completeness, and the amount of human correction required.
    4. Test repeatability. Run comparable tasks more than once and examine whether the workflow produces dependable results when inputs become ambiguous or incomplete.
    5. Review operational fit. Consider oversight, traceability, data-handling requirements, latency, and cost using the terms and controls actually available to the organization.

    A useful evaluation should separate model quality from workflow quality. A weak result may come from the model, the instructions, missing context, or the way the integration passes information between steps. Recording those failure modes makes comparisons more informative than selecting a model from a few preferred answers.

    What remains unconfirmed

    The supplied announcement does not specify access requirements, pricing, context limits, supported tools, routing behavior, governance controls, or technical implementation. It also does not report independent tests showing how Grok 4.5 performs inside Profound against other available approaches.

    Profound’s support is therefore best understood as expanded model choice and an invitation to evaluate new workflows. Documentation and task-level testing will determine whether that choice produces measurable gains for a particular team.

    References

  • Enterprise AI Automation: A Practical Path to Production

    Enterprise AI Automation: A Practical Path to Production

    Your AI pilot probably does not need a smarter demo. It needs an accountable owner, a credible baseline, reliable data, permission boundaries, an escalation path, and a clear reason to exist after the demonstration ends.

    That is where many enterprise programs stall. In adoption data compiled through May 14, 2026, enterprises led at 25% adoption, but adoption covered everything from an initial trial to full-scale implementation. Among enterprise adopters, 62% remained in experimentation and only 13% had reached full deployment. If you are responsible for moving AI automation into production, the job is not to collect more use cases. It is to turn a carefully chosen workflow into a controlled, measurable operating process.

    Key takeaways

    • Fund a defined workflow with a business owner, not a broad AI capability looking for a problem.
    • Record the current cost, delay, error rate, conversion rate, or customer outcome before changing the process.
    • Favor workflows with stable triggers, accessible data, verifiable completion, bounded exceptions, and reversible actions.
    • Treat the model as one component. Production also requires permissions, deterministic rules, evaluations, monitoring, audit logs, human escalation, and rollback.
    • Set stage-gate criteria and stop conditions before the pilot begins. A project that cannot prove value should end without becoming permanent experimental infrastructure.

    Choose the first workflow by value and controllability

    Two operations leaders examine one illuminated, guardrailed process lane within a larger floor of branching workflows.

    Start below the level of a department. Customer service transformation is too broad. Qualifying an after-hours inquiry, answering approved questions, and offering an available appointment is a workflow. Supply chain optimization is too broad. Detecting a delayed shipment, checking an approved set of alternatives, and preparing a resolution for review is a workflow.

    This distinction matters because ordinary automation and agentic AI solve different parts of the process. A conventional automation follows predefined rules. Generative AI produces an output such as a summary or draft. An agentic system can plan, decide, and execute a multi-step task from beginning to end. More autonomy creates more ways to complete useful work, but it also expands the number of decisions, integrations, and failure modes you must control.

    A strong initial candidate has the following properties:

    • A visible operational leak: Work is being delayed, repeated, missed, or handled at an unnecessarily high cost.
    • A stable trigger: The workflow starts from a recognizable event such as an inbound request, completed meeting, status change, or new record.
    • Accessible inputs: The required data can be retrieved with appropriate permissions and has meanings the operating team agrees on.
    • A verifiable finish: You can tell whether the appointment was booked, case was resolved, package was sent, record was updated, or decision reached the right person.
    • Bounded exceptions: Unusual cases can be recognized and routed to a person instead of forcing the system to improvise.
    • Manageable consequences: A wrong draft can be reviewed or discarded. An unauthorized payment, deletion, price change, or legal commitment is much harder to reverse.
    • Enough recurring demand: The workflow occurs often enough for reduced handling time, faster response, or higher completion to matter.

    Score candidate workflows as high, medium, or low on each property. Do not average away a fatal weakness. Low data access, an undefined finish, or an unbounded consequence should block the candidate until the underlying process is redesigned.

    Structured processes tend to move first. Customer service and supply chain coordination show stronger agentic AI adoption, while finance faces more regulatory scrutiny. The practical lesson is not that every enterprise should begin in customer service. It is that repeatable inputs, explicit policies, and observable outcomes make automation easier to validate.

    A useful workflow can also be unglamorous. One documented PR automation locates a completed Zoom recording, creates a transcript, and prepares an email containing both for the journalist. It saves about 30 minutes per interview while shortening the handoff. The value comes from removing a specific delay, not from inventing a new communications platform.

    Apply the same discipline to the build-versus-buy decision. Existing software should handle commodity functions such as scheduling, transcription, telephony, CRM records, and routine orchestration when it meets your requirements. Custom development is easier to justify when the workflow depends on a proprietary process, distinctive formula, or exclusive data that is central to the business. Otherwise, concentrate engineering effort on integration, policy, evaluation, and observability rather than recreating a mature product category.

    Make the pilot prove a business case it cannot game

    Before selecting a model or vendor, write a testable operating hypothesis:

    By automating these defined steps for these eligible cases, we expect this business metric to move from its recorded baseline to an approved target, without worsening these guardrails, as measured in this system over this evaluation window.

    If the team cannot fill in each part, it is not ready to approve the pilot. A goal such as improve productivity leaves too much room to declare success after the fact. Reduce median handling time for eligible requests while maintaining resolution quality and escalation compliance can be measured.

    The measurement plan should separate five kinds of evidence:

    • Business outcome: Completed bookings, qualified opportunities, resolved cases, accepted deliverables, cycle time, recovered demand, or another result the operating owner already values.
    • Guardrail: Error severity, complaint rate, rework, policy violations, inappropriate messages, missed escalations, or another consequence that must not deteriorate.
    • Coverage: The share of incoming work that is actually eligible and processed. A system can perform well on a narrow subset without materially changing the operation.
    • Technical diagnostic: Extraction quality, classification quality, tool-call success, retrieval failures, latency, retries, and exception frequency. These explain performance but do not replace a business result.
    • Economics: Software, model usage, integration, monitoring, review labor, incident handling, and ongoing process ownership.

    Measure the baseline before the team sees pilot results. Otherwise, definitions tend to drift toward whatever the system can demonstrate. Specify which cases qualify, which are excluded, where each metric comes from, and who resolves disputed labels. When feasible, compare pilot cases with equivalent manually handled cases rather than assuming every change came from the automation.

    Do not count outputs as outcomes. Drafts generated, conversations handled, or tasks attempted are activity measures. They matter only when the workflow reaches a valid completion or produces verified capacity that the business can use. Time saved is not automatically a cash saving, either. State whether the capacity will absorb growth, reduce a queue, improve service, avoid new hiring, or be reassigned to higher-value work.

    Revenue automations need an additional capacity check. AI can help build targeted prospect lists, accelerate qualification, recover missed calls, and respond outside staffed hours, but increased demand can damage the customer experience when the business cannot fulfill it reliably. Map the next handoff before accelerating the top of the funnel. A faster response is not valuable if it creates an unstaffed queue downstream.

    Finally, define the stop rule while expectations are still neutral. Stop, narrow, or redesign the pilot if it cannot move the primary outcome, breaches an approved guardrail, depends on unsustainable review labor, or lacks a credible path to production economics. Unclear success criteria and weak data are recurring reasons AI projects fail to progress, while cost pressure is particularly important for smaller organizations. An enterprise budget may delay that reckoning, but it does not remove it.

    Build the operating system around the model

    A central AI computing unit is surrounded by data filters, permission gates, test chambers, monitoring equipment, audit storage, and human review stations.

    Separate deterministic rules from model judgment

    Map the workflow from trigger to completion before deciding what the model should do. For every step, record the input, rule or judgment, system of record, permitted action, expected output, exception path, and owner.

    Use ordinary code or workflow rules where the answer is deterministic. Required fields, account permissions, arithmetic, approved status transitions, duplicate checks, and routing tables should not become probabilistic merely because a language model is available. Use AI where interpretation is genuinely required, such as extracting intent from a message, summarizing an interaction, comparing unstructured evidence, or preparing a response under policy constraints.

    This separation makes failures easier to locate. It also reduces the chance that a persuasive output will bypass a rule the business intended to enforce.

    Increase authority only after the evidence supports it

    Autonomy should be an explicit permission level, not an accidental property of an integration. A practical authority ladder is:

    1. Read and recommend: The system analyzes data but cannot change a record or communicate externally.
    2. Prepare a draft: It creates a message, decision, or action package for a person to review.
    3. Execute after approval: A named reviewer authorizes the action with the relevant evidence visible.
    4. Execute within narrow limits: The system acts only for approved case types, values, destinations, and tools; exceptions are escalated.
    5. Execute the bounded workflow: The system completes eligible work autonomously while monitoring, audit, and shutdown controls remain active.

    Start at the lowest level that can test the business hypothesis. Advance only when the prior level meets predeclared quality and guardrail requirements. Full deployment does not require maximum autonomy. A stable draft-and-approval system can be the right production design when the action carries legal, financial, employment, security, reputational, or regulatory consequences.

    Use least-privilege credentials and separate test access from production access. Restrict the agent to the systems, records, fields, and actions required for the approved workflow. Payments, deletions, contractual commitments, price changes, sensitive employee decisions, and regulated communications should not become autonomous merely to remove a review step. If the business later approves that authority, it needs risk-specific testing, monitoring, and recovery controls.

    Make every handoff observable and recoverable

    A production trace should let an operator reconstruct what happened without relying on the model to explain itself. Capture the case identifier, input snapshot, relevant data version, workflow and prompt version, model and tool calls, retrieved evidence, proposed action, approval or override, external write, error, retry, elapsed time, unit cost, and final business outcome.

    Design retries so they do not duplicate a booking, order, message, refund, or record. Provide a clear shutdown control, queue failed work for recovery, and document how the operating team restores the last valid state. Alerts should identify an actionable condition and its owner; a dashboard that merely shows activity will not shorten an incident.

    Data readiness should be scoped to the workflow. You do not need to repair every enterprise dataset before beginning, but you do need a reliable contract for the fields this automation uses: canonical definitions, stable identifiers, permitted sources, freshness expectations, missing-value behavior, conflict resolution, and write-back ownership. Poor-quality and inconsistent data are common barriers to successful agent deployment. Giving an agent access to more systems does not solve disagreement between those systems.

    Build an evaluation set from representative normal cases, boundary cases, known exceptions, and costly failure modes. For each case, define an acceptable result, required escalation, and prohibited action. Run it before live access, compare the system with the existing process in shadow mode, and retain it as a regression suite whenever the prompt, model, tools, policy, or data mapping changes. Production monitoring then checks whether real traffic is drifting beyond what the evaluation set covered.

    Use stage gates to escape permanent pilot mode

    The large gap between experimentation and full deployment is a governance problem as much as a technical one. Teams can keep improving a demonstration indefinitely when nobody has defined the evidence required for the next decision. Gartner has projected that around 40% of agentic AI projects could be canceled by 2027. Cancellation is not necessarily the wrong outcome; discovering weak value or uncontrolled risk early is cheaper than scaling it.

    GateEvidence requiredDecision
    Workflow approvalNamed owner, process map, baseline, eligible cases, business hypothesis, risks, and stop ruleApprove a bounded test, redesign the workflow, or reject the use case
    Offline validationData contract, representative evaluation set, expected results, prohibited actions, permission design, and cost modelMove to shadow operation only if declared quality and safety requirements are met
    Shadow operationComparison with the existing process, exception analysis, reviewer feedback, diagnostic logs, and revised operating proceduresEnter limited production, narrow the scope, or return to offline work
    Limited productionVerified business outcome, guardrail performance, coverage, review burden, incident response, rollback, and actual unit costScale, maintain the bounded scope, redesign, or stop
    Operational scaleAccountable service owner, support model, change control, recurring evaluation, capacity plan, security review, and portfolio fundingExpand only while value and controls remain intact

    Set the thresholds for these gates according to the consequence of failure, and approve them before results arrive. A drafting assistant and a payment agent should not share the same tolerance. The important discipline is that the team cannot redefine success after seeing the output.

    At portfolio level, centralize the controls that should be consistent and decentralize ownership of the business outcome. A central AI function can provide identity, approved integrations, logging, evaluation tooling, security patterns, vendor review, and incident standards. The operating team should still own the process, metric, exceptions, staffing impact, and customer consequence. If ownership remains with an innovation lab after launch, the automation has not truly entered the business.

    Maintain a register of active automations showing the workflow owner, systems touched, data classification, permitted actions, risk level, deployment stage, model and vendor dependencies, current economics, and next gate. Use it to find duplicate experiments, unsupported integrations, and pilots that consume resources without approaching a decision.

    Before the next platform purchase, choose a specific queue or handoff that is already causing measurable loss. Name its owner, baseline, eligible cases, prohibited actions, escalation path, and stop rule. If those items cannot be written clearly, more AI will not make the process ready. If they can, you have the beginning of an automation that can earn its way into production.

    References

  • Google’s Agentic Search and Commerce Overhaul: An SEO Plan

    Google’s Agentic Search and Commerce Overhaul: An SEO Plan

    If your search strategy still ends with earning the click, the next version of Google Search creates a blind spot. A user can hand Google an open-ended task, let an agent monitor it, ask Search to assemble a purpose-built interface, and move from comparison to booking or purchase without restarting the journey on your site.

    Your site still matters, but its role expands. It has to be a reliable evidence layer, a clean record of changing commercial facts, and an unambiguous handoff to action. This guide shows you how to audit those layers before you chase speculative agentic SEO tactics or produce more content.

    Google is turning a result page into a task environment

    The familiar search journey has a simple rhythm: query, results, click, website. Agentic Search can stretch that journey across time, combine several kinds of input, construct a temporary tool, and complete parts of the task inside Google’s interface.

    The redesigned Intelligent Search Box supports longer prompts and input from text, images, files, videos, and Chrome tabs. Its suggestions go beyond conventional autocomplete, while the path from an AI Overview into AI Mode becomes easier. That encourages people to express a complete situation instead of compressing it into a short keyword phrase.

    AI Mode is also being shaped around continued work rather than one-off answers. Gemini 3.5 Flash was announced as its default model, with an emphasis on agentic, coding, and multimodal performance. The model name matters less to your strategy than the behaviors it enables: decomposition, synthesis, tool construction, and action.

    Those behaviors now appear in several distinct experiences. Information agents can keep monitoring the web for changes, then return a synthesized update that helps the user act. An apartment search can persist until a qualifying listing appears. A product-release watch can continue until a relevant launch is detected. Local agentic experiences can find services or activities using requirements such as time, availability, price, and specific amenities.

    Search can also generate the interface required by the question. The announced generative UI can assemble visual tools, tables, simulations, trackers, and ongoing dashboards. A page is therefore no longer competing only with another page. Its facts may become inputs to an interface created for one user’s exact task.

    Commerce completes the pattern. Google’s Universal Cart is designed to collect items from multiple retailers, surface in-stock options and deals, identify compatibility problems, account for eligible payment or loyalty benefits, and move the user toward checkout through Google Wallet. Search is moving closer to the decision and the transaction at the same time.

    Key takeaways

    • Optimize for the complete task, not only the opening query. The task may include monitoring, comparison, configuration, booking, or purchase.
    • Treat every important claim as reusable data. An agent needs to identify the subject, value, qualifier, current state, and next action without guessing.
    • Keep visible content, JSON-LD, commercial data, and the action endpoint aligned. A contradiction at any handoff makes the whole journey less dependable.
    • Compete for selection as well as visibility. Price, availability, compatibility, merchant identity, and verifiable benefits can affect which option fits the user’s criteria.
    • Measure accuracy and task completion alongside citations and clicks. A mention with the wrong variant, stale price, or broken booking path is not a useful win.

    The practical shift is from a document-query match to a task-state match. A query asks what is relevant now. A task also carries criteria, changing conditions, previous progress, choices, and a next action. This is not a claim about a newly disclosed ranking factor. It is a more useful model for deciding what your site must make clear.

    Map the journeys Google can now continue without a click

    A person follows one continuous digital path through research, product comparison, monitoring, scheduling, and booking stages.

    Start with the work your customer is trying to complete. Do not begin with a list of keywords or schema properties. Choose a high-value journey and write the user’s full request as it would appear in a conversational search box.

    Task shapeEvidence the task needsWhat to audit on your site
    Monitor for a changeExact criteria, current status, freshness, and a clearly defined change worth reportingPlace the current state and its relevant date together. Keep expired states out of active sections and remove conflicting copies.
    Explain or build a custom toolModular explanations, labeled inputs, relationships, constraints, and expected outputsReplace buried dependencies with explicit steps, definitions, inputs, and decision rules that can stand on their own.
    Compare or assemble optionsEquivalent attributes, compatibility rules, exclusions, and meaningful differencesUse consistent labels across comparable options. State when an option does not fit instead of describing every option as suitable.
    Book a service or experienceService definition, location, time requirements, current pricing and availability, special constraints, and an action pathShow eligibility and booking conditions before the call to action. Check that the destination preserves the service and location the user selected.
    Buy across merchantsProduct and variant identity, price, stock state, deal conditions, compatibility, merchant choice, and checkout pathReconcile changing commercial facts everywhere they appear. Make merchant and variant differences explicit before checkout.

    Use task prompts to find missing information

    A short head term hides the details an agent must resolve. A constrained prompt exposes them. Draft prompts in the same shape as these examples:

    • Monitoring: Track [category] and notify me when [qualifying change] occurs, but exclude [disqualifying condition].
    • Decision: Compare [options] for [use case], subject to [budget, compatibility, location, or timing constraints], and explain the tradeoff.
    • Booking: Find [service] in [area] for [time], confirm [requirement], show current pricing and availability, and provide the booking path.
    • Shopping: Assemble [set of products], verify that the parts work together, identify available merchants and benefits, and provide a purchase path.

    Underline every term that can change the outcome. Those terms become your required evidence fields. If compatibility determines the answer, compatibility cannot remain implicit. If a discount depends on a payment method or loyalty status, the condition has to travel with the discount. If availability differs by location or variant, an unqualified available label is not enough.

    Then trace each required fact through the journey. Where is it stated? Who maintains it? How does it reach the visible page and structured data? What happens when it changes? Does the booking or purchase destination preserve the user’s choice? A missing answer identifies an operational problem, not merely a content gap.

    Run the same five checks against each important page: Can a system identify the exact subject? Can it extract the decisive fact? Is the qualifier attached? Is the value current? Is the next action clear? A page that fails one of these checks may still read well to a person, but it is fragile when its contents are reused in an agentic workflow.

    Make every important fact safe for an agent to reuse

    An abstract AI agent selects verified product, inventory, delivery, return, location, and scheduling records from an organized website data layer.

    Agentic visibility is often lost at the seams. The product page says one thing, the structured data implies another, a category page repeats an old promotion, and the checkout reveals a condition that appeared nowhere else. A human may investigate the discrepancy. An agent asked to make progress has to decide whether the evidence is dependable enough to use.

    1. Write decisive facts atomically. Put the subject and claim together. A direct sentence or labeled field is safer to reuse than a conclusion spread across several paragraphs.
    2. Bind every qualifier to the claim it limits. Location, variant, time, membership, compatibility, and payment conditions should not sit in a distant footnote or unrelated accordion.
    3. Separate changing state from durable explanation. Maintain price, availability, release status, and bookable times in controlled fields. Do not manually echo a changing value throughout descriptive copy unless every copy is updated from the same record.
    4. Align visible content and JSON-LD. Markup should describe the same entity, value, condition, and availability that a visitor sees. Never use structured data to make a stronger or more current claim than the page supports.
    5. Make identity explicit. A product family is not a variant, a marketplace is not necessarily the merchant, and a service category is not a bookable service. Name the exact object to which each fact belongs.
    6. Preserve the action state. A buy, book, or request link should lead to the relevant product, variant, service, or location whenever the destination supports it. Explain any required selection before the handoff.

    JSON-LD is useful here because it can express facts in a machine-readable form, but it cannot repair an incoherent operation. Treat markup as a representation of maintained reality, not as a place to add claims that the rest of the journey cannot honor. If a fact changes too often to keep current on the page, creating additional unmanaged copies of it increases the risk.

    For commerce pages

    • Identify the exact product and variant rather than relying on a family-level title.
    • Attach currency, discount conditions, and eligibility requirements to the displayed price or benefit.
    • Distinguish current stock from general product availability or an expected future release.
    • State compatibility as a rule that can be evaluated, including the condition that makes an option unsuitable.
    • Make the merchant relationship and checkout path clear when several sellers or stores may offer the item.
    • Describe loyalty or payment benefits only where their qualifying conditions are visible and maintained.

    For local service and booking pages

    • Name the actual service, service area, and location instead of expecting a broad business description to establish all three.
    • Keep bookable availability separate from ordinary opening hours. A business can be open without having a qualifying appointment.
    • Show whether a displayed amount is a current price, a starting price, or a quote that depends on additional information.
    • Place decisive requirements near availability, including timing, location, capacity, or service-specific conditions.
    • Send the user to the matching booking state and disclose any remaining selection required there.

    Use the visible page as the editorial contract. If your structured data, commercial integrations, or booking system cannot support that contract, fix the underlying record before adding another optimization layer.

    Compete for selection, not just a citation

    Classic SEO often treats inclusion as the central win: rank, appear, earn a rich result, or receive a citation. Agentic commerce adds a harder question. Does your option satisfy the user’s constraints well enough to remain in the working set and move toward action?

    Google’s Shopping Graph has reached 60 billion product listings. Universal Cart is intended to help users compare in-stock availability and deals across retailers, choose a preferred store, detect incompatible components, and see eligible payment or loyalty savings. Raw product presence is therefore not a meaningful differentiator on its own.

    Build a selection record for each important offer

    A selection record is not another block of promotional copy. It is a compact internal inventory of facts that explain when your option should or should not be chosen. Build it around these questions:

    • Which user constraints make this option a fit?
    • Which condition immediately disqualifies it?
    • What compatibility rule must be checked before purchase?
    • Which price, deal, loyalty benefit, or payment perk is verifiable, and what condition limits it?
    • Which variant and merchant does the claim describe?
    • What can the user actually do now: buy, reserve, book, join a waitlist, request a quote, or only learn more?

    Move the answers into the places an agent is likely to retrieve: descriptive copy, labeled commercial fields, comparison material, structured data that accurately reflects the page, and the action endpoint. Avoid interchangeable superlatives. Best, premium, advanced, and ideal do not resolve a constraint unless the page supplies the facts behind them.

    Compatibility deserves special attention. If two components work together only under a particular version, size, configuration, or use case, describe that relationship directly. Universal Cart’s ability to flag incompatible parts and suggest alternatives means compatibility data can influence whether an item remains in the assembled order, not merely whether its page is discovered.

    The transaction layer is expanding geographically and technically, but you should distinguish a roadmap from confirmed merchant readiness. The announced plan extends the Universal Commerce Protocol to Canada and Australia, with the United Kingdom planned, while the Agent Payments Protocol is intended to authorize agents to transact within criteria set by the user. That does not establish that every merchant, market, or surface is ready.

    Assign an owner to commerce-protocol changes, record which markets and surfaces you have actually validated, and document the last successful checkout or booking test. Do not publish an integration, availability, or agent-readiness claim because a protocol was announced. Confirm that your own account, catalog, market, and transaction path support it first.

    Measure task coverage, accuracy, selection, and action

    Clicks remain useful, but they cannot describe the whole agentic journey. A user may encounter your information inside a synthesized update, use it in a generated tool, compare your offer without visiting, or reach a booking page only after Google has resolved several intermediate questions.

    Build a measurement view that keeps four outcomes separate:

    • Task coverage: Can the system produce a useful response for the high-value task, or does it lack a decisive fact?
    • Accuracy: Are the surfaced entity, variant, price, availability, compatibility, and conditions consistent with the maintained record?
    • Selection: Does your option remain present when the prompt includes the constraints your offer genuinely satisfies?
    • Action: Does the resulting link, booking flow, or checkout path preserve the user’s intent and reach a valid next step?

    Do not collapse those outcomes into one AI visibility score. A citation with stale information is a coverage event and an accuracy failure. A correctly described product that disappears when compatibility is added points to a selection problem. A strong recommendation that lands on a generic category page is an action failure.

    Use a repeatable validation loop

    1. Freeze a set of prompts that represent your priority monitoring, comparison, booking, and shopping tasks.
    2. Record the surface, market, account tier, and test date. Availability may differ across those dimensions.
    3. Capture the answer, cited or named entities, extracted facts, stated conditions, suggested option, and action path.
    4. Classify each failure as missing, inaccessible, ambiguous, conflicting, stale, undifferentiated, or broken at the handoff.
    5. Fix the maintained fact or template that created the failure. Avoid patching one page if the same faulty field feeds several pages.
    6. Repeat the same prompt after the relevant page, markup, or commercial record has been updated, and keep the before-and-after evidence.

    A single generated response shows what happened in that run. It does not establish a permanent position. Use the same prompts and evaluation criteria over time so that you can distinguish a real improvement from ordinary variation in presentation.

    Keep a rollout ledger instead of assuming one launch date

    Several capabilities were announced with different markets, products, and access levels. Treat them as separate rows in your operational plan:

    • Gemini 3.5 Flash was announced as the default model for AI Mode and as the model powering the Gemini app for users broadly.
    • Custom generative UI was announced for wider availability in the summer, beginning with Google AI Pro and Ultra subscribers in the United States.
    • Information agents were also announced for an initial summer rollout to Google AI Pro and Ultra subscribers.
    • Agentic booking for local experiences and services was announced for the United States in the summer.
    • Universal Cart was announced for a summer launch in the United States on Google Search and the Gemini app, with YouTube and Gmail planned afterward.
    • Personal Intelligence in AI Mode was described as expanding to about 200 countries and territories across 98 languages, which is a different capability from transaction availability.

    Your ledger should record the feature, market, product surface, entitlement, announced state, actual tested state, owner, and last validation. This prevents a common planning error: treating an announcement about one AI surface as proof that the same behavior is available to every searcher and merchant.

    What to do in your next optimization cycle

    1. Select one revenue-linked task rather than attempting a site-wide agentic optimization project.
    2. Write the full constrained prompt a serious customer would use.
    3. List every fact and relationship required to answer it, including disqualifiers.
    4. Reconcile those facts across the visible page, JSON-LD, maintained commercial records, and action destination.
    5. Rewrite ambiguous claims so that the subject, value, condition, and current state remain attached.
    6. Run the validation loop and log where the task breaks.
    7. Scale the improved structure only after the complete journey works for the original task.

    Start with a journey where price, availability, compatibility, or bookability changes frequently. Volatile facts expose weak handoffs quickly, and errors there can change the user’s decision. Fix that journey before producing another batch of top-of-funnel copy.

    Google’s interface will keep moving. Your best hedge is not predicting every feature. It is making one valuable customer journey legible, current, differentiated, and executable from end to end. Pick that journey now and repair its weakest handoff.

    References

  • How to Build AI Marketing Operations That Improve Visibility

    How to Build AI Marketing Operations That Improve Visibility

    Your team can use AI to produce briefs, drafts, reports, and campaign variants faster and still become no more visible in AI search. When that happens, generation is not the constraint. The missing piece is usually the operating system between a buyer’s question, the evidence your company owns, the page that carries the answer, and the feedback that tells you whether the answer was found.

    Treat AI visibility as a marketing operations problem. Connect demand discovery, content decisions, evidence management, publishing, structured data, technical access, and measurement in one governed loop. You will automate less blindly, publish fewer disposable assets, and learn where visibility is actually breaking down.

    Build a closed loop, not a collection of AI tools

    An AI-powered marketing operation should move through a repeatable loop: observe how people express a need, decide which questions matter, locate defensible evidence, create or update the right asset, make that asset technically understandable, measure its appearance and impact, and feed the result into the next decision.

    That is different from adding an AI tool to every task. A drafting tool may reduce production time without improving accuracy, retrieval, or conversion. A reporting assistant may summarize a dashboard without telling you which content gap caused the result. Local efficiencies matter, but they become useful only when each output has an owner, an acceptance rule, a destination, and a measurable purpose.

    Key takeaways

    • Design visibility work around real decision prompts and their likely subquestions, not isolated keywords.
    • Package repeatable marketing judgment as governed AI skills with approved inputs, output contracts, permission limits, and review gates.
    • Maintain a canonical evidence layer so AI workflows reuse verified facts instead of regenerating claims from memory.
    • Make visible content, internal relationships, technical signals, and JSON-LD describe the same entities and facts.
    • Measure the full chain from workflow quality to retrieval, citation context, qualified visits, and business outcomes.

    Use three separate questions when evaluating an AI initiative. Can the system complete the task? Can it complete the task consistently under your rules? Does the result improve discovery or a business decision? A workflow is not successful merely because it generated an output.

    Map buyer prompts to fan-out query coverage

    A glowing inquiry orb branches into many connected paths that lead to a coordinated group of content modules.

    A buyer’s prompt is not necessarily one retrieval event. The mechanics associated with ChatGPT Search include web.run and fan-out queries, which can turn one request into several related searches before an answer is composed. Do not assume every model, product surface, prompt, or session behaves identically. For planning purposes, however, a prompt should be treated as a bundle of information needs rather than a long keyword.

    Suppose a buyer asks which inventory platform fits a multi-location retailer with limited implementation resources. The visible prompt contains several possible subquestions: which platforms support multiple locations, what implementation involves, which systems integrate with the buyer’s stack, how migration works, what support is available, what commercial constraints apply, and which alternatives deserve consideration. A page optimized only for the phrase inventory platform may answer none of them well.

    Create a prompt map before creating more content. Give every row these fields:

    • Exact prompt: the question as the buyer would ask it, including relevant context and constraints.
    • Decision stage: learning, narrowing options, validating a choice, implementing, or troubleshooting.
    • Likely subquestions: the facts, comparisons, definitions, risks, and next steps needed to resolve the main prompt.
    • Entities: the products, organizations, people, locations, standards, or concepts that must be identified consistently.
    • Evidence requirement: the proof needed for each meaningful claim and the person responsible for maintaining it.
    • Canonical answer: the best existing URL or source-of-truth record for that subquestion.
    • Gap status: absent, incomplete, unsupported, stale, duplicated, technically inaccessible, or ready.
    • Next action: update an existing asset, create a focused asset, improve an internal relationship, fix technical access, or leave the coverage unchanged.

    The map prevents two common mistakes. The first is forcing every subquestion into one oversized page. The second is publishing several pages that compete to answer the same question. Keep related subquestions together when they serve the same intent and depend on the same evidence. Split them when the audience, decision stage, evidence, or required action differs materially.

    Assign one editorial source of truth to every important claim. That is not merely an HTML canonical tag. It is the internal record your people and AI workflows are expected to reuse. Other pages can adapt the explanation for a different context, but names, definitions, product capabilities, dates, limitations, and relationships should remain consistent.

    Prioritize gaps by decision value, not estimated content volume alone. A narrow implementation question that blocks a purchase may deserve attention before a broad informational query. Record why each prompt matters, what action a satisfactory answer should enable, and how you would recognize a useful visit or conversion.

    Turn repeatable judgment into governed AI skills

    Traditional automation works well when a trigger and response can be specified in advance. Marketing work often contains a layer of judgment between them: interpreting a prompt, selecting evidence, resolving conflicting inputs, applying brand rules, and deciding whether a human must intervene. The move toward AI skills as a layer of marketing automation gives you a practical way to package that judgment without pretending the entire operation can run unattended.

    For operating-design purposes, a skill is a reusable method with defined inputs, instructions, tools, quality checks, and handoffs. An agent may decide which actions to take and invoke one or more skills. Keeping those concepts separate helps you test the method before granting a system broader autonomy.

    Skill fieldWhat to specifyOperational purpose
    TriggerThe event that starts the work, such as a new prompt gap, changed product fact, failed validation, or scheduled reviewPrevents vague or unnecessary runs
    GoalThe decision or accepted outcome, not a generic activity such as analyze contentKeeps the workflow tied to value
    Approved inputsNamed repositories, fields, versions, owners, and freshness statusLimits unsupported claims and stale data
    ProcedureThe required sequence, decision rules, tool permissions, and stop conditionsMakes execution repeatable and auditable
    Output contractRequired fields, format, status labels, destination, and confidence or uncertainty notesAllows downstream systems and reviewers to rely on the result
    Evidence policyAcceptable evidence, citation requirements, and the treatment of missing or conflicting informationSeparates verified facts from generated language
    GuardrailsActions the skill may not take, including publishing, deleting, changing spend, or altering protected claims without approvalContains financial, reputational, and data-loss risk
    Review gateThe reviewer, acceptance criteria, escalation path, and rejection reasonsTurns human review into a defined control
    Run logInstruction version, inputs, tool actions, outputs, approvals, errors, and final statusMakes failures diagnosable instead of anecdotal

    A useful first skill is visibility-gap triage. Give it a fixed prompt set, your published URL inventory, the evidence registry, and current technical status. Require it to classify intent, propose likely subquestions as hypotheses, map those subquestions to existing assets, identify missing or weak support, and return a prioritized backlog with an owner and rationale. Do not let it invent supporting facts or publish the resulting content.

    The distinction between evidence and generated language must be explicit. A model can rewrite an approved claim for clarity. It should not turn its own prior output into proof. When evidence is absent or contradictory, the correct output is a flagged gap, not a smoother sentence.

    Start new skills with read access and a preview output. Add write access only after you can identify recurring failure modes and show that the review gate catches them. Publishing, budget changes, destructive edits, pricing updates, regulated claims, and legal commitments need explicit approval and a recoverable change path. Faster execution is not worth an untraceable change to a live asset.

    Treat external text as input data, not as instructions to the workflow. Keep governing instructions separate from fetched pages, restrict the available tools and destinations, and stop the run when a requested action crosses its permission boundary. These controls belong in the skill definition rather than in a reviewer’s memory.

    Publish answer-ready assets backed by a shared evidence layer

    A secure central repository of source materials connects to multiple digital content assets while human reviewers inspect the information flow.

    AI visibility does not improve simply because you publish more often. Your assets need to make the answer, its scope, its supporting evidence, and the relevant entity relationships easy to identify. The same structure also helps human readers decide whether the answer applies to them.

    For each important prompt, make sure the destination asset resolves these questions:

    • What is the direct answer to the user’s question?
    • Which audience, product, location, situation, or version does the answer cover?
    • What evidence supports each consequential claim?
    • What limitation, dependency, or uncertainty could change the answer?
    • Which named entity does each capability, quote, statistic, or relationship belong to?
    • Where can a reader verify details or continue to the next decision?

    Put a concise answer close to the relevant heading, then explain the mechanism, evidence, scope, and next action. Do not make the reader cross several promotional paragraphs to discover whether the page answers the question. Descriptive headings, short answer passages, explicit comparison criteria, and nearby evidence create clearer units for both reading and extraction.

    Keep an evidence registry outside the prose. A practical record includes the claim, supporting material, entity, scope, owner, approval status, last verified state, affected URLs, and the event that should trigger revalidation. Refreshing on a fixed calendar can miss an important product or policy change; trigger review when a dependency changes.

    Your structured data must agree with the visible page and the evidence registry. Choose Schema.org types that describe entities actually present on the page. Use stable @id values where you need to connect the same entity across nodes. Keep names, canonical URLs, authors, dates, products, organizations, and relationships consistent. Validate the generated JSON-LD after rendering, not merely inside the content management form.

    Do not use schema to manufacture certainty. Marking a statement as structured data does not substantiate it, and adding an unsupported property can make the machine-readable version less trustworthy than the visible content. If your team cannot verify a claim, fix or remove the claim before encoding it.

    Technical availability is the other half of answer readiness. Confirm that the canonical URL returns meaningful rendered content, is linked from an appropriate part of the site, is not blocked unintentionally, and does not send conflicting canonical, redirect, or indexability signals. Check whether important content appears only after an interaction that a crawler may not perform. Keep sitemaps, internal links, metadata, visible facts, and structured data aligned after migrations and template changes.

    Do not create a separate AI version of every page unless a real audience or delivery requirement justifies it. A parallel content layer creates another place for facts to drift. Improve the canonical human-readable asset first, then expose the same approved facts through the formats your workflows and distribution systems need.

    Measure the chain, then scale one workflow at a time

    A single AI visibility score cannot tell you why performance changed. Separate the operating chain into layers so that each signal points to a possible action.

    LayerWhat to recordWhat a problem may mean
    Workflow qualityAccepted outputs, rejection reasons, manual corrections, failed runs, review effort, and cost per approved resultThe skill, inputs, permissions, or output contract needs revision
    Answer coveragePrompts mapped, subquestions covered, evidence gaps, duplicated answers, and change dependenciesYour content plan does not match the decision journey
    Technical readinessCanonical status, indexability, rendered content, internal discovery, structured data validity, and identifiable crawler activityA good answer may be inaccessible or ambiguous to machines
    AI visibilityBrand presence, cited URL, citation context, answer position or role, and other entities included for a controlled prompt setThe asset may lack relevance, authority, clarity, coverage, or retrievability
    Business effectQualified landing-page visits, assisted conversions, sales or support actions, and downstream value supported by your attribution modelVisibility may be reaching the wrong audience or failing to help a decision

    Build a controlled prompt panel for measurement. Preserve the exact prompt and record the model or product label, date, language, locale, account or personalization state when known, full answer, cited links, and citation context. AI outputs can vary across runs and product contexts, so a screenshot from one prompt is evidence of an occurrence, not a trend.

    Compare like with like and retain the raw result. Do not average several models, languages, prompt variants, and user states into one unexplained number. A visibility score can be useful as a directional summary, but the underlying prompt-level evidence must remain available for diagnosis.

    Inspect how your brand appears, not merely whether it appears. A citation can support a competitor, repeat an outdated limitation, or place your company in the wrong category. Record the claim being supported and whether the cited page is the asset you want representing that claim.

    Use a narrow rollout to connect the layers:

    1. Choose one commercially meaningful buyer decision and define the action a useful answer should enable.
    2. Create a controlled prompt set and map each prompt to likely subquestions, entities, evidence, and canonical URLs.
    3. Audit those URLs for answer completeness, factual support, entity consistency, JSON-LD alignment, and technical access.
    4. Select one repeated handoff or analysis task and encode it as a governed skill with a preview output.
    5. Run the skill against approved inputs, categorize every rejection, and revise its rules before granting broader permissions.
    6. Publish only reviewed changes and preserve the previous version or another safe rollback path.
    7. Capture a prompt-level visibility baseline and connect referred or assisted activity to your existing analytics and attribution process.
    8. Expand to another journey only when outputs are traceable, permission boundaries hold, and reviewers are correcting exceptions rather than rewriting everything.

    Pause expansion when the workflow cannot identify the evidence behind a claim, repeatedly selects the wrong destination, changes protected content without approval, or produces an output that depends on extensive reviewer reconstruction. Those are design failures, not signs that you need more content volume.

    Start with one high-value buying question and one recurring workflow that currently creates avoidable handoffs. Map the question, strengthen its evidence-backed answer, wrap the repeatable work in a controlled skill, and measure the same prompt set before and after the change. That scope is small enough to govern and complete enough to reveal whether your real constraint is content, evidence, access, execution, or demand.

    References