Tag: Agentic AI

  • Human Factors That Make Agentic AI Deployments Work

    Human Factors That Make Agentic AI Deployments Work

    Your agent can draft pages, change metadata, select audiences, trigger campaigns, and coordinate customer journeys. The hard question isn’t whether it can perform those actions. It’s whether it should be allowed to perform each one without stopping for a person.

    If you’re deciding how much autonomy to grant, treat the deployment as an operating-model decision rather than a software installation. Define who owns the outcome, which actions require approval, how people will detect a bad decision, and how they can stop or reverse it. Those human controls determine whether the agent produces useful leverage or merely executes mistakes faster.

    Start with a decision, not an AI agent

    Agentic AI projects often begin with a capability demonstration: the system can plan a campaign, create content, update a workflow, or act across several tools. A convincing demonstration doesn’t establish that the workflow is worth automating or safe to delegate.

    The warning is concrete. Gartner expects more than 40% of agentic AI projects to be canceled by the end of 2027. The projection, based on more than 3,400 organizations investing in the technology, points to unclear value, weak governance, and hype-led experimentation rather than a simple lack of technical capability. Treat that percentage as a forecast, not a settled outcome, but don’t miss the operational problem behind it.

    Before you select a product or build an agent, write a decision brief for one workflow. It should answer these questions:

    • What outcome changes? Name the business result, not the AI activity. “Reduce the time required to prepare a technically reviewed content brief” is an outcome. “Use an agent for briefs” is not.
    • What does the workflow look like now? Record its inputs, decisions, handoffs, failure points, review work, and final action. Otherwise, you won’t know whether the agent improved the process or merely moved effort into supervision and repair.
    • Which judgment is scarce? Separate repetitive coordination from decisions that depend on audience knowledge, brand context, ethics, or commercial priorities. Automating the former may create capacity. Hiding the latter inside a prompt creates unmanaged risk.
    • What evidence would justify continuation? Choose outcome, quality, intervention, and recovery measures before launch. A pilot without an exit rule tends to survive because it exists, not because it works.
    • Who can stop it? Assign a named operational owner with authority to pause actions, narrow scope, and require remediation.

    This brief also protects you from “agent washing.” A conventional chatbot or fixed automation shouldn’t be purchased as an autonomous agent simply because the label changed. Ask the vendor or internal team to demonstrate the operating loop: what the system observes, which choices it makes, what it can change, how it checks the result, when it stops, and when it escalates. If every meaningful path was predetermined, you may still have useful automation, but you don’t have the adaptive autonomy the name implies.

    For an SEO or GEO workflow, make the distinction visible. An agent that recommends schema corrections is materially different from one that edits production markup. An agent that identifies possible internal links is different from one that publishes them. An agent that proposes a redirect is different from one that changes routing. Evaluate the authority being granted, not just the sophistication of the output.

    Design human control before you grant autonomy
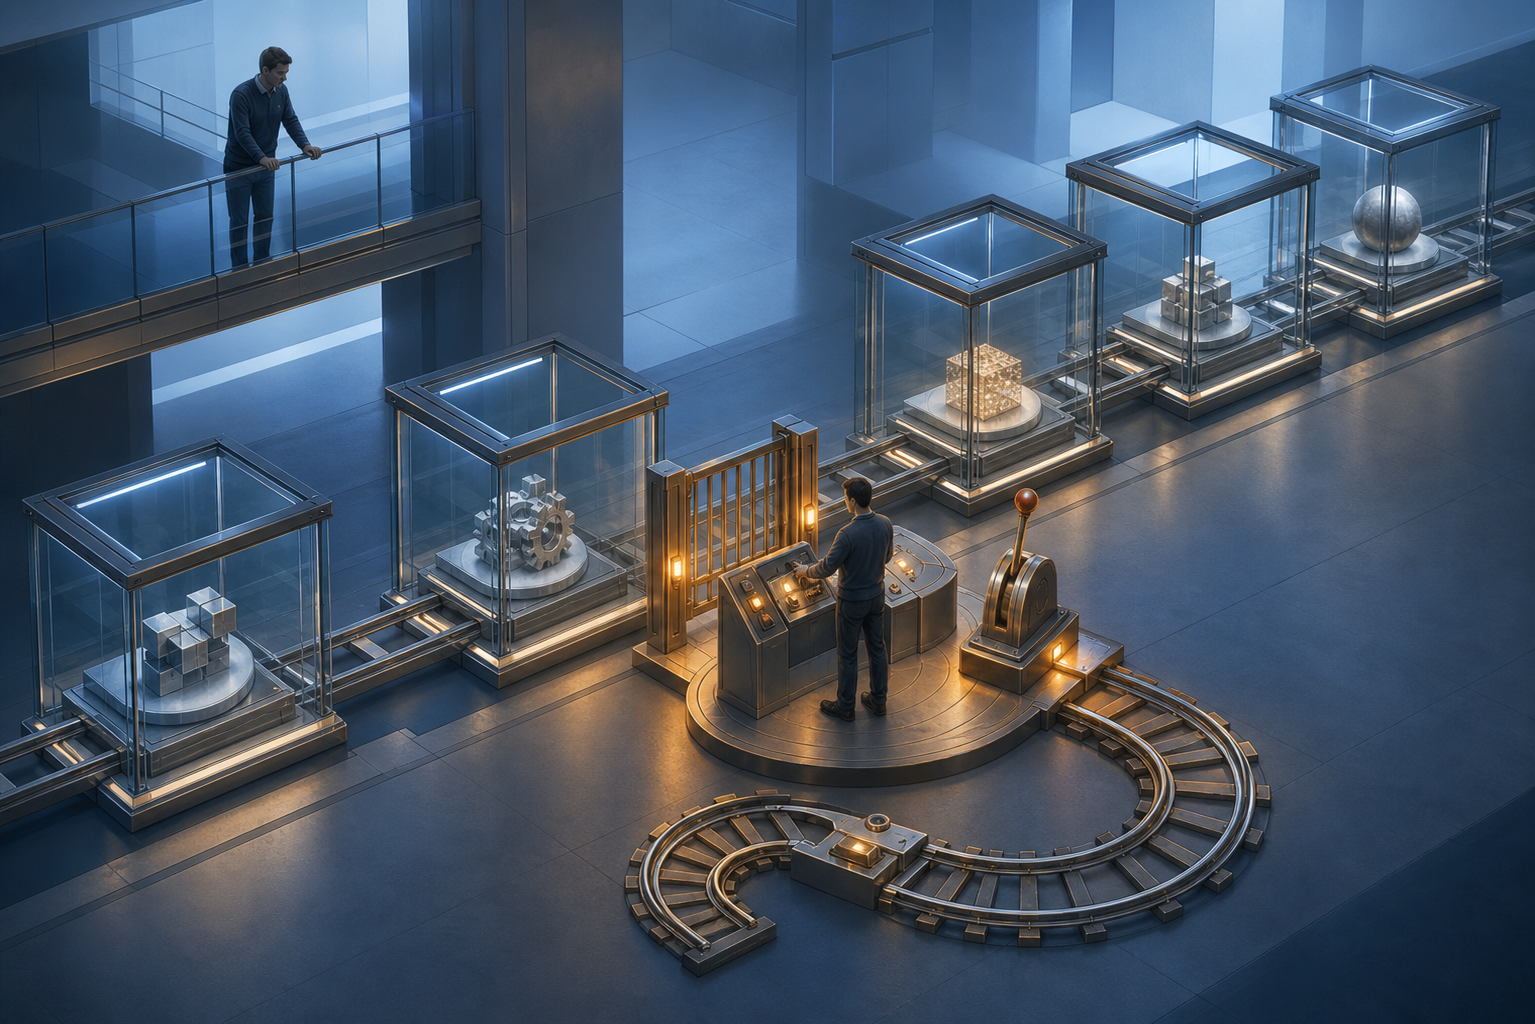
    Two operators oversee a modular automated workflow equipped with an approval gate, a pause lever, and a track that can reverse direction.

    “Human in the loop” is too vague to serve as a control. A person can technically appear in a workflow while lacking the context, time, authority, or evidence needed to catch a problem. Effective oversight specifies the decision rights on both sides of the human-agent boundary.

    Classify every action the agent may take using four practical questions:

    • Can it be reversed? Saving a draft is easy to undo. Sending a customer message, changing access, publishing an unsupported claim, or allowing a damaging URL change to propagate may not be.
    • How wide is the impact? A suggestion affecting one draft has a smaller blast radius than a template change affecting thousands of pages or an audience rule applied across campaigns.
    • How much context does the decision require? Stable rules are easier to delegate than choices involving brand nuance, conflicting evidence, unusual customer circumstances, or several acceptable outcomes.
    • Will failure be visible quickly? A malformed output may be obvious. A plausible but strategically wrong recommendation can remain unnoticed while it influences content, spend, or customer treatment.

    Use the answers to assign authority. Reversible, narrow, observable actions with clear rules are reasonable candidates for bounded autonomy. Irreversible, broad, ambiguous, or slow-to-detect actions should require approval or remain human-owned. Don’t use one autonomy setting for the entire workflow.

    ControlQuestion it must answerEvidence to retain
    Named ownerWho is accountable for the business outcome and failure response?Owner, backup, authority, and escalation route
    Scope boundaryWhich systems, records, audiences, and actions may the agent touch?Allowlist, denied actions, and permission configuration
    Approval gateWhich conditions force a person to decide?Trigger, reviewer, required context, and decision record
    Stop controlHow can a person halt new actions without waiting for the agent?Pause procedure, access owner, and confirmation that execution stopped
    Recovery pathHow will the team contain and reverse a bad action?Rollback method, affected-system inventory, and notification route
    Audit trailCan reviewers reconstruct what the agent knew, chose, and changed?Inputs, retrieved context, proposed action, approval, execution result, and exceptions

    The audit trail needs to capture more than generated text. Store the context used for the decision, the action requested, the tools called, the result returned, any human intervention, and the final system state. A polished explanation generated after the event isn’t a substitute for an execution record.

    Approval interfaces deserve the same care. Don’t ask a reviewer to click “approve” after showing only the agent’s preferred answer. Show the original input, relevant constraints, proposed change, affected assets, uncertainty or missing information, and available alternatives. Make rejection and escalation as easy as approval. Otherwise, the interface quietly trains people to accept.

    For content and search operations, require explicit review before actions such as publishing factual claims, changing canonical directives, modifying crawl controls, issuing broad redirects, altering product or business data, sending outreach, or communicating with customers. Your exact gates should reflect your systems and risk, but the rule is stable: the person must intervene before the consequential action, not after the impact appears in analytics.

    Increase autonomy only after the workflow becomes observable
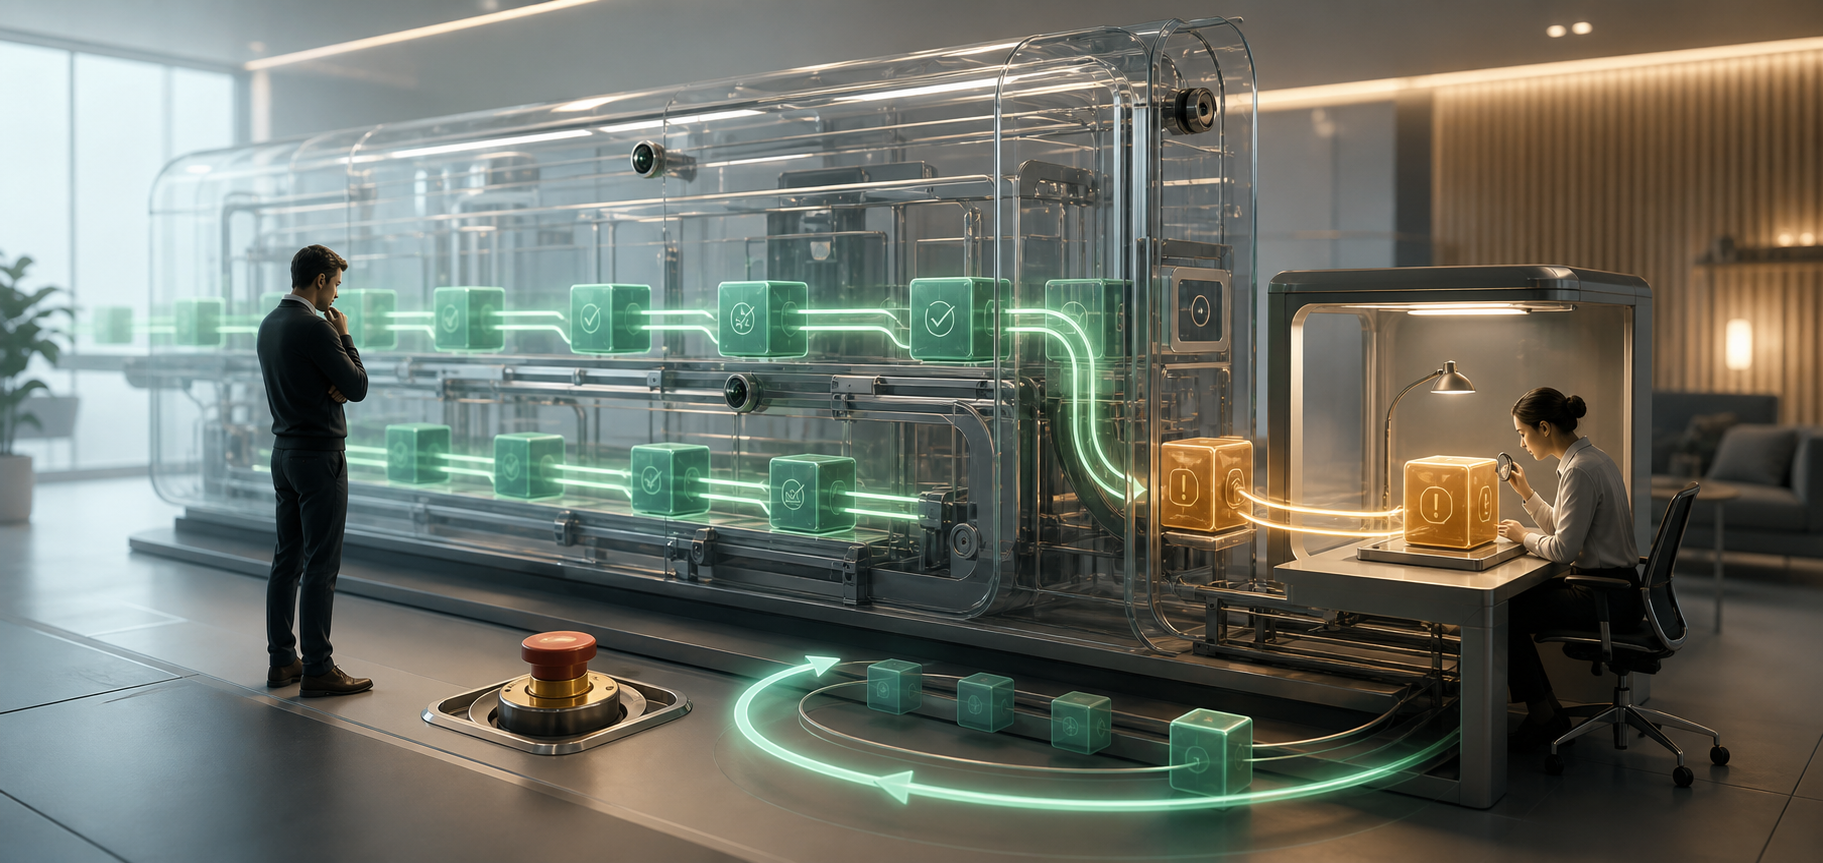
    Analysts monitor tasks moving through a transparent automated system while an unusual task is diverted into a separate human review bay.

    A pilot should test the complete operating system around the agent. Testing only whether the model can produce a good answer leaves permissions, handoffs, monitoring, escalation, and recovery unexamined.

    Move through these modes in order:

    1. Shadow mode: Let the agent observe real inputs and record what it would do, but prevent external actions. Compare its proposed decisions with actual outcomes and inspect where its context is incomplete.
    2. Advisory mode: Let it recommend actions to a responsible operator. Record approvals, edits, rejections, escalation reasons, and the time required to review. Heavy correction is evidence that the workflow or context is not ready for autonomy.
    3. Bounded action mode: Allow a defined set of reversible actions within an allowlisted scope. Keep consequential actions behind approval gates and enforce a direct stop mechanism.
    4. Expanded autonomy: Broaden authority only when the existing scope produces acceptable outcomes, exceptions are understood, logs support investigation, and the team can demonstrate recovery.

    Promotion between modes should be an evidence decision. Don’t advance because the pilot deadline arrived or because a successful demonstration created executive enthusiasm. Review routine cases, edge cases, ambiguous requests, missing-data situations, conflicting instructions, permission failures, and attempts to push the agent beyond its assigned scope.

    Measure the deployment across four layers:

    • Outcome: Did the workflow improve the business result named in the decision brief?
    • Quality: Were outputs accurate, complete, on-brand, appropriately sourced, and suitable for the intended audience?
    • Control: How often did people edit, reject, stop, or escalate an action, and why?
    • Recovery: Could the team identify affected assets, contain the problem, restore the correct state, and learn from the failure?

    Don’t optimize the intervention rate toward zero. A falling rate can mean the system improved, but it can also mean reviewers stopped looking carefully. Read intervention data alongside sampled quality checks, downstream outcomes, and exception reports. The useful question is whether human attention is landing on the decisions where it changes the outcome.

    FOMO creates pressure to skip this progression and move directly from demo to production. That pressure is especially dangerous when an agent can act at campaign or site scale. Speed comes from making the safe path repeatable: clear permissions, reusable evaluation cases, reliable logs, tested rollback, and known escalation owners.

    Protect human judgment and customer trust as operating assets

    An agent’s output can look coherent even when its recommendation is unsuitable. That makes reviewer competence part of the control environment. If the person approving an action can’t recognize a strategic, factual, or ethical error, the approval step is ceremonial.

    One projection expects half of organizations to reassess their competencies as reliance on AI threatens critical thinking. You don’t need to reject automation to respond. You need to keep the relevant judgment active.

    • Require a reason for consequential approvals. The reviewer should identify why the action fits the goal and constraints, not merely confirm that the output reads well.
    • Keep people capable of performing the underlying task. Rotate qualified operators through manual cases and exception handling so the team retains a working model of what good looks like.
    • Separate creation from high-impact approval. The person who configured or champions the agent shouldn’t be the only person judging its production readiness.
    • Review disagreements, not just errors. Repeated edits and rejected recommendations reveal missing context, unclear policy, or a task that requires more human judgment than expected.
    • Run post-incident reviews around the system. Examine instructions, data, permissions, interface design, workload, escalation, and incentives. Telling reviewers to “be more careful” leaves the mechanism intact.

    Customer trust needs its own controls. A related forecast warns that poorly applied agentic AI could damage customer relationships by 2026. The risk isn’t limited to obviously nonsensical responses. An agent can send a polished message to the wrong person, apply a reasonable rule at the wrong moment, or take an authorized action that conflicts with the customer’s circumstances.

    Map each customer-facing action to an identity, authority, and escalation rule. The customer should be able to tell what happened, correct wrong information, reach a person when the automated path is unsuitable, and receive a clear resolution when an action causes harm. Internally, the team should be able to identify which agent acted, under whose authority, using what information.

    Brand alignment can’t live only in a long prompt. Translate it into reviewable policies: prohibited claims, evidence requirements, tone boundaries, audience exclusions, escalation topics, and actions the agent may never take. Give each policy an owner and a process for change. That turns “use good judgment” into controls a team can inspect.

    Key takeaways

    • Begin with one defined business decision and its current workflow, not a general mandate to deploy an agent.
    • Evaluate actual autonomy by inspecting what the system observes, decides, changes, verifies, and escalates.
    • Grant authority action by action. Reversibility, impact, ambiguity, and observability should determine where people intervene.
    • Test in shadow, advisory, bounded-action, and expanded-autonomy modes, with evidence required before each increase in authority.
    • Retain execution logs, explicit stop controls, and tested recovery paths before the agent touches consequential systems.
    • Treat reviewer competence and customer escalation as core infrastructure, not training tasks to add after launch.

    Before your next agent demo, produce a one-page deployment contract for the workflow: outcome, owner, allowed actions, prohibited actions, approval triggers, stop mechanism, recovery path, and evidence required for more autonomy. If the team can’t agree on that page, the agent isn’t ready for broader access. Resolving those human decisions first is the shortest route to a deployment you can trust.
    References

  • How to Prepare for Google Search as a Task-Completing Agent

    How to Prepare for Google Search as a Task-Completing Agent

    If your SEO strategy ends when somebody clicks a result, you are preparing for an older version of Search. A task-completing system may use your content to compare options, resolve constraints, choose a next step and initiate an action. Your page is no longer competing only to be read. It is competing to be useful inside a larger job.

    This does not mean abandoning rankings, traffic or conventional SEO. It means adding a second standard: can Google understand what your business offers, determine when it is appropriate and move a user toward a safe, verifiable outcome?

    The search result is becoming part of the workflow

    Traditional search usually separates discovery from execution. You search for information, open several pages, make sense of them and complete the task somewhere else. Agentic search compresses those stages. Google’s stated direction is for more information-seeking queries to become agentic, with Search coordinating long-running work and multiple concurrent threads.

    Think about a request such as, “Find accounting software suitable for a small Canadian consultancy, compare the plans and help me arrange a demonstration.” An ordinary results page can supply links for each part. A task-oriented system has to preserve the user’s requirements while it researches vendors, rules out unsuitable choices, explains trade-offs and hands the user into an action.

    That changes the unit of optimization. A keyword is one expression of demand. A task includes the desired outcome, the constraints, the decisions that must be made, the evidence needed to make them and the action that finishes the job.

    • Question: What does the user need to know?
    • Qualification: Which options fit the user’s location, situation, budget, timing or technical requirements?
    • Decision: What evidence separates an appropriate choice from an inappropriate one?
    • Action: What can the user book, buy, configure, submit or request?
    • Verification: How does the user know the action succeeded, and how can it be changed or reversed?

    People are already using AI Mode for deep-research queries that stretch beyond the old one-query, one-answer pattern. That is the immediate signal to act on. You do not need to predict every interface Google will release. You need to make your public information dependable enough to support a multi-step decision.

    Search and Gemini are also expected to coexist, overlapping in some uses while diverging in others. Do not reduce your plan to optimizing for one chatbot response. Your information may be encountered through a conventional result, an AI-generated answer, a research workflow or an action-oriented experience. The underlying facts should remain consistent across all of them.

    Optimize the complete task, not just its opening query

    An isometric workflow follows a user request through comparison, constraint checking, availability, verification, and a completed outcome.

    Start with one task that matters to your audience and your business. Avoid broad goals such as “learn about payroll” or “rank for payroll software.” Use an observable outcome: “Determine whether this payroll service supports my type of company and begin the correct signup process.”

    Then create a task map. This is more useful than a keyword cluster because it exposes the information gaps that can stop an agent or a person from proceeding.

    1. Write the outcome in the user’s language. State what will be decided or completed, not what content will be consumed.
    2. List the required inputs. Identify the details that change the answer, such as location, organization type, compatibility, eligibility, timing or service area.
    3. Break out the decisions. Record every choice the user must make before acting. A product tier, appointment type or implementation route may each require a separate decision.
    4. Assign evidence to each decision. Decide which page supplies the specification, policy, price, limitation, comparison or proof needed at that point.
    5. Define the action and handoff. Make clear where the user can start, what information will be requested and what happens after submission.
    6. Document failure and recovery paths. Explain what to do when the user is ineligible, an option is unavailable, a form fails or an action must be cancelled.

    The recovery path matters because task completion is not the same as pushing every visitor toward conversion. A reliable system must also recognize when your offer does not fit. If exclusions are buried in terms, an agent may recommend the wrong route and the user will discover the problem late. Put decisive limitations beside the claims they qualify.

    Next, label the role of every page in the task. One page may establish eligibility, another may compare options, another may explain a procedure and another may host the transaction. A page can serve more than one role, but each role should be explicit. If your team cannot agree on what a page contributes to the task, an automated system is unlikely to infer it reliably.

    Build pages an agent can interpret and use

    An agent-ready page is not a page written for robots. It is a page on which the decisive facts are clear, scoped and consistent. Good structure helps people and machines for the same reason: neither should have to reconstruct a critical condition from vague marketing language.

    Task layerWhat must be resolvedWhat to improve on the site
    IntentThe outcome the page supportsUse a descriptive title, a direct opening answer and a clear statement of who the page is for.
    QualificationWhether the offer fits the user’s constraintsState eligibility, locations, dependencies, exclusions and prerequisites beside the relevant offer.
    DecisionWhy one option should be chosen over anotherUse comparable attributes, defined terms and evidence tied to specific claims.
    ActionHow to begin or complete the next stepName the action precisely, disclose required inputs and explain what happens after it is submitted.
    VerificationWhether the action succeededProvide an explicit confirmation state, reference information and a route for correction or cancellation.
    Machine interpretationWhich entities and relationships the content describesUse accurate structured data that matches the visible page and the site’s canonical facts.

    Several practical rules follow from this model.

    Put the decisive answer before the supporting narrative

    If a service is available only in particular locations, say that near the service description. If a plan requires another product, state the dependency beside the plan. If the next step is a consultation rather than an immediate purchase, label it accurately. Do not make the reader decode “Get started” to discover what will actually happen.

    Turn implied knowledge into explicit facts

    Businesses often assume that visitors understand their terminology, market, service boundary or product hierarchy. An agent cannot safely rely on that assumption. Define ambiguous terms, attach units to measurements, give conditions to claims and distinguish facts about the company from facts about a particular offer.

    Consistency is more important than repetition. If a product name, service area, policy or plan description differs across a landing page, help page and checkout flow, decide which version is canonical and correct the others. Structured data should reflect that same version.

    Use JSON-LD as a factual layer, not a persuasion layer

    Choose Schema.org types and properties that match what is visibly present. Identify the organization, offer, product, service, person, place or event only when the page genuinely describes that entity. Connect related entities where the relationship is real. Keep names, URLs, identifiers and offer details aligned with the canonical content.

    Do not add unsupported properties because they look advantageous, and do not mark up claims that a visitor cannot verify on the page. JSON-LD can make a fact easier to interpret; it cannot turn an incomplete, stale or contradictory claim into a trustworthy one.

    Design the action boundary deliberately

    Research and execution carry different risks. Reading a comparison is low commitment. Sending personal information, placing an order or booking an appointment is not. If your task ends in an action, make the commitment point unmistakable.

    • Show what will be submitted or purchased before confirmation.
    • Separate required inputs from optional ones.
    • Display material conditions before the final action, not only after it.
    • Explain whether the action is immediate, pending review or merely a request.
    • Provide a correction, cancellation or support route where the action permits one.
    • Return a clear success or failure state instead of leaving the user to infer the result.

    These are conversion fundamentals, but they become more important when software may coordinate the handoff. Ambiguous buttons, silent form failures and hidden conditions do not merely reduce conversion. They make the task unsafe to delegate.

    Audit task readiness before agent traffic becomes measurable

    A digital inspection agent scans the modular elements of a webpage while a human specialist supervises from a control station.

    You may not be able to isolate every agent-assisted visit or decision in your reporting. You can still measure whether your site is ready to participate. Treat readiness as a content, data and workflow quality problem.

    Use a simple zero-to-two audit for each important task. This is a prioritization method, not a search-engine score:

    • 0 — Missing or contradictory: the task cannot proceed without guessing, or two public pages give incompatible answers.
    • 1 — Inferable: the answer exists, but the user must combine pages, interpret vague wording or uncover a condition late.
    • 2 — Explicit and usable: the answer is clear, appropriately qualified, current and connected to the correct next step.

    Score the task across six dimensions: outcome definition, qualification facts, decision evidence, action path, confirmation or recovery, and measurement. Do not obsess over the total. A zero in any dimension identifies a broken link in the workflow and deserves attention before cosmetic content changes.

    Run the audit from the public site, without internal knowledge. Give a team member the task and its constraints. Ask them to find the right option, explain why it fits, begin the action and identify how they would reverse or correct it. Record every point where they have to guess. Those guesses become your content and workflow backlog.

    Measure the workflow in stages so a completed task is not reduced to a pageview:

    • Discovery: Did the relevant landing page become visible for the task?
    • Qualification: Did the visitor reach the eligibility, specification, policy or comparison information needed to proceed?
    • Action: Did the visitor start and complete the intended form, booking, configuration or transaction?
    • Failure: Where did validation errors, unavailable options or unclear requirements stop progress?
    • Outcome quality: Did the action lead to confirmation, or did it create cancellations, corrections and avoidable support work?

    This measurement model also protects you from a misleading success signal. More action starts are not helpful if users are being routed into an unsuitable option. Pair completion data with failure, cancellation and correction data so you can distinguish task volume from task quality.

    Key takeaways

    • Optimize for a defined user outcome, not only the keyword that begins the journey.
    • Map qualification, decision, action and verification as separate stages, then assign each stage to reliable public information.
    • State decisive constraints beside the claims they limit. Do not hide eligibility, dependencies or exclusions at the end of the path.
    • Keep visible content, structured data and transactional interfaces consistent about the same entities and offers.
    • Treat confirmation, correction and cancellation as part of task completion, not as support details.
    • Audit every task for missing or contradictory information before trying to infer performance from agent-specific traffic.

    Choose one commercially important task this week. Write its outcome, inputs, decisions, evidence, action and recovery path on a single page. Then follow it through your public site and fix the first place where a user has to guess. That work will improve the experience now, while giving agentic Search cleaner material to use as it moves from answering questions toward completing jobs.

    References

  • Google Ads Developer AI Updates: A Practical Playbook

    Google Ads Developer AI Updates: A Practical Playbook

    You do not need another AI announcement in your backlog. You need to know whether Google’s direction changes what your advertising team should build, who should control it, and how much authority an AI agent should receive.

    The immediate answer is not to rebuild your Google Ads integration around agents. Treat the update as an architectural signal: prepare for AI systems to propose and invoke advertising actions, but keep permissions, validation, approvals, execution, and audit controls outside the model.

    The update is a learning channel, not an API release

    An engineer studies abstract signals from a studio beacon while a separate sealed production system remains unchanged on the workbench.

    Google has introduced Ads DevCast as a bi-weekly pilot hosted by Cory Liseno from its Advertising and Measurement Developer Relations team. Its technical scope includes Google Ads, Google Analytics, and Display & Video 360. Google is also inviting feedback while the pilot develops.

    That positioning matters. Ads Decoded, hosted by Ginny Marvin, addresses campaign strategy. Ads DevCast is intended for the people building, configuring, debugging, and governing the systems beneath that strategy. Subscribe the technical owner of your advertising stack, not only the person who manages campaigns.

    A new developer show does not, by itself, change an endpoint, schema, authentication flow, or deprecation date. Do not turn an episode into a production migration ticket merely because an idea sounds important. Use three separate lanes:

    • Discovery: Use Ads DevCast to notice technical themes, emerging capabilities, and the problems Google expects developers to encounter.
    • Verification: Confirm implementation details in the relevant official API documentation, release notes, schemas, and account controls before changing code.
    • Delivery: Create an engineering task only after you can name the affected platform, resource, operation, permission, test case, and rollback path.

    This distinction prevents two common errors. One is ignoring a directional signal until it becomes an urgent implementation problem. The other is treating a discussion of future architecture as though it were a released feature with stable production behavior.

    The agentic shift changes your control plane

    The first episode, titled “MCPs, Agents, and Ads. Oh My!”, presents an “agentic shift” in which AI agents become important users of advertising APIs. Treat that as Google’s direction of travel, not as evidence that every advertiser should give an agent unrestricted control of live campaigns.

    Model Context Protocol, or MCP, is relevant because it gives AI systems a common way to discover and invoke tools. A consistent tool interface can make an API easier for an agent to reach. It does not make the requested action correct, authorized, affordable, or reversible.

    The safest mental model is simple: the agent is a planner and operator working inside a control system. It is not the control system. A production workflow should separate intent from execution:

    1. Observe: Retrieve only the account and campaign data needed for the task.
    2. Propose: Produce a structured change showing the target resource, current value, proposed value, rationale, and expected scope.
    3. Validate: Check the proposal against the API schema, account state, internal policy, and allowed operations.
    4. Approve: Require the appropriate human or policy-based approval before any consequential write.
    5. Execute: Pass the approved action to deterministic code that calls the advertising API.
    6. Verify: Read the affected resource again, record the result, and surface any difference between the approved proposal and the final state.

    Put hard limits outside the prompt

    A prompt can tell an agent not to make risky changes. It should not be the only thing preventing them. The enforceable rules belong in the gateway between the agent and the ad platform.

    • Allowlist the accounts, resource types, fields, and operations the agent may access.
    • Use read-only access by default and grant write access per workflow rather than per agent.
    • Reject requests that omit the target account, current state, proposed state, or approval record.
    • Place budget, bid, scheduling, targeting, and deletion constraints in code or platform policy.
    • Use idempotency or equivalent duplicate protection where the operation supports it.
    • Log the request, tool call, actor, approval, API response, and resulting resource state.
    • Maintain a tested way to reverse mutable changes and a separate recovery procedure for actions that cannot be cleanly undone.

    This is a money-sensitive system. An agent with broad write access can alter live delivery before a person notices the mistake. For any action that can increase spend, narrow reach, pause revenue-producing activity, remove data, or change measurement, use a preview-and-approval flow until you have evidence that a more automated policy is safe for that exact operation.

    Turn each episode into an engineering decision

    A bi-weekly technical program can quickly become background noise unless someone owns the intake process. Give one person responsibility for converting each relevant item into a decision, including a deliberate decision to take no action.

    1. Capture the claim precisely. Write down the named product, capability, resource, or workflow. Avoid tickets such as “investigate AI for ads” because they have no testable boundary.
    2. Classify its status. Mark it as a concept, directional signal, pilot, documented capability, released change, or deprecation. Do not let enthusiasm silently upgrade its maturity.
    3. Map the affected surface. Identify whether it touches Google Ads, Google Analytics, Display & Video 360, or more than one system. Then name the relevant integration, credential, data flow, and owner.
    4. Verify implementation facts. Check the authoritative documentation for availability, supported operations, permissions, quotas, version requirements, and known limitations.
    5. Record the decision. Choose watch, prototype, adopt, migrate, or reject. Include the evidence needed to revisit that choice.

    Your decision record does not need to be elaborate. It should include the topic, status, affected system, documentation link, owner, next review trigger, test environment, approval requirement, and rollback method. That is enough to distinguish a useful technical signal from an unverified idea circulating in team chat.

    Use a prototype when the value is plausible but the operational risk is unclear. Start with a read-only workflow that answers one bounded question, then let the agent draft a change without executing it. Compare its proposal with the decision a qualified operator would make. Only after that should you test an approved write in a controlled account or environment.

    Because Ads DevCast is a pilot seeking community input, document where explanations leave an implementation gap. Useful feedback is specific: name the platform, operation, missing detail, and decision you could not safely make. That gives Google a clearer request than a general demand for more examples.

    Your ownership model must evolve with the integration

    An isometric AI advertising workflow routes action tokens through access controls, validation, human review, staging, and an audit vault while separate teams supervise their areas.

    Google is broadening the frame from a specialist Ads Developer Community toward a wider Ads Technical Community. That makes room for marketers to perform more technical work without waiting for a full development cycle. It does not erase the need for engineering ownership; it changes where the handoffs occur.

    Before connecting an agent to advertising tools, assign these responsibilities by name:

    • Business owner: Defines the campaign objective and decides which tradeoffs are acceptable.
    • Platform owner: Controls credentials, permissions, API configuration, and production access.
    • Workflow owner: Defines the agent’s tools, inputs, outputs, validation rules, and failure behavior.
    • Approver: Reviews consequential changes and has enough context to reject a technically valid but commercially poor action.
    • Incident owner: Can stop execution, assess affected resources, restore safe state, and preserve the audit trail.

    Do not collapse all five roles into “the AI team.” The business owner knows what should happen. The platform owner knows what can happen. The workflow owner controls how a request becomes an API call. The approver evaluates the actual change. The incident owner handles the moment when the system behaves differently from the plan.

    This division also makes low-code and agent-assisted work more practical. A marketer can describe or initiate a task without receiving unrestricted platform access. Engineering can provide constrained tools and reusable policies instead of implementing every request from scratch. The speed comes from a safer interface between roles, not from removing the roles.

    Key takeaways for your next working session

    • Use Ads DevCast as a technical discovery channel; verify every implementation detail in authoritative product documentation.
    • Treat Google’s agentic direction as a reason to prepare your architecture, not as permission to automate every campaign action.
    • Keep the agent focused on observation and structured proposals before granting narrowly scoped write capability.
    • Enforce permissions, spend constraints, approvals, logging, and recovery outside the model and its prompt.
    • Assign business, platform, workflow, approval, and incident ownership before connecting an agent to a live advertising account.
    • Convert each relevant update into a recorded decision: watch, prototype, adopt, migrate, or reject.

    Start with one existing Google Ads workflow that consumes too much operator time but has a clear input and output. Draw the six stages from observation through verification. Mark every place where a bad decision could affect spend, delivery, measurement, or data. Those marks define the controls your agent needs before it gets write access.

    Then build the smallest read-only version and require a structured proposal. That gives you a concrete way to evaluate Google’s agentic direction without betting a live account on an immature design.

    References


  • AI-Driven Marketing Measurement: A Practical Experiment System

    AI-Driven Marketing Measurement: A Practical Experiment System

    Your paid dashboard says efficiency is acceptable, your SEO and AEO reports show visibility moving, and the CRM says revenue is flat. You do not need another chart. You need to determine whether demand is weakening, conversion is breaking, or the measurement itself is misleading you.

    AI can shorten that investigation and help you choose the next experiment. It cannot rescue disconnected definitions, overlapping tests, or a team that has not agreed on what evidence would change a decision. The practical goal is a governed measurement loop: connect signals across the customer journey, expose uncertainty, run the least disruptive useful test, and preserve what you learn.

    Start with the decision your measurement must support

    A measurement system should begin with a decision, not a collection of available metrics. Before you connect an AI model to your dashboards, write one sentence that names the choice in front of you:

    "Should we increase, hold, redirect, or reduce this investment, and what evidence would make us change our current position?"

    That sentence forces useful specificity. It identifies the intervention, the person who owns the decision, the business outcome, the acceptable risk, and the uncertainty that needs to be resolved. Without it, AI will produce an intelligent-sounding tour of your metrics. With it, AI has an analytical job.

    Map the decision to a measurement chain rather than a single conversion number. For SEO, GEO, paid media, content, and brand campaigns, that chain usually moves through four distinct stages:

    Measurement stageQuestion it answersUseful evidenceWhat it does not prove
    Demand formationAre more relevant people becoming aware of the problem and your brand?Non-brand discovery, visibility in relevant AI answers, brand mentions, branded search interest, and engagement from the intended audienceThat marketing caused revenue
    Demand captureAre interested people entering and progressing through an owned journey?Relevant landing-page visits, return visits, form starts, content progression, and response to calls to actionThat the captured demand is incremental
    Commercial progressionAre the right prospects becoming viable sales opportunities?Qualified leads, sales acceptance, opportunity creation, stage movement, and account-level engagementThat a particular platform deserves all the credit
    Business outcomeIs the activity producing commercial value?Pipeline, revenue, retention, margin, or another agreed business resultWhich intervention caused the difference

    This separation matters when the lower funnel looks weak. A decline in remarketing conversion may appear to justify a budget cut. But if non-brand acquisition has slowed, competitors are gaining visibility, and fewer new qualified visitors are entering the journey, remarketing may be displaying an upstream demand problem rather than causing it. Looking across systems can reveal that the apparent channel failure is really a missing layer of demand creation.

    Use four evidence labels consistently: observed, attributed, associated, and incremental. An observed change is simply present in the data. An attributed result received credit under a platform or analytics rule. An associated result moved alongside another signal. An incremental result is the difference that would not have occurred without the intervention, supported by a suitable experimental comparison. AI should never silently promote evidence from one level to another.

    This is especially important for AI-search measurement. A citation or brand mention in a relevant answer is an upstream visibility signal. Branded search, direct visits, and assisted engagement can provide additional evidence. CRM outcomes show commercial progression. These signals belong in the same chain, but placing them next to one another does not make the first one the proven cause of the last one.

    Build a measurement spine before adding an AI agent

    Four abstract marketing signal streams connect through calibrated gateways to a shared central measurement backbone and decision chamber.

    AI does not remove data silos merely because it can read several exports. If web analytics, Google Search Console, brand monitoring, advertising platforms, and the CRM use different campaign names, conversion definitions, timestamps, and identity rules, the model will automate the disagreement.

    A measurement spine is the small set of shared definitions and identifiers that connects those systems. It does not require every tool to become one giant database. It requires each system to describe the same business events consistently enough that evidence can be reconciled.

    Create a measurement contract for every metric that can affect a budget or campaign decision. Record:

    • The canonical metric name and plain-language definition.
    • The business question the metric is allowed to answer.
    • The system of record when platforms disagree.
    • The unit represented by each row, such as a person, account, session, campaign, opportunity, or transaction.
    • The event timestamp, reporting timestamp, timezone, and currency rules.
    • The identifiers used to join campaign, content, account, and revenue data.
    • Inclusion and exclusion rules, including internal traffic, duplicates, test records, and disqualified leads.
    • The expected update cadence and how stale data is marked.
    • Known coverage gaps and changes in tracking.
    • The experiment identifier and exposure status when a test is active.

    Keep the original channel-native value alongside the canonical value. A platform conversion can still be useful for platform optimization even when finance uses a different revenue definition. Preserving both prevents a clean warehouse field from erasing the context needed to explain a discrepancy.

    Identity resolution also needs restraint. Join data at the least sensitive level that can answer the decision. An account-level key may be sufficient for a B2B pipeline question; a campaign or content identifier may be sufficient for a visibility question. Do not send raw personal information, credentials, or unrestricted customer records to an AI system. Use an approved environment, restrict access, and provide only the fields required for the analysis.

    Put a data-quality gate in front of every AI analysis. The gate should ask:

    • Did all expected systems update for the reporting period?
    • Do totals reconcile with the designated systems of record?
    • Are joins dropping or duplicating campaigns, accounts, opportunities, or revenue?
    • Are timestamps, currencies, attribution windows, and conversion definitions aligned?
    • Did a tag, consent rule, CRM stage, platform setting, budget, or campaign structure change?
    • Did another experiment expose the same audience during the same period?

    If a check fails, the correct AI output is "analysis blocked" or "result qualified," not a plausible estimate inserted into the gap. Missing data is a measurement state. Hiding it turns uncertainty into false precision.

    Use AI as a governed analyst, not the final judge

    Once the measurement spine is reliable, AI is useful for work that is tedious, cross-channel, and easy to perform inconsistently. Give it bounded analytical jobs:

    • Reconcile channel, site, search, brand, CRM, and revenue signals around one decision.
    • Flag divergences, such as improving click efficiency alongside declining new-audience reach or qualified pipeline.
    • Audit experiment history for repeated variables, inconclusive tests, audience collisions, platform resets, and unexamined failures.
    • Convert a business question into candidate hypotheses with an explicit mechanism and predicted direction.
    • Rank proposed tests by risk, learning value, and operational feasibility.
    • Monitor declared primary and guardrail metrics without changing the test autonomously.
    • Draft a result summary that distinguishes measured facts, interpretations, data gaps, and recommended follow-up.

    Require a fixed response structure from the model. Each analysis should return the decision being supported, evidence for and against the current hypothesis, conflicting signals, data-quality limitations, plausible alternative explanations, the smallest useful next test, operational risk, and a confidence label. This makes the output reviewable and discourages a polished narrative built around whichever metric happened to move.

    Keep human approval at three boundaries: choosing what the business is willing to risk, authorizing changes to live campaigns, and deciding whether evidence is strong enough to scale. Start with read-only AI access. A model that detects a CPA spike can recommend an interruption review; it should not rewrite budgets unless you have deliberately built and validated that authority.

    AI also needs explicit causal limits. Attribution models distribute credit according to configured rules. Cross-system analysis identifies patterns and likely failure points. A controlled experiment estimates what changed because of an intervention. These are different jobs. A model can help design or analyze the experiment, but it cannot manufacture the missing counterfactual from an ordinary dashboard.

    Synthetic audiences can screen messaging before real-world exposure. Use them to identify confusing language, obvious positioning conflicts, or persona-specific objections. Do not use simulated preference as proof of demand, conversion lift, or market response. It is a filter for weak candidates, not a substitute for observed behavior.

    Run fewer experiments with cleaner isolation

    A researcher observes two isolated test chambers where one colored light is the only visible difference between otherwise identical setups.

    The best next experiment is not the most creative one. It is the test that resolves an important uncertainty without exposing the business, the brand, or the platform algorithm to unnecessary disruption.

    Write the hypothesis before producing variants. Use this structure:

    "Among the eligible audience, changing this defined variable should move this primary outcome in the predicted direction because of this mechanism. We will advance, reject, or classify the result as inconclusive under the prewritten decision rule, provided the guardrail metrics remain acceptable."

    The mechanism is the most valuable part. "Test a new headline" names an activity. "Emphasize faster time-to-value because the intended buyer appears to prioritize speed over ease of use" names an idea that can be supported, weakened, or refined. Even a losing test can improve future decisions when the mechanism is explicit.

    Every test card should identify the decision owner, eligible population, assignment unit, control and treatment, variable being changed, primary outcome, guardrail metrics, planned analysis window, completion rule, interruption rule, conflicting campaigns, and platform changes that could invalidate interpretation. If one of these fields cannot be filled in, the test is not ready.

    Next, score operational risk against learning value. Useful dimensions include budget impact, algorithm disruption, audience overlap, brand sensitivity, and the value of the expected learning.

    Learning valueOperational riskDefault decision
    HighLowPrioritize and run with the normal controls.
    HighHighReduce exposure, pre-test the risky element, isolate the audience, or use a stronger control.
    LowLowBacklog it unless it is exceptionally cheap and does not interfere with a more valuable test.
    LowHighReject it. Activity does not justify disruption.

    Guardrails should be written before anyone sees a result. As illustrations, a team might reserve 10% of a budget for experimentation and define an interruption review if CPA deteriorates by more than 15% across five days. Those are examples, not universal defaults. Your limits must reflect margins, conversion volume, cash constraints, brand exposure, and the normal volatility of the channel.

    Your guardrail document should cover the testing budget, maximum acceptable performance deterioration, platform-specific reset conditions, tracking failures, audience contamination, early warning signals, and brand boundaries that cannot be crossed. Give the same document to the AI system that proposes and monitors experiments. Otherwise, the model is optimizing without knowing what the business considers unacceptable.

    Sequence tests so that each one answers a recognizable question. If you change the audience, creative concept, offer, landing page, and budget together, a better result does not reveal which change mattered. Start with the lowest-risk environment that can reject a weak idea. A positioning claim might be screened with synthetic personas, then observed in an organic setting, then tested in a controlled paid environment. Evidence from each stage determines whether the next exposure is justified.

    When a live test begins, protect its isolation. Avoid overlapping experiments on the same eligible audience. Hold the major variable families steady. If simultaneous changes are unavoidable, preserve a credible control group and record every collision. Do not let an AI agent quietly "improve" a weak variant halfway through the run; that creates a new treatment and compromises the original comparison.

    Platform stability is part of experiment cost. Significant changes to creative, audience, campaign structure, or budget can restart learning and cloud the result. Ad sets that remain in a learning phase have been associated with CPAs 20%-40% above those of stable ad sets, though the effect in your account may differ. Multiple overlapping resets can therefore make the whole account look worse, even when none of the ideas being tested is inherently bad.

    Prewrite both completion and interruption rules. Do not stop merely because an early reading looks attractive or uncomfortable. Interrupt when a declared safety, brand, tracking, or financial boundary is crossed. Otherwise, allow the planned evidence to accumulate and classify the outcome honestly as a supported win, supported loss, inconclusive result, or invalidated test.

    Turn every result into reusable measurement memory

    A completed experiment should change more than the current campaign. It should improve the quality of the next hypothesis, reduce repeated mistakes, and help a future analyst understand why a decision was made.

    Store one durable record for every launched test, including:

    • An immutable experiment identifier and the decision it supported.
    • The hypothesis, proposed mechanism, and expected direction.
    • The audience, channel, content, creative, offer, and landing experience involved.
    • The assignment method, control, treatment, and exposure rules.
    • The primary outcome and guardrail metrics.
    • Tracking changes, platform resets, audience overlap, and other anomalies.
    • The result, evidence label, confidence assessment, and unresolved uncertainty.
    • The decision made, responsible owner, and next test if one is warranted.
    • Any later check showing whether the effect persisted, weakened, or disappeared.

    Link every AI-generated interpretation back to the underlying experiment record, query, or dashboard view. The summary is a navigation layer, not the evidence itself. A future reviewer should be able to trace "speed messaging worked" to the precise audience, outcome, comparison, and limitations. Otherwise, a narrow result will gradually become an unsupported company-wide belief.

    Before approving a new test, ask AI to search this memory for similar mechanisms, audiences, and variables. It should identify repeated low-value ideas, apparent failures that were actually inconclusive, results compromised by volatility, and interactions worth examining. The output should recommend the smallest remaining uncertainty, not simply generate another batch of variants.

    This memory also helps you respond intelligently when leading and commercial indicators move at different speeds. If upstream visibility and qualified engagement improve while pipeline remains flat, keep the claims narrow: demand signals are strengthening, but commercial impact is unproven. Check the next handoff and any expected reporting lag before scaling. If every stage suddenly declines, verify tracking and joins before rewriting strategy. If only the platform deteriorates during several overlapping tests, investigate resets and audience contamination before declaring that demand has vanished.

    Integrated measurement is valuable because it shows where momentum may be forming and where the chain is breaking. It is not a license to claim causality from a synchronized chart. The discipline is to act on leading evidence with bounded exposure, then require stronger evidence before making a larger commitment.

    Key takeaways

    • Begin with a budget, campaign, or positioning decision and define what evidence would change it.
    • Connect demand, capture, commercial, and revenue signals through shared definitions and identifiers.
    • Use AI to reconcile evidence, expose uncertainty, audit test history, and propose the smallest useful experiment.
    • Keep causality labels, live-campaign authority, sensitive data, and acceptable risk under human control.
    • Sequence experiments, protect controls, record platform resets, and reject tests whose disruption exceeds their learning value.
    • Preserve every result in a traceable knowledge base so future tests start from accumulated evidence rather than memory.

    Your next move is to choose one live marketing decision and build its measurement chain. Give AI the definitions, guardrails, historical tests, and permission to identify the single uncertainty blocking that decision. Then run the cleanest affordable experiment that can resolve it. If the proposed test cannot explain what you will do differently after each possible result, do not launch it.

    References

  • Agentic AI for E-commerce: A Leadership Operating Plan

    Agentic AI for E-commerce: A Leadership Operating Plan

    If your leadership team is asking whether agentic AI will make product pages, search traffic, or brand marketing obsolete, the useful answer is no. That is not a reason to wait. The practical change is that more discovery, comparison, filtering, and execution can move into software acting for the shopper.

    You need an operating plan that makes your products easy for both people and machines to understand, verify, and select. You also need measurement that remains honest when part of the buying journey happens beyond your analytics. Here is how to build both without reorganizing the company around an adoption curve nobody can forecast precisely.

    Key takeaways

    • Agentic commerce adds a software decision layer between customer intent and commercial execution. It does not remove the customer or the need to earn trust.
    • Your central readiness question is no longer only whether a product can rank. It is whether the product is eligible to survive a constraint-based selection process.
    • Eligibility depends on complete, consistent product facts, dependable price and availability data, clear policies, technical accessibility, and a transaction path that works.
    • JSON-LD and other machine-readable formats should publish canonical business facts, not compensate for contradictions between your systems.
    • SEO, merchandising, engineering, operations, customer experience, and analytics need named ownership. Agent readiness cannot sit entirely inside the marketing team.
    • Exact attribution will become less reliable as more evaluation happens inside AI systems. Measure readiness directly and interpret commercial outcomes directionally.

    Reframe the agent as a customer proxy

    In this context, agentic AI means software can carry part of a task forward from a person’s intention. The shopper still supplies the need, preferences, budget, and acceptable trade-offs. The software interprets those constraints, investigates options, narrows the field, and may take an action on the shopper’s behalf.

    Consider the difference between a shopper searching for running shoes and a shopper asking for a pair that fits a particular use, budget, size, delivery requirement, and material preference. A traditional search journey requires the person to open results and resolve those constraints manually. An agent can turn the same request into a filtering job before the shopper reaches a product page.

    A useful leadership model separates the journey into distinct decisions:

    • The person defines the desired outcome and acceptable constraints.
    • The agent interprets those constraints and identifies possible candidates.
    • Your published product and business data determine whether your offer can be understood and qualified.
    • Trust signals, policies, and commercial reliability help the agent distinguish between otherwise suitable candidates.
    • Your commerce systems determine whether the selected action can be completed successfully.

    This model changes the executive question. Instead of asking, ‘Will agents replace our customers?’, ask, ‘At which decision could incomplete or unreliable information remove us from consideration?’

    Rankings still matter because agents need candidates to evaluate. They are no longer a sufficient definition of success. A highly visible offer can still be filtered out if its suitability is unclear, its current price cannot be trusted, or its policies create unresolved risk. A lower-profile offer may remain eligible because it answers the request more precisely.

    The transition will not move at the same speed in every market. Categories with standardized products and organized data are easier for software to evaluate. Complex purchases and categories with regulatory constraints introduce more ambiguity. Treat adoption as gradual and category-dependent, then set investment levels for your own selection conditions rather than following a general hype cycle.

    The earliest pressure is likely to appear in discovery and consideration. Natural-language requests can carry far more context than short category queries, while software can perform the initial comparison without exposing every intermediate step. That weakens the assumption that owning a broad head term guarantees access to the consideration set.

    It also changes the job of content. A page should not merely attract a click or repeat a category phrase. It should resolve the variables that determine fit: what the product is, whom it serves, where it does not fit, what it costs, whether it is available, what conditions apply, and why the claims are credible.

    Audit the selection chain, not just the search result

    A glowing software agent passes generic products through several visual filtering and verification stages before making a final selection.

    Eligibility is not an official score supplied by an AI platform. It is a management lens for identifying the facts and systems that must work before an offer can be selected confidently. That makes it more useful than a vague goal such as ‘be ready for agents.’

    Selection stageQuestion the system must resolveEvidence to inspect
    IdentityWhat exactly is being offered?Canonical product name, identifiers, category, variant relationships, and consistent descriptions.
    SuitabilityDoes the offer satisfy the shopper’s constraints?Category-specific attributes, compatibility, dimensions, use conditions, exclusions, and variant-level facts.
    Commercial truthWhat will the shopper pay, and can the item be obtained?Current price, availability, offer conditions, and agreement between public surfaces and commerce systems.
    Trust and riskWhat uncertainty comes with choosing the offer?Clear return terms, restrictions, warranties where relevant, evidence for claims, and consistent policy language.
    ExecutionCan the intended action be completed reliably?Working product and checkout paths, accurate inventory state, dependable payment handling, and technical availability.

    Do not begin this audit with a new AI tool. Begin with a representative product family and a realistic, constraint-rich shopping request. The request should contain the kinds of conditions that would change the answer, not merely the category name.

    1. Write down the product facts, offer conditions, and policies required to answer the request without guessing.
    2. Identify the authoritative system and accountable owner for each fact.
    3. Trace the fact through every surface that publishes it, including the product page, product feeds, structured data, inventory displays, policy pages, and checkout where relevant.
    4. Mark each fact as present and consistent, absent, contradictory, stale, or technically inaccessible.
    5. Repair the authoritative value or propagation path rather than editing one visible symptom.
    6. Republish the affected surfaces and repeat the same shopping request to confirm that the ambiguity has actually disappeared.

    Prioritize contradictions before polishing optional copy. A missing secondary detail may narrow your eligibility for a particular request. Conflicting price, availability, variant, or policy information can undermine confidence in the entire offer. Dynamic facts deserve particular attention because a value that was correct when published can become wrong when updates fail to propagate.

    JSON-LD belongs in this chain, but it is a publication layer rather than a separate version of reality. If your visible page, feed, structured data, and backend expose different values, adding more markup gives the system another conflicting claimant. Define the canonical fact, define which system owns it, and make every machine-readable representation inherit from that source wherever your architecture allows.

    Your audit record should preserve the shopping request, required constraints, expected eligible products, retrieved facts, contradictions, remediation owner, and retest result. That turns agent readiness into a repeatable quality process instead of a collection of screenshots from impressive demonstrations.

    Build agent readiness into normal commerce ownership

    A cross-functional commerce team coordinates product information, inventory, fulfillment, analytics, and customer experience around a shared digital product model.

    Agentic selection crosses organizational boundaries because the deciding signals do. Marketing can improve discovery, but it cannot independently correct an inventory state, repair checkout, define a returns policy, or decide which product database is authoritative. Machine-readable trust depends on technical and operational integrity as much as promotional visibility.

    Assign the fact, the path, and the control

    Team names will vary, but the accountability cannot remain vague. Use the following division as a starting point:

    WorkstreamQuestion it should ownEvidence leadership should request
    Merchandising or product dataWhich attributes and variant relationships are authoritative?A documented source for selection-critical product facts and a queue of unresolved data defects.
    Commerce operationsAre price, availability, and offer conditions current?Exception reporting for mismatches and a defined response when updates fail.
    EngineeringCan machines reliably retrieve the same facts customers see?Healthy publication paths for pages, feeds, structured data, inventory, payment, and checkout.
    SEO, AEO, and GEOWhich intents and constraints determine eligibility, and where is ambiguity visible?Constraint maps, crawl and rendering findings, content gaps, and cross-surface consistency checks.
    Customer experience and policy ownersCan a buyer resolve risk without interpretation or conflicting language?Explicit policy terms, known ambiguity cases, and a path for correcting recurring questions.
    AnalyticsWhat can be observed directly, and what can only be inferred?Metric definitions that separate readiness, observable behavior, commercial outcomes, and unknowns.
    Executive sponsorWho resolves ownership conflicts and approves contingent investment?A prioritized defect register, decision gates, and accepted limits on attribution.

    Attach this work to an existing digital commerce, merchandising, or operational review. A separate agentic AI committee will not help if it lacks authority over product truth and commerce systems. The standing agenda can remain short: which selection-critical defects appeared, which source owns them, which customers or products are exposed, and whether the repair survived retesting.

    Change the content brief from attention to resolution

    Traditional consideration content often accumulates reviews, comparisons, benefit claims, and reassurance. Those assets still have value, but an agent can turn consideration into a strict filtering exercise. Content must therefore make fit and evidence easy to extract, not merely make the page persuasive.

    • State who and what the product is for, including meaningful limitations and exclusions.
    • Use stable terminology for the same attribute across product copy, specifications, feeds, structured data, and policies.
    • Keep claims close to their supporting evidence. Avoid vague superiority language that cannot help resolve a constraint.
    • Put selection-critical facts on the canonical page where they belong instead of scattering answers across thin supporting pages.
    • Make comparisons explicit about the condition that changes the recommendation. Not every product should appear to be the best option for every buyer.
    • Review policy language as decision data. A policy that requires interpretation leaves a risk variable unresolved.

    This favors content quality over page volume. If the answer already belongs on a product or category page, repair that page rather than publishing another near-duplicate merely to target a longer query. The goal is a coherent representation of the offer across every surface an agent may use.

    There is also a brand consequence. Software may filter and select products before a shopper becomes familiar with every candidate. That can improve conversion while weakening brand recognition. Preserve clear brand identity in the product facts and trust signals likely to travel with the offer, and continue building familiarity beyond search. A trusted brand gives both the shopper and the software fewer unresolved reasons to reject the choice.

    Measure readiness honestly and stage your investment

    Agentic journeys make precise attribution harder because more evaluation can happen inside an external AI system. Fewer visible page interactions do not automatically mean your optimization failed, just as a conversion cannot automatically prove that an agent caused the outcome. Leadership should expect directional indicators and blended performance to carry more weight than a perfectly reconstructed path.

    Use a layered scorecard

    Start with measures your business can observe and control:

    • Critical-fact completeness: the share of in-scope products with every attribute required for the tested shopping requests.
    • Cross-surface agreement: whether product pages, feeds, structured data, inventory displays, policies, and checkout expose the same current facts.
    • Update propagation: how reliably a canonical change reaches each public surface, and where stale values persist.
    • Technical availability: whether the relevant content and transaction paths can be retrieved and completed without an avoidable failure.
    • Policy ambiguity: unresolved cases in which offer conditions or customer protections conflict or require interpretation.

    Then place behavioral and commercial indicators beside those readiness measures:

    Leadership questionUseful indicatorWhat it cannot prove
    Are our offers becoming easier to qualify?Improved completeness, consistency, accessibility, and retest results for priority product families.That a specific AI system selected the offer.
    Can we see agent-associated visits?Identifiable referral or journey evidence where analytics exposes it.The total volume of agent influence, because many intermediate decisions may remain hidden.
    Are repaired journeys performing better?Product-family conversion, completion, cancellation, and other relevant outcome trends interpreted with the defect history.That the repair alone caused the change.
    Is the business gaining selection without losing recognition?Blended commercial performance considered alongside branded demand and returning-customer behavior.Exact credit for any single search, content, brand, or agent interaction.

    Report observation, inference, and unknowns separately. ‘The price mismatch was removed and the affected family improved’ is an observation followed by a correlation. ‘Agents generated the improvement’ is a causal claim that requires evidence you may not possess. This distinction protects the budget conversation from false precision.

    Separate foundation work from contingent bets

    The most defensible investments help current customers and current commerce operations even if agent adoption is slower than expected. Approve work that improves product information, removes contradictions, clarifies policies, strengthens technical reliability, or fixes price, inventory, payment, and checkout defects. These changes reduce uncertainty regardless of which interface initiates the purchase.

    Run controlled experiments for questions your analytics cannot answer yet. Reuse realistic shopping requests, record the expected eligibility conditions before testing, and preserve failures as well as successes. A demonstration is useful for discovering defects; it is not enough evidence for a large strategy change.

    Keep bespoke integrations, major budget reallocations, and platform-dependent builds behind explicit decision gates. Before approving one, ask whether the business controls the required data, whether a recurring failure or opportunity has been observed, whether the dependency is stable enough to support the investment, and whether the work remains valuable if adoption develops differently.

    This avoids the two expensive extremes: making sweeping changes because a demonstration looks inevitable, or ignoring agentic behavior until commercial performance forces a rushed response. The practical middle is to repair known eligibility weaknesses now and reserve harder-to-reverse bets for evidence that justifies them.

    At your next operating review, put a real product family and a real constraint-rich shopping request on screen. Trace every fact a shopper’s proxy would need, name the owner of each contradiction, repair the problem at its source, and retest the same request. You will make the business easier to select now without pretending anyone knows the final shape or pace of agentic commerce.

    References

  • Publisher Strategy for Content Markets on the Agentic Web

    Publisher Strategy for Content Markets on the Agentic Web

    An AI agent can use your reporting to answer a question, recommend a product, and help complete a task without sending the user to your page. If your publishing model treats every machine interaction as a future click, you may be assigning value to an event that never happens.

    You do not have to choose between unlimited reuse and disappearing from AI discovery. The practical job is to separate access, interpretation, permission, attribution, and payment. Once those decisions are explicit, you can pursue visibility without quietly giving every commercial use the same terms.

    When the answer performs the task, the traffic bargain weakens

    The agentic web is more than a search box with longer answers. An agent can interpret a person’s intended outcome, gather information, coordinate with other systems, request consent where needed, and take an action. That progression from expressed intent to an outcome changes where publisher content creates value.

    QuestionSearch-led webAgentic webPublisher implication
    What does the user provide?A query to investigateA goal the agent can interpretContent must support decisions, not merely match keywords
    How is information gathered?The user opens and compares pagesThe agent can retrieve and combine relevant materialA page may contribute value without receiving a visit
    Where does the decision happen?Mostly on publisher, merchant, or service pagesPartly inside the agent’s reasoning and recommendation layerQualifications and provenance must survive extraction
    How can an action follow?The user moves between sites and completes each stepThe agent can coordinate systems with the user’s permissionAccurate operational details become as important as persuasive copy
    How can the publisher benefit?Referrals, advertising, subscriptions, leads, or salesThose outcomes may remain, but licensing, attribution, and measured usage can also matterTraffic alone is no longer a complete value model

    The old exchange was easy to understand: a platform discovered a page, displayed a link, and sent some users to it. AI answers can compress that journey. They may rely on a publisher’s work while satisfying the user before a click occurs. That does not make traffic irrelevant. It means traffic, content use, and commercial value can separate.

    Keep these layers distinct in your strategy:

    • Access: Can an agent retrieve the content through a public page, authenticated archive, feed, API, or licensed system?
    • Interpretation: Can it reliably identify the entities, claims, dates, qualifications, and relationships on the page?
    • Permission: What may the operator do with the content, in which products, for which purposes, and for how long?
    • Attribution: Will the output identify the publisher, author, and canonical page in a form the user can follow?
    • Compensation: What event creates payment, how is that event measured, and what reporting lets you verify it?

    A crawl directive addresses access. JSON-LD can improve interpretation. Neither one, by itself, grants a commercial license or establishes a price. A licensing agreement cannot rescue content that is too ambiguous or stale for an agent to use safely. Treating these controls as interchangeable is how publishers either expose too much or block more than they intended.

    The distinction becomes more consequential when agents influence purchases, finance, or healthcare. In those settings, trusted inputs can shape decisions rather than merely inform browsing. If you publish high-stakes material, keep eligibility conditions, uncertainty, audience limits, and safety qualifications adjacent to the claim they modify. A caveat placed several paragraphs away may disappear when an answer system extracts only the central sentence.

    Turn your archive into rights-aware content inventory

    Hands organize articles, photographs, audio, video, and research files into an archive with distinct visual markers for permissions and provenance.

    Do not begin marketplace evaluation with a sitewide yes or no. Begin with an inventory. Most publishing archives contain a mixture of original work, syndicated material, commissioned assets, contributor content, licensed data, outdated pages, and material governed by different agreements. A single technical switch cannot represent those differences.

    Create a rights and readiness ledger at the page or collection level. Record:

    • The canonical URL, content identifier, current version, publication date, and latest substantive update.
    • The publisher, author, contributor, data provider, photographer, illustrator, and any other party whose rights may be involved.
    • Whether the text, images, tables, audio, video, and underlying data can be licensed for the contemplated use.
    • The topic, named entities, geography, audience, and decision context the content supports.
    • The editorial method, evidence trail, and qualifications an agent would need to preserve.
    • The person or team responsible for corrections, expiry decisions, and future updates.
    • The permitted products and uses, prohibited uses, attribution requirements, and withdrawal process.
    • The commercial role of the content: audience acquisition, advertising, subscription retention, lead generation, direct sales, or licensing.

    If a contributor agreement or third-party license does not clearly cover the proposed AI use, stop at that item and get qualified legal review. Marketplace enrollment should not become the event that silently resolves an ambiguous right. The downside can include licensing material you do not control or accepting obligations that conflict with an existing agreement.

    Once the ledger exists, place content into practical access classes:

    • Open for discovery: Public material you want search engines and answer systems to find, summarize within acceptable limits, and cite back to you.
    • Eligible for commercial licensing: Material you control and are willing to provide for defined products, use cases, reporting, attribution, and payment terms.
    • Restricted or excluded: Content with unclear rights, private information, contractual limits, unacceptable substitution risk, unresolved accuracy issues, or no reliable update owner.

    This segmentation lets you test a controlled collection without packaging the entire archive. It also improves negotiation. You can describe what makes a collection distinctive, how it is maintained, which decisions it supports, and what a licensee must do when it changes.

    Length is not a useful proxy for licensing value. A long generic explainer may add little to an agent that already has abundant coverage. A concise specialist archive, original reporting stream, maintained reference set, or decision-grade dataset may be harder to replace. Ask what the content contributes that a model cannot safely infer from generic material.

    Paywalled and secured archives deserve separate attention. High-quality material in those systems may be unavailable to open-web retrieval, which is part of the rationale for licensed access to premium publisher content. That does not mean every paywalled page should be licensed. Compare the potential licensing return with the subscription, exclusivity, and audience value the same material already creates.

    Use a simple value test for each candidate collection. Can you establish the rights? Is the information meaningfully differentiated? Can an agent preserve its important qualifications? Can you keep it current? Would agent use create incremental value, or mainly replace a paid interaction you already own? If you cannot answer those questions, the collection is not ready for pricing.

    Evaluate a content marketplace by its terms and evidence

    Three transparent marketplace mechanisms are inspected side by side for content tracking, attribution, payment, and audit trails.

    Microsoft’s Publisher Content Marketplace offers an early model for a more direct exchange. Its stated design lets publishers set licensing and usage terms, lets AI developers discover content for grounding, and provides usage reporting intended to show how licensed material contributes. The marketplace is also designed to reduce reliance on separate one-off deals.

    Those are useful design principles, but a marketplace description is not the contract you will sign. Participation is presented as voluntary, with publishers retaining ownership and editorial independence. Confirm how each promise appears in the actual agreement, technical controls, reporting fields, and withdrawal procedure.

    Define the licensed use precisely

    The label AI licensing is too broad for a commercial decision. Ask:

    • Does the license cover run-time retrieval and grounding, model training, fine-tuning, evaluation, embeddings, caching, synthetic outputs, or only a defined subset?
    • Can the system use full text, excerpts, facts, media assets, metadata, or structured data? Do different asset types receive different treatment?
    • Which named products, developers, customers, affiliates, or subcontractors can use the material?
    • What territories, languages, audiences, and use cases are included?
    • How long may content and derived representations be retained after an update, withdrawal, or termination?
    • Can rights be sublicensed, bundled, transferred, or used in a product category you would not approve directly?

    Have counsel review the language against your contributor, syndication, data, image, and customer agreements. A marketplace can reduce transaction overhead; it cannot make an overly broad license safe.

    Make attribution and correction operational

    Attribution should be testable, not ceremonial. Specify whether an output displays the publisher name, author where relevant, content date, and a clickable canonical URL. Ask where attribution appears when several publishers contribute to one answer and whether it remains visible when the agent completes a task rather than showing a research-style response.

    Then test the correction path. Who receives a publisher correction? How quickly can an updated version replace the prior one? Are cached passages and generated summaries refreshed? Can the publisher flag a dangerous misrepresentation? What evidence shows that withdrawal reached participating products? These controls matter most for content whose advice changes, expires, or carries material qualifications.

    Interrogate the unit called usage

    A promise of usage-based revenue is incomplete until usage has a definition. It could refer to content retrieval, inclusion in a grounding set, contribution to an answer, a displayed citation, an agent-assisted transaction, or another event. Each unit values the publisher differently.

    Request the reporting schema and a representative record before agreeing to pricing. Determine whether reports identify the content item, version, product, use type, time, geography, citation outcome, and payment calculation. Ask how value is assigned when several items or publishers contribute to the same output. Establish how disputed records, invalid activity, reporting errors, and delayed data are handled.

    Detailed reporting is part of the proposed content-marketplace value exchange. Its usefulness depends on whether you can reconcile the report with your catalog and commercial terms. A total usage number without content-level identity will not tell you which collection deserves more investment, which page needs an update, or whether the payment is correct.

    Protect your ability to change course

    Confirm that you can exclude individual assets or collections, reject sensitive use cases, update prices and terms, correct content, and withdraw future access. Examine exclusivity, renewal, termination, post-termination retention, confidentiality, and conflicts with direct licensing deals. If editorial independence matters, identify the specific contractual and product controls that protect it.

    Early PCM activity included co-design work with Business Insider, Conde Nast, and Hearst, pilots that grounded Microsoft Copilot responses in licensed content, and Yahoo as an early adopter. That demonstrates real industry experimentation. It does not yet establish a universal price, reporting standard, publisher return, or optimal deal structure.

    Use a decision model rather than the size of the marketplace logo. Consider net expected value as licensing revenue, retained audience value, useful market intelligence, and strategic access, minus substitution risk, rights exposure, operational cost, and any value lost from conflicting deals. The expression is an agenda for due diligence, not a precise forecast. If a proposed agreement cannot provide the inputs, that uncertainty belongs in the decision.

    Make content agent-ready without flattening it for machines

    Licensable content can still be difficult to use. An agent needs to determine what a passage claims, which entity it concerns, when it was valid, who stands behind it, and which qualification changes its meaning. Your AEO and GEO work should make those elements easier to identify while preserving the page’s value for a human reader.

    Use this editorial and technical checklist:

    • State the decision-grade answer early. Give the reader the direct answer, rule, or distinction before expanding the reasoning.
    • Attach scope to the claim. Keep audience, geography, version, date, eligibility, and uncertainty in the same sentence or adjacent sentence. Do not strand a critical exception in a distant footnote.
    • Use descriptive headings. A heading should identify the question being resolved, not merely label a broad theme.
    • Expose provenance. Show authorship, editorial ownership, source or methodology information, publication date, substantive update date, and a correction route where appropriate.
    • Name entities consistently. Stable names and identifiers reduce the risk that an agent merges different people, products, organizations, places, or versions.
    • Maintain a canonical identity. Syndicated, translated, updated, and feed versions should point back to a stable record your internal catalog can also recognize.
    • Keep structured data truthful. JSON-LD should describe what is visibly present and should use the most specific accurate type. It should not convert an editorial judgment into a fact or imply an offer the page does not make.
    • Publish corrections as data, not only prose. Update the visible page, version record, feed, API, and licensing catalog so downstream systems do not continue receiving the superseded material.
    • Separate volatile facts from durable analysis. Prices, availability, eligibility, and similar operational facts need a clear update owner; the surrounding explanation can remain stable.
    • Preserve a human reading path. Concise answer blocks are useful, but they should lead into evidence and judgment rather than turn the page into disconnected fragments.

    Apply an extraction test to every important passage. Read the sentence by itself. Can you tell what is being claimed, whom it applies to, when it applies, and what would make it false or unsafe to act on? If the answer changes when the surrounding paragraph disappears, move the necessary qualifier closer.

    Schema helps with interpretation, not truth, authority, access, or permission. A technically valid graph cannot establish that your evidence is sound, that you own every asset, or that an agent has accepted your license. Keep editorial review, rights management, delivery controls, and structured data connected, but do not collapse them into one SEO task.

    Feeds and APIs can give licensed systems a cleaner way to receive content, identifiers, versions, and updates. APIs are also important connective tissue in the agentic environment, where separate systems must coordinate. If you offer a machine-readable delivery surface, document its fields, version behavior, correction process, authentication, permitted uses, and relationship to the canonical page. Delivery access should enforce the agreement rather than leave its boundaries to guesswork.

    Commerce publishers should also distinguish exploration from execution. The Agentic Commerce Protocol focuses on actions arising from express user intent, while the Universal Commerce Protocol addresses the wider shopping experience across platforms and payment systems. They support different stages of the journey rather than serving as simple substitutes. Product content therefore needs to support both evaluation and action: editorial recommendations require evidence and scope, while transactional facts require current, unambiguous fields.

    A brand-owned assistant can provide another route to the same material. It can operate with first-party information, a controlled editorial voice, and a clear point of accountability. That will not eliminate the need to appear in external agents, but it gives loyal users a place to ask questions within an environment you govern. Treat it as owned distribution, not merely a chatbot feature.

    The design tension is real: publishers need content that AI systems can understand without making the human page feel as if it was written for a parser. The answer is not machine-first prose. It is precise prose with visible evidence, stable entities, useful structure, and qualifications that survive reuse.

    Key takeaways for your next licensing decision

    • Separate retrieval, interpretation, permission, attribution, and compensation. Each requires a different control.
    • Inventory rights and update responsibilities before offering an archive. Exclude anything you cannot confidently license or maintain.
    • Segment public discovery content, commercially licensable collections, and restricted material instead of applying one policy to the whole site.
    • Define whether a deal covers grounding, training, caching, generated outputs, or other uses. Do not accept AI use as a sufficient definition.
    • Require content-level reporting that connects a use event to the licensed item, version, product, attribution outcome, and payment calculation.
    • Optimize pages for clear extraction, provenance, freshness, stable identity, and attached qualifications. Do not expect JSON-LD to manufacture authority or grant rights.
    • Preserve correction, exclusion, and withdrawal controls, especially for changing or high-stakes information.
    • Measure licensing revenue alongside referrals, subscriptions, leads, sales, citations, and substitution effects. A single visibility score cannot represent the whole exchange.

    Establish a baseline before making a collection available. Record the referrals, subscriber starts, leads, commerce outcomes, citations, and direct revenue the eligible material already supports. After licensing begins, compare those outcomes with licensed retrieval or grounding activity, attributed mentions, payments, correction latency, and operational cost. Usage reports can help reveal where content contributes value, but only if you can join them to your own content identifiers and business data.

    Do not interpret every decline in referrals as failure if a measured licensing return or higher-value action replaces it. Do not call licensing revenue incremental when the same use displaces subscriptions, direct deals, or profitable visits. Review the collection as a portfolio, then inspect individual items when aggregate results hide winners, stale assets, or damaging substitution.

    Your next move should be a controlled commercial decision, not a sitewide reaction. Choose a collection whose rights, quality, and update process you understand. Define acceptable use, attribution, reporting, correction, payment, and withdrawal before comparing marketplace terms. If a proposal cannot tell you what use occurred, how value was calculated, and how an error can be removed, it is not ready to govern your best content.

    References

  • Agentic AI: Transforming PPC with Smart Automation

    Agentic AI: Transforming PPC with Smart Automation

    I’ve watched automation quietly transform PPC management over the years with rules, scripts, and API-driven workflows in Google Ads.

    Like many other marketers, I’m already very comfortable with automated bidding, data-driven optimization, and a suite of other AI-powered enhancements. But there’s a new shift on the horizon that’s set to redefine how we manage and optimize PPC campaigns.

    This time, I’m talking about AI agents and vibe coding. These innovations are ushering in a more autonomous mode of working where AI takes the lead in execution, allowing marketers like me to focus on strategy and creativity.

    This evolution promises unprecedented efficiency and flexibility, redefining effective PPC management.

    Agentic AI: Google Ads’ Game-Changing Feature

    In November 2025, Google rolled out its Agentic Ads Advisor, powered by advanced Gemini models. This tool helps advertisers like me uncover insights and boost campaign performance effortlessly.

    Google positions Ads Advisor as an AI partner that enhances campaign management by understanding business contexts, simplifying tasks, and learning from interactions to deliver better outcomes.

    However, the pressing question remains: What functionalities should an agentic AI tool embody?

    It should function as an autonomous agent, surfacing information as needed but also operating independently. It should identify opportunities for enhancing campaign setups, assets, ad copy, and more.

    An ideal agentic AI wouldn’t just make recommendations but also implement essential changes on its own.

    Integrating Agentic AI in PPC Workflows

    Agentic AI should ideally make decisions autonomously without needing constant human input, thereby managing, adjusting, and optimizing campaigns as they run.

    Beyond just advice or reporting, its real value lies in managing bidding, ad placements, and creative testing in real-time, based on live data, seasonality, and user behavior trends.

    With agentic AI handling more operational tasks, I can direct my efforts toward strategic decision-making.

    The competitive edge will increasingly rely on strategy rather than tools, focusing on marketing fundamentals like positioning, value propositions, and brand awareness.

    Read more: Agentic PPC: What Performance Marketing Could Look Like in 2030

    Why Agentic AI is Key for Advanced PPC Marketers

    Agentic AI appeals to experienced PPC marketers like myself because it scales campaigns without compromising strategic control, proving to be a true game-changer.

    With real-time optimization, data-driven creativity, and reduced human error, it redefines my role by allowing more time for strategy rather than execution.

    Despite its capabilities, informed oversight is essential to ensure alignment with broader marketing objectives, highlighting the need for ongoing professional engagement.

    Agentic AI isn’t replacing PPC professionals. Instead, it extends our capabilities, reduces manual effort, and facilitates better outcomes with minimal friction.

    Vibe Coding: Creating Your Marketing Toolbox

    In tandem with agentic AI, vibe coding is redefining how I work with AI-powered platforms, allowing me to create personalized, intuitive marketing tools and campaigns.

    Tools like Cursor and AI Studio have enabled me to articulate and realize specific needs seamlessly, even without being a developer.

    Incorporating vibe coding led me to build an SEO schema markup generator, an SEO audit tool, and a marketing idea generator, proving its practical value in my professional life.

    The possibilities expand when combining vibe coding with agentic AI, empowering marketers to engineer their AI agents tailored for PPC work.

    With this combination, I integrated these tools effectively within my marketing workflows, enhancing performance and strategy development at scale.

    Explore further: How Vibe Coding is Changing Search Marketing Workflows

    The Future: Navigating PPC with Agentic AI and Vibe Coding

    Agentic AI and vibe coding present immense opportunities to streamline PPC operations, enhance performance, and maintain competitiveness in a fast-evolving landscape.

    The future is about leveraging these technologies for more autonomous, data-driven, and personalized marketing strategies that benefit both internal teams and customers alike.

    As a PPC professional, it is crucial to embrace these advancements, ensuring adaptability and continued relevance in an AI-powered future.

    Follow experts like Alfred Simon, Mike Rhodes, and Ales Sturala to see practical applications of these innovative technologies in real-world scenarios.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Orchestration Systems: A Practical Production Guide

    AI Orchestration Systems: A Practical Production Guide

    You may already have a model that writes, an agent that analyzes, and automations that move data between applications. Each component can look impressive on its own. The trouble appears at the handoffs: context gets lost, nobody owns exceptions, and the workflow stops before it produces a measurable business result.

    An AI orchestration system closes those gaps. It determines what should happen next, routes work to the right tool or person, preserves state, enforces permissions, checks results, and captures evidence. The practical question is not how many agents you can deploy. It is which decisions you want the system to coordinate, and where human control still matters.

    The coordination gap is where AI value disappears

    Most organizations do not lack AI capabilities. They lack a reliable way to combine those capabilities into an end-to-end operating process. The martech market contains more than 15,384 solutions, yet only 33% of available technology is fully used. Adding another isolated tool can increase the number of possible actions without improving the flow of work.

    This is how pilot theater develops. A team proves that a model can produce a draft, classify a lead, or summarize a report. The demonstration succeeds, but the business workflow remains incomplete. The draft still needs facts, approval, publication, distribution, and measurement. The classified lead still needs routing, ownership, follow-up, and a feedback signal from the CRM. The summary still needs a decision and an accountable person.

    Point solutions optimize individual tasks. Orchestration coordinates the outcome across tasks. That coordination can support fluid budget decisions, buying-group alignment, and content loops connected to real buyer needs. In each case, the value comes from moving information and decision rights across boundaries, not from generating more output inside one application.

    Design questionSimple automationAI orchestration
    How is the next step chosen?A fixed rule or sequence determines it.Rules, models, context, and policy can select a route within defined boundaries.
    What happens to context?Each step receives a predetermined set of fields.The system assembles relevant context and preserves task state across tools.
    What happens when work fails?The workflow retries, stops, or sends a generic alert.The system classifies the exception, selects an allowed fallback, or escalates it with evidence.
    How is success measured?Execution is often treated as completion.Completion requires verified output and a connection to the intended operational or business result.

    Not every process needs AI orchestration. If a workflow follows stable rules, uses known inputs, and has one valid path, conventional automation is usually easier to test and maintain. Orchestration earns its added complexity when the process crosses systems, requires interpretation, contains meaningful exceptions, or must adapt its route without surrendering control.

    What a production orchestrator must control

    An isometric workflow facility routes a task through state management, permission checks, AI tools, human review, verification, and evidence storage.

    An orchestration system is not merely an LLM with access to several APIs. A production design needs an explicit control layer around every decision and action. Whether you buy a platform or assemble one from existing components, make sure it covers these seven responsibilities:

    1. Trigger and goal: Define what starts the workflow, what outcome it is pursuing, and what conditions should stop it. A vague instruction such as “improve this page” is not an operational goal. “Prepare a reviewable refresh package for this URL using approved product facts” is bounded and verifiable.
    2. Context assembly: Retrieve only the information needed for the current decision. That may include customer records, content history, analytics, brand rules, product facts, or approval status. More context is not automatically better; irrelevant or conflicting material can make the decision harder to inspect.
    3. Planning and routing: Select the next valid step. The router may use deterministic rules, a model, or a combination of both. Put hard requirements in rules and reserve model judgment for genuinely ambiguous work.
    4. Tool execution: Invoke a search service, CMS, analytics platform, CRM, validation tool, or specialist agent through a controlled interface. The orchestrator should know what an action is allowed to do, not merely how to call an endpoint.
    5. State management: Record the task’s status, inputs, decisions, outputs, approvals, and outstanding exceptions. Do not treat a model’s chat history as the system of record. Operational state needs a durable structure that other systems and people can inspect.
    6. Policy and approval: Check permissions before an action runs. Data access, publishing, deletion, customer communication, and budget changes should each have explicit authorization rules.
    7. Evaluation and feedback: Validate the immediate output, observe what happened after the action, and return that evidence to the workflow. Feedback may change a later route, create a follow-up task, or show that no further action is warranted.

    Give every action a contract

    The fastest way to expose a fragile orchestration design is to ask what each action promises. Create a short contract for every tool, agent, and human handoff:

    • Accepted input: The required fields, formats, and data sources.
    • Preconditions: The permissions, approvals, and prior states that must exist.
    • Allowed effect: What the action may read, create, change, publish, send, or spend.
    • Success evidence: The artifact or system state that proves the action completed correctly.
    • Failure output: A structured error that distinguishes missing data, denied access, invalid output, provider failure, and policy rejection.
    • Retry behavior: Whether retrying is safe and how the system prevents duplicate actions.
    • Escalation owner: The person or queue that receives an unresolved exception, along with the context needed to act.

    This contract turns an unpredictable failure into a known operational state. It also makes tools replaceable. The orchestrator can request a capability such as create_content_brief or validate_structured_data without embedding the entire workflow in one vendor’s prompt format.

    That separation matters in a fragmented market. Nearly 40% of US consumers have tried generative AI, while regular usage and platform loyalty remain less settled. Your production process should not assume that one model, interface, or vendor will always be the best route. Keep business policy, operational state, and evaluation criteria outside the model so you can change providers without redesigning the workflow.

    Design the first workflow around a costly handoff

    Do not begin with a goal as broad as “orchestrate marketing.” Choose one workflow where coordination failure is already visible. A strong first candidate has several of these characteristics:

    • Work repeatedly crosses tools, teams, or approval boundaries.
    • People spend time copying context, checking status, or deciding who should act next.
    • The desired completion state can be observed in a system or reviewed as an artifact.
    • The first version can recommend, draft, classify, or route before it receives permission to make irreversible changes.
    • Common exceptions can be named, even if they cannot all be resolved automatically.
    • The outcome matters enough to measure, but the workflow is narrow enough that one owner can govern it.

    Map the current process before selecting an orchestration platform. Write down the trigger, end state, decision points, required systems, human owners, exception paths, and completion evidence. If the team cannot agree on those elements, an agent will not resolve the ambiguity. It will automate the disagreement.

    An SEO and GEO content workflow example

    Consider a content refresh process. A weak implementation asks a model to rewrite a declining page and treats the new draft as the result. A properly orchestrated workflow connects diagnosis, evidence, production, quality control, publication, and post-publication observation.

    1. Observe: A defined signal creates a task. The signal might be a product change, an identified content gap, outdated information, or a meaningful visibility change. The task records why the page entered the workflow.
    2. Assemble evidence: Retrieve the existing page, approved product facts, site taxonomy, relevant performance data, editorial requirements, and known related content. Each input should carry its origin and current version.
    3. Decide: Choose among refresh, consolidation, new content, technical correction, escalation, or no action. Allowing a no-action decision is important; orchestration should reduce unnecessary work, not manufacture it.
    4. Prepare: Produce the bounded artifacts the next owner needs, such as a brief, proposed changes, internal-link recommendations, or eligible structured-data updates. Structured data should describe facts actually present on the page, not claims invented to satisfy a schema type.
    5. Verify and approve: Check factual support, links, required fields, schema syntax, indexability, and editorial policy. Keep publishing behind human approval until the workflow’s reliability and exception handling are demonstrated.
    6. Observe the result: Record publication and subsequent operational signals, then connect them to the original task. Search visibility, qualified actions, editorial rework, and technical errors answer different questions, so do not collapse them into one vague success score.

    The important change is not that AI generated part of the work. It is that every transition has an owner, a state, a control, and evidence. The same pattern can be applied to campaign changes, lead routing, customer-support escalation, or research workflows without pretending that those processes share identical rules.

    Close the loop with evidence, guardrails, and economics

    A circular workflow passes through automation, human approval, security inspection, verification, evidence storage, and a metered resource supply.

    A workflow is not closed merely because the last API call returned successfully. It is closed when the intended effect is verified, exceptions are accounted for, and the result can inform the next decision. Build that evidence into the design before you scale execution.

    Measure the outcome and the machinery separately

    Choose one primary business outcome and a small set of operational measures before launch. A useful measurement stack separates four layers:

    • Outcome: The result the workflow exists to influence, such as qualified opportunities, organic conversions, resolved issues, accepted content updates, or another observable business event.
    • Flow: Completion rate, cycle time, queue age, handoff delay, and exception rate. These show whether work is moving through the system.
    • Quality: Approval without rework, validation success, factual corrections, policy violations, and downstream reversals. These show whether completion is trustworthy.
    • Economics: Total model, platform, review, and remediation cost divided by an accepted outcome. Token spend is a useful diagnostic, but it is not a return-on-investment measure by itself.

    Do not optimize a local metric at the expense of the workflow. A cheaper draft that creates more editorial rework can increase total cost. A faster agent that produces duplicate CRM actions can damage the process it was meant to improve. Measure from trigger to verified outcome so the trade-off remains visible.

    Put control points before consequential actions

    • Use least-privilege access: Give each tool only the records and actions required for its role. A research agent does not need publishing permission merely because both functions appear in the same workflow.
    • Validate before writing: Check required fields, formats, factual support, policy conditions, and destination state before changing an external system.
    • Require approval where consequences are material: Publishing, deletion, customer communication, access changes, and budget movement should have named approval rules. The reviewer should receive evidence and proposed effects, not a bare approve-or-reject button.
    • Make retries safe: Assign an operation identifier and check whether an action already succeeded before repeating it. Otherwise, a timeout can become a duplicate publication, message, order, or record.
    • Set explicit fallbacks: Define what happens when a model, API, or data source is unavailable. Valid options include a deterministic route, another approved provider, a human queue, or a controlled stop.
    • Version the operating logic: Record which prompt, policy, model, tool definition, and data version influenced a decision. Without versions, you cannot explain a changed result or reproduce a failure.
    • Provide a stop mechanism: An owner must be able to pause new work without erasing in-progress state. Recovery is much easier when the system can resume from a known checkpoint.

    Use a go-live test that a business owner can answer

    Before moving beyond a controlled pilot, require a clear yes to each of these questions:

    • Can you trace one task from its trigger to its verified outcome?
    • Is there a named system of record for task state and approvals?
    • Can the system distinguish a failed action from an action whose result is merely unknown?
    • Can a failed step be replayed without duplicating an external effect?
    • Does every unresolved exception reach a named owner with useful context?
    • Can you change a model or tool without rewriting the business policy?
    • Does reporting show outcomes, quality, exceptions, and total cost rather than only calls and tokens?

    If any answer is no, keep the workflow in a learning environment. The missing item is not administrative polish. It is part of the production system.

    Key takeaways

    • An AI orchestration system coordinates decisions, tools, state, permissions, exceptions, and feedback across an end-to-end workflow.
    • Use simple automation for fixed, predictable paths. Add orchestration when context, interpretation, multiple systems, or variable routes make coordination the real problem.
    • Start with one costly handoff whose trigger, owner, completion state, and business outcome can be named.
    • Give every agent and tool an action contract covering inputs, permissions, effects, success evidence, failure output, retries, and escalation.
    • Keep policy, operational state, and evaluation criteria outside individual models so providers remain replaceable.
    • Measure verified outcomes, flow, quality, and total cost. A successful API call or generated artifact is not sufficient evidence of business value.

    Your next step is to draw one real workflow from trigger to outcome. Circle every point where someone interprets context, moves information between systems, waits for approval, or repairs a failed handoff. Those circles are your orchestration candidates.

    Choose one candidate, define its action contracts, and run it with narrow permissions and visible approvals. If you cannot name the evidence that proves the workflow finished correctly, do not add another agent yet. Fix the definition of done first.

    References

  • Google AI Travel Planning: An Action Plan for Travel Brands

    Google AI Travel Planning: An Action Plan for Travel Brands

    If you market a hotel, airline, restaurant, destination, or travel platform, the uncomfortable question is not whether travelers will use AI to brainstorm trips. It is whether your offer will remain visible when the same interface can compare the options and move the traveler toward a reservation.

    Google is connecting discovery, itinerary planning, deal-finding, and booking inside AI Mode. You do not need to chase every new feature. You need to separate live capabilities from planned ones, make your inventory easy to compare, and test whether a traveler can move from a conversational request to a correct booking without hitting conflicting information.

    Separate the live travel tools from planned booking features

    Google’s travel rollout is not one feature with one availability date. Some capabilities are already rolling out in particular markets and devices. Others describe the direction of flight and hotel booking but should not yet be treated as universally available. That distinction should determine what your team fixes now and what it prepares for next.

    CapabilityDocumented availabilityWhat your business should do
    Dinner reservations in AI ModeAgentic dinner reservations are rolling out in the U.S. through services including OpenTable and Resy, without being confined to a Google Labs opt-in.Check that your restaurant name, location, availability, party rules, and booking destination agree across your website, Google presence, and reservation provider.
    Canvas for trip planningCanvas is available for travel planning on desktop in the U.S.Publish information that remains useful within an itinerary, including location context, operating constraints, policies, and what must be reserved in advance.
    Flight DealsFlight Deals is expanding to more than 200 countries and multiple languages, and it accepts travel requests written in conversational terms.Make route, schedule, price, and eligibility information unambiguous. Review localized content as operational data, not merely translated marketing copy.
    Agentic flight and hotel bookingGoogle plans to help travelers compare flights and hotels by schedule, price, and reviews before completing a booking with a selected partner. Booking.com, Expedia, and Marriott are among the companies working with Google on the experience.Prepare your content, inventory, and distribution handoffs, but do not tell customers that universal AI Mode flight or hotel booking is already available.

    This prevents two expensive mistakes. The first is postponing all work because flight and hotel transactions are still developing, even though restaurant reservations and conversational deal discovery already create practical work. The second is promising a booking experience that a traveler cannot access in their market, device, or category.

    Label every internal project as live optimization, rollout monitoring, or future readiness. A U.S. restaurant connected to a supported reservation service belongs in the first group. A hotel preparing its distribution data for agentic booking belongs in the third. Flight offers shown across languages need both optimization and monitoring because geographic expansion does not guarantee that every offer is eligible or represented correctly.

    Optimize for a travel brief, not just a destination keyword

    A traveler's preferences for family, timing, budget, dining, and transportation flow into three consistently arranged trip options.

    A conventional travel query often looks like a destination plus a category. A conversational request can contain the whole decision: origin, timing, budget, preferred pace, who is traveling, acceptable connections, desired amenities, and conditions the traveler wants to avoid. Google is explicitly letting people describe the flight deal they want as they would describe it to another person.

    That changes the useful unit of content. A page that repeats a broad phrase such as “city hotel” may match a category, but it does not resolve whether the property fits a particular trip. Your page should help a planning system answer selection questions without inventing the missing context.

    1. State the fit. Say which traveler, occasion, route, or itinerary the offer serves. Avoid claiming that every product is ideal for everyone.
    2. Expose the constraints. Put operating days, stay requirements, connection rules, age or party restrictions, accessibility details, and booking conditions where they are relevant and visible.
    3. Explain the tradeoff. If an option is cheaper because it is less flexible, farther away, indirect, or limited to particular inventory, make that distinction explicit.
    4. Define the price context. Identify what the displayed amount covers, what may change it, what is excluded, and where the traveler must confirm the current total.
    5. Give the next action. Link the exact offer to the matching availability or booking step instead of sending every traveler to a generic homepage.

    Use that sequence as a content brief. Start with the travel need, answer the constraints, present the tradeoffs, supply evidence, and expose the booking path. It works better than manufacturing a separate page for every conversational variation because the underlying offer stays canonical while its decision facts become clearer.

    Do the same with destination content. A useful neighborhood page should explain what the location makes convenient, what remains inconvenient, which transport assumptions matter, and how the property or experience fits into a realistic itinerary. Generic inspiration can attract attention, but comparison-ready facts help a traveler make a choice.

    Make every offer comparable, verifiable, and machine-readable

    Google’s planned flight and hotel experience centers on schedules, prices, and reviews. Those are not decorative content fields. They are decision inputs. If your website, feed, booking engine, and distribution partners describe them differently, an AI interface has no reliable version to carry into the traveler’s plan.

    Audit each bookable offer as a record with the following components:

    • A stable identity: the exact property, route, room, fare, table, package, or experience being offered.
    • A precise location or operating area: not just a destination label, but the information needed to place the offer in an itinerary.
    • Availability context: the dates, times, operating pattern, inventory status, or conditions that control whether the offer can actually be selected.
    • Price context: currency, inclusions, exclusions, mandatory charges, variability, and the point at which the traveler receives the final amount.
    • Policies: cancellation, changes, refunds, deposits, check-in or arrival rules, and any restriction that could reverse the decision.
    • Fit attributes: the amenities, service conditions, accessibility information, traveler requirements, and limitations that distinguish the option.
    • Review evidence: ratings or review summaries that are genuine, attributable, current enough to use, and consistent with what the visitor can see.
    • A specific booking destination: the page or provider that can act on the offer without making the traveler reconstruct the search.

    Then compare the record across every system that publishes it. Begin with the visible page, continue through your structured data and feeds, and finish in the booking flow. A price that is correct in a feed but stale on the page is still a problem. So is an amenity marked up in JSON-LD that the visible content does not support.

    Use structured data as a consistency layer. Choose the narrowest valid type and properties supported by the page, connect records with stable identifiers, and make the marked-up values agree with the content a visitor can read. Do not use markup to assert unavailable inventory, hidden reviews, or an offer that the linked booking page cannot reproduce. Schema can reduce ambiguity; it cannot compensate for contradictory business data or guarantee inclusion in an AI response.

    Keep critical decision facts in readable page text rather than only inside promotional images or an interaction that reveals nothing until checkout. You should not require a person or a machine to infer whether breakfast is included, whether the rate can be canceled, or whether a venue accepts the requested party. If a fact materially changes the booking decision, publish it before the handoff.

    Test the booking handoff as carefully as the search result

    A traveler follows a connected path from trip planning through room selection and payment to a hotel reservation, beside a second path that ends at a disconnected doorway.

    Agentic booking does not remove the rest of the travel stack. Google is working with reservation and travel partners, and its planned flow still ends with a chosen booking partner. Your visibility can therefore depend on information and transaction paths that your own marketing site does not fully control.

    Run a complete journey for each priority offer:

    1. Start with a realistic conversational request that includes the constraints your customers actually use.
    2. Check whether your business or offer appears, whether it is described accurately, and which page or provider is attached to it.
    3. Select the offer and compare the displayed schedule, price, availability, review information, and policy with your authoritative records.
    4. Continue to the reservation provider. Confirm that dates, party details, route, room, fare, or package context survives the handoff.
    5. Proceed far enough to see the payable amount and essential terms. Stop before creating a charge unless the test booking is authorized and can be safely reversed.
    6. Test an unavailable option and a changed option. The experience should return a clear alternative or current status rather than a dead end or misleading confirmation.
    7. Verify the confirmation path. The traveler should know who holds the reservation, where support comes from, and which rules govern changes or cancellation.

    For a U.S. restaurant, include the reservation provider you actually use when checking the live dinner-booking path. For a hotel or airline, start with existing distribution relationships and monitor Google’s flight and hotel rollout. The fact that Booking.com, Expedia, and Marriott are named collaborators is not evidence that every supplier, property, or rate connected to them will automatically qualify.

    Do not move inventory to a new channel solely because its company appears in a product rollout. A change in distribution can alter commissions, contract terms, customer ownership, support obligations, and margin. First ask your existing provider what data it sends, which identifiers it preserves, how corrections propagate, and whether your inventory is eligible for the relevant Google experience. Review the commercial terms before changing the channel mix.

    Assign ownership for mismatches. Marketing can maintain descriptive content, but pricing, inventory, distribution, and reservation failures often sit elsewhere. Give each field an authoritative system and an escalation path. Otherwise, the first person to discover the inconsistency will be the traveler attempting to book.

    Measure the full prompt-to-reservation journey

    Organic clicks alone cannot tell you whether Google AI travel planning is helping or displacing your business. If more comparison happens inside the planning interface, a visitor may arrive later in the decision process, transact through a partner, or remember the brand and return directly. None of those possibilities makes a click unimportant; they make it incomplete as a standalone measure.

    Build a repeatable prompt set from real customer questions and group the observations by market, language, device, and travel category. Record the prompt, test conditions, options shown, facts attributed to your offer, linked destination, booking provider, and result of the handoff. Keep the conditions with the result so that a desktop Canvas observation in the U.S. is not silently treated as evidence of identical availability everywhere.

    Use operational measures that point to a fix:

    • Discovery rate: the share of applicable test prompts in which the business or eligible offer appears.
    • Fact accuracy rate: the share of checked decision fields that agree with the authoritative record.
    • Price parity rate: the share of tested offers whose displayed price context matches the booking destination.
    • Handoff success rate: the share of selections that reach the correct bookable inventory with the important context preserved.
    • Confirmation rate: the share of authorized test or customer journeys that produce a valid reservation rather than an error, unavailable result, or abandoned mismatch.
    • Correction time: how long it takes an updated schedule, policy, price, or availability status to become consistent across the systems you control.

    Do not collapse all of this into one AI visibility score. An appearance with the wrong cancellation policy is not a success. Neither is an accurate citation that sends the traveler to an unrelated booking page. Diagnose the failing stage: discovery, comparison, handoff, or transaction. Then fix the system responsible for that stage.

    Key takeaways

    • Treat U.S. dinner reservations, desktop Canvas, international Flight Deals, and planned flight or hotel booking as different rollouts with different actions.
    • Write for the complete travel brief by exposing fit, constraints, tradeoffs, price context, policies, and the exact next step.
    • Keep visible content, structured data, feeds, provider records, and checkout information consistent.
    • Test whether offer context survives the move from an AI recommendation to the reservation provider.
    • Measure accurate discovery and successful booking separately; visibility with incorrect facts is a failure, not a partial win.

    Start with the journey tied to your most important bookable offer. Reproduce it from a realistic prompt to the final reservation step, find the first fact or handoff that fails, and correct its authoritative record. Repeat that process across the markets and languages you actually serve. That work will remain useful as Google’s travel features expand because it improves the same thing every planning interface needs: an offer that can be understood, compared, and booked without surprises.

    References