Your team has found a marketing workflow worth improving with AI. A vendor can sell you a platform, a specialist can configure a solution, and someone internally is probably confident they can build a prototype. The dangerous question is which option looks cheapest at the start.
The useful question is where repeatable software should end, where your workflow needs specialist implementation, and where qualified human judgment must remain. A focused 30-minute sorting exercise can answer that before an interesting prototype becomes an unsupported internal product.
Key takeaways
- Buy software when the capability is common across companies and the vendor can absorb maintenance, updates, and support.
- Outsource implementation knowledge when your workflow is custom but the expertise needed to build it is temporary.
- Build internally when the logic is genuinely differentiating, your team will improve it regularly, and you can support it after launch.
- Do not deploy an AI workflow unless a named person can verify its output using evidence and subject knowledge.
- Make the decision for each workflow step, not for an entire department, role, or AI initiative.
- Compare lifecycle cost, including review and maintenance, and validate the choice with a controlled pilot before allowing autonomous action.
Treat the workflow as layers, not one build-or-buy choice
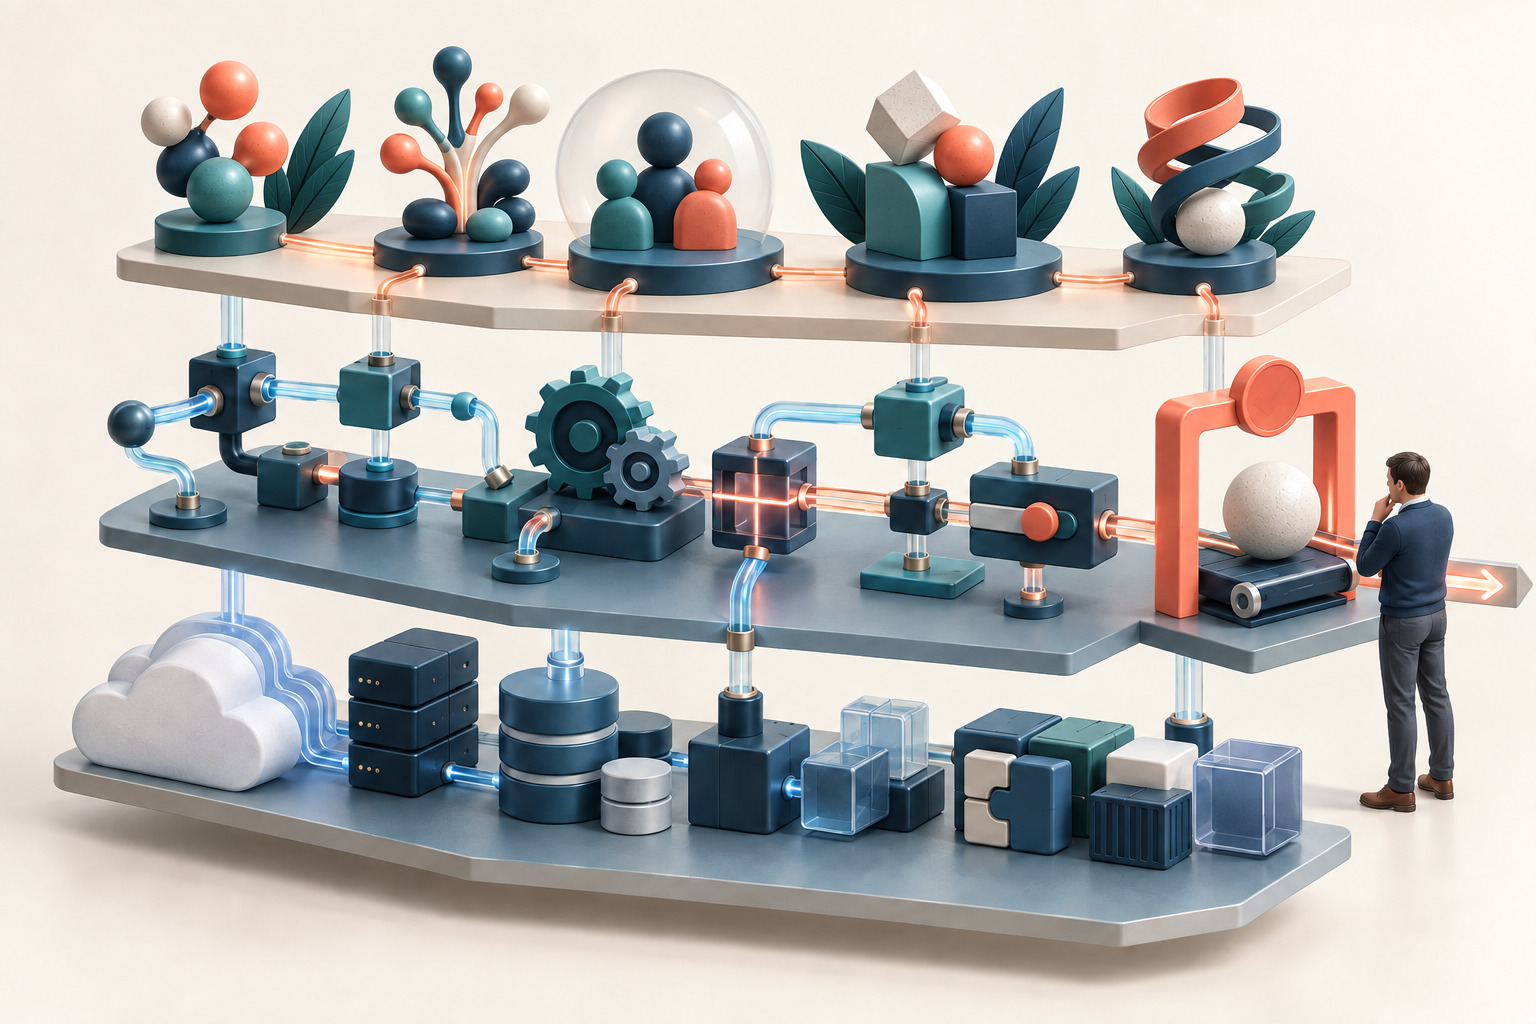
A marketing automation is rarely one indivisible system. A visibility report, for example, may collect data, normalize names, identify changes, interpret those changes, route exceptions, obtain approval, and distribute a finished report. Those steps do not have to come from the same place.
Break the workflow into boxes before comparing solutions. For every box, record its input, transformation, output, owner, reviewer, and downstream decision. You can then route each layer according to what makes it difficult.
| Workflow layer | Marketing examples | Sensible default | Your continuing responsibility |
|---|---|---|---|
| Common software capability | Rank tracking, citation monitoring, brand-mention tracking, crawl diagnostics, and content scoring | Buy | Configuration, data access, quality checks, and vendor oversight |
| Company-specific implementation | Approval routing, data mapping, reporting cadence, subject-matter-expert intake, and approved CTA insertion | Outsource the initial design or implementation, then own it | Requirements, acceptance tests, documentation, and an internal process owner |
| Differentiating logic | Your prioritization rules, proprietary data relationships, brand judgment, and decision criteria | Build or retain internally | Roadmap, maintenance, testing, and knowledge continuity |
| Human control | Accuracy review, exception handling, interpretation, and final approval | Keep qualified ownership inside the team | Evidence standards, escalation rules, and accountability for the resulting decision |
This is a deliberate hybrid, not a compromise. You might buy the monitoring engine, hire a specialist to connect it to your reporting process, build a narrow layer containing your prioritization rules, and keep final interpretation with an analyst. Recreating the monitoring platform would add little advantage; handing your judgment to an opaque system would surrender too much.
An MIT review of enterprise generative AI projects reported zero return among 95% of the organizations it examined, while external partnerships represented a higher share of successful deployments than internal development. That should not be converted into a universal failure probability: the initiative volumes were uneven, and there was too little hybrid build-buy evidence to quantify that route. The practical warning is narrower. A working prototype is not a successful deployment, especially when the system does not fit the way people already work.
Do not automate work that nobody can verify
Before discussing price or architecture, ask one gating question: can a named person on your team perform the task manually or reliably check the result? If the answer is no, pause the automation. You would be installing a system whose failures your team cannot recognize.
Fluent output makes this risk easy to underestimate. A model can turn a spike in a group of Google Search Console queries into a confident claim that AI visibility is rising, even though the data does not establish that conclusion. The error can look polished enough to enter a leadership meeting unless someone understands both the data and the inference being made.
Only 13% of marketers fully trust AI output without a human reading it. That is not merely an adoption problem. It is a staffing and workflow requirement: the review still needs time from someone qualified to judge the work.
The State of CRM Data Report 2026 found that nearly 78% of C-suite respondents and 92% of SVP or VP respondents had acted on an AI recommendation they later suspected was wrong because of poor underlying data. The corresponding figure among individual contributors was 41%. These are self-reported suspicions, not measured model error rates, but they expose an important control problem: the person with authority to act may be farther from the evidence needed to challenge the recommendation.
Create a verification contract before you automate. It should answer:
- What decision can this output influence? A draft that stays in an editor is different from a report that changes budget or reaches an executive.
- What evidence should support the answer? Require links, source records, query data, calculation inputs, or another trace that the reviewer can inspect.
- Who is qualified to review it? Assign a person or role, not an unspecified human in the loop.
- What counts as an unacceptable error? Define concrete failure classes such as fabricated facts, incorrect data mapping, unsupported attribution, missing exceptions, or off-brand recommendations.
- What happens when confidence is low or evidence is missing? Route the case to a person rather than letting the system improvise.
- Which outputs always require approval? Keep review on every output that can publish content, contact a customer, alter spending, or materially influence a leadership decision.
If no one can fill in that contract, your next investment is expertise, not automation. Narrow the task, train an owner, or obtain specialist help before deploying the tool.
Buy common capability, outsource the learning curve, build your edge
Buy when the underlying problem is common
Buying is usually the sound route when thousands of other teams need substantially the same capability. Tracking, monitoring, crawling, diagnostics, and scoring all require unglamorous infrastructure work: connectors change, interfaces break, usage grows, and edge cases accumulate. A mature vendor spreads that work across its customers and provides someone to fix the product when it fails.
Do not evaluate only the demo. Ask the vendor to show how the product handles your real inputs and exceptions. Confirm:
- whether it supports the data systems you actually use;
- how it logs inputs, changes, failures, and human approvals;
- whether reviewers can inspect the evidence behind an output;
- how data, configurations, and results can be exported;
- which maintenance and support work is included;
- how usage, seats, or additional integrations affect cost;
- what happens to your workflow when the vendor changes a model or feature; and
- what access controls apply before customer, employee, or proprietary data enters the system.
The product does not need to mirror your process perfectly out of the box. It does need to cover the commodity layer without forcing your team to become its unpaid engineering and support department.
Outsource when the workflow is yours but the learning is temporary
Your approval chain, internal taxonomy, reporting schedule, subject-matter-expert process, and pre-approved copy may be unique. The implementation problems hiding underneath them often are not. Someone who has configured similar workflows already knows where handoffs fail, which exceptions need human input, and which apparently simple steps become brittle when automated.
Use a practical test: will your team apply the knowledge gained from building this every week? If not, paying employees to discover each failure mode for the first time is an expensive way to acquire one-use expertise. Buy the learning curve through a validated template, a focused consultation, a short implementation engagement, or a specialist resource library.
Outsourcing should leave you with an operable system, not a permanent mystery. Put these deliverables into the engagement:
- a map of the workflow, inputs, outputs, owners, and exceptions;
- documented configuration and administrator access;
- acceptance tests covering normal, messy, and missing inputs;
- a failure log describing known limits and escalation paths;
- training for the internal owner and reviewers;
- a handover plan, maintenance estimate, and change process; and
- clear ownership and export rights for data, prompts, rules, documentation, and other deliverables.
Keep an internal owner involved throughout. A handoff at the end cannot recover reasoning and decisions that were never documented.
Build when the capability creates durable advantage
Building internally makes sense when the system encodes something meaningfully different about how you market, not merely because your workflow has custom field names. Your team should be able to answer yes to all of these questions:
- Does the logic create a real advantage rather than duplicate a standard product feature?
- Will your team use and improve the resulting technical or operational knowledge regularly?
- Are your requirements unlikely to be met through configuration, integration, or a narrow extension of existing software?
- Can you assign an enduring product owner and the people needed to test, monitor, document, and repair it?
- Will ownership survive if the original builder changes roles or leaves?
- Can a qualified person verify the system’s output and stop it when it behaves incorrectly?
An internal prototype may appear inexpensive because its future obligations are invisible. Once colleagues depend on it, the team owns permissions, changing integrations, model behavior, tests, documentation, support, incident response, and every request for a small improvement. If those duties do not have owners, the organization has created software without creating a software function.
Build the narrowest layer that contains your advantage. Purchasing a stable platform and adding your own orchestration or decision rules is often more defensible than rebuilding data collection, authentication, dashboards, and administrative features around it.
Use a hybrid route deliberately
A strong marketing AI workflow may use all three routes. A vendor collects visibility data. A specialist maps the data to your taxonomy and approval path. Your team encodes its prioritization rules and approved CTA library. An analyst reviews anomalies and interpretation before the report reaches leadership.
Write the boundary between those layers down. Specify who owns the data, configuration, custom logic, review, maintenance, and recovery process. Hybrid systems become fragile when every participant assumes somebody else owns the seam.
Make the decision in 30 minutes, then test one handoff
You do not need a long procurement exercise to choose an initial route. You do need a disciplined comparison that counts work beyond the visible fee.
Use this 30-minute decision agenda
- Minutes 0-5: define the outcome. Name the marketing result, the user, and the decision the workflow should improve. Reject objectives such as use AI or automate content; they do not define value.
- Minutes 5-10: map the steps. Draw each input, transformation, review, exception, and output. Do not route the workflow until you can see its parts.
- Minutes 10-15: classify the layers. Mark each step as common capability, company-specific implementation, differentiating logic, or human control.
- Minutes 15-20: apply the verification gate. Name the reviewer, required evidence, unacceptable errors, and escalation path.
- Minutes 20-25: compare lifecycle cost. Add internal labor, implementation, review, maintenance, support, and displaced marketing work to the visible price.
- Minutes 25-30: choose a route and pilot boundary. Decide what to buy, outsource, build, or leave manual. Assign an owner and state what evidence would justify expansion.
Compare total cost on the same basis
A subscription price cannot be compared directly with a development estimate. Use the same operating horizon and the same labor assumptions for every option.
- Buy: subscription or usage charges, implementation, integrations, internal administration, review, training, migration, and eventual exit work.
- Outsource: specialist fees, required software, internal subject-matter-expert time, review, training, handover, and ongoing maintenance.
- Build: discovery, meetings, design, development, testing, infrastructure, documentation, monitoring, support, review, repairs, and the marketing work displaced by those hours.
Calculate internal labor using the time of every contributor, not just the person writing prompts or code. Include the people clarifying requirements, attending meetings, preparing data, testing outputs, correcting errors, approving work, and responding when the workflow breaks.
Then name the opportunity cost in operational terms. Which campaign, analysis, customer interview, content update, or technical fix will wait while the team builds and maintains this? If no displaced work appears in the comparison, the internal option has been priced as though staff time were unlimited.
Keep consequence separate from speculative arithmetic. If a bad output could publish an unsupported claim, misclassify performance, expose sensitive data, or redirect budget, record that failure and the control that prevents it. Do not invent a precise dollar value merely to make the spreadsheet look complete.
Pilot a bounded step before replacing a job
Test one handoff whose output can be compared with the existing process. A narrow pilot reveals whether the proposed route reduces work or merely moves it into checking, correction, and maintenance.
- Capture the baseline. Record the current input, output, turnaround, human effort, recurring errors, and approval path.
- Prepare test cases. Include normal inputs, incomplete data, unusual cases, and situations that should be escalated rather than answered.
- Define acceptance before testing. State the required evidence, allowed error classes, review time, and conditions that would stop the pilot.
- Run in shadow mode. Compare results without letting the system publish, send, spend, or change a production record on its own.
- Log every intervention. Separate factual corrections, data-mapping problems, brand edits, integration failures, and exceptions. That log shows whether the problem is the model, the implementation, the input, or the process itself.
- Calculate net value. Subtract review, repair, administration, and maintenance effort from gross time saved. Include improvements in consistency or turnaround only when the pilot demonstrates them.
- Decide explicitly. Expand, revise, change the sourcing route, keep the step manual, or stop. Name the production owner and rollback method before expansion.
Stop or narrow the automation when failures are hard to detect, review consumes most of the apparent saving, changing inputs repeatedly break the workflow, or nobody accepts maintenance ownership. That is useful pilot evidence, not a reason to keep investing until the original idea appears justified.
Take the next proposed marketing automation and draw its steps on one page. Mark each box buy, outsource, build, or human control. Do not approve procurement or development until every box has a verification owner and the resulting system has a lifecycle owner. The goal is not to own more AI software. It is to improve a marketing outcome with the smallest reliable system that your team can understand and sustain.
References

Leave a Reply