Tag: AI Integration

  • Google Merchant Center UCP Integrations: What to Enable

    Google Merchant Center UCP Integrations: What to Enable

    You have three separate decisions to make when Google’s UCP integration hub appears in Merchant Center. You can send a cart to your website, support checkout on Google, link customer identities, or adopt only the capabilities that fit your operation.

    The right choice depends less on what you can switch on than on where you can safely own the customer, order, and recovery experience. Use the framework below to choose a scope, test the handoffs, and measure whether UCP removes purchasing friction without creating an operational blind spot.

    What the UCP integration hub actually changes

    Google is gradually making the Merchant Center UCP integration hub available to eligible U.S. merchants. UCP stands for Universal Commerce Protocol. In this rollout, it acts as a connection layer between Google’s shopping experiences and a merchant’s commerce infrastructure.

    The meaningful change is modularity. An eligible merchant can select individual capabilities instead of accepting one predetermined checkout experience. That turns UCP configuration into a set of business decisions rather than a single technical integration.

    CapabilityWhat changes in the journeyYour release gate
    Cart transferThe shopper’s cart moves from Google to the merchant’s website, where the purchase can continue.The correct products, variants, quantities, prices, and context must survive the handoff.
    Native checkout on GoogleThe shopper can complete checkout within Google’s experience.Your order operation must reliably receive, fulfill, reconcile, support, cancel, and refund the resulting orders.
    Identity linkingThe shopper’s Google identity can be connected with the merchant’s customer relationship.The customer benefit, consent path, account-matching rules, unlinking process, and support recovery must be clear.

    Treat the last column as your own acceptance standard. The presence of a capability in Merchant Center tells you that it is available to configure; it does not prove that your downstream systems, policies, analytics, or support team are ready for it.

    For SEO, AEO, and GEO teams, the boundary matters. UCP is commerce infrastructure. It can shorten the distance between product discovery and purchase, including journeys in which AI agents help people research products, assemble carts, and transact. It should not be treated as a ranking switch, a replacement for Merchant Center feed quality, or a substitute for accurate product pages and structured data.

    Choose each capability by ownership and failure radius
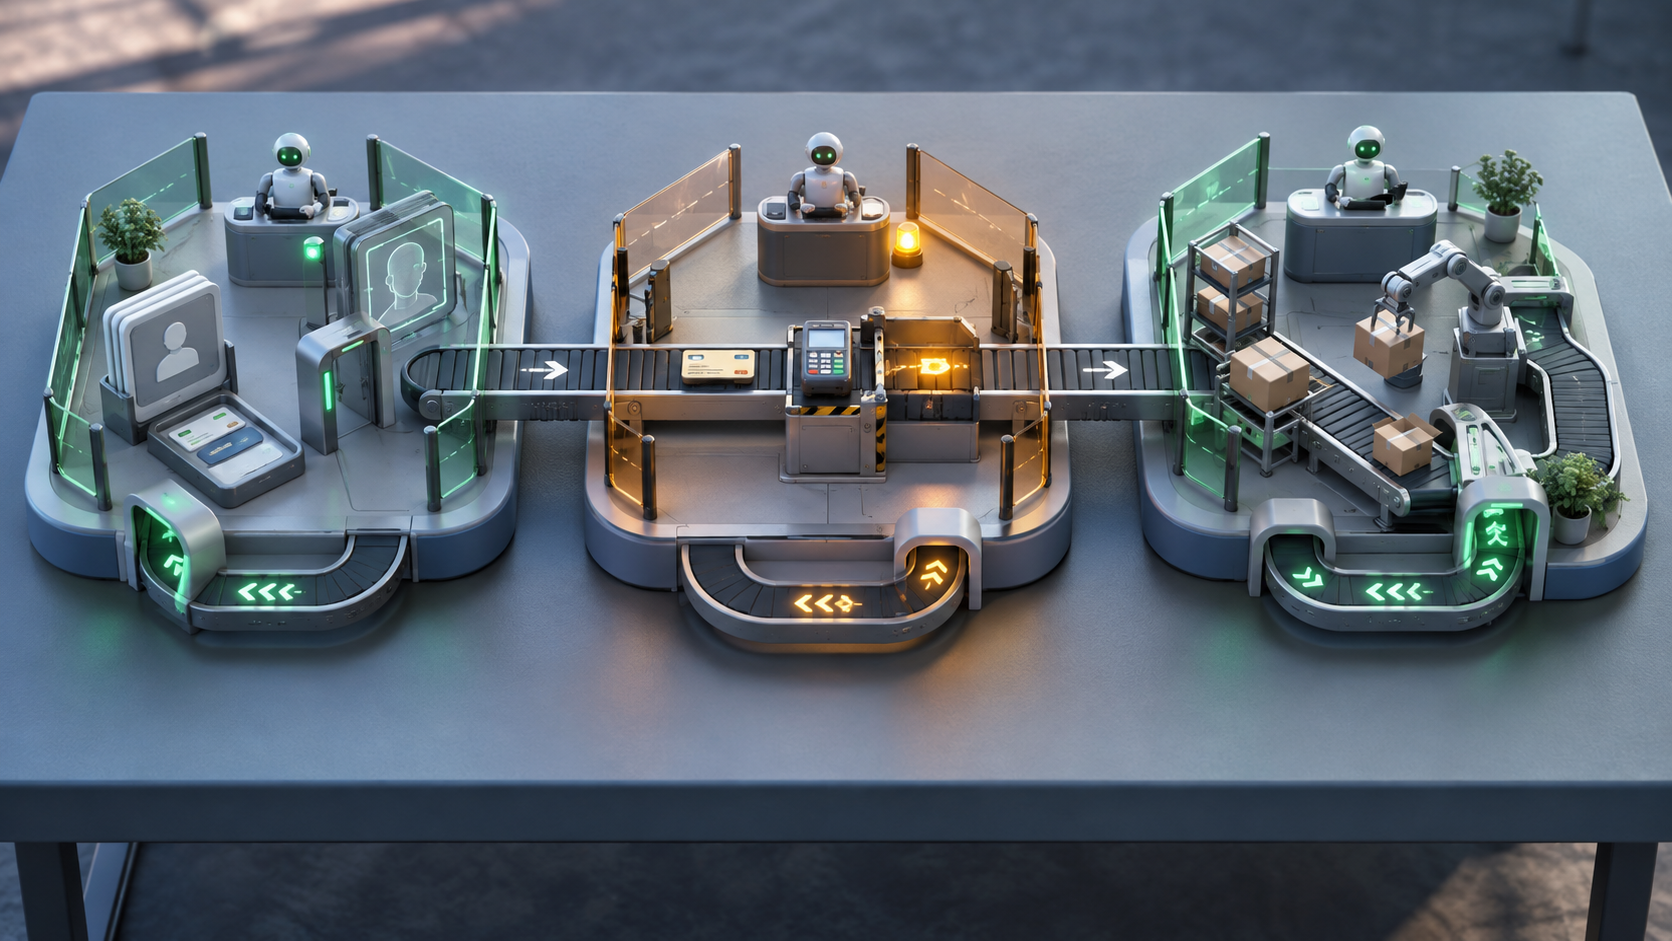
    A modular ecommerce system separates identity, checkout, and fulfillment into bounded zones, with an amber warning contained inside the checkout area.

    Start with the customer journey you can operate reliably. A shorter path is valuable only when the order that emerges from it is accurate, observable, and recoverable.

    1. Consider cart transfer first when your website checkout is already the strongest part of the journey. It lets Google participate in discovery and cart creation while your existing site remains the purchase destination. Test the handoff as a data contract: the product identifier, selected variant, quantity, current price, availability, promotion context, and destination page must agree. Also define what the shopper sees when a price changes, an item sells out, or the cart cannot be reconstructed.
    2. Consider native checkout when your order operation can support a transaction completed outside your website. Map the entire order lifecycle before enabling it: creation, payment state, tax, shipping, inventory reservation, fulfillment, cancellation, returns, refunds, customer notifications, fraud review, and support. Do not assume that a native interface transfers responsibility for these functions. Confirm the division of responsibility for your particular setup.
    3. Consider identity linking when signing in produces a real customer benefit. That benefit might involve account continuity, saved preferences, loyalty, or post-purchase service, but the benefit must be explicit. Define how accounts are matched, what happens when identifiers disagree, how duplicate accounts are handled, how consent is recorded, and how a customer can unlink or recover access.

    The hub’s capability-by-capability selection model gives you a reason to avoid an all-at-once launch. Enable the smallest useful combination first. If cart transfer fails, you can investigate the cart contract. If identity linking and native checkout go live at the same time, an order problem may involve identity resolution, checkout state, or the order pipeline, making the cause harder to isolate.

    That sequencing is especially important for identity linking. It introduces customer-data, authentication, privacy, and support consequences that are different from the mechanics of moving a cart. Review it as its own workstream rather than treating it as a convenience setting attached to checkout.

    Build six release checks before changing the customer journey
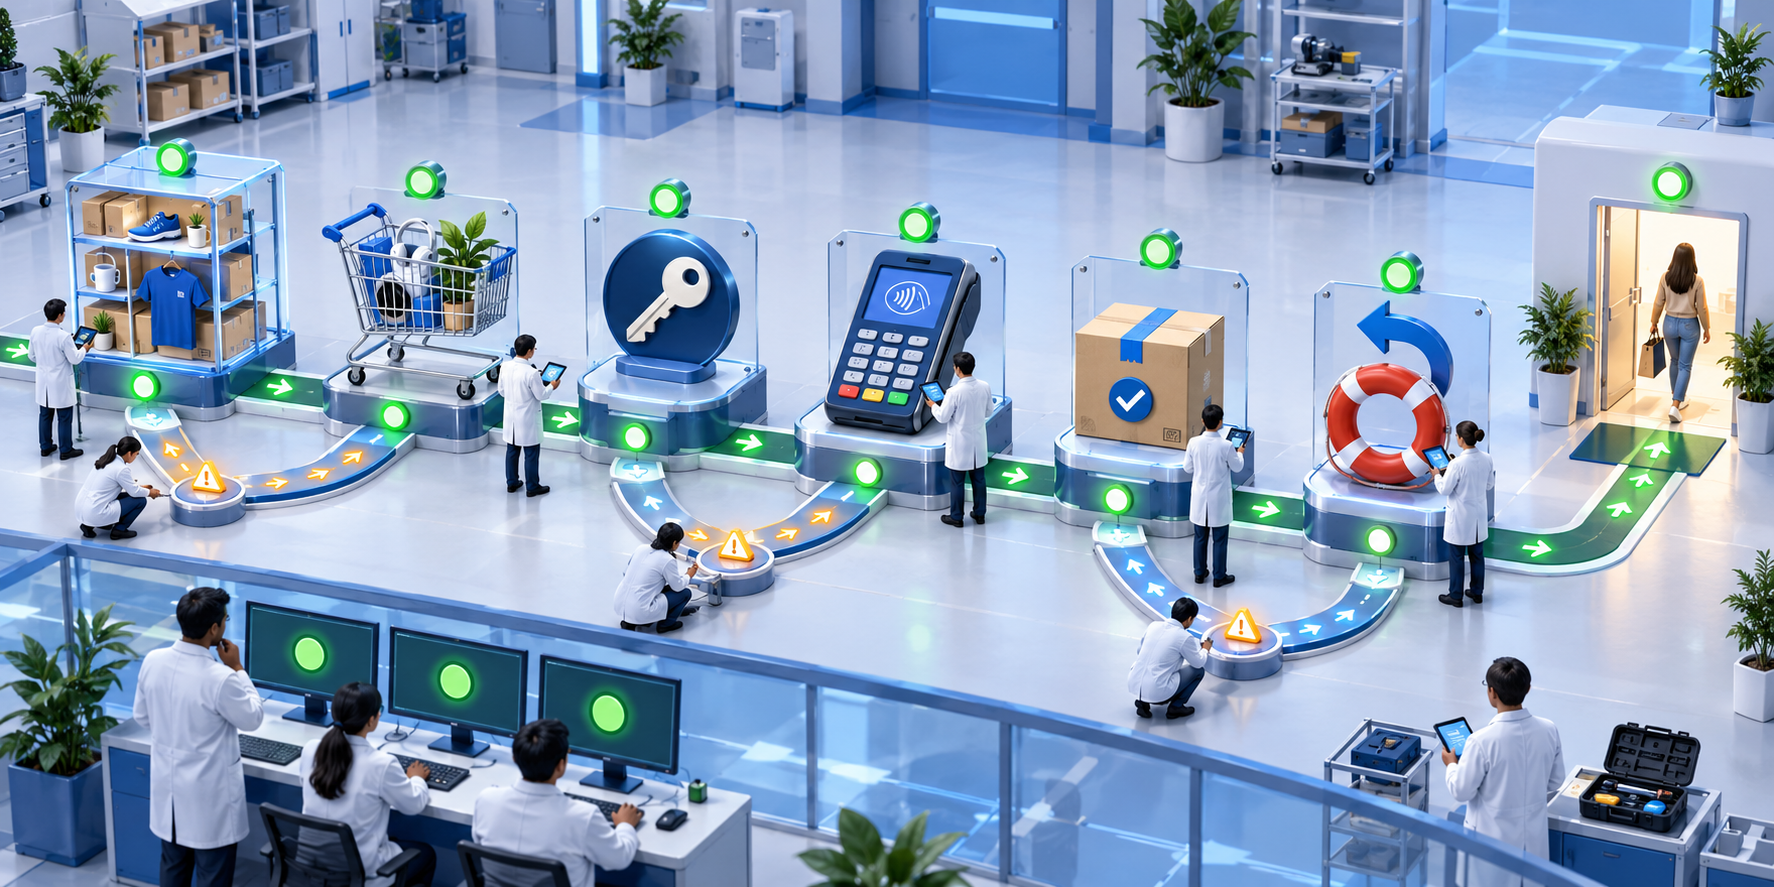
    Six quality-control stations test product availability, cart transfer, identity, payment, order confirmation, and customer recovery along an ecommerce purchase path.

    You do not need to wait for a full implementation project before preparing. You do need a written acceptance plan. Build these six checks while access is rolling out:

    1. Confirm the actual scope in your account. Record which Merchant Center account, market, storefront, and capabilities are eligible. The rollout begins with eligible U.S. merchants, while plans for Australia and Canada have moved to a later schedule. Work from the controls present in your account rather than treating an announced market sequence as a guaranteed activation date.
    2. Define the catalog contract. Name the system that owns each product identifier, variant, price, currency, availability state, image, and fulfillment promise. The website, Merchant Center data, cart, and order record should refer to the same sellable item. If two systems can overwrite a value, document which one wins and when.
    3. Define the cart contract. Specify what must survive a transfer and what can be recalculated on arrival. Include quantity limits, variant selections, promotions, unavailable items, expired carts, and price changes. Write the customer-facing fallback for each failure; a silent empty cart is not an acceptable recovery path.
    4. Define the order contract. For native checkout, trace a successful order and every material exception through the systems your teams use. An order is not complete merely because payment appears successful. It must enter inventory, fulfillment, notifications, reporting, customer service, cancellation, return, and refund workflows with a stable identifier.
    5. Define the identity contract. Decide what data is linked, why it is needed, what consent is required, how long it is retained, and which team handles mismatches. Include duplicate accounts, shared email addresses, changed email addresses, revoked access, deletion requests, and support verification.
    6. Define observability and recovery. Assign an owner for integration errors, order discrepancies, customer complaints, and rollback decisions. Preserve enough identifiers to trace a journey across the surfaces you control without exposing unnecessary personal data. Document how you will pause a capability safely if failures rise.

    Use any preview, testing, or diagnostic path that your Merchant Center account makes available. If your account exposes only a broad production control, complete the data and operational checks before changing it. Do not discover your refund path, account-recovery rules, or missing order identifiers through the first customer complaint.

    Launch one capability at a time when the available controls permit it. Start with the smallest reversible product or operational scope supported by your setup. Keep a written record of the prior configuration, the activation time, the owner on duty, the expected signals, and the condition that triggers a pause.

    Measure the handoff, not just the final sale

    A conversion total can hide the exact friction UCP is meant to remove. Build a funnel that shows where an eligible journey stopped. Instrument the events available on the systems you control, then reconcile them with the commerce and order records available from the integration.

    • Eligible journey volume: the number of shopping journeys that could use the enabled capability.
    • Cart initiation and transfer: how many carts begin, how many handoffs are attempted, and how many arrive with usable contents.
    • Checkout progression: how many transferred or native journeys reach checkout, encounter an error, and complete.
    • Order reconciliation: whether each completed transaction produces one accurate order in the system of record, without omissions or duplicates.
    • Commercial consistency: discrepancies involving products, variants, quantities, price, availability, tax, shipping, discounts, or currency.
    • Operational consequences: cancellations, refunds, identity-recovery cases, integration-related support contacts, and manual corrections.

    Capture a baseline before launch. Compare the same journey before and after enablement where your data permits, and separate technical success from business success. A cart can transfer perfectly while conversion falls because the landing experience is confusing. Native checkout can increase completed orders while creating reconciliation work that erases the operational benefit.

    Website analytics alone will be incomplete when checkout finishes on another surface. Do not interpret a drop in site-recorded purchases as a drop in total purchases until native orders have been reconciled. Conversely, do not count an external checkout confirmation as a clean success until the corresponding order is present and actionable in your system of record.

    Keep search visibility and commerce performance in separate reporting layers. Monitor product discovery, landing-page visibility, feed health, and structured-data quality alongside the UCP funnel, but do not attribute a ranking change to UCP merely because the dates overlap. Its immediate job is to connect discovery, cart, identity, and transaction paths more effectively.

    Consistency is the point where the SEO and commerce teams meet. Use the same product identity, variant language, pricing state, availability, and merchant policy across Merchant Center, the website, structured data, cart, checkout, and order systems. UCP cannot compensate for contradictory facts moving through those systems; it can only make those contradictions reach the customer faster.

    Key takeaways

    • UCP in Merchant Center is a selectable integration layer, not one mandatory checkout model.
    • Choose cart transfer when your site checkout should remain the transaction destination and you can preserve cart accuracy through the handoff.
    • Choose native checkout only after the complete order, support, cancellation, return, and refund lifecycle works outside a website-completed purchase.
    • Review identity linking separately because it adds consent, account-matching, privacy, authentication, and recovery requirements.
    • Measure attempted handoffs, errors, discrepancies, and reconciled orders as well as conversions.
    • Do not treat UCP enablement as evidence of improved rankings; maintain product data, content, feeds, and structured data as separate visibility work.

    If the hub is already available in your account, begin with a capability decision and an acceptance checklist, not the activation control. If it is not available, prepare the catalog, cart, order, identity, and measurement contracts now. That work remains useful regardless of when eligibility reaches your market or account.

    References


  • Build, Buy, or Outsource Marketing AI: A Decision Framework

    Build, Buy, or Outsource Marketing AI: A Decision Framework

    Your team has found a marketing workflow worth improving with AI. A vendor can sell you a platform, a specialist can configure a solution, and someone internally is probably confident they can build a prototype. The dangerous question is which option looks cheapest at the start.

    The useful question is where repeatable software should end, where your workflow needs specialist implementation, and where qualified human judgment must remain. A focused 30-minute sorting exercise can answer that before an interesting prototype becomes an unsupported internal product.

    Key takeaways

    • Buy software when the capability is common across companies and the vendor can absorb maintenance, updates, and support.
    • Outsource implementation knowledge when your workflow is custom but the expertise needed to build it is temporary.
    • Build internally when the logic is genuinely differentiating, your team will improve it regularly, and you can support it after launch.
    • Do not deploy an AI workflow unless a named person can verify its output using evidence and subject knowledge.
    • Make the decision for each workflow step, not for an entire department, role, or AI initiative.
    • Compare lifecycle cost, including review and maintenance, and validate the choice with a controlled pilot before allowing autonomous action.

    Treat the workflow as layers, not one build-or-buy choice

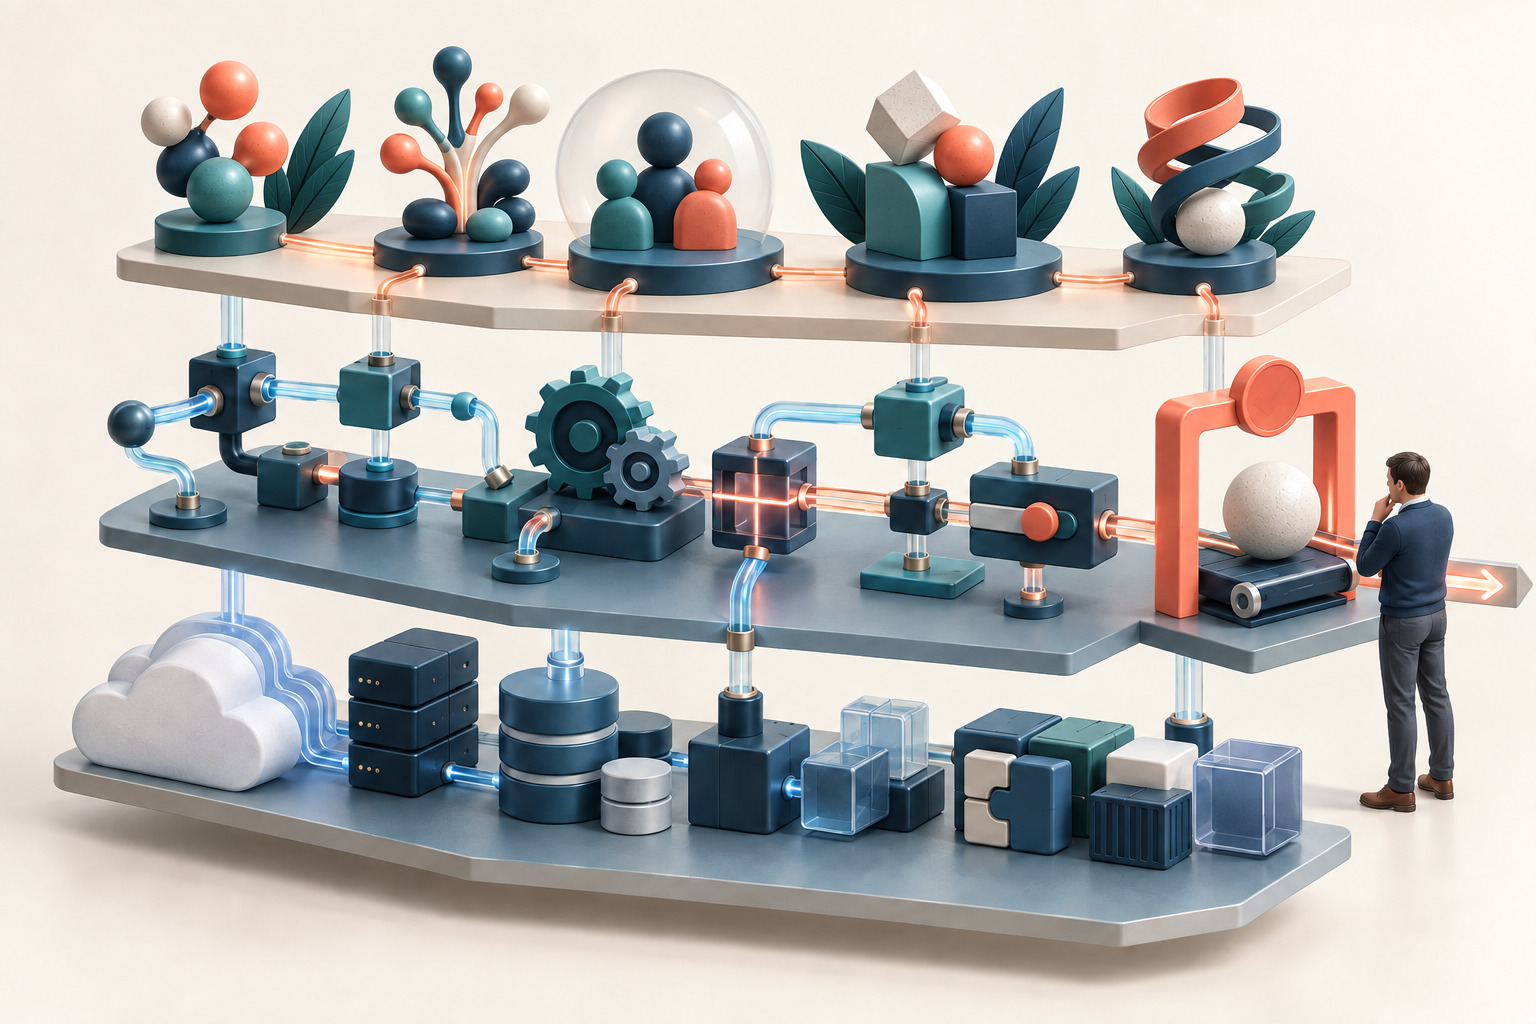
    An exploded three-layer workflow combines standard software modules, configurable connections, and a human approval checkpoint.

    A marketing automation is rarely one indivisible system. A visibility report, for example, may collect data, normalize names, identify changes, interpret those changes, route exceptions, obtain approval, and distribute a finished report. Those steps do not have to come from the same place.

    Break the workflow into boxes before comparing solutions. For every box, record its input, transformation, output, owner, reviewer, and downstream decision. You can then route each layer according to what makes it difficult.

    Workflow layerMarketing examplesSensible defaultYour continuing responsibility
    Common software capabilityRank tracking, citation monitoring, brand-mention tracking, crawl diagnostics, and content scoringBuyConfiguration, data access, quality checks, and vendor oversight
    Company-specific implementationApproval routing, data mapping, reporting cadence, subject-matter-expert intake, and approved CTA insertionOutsource the initial design or implementation, then own itRequirements, acceptance tests, documentation, and an internal process owner
    Differentiating logicYour prioritization rules, proprietary data relationships, brand judgment, and decision criteriaBuild or retain internallyRoadmap, maintenance, testing, and knowledge continuity
    Human controlAccuracy review, exception handling, interpretation, and final approvalKeep qualified ownership inside the teamEvidence standards, escalation rules, and accountability for the resulting decision

    This is a deliberate hybrid, not a compromise. You might buy the monitoring engine, hire a specialist to connect it to your reporting process, build a narrow layer containing your prioritization rules, and keep final interpretation with an analyst. Recreating the monitoring platform would add little advantage; handing your judgment to an opaque system would surrender too much.

    An MIT review of enterprise generative AI projects reported zero return among 95% of the organizations it examined, while external partnerships represented a higher share of successful deployments than internal development. That should not be converted into a universal failure probability: the initiative volumes were uneven, and there was too little hybrid build-buy evidence to quantify that route. The practical warning is narrower. A working prototype is not a successful deployment, especially when the system does not fit the way people already work.

    Do not automate work that nobody can verify

    Two people inspect assets at a checkpoint in an automated production line before approved items continue.

    Before discussing price or architecture, ask one gating question: can a named person on your team perform the task manually or reliably check the result? If the answer is no, pause the automation. You would be installing a system whose failures your team cannot recognize.

    Fluent output makes this risk easy to underestimate. A model can turn a spike in a group of Google Search Console queries into a confident claim that AI visibility is rising, even though the data does not establish that conclusion. The error can look polished enough to enter a leadership meeting unless someone understands both the data and the inference being made.

    Only 13% of marketers fully trust AI output without a human reading it. That is not merely an adoption problem. It is a staffing and workflow requirement: the review still needs time from someone qualified to judge the work.

    The State of CRM Data Report 2026 found that nearly 78% of C-suite respondents and 92% of SVP or VP respondents had acted on an AI recommendation they later suspected was wrong because of poor underlying data. The corresponding figure among individual contributors was 41%. These are self-reported suspicions, not measured model error rates, but they expose an important control problem: the person with authority to act may be farther from the evidence needed to challenge the recommendation.

    Create a verification contract before you automate. It should answer:

    • What decision can this output influence? A draft that stays in an editor is different from a report that changes budget or reaches an executive.
    • What evidence should support the answer? Require links, source records, query data, calculation inputs, or another trace that the reviewer can inspect.
    • Who is qualified to review it? Assign a person or role, not an unspecified human in the loop.
    • What counts as an unacceptable error? Define concrete failure classes such as fabricated facts, incorrect data mapping, unsupported attribution, missing exceptions, or off-brand recommendations.
    • What happens when confidence is low or evidence is missing? Route the case to a person rather than letting the system improvise.
    • Which outputs always require approval? Keep review on every output that can publish content, contact a customer, alter spending, or materially influence a leadership decision.

    If no one can fill in that contract, your next investment is expertise, not automation. Narrow the task, train an owner, or obtain specialist help before deploying the tool.

    Buy common capability, outsource the learning curve, build your edge

    Buy when the underlying problem is common

    Buying is usually the sound route when thousands of other teams need substantially the same capability. Tracking, monitoring, crawling, diagnostics, and scoring all require unglamorous infrastructure work: connectors change, interfaces break, usage grows, and edge cases accumulate. A mature vendor spreads that work across its customers and provides someone to fix the product when it fails.

    Do not evaluate only the demo. Ask the vendor to show how the product handles your real inputs and exceptions. Confirm:

    • whether it supports the data systems you actually use;
    • how it logs inputs, changes, failures, and human approvals;
    • whether reviewers can inspect the evidence behind an output;
    • how data, configurations, and results can be exported;
    • which maintenance and support work is included;
    • how usage, seats, or additional integrations affect cost;
    • what happens to your workflow when the vendor changes a model or feature; and
    • what access controls apply before customer, employee, or proprietary data enters the system.

    The product does not need to mirror your process perfectly out of the box. It does need to cover the commodity layer without forcing your team to become its unpaid engineering and support department.

    Outsource when the workflow is yours but the learning is temporary

    Your approval chain, internal taxonomy, reporting schedule, subject-matter-expert process, and pre-approved copy may be unique. The implementation problems hiding underneath them often are not. Someone who has configured similar workflows already knows where handoffs fail, which exceptions need human input, and which apparently simple steps become brittle when automated.

    Use a practical test: will your team apply the knowledge gained from building this every week? If not, paying employees to discover each failure mode for the first time is an expensive way to acquire one-use expertise. Buy the learning curve through a validated template, a focused consultation, a short implementation engagement, or a specialist resource library.

    Outsourcing should leave you with an operable system, not a permanent mystery. Put these deliverables into the engagement:

    • a map of the workflow, inputs, outputs, owners, and exceptions;
    • documented configuration and administrator access;
    • acceptance tests covering normal, messy, and missing inputs;
    • a failure log describing known limits and escalation paths;
    • training for the internal owner and reviewers;
    • a handover plan, maintenance estimate, and change process; and
    • clear ownership and export rights for data, prompts, rules, documentation, and other deliverables.

    Keep an internal owner involved throughout. A handoff at the end cannot recover reasoning and decisions that were never documented.

    Build when the capability creates durable advantage

    Building internally makes sense when the system encodes something meaningfully different about how you market, not merely because your workflow has custom field names. Your team should be able to answer yes to all of these questions:

    • Does the logic create a real advantage rather than duplicate a standard product feature?
    • Will your team use and improve the resulting technical or operational knowledge regularly?
    • Are your requirements unlikely to be met through configuration, integration, or a narrow extension of existing software?
    • Can you assign an enduring product owner and the people needed to test, monitor, document, and repair it?
    • Will ownership survive if the original builder changes roles or leaves?
    • Can a qualified person verify the system’s output and stop it when it behaves incorrectly?

    An internal prototype may appear inexpensive because its future obligations are invisible. Once colleagues depend on it, the team owns permissions, changing integrations, model behavior, tests, documentation, support, incident response, and every request for a small improvement. If those duties do not have owners, the organization has created software without creating a software function.

    Build the narrowest layer that contains your advantage. Purchasing a stable platform and adding your own orchestration or decision rules is often more defensible than rebuilding data collection, authentication, dashboards, and administrative features around it.

    Use a hybrid route deliberately

    A strong marketing AI workflow may use all three routes. A vendor collects visibility data. A specialist maps the data to your taxonomy and approval path. Your team encodes its prioritization rules and approved CTA library. An analyst reviews anomalies and interpretation before the report reaches leadership.

    Write the boundary between those layers down. Specify who owns the data, configuration, custom logic, review, maintenance, and recovery process. Hybrid systems become fragile when every participant assumes somebody else owns the seam.

    Make the decision in 30 minutes, then test one handoff

    You do not need a long procurement exercise to choose an initial route. You do need a disciplined comparison that counts work beyond the visible fee.

    Use this 30-minute decision agenda

    1. Minutes 0-5: define the outcome. Name the marketing result, the user, and the decision the workflow should improve. Reject objectives such as use AI or automate content; they do not define value.
    2. Minutes 5-10: map the steps. Draw each input, transformation, review, exception, and output. Do not route the workflow until you can see its parts.
    3. Minutes 10-15: classify the layers. Mark each step as common capability, company-specific implementation, differentiating logic, or human control.
    4. Minutes 15-20: apply the verification gate. Name the reviewer, required evidence, unacceptable errors, and escalation path.
    5. Minutes 20-25: compare lifecycle cost. Add internal labor, implementation, review, maintenance, support, and displaced marketing work to the visible price.
    6. Minutes 25-30: choose a route and pilot boundary. Decide what to buy, outsource, build, or leave manual. Assign an owner and state what evidence would justify expansion.

    Compare total cost on the same basis

    A subscription price cannot be compared directly with a development estimate. Use the same operating horizon and the same labor assumptions for every option.

    • Buy: subscription or usage charges, implementation, integrations, internal administration, review, training, migration, and eventual exit work.
    • Outsource: specialist fees, required software, internal subject-matter-expert time, review, training, handover, and ongoing maintenance.
    • Build: discovery, meetings, design, development, testing, infrastructure, documentation, monitoring, support, review, repairs, and the marketing work displaced by those hours.

    Calculate internal labor using the time of every contributor, not just the person writing prompts or code. Include the people clarifying requirements, attending meetings, preparing data, testing outputs, correcting errors, approving work, and responding when the workflow breaks.

    Then name the opportunity cost in operational terms. Which campaign, analysis, customer interview, content update, or technical fix will wait while the team builds and maintains this? If no displaced work appears in the comparison, the internal option has been priced as though staff time were unlimited.

    Keep consequence separate from speculative arithmetic. If a bad output could publish an unsupported claim, misclassify performance, expose sensitive data, or redirect budget, record that failure and the control that prevents it. Do not invent a precise dollar value merely to make the spreadsheet look complete.

    Pilot a bounded step before replacing a job

    Test one handoff whose output can be compared with the existing process. A narrow pilot reveals whether the proposed route reduces work or merely moves it into checking, correction, and maintenance.

    1. Capture the baseline. Record the current input, output, turnaround, human effort, recurring errors, and approval path.
    2. Prepare test cases. Include normal inputs, incomplete data, unusual cases, and situations that should be escalated rather than answered.
    3. Define acceptance before testing. State the required evidence, allowed error classes, review time, and conditions that would stop the pilot.
    4. Run in shadow mode. Compare results without letting the system publish, send, spend, or change a production record on its own.
    5. Log every intervention. Separate factual corrections, data-mapping problems, brand edits, integration failures, and exceptions. That log shows whether the problem is the model, the implementation, the input, or the process itself.
    6. Calculate net value. Subtract review, repair, administration, and maintenance effort from gross time saved. Include improvements in consistency or turnaround only when the pilot demonstrates them.
    7. Decide explicitly. Expand, revise, change the sourcing route, keep the step manual, or stop. Name the production owner and rollback method before expansion.

    Stop or narrow the automation when failures are hard to detect, review consumes most of the apparent saving, changing inputs repeatedly break the workflow, or nobody accepts maintenance ownership. That is useful pilot evidence, not a reason to keep investing until the original idea appears justified.

    Take the next proposed marketing automation and draw its steps on one page. Mark each box buy, outsource, build, or human control. Do not approve procurement or development until every box has a verification owner and the resulting system has a lifecycle owner. The goal is not to own more AI software. It is to improve a marketing outcome with the smallest reliable system that your team can understand and sustain.

    References


  • Profound’s $180M Funding: What Marketing Teams Should Test

    Profound’s $180M Funding: What Marketing Teams Should Test

    If you are deciding whether Profound’s funding makes its platform a safer strategic bet, separate two questions immediately: Does the company have more capacity to pursue its vision, and can the product remove work from your marketing operation? The first is supported by the raise. The second still requires proof inside a workflow that matters to you.

    That distinction will keep a large funding number from becoming a substitute for product, governance, and commercial due diligence. It also gives you a practical way to evaluate AI Marketer without either dismissing the platform or buying the story before testing the system.

    What Profound has actually committed to

    Profound has raised $180 million to build an AI platform for marketing. Its stated premise is that AI is generating additional work for marketers, not simply automating existing tasks. AI Marketer is positioned as the response: a system that brings company context and agents together so marketing teams can get that work done.

    Those points establish capital, direction, and a product thesis. They do not establish the return a customer will receive. A funding total cannot tell you whether the platform fits your data, integrates with your operating stack, produces reliable outputs, shortens approval cycles, or reduces the total cost of a workflow.

    The stated goal also indicates a broad platform ambition rather than a single-purpose feature. That can be valuable when your work crosses research, analysis, content, brand governance, and execution. It can also increase implementation scope. The more jobs a platform is expected to coordinate, the more important permissions, source quality, handoffs, and ownership become.

    Use the announcement as a reason to ask better questions, not as the answer to them. Do not add unconfirmed details about valuation, investors, product allocation, delivery dates, or business performance to your internal brief. If one of those details affects your decision, request it directly and distinguish a written commitment from a forward-looking plan.

    Why more AI can create more marketing work

    A marketing team sorts and reviews a growing flow of campaign materials produced by several automated machines.

    AI reduces the cost of producing an output, but output generation is only one part of marketing. Every new model, answer surface, automated campaign, and content variant can create additional monitoring, interpretation, validation, approval, and measurement work. Faster production can therefore move the constraint downstream rather than remove it.

    You can see that effect by mapping the full chain around an AI-assisted task:

    • Inputs: Someone must select the relevant brand rules, product facts, audience assumptions, performance data, and prior decisions.
    • Generation: A model or agent produces an analysis, recommendation, brief, campaign asset, or other deliverable.
    • Verification: A person checks factual accuracy, source quality, brand fit, compliance, and whether the output answers the original question.
    • Execution: The approved output must reach the correct channel, owner, or system without losing its context.
    • Learning: Results must return to the process so that the next action reflects what changed.

    A platform can make generation faster while leaving every other stage intact. It can even increase review work if it produces more material than your team can verify. That is why prompts completed, agents deployed, and assets generated are weak measures of operating value on their own.

    Before watching a demonstration, draw one real workflow from request to approved outcome. Mark every system, human handoff, approval, wait state, and rework loop. Record the elapsed time, active working time, and recurring errors using evidence you already have. You now have a baseline against which automation can be judged.

    If your remit includes AI search visibility or generative engine optimization, a suitable workflow might begin with a visibility finding and end with an approved content or entity-data change. The test should include the analysis, supporting evidence, assignment, revision, publication approval, and follow-up measurement. Automating only the first step does not automate the workflow.

    What company context and agents must prove

    The combination of company context and agents is the central idea behind AI Marketer’s positioning. Those terms can sound complete while hiding the hardest implementation questions. Treat them as two systems to test separately.

    Test context as a governed source of truth

    Company context should do more than place files near a model. It should help the system select current, authorized information and show you what influenced an output. Ask for a live demonstration that answers these questions:

    • Which repositories, pages, records, and instructions can the system use for this task?
    • How does it decide which source is authoritative when two sources conflict?
    • How quickly does a changed product fact, policy, or brand rule become available?
    • Can access be limited by team, role, market, client, or workspace?
    • Can a reviewer trace an output back to the facts and instructions that shaped it?
    • What happens when the required evidence is missing, stale, or ambiguous?

    Do not test this with a polished sample library. Bring a controlled set of realistic material that includes one outdated item, one conflict, and one fact the system should not expose to every user. Designate the correct source in advance. A useful context layer should handle the conflict predictably, respect access boundaries, and make its reasoning inspectable enough for a reviewer to catch a mistake.

    Test agents as bounded operators

    An agent is valuable when it can advance work without gaining more authority than the task requires. Evaluate its operating boundaries, not only the quality of its final output:

    • What triggers the agent, and who can change that trigger?
    • Which data can it read, and which systems can it alter?
    • Which steps require human approval before the agent proceeds?
    • Can you stop a run immediately and prevent it from retrying?
    • Does the audit history preserve inputs, actions, outputs, approvals, and failures?
    • How does the agent behave when a dependency is unavailable or the evidence is inconclusive?
    • Can its work be exported, reassigned, or completed manually?

    Run the same task after changing a canonical input, revoking a permission, and withholding a required fact. You are looking for controlled behavior: the output should update when the approved context changes, access should disappear when permission is removed, and the agent should stop or escalate when it cannot support an answer.

    Do not grant autonomous publishing or campaign-changing permissions merely to make a pilot look complete. An opaque error can create public misinformation, brand damage, or avoidable spend. Start with read access, draft outputs, explicit approval gates, and a visible audit trail. Expand authority only after the failure behavior is understood.

    Turn the funding story into a procurement test

    A cross-functional team evaluates an AI agent in a transparent test chamber using visual checkpoints for quality, security, time savings, and commercial value.

    New capital can support product development, infrastructure, implementation, hiring, or market expansion, but the amount alone does not tell you which customer outcomes will improve. Ask Profound to connect its funded platform direction to the operating requirements in your evaluation.

    Use a short, evidence-based process:

    1. Separate product from roadmap. Mark every required capability as available, configurable, dependent on services, planned, or unsupported. Ask for written confirmation of anything that affects the purchase.
    2. Select one costly workflow. Choose a process with a clear owner, recurring inputs, an observable outcome, and enough friction to justify change. Do not begin with a broad goal such as improving marketing productivity.
    3. Run your material through the system. Use representative company context, normal approval requirements, and the systems the production workflow would need. A vendor-curated example cannot expose your integration or governance problems.
    4. Measure total work. Compare active effort, waiting, handoffs, corrections, and review demand with the baseline. Count work displaced to administrators, analysts, agencies, or implementation teams.
    5. Test failure and exit paths. Introduce stale context, a conflicting instruction, a denied permission, and an unavailable dependency. Then verify how you export outputs, retrieve records, remove data, and continue the workflow if the platform is unavailable.

    A pass-or-fail scorecard keeps the evaluation focused when a demonstration is visually impressive:

    DimensionEvidence to requestReason to pause
    Workflow valueA proof run showing less total effort, delay, or reworkThe claimed value depends mainly on future features
    Context integritySource traceability, conflict handling, freshness controls, and scoped accessThe system cannot explain which facts governed an output
    Agent controlLeast-privilege permissions, approvals, stop controls, and audit historyAgents require broad access or take opaque actions
    Operational fitWorking integrations, clear ownership, administration, and support pathsManual bridges recreate the work you intended to remove
    Commercial durabilityWritten terms for current capabilities, service levels, support, and pricingThe funding total is used in place of contractual commitments
    Exit safetyDocumented export, deletion, access removal, and offboarding proceduresYour data or workflow history cannot leave cleanly

    Funding matters most where it changes the risk of relying on the platform. Ask which capabilities exist now, which dependencies require professional services or third-party systems, what support is included, and how roadmap changes are communicated. For every answer, identify the proof: a live control, a technical document, a contractual term, or merely an intention.

    Data handling deserves the same precision. Confirm what information the system stores, where it is processed, who can access it, how long it is retained, whether it is used to improve models, and how deletion is verified. If your marketing context contains customer, partner, employee, or confidential product information, involve the people responsible for security, privacy, and legal review before production access is granted.

    Key takeaways

    • Profound’s $180 million raise supports its ability to pursue an AI platform for marketing, but it does not prove customer outcomes.
    • AI can create work after generation, especially in verification, approval, execution, governance, and measurement. Evaluate the whole workflow.
    • Company context must demonstrate source authority, freshness, traceability, conflict handling, and permission boundaries.
    • Agents must demonstrate limited authority, approval controls, predictable failure behavior, auditability, and a safe manual path.
    • Your decision should depend on production-like evidence and written commitments, not funding momentum or a curated demonstration.

    For your next step, take one workflow into the evaluation meeting and bring its real inputs, permissions, exceptions, and approval rules. Ask Profound to show what AI Marketer does at each stage, what remains human work, and which capabilities are available now.

    A platform is worth adopting when it reduces the total burden of producing a trustworthy marketing outcome while preserving control. The funding gives Profound room to pursue that standard. Your proof run should determine whether the product meets it for you.

    References


  • Leading RevOps Firms: How to Choose a Fractional Agency

    Leading RevOps Firms: How to Choose a Fractional Agency

    You are not buying RevOps in the abstract. You are deciding whether an outside team can repair your revenue engine without slowing sales, damaging CRM data, or leaving you with an expensive system nobody internally knows how to run.

    The difficult part is that fractional leadership, managed operations, CRM implementation, enablement, and AI automation are often sold under the same label. The right choice depends less on which firm tops a general leaderboard and more on the work you need someone to own. This guide helps you identify that work, match it to leading RevOps firms, and test whether a candidate can deliver it.

    Key takeaways

    • Choose the engagement model before the agency. Embedded fractional ownership, managed RevOps, project implementation, and coaching solve different problems.
    • Match lifecycle breadth to the actual break. A problem spanning marketing, sales, onboarding, retention, and expansion needs broader coverage than a contained CRM or outbound project.
    • Do not mistake a long platform list for operational depth. Test the candidate against a real workflow, data model, integration, or handoff from your environment.
    • Make every AI claim concrete. Require a named workflow, defined data access, approval rules, evaluation criteria, logs, failure handling, and a human owner.
    • Replace generic ranking weights with your own priorities. Published 2026 methodologies give substantially different weight to leadership, platforms, AI implementation, and lifecycle scope.
    • Treat recognizable client logos as context, not proof of fit. Even the ranking methodologies used for this shortlist assigned notable clients only 5% of the total score.

    Choose the RevOps engagement model before the firm

    A leadership team compares three visual pathways representing fractional leadership, managed operations, and technical implementation services.

    Fractional describes how you access leadership or operating capacity. It does not guarantee that a senior operator will be embedded in your team, that the agency will configure systems, or that it will cover the complete customer lifecycle. Confirm the operating model in the contract rather than relying on the label.

    • Embedded fractional ownership: Choose this when no internal leader owns the revenue system across functions. The outside operator should make decisions, coordinate stakeholders, prioritize work, and remain accountable for implementation rather than merely recommend changes.
    • Managed RevOps or RevOps as a Service: Choose this when you have an ongoing queue of administration, reporting, automation, data, and process work but do not want to assemble an internal team. The central buying question is how strategic decisions and recurring execution are divided.
    • Project-based specialist: Choose this for a bounded migration, CRM rebuild, routing redesign, CPQ implementation, outbound system, or integration. A contained scope should have explicit deliverables, acceptance tests, change controls, and a handoff owner.
    • Coaching, methodology, or enablement: Choose this when your internal team can implement but needs a common sales process, operating language, management cadence, or training system. Do not buy advisory work if your real constraint is a lack of hands-on capacity.

    Map the failure before contacting vendors. Trace the customer path from acquisition through qualification, opportunity management, closed-won, onboarding, adoption, renewal, and expansion. Mark the point where ownership becomes unclear, data stops moving, or teams begin using conflicting definitions.

    If failures appear across Marketing Operations, Sales Operations, and Customer Success Operations, favor a full-lifecycle team. If the problem stays inside a known system or workflow, a specialist may be faster and easier to govern. If your team knows what to do but applies it inconsistently, coaching may be sufficient. If nobody has authority to decide what should happen, you need an accountable fractional leader before you need more tools.

    A useful buying brief fits in one sentence: We need an accountable owner to improve this lifecycle handoff in these systems, with success judged by these business and operational measures. If you cannot complete that sentence, use discovery to define the problem before committing to a large implementation.

    Leading RevOps firms, organized by the work they fit

    No firm is the universal best choice. The table below treats leading RevOps companies as a fit map: what each appears equipped to handle, followed by the issue you should validate before signing.

    FirmConsider it whenWhat to validate
    DomestiqueYou are a B2B SaaS company seeking embedded, full-lifecycle coverage across Marketing Operations, Sales Operations, Customer Success Operations, platform implementation, and agentic infrastructure. Its reported capabilities include more than 60 senior operators, work with more than 250 B2B organizations, and hands-on AI agents and MCP integrations.Confirm which senior operators will work on your account, their allocated capacity, and the leadership participation expected from your team. The fractional-agency assessment specifically notes that active client leadership involvement is important at the strategy layer.
    Go NimblyYou run a Salesforce- or HubSpot-centered growth-stage SaaS environment and need revenue architecture, technical execution, AI readiness work, or RevOps coaching. Its positioning combines AI-enabled GTM strategy with Salesforce, HubSpot, Outreach, and Salesloft experience.Define how much hands-on Customer Success Operations coverage is included. Also identify the exact team composition because reported delivery pace can depend on scope and staffing.
    SkaledYou need a modular intervention rather than complete outsourced ownership. Available services span fractional CRO or VP leadership, CRM and automation support, revenue enablement, outbound performance, and an AI GTM system. A NoFraud case study reports a 126% pipeline increase and 95% MQL growth over eight months, but that result is case-specific rather than a forecast for another company.Ask who coordinates work when your scope crosses leadership, administration, enablement, and AI practices. Confirm which result from the relevant case work is transferable to your market, team, and funnel.
    RevPartnersYou are committed to HubSpot and want an ongoing RevOps-as-a-Service model, lifecycle measurement, GTM engineering, or Clay-powered outbound automation. Its Revenue Performance Model connects acquisition, conversion, retention, and expansion.Test the required depth outside HubSpot and Clay. Salesforce-primary companies and teams requiring extensive hands-on Customer Success Operations should define those needs explicitly before assuming they are covered.
    FullFunnelYou need broad B2B GTM strategy plus Sales Operations, Marketing Operations, or managed RevOps. Its listed platform footprint includes HubSpot, Salesforce, Clay, Apollo, and n8n.Ask which lifecycle stages the proposed team will own, which it will support, and which remain with you. Platform breadth should be converted into named deliverables and accountable operators.
    OperatusYour requirements center on Salesforce CPQ, MuleSoft, systems integration, or managed RevOps in a stack that may also include HubSpot, Apollo, Salesloft, LeanData, Outreach, or Marketo. Those platform and consulting specialties distinguish its systems-oriented offer.Verify whether your scope needs a technical implementation partner, a cross-functional operating leader, or both. Do not assume CPQ and integration expertise automatically includes deep marketing and post-sale ownership.
    Winning By DesignYou already have people who can execute and primarily need GTM methodology, the SPICED framework, revenue coaching, or certification. Its listed specialty is methodology training and advisory rather than comprehensive outsourced operations.Separate enablement deliverables from system-building deliverables. If you need CRM administration, integration work, data remediation, or ongoing workflow ownership, identify who will perform it.
    Think RevOpsYou want RevOps as a Service or stack optimization across HubSpot, Salesforce, and Gainsight. The inclusion of Gainsight makes it worth considering when customer-success tooling is part of the operating problem.Request direct evidence for any AI implementation requirement. AI or agentic capability was not listed for the firm in the 2026 fractional-agency comparison.
    RevOps AutomatedYou need GTM strategy, system integration, managed services, or AI-powered workflow automation in HubSpot and Salesforce. Its positioning emphasizes automation and AI-powered GTM workflows.Ask to see the architecture, controls, and operational results of a comparable workflow. Also define the required Customer Success Operations depth rather than inferring it from the managed-services label.
    Process Pro ConsultingYou have a focused HubSpot build, cleanup, or optimization requirement and prefer a specialist over a broad multi-platform firm. Its listed proficiency and specialty are centered on HubSpot.Inventory every system that must exchange data with HubSpot. If Salesforce, customer-success platforms, or agentic automation are material to the scope, determine whether another specialist will be needed.

    Your preferred order can change simply by changing the scoring weights. The fractional-agency methodology assigned 30% to platform proficiency and 30% to AI and agentic capability. The broader RevOps methodology assigned 30% to leadership, 25% to platforms, 20% to customer reviews, and 10% each to AI capability and lifecycle scope. A company prioritizing AI infrastructure could therefore reach a different answer from one prioritizing executive leadership or full-lifecycle operations.

    Rewrite those weights around your own risk. If your CRM is unstable, architecture and implementation depth should dominate. If functions disagree about stages, ownership, or forecasting, leadership and lifecycle scope matter more. If you already have strong operators and need a repeatable selling method, coaching quality should carry more weight than platform breadth.

    Do not let a logo wall override this work. Notable clients accounted for only 5% in the fractional-agency methodology and 5% in the broader company methodology. A famous client proves that some relationship existed; it does not establish that the agency handled your use case, systems, lifecycle stage, or engagement model.

    Use a buying process that exposes delivery risk

    Client and agency teams test a modular revenue workflow together while reviewing handoffs, system access, and contingency paths.

    Give every candidate the same written brief and ask for the same evidence. Otherwise, the most polished pitch will seem like the strongest capability even when candidates are solving different versions of your problem.

    Identify the operator who will actually own the work

    A senior leadership page does not tell you who will attend your operating meetings, make architecture decisions, configure systems, or resolve conflicts between marketing, sales, finance, and customer success. Ask the candidate to name the proposed operator and explain the delivery chain.

    • Who is accountable for the business outcome, and who performs the implementation?
    • Which proposed team members are employees, contractors, specialists, or executive sponsors?
    • How much concurrent client work does each assigned operator carry?
    • Who has authority to approve process, data-model, and automation decisions?
    • What happens when a requirement crosses practice areas or falls outside the original platform specialty?
    • Which responsibilities remain with your internal leaders, administrators, analysts, and front-line managers?

    Listen for clear ownership, not a large roster. A fractional executive who cannot direct implementation may leave you coordinating multiple delivery teams. An administrator without authority may complete tickets while the underlying operating disagreement remains untouched.

    Test platform depth with one of your real workflows

    Partner status and certifications are useful screening signals, but they do not prove that the proposed operator has solved your specific architecture problem. Bring a representative workflow to the evaluation: lead routing, account matching, opportunity-stage governance, CPQ approval, marketing attribution, closed-won handoff, renewal management, or expansion identification.

    Ask the candidate to map the systems of record, objects, fields, triggers, dependencies, permissions, exception paths, and reporting effects. Strong operators will surface ambiguities before proposing automation. Weak answers jump directly to a tool or produce a generic diagram that could apply to any company.

    Protect production data during implementation. Do not permit bulk CRM writes, object changes, routing changes, destructive merges, or new automations without an approved backup or export, a test environment where the platform supports one, defined validation checks, a release owner, and a rollback plan. A failed routing rule can hide demand; a poorly governed merge or overwrite can destroy history needed for attribution, forecasting, or account management.

    Trace ownership through the complete customer lifecycle

    Full-funnel language can describe measurement rather than hands-on ownership. Ask each candidate to walk through the lifecycle and identify who designs, implements, monitors, and improves every important handoff.

    • Acquisition to qualification: Who defines fit, intent, routing, response expectations, and rejection reasons?
    • Qualification to opportunity: Who governs stage entry, required fields, ownership changes, and pipeline reporting?
    • Closed-won to onboarding: Which data crosses the handoff, where is it stored, and who checks completeness?
    • Onboarding to adoption: How do product, service, or customer-success signals become visible to the revenue team?
    • Adoption to renewal: Who owns renewal dates, risk signals, commercial actions, forecasts, and escalation?
    • Renewal to expansion: How are expansion opportunities identified, assigned, measured, and separated from retention?

    If the answer becomes vague after closed-won, you are probably evaluating a sales-and-marketing operations firm rather than a complete lifecycle partner. That may be the right fit, but it should be an explicit decision rather than a discovery made after the engagement begins.

    Turn AI positioning into an auditable system design

    AI readiness, AI strategy, agent deployment, and agentic infrastructure are different deliverables. Domestique lists MCP server deployments, a deterministic harness framework, and Claude and Clay agents. Go Nimbly emphasizes AI-enabled architecture and readiness. Skaled combines maturity benchmarking, deployment, training, and certification. RevPartners focuses on Clay-powered allbound automation, while RevOps Automated emphasizes AI-powered GTM workflows. Put the exact capability you need into the scope instead of purchasing the broadest label.

    • Use case: What specific decision or task will the system assist, automate, or execute?
    • Inputs: Which CRM records, conversations, documents, enrichment data, or customer-success signals can it read?
    • Permissions: Can it only recommend an action, or can it create, update, route, message, or delete?
    • Control: Which actions require human approval, and who is accountable for that approval?
    • Evaluation: How will you test accuracy, completeness, consistency, and business usefulness before release?
    • Observability: What prompts, tool calls, outputs, errors, and record changes are logged?
    • Failure handling: What happens when the model is unavailable, uncertain, wrong, or given incomplete data?
    • Ownership: Who maintains instructions, integrations, permissions, evaluations, and vendor dependencies after launch?

    A working demo is more valuable than an AI strategy slide. Use representative but non-sensitive data and ask the candidate to show the complete path from input through reasoning or rules to the resulting CRM action. If the workflow can change customer records, routing, forecasts, or outbound messages, require approval boundaries and a recoverable path before production access is granted.

    Read reviews for engagement similarity, not just stars

    Review averages compress important differences. One 2026 methodology aggregated verified G2, Clutch, and Google ratings and rounded them to the nearest half star; the broader methodology weighted RevOps-specific engagements and rounded ratings to whole stars. Neither treatment tells you whether a positive review came from an embedded transformation, a migration, a small administration project, or executive coaching.

    Ask for references that match your company stage, primary platform, lifecycle problem, and engagement model. Questions about setbacks are more revealing than requests for general satisfaction: what slipped, which assumption proved wrong, how scope changed, who resolved cross-functional conflict, and what the client had to own internally.

    Scope the first engagement so you can judge real progress

    A strong statement of work turns RevOps language into operating commitments. It should make clear what will change, how you will accept it, who can decide, and how your team will run the result after the agency leaves.

    • Problem boundary: Name the lifecycle failure, affected teams, systems, records, and processes. Also state what is out of scope.
    • Baseline and outcome: Record the current operational and business measures that matter. Distinguish outputs such as workflows built from outcomes such as cleaner routing, more reliable stage data, better handoff completeness, or usable renewal visibility.
    • Target operating design: Define stages, ownership, systems of record, required data, decision rights, and escalation paths before automating them.
    • Deliverables: List the actual artifacts and system changes: architecture maps, data dictionaries, lifecycle definitions, configured workflows, dashboards, documentation, training, and governance procedures.
    • Acceptance criteria: State how each deliverable will be tested and who can approve it. Completion should not depend solely on the agency declaring a task done.
    • Change control: Specify test procedures, production permissions, release approval, backups, rollback, and incident ownership.
    • Internal participation: Name the executive sponsor, operational owner, system administrator, subject-matter experts, and front-line users whose decisions or feedback are required.
    • Handoff: Require accessible documentation, administrator training, unresolved-risk tracking, credential and integration ownership, and a prioritized backlog for work that remains.
    • Commercial boundaries: Clarify which work is included, what triggers additional fees or a change request, and how staffing changes affect delivery.

    If your problem is still poorly defined, make the first phase a diagnostic with implementation-ready outputs: a current-state map, target-state design, prioritized backlog, ownership model, dependencies, risks, and acceptance criteria. Do not accept a generic strategy presentation that forces the implementation team to rediscover the same requirements.

    Before your next agency call, write the one-sentence problem, list the systems involved, mark the affected lifecycle handoffs, and identify the proof you need to see. Send the same brief to each candidate. The safer choice is usually the firm that sharpens your scope, names tradeoffs, assigns an accountable operator, and makes its implementation testable.

    References


  • Yelp Data in ChatGPT: A Local Visibility Action Plan

    Yelp Data in ChatGPT: A Local Visibility Action Plan

    If local customers find you through recommendations, your Yelp presence can now affect a conversation that happens before anyone opens Yelp. ChatGPT can use licensed Yelp business details, ratings, reviews, and photos when responding to local queries.

    You do not need a new ChatGPT setting to prepare for this. You need accurate business data, a Yelp profile that represents the current customer experience, consistent information on your own site, and a way to measure whether AI recommendations lead to useful actions.

    Key takeaways

    • ChatGPT can incorporate Yelp reviews, ratings, photos, and business information into answers to local queries.
    • Yelp branding and links are expected when Yelp content is used, but OpenAI controls how the resulting experience is presented.
    • Yelp’s Request a Quote feature is also slated to appear in ChatGPT local-services searches, shortening the path from recommendation to inquiry.
    • There is no disclosed formula showing how Yelp data is selected, weighted, refreshed, or combined with other information. A strong Yelp profile should be treated as one visibility input, not a guaranteed ChatGPT ranking tactic.
    • Your practical priorities are source accuracy, entity consistency, honest reputation management, representative photos, lead readiness, and repeatable monitoring.

    What the integration changes in local discovery

    A conventional local-search journey often sends a user to a results page, a map listing, a review platform, and then a business website. A conversational journey can compress those steps. Someone can describe a need, ask for nearby options, compare reputations, inspect photos, and continue toward an inquiry without conducting several separate searches.

    Yelp’s contribution is a licensed layer of local evidence. ChatGPT gains access to real-time local recommendation data that includes reviews, ratings, photos, and business details. That gives it material for questions such as which businesses serve a particular need, what customers tend to mention, and how the available options appear to differ.

    Do not interpret the phrase real-time as a promise that every Yelp edit will appear in every ChatGPT response immediately. No synchronization interval or refresh guarantee has been disclosed. Treat Yelp as an active data source, but verify important changes in both places instead of assuming that one update has propagated everywhere.

    The commercial path may become shorter as well. Request a Quote is expected to support provider contact from ChatGPT local-services searches, including actions related to consultations or appointments. For a service business, visibility may therefore turn into an inquiry inside the conversational experience rather than a visit to the business’s website.

    This also makes attribution more complicated. A customer may discover you in ChatGPT, inspect Yelp-derived information, request a quote, and never generate a conventional organic-search session. Website traffic alone will not describe that journey.

    What you can control, and what you cannot

    You can control the accuracy of information you publish, the quality of your profile, the customer experience that produces reviews, and how reliably your team handles inquiries. You cannot control whether a particular prompt invokes Yelp data, which businesses ChatGPT includes, how Yelp information is summarized, or where a citation appears.

    That distinction matters because OpenAI, not Yelp, controls the presentation. Yelp branding and links are intended to accompany its content when used, but that does not mean every local answer will contain a Yelp link or preserve Yelp’s familiar listing layout. A conversational answer may select, condense, or contextualize the available information differently.

    No public ranking recipe accompanies the integration. There is no disclosed Yelp-rating threshold for inclusion, no stated review-count requirement, no guaranteed placement for advertisers, and no evidence that adding a particular schema property forces ChatGPT to cite a business. Anyone promising a deterministic optimization formula is going beyond what is known.

    Source visibility still matters. A Morning Consult survey found that 65% of Americans had used AI search, only 15% trusted it a lot, and 72% believed AI platforms should always identify their information sources. Yelp branding can help a user inspect the evidence behind a recommendation, but your listing must withstand that inspection. A citation is not useful if it sends the customer to stale details, unrepresentative photos, or unresolved complaints.

    The agreement is also non-exclusive, and Yelp already licenses data to Apple Maps and Yahoo+. That makes profile maintenance a cross-channel task. Do not create a special version of your business for ChatGPT. Maintain one defensible set of facts that can survive distribution across Yelp’s wider network.

    Run this Yelp-to-ChatGPT readiness audit

    A cafe owner compares a laptop and phone with icon-based cards for location, contact details, hours, photos, services, and customer feedback.

    Start at the data layer that ChatGPT can actually receive. A polished website cannot directly repair an incorrect Yelp record, and structured data on your site does not overwrite Yelp content.

    1. Capture a baseline. Record the business details, rating, prominent review themes, photos, and available contact actions currently visible on Yelp. Save enough context to identify what changed later. Without a baseline, you cannot distinguish an integration change from an ordinary profile update.
    2. Resolve factual conflicts at their origin. Compare Yelp with the business’s official website and other profiles you actively maintain. Check the business name, location information, contact details, hours, service descriptions, and customer-facing policies. Decide which value is canonical, then correct each property through its own publishing workflow.
    3. Check what the profile implies, not just what its fields say. A technically accurate profile can still create the wrong expectation. Read it as a new customer would. Confirm that the categories, description, photos, and recent customer feedback collectively represent what the business currently does.
    4. Review reputation themes. Look for repeated praise, repeated complaints, and outdated perceptions. You cannot edit legitimate customer sentiment into a better story. You can fix the operational cause of a recurring problem, clarify a misunderstood offering, respond appropriately through the platform, and make current capabilities easier to verify.
    5. Inspect the photo set. Yelp photos can enter the ChatGPT recommendation experience, so check whether the visible collection accurately depicts the location, work, products, or service context. Remove or replace business-controlled images that are obsolete or misleading where the platform permits. Do not assume that a polished stock image is more useful than an accurate one.
    6. Prepare the inquiry handoff. If your category relies on estimates, consultations, or appointments, assign ownership for incoming quote requests. Confirm that the recipient can identify the requested service, respond with the information needed for a next step, and record where the inquiry originated. A shorter discovery path only helps when the operational handoff works.

    Your website and structured data remain useful, but they solve a different part of the problem. Keep visible business details and appropriate LocalBusiness structured data aligned. Mark up facts that users can verify on the page, and correct discrepancies rather than trying to hide them behind schema. JSON-LD can help machines interpret your owned pages; it is not a command that edits Yelp or guarantees selection in ChatGPT.

    Use your site to answer details that a review profile may not express clearly: what you offer, whom it is for, where it is available, what constraints apply, and how to take the next step. The goal is not to repeat Yelp. It is to make your first-party explanation and third-party reputation coherent when a person follows the citation and checks your official site.

    Measure visibility without pretending you know the ranking system

    Icon-based paths connect a conversational phone interface to website visits, phone calls, and storefront directions while a sealed abstract system remains hidden.

    A useful monitoring program separates retrieval, representation, and action. Combining them into one vague AI visibility score hides the problem you need to fix.

    • Retrieval: Does the business appear for a relevant local need, and does the response show Yelp branding or a Yelp link?
    • Representation: Are the business facts correct? Does the summary reflect the actual service? Are review themes presented fairly? Are displayed photos representative?
    • Action: Can the user reach an appropriate next step, such as visiting a profile, contacting the business, requesting a quote, scheduling, or navigating to an official page?

    Build a prompt set around the ways real customers describe the decision. Include category-and-location searches, problem-led searches, comparison questions, reputation questions, and branded questions about what customers say. Record the exact prompt, relevant location context, date, businesses mentioned, citations shown, factual errors, photos, available actions, and destination URLs.

    Keep the prompts and testing conditions consistent when you repeat the check. Treat each response as an observation, not a permanent rank. Conversational output can change, and the integration does not come with a fixed position-reporting system comparable to a traditional search-results page.

    Connect this monitoring to commercial records. Track ChatGPT referrals where they reach your site, Yelp profile activity where available, quote requests, calls, appointments, and qualified leads. Add a simple source question to intake when appropriate. If an inquiry happens inside ChatGPT, ordinary website analytics may never see the discovery step, so avoid declaring the channel ineffective merely because it produced no web session.

    When you find a problem, repair the correct layer. Fix a wrong Yelp fact on Yelp. Fix inconsistent official information on your website and other maintained profiles. Address a repeated service complaint operationally. Improve lead routing when inquiries go unanswered. Escalate a demonstrably incorrect ChatGPT representation through the feedback options available in that experience, while keeping a record of the prompt and cited material.

    Begin with the baseline audit, then monitor the customer journeys that matter to your business. The durable advantage is not a speculative ChatGPT trick. It is a local entity whose facts, reputation, visual evidence, owned content, and inquiry handling remain credible wherever Yelp data is distributed.

    References

  • How to Choose a HubSpot Revenue Operations Consulting Firm

    How to Choose a HubSpot Revenue Operations Consulting Firm

    If your HubSpot portal is messy, the tempting brief is simple: fix HubSpot. That brief is usually too small. A consultant can clean fields and rebuild workflows while leaving lead ownership, lifecycle definitions, forecasting, and customer handoffs just as fragmented as they were before.

    Your real decision is whether you need a HubSpot specialist, a Revenue Operations operator, or a firm that can do both. The framework below will help you define the job, build a relevant shortlist, test delivery depth, and contract for a system your team can operate after the consultants leave.

    Key takeaways

    • Hire a HubSpot specialist when the main problem is platform architecture, migration, integration, or configuration. Hire a RevOps firm when ownership, definitions, incentives, and handoffs are broken across marketing, sales, and customer success.
    • Use a hybrid firm when the operating model and the HubSpot build must change together. Confirm that it supplies both a senior process owner and a hands-on technical lead.
    • Shortlist firms by engagement shape, platform coverage, functional depth, and execution model. Partner tier, awards, reviews, and client logos are useful filters, not substitutes for fit.
    • Require concrete artifacts: a lifecycle map, data dictionary, automation inventory, integration design, migration controls, reporting definitions, enablement plan, and administrator runbook.
    • Ask who will work in the portal, how destructive changes will be tested, and what happens when an integration or automation fails.
    • If AI is included, insist on a named workflow, approved data inputs, human-review rules, logging, and a fallback path. An AI label is not an operating design.

    Decide which problem you are actually paying to solve

    A revenue operations specialist inspects broken and duplicated connections among five stages of a business process before opening a toolkit.

    Revenue Operations treats marketing operations, sales operations, and customer success operations as connected parts of the same revenue system. HubSpot is one place where that system can be implemented, but the platform cannot decide what your teams mean by qualified, who owns an idle opportunity, or when sales should return a lead to marketing.

    Automation encodes operating decisions. If those decisions are unresolved, faster automation produces faster confusion. Start with the failure you can observe, then choose the engagement that addresses its cause.

    What you can observeLikely engagementWhat completion should look like
    Duplicate properties, unreliable syncs, brittle workflows, or an incomplete migrationHubSpot implementation, integration, or platform optimizationA documented data model, tested integrations, controlled migration, monitored automation, and an administrator handoff
    Marketing and sales disagree about qualification, ownership, attribution, or pipeline stagesCross-functional RevOps design with CRM implementationAgreed definitions, entry and exit rules, named owners, exception paths, and corresponding HubSpot configuration
    The roadmap is understood, but nobody has the capacity or authority to operate itFractional RevOps or marketing operationsA prioritized operating backlog, a clear decision cadence, hands-on system ownership, and a plan for eventual internal ownership
    The portal is configured, but representatives work around it or managers maintain shadow spreadsheetsSales enablement, process redesign, and role-based adoption workFewer duplicate paths, usable views, manager inspection routines, role-specific training, and an explicit feedback process
    Ticketing, help desk work, renewals, and customer health are disconnected from the sales lifecycleService Hub and customer operations implementationDocumented support and escalation flows, connected customer records, ownership rules, and lifecycle reporting across the handoff

    Several rows may describe your situation. That does not automatically mean you need the broadest firm. It means one person must own the end-to-end architecture while specialists handle bounded work beneath it. Without that owner, a marketing workflow, sales process, customer service design, and integration can each be locally correct while the complete system remains incoherent.

    Write down the disputed operating decisions before you discuss software. Define your lifecycle stages, qualification rules, record ownership, system of record, revenue metrics, and exception paths. Mark any unresolved item as a decision the engagement must facilitate. Do not let an implementation team silently convert its preferred defaults into company policy.

    Build a shortlist around the work, not the badges

    The labels agency, consultancy, solutions partner, and fractional operator do not tell you who will design the process or touch the configuration. Look through the label to the firm’s actual operating model.

    For HubSpot work, leadership experience, customer reviews, partner tier, and HubSpot awards can narrow the market. For broader RevOps work, GTM platform breadth, experienced leadership, customer evidence, and complex-account experience add useful context. None of those signals tells you whether the proposed team has solved your type of handoff, whether its senior architect will remain involved, or whether it will perform the keyboard-level work.

    The following firms are useful names to investigate for particular engagement shapes. This is a starting map, not a universal ranking. Your scope, stack, industry constraints, internal capability, and desired working model determine the fit.

    Firm to investigateRelevant engagement shapeWhat to pressure-test
    DomestiqueFractional RevOps and marketing operations across the customer lifecycle, including migrations, technical implementation, funnel work, and a multi-platform GTM stackWhich senior operator owns cross-functional decisions, who performs weekly system work, and how knowledge transfers to your team
    Aptitude 8Complex HubSpot implementations, custom integrations, multi-hub architecture, platform optimization, and extensions beyond standard configurationArchitecture ownership after launch, integration monitoring, failure handling, and the boundary between custom development and maintainable native configuration
    SmartBug MediaService Hub, customer experience workflows, CRM implementation or migration, and sales coaching or trainingHow ticketing, service, sales, and customer-success data will share definitions and ownership rather than becoming separate HubSpot projects
    New BreedSales Hub and broader HubSpot migrations or implementations, including complex sales motions and integration workData reconciliation, sales-stage governance, representative adoption, manager inspection, and the post-launch administration model
    Six & FlowHubSpot-first RevOps, sales and marketing alignment, sales enablement, and AI or CRM enablementWhether a HubSpot-first recommendation matches your actual architecture, especially if Salesforce or multiple CRMs remain in scope
    SkaledOutbound performance, technology migration and support, sales alignment, and AI-enabled go-to-market executionWhich result depends on process, data, staffing, tooling, or message changes, and which part of the program the firm will directly own
    Go NimblyEmbedded RevOps work, revenue and technical architecture, fractional support, coaching, and AI-ready GTM foundations for SaaS or technology teamsThe embedded consultant’s decision rights, delivery cadence, technical contribution, and relationship with your functional leaders
    Winning by DesignRevenue architecture, GTM training, and methodology work built around the SPICED Framework and Bowtie ModelWhether you need methodology and enablement, system implementation, or both – and who translates the method into CRM fields, workflows, and reporting
    OperatusSalesforce CPQ, MuleSoft, RevOps as a service, and a stack spanning HubSpot, Salesforce, outbound, routing, and marketing automation toolsWhich platform is authoritative for each entity, how cross-platform changes are governed, and who supports the integration layer

    Apply hard gates before you debate presentation quality. A candidate should understand every critical platform in scope, have delivered the same shape of engagement, cover the functions affected by the change, and agree to an explicit execution model. It should also name the people who will do the work, not just the executives who join the sales call.

    • Platform gate: Can the team safely operate your real stack, including the systems that will remain outside HubSpot?
    • Engagement-shape gate: Has it handled a migration, fractional operating role, Service Hub build, outbound redesign, or custom integration comparable to yours?
    • Functional gate: Can it work with every team whose definitions or behavior must change?
    • Execution gate: Will it configure, test, document, and train, or will it stop at recommendations?
    • Accountability gate: Is there one named owner for architecture, decisions, risks, and acceptance?
    • Handoff gate: Will your internal team be able to diagnose, maintain, and extend the system at the end?

    A firm that fails a hard gate should not advance because it has a higher partner tier or a more recognizable client list. Those credentials may break a tie after delivery fit has been established.

    Turn the brief into a measurable engagement

    A vague request for HubSpot optimization invites vague proposals. Give every candidate the same one-page brief so differences in approach become visible.

    1. State the business failure. Describe what is happening in operational language: leads have no clear owner, managers cannot explain stage movement, renewals are missing from the customer record, or an integration creates conflicting values.
    2. Attach current-state evidence. Include the relevant portal inventory, object and property lists, workflow inventory, integration list, sample records, reports, process documents, and known data-quality problems. Remove or protect sensitive data before sharing it during procurement.
    3. Name the affected functions. Identify which marketing, sales, service, finance, operations, and technical owners must approve definitions or change their behavior.
    4. Set the system boundary. List what is moving into HubSpot, what remains elsewhere, which system should govern each important record type, and which integrations are in or out of scope.
    5. Expose unresolved decisions. Separate missing configuration from missing policy. If leadership has not agreed on qualification, attribution, ownership, or stage criteria, say so explicitly.
    6. Define done. Specify the artifacts, configured behavior, validation evidence, training, documentation, and ownership transfer required for acceptance.

    Use your own baselines and business targets. A consultancy can help validate how a metric is calculated, but it should not invent a success threshold merely because procurement expects a number. If your baseline is not trustworthy, establishing one is part of the work.

    Require artifacts that survive the engagement

    Strategy becomes operable when it is expressed as maintained artifacts, configured behavior, and acceptance evidence. The exact package will vary, but the following deliverables prevent essential knowledge from remaining in meeting notes or in a consultant’s head.

    DeliverableMinimum acceptance test
    Current-state and future-state lifecycle mapEach stage has a definition, entry rule, exit rule, owner, handoff, exception path, and corresponding system behavior
    CRM data model and dictionaryObjects, properties, associations, allowed values, naming rules, required fields, owners, and systems of record are documented
    Automation and routing inventoryEvery active workflow has a purpose, trigger, conditions, exclusions, owner, failure path, and retirement rule
    Integration architectureData direction, identity matching, overwrite behavior, conflict handling, permissions, monitoring, and support ownership are explicit
    Migration and cleanup planMapping, deduplication rules, test imports, approvals, reconciliation, backup, rollback, and exception handling are defined before production changes
    Reporting specificationEvery key metric has a plain-language definition, calculation logic, filters, data origin, refresh behavior, and accountable owner
    AI-assisted workflow specification, if applicableThe approved inputs, intended output or action, model and tool boundary, permission scope, human-review rule, logging, error handling, and fallback path are documented
    Enablement and administrator handoffRole-based instructions, governance rules, troubleshooting steps, open risks, credentials ownership, and the post-launch backlog are transferred to named internal owners

    Weak scope: Implement HubSpot for marketing and sales.

    Stronger scope: Facilitate agreement on the lead and opportunity lifecycle, map the approved CRM data model, migrate agreed records, configure ownership and routing, validate integrations and reporting, train each operating role, and deliver an administrator runbook with unresolved risks.

    If the lifecycle, data model, and system boundaries are still uncertain, make discovery an explicit deliverable before committing to the complete build. Discovery should finish with decisions, maps, risks, assumptions, a prioritized backlog, and an implementable scope. A slide deck that merely confirms the original ambiguity is not enough.

    Ask candidates to label assumptions and dependencies in their proposal. This reveals where pricing and timing could change: unavailable internal owners, undocumented integrations, poor data quality, conflicting executive definitions, limited API access, or a separate vendor that controls part of the stack. Change is easier to govern when the trigger is visible before the contract is signed.

    Interview and contract for a safe handoff

    A consultant transfers a key, an unmarked binder, and a toolkit to an internal administrator beside a completed modular business system.

    A polished sales presentation shows that a firm can sell an engagement. Your interview must show how it diagnoses, decides, builds, tests, escalates, and hands over the result.

    Ask questions that expose the delivery model

    1. Walk us through a comparable handoff from beginning to end. Listen for definitions, decision owners, system behavior, exceptions, testing, adoption, and measurement – not just a list of HubSpot features.
    2. Who will lead our work, who will configure the portal, and who reviews the configuration? Ask for named roles and expected involvement. Clarify what happens if a proposed team member is replaced.
    3. Show us an anonymized example of the artifacts we will receive. A lifecycle map, data dictionary, integration design, test plan, or administrator runbook reveals more than a general methodology diagram.
    4. How do you handle disagreement between marketing, sales, and customer success? A strong answer should explain facilitation, decision rights, documentation, and escalation. The consultant should not disguise an unresolved leadership decision as a software setting.
    5. How do you choose between native configuration, custom code, and another tool? Look for attention to maintainability, permissions, failure modes, administrator skill, and total operational burden.
    6. How will you test a migration or destructive cleanup? Require a staged approach, backup, reconciliation method, approval point, exception log, rollback path, and named decision-maker.
    7. What happens when a sync or workflow fails after launch? The answer should identify monitoring, alert ownership, triage, remediation, documentation, and the boundary between project support and ongoing operations.
    8. How will you establish the baseline and connect the work to an outcome? Listen for metric definitions and data validation. Be cautious if a firm promises a business result before it understands your baseline, dependencies, and adoption risks.
    9. How will users and managers change their behavior? Training alone is not adoption. Ask about role-specific processes, manager inspection, feedback, documentation, and who owns reinforcement after launch.
    10. What exactly does AI do in the proposed solution? Ask which decision or task it supports, which CRM data it can access, where data is sent, how output is reviewed, how errors are logged, and what happens when the model or external service is unavailable.
    11. What can our administrator operate without you at the end? The answer should connect system complexity to your team’s actual skills and identify any continuing dependency clearly.

    Watch for signals that the engagement will drift

    • The firm recommends a new tool or major reimplementation before inspecting your process, portal, data, and integration boundaries.
    • The senior operator runs discovery and then disappears, leaving an implementation team with no authority to resolve cross-functional decisions.
    • Every problem is described as a HubSpot configuration issue even when ownership, incentives, definitions, or management routines are clearly involved.
    • The proposal promises dashboards before defining the lifecycle, metric logic, required fields, and data-quality controls beneath them.
    • Migration language covers importing records but not matching identities, reconciling totals, logging exceptions, obtaining approval, or rolling back.
    • AI is presented as a general capability rather than a bounded workflow with approved data, evaluation, human oversight, logging, and fallback behavior.
    • Partner tier, certification volume, awards, or client logos are used in place of showing the proposed team’s relevant work products.
    • Post-launch ownership is vague. Nobody is named to monitor integrations, approve changes, maintain documentation, or manage the backlog.

    Put acceptance, control, and ownership in the contract

    • Named delivery team: Identify the engagement owner, architect, implementers, reviewers, trainers, and escalation contact, along with the process for substitutions.
    • Phases and acceptance: Tie each phase to deliverables, review responsibilities, approval criteria, and the consequence of rejected or incomplete work.
    • Decision rights: Record which decisions the consultant may make, which require client approval, and who resolves cross-functional disputes.
    • Assumptions and dependencies: Make access, internal participation, third-party vendors, data condition, and technical constraints visible.
    • Change control: Define how new requirements, unexpected data conditions, or platform limitations change scope, cost, sequencing, or delivery expectations.
    • Security and access: Require least-privilege access, approved handling of sensitive data, credential ownership, access removal, and disclosure of relevant subcontractors or external systems.
    • Configuration and data ownership: Confirm that your organization retains its portal, data, custom assets, configuration documentation, and administrator access.
    • Operational support: Define what is covered after launch, how issues are reported, who monitors failures, and what becomes a separate managed-service engagement.
    • Exit package: Require final diagrams, inventories, decision records, test evidence, unresolved risks, training materials, and the prioritized backlog.

    Do not approve property deletion, irreversible deduplication, workflow retirement, association changes, or a production migration without a recoverable backup, a controlled test, reconciliation evidence, an approval point, and a rollback owner. The downside is not merely a delayed project. It can be permanent data loss, incorrect routing, broken reporting, or customer-facing automation triggered from bad records.

    Give each finalist the same brief and ask for the same response structure: problem interpretation, approach, named team, assumptions, dependencies, risks, deliverables, acceptance process, and support model. This makes omissions visible. Then speak with references whose engagement resembles yours and ask what broke, how scope changes were handled, whether senior people stayed involved, and whether the internal team could operate the system afterward.

    Start by writing the failing lifecycle or handoff in one sentence and attach the evidence behind it. Send that brief to firms selected for the shape of the work. The right HubSpot and RevOps consulting firm will make the process, data, ownership, risks, and handoff more specific before it asks you to trust its brand.

    References

  • Profound Claude Connector: A Practical AI Visibility Workflow

    Profound Claude Connector: A Practical AI Visibility Workflow

    If you have connected Profound to Claude and are staring at an empty conversation, do not begin with a broad request such as “analyze our AI visibility.” That leaves Claude to choose the scope, comparisons, and standard of proof. The response may sound decisive while answering a different question from the one your team needs resolved.

    Profound is now available as an official Anthropic connector. The practical opportunity is a shorter path from authorized Profound data to analysis inside Claude. You still need to define the decision, verify what the connection exposes, and keep measured evidence separate from Claude’s interpretation.

    What the Profound connector changes – and what it does not

    Treat the connector as an access layer, not a new measurement system. Profound remains the origin of the connected data. Claude can help you inspect, organize, compare, and explain what the connection returns. It cannot recover fields that were not returned, repair an inappropriate comparison, or turn correlation into proof of causation.

    Four boundaries matter in every conversation:

    • Account boundary: confirm which Profound account or workspace is connected. A polished analysis of the wrong property is still wrong.
    • Field boundary: establish which records, metrics, dimensions, and identifiers Claude can actually access. Do not assume that every object visible in Profound is available through the connector.
    • Filter boundary: record the market, language, AI platform, topic, brand, competitor set, and date range whenever those dimensions are present. A change in scope can create an apparent performance change.
    • Interpretation boundary: separate returned measurements from explanations proposed by Claude. The former can be verified against Profound; the latter are hypotheses until checked.

    Official connector status should not be interpreted as a promise of complete data coverage, live refreshes, write access, or a particular permission model. Verify those details in your own connected environment instead of building a workflow around assumptions.

    Your first message should therefore be an inventory request:

    Starter prompt: Inspect the Profound connection available in this conversation. List the accounts or workspaces, record types, fields, filters, date ranges, and identifiers you can access. Distinguish fields you can retrieve from fields you are inferring. Do not begin the analysis yet. Tell me which parts of the requested scope cannot be verified from the connection.

    Save the answer with the analysis. It becomes a compact data contract: a record of what Claude could see when it produced the result. If Claude cannot identify the available scope clearly, resolve the connection or permissions question before asking for strategy.

    Scope the decision before you scope the data

    An analyst uses a focusing lens to isolate a small set of evidence tiles from a larger blurred collection.

    A useful connector workflow starts with a decision, not a dashboard tour. “Understand our visibility” is not a decision. “Choose which topic cluster should receive the next content update” is. The second version tells Claude what evidence to prioritize and gives you a clear way to reject irrelevant analysis.

    1. Name the decision. State what will change if the analysis supports it: a content update, a new page, a technical investigation, a brand-entity correction, or continued monitoring.
    2. Name the entity. Use the exact brand, product, property, or business unit you intend to evaluate. Add aliases only when you deliberately want them included.
    3. Set the comparison. Supply an approved competitor list or ask Claude to analyze the brand alone. Do not let the model silently invent a comparison set.
    4. Lock the scope. Specify the topic, audience, market, language, AI platform, and time window that matter. If a requested dimension is unavailable, require Claude to say so rather than substitute another one.
    5. Define acceptable evidence. Require every conclusion to point to returned fields, records, citations, or other traceable identifiers. Anything else must be labeled as an inference or a proposed next check.

    A reusable control prompt can carry those rules into the rest of the conversation:

    Control prompt: Use only information returned through the connected Profound account and context I explicitly provide. Preserve the available date range and filters. For every finding, show the supporting field or record identifier. Put measured observations, interpretations, and recommended actions in separate sections. Mark missing data as missing; do not estimate it. Ask for clarification when a missing input would change the decision.

    Before using connected business data, also confirm who is permitted to access the selected workspace, whether the conversation may be shared, and what information can be placed in prompts under your organization’s policies. A connector reduces manual transfer; it does not remove your responsibility to control sensitive data.

    Three workflows that produce defensible AI visibility actions

    1. Find a visibility gap without inventing its cause

    The most useful gap analysis identifies where a brand underperforms within a defined set of prompts or topics. It does not immediately claim to know why. Visibility can differ alongside many variables, and the connector alone does not establish which variable caused the difference.

    Diagnostic prompt: For [brand], analyze [topic] in [market and language] across [available time window]. Compare it with [approved competitors] only where equivalent comparison data exists. Rank the most consistent visibility gaps. For each gap, return: the observed result, the fields or records supporting it, the scope and filters, one or more plausible explanations labeled as hypotheses, and the next evidence needed to test each explanation. Do not present a hypothesis as a finding.

    Review the output in that order. First decide whether the observation is supported. Then check whether all compared entities use the same filters and coverage. Only after those checks should you consider the proposed explanations. This prevents an appealing theory about content quality, authority, or entity recognition from outrunning the connected data.

    2. Turn prompt and citation signals into a content brief

    If the connection returns prompt-level answers, cited domains, URLs, or related records, Claude can organize those signals into editorial questions. Make the availability of those fields a condition of the task. A domain name in a generated explanation is not evidence that the domain appeared in Profound.

    Content-opportunity prompt: From the records available through Profound, find recurring prompts about [topic] where [brand] is absent, represented weakly, or trails [approved competitors]. If citation fields are available, show the exact cited domains or URLs and their associated records. Group the prompts by user intent rather than by shared keywords. For each group, propose one content action tied directly to the observed gap. Label any claim about why another page was selected as a hypothesis unless its page content is also available for inspection.

    Translate the result into a brief with five required fields:

    • User question: the specific decision or problem represented by the prompt group.
    • Observed gap: what the connected records actually show about the brand.
    • Evidence: the record, metric, answer, citation, or identifier supporting the gap.
    • Page action: update an existing answer, create a missing resource, clarify an entity relationship, or investigate a technical obstacle.
    • Validation condition: what comparable Profound signal you will inspect after the action has had an opportunity to appear in the available data.

    Do not treat every missing brand mention as a reason to publish another page. If an existing page already answers the intent, the next step may be to improve its clarity, structure, supporting evidence, or entity references. If the connected data cannot distinguish among those possibilities, use it to prioritize an investigation rather than to prescribe the edit.

    3. Compare periods without turning movement into causality

    Trend analysis is only defensible when the compared records use equivalent scope. A different prompt set, market, platform, competitor group, or coverage level can make two periods look comparable when they are not.

    Monitoring prompt: If date-stamped Profound records are available, compare [period A] with [period B] using the same brand, topic, market, language, platform, prompt set, and competitor filters. Identify any dimension that is not equivalent before calculating or describing change. Report observed direction and magnitude only from returned values. Do not attribute movement to a content release, campaign, algorithm change, or competitor action. List those events separately as possible explanations that require additional evidence.

    Use the same saved prompt for future checks, changing only the intended date window. If the accessible schema or coverage changes, note the break instead of joining the results into one uninterrupted trend. Consistency is what makes a connector-based monitoring workflow useful; a fluent narrative cannot compensate for mismatched inputs.

    Build an evidence trail from conversation to action

    Connected conversation, source, evidence, review, and approval objects form a traceable path across an analyst's workspace.

    Claude’s final answer should not become the only record of the analysis. Preserve enough structure that another person can reproduce the finding in Profound, challenge the interpretation, and understand why an action was approved.

    1. Inventory the connection. Record the accessible workspace, fields, identifiers, filters, and coverage before analysis begins.
    2. Run one decision-focused query. Keep unrelated brands, topics, and time windows out of the first pass.
    3. Request counterevidence. Ask Claude which returned records weaken or contradict its leading interpretation. A robust finding should survive that check.
    4. Verify the underlying records. Open the relevant Profound view or record where possible. Check values, labels, dates, filters, and citations rather than approving an action from the prose alone.
    5. Create an evidence ledger. For each recommendation, save the observation, scope, supporting identifiers, interpretation, action owner, and validation condition.
    6. Repeat with equivalent scope. At the next comparable data refresh, use the saved control prompt and document any change in coverage before comparing results.

    Add a final quality-control request before sharing the work:

    Audit prompt: Audit your previous response. Create three lists: claims directly supported by returned Profound data, inferences that require validation, and recommendations based on editorial judgment. For each supported claim, include the relevant field, filter, date range, and record or citation identifier. Remove any claim you cannot trace.

    This audit will not guarantee correctness, but it exposes a common failure mode: a valid observation, a plausible explanation, and a recommended action being compressed into one sentence as though all three had equal evidentiary weight.

    Key takeaways

    • The Profound connector gives Claude a route to authorized Profound context; it does not make every Profound field available by default.
    • Begin by inventorying accessible accounts, records, fields, filters, identifiers, and date coverage.
    • Frame each conversation around one decision, one defined scope, and an explicit standard of proof.
    • Require Claude to separate measured observations from hypotheses and recommended actions.
    • Verify important findings in the underlying Profound records and save an evidence ledger before assigning work.
    • Compare periods only when their scope and coverage are equivalent, and never treat movement alone as proof of causation.

    Start with one narrow, diagnostic conversation. Inventory the connection, investigate a single visibility gap, and verify every consequential claim before converting it into a content ticket. Once that path is reproducible, save the prompts and evidence fields as a team workflow. The value of the Profound Claude connector will come from disciplined questions and traceable decisions, not from the volume of analysis it can generate.

    References

  • Google AI Mode Connects Instacart, Canva and YouTube Music

    Google AI Mode Connects Instacart, Canva and YouTube Music

    Google is turning AI Mode in Search into more than a place to generate answers. According to Search Engine Land, a rollout for U.S. users will let people connect supported apps and act on an AI-assisted plan through services including Instacart, Canva and YouTube Music.

    The early examples point to a broader change in the search journey: a result can lead directly into shopping, design or entertainment workflows. That convenience may also change where brands earn visibility and how much of the customer journey happens inside Google’s interface.

    AI Mode is moving closer to task completion

    Traditional search usually helps a person discover information before sending that person elsewhere to take action. Connected apps shorten that sequence. Google says users can securely link supported services and interact with them from AI Mode, as reported by Search Engine Land.

    The distinction matters because the integration is not merely another way to display a link. AI Mode can participate in the transition from deciding what to do to beginning the task in a relevant service. Completion may still occur outside Search; in the Instacart example, checkout happens through the retailer’s app or website.

    The first examples cover three different user goals

    Google’s initial examples illustrate how one connected-app model can support different kinds of intent. A person organizing a barbecue could connect Instacart, place the required ingredients in a cart and then move to Instacart to check out.

    For a creative task, someone making a flyer could ask Canva to surface template options. For entertainment, a person planning a party could build a playlist through AI Mode, save it to YouTube Music and begin listening. Together, these examples span a purchase, a design workflow and a media experience rather than concentrating on one vertical.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    Key takeaways

    • The connected-app rollout is starting with U.S. users of AI Mode in Search.
    • Instacart, Canva and YouTube Music are among the services highlighted in the initial examples.
    • The integrations reduce steps between planning in Search and acting through another service.
    • Google says it is working with more partners and intends to add further integrations.

    Why marketers should examine the handoff

    Search Engine Land notes that this approach could affect the traffic, visibility and control brands receive after a search. The key issue is not simply whether a company appears in an AI-generated response. It is also whether the next action takes place through an integrated service before the user visits other sites or evaluates more options.

    That creates a practical measurement challenge. Referral traffic alone may provide an incomplete picture if AI Mode assists with planning and starts a workflow elsewhere. Marketers may need to distinguish between visibility during the decision process, selection within a connected experience and the final conversion on a partner platform. This is an analytical implication of the reported design, not evidence that any specific traffic effect has already occurred.

    Brands should also consider how well their products, creative assets or media offerings can be represented through third-party services. When a platform becomes the execution layer for an AI-assisted task, the quality and availability of information within that platform can influence what the user is able to do.

    Important details remain unresolved

    The report describes the feature as a rollout rather than universal availability. It does not provide a schedule for broader access, name the next partners or explain the commercial arrangements behind the integrations. It also does not establish how frequently users will choose connected actions over conventional search paths.

    Those limitations make early conclusions about traffic or conversion premature. The more useful signals will be which app categories Google adds, where users complete each task and what measurement options become available. As the partner roster grows, marketers will gain a clearer view of whether connected apps become an occasional convenience or a meaningful new layer in the search journey.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • OpenAI’s Desktop Consolidation: What Atlas Users Face

    OpenAI’s Desktop Consolidation: What Atlas Users Face

    OpenAI’s reported plan to retire ChatGPT Atlas is more than a product cancellation. It points to a desktop strategy built around one primary ChatGPT application that combines browsing, agent-led work, and Codex capabilities.

    For users and organizations, the immediate questions are practical: how firm the retirement date is, whether adopting an OpenAI browser remains necessary, and what the consolidation could mean for research and digital discovery.

    The desktop app is becoming the center of the product

    CrushPress.AI reported that OpenAI intends to discontinue Atlas as a standalone desktop browser and move its browser-based AI features into a new ChatGPT desktop app. The same report describes that app as bringing together ChatGPT Work, OpenAI’s work-focused agent, and ChatGPT Codex.

    This is a consolidation of entry points as much as a consolidation of features. Instead of asking users to choose among a dedicated AI browser, a separate Codex application, and the broader ChatGPT experience, the reported direction places those functions inside a common desktop environment.

    The sequence reported by CrushPress.AI helps explain the shift. Atlas launched on Mac in October, a dedicated Codex app followed, and an in-app browser was added in April. The planned unified app appears to gather capabilities that had been introduced through separate products, although the source does not provide a detailed migration map.

    Key takeaways

    • ChatGPT Atlas is reportedly scheduled to be retired as a standalone browser.
    • The stated Aug. 9 date is a target, so it should not be treated as an unconditional deadline without further notice.
    • Browser functions, ChatGPT Work, and Codex are being positioned within a unified ChatGPT desktop app.
    • Chrome users are expected to retain access to ChatGPT and Codex through OpenAI’s Chrome extension.
    • The change could concentrate more research and task completion inside ChatGPT, increasing its role in digital discovery.

    The Aug. 9 date carries an important qualification

    CrushPress.AI cited OpenAI’s James Sun as saying on X that Aug. 9 was the current targeted date for deprecation. According to the report, Sun also said that more information would be shared in the application and by email.

    That wording establishes a planned direction but preserves uncertainty around execution. A target date can change, and the supplied report does not specify when access will stop, whether data or settings will transfer automatically, or whether every Atlas feature will have an equivalent in the new app.

    Atlas users should therefore treat official in-app and email notices as the operative migration guidance. Before the target date, organizations can identify which workflows depend on Atlas and document any browser-specific behavior they would need to reproduce. That is prudent continuity planning, not evidence that any particular feature will be lost.

    Users still have two reported browser paths

    A computer user views two visual pathways from a desktop application to separate generic browser experiences.

    The consolidation does not necessarily require every user to replace an existing browser. CrushPress.AI reported that the new desktop app will include browser capabilities, while people who prefer Chrome can use OpenAI’s Chrome extension to access ChatGPT and Codex.

    Those paths serve different working preferences. A unified desktop app can keep browsing and agent tools in one OpenAI-controlled environment. An extension can place the same broad services closer to an established Chrome workflow. The source does not compare feature parity, security controls, performance, or account requirements, so it would be premature to declare either route universally better.

    For teams, the decision should follow the work being performed. Relevant considerations include whether tasks depend on existing Chrome profiles and extensions, whether the unified app offers necessary workflow controls, and how each option fits internal software and security policies. These are evaluation criteria rather than reported product guarantees.

    Consolidation could expand ChatGPT’s role in discovery

    A person uses a central desktop assistant connected to floating research pages, documents, code panels, and media tiles.

    The strategic consequence extends beyond desktop software. When browsing, questions, research, coding, and task execution occupy the same interface, the distance between finding information and acting on it becomes shorter. CrushPress.AI argues that this gives ChatGPT another opportunity to influence how people research brands and discover information outside traditional search-result pages.

    For marketers and publishers, the relevant change is not merely the disappearance of an Atlas icon. It is the possibility that more discovery activity will occur within the main ChatGPT experience, where answers and actions may be combined. That makes accurate, accessible, and clearly attributable information increasingly important, while the supplied source does not establish how the new app will select or present particular brands.

    The next signals to watch are OpenAI’s promised notices, the final treatment of Atlas accounts and workflows, and the practical feature differences between the desktop app and Chrome extension. Those details will determine whether this is mostly a packaging change or a meaningful shift in how desktop users browse and complete work.

    References

  • GPT-5.6 in Profound: Tiers and Workflow Implications

    GPT-5.6 in Profound: Tiers and Workflow Implications

    Profound has announced support for GPT-5.6, giving its users access to the model family through the platform’s existing AI workflows. The announcement emphasizes a choice among Sol, Terra, and Luna tiers rather than presenting GPT-5.6 as a single configuration for every task.

    The practical significance is workload matching: teams can consider different tiers for demanding reasoning and production-scale activity while evaluating whether the reported gains in capability, reliability, and efficiency hold for their own use cases.

    What GPT-5.6 support changes in Profound

    According to Profound’s announcement, GPT-5.6 is now available directly within the workflows supported by the platform. Profound characterizes it as OpenAI’s newest flagship model family and identifies advanced AI performance as the central reason for adding it.

    This is an integration announcement, not an independent benchmark. The source reports improvements in capability, reliability, and efficiency, but it does not provide test results, pricing, latency figures, context limits, or comparisons with earlier models. Those omissions matter when deciding whether the new option should replace an existing model or serve only selected workloads.

    Sol, Terra, and Luna introduce a tier-selection decision

    Profound says its GPT-5.6 support spans the Sol, Terra, and Luna tiers. It presents this range as a way to cover work extending from frontier reasoning to high-throughput production workloads, although the announcement does not assign detailed specifications or a fixed use case to each named tier.

    For teams, the important shift is therefore operational: model selection can be treated as a workload decision. A demanding research or reasoning task may call for a different balance than a repeatable, high-volume process. Without tier-level measurements in the source, however, buyers should avoid assuming which option will deliver the best quality, speed, or cost for a particular application.

    The workflows Profound expects to benefit

    Abstract task objects travel along branching illuminated paths through three differently scaled processing chambers before converging into organized outputs.

    The announcement highlights four areas: agentic workflows, coding, research, and enterprise knowledge work. These categories share a need for dependable handling of instructions and context, but they create different evaluation requirements.

    • Agentic workflows: Evaluate whether the selected tier follows multi-step instructions consistently and handles failure conditions appropriately.
    • Coding: Test against the languages, repositories, review practices, and validation tools used by the organization.
    • Research: Check source handling, factual accuracy, uncertainty, and the usefulness of generated synthesis.
    • Enterprise knowledge work: Examine performance with internal terminology, access controls, document retrieval, and required approval processes.

    These checks are general implementation practices rather than performance claims about GPT-5.6. Profound’s post identifies the target workflow categories but does not publish evidence for individual tasks within them.

    Key takeaways

    • Profound reports that GPT-5.6 is supported within its AI workflows.
    • The integration includes the Sol, Terra, and Luna tiers.
    • Profound positions the model family for uses ranging from advanced reasoning to high-throughput production.
    • Agentic systems, coding, research, and enterprise knowledge work are the principal use cases named in the announcement.
    • The post reports capability, reliability, and efficiency improvements but supplies no benchmarks or tier-level specifications.

    How teams can evaluate the integration responsibly

    A sensible evaluation begins with representative tasks rather than a broad platform-wide switch. Teams can define the required output quality, acceptable error patterns, response-time needs, and operating constraints for each workflow, then compare the available tiers under the same conditions.

    1. Select a small set of real tasks from each intended workflow.
    2. Define pass criteria before comparing model outputs.
    3. Record quality, consistency, failure modes, and human-review effort.
    4. Compare tiers without presuming that the same option will suit every workload.
    5. Expand adoption only where the results support Profound’s reported benefits.

    GPT-5.6 support broadens the choices available inside Profound, but the integration’s value will ultimately depend on how clearly organizations match those choices to their own work. More detailed tier documentation and workload-specific evidence would make that decision easier.

    References