Tag: AI Integration

  • SAP Customer Engagement Strategy: Build One Customer Memory

    SAP Customer Engagement Strategy: Build One Customer Memory

    Your SAP landscape can execute every message as designed and still produce a disjointed customer experience. When service, sales, commerce, stores, and marketing each act on a different version of the customer’s history, you aren’t managing a relationship. You’re scheduling collisions.

    A workable SAP customer engagement strategy gives those teams a shared customer state, consistent decision rules, and a feedback loop. The goal isn’t to make every channel sound identical. It’s to make the next action appropriate to what the customer has already done, requested, purchased, or declined.

    Key takeaways

    • Start with customer decisions and handoffs, not a list of channels or SAP modules.
    • Create a usable customer memory that includes identity, permissions, recent events, active issues, eligibility, and suppressions.
    • Model each journey as a set of states, entry conditions, decisions, exits, and conflict rules.
    • Use AI for bounded tasks inside an approved decision system. Do not ask it to compensate for disconnected data or unclear ownership.
    • Measure contradictory contacts, failed handoffs, repeat questions, and suppression errors alongside conventional campaign results.

    Replace channel plans with a relationship operating model

    A channel plan asks, “What should email send?” or “What should sales do next?” A relationship plan asks, “Given what we know about this customer now, what should the business do next, who should do it, and which actions must be suppressed?”

    That distinction exposes the real problem. Email, social, ecommerce, sales, and service can all meet their own targets while the customer receives incompatible treatment. SAP calls the gap between customer expectations and an organization’s ability to deliver coherent engagement the Engagement Divide. Closing it requires an operating model, not merely another campaign layer.

    Use four connected layers to define that model:

    • Memory: What does the organization know about the customer’s identity, permissions, activity, purchases, conversations, and unresolved needs?
    • Decision: Which actions are eligible, which should take priority, and which must be blocked?
    • Execution: Which channel or employee should carry out the decision?
    • Learning: What happened, and how will that outcome change the next customer state?

    Write each important interaction as a complete operating statement: When this customer state occurs, make this decision, execute it through this owner or channel, suppress these conflicting actions, and record this outcome. If you cannot fill in every part, the journey isn’t operational yet.

    Start your audit with collisions rather than architecture. Select a journey in which customers can encounter more than one department. Map every system that reads or changes the relationship during that journey. For each system, record what it knows, what it can trigger, what it writes back, and how quickly another team can see the change.

    If this happensThe meaningful customer stateThe response to coordinateThe rule to encode
    A service case remains unresolvedThe relationship is in recoveryLet service lead while promotional contacts are reviewed or suppressedCurrent case status overrides ordinary marketing eligibility
    A prospect has completed a demoThe prospect is evaluating, not awaiting an introductionContinue from the known demo outcomeThe completion event suppresses another introductory demo invitation
    A store purchase has been recordedThe person is a recent purchaserUpdate ecommerce treatment before the next follow-upThe purchase event becomes available to every relevant activation channel

    This exercise gives you a prioritized backlog. A missing event, an ambiguous owner, and an absent suppression rule are different defects. Label them separately so the team fixes the mechanism instead of redesigning the message around it.

    Build the customer memory your decisions actually need
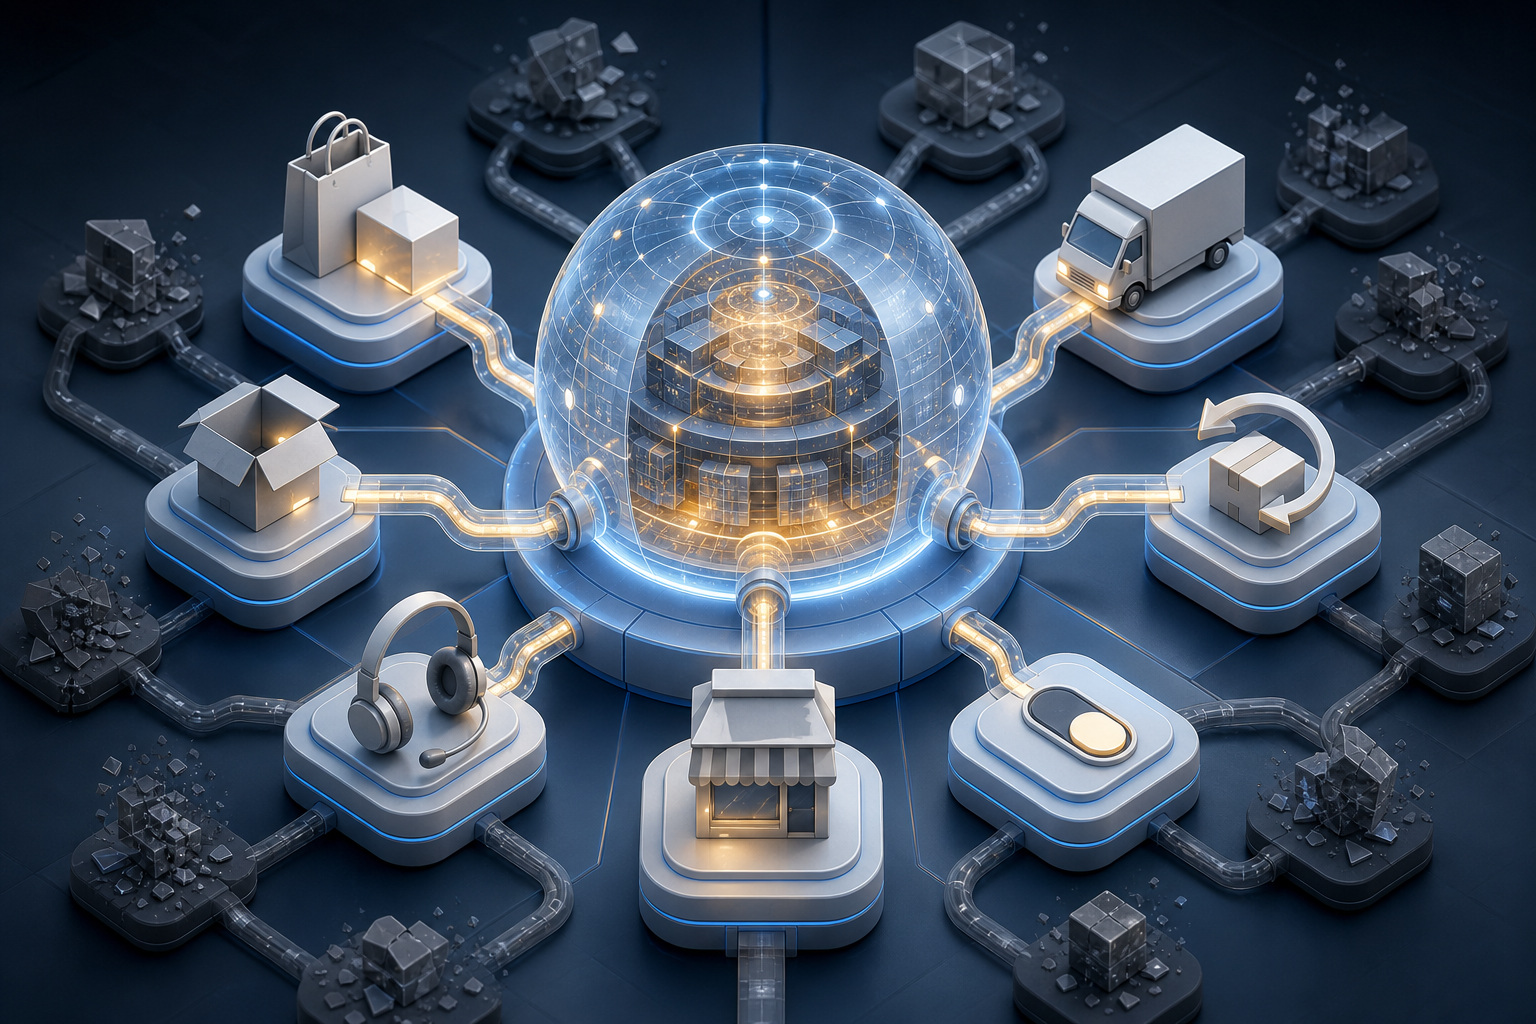
    Purchase, delivery, service, store, consent, and return signals converge into a single translucent customer-memory hub while duplicate fragments are filtered out.

    “Single customer view” sounds like a complete answer, but a large consolidated profile can still be useless at the moment of engagement. Your decision layer needs a current, explainable relationship record, not every field the organization has ever collected.

    Define a minimum viable relationship record for the first journey. It should usually cover:

    • Identity keys: the identifiers used to connect activity without merging people on weak evidence.
    • Permission state: what the customer permitted, where the permission came from, when it changed, and which uses or channels it covers.
    • Lifecycle state: the customer’s current relationship with the business, such as prospect, active customer, recent purchaser, or former customer.
    • Recent events: purchases, demo completion, service contacts, responses, and other actions that materially affect the next decision.
    • Open business context: unresolved cases, active opportunities, pending orders, returns, or other processes that should change treatment.
    • Eligibility and suppressions: actions the customer can receive, actions currently blocked, the reason for each block, and when the status should be reconsidered.
    • Decision history: what the system or employee decided, which rule was applied, and what action followed.
    • Outcome history: whether the customer responded, ignored the action, opted out, reopened an issue, progressed, or left the journey.

    Keep observations, interpretations, and decisions separate. “Case opened” is an observed event. “Relationship in recovery” is an interpreted state. “Suppress promotional message” is a decision. If those are collapsed into one field, you will struggle to explain why an action occurred or safely change the rule later.

    Attach a source and timestamp to every state-changing signal. Where identity or classification is uncertain, preserve that uncertainty instead of silently converting it into fact. An incorrect merge can expose one person’s activity to another person’s journey, while an overconfident classification can trigger an inappropriate action. Ambiguous records should follow an explicit review or fallback path.

    Freshness should be defined by decision, not by a blanket demand for “real time.” A service status must be current before marketing checks a suppression rule. A slower analytical attribute may remain useful for planning. Document the maximum acceptable age of each input at the point of decision, then verify that the integration path can meet it.

    Finally, name the authoritative system for every required field. If service, commerce, and marketing can all overwrite the same status without precedence rules, integration will distribute the conflict faster. A shared memory needs clear write ownership as much as it needs connectivity.

    Turn customer journeys into governed decision systems
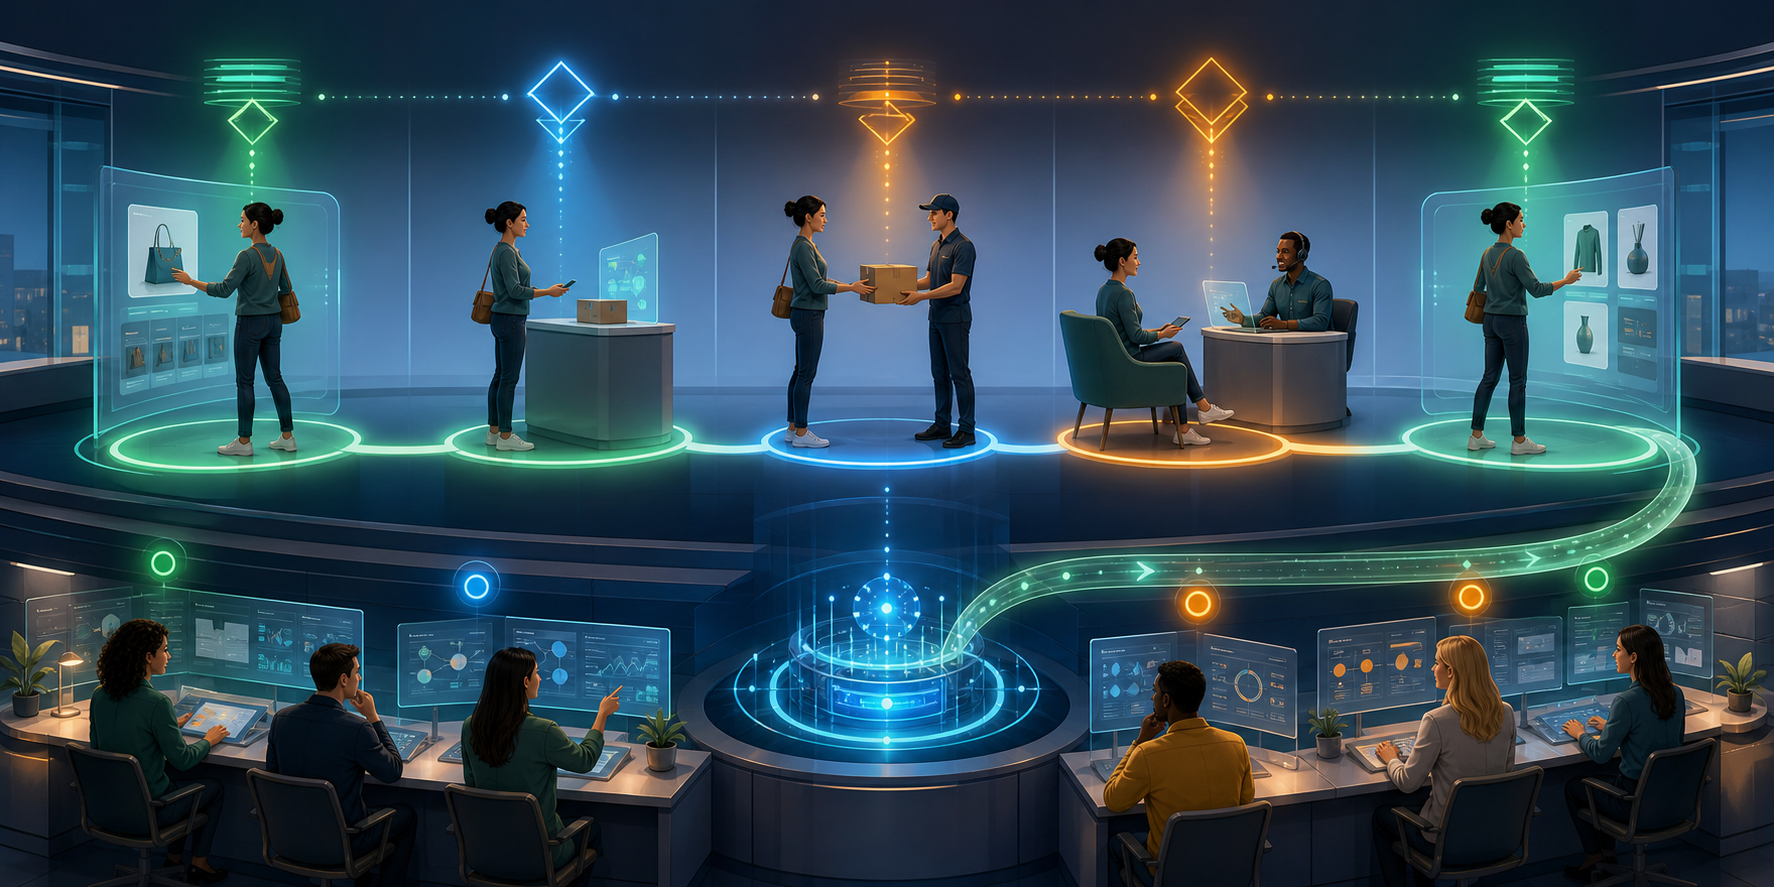
    A customer journey passes through connected purchase, delivery, support, and shopping moments while shared decision gates and a feedback loop coordinate several teams.

    A journey diagram shows the experience you hope to create. An executable journey defines what the organization will do when reality departs from that diagram.

    For each journey, specify:

    • Entry condition: the event and qualifying state that place a customer in the journey.
    • Current states: the meaningful stages the customer can occupy, expressed in business language that channel teams understand.
    • Decision inputs: the precise fields and events needed to select an action.
    • Eligible actions: what the business may do in each state.
    • Priority rules: which need takes precedence when service, sales, and marketing all have a possible action.
    • Suppression rules: which actions must pause, stop, or yield to another journey.
    • Exit conditions: the events that complete, cancel, or transfer the journey.
    • Fallback behavior: the safe action when data is late, missing, conflicting, or uncertain.
    • Outcome event: what must be written back so the next decision reflects what happened.
    • Owner: the person accountable for the cross-channel decision, not merely the team operating a channel.

    Cross-journey priority is where many otherwise polished designs fail. A customer can be part of a retention program, a sales opportunity, a service recovery process, and a product campaign at the same time. Define which state wins before the systems encounter that conflict. The rule should be visible to every affected team and testable with a sample customer history.

    AI belongs inside this system, not above it. It can help classify an inbound request, summarize a long interaction history, identify relevant approved content, or recommend an action from an eligible set. Those are bounded jobs with observable inputs and reviewable outputs.

    Do not delegate permissions, identity resolution, mandatory suppressions, or other hard constraints to a probabilistic recommendation. Keep those decisions deterministic. AI should never invent missing customer context, infer consent, or bypass an unresolved service state simply because a promotional action appears likely to perform.

    Every AI-assisted decision needs the same operational record as a rules-based decision: the inputs available at the time, the eligible options, the selected option, any human override, the action taken, and the outcome. Without that record, you cannot distinguish a model problem from stale data, a bad rule, or a channel execution failure.

    Govern the handoffs and launch one coherent journey

    Channel ownership is necessary, but it is not enough. Someone must own the relationship decision across channels. That owner resolves priority conflicts, approves state definitions, coordinates rule changes, and accepts the outcome when a handoff fails.

    Assign the supporting responsibilities explicitly:

    • A relationship owner defines the journey outcome and cross-channel priorities.
    • Business data owners define authoritative fields and approve changes to their meaning.
    • Integration owners deliver the required events with the agreed freshness and failure handling.
    • Channel owners execute eligible actions and return outcomes in a consistent form.
    • Service, sales, commerce, and marketing leaders approve rules that affect their teams.
    • Privacy and compliance owners review identity, permission, retention, and activation controls.
    • Analytics owners monitor customer-level coherence as well as channel performance.

    Your scorecard should make fragmented engagement visible. Keep delivery, response, conversion, and revenue measures where they are useful, but add operational measures such as contradictory-contact rate, contacts made during an active suppression, handoff completion, repeated information requests, unresolved-case contact, identity corrections, and decisions that fell back because required data was unavailable.

    These measures tell you where the relationship breaks. A campaign can produce a strong response while still creating avoidable service contacts or contradicting another interaction. Looking only at the campaign result hides that cost.

    Use this rollout sequence to move from architecture discussion to a live, controlled journey:

    1. Choose a visible fracture. Start with a journey where channel conflict is recognizable, the business outcome matters, and an accountable owner is available.
    2. Reconstruct the current path. Follow the customer state across systems and mark missing events, stale fields, manual handoffs, conflicting owners, and absent suppressions.
    3. Define the required memory. Name only the identity, permission, event, state, and outcome data needed for this journey, along with the authoritative source for each item.
    4. Write the decisions before configuring tools. Document eligibility, priority, suppression, exit, and fallback rules in language business and technical teams can test together.
    5. Test complete event sequences. Include normal progression, unresolved service issues, duplicate identities, missing data, late events, permission changes, and simultaneous journey eligibility.
    6. Observe decisions before broad activation. Replay representative histories or run the logic without sending customer-facing actions. Review what would have happened and why.
    7. Launch within a controlled scope. Limit the initial journey so owners can inspect exceptions, correct state definitions, and verify that outcomes return to the shared memory.
    8. Expand by decision pattern. Reuse proven identity, permission, priority, and outcome patterns in the next journey instead of copying an entire campaign workflow.

    Before launch, ask one final question: if the customer contacts a different department immediately after this action, will that team know what happened and respond appropriately? If the answer is no, the feedback loop is still open.

    Your next move is small but consequential. Pick one broken handoff, name the customer state both teams must share, and write the priority and suppression rules that should govern it. Once that decision works across SAP-connected systems, you have the foundation for a relationship strategy that can scale.
    References

  • AI Advances in Healthcare: A Practical Evaluation Guide

    AI Advances in Healthcare: A Practical Evaluation Guide

    You’ve got a healthcare AI announcement in front of you and a decision to make: is this a meaningful advance, a promising demonstration, or a polished claim that has outrun its evidence? The model’s reputation won’t answer that question.

    You need to connect the technology to a care task, the care task to evidence, and the evidence to a controlled workflow. That framework works whether you’re evaluating a product, planning adoption, writing clinical content, or deciding which claims deserve visibility in search and AI-generated answers.

    The useful unit of progress is the care task

    The potential of healthcare AI extends from diagnostics to patient care. That range is also why broad statements about AI transforming healthcare tell you so little. Diagnostics, documentation, scheduling, patient education, and clinical decision support are different jobs with different users, failure modes, and consequences.

    Start by reducing every claimed advance to one task statement. It should identify five things:

    1. User: Who receives or acts on the output: a patient, clinician, administrator, researcher, or another system?
    2. Input: What information does the system receive, and where did that information come from?
    3. Output: Does it draft text, summarize a record, flag a case, rank options, predict an event, or initiate an action?
    4. Decision: What real decision could change because of the output?
    5. Failure consequence: What happens if the output is incomplete, late, biased, misleading, or wrong?

    For example, AI that summarizes clinician-authored encounter notes for clinician review is an assessable use case. AI that improves patient care is not. The first statement identifies a user, input, output, and review step. The second jumps directly to an outcome without showing the mechanism.

    Once the task is clear, ask what actually improved. An advance might reduce the time required for a task, make documentation more consistent, identify relevant cases, expand access, or reduce avoidable administrative work. Those are separate claims. Evidence for faster drafting does not establish better diagnosis, and stronger performance on a technical evaluation does not automatically establish better patient outcomes.

    This distinction should shape your language. If a system generates possibilities for a qualified professional to consider, say that. Don’t say it diagnoses. If it drafts an explanation that must be reviewed, call it a draft. Don’t describe it as patient guidance delivered independently. Precise verbs prevent a capability claim from quietly becoming a clinical claim.

    Separate assistance, recommendation, and action

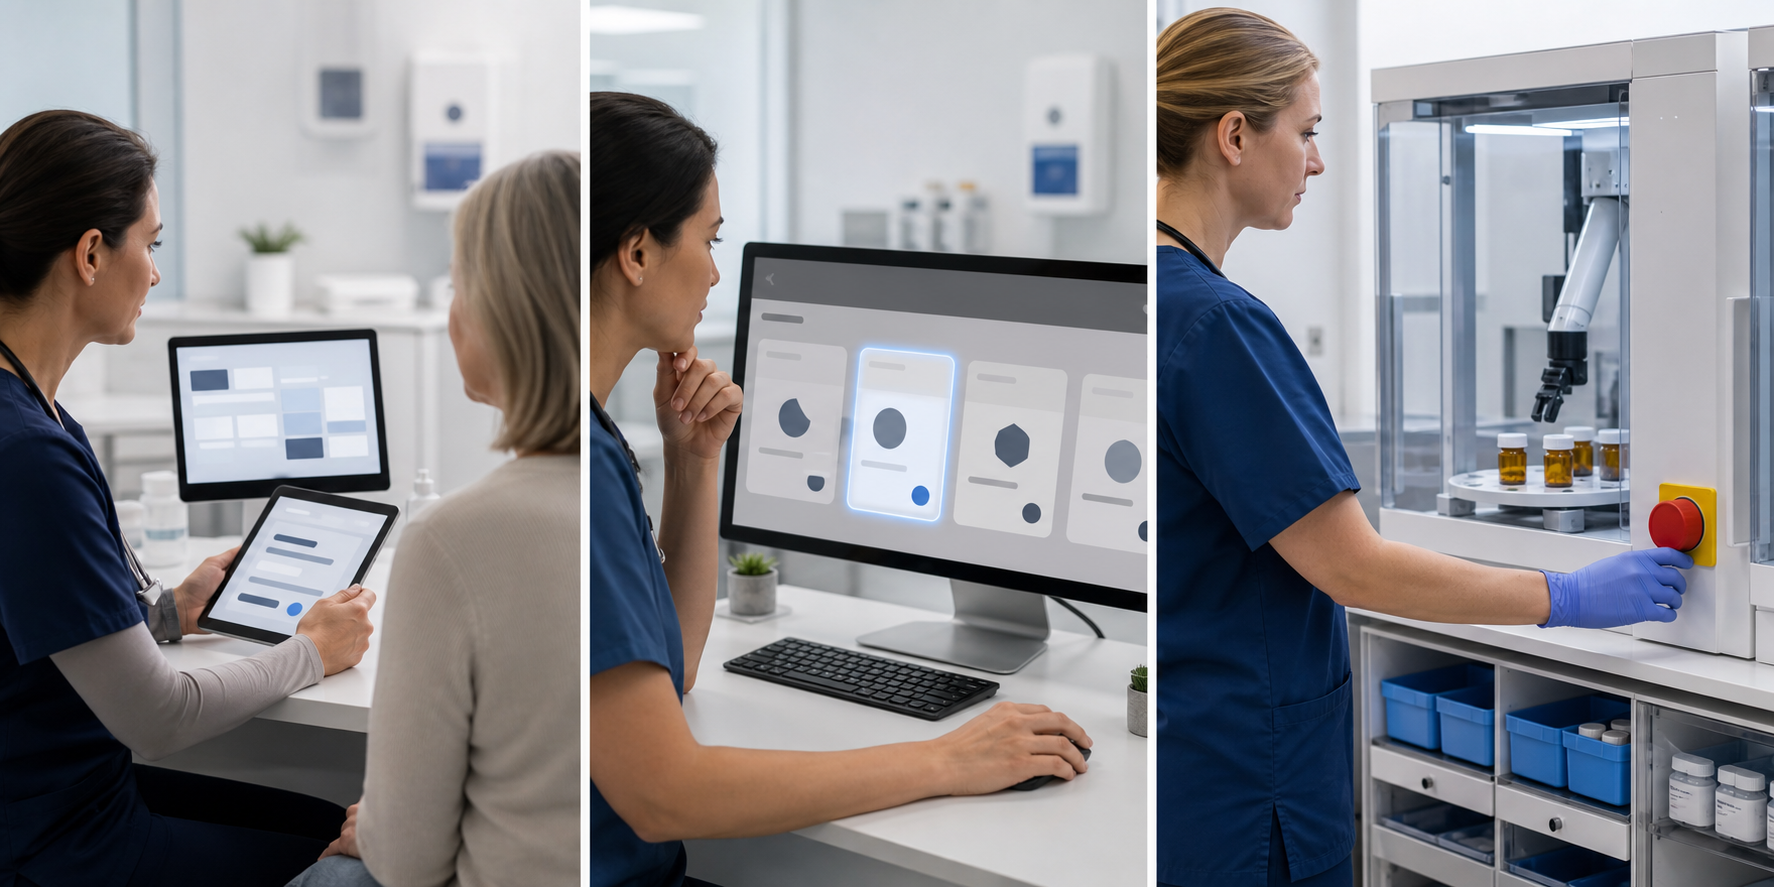
    A three-part clinical scene shows AI organizing information, presenting a recommendation, and operating supervised medication equipment.

    Healthcare AI systems can occupy very different positions in a workflow. A useful first classification is whether the system assists, recommends, or acts. This is an evaluation framework, not a regulatory classification, but it quickly exposes how much control the workflow needs.

    ModeWhat the AI doesHuman control to verifyClaim discipline
    AssistsDrafts, organizes, retrieves, or summarizes informationA person can inspect, edit, reject, and replace the outputDescribe the task support, not an unmeasured care outcome
    RecommendsFlags cases, ranks options, or proposes a next stepA qualified person evaluates the recommendation before it affects careName the intended user, decision, evaluation context, and known limits
    ActsTriggers, routes, schedules, or changes something in the workflowThe system has defined boundaries, escalation paths, and a way to stop or reverse inappropriate actionExplain exactly what is automated and where human oversight remains

    Risk does not begin only when AI acts autonomously. An incorrect summary can carry an old fact forward. A fluent explanation can make uncertain information sound settled. A recommendation can attract more trust than its evidence deserves. Human review is not a meaningful safeguard unless the reviewer has the information, authority, time, and interface needed to catch a problem.

    Inspect the control itself. A reviewable workflow should make the AI-generated material identifiable, preserve relevant input context, let the reviewer edit or reject the output, provide an escalation route, and record what was accepted or changed. A button labeled approve is not sufficient if the reviewer cannot see how the output was produced or cannot safely disagree with it.

    The closer an output gets to diagnosis, medication, treatment, or urgent-care decisions, the more explicit these boundaries must become. Patient-facing AI must not be presented as a substitute for a qualified healthcare professional. If an output conflicts with a clinician’s instructions or a medication label, the safe next step is to contact the appropriate clinician or pharmacist rather than act on the AI response. Situations involving possible immediate harm require established local emergency channels, not another chatbot prompt.

    Match every claim to its actual level of evidence

    A compelling output proves that the system produced a compelling output once. It does not establish reliability, clinical usefulness, or patient benefit. To avoid that leap, place evidence on a ladder and stop at the highest rung the evaluation genuinely supports.

    1. Capability evidence: The system can produce the intended kind of output in selected examples.
    2. Task validation: Its outputs have been evaluated against a predefined reference, process, or reviewer judgment for the stated task.
    3. Workflow validation: Intended users have used it under conditions that resemble the intended setting, including realistic inputs and handoffs.
    4. Outcome evidence: The evaluation measured the patient, clinical, or operational outcome named in the claim rather than using a technical metric as a substitute.
    5. Post-deployment evidence: Performance, failures, overrides, and changes continue to be monitored in actual use.

    Each rung answers a different question. Task validation may show that a system performs a bounded function well. Workflow validation asks whether people can use that function safely and effectively. Outcome evidence asks whether the claimed real-world result occurred. Post-deployment monitoring matters because users, data, interfaces, prompts, retrieval material, and models can change after an initial evaluation.

    When you inspect an evaluation, ask questions that reveal what the headline leaves out:

    • Which population, language, care setting, and task were represented?
    • What counted as success, and was that definition chosen before the results were reviewed?
    • What was the comparison: no tool, the existing workflow, another system, or an expert judgment?
    • Which failures occurred, who was affected, and which failures carried the greatest clinical consequence?
    • Were intended users evaluating the output, or was the system assessed only outside the care workflow?
    • What happens when information is missing, contradictory, unusually phrased, or outside the intended scope?
    • Which model, configuration, retrieval material, interface, and review process produced the result?

    If those details are unavailable, treat that absence as an evidence limit. Don’t fill the gap with a stronger adjective. Promising can be appropriate for an early capability. Validated needs a stated task and context. Effective should identify the outcome that improved. Safe is usually too broad to stand alone because safety depends on the user, setting, controls, and type of failure being considered.

    Keep the evaluated system distinct from the underlying model. A healthcare AI implementation may include a model, prompts, retrieval sources, interface rules, access controls, escalation policies, and human review. Changing any of those elements can change the behavior that users experience. Record them together, and retest material changes instead of assuming that an earlier result transfers automatically.

    Test the workflow around the model, not just the model

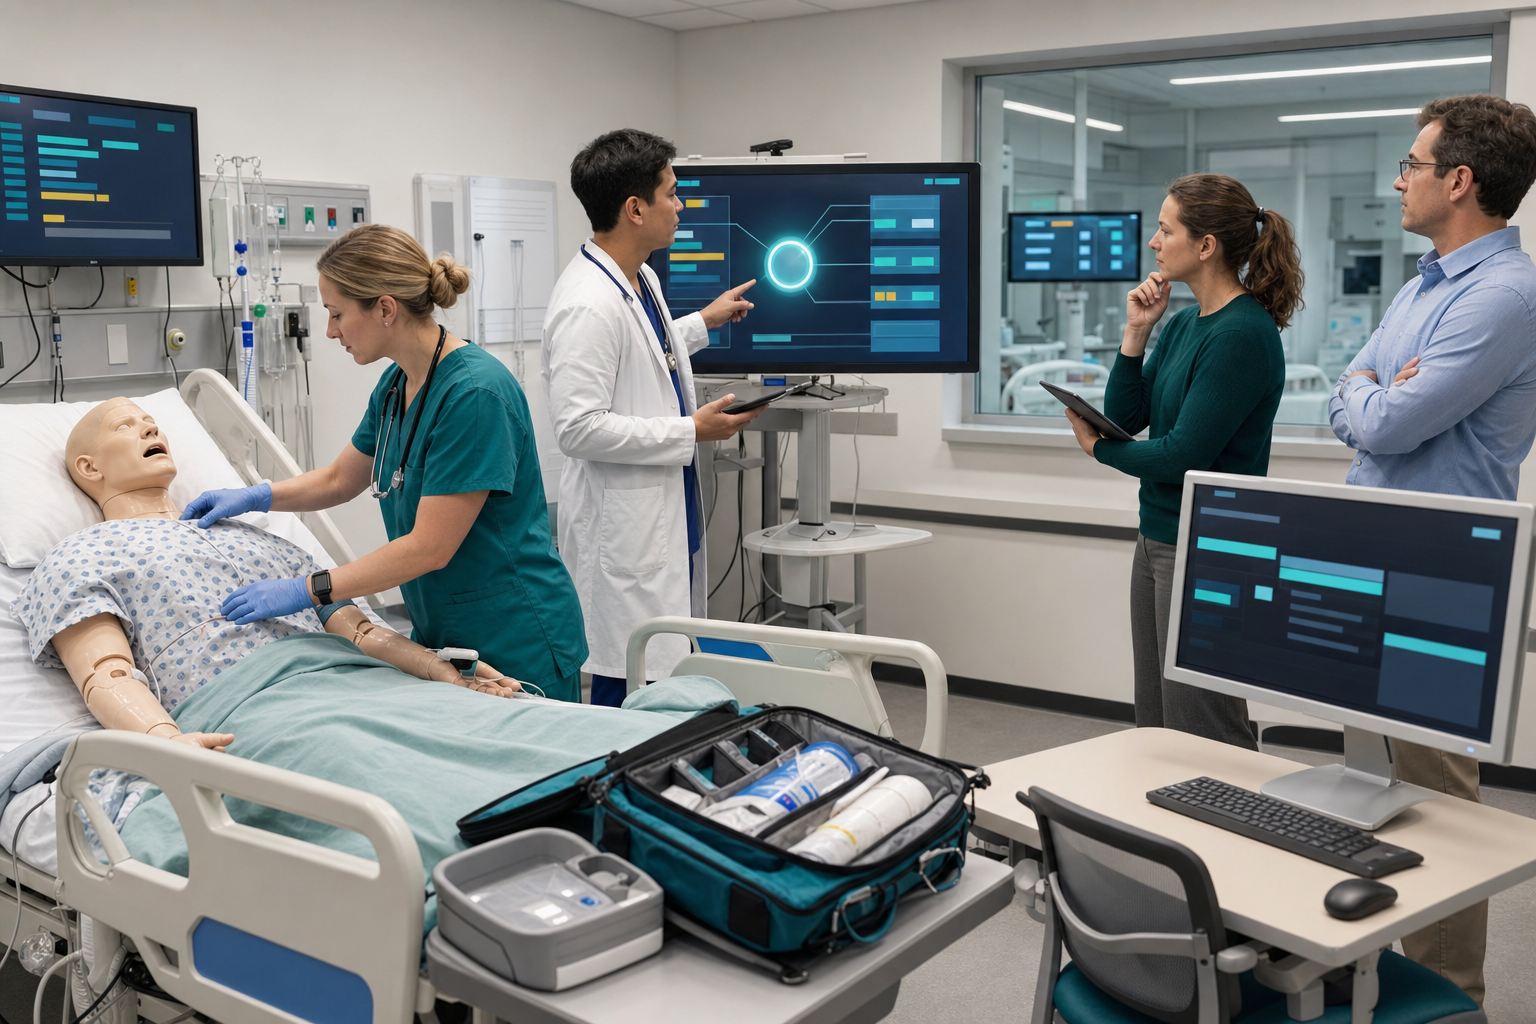
    A nurse, physician, informaticist, and human-factors specialist test an AI-supported process with a training mannequin in a clinical simulation room.

    A technically capable model can still fail as a healthcare system. The failure often appears at the handoff: the wrong information enters, the output reaches the wrong person, a warning arrives too late, or nobody owns the exception. Evaluate the full route from input to consequence.

    Use these six gates before treating a capability as deployment-ready:

    1. Context match: Confirm that the intended users, population, language, setting, and task resemble those represented in the evaluation.
    2. Input control: Define which data the system may receive, how missing or conflicting information is handled, and who is responsible for input quality. Never place identifiable patient information into an AI tool that your organization has not approved for that use.
    3. Output routing: Specify who sees the result, when they see it, what supporting context accompanies it, and whether it can alter a decision before review.
    4. Human factors: Verify that users can understand the output’s role, identify uncertainty, disagree with it, and complete the task without becoming dependent on it.
    5. Failure response: Decide in advance how the workflow handles false alarms, missed cases, unsupported statements, system outages, and outputs outside the intended scope.
    6. Change monitoring: Assign an owner to watch failures, overrides, complaints, model or configuration changes, and performance drift after launch.

    Run the workflow with difficult cases before routine ones create false confidence. Test missing context, ambiguous requests, contradictory records, out-of-scope questions, and attempts to bypass the intended process. The goal is not to prove that the system never fails. It is to learn whether failures are visible, containable, recoverable, and routed to someone able to respond.

    Define a stop condition as well as a success condition. A responsible deployment plan says who can pause the system, which events trigger review, what work continues without it, and how affected users are notified or corrected. If nobody has authority to stop an unsafe workflow, the oversight plan is incomplete.

    Publish healthcare AI claims that can survive scrutiny

    Healthcare AI content has to work for a person assessing risk and for search or answer systems extracting a concise statement. Both benefit from the same thing: explicit claims with their qualifications attached. A vague page cannot become trustworthy through optimization, and structured data cannot turn unsupported language into evidence.

    Put the central claim in a form that can stand on its own: the system, intended user, task, setting, oversight, and demonstrated evidence level should appear together. Put an important limitation in the same sentence or adjacent paragraph, not in a distant disclaimer that disappears when the sentence is quoted.

    A useful claim pattern is: [System] helps [intended user] perform [task] in [setting]. [Reviewer or control] checks [output] before [decision or action]. Current evidence establishes [capability, task performance, workflow performance, or outcome], while [important limitation] remains unresolved.

    Before publication, apply these editorial thresholds:

    • Can generate or summarize: Show that the capability was tested with the stated input and output. Don’t convert generation into an accuracy or outcome claim.
    • Supports review or decision-making: Identify the qualified user, the decision being supported, the review step, and the context in which the support was evaluated.
    • Improves a workflow: Name the measured operational result and the workflow used for comparison. Don’t use an isolated model score as proof of workflow improvement.
    • Improves diagnosis or patient outcomes: Reserve this language for evidence that measured the named diagnostic or patient outcome in the defined population and setting.
    • Is safe: Replace the blanket claim with the risks evaluated, controls used, limitations found, and context covered. No system is safe independently of its use.

    Keep vendor, model, product, and care provider roles separate. OpenAI, Google, and Anthropic may be relevant to the underlying AI landscape, but a familiar model developer’s name does not establish that a particular healthcare implementation is clinically validated. State who built the model, who configured the system, who operates the workflow, and who is responsible for clinical review whenever those roles differ.

    Your maintenance process matters as much as the launch page. Keep a claim inventory linking each public statement to its evidence, evaluated configuration, owner, review date, limitations, and correction route. When a model, prompt, retrieval source, interface, intended use, or oversight process changes, review the dependent claims. Otherwise, accurate content can become misleading while its publication date and search visibility remain unchanged.

    Use schema and other machine-readable markup to describe what the visible page actually says. Keep the evidence level, intended use, limitations, author or reviewer responsibility, and update history readable on the page itself. Machines may extract the markup, but people still need enough context to judge the claim.

    Key takeaways

    • Judge healthcare AI at the level of a defined care task, not the reputation of a model or developer.
    • Separate systems that assist, recommend, and act; each position requires a different degree of control and claim restraint.
    • Don’t treat a demonstration, task evaluation, workflow evaluation, outcome evaluation, and monitored deployment as interchangeable evidence.
    • Evaluate inputs, handoffs, human review, failure response, and change control alongside model performance.
    • Keep qualifications beside the claim so readers and AI answer systems do not receive a stronger statement than the evidence supports.
    • Do not present patient-facing AI as a replacement for qualified medical care, especially where diagnosis, medication, treatment, or urgent decisions are involved.

    For the next healthcare AI claim you encounter, write the five-part task statement before you draft a headline, approve a tool, or publish a page. Then label the highest evidence rung it has reached. If you cannot complete either step, hold the claim at capability level until the missing context is available.

    References

  • How to Evaluate Leading AI Software Companies in 2026

    How to Evaluate Leading AI Software Companies in 2026

    If you are shortlisting AI software companies, a generic ranking answers the wrong question. A company can lead at the model layer and still be a poor choice for deploying a governed workflow inside your business.

    Your real task is to identify the kind of company you need, define what leadership means for your use case, and make each candidate prove it with your workflow and representative data. That turns a crowded market into a decision you can defend.

    Start with the job, not the company ranking

    There is no useful universal winner. A packaged AI application, a model provider, a cloud platform, and a custom development company solve different parts of the problem. Ranking them together is like ranking an engine, a delivery van, and a logistics contractor on the same scale.

    Before you collect vendor names, write a short procurement brief. It should be specific enough that another person could recognize a successful deployment without hearing the sales pitch.

    • Workflow: Name the task or decision the software will support. Avoid broad goals such as “use AI for marketing.” A workable definition is closer to “produce a cited first draft from approved product documentation for an editor to review.”
    • Owner: Identify the person accountable for the workflow after launch. A sponsor can approve a purchase, but an operational owner has to manage errors, updates, and user adoption.
    • Inputs: List the documents, databases, messages, images, or application events the system may use. Record where that data lives and who has permission to expose it.
    • Output and action: State what the system produces and what happens next. Distinguish a suggestion shown to a person from an action executed in another system.
    • Failure boundary: Describe acceptable mistakes, unacceptable mistakes, and the point at which a human must intervene. A formatting error and an invented compliance claim cannot share the same severity.
    • Environment: Name the identity system, content repository, analytics stack, customer platform, or other software the product must work with.
    • Evidence: Define what a candidate must demonstrate using representative cases. A polished demonstration using vendor-selected examples is not evidence of fit.
    • Exit conditions: Decide what data, configurations, prompts, evaluation cases, logs, and code you must be able to recover if you change providers.

    If you cannot complete this brief, pause the vendor search. When the outcome is vague, almost any demonstration can look successful, and disagreements about quality appear only after money and integration work have been committed.

    Compare companies that perform the same role

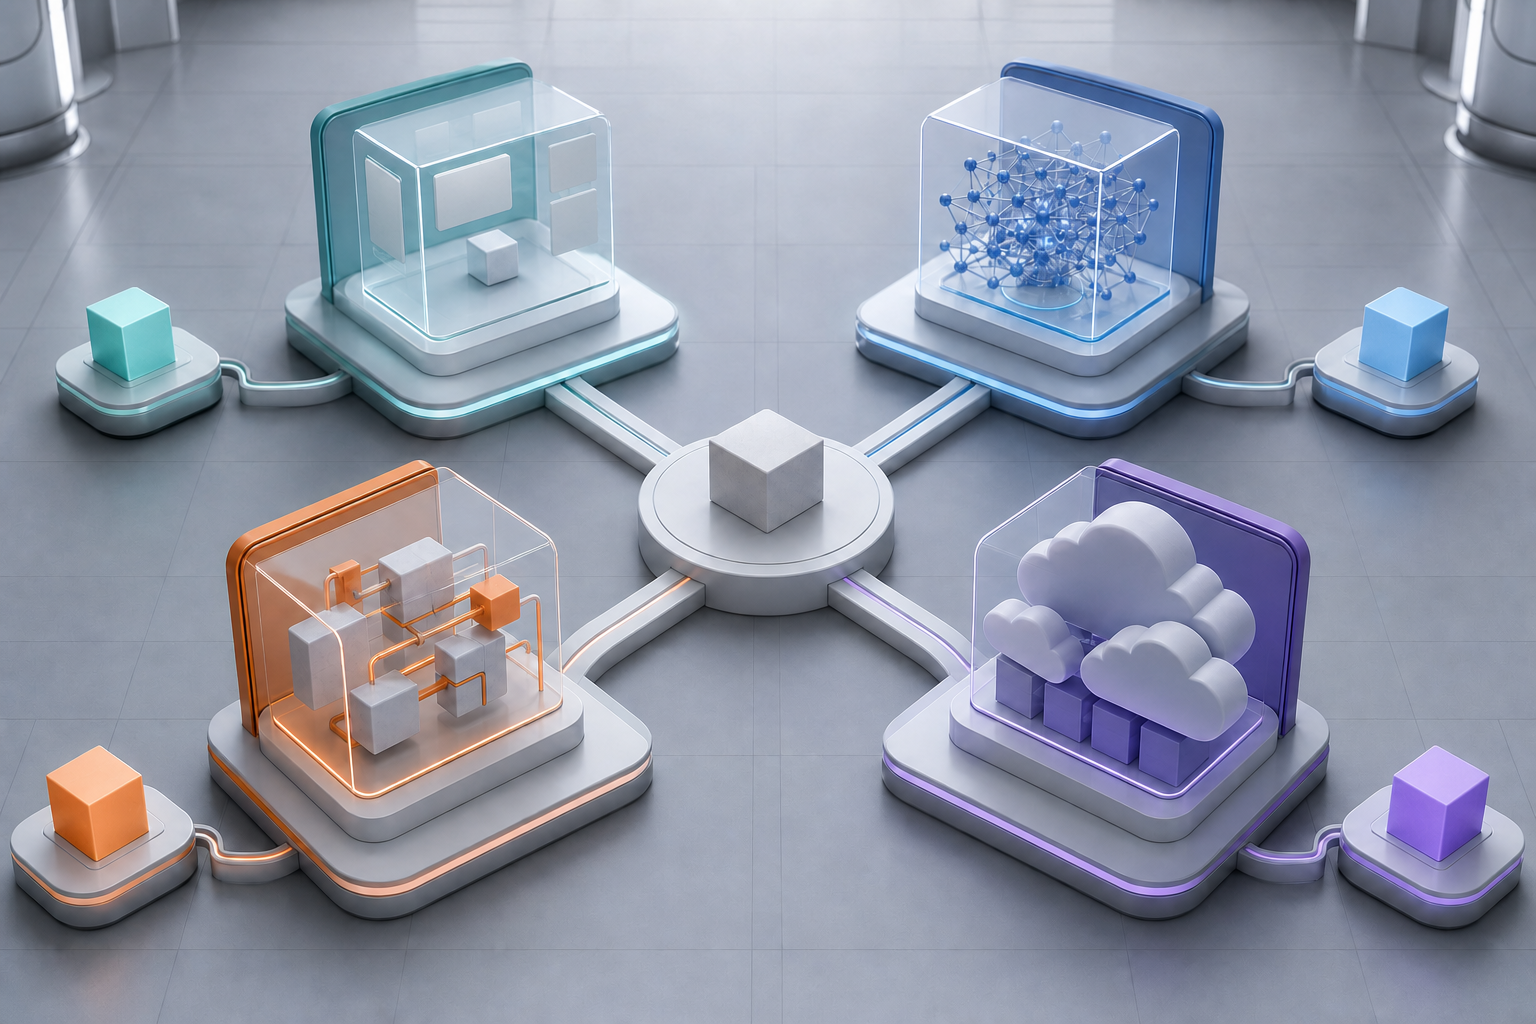
    Four distinct AI software workstations connect to the same central business task for a role-based comparison.

    The label leading AI software development companies can cover businesses with very different products and delivery models. Put each candidate into a functional category before you compare features, pricing, or market visibility.

    Company typeChoose it whenEvidence to requestCommon mismatch
    Model or API providerYour team is building its own application and needs model capabilities as a component.Results on your evaluation cases, usage controls, model-change procedures, latency behavior, and data-handling terms.Buying raw capability when you do not have the engineering or operational team to turn it into a reliable workflow.
    Cloud or data platformYour priority is connecting AI to governed data, existing infrastructure, and enterprise controls.Architecture fit, identity integration, data boundaries, deployment options, monitoring, and portability.Assuming platform breadth means the desired business application is already complete.
    Packaged AI applicationYou need a defined outcome in a familiar function such as content operations, support, analytics, or sales workflow.Workflow coverage, administrator controls, export options, user permissions, integration depth, and evidence from representative tasks.Paying for a broad feature set while the product remains weak at the narrow task that matters.
    Workflow or agent platformYou need AI to coordinate steps, tools, and approvals across systems.Action permissions, state handling, retries, approval gates, audit logs, failure recovery, and limits on autonomous behavior.Treating an impressive prototype as a dependable operational process.
    Custom AI development companyNo packaged product fits the workflow, or your process and data create meaningful differentiation.Proposed architecture, delivery ownership, evaluation method, repository access, documentation, deployment plan, support model, and intellectual-property terms.Commissioning custom software before confirming that the workflow is stable enough to specify and maintain.
    AI operations or governance providerYou already have AI systems and need evaluation, observability, policy enforcement, or control across them.Coverage of your actual stack, alert quality, policy implementation, evidence retention, and response procedures.Expecting a control layer to repair poor application design or unsuitable source data.

    A candidate can belong to more than one category, but you should still name the role you are buying from it. Otherwise, a vendor’s strength in one layer can distract you from a gap in another. If you need a finished application, model quality alone does not settle the decision. If you need a model component, a large catalogue of packaged features may be irrelevant.

    Turn “leading” into pass-or-fail requirements

    Feature counts reward breadth, and weighted scorecards can hide a fatal weakness behind a high total. Use non-negotiable gates first. Score or rank only the companies that pass every gate that protects the workflow.

    • Task performance: The product must produce usable results on ordinary cases, difficult edge cases, and inputs that should trigger refusal or escalation. Define “usable” in terms of the next step in the workflow, not whether the output sounds polished.
    • Evaluation discipline: Ask how the company detects regressions and separates different error types. For generated answers, completeness, factual support, citation quality, format compliance, and harmful fabrication are different dimensions. A blended quality claim can conceal the failure that matters most to you.
    • Data governance: Get written answers about retention, use of customer data for training, storage location, deletion, subprocessors, tenant separation, and access by vendor personnel. Product controls and contract language should agree.
    • Security and human control: Confirm authentication, role-based access, approval steps, auditability, and the ability to stop or override automated actions. The more consequential the action, the less acceptable an invisible decision path becomes.
    • Integration depth: Distinguish a live, supported integration from a demonstration, roadmap item, or generic API. Verify the exact records the system can read, create, update, and export.
    • Operational resilience: Ask what happens when a model, connector, data source, or downstream system fails. A production workflow needs observable errors, safe fallbacks, ownership, and a recovery procedure.
    • Commercial fit: Calculate the cost of the working process, including usage, integration, human review, monitoring, support, and ongoing evaluation. A low software price can still produce an expensive workflow if reviewers must repair most outputs.
    • Exit viability: Confirm that you can retrieve business data and the operational assets needed to continue elsewhere. For custom development, define ownership of code, prompts, configurations, documentation, and deployment materials before work begins.

    Treat unsupported roadmap promises as unavailable. Record each capability as proven, contractually committed, or absent. Those labels keep a persuasive demonstration from turning future intent into present functionality.

    References and customer logos can help you understand where to investigate, but they do not replace workflow evidence. Ask references about deployment effort, failure handling, support after the sale, and what their internal team still has to operate. A similar industry is useful; a similar data shape, risk level, and workflow is better.

    Run a production-shaped proof before you commit

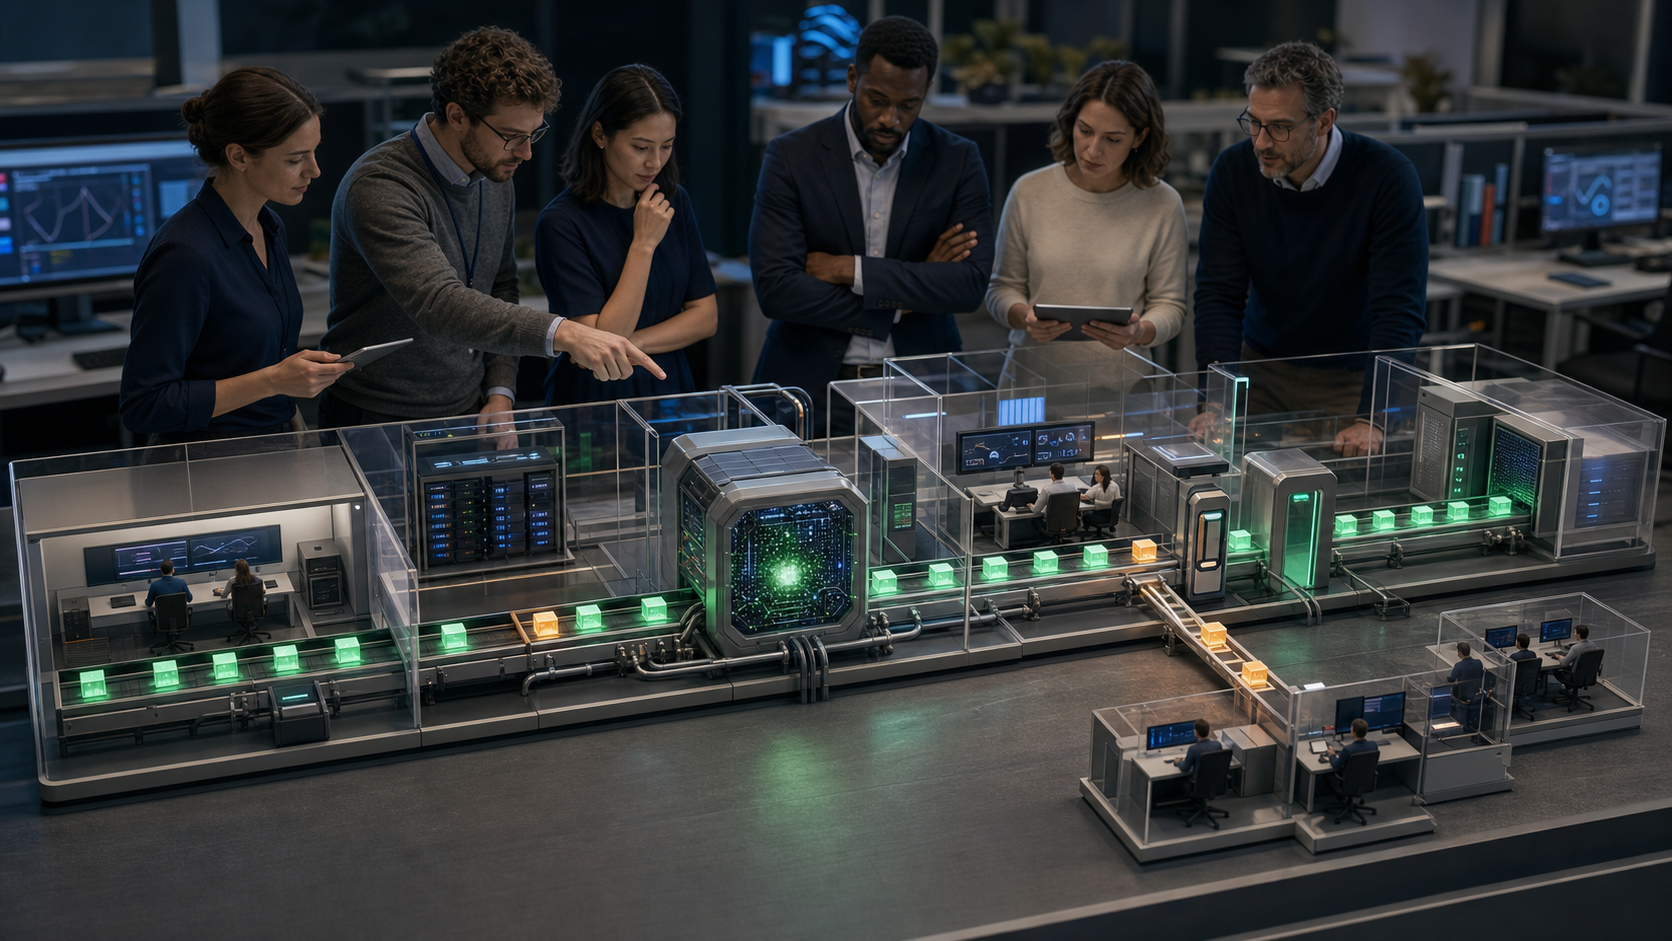
    A business and engineering team observes an AI proof-of-concept moving through security, human review, monitoring, and final delivery stages.

    A proof should test the operating system around the AI, not just the most attractive output. Keep the workflow narrow enough to inspect closely, but preserve the data conditions, permissions, integrations, and review steps that will exist in production.

    1. Freeze the use case. Give every candidate the same workflow definition, input boundaries, expected output, and failure rules. Do not let each vendor redefine success around its strongest feature.
    2. Build the evaluation set. Include routine examples, ambiguous inputs, incomplete information, edge cases, and requests the system should decline or escalate. Keep a portion of the cases out of vendor-led configuration so you can see how the system handles unfamiliar inputs.
    3. Protect sensitive information. Use de-identified or synthetic material until contractual, security, and internal approvals permit representative production data. When real data becomes necessary, expose only what the approved test requires.
    4. Record configuration work. Track the prompts, rules, connectors, data cleanup, and human assistance required to achieve the result. A system that performs well only after extensive hidden preparation may carry a much higher operating cost than the demonstration implies.
    5. Test the whole handoff. Measure whether users can review, correct, approve, reject, and trace the output inside the intended workflow. A strong answer copied manually between applications may still be a weak production solution.
    6. Force recoverable failures. Remove a source, deny a permission, provide conflicting information, or interrupt a downstream service in a controlled test. Check whether the system fails visibly, preserves state, avoids unsafe actions, and gives an operator a clear recovery path.
    7. Review the evidence by error type. Keep a failure log that identifies what went wrong, its consequence, whether a person detected it, and whether the proposed fix is repeatable. Do not average a severe failure into a reassuring overall score.
    8. Price the observed workflow. Use the actual configuration, workload shape, review effort, support requirement, and integration pattern from the proof. Model an increase and decrease in usage so you can see which charges are fixed and which scale with activity.
    9. Test the exit. Export representative data and configuration, inspect its format, and identify what cannot move. For a custom system, verify access to the repository, build instructions, environment configuration, and operating documentation.

    The proof should leave you with artifacts you can inspect later: the frozen evaluation set, result sheet, failure log, data-flow map, architecture diagram, cost model, operating runbook, and exit plan. If the only durable artifact is a presentation, you have evaluated a sales process rather than a production system.

    Reject any company that fails a non-negotiable gate, even if it has the highest total score. Among the survivors, prefer the option that reaches the required outcome with the clearest controls, lowest operational burden, and most credible path out. That is a more useful definition of leadership than size, visibility, or the longest feature list.

    Key takeaways for your shortlist

    • Define the workflow, owner, data, action, failure boundary, evidence, and exit conditions before collecting vendor names.
    • Compare model providers with model providers, applications with applications, and development companies with development companies.
    • Make task performance, data governance, security, operational resilience, economics, and exit viability pass-or-fail gates.
    • Use the same production-shaped evaluation cases for every candidate, and keep severe errors visible instead of burying them in an average.
    • Count configuration, integration, review, monitoring, and support when calculating cost.
    • Choose the company that can prove the required outcome and remain operable when inputs, systems, or providers change.

    Take your current list and write each company’s intended role beside its name. Remove candidates that solve a different layer, send the survivors the same procurement brief, and do not declare a leader until the proof produces evidence your operational owner is willing to accept.

    References

  • Gemini Trends and Personal Intelligence: An SEO Workflow

    Gemini Trends and Personal Intelligence: An SEO Workflow

    You have a topic worth covering, but two questions are blocking the brief: which language reflects real search demand, and whether the answer will remain relevant when Gemini knows something about the person asking.

    Google’s Gemini integrations now touch both questions. Gemini in Google Trends can suggest related terms and place them into a trend comparison. Personal Intelligence can use selected information from connected Google apps to shape an individual response. The opportunity is useful, but only if you keep those signals separate: Trends helps you map public demand, while Personal Intelligence introduces private context.

    Treat the integrations as two different signal layers

    The Trends integration is an editorial research tool. You give it a keyword or a natural-language description, and Gemini proposes related search terms for comparison. Personal Intelligence operates later in the journey. With the user’s permission, Gemini can draw on information associated with Search, Gmail, Google Photos, and YouTube to produce a response that may be more useful to that person.

    Gemini surfaceInputUseful decisionWhat it cannot establish
    Google Trends ExploreA keyword or natural-language topicWhich terms, variants, and rising questions deserve closer investigationWhether a term will convert, whether two terms share the same intent, or whether you should publish a separate page for each suggestion
    Personal IntelligenceA prompt plus the Google apps and history the user has chosen to connectWhich details could make an answer more relevant in a particular personal contextA universal ranking position, a reusable audience profile, or access to other users’ private context

    This distinction prevents two common mistakes. A rising query is not automatically a content brief, and a personalized answer is not automatically a public search result. The first is a lead that needs editorial judgment. The second is an individual output whose conditions must be recorded before you draw conclusions from it.

    Access conditions also matter when you plan a workflow. The Trends redesign was introduced through a gradual desktop rollout, so the Gemini control may not appear in every interface at the same time. Personal Intelligence initially launched as a U.S. beta for Google AI Pro and AI Ultra subscribers using personal Google accounts across the web, Android, and iOS; Workspace accounts were excluded from that initial availability. Treat those as launch conditions to verify in the account you will actually use, not as permanent assumptions.

    Turn Gemini’s Trends suggestions into a defensible query map

    Blank query tokens pass through an analysis lens, branch into thematic clusters, and organize into page modules.

    The useful output from Gemini in Trends is not a list of titles. It is a query map: a record of how people describe a problem, which terms appear related, and where the language may represent a genuinely different need. Build that map before you decide whether to update a page, add a section, or create something new.

    1. Start with the editorial decision. Write the question you need the data to resolve. For example: Do searchers treat two product categories as alternatives, or are they looking for different jobs to be done? A clear decision keeps Gemini’s suggestions from becoming an unfiltered brainstorming exercise.
    2. Describe the topic in natural language. In the desktop Explore interface, use Suggest search terms and enter either a seed keyword or a sentence describing the audience and problem. Natural language is especially useful when the market uses several labels and you do not yet know which one belongs in the comparison.
    3. Curate the suggestions before accepting them. Ask whether each term describes the same entity, the same task, a narrower condition, or an unrelated meaning. Remove ambiguous lookalikes. Keep a term when it exposes a meaningful vocabulary choice or a separate intent worth testing.
    4. Compare the terms as a group. The redesigned interface allows more terms to be compared and gives each one a distinct icon and color. Look for divergence, convergence, and sudden movement. Similar movement can indicate a shared external trigger, but it does not prove that searchers want the same answer.
    5. Inspect the rising queries for the mechanism behind the movement. The updated timeline exposes twice as many rising queries as the earlier layout. Use them to identify new modifiers, questions, products, or events that may explain the trend. Treat a rising query as an investigation lead, not a forecast that demand will last.
    6. Make one of three explicit content decisions. Add a missing answer to an existing page when the intent is already covered. Create a focused page when the searcher needs a materially different answer. Put the term on a watchlist when the meaning or durability is still unclear.

    Your query map should record the core question, accepted term variants, excluded ambiguities, notable rising queries, and the content decision attached to each cluster. Save the comparison context shown in Trends as well. Without that record, a later editor cannot tell whether a page was built around sustained demand, a temporary spike, or an AI-generated suggestion that was never validated.

    Do not publish one page per suggested term. If several phrases express the same task, a single strong page can define the shared concept and use the variants naturally. Separate pages make sense only when the reader needs a different decision, procedure, constraint, or outcome. That is an information-architecture choice, not something Gemini can decide from term similarity alone.

    Build pages for context without trying to predict the user

    Personal Intelligence changes the selection problem. Gemini was already able to retrieve information from connected apps; in the announced Gemini 3 implementation, it can reason across that information and use it in recommendations. Your public page cannot know the private facts available in a particular conversation. It can, however, make its answer easy to adapt when different facts matter.

    • Lead with the stable answer. State what remains true regardless of the user’s history. Do not bury the definition, process, or central recommendation beneath persona language.
    • Branch on explicit conditions. Label the cases that change the answer: platform, account type, experience level, objective, compatibility requirement, or other relevant constraint. A reader and an answer system should be able to identify the applicable branch without inferring what the page meant.
    • Name entities consistently. Use the canonical product, organization, feature, and version names that the answer depends on. Introduce genuine search-language variants from your Trends map, but do not alternate among labels in a way that makes separate concepts look identical.
    • Explain relationships in visible prose. State which feature belongs to which product, which step precedes another, and why a condition changes the recommendation. Do not expect a heading, internal link, or schema property to carry an important relationship by itself.
    • Separate facts from judgment. Identify what a feature does before recommending who should use it. Personalized systems may combine a factual passage with private context, so an unsupported universal recommendation is especially fragile.
    • Keep structured data aligned with the page. JSON-LD should describe entities, authorship, content types, and other information that visitors can verify in the visible content. The announced Gemini integrations do not establish a new Gemini-specific schema or a markup switch that guarantees selection in personalized answers.

    Consider a hypothetical page about organizing a photo library. A context-ready page would answer the universal setup question first, then separate paths for finding images, sharing collections, creating a backup, and cleaning up duplicates. It would not guess which path applies to the reader. It would label the paths clearly enough for the reader or an answer system to select the relevant one.

    This is the practical GEO implication: public content establishes what your organization knows, while personal context can influence which part of that knowledge is useful. You control the clarity, completeness, and consistency of the public material. You do not control the private context or the final selection, so promises of guaranteed personalized visibility do not hold up.

    Measure public visibility and personalized usefulness separately

    One blank content page connects to separate stations for measuring anonymous public visibility and private personalized usefulness.

    A personalized Gemini response can vary with connected apps, personalization settings, and past conversations. Compressing all of that into one rank number strips away the conditions that produced the answer. Use a small controlled test matrix instead.

    Run a controlled visibility check

    1. Record the demand evidence. Save the Trends prompt, comparison set, relevant rising queries, date, and comparison context visible in the interface. This becomes the public-demand side of the test.
    2. Document the personalization state. Establish a baseline with personalization off. If you test a connected condition, record which permitted apps are active without copying private contents into the report.
    3. Hold the prompts constant. Use the same wording, task, and follow-up sequence across conditions. If you change the prompt and the personalization state at once, you will not know which change affected the response.
    4. Log treatment instead of claiming a fixed rank. Record whether your page or brand appeared, which question the response answered, which details it used, whether it cited or linked to a public page, and whether it represented the entity accurately.
    5. Translate differences into content changes carefully. Revise a page only when the test exposes a public-content gap, such as an omitted condition, unclear entity relationship, outdated fact, or unsupported recommendation. You cannot repair a private-context mismatch by adding speculative personal details to the page.
    6. Repeat under the same conditions. After an editorial change, rerun the fixed prompts with the same documented settings. The useful comparison is the change in answer quality and representation under matched conditions, not a screenshot from an unrelated conversation.

    Make privacy part of the test design

    Personal Intelligence is off by default and lets the user choose which apps to connect. Connected apps do not personalize every response automatically, and users can manage past chats and provide feedback when personalization misses the mark. Those controls are not implementation details. They are variables that determine what your test actually measures.

    Do not ask employees, clients, or research participants to expose personal Gmail, Photos, Search, or YouTube information merely to generate a marketing screenshot. Use only an account and data that the owner has explicitly authorized for the test. If private information affects an output, report the pattern at a high level and omit the underlying email, image, search, or viewing history.

    The initial exclusion of Workspace accounts also means you should not present a personal-account test as proof of an enterprise workflow. Google indicated that Personal Intelligence would expand to Search in AI Mode, but a planned expansion is not the same as universal availability. Verify the feature, account type, country, and personalization state whenever you interpret a result.

    Key takeaways

    • Use Gemini in Google Trends to expand and compare a query cluster, not to automate your editorial calendar.
    • Treat rising queries as clues about changing language or demand. Validate their meaning before creating or restructuring a page.
    • Prepare for personalized answers by publishing a stable core answer with clearly labeled branches for the conditions that change it.
    • Keep visible content and JSON-LD consistent. Neither markup nor trend data guarantees inclusion in a personalized Gemini response.
    • Measure public demand and personalized usefulness as separate layers, documenting the prompt, account state, app connections, and answer treatment.
    • Keep private Google data out of shared SEO artifacts unless the data owner has explicitly authorized its use.

    Start with one existing page rather than a site-wide overhaul. Build its query map in Trends, add the most important missing conditional branch, and run one baseline and one authorized personalized check with the same prompt. That gives you a defensible editorial action now, plus a repeatable method as Gemini’s integrations reach more accounts and search surfaces.

    References

  • AI Orchestration Systems: A Practical Production Guide

    AI Orchestration Systems: A Practical Production Guide

    You may already have a model that writes, an agent that analyzes, and automations that move data between applications. Each component can look impressive on its own. The trouble appears at the handoffs: context gets lost, nobody owns exceptions, and the workflow stops before it produces a measurable business result.

    An AI orchestration system closes those gaps. It determines what should happen next, routes work to the right tool or person, preserves state, enforces permissions, checks results, and captures evidence. The practical question is not how many agents you can deploy. It is which decisions you want the system to coordinate, and where human control still matters.

    The coordination gap is where AI value disappears

    Most organizations do not lack AI capabilities. They lack a reliable way to combine those capabilities into an end-to-end operating process. The martech market contains more than 15,384 solutions, yet only 33% of available technology is fully used. Adding another isolated tool can increase the number of possible actions without improving the flow of work.

    This is how pilot theater develops. A team proves that a model can produce a draft, classify a lead, or summarize a report. The demonstration succeeds, but the business workflow remains incomplete. The draft still needs facts, approval, publication, distribution, and measurement. The classified lead still needs routing, ownership, follow-up, and a feedback signal from the CRM. The summary still needs a decision and an accountable person.

    Point solutions optimize individual tasks. Orchestration coordinates the outcome across tasks. That coordination can support fluid budget decisions, buying-group alignment, and content loops connected to real buyer needs. In each case, the value comes from moving information and decision rights across boundaries, not from generating more output inside one application.

    Design questionSimple automationAI orchestration
    How is the next step chosen?A fixed rule or sequence determines it.Rules, models, context, and policy can select a route within defined boundaries.
    What happens to context?Each step receives a predetermined set of fields.The system assembles relevant context and preserves task state across tools.
    What happens when work fails?The workflow retries, stops, or sends a generic alert.The system classifies the exception, selects an allowed fallback, or escalates it with evidence.
    How is success measured?Execution is often treated as completion.Completion requires verified output and a connection to the intended operational or business result.

    Not every process needs AI orchestration. If a workflow follows stable rules, uses known inputs, and has one valid path, conventional automation is usually easier to test and maintain. Orchestration earns its added complexity when the process crosses systems, requires interpretation, contains meaningful exceptions, or must adapt its route without surrendering control.

    What a production orchestrator must control

    An isometric workflow facility routes a task through state management, permission checks, AI tools, human review, verification, and evidence storage.

    An orchestration system is not merely an LLM with access to several APIs. A production design needs an explicit control layer around every decision and action. Whether you buy a platform or assemble one from existing components, make sure it covers these seven responsibilities:

    1. Trigger and goal: Define what starts the workflow, what outcome it is pursuing, and what conditions should stop it. A vague instruction such as “improve this page” is not an operational goal. “Prepare a reviewable refresh package for this URL using approved product facts” is bounded and verifiable.
    2. Context assembly: Retrieve only the information needed for the current decision. That may include customer records, content history, analytics, brand rules, product facts, or approval status. More context is not automatically better; irrelevant or conflicting material can make the decision harder to inspect.
    3. Planning and routing: Select the next valid step. The router may use deterministic rules, a model, or a combination of both. Put hard requirements in rules and reserve model judgment for genuinely ambiguous work.
    4. Tool execution: Invoke a search service, CMS, analytics platform, CRM, validation tool, or specialist agent through a controlled interface. The orchestrator should know what an action is allowed to do, not merely how to call an endpoint.
    5. State management: Record the task’s status, inputs, decisions, outputs, approvals, and outstanding exceptions. Do not treat a model’s chat history as the system of record. Operational state needs a durable structure that other systems and people can inspect.
    6. Policy and approval: Check permissions before an action runs. Data access, publishing, deletion, customer communication, and budget changes should each have explicit authorization rules.
    7. Evaluation and feedback: Validate the immediate output, observe what happened after the action, and return that evidence to the workflow. Feedback may change a later route, create a follow-up task, or show that no further action is warranted.

    Give every action a contract

    The fastest way to expose a fragile orchestration design is to ask what each action promises. Create a short contract for every tool, agent, and human handoff:

    • Accepted input: The required fields, formats, and data sources.
    • Preconditions: The permissions, approvals, and prior states that must exist.
    • Allowed effect: What the action may read, create, change, publish, send, or spend.
    • Success evidence: The artifact or system state that proves the action completed correctly.
    • Failure output: A structured error that distinguishes missing data, denied access, invalid output, provider failure, and policy rejection.
    • Retry behavior: Whether retrying is safe and how the system prevents duplicate actions.
    • Escalation owner: The person or queue that receives an unresolved exception, along with the context needed to act.

    This contract turns an unpredictable failure into a known operational state. It also makes tools replaceable. The orchestrator can request a capability such as create_content_brief or validate_structured_data without embedding the entire workflow in one vendor’s prompt format.

    That separation matters in a fragmented market. Nearly 40% of US consumers have tried generative AI, while regular usage and platform loyalty remain less settled. Your production process should not assume that one model, interface, or vendor will always be the best route. Keep business policy, operational state, and evaluation criteria outside the model so you can change providers without redesigning the workflow.

    Design the first workflow around a costly handoff

    Do not begin with a goal as broad as “orchestrate marketing.” Choose one workflow where coordination failure is already visible. A strong first candidate has several of these characteristics:

    • Work repeatedly crosses tools, teams, or approval boundaries.
    • People spend time copying context, checking status, or deciding who should act next.
    • The desired completion state can be observed in a system or reviewed as an artifact.
    • The first version can recommend, draft, classify, or route before it receives permission to make irreversible changes.
    • Common exceptions can be named, even if they cannot all be resolved automatically.
    • The outcome matters enough to measure, but the workflow is narrow enough that one owner can govern it.

    Map the current process before selecting an orchestration platform. Write down the trigger, end state, decision points, required systems, human owners, exception paths, and completion evidence. If the team cannot agree on those elements, an agent will not resolve the ambiguity. It will automate the disagreement.

    An SEO and GEO content workflow example

    Consider a content refresh process. A weak implementation asks a model to rewrite a declining page and treats the new draft as the result. A properly orchestrated workflow connects diagnosis, evidence, production, quality control, publication, and post-publication observation.

    1. Observe: A defined signal creates a task. The signal might be a product change, an identified content gap, outdated information, or a meaningful visibility change. The task records why the page entered the workflow.
    2. Assemble evidence: Retrieve the existing page, approved product facts, site taxonomy, relevant performance data, editorial requirements, and known related content. Each input should carry its origin and current version.
    3. Decide: Choose among refresh, consolidation, new content, technical correction, escalation, or no action. Allowing a no-action decision is important; orchestration should reduce unnecessary work, not manufacture it.
    4. Prepare: Produce the bounded artifacts the next owner needs, such as a brief, proposed changes, internal-link recommendations, or eligible structured-data updates. Structured data should describe facts actually present on the page, not claims invented to satisfy a schema type.
    5. Verify and approve: Check factual support, links, required fields, schema syntax, indexability, and editorial policy. Keep publishing behind human approval until the workflow’s reliability and exception handling are demonstrated.
    6. Observe the result: Record publication and subsequent operational signals, then connect them to the original task. Search visibility, qualified actions, editorial rework, and technical errors answer different questions, so do not collapse them into one vague success score.

    The important change is not that AI generated part of the work. It is that every transition has an owner, a state, a control, and evidence. The same pattern can be applied to campaign changes, lead routing, customer-support escalation, or research workflows without pretending that those processes share identical rules.

    Close the loop with evidence, guardrails, and economics

    A circular workflow passes through automation, human approval, security inspection, verification, evidence storage, and a metered resource supply.

    A workflow is not closed merely because the last API call returned successfully. It is closed when the intended effect is verified, exceptions are accounted for, and the result can inform the next decision. Build that evidence into the design before you scale execution.

    Measure the outcome and the machinery separately

    Choose one primary business outcome and a small set of operational measures before launch. A useful measurement stack separates four layers:

    • Outcome: The result the workflow exists to influence, such as qualified opportunities, organic conversions, resolved issues, accepted content updates, or another observable business event.
    • Flow: Completion rate, cycle time, queue age, handoff delay, and exception rate. These show whether work is moving through the system.
    • Quality: Approval without rework, validation success, factual corrections, policy violations, and downstream reversals. These show whether completion is trustworthy.
    • Economics: Total model, platform, review, and remediation cost divided by an accepted outcome. Token spend is a useful diagnostic, but it is not a return-on-investment measure by itself.

    Do not optimize a local metric at the expense of the workflow. A cheaper draft that creates more editorial rework can increase total cost. A faster agent that produces duplicate CRM actions can damage the process it was meant to improve. Measure from trigger to verified outcome so the trade-off remains visible.

    Put control points before consequential actions

    • Use least-privilege access: Give each tool only the records and actions required for its role. A research agent does not need publishing permission merely because both functions appear in the same workflow.
    • Validate before writing: Check required fields, formats, factual support, policy conditions, and destination state before changing an external system.
    • Require approval where consequences are material: Publishing, deletion, customer communication, access changes, and budget movement should have named approval rules. The reviewer should receive evidence and proposed effects, not a bare approve-or-reject button.
    • Make retries safe: Assign an operation identifier and check whether an action already succeeded before repeating it. Otherwise, a timeout can become a duplicate publication, message, order, or record.
    • Set explicit fallbacks: Define what happens when a model, API, or data source is unavailable. Valid options include a deterministic route, another approved provider, a human queue, or a controlled stop.
    • Version the operating logic: Record which prompt, policy, model, tool definition, and data version influenced a decision. Without versions, you cannot explain a changed result or reproduce a failure.
    • Provide a stop mechanism: An owner must be able to pause new work without erasing in-progress state. Recovery is much easier when the system can resume from a known checkpoint.

    Use a go-live test that a business owner can answer

    Before moving beyond a controlled pilot, require a clear yes to each of these questions:

    • Can you trace one task from its trigger to its verified outcome?
    • Is there a named system of record for task state and approvals?
    • Can the system distinguish a failed action from an action whose result is merely unknown?
    • Can a failed step be replayed without duplicating an external effect?
    • Does every unresolved exception reach a named owner with useful context?
    • Can you change a model or tool without rewriting the business policy?
    • Does reporting show outcomes, quality, exceptions, and total cost rather than only calls and tokens?

    If any answer is no, keep the workflow in a learning environment. The missing item is not administrative polish. It is part of the production system.

    Key takeaways

    • An AI orchestration system coordinates decisions, tools, state, permissions, exceptions, and feedback across an end-to-end workflow.
    • Use simple automation for fixed, predictable paths. Add orchestration when context, interpretation, multiple systems, or variable routes make coordination the real problem.
    • Start with one costly handoff whose trigger, owner, completion state, and business outcome can be named.
    • Give every agent and tool an action contract covering inputs, permissions, effects, success evidence, failure output, retries, and escalation.
    • Keep policy, operational state, and evaluation criteria outside individual models so providers remain replaceable.
    • Measure verified outcomes, flow, quality, and total cost. A successful API call or generated artifact is not sufficient evidence of business value.

    Your next step is to draw one real workflow from trigger to outcome. Circle every point where someone interprets context, moves information between systems, waits for approval, or repairs a failed handoff. Those circles are your orchestration candidates.

    Choose one candidate, define its action contracts, and run it with narrow permissions and visible approvals. If you cannot name the evidence that proves the workflow finished correctly, do not add another agent yet. Fix the definition of done first.

    References

  • B2B eCommerce Platform Strategy for 2026: A Practical Plan

    If your 2026 platform decision has turned into a contest between vendor logos, pause the shortlist. The expensive mistake is rarely choosing the platform with fewer headline features. It is choosing before you have defined how pricing, accounts, approvals, inventory, orders, payments, and service must work together.

    Your goal is not to buy the most flexible technology available. It is to create the least complicated system that can preserve the commercial rules your customers depend on, integrate with the systems that hold the truth, and change without making every release a recovery project. This framework will help you make that decision and turn it into a delivery plan.

    Turn your operating model into non-negotiable buying scenarios

    There is no universally best B2B eCommerce platform. The useful question is whether a platform fits your specific operational and customer requirements with an acceptable amount of customization.

    Start by describing the transactions your business must complete. Do this before requesting demonstrations. A generic demonstration can make almost any platform look suitable because it avoids your account structure, contract rules, exceptions, and source data.

    Create a scenario for every commercially important journey that actually exists in your business. Depending on your model, that may include:

    • A new buyer requests access and is attached to the correct company account.
    • An account administrator creates users with different purchasing, approval, and invoice permissions.
    • A buyer sees the products, units, prices, and payment terms allowed by the account’s contract.
    • A purchasing team builds a large order by SKU, saved list, previous order, or file upload.
    • An order crosses an internal threshold and must be approved before submission.
    • A buyer requests a quote, negotiates it through the appropriate channel, and converts the accepted version into an order.
    • Inventory, lead-time, or availability information is shown without contradicting the ERP or other authoritative system.
    • An order moves from the storefront to fulfillment without manual re-entry.
    • A buyer retrieves order status, shipment information, invoices, and payment information without contacting a representative.
    • A sales or service employee assists the account without creating a second, disconnected version of the transaction.

    Do not turn these into vague requirements such as “supports account pricing.” Write each one as a testable story. Name the user, starting state, required data, normal steps, important exception, expected result, and system that owns each value. Include an actual example of the relevant account, product, contract, or order structure, with sensitive information removed where necessary.

    For example, “the platform supports approvals” is too weak to evaluate. A useful scenario specifies who requests the order, who may approve it, what causes approval to be required, what happens when an approver is unavailable, whether a changed order needs fresh approval, and what the ERP receives after approval.

    Separate the resulting requirements into two groups:

    • Pass-or-fail requirements: Rules without which you cannot trade correctly, protect account access, or reconcile an order.
    • Scored differentiators: Capabilities that improve adoption, speed, merchandising, or administration but are not prerequisites for a valid transaction.

    This distinction prevents an attractive convenience feature from compensating for a failure in contract pricing or account authorization. If a candidate cannot execute a revenue-critical scenario with representative data, treat that as a failed gate. A promised roadmap item is not equivalent to a working capability.

    Choose architecture by the complexity you must preserve

    Begin with an established platform unless your business has a clear requirement that platforms cannot reasonably support. A platform gives you working commerce foundations and an upgrade path. A fully custom build makes your team responsible not only for the differentiating workflow, but also for the ordinary capabilities buyers expect and the maintenance those capabilities require.

    That does not mean choosing the least configurable product. Intricate account structures, catalogs, pricing rules, approvals, and integrations can justify a more flexible foundation. Adobe Commerce and Shopware are often considered for complex B2B operations because their architectures accommodate extensive business requirements. Shopify Plus, Magento, and other candidates may also belong on a shortlist when they fit the operating model. A product name is the start of evaluation, not its conclusion.

    Evaluate each candidate through three filters.

    • Native fit: Which critical scenarios work through supported configuration? Native fit generally reduces the amount of code you must own, but only if the capability matches your actual rule rather than a simplified version of it.
    • Extension fit: Which gaps can be handled through documented extension points without changing the platform’s core? Ask how those extensions are tested during upgrades and who is accountable when an extension conflicts with a new release.
    • Operating fit: Can your team deploy, observe, secure, support, and improve the resulting system? Architecture that exceeds the organization’s operating capacity will convert flexibility into delay.

    Apply the same discipline to headless or composable architecture. Separating the storefront from commerce services can give teams more control over experiences and release cycles. It also creates more interfaces, deployments, failure modes, and ownership boundaries. Choose that separation when a defined requirement needs it, not because architectural novelty has been mistaken for strategy.

    Customization deserves its own ledger. For every proposed customization, record the requirement it serves, why configuration cannot meet it, the data it reads or writes, its upgrade impact, its test owner, and the supported extension mechanism it uses. If nobody can name the requirement, remove the customization. If the requirement matters but the implementation changes core platform behavior, redesign the extension before approving it.

    Compare total ownership obligations, not just the license and initial implementation. Your evaluation should expose integration development, data cleanup, extension maintenance, upgrade testing, hosting or infrastructure, observability, support, content operations, and internal change management. You do not need an artificially precise long-term forecast. You do need every candidate estimated against the same scope and assumptions.

    The final demonstration should use your scenarios and representative data. Ask the vendor or implementation partner to identify what is native, configured, extended, supplied by another product, or unavailable. Capture those answers in the decision record. That is far more useful than a feature checklist in which every row is marked yes.

    Treat ERP integration as a product, not plumbing

    The storefront is usually not the sole authority for products, customers, pricing, availability, orders, invoices, and fulfillment. That makes reliable eCommerce-to-ERP connectivity essential to preventing data errors and protecting the customer experience.

    Before selecting middleware or designing APIs, create a source-of-truth matrix. Do not assume the ERP owns every field or allow two systems to own the same value without a conflict rule.

    Business objectDecision you must documentFailure to test
    ProductWhich system owns identifiers, descriptions, attributes, units, and lifecycle status?A discontinued or incomplete item remains orderable.
    Company accountWhere are account identity, locations, contacts, roles, and commercial eligibility maintained?A user is attached to the wrong account or ship-to location.
    Price and catalog entitlementWhich system calculates or supplies the price and determines which items the account may buy?The storefront shows a valid-looking but contractually incorrect offer.
    Inventory and availabilityWhat value is authoritative, how fresh must it be, and what should the buyer see when it is unavailable?Stale data is presented as a firm promise.
    OrderWhere is the order created, when is it accepted, and which identifier follows it across systems?A retry creates a duplicate or the storefront reports success before acceptance.
    Fulfillment, invoice, and payment statusWhich status is exposed, what does it mean, and where can a buyer act on it?Internal and customer-facing statuses contradict one another.

    Then define an integration contract for every data flow. At minimum, document:

    • The canonical identifiers and the mapping between systems.
    • The required fields, formats, allowed values, and validation rules.
    • The direction of travel and the event or schedule that initiates it.
    • How duplicate messages and repeated requests are handled safely.
    • What is retried automatically, what is rejected, and what requires human review.
    • Which team receives an alert and which team owns correction.
    • How records are reconciled so silent mismatches can be found.
    • What the customer sees when a dependency is slow or unavailable.

    The degraded experience is part of the product. If a live price cannot be verified, decide whether the buyer may request a quote, save the cart, or contact the account team. Do not silently substitute a generic price. If order submission times out, do not invite an immediate second submission unless the system can determine whether the first one was accepted.

    Test failures deliberately before launch. Interrupt an ERP response, submit the same order message twice, send an unknown account identifier, remove a required product field, and return a status the storefront does not recognize. Confirm that the transaction is recoverable, the customer receives an accurate message, and the responsible team gets enough context to act.

    Migration and cutover can create duplicate orders, incorrect prices, and accounting discrepancies. Protect the business with repeatable migration runs, pre-launch reconciliation, a defined rollback route, and read access to the legacy records needed for support. Do not delete source records merely because they have been copied into the new environment.

    A minimal viable product should still complete a full commercial loop. It can serve a limited buyer group, product range, geography, or order type, but it must carry a real transaction from account access through order acceptance and post-order visibility. A storefront that collects orders for employees to re-enter elsewhere is a prototype, not a completed digital channel.

    Make AI discoverability a data and content requirement

    AI-assisted product discovery, integrated experiences, and personalization are shaping the next stage of B2B commerce. Preparing for that shift is not primarily a chatbot project. It is a product-data, content, identity, and integration project.

    Start with the public information layer. A search engine or frontier model cannot reliably surface commercial facts that exist only in a sales representative’s notes, an inaccessible file, or an authenticated portal. Give each indexable product, category, solution, or application a stable page where a buyer can understand what it is, who it is for, what problem it addresses, and how it relates to other entities in your catalog.

    For product and solution content, make the important facts explicit rather than forcing a system to infer them. Use consistent names, manufacturer identifiers, SKUs, units, specifications, compatibility statements, application language, and lifecycle terminology. Explain synonyms and industry vocabulary where buyers use different terms for the same item. Link related products, categories, applications, support material, and policies through crawlable navigation.

    Add applicable JSON-LD only when it represents the visible page accurately. Product, offer, organization, and breadcrumb data can help machines interpret entities and relationships, but markup cannot repair contradictory source data or thin content. Validate that identifiers, names, currencies, availability language, and canonical URLs agree across the page, structured data, feeds, and commerce APIs.

    B2B pricing creates an important boundary. Public structured data must not expose confidential contract terms or imply that a general price applies to every account. Keep account-specific catalogs, negotiated prices, credit information, order history, and permissions behind authentication. On public pages, explain the purchasing process and how eligibility or terms are determined when your policies allow it.

    Build the public truth layer before adding logged-in personalization. Personalization should select or arrange reliable information for a known account; it should not create a separate set of facts that cannot be traced to an owner. The same rule applies to an AI assistant. It should retrieve approved product, policy, and order information through controlled interfaces, identify the account before exposing private data, and hand the conversation to a person when it cannot verify an answer.

    Test AI readiness with buyer tasks, not novelty prompts. Can a system distinguish similarly named products, find a compatible option from published facts, explain the difference between two categories, locate the correct purchasing path, and cite the canonical page? Record wrong answers by cause: missing content, conflicting identifiers, inaccessible information, weak relationships, or stale source data. Fix the underlying cause rather than rewriting prompts around it.

    AI visibility is not guaranteed by a schema type, content template, or platform choice. The defensible objective is to make your public information unambiguous, internally consistent, current, and easy to retrieve. That improves the foundation for conventional search, answer engines, and on-site assistance without pretending that any implementation can guarantee a citation or ranking.

    Run a phased plan with evidence-based decision gates

    Platform transformation fails when selection, integration, migration, content, and adoption are treated as separate projects that happen to share a launch date. Run them as one program with a decision gate at the end of each phase.

    1. Define the operating model. Produce the buying scenarios, pass-or-fail requirements, source-of-truth matrix, current performance baseline, and named data owners. The gate is agreement across commercial, operational, financial, and technical teams about what the system must do.
    2. Prove the architecture. Execute critical scenarios with representative data. Identify every configuration, extension, integration, and external dependency. The gate is evidence that the proposed design can support the hard transactions without uncontrolled core customization.
    3. Launch a complete MVP. Limit scope deliberately, but complete the transaction and service loop for the chosen cohort. The gate is a real order that can be priced, submitted, accepted, reconciled, tracked, and supported without hidden manual repair becoming the default process.
    4. Harden operations. Test failure handling, monitoring, reconciliation, security boundaries, migration, support procedures, and rollback. The gate is not the absence of all errors; it is proof that errors are visible, owned, recoverable, and accurately communicated.
    5. Expand from observed behavior. Add customer groups, catalog scope, workflow sophistication, personalization, and AI-assisted experiences in response to measured demand and feedback. The gate is a demonstrated problem or opportunity, not an unused feature on the platform roadmap.

    This approach preserves speed because it exposes incorrect assumptions while the affected scope is still limited. Starting with an MVP, refining it through feedback, and planning delivery in phases also gives you a practical way to adapt the platform as business needs change.

    Measure the operating outcome, not merely traffic and launch completion. Useful measures can include successful order completion, manual corrections per order, price discrepancies, integration failures, duplicate transactions, time spent resolving exceptions, repeat-order success, status-related service contacts, and adoption among eligible accounts. Establish the baseline before launch, assign an owner to each measure, and define what action a poor result will trigger.

    Your implementation partner should be able to discuss those operating outcomes as fluently as the platform. Look for evidence that the team understands your industry, can challenge unnecessary customization, can map ERP and commerce responsibilities, and will document the decisions your internal team must inherit. The deliverable is not just deployed code. It is a system your organization can understand and change.

    Key takeaways

    • Choose a platform against testable buying scenarios, not a generic feature list.
    • Use pass-or-fail gates for commercial rules that affect access, price, order validity, or reconciliation.
    • Prefer supported configuration and extension points; make every customization justify its lifecycle cost.
    • Define ownership, failure handling, and reconciliation for ERP data before designing interfaces.
    • Prepare for AI discovery by building a consistent public information layer while keeping account-specific data private.
    • Start with a limited but complete transaction loop, then expand from measured behavior and customer feedback.

    Your next move is to put commerce, sales, operations, finance, service, and technology around the same set of revenue-critical scenarios. If a platform cannot prove those journeys with your data, remove it from the shortlist. If it can, you have the basis for an MVP that solves an operational problem now and a commerce architecture that can still change after 2026.

    References

  • How to Build a B2B Go-to-Market Operating Model

    How to Build a B2B Go-to-Market Operating Model

    Your go-to-market strategy can be sound while execution still feels improvised. Marketing generates demand, sales qualifies it, enablement creates materials, and customer teams hear the objections, but each function uses a different definition of progress. That is an operating-model gap.

    You close that gap by specifying how buyer evidence becomes a decision, how work crosses team boundaries, where the official record lives, and how feedback changes the system. The goal is not a larger process manual. It is a small set of rules that helps your teams make the same good decision without rebuilding the process around every campaign or deal.

    Separate your strategy from the system that runs it

    A GTM strategy defines where you intend to compete and how you expect to win. A GTM operating model defines how people, workflows, systems, and decision rights turn those choices into coordinated action. An execution plan covers the work currently in motion.

    LayerQuestion it answersRequired output
    GTM strategyWhere will we play, for whom, and why should they choose us?Target market, buyer problem, value proposition, commercial motion, and strategic constraints
    GTM operating modelHow will teams repeatedly turn those choices into revenue work?Buyer stages, decision rights, handoffs, workflows, systems of record, controls, and feedback loops
    Execution planWhat are we doing now?Active accounts, campaigns, opportunities, experiments, deliverables, owners, and commitments

    The distinction matters because changing tools does not repair an undefined decision. Adding an AI assistant does not repair a weak handoff. Hiring another specialist does not repair incompatible stage definitions. Start with the outcome the system must produce, then decide which roles and technology support it. That follows an outcome-first Service as Software principle: the useful unit of design is the result, not the tool itself.

    Use the following questions as a completeness test. If the answers depend on whom you ask, the operating model is still implicit:

    • Which buyer and buying situation does this revenue motion serve?
    • What observable evidence moves an account from one stage to the next?
    • Who decides whether that evidence is sufficient?
    • What information must accompany a handoff?
    • Where is acceptance, rejection, or rework recorded?
    • Which signal causes the team to change targeting, messaging, channel use, or process?
    • Which decisions may AI support, and which still require human approval?

    Do not begin with the organization chart. Roles will change, and the same role name can carry different authority in different companies. Begin with a bounded revenue motion: a defined audience, problem, offer, route to market, and desired customer outcome. Build the operating model around that flow of value.

    Use buyer progression as the spine of the model

    A central illuminated path connects successive buyer situations while several business teams contribute evidence at different stages.

    Internal funnel labels are useful only when they correspond to something that has changed for the buyer. A label such as MQL describes an internal classification. It does not, by itself, tell sales what the buyer understands, what evidence exists, or what should happen next.

    Define stages as buyer states that your team can recognize from evidence. Starter language might include exploring a problem, validating an approach, resolving risk, committing to a decision, and beginning adoption. Those names are not universal. The important part is that each state has an observable entry condition and an observable exit condition.

    1. Write the audience, buying situation, problem, offer, and route to market on a shared brief. If those choices vary materially, you may be dealing with separate revenue motions that need separate rules.
    2. Name each buyer state in plain language. Avoid stage names that merely identify the department currently holding the record.
    3. Define entry evidence. Specify what must be known or confirmed before an account belongs in that state.
    4. Define exit evidence. Use a change in buyer commitment, understanding, access, or risk resolution rather than a seller activity such as sending an email.
    5. Assign an accountable owner, the required system fields, and the next commitment that advances the buyer.
    6. Define what happens when evidence is missing, the buyer pauses, or the account no longer fits. Recycling and disqualification are operating paths, not miscellaneous exceptions.

    A stage specification should be usable during live work, not only during training. Give each stage the following fields:

    FieldQuestion to answerExample of useful evidence
    Buyer stateWhat is now true for the buyer?The problem has been confirmed in the buyer’s own terms
    Entry conditionWhat evidence allows the record to enter?A relevant stakeholder has confirmed the operational consequence
    Exit conditionWhat must change before the record advances?The buyer has agreed to evaluate a defined approach
    Accountable ownerWho decides whether the condition is met?The role with the authority and context to accept the stage
    Required recordWhere can another team verify the evidence?A structured field plus a concise evidence note in the system of record
    Next commitmentWhat mutually understood action advances the buyer?An agreed review with the relevant participants and purpose
    Return pathWhat happens if the evidence is incomplete?Return to the prior owner with a recorded reason and required correction

    Test the definitions against active accounts. Give independent teammates the same evidence and ask them to classify the buyer state and identify the next action. If they reach different answers, do not add more dashboard fields yet. Tighten the stage language, evidence standard, or decision owner.

    This buyer-centered spine also keeps content connected to revenue work. Every important asset should support a specific buyer question, evidence requirement, risk, or next commitment. If nobody can name the buyer state and decision the asset supports, its place in the operating model is unclear.

    Give decisions and handoffs explicit owners

    Cross-functional collaboration does not mean collective accountability. A decision can have many contributors, but it needs a clearly identified owner with enough authority, information, and capacity to make the call. Otherwise, teams keep revisiting the same issue while execution moves ahead on incompatible assumptions.

    Keep a lightweight decision record

    Record recurring or consequential GTM decisions in a shared location. This is not a transcript of the discussion. It is the minimum context someone needs to execute the decision and know when it may be reopened.

    • Decision: State the choice in terms that can be acted on.
    • Owner: Name the role responsible for making and maintaining the decision.
    • Required inputs: Identify the buyer, market, operational, financial, or risk evidence needed.
    • Decision rule: Explain what would make one option preferable to another.
    • Contributors: List the roles that supply expertise without transferring ownership.
    • Record: Link the approved definition, workflow, message, or configuration affected.
    • Revisit condition: Name the new evidence or material change that would justify reopening the choice.

    Apply this structure to decisions such as target-account eligibility, stage acceptance, message approval, channel allocation, proof requirements, process exceptions, and permitted AI use. The owner may differ by decision. What should not change is the visibility of the ownership.

    Treat every handoff as a contract

    A handoff is not complete when the sending team changes a status field. It is complete when the receiving team can accept the work, understand why it matters, and take the next action without reconstructing the missing context.

    For each important boundary, document:

    • Trigger: The buyer evidence or operational event that starts the handoff.
    • Payload: The fields, notes, assets, permissions, and context that must travel with it.
    • Receiver response: The available outcomes, such as accept, reject, or return for correction.
    • Reason codes: A short, controlled set of explanations that can reveal repeated failure patterns.
    • Response expectation: The agreed service window and the event that starts it.
    • System of record: The place where status, evidence, ownership, and response are authoritative.
    • Escalation path: The owner who resolves a disputed definition or stalled boundary.

    Track acceptance and rework, not just handoff volume. High volume can look productive while the receiving team quietly discards weak records. Repeated rejection for the same reason usually points to a targeting problem, an evidence problem, an unclear definition, or a missing field. Fix that boundary instead of asking the sender to produce more volume.

    The same contract should cover the transition from sales to onboarding and from customer feedback back to marketing, product, and enablement. A GTM model is incomplete if it ends when a deal is marked won. The promises made during acquisition need to remain visible to the team responsible for delivering and expanding the relationship.

    Run feedback loops that change the work

    Four connected teams collect customer signals, identify patterns, update modular processes, and return the revised system to frontline work.

    A full meeting calendar is not a feedback system. Every operating ritual needs a defined question, required inputs, a decision it can produce, an owner, and a place where the result changes the workflow.

    • Flow review: Identify where buyer progress is blocked, where records wait, and where work returns for correction. The output is an owner and a change to the blocked path.
    • Market-signal review: Examine recurring objections, failed assumptions, competitive pressure, search behavior, and language used by buyers. The output may change targeting, positioning, content, or qualification.
    • Experiment review: Compare the original hypothesis, execution, observed signal, and decision. The output is to continue, change, stop, or design a better test.
    • Adoption review: Determine whether the intended users can perform the process inside their normal tools. The output is a workflow, training, field, or artifact change.
    • Promise-delivery review: Compare what acquisition teams promised with what onboarding and customer teams can deliver. The output is a corrected promise, delivery change, or escalation.

    Match the cadence to the rate at which useful evidence appears. Routing problems need an execution cadence because they obstruct current work. Positioning changes need enough accumulated market evidence to distinguish a pattern from an isolated comment. Do not use the same meeting rhythm for every decision merely because the calendar makes that convenient.

    Use a metric stack that exposes both business results and the mechanism producing them:

    • Outcome measures show commercial progress, customer value, and retention.
    • Flow measures show movement, waiting, conversion, and backlog across buyer stages.
    • Quality measures show acceptance, completeness, correction, and avoidable rework.
    • Adoption measures show whether the intended workflow and assets are actually being used.
    • Learning measures show which assumptions were tested and which decisions changed as a result.

    For every metric, document its definition, data source, owner, review context, and the decision it can trigger. A dashboard that cannot change a decision is reporting overhead. A dashboard whose definitions vary by function is a visual version of the operating-model problem.

    Put AI inside a controlled workflow

    AI should have the same operational discipline as any other part of the GTM model. Do not make adoption of an AI tool the outcome. Define the work it supports, the evidence it may use, the quality standard it must meet, and the accountable human decision.

    • Permitted input: Specify which customer, market, performance, and internal data may enter the workflow.
    • Bounded task: Define whether AI is classifying, drafting, retrieving, summarizing, recommending, or executing.
    • Acceptance criteria: State what makes the output accurate, relevant, complete, brand-safe, and usable.
    • Approval boundary: Identify what a person must verify before publication, customer contact, data change, or commercial action.
    • Audit record: Preserve the input context, output, reviewer, disposition, and downstream action where the risk warrants it.
    • Fallback: Define how work continues when the model, integration, or output is unavailable or unsuitable.

    For SEO, AEO, and GEO content workflows, acceptance may include traceable claims, a defined search or buyer intent, approved product language, clear ownership of structured data, and editorial review before publication. That connects AI-assisted content to the GTM system instead of allowing generated assets to accumulate without a buyer decision or distribution path.

    Earn sophistication through adoption

    A new operating model usually fails at the point of use, not at the level of the diagram. If a seller must leave the CRM, find a separate document, reinterpret a stage, and duplicate the evidence in another system, the designed workflow is competing with the actual job.

    Behavior change depends on fitting enablement into daily work. A polished deck cannot compensate for a process that requires extra steps at every deal. Put definitions, prompts, assets, approvals, and feedback controls where the relevant decision occurs. Train with live work, and observe where users hesitate, invent workarounds, or omit information.

    Use the Shu Ha Ri progression from fundamentals toward innovation as a practical maturity lens:

    • Stabilize the standard: Establish common language, buyer stages, owners, handoff rules, and an authoritative record. At this point, consistency matters more than customization.
    • Adapt from evidence: Change a bounded part of the model when recorded exceptions, buyer signals, or adoption friction reveal a real mismatch. Preserve the reason for the change so adaptation does not become drift.
    • Innovate on a stable base: Add custom automation, AI agents, new channels, or differentiated motions only after the underlying decision and feedback paths are visible. Automation scales ambiguity as readily as it scales good work.

    Roll out the model through a revenue motion that matters and is narrow enough to observe. Embed its required fields and decisions in the systems people already use. Remove duplicate paths where it is safe to do so, because leaving the old workflow available teaches users that the new model is optional. Keep an exception route for legitimate edge cases, but require a reason that can feed the adaptation loop.

    Before expanding the model, look for operational proof:

    • Independent teammates classify the same buyer evidence consistently.
    • Receivers accept, reject, or return handoffs with a recorded reason.
    • Teams can find the current decision, asset, and definition at the point of work.
    • Operating reviews produce documented changes rather than repeated discussion.
    • Exceptions reveal patterns that can improve the standard path.
    • AI-supported outputs have visible acceptance criteria, review ownership, and disposition.

    Key takeaways

    • A GTM strategy defines the choices; a GTM operating model defines how teams repeatedly execute and revise those choices.
    • Build the model around observable buyer progression, not departmental funnel labels.
    • Give every recurring decision an accountable owner and every cross-team handoff an acceptance contract.
    • Measure outcomes, flow, quality, adoption, and learning so you can see both the result and its mechanism.
    • Place AI inside a bounded, reviewable workflow with explicit inputs, acceptance criteria, approval, and fallback.
    • Standardize before you customize, then innovate only when feedback and adoption are reliable.

    Choose the revenue motion creating the most consequential friction now. Map its buyer states, write the acceptance contract for its weakest handoff, and assign the unresolved decisions. Once the people doing the work can point to the same evidence and know who decides what happens next, expand the model to the next boundary.

    References

  • How to Build an AI Marketing Tool Stack That Actually Works

    How to Build an AI Marketing Tool Stack That Actually Works

    If every campaign begins with hunting through tabs, copying context between tools, and checking which draft is current, your marketing stack is consuming the attention it was supposed to save. Another AI subscription will not fix a broken handoff.

    The fix is to design the stack around a repeatable workflow: where trustworthy information enters, what each tool changes, who approves the result, where the finished work goes, and how the outcome informs the next decision. Do that first, and choosing tools becomes much easier.

    Map the campaign before you choose the software

    Marketing software already spans content creation, conversion-rate optimization, design, analytics, and AI visibility. That breadth creates a predictable buying mistake: teams compare tools within each category before deciding how those categories need to work together.

    Start with a campaign your team performs often. Map the work from the event that starts it to the decision made after results arrive. Do not map an idealized process. Use the path a real brief, asset, landing page, email, or report currently follows.

    For every stage, complete a workflow card with these fields:

    • Trigger: the event that starts the work, such as an approved campaign objective, a product update, or a performance question.
    • Authoritative input: the facts, instructions, audience data, brand rules, and approved claims the stage is allowed to use.
    • Transformation: the specific job performed, such as turning a brief into draft copy or converting approved copy into channel variants.
    • Output: the artifact produced, including its required format, fields, status, and destination.
    • Approval: the person accountable for deciding whether the output can move forward.
    • Feedback: the evidence that should change the next brief, asset, audience choice, or optimization decision.

    This exercise exposes the real gaps. You may discover that several tools can generate copy while none carries an approved product claim into the prompt. You may find that design files lose their campaign identifiers before analytics can connect them to outcomes. You may also find that a report is produced regularly but never changes a decision.

    Mark every place where a person copies information, renames an artifact, changes a format, requests approval, or reconciles conflicting versions. Those seams are usually better automation candidates than the visible creative task. Generating another draft is less valuable if someone still has to determine which facts it used, paste it into another system, and rebuild its history by hand.

    Also separate assistance from authority. An AI tool can classify feedback, propose a campaign angle, rewrite copy, or summarize performance. It should not quietly become the source of truth for product facts, consent status, approved language, pricing, or campaign results. Keep those records in the systems that already own them, and pass only the required context into the AI layer.

    Give each layer a job, an owner, and a handoff

    Five connected campaign stations show team members handing work from research and creation through approval, publishing, and measurement.

    A useful stack is not a pile of applications. It is a chain of accountable artifacts. A tool may serve more than one layer, but two tools should not silently own competing versions of the same brief, asset, audience, or performance record.

    Stack layerJob it ownsRequired handoffWarning sign
    FoundationMaintains approved facts, audience definitions, brand rules, permissions, and campaign identifiers.Current, structured context with a named owner and status.People use an AI-generated summary as the authoritative record.
    Planning and researchTurns an objective and evidence into a brief, audience question, channel plan, or test hypothesis.An approved brief that states the goal, constraints, evidence, and decision to be made.The rationale disappears and only the generated idea survives.
    Content and designCreates draft copy, visual directions, variants, and production assets from the approved brief.Reviewable assets carrying the campaign identifier, source context, and approval status.Drafts multiply faster than reviewers can verify them.
    Conversion and deliveryAssembles the customer-facing experience and sends or publishes approved material.A published identifier, destination, audience or variant record, and rollback path.Publishing is automated before claims, links, targeting, and tracking are checked.
    AnalyticsConnects delivery records with observable behavior and business outcomes.Evidence tied back to the campaign, asset, audience, and decision.A dashboard reports activity without identifying what should change.
    AI visibilityObserves how the brand, products, and pages appear in relevant AI-generated answers.The tested question, exact answer, mention or citation, cited URL, and content change under review.A visibility score is reported without the prompts and answers behind it.

    The foundation layer deserves more attention than it usually gets. Generated work is only as dependable as the context supplied to it. If a prompt can pull an outdated claim, an unapproved positioning statement, and a current product description with equal confidence, better generation will only produce a more convincing inconsistency.

    Make the handoff itself a contract. Define the fields that must be present, the allowed source, the owner, the approval state, and the destination. A content handoff might require a campaign identifier, target question, approved factual claims, audience, call to action, destination URL, reviewer, and status. If an output lacks a required field, it is incomplete even when the writing looks polished.

    The AI visibility layer needs the same discipline. Build a stable set of questions that reflect how prospective buyers investigate the problem, compare approaches, and evaluate risk. For each check, preserve the question, the generated answer, whether the brand or page appeared, the exact cited URL when one is present, and whether the representation was accurate. A single answer is an observation. A controlled record gives you something you can compare after content, entity information, or internal linking changes.

    Your operating flow should now be legible in a single line: approved context becomes a brief; the brief becomes reviewable assets; approved assets become a published experience; delivery records become evidence; evidence and AI visibility observations become the next decision. Any tool that cannot participate in that flow needs an exceptional reason to remain in the stack.

    Put every candidate through a real task and a failure test

    Two marketers test an AI tool with normal campaign materials and problematic inputs while checking its outputs against source cards.

    Feature lists reward breadth. Your team benefits from fit. A tool that can perform many impressive tasks may still create more work if it requires special input formatting, hides its references, traps approved output, or cannot preserve the identifiers your workflow needs.

    Run the task trial

    Use a representative task from the workflow map, including the awkward parts. Vendor samples and pristine prompts remove the context conflicts, exceptions, and approval requirements that determine whether a tool survives normal use.

    1. Prepare a real input package. Include the approved brief, source material, brand constraints, required output format, and an intentionally irrelevant document. The candidate should use the right context and ignore the wrong context.
    2. Define acceptance before generating. State which facts must be preserved, what the output must contain, what it must avoid, who will review it, and where it needs to go next.
    3. Complete the task without hidden cleanup. Record every manual copy, format conversion, prompt repair, factual check, permission change, and upload required to reach an approved output.
    4. Force an exception. Remove a required field, introduce conflicting instructions, deny a permission, or supply an unsupported request. Check whether the tool stops clearly, requests clarification, or produces a plausible but unusable answer.
    5. Inspect the handoff. Export the output and confirm that its identifier, status, references, and revision context survive. A polished artifact with no reliable lineage is difficult to govern and measure.
    6. Test reversibility. Confirm that your team can correct, replace, unpublish, or roll back the result without reconstructing the workflow from memory.

    Apply non-negotiable buying gates

    Do not average a serious weakness into a high overall score. A candidate should be disqualified if it fails a requirement that protects data, approvals, measurement, or continuity. Use these questions as gates:

    • Workflow fit: Does it remove a defined bottleneck, or does it merely produce another version of an artifact you already have?
    • Context control: Can you specify which material is authoritative, restrict irrelevant context, and update stale information without rebuilding everything?
    • Traceability: Can reviewers determine which inputs, instructions, and revisions produced the output?
    • Output control: Can approved work leave the tool in the format your CMS, campaign platform, analytics process, or archive requires?
    • Access control: Can permissions separate viewing, generating, approving, publishing, spending, and administrative actions where your workflow requires that separation?
    • Integration fit: Does it work with the identifiers and systems you already use, or will the team maintain a fragile manual bridge?
    • Failure behavior: When context, permissions, integrations, or instructions fail, does the problem become visible before the output reaches a customer?
    • Economic fit: Which usage driver creates cost, and does that driver grow with valuable approved work or with drafts, retries, storage, and duplicated seats?
    • Exit readiness: Can you retrieve approved assets, history, configuration, and required metadata if the tool no longer fits?

    Once the non-negotiable candidates survive, compare the work removed from the complete process. Count review and correction as part of the task. A generator that produces drafts quickly but shifts substantial verification and formatting onto senior staff has not eliminated that work; it has moved it to a more expensive point in the workflow.

    Overlap should face the same test. If two tools generate similar outputs, decide which one owns the artifact, which one handles an explicitly different exception, and where the final version lives. If you cannot state those roles plainly, the overlap will eventually create duplicate spend, inconsistent instructions, or conflicting campaign records.

    Control automation, then measure the decisions it improves

    Limit write access until the workflow is proven

    Automation becomes materially riskier when it can publish, message customers, change targeting, alter advertising spend, or overwrite business records. A wrong draft is recoverable. A wrong draft sent to an audience, attached to live spend, or written over trusted data can create financial, reputational, and data-integrity damage.

    Evaluate new automation with read-only access or in a separate test environment where practical. Keep a person in the approval path for factual and legal claims, public publishing, audience-wide sends, budget or bid changes, and destructive record updates. Expand permissions only after the team has documented the normal path, exception path, owner, and rollback procedure.

    For every automated step, record:

    • the event that triggered it;
    • the authoritative inputs and campaign identifier;
    • the instruction or workflow version;
    • the output and destination;
    • the checks applied;
    • the approver when approval is required;
    • the exception raised, if any; and
    • the action needed to reverse or correct the result.

    This record is not bureaucracy for its own sake. It lets you distinguish a bad instruction from stale context, an integration failure from a model error, and an approved change from an unauthorized one. Without that distinction, the team can see that something went wrong but cannot correct the mechanism that caused it.

    Measure approved work, not raw generation

    Output volume is an easy metric and often the wrong one. More drafts can increase review queues, version conflicts, and publishing delays. Evaluate the stack at the point where work becomes usable and at the point where it informs a business decision.

    • Flow: Track elapsed time from the workflow trigger to approved output, not merely generation time.
    • Acceptance: Track how much generated work reaches approval without substantial factual, brand, or structural correction.
    • Rework: Record why work returns for revision. Repeated failures usually point to missing context, a weak handoff contract, or an unsuitable task.
    • Exception load: Track how often people must rescue, reroute, or reconstruct the process outside the intended workflow.
    • Unit economics: Include subscriptions, usage charges, integration upkeep, review, correction, and administration when comparing the cost of approved output.
    • Downstream outcome: Connect the approved artifact to the relevant campaign result before claiming that the stack improved marketing performance.
    • Decision value: Name the decision each report or visibility check changed. If it never changes a brief, budget, page, message, audience, or test, reconsider why it exists.

    Preserve campaign and asset identifiers through publication and measurement. That lineage lets analytics connect an outcome to the actual approved artifact instead of to a generic channel label. It also prevents a common attribution error: crediting an AI tool for a business result when the result may also reflect the offer, audience, distribution, timing, page experience, or human edits.

    Apply the same restraint to AI visibility. If a relevant answer begins mentioning or citing a page after you change it, record the sequence as a useful signal, not automatic proof of causation. Preserve the prompt, answer, cited page, content revision, and test conditions. The purpose of the visibility layer is to produce evidence your content and SEO teams can inspect, not a score that floats free of observable answers.

    At campaign close, review the tools alongside the workflow. Keep a tool when it owns a necessary job, passes its handoff cleanly, and improves a decision or an approved outcome. Reconfigure it when the problem is context or process. Remove it from the workflow when it duplicates an owner, creates persistent hidden work, blocks traceability, or produces information nobody uses.

    Key takeaways

    • Map a real campaign from trigger to decision before comparing AI tools.
    • Keep approved facts and business records in authoritative systems; use AI to transform controlled context rather than replace the source of truth.
    • Assign every layer a job, an artifact owner, a required handoff, and an exception path.
    • Trial candidates with representative inputs, explicit acceptance criteria, an induced failure, and an export test.
    • Keep publishing, customer messaging, spend changes, and destructive record updates behind appropriate approval and rollback controls.
    • Measure time to approved work, rework, exception load, complete cost, downstream outcomes, and the decisions changed.
    • For AI visibility, preserve the question, exact answer, mention or citation, cited URL, and related content change.

    Open your last completed campaign and list every handoff from approved context to measured outcome. Mark where information was copied, ownership became unclear, or a result failed to reach the next decision. Fix the most consequential seam before you add another subscription. That is where a tool stack begins to become an operating system for marketing rather than a collection of accounts.

    References

  • Marketing Is Becoming AI Systems Engineering: What to Build

    Marketing Is Becoming AI Systems Engineering: What to Build

    Your team can use AI to produce campaigns, briefs and content faster. That does not automatically make the operation faster. If reviewers cannot trace a claim, teams keep correcting the same errors, or nobody knows which instruction produced an output, the saved production time simply moves into review and repair.

    This is not mainly a prompting problem. It is a systems problem. As marketing moves toward engineering and AI-shaped roles, the practical advantage comes from designing reliable inputs, decision rules, interfaces, controls and feedback loops. You do not need to turn every marketer into a software engineer. You do need to make the marketing operation understandable enough to test, govern and improve.

    Production is no longer the only bottleneck

    A conventional campaign workflow is often organized around deliverables. A strategist writes a brief, a creator makes an asset, a reviewer approves it, an operator publishes it and an analyst reports on it. The handoffs may be inefficient, but each person can usually explain what they did.

    AI changes that structure. A model may summarize research, infer an audience, select supporting facts, generate variants, assign metadata and recommend distribution. What looks like a single content-generation step can contain several hidden decisions. When those decisions are not explicit, a fluent output can conceal a weak premise, an outdated input or an unsupported claim.

    The unit of management therefore has to change from the asset to the decision pipeline. For every AI-assisted workflow, you should be able to answer:

    • What business decision or customer action is this workflow meant to support?
    • Which information is allowed to influence the output?
    • Which decisions are fixed rules, and which are left to a model?
    • What must be true before the output can move to the next stage?
    • Who owns the result when several tools and teams contributed to it?
    • What signal will cause the system to stop, fall back or be revised?

    This distinction also prevents needless use of generative AI. A product name stored in an approved catalog should be retrieved exactly, not recreated from a prompt. A required JSON field should be validated by software, not judged by whether its formatting looks plausible. Generative models are useful where interpretation or variation is valuable. Deterministic rules are better where the correct result is already known.

    A quick diagnostic is to pick a live campaign and trace one customer-facing claim backward. If you cannot identify its approved origin, the transformation that produced it, the validation it passed and the person accountable for releasing it, you have found a system gap. Rewriting the prompt may hide that gap for a while, but it will not close it.

    Map the marketing operating system before buying more tools

    An isometric marketing workflow connects source materials, planning, AI creation, human review, distribution and feedback while isolated tool modules sit at the edge.

    Tool selection is easier after the workflow is visible. Start at the point where an objective is accepted, not where somebody opens an AI interface. End where performance evidence changes a later decision, not where an asset is published. That wider boundary exposes missing inputs, duplicated approvals and feedback that reaches a dashboard but never reaches the system.

    The layers every workflow needs

    LayerDecision to makeWorking artifactFailure signal
    IntentWhat outcome and audience are in scope?Workflow brief with acceptance criteriaOutput is polished but unrelated to the business decision
    KnowledgeWhich facts, policies and examples are approved?Source registry with owners and review conditionsClaims cannot be traced or conflict across outputs
    LogicWhich rules, model calls and exceptions transform the inputs?Decision map and versioned instructionsSimilar inputs follow inconsistent paths
    DeliveryWhere may the result be written, published or activated?Channel specification and permission policyContent reaches the wrong destination or bypasses review
    QualityWhat must pass before the next action?Evaluation cases, validators and approval policyReviewers repeatedly catch the same preventable defect
    FeedbackWhich outcome should change the next decision?Monitoring view and change logPerformance is reported but workflow behavior does not improve

    The knowledge layer deserves particular attention. A source of truth does not have to be one enormous document. It means that each important fact has an authoritative home, a responsible owner and a clear way to resolve conflicts. Product specifications may belong in a catalog, brand language in a controlled library and legal restrictions in an approval policy. Copying all of them into an unowned prompt creates another version that can drift.

    Next, mark each decision as deterministic, probabilistic or human. Eligibility rules, required fields, naming conventions and permission checks are usually candidates for deterministic handling. Drafting, clustering and interpreting ambiguous language may need probabilistic handling. Decisions involving strategic tradeoffs, sensitive claims or material consequences should retain accountable human judgment.

    Then make the interfaces explicit. An input contract should state which fields are required, what format they use, where their values come from and what happens when information is missing. An output contract should define the expected structure, permitted destinations, prohibited content and validation requirements. A JSON schema, a CMS field definition or a structured brief can all serve as a contract. The point is to make failure visible instead of allowing each stage to guess what the previous stage meant.

    Control AI with contracts, evaluations and observability

    A transparent AI workflow passes content through an input gate, sensor-filled inspection chamber and human-supervised release gate, with source trails and a repair loop.

    A prompt is configuration, not a complete control system. It can express the desired behavior, but it does not prove that the right input arrived, that the output is grounded, or that the next tool used the result safely. Reliable workflows place controls around the model rather than expecting the model to control itself.

    Test behavior before granting action

    Build an evaluation set from the situations the workflow must handle. Include routine requests, ambiguous instructions, missing fields, stale or conflicting information, prohibited claims and inputs that should trigger escalation. The expected result does not need to prescribe exact wording. It can define pass-or-fail conditions such as using an approved fact, preserving a required field, refusing an unsupported request or routing an exception to a reviewer.

    Evaluate separate qualities separately. Structural validity, factual grounding, audience relevance, brand compliance and channel suitability are different questions. A single quality score makes diagnosis difficult: the score can improve while a business-critical failure remains hidden. Record the failure category so the team knows whether to repair the knowledge, rule, prompt, integration or approval step.

    An AI-based evaluator can help triage outputs, but it is not independent proof. When similar model behavior produces and judges an answer, the same blind spot can affect both stages. Use deterministic validation wherever the requirement can be expressed as a rule, compare factual claims with approved information, and preserve human review for consequences that cannot be reduced to formatting checks.

    Log enough context to reconstruct a failure

    Useful observability lets you connect an outcome to the state of the system that produced it. For each run, retain the input reference, knowledge version, workflow or prompt version, model or service used, validation result, approval state and destination. Protect those records according to the sensitivity of the data they contain. A performance dashboard alone is not observability if it cannot show which system change preceded a failure.

    Define stop and fallback behavior before activation. If a required input is absent, the workflow can request it rather than inventing it. If a validator fails, the output can remain a draft. If a service is unavailable, the workflow can route work to a manual queue instead of silently skipping a control. Every automated action should also have a named owner who can pause it and a recovery path appropriate to the change it makes.

    Match autonomy to consequence:

    • For reversible internal suggestions, review samples and monitor recurring failure types.
    • For customer-facing content, require validation against approved facts and a clear publication policy.
    • For audience selection, material budget changes or actions that alter customer records, keep permissions narrow and require accountable approval before execution.
    • For workflows involving personal data, regulated claims, contractual promises or legal obligations, involve the appropriate privacy, legal, compliance or financial owner before activation. A technically valid output can still create exposure.
    • For destructive or difficult-to-reverse actions, use a staging environment, explicit confirmation and a tested rollback path rather than direct autonomous access.

    Do not expand a workflow’s permissions because a handful of outputs looked good. Expand them only after the system handles ordinary inputs, edge cases and failures in a way the responsible owner can inspect and accept.

    Redesign roles around system ownership, not prompt writing

    The engineering shift does not require renaming every marketer as a developer. It requires assigning responsibilities that campaign-oriented teams often leave implicit. A small team may combine several responsibilities in the same person, but each responsibility still needs an identifiable owner.

    • System owner: defines the workflow’s purpose, acceptable behavior, boundaries and business outcome. This person decides when the system should change or stop.
    • Knowledge owner: maintains approved facts, policies, examples and review conditions. This person resolves conflicts instead of allowing the model to choose between competing versions.
    • Workflow builder: connects tools, expresses rules, manages permissions and designs fallback behavior. This may be a marketing operations, automation or engineering responsibility.
    • Evaluator: creates test cases, classifies failures and checks whether changes improve the intended behavior without breaking another requirement.
    • Operator or analyst: monitors live performance, investigates anomalies and turns business feedback into proposed system changes.

    The handoff between these responsibilities matters more than the job titles. Before launch, everyone should know who can change an instruction, who can approve a new knowledge source, who reviews exceptions, who can grant write access and who can stop the workflow. If those answers live only in informal conversations, the operation will become harder to govern as automation spreads.

    Measure reliability as well as output

    Asset volume becomes less informative when generation is inexpensive. Track whether the system produces usable work and supports the intended business decision. Depending on the workflow, useful operating measures may include first-pass acceptance, rework by failure category, unsupported-claim incidents, manual intervention, recovery time and cost per approved result. Pair them with the actual marketing outcome; a technically stable pipeline that does not improve customer or business behavior is still the wrong system.

    This also changes career development. If you are an individual contributor, learn to map a process, write acceptance criteria, structure information, inspect a run log and design a useful edge case. If you manage or hire people, test whether they can diagnose a broken workflow. Give them a scenario with conflicting inputs, an invalid output and an unclear owner. Ask what they would inspect first, which control they would add and how they would know the repair worked. That reveals more than asking for a favorite prompt.

    Key takeaways and a safe place to start

    • AI-driven marketing systems engineering means designing the full decision pipeline, not merely adding generation to an existing task.
    • Use deterministic rules for known requirements and probabilistic models where interpretation or variation creates value.
    • Give every important fact an approved home and owner before placing it inside an automated workflow.
    • Define input and output contracts so missing data, invalid structure and prohibited actions fail visibly.
    • Evaluate edge cases, log system versions and set stop conditions before granting a workflow permission to act.
    • Assign ownership for the system, knowledge, implementation, evaluation and live operation even when one person holds several responsibilities.

    Begin with a workflow that is frequent enough to observe, bounded enough to map and reversible enough to recover. Drafting a brief from approved material or classifying incoming requests is easier to contain than a workflow that publishes claims, changes spend and updates customer data in the same run.

    1. Draw the current workflow from accepted objective to feedback, including manual copying, approvals and exception handling.
    2. Choose one recurring failure or delay. Do not redesign every stage at once.
    3. Name the approved inputs and their owners, then write the input and output contracts.
    4. Create evaluation cases for normal, ambiguous, missing, conflicting and prohibited inputs.
    5. Run the AI-assisted version in shadow mode: let it produce recommendations or drafts without publishing, spending or changing records.
    6. Compare its behavior with the acceptance criteria and classify every meaningful failure by cause.
    7. Grant only the permissions needed for the next bounded action, with monitoring, an approval rule and a recovery path.
    8. Version every material change and rerun the evaluation set before promoting it into the live workflow.

    At your next planning session, bring a workflow map instead of a list of AI tools. Pick the decision that causes the most repeated repair, make its inputs and rules explicit, and build the controls around it. That is where AI stops being an isolated productivity feature and becomes dependable marketing infrastructure.

    References

  • OpenAI Agent Automation Tools: A Practical Build Guide

    OpenAI Agent Automation Tools: A Practical Build Guide

    You have a recurring marketing workflow that is too judgment-heavy for a simple rule and too repetitive to justify doing by hand. That is a sensible place to consider an OpenAI agent. The mistake is handing it a broad objective such as “manage PPC” or “run content operations” before you have defined what it may read, decide, change, and escalate.

    OpenAI’s AgentKit brings visual workflow building together with familiar tools such as Gmail and Dropbox, reducing how much glue code may be needed around an agent. That makes construction easier. It does not remove the harder work: designing a workflow that produces useful results without creating expensive surprises.

    Give the first agent a narrow outcome, not a department

    An agent is most useful in the gap between rigid automation and unrestricted human judgment. It can interpret messy inputs, choose among permitted actions, and use connected tools. It should not be treated as an autonomous employee with an implied understanding of your business.

    Start with a workflow that has a recognizable trigger, a bounded decision, a small set of tools, and an output you can inspect. A strong candidate can usually be described in one sentence: “When this event occurs, use these approved inputs to prepare this defined result for this person or system.”

    • Turn campaign data into an exception brief that identifies what needs a human decision.
    • Collect approved reporting inputs, prepare a dashboard entry, and draft the accompanying client summary.
    • Check draft ad copy against explicit brand rules and flag the exact rule behind each problem.
    • Prepare a meeting agenda from an approved account summary and unresolved action items.
    • Review an existing content brief for missing entities, unanswered questions, or unsupported claims before publication.

    Each example ends in an inspectable artifact. None asks the agent to “improve performance” without defining what improvement means or what authority the agent has.

    Use a simple eligibility test

    Before building, answer the following questions. If several answers are unclear, the process is not ready for an agent yet.

    • What exact event starts the workflow?
    • Which systems contain the facts the agent is allowed to use?
    • Which part requires interpretation rather than a fixed rule?
    • What does a complete output contain?
    • How can a reviewer verify the result without recreating all the work?
    • What is the worst plausible result of a wrong decision?
    • Can that result be prevented with permissions, validation, or approval?

    A poor starting workflow has an ambiguous goal, no authoritative data source, broad credentials, and no obvious stopping point. It may still be worth redesigning, but adding an agent will not repair those weaknesses.

    Know when ordinary automation is enough

    If the same input should always produce the same action, use a deterministic rule. Scheduling a recurring run, checking whether a required field is empty, applying a known naming convention, and moving an approved file do not require model judgment.

    Use an agent for the step that genuinely needs interpretation: classifying an unusual campaign change, reconciling context from a client email with a performance report, or explaining why draft copy conflicts with a brand rule. The strongest design is often a hybrid. Conventional automation handles triggers and validation; the agent handles a bounded judgment; conventional automation checks the output and routes it to the next stage.

    Separate facts, reasoning, actions, and controls

    A four-part automation model separates source records, a reasoning chamber, an action mechanism, and an independent control frame with locks and an approval gate.

    A visual canvas can make a complicated workflow look like one continuous chain. Operationally, you should still treat it as distinct layers. That separation tells you where an error started and which safeguard should catch it.

    LayerIts jobMarketing exampleMain failure to prevent
    FactsRetrieve authoritative input without changing itCampaign data, an approved brief, or brand rulesUsing stale, incomplete, or unapproved material
    ReasoningClassify, compare, prioritize, or draftExplain which exception deserves reviewProducing a plausible conclusion that the evidence does not support
    ActionWrite or send an approved result through a toolCreate a report draft or update a workflow statusChanging the wrong record or acting before approval
    ControlValidate, log, stop, or request authorizationRequire evidence fields and approval before publicationAllowing an error to pass silently into a consequential action

    Your language model should not become the system of record. Let tools retrieve facts from the authoritative system, and require the agent to preserve the identifiers that connect every conclusion to those facts. If it says a campaign needs attention, the output should identify the campaign, the relevant observation, the input used, and the proposed next step.

    Policies deserve the same separation. Brand requirements, approval rules, prohibited claims, and escalation conditions should be maintained as explicit instructions or structured data. Do not hide critical policy in an example and expect the agent to infer that the example is binding.

    A useful division of labor is straightforward: tools fetch facts, the agent interprets them, deterministic checks validate required conditions, and a person approves consequential changes. You can relax an approval later if the workflow earns that authority. Recovering from an unreviewed budget change or public claim is much harder.

    Write an executable contract before you build

    The workflow specification is the real product. The canvas, model, prompts, and connectors implement it. Write the specification in operational language that a reviewer can challenge before the agent touches live data.

    1. Define the outcome. Name the artifact or state the workflow must produce, not the general business goal it supports.
    2. Define the trigger. Identify the approved event, schedule, or human request that starts a run.
    3. Define the inputs. List the allowed systems, records, fields, and policy documents. State which one wins if two inputs conflict.
    4. Define the decision. Explain what the agent may infer and the criteria it must apply.
    5. Define the output. Require a stable structure with evidence, unresolved questions, and approval status.
    6. Define the tools. Grant only the operations needed for this workflow.
    7. Define the boundaries. State forbidden actions, stop conditions, and matters that always require escalation.
    8. Define completion. Say what must be true before a run can be marked successful.
    9. Define the evidence trail. Preserve the input references, tool results, output, approval, and final action.

    A practical specification for a PPC reporting agent

    Suppose you want an agent to prepare a campaign exception brief. The specification could read like this:

    • Outcome: prepare a review brief describing campaign exceptions; do not optimize the account.
    • Trigger: an approved reporting request with an account identifier and reporting context.
    • Inputs: current campaign data, the agreed comparison context, active brand rules, and unresolved items from the previous review.
    • Allowed decisions: group related observations, rank them by the supplied business criteria, and propose questions or next actions.
    • Required output: campaign identifier, observation, supporting evidence, applicable rule or objective, proposed action, uncertainty, and approval status.
    • Allowed actions: read approved inputs and create a draft in the designated location.
    • Forbidden actions: change bids or budgets, alter targeting, send client communications, publish copy, or invent a missing value.
    • Stop conditions: required data is missing, identifiers do not match, instructions conflict, or a tool returns an uncertain result.
    • Approval: the account owner reviews the brief before any recommendation enters a live campaign workflow.
    • Completion: every recommendation has evidence, every unresolved issue is labeled, and no prohibited action was attempted.

    This contract turns a vague assistant into a bounded operator. It also makes evaluation possible. A reviewer can test whether the agent followed each condition instead of debating whether the response merely looked intelligent.

    Express authority with precise verbs

    Words such as read, classify, draft, propose, update, send, publish, and delete represent very different levels of authority. Use them deliberately. “Handle the client report” conceals several decisions. “Read approved campaign data, draft the report summary, and request approval” exposes them.

    Do the same with uncertainty. If a required value is absent, tell the agent to stop or label the gap. Never ask it to complete a record using “the most likely” value unless inference is explicitly acceptable and clearly marked. A polished guess is still a data-quality failure.

    Place controls at the action boundary

    Permissions should follow a ladder. Reading is less consequential than drafting; drafting is less consequential than committing a database change; an internal change is usually less consequential than sending a message, publishing content, or changing advertising spend.

    • Begin with read-only access wherever the workflow allows it.
    • Write drafts to a staging location rather than replacing an approved asset.
    • Require a human decision immediately before an external, public, financial, destructive, or difficult-to-reverse action.
    • Use separate credentials or scoped permissions so one workflow cannot inherit unrelated authority.
    • Require the tool to return a stable record identifier and confirmation before the agent treats a write as successful.
    • Make repeated runs safe. A duplicate trigger should find the existing draft or action record rather than create another one.
    • Log the request, retrieved input references, tool calls, result, approval, and final action in a form that can be reviewed later.

    Connected email and document stores introduce another boundary: retrieved content is data, not authority. An email, attachment, or cloud document may contain text that tells the agent to ignore its rules or use another tool. The workflow should treat those instructions as untrusted unless they arrive through the approved control path. Keep system instructions, business policy, and retrieved content distinct.

    Test the agent’s failures before trusting its successes

    An engineer observes an automated agent being tested against missing inputs, conflicting records, unavailable tools, and a blocked unsafe action in a simulation lab.

    A smooth demonstration proves that the happy path can work. It does not show what happens when data is absent, tools fail, instructions conflict, or the same event arrives twice. Those cases determine whether the automation is fit for routine use.

    Build a test set from the ways the real workflow can break. It should include:

    • An ordinary case with complete, consistent inputs.
    • A case with a required input missing.
    • A stale, malformed, or mismatched record.
    • Two approved inputs that disagree.
    • An ambiguous request that permits more than one interpretation.
    • Retrieved content containing instructions the workflow must not obey.
    • A tool timeout, rejection, or incomplete response.
    • A duplicate trigger for a run that already produced an output.
    • A proposed action that violates a brand, permission, or approval rule.
    • A case where the correct behavior is to stop and ask for help.

    Score behavior against the contract, not writing quality. Check whether the conclusion is supported, required fields are present, prohibited actions are avoided, tool results match the intended record, and uncertainty is visible. Also record how much human correction the result needs. An agent that saves preparation time but creates a difficult verification job has moved the work rather than removed it.

    Roll out in stages

    Start in shadow mode: let the agent process real workflow inputs without writing to production systems or contacting anyone. Compare its proposed output with the existing process, classify the differences, and revise the contract or controls when the same error pattern returns.

    Next, allow draft creation while keeping approval mandatory. Expand authority only after the defined test set and real shadow runs show that failures are visible and contained. Increase one dimension at a time, such as the range of accepted inputs or the ability to update an internal status. If you broaden the workflow and its permissions simultaneously, you will not know which change caused a new failure.

    Monitor the operating result after launch. Useful measures include successful completions, stops and escalations, human edits, attempted policy violations, tool failures, duplicate prevention, and time saved after review and recovery work are included. Review the failure categories themselves. A rising cluster of missing-data errors may point to an upstream process problem rather than a prompt problem.

    Keep rollback practical. Preserve the previous state for reversible updates, retain the identifiers returned by action tools, and document how a reviewer disables the workflow without disabling unrelated automations. If a safe rollback is impossible, keep a person at the commit boundary.

    Key takeaways

    • Choose a narrow workflow with a clear trigger, bounded judgment, limited tools, and a verifiable output.
    • Keep deterministic triggers and validation outside the model; use agent reasoning only where interpretation adds value.
    • Treat the workflow specification as an executable contract covering inputs, decisions, outputs, permissions, stops, and evidence.
    • Start with read or draft access and require approval before public, financial, destructive, or difficult-to-reverse actions.
    • Treat email, attachments, and retrieved documents as untrusted data rather than instructions.
    • Test missing data, conflicting instructions, tool failures, duplicate events, and safe escalation before expanding authority.
    • Measure correction and recovery work as well as successful task completion.

    Pick one recurring workflow and write its contract before opening the visual builder. If you cannot identify the authoritative inputs, forbidden actions, approval point, and proof of completion on one page, narrow the job again. Once those boundaries are clear, OpenAI’s agent tools can automate the judgment bottleneck without quietly taking control of the whole operation.

    References