If your product creates a URL whenever someone shares a result, report, conversation, generated output, or interactive tool, its default indexing policy may be backwards. A page can be reachable by anyone who has its link without belonging in public search results.
The safest operating rule is simple: link access does not equal permission to index. Keep direct-share pages out of search by default, then make public discovery a deliberate publishing decision.
Decide by search intent, not URL accessibility
Teams often collapse two separate questions into one: Can someone open this URL, and should a search engine recommend this URL? Those questions need separate controls.
A saved calculator result might be useful to the person who created it and the colleague receiving the link. It may still be meaningless to a searcher because it lacks context, duplicates a template, or exposes an output that was never reviewed for public publication. The fact that it returns a successful response does not make it a search landing page.
Google now explicitly advises platforms with shareable pages, generated outputs, and interactive tools to distinguish content intended for search from content created for sharing, collaboration, or utility. For the latter group, the recommended default is noindex or blocked crawling.
| Page state | Intended audience | Default control |
|---|---|---|
| Private | Authorized account members | Require authentication; do not treat noindex as the privacy control |
| Link-only | People who receive the URL | Allow direct access if appropriate, but return noindex |
| Public | People searching for the subject | Permit indexing only after the page passes your publication checks |
| Revoked or removed | No intended audience | Remove access or the resource itself; noindex alone is insufficient |
Before making a user-created page indexable, require clear answers to three questions:
- Would a person arriving from search receive stand-alone value without private context from the creator?
- Did the creator intentionally choose public publication rather than merely copying a share link?
- Can your platform moderate the page and keep it within the same quality and spam standards as the rest of the indexable site?
If any answer is no, keep the page in the link-only state. This is not a blanket argument against user-generated content. It is a boundary between publishing and sharing.
Use the indexing control that matches the job
Noindex, robots.txt, authentication, canonical tags, and structured data solve different problems. Substituting one for another is how link-only pages leak into search or legitimate public pages disappear from it.
Robots meta tags for crawlable HTML pages
For an HTML page that recipients can open but search engines should not retain in their indexes, return <meta name="robots" content="noindex"> in the document head. Apply it in the shared-page template or rendering path so every page in that state receives the directive automatically.
The crawler must be able to fetch the page to read this instruction. Do not simultaneously disallow the same URL in robots.txt when you need the noindex directive to be discovered.
X-Robots-Tag for response-level enforcement
The HTTP response header X-Robots-Tag: noindex is useful when indexing policy belongs in middleware, an application gateway, or a file-serving response rather than an HTML template. It also reduces the risk that one rendering variant omits the meta tag.
Choose one authoritative policy layer and test the final response that a crawler receives. A database flag does nothing if a cache, export route, alternate renderer, or CDN response fails to carry the resulting directive.
Robots.txt for crawl management
A robots.txt rule can stop compliant crawlers from fetching an entire route pattern. That can be appropriate for a clearly separated utility area, especially when the URLs should never be crawled in the first place.
It is not a privacy mechanism, an access control, or a dependable way to remove a URL that is already known. A blocked crawler also cannot see a noindex tag on the blocked page. If URLs have already entered search, make them crawlable with noindex first and verify that the directive has been processed before considering a crawl block.
Controls that do not replace noindex
- Authentication: Use it when the content must be private. Noindex is a search instruction, not protection against unauthorized access.
- Canonical tags: Use them to express a preferred URL among duplicate or similar public pages. They are not a substitute for excluding a link-only page.
- Structured data: Use it to describe eligible public content. Removing JSON-LD does not tell a search engine to exclude the underlying URL.
- Sitemaps and internal links: Reserve these discovery signals for public pages. Omitting a URL from a sitemap can reduce discovery, but omission alone is not an indexing prohibition.
Make indexability a controlled publication state
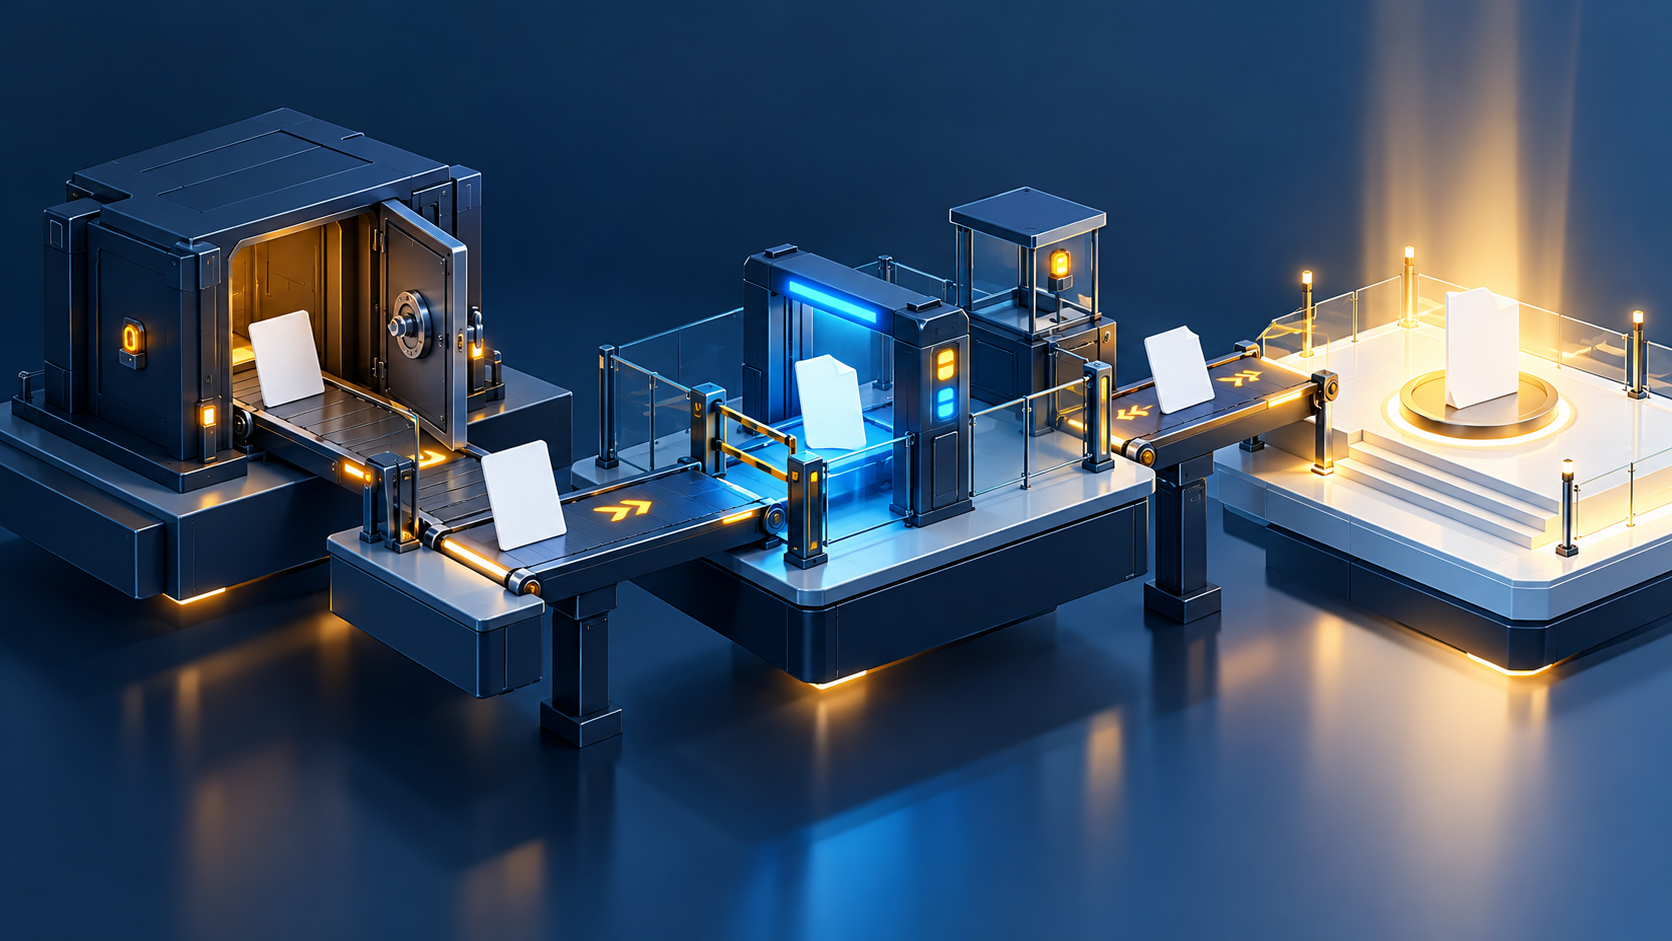
The durable fix is not a cleanup script. It is a small state model in the product. Treat private, link-only, and public as explicit states with deterministic response behavior.
- Define the states. Store whether a resource is private, link-only, or public instead of inferring intent from the existence of a URL.
- Default new shared resources to link-only. Creating a page or pressing Share should not silently become a search-publication event.
- Enforce the state in the response. Every link-only HTML page should emit a robots noindex tag, or the response layer should emit an X-Robots-Tag header.
- Create an explicit public-publish action. Promotion to public should remove noindex, permit crawling, and only then add the URL to public navigation or a sitemap.
- Handle demotion in the right order. When a public page becomes link-only, add noindex while leaving it crawlable so the change can be observed. Verify the result before applying any route-level crawl block.
- Separate revocation from deindexing. If sharing is revoked, remove access or the resource. Waiting for a crawler to process noindex does not protect content during the interval.
Your public-publish action should also be a quality gate. Confirm that the page has an intelligible purpose, enough context to stand on its own, a stable public URL, and a moderation path. Generated output should not become indexable merely because a user changed a visibility toggle; the platform still owns what it makes available to search.
Test transitions as carefully as initial creation. Inspect the rendered HTML and response headers for a new link-only page, a promoted public page, a demoted page, an alternate URL format, and a cached response. The most damaging failures often live in secondary routes rather than the primary template.
Detect indexing abuse before it becomes a site-wide problem
A noindex default reduces exposure, but it does not replace monitoring. User-controlled publishing systems attract automation because one account can create many URLs on a trusted host. The warning signs usually appear first as a change in creation patterns, then as unfamiliar index coverage, impressions, or queries.
Verify the relevant site or subdomain in Google Search Console and make sure operational owners receive alerts for manual actions and security issues. Review the Page Indexing and Search performance reports for unexpected increases in indexed URLs, impressions, or queries that do not match the platform’s purpose.
Pair those external signals with a platform dashboard that records:
- New pages created, grouped by route or template.
- New pages made public, separate from pages merely shared by link.
- The current count of private, link-only, and public resources.
- Public-page creation by account so one creator cannot dominate unnoticed.
- Indexing and search activity by route, where that data is available.
Do not wait for a universal numeric threshold; publication volume differs too much between products. Alert on deviations from your own expected pattern. A sudden rise in public URLs, a small group of accounts producing most indexable pages, or search queries unrelated to the product’s purpose all warrant inspection.
When an alert fires, identify the affected route and accounts first. Then stop additional public publication, apply noindex at the shared response layer if appropriate, preserve evidence needed for moderation, and inspect Search Console for the scope of exposure. Fixing one URL at a time will not contain abuse if the route can continue generating indexable pages.
FAQ: link sharing and search indexing
Should every shared URL be noindexed?
Use noindex by default when sharing is meant for direct recipients rather than public discovery. A page can become indexable later if the creator intentionally publishes it and your platform confirms that it is suitable for search.
Does noindex make a shared page private?
No. Anyone who obtains an unprotected URL may still be able to open it. Use authentication, authorization, or another real access control when the content must remain private.
Can robots.txt replace a noindex directive?
Not in every case. Robots.txt controls crawling, while noindex communicates that a fetched page should not remain in the index. Blocking a URL can prevent a crawler from seeing its noindex directive, so already discovered pages generally need crawl access while that directive is being processed.
What changes when a link-only page becomes public?
Remove the noindex instruction, confirm that robots.txt permits crawling, and expose the page through appropriate public discovery paths such as internal links or a sitemap. Check the final response rather than assuming that changing the database state updated every cached or alternate version.
Start with one route inventory: list every feature that creates a shareable URL, record its current default, and inspect what the live response tells crawlers. Change direct-share routes to link-only by default, then require a separate, reviewable transition for anything you want search engines to surface.
References

Leave a Reply