Tag: Automation

  • Automated B2B Lead Generation: Build a Quality Feedback Loop

    Automated B2B Lead Generation: Build a Quality Feedback Loop

    You probably do not need another lead generation tool. If your automated campaigns produce cheap form fills that sales rejects, the system is working exactly as instructed: it has learned that submitting a form is the outcome that matters.

    The fix is to give automation a visible path from early interest to qualified pipeline, then make each campaign optimize for one stage of that path. You can scale from there without mistaking activity for demand.

    Fix the objective before you automate the campaign

    B2B automation has a signal problem. A purchase platform can often see an order, its value, and the ad that produced it within a short period. B2B campaigns may generate fewer conversions, lack an immediate transaction value, and feed a sales process that can continue for more than a year.

    The bidding system cannot infer what happened in your CRM unless you send that information back. Left alone, it will favor the observable event it receives most frequently. That is usually the form submission, regardless of whether the person used a personal email address, fell outside your service area, represented the wrong company size, or never progressed beyond the first sales review.

    Before changing bids, audiences, creative, or campaign types, answer four questions:

    • What is the deepest business outcome you can reliably connect to the originating campaign?
    • How consistently does your team apply that lifecycle stage in the CRM?
    • How long does it take for that outcome to appear?
    • Which earlier event is the best available proxy while the deeper outcome is still pending?

    Your ideal optimization event is not automatically the final sale. A closed deal may be economically meaningful but too delayed or infrequent to guide every campaign. A marketing qualified lead may be available sooner, while an accepted opportunity may carry a stronger connection to revenue. Choose the deepest stage that is both trustworthy and repeatable, then continue importing later outcomes for measurement.

    Do not judge this system on lead count alone. Review the number of leads, the share becoming qualified, the opportunities created, and the deals closed. One documented implementation reported a 150% increase in leads, a 350% increase in opportunities, and a 200% increase in closed deals. That is a single case result, not a benchmark, but the uneven movement across stages makes the important point: top-of-funnel volume and downstream value do not necessarily rise at the same rate.

    Build the CRM-to-ad feedback loop first
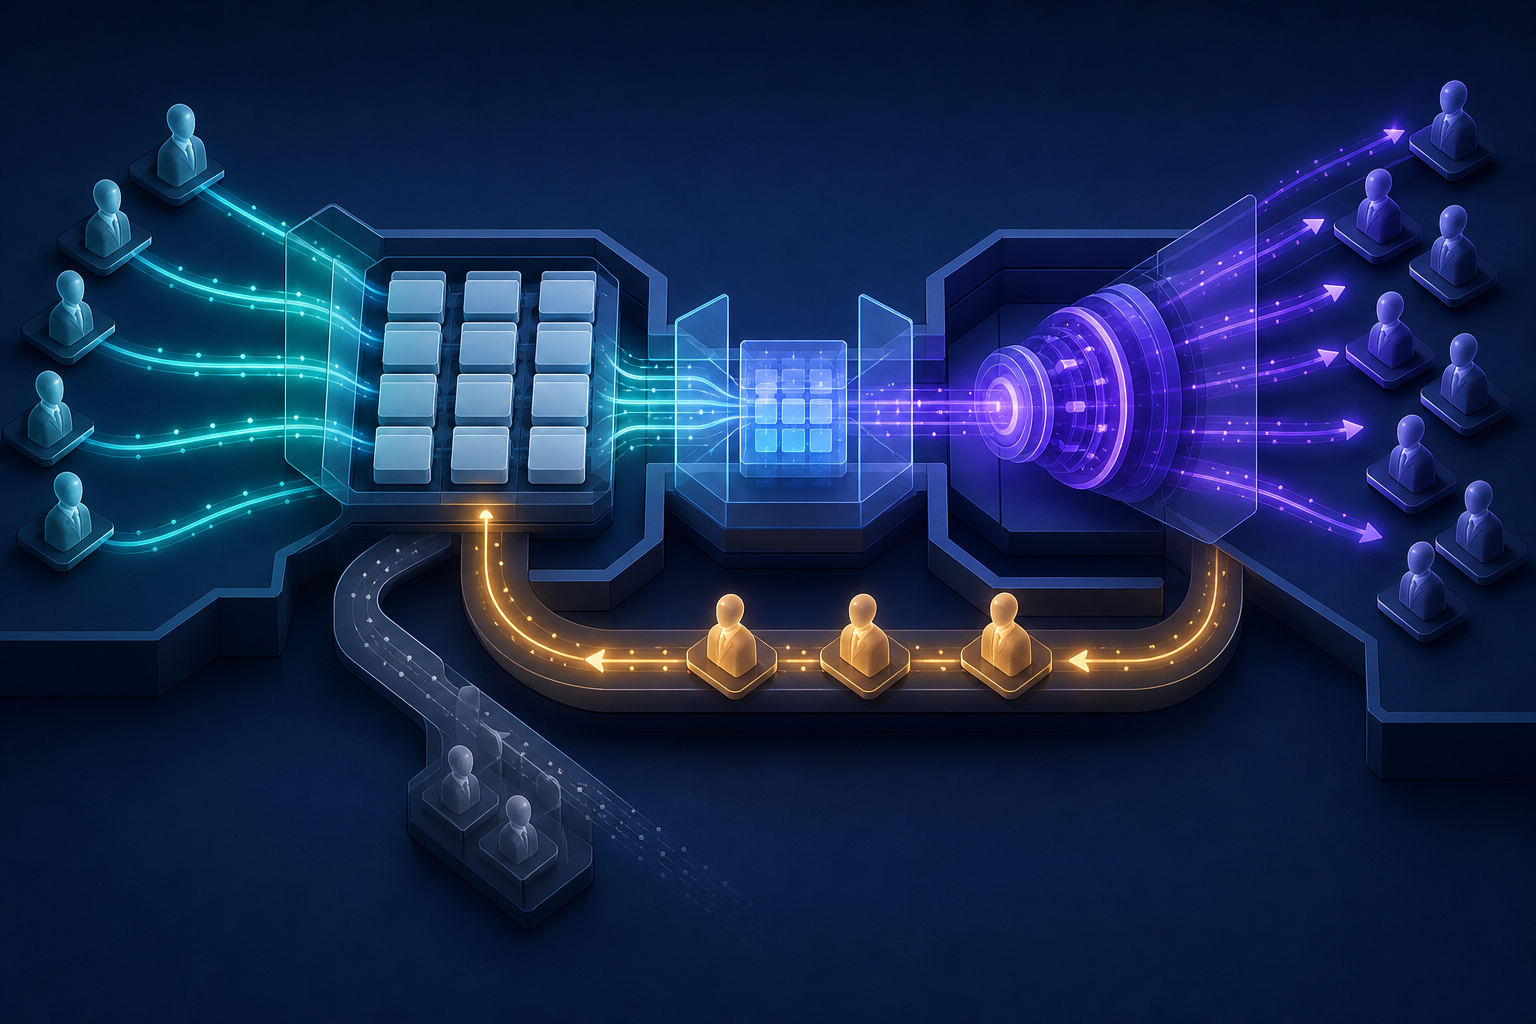
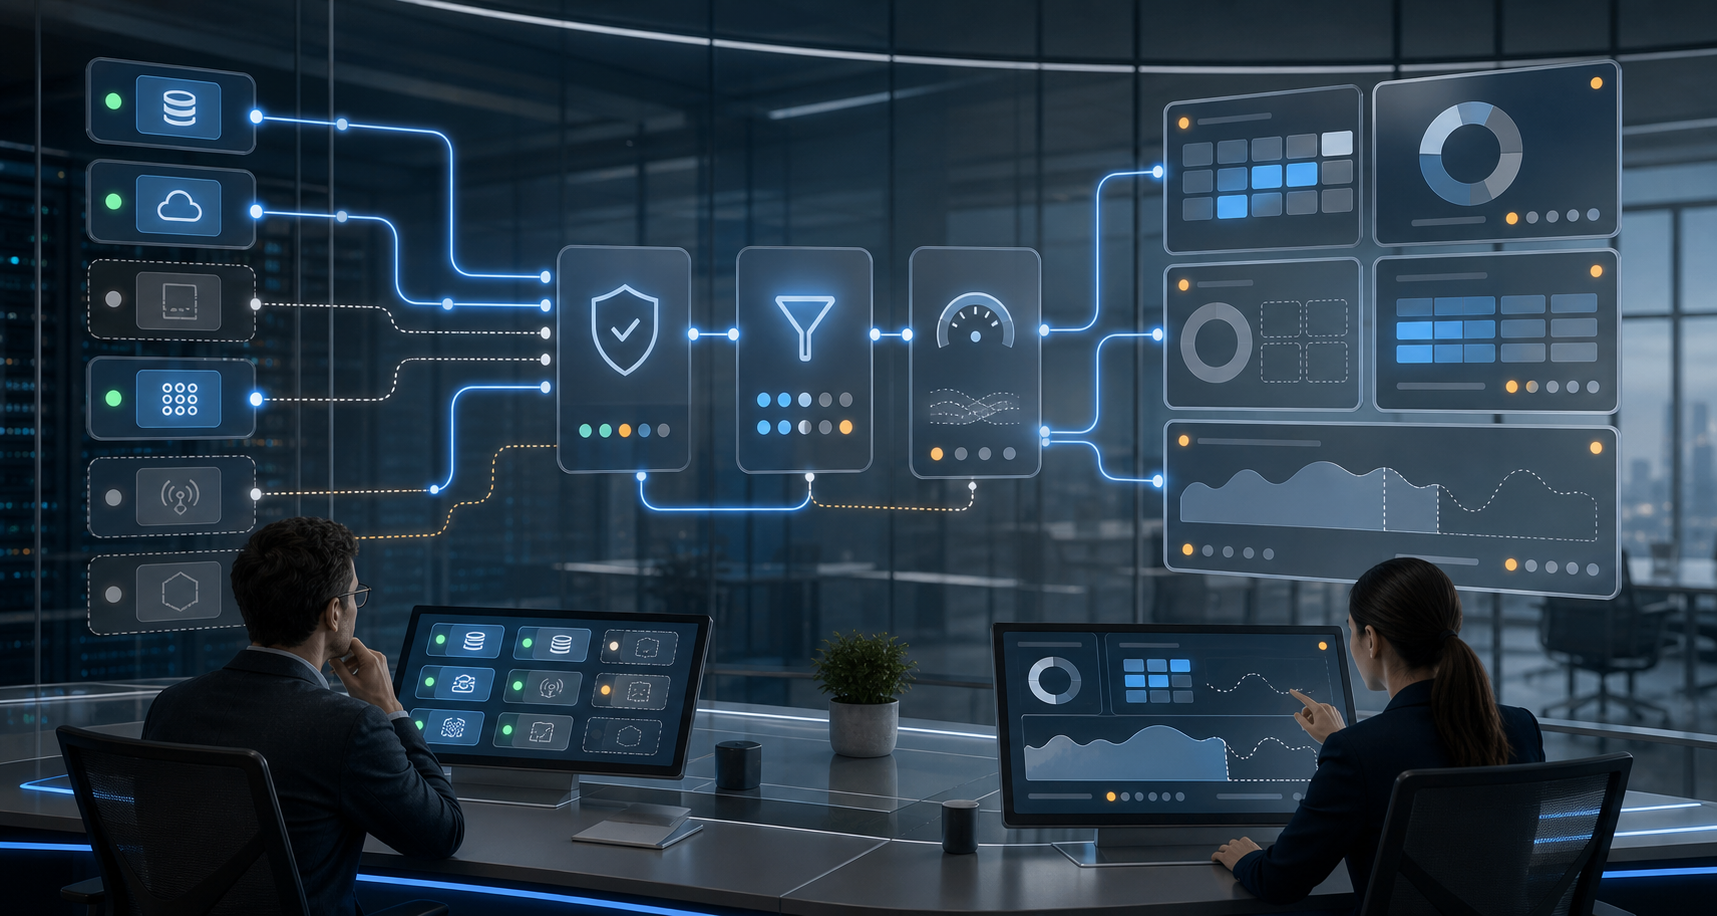
    An isometric system sends lead signals between business contacts, organized customer records, and an advertising engine, with bright qualified signals returning through the loop.

    Offline conversion tracking is the foundation of automated B2B acquisition. Your ad platform needs to learn when an online inquiry becomes a qualified lead, an opportunity, or a customer. Google Ads Data Manager provides integration paths involving HubSpot and Salesforce, as well as custom workflows using systems such as Snowflake and Zapier.

    The connector matters less than the integrity of the lifecycle data moving through it. A fast integration will only automate confusion if sales and marketing use the same CRM stage for different situations.

    1. Define each stage in operational terms. State what must be true before a contact becomes a marketing qualified lead, sales-accepted lead, opportunity, or closed deal. Avoid definitions based on intuition alone.
    2. Assign one owner to each transition. Decide whether marketing automation, a sales representative, or another system changes the stage. Conflicting updates make imported outcomes unreliable.
    3. Preserve the acquisition connection. The downstream CRM record must remain traceable to the campaign interaction that created it. If that connection disappears during routing, enrichment, or deduplication, the ad platform cannot learn from the result.
    4. Exclude invalid records before importing value. Spam, tests, duplicates, existing customers, job seekers, vendors, and other non-prospects should not teach the bidding system what to find next.
    5. Validate a sample from end to end. Compare the campaign record, form record, CRM contact, lifecycle change, and imported conversion. Check both successful imports and records that should have been excluded.
    6. Document the delay. Record how long qualification and opportunity creation normally take in your process. A recent campaign can look weak simply because its downstream outcomes have not matured yet.

    Give early intent a weighted vote, not control of the account

    Micro conversions can help when qualified outcomes are sparse or delayed. The important move is to assign relative values that express the difference between curiosity and commercial intent. One workable example uses values of 1 for a video view, 10 for an asset download, 100 for a form fill, and 1,000 for a marketing qualified lead.

    EventExample relative valueWhat it tells the systemHow to treat it
    Video view1The visitor showed initial interestUse as a weak supporting signal, not proof of demand
    Asset download10The visitor exchanged attention for useful materialUse as a stronger engagement signal, while checking whether the asset attracts your ideal buyer
    Form submission100The visitor initiated direct contactCount it as intent, but separate valid prospects from spam and poor-fit inquiries
    Marketing qualified lead1,000The record passed an agreed qualification ruleUse as a primary quality signal when the CRM stage is reliable

    These are utility points, not universal prices. Do not label them as revenue or report a value-based bid result as financial return on ad spend unless the values actually represent money. Their purpose is to tell the optimizer that one qualified lead should matter far more than one video view.

    Review how much total conversion value each event contributes. A low-value event can still dominate if it happens often enough. If video views or downloads create most of the recorded value, the campaign may learn to buy abundant engagement instead of scarce business intent. Reduce the shallow event’s value, remove it from the campaign’s optimization goal, or keep it for observation only.

    Also control repeated actions. One person replaying a video, downloading several files, or submitting the same form twice should not automatically look more valuable than a newly qualified account. Your counting rules, deduplication, and CRM logic must reflect the business event you actually want to reproduce.

    Make every campaign do one job

    An account-wide list of conversion actions is not a strategy. If the same campaign is rewarded for video engagement, downloads, inquiries, and qualified leads without a clear hierarchy, the easiest event can overpower the event that matters.

    Use campaign-specific goals to match optimization to the campaign’s role:

    • Awareness and audience development: measure video engagement or content interaction, but do not let those actions steer a high-intent acquisition campaign.
    • Mid-funnel demand capture: optimize for a meaningful form submission when qualification data is not yet frequent or timely enough.
    • Warm-audience acquisition: optimize toward the qualified lead event when the audience, offer, and CRM feedback can support it.
    • Pipeline-focused campaigns: use opportunity or revenue values when those offline outcomes are accurate enough to guide bidding.

    This separation also makes diagnosis easier. If an awareness campaign produces inexpensive views but no later demand, you can question the audience or message without contaminating the performance signal of a campaign designed to generate qualified inquiries.

    Low volume does not always require collapsing every initiative into one campaign. When several campaigns serve similar buyers and pursue the same conversion goal, portfolio bidding can combine their data. It is particularly useful when separate campaigns struggle to reach the commonly cited 30-conversion-per-month threshold. Portfolio strategies can also provide a maximum cost-per-click cap, which helps limit runaway bids.

    Only pool campaigns whose economics and objectives belong together. Combining a high-value enterprise offer with a low-value self-service offer may produce more data, but the shared strategy will be learning from two different businesses. More observations do not help when they describe incompatible outcomes.

    Your first-party CRM data should also shape targeting. Customer lists can support exclusions when acquisition campaigns should not spend on current customers. Contact and prospect lists can be used for observation, direct targeting, or audience signals where the campaign type permits. These lists give broad, AI-driven campaigns a concrete description of the people and accounts you already recognize.

    Performance Max is not automatically unsuitable for B2B lead generation. It becomes a defensible test after you have reliable offline outcomes, sensible conversion values, a campaign-specific goal, and useful first-party signals. A Target ROAS strategy can then optimize toward recorded customer value instead of treating every conversion as equivalent. If you use relative utility points rather than monetary values, remember that the resulting ROAS is an optimization ratio, not an accounting measure.

    Use AI where mistakes are visible and reversible

    AI can shorten research, organization, and drafting work, but it cannot repair a missing feedback loop. Put it on bounded tasks whose outputs a marketer can inspect before they affect bids, budgets, exclusions, or customer communication.

    Start with a reusable context brief. Include your offer, differentiators, target personas, ideal client profile, buying roles, disqualifiers, and approved claims. Explicitly state that the customer is another business; that B2B instruction changes the frame of the response and reduces the chance of receiving consumer-oriented ideas.

    Prompt skeleton: You are supporting B2B demand generation for [company]. We sell [offer] to [ideal client profile]. The buying group includes [roles]. Our differentiators are [approved claims], and we do not serve [disqualifiers]. Complete [task]. Separate verified inputs from inferences, identify missing information, and do not invent competitor claims or customer evidence.

    That context can support several practical workflows:

    • Competitor analysis: organize known offers, positioning, value propositions, and customer sentiment into a consistent matrix. Require a traceable input for every factual claim and leave unsupported cells blank.
    • Keyword gap review: give AI an export from a tool such as Semrush and ask it to separate terms competitors cover, terms you already lead on, and recurring themes that may deserve their own campaigns.
    • Search-term triage: classify terms as relevant, irrelevant, or ambiguous. A human should review ambiguous cases and approve negative keywords before they are applied.
    • Ad-copy drafting: request variations tied to a named persona, problem, offer, and approved proof point. Treat every line as a draft that still needs factual and policy review.
    • Reporting support: summarize anomalies and prepare questions for investigation. Google Ads also provides pre-built automation solutions for reporting, anomaly detection, and keyword-list creation, although complex enterprise accounts need careful validation before broad use.

    Keep consequential decisions outside a fully automatic chain until you trust the inputs and failure modes. A mistaken theme label is easy to correct. An automatically applied negative keyword can suppress qualified demand, while an unverified competitor claim can create reputational or legal exposure. Let AI propose; require an accountable person to approve.

    Use controlled experiments for bid strategies, match types, and landing pages. Write the hypothesis and success measure before launch. If you change the audience, bid strategy, offer, creative, and page at once, even a positive result will not tell you which decision to repeat.

    Roll out automation in an order you can audit
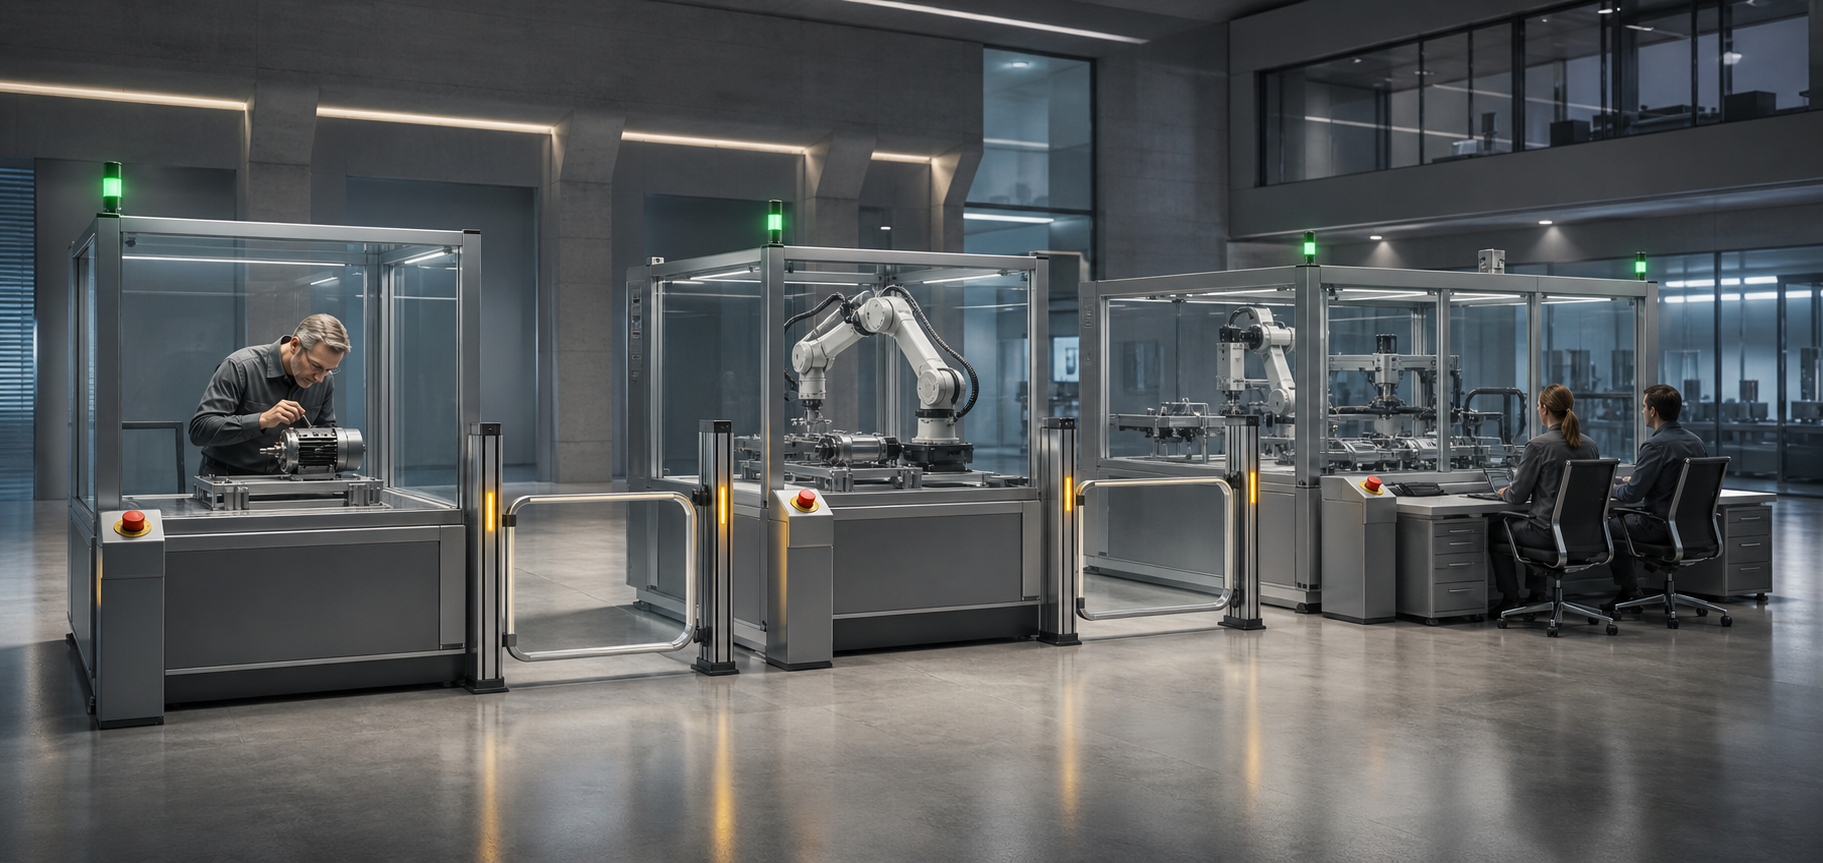
    Three transparent workstations show automation expanding from one inspected mechanism to a larger system monitored by two analysts, with checkpoints between stages.

    You do not need to rebuild the whole account at once. Start with one meaningful campaign and make its data path trustworthy before expanding the design.

    1. Select the downstream outcome. Choose the deepest lifecycle stage that is consistently recorded and still occurs often enough to inform the campaign.
    2. Write the qualification rule. Make the rule specific enough that two team members would classify the same record the same way.
    3. Connect the CRM outcome. Import the offline event and verify that it connects to the correct campaign interaction.
    4. Add a restrained value ladder. Give early actions lower relative values and the qualified outcome a clearly dominant value.
    5. Set the campaign-specific goal. Remove unrelated actions from the campaign’s optimization objective, even if you continue measuring them elsewhere.
    6. Add relevant first-party data. Exclude existing customers where appropriate and use qualified contact lists as targeting or audience signals.
    7. Consider portfolio bidding. Pool only campaigns with compatible goals and economics when each one lacks sufficient conversion volume on its own.
    8. Test broader automation. Introduce Performance Max, Target ROAS, broader matching, or another automated feature only after the outcome data is dependable.
    9. Automate repetitive analysis. Use AI and platform solutions for drafts, classifications, reports, and anomaly alerts, with human approval for consequential changes.
    10. Review the full funnel. Compare lead volume, qualification, opportunities, closed deals, and the share of recorded value coming from each conversion action.

    Key takeaways

    • Automated B2B lead generation improves when the ad platform can distinguish an inquiry from a qualified business outcome.
    • Offline CRM conversions should carry more authority than abundant micro conversions.
    • Relative values must reflect intent hierarchy and should not be presented as revenue unless they represent actual money.
    • Campaign-specific goals prevent easy engagement events from steering pipeline-focused campaigns.
    • AI is most useful for inspectable research, classification, drafting, and reporting tasks; it should not silently approve high-consequence changes.

    Your next step is small: choose one campaign, one qualified CRM stage, and one imported offline event. Trace a real record through that loop. Once the campaign can tell the difference between a completed form and a viable prospect, additional automation has something worth scaling.
    References

  • Performance Max Testing and Diagnostics: A Practical System

    Performance Max Testing and Diagnostics: A Practical System

    Your Performance Max results have moved in the wrong direction, and the campaign offers enough levers to make almost any explanation sound plausible. You could replace assets, add negatives, split campaigns, exclude placements, or change the budget before lunch. If you do all of them, you may change performance, but you will lose the ability to explain why.

    The better question is not “What can I optimize?” It is “Which layer failed?” Start with conversion data, establish a stable baseline, test one hypothesis, and only then intervene at the search, channel, placement, or device layer.

    Verify the conversion signal before diagnosing the campaign

    A technician inspects a glowing signal passing from a parcel through translucent verification gates, with one gate visibly misaligned.

    Performance Max depends on conversion data for both reporting and automated bidding. When a CRM import, offline conversion feed, or tag connection breaks, the campaign can appear to deteriorate even when the first failure occurred in the measurement pipeline. Optimizing against that false decline can waste budget and teach the bidding system from incomplete outcomes.

    Google Ads’ Data Manager includes a central diagnostics view for data connections. It assigns statuses such as Excellent, Good, Needs Attention, and Urgent, and it can surface refused credentials, formatting problems, failed imports, and tagging mismatches. Its run history also shows recent synchronization attempts and error counts.

    Use that information as an incident log, not as decoration. A Needs Attention or Urgent connection should stop a creative or targeting diagnosis until you understand whether conversions are missing. An Excellent or Good status is useful, but it is not proof that you selected the right conversion action or assigned the right business value. It tells you about connection health, not the quality of your measurement design.

    1. Record when the unexplained performance shift began. Do not rely on memory; you will need to compare that point with import and synchronization history.
    2. Check every data connection that supplies conversions used by the campaign, including CRM and offline conversion imports.
    3. Read the status and actionable alerts. Separate an authentication failure from a formatting error, a failed import, or a tag mismatch because each requires a different fix.
    4. Open the run history and identify the first unsuccessful or error-heavy synchronization. A failure that starts near the apparent campaign decline is a measurement lead worth resolving first.
    5. Compare completed outcomes in the originating business system with successfully imported outcomes for the same period. This helps distinguish a reporting gap from a real demand or traffic problem.
    6. After restoring the connection, mark the affected dates as an incident window. Do not use that contaminated period to declare a creative winner or justify a structural campaign change.

    This order matters most when you optimize toward offline revenue, qualified leads, or later-stage CRM events. A small import failure can make high-quality traffic look unproductive, while a delayed correction can make the recovery look like sudden campaign growth. Neither interpretation describes the media accurately.

    Build a baseline that separates the diagnostic layers

    Once the conversion pipeline is credible, take a campaign snapshot before editing anything. Record the campaign and asset group, the conversion objective being evaluated, the date of the last material change, conversion volume or value, spend, and the efficiency metric tied to your business goal. Add notes for promotions, feed changes, landing-page changes, and other events that could alter demand or conversion rate.

    The snapshot gives every later comparison an anchor. It also forces you to distinguish a campaign-wide decline from a concentrated problem. That distinction determines whether you need an experiment, an exclusion, or no change at all.

    Diagnostic questionWhere to inspect itWhat the view can establishImportant limitation
    Did the conversion pipeline fail?Data Manager diagnostics and run historyConnection status, synchronization failures, error types, and error countsA healthy connection does not validate the business definition of a conversion
    Did query intent change?Campaign-level search term viewSearch terms with campaign metrics that can support exclusions and intent analysisThe visibility applies to search-network traffic, not every Performance Max channel
    Are search themes contributing?Search theme reportingWhether a theme is receiving traffic and producing conversionsLow use is different from poor performance
    Did delivery move between networks?Channel performance reportPerformance across channels such as Search, Discover, and DisplayA channel difference identifies where to investigate; it does not by itself prove the cause
    Is inventory irrelevant or unsafe?Placement data in the API or Report EditorSpecific placements that warrant relevance or brand-safety reviewPlacement analysis does not explain search-query performance
    Is the issue concentrated by device?Device reportingDifferences in product and campaign outcomes across devicesSplitting campaigns can fragment the data used by machine learning

    Do not confuse grouped search term insights with the campaign-level search term view. Grouped insights can help you recognize query categories, but they have lacked the cost depth needed for many optimization decisions. The campaign-level view exposes more detailed search metrics, although it still describes only the search-network portion of Performance Max.

    That limitation changes how you interpret silence. If the search view does not explain the decline, you have not proved that search is healthy or that another channel is guilty. You have only eliminated the visible search terms as the complete explanation. Move to the channel report rather than stretching search-only data across the whole campaign.

    Run a creative experiment only when creative is the question

    A built-in Performance Max beta makes structured creative testing possible inside one campaign and asset group. You can define a control from existing assets, create a treatment with alternatives, retain shared assets across both variants, and assign a traffic split such as 50/50. This within-asset-group experiment reduces interference from separate campaign structures.

    Use the beta when your hypothesis is genuinely about creative. It cannot cleanly answer whether a budget change, product feed edit, landing-page release, search-term exclusion, or conversion import repair caused the result. If those variables move during the experiment, the split may still produce numbers, but the business conclusion will be weak.

    1. Write one falsifiable hypothesis. Name the asset change, the business metric expected to improve, and the reason the audience should respond differently.
    2. Select one campaign and one asset group where the beta is available. Confirm that both variants will be evaluated against the same conversion setup.
    3. Use the current creative set as the control. Change only the intended creative variable in the treatment, and share assets that are not part of the hypothesis across both sides.
    4. Choose the traffic allocation deliberately. A 50/50 split gives the two variants equal traffic opportunity, but it also assigns half of experiment traffic to an unproven treatment.
    5. Define the decision rule before launch. Choose a primary business outcome and note any guardrails, such as conversion volume or spend, that would make an apparent efficiency gain commercially unacceptable.
    6. Freeze unrelated campaign changes. Keep a change log so that an emergency edit, promotion, feed update, or measurement incident is visible during interpretation.
    7. Give the experiment enough time. Early experience indicates that tests shorter than three weeks can be unstable, particularly in lower-volume accounts. Three weeks is a warning boundary, not a universal guarantee of certainty; low volume may require a longer run.
    8. Apply the treatment only when the result answers the original hypothesis. If the evidence is inconclusive, preserve that conclusion instead of promoting whichever side happens to be ahead at the stopping point.

    The last step is easy to mishandle. A tie or inconclusive result is useful: it tells you that the proposed creative change has not demonstrated enough value to justify rollout under the observed conditions. It does not authorize a second round of post-hoc metric hunting until something looks favorable.

    Randomized traffic improves causal confidence, but it cannot rescue a damaged conversion feed or a test that overlaps several campaign edits. Test quality still begins with signal quality and operational discipline.

    Diagnose search, channel, placement, and device problems separately

    Four isolated diagnostic stations represent search, media channels, placements, and devices on an organized dark workbench.

    If creative is not the only credible cause, work down through the remaining delivery layers. Make the smallest change supported by the evidence. A query problem calls for a query control; a risky placement calls for a placement review. Neither automatically justifies rebuilding the campaign.

    Search terms, search themes, and brand traffic

    Start with the campaign-level search term view and compare terms by both traffic and outcomes. Terms with higher-than-average click volume and zero conversions are sensible exclusion candidates. They are not automatic exclusions. Check whether tracking is complete, whether the term is relevant, and whether the evaluation period contains enough activity to support the decision.

    Review brand traffic separately. Performance Max can lean toward high-intent branded searches, which may make aggregate efficiency look stronger without answering how much non-brand demand the campaign is creating. When preventing brand leakage is the actual requirement, explicit negative keywords provide more direct control than simply admiring the blended result. Brand exclusions also exist, but the key is to choose a control that matches the question you are trying to answer.

    Treat search themes as positive targeting input, not as a substitute for term-level diagnosis. Use search theme reporting to see whether a theme receives traffic, where that traffic originates, and whether it converts. An underused theme has not necessarily failed; it may simply have received too little delivery to evaluate. A used theme with meaningful traffic and no business outcome presents a different problem.

    Channels and placements

    The channel performance report helps you locate delivery and performance across networks such as Discover and Display. Use it to identify where the deviation is concentrated. If total campaign efficiency falls while one channel’s delivery or outcomes change sharply, inspect that channel’s inventory and creative fit before changing every asset group.

    For placement-level work, use the API or Report Editor data to identify inventory that is irrelevant or creates brand-safety concerns. Political content and children’s videos on YouTube are examples of placements that may require closer scrutiny for some advertisers. When placement names or video titles are in an unfamiliar language, Google Sheets’ translation function can speed up the relevance review.

    Keep Search Partner Network limitations in view. Performance Max does not provide a simple opt-out for that network. Compare its performance with Google Search where the reporting permits, document the constraint, and focus on exclusions and controls that are actually available. Do not promise an optimization that the campaign settings cannot enforce.

    Devices

    Device reporting can reveal that certain products perform differently across phones, computers, or other devices. Treat that as a prompt to inspect the experience as well as the media. Product presentation, landing-page usability, checkout behavior, and competitive conditions may all sit between the click and the conversion.

    Do not split campaigns by device merely because the report shows a difference. Campaign splits reduce the data available to each campaign and can weaken machine-learning inputs. Consider a split only when the difference is sustained and commercially material, both sides will retain enough volume to evaluate, and the new structure gives you a control you can use. If the split only produces cleaner-looking reports, the cost in fragmented learning may be higher than the benefit.

    Key takeaways: use this Performance Max diagnostic order

    • If a conversion connection needs attention, shows urgent errors, or has failed imports, repair measurement before judging campaign performance.
    • If measurement is healthy, capture a stable baseline and identify whether the deviation belongs to search, a broader channel, placements, devices, or creative.
    • If the question is specifically about creative and the beta is available, use the native asset experiment inside one campaign and asset group.
    • If a creative test has run for less than three weeks, especially with low volume, treat an apparent lead as unstable rather than rushing to declare a winner.
    • If a search term has unusually high click volume and no conversions, review it as an exclusion candidate instead of applying an arbitrary account-wide threshold.
    • If a problem is confined to one delivery layer, change that layer. Avoid campaign-wide restructuring until the evidence shows that the structure itself is the constraint.
    • If a device or campaign split would starve each side of useful data, keep the structure intact and use reporting for diagnosis rather than control for its own sake.

    On your next review, begin with the data connection history and a dated baseline. Then write down one question that the available report or experiment can actually answer. One clean diagnosis gives you a reusable decision; five simultaneous optimizations give you a new mystery.

    References

  • How to Run CMS Content Operations From Slack Without Chaos

    How to Run CMS Content Operations From Slack Without Chaos

    Your team works in Slack, but your content lives in a CMS. When review requests, approvals, publication decisions, and correction notes drift between the two, nobody can tell which instruction is current.

    The fix is not to move content management into chat. Keep the CMS authoritative and use Slack to bring the right decision to the right person. A well-designed connection between WordPress or Sanity and Slack can streamline publishing, updates, and coordination. The operational gain comes from how you define states, permissions, alerts, and write-backs around that connection.

    Make the CMS authoritative and Slack actionable

    Start with a hard boundary: the CMS owns durable content state; Slack owns attention and conversation. This distinction prevents a familiar failure mode in which a message says an item is approved while the CMS still says it is in review.

    What the CMS should own

    • The current body, title, media, taxonomy, and machine-readable metadata.
    • The content status, such as draft, in review, approved, scheduled, published, or update required.
    • The current revision identifier and revision history.
    • The assigned owner, reviewer, and publisher.
    • Publication settings, including the URL, schedule, canonical selection, and index controls.
    • The durable record of approvals, rejections, overrides, and publication events.

    What Slack should own

    • Notifications that a content item needs attention.
    • A concise summary of the proposed transition and its consequences.
    • Links to the editing screen, preview, and relevant validation results.
    • Authorized actions that write a decision back to the CMS.
    • Discussion about an exception, contained in a thread associated with the content item.
    • Escalation when an automated step fails or a deadline is at risk.

    Apply one rule to every integration feature: if a Slack action changes the official state of a content item, the integration must record that change in the CMS. A button that only changes a message, adds an emoji, or posts a reply has not completed the workflow.

    The boundary also protects sensitive implementation details. Slack messages should contain content identifiers and links, not CMS credentials, API tokens, unpublished secrets, or full payloads that do not belong in chat. Keep credentials in the integration’s secret store and let CMS permissions determine what each person may do.

    Model content events before connecting the tools

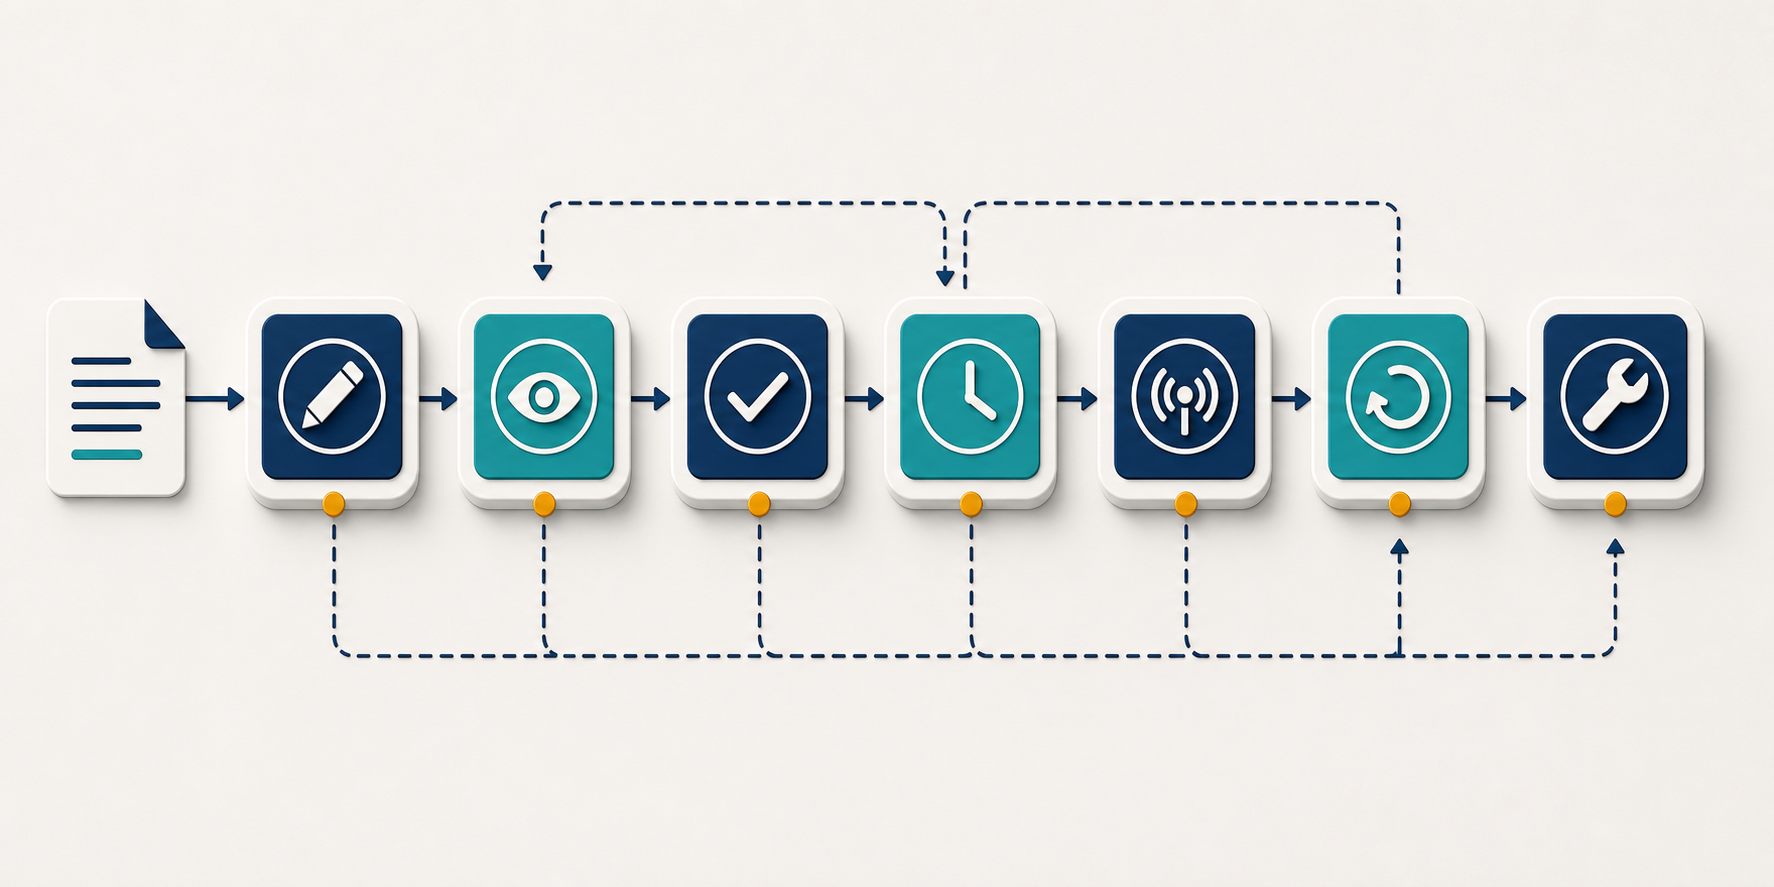
    A document moves through connected editing, review, approval, scheduling, publication, revision, and correction stages represented by symbols.

    Do not begin by sending every CMS update to a channel. That creates a feed, not an operating system. Begin with the state changes that require a person to decide, act, or investigate.

    A practical first workflow is the review loop: an author requests review, a reviewer approves or returns the item, a publisher schedules it, and the system confirms publication. It is narrow enough to test, but it exposes the permissions, stale-revision, notification, and failure-handling problems that larger automations must solve.

    1. Name each event for what happened, such as content.review_requested, content.approved, content.scheduled, content.published, and content.publish_failed.
    2. Define the CMS state required before each event. A schedule action, for example, should not accept an item that is still marked in review.
    3. Define who may trigger the transition. Channel membership alone should never grant publication authority.
    4. Specify the write-back. Record the actor, decision, relevant revision, timestamp, and reason where one is required.
    5. Specify the failure path. Decide who is notified, what remains unchanged, and how the action can be retried safely.

    Put enough context in every actionable message

    A reviewer should not have to search several systems just to understand the request. Each actionable Slack message should identify:

    • The content title and stable CMS identifier.
    • The content type, site, locale, and environment when your operation has more than one.
    • The current state and requested next state.
    • The owner and requested reviewer.
    • The revision being reviewed.
    • A preview link and an edit link with visibly different labels.
    • The requested action and any deadline already stored in the workflow.
    • Validation failures or missing fields that could block the transition.

    Include the revision identifier even if people rarely read it. Without it, someone can approve an earlier preview after another editor has changed the content. The integration should reject or re-request an approval when the underlying revision no longer matches.

    Engineer for duplicate and delayed events

    CMS events can be retried, delivered late, or received more than once. Give each event a stable identifier, retain the content and revision identifiers, and make handlers idempotent so a retry cannot schedule or publish the same revision again. When event order matters, compare the incoming revision and state with the current CMS record before changing anything.

    A failed delivery also needs an explicit destination. Send operational failures to a channel monitored by the people who can resolve them, with the content identifier, attempted action, error category, and safe retry path. Do not report success until the CMS has accepted the mutation.

    Route by responsibility rather than broadcasting everything. Review requests belong where reviewers work; release confirmations belong where publishers monitor launches; integration failures belong with the workflow owner. Batch low-priority activity into a digest if nobody needs to act immediately. Notification volume is part of the design because an alert that is routinely ignored is not a control.

    Make approvals durable, scoped, and revision-aware

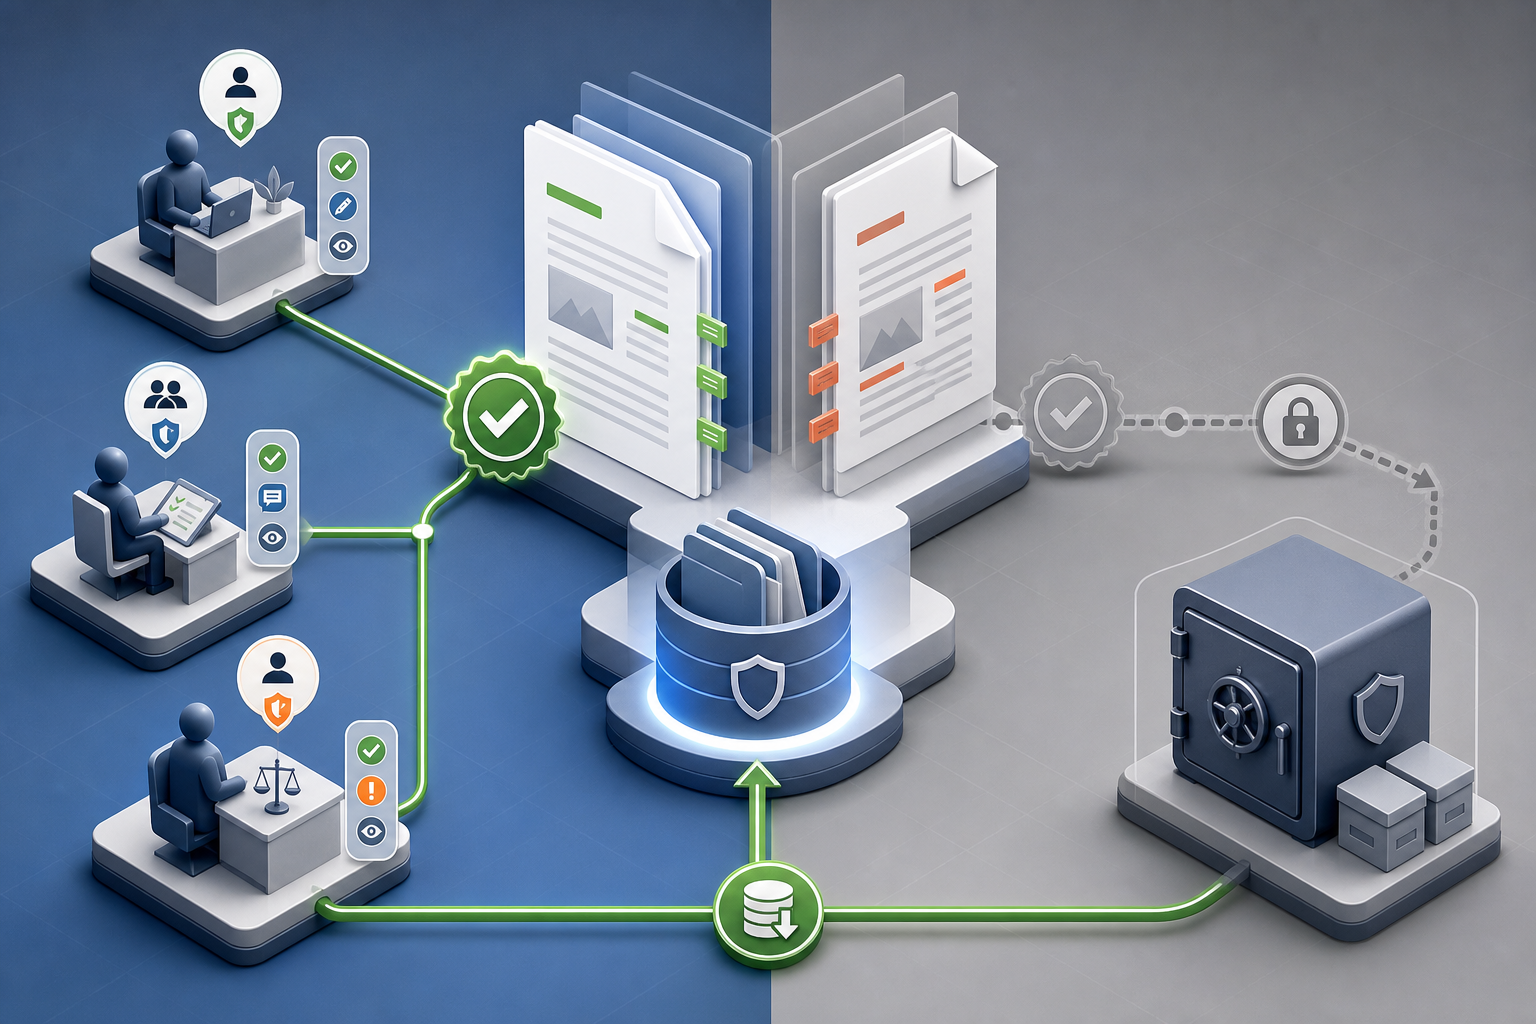
    An isometric workflow shows two document revisions, with the latest connected to an approval seal and archive while the older approval path is locked.

    Approval is a state transition, not a reaction. An emoji can communicate sentiment, but it should not be the only evidence that a specific person approved a specific revision for publication.

    Use separate roles even when one person fills more than one of them:

    • The author prepares the item and requests review.
    • The reviewer approves the current revision or returns it with a reason.
    • The publisher confirms the destination and schedule.
    • The integration verifies the transition, writes it to the CMS, and reports the resulting state.

    Keeping the actions distinct makes handoffs visible. It also lets you change permissions later without redesigning the entire workflow.

    Validate every action at the moment it is taken

    • Authenticate the Slack user and map that identity to an authorized CMS user or role.
    • Confirm that the content remains in the expected state.
    • Confirm that the revision still matches the one shown in the message.
    • Require a reason when content is rejected, sent back, or moved through an override path.
    • Write the result to the CMS before updating the Slack message.
    • Replace the actionable controls with the final outcome so an old button cannot be used later.

    If any check fails, leave the CMS state unchanged and explain what the person should do next. A stale approval should lead to a fresh preview and review request, not a best-effort approval of whatever revision happens to be current.

    Plan the exception path before you need it

    Urgent corrections will eventually bypass a normal queue. Give that path tighter controls rather than no controls: limit who can use it, require a reason, identify the revision, record the override, and notify the content owner. For destructive actions, prefer unpublishing or archiving with revision history intact over deleting content from a Slack control. A mistaken chat action should not erase the recovery path.

    Threads are useful for discussion, but the final decision must still return to the CMS. Summarize the resolution in a structured field or audit entry rather than expecting a future editor to reconstruct it from channel history.

    Tie the workflow to AI-search quality, then measure it

    Connecting Slack to a CMS does not, by itself, make a page more visible in AI search. The connection supports visibility when it helps your team publish accurate, accessible, well-structured content and correct problems without losing ownership or context.

    Turn high-risk quality checks into publication gates

    Store these checks in the CMS or validation service and surface their results in Slack. Do not ask reviewers to type machine-readable values into chat.

    • Confirm that the title, summary, headings, and visible answer agree about the page’s subject.
    • Confirm that the intended public URL, canonical selection, and index controls are set for the correct environment.
    • Validate that structured data describes the content a visitor can actually see rather than an earlier draft or a different page type.
    • Require the relevant author, organization, product, service, date, and taxonomy fields for the content type.
    • Check that important claims, citations, and destination links survived the latest revision.
    • Assign an owner for future corrections so a published item does not become operationally anonymous.

    The Slack notification should report pass, fail, or needs review for each gate and link to the field that needs work. It should not bury a blocking error in a long log. If a check is advisory rather than mandatory, label it that way so reviewers know whether they can proceed.

    After publication, send a separate confirmation containing the public URL, CMS identifier, published revision, responsible user, and validation outcome. A publication request and a successful publication are different events. Treating them separately keeps a timeout or platform error from looking like a completed launch.

    Measure the handoffs, not the message count

    Slack activity is not a useful success metric on its own. Join workflow events by content identifier and track the points where work waits, returns, or fails:

    • Review queue age: time from review request to the first reviewer action.
    • Approval cycle time: time from review request to approval of the accepted revision.
    • Revision loops: how often an item returns to the author before approval.
    • Stale actions: attempted decisions against a revision or state that has already changed.
    • Metadata completeness: required fields present when review or publication is requested.
    • Publication reliability: successful confirmations compared with failed or unresolved publication attempts.
    • Post-publication corrections: items that require an avoidable fix after release.

    Establish the baseline before adding more automation, then compare the same content type and workflow stage. If review time remains high but routing delay falls, the integration is doing its job and the remaining constraint is editorial capacity or decision quality. If correction volume rises, faster publishing has exposed a weak gate rather than solved the operation.

    Keep operational measures separate from AI-search outcomes. Visibility, mentions, citations, and referral traffic can change for many reasons outside Slack. Use the integration to preserve a reliable record of what changed and when, then evaluate search outcomes against that record without assigning the entire movement to one tool connection.

    Key takeaways

    • Keep content, metadata, permissions, revisions, and final state in the CMS; use Slack to route attention and authorized actions.
    • Automate named state transitions rather than forwarding every update into a channel.
    • Attach every approval to a specific content item and revision, then write the decision back to the CMS.
    • Design for duplicate events, delayed events, stale buttons, permission failures, and publication errors from the beginning.
    • Surface SEO, structured-data, and content-quality gates in Slack while retaining their values and validation logic outside chat.
    • Measure queue age, revision loops, stale actions, failed publications, metadata completeness, and corrections before expanding the workflow.

    Start with one transition that currently causes visible friction, usually the move from ready for review to approved. Make that loop authoritative, revision-aware, and recoverable. Once it works without manual reconciliation, extend the same event model to scheduling, publication, updates, and post-publication quality checks.

    References

  • 7 Creative GPT Automations to Boost Your SEO Workflow

    7 Creative GPT Automations to Boost Your SEO Workflow

    I’ve discovered how custom GPTs can revolutionize how we handle SEO, transforming repetitive tasks into efficient workflows. By leveraging AI, we can speed up our processes, from planning and analysis to reporting and technical work.

    If you don’t have access to paid ChatGPT, don’t worry. You can still utilize these prompts by saving them as standalone references in your notes. Remember, they’re just starting points, so modify them to fit your team’s requirements.

    Working with AI requires trial and error. My advice is to start with small tasks to practice writing prompts. Iterate on them and take notes on what produces good outputs.

    AI can sometimes be verbose, so it’s helpful to set strict formatting guidelines and clear context. Upload resources and articles to guide AI results, and always define the role and audience upfront.

    Let’s dive into seven prompts that I’ve found incredibly useful for developing custom GPTs dedicated to planning, analysis, and ongoing SEO tasks:

    1. Project plan GPT

    By analyzing previous project plans, I can create a GPT that assists in drafting this year’s focus areas.

    How to set it up

    • Input project plans from previous years.
    • Specify a format for consistency.
    • Determine the number of items or sections to include.
    • Include specific details unique to your team.
    • Optionally, integrate team feedback and retrospectives.

    Example prompt

    Based on last year’s project plan, outline this year’s focus. List three critical items for each quarter, ensuring at least one covers link building.

    Include a one-sentence summary for each recommended item and at least two KPIs to measure success.

    [Insert last year’s plan.]

    Now critique the plan. Offer three reasons against focusing on these items, providing sources for your notes.

    Dig deeper: How to use ChatGPT Tasks for SEO

    2. Site performance GPT

    By connecting performance dashboards or custom GA reports to ChatGPT, it can handle initial issue identification. This allows me to focus on investigating critical trends.

    How to set it up

    • Hook up reporting tools or upload data directly.
    • Direct AI on specific aspects to investigate.
    • Set frequency for data review, such as daily or weekly.
    • Provide examples of pages or categories to analyze.

    Example prompt

    Here’s the weekly site report. Analyze this week’s performance against last week’s data, summarizing sessions, conversions, and engagement.

    Highlight three successes and three areas needing improvement, color-coded by significance.

    [Insert report doc.]

    3. Competitor analysis GPT

    I’ve found it invaluable to scrutinize what works on competitor sites. This often involves tools like Semrush or Ahrefs.

    How to set it up

    • Integrate Ahrefs, Semrush, or upload relevant reports.
    • Select competitors and identify top-performing pages.
    • List key metrics for evaluation.
    • Create unique prompts for various levels of analysis.
    • Optionally, document metrics requiring deeper scrutiny.

    Example prompt

    As an SEO analyst, compare these URLs. Present a table detailing backlinks, average rank, top keyword, sessions, and value for each URL.

    Provide a concise summary of category leaders, referencing this link for criteria and citing sources.

    URL 1:
    URL 2:
    URL 3:
    Article reference:

    Dig deeper: Advanced SEO competitor analysis for better rankings

    Now, more than ever, custom GPTs are making a significant impact alongside existing SEO tools and workflows. They’re not about replacing the tools we use, but about making initial tasks smoother so that we can focus on insightful and strategic actions. By integrating them into our everyday processes, from planning to technical checks, we can really enhance our productivity.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google Performance Max Ad Previews: A Practical QA Guide

    Google Performance Max Ad Previews: A Practical QA Guide

    You’ve refreshed a Performance Max asset group and need a clear answer before approving it: will the creative still look deliberate when it appears across different placements? Until now, getting that answer could take more navigation than the review itself.

    The one-click preview makes the mechanical part faster. Its real value, however, depends on what you do after opening it. With a fixed review sequence, you can turn a convenient interface shortcut into a reliable quality-control step.

    Where the one-click PMax preview lives

    Google Ads has shortened the path between the asset list and the rendered ad. From the Asset Groups table, clicking an image or video now opens previews for different Performance Max placements without requiring you to leave the page.

    That is a workflow change, not a new campaign strategy. The preview does not, by itself, add targeting control, supply performance evidence, or explain why PMax gives one asset more delivery than another. It puts the creative closer to the surface so you can inspect it with less friction.

    The time saving matters most when you manage a large asset library or replace creative frequently. Instead of treating previews as a separate destination that you visit only when something looks wrong, you can use the Asset Groups table as a review queue: open an asset, inspect the available presentations, record the decision, and move to the next one.

    Do not assume that opening one image validates the entire asset group. A preview answers a narrow question about the creative in front of you. If several images or videos changed, each changed asset needs its own review.

    A repeatable workflow for reviewing PMax creative

    Hands arranging abstract ad-preview cards through visual checks for first impression, cropping, contrast, and consistency across devices.

    Random clicking is quick but unreliable. Use the same sequence every time so that a busy reviewer does not approve the first attractive rendering and miss a problem elsewhere.

    1. Define the scope before opening previews. Identify which asset groups changed and whether the change involved an image, a video, the surrounding message, or several elements. If the message changed, include older assets in the review because a previously acceptable visual may no longer fit the new offer.
    2. Set the blocking criteria. Decide what requires revision before approval: an unclear focal point, unreadable embedded text, a hidden logo, a conflicting offer, an awkward crop, or a mismatch with the destination. This keeps personal taste from becoming the approval standard.
    3. Open each image and video from the Asset Groups table. Review every placement presentation the interface makes available. Do not stop after the first version simply because it looks acceptable.
    4. Inspect in a fixed order. Check composition first, legibility second, brand and product recognition third, and message consistency last. A fixed order reduces the chance that a strong headline distracts you from a weak crop.
    5. Record an asset-level decision. Use simple statuses such as Pass, Revise, and Block. Include the asset identifier, the placement or rendering where the issue appeared, the reason for the decision, the required change, and the person responsible for it.
    6. Reopen the preview after revision. A corrected source asset can solve one problem while creating another presentation issue. Approval should apply to the revised rendering, not to the intention behind the revision.

    This process also makes team reviews easier to resolve. “The creative feels off” gives a designer little direction. “The product is no longer recognizable in the narrow rendering” identifies the visible failure and the condition the next version must satisfy.

    What to inspect across the available placements

    Image composition and legibility

    An image can be strong as a standalone file and weak once placed inside an ad layout. Review the displayed creative as a user would encounter it, not as the designer saw it on a full-size canvas.

    • Focal point: Confirm that the product, person, or action remains immediately understandable in each displayed presentation.
    • Embedded text: Check whether words inside the image remain readable. If the message depends on enlarging the preview, it is not doing its job in the ad.
    • Logo and product recognition: Make sure the identifying elements are visible without crowding the composition.
    • Edges: Look for important details that sit too close to the boundary or appear cut off in a displayed rendering.
    • Visual hierarchy: The main subject should win attention before decorative elements, badges, or background details.

    A useful test is to ignore the surrounding copy for a moment. If you cannot tell what the image is trying to communicate, the text is being asked to rescue the creative.

    Video clarity and continuity

    Review a video as a sequence, not merely as a valid uploaded file. The opening should establish enough context for the viewer to understand what follows. Watch on-screen text, scene changes, product visibility, logos, and the ending. Important information should not become hard to read or appear crowded by the displayed layout.

    Then compare the video’s promise with the rest of the ad. A polished video can still fail review if it promotes a different product, audience, offer, or next step from the copy presented with it.

    Asset pairing and destination consistency

    PMax creative should be reviewed both as individual assets and as an assembled message. When copy appears with the selected image or video, read the combination from beginning to end.

    • Confirm that the visual and copy refer to the same product, service, or action.
    • Remove accidental repetition when an image already contains the same wording shown beside it.
    • Check that a specific offer in the creative agrees with the current campaign message.
    • Make sure the requested action is a sensible next step for the user.
    • Compare the approved ad message with the destination page separately. The preview can show the ad side of the experience, but it cannot perform that destination review for you.

    This is where the preview earns more than a quick visual check. Assets that look acceptable in isolation can become confusing when presented together. Reviewing the assembled message helps you catch that problem before treating it as a performance mystery.

    What a PMax preview can and cannot prove

    Split illustration showing a controlled ad preview beside the same creative appearing in varied real-world screen contexts.

    The most important distinction is between visual evidence and performance evidence. A preview lets you examine what is displayed in the preview. It does not tell you whether that presentation will receive meaningful delivery or produce better campaign results.

    DecisionWhat the preview establishesWhat you should do
    Visual approvalWhether the displayed examples meet your creative standard.Inspect every available placement presentation for each asset in scope.
    Actual deliveryIt does not guarantee which asset combination will receive impressions.Use campaign reporting to evaluate delivery after the ads run.
    PerformanceIt does not show which asset will generate stronger results.Base performance decisions on relevant campaign data, not appearance alone.
    Destination consistencyIt shows the ad side of the message, not the full landing-page experience.Compare the creative, offer, and requested action with the destination manually.
    Root causeIt can expose a visible flaw but cannot prove that the flaw caused a performance change.Treat the preview as diagnostic evidence and investigate other campaign factors before assigning cause.

    This boundary prevents two common errors. First, an attractive preview is not proof that an ad will perform well. Second, weak results do not automatically prove that the crop, image, or video is responsible. Use previews to remove visible defects; use delivery and outcome data to make performance calls.

    The update also does not eliminate the broader transparency limits associated with Performance Max. It makes creative inspection easier, but it should not be mistaken for a complete view of the system’s selection and delivery decisions.

    Key takeaways

    • You can open placement previews by clicking an image or video directly in the Performance Max Asset Groups table.
    • Review every changed asset and every presentation available to you; one acceptable rendering does not validate the whole asset group.
    • Check composition, legibility, brand recognition, message consistency, and destination alignment in the same order every time.
    • Record Pass, Revise, or Block at the asset level, with the visible reason and required correction.
    • Use previews for creative quality assurance, not as proof of delivery, performance, or causation.

    For your next creative refresh, make preview review a release gate: no changed image or video leaves QA without a recorded pass or revision. The interface saves the clicks. A consistent checklist turns those saved clicks into fewer preventable creative mistakes.

    References

  • Agentic AI: Transforming PPC with Smart Automation

    Agentic AI: Transforming PPC with Smart Automation

    I’ve watched automation quietly transform PPC management over the years with rules, scripts, and API-driven workflows in Google Ads.

    Like many other marketers, I’m already very comfortable with automated bidding, data-driven optimization, and a suite of other AI-powered enhancements. But there’s a new shift on the horizon that’s set to redefine how we manage and optimize PPC campaigns.

    This time, I’m talking about AI agents and vibe coding. These innovations are ushering in a more autonomous mode of working where AI takes the lead in execution, allowing marketers like me to focus on strategy and creativity.

    This evolution promises unprecedented efficiency and flexibility, redefining effective PPC management.

    Agentic AI: Google Ads’ Game-Changing Feature

    In November 2025, Google rolled out its Agentic Ads Advisor, powered by advanced Gemini models. This tool helps advertisers like me uncover insights and boost campaign performance effortlessly.

    Google positions Ads Advisor as an AI partner that enhances campaign management by understanding business contexts, simplifying tasks, and learning from interactions to deliver better outcomes.

    However, the pressing question remains: What functionalities should an agentic AI tool embody?

    It should function as an autonomous agent, surfacing information as needed but also operating independently. It should identify opportunities for enhancing campaign setups, assets, ad copy, and more.

    An ideal agentic AI wouldn’t just make recommendations but also implement essential changes on its own.

    Integrating Agentic AI in PPC Workflows

    Agentic AI should ideally make decisions autonomously without needing constant human input, thereby managing, adjusting, and optimizing campaigns as they run.

    Beyond just advice or reporting, its real value lies in managing bidding, ad placements, and creative testing in real-time, based on live data, seasonality, and user behavior trends.

    With agentic AI handling more operational tasks, I can direct my efforts toward strategic decision-making.

    The competitive edge will increasingly rely on strategy rather than tools, focusing on marketing fundamentals like positioning, value propositions, and brand awareness.

    Read more: Agentic PPC: What Performance Marketing Could Look Like in 2030

    Why Agentic AI is Key for Advanced PPC Marketers

    Agentic AI appeals to experienced PPC marketers like myself because it scales campaigns without compromising strategic control, proving to be a true game-changer.

    With real-time optimization, data-driven creativity, and reduced human error, it redefines my role by allowing more time for strategy rather than execution.

    Despite its capabilities, informed oversight is essential to ensure alignment with broader marketing objectives, highlighting the need for ongoing professional engagement.

    Agentic AI isn’t replacing PPC professionals. Instead, it extends our capabilities, reduces manual effort, and facilitates better outcomes with minimal friction.

    Vibe Coding: Creating Your Marketing Toolbox

    In tandem with agentic AI, vibe coding is redefining how I work with AI-powered platforms, allowing me to create personalized, intuitive marketing tools and campaigns.

    Tools like Cursor and AI Studio have enabled me to articulate and realize specific needs seamlessly, even without being a developer.

    Incorporating vibe coding led me to build an SEO schema markup generator, an SEO audit tool, and a marketing idea generator, proving its practical value in my professional life.

    The possibilities expand when combining vibe coding with agentic AI, empowering marketers to engineer their AI agents tailored for PPC work.

    With this combination, I integrated these tools effectively within my marketing workflows, enhancing performance and strategy development at scale.

    Explore further: How Vibe Coding is Changing Search Marketing Workflows

    The Future: Navigating PPC with Agentic AI and Vibe Coding

    Agentic AI and vibe coding present immense opportunities to streamline PPC operations, enhance performance, and maintain competitiveness in a fast-evolving landscape.

    The future is about leveraging these technologies for more autonomous, data-driven, and personalized marketing strategies that benefit both internal teams and customers alike.

    As a PPC professional, it is crucial to embrace these advancements, ensuring adaptability and continued relevance in an AI-powered future.

    Follow experts like Alfred Simon, Mike Rhodes, and Ales Sturala to see practical applications of these innovative technologies in real-world scenarios.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google Merchant API Migration: A No-Surprises Checklist

    Google Merchant API Migration: A No-Surprises Checklist

    If your Shopping or Performance Max campaigns rely on an API-fed catalog, the Merchant API migration is a delivery dependency, not routine backend maintenance. Letting a legacy Content API connection reach its cutoff can interrupt campaigns that depend on its product feed.

    The dangerous version of this failure is not always an obvious API error. Products may arrive through the new connection while feed labels, campaign structure, or bidding logic no longer match. Your migration is complete only when the new API writes the right product data and the campaigns consuming that data still behave as intended.

    Confirm whether your account is exposed

    Start in Merchant Center Next. Open Settings > Data sources and inspect the type shown for every product source. Any source marked Content API belongs in your migration inventory. Do not assume that an ecommerce app, scheduled file, or newer integration elsewhere in the account means the legacy connection has already been replaced.

    For each Content API source, record:

    • The Merchant Center account and data source name.
    • The application, connector, platform, or custom code that writes the product data.
    • The person or provider able to change and deploy that integration.
    • How updates are triggered, including scheduled jobs and manual runs.
    • The Shopping and Performance Max campaigns that consume the products.
    • Every feed label associated with the source and what that label controls.
    • The evidence you will require before declaring the migration complete.

    If a third-party platform manages the connection, ask for more than a general confirmation that it supports Merchant API. You need four explicit answers: which connection will be replaced, when the change will reach your account, whether feed labels will be recreated or mapped, and whether you must reconnect anything inside Merchant Center Next. The provider may own the deployment, but you still own campaign validation.

    The transition began in mid-2024, and the communicated migration path cited February 28 for beta participants and August 18 for other Content API users. Those month-and-day references are not safe planning dates without the applicable year and account context. Use the dated notice attached to your own account as the operative cutoff. If nobody can produce that notice, treat the connection as an active risk rather than assuming you have more time.

    Preserve feed labels before moving product data

    Generic retail products with colored geometric tags cross a bridge between two database structures with their tags still attached.

    Feed labels can be part of your campaign architecture. They may separate inventory or support bidding decisions, yet they do not transfer seamlessly during this migration. That creates a misleading success state: the new connection works, products appear, and the technical ticket closes, but a label-dependent campaign no longer addresses the same inventory.

    Build a label map before changing the connection. For each existing label, capture:

    • The exact current value, including spelling and capitalization.
    • A small set of representative products that should carry it.
    • The campaign structure or bidding rule that depends on it.
    • The value expected after migration.
    • The person responsible for checking it in the advertising account.

    Include products from every label and at least one product that intentionally has no label. That last case helps you distinguish a valid blank value from a failed transfer. Compare the same products before and after cutover instead of checking whichever items happen to be easiest to find.

    Do not rename, consolidate, or reorganize labels during the API migration unless the old structure makes the cutover impossible. Combining cleanup with migration destroys your baseline: when inventory changes, you will not know whether the API, the new label design, or the campaign edit caused it. Move the existing behavior first, prove parity, and schedule cleanup as a separate change.

    Run the migration as a controlled cutover

    A useful migration plan separates preparation, technical cutover, and advertising validation. It also names the person who can stop or reverse the change. Use this sequence:

    1. Assign two owners. The technical owner changes the integration. The paid media owner verifies labels, inventory coverage, and campaign behavior.
    2. Freeze unrelated changes. Avoid simultaneous feed restructures, label renaming, and major campaign edits from baseline capture through validation.
    3. Capture the baseline. Save the current data source type, label map, representative products, update process, and dependent campaigns.
    4. Configure the Merchant API connection. Update the system that actually writes product data, then reconnect the data feed where the migration flow requires it. A code deployment alone does not prove that Merchant Center is receiving the new writes.
    5. Preserve rollback material. Keep the previous configuration, mappings, and baseline evidence until validation finishes. Do not allow two uncontrolled connections to write conflicting versions of the same products.
    6. Send a controlled update. If the integration permits it, change a representative product through the real production path. Choose a field whose before-and-after state is easy to verify.
    7. Check every label path. Compare the representative products against the label map and confirm that dependent campaign structures still include the intended inventory.
    8. Observe a scheduled run. A successful manual request does not prove that the recurring job, connector, or automation has been migrated.
    9. Retire the legacy connection only after sign-off. Require approval from both the technical owner and the paid media owner.

    Define rollback triggers before cutover. Missing labels, a test update that never reaches Merchant Center, or a campaign structure that loses its intended inventory are reasons to stop and investigate. A rollback should restore a known configuration, not blindly reactivate every old process.

    Validate business behavior, not just API success

    An operator oversees parallel product-data pipelines as checkpoints verify deliveries to a storefront, campaign engine, and bidding controls.

    An authenticated request proves only that one request was accepted. End-to-end validation has three layers: the connection, the product data, and the campaign consuming that data.

    Connection validation

    • Confirm that Merchant Center Next shows the intended new data-source connection rather than the legacy Content API source.
    • Verify that a deliberately changed product value arrives through the new path.
    • Run or observe the normal scheduled process and confirm that it uses the same path.
    • Record the time, product tested, expected result, actual result, and validator.

    Product and label validation

    • Check the same representative products captured in the baseline.
    • Compare each expected label character for character.
    • Confirm that intentionally unlabeled products remain unlabeled.
    • Test an ordinary product update after the initial migration so you know the connection handles ongoing changes, not only the first import.

    Campaign validation

    • Inspect every Shopping or Performance Max structure that relies on a migrated feed label.
    • Confirm that each label still selects the intended inventory and that no expected subset has become empty.
    • Check that bidding logic tied to those labels still points to the right product group.
    • Have the paid media owner sign off independently of the developer or integration provider.

    Do not use immediate spend or revenue as your only acceptance test. Auction results vary, and business metrics can lag behind a configuration error. Structural checks – the right products, labels, and campaign relationships – reveal migration mistakes sooner. Performance monitoring should follow, but it cannot replace those checks.

    Keep the validation record with the integration documentation. It should show the old and new connection, the label mapping, the test products, the scheduled-run result, the dependent campaigns, and both approvals. That evidence gives you a precise starting point if a later feed or campaign problem appears.

    Key takeaways

    • A data source marked Content API in Merchant Center Next is a migration dependency that needs a named owner.
    • Moving products is not enough. Feed labels require an explicit before-and-after mapping because they may not transfer cleanly.
    • Separate the API cutover from feed cleanup and campaign restructuring so you retain a useful baseline.
    • Validate the new connection, a normal scheduled update, representative products, labels, and every dependent Shopping or Performance Max structure.
    • Use the dated notice for your own account to determine the applicable cutoff rather than relying on an unqualified calendar date.

    Open Merchant Center Next and inspect Data sources now. If Content API appears, assign a technical owner and a paid media validator in the same work item. Close that item only after a scheduled product update reaches the new connection and the label-dependent campaigns still address the inventory you intended.

    References

  • Google SearchGuard: An Operations Guide for SEO Teams

    Google SearchGuard: An Operations Guide for SEO Teams

    If your rank tracking, share-of-voice reporting, or AI visibility workflow depends on automated Google results, SearchGuard can turn a routine data feed into a business-continuity problem. Collection may become incomplete or unavailable while the dashboards built on top of it continue to look authoritative.

    Your immediate job is not to find a cleverer bypass. It is to identify which decisions depend on scraped search results, establish how each provider acquires them, and prevent missing observations from being misreported as ranking losses.

    Why SearchGuard breaks the old scraper playbook

    BotGuard, internally called Web Application Attestation or WAA, protects multiple Google services. SearchGuard is the Search-specific implementation. It is designed to distinguish a person using a browser from an automated script without relying on a traditional, visible CAPTCHA.

    That distinction changes the failure model. A CAPTCHA is an obvious interruption. An invisible attestation system can evaluate the session while the interaction is happening. Loading a results page once therefore does not demonstrate that an automated collection method will remain stable at scale.

    The early-2025 implementation was reported to have disrupted nearly all SERP scrapers. Whether that disruption reaches your team directly or through a vendor, the operational lesson is the same: automated Google access is an external dependency whose availability and data quality must be measured, not assumed.

    Start by separating three questions that teams often collapse into one:

    • Can the collector retrieve a page? This is a technical availability question.
    • Did it retrieve the complete observation you requested? This is a data-quality question.
    • Is the collection method authorized and legally defensible? This is a governance question.

    A provider can answer yes to the first question while leaving the other two unresolved. Your dashboard should not treat technical success as proof of completeness, permission, or long-term reliability.

    The signal stack goes beyond a single bot tell

    Automated request signals pass through several layers of digital inspection while suspicious signals are diverted and human-origin signals continue.

    The available technical detail comes from decrypted version 41 of BotGuard, the broader system behind the Search implementation. Treat it as a map of relevant signal classes, not a complete or permanent specification of every SearchGuard decision.

    Behavioral signals form a composite pattern

    Mouse, keyboard, scrolling, and timing behavior can all contribute evidence about whether an interaction looks human:

    • Mouse analysis can include path shape, speed, changes in acceleration, and small irregularities in movement.
    • Keyboard analysis can include intervals between keys, keypress duration, error sequences, and pauses after punctuation.
    • Scrolling and general timing can reveal whether actions contain natural, context-dependent variation rather than fixed automation intervals.

    The important point is not that one straight mouse path or one regular pause proves automation. SearchGuard can assemble multiple observations into a broader behavioral profile. A vendor that talks only about imitating one visible action is addressing a much narrower problem than the system presents.

    The browser environment is part of the evidence

    The evaluation is not confined to pointer and keyboard events. BotGuard can use more than 100 HTML elements and browser-environment signals, including navigator properties, screen metrics, performance information, and interaction with browser APIs.

    This is why a collector that produces a visually correct page can still be fragile. Rendering the right DOM is only one part of the session. The surrounding environment and the way it behaves can be evaluated as well.

    Statistical profiling makes fixed emulation brittle

    Welford’s algorithm and reservoir sampling are among the techniques associated with the system. They support continuously updated statistical summaries and sampling from streams of observations. Operationally, that points to a moving composite profile rather than a permanent list of checks that can be patched once and forgotten.

    The protected bytecode virtual machine and cryptographic integrity measures add another layer of resistance to reverse engineering. A temporary workaround can therefore expire when code, challenges, expected behavior, or the scoring model changes.

    Do not use this signal list as an evasion checklist. Use it to set the right expectations with engineering teams and vendors. A durable measurement program needs observability around collection, not just a promise that automation worked during a demo.

    Key takeaways

    • SearchGuard is the Search-specific form of Google’s broader BotGuard or Web Application Attestation system.
    • It can combine behavioral, timing, browser-environment, and statistical signals instead of depending on a visible CAPTCHA.
    • A rendered results page does not, by itself, establish complete data, durable access, or authorization.
    • Attempts to bypass the system can create both technical fragility and legal exposure.
    • Your safest response is to audit data provenance, label collection failures correctly, and give every important workflow a fallback.

    Audit vendors before enforcement becomes your outage

    Google’s lawsuit against SerpAPI alleges that the company bypassed SearchGuard to extract copyrighted Google Search data at large scale. Google framed the claim around the anti-circumvention provisions of DMCA Section 1201 rather than making a terms-of-service dispute the center of the case.

    An allegation is not a final ruling, and it does not establish that every form of search-result collection is unlawful. SerpAPI’s CEO says Google did not contact the company before filing and characterizes the action as an attempt to restrain a service used by other innovators. That disagreement matters because the technical method, the rights involved, and the legal theory may all be contested.

    It would still be a mistake to classify this as somebody else’s vendor dispute. If a provider intentionally circumvents a technological control, you may face service interruption, contract problems, replacement costs, and legal questions that an uptime report cannot answer. Have qualified counsel review your particular method and jurisdiction when circumvention is part of the collection chain.

    The dependency can also be several layers removed from the final product. OpenAI used Google results obtained through SerpAPI after Google denied a 2024 request for direct access to its index. For an SEO or AI visibility team, that is a reminder to examine your vendor’s suppliers as well as the name on your own contract.

    Run the audit in this order:

    1. Map the dependency. Record every report, alert, model, recommendation, and client deliverable that consumes automated Google results. Assign an owner to each one.
    2. Document the complete collection chain. Ask who retrieves the results, whether subcontractors or resellers participate, and whether the provider collects directly or buys from another supplier.
    3. Request the provider’s stated basis for access. Get the answer in writing. Browser automation describes a mechanism; it does not explain authorization, rights, or legal defensibility.
    4. Define the requested observation. Record the query, requested context, expected fields, refresh cadence, and timestamp. Without that contract, you cannot distinguish a complete result from a plausible-looking fragment.
    5. Require explicit failure semantics. The provider must distinguish a successful observation, an access failure, a partial response, and a reused cached response. A blank field is not an adequate status code.
    6. Add commercial protections. Review incident-notification duties, subcontractor disclosure, data-quality commitments, termination rights, and the process for exporting your configurations if the feed becomes unavailable.
    7. Choose the fallback before launch. Decide which workflows can use a manual sample or first-party performance data, which must pause, and which can proceed with a clearly displayed uncertainty warning.

    Answers that should stop a launch

    Do not let a data feed into consequential reporting if the provider:

    • will not identify the collector or disclose whether additional suppliers are involved;
    • uses the word compliant without identifying the scope, jurisdiction, contract, or other basis for that claim;
    • cannot distinguish blocked collection from a genuine absence in the search results;
    • does not attach collection time, freshness, and completeness metadata to observations;
    • treats repeated workaround deployment as its only continuity plan; or
    • cannot explain what happens to your history, configurations, and reporting when access fails.

    None of these signs proves misconduct. Each one does prevent you from evaluating the reliability and exposure of a dependency that may influence budgets, content priorities, client reports, or executive decisions.

    Build reporting that survives missing SERP data

    Two analysts review a reporting pipeline that routes around missing data sources and shows affected dashboard areas with caution indicators.

    The most damaging SearchGuard failure may not be an obvious outage. It may be a partial dataset that enters a trend line as though collection completed normally. Protect the decision layer by giving every observation an explicit state.

    Data stateWhat it meansHow reporting should behave
    ObservedThe requested collection completed and the expected fields passed validation.Include it with its collection time and requested context.
    UnavailableThe collector could not complete the request.Report an availability gap. Never translate it into a ranking loss or absence.
    IncompleteOnly part of the planned query set or expected response was obtained.Show coverage and suppress aggregates that require the missing observations.
    StaleThe workflow is reusing an older observation beyond the freshness allowed for that decision.Display the original timestamp and exclude it from comparisons presented as current.

    Your acceptable freshness and completeness thresholds should follow the decision cadence. A dataset may be adequate for a slow-moving planning exercise and inadequate for a report that triggers an immediate campaign change. Define that rule in the workflow instead of asking an analyst to make an improvised judgment after a failure.

    Design around the decision, not maximum collection

    1. Collect the smallest representative query set that supports the decision. More queries create more dependency without automatically improving the conclusion. Tie each segment of the set to a reporting or monitoring need.
    2. Gate every aggregate on coverage. Store planned, completed, valid, incomplete, and unavailable observation counts. Do not publish a visibility change when the underlying comparison fails your predefined coverage rule.
    3. Preserve provenance with the metric. Keep the provider, collection time, requested context, processing version, and data state attached through exports and dashboards. Retain raw material only where your rights, contract, and policies allow it.
    4. Separate acquisition from analysis. Give the analysis layer a documented input format so an approved replacement feed, manual observation, or first-party dataset can be introduced without rebuilding every dashboard.
    5. Use independent evidence for consequential changes. Before changing budget, content, or reporting because an external SERP metric moved, compare it with owned-site performance and manually inspect the high-impact queries where appropriate.
    6. Write a stop rule. Specify which recommendation, alert, or report must be withheld when collection is unavailable, incomplete, or stale. Missing evidence should remain unknown; it should not silently become zero.

    Start with the next search dashboard your team is scheduled to use. Trace every Google-derived field back to its collector, timestamp, completeness state, and fallback. If that chain cannot be explained, do not let the number silently drive the next decision.

    References

  • Google Ads Campaign Mistakes That Undermine Your Results

    Google Ads Campaign Mistakes That Undermine Your Results

    You can make a Google Ads account look more polished while making its decisions less reliable. Raise Ad Strength, accept recommendations, expand match types, and adjust bids, and you may still have no trustworthy answer to the question that matters: are the campaigns producing valuable business outcomes?

    If performance has become difficult to explain, resist the urge to rewrite everything at once. Audit the account in this order: measurement, search-term routing, campaign settings, and automation. That sequence protects the signal you need to decide what should change next.

    Fix measurement before tuning bids or targeting

    A specialist traces cables from a laptop, shopping bag, phone, and blank form to a measurement hub with one duplicate and one disconnected signal.

    Google Ads optimization inherits whatever definition of success you give it. If that definition changes from one campaign to another, the account can look internally consistent while comparing unlike outcomes.

    The common fault lines are attribution methods, count settings, conversion windows, and campaign-level overrides. Two campaigns may generate the same kind of customer action yet value the associated clicks differently because their conversion configurations differ. More traffic cannot solve that problem. It only produces more data under incompatible definitions.

    Create a conversion contract for the account

    A conversion contract is a simple record of what the account considers success. It does not need to be a complex measurement document. It needs to answer the same questions for every campaign you intend to compare:

    1. What real business event does this conversion action represent?
    2. Is the action used by bidding, or is it retained only for observation?
    3. Which attribution method assigns credit?
    4. Which count setting is used?
    5. How long is the conversion window?
    6. Does the campaign inherit the account configuration, or does it override it?
    7. If there is an override, what business reason requires it?

    Consistency does not mean forcing every conversion action into one configuration. A purchase, a qualified lead, and an informational interaction are different events. The goal is to measure the same event the same way wherever it appears and to document intentional exceptions.

    Campaign-level overrides deserve special attention because they can make one campaign accurate in isolation while weakening account-level comparisons. If an override no longer has a clear owner and rationale, treat it as configuration drift rather than strategy.

    Changing conversion settings can alter the signals used by automated bidding and therefore affect spend. Record the date and reason for each correction. Avoid changing conversion definitions, bid strategy, and keyword scope at the same time. When several inputs move together, you cannot tell which change produced the next result.

    Rebuild query control around real search terms

    An analyst sorts abstract search-query tokens into separate campaign channels and diverts irrelevant tokens through a side gate.

    Keywords are planning inputs. Search terms show the language people actually used. When the two diverge, the account can send valuable intent to inconsistent ads, bids, or landing pages.

    Do not abandon exact match because broad match is prominent

    The interface may encourage broad match, but that does not make exact match obsolete. Exact match can still be the highest-converting match type in an account. That is not a guarantee for every advertiser; it is a reason to preserve exact coverage where the account has already identified valuable intent.

    Start with the search-term report, not a speculative keyword expansion. Find terms that repeatedly produce the business outcome you care about. Then ask three questions:

    • Does the term have an exact-match keyword in the account?
    • Is that keyword located with the ad message and landing page best suited to the intent?
    • Does the term appear under several keywords or campaigns, producing different user experiences?

    If a proven term has no clear home, add exact-match coverage in the most relevant campaign or ad group. The aim is not to promise perfect routing. It is to give valuable intent a deliberate destination with a suitable message, bid context, and landing page.

    Find search terms that wander between keywords

    Looser matching can allow one search term to trigger multiple keywords. That duplication matters when those keywords sit behind different offers or messages. A person can express the same intent twice and receive two materially different paths through the account.

    Group repeated search terms by intent and identify the keyword, campaign, ad message, and landing page associated with each appearance. Choose a preferred destination for every important intent. Add exact coverage there and correct the surrounding message. Use negative keywords to prevent overlap only after checking the possible effects, because an overly broad negative can block demand beyond the conflict you intended to resolve.

    Evaluate broad match and bidding as one decision

    Broad match does not have one fixed performance profile. Its results depend partly on the bid strategy and on the conversion data supplied to that strategy. This is why broadening keyword eligibility before fixing tracking is especially risky: the system receives more freedom while pursuing an unreliable goal.

    Before expanding a keyword, write down the campaign objective, the bid strategy, the conversion actions informing it, and the search intents you are willing to buy. If any of those answers is unclear, the match-type change is premature. When you do test broader eligibility, keep the bidding and measurement definitions stable so the result remains interpretable.

    Treat negative keywords as living controls

    A negative keyword list captures an old decision. Products change, positioning changes, search behavior changes, and campaigns are reorganized. A list that was sensible when created can later block relevant searches and remove opportunities.

    Audit shared lists and campaign-specific negatives together. Classify each negative into one of three groups: always irrelevant, relevant only to an older campaign structure, or uncertain. Keep the first group, investigate the second, and compare the third against current keyword themes and converting search terms.

    Do not delete a large negative list merely because it is old. Removing negatives can immediately admit new traffic and increase cost. Correct confirmed conflicts in controlled batches, then inspect the resulting search terms before opening more traffic.

    Standardize campaign settings before comparing performance

    Campaigns sometimes need different settings. A regional campaign may require a unique location boundary, and a campaign tied to staffed sales hours may require a different schedule. The mistake is not variation. The mistake is unexplained variation that gets mistaken for performance.

    Build a settings matrix with campaigns as columns and the following controls as rows. The matrix makes invisible configuration differences easy to inspect:

    ControlWhat to compareDecision to record
    Conversion configurationActions used for optimization, attribution method, count setting, window, and overridesWhich campaigns should share the same definition of success?
    LocationsIncluded and excluded regionsWhich geographic differences are required by the offer?
    Ad schedulesDays and periods when ads can serveIs each restriction operationally necessary?
    Bid strategiesThe objective pursued by each campaignDoes the strategy match the campaign goal and available conversion signal?
    Keyword controlsMatch-type mix and exact coverage for proven termsWhich search intents should have a deliberate home?
    Negative listsShared and campaign-specific exclusionsWhich exclusions are permanent, contextual, or obsolete?
    AutomationRecommendation auto-apply status and allowed changesWhich changes require human approval?

    Review each difference as either intentional or accidental. An intentional difference gets a short rationale and an owner. An accidental difference gets corrected in a controlled change. If nobody can explain why one campaign excludes a region, runs a different schedule, or uses a different bid strategy, do not assume the setting is harmless.

    This matrix also prevents a common analytical error: crediting ads or keywords for a result created by campaign configuration. A campaign with wider geography, longer serving hours, or different conversion rules is not a clean comparison with its neighbors.

    Put interface scores and automation behind approval gates

    Google Ads can recommend an action, score an ad, and execute certain changes automatically. None of those mechanisms knows whether the change respects your commercial constraints unless those constraints are represented in the account’s data and settings.

    Ad Strength is a diagnostic, not the business objective

    A lower Ad Strength rating can reflect a deliberate decision to limit how ad content is combined. It can also coexist with stronger conversion performance. That relationship is not universal, but it is enough to reject the idea that maximizing the interface score should override measured outcomes.

    Before adding assets to improve the rating, identify what the existing constraints protect. They may preserve a required promise, keep a qualifier attached to an offer, or maintain alignment with the landing page. If a proposed variation weakens that connection, a higher score does not make it a better ad.

    Evaluate ads with the conversion action that represents the campaign’s goal. Use Ad Strength to notice possible limitations, then decide whether those limitations are intentional. Do not use it as a substitute for conversion quality or commercial value.

    Disable unattended changes that alter strategy

    Recommendation auto-apply can introduce changes such as adding keywords or modifying bid strategies. Those are not cosmetic edits. They can change which searches become eligible, how aggressively the account bids, and how budget is distributed.

    Review the account’s auto-apply status and turn off unattended changes that alter keyword scope, bidding, or other strategic controls. Recommendations can remain inputs to a review process. They should not bypass it.

    Apply the same standard to AI-generated recommendations. Automation works from the objectives and data it receives. If the conversion definition rewards low-value actions, the system can become efficient at producing the wrong result. If a stale negative list hides valuable demand, automation cannot optimize traffic it is never allowed to see.

    Require a short change brief before approving an automated recommendation:

    1. What account setting or campaign element will change?
    2. Which business outcome is the change expected to improve?
    3. Does it alter the definition of a conversion, query eligibility, bidding, or message control?
    4. Which result will show that the change helped?
    5. What condition would justify reversing it?

    If the recommendation cannot survive those questions, it is not ready to run. AI is useful for generating possibilities and finding patterns. Judgment is still required to decide which objective deserves optimization and which constraints should remain.

    Key takeaways: audit the account in a safe order

    • Align attribution methods, count settings, conversion windows, and campaign overrides before trusting comparisons.
    • Document the business event behind every conversion action used for bidding.
    • Add exact-match coverage for proven search terms that lack a deliberate destination.
    • Investigate valuable search terms that move between keywords, campaigns, messages, or landing pages.
    • Evaluate broad match together with its bid strategy and conversion signal.
    • Review negative keyword lists for conflicts before expanding traffic or removing exclusions.
    • Explain differences in locations, schedules, bid strategies, and other campaign settings.
    • Judge ads by relevant outcomes, not Ad Strength alone.
    • Turn off unattended strategic changes and require an approval brief for automated recommendations.
    • Change one decision layer at a time so the next result remains interpretable.

    Open the account and build the conversion and settings matrix before touching bids, budgets, or creative. Make the smallest correction that restores consistency, record it, and let the resulting signal determine the next move. That is slower than accepting every prompt in the interface, but it gives you something far more useful: an account whose results you can explain.

    References

  • Must-Read PPC Insights: 2025’s Top 10 Expert Articles

    Must-Read PPC Insights: 2025’s Top 10 Expert Articles

    Top 10 Search Engine Land PPC columns of 2025

    This past year, PPC has been anything but static – it has evolved. As I explored the insights from 2025, I found these articles resonated deeply. They addressed crucial questions like maintaining a competitive edge, eliminating wasteful spending, collaborating with automation, and gearing up for the future.

    Join me as I take you through the links to the top 10 most-read PPC columns on Search Engine Land from 2025, crafted by our incredible experts.

    10. Can small businesses compete on Google Ads anymore?

    Though it might seem challenging, even the smallest businesses can carve out their niche and captivate customers. Discover the strategies that make this possible. (By Sophie Logan. Published Sept. 16.)

    9. Google Ads optimization: What to stop, start, and continue in 2025

    Update your optimization techniques for 2025 with innovative approaches to keywords, Performance Max, and audience targeting. (By Pauline Jakober. Published Feb. 6.)

    8. CPC inflation: How fast are Google Ads costs rising?

    With increasing CPCs, understanding the pace of this inflation and comparing it to the consumer price index is essential for shaping your ad strategies. (By Mark Meyerson. Published April 16.)

    7. The end of SEO-PPC silos: Building a unified search strategy for the AI era

    AI is bridging the gap between organic and paid search. Learn how integrating SEO and PPC can enhance your visibility and brand presence. (By Jen Cornwell. Published Oct. 6.)

    6. How to vibe code for PPC: Building a seasonality analysis tool

    PPC scripts have limitations, but with vibe coding, you can remove obstacles and transform complex seasonal data into practical planning tools. (By Frederick Vallaeys. Published Aug. 21.)

    5. How to write high-performing Google Ads copy with generative AI

    Streamline your ad creation process without losing your core message. Leveraging generative AI can help craft engaging, personalized copy that truly connects. (By Jason Tabeling. Published Aug. 1.)

    4. 7 Google Ads search term filters to cut wasted spend

    Discover filtering techniques that refine targeting, reduce unnecessary clicks, and reveal new keyword opportunities. (By Menachem Ani. Published July 22.)

    3. Google Ads scripts: Everything you need to know

    Enhance your campaign management with Google Ads scripts. Uncover insights, actionable tips, and use cases for leveraging automation to improve performance. (By Frederick Vallaeys. Published Jan. 9.)

    2. PPC in the age of zero-click search: How to stay profitable

    As clicks become scarcer, maintaining visibility requires precise targeting and value-based bidding. Achieving this ensures your prominence in both paid and organic searches. (By Sarah Stemen. Published Oct. 7.)

    1. 5 Google Ads tactics to drop in 2026

    With Google’s environment becoming more automated, some PPC tactics are now obsolete. Discover what to eliminate and what to focus on for the coming year. (By Sarah Vlietstra. Published Nov. 4.)


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot